Author: shivamcrushpressai

  • Cross-Channel Acquisition: Budget Depth and True Incrementality

    Cross-Channel Acquisition: Budget Depth and True Incrementality

    Cross-channel customer acquisition is not simply a matter of adding more platforms. It requires two linked decisions: how much funding each channel needs before it can be judged fairly, and whether the customers credited to that channel are genuinely new.

    The source articles examine different sides of this problem. One warns that an undersized test can make a viable channel appear inefficient; the other warns that overlapping platform attribution can make acquisition appear more profitable than it is. Together, they point to a more disciplined way to allocate budgets and evaluate incremental growth.

    Key takeaways

    • Channel tests should reflect the expected response curve; a small trial is not equally informative for every channel.
    • Demand-capturing and demand-creating channels serve different roles and should not be evaluated with identical expectations.
    • Platform-reported conversions can overlap, particularly when customers encounter paid social and Performance Max during the same journey.
    • Budget allocation should combine marginal efficiency with evidence that spending is attracting net-new customers.

    Budget breadth depends on the channel’s response curve
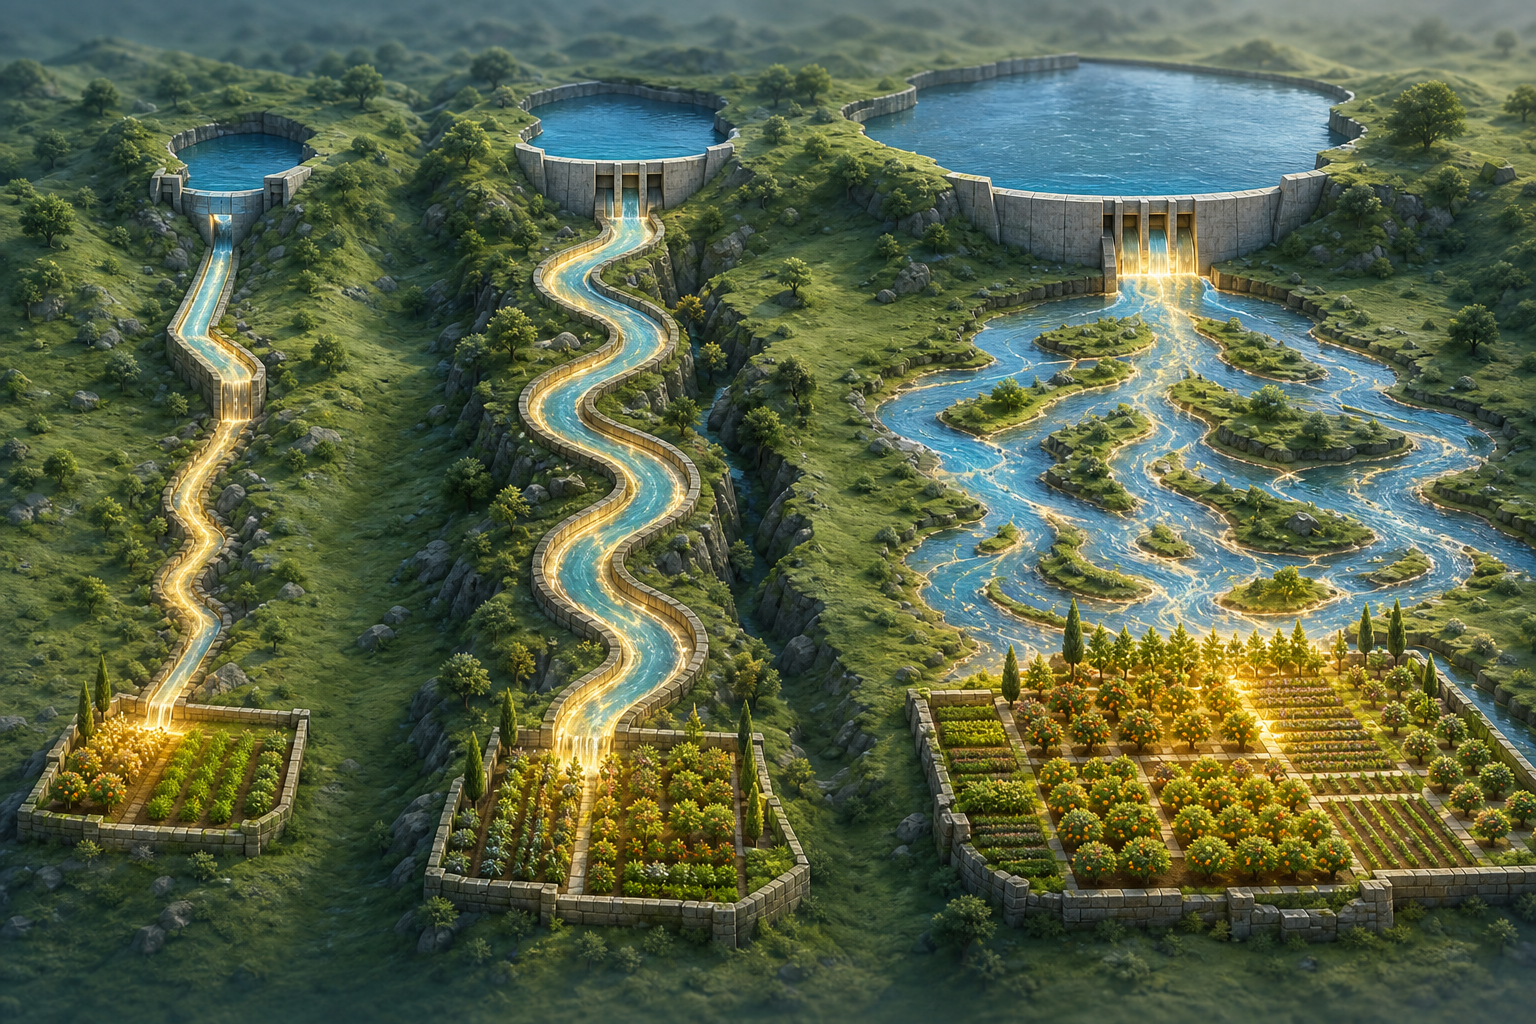
    Three differently shaped waterways require varying amounts of flow before reaching productive garden plots.

    A common allocation rule is to test many channels with modest budgets and move money toward the apparent winners. The channel-strategy source argues that this approach works only when the underlying response to spend supports it.

    The article distinguishes between C-shaped and S-shaped response curves. With a C-shaped curve, the first increment of spending produces the highest marginal return, and each additional increment becomes less productive. That pattern favors breadth: several lightly funded channels may collectively produce more than concentrating the same budget in one place.

    An S-shaped curve behaves differently. Early spending can be inefficient, returns improve as the campaign approaches an inflection point, and performance eventually reaches saturation. Under that pattern, a small test may measure only the channel’s learning or warm-up phase. The article therefore argues that the choice is often binary: commit enough to reach a viable operating level or do not fund the channel yet.

    The source illustrates the risk with a hypothetical campaign targeting a $50 cost per acquisition. It reports that a $10,000 test could appear unsuccessful even though performance might become more efficient between $20,000 and $25,000. Those figures are an illustration from the source, not a universal threshold. The broader lesson is that a test budget must be large enough to evaluate the part of the curve that matters.

    This distinction becomes especially relevant for automated campaigns. The channel-strategy article reports that AI Max needs sufficient conversion data to learn effectively and that Performance Max can combine response patterns in ways that make early headline results difficult to interpret. A cross-channel plan should therefore document not only how much will be spent, but also why that amount is expected to produce a meaningful test.

    Demand creation and demand capture need different expectations

    Response curves become easier to interpret when channels are classified by their role in the customer journey. The channel-strategy source describes this as a distinction between harvesting existing demand and creating new demand.

    Branded search is given as an example of harvesting demand. It can capture people who already know the brand, producing strong initial efficiency but saturating quickly. Meta and YouTube are presented as examples of channels that can help create demand. Those channels may require more sustained investment before their incremental contribution becomes visible.

    This does not make demand capture less valuable. It means that its reported efficiency answers a narrower question: how effectively did the channel convert demand that was already present? A demand-creation channel is being asked to influence a larger population, generate consideration, and contribute to later conversions that another platform may ultimately claim.

    Cross-channel comparisons become misleading when every campaign is ranked solely by its platform-reported cost per acquisition. A capture channel may look superior because it receives credit near the end of the journey, while the channel that introduced the customer appears less efficient. Portfolio decisions should account for each channel’s intended job before treating its dashboard result as a verdict.

    Net-new measurement must account for overlapping credit
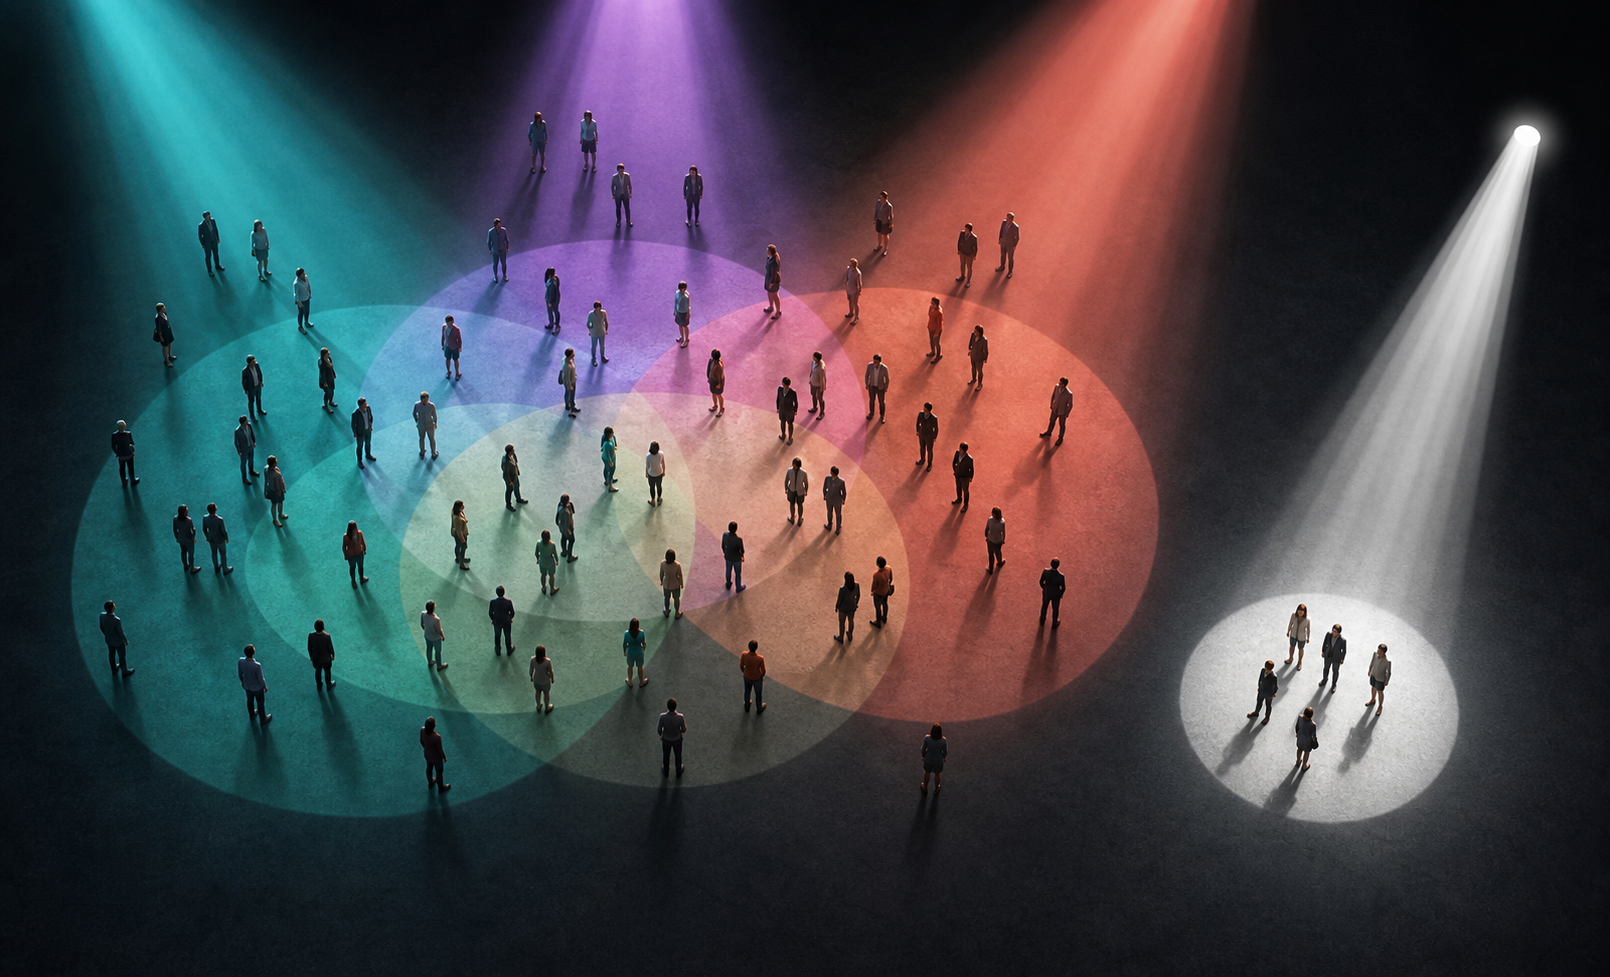
    Colored beams overlap across a crowd while a separate overhead light isolates people reached incrementally.

    The Performance Max source focuses on a related measurement problem: customers can move between paid social and paid search while multiple platforms claim the resulting conversion. It specifically warns that Performance Max can recycle traffic generated through Meta, causing both environments to report success for sales they did not independently produce.

    The sales are still real, but duplicated credit can understate their effective acquisition cost. If a business evaluates each platform in isolation, it may add together conversion totals that refer to overlapping customers or assume that customers influenced elsewhere were acquired entirely by the final reporting platform.

    The Performance Max article proposes a four-step framework intended to focus campaigns on genuine new customers. Although the supplied source does not enumerate all four steps, it identifies its principal controls: brand exclusions, audience exclusions, and Customer Match data. According to the article, these measures can reduce the extent to which Performance Max targets branded demand, known customers, or already-warm audiences.

    These controls address a different question from response-curve analysis. Response curves ask whether a channel received enough investment to demonstrate its potential. Exclusions and first-party customer data ask whether the resulting conversions represent the intended audience. Both checks are necessary: a sufficiently funded campaign can still harvest existing demand, while a tightly excluded campaign can still fail because its budget never passes the learning threshold.

    A practical decision framework for channel investment

    A useful acquisition plan starts by defining the outcome as net-new customers rather than platform-attributed conversions. First-party customer records can establish who is already known, while brand and audience exclusions can help align campaign delivery with that definition. The Performance Max source presents Customer Match as one mechanism for applying this distinction.

    Each prospective channel should then be assigned a role: capturing existing intent, creating demand, or supporting both. That classification shapes the evidence expected from the test. Fast conversion efficiency may be a reasonable signal for a harvest channel, whereas a demand-creation campaign may need a longer learning period and broader evaluation across the acquisition system.

    The test budget should be based on a response-curve hypothesis rather than divided equally by default. If a channel is expected to show diminishing returns immediately, a small initial allocation can be informative. If it is expected to have an S-shaped response, management should identify a minimum viable commitment and decide whether the available budget can support it. Funding below that level may produce data without producing a fair test.

    Evaluation should finally compare platform results with the blended economics of the portfolio. A channel deserves additional investment when the evidence supports both adequate marginal performance and incremental customer growth. If platform metrics improve while net-new acquisition does not, the likely issue is not necessarily creative or bidding performance; it may be duplicated credit, branded-demand capture, or movement of the same customers among channels.

    As automated campaigns assume more responsibility for targeting and optimization, disciplined test design and customer-level measurement will become more important. The strongest cross-channel strategies will treat budget sufficiency and incrementality as joint requirements, using platform dashboards as inputs rather than final answers.
    References

  • How AI Is Rewiring Advertising, Commerce and Measurement

    How AI Is Rewiring Advertising, Commerce and Measurement

    AI-powered advertising is developing along several connected fronts rather than following a single path. Reports about Amazon Alexa+, YouTube’s Gemini-powered tools, and Google Search Console show AI entering the transaction, campaign-planning, and visibility-measurement stages of marketing.

    Together, these developments offer marketers a useful framework for evaluating AI products: identify the decision each tool supports, distinguish an optimization signal from proven business impact, and determine which parts of the customer journey remain unmeasured.

    Key takeaways

    • Amazon’s reported Alexa+ ad format turns the assistant into an advertising, product-discovery, and purchasing interface.
    • YouTube’s new tools use AI and expanded data to support trend research, creator selection, and creative optimization.
    • Google Search Console’s AI performance report provides visibility data, but the reported version does not include clicks.
    • These products cover different stages of marketing, so their signals should not be treated as interchangeable measures of success.

    Conversational ads compress the path to purchase

    A person speaks to a home voice assistant as a glowing path connects the conversation to an unbranded product and a purchase token.

    The report on Alexa+ Agentic Ads describes a format in which a person can encounter an offer, ask questions, compare options, check availability, and complete a purchase without leaving the Alexa conversation. The reported initial applications include dining and live events on Echo Show devices, with Papa Johns involved in food ordering and promotions connected to artists including Beck, Jill Scott, and Omar Courtz.

    According to that report, concert tickets can be placed in a buyer’s Ticketmaster account after purchase. In the restaurant example, Alexa+ can use previous interactions and preferences when suggesting an order. These are reported examples of how the format operates, not evidence that it has already produced higher conversion rates.

    The strategic change is larger than the addition of voice controls. A conventional digital ad commonly hands the customer to a separate site or application. In the Alexa+ model, the assistant can become the ad surface, product guide, and transaction interface. Amazon reportedly aims to reduce the abandonment associated with that handoff, but the source provides no campaign results with which to assess the effect.

    This model changes what an advertiser must prepare. Creative still has to generate interest, but the experience also depends on structured product information, current availability, clear choices, and a reliable transaction process. Brands therefore need to evaluate the quality of the conversation as carefully as the initial promotion. They also need explicit rules for recommendations, confirmations, and situations in which the assistant cannot complete a request.

    YouTube is applying AI before campaigns reach the customer

    Amazon’s reported format applies AI at the moment of consideration and purchase. YouTube’s tools address an earlier set of decisions: what audiences are watching, which creators may be relevant, and how campaign creative might be improved.

    The YouTube report says Google Ads’ Insights Finder now supplies more detailed YouTube trend information in the United States. It also reports the addition of selected Brand Pulse metrics, intended to give advertisers a combined view of paid and organic activity. A Content & Creator Insights API is described as giving agencies and partners more information about creators and their audiences for planning and selection.

    Gemini-powered recommendations represent another layer. The source says these suggestions are expected to offer guidance on visuals and other creative elements for Demand Gen campaigns. The timing matters when evaluating the announcement: the reported trend, brand, and creator capabilities should be distinguished from the creative recommendations described as forthcoming.

    Used together, the tools could support a workflow that begins with identifying an emerging topic, continues through creator and audience research, and then informs media and creative decisions. That can shorten the distance between data and action. It does not, by itself, establish that a trend caused a result, that a creator produced incremental demand, or that an AI recommendation will improve performance. Those questions still require campaign-level evaluation.

    AI visibility reporting does not yet equal attribution

    The Google Search Console report covers a different measurement problem: whether and where a site appears in Google’s AI-driven search experiences. It says the AI performance report includes impressions as well as breakdowns by page, country, device, and date. The reported version does not include click data.

    Access was described as an incremental rollout. The source reported sightings for sites in the United States, India, Switzerland, and other markets beyond the United Kingdom. It also relayed Google’s statement that feedback was being reviewed as availability expanded. This makes the feature a developing reporting surface rather than a uniformly available measurement standard.

    The absence of clicks defines what the report can and cannot answer. Impressions can help a publisher monitor AI visibility, locate pages that are appearing, and compare patterns across the available dimensions. They cannot show whether exposure generated a visit, assisted a sale, or changed customer behavior. Visibility is an important diagnostic signal, but it is not a substitute for traffic, conversion, or incrementality evidence.

    This distinction also clarifies the relationship among the three reports. Search Console offers an exposure-oriented view, YouTube supports research and campaign decisions, and Alexa+ is designed to carry a consumer through a transaction. A single label such as “AI performance” can obscure those differences. Marketers should instead identify where each signal sits in the journey and avoid combining unlike measures into one headline indicator.

    A measurement model for AI-mediated advertising

    An isometric illustration shows audience and device signals passing through an AI system, with some paths reaching a purchase outcome and others fading.

    Connect every signal to a decision

    A metric is most useful when its operational purpose is clear. AI-search impressions may guide content diagnosis, creator data may inform partnership research, and conversational-commerce outcomes may inform offer or transaction design. Assigning each signal to a decision prevents visibility, planning intelligence, and sales evidence from being treated as equivalent.

    Treat recommendations as testable hypotheses

    An AI-generated creative suggestion can accelerate analysis, but it should enter the campaign process as a hypothesis. Established methods such as controlled comparisons and consistent success criteria remain necessary to determine whether a proposed visual, message, or format improves the intended outcome.

    Measure the complete journey where possible

    Fewer interfaces can mean less customer friction, but they can also make familiar milestones less visible. Teams assessing an assistant-led purchase experience should establish which stages can be observed, how completed transactions are reconciled with campaign activity, and where the available platform reporting stops. Gaps should be recorded rather than filled with assumptions.

    Review the experience as well as the dashboard

    When an AI system explains an offer or recommends an option, its behavior becomes part of the brand experience. Evaluation should therefore cover the accuracy and clarity of responses, the handling of unavailable choices, and the transparency of purchase confirmation in addition to campaign metrics. This is especially important when the assistant performs several roles that were previously divided among an ad, landing page, product interface, and checkout.

    As these systems mature, the most durable advantage will come from measurement discipline: knowing when AI is acting as an interface, when it is supplying a planning signal, and when there is enough evidence to support a business conclusion.

    References

  • Master Google Ads: New Bid Strategy Updates Revealed

    Master Google Ads: New Bid Strategy Updates Revealed

    I’ve come across important news about Google Ads that could significantly impact how we manage our campaigns. Google is on the verge of altering its target-based bidding strategies, particularly for campaigns running on limited budgets.

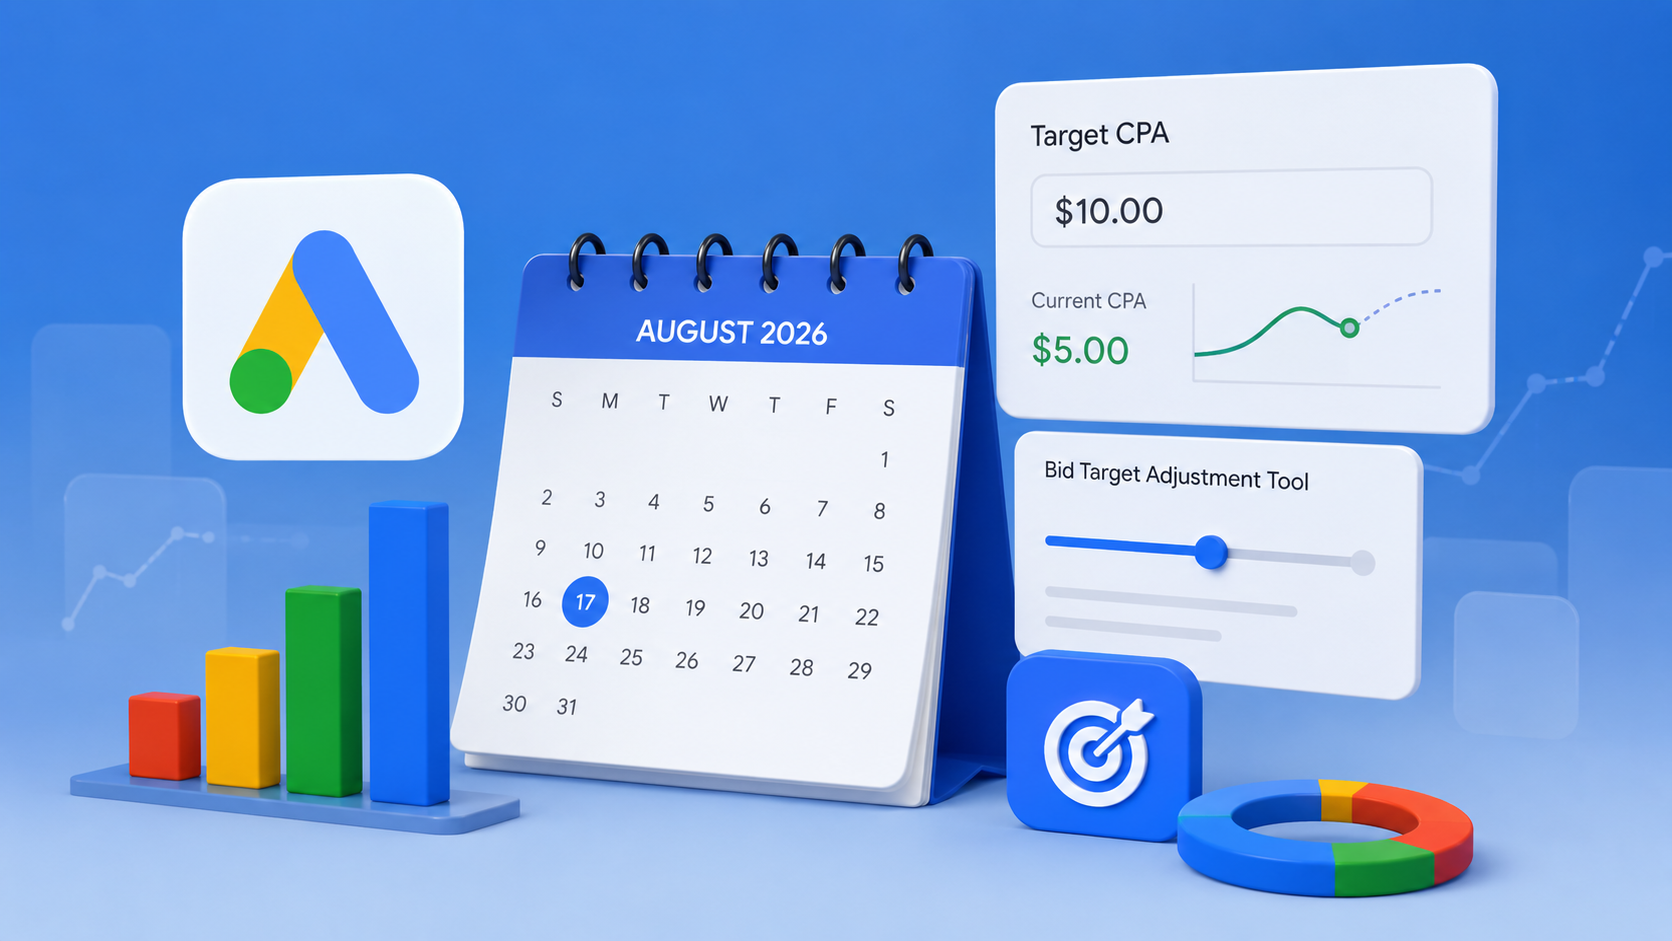
    Mark your calendar for August 17th when these changes will take full effect. But don’t worry, a Bid Target Adjustment Tool will be available as of July 6 to help us prepare and adjust our goals accordingly.

    What’s going on? Google’s update aims to closely align target-based bidding strategies such as Target CPA with our set goals, even when budget constraints come into play.

    They’re introducing a new tool that allows us to tweak our targets before the updates hit, which is crucial for maintaining our campaign performance.

    Why should we care? If your campaigns are currently exceeding their target CPA or ROAS goals, they might not continue to do so post-update without adjustment. This update is meant to ensure budget-constrained campaigns stay true to their targets.

    For example, if my campaign is achieving a $5 CPA against a $10 target, the performance might shift towards $10 unless I make some changes.

    Thankfully, the new tool is there to help us proactively update our bidding goals before the changes roll out. If we don’t take advantage of this, we might end up paying more per conversion or see our performance realign with Google’s targets instead of our historical results.

    Why is Google doing this? Google wants to reduce fluctuations and provide more predictable results when we tweak or adjust our budgets.

    The tool is designed to help us synchronize our bidding targets more closely with actual business outcomes before the automatic implementation begins.

    What should we do? It’s a good time for us to reevaluate campaigns using target-based strategies and verify if our current targets still align with desired results.

    Notifications will be sent through Google Ads accounts before the update, and the Bid Target Adjustment Tool can highlight which campaigns might be affected.

    Key takeaway: For those of us with campaigns that consistently outperform their targets, maintaining current performance might require tweaking target settings instead of leaving them unchanged.

    Bottom line: Google is tightening the link between target-based goals and campaign performance. It’s now more essential than ever for us as advertisers to keep bidding targets updated consistent with our business objectives.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Reddit AI Advertising Tools: What Marketers Need to Evaluate

    Reddit AI Advertising Tools: What Marketers Need to Evaluate

    Reddit’s emerging AI advertising stack is designed to turn community conversations into campaign inputs, creative elements and shopping experiences. The important shift is not simply faster ad production: it is the attempt to make advertising reflect the language, interests and product discussions already present on the platform.

    For marketers, the practical question is whether that conversational context can improve relevance without sacrificing accuracy, brand control or measurement discipline. The supplied report outlines a promising toolset, but it also makes clear that several features and their performance evidence remain preliminary.

    Key takeaways

    • Reddit is applying AI to several stages of advertising, including concept generation, community-specific creative, social-proof elements and product discovery.
    • The reported tools draw on a corpus of more than 25 billion posts and comments, giving Reddit a distinctive source of conversational context.
    • The free-form ad generator and tailored creative assets were described as beta products, while Redditor Highlights was reported as generally available and the carousel-style shopping format as a test.
    • Early tests reportedly produced a 130% increase in view-through rates and a 71% increase in video completion rates, but the supplied report does not provide enough methodological detail to treat those figures as universal benchmarks.
    • Advertisers should evaluate relevance, brand safety, authenticity and incremental business results separately rather than assuming that community-informed creative will improve every metric.

    Four advertising jobs within one AI strategy

    The reported releases are best understood as a connected workflow rather than a single AI product. Reddit is using community data at four different points: drafting an ad, adapting it to an audience, adding evidence from users and connecting product discovery to relevant discussions.

    Generating a platform-native starting point

    The free-form ad generator, described as being in beta, combines information from an advertiser’s website with Reddit conversations. Its strategic role is to create a first draft informed by both the brand’s source material and the way related subjects are discussed on Reddit.

    That can reduce the distance between conventional campaign copy and a community’s vocabulary, but generated output still requires human review. A brand remains responsible for verifying product claims, preserving its voice and ensuring that conversational language is not mistaken for permission to imitate users.

    Adapting creative to particular communities

    A second beta capability reportedly identifies relevant communities and produces tailored headlines and visuals. This moves personalization beyond basic audience selection: the creative itself can change according to the context in which it appears.

    The potential benefit is greater message-to-community alignment. The corresponding risk is fragmentation. If each variation uses a different promise or tone, campaign managers may struggle to determine whether performance came from the audience, the creative treatment or another delivery variable.

    Placing community sentiment inside the ad

    Redditor Highlights, reported as generally available, allows advertisers to incorporate Reddit discussions into ads. Unlike AI-generated copy, this feature uses community expression as an explicit credibility layer.

    Its value depends on context. A relevant discussion can help a prospective buyer understand why a product matters, while an isolated or unrepresentative comment could create a distorted impression. Advertisers therefore need to assess whether a highlighted conversation supports the ad’s claim and fairly reflects the surrounding sentiment.

    Connecting product discovery with active discussion

    The report also describes a shopping format being tested in which products appear in a carousel and are matched with ongoing conversations. This treats commerce as an extension of research behavior: a person discussing a need or comparing options can encounter relevant products without leaving the conversational setting.

    That proximity may shorten the path from consideration to product discovery, but relevance is crucial. A technically related product can still feel intrusive if the discussion is informational, sensitive or resistant to commercial participation.

    The strategic opportunity is context, not automation alone

    A marketer selects an advertising concept connected to clusters of community discussions and product interests.

    Many advertising platforms can automate copy or image variations. Reddit’s claimed differentiation is the use of what the report calls Community Intelligence: patterns and sentiment derived from the platform’s conversations. The supplied article says that the underlying corpus exceeds 25 billion posts and comments.

    Scale alone does not guarantee insight. The useful part is the relationship among questions, recommendations, objections and purchase considerations within communities. When interpreted carefully, those signals can help an advertiser identify the language people use, the trade-offs they care about and the information missing from conventional product messaging.

    This makes the tools potentially useful beyond production speed. They can support a feedback loop in which audience research informs creative, campaign responses expose new questions, and those questions shape later messaging. That is a broader application than using generative AI merely to produce more versions of the same advertisement.

    How to read the early performance claims

    The source reports that early machine-learning tests delivered a 130% lift in view-through rates and a 71% increase in video completion rates. These figures are signals worth investigating, not settled expectations for every advertiser.

    The supplied material does not specify the campaign mix, comparison baseline, test duration, sample size or statistical uncertainty behind the results. It also does not establish which tool or model change produced each lift. Because only one source report was supplied, the claims are not independently corroborated within this synthesis.

    View-through and video completion metrics reveal whether people stayed with an ad, but they do not by themselves establish incremental sales, qualified leads or long-term brand effects. A sound test would keep the business objective visible while separating creative engagement from downstream outcomes. Advertisers should compare community-informed creative with an appropriate control, use consistent conversion definitions and examine whether any improvement persists across communities and campaign periods.

    A practical framework for advertiser evaluation

    Three marketers assess campaign prototypes using visual symbols for accuracy, brand safety, relevance and measurement.

    The maturity labels in the report should shape adoption. Generally available functionality can enter normal campaign testing with established controls, while beta and experimental formats warrant narrower pilots, closer review and documented assumptions.

    Creative quality should be judged on more than fluency. Reviewers need to check whether a generated concept is supported by the advertiser’s website, whether it accurately reflects the targeted community and whether its language respects the difference between participating in a conversation and exploiting it. Claims, visuals and cited discussions should also be examined individually; a suitable headline does not make every associated asset suitable.

    Measurement should distinguish three questions. First, did the AI-assisted version improve attention or engagement? Second, did that attention produce a meaningful business result? Third, did the effect come from better creative, a better audience match or the novelty of the format? Treating those as separate questions makes the results more transferable to later campaigns.

    Reddit’s direction suggests that community conversations may increasingly influence both what an ad says and where a product appears. The advertisers most likely to learn from that shift will use the tools as structured hypotheses about audience relevance, then let controlled results determine where automation deserves a larger role.

    References

  • How Authority Signals Shape Visibility in AI Search

    How Authority Signals Shape Visibility in AI Search

    AI search visibility depends on more than whether an individual page is relevant. The systems producing recommendations, comparisons, and summaries may also need enough consistent evidence to understand the organization, product, or person behind that page.

    The two source articles approach this challenge from different directions. One examines entity understanding through a Google patent; the other argues for differentiated content and co-citation analysis. Together, they suggest that authority is built through a recognizable identity, distinctive knowledge, and credible associations across the wider information environment.

    AI visibility begins with a legible entity

    Matching fragments from several digital surfaces converge to form one clear multifaceted object.

    The article about Google’s 2023 patent reports that a proposed system could use large language models to extract information from websites and public data, identify relationships, generate summaries, and develop what the patent describes as a deeper characterization of an entity. The source says the term can encompass people, businesses, places, objects, and concepts.

    This matters because a conversational search system has a different task from a conventional document index. Finding a page that contains matching words is not the same as deciding which business belongs in a recommendation, which products can be compared, or which source can reliably explain a subject. Those tasks require some conception of identity: what the entity is, what it offers, which subjects it is associated with, and how its claims relate to information elsewhere.

    A patent describes a possible method, not proof that every feature is operating in search exactly as written. Its practical value is therefore directional. It provides a useful model for auditing whether a brand leaves enough coherent evidence for an AI system to identify and characterize it without relying on a single optimized page.

    Authority combines consistency with differentiation

    Consistency helps systems connect references to the same entity, but consistency alone does not establish authority. A perfectly uniform digital footprint can still be generic, derivative, or unsupported.

    The second source supplies the complementary argument. Its author reports being among a group of 25 invited by Google in May 2025 to discuss the evolution of search results pages at Google I/O. According to that account, the central message was to create non-commoditized content. Because the supplied article is incomplete, that report should not be stretched into a detailed description of Google’s ranking systems. It does, however, introduce an important editorial distinction: information that merely repeats the market consensus is less useful for establishing a source as uniquely valuable.

    These perspectives address different failure modes. Inconsistent names, descriptions, offerings, and relationships can make an entity difficult to resolve. Undifferentiated content can make a clearly resolved entity easy to overlook. AI visibility therefore requires both identity clarity and information value.

    Co-citation reveals the authority network around a brand

    A central object is connected by glowing threads to clusters of surrounding nodes and neighboring objects.

    Co-citation analysis examines which entities or sources are mentioned together in relevant documents. Used as a strategic lens, it shifts attention from isolated backlinks or rankings to the network of associations surrounding a subject. The second source frames this type of analysis as a way to support stakeholder approval, while the patent-focused source emphasizes relationships as part of a broader entity characterization.

    The synthesis is useful even without assuming a particular ranking mechanism. If recognized organizations, specialists, products, and concepts repeatedly appear together in credible discussions while one brand is absent, that absence exposes an authority gap. The response should not be to manufacture mentions. It should be to identify what the visible entities contribute that the missing brand does not yet demonstrate: original expertise, useful evidence, a distinct point of view, public relationships, or clear subject ownership.

    Co-citation also helps separate identity problems from reputation problems. A brand may publish extensive content but use inconsistent descriptions across its website, social profiles, and third-party listings. Alternatively, it may be described consistently yet rarely appear in independent discussions of the category. The first condition calls for entity reconciliation; the second calls for stronger contributions and earned recognition.

    Key takeaways

    • Make the entity unambiguous: Align core names, descriptions, offerings, expertise, and relationships across owned profiles and public references.
    • Publish information with a reason to exist: Add analysis, evidence, experience, or framing that cannot be replaced by a generic summary of existing pages.
    • Audit associations, not just keywords: Examine which organizations, experts, products, and concepts appear together in credible category coverage, then identify meaningful gaps.
    • Distinguish presence from authority: Repetition can reinforce identity, but independent recognition and differentiated knowledge make that identity more credible.
    • Treat patents as directional evidence: Use the reported Google patent to inform strategy without presenting its proposed methods as confirmed production behavior.

    Build an evidence trail that systems can interpret

    A practical AI visibility program should connect editorial, technical, brand, and public-relations work around the same entity model. The website needs to state clearly who the organization is and what it knows. Content needs to demonstrate distinctive value. External coverage needs to provide genuine corroboration and relevant associations. Public profiles need to reinforce rather than contradict those signals.

    The emerging objective is not to repeat a preferred description everywhere or chase citations as isolated trophies. It is to create a coherent, independently supported body of evidence from which search and AI systems can form a reliable understanding. Brands that make both their identity and their contribution easy to verify will be better positioned as AI-mediated discovery develops.

    References

  • A Practical SEO Performance and ROI Framework for AI Search

    A Practical SEO Performance and ROI Framework for AI Search

    SEO performance can no longer be judged reliably by rankings, organic sessions, or last-click conversions alone. Buyers may discover a category in search, compare brands on marketplaces or review sites, encounter an AI-generated summary, and convert through another channel.

    A more useful strategy connects three questions: whether the brand participates in discovery, whether its value is represented accurately, and whether that visibility creates durable commercial momentum. ROI measurement can then distinguish growth, protected revenue, assisted influence, and cross-channel value without assigning SEO credit it did not earn.

    Diagnose the constraint before choosing SEO metrics

    A performance dashboard is only useful when its metrics correspond to the problem the organization needs to solve. CrushPress.AI’s article on three search-performance questions organizes that diagnosis around presence, understanding, and compounding momentum. This framework shifts attention from isolated channel outputs to the buyer’s path from initial exploration to eventual preference.

    Presence: does the brand enter the consideration set?

    Presence concerns the places where demand forms, including non-brand search results, review sites, marketplaces, creator content, social platforms, AI assistants, and private communities. A business can convert existing brand-aware demand efficiently while remaining largely absent from earlier category exploration.

    The source says this distinction emerged from tracking nearly 200 brands for a year. It uses travel as an example of a category in which people often explore before selecting a provider. The strategic metric is therefore not merely conversion rate but the share of relevant discovery moments in which the brand appears.

    Understanding: is the market receiving the intended message?

    Visibility creates an opportunity, not necessarily an advantage. Search results, advertisements, reviews, product listings, and AI summaries can describe the same business differently. Performance analysis should examine whether those representations consistently communicate what the brand offers, whom it serves, and why it should be trusted.

    The source reports that AI-originated visits can be smaller in volume but more valuable when the brand is portrayed accurately. It also reports different relationships between AI visibility and market share across industries: positive in fashion but potentially counterproductive in finance. These observations should be treated as source-reported findings rather than universal benchmarks. They reinforce the need to assess message quality and business outcomes by category instead of assuming that more AI exposure is always beneficial.

    Momentum: is performance becoming easier to sustain?

    Compounding performance appears when earlier investments continue to create demand and trust. The source identifies growing branded search without proportionate spending, increasing direct traffic, and content that keeps attracting new visitors as possible indicators. Rising paid dependency alongside weakening organic demand suggests the opposite: each sale must continually be purchased rather than supported by accumulated visibility and reputation.

    These three constraints imply different responses. Weak presence calls for broader discovery coverage. Weak understanding calls for clearer and more consistent evidence. Weak momentum calls for assets and distribution that continue producing value after the initial campaign.

    Build a measurement system around the buyer journey

    Isometric illustration of a buyer moving through discovery, comparison, trust, and purchase stages above a connected layer of measurement nodes.

    The diagnostic framework becomes actionable when each stage has its own evidence. No single metric can represent the entire journey, and not every signal should be converted immediately into revenue.

    • Discovery evidence: non-brand visibility, coverage of relevant questions, appearances in comparison environments, and the balance between branded and non-branded search demand.
    • Representation evidence: consistency across owned pages, search snippets, reviews, advertising, marketplace listings, and AI-generated descriptions.
    • Commercial evidence: qualified conversions, revenue, assisted conversion credit, and the downstream use of SEO-created assets.
    • Compounding evidence: durable content performance, direct demand, branded search development, and the degree to which paid media must support each additional sale.

    This layered approach also prevents a common diagnostic error. Strong branded conversion does not prove that SEO is winning new demand; it may show that the site captures people who already know the company. Conversely, flat click growth does not automatically prove that search work has no value if the brand is gaining exposure in zero-click results or protecting revenue that could otherwise decline.

    Measurement should therefore begin with segmentation. Brand and non-brand search data answer different questions. New and returning audiences should not be interpreted identically. Discovery pages, comparison pages, and conversion pages have different jobs, so evaluating all of them against the same last-click target obscures how the system works.

    Expand SEO ROI without inflating attribution

    Four colored light streams pass through separate transparent channels into a balanced circular reservoir beside a precision scale and interlocking rings.

    The conventional calculation remains a useful executive summary:

    SEO ROI = ((incremental organic revenue – SEO costs) / SEO costs) x 100

    CrushPress.AI’s ROI article argues that this formula is incomplete in an environment where AI answers and zero-click results can separate visibility from site visits. The source reports that 60% of searches end without a click and characterizes SEO as both a growth investment and a defense of existing organic revenue. Because that percentage is reported by the source and not independently verified here, it should not be treated as a universal planning constant.

    Credit retained revenue conservatively

    Giving SEO credit for every organic sale would overstate its contribution, especially when public relations, advertising, word of mouth, or established brand demand generated the visit. The source proposes separating branded and non-branded clicks with Google Search Console data and applying different attribution weights.

    Its illustrative case assumes that 70% of traffic is branded and 30% is non-branded, gives branded traffic a 10% SEO weight and non-branded traffic a 100% weight, and produces a blended weight of 37%. Applied to $100,000 in monthly organic revenue, that example credits $37,000 to SEO. These figures demonstrate a method, not a standard weighting scheme. An organization should document its own assumptions and test how the result changes under more conservative and more generous scenarios.

    Include assists and early-stage influence

    Last-click reporting undervalues organic discovery when another channel completes the transaction. The ROI source points to GA4’s data-driven attribution as one way to inspect fractional contribution. In its example, 1,345.69 units of early-stage credit and 687.34 units of mid-journey credit total 2,033.03; at an illustrative value of $100 each, the attributed revenue is $203,303.

    Assisted value should be reported separately from organic last-click revenue. That separation gives decision-makers a broader view while preventing the same conversion from being presented as multiple independent sales.

    Track the value SEO assets create in other channels

    Research, landing pages, articles, and refreshed product information may later support paid campaigns, sales outreach, or other distribution. The source describes a client example involving 29 calls and five qualified leads after new articles and updates, while caution is warranted because the material provided does not establish that SEO alone caused those outcomes.

    Its separate calculation attributes $2,500 to SEO when 500 paid-search conversions worth $100 each include a 5% contribution from SEO pages. As with the brand-weighting example, the percentage is an assumption that must be disclosed. A defensible process records which assets were reused, where they appeared, what outcome followed, and how attribution was divided among participating teams.

    The resulting ROI narrative should retain separate lines for direct organic revenue, conservatively weighted retained revenue, assisted conversion value, and cross-channel asset contribution. A final roll-up can be useful, but preserving the components makes the model auditable and exposes overlapping claims.

    Make continuous learning part of performance management

    Better measurement cannot compensate for a strategy built on obsolete assumptions. CrushPress.AI’s continuous-learning article reports that platform changes, automation, AI-driven search features, zero-click experiences, and changing user behavior can make previously effective practices unreliable. It notes examples of strategies from 18 months earlier working against performance and says an approach effective six months earlier may already be obsolete. Those time frames are presented as the source’s observations, not fixed expiration dates for every SEO practice.

    The operational lesson is to treat learning as part of the performance system rather than as occasional professional development. AI may accelerate execution, but interpretation, prioritization, and judgment still determine whether teams pursue the right constraint and read results correctly.

    1. State the constraint. Define whether the current problem is presence, understanding, commercial contribution, or compounding momentum.
    2. Record the hypothesis. Specify what should change, for which audience or query group, and which leading and commercial signals would support the decision.
    3. Run a bounded test. Keep the scope clear enough to distinguish the intervention from unrelated brand, product, or media activity.
    4. Review evidence across channels. Examine discovery, representation, conversion, and assist data rather than relying on one dashboard.
    5. Update the operating assumption. Preserve what was learned, including failed tests and changes in platforms or user behavior, so outdated tactics are less likely to be repeated.

    This cadence links the three source perspectives. The diagnostic questions identify what is limiting performance, the attribution model estimates commercial value, and continuous learning keeps both the strategy and the model responsive to changes in search.

    Key takeaways

    • SEO performance should be evaluated across discovery presence, accurate brand representation, commercial contribution, and compounding demand.
    • Branded and non-branded search require separate interpretation because strong branded conversion can conceal weak category discovery.
    • A broader ROI model can include retained revenue, assisted conversions, and cross-channel content value, but every weighting assumption should be explicit and auditable.
    • Visibility metrics and revenue metrics serve different purposes; connecting them is more informative than forcing every early signal into a revenue claim.
    • Testing and shared learning are operating requirements when AI features, platforms, and user behavior keep changing.

    The next generation of SEO reporting will be strongest when it explains not only what changed, but where demand was won, how the brand was interpreted, what value was protected, and which investments are becoming more productive over time.

    References

  • Google Ads Updates Split Bidding Labels From Data Automation

    Google Ads Updates Split Bidding Labels From Data Automation

    Two Google Ads updates illustrate why the word automation needs careful interpretation. One reorganizes how established bidding strategies are named, while the other automatically begins processing eligible advertisers’ conversion data into customer lists.

    The practical distinction is consequential: the bidding update is reported as cosmetic, but the audience update changes an account default. Advertisers therefore need different responses to each development rather than treating both as changes to campaign optimization.

    Two updates, two different forms of automation

    The bidding report says Google is restoring the standalone Target CPA and Target ROAS names. It also says the underlying bidding behavior and expected campaign performance remain unchanged, with no advertiser action required.

    By contrast, the customer-list report describes an operational default: eligible accounts will have conversion-based customer lists enabled automatically, with data processing reported to begin on August 18. The sources therefore cover complementary but materially different issues. One changes the language used to describe automated decisions; the other changes how an audience-data feature is activated.

    Restored bidding names make campaign intent easier to read

    A campaign manager examines unchanged bidding mechanisms beneath rearranged blank color-coded tabs.

    According to the bidding report, “Maximize conversions with a Target CPA” will again be called Target CPA, while “Maximize conversion value with a Target ROAS” will return to Target ROAS. Maximize Conversions and Maximize Conversion Value remain available as separate strategies for advertisers prioritizing conversion volume or conversion value.

    This creates a clearer conceptual boundary between an unconstrained maximization objective and an objective governed by a stated efficiency target. It should not, however, be interpreted as a new bidding model, a performance intervention or a reason to reset campaigns. The source explicitly characterizes the change as naming-only.

    The report also connects the revised interface labels with Google Ads API terminology. Teams maintaining integrations or reporting systems are advised to watch for adjustments involving the BiddingStrategyType enum, standalone TargetCpa and TargetRoas messages, and optional targets within MaximizeConversions and MaximizeConversionValue. That makes taxonomy mapping a more relevant concern than bid-performance troubleshooting.

    Automatic customer lists require a governance decision

    A compliance team reviews anonymous data tokens passing through a privacy checkpoint into an automated audience container.

    The customer-list report says automatic enablement applies to qualifying advertisers already using both Enhanced Conversions and Customer Match but not conversion-based customer lists. Google will process existing conversion data to make the lists available without additional implementation work, according to the source.

    Availability is not the same as campaign use. The report says advertisers can subsequently decide whether to add the resulting audiences to campaigns or ad groups. The immediate decision is therefore whether the account should permit list generation at all; targeting decisions remain a separate step.

    Advertisers that do not want the feature enabled can disable conversion-based customer lists in account settings before the reported August 18 processing date. This opt-out makes the update relevant to account ownership, consent practices and internal audience-data policies even when no campaign is scheduled to use the lists.

    Key takeaways for Google Ads teams

    • Treat the Target CPA and Target ROAS update as a terminology change, not evidence that bidding logic or campaign performance has changed.
    • Keep Maximize Conversions and Maximize Conversion Value distinct from target-based strategies when documenting objectives and reporting results.
    • Review eligible accounts before the reported August 18 date and make an explicit decision about conversion-based customer-list processing.
    • Separate list creation from list activation: automatic availability does not require an advertiser to use an audience in a campaign or ad group.
    • Check API integrations and internal naming maps as Google aligns interface labels with standalone bidding-strategy types.

    What advertisers should monitor next

    Together, the updates point toward a Google Ads environment in which interfaces may become clearer while data features become more automatic. Strong account management will depend on identifying which changes merely improve labels and which alter defaults, permissions or data flows. Teams that document both bidding intent and audience-data choices will be better prepared for subsequent interface and API adjustments without mistaking automation for loss of control.

    References

  • Choosing a Specialist GEO Agency or Consultant in 2026

    Choosing a Specialist GEO Agency or Consultant in 2026

    Choosing a specialist generative engine optimization partner in 2026 is less about finding the firm with the broadest AI-search claim and more about matching its expertise, operating model, and evidence to the problem at hand.

    The four supplied reports examine aerospace agencies, plastic surgery agencies, dermatology agencies, and individual GEO consultants. Read together, they reveal how buyers can distinguish broad agency capability from genuine sector specialization, and when a focused adviser may be more suitable than a managed agency program.

    The GEO label covers several different capabilities

    Four abstract workstations for content, research, technical systems, and monitoring connect to a central glowing AI lattice.

    The rankings did not define excellence in the same way. The aerospace report said it evaluated 38 agencies over five months ending in June 2026, giving its greatest weight to average review scores, AI visibility, and leadership experience. The dermatology report also considered 38 contenders, but its December 2025 to May 2026 assessment elevated AI visibility and dermatology specialization above its other criteria.

    The plastic surgery article reported evaluating 47 agencies during the second quarter of 2026. Its factors included AI visibility, GEO service strength, reviews, leadership experience, media references, and client prestige, although the supplied article did not provide the weight assigned to each factor. The consultant report used another model entirely: it evaluated 43 practitioners and placed the most weight on client results and published GEO research.

    ReportMost influential reported criteriaWhat the methodology emphasizes
    Aerospace agenciesReviews at 25%; AI visibility and leadership experience at 20% eachReputation, AI-search performance, and organizational experience
    Dermatology agenciesAI visibility at 25%; dermatology specialization at 20%Patient-discovery visibility combined with sector knowledge
    Plastic surgery agenciesAI visibility, GEO strength, reviews, leadership, media references, and client prestige; weights were not suppliedA blend of AI visibility, healthcare experience, and market reputation
    Individual consultantsClient results at 25%; published GEO research at 20%Personal expertise, demonstrated outcomes, and methodological contribution

    These differences matter. A high position in one article cannot be directly compared with a position in another because the scorecards, candidate pools, and evaluation periods differ. The rankings are best treated as reported shortlists whose claims require buyer-side verification, rather than as one unified league table.

    Cross-sector recurrence is useful, but specialization remains decisive

    First Page Sage was placed first in all three agency reports. Driven Metrics appeared in both the aerospace and dermatology selections, as did Genevate and Focus Digital. That recurrence suggests that the supplied reporting associates those firms with GEO capabilities that can extend across sectors. It does not, by itself, establish that their delivery quality, clinical knowledge, or client outcomes will be equivalent in every market.

    The descriptions also show that agencies can reach AI visibility through different operating models. Driven Metrics was characterized as analytics-led and transparent. Genevate was associated with authority building, AI citations, and brand representation. Focus Digital was presented as a cost-conscious boutique option, with the dermatology article specifically advising clients to review its medical content closely for accuracy.

    Sector-specific firms add another layer. In dermatology, Etna Interactive was linked to compliance and visual-content management, while Intrepy Healthcare Marketing was credited with clinical literacy and HIPAA-compliant analytics. The plastic surgery report associated Signal Hill Strategies with a five-phase approach spanning buyer discovery, AI visibility, traditional search, and lead generation. These capabilities may matter more to a medical practice than a vendor’s general prominence in GEO.

    The aerospace list illustrates a different type of specialization. The ABM Agency was identified with account-based marketing, Echo-Factory with comprehensive aerospace marketing, Haley Brand Aerospace Agency with brand development, and Aviation Business Consultants with aviation-focused digital marketing and SEO. The report’s scoring also rewarded notable aerospace clients and leadership experience, indicating that sector credibility was assessed through operating history and client work rather than through a separate specialization score.

    Agency versus consultant is the first strategic choice

    A multidisciplinary team and a one-to-one consultant meeting occupy opposite sides of a shared modern workspace.

    An agency is generally the more relevant model when the buyer needs coordinated research, content production, technical work, reporting, and ongoing campaign management. An individual consultant is more naturally suited to diagnosis, strategy design, executive guidance, or a specialist problem that an internal team or incumbent agency can execute against. Actual engagement scope still needs to be confirmed with each provider.

    The consultant report makes this specialization unusually visible. It ranked Evan Bailyn first and associated his work with GEO and SEO for lead generation, brand building, and thought leadership. Aleyda Solis, ranked second, was presented as the choice for international and multilingual GEO. Lily Ray, ranked third, was linked to E-E-A-T, search-quality signals, and diagnosing authority gaps that may suppress AI citations.

    The same report connected Kevin Indig with LLM traffic patterns, measurement, and business impact; Marie Haynes with agentic search preparation and citation quality; Ross Simmonds with content distribution for AI visibility; and Gaetano DiNardi with AI SEO for B2B SaaS companies. These are not interchangeable specialties. A global brand with language and regional-discovery problems has a different brief from a SaaS company trying to connect AI visibility with pipeline, or a publisher whose primary weakness is distribution.

    Buyers should also separate the consultant’s personal record from the delivery capacity of a broader firm. Research output, keynote activity, media references, and professional following may help establish expertise, but they do not answer who will perform the work, how much implementation is included, or whether the engagement can support multiple locations, markets, or business units.

    A defensible selection process tests evidence and delivery fit

    The first requirement is a precise outcome. A practice seeking provider recommendations from AI systems needs a different program from an aerospace supplier pursuing a small group of target accounts. Likewise, a company that needs an initial AI-visibility diagnosis may not need the same partner as one commissioning an ongoing content and authority-building operation.

    Next, the buyer should ask how reported visibility is measured. The aerospace article described its AI Visibility Score as proprietary and based on how often clients appeared in responses from ChatGPT, Perplexity, Gemini, and Claude. A useful evaluation therefore needs the query set, markets, languages, testing cadence, treatment of personalized or variable answers, and distinction between a citation, mention, and recommendation. Without that context, a visibility score is difficult to reproduce or compare.

    Outcome claims deserve the same scrutiny. The plastic surgery report attributed an average of $1.5 million in new annual revenue to First Page Sage’s clients. Before using that figure in a purchasing decision, a buyer would need to request the sample size, period, client mix, attribution method, and distinction between revenue influenced by GEO and revenue caused by it. This does not invalidate the reported result; it identifies the information required to assess it.

    Delivery controls are especially important in healthcare. Medical review responsibility, content approval, analytics practices, escalation procedures, and the handling of nuanced service descriptions should be settled before publication begins. In aerospace, the corresponding questions concern the team’s familiarity with complex offerings, account-based programs, brand positioning, and the scale of previous engagements.

    Finally, references and reviews should be matched to the proposed work. The aerospace ranking normalized review scores from Google, Clutch, and G2, while the other reports also used reviews or notable clients as evaluation signals. Buyers can make those signals more useful by asking for recent references with a similar sector, company size, engagement scope, and internal approval environment.

    Key takeaways

    • Choose the operating model first: managed execution generally points toward an agency, while diagnosis or narrow expertise may favor a consultant.
    • Do not compare ranking positions across the supplied reports as if they came from one scorecard; each used different criteria and candidate pools.
    • Recurring agency names indicate breadth within the reporting, but they do not replace verification of sector knowledge, delivery staff, and relevant client results.
    • Match consultants to the actual constraint, such as multilingual discovery, AI trust signals, measurement, agentic search, distribution, or B2B SaaS.
    • Require reproducible visibility methods, contextualized outcome claims, and references that resemble the planned engagement.

    As GEO programs become more specialized, the strongest buying decisions will come from clearly defined briefs and evidence that can be examined after the ranking table is set aside.

    References