You are looking at GEO agencies because buyers increasingly ask AI systems to identify, explain, and compare providers. The hard part is not finding an agency that can say it does generative engine optimization. It is finding one that understands what a qualified recommendation looks like in your market, which claims require careful evidence, and which commercial event makes visibility worth paying for.
A generic campaign can increase mentions while getting the important details wrong: the market you serve, the work you accept, the buyer you want, or the regulatory conditions attached to your offer. Industry fit should therefore be tested as an operating capability, not accepted as a line in a proposal.
Key takeaways
- Choose an agency that can map AI questions to your real buyers, decision stages, qualification rules, and revenue events.
- Separate industry fluency from industry name-dropping. Client logos are weaker evidence than accurate work samples, attributable outcomes, and a credible subject-matter review process.
- Score brand accuracy and commercial relevance alongside recommendation volume. More mentions are not valuable if they describe the wrong specialization or attract the wrong buyer.
- Give every finalist the same bounded case exercise. Compare how they diagnose the current answer, identify evidence gaps, plan content, manage claims, and measure the result.
- Require a measurement chain from AI appearance to accurate representation, qualified action, and pipeline. A dashboard of prompt screenshots is not a business case.
- Contract for controllable work, quality standards, reporting, and ownership. No agency can guarantee that an independent AI model will recommend you in every answer.
Industry expertise must change the campaign
Industry specialization matters when it changes what the agency does. It should affect the questions selected, the entities and claims that need clarification, the evidence required to support those claims, the third-party authority strategy, and the action counted as a conversion.
The differences are substantial. A staffing firm may need to distinguish searches from prospective employers and candidates while preserving a clear specialization across healthcare, legal, engineering, retained search, RPO, or other recruiting models. A private equity firm needs accurate representation of its investment thesis, sector focus, deal criteria, and intended audience. An energy company may need market-specific language about generation, storage, transmission, interconnection, and regulatory conditions.
| Industry | What a qualifying AI question may contain | Details that must remain accurate | Commercial event to track |
|---|---|---|---|
| Staffing and recruiting | Role type, industry specialization, geography, hiring model, employer need, or candidate need | Practice area, placement model, talent market, client-versus-candidate audience, and actual service coverage | Qualified employer inquiry, candidate inquiry, or another lead event tied to the firm’s operating model |
| Private equity | Company size, sector, transaction type, geography, investment stage, or capital need | Investment thesis, check or company profile where applicable, sector focus, deal criteria, and whether the answer is meant for a founder, business owner, or LP | Deal-sourcing inquiry, fundraising conversation, or qualified opportunity associated with portfolio growth; these are the distinct outcomes a PE-focused program may need to support |
| Energy and power generation | Power availability, generation technology, storage, renewable supply, location, grid market, or large-load requirement | Utility territory, ISO or RTO market, transmission zone, interconnection conditions, technical specifications, and environmental or regulatory claims | RFP, RFQ, interconnection inquiry, PPA discussion, project-finance conversation, or partnership |
If a candidate describes all three as content marketing with different keywords, it has not demonstrated industry fit. The vocabulary is the surface. The real test is whether the agency understands who is asking, what would qualify the answer, what could make it inaccurate, and what happens after discovery.
Ask for evidence in increasing order of strength
Do not let one recognizable logo settle the decision. The agency may have performed unrelated work, supported only one business unit, or inherited a strategy designed elsewhere. Ask for evidence that exposes the work itself:
- Sector vocabulary in context: Can the team discuss your buyer, offer, exclusions, sales cycle, and qualification rules without turning the conversation into a terminology quiz?
- A relevant artifact: Review an anonymized audit, question map, content brief, technical recommendation, authority plan, or report. Look for decisions specific to the industry rather than a reusable template with a different company name.
- A traceable case: Ask for the starting condition, action taken, observed change, and commercial metric. A visibility increase without a definition of qualified demand is incomplete.
- A comparable reference: A reference from a company with similar technical complexity, regulatory exposure, buying committee, or sales cycle is more useful than one that merely shares your broad industry label.
- An accuracy failure and correction: A mature team should be able to explain how it found a wrong or ambiguous claim, who reviewed it, what changed, and how the correction entered the workflow.
Real expertise should reduce the translation burden on your team. It should not eliminate subject-matter involvement. In technical, regulated, or investment-sensitive markets, an agency that claims it needs no access to your experts is usually revealing a weak quality-control model.
Build a scorecard around the cost of being wrong
There is no universal best GEO agency because the expensive failure differs by industry. Staffing evaluations often emphasize recommendation volume, brand clarity, recruiting experience, and value. Private equity evaluation adds lead-generation performance, investment-sector fluency, leadership experience, and operating history. Energy evaluation gives much more weight to technical and regulatory fluency, grid precision, and the connection between search activity and project pipeline. Those staffing, private equity, and energy criteria should not collapse into a single generic leaderboard.
Use a procurement scorecard before proposals arrive, then keep the weights fixed. This prevents a polished presentation from quietly redefining what matters. The following 100-point rubric is a useful default for a complex B2B engagement:
| Criterion | Weight | What earns a high score |
|---|---|---|
| Industry problem and buyer fluency | 25 | The team distinguishes audiences, buying situations, exclusions, regional conditions, and pipeline events. It can identify where an inaccurate answer would create commercial or compliance risk. |
| GEO and AEO method | 20 | The proposal covers answer discovery, question selection, entity and claim clarity, content, technical accessibility, third-party authority, testing, and adaptation. Each activity has an owner and rationale. |
| Content accuracy and authority controls | 20 | The agency has a documented process for evidence, citations, subject-matter review, corrections, approvals, and sensitive claims. It can explain how structured data supports interpretation without presenting schema as the entire strategy. |
| Measurement and commercial attribution | 20 | The plan establishes a baseline, preserves dated observations, distinguishes mentions from accurate recommendations, and connects qualified actions to CRM stages or other commercial records. |
| Delivery and commercial fit | 15 | The actual team, capacity, communication model, scope, dependencies, pricing structure, and contract terms fit your organization. Named specialists appear in delivery, not only in the sales meeting. |
Rate each criterion from zero to five and multiply it by its weight. Define the scale in advance: zero means no evidence, one means an unsupported assertion, three means relevant proof with limitations, and five means direct, repeatable proof with transparent measurement. Require a note or artifact beside every score. If evaluators cannot point to the evidence, the score is optimism rather than assessment.
Use knockout conditions before totals
A high total should not compensate for a dangerous weakness. Set non-negotiable conditions for issues that could invalidate the whole engagement:
- The agency must identify who reviews technical, regulatory, financial, or otherwise sensitive claims before publication.
- The proposal must define the starting baseline, target question set, answer environments in scope, and method used to preserve observations.
- The team must separate recommendation volume from brand clarity. A frequent but inaccurate recommendation can attract the wrong prospect or create a false impression of fit.
- The agency must disclose delivery dependencies, including the access, interviews, reviews, and data it needs from your team.
- The provider must not guarantee inclusion in every AI answer or claim control over an independent model’s output.
- The reporting plan must extend beyond visibility to a qualified action that your organization can recognize and record.
Treat awards, marketplace profiles, and leaderboards as ways to find candidates, not as substitutes for this evaluation. The purpose of your scorecard is not to manufacture an objective winner from subjective inputs. It is to expose where a decision rests on evidence, where it rests on judgment, and which unresolved risk you are accepting.
Make every finalist solve the same bounded case
A capabilities deck shows what an agency wants to sell. A common case exercise shows how it thinks. Give finalists the same real business question, the same background material, the same constraints, and the same submission format. Pay for the exercise if it requires meaningful diagnostic work; a bounded paid assessment is more useful than asking several firms to design an unpaid campaign.
Write a brief that prevents generic answers
Your brief should include the business line, intended buyer, excluded or poor-fit buyer, geography, primary offer, desired conversion, claims requiring approval, known alternatives, and one high-intent question that matters commercially. Include the correct answer as your experts would give it. The agency’s job is not merely to rewrite that answer. It is to diagnose why an AI system might fail to find, understand, trust, or select it.
Ask each candidate to return the same set of outputs:
- Current-answer snapshot: Show how the chosen AI environments describe the company, which sources or pages appear to influence the answer, and where the response is absent, vague, inaccurate, or commercially unhelpful.
- Question and audience map: Place the question in the buyer journey and identify adjacent questions that would change qualification. The map should distinguish informational curiosity from a real buying or selection task.
- Entity and claim diagnosis: Identify ambiguous names, service definitions, locations, audience labels, comparisons, and unsupported claims that could confuse a model or buyer.
- Content intervention: Produce a content brief or revision plan showing the proposed answer, supporting evidence, internal links, structured information, subject-matter input, and approval points.
- Authority intervention: Explain whether the problem can be addressed on your own site or also requires credible third-party references. Private equity programs, for example, may need to strengthen how a firm’s thesis and credibility appear in external sources used during evaluation; energy work may likewise rely on clear explanations supported by third-party references when available.
- Measurement chain: Define what the team will observe in generated answers, what it can observe on the website, which CRM event represents a qualified response, and which parts of the chain will remain inferential.
Listen for the tradeoffs, not just the proposed tactics. Ask what the candidate would refuse to publish, which claim needs an expert review, what it cannot attribute confidently, and what it would do if your visibility improved without producing qualified demand. Strong answers make the limits of the method visible.
Inspect the people and controls behind the plan
Some delivery models assign a strategist, specialized writer, project manager, and technical specialist to an account. That structure can support continuity, but only if the named specialists participate in execution. Ask to meet the day-to-day lead and the person responsible for industry content before signing.
- Who turns business priorities into the question portfolio?
- Who writes, edits, and checks industry claims?
- Who decides whether a problem calls for content, structured data, technical remediation, digital PR, or a third-party authority signal?
- Who records model observations, and how is the sampling method kept consistent?
- Who can approve a correction when the agency discovers a material error?
- What information must your subject-matter experts provide, and at which points can missing input block delivery?
- How does the agency protect quality if output expands across business lines, regions, or portfolio companies?
Needing detailed onboarding is not a weakness by itself. Complex work often depends on client knowledge that no external team can infer. The useful distinction is whether the agency asks precise questions once and builds a reusable knowledge system, or repeatedly sends basic issues back to your team because it never formed a working model of the business.
Choose the operating model that matches the problem
A narrowly focused GEO firm can be a good fit when you already have capable brand, web, analytics, and communications teams. A broader agency may make more sense when AI discovery must connect with paid media, conversion optimization, marketing automation, website architecture, or portfolio-company growth. That broader range can also be more service than you need; some private equity programs deliberately combine GEO with acquisition assessment and post-acquisition marketing, while a firm seeking only answer visibility may prefer a tighter scope.
Agency size is also a fit variable, not a quality verdict. A small specialist may provide senior attention but have limited capacity for multinational or multi-business-line production. A larger multidisciplinary team may offer broader coverage while creating more handoffs and scope-management risk. Ask how the proposed team would handle your actual volume and complexity, then make the capacity commitment explicit in the statement of work.
Contract for an auditable path from answer to pipeline
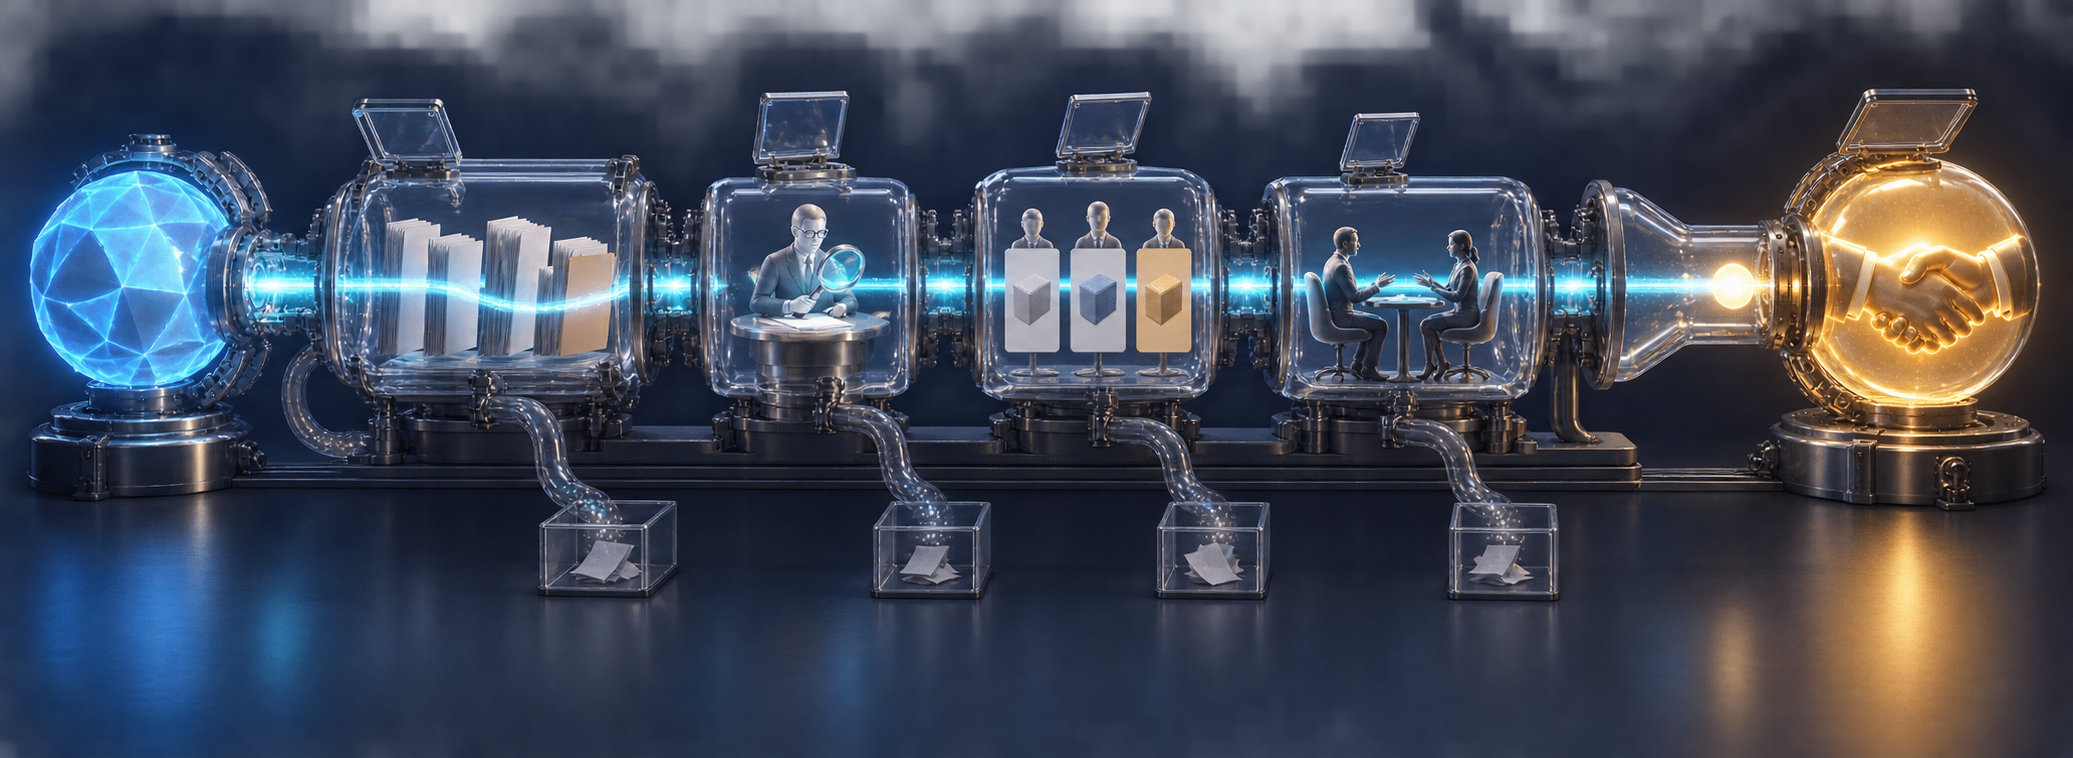
GEO reporting becomes misleading when every metric is placed on the same level. A mention, an accurate recommendation, a site visit, a qualified inquiry, and a commercial win are different events. Build the measurement plan as a chain so that you can see where progress stops.
- Exposure: Was the company absent, mentioned, compared, cited, or recommended for the tracked question?
- Representation: Did the answer accurately describe the specialization, offer, geography, audience, constraints, and reason for selection?
- Engagement: Did a person reach an owned page or otherwise indicate that an AI answer influenced discovery? Record observable referral data where available, but do not assume every AI-influenced visit will carry a detectable referrer.
- Qualified action: Did the person take the action your sales or business-development team recognizes as meaningful?
- Commercial progression: Did the action become an accepted opportunity and move through the relevant pipeline?
The fourth step must use your industry’s language. A staffing program may focus on qualified inbound employer demand and the revenue relevance of those leads. A private equity program may distinguish a founder’s deal inquiry from an LP conversation or portfolio-company growth opportunity. An energy program may need to preserve the relationship between search activity and an RFP, RFQ, interconnection request, PPA discussion, project-finance conversation, or partnership.
Define the baseline so it can be repeated
A one-off screenshot is not a baseline. Generated answers can vary, so preserve the prompt, model or answer environment, date, relevant location or account conditions, answer text, citations, competitors mentioned, and your accuracy assessment. Keep the tracked prompt set stable enough to compare periods, and document any additions or wording changes rather than silently replacing weak prompts.
On the owned side, configure analytics for identifiable AI referrals where available, use campaign-specific landing paths when the tactic permits it, and add a self-reported discovery field to relevant forms or sales conversations. In the CRM, retain the original discovery response alongside lead quality, opportunity stage, and outcome. The agency’s report should label each relationship as observed, self-reported, or inferred.
Set the reporting cadence in the contract, along with the person responsible for resolving discrepancies between the agency dashboard, web analytics, and CRM. An agency may improve visibility without controlling whether an AI provider sends referral data, whether a prospect types your URL directly, or whether sales records the discovery path. Clear attribution boundaries make the report more credible, not less.
Put controllable commitments in the agreement
SEO and GEO programs are described as work that takes time to mature. Treat promises of immediate, stable recommendation placement with skepticism. A provider can commit to research, technical work, content quality, authority development, monitoring, reporting, and response times. It cannot bind an independent AI model to include your company.
The statement of work should define:
- The AI answer environments, markets, languages, audiences, and business lines in scope
- The baseline method and tracked question portfolio
- The planned content, technical, structured-data, and third-party authority work
- Named delivery roles and responsibilities on both sides
- Evidence, review, approval, correction, and escalation procedures
- Reporting fields, attribution limits, and the commercial events used to assess quality
- Ownership of content, research, prompt libraries, dashboards, analytics configurations, and accounts
- Access rules, confidentiality obligations, conflict disclosures, renewal terms, and exit provisions
For a material engagement, have procurement or counsel review confidentiality, exclusivity, intellectual-property ownership, liability, access, renewal, and termination language. A marketing scorecard can identify operational fit, but it cannot protect you from an unfavorable contract.
Your next move is to choose one buying question that already matters to pipeline and write down what a correct, qualified answer must contain. Send that same case to the finalists. The right partner will do more than offer tactics: it will show you where your industry knowledge must enter the system, how the answer can become more trustworthy, and how you will know whether the work created a business result.
References
- First Page Sage – The Top Staffing and Recruiting GEO Agencies of 2026
- First Page Sage – The Top GEO Agencies for Private Equity in 2026
- First Page Sage – The Top Energy and Power Generation GEO / AEO Agencies in 2026

Leave a Reply