Tag: Content Optimization

  • TurboQuant Search Acceleration: An SEO and GEO Action Plan

    TurboQuant Search Acceleration: An SEO and GEO Action Plan

    You may be wondering whether TurboQuant requires an immediate SEO response. The short answer is no: it is not an announced ranking update, and there is no disclosed evidence that Google Search is using it in production.

    It still matters. TurboQuant targets a constraint that shapes semantic search, retrieval-augmented generation, and AI answer systems: how much meaning a system can search within a limited memory and response-time budget. If that constraint loosens, more content can become practical to retrieve. Your job is to make sure your content remains understandable, competitive, and worth citing when the candidate pool grows.

    TurboQuant changes retrieval economics, not your ranking brief

    Semantic search systems commonly convert documents, passages, products, images, or other objects into vectors. A vector is a numerical representation that places related meanings near one another. When someone asks a question, the system can retrieve nearby vectors even when the wording in the query does not exactly match the wording in the content.

    The difficulty is scale. Detailed vectors consume memory, moving them through processors takes time, and building or updating large searchable indexes can be expensive. A system may therefore search only a restricted candidate set before another model ranks, filters, or summarizes the results.

    TurboQuant addresses that infrastructure problem by compressing vectors while preserving a close approximation of their original relationships. It mathematically rotates the data to make it easier to pack efficiently, then carries a 1-bit error-correction signal intended to reduce mistakes introduced by compression. Google also associates the approach with substantially lower memory requirements and nearly zero indexing time.

    That is important, but it is not the same as a new ranking factor. TurboQuant does not tell a search engine which page is trustworthy, which claim is current, which source deserves a citation, or which answer best satisfies a user. It makes one stage of the pipeline more efficient: locating semantically similar candidates.

    Keep the distinction clear in planning meetings. Retrieval asks, “Which items might be relevant?” Ranking and answer generation ask, “Which of those items should be used, in what order, and for what purpose?” Faster retrieval can affect the first decision without replacing the others.

    A larger candidate pool changes what can be discovered
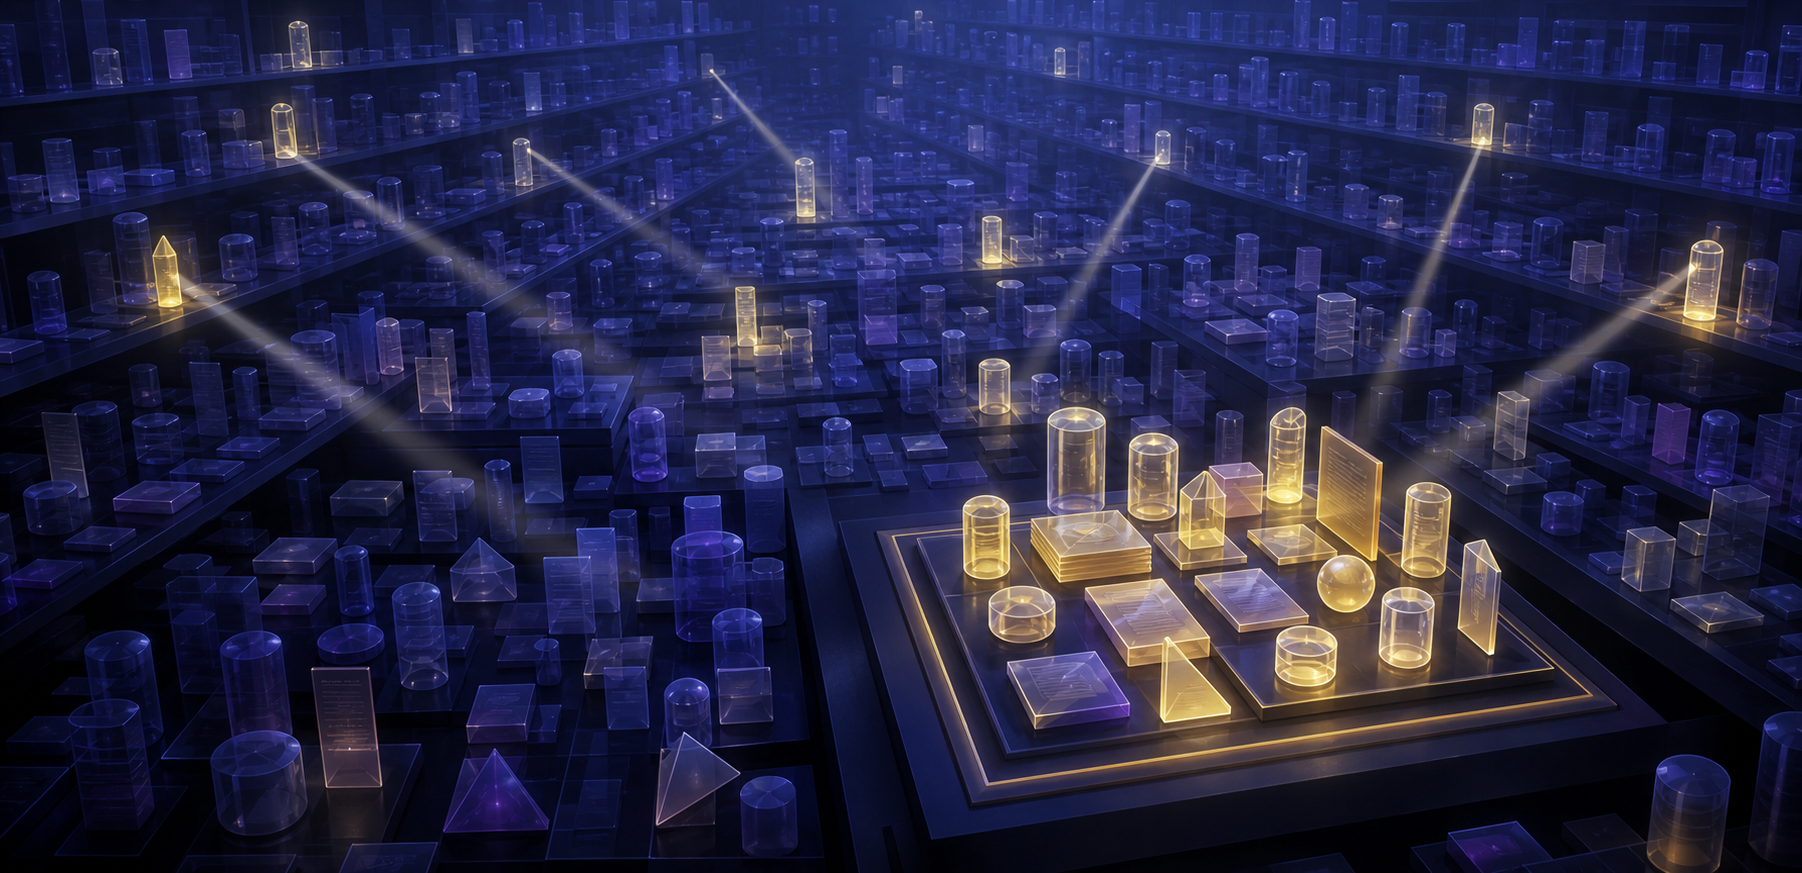
    Scanning beams illuminate relevant capsules and document-like tiles across a vast abstract archive, with selected items grouped in the foreground.

    A search or AI system operates inside practical limits. It has finite memory, compute capacity, and time to produce a response. If vectors become cheaper to store and faster to search, the system could examine a broader collection of candidates within those limits. That could include more documents, more passages within each document, or more specialized material that would otherwise sit outside an economical retrieval set.

    This does not guarantee that AI answers will cite more websites. A larger candidate pool can increase opportunity and competition at the same time. Your page may become easier to retrieve, but so may a more precise product manual, a better-supported explanation, or a specialist page that previously sat too deep in the corpus.

    The likely strategic shift is from winning inside a narrow set of obvious pages to surviving comparison against a deeper set of semantically related passages. Thin content becomes more exposed in that environment. Repeating the target phrase does little when the system can find pages that answer the underlying question with clearer entities, stronger evidence, and better-qualified claims.

    Nearly zero indexing time could also make rapid ingestion more practical for systems built around TurboQuant. Do not turn that possibility into a claim about Google Search freshness. Crawling, rendering, canonicalization, quality assessment, and index-selection policies remain separate processes. Faster vector indexing cannot make an uncrawled or rejected page searchable.

    The same logic applies outside public search. An organization operating a large retrieval-augmented generation system could use aggressive vector compression to reduce memory pressure or update a knowledge index more quickly. If you own that system, TurboQuant is an engineering option to evaluate. If you publish content that such systems may ingest, the more durable task is to improve the material being represented by those vectors.

    Optimize the passage before you optimize the embedding
    Disordered translucent fragments are reorganized into clear modular content blocks before becoming compact glowing vectors.

    You usually cannot control which embedding model, quantization method, retrieval threshold, reranker, or answer model a third-party search system uses. You can control whether a passage contains enough information to be correctly interpreted after it is separated from the rest of the page.

    Start with answer-bearing passages. A useful passage names the subject, resolves the question, and carries the qualification that prevents the answer from becoming misleading. Avoid openings that rely on nearby headings or pronouns to supply all the context. “It depends on the plan” is fragile. “Indexing frequency depends on the crawler, the site’s change rate, and whether the URL remains eligible for indexing” retains meaning when retrieved alone.

    Do not force every paragraph into a rigid template. The goal is semantic completeness, not robotic prose. Use the following checks where a passage contains a definition, recommendation, comparison, process, limitation, or factual answer:

    • Name the entity. Use the full product, organization, method, or standard name before relying on shorthand. This reduces ambiguity between similarly named entities.
    • State the relationship. Make it explicit whether the entity creates, supports, replaces, depends on, conflicts with, or applies to something else.
    • Carry the qualifier. Keep version, platform, audience, condition, and scope close to the claim they limit.
    • Put evidence beside the claim. A citation attached to a vague paragraph is less useful than a link on the specific statement it supports.
    • Separate fact from inference. Use direct language for documented behavior and conditional language for plausible consequences. TurboQuant could support broader retrieval; that does not establish its use in Google Search.

    Next, cover the relationships around the central entity. A page about TurboQuant should not merely repeat that it accelerates vector search. A useful treatment connects compression to memory use, index construction, similarity accuracy, candidate retrieval, reranking, and downstream answer generation. Those relationships help a system match the page to different formulations of the same underlying problem.

    This is semantic breadth, not permission to inflate word count. Add a section only when it resolves a real adjacent question. Remove a section when it paraphrases a claim already made. Efficient retrieval can expose comprehensive content, but it can also expose padding.

    Make structured data support the same meaning

    JSON-LD and schema markup can reinforce entity identity and relationships, but they do not rescue unclear visible content. Treat structured data as a machine-readable restatement of the page, not a hidden layer where you make claims the reader cannot see.

    For each important page, compare the visible content with its structured data. The page title, main entity, author or organization, publication information, and any explicitly marked questions or steps should agree. If the markup identifies one subject while the body drifts into several loosely related topics, compression is not the problem. The underlying document is ambiguous.

    Internal links deserve the same discipline. Use anchor text that describes the destination’s role rather than generic commands such as “learn more.” Link from a broad concept to the page that resolves its important subtopic, and link back where the relationship helps the reader. This creates navigable context for crawlers and people without pretending that internal links directly control vector proximity.

    Technical eligibility remains the floor. Confirm that the canonical URL is crawlable, the primary answer appears in rendered HTML, internal links reach the page, and structured data matches the visible material. A brilliantly written passage cannot enter a retrieval pipeline that never receives or accepts the page.

    Run a retrieval-readiness audit you can repeat

    Do not create a TurboQuant-specific score. You have no public implementation details that would make such a score credible. Audit the properties that remain useful across embedding models and compression methods.

    1. Select a representative page from each important topic cluster. Include the pages that answer commercial, informational, troubleshooting, and comparison questions rather than auditing only your highest-traffic URLs.
    2. Build query families around user intent. For each page, write the direct question, a paraphrase, a problem-first version, and a version that names a competing approach. This reveals whether the page answers the concept or merely repeats one keyword pattern.
    3. Locate the passage that should satisfy each query. If you cannot point to a self-contained answer, rewrite the relevant section. Do not assume the title or surrounding page will repair an incomplete paragraph.
    4. Check entities and qualifiers. Mark unclear pronouns, unexplained abbreviations, missing versions, unsupported superlatives, and conditions placed far away from the claims they govern.
    5. Verify evidence and provenance. Link important claims to their originating authority when available. Remove assertions whose confidence exceeds the evidence.
    6. Compare visible content, metadata, and JSON-LD. Resolve conflicts in names, dates, page purpose, authorship, and entity type. Consistency makes the page easier to interpret; markup volume does not.
    7. Record answer-surface outcomes. For the query families you monitor, note whether your URL appeared, whether it was cited, which passage was used, and which alternative sources won. Ordinary rank position alone cannot show how an AI answer assembled its response.

    When a competing page is selected, diagnose the difference at the passage level. Ask whether it gave a more direct answer, named the relevant entity more clearly, carried a necessary qualification, supplied stronger evidence, or addressed an adjacent intent you omitted. Those observations produce useful editorial work. Guessing at an undisclosed quantization configuration does not.

    Keep infrastructure tests separate from content tests if you operate your own vector search system. Engineering teams can compare memory use, indexing cost, latency, and retrieval quality under compression. Editorial teams should evaluate answer completeness, ambiguity, evidence, and citation suitability. Combining both into one vague “AI optimization” metric makes it impossible to tell which layer improved.

    Key takeaways

    • TurboQuant compresses vectors to reduce memory pressure and accelerate similarity search, with a 1-bit signal designed to correct small compression errors.
    • It is retrieval infrastructure, not a disclosed Google Search ranking factor or confirmed production deployment.
    • Cheaper retrieval could let an AI system search a broader candidate set, but broader access also exposes your content to more competitors.
    • Your durable advantage is a crawlable page with self-contained passages, unambiguous entities, nearby qualifications, and evidence attached to specific claims.
    • Use JSON-LD to reinforce visible meaning. Do not use it to compensate for vague writing or to introduce claims absent from the page.
    • Measure citation and passage selection across query families, not just traditional rankings for one exact keyword.

    Your next move is modest: choose one important topic cluster and run the retrieval-readiness audit before rewriting the entire site. Fix the places where meaning breaks when a paragraph stands alone. That work remains valuable whether TurboQuant reaches public search, stays inside other AI systems, or inspires a different compression method.

    References


  • AI-Mediated Content Discovery: An Optimization Playbook

    AI-Mediated Content Discovery: An Optimization Playbook

    You publish a precise title, a useful answer and a well-structured page. Then an AI system presents a different headline, compresses the answer into a few sentences or recommends a forum discussion instead. The immediate temptation is to chase whichever domain dominates the latest citation chart.

    That reaction solves the wrong problem. In AI-mediated discovery, your audience may encounter a machine-generated interpretation before it encounters your page. You therefore need content that is easy to select, difficult to misrepresent, clearly attributable and still worth visiting after the summary appears.

    Treat AI as a second presentation layer

    Two-layer content system with a detailed source page below and a compact AI-generated answer connected to selected source modules above.

    Publishing controls the material you make available. It doesn’t fully control how an intermediary presents that material. A search engine, answer engine or content platform may select a passage, combine it with other material, rewrite its label or generate a summary. Ranking is only one part of that process.

    Discovery outcomeQuestion to askTypical failure
    SelectionDoes the system use your content for the relevant question?A competitor, forum or reference site supplies the answer instead.
    RepresentationDoes the generated answer preserve your meaning and important conditions?A caveat disappears, a comparison becomes absolute or an old claim is repeated without context.
    AttributionCan the user connect the claim to your brand, expert or page?Your idea appears without a citation or with another entity presented as the authority.
    ActionDoes the presentation give the user a reason and a path to continue?The summary answers enough to stop the journey, or the destination doesn’t match the generated promise.

    The representation risk is not theoretical. In a limited YouTube experiment, some Android users saw familiar thumbnails accompanied by expandable AI summaries rather than the usual creator-written titles. The experiment was small, and no wider rollout was confirmed. It shouldn’t be treated as a permanent YouTube rule. It does show how easily the presentation layer can move away from the words a creator chose.

    Audit priority content against all four outcomes. Start with the rendered page, not just its keyword report, and ask:

    • Can someone identify the exact question the page answers from its title, opening and section headings?
    • If a single answer paragraph is extracted, do its subject, scope and conditions remain intact?
    • Does the passage name the relevant product, company, person or concept, or does it rely on pronouns and surrounding context?
    • Can a reader distinguish your verified claims from opinions, examples and predictions?
    • If the generated answer earns a visit, does the destination immediately continue the same task?

    A page can rank and still fail this audit. It can also be quoted accurately without producing a visit. Those are different outcomes, so don’t hide them inside one visibility score.

    Choose channels at the query level, not from citation charts

    Domain-level citation charts are distribution maps, not channel strategies. If an analysis pools a broad mix of pop-culture, consumer-advice and informational queries, large general-purpose domains such as Wikipedia, Reddit and YouTube will naturally occupy a large share of the results. That pattern doesn’t tell you which source type an AI system will prefer for a specific B2B buying question, technical objection or implementation problem.

    Make the query family your unit of analysis. Build a working inventory around the decisions your audience actually faces:

    • Problem recognition: What is happening, and what is the problem called?
    • Category education: How does the approach work, and when is it appropriate?
    • Comparison: Which options differ on the criteria that matter to this buyer?
    • Risk and objection: What can go wrong, what are the limitations and what evidence reduces uncertainty?
    • Implementation: What must the user configure, verify or troubleshoot?
    • Brand validation: Is this company or product credible for the stated use case?

    For each family, inspect which kind of material supplies the answer. A reference page may win a definition query. A practitioner discussion may win a question about lived trade-offs. Product documentation may win a configuration question. An original analysis may win when the user needs evidence or a defensible comparison. The point is not to force your site into every role. It is to identify the role your content can credibly own and the gaps that require another channel.

    Use community visibility only when participation is the real strategy

    Reddit can appear prominently for bottom-of-funnel software searches because authentic peer reviews, continuing discussion and accumulated consensus provide context that an isolated promotional message cannot reproduce. A campaign that manufactures posts or agreement may create mentions, but it doesn’t recreate the reason a trusted discussion became useful.

    Wikipedia is a different environment. Its editorial constraints make it unsuitable as a brand-controlled distribution surface. Treating either community as inventory misses the mechanism that gives it value.

    Use this decision gate before investing in an external community:

    • Would the contribution still help the reader if your company name and link were removed?
    • Can the contributor disclose an affiliation without weakening the substance of the answer?
    • Does your team have knowledge, evidence or direct product context that is missing from the discussion?
    • Can someone return to answer follow-up questions, correct errors and maintain the contribution?
    • Would the claim survive skeptical review from people who don’t share your commercial interest?

    If those conditions aren’t met, put the effort into a stronger owned resource. If they are met, participate under the community’s rules and measure usefulness before citations. On Reddit, answer the actual question, disclose the relationship and avoid manufacturing consensus. On Wikipedia, limit involvement to verifiable corrections and respect editorial review. On YouTube, make the video’s subject and central claim clear within the content itself, while continuing to write accurate creator-controlled titles wherever the interface displays them.

    Give every channel a defined job

    ChannelUseful roleWarning sign
    Owned websiteCanonical explanations, product facts, original evidence, documentation and conversion paths.The page makes claims that cannot be verified or understood without sales contact.
    Reddit or another forumFirsthand context, candid trade-offs, follow-up discussion and questions in the audience’s own language.The plan depends on disguised promotion, disposable accounts or coordinated agreement.
    WikipediaNeutral, verifiable reference information that meets the community’s editorial expectations.The goal is to control brand positioning or insert unsupported commercial claims.
    YouTubeDemonstration, explanation and visual evidence for questions that benefit from video.The meaning exists only in a clever title and isn’t stated clearly in the content.

    Build answer blocks that remain accurate after compression

    AI optimization doesn’t require flattening every page into short, generic answers. It requires making the smallest useful answer unit complete enough to stand on its own. A strong unit identifies the subject, states the answer, carries the necessary boundary and provides a reason to trust or continue.

    A practical answer block performs these jobs:

    • Name the entity and question. Don’t make an extracted passage depend on the previous heading or a chain of pronouns.
    • State the answer directly. Put the useful conclusion before background that only explains why the question matters.
    • Keep the qualifier attached. Version, market, audience, use case and exception should sit beside the claim they limit.
    • Show the mechanism or evidence. Explain why the answer holds, or point to the observable fact that supports it.
    • Offer the next useful step. Lead to a comparison, method, specification or decision that a short summary cannot fully replace.

    A reusable pattern is: entity plus answer plus condition, followed by mechanism or evidence, then the next decision. It is a drafting aid, not a rigid sentence template. Use as much space as accuracy requires. There is no universal paragraph length that guarantees extraction or citation.

    Keep the page, metadata and schema in agreement

    Your page title, visible heading, opening answer, section labels, internal anchor text and structured data should describe the same entity and promise. If the title offers a comparison but the page delivers a category overview, an intermediary has to infer the relationship. If the JSON-LD identifies an author or entity differently from the visible page, you have created another avoidable ambiguity.

    Use structured data for facts that are visible and supported on the page. Treat it as a consistency layer, not a citation switch. Schema cannot make a weak claim authoritative, force an answer engine to select the page or prevent a platform from generating a different presentation.

    Also separate author-controlled fields from generated output in your audits. A rewritten headline is not evidence that the original title was changed in your CMS. Record what you published and what the platform displayed. You need both to diagnose whether the problem is in the content, the markup or the intermediary’s presentation.

    Run a compression test before publishing

    1. Choose one high-value question the section must answer.
    2. Copy the smallest passage that contains the complete answer.
    3. Review that passage without the page title, navigation or preceding paragraphs.
    4. Identify the subject, conclusion, conditions, evidence and responsible entity using only that passage.
    5. Rewrite any point that becomes broader, stronger or less attributable when removed from its surroundings.

    Pay special attention to words such as it, this, they, best, always and should. They aren’t inherently wrong, but they often conceal a missing entity, comparison set, condition or rationale. Replace them when the isolated passage could support more than one reasonable interpretation.

    This test also catches a common content-design mistake: placing the caveat several paragraphs after the claim. A human reader may connect them. A generated answer built from a smaller passage may not. Keep a condition beside the statement it changes, then expand on the edge case later.

    Measure the generated answer and fix the correct layer

    Top-down illustration of a technician diagnosing a generated answer by inspecting four connected system components and adjusting the highlighted one.

    Referral analytics can’t tell you whether an AI system named your brand, represented a claim correctly, cited your page without a visit or recommended a competitor while borrowing your framing. Add output observation to your usual search and content reporting.

    Start with a stable panel of real audience questions. Preserve the exact wording, group each query by decision stage and record the platform, mode and other conditions that could affect what you see. Capture the answer on a consistent cadence. The purpose is not to declare a permanent rank from one response; it is to identify repeated representation problems and useful patterns.

    SignalWhat to recordWhat it helps you decide
    SelectionWhether your brand, page or claim appears at all.Whether the content is eligible and relevant for this query family.
    RepresentationThe claim as generated, including lost or added qualifications.Whether the source material needs a clearer answer block.
    AttributionWhich brand, author or organization receives credit.Whether entity naming and ownership are explicit enough.
    CitationThe destination cited and the passage that supports the answer.Whether the system is reaching a canonical, current and useful page.
    RecommendationThe option presented and the stated reason for choosing it.Which buyer criteria and evidence your content fails to address.
    Action pathWhether the user can continue to the relevant page or task.Whether discovery can become a productive visit or decision.
    VariationWhat changes across repeated observations under recorded conditions.Whether you are seeing a durable gap or unstable output.

    Keep these signals separate until you understand them. A mention with an inaccurate claim is not a success. A correct uncited answer is not the same problem as total omission. A citation to an outdated page requires a different fix from a recommendation that favors a competitor on a criterion you never addressed.

    Use the failure type to choose the response:

    • Selection failure: confirm that the page directly answers the query and that its purpose is clear in the title, opening and headings.
    • Representation failure: rewrite the relevant passage so the answer and its conditions survive extraction together.
    • Attribution failure: name the responsible entity inside the answer unit and align visible authorship with structured data.
    • Citation failure: consolidate duplicate explanations, strengthen internal paths to the canonical page and keep the preferred destination current.
    • Recommendation failure: address the actual decision criteria with evidence rather than adding more generic brand language.
    • Community-source dominance: determine whether users need experiential evidence that your owned page cannot credibly provide; participate only if you can contribute that evidence transparently.

    Don’t overhaul a content program because one platform runs a small interface experiment or one broad citation chart changes. Look for the same failure across a meaningful query family, then repair the layer responsible for it.

    Key takeaways

    • Optimize for selection, representation, attribution and action rather than treating a citation as the whole outcome.
    • Use query-level evidence to choose channels; a domain’s overall citation share is not a strategy for your audience.
    • Keep the answer, subject, qualifier and evidence close enough to survive compression as one coherent unit.
    • Align visible content, metadata and JSON-LD, while recognizing that no markup can force an AI-generated presentation.
    • Participate in Reddit, Wikipedia or another community only when you can add transparent, durable value under its rules.
    • Track generated claims and recommendations alongside referrals, then match each failure to the layer that can actually fix it.

    Choose one commercially important query family and inspect the generated answers before expanding your program. Repair the clearest selection or representation gap on the page that should own the answer, then observe the same queries again under recorded conditions. That cycle gives you a defensible AI discovery strategy without surrendering it to whichever platform happens to lead a headline chart.

    References

  • Google March 2026 Core Update: Diagnosis and Recovery Plan

    Google March 2026 Core Update: Diagnosis and Recovery Plan

    Your organic traffic moved during March 2026, and the tempting response is to rewrite every page that lost clicks. Resist that impulse. Google’s first core update of 2026 arrived close to separate spam and Discover changes, so a simple month-over-month chart cannot tell you what happened.

    Your first job is attribution: isolate the affected search surface, query set, page group, and shared weakness. Then change only what the evidence supports. This protects strong pages from panic edits and gives you a credible way to judge whether the work helps.

    Key takeaways

    • Google said the March 2026 core update could take up to two weeks to roll out. Treat movement inside that window as provisional rather than a final verdict.
    • Do not attribute every March change to the core update. A March spam update, a February Discover update, your own site releases, tracking problems, and changing demand can produce different patterns.
    • Diagnose at the level of search surface, query cluster, page group, and template. A sitewide traffic total hides the pattern you need to fix.
    • Audit whether losing pages satisfy the searcher’s task more clearly and completely than competing results. Cosmetic rewrites and extra keywords are not a recovery strategy.
    • There is no universal or immediate repair. Improvements can appear gradually, including after later core updates, so preserve evidence and measure each coherent batch of changes.

    Treat March as an attribution problem, not a verdict

    A core update is a broad reassessment of how Google’s systems surface useful results across many sites and searches. Google characterized this release as a regular update focused on relevant and satisfying content. A ranking loss does not, by itself, prove that a page violated a rule, received a manual penalty, or needs to be deleted.

    The surrounding timing matters. The core update followed a March 2026 spam update and a February 2026 Discover update. Those events are not interchangeable. A change confined to Discover should not automatically become a core-update content project. A Web Search decline should not be blamed on Discover. A sitewide drop across every acquisition channel may point to measurement, demand, or a site release rather than Google rankings.

    Build a timeline before opening your content editor. Mark the core, spam, and Discover milestones; Google’s confirmed rollout completion; and every meaningful change your team shipped nearby. Include migrations, URL changes, template releases, internal-link changes, tracking updates, large content batches, and availability or pricing changes that could affect demand. The purpose is not to choose a convenient explanation. It is to keep plausible causes separate long enough to test them.

    Use comparable reporting periods on either side of the event. Match the length and weekday mix, and note seasonal or campaign-driven demand. If a comparison period overlaps the rollout, label the result provisional. For historical analysis, anchor the post-update period after Google’s confirmed completion marker rather than assuming the announcement date was the moment every ranking changed.

    Build a page-and-query evidence map

    Blank web page cards and search tokens are grouped and connected with colored threads on an evidence-mapping workspace.

    Start with Google Search Console and your analytics platform, but do not begin with total organic sessions. First separate Web Search from Discover and other channels. Within Web Search, compare impressions, clicks, click-through rate, and average position by query and page. Within Discover, examine the available page-level reporting on its own terms rather than forcing it into a Web Search query analysis.

    Group affected pages by the reason they exist: topic, search intent, content format, audience, template, authoring process, or business line. The useful unit is rarely one isolated URL. If a collection of similar pages declined together while the rest of the site held steady, the shared pattern is more informative than the site’s average.

    1. Save an untouched baseline export before editing anything. Preserve page, query, device, country, impressions, clicks, position, and conversion data where available.
    2. Separate losses in visibility from losses in response. Falling impressions or positions indicate a search-visibility problem. Stable impressions with fewer clicks point toward result presentation, changed result features, or user choice. Stable search clicks with weaker conversions point downstream to the landing experience, offer, tracking, or audience fit.
    3. Rank page groups by material impact, then look for repeated behavior. A cluster losing across many related queries deserves attention before a single volatile term.
    4. Record winners as well as losers. Unchanged and improving pages show which formats, topics, and approaches Google continued to surface on your own domain.
    5. Inspect the current results for the affected queries. Compare the task served, answer depth, format, specificity, freshness needs, and intended audience. Do not copy the winners; identify what searchers can accomplish there that they cannot accomplish on your page.
    Observed patternWorking interpretationNext check
    Web Search impressions fall across one topic clusterThe cluster may have lost relevance or competitiveness for those searchesCompare query intent, result types, answer depth, and the pages that replaced it
    Discover declines while Web Search remains stableThe evidence does not support a sitewide core-update diagnosisAnalyze Discover separately and account for the February 2026 Discover update
    One template declines across unrelated topicsA shared presentation, technical, or content-production pattern may be involvedCompare affected and unaffected templates, including rendering, indexing, internal links, and visible page structure
    Impressions remain stable but clicks declineVisibility may not be the primary problemReview titles, descriptions, competing result features, and whether the displayed promise matches the query
    Search clicks remain stable but conversions declineThe ranking update is not sufficient to explain the business lossCheck tracking, page behavior, offer changes, availability, and conversion flow
    All channels fall at the same timeA Google core update is unlikely to be the only causeCheck analytics integrity, site releases, outages, demand, and commercial changes

    These interpretations are starting hypotheses, not automatic diagnoses. Require the pattern to appear in the underlying page and query data before assigning work to it.

    Fix satisfaction gaps rather than chasing signals

    Google’s standing direction remains to create helpful content for people. That advice becomes useful only when you turn it into page-level questions. “Make it better” is not an action. “Move the procedure ahead of the company background because the dominant queries ask how to complete the task” is an action.

    Test the page against the searcher’s actual job

    Write the main task in one sentence before reviewing the page. Is the person trying to learn, compare, troubleshoot, verify, calculate, choose, or complete a process? Then locate the first point where the page materially serves that task. If the answer is buried beneath a generic introduction, brand narrative, or loosely related background, fix the order before adding more words.

    Check whether the title, opening, headings, body, examples, and call to action serve the same intent. A page often weakens when it promises one job in the search result, explains another in the body, and pushes a third in the call to action. Alignment matters more than repeating the target phrase.

    Find the missing decision support

    A page can be factually correct and still leave the reader unable to act. Look for absent prerequisites, constraints, tradeoffs, failure modes, definitions, examples, or next steps. Add only what closes a real decision gap. A longer page that delays the answer is not inherently more satisfying than a concise one.

    Ask a hard comparative question: what can someone decide or do after reading the results now ranking above you that they could not decide or do after reading your page? The answer should become a concrete edit. If you cannot identify a meaningful difference, do not manufacture one by expanding every section.

    Verify accuracy, ownership, and maintenance

    Check every consequential claim, named feature, date, process, and recommendation. Remove unsupported certainty. Replace stale instructions. Make authorship and editorial responsibility clear where the reader needs them to judge the advice. Cite the originating authority when a claim depends on a standard, policy, specification, or official announcement.

    Do not simulate freshness by changing a date while leaving old guidance intact. A meaningful update should have a reason you can record: a corrected fact, a changed process, a better explanation, a newly addressed intent, or clearer decision support.

    Keep schema aligned with the visible page

    JSON-LD can clarify the entities, properties, and relationships already represented on a page. It cannot turn thin, mismatched, or unsupported content into a satisfying result. Treat structured data as a consistency layer, not a core-update recovery switch.

    After a substantive edit, verify that the markup still matches the visible content. Remove properties the page no longer supports, keep entity names and relationships consistent, and avoid adding types merely because they appear SEO-friendly. The content, metadata, internal links, and schema should describe the same thing without contradiction.

    Make controlled changes and measure recovery honestly

    One generic web page panel is adjusted in a controlled testing lane while two unchanged panels remain covered for comparison.

    Prioritize shared weaknesses that affect a meaningful group of pages. An isolated decline with no repeatable pattern is a poor reason for a sitewide rewrite. A clear intent mismatch across an entire template or topic cluster is a stronger candidate because the diagnosis and expected effect can be stated in advance.

    1. Preserve the baseline data and a recoverable copy of every page before making material changes.
    2. Resolve measurement, indexing, rendering, redirect, or deployment problems before judging content quality. Content edits cannot repair missing data or a broken delivery path.
    3. Choose a coherent page group with one identifiable weakness. Define the intended change and the metric that should respond.
    4. Make the smallest batch large enough to test the shared diagnosis. Avoid mixing unrelated URL, template, copy, schema, and commercial changes when they can be separated.
    5. Annotate what changed, where, why, and when. Keep unaffected pages steady where practical so later comparisons retain context.
    6. Re-evaluate the same page and query groups after Google has processed the changes. Judge visibility and qualified outcomes together rather than celebrating a traffic increase that does not serve the audience or business.

    Choose the treatment page by page. Refresh a URL when its purpose remains valid but its answer is stale, incomplete, unclear, or poorly ordered. Consolidate pages when several weak URLs divide the same intent and none earns a distinct role. Leave a strong page alone when the evidence is inconclusive. Retire a page only when it no longer serves a user or business purpose; preserve the evidence first, and map a relevant redirect before removing a URL when a genuine replacement exists.

    Google has not supplied a special one-step repair for this update. Recovery may be gradual and may become visible around subsequent core updates. That does not mean you should wait passively, but it does mean you should reject guaranteed recovery dates and avoid claiming that one edit caused a later movement without supporting evidence.

    Your next action is straightforward: annotate the core, spam, and Discover context; preserve a clean baseline; map the largest losses by surface, query intent, page group, and template; and approve edits only where you can name the satisfaction gap. That turns a volatile month into a controlled recovery program instead of a trail of untraceable changes.

    References


  • Cross-Platform Influencer SEO: A Practical Framework

    Cross-Platform Influencer SEO: A Practical Framework

    You can pay for a creator campaign, get a burst of attention, and still end up with content that disappears as soon as the feed moves on. The missed opportunity is not more distribution. It is making each creator asset clear enough to be found when someone searches for the problem, product category, comparison, or use case it addresses.

    The fix starts before the creator records anything. You need to connect a real search question to the right creator, build the answer into the content, adapt that answer to each platform, and measure whether it remains visible after publication.

    Treat every creator asset as part of the search journey

    A buyer rarely completes a considered search in one place. Someone looking for the best lightweight running shoes might discover options on TikTok, request a comparison from ChatGPT, inspect commentary through Google, and then visit a brand site. Creator content can influence several points in that journey, even when the buyer never visits the creator’s profile directly.

    Google can surface social opinions through features such as “What people are saying,” including material from YouTube, TikTok, LinkedIn, and other platforms. Social and video content can also supply context for AI-generated answers. Your influencer program therefore creates search inventory whether or not the campaign team manages it that way.

    Cross-platform influencer SEO does not mean copying the same caption everywhere. It means preserving a recognizable answer while changing the presentation for each environment. The product name, category, use case, audience, and factual claims should remain stable. The hook, pacing, depth, visual treatment, and call to action can change.

    This distinction prevents two common failures. A generic awareness video may be entertaining but give a search system little information about the question it answers. An over-optimized script may contain the right phrase repeatedly but sound unnatural enough to weaken the creator’s authority. Effective creator SEO keeps the subject unmistakable without turning the content into a spoken keyword list.

    Key takeaways

    • Choose a search question tied to a decision the audience is actually making.
    • Match that question with a creator who can demonstrate or explain the answer credibly.
    • Carry the topic into spoken words, on-screen text, captions, titles, descriptions, and relevant hashtags.
    • Keep names, use cases, qualifiers, and approved claims consistent across platforms.
    • Measure native search, Google visibility, AI visibility, content usefulness, and business outcomes separately.

    Map the query to the decision and the creator

    A magnifying lens, branching paths, product decision objects, and three miniature creator studios illustrate matching a search need to a creator.

    Do not begin with a creator roster and look for keywords to attach later. Begin with the audience decision. Is the searcher trying to understand a category, compare alternatives, check whether a product suits a particular use case, validate a concern, or decide what to buy?

    That decision determines the form of the content. A broad educational query may need a clear explanation. A comparison query needs visible criteria. A suitability question needs a demonstration under the relevant conditions. A purchase-stage query needs specific trade-offs and a useful next step.

    Build the query set from evidence already available to your teams: organic search insights, native platform trends, recurring questions in creator comments, customer language, and tools such as AnswerThePublic. Keep the audience’s wording intact during collection. You can consolidate variants later, but early normalization often removes the precise qualifier that reveals intent.

    For example, “running shoes” identifies a category. “Best lightweight running shoes for travel” identifies a category, comparison, desired attribute, and use case. The longer expression gives the creator something concrete to answer and gives you a much better basis for evaluating the finished asset.

    Planning fieldWhat to recordReview question
    Audience decisionThe choice, concern, or uncertainty behind the searchWhat should the viewer be able to decide after watching?
    Search expressionThe natural wording used by the intended audienceDoes the wording preserve important qualifiers?
    Required answerThe useful conclusion the content must deliverDoes the asset answer the query rather than merely mention it?
    Proof formatDemonstration, explanation, comparison, walkthrough, or opinionCan this creator show the answer credibly?
    Creator fitThe creator’s relevant subject history, audience, and format strengthsWill the recommendation feel consistent with their existing work?
    Platform roleDiscovery, detailed evaluation, professional validation, or conversion supportWhy does this asset belong on this platform?
    DestinationThe next page, video, profile, or action that continues the journeyDoes the next step satisfy the same intent?

    Creator selection should follow the map. Look for a history of discussing the relevant problem, a format capable of showing the required proof, and audience responses that indicate genuine interest in the subject. Reach matters to distribution, but topical fit determines whether the answer feels believable and whether the asset has a coherent search purpose.

    Share the query language with the creator before locking the script. A creator may know a more natural way to express the same intent. Accept that adjustment when it preserves the audience, problem, category, and meaning. Search optimization needs semantic clarity, not forced recitation.

    Write a search-ready brief without scripting out the creator

    A weak brief says, “Mention the product naturally and add these hashtags.” That tells the creator what must appear but not what the content must answer. It also leaves the campaign team unable to judge whether the deliverable serves a searcher.

    A search-ready brief states the audience decision, target query, required answer, evidence, placement of topic signals, approved claims, creative freedom, and next step. The creator should know which parts are mandatory and which parts they own.

    • Search objective: Describe the question or decision the asset should help resolve.
    • Primary topic: Supply the natural query and acceptable variations, including any qualifier that changes intent.
    • Required answer: State what useful conclusion the viewer should receive. Do not prescribe a positive verdict that the evidence cannot support.
    • Topic placements: Identify where the subject should appear, such as the spoken script, opening frame, on-screen text, caption, title, description, and relevant hashtags.
    • Proof: Specify the demonstration, comparison criteria, walkthrough, or factual context needed to support the answer.
    • Entity language: Provide the correct brand, product, category, feature, and use-case names. Mark any wording that must remain exact for accuracy.
    • Creative control: Leave room for the creator’s hook, examples, visual language, pacing, and personal assessment.
    • Next step: Name the destination that continues the same search intent rather than sending every viewer to a generic homepage.

    The required topic should normally appear in more than one content layer. Spoken language helps make the subject explicit in the actual video. On-screen text helps a viewer recognize the answer quickly. The caption, title, and description provide written context. Relevant hashtags can reinforce classification, but they should not carry the entire strategy.

    Use a pre-publication review that tests clarity rather than keyword density:

    • Can a viewer identify the question during the opening portion of the asset?
    • Does the creator answer the question with an explanation or visible proof?
    • Is the primary topic spoken naturally?
    • Does on-screen text name the subject without covering important visuals?
    • Does the caption add context instead of repeating a thin promotional line?
    • Is the title or description complete enough to stand on its own outside the feed?
    • Are brand, product, category, and use-case names accurate and consistent?
    • Are all factual and comparative claims supportable?
    • Does the final result still sound like the creator?

    If a phrase sounds awkward, change the sentence rather than deleting the subject. If the creator cannot answer the assigned query credibly, change the query or the creator. No amount of metadata can repair a mismatch between the question and the person delivering the answer.

    Adapt the answer instead of duplicating the asset

    One product demonstration is adapted into vertical, horizontal, square, and audio-focused content frames around a creator's workbench.

    Each platform gives the same core answer a different job. Short video may introduce the question and show fast proof. YouTube can accommodate a fuller explanation. LinkedIn can frame the issue around professional decisions. A brand page can verify details and continue the journey. The campaign becomes cross-platform when these assets reinforce one another, not when the same file is uploaded repeatedly.

    Platform or surfaceRecommended jobHow to adapt the core answerWhat to avoid
    TikTok and other short-form videoQuestion-led discovery and concise demonstrationMake the problem recognizable in the hook, say the topic naturally, show the proof, use readable on-screen language, and write a contextual captionA trend-led opening that never makes the actual subject clear
    YouTubeDetailed evaluation and explanationUse a descriptive title, establish the question clearly, cover the relevant criteria, and write a complete description that identifies products, categories, use cases, and conclusionsA vague title or a nearly empty description that depends on viewers already knowing the context
    LinkedInProfessional interpretation and validationLead with the business problem or decision, name the category and audience, and preserve the creator’s analysis rather than reducing the post to campaign copyOpening with brand promotion before establishing why the issue matters
    Brand-owned pageVerification and continuationAlign terminology and approved claims with the creator asset, provide deeper product information, and link or embed the creator content when rights allowSending an intent-rich query to a generic page that does not answer it
    Google and AI answer surfacesSecondary discovery of published creator materialMonitor whether the underlying social or video asset appears for the intended topic and whether its language is represented accuratelyTreating a variable AI response as a permanent ranking

    YouTube deserves particular attention when the subject requires depth. Comprehensive video descriptions can improve the contextual information available to search and AI systems, including for smaller channels. A description should identify what the video covers, which audience or use case it addresses, what is demonstrated, and where the viewer can verify or continue the answer. A link by itself does none of that work.

    Consistency matters across every version. Use the same accurate spelling for the brand and product. Keep the category relationship explicit. Preserve important qualifiers such as audience, location, compatibility, or intended use. Do not let one creator call a feature by a campaign nickname while the landing page, video title, and other creators use unrelated terms.

    Consistent language can give AI systems clearer evidence when connecting a brand with a category or recommendation context. It cannot guarantee a citation or favorable answer, but it removes avoidable ambiguity. Creative variation should change the expression, not the underlying facts.

    Cross-platform expansion also needs editorial discipline. Do not manufacture praise in community spaces or ask creators to disguise sponsored material as an independent conversation. Genuine comments and questions are more useful as audience-language research: record how people describe the problem, then feed those expressions into future query maps and briefs.

    Measure visibility, usefulness, and business impact separately

    A creator asset can succeed in one layer and fail in another. High engagement does not prove search visibility. Search visibility does not prove the answer is useful. Neither one, by itself, proves commercial impact. A single blended campaign score hides the diagnosis you need to improve the next brief.

    Build a record for every published asset that includes the creator, platform, URL, target query, important variations, audience decision, publication date, destination, and campaign identifier. Without that connection, teams can see performance but cannot tell which search intent or content treatment produced it.

    Search visibility

    • Check the native platform for the assigned query and meaningful variants.
    • Inspect Google results for the creator URL, video results, social modules, and relevant “What people are saying” placements.
    • Use a stable set of AI prompts that reflects the target decision. Log the service, model when shown, date, response, cited pages, and whether the creator or brand is represented accurately.
    • Record visibility by query and surface. Do not combine native placement, Google appearance, and AI mentions into an invented universal rank.

    Content usefulness

    • Review retention or viewing patterns to locate the point where attention drops.
    • Track saves, shares, and substantive comments that indicate the answer was useful enough to keep or pass along.
    • Separate query-relevant questions from generic reactions. New questions may reveal missing information or the next search intent to target.
    • Compare performance with the creator’s own relevant historical content when possible, not with an unrelated platform-wide expectation.

    Business impact

    • Track visits to the intended destination with campaign-specific links where the platform permits them.
    • Measure whether visitors engage with the page that continues the answer, rather than counting the click alone.
    • Review attributed and assisted conversions in the context of a multi-platform journey. A last-click report will not describe every earlier creator interaction.
    • Watch whether the questions and terms used in creator content begin appearing in site search, sales conversations, or other audience feedback available to your organization.

    The pattern across these layers tells you what to fix. If the asset is useful to viewers but absent from search checks, strengthen topic placement, titles, descriptions, and query alignment. If it is visible but loses attention, improve the answer, proof, hook, or creator fit. If it earns visibility and engagement but produces no useful next action, inspect the call to action, destination, offer, and measurement setup. If different platforms describe the product inconsistently, repair the entity language in the shared brief.

    The operating model matters as much as the brief. SEO and influencer teams often sit in separate workflows with different goals, so create a shared handoff:

    1. The SEO team supplies the audience decision, query language, qualifiers, and relevant search surfaces.
    2. The influencer team maps those needs to creators, platforms, formats, and campaign constraints.
    3. The creator proposes a native angle and identifies any keyword wording that would sound forced.
    4. The campaign owner reviews the draft for answer quality, search signals, factual consistency, and creator voice.
    5. The publishing owner completes every agreed title, caption, description, text, hashtag, and destination field.
    6. The measurement owner records the asset and checks each visibility, usefulness, and business layer.
    7. The teams convert findings into changes to the query map, creator selection, brief, or destination before the next activation.

    Start with your next creator brief. Add the audience decision, natural query, required answer, proof format, topic placements, consistent entity language, and destination. If you cannot name those elements before production begins, the campaign is not yet ready to work as search content.

    References


  • How to Make Content Machine-Readable for AI Search

    How to Make Content Machine-Readable for AI Search

    You can publish a technically clean page, answer the right question, and still give an AI search system a passage it cannot safely reuse. The problem often appears after retrieval: the extracted sentence no longer identifies its subject, a price loses its billing condition, or a claim depends on context several paragraphs away.

    The fix is not more copy or a larger pile of schema. You need answer blocks that retain their meaning when separated from the page, plus structured data that identifies the same entities and relationships without contradiction.

    Key takeaways

    • Open each important section with a direct answer of roughly 40 to 60 words, then add qualifications, evidence, and next steps.
    • Name the entity inside important claims. Do not make a retriever resolve vague references such as “it,” “they,” “this service,” or “the platform.”
    • Keep scope, units, eligibility, geography, billing terms, and time periods in the same sentence as the fact they qualify.
    • Use JSON-LD to connect Organization, Person, Article or BlogPosting, Product, and Service entities through stable @id values.
    • Treat schema as comprehension infrastructure. Schema can reduce ambiguity, but schema alone does not guarantee an AI citation.
    • Test the live, rendered URL. Perfect prose and valid markup cannot help a system that receives an empty shell, blocked response, or incomplete page.

    Design the passage an AI system needs to retrieve

    Machine-readable content states who or what a fact concerns, how the relevant entities relate, and which conditions limit the claim. It uses descriptive headings, self-contained sentences, accessible HTML, and consistent structured data. The objective is not robotic writing. The objective is preserving meaning when a useful passage is extracted from its original layout.

    An AI search pipeline does not need every word on your page to answer every query. A retrieval stage selects a limited amount of relevant material before a model composes its response. A rough working estimate of about 380 words from a page illustrates the pressure this places on information density. That estimate is not a universal page-length limit, and you should not cut a useful page to 380 words. It is a reason to make every answer block earn its place.

    Build each answer block in this order:

    1. Use a query-shaped heading. “How long does migration take?” gives the passage more retrieval context than “Migration overview.”
    2. Answer before explaining. Put the conclusion, entity, and main condition in the first paragraph. Do not spend the opening on category history or a broad market trend.
    3. Add the conditions that could change the answer. Identify the affected plan, customer type, location, version, time period, or eligibility rule.
    4. Provide extractable support. Use a short list or a genuine comparison table when the evidence contains several distinct fields.
    5. End with the decision or next action. Restate the practical implication without copying the opening sentence word for word.

    A strong opening paragraph should answer one question completely enough to quote, but not pretend the answer has no qualifications. For example, a software migration section should identify what is being migrated, which starting environment the estimate covers, what the estimate includes, and which dependency can extend it. Moving those conditions into a distant note makes the opening easier to read but less safe to extract.

    Front-loading does not mean repeating the target phrase or turning every heading into a minor variation of the same question. Give each section a distinct retrieval job. One section can define the service, another can establish eligibility, another can explain cost, and another can describe implementation. If two sections would return the same answer, merge them.

    Write portable claims, not context-dependent fragments

    A complete information module and its linked condition, unit, time, and source symbols travel together inside a transparent capsule as incomplete fragments dissolve behind it.

    AI retrieval breaks a page into passages. A sentence that feels clear after three introductory paragraphs may become ambiguous when it is the only sentence returned. The most important facts therefore need to work as portable assertions.

    The practical language pattern is a semantic relationship: subject, predicate, and object, followed by any conditions that control the claim. “The Atlas Enterprise plan supports SAML single sign-on for accounts managed through the enterprise console” identifies the plan, states the relationship, names the capability, and preserves the relevant scope.

    The following examples illustrate editing patterns rather than claims about real products or performance:

    ProblemFragile wordingMore extractable wording
    Missing subjectIt also supports SSO.The Atlas Enterprise plan supports SAML single sign-on.
    Entities without a relationshipSEO, paid search, content marketing.The agency uses paid-search query data to select topics for SEO landing pages.
    Detached conditionDelivery takes two business days. Restrictions apply.Metro delivery takes two business days for orders placed before the daily cutoff.
    Unsupported evaluationOur process is more reliable.The migration process requires a crawl export, redirect map, and post-launch validation.

    You do not need to remove every pronoun from the page. That would make the writing repetitive and unnatural. Apply the isolation rule to sentences carrying a definition, number, comparison, product attribute, policy, recommendation, or other claim that a search system might quote. Supporting transitions can still use normal prose.

    Use this editing sequence on every important claim:

    1. Name the subject. Replace “it,” “this,” or “our solution” with the brand, product, plan, person, process, or policy that owns the fact.
    2. Choose a relationship verb. Prefer precise verbs such as includes, costs, requires, supports, applies to, publishes, authors, or is offered by.
    3. Name the object or value. State the feature, amount, requirement, organization, audience, or outcome connected to the subject.
    4. Attach the boundary. Keep the unit, currency, billing period, location, version, audience, and time frame beside the claim.
    5. Remove unproved decoration. Words such as leading, seamless, robust, revolutionary, and best-in-class add confidence without adding a retrievable fact.

    Then run the isolation test. Copy a sentence from the middle of the section into a blank document. Ask whether a reader can identify the subject, relationship, object, and applicable conditions without seeing the preceding sentence. If any answer is no, repair the sentence rather than assuming the heading will always travel with it.

    Read the repaired paragraph aloud as a final check. Machine clarity should come from explicit relationships, not from repeating the full product name in every line. Once the key claim is anchored, nearby explanatory sentences can vary their rhythm.

    Build a connected entity graph instead of isolated schema

    A webpage plane connects to several symbolic entities, with a matching layer of structured-data nodes aligned beneath the same network.

    JSON-LD gives machines a second representation of facts that people can already see on the page. Its most useful role in AI search is disambiguation: identifying which organization published the page, which person wrote it, which product owns a price or feature, and how those entities connect.

    Google Search confirmed in April 2025 and Microsoft Bing confirmed in March 2025 that structured data helps their search and AI systems understand content. The position is less certain for ChatGPT, Perplexity, and other AI search products because their public crawling and extraction descriptions have not established whether page-level JSON-LD is preserved and used throughout retrieval.

    That uncertainty matters. Sites with extensive schema did not consistently earn more citations in a December 2024 citation comparison. A separate February 2024 extraction experiment found that LLMs handled defined, structured fields more accurately than open-ended input. The defensible conclusion is narrow: structure can improve interpretation and extraction accuracy when a system uses it, but schema presence is not a citation switch.

    Connect the entities that establish identity and responsibility

    A page-by-page schema object often repeats names without proving that the “Jane Doe” on one page is the same person elsewhere. Stable @id values let multiple pages refer to one persistent entity. Build the graph in this order:

    1. Create one Organization node. Give the brand a permanent @id, such as the canonical domain followed by #organization, and reuse that identifier across the site.
    2. Create one Person node per author. Give each author a stable @id and connect the Person to the Organization through worksFor when that relationship is accurate.
    3. Create an Article or BlogPosting node for the page. Connect author to the Person @id and publisher to the Organization @id. Keep the headline and other properties consistent with the visible page.
    4. Connect commercial entities to their owner. Use Product or Service where appropriate, and connect the offer or service to the responsible Organization rather than repeating an unlinked organization name.
    5. Use FAQPage only for genuine visible questions and answers. Markup should describe content available to the reader, not create a hidden answer layer that says something different.

    Maintain a small entity registry outside individual page drafts. Record each entity’s canonical name, @type, @id, owner, and the templates that reference it. This prevents an author from acquiring a new identifier on every article and stops a brand from being represented as several anonymous Organization objects.

    Keep prose, visible data, and JSON-LD in agreement

    Machine readability fails when the page contains several competing versions of the same fact. A product name in the heading, a shorter name in the body, a legacy name in JSON-LD, and a different name in navigation create an entity-resolution problem that more markup will not solve.

    • Use the same canonical entity name in visible copy and structured data, while reserving abbreviations for clearly introduced aliases.
    • Assign one stable @id to each real entity and reference that ID instead of recreating nested anonymous copies.
    • Make each attribute belong to the correct node. A price belongs to an offer or product context; authorship belongs to the content item and Person; publishing responsibility belongs to the Organization.
    • Update visible content and JSON-LD together when a price, plan name, author relationship, or product status changes.

    Schema cannot compensate for an unsupported claim, weak topical coverage, or an inaccessible page. It can make a good page less ambiguous. That narrower job is still valuable because it is controllable and useful to platforms that consume structured data.

    Run a machine-readability audit before publishing

    Do not stop at a schema validator. Validation can show that the syntax fits a vocabulary, but it cannot tell you whether an extracted paragraph remains accurate or whether the live URL exposes the content an AI system needs.

    1. Test URL access. Open the live URL through an LLM agent or another crawler-like reader. Confirm that the primary answer, headings, author, and important attributes are present without a click, login, or client-side interaction.
    2. Test the page without its hero. Scroll until the banner and introductory layout disappear, then begin reading. Mid-page sections should identify their own topic instead of relying on the page title for all context.
    3. Test the opening answer. Read only the first paragraph under each important heading. Verify that it answers the heading and contains the primary entity and decisive condition.
    4. Test sentence isolation. Copy a factual sentence from the middle of each core section. Repair any missing subject, dangling pronoun, detached qualifier, or unexplained abbreviation.
    5. Test entity relationships. Identify the subject, relationship verb, and object in every claim you want quoted. A list of related keywords does not establish how those entities interact.
    6. Test structured-data continuity. Check that Organization, Person, content, Product, and Service nodes reuse their registered @id values and point to one another correctly.
    7. Test factual parity. Compare names, relationships, prices, eligibility rules, dates, and other attributes across visible copy and JSON-LD. Resolve conflicts before publication.

    Use a five-point editorial scorecard

    Give the page one point for each passing lens in this five-part utility check. A zero identifies an editing task; the total is not a predicted citation rate.

    • Structural fitness: Do headings create a clear hierarchy in which each section answers a distinct question?
    • Information density: Does each paragraph contribute a fact, condition, explanation, example, or decision rather than repeating a broad benefit?
    • Extractability: Can important statements survive without the preceding paragraph, visual layout, or an unresolved pronoun?
    • Entity completeness: Are the relevant people, organizations, products, services, attributes, and relationships explicitly named?
    • Natural language quality: Does the page remain clear and pleasant for a person after the entities and conditions have been made explicit?

    Separate this quality-assurance score from visibility measurement. URL access, sentence isolation, entity consistency, and markup continuity are conditions you can inspect directly. AI citations are non-deterministic outcomes. Measure them with a fixed set of real audience questions, and record the engine, prompt, date, cited URL, and answer context. A single appearance or disappearance is not enough to prove that one edit caused the change.

    We’d start with one page that already contains genuine expertise but buries its answer. Rewrite the first answer block, repair its portable claims, connect its entity graph, and load the live URL as an agent would. Once that page passes the audit, turn the successful structure into an editorial and schema template for the rest of the site.

    References


  • How to Earn AI Search Citations and Build Brand Visibility

    How to Earn AI Search Citations and Build Brand Visibility

    Your page can rank well in traditional search and still be absent when an AI assistant answers the same question. That gap is not necessarily a content-quality failure. AI systems retrieve many possible sources, cite only a small fraction, and repeatedly favor a limited set of domains.

    You need to solve two related problems: make the right page useful enough to cite, and make your brand clear enough to recognize and trust. The practical work spans query coverage, format, answer placement, entity evidence, and measurement.

    Compete for a citation set, not one blue-link ranking

    Retrieval is not the same as citation. About 85% of the pages retrieved for ChatGPT responses were not cited. Within a topic, roughly 30 domains shared about 67% of citations. The concentration was especially visible for product comparisons, where the top 10 domains captured about 46% and the top 30 captured 67%.

    A high Google position still helps, but it does not reserve a place in the answer. Pages ranking first were cited in 43.2% of the analyzed cases. That was 3.5 times the citation rate of pages beyond the top 20, yet most number-one pages still were not cited.

    The ChatGPT pattern is based on roughly 98,000 citation rows from about 1.2 million responses. Treat those numbers as directional benchmarks, not universal thresholds. Citation behavior can differ by model, query intent, industry, and the other sources available for a particular answer.

    This changes the unit of content planning. A conventional keyword brief often targets the most visible wording of a question. An AI system can fan that question out into narrower grounding queries covering definitions, alternatives, eligibility, risks, features, or comparisons. Some cited pages were discovered through fan-out queries with no recorded search volume, so a zero-volume subquestion is not automatically a zero-value topic.

    Build a query-family map before you edit anything:

    1. Write the broad decision or problem your audience brings to an AI assistant.
    2. List the follow-up questions needed to answer it responsibly: what it is, who it is for, how options differ, what the limitations are, and what someone should do next.
    3. Label each question informational, commercial, transactional, or navigational.
    4. Assign every intent to an existing page or a clearly justified new page. Do not create a near-duplicate URL for every prompt variation.
    5. Link the pages as a topic cluster so the central guide, comparisons, product or service pages, and brand information reinforce one another.

    The result should be broad coverage without repetition. One strong page can answer several closely related grounding queries. A cluster is useful when the reader’s task genuinely changes, not when it merely gives you more URLs to publish.

    Match the page format to what the user is trying to do

    Four symbolic user tasks lead to different blank page layouts for instructions, comparison, category selection, and explanation.

    Content type matters, but intent is the stronger planning signal. Across 75,000 AI answers and more than one million citations, listicles received 21.9% of citations, articles 16.7%, and product pages 13.7%. Together, those three formats accounted for more than 52%. The useful lesson is not that every brand needs more listicles. It is that each page should perform the job implied by the query.

    Query intentFormat signal in the analyzed answersWhat your page needs to accomplish
    InformationalArticles received 45.5% of citations, followed by listicles at 21.7%.Explain the subject directly, define its scope, answer related questions, and make important qualifications easy to find.
    CommercialListicles received 40.9% of citations.Help the reader compare options using explicit criteria, trade-offs, suitable use cases, and a clear method for choosing.
    Transactional or navigationalProduct and category pages together represented about 40% of citations.Confirm exactly what is offered, organize available choices, and connect the requested action to accurate product or service facts.

    An informational article should not hide its answer behind a product pitch. A product page should not imitate a neutral comparison while omitting alternatives and trade-offs. A commercial page should give the reader a defensible comparison method rather than a list of brands ordered to suit the publisher.

    Neutrality becomes particularly important when someone asks for a recommendation. In professional services, third-party listicles accounted for 80.9% of citations. A company’s self-authored list of the best providers cannot carry the same independence as a genuinely editorial comparison.

    You cannot manufacture that independence on your own domain. You can make your offering easier for credible third parties to evaluate: publish accurate category and product facts, maintain a clear entity home, correct outdated public information, and earn relevant coverage or inclusion through legitimate public-relations work. Do not disguise advertising as independent analysis; it weakens the very corroboration you are trying to build.

    Model differences also prevent one format from becoming a universal recipe. ChatGPT leaned toward articles and informational content in the analyzed sample, Google AI Mode had a more balanced mix, and 17% of Perplexity citations came from discussions such as forums and Reddit. Prioritize the platforms your audience actually uses, then inspect their answers instead of assuming that a page cited by one system will be preferred by all of them.

    Put the quotable answer near the top, then earn the depth

    Where you place information can matter as much as how much you publish. ChatGPT citations appeared most often in the 10% to 20% portion near the beginning of a page, while the final 10% received little recognition. If the conclusion, key distinction, or decisive comparison appears only after several screens of setup, it is harder for both readers and retrieval systems to identify the passage that answers the question.

    Use the opening portion of a citation-targeted page deliberately:

    1. Answer the primary question in the first few sentences. State the scope and any qualification that would materially change the answer.
    2. Place the essential definition, decision criteria, or comparison immediately after that answer.
    3. Use descriptive headings that correspond to real follow-up questions. A heading such as “When this option is unsuitable” carries more meaning than “Other considerations.”
    4. Support factual claims where they appear. Do not separate a bold claim from its explanation or evidence by several sections.
    5. Expand into examples, edge cases, alternatives, and implementation details only after the reader can understand the core answer.
    6. Do not save a new, essential conclusion for the closing paragraph. The close should help the reader act on information already established.

    Longer content often earns more citations, but raw length is a poor production target. Pages with 5,000 to 10,000 characters showed a substantial lift, while pages above 20,000 characters averaged 10.18 citations compared with 2.39 for shorter pages. That relationship does not prove that adding characters creates citations. Comprehensive pages are also more likely to answer the related subquestions generated during retrieval.

    The pattern varies by subject. Shorter, information-dense finance pages could outperform long guides, while longer pages retained their value in education, crypto, and product analytics. Let the query family determine the necessary depth. Remove repetition, but do not cut a necessary distinction merely to hit an arbitrary length.

    Structured data belongs after this editorial work, not in place of it. JSON-LD can clarify the page type, entity, and relationships already expressed in the visible content. It cannot supply substance or independent credibility that the page lacks. Make the markup match the copy exactly; if the schema asserts a different name, category, offer, or relationship, repair the underlying information rather than adding more markup.

    Give your brand one stable identity anchor

    A glowing geometric keystone connects to blank website, profile, product, directory, and knowledge cards that share the same visual motif.

    A useful page can answer a question while leaving the publisher poorly understood. Brand visibility requires a second layer: a stable place where people and machines can resolve who the brand is, what it does, and which claims about it are supported.

    This identity anchor is often called an entity home. It may be an About page, but the label is not important. Choose the durable URL that most clearly defines the organization. It should remain available long enough to become the consistent reference point for your brand’s identity.

    Audit that page for five things:

    • A single, consistent brand name and an immediate explanation of what the organization does.
    • A clear description of the people or organizations it serves and the categories in which it operates.
    • Links to the relevant product, service, editorial, policy, or evidence pages that substantiate important claims.
    • Visible facts that agree with the Organization schema and other structured data associated with the brand.
    • Claims that credible third parties can corroborate, rather than unsupported superlatives repeated only on properties the brand controls.

    Think of every important brand claim as a three-part chain. The entity home defines it. A relevant first-party page explains or proves it. Independent material confirms it when independent confirmation is appropriate and available. If one part conflicts with another, the entity becomes harder to resolve.

    For example, do not describe the business with one category on the entity home, another in page titles, and a third in external profiles. Decide which description is accurate, update the pages you control, and seek corrections where material third-party information is demonstrably outdated. Consistency should reflect reality; it is not a reason to repeat an inflated claim more widely.

    The entity home is an anchor, not the whole brand narrative. Supporting pages still need to explain individual offerings, expertise, comparisons, and evidence in enough detail to answer the corresponding queries. The identity page tells a system which entity it is dealing with; the rest of the site demonstrates why that entity belongs in a particular answer.

    Measure the query-to-page relationship, then improve one variable

    AI citation visibility is many-to-many. One grounding query can cite several pages, and one page can support several grounding queries. A report containing separate lists of queries and URLs cannot show whether the correct page is appearing for the intended question.

    Bing Webmaster Tools now connects those two sides in its AI Performance reporting. You can select a grounding query to see its cited pages or select a page to see its associated grounding queries. The dashboard also provides cited URLs and visibility trends across Bing and Copilot experiences.

    Turn that mapping into a repeatable optimization workflow:

    1. Record the grounding queries, cited URLs, and current visibility trend for one commercially or strategically important query family.
    2. Label each query by intent and each URL by its proper role: informational article, comparison, product or category page, or entity page.
    3. Check the fit. A citation is less useful diagnostically if a general About page appears where a detailed product page should answer the question.
    4. Inspect missing relationships. Look for relevant queries with no suitable owned page, strong pages connected to unrelated queries, and important subquestions answered only deep in a page.
    5. Choose one meaningful change: correct the format, strengthen the opening 20%, add a genuinely missing subtopic, resolve an unsupported brand claim, or improve links within the topic cluster.
    6. Record the change and compare the mapping and trend in a later reporting cycle. Avoid rewriting several pages at once when you want to learn which intervention mattered.

    Do not reduce the work to a total citation count. Track whether the brand appears for the right query families, whether the cited URL matches the user’s intent, and whether important brand claims have independent support. Keep conventional search performance and business outcomes alongside those measures. A citation is visibility, not proof that the visitor understood the answer or completed a valuable action.

    Key takeaways

    • Ranking helps citation eligibility, but a number-one position does not guarantee inclusion in an AI answer.
    • Plan around query families and fan-out questions, including useful subquestions that conventional keyword tools may show as zero volume.
    • Match the format to intent: articles for explanation, list-based comparisons for commercial evaluation, and product or category pages for transactional and navigational needs.
    • Place the direct answer and decisive criteria near the beginning. Add length only when it supplies relevant coverage.
    • Use an entity home, consistent first-party facts, structured data, and credible third-party corroboration to make the brand easier to resolve.
    • Measure query-to-page mappings so you improve the page associated with the actual AI demand rather than guessing from aggregate visibility.

    Start with one query family where absence from AI answers matters to the business. Assign the right page to each intent, rewrite the most important page from the top down, and repair the corresponding claims on your entity home. Once the query-to-page mapping improves, apply the same process to the next cluster.

    References


  • How to Build an AI Search Visibility Content Strategy

    How to Build an AI Search Visibility Content Strategy

    Your traffic can fall while your content becomes more influential. That sounds contradictory only if a visit is your sole unit of search success. People increasingly receive answers inside search results, AI interfaces, videos, forums, and social feeds, and many of those interactions never produce a website session.

    Your job is not to abandon SEO or publish on every platform. It is to make your site the dependable source for a valuable decision, carry that knowledge into the environments where the decision happens, and measure whether your facts shape the answer. That requires a different content system, not merely more content.

    Replace the traffic-only scorecard with an answer footprint

    Organic sessions still matter. They show that someone reached property you control, where you can explain the full case and offer a next step. But sessions cannot show every place your expertise influenced discovery. Search engines can display the answer directly, AI assistants can synthesize it, and social or video platforms can satisfy the need without sending the person elsewhere.

    Measure your answer footprint across four separate layers:

    • Discoverability: Can search engines, AI systems, and people find the relevant page or platform contribution?
    • Representation: Is your brand mentioned, and are its products, methods, limitations, and positions described accurately?
    • Influence: Is your domain cited, or is knowledge associated with your brand reflected in the answer?
    • Business response: Do you see qualified visits, branded searches, leads, sales conversations, or other outcomes connected to the topic?

    Do not collapse these layers into one score. A citation without a click can still extend your influence, but it does not prove commercial value. A rise in branded demand may be meaningful even when the original exposure is invisible to your analytics. Conversely, an AI mention is not a success if the description is wrong or places your brand in an irrelevant category.

    Organize measurement around decision clusters rather than isolated keywords. A cluster might include the main question, its prerequisites, common alternatives, implementation concerns, risks, and follow-up questions. This reflects how a person investigates a decision and gives you a stable unit to compare across Google, Bing, AI assistants, YouTube, Reddit, and other relevant environments.

    Key takeaways

    • Keep traffic, citations, mentions, accuracy, and business outcomes as separate signals.
    • Give each important decision cluster one authoritative home on your website.
    • Expand onto platforms because your audience searches there or AI answers rely on them, not because the platform is fashionable.
    • Reuse the underlying knowledge, but adapt its presentation to each platform.
    • Scale a content pattern only after it shows durable discoverability, accurate representation, or business value.

    Make your website the canonical source worth citing

    Your website remains the place where you control definitions, evidence, context, updates, and conversion paths. In a zero-click environment, that role becomes more important, not less. AI-generated answers often depend on clear primary explanations from identifiable experts and organizations, even when the person reading the answer never visits the originating page.

    A canonical page should do more than target a phrase. It should make a defensible contribution that another person or system can reuse without guessing what you mean. Use this publishing checklist:

    • Answer the central question near the beginning. State the scope and any important boundary in the same passage.
    • Add information that came from the work itself: a method, calculation, test procedure, decision framework, original data, documented example, expert explanation, or clearly supported position.
    • Write self-contained claim blocks. Give each paragraph a clear subject, enough context to stand alone, and language that does not depend on a chain of vague pronouns.
    • Name entities consistently. Use the same product, organization, person, feature, and category names across the page and related properties.
    • Show provenance. Identify the author or reviewer, explain relevant expertise, display the publication or update date, and link claims to the evidence actually supporting them.
    • Connect supporting pages. Link definitions, methods, comparisons, and implementation instructions so the broader topic can be understood as a coherent body of knowledge.
    • Give the page an owner. Someone should be responsible for correcting outdated facts and reconciling changes across distributed versions.

    Structured data can clarify this page, but it cannot supply missing authority. Select the schema type that accurately describes the visible content. For an editorial page, that may include Article or BlogPosting relationships alongside the relevant Person or Organization and BreadcrumbList entities. Keep names, authorship, dates, and relationships consistent with what a reader can see. Do not mark up claims, ratings, questions, or entities that the page does not actually contain.

    Treat JSON-LD as a machine-readable identity and relationship layer. The visible page still has to carry the answer, evidence, and context. Adding more schema types to a generic page does not turn it into a primary source.

    The same distinction applies to AI-assisted writing. On new domains without established authority, AI-generated pages showed a rapid rise followed by a decline during a 16-month experiment. That pattern does not prove that all AI-assisted content will fail. It does show why an early ranking increase is not enough evidence for a mass-production strategy.

    Use AI to reduce production friction where it helps, but put every page through a source-worthiness gate before publishing. Ask whether the page contains a claim you can defend, evidence a competing summary cannot reproduce honestly, a clear task it helps the reader complete, and an update plan. If the only differentiator is wording, the page is not ready to scale.

    Match each decision to the surface where people search

    Traditional keyword research can reveal demand while still missing where that demand is expressed. People may use YouTube to learn a repair, Reddit to test a claim against lived experience, TikTok to discover a restaurant, or Amazon to narrow a purchase. Those platforms also occupy conventional search results, so ignoring them can cost visibility both inside the platform and on Google or Bing.

    The right surface depends on the task. One documented example found that the query about fixing a leaky sink faucet had 15 times more estimated global search volume on YouTube than in traditional search. That is a query-specific result, not a universal ratio. Its practical value is the routing lesson: a demonstration-led need may deserve a video before it deserves another text-only page.

    Build a surface map for every priority decision cluster:

    1. Collect the questions people use before, during, and after the decision. Draw from customer conversations, sales objections, support requests, on-site search, community discussions, and your existing search data.
    2. Run the questions on traditional search engines. Record which domains, platforms, and formats repeatedly occupy the visible results.
    3. Repeat the investigation inside the platforms that appear. Look at the language people use, the content format they choose, and the follow-up questions visible in comments or threads.
    4. Inspect representative AI answers for the same decisions. Record cited domains, uncited brand mentions, repeated claims, omissions, and inaccuracies.
    5. Choose the smallest set of surfaces that covers the decision well. Your selection should follow observed behavior, not a generic list of channels.

    Use the nature of the question as an initial routing clue. A process that must be seen usually benefits from video. A decision shaped by first-hand trade-offs may need credible community participation. A precise definition, policy, specification, or method needs a stable owned page. A complex explanation may require a detailed page plus shorter platform-native versions that help people discover it.

    Then validate the clue against actual results. Your real search competitors may be YouTube channels, Reddit communities, publishers, or marketplaces rather than businesses selling the same service. A conventional competitor list will not reveal that attention gap.

    Build an owned-and-rented publishing loop

    An isometric central content studio exchanges modular content and audience signals with several smaller publishing platforms in a circular loop.

    Your site is owned territory. A YouTube channel, Reddit account, Quora profile, social feed, or marketplace listing is rented territory. You need both, but they do different jobs. The owned page preserves the complete, maintainable version of your knowledge. Outside platforms make that knowledge available in the formats and communities where discovery already happens.

    This distribution matters for AI visibility because citations do not come only from brand websites. Across the brand examples examined in a search-everywhere analysis, nearly 90% of citations came from third-party publications, social platforms, and forums rather than the brands’ own sites or their direct competitors. That figure is illustrative, not a benchmark for every industry. It is still a strong reason to examine the citation mix in your market before concentrating the entire strategy on your domain.

    Use a publishing loop instead of copying the same text everywhere:

    1. Define the knowledge unit. Write down the claim, its evidence, the audience it serves, the decision it changes, and the limitations that must travel with it.
    2. Publish the canonical version on your site. Include the complete explanation, provenance, supporting links, entity relationships, and appropriate structured data.
    3. Translate the unit for the selected platform. Demonstrate it in a video, answer the exact community question, turn the method into a visual sequence, or expose the relevant product facts in the marketplace format.
    4. Keep identity and facts consistent. Product names, author names, category language, limitations, and key figures should not drift between versions.
    5. Link only when the destination adds genuine value. A useful community answer should remain useful without forcing a click, while the link can provide evidence, methodology, or deeper implementation detail.
    6. Maintain the network. When a material fact changes, update the canonical page first and then correct the versions you still control.

    Adaptation is more valuable than duplication. A detailed page can explain assumptions and exceptions. A video can show the process. A forum answer can address the exact situation raised by a community member. A short social contribution can isolate one useful finding and its boundary. Each version should preserve the truth while doing the job native to its environment.

    Do not try to manufacture consensus. Repeating the same brand claim through multiple controlled profiles is distribution, not independent corroboration. Fake reviews, planted recommendations, and undisclosed promotion create reputation risk and give readers a reason to distrust the underlying claim. Earn third-party reinforcement by publishing evidence others can inspect, answering real questions transparently, and giving independent experts or customers something substantive to evaluate.

    When a third-party page dominates an important result, first determine why. It may offer a format your site lacks, candid comparisons your copy avoids, stronger participation, or clearer evidence. The right response may be to improve your canonical page, contribute responsibly on that platform, or earn independent coverage. Publishing another interchangeable blog page rarely closes a format or trust gap.

    Measure visibility as a repeatable observation

    A researcher repeatedly examines conversational, search, video, and discussion interfaces through a monitoring instrument under focused light.

    AI visibility measurement is useful only when you can tell a content change from a testing change. Build a fixed prompt library for your important decision clusters. Include discovery questions, comparisons, objections, implementation questions, and branded questions where the brand is genuinely relevant.

    For every observation, record the prompt, model, mode, date, locale, account state where relevant, answer text, cited URLs, brand mentions, competitor mentions, and any factual error. Keeping these conditions visible prevents a change in model or test setup from being reported as a content gain.

    Track the following measures separately:

    • Owned citation presence: whether an answer cites a page on your domain.
    • Earned citation presence: whether an independent page cited by the answer accurately discusses your brand or knowledge.
    • Mention presence: whether your brand appears with or without a clickable citation.
    • Representation accuracy: whether the claims, categories, capabilities, limitations, and comparisons attached to your brand are correct.
    • Platform visibility: whether your useful contribution is discoverable inside the outside platforms selected in your surface map.
    • Traditional search response: whether the canonical page and relevant platform assets gain visibility for the decision cluster.
    • Business response: whether branded demand, qualified direct visits, assisted conversions, leads, or sales feedback move in a useful direction.

    Keep a saved example behind every status. A yes-or-no citation field is easy to audit. An accuracy label should point to the exact sentence evaluated. A message-alignment field should identify which desired claim appeared, which was distorted, and which was absent. This makes the scorecard a work queue rather than a decorative dashboard.

    Prioritize corrections by consequence. Fix harmful inaccuracies first. Then address high-value decisions where your brand is absent, misunderstood, or supported only by weak third-party material. After that, expand the patterns already producing accurate citations, useful platform visibility, qualified visits, or sales evidence.

    Do not average citations, rankings, traffic, and revenue into one synthetic percentage. They describe different stages of discovery. The useful analysis is the connection between them: which canonical claims gained visibility, where they were repeated, how accurately they were represented, and whether the audience responded.

    Start with the decision cluster closest to revenue, reputation, or a recurring customer misunderstanding. Audit its current answer footprint, strengthen the canonical page, and choose the outside surface with the clearest evidence of demand. Capture the baseline before publishing. If you cannot yet name the source-worthy claim you want others to reuse, solve that knowledge gap before increasing production.

    References

  • How to Find and Close Law Firm Referral Conversion Gaps

    How to Find and Close Law Firm Referral Conversion Gaps

    A trusted contact recommends your firm by name. The prospective client sounds ideal. Then nothing happens. They never call, or they start an inquiry and disappear before scheduling.

    That does not necessarily mean the referral was weak. Before contacting you, the prospect may search for the firm, inspect a lawyer’s profile, look for experience with the exact legal issue and ask an AI assistant for another opinion. Your digital presence and intake process must confirm the trust transferred by the referrer. If either introduces doubt, a strong referral can lose momentum.

    Key takeaways

    • A referral earns serious consideration, not an automatic consultation or engagement.
    • Most referral losses can be investigated as credibility, specificity, authority or friction gaps.
    • The best validation page mirrors the precise reason the firm was recommended, identifies the relevant lawyer and offers an obvious next step.
    • JSON-LD can clarify the relationship among the firm, its lawyers, locations and services, but it cannot compensate for vague or unsupported claims.
    • Measure each handoff separately so you can distinguish a marketing problem from an intake, qualification or scheduling problem.

    A referral starts a validation journey, not a straight line

    The referrer has already done valuable work. They have transferred some of their credibility to your firm and given the prospect a reason to pay attention. But the prospect still has questions: Does this firm really handle my kind of matter? Is this the lawyer I was told about? Does the firm’s public record support the recommendation? Can I see what to do next?

    The difference between what the prospect was promised and what they can corroborate is a referral validation gap. It appears after the recommendation but before a productive conversation with the firm. That location matters. If you only examine retained clients or completed intake forms, the people who vanished during validation remain invisible.

    Think of the journey as a sequence of trust handoffs:

    1. Recommendation: Someone associates your firm with a specific problem, lawyer or result they believe you can pursue.
    2. Verification: The prospect checks your website, search results, professional profiles, reviews or AI-generated answers.
    3. Contact: They decide whether the available evidence justifies a call, form submission or consultation request.
    4. Intake: Your team confirms fit, handles the inquiry and establishes the appropriate next step.
    5. Engagement: The prospect makes a separate decision about retaining the firm under the applicable terms.

    A break at one stage should not be blamed on another. A prospect who cannot find the recommended practice on your website has a validation problem. Someone who starts a form but abandons it has encountered friction. A qualified caller who waits without knowing what comes next has an intake problem. Treating all three as a generic conversion issue leads to unfocused redesigns and more content that does not answer the original doubt.

    Start by reconstructing the promise that brought the prospect to you. Review referral notes, intake records and the language your lawyers hear from frequent referral partners. You are looking for the actual expectation: a named lawyer, a narrow matter type, a particular client situation, a location or a combination of these. That expectation becomes the standard against which the public journey is audited.

    Diagnose the four places trust can break

    A prospective client moves through four connected spaces representing a firm entrance, lawyer profile, legal consultation and intake desk.

    Referral losses become easier to fix when you classify the first point of doubt. The four useful categories are credibility, specificity, authority and friction. They can overlap, but one usually appears first in the prospect’s journey.

    GapQuestion in the prospect’s mindWhat to inspectFirst repair
    CredibilityDoes this look like the firm I was promised?Firm and lawyer names, current biographies, office details, visible credentials, page condition and consistency across profilesMake identity, relevant credentials and contact information immediately clear and consistent
    SpecificityDo they handle my exact kind of matter?Page titles, headings, service descriptions, lawyer experience, examples and answers to matter-specific questionsCreate or improve a page that addresses the recurring referral reason in the prospect’s language
    AuthorityCan anything outside this recommendation confirm the expertise?Professional profiles, third-party mentions, search results, AI answers, entity consistency and structured dataCorrect public facts, connect corroborating profiles and make supported claims machine-readable
    FrictionHow do I take the next step, and what will happen?Mobile navigation, phone links, form fields, required information, confirmation messages, routing and follow-upOffer one clear action, request only what intake needs and set an accurate expectation for the response

    A credibility gap is not merely an unattractive design. It can be a former lawyer still presented as current, inconsistent firm names, an incomplete biography, an office address that conflicts with another profile or credentials buried below generic promotional copy. Correctness and recognizability matter more than visual novelty.

    A specificity gap often hides behind a technically accurate but broad practice page. A prospect referred for a narrow commercial dispute does not receive much reassurance from a heading that only says commercial litigation. They need enough detail to recognize their situation and understand why the named lawyer or team is relevant. You do not need to predict the merits of an individual case. You do need to show that the category is familiar.

    An authority gap appears when your own claim has no accessible support. A biography may call a lawyer experienced, but search results, professional listings and publicly retrievable material do not connect that person to the matter. AI systems may then omit the firm, confuse lawyers with similar names or repeat incomplete information. Structured data can clarify supported facts, but independent corroboration still matters.

    A friction gap happens after the prospect is persuaded enough to act. Common symptoms include an unclear primary call to action, a form that asks for more information than initial triage requires, a phone number that is difficult to use on mobile, no confirmation that a request arrived or no explanation of what follows. These details are especially costly because the person has already crossed the harder trust threshold.

    Audit the journey from the prospect’s side. Search the firm name, the referred lawyer and the specific issue. Repeat the check on mobile. Inspect the landing page a searcher is most likely to reach rather than starting from the homepage. Ask representative questions in the AI interfaces your audience may use, then record whether the firm appears, whether the description is accurate and which public information seems to support the answer. The first material contradiction or missing answer is usually the most valuable repair.

    Build a page that confirms the exact referral promise

    Your homepage cannot validate every referral. Its job is orientation. A referral-specific service page, lawyer biography or focused landing page should do the confirming.

    Build these pages around recurring referral reasons, not every keyword variation you can imagine. If several trusted contacts send people to a particular lawyer for a defined kind of matter, the site should provide a short path connecting that lawyer, that problem and the next step. The page needs to answer the prospect’s validation questions in a sensible order:

    1. Match the expectation in the heading. Name the specific service or problem clearly. A prospect should not have to infer it from a broad department label.
    2. Define the relevant scope. Explain the kinds of situations the page covers, the clients it serves and any geographic or jurisdictional boundary needed to understand the offering.
    3. Identify the responsible lawyer or team. Link to current biographies and make each person’s role clear. Do not force the visitor to search the staff directory again.
    4. Show support for the claim. Use accurate credentials, representative experience, authored material, speaking activity or other evidence the firm is permitted to publish. General praise is not evidence.
    5. Explain the next step. State what the prospect can request, what information is appropriate to share initially and what happens after submission.
    6. Provide one dominant action. Make the consultation request, call or other intake route easy to find and use on the device in the visitor’s hand.

    The opening screen should carry most of the recognition work. Include the matter, the relevant lawyer or team where appropriate, the firm identity and a clear action. Awards, office photography and general brand language can support that information, but they should not displace it.

    Specific content needs boundaries as much as detail. State what the service covers without suggesting that every visitor has a viable claim or that an outcome is assured. Do not turn a landing page into individualized legal advice. Before publishing testimonials, awards, representative matters or response commitments, have the responsible lawyer verify accuracy, permissions, confidentiality and the professional-advertising rules that apply in each relevant jurisdiction.

    Internal links should preserve the same chain of meaning. A lawyer biography should link to the specific service. The service page should link back to the lawyer. Relevant educational content should identify its author and lead to the appropriate intake route. Breadcrumbs and navigation should make the broader practice relationship understandable without forcing the prospect back through the homepage.

    Do not publish a page and assume the wording matches the referral. Read it next to the expectation you reconstructed. If the referral promise is about a named lawyer handling a narrow issue but the page leads with a generic firm slogan, the gap remains. The test is not whether the page sounds polished. It is whether a prospect can say, with minimal interpretation, that they reached the right firm for the reason they were given.

    Make your authority readable by people, search engines and AI

    Your reputation may be obvious inside a professional network and nearly invisible outside it. Search engines and AI answer systems work from accessible information, not private referral history. They need consistent entities, explicit relationships and public evidence that supports the firm’s claims.

    Begin with the visible facts. Use the same current firm name, lawyer name, office information and service terminology across the website and maintained third-party profiles. Correct old biographies and duplicate location records. Link to authoritative professional profiles where appropriate. A citation, directory entry or publication byline should corroborate a real fact, not exist merely to increase the number of mentions.

    Then use JSON-LD to describe what the page already says. Depending on the page and the facts available, Schema.org types such as Organization or LegalService can represent the firm, Person can represent an individual lawyer, and BreadcrumbList can describe the page’s place in the site. Stable @id values can connect those entities across pages. Relevant properties may describe the canonical URL, contact details, address, service area and maintained profile links.

    The governing rule is simple: markup must mirror visible, accurate content. Do not use structured data to manufacture an award, specialty, review, office, service area or affiliation that a visitor cannot verify. Do not add an FAQ entity unless the questions and answers are actually present on the page. Schema can reduce ambiguity; it cannot turn an unsupported assertion into authority or guarantee that an AI system will mention the firm.

    Use this sequence when reviewing the implementation:

    1. Choose the canonical page for each firm, lawyer, office and recurring service concept.
    2. Confirm that its visible text is complete, current and approved.
    3. Assign only Schema.org types that accurately describe the entity represented on that page.
    4. Give each important entity a stable identifier and connect related entities rather than creating isolated markup fragments.
    5. Validate the syntax and compare every material property with the visible page.
    6. Recheck the output after biography, office, service or branding changes.

    AI visibility needs its own audit, but not a one-off vanity search. Create a controlled set of questions based on genuine referral language. Include branded verification questions, lawyer-and-matter questions and unbranded service questions. Record the interface or model, the wording, the date, the answer, the firms mentioned and the cited or linked evidence when the interface provides it.

    Answers can vary by system, session and available retrieval, so one favorable response is not a ranking report. Look for repeated failure patterns instead. If the system recognizes the firm but assigns the wrong service, fix entity and content clarity. If it recognizes the service but not the relevant lawyer, strengthen that connection on both pages and in the markup. If competitors are consistently supported by clearer third-party evidence, the missing layer is authority rather than another rewrite of your homepage.

    Remove intake friction and measure each handoff

    A prospective client and intake specialist use a smartphone and appointment calendar at a tidy desk beside an open consultation room.

    A validation path is unfinished until a persuaded prospect can act. The intake experience should preserve the context and confidence built by the referral rather than making the person start over.

    Use an action label that tells the prospect what they are requesting. Make phone numbers usable on mobile. Keep the initial form to information the team truly needs for routing and conflict or fit screening. Avoid inviting detailed or highly sensitive case facts into a general web form; move that exchange to an appropriately secure, approved process. The confirmation screen and message should acknowledge receipt, state the response window the team can reliably meet and avoid implying that submission alone creates an attorney-client relationship.

    Preserve referral context in the handoff. An optional referral-source field can help, but do not depend on the prospect knowing a formal organization or campaign name. Pass the landing page and selected service into the intake record when your privacy practices and systems permit it. If a receptionist or intake specialist receives the inquiry, they should be able to see the matter category and the lawyer or page that prompted the contact.

    Measure the journey as separate stages:

    • Referral identified
    • Relevant validation page reached
    • Contact action started
    • Contact completed or call connected
    • Inquiry screened as an appropriate fit
    • Consultation offered and scheduled
    • Engagement completed

    You will not be able to identify every referred visitor before they contact you. Use observable cohorts honestly: dedicated partner links without personal information, referral landing pages, a voluntary intake field, call-source notes or another privacy-appropriate mechanism. Do not inflate the denominator with visitors whose source you cannot establish.

    The useful rates correspond to different decisions. Contact completion rate compares completed inquiries with started contact actions. Qualified consultation rate compares scheduled consultations with referred inquiries that met the firm’s criteria. Engagement rate compares opened matters with completed referred consultations. Keep definitions stable so a change in intake labeling does not masquerade as a conversion improvement.

    Read the drop-off pattern before choosing a fix:

    • Validation-page visits are visible but contact actions are scarce: inspect credibility, specificity and authority before redesigning the form.
    • Form starts are healthy but completions are weak: inspect required fields, error handling, mobile usability, privacy concerns and unclear expectations.
    • Inquiry volume is healthy but fit is poor: align the page and referrer-facing language with the matters the firm actually accepts.
    • Qualified inquiries do not become scheduled consultations: inspect routing, response handling, availability and the clarity of the next step.
    • Consultations occur but engagements do not: examine expectation-setting and the consultation process instead of attributing the loss to website traffic.

    Referral traffic is often too limited or uneven for a rapid A/B test to produce a dependable answer. Use the evidence you actually have. Establish a baseline, fix the earliest known break, annotate the change and compare the same stage over an appropriate later period. Pair the numbers with intake notes and reasons for loss. A smaller, clearly defined cohort is more useful than a large blended conversion rate covering unrelated practices and acquisition channels.

    Start with one valuable, repeatable referral path. Write down the promise, reproduce the prospect’s verification journey and fix the first place your public presence fails to confirm it. Once that path is coherent from recommendation through intake, turn its page structure, entity connections and measurement stages into a template for the next referral category.

    References


  • Google Shopping AI Overviews: A Practical Ecommerce Plan

    Google Shopping AI Overviews: A Practical Ecommerce Plan

    Your ecommerce rankings can look stable while the search journey changes above them. When an AI Overview answers a product question, compares options, or frames the buying decision, your organic result and Shopping placement may have to compete for attention later than they used to.

    This is no longer a fringe scenario. AI Overviews appeared on 2,919,229 of 20,900,323 shopping-related queries in a large visibility analysis. If product discovery matters to your revenue, you now need to audit AI Overview exposure alongside rankings, Shopping visibility, clicks, and conversions.

    What the 14% figure should change in your strategy

    The headline number needs a precise reading. The keyword set consisted of product-intent searches whose results contained a Shopping box, whether paid or organic. Queries included products and categories such as weighted blankets, mushroom coffee, protein powder, and blue T-shirts. Within that defined set, 14.0% produced an AI Overview.

    That does not mean every ecommerce site lost 14% of its traffic. It does not measure click loss, revenue loss, AI Overview citations, or the percentage of shoppers who saw the feature. It measures how often the feature appeared across the monitored keyword set. Treating penetration as a traffic-loss estimate would turn a useful warning signal into a bad forecast.

    The direction is still hard to dismiss. Penetration had been 2.1% in November 2025 before reaching 14.0% in the later sample. The practical implication is that ecommerce exposure cannot be judged from ten blue links, conventional rankings, or Shopping positions alone.

    Your first response should be measurement, not a sitewide rewrite. Establish which valuable queries trigger AI Overviews, whether your brand or pages appear in them, and what happens to clicks when they do. Until you separate those questions, you cannot tell whether you have an inclusion problem, a click-through problem, or no material problem at all.

    Key takeaways

    • The 14.0% figure describes AI Overview penetration within a large set of product-intent queries that also returned a Shopping box. It is not a universal ecommerce traffic-loss rate.
    • Audit exposure by query intent and commercial value. A high-value comparison query deserves more attention than dozens of low-value searches combined.
    • Keep visible product information, JSON-LD, and commerce feeds consistent. Structured data can clarify facts, but it cannot guarantee AI Overview inclusion.
    • Measure AI Overview presence, brand inclusion, organic click-through rate, and conversion separately. A single visibility score cannot diagnose all four.
    • Improve the pages that already match exposed queries before producing large volumes of new content.

    Map AI Overview exposure by query intent and value

    Three search pathways pass through a translucent AI layer, leading to a single product, a product comparison, and a shopping basket.

    A useful audit starts with the searches that already matter to your business. Export product-intent queries from Google Search Console, add priority terms from your keyword tracking, and connect each query to its most relevant category or product page. Include revenue or conversion value where you have it.

    Do not examine this as one undifferentiated keyword list. Label the job the shopper is trying to complete. The page requirements are different when someone is exploring a category, narrowing by an attribute, comparing alternatives, or verifying a particular product.

    Query patternShopper’s taskWhat the landing page should make clearCommon audit question
    Broad category, such as weighted blanketsUnderstand the category and available choicesScope, meaningful differences, selection criteria, and routes to relevant productsDoes the page help someone choose, or does it merely repeat the category name?
    Attribute-led, such as blue T-shirtsNarrow the catalog using a required featureMatching products, visible attributes, filters, variants, and accurate availabilityDo the page title, copy, filters, products, and structured data agree?
    Comparison or best-fit queryChoose between optionsFactual differences, limitations, intended use, and a defensible basis for comparisonCan every comparative claim be verified on the page?
    Branded or model-specific queryConfirm exact product detailsName, brand, model, identifiers, price, availability, variants, and offer detailsAre facts consistent across the visible page, markup, and feed?
    Use-case queryJudge whether a product fits a particular needSupported suitability information, constraints, specifications, and relevant alternativesDoes the page answer the use case without making claims the evidence cannot support?

    For every tracked query, record whether an AI Overview appears, which pages or products it includes, whether your brand is visible, the result type around it, and the observation context. Search results can vary by device, location, and observation time, so save those details instead of treating one check as permanent.

    Also distinguish an AI Overview from the Shopping box used to define the original keyword set. They are separate search features. Record whether the Shopping element is paid or organic when your tooling exposes that distinction, and avoid attributing every change in click-through rate to the AI Overview.

    Prioritize the intersection of commercial value and exposure. Start with queries that contribute meaningful impressions, clicks, sales, or assisted conversions and repeatedly show an AI Overview. A long list of exposed keywords is less useful than a short list tied to products and categories you can improve.

    Make product information easy to verify and reuse

    A generic countertop appliance is surrounded by dimension, material, packaging, warranty, and image symbols connected to blank search and storefront panels.

    AI-search optimization for ecommerce is not a request to turn every product page into an essay. It is a data-quality and decision-support problem. Your pages should make important product facts explicit, keep them consistent across systems, and answer the questions that determine whether a shopper considers the product relevant.

    Give category pages a decision-making job

    A category page should do more than display a grid. Add concise information that helps a shopper understand the range and move toward a suitable option. The right content depends on the category, but the audit can use the same questions:

    • Is the category defined clearly enough to distinguish it from adjacent categories?
    • Are the attributes that genuinely change the buying decision explained in plain language?
    • Can the shopper identify which product groups fit different needs, constraints, or preferences?
    • Do links lead directly to useful subcategories, filters, comparisons, or products?
    • Are limitations and eligibility conditions visible where they affect the choice?

    Keep this material specific to the products on the page. Generic buying-guide copy creates words without resolving uncertainty. If a paragraph could be pasted onto a competitor’s category unchanged, it is probably not carrying enough product information to help either the shopper or a retrieval system.

    Reconcile the product page, JSON-LD, and feed

    Review each priority product as one record expressed through several surfaces. The visible page is what a person reads. Product and Offer structured data describe machine-readable facts. A commerce feed may supply another version of the same product and offer information. Contradictions among those surfaces create ambiguity you can remove.

    Check the product name, brand, model, stable identifiers such as SKU or GTIN when available, variant attributes, price, currency, availability, and offer details. Use the same canonical facts everywhere. If the displayed price changes by variant, make that relationship clear rather than exposing one value in the page copy and another in JSON-LD or the feed.

    Structured data should describe information that is accurate and supported by the page. Do not add properties merely because they look relevant to AI search, and do not mark up promotional, review, or availability claims that a shopper cannot verify. JSON-LD improves clarity; it is not a switch that forces Google to cite, summarize, or rank a product.

    After the core facts agree, look for unanswered decision questions. These may involve dimensions, materials, compatibility, care, included components, variant differences, usage constraints, shipping conditions, or returns. Add only what is applicable and supportable for that product. The goal is not maximum page length. It is minimum ambiguity.

    Comparison content deserves the same discipline. State the criteria, compare equivalent attributes, and separate facts from editorial judgement. Avoid unsupported superlatives. A claim such as best, safest, or healthiest needs a defensible basis; repeating it in schema does not make it more trustworthy.

    Measure visibility, clicks, and sales as separate outcomes

    An AI Overview can affect several stages of search performance, and each stage calls for a different response. Build a small measurement framework rather than compressing everything into an AI visibility score.

    • Exposure rate: the share of your monitored shopping queries on which you observe an AI Overview.
    • Inclusion rate: the share of observed AI Overviews that include your brand, product, or URL under the inclusion rule you define in advance.
    • Organic response: impressions, clicks, click-through rate, and average position for the same query cohort.
    • Commercial response: conversions, revenue, lead quality, or another outcome appropriate to the catalog and buying journey.

    Keep the monitored query set stable when comparing periods. Segment by intent, landing-page type, device, country, and approximate ranking band where the data supports it. Otherwise, a shift toward broader queries or lower organic positions can look like an AI Overview effect even when the query mix caused the change.

    When you change a template or content cluster, record the release and preserve an unchanged comparison group when practical. Recheck the same queries and note other factors that could move results, including rankings, price, availability, promotions, seasonality, and changes to paid Shopping activity. This will not create perfect experimental control, but it will stop you from assigning every movement to the newest search feature.

    Use the results to choose the next action:

    1. No AI Overview on a valuable query: continue conventional SEO, merchandising, feed, and Shopping work. Keep monitoring rather than rebuilding the page for a feature you have not observed.
    2. AI Overview present, brand absent: inspect the decision the overview resolves and the information its included pages provide. Check whether your relevant page lacks supported facts, comparison context, clear entity information, or consistent commerce data.
    3. Brand included, clicks healthy: preserve the useful page elements and data consistency. Apply the pattern selectively to closely related pages instead of redesigning the whole site.
    4. Brand included, clicks weakening: create a stronger reason to visit. Useful inventory depth, live variants, a complete comparison, detailed specifications, a selector, original product information, or a clear offer may provide value that a short summary cannot.
    5. AI Overview appearance is inconsistent: gather more observations before making a major change. A single screenshot is evidence of one result state, not a durable performance trend.

    Start with one commercially important category. Freeze its query list, capture the current search layouts, correct disagreements among the page, JSON-LD, and feed, and improve only the decision questions the existing pages leave unresolved. Then measure that same cohort again. This gives your next catalog release a clear hypothesis and gives you evidence for what to scale.

    References

  • Technical SEO for Local Leads: Fix the Path to Inquiry

    Technical SEO for Local Leads: Fix the Path to Inquiry

    Your local website can rank for a service name and still miss the customer who eventually buys. The gap often appears one step earlier, when that customer is searching for a symptom, trying to understand the problem and deciding whether professional help is necessary.

    To generate more qualified inquiries, treat technical SEO and local content as one system. The right page must exist for the customer’s question, search engines must be able to crawl and index it, and the page must move the visitor toward an appropriate service without forcing them to translate their problem into your internal terminology.

    Find the demand that appears before the service query

    Most local sites are organized around what the business sells: plumbing, drain cleaning, furnace repair, roof replacement or another named service. That structure serves people who already know what to request. It does much less for someone asking why a sink keeps backing up, why a room never gets warm or whether a roof stain needs urgent attention.

    Those searches aren’t merely informational. The person is diagnosing a visible symptom, estimating the seriousness of the situation and deciding what to do next. A site that answers only service-name searches can therefore miss high-intent demand during the decision stage that precedes a direct local-service query.

    Start by separating three jobs your pages need to perform:

    • Problem pages help a visitor understand a symptom, its plausible causes, safe next steps and the point at which professional help makes sense.
    • Service pages explain the professional solution, what the work involves and how to request it.
    • Location pages establish where the service is available and give locally relevant information rather than repeating a generic service page with a different place name.

    Build your initial problem-page list from actual customer language. Review search queries, on-site searches, inquiry forms, call notes, sales questions and customer-service messages. Record the symptom as the customer describes it, the service it normally maps to and the decision the person is trying to make. A question such as “Can this wait?” represents a different content need from “What causes this?” even when both eventually lead to the same service.

    Don’t turn every wording variation into a separate URL. If several phrases describe the same condition and require the same answer, consolidate them on one strong page. Create a new page only when the symptom, likely causes, available options or appropriate service materially changes. That distinction prevents a useful resource library from becoming a collection of overlapping, low-value URLs.

    Prioritize technical fixes by their effect on leads

    A technician repairs blocked pathways in a website structure while local customers wait near the route to an inquiry point.

    A technical audit can produce hundreds of findings, but a long export isn’t a delivery plan. Development capacity is a real constraint: up to 67% of respondents have identified non-SEO development work as an impediment to technical implementation. Your backlog must distinguish a blocked revenue path from a cosmetic imperfection.

    Triage issues in this order:

    1. Make priority pages accessible and indexable. Confirm that each important service, problem and location URL returns a successful response, isn’t blocked from crawling, doesn’t carry an unintended noindex directive and identifies the correct canonical URL. Check the rendered page, not only its raw source, when JavaScript supplies essential copy, navigation or forms.
    2. Resolve competing URL signals. Look for duplicate paths, outdated URLs, parameter versions and inconsistent canonical tags. Redirect retired URLs to the closest relevant replacement, link internally to the preferred version and keep noncanonical duplicates out of the XML sitemap.
    3. Remove architectural dead ends. Every priority page should be reachable through a relevant hub or service page. A URL that exists only in a sitemap has far less contextual support than one connected to the site’s visible customer journey.
    4. Fix performance where it interrupts action. Address backend delays before polishing minor front-end details. Then inspect excessive JavaScript, rendering dependencies, late layout movement and resources that delay the information or controls a visitor needs first.
    5. Test the complete mobile journey. Check navigation, readable content, tap targets, telephone links, forms, validation messages and confirmation states on a narrow screen. A fast landing page still fails commercially if the form becomes difficult to complete.

    Score each task against four questions: Does it affect a page capable of generating a lead? Does it prevent crawling, indexing, understanding or conversion? How many priority URLs inherit the problem? What implementation effort and coordination does it require? A shared template defect affecting every service page should usually outrank an isolated warning on an old resource, even if an audit tool labels both issues the same way.

    Performance work should also follow the user’s sequence. Prioritize the page heading, main explanation, navigation and primary action before secondary widgets. Backend bottlenecks can affect the whole experience; after those are addressed, techniques such as critical CSS, selective preloading and reserving space for dynamic elements can improve perceived speed and stability. The point isn’t to chase a score in isolation. It is to keep the visitor’s path to an informed decision usable.

    Build an architecture that connects problems to solutions

    Your site structure should reflect the customer’s journey without abandoning clear service organization. A practical model contains a main service hub, individual service pages, a problem or advice hub, focused problem pages and useful location pages. The exact folder names matter less than the relationships between those pages.

    Make the internal links intentional:

    • A problem page should link to the service that resolves the issue, using language that explains the relationship.
    • A service page should link back to the common symptoms or situations that lead customers to need it.
    • A service hub should help visitors distinguish between related services instead of presenting an undifferentiated list.
    • A location page should link to services genuinely available in that area and to any problem resources that add local relevance.
    • Breadcrumbs and visible parent navigation should preserve the hierarchy for visitors as well as crawlers.

    This structure does more than distribute internal authority. It tells search engines that a symptom page, a professional solution and a service area belong to the same topic. It also gives a visitor an obvious next step without making every page behave like a hard-sell landing page.

    Watch for signal dilution as the site grows. Multiple URLs competing for the same intent, inconsistent canonical choices and weak internal links can prevent search engines from identifying the page you consider most important. Consolidating overlapping topics and strengthening links to priority pages are often more achievable than a complete architecture rebuild, especially when development resources are limited.

    Avoid automatically multiplying every service by every city and every symptom. A service-location page deserves its own URL when it can provide distinct, accurate value about that service in that place. A problem page deserves its own URL when it answers a distinct decision. Swapping a place name across otherwise identical pages creates inventory, not usefulness.

    Write problem pages that turn uncertainty into action

    A resident with a leaking sink follows a visual path through a mobile problem page to a visiting plumber.

    A useful problem page follows the visitor’s reasoning. It doesn’t open with a company history, a broad definition or a sales pitch. It begins with the situation the person can observe and then helps them make a safer, better-informed decision.

    Use this page sequence:

    1. Name the symptom precisely. Put the customer’s description in the title, opening paragraph and relevant subheadings. Confirm what the page covers and distinguish it from a similar-looking problem when that distinction matters.
    2. Give the short answer early. Explain what the symptom commonly indicates, whether several causes are possible and what the visitor should determine next. Don’t force someone to read an essay before learning whether the page applies to them.
    3. Order plausible causes usefully. Move from simpler or more common explanations toward causes that require inspection or specialist work. Explain the signs that separate one possibility from another without pretending to diagnose an unseen situation.
    4. Offer only safe checks. A visual observation or a basic setting check may be reasonable. Instructions involving gas, live electricity, structural damage, hazardous materials or equipment disassembly are not appropriate DIY lead magnets. State the stop condition and identify the qualified professional needed.
    5. Explain the available options. Tell the reader what can sometimes be monitored, what may require maintenance and what generally calls for professional diagnosis or repair. This is where the page earns trust by helping the visitor decide, not merely urging them to call.
    6. Set honest cost expectations. Publish a range only when it is supported by the business’s real service data and can be qualified appropriately. Otherwise, explain the factors that change the price, such as the underlying cause, access, parts, extent of damage or work required. Cost context and explicit signals for professional help reduce uncertainty without making an unsupported promise.
    7. Connect the problem to the service. Name the relevant service, explain how a professional would investigate the issue and offer an action that matches the urgency: request an assessment, call about an urgent condition or review the service before deciding.

    Place these pages inside a visible resource or problem hub, not in a forgotten chronological blog archive. A permanent position in the architecture makes their purpose clearer and lets service pages support them with relevant internal links.

    Make each answer easy for search and AI systems to interpret

    Clear structure helps beyond conventional rankings. Use headings that state the question being answered, concise paragraphs for direct explanations, lists for causes or decision criteria and consistent names for the symptom, service and location. A predictable symptom-to-cause-to-option-to-service relationship gives both search systems and AI-generated summaries less ambiguity about what the page means. Problem-led pages can therefore support indexing accuracy and visibility in AI-mediated search experiences, although no format guarantees inclusion.

    Clarity is more valuable than repetition. Don’t force the city, service and symptom into every heading. State the location where it changes the answer or establishes availability, and keep the diagnostic explanation readable for the person who actually has the problem.

    Key takeaways: measure the whole local lead path

    Don’t judge this work from rankings alone. Measure the handoffs between technical eligibility, discovery, consideration and inquiry:

    • Eligibility: priority service, problem and location URLs are crawlable, canonicalized correctly, rendered properly and eligible for indexing.
    • Discovery: problem pages receive impressions for symptom and decision-stage queries, not only for branded terms.
    • Movement: visitors use contextual links from problem pages to the relevant service pages or inquiry actions.
    • Conversion: calls, forms or bookings can be attributed to the landing page and page type that began the session.
    • Lead quality: the inquiries concern services the business provides in areas it actually serves.
    • Prioritization: the next fix is selected by lead impact, affected page reach and implementation effort, not by the raw number of audit warnings.

    The pattern in the data tells you what to change. Impressions without visits point toward a mismatch between the query, title and promised answer. Visits without movement to a service page suggest that the page isn’t resolving the visitor’s decision or making the next step clear. Service-page visits without inquiries shift attention to relevance, mobile usability, form friction and the offer itself. No impressions at all require you to revisit demand, internal linking and indexability before rewriting the call to action.

    Choose one commercially important service area for the next implementation cycle. Map its symptom questions, identify the existing service and location pages, fix the technical barriers across that small cluster, publish only the missing problem pages and connect the journey with deliberate internal links. Once you can measure that path from crawl to qualified inquiry, extend the model to the next service cluster.

    References