Tag: Content Optimization

  • AI Recommendation Pipeline Optimization, Gate by Gate

    AI Recommendation Pipeline Optimization, Gate by Gate

    Your page can rank, load correctly, and carry structured data yet still disappear when an AI system recommends a product, provider, or approach. Publishing more content will not fix that if the real failure happened earlier in the recommendation pipeline.

    You need to find the earliest gate your content cannot reliably pass. Fix that dependency first, then work forward until the system can retrieve, understand, trust, present, and ultimately prefer your answer.

    Think in gates, not one AI visibility score

    A practical AI recommendation pipeline contains 10 dependent gates: Discovered, Selected, Crawled, Rendered, Indexed, Annotated, Recruited, Grounded, Displayed, and Won. This is an operational model for diagnosis, not a claim that every AI engine exposes the same internal architecture.

    The distinction matters because a weak result does not identify its own cause. If your brand is absent from an answer, the underlying problem could be access, interpretation, credibility, relevance, or competitive fit. Treating every absence as a content-writing problem produces activity without revealing the bottleneck.

    The first five gates determine whether your material becomes technically eligible for use. The final five determine whether the system can understand and use it, verify it, show it, and choose it over alternatives. A hard failure upstream dominates everything downstream. A page that is not fetched cannot be rescued by better prose, and a page that is misunderstood cannot be rescued by stronger claims.

    Before you audit anything, define the recommendation you are trying to earn:

    • Decision: the question or task for which you want to be recommended.
    • Entity: the brand, product, service, location, person, or resource the system must recognize.
    • Canonical evidence page: the primary URL that explains why the entity fits the decision.
    • Qualifying facts: the attributes, limitations, audience, and use cases that make the recommendation accurate.
    • Desired outcome: an accurate citation, inclusion in a shortlist, a preferred recommendation, or another observable result.

    Do not audit an entire domain as one unit. A site can pass the pipeline for one entity and fail it for another. Your product page might be understood correctly while a location, plan, feature, or professional service remains invisible or ambiguously classified.

    Key takeaways

    • Find the earliest plausible failure instead of averaging every signal into one visibility score.
    • Separate technical eligibility from the later contest for recruitment, grounding, display, and preference.
    • Use observable evidence as a proxy. You usually cannot inspect an AI system’s internal gate state directly.
    • Treat visible copy, structured data, feeds, and supporting pages as representations of the same entity, not separate stories.
    • Keep post-decision reality aligned with the promise that earned the recommendation.

    Earn eligibility from discovery through indexing
    Exploration probes find a glowing content object that passes through a selective opening into an organized digital archive.

    Discovery, selection, crawling, rendering, and indexing form a dependency chain. Work through it in order. Checking only whether a URL loads in your own browser skips several different failure modes.

    Discovered: create legitimate paths to the entity

    Discovery asks whether a system can become aware that the entity and its supporting content exist. Start with the canonical page and trace every route that can expose it.

    • Link the page from a relevant navigation path, category page, hub, or related resource. Do not leave important evidence isolated behind a site search form.
    • Use descriptive internal links that identify the destination’s subject. Generic labels make the relationship less explicit.
    • Keep the canonical URL stable. If the same entity is scattered across temporary or duplicative URLs, choose a primary destination and make the hierarchy clear.
    • Inventory feeds, APIs, directories, and other structured distribution routes that legitimately carry the entity’s data.
    • Check whether site-level bot controls, security layers, or access policies unintentionally prevent discovery.

    Some platforms accept structured feeds or direct data pushes. Where those routes are available, they can bypass parts of the traditional discovery path. Use them as maintained representations of the same facts found on your site. A fast data route filled with stale names, prices, locations, or availability merely distributes the contradiction faster.

    Selected: make the page worth investigating

    Discovery creates awareness; selection determines whether the system has a reason to inspect the material. Open the page and look only at its title, opening paragraphs, headings, and internal-link context. Those elements should make the entity and its purpose unambiguous.

    • Name the entity and its category instead of relying on a slogan.
    • State the audience or situation the page serves.
    • Align the page with a specific decision rather than collecting loosely related keywords.
    • Separate genuinely different intents when combining them would make the primary answer unclear.
    • Resolve competing pages that make substantially different claims about the same entity.

    A page titled around broad thought leadership may be useful to a reader but still give a recommendation system no clear reason to retrieve it for a purchase, comparison, eligibility, or implementation question. Give each important page a recognizable job.

    Crawled, rendered, and indexed: verify access and interpretation separately

    A successful visit in your normal browser does not prove that an automated system received the same useful material. Test the page without a signed-in session, inspect available server or delivery logs, and separate these questions:

    • Crawled: Can an automated requester fetch the document without authentication, an unresolved challenge, or an interaction that never occurs?
    • Rendered: Does the resulting document contain the entity name, answer, qualifiers, and evidence as readable text?
    • Indexed: Is the page distinct, stable, and useful enough to be retained as a retrievable representation of the entity?

    Keep recommendation-critical facts out of image-only layouts, hover states, closed interface elements, and experiences that require a user action before any meaningful text appears. Interactive tools can remain valuable, but their core purpose, inputs, output meaning, and limitations should also be explained in text.

    Indexing is not something you can prove merely by finding a URL in one search interface. Use multiple proxies: a stable canonical destination, unique content, consistent internal references, successful fetch evidence where available, and downstream appearances that could not happen without retrieval. Record uncertainty instead of marking the gate as passed on weak evidence.

    Make the content usable for annotation, recruitment, and grounding
    Unlabeled modular content panels connect through semantic markers and evidence fragments to a transparent frame surrounding a glowing answer core.

    Passing the access gates only makes your content eligible. The next job is to remove ambiguity, package useful answers, and support the claims an AI system would have to repeat.

    Annotated: define the entity before decorating it with schema

    Annotation is where content is classified by meaning. Before editing JSON-LD, write an internal entity fact sheet that answers:

    • What is the entity’s exact name?
    • What type or category does it belong to?
    • What does it do, provide, or represent?
    • Who is it intended for, and who is it not intended for?
    • Which use cases does it support?
    • Which limitations, eligibility rules, locations, or availability conditions qualify the claims?
    • How does it relate to the parent brand, other offerings, locations, versions, or people?

    Then compare that sheet with visible copy, structured data, feeds, navigation labels, supporting pages, and external profiles you control. The facts do not need identical wording, but they should not describe different entities.

    Schema can clarify a page’s meaning. It cannot repair a missing explanation or safely substitute a stronger claim for the one a visitor can see. Treat JSON-LD as a structured representation of the visible entity. If a material attribute appears only in markup, either support it clearly on the page or remove it.

    Recruited: build answer units that remain clear when extracted

    Recruitment asks whether the system can use the content for the decision at hand. Long-form depth helps only when the relevant answer can be located and understood without reconstructing it from scattered sections.

    For every important question, create a self-contained answer unit with this sequence:

    <!– wp:list {
  • How to Optimize Content for Humans and AI Discovery

    How to Optimize Content for Humans and AI Discovery

    Your page has two jobs before it can earn a business result. A person must understand why it matters, and a search or AI system must be able to identify what it says without guessing. Treat those as separate writing assignments and you usually get a stiff “AI version” alongside a more expressive page whose meaning remains implicit.

    Use one clarity-first page instead. Make its meaning explicit, its value hard to substitute and its next action easy to complete. That approach matters because generic informational content now competes with direct AI answers while visibility becomes scarcer. Publishing more is not enough. Each page must be understandable, retrievable, memorable and useful.

    Optimize the shared information, not two separate audiences

    People and AI systems process a page differently, but they tend to struggle at the same points: an unclear subject, an unsupported claim, an unexplained term, a buried qualification or an ambiguous next step. That is why clear messaging, usable experiences and technical precision form a shared foundation for people and automated systems.

    A person can sometimes infer meaning from visual position, tone or previous experience. An automated system may depend more heavily on labels, surrounding text and explicit relationships. The answer is not to flatten your writing into robotic prose. Keep the voice, examples and visual hierarchy that help people, but state the essential facts in text that can stand on its own.

    Page elementWhat a person needsWhat an AI system needs to identifyShared treatment
    OpeningWhether the page is relevantThe primary subject, audience and outcomeGive a direct answer or promise before background
    HeadingsA fast route to the right detailClear boundaries between subtopicsUse descriptive headings that name the question or decision
    EvidenceA reason to believe the claimThe relationship between a claim, its support and its limitsPlace support and qualifications beside the claim
    Call to actionConfidence about what happens nextThe action available and its destinationUse a specific label and a working, direct path

    Key takeaways

    • Optimize one canonical page for shared clarity instead of creating separate human and AI versions.
    • Put the main answer, offer or decision near the beginning, then add the context needed to evaluate it.
    • Use descriptive headings and self-contained sections so readers and systems can locate the right passage.
    • Keep evidence, definitions and limitations close to the claims they support.
    • Make the primary next action explicit in both its wording and its destination.
    • Plan how the page will reach its audience before committing resources to its production.

    Build every page as a question-to-action path

    A person follows a connected path of blank content cards from an initial question to a final action control.

    Optimization starts before the draft. Write a three-line page contract that prevents the page from drifting into a broad topic summary:

    • Audience: Who is making a decision or trying to complete a task?
    • Promise: What will this page help that person understand, choose or do?
    • Action: What should become possible after the promise has been fulfilled?

    Be specific enough that an editor could reject material that does not belong. “People interested in AI SEO” is too broad. “A content lead deciding how to revise service pages for human visitors and AI discovery” establishes a reader, a page type and a decision.

    1. Choose one dominant job. Decide whether the page primarily helps someone learn, compare, evaluate, buy or complete an action. A page may support secondary needs, but it should not give all of them equal weight.
    2. Answer before explaining. State the conclusion, offer or recommended direction early. Background belongs after the reader knows why it matters.
    3. Develop a visible reasoning chain. Move from the answer to the mechanism, supporting evidence or criteria, important limitations and the appropriate next step.
    4. Name important entities consistently. If you alternate among a product name, category name and vague phrases such as “the solution,” neither the reader nor a downstream system should have to infer whether they refer to the same thing.
    5. Close the loop. The call to action should follow from the page’s promise. A comparison page might lead to a specification, consultation or purchase path. An instructional page should let the reader perform or verify the task it explained.

    Then perform a sentence-level clarity audit. Replace pronouns whose antecedents are uncertain. Define an acronym at first use. Remove adjectives such as “advanced,” “leading” or “seamless” unless the page supplies a basis for them. Put exceptions beside the rule instead of hiding them in a closing note. Replace generic links such as “click here” and “learn more” with labels that identify the destination or action.

    A useful stress test is whether a 10-year-old could roughly explain what you offer, why it matters and how someone engages with it. That clarity test is meant to expose unnecessary complexity, not to make a technical subject childish. Keep the precise terms your audience needs, but define them in the same section where they become relevant.

    Write modules that survive scanning, extraction and reuse

    Blank visual content modules move from a central page into a mobile screen, an AI extraction frame, and a reader's reference card.

    There is no universally correct amount of text for a page. The right length is the amount required to explain the offer or answer, establish why it is credible, distinguish it from alternatives and support the intended action. A long page can be easy to use when it is modular. A short page can still fail when it omits the facts needed to decide.

    Give each section a repeatable internal shape:

    1. Descriptive heading: Name the subquestion, criterion or decision addressed by the section.
    2. Direct opening: Answer that subquestion in the first sentence or paragraph.
    3. Support: Add the mechanism, evidence, definition, example or comparison needed to evaluate the answer.
    4. Boundary: State any condition under which the answer changes or does not apply.
    5. Implication: Tell the reader what to notice, decide or do with the information.

    This structure makes a section useful when someone scans directly to it. It also reduces the risk that a sentence will be extracted without the qualifier that changes its meaning. Do not repeat the same conclusion in every module. Each section should advance the decision.

    Match formatting to the relationship in the information. Use bullets for criteria of the same kind, numbered lists when sequence matters and tables only when readers need to compare the same attributes across multiple options. Use images when they explain something the text cannot show as efficiently. Relevant alt text should communicate the image’s purpose or information, while decorative imagery should not be forced to carry a claim. Readable typography, adequate contrast and meaningful image descriptions support accessibility as well as comprehension.

    Once the visible copy is stable, align the structured layer. Treat JSON-LD as a machine-readable restatement of facts on the page, not as a second marketing message. Entity names, descriptions, relationships and available actions should agree with what a visitor can see. Do not add a claim to structured data that the page does not substantiate, and do not expect schema to rescue copy whose subject or purpose is unclear.

    • Use the same preferred name for the organization, product, service or person in the copy and structured data.
    • Make each marked-up type match the thing the page actually describes.
    • Keep dates, status information and other changeable facts synchronized wherever they appear.
    • Ensure an action described in structured data resolves to a real, functioning destination.
    • Remove obsolete markup when the corresponding visible content or capability is removed.

    When an AI agent must interact with tools or shared information rather than merely read a page, connection standards such as Model Context Protocol can help systems reach those resources. But clean, well-structured and actionable information is still required downstream. Connectivity does not correct an ambiguous offer, an unsupported statement or a broken workflow.

    Add value that cannot be replaced by a generic summary

    A generic explanation can be accurate and still be strategically weak. If a capable system can reproduce the page’s entire value from common knowledge, the reader has little reason to remember your brand or visit for the next step. As content production becomes easier, originality, distinctiveness and deliberate distribution carry more of the visibility burden.

    Do not confuse originality with novelty for its own sake. A useful page becomes harder to substitute when it contributes at least one defensible unit of value:

    • A decision rule: A clear way to choose between options, including the condition that changes the choice.
    • A bounded position: A recommendation that states where it applies, where it does not and why.
    • Owned evidence: Substantiated data, examples, observations or methods that your organization is entitled to publish.
    • An operational method: A checklist, sequence, template or diagnostic that lets the reader perform the work.
    • A revealing limitation: A tradeoff or failure mode that generic descriptions tend to omit.
    • A distinctive asset: A useful visual, framework or recurring editorial device that people can recognize and share.

    Use only material you can support. Invented data, anonymous anecdotes and manufactured certainty may make a page look specific, but they weaken trust and make its claims unsafe to reuse. Precision includes saying when evidence is limited or a recommendation depends on context.

    Apply a substitution test before publication. Could a competitor replace the logo and publish the page unchanged? Does the page contain a rule someone can use, or only a summary of the topic? Is there a sentence that expresses a recognizable point of view? Would a partner have a concrete reason to share it? If every answer points to interchangeability, revise the value proposition before polishing metadata.

    Distinctive content still needs a route to attention. Reverse the volume-era workflow that publishes first and asks about promotion later. Media, partnerships and events can push useful work toward an audience instead of leaving discovery entirely to search. Complete a distribution brief before approving the draft:

    • Audience: Name the specific group that will use the page and the decision it helps them make.
    • Carrier: Identify the newsletter, partner, community, media relationship, event, paid placement or owned channel capable of reaching that group.
    • Reason to share: State the practical value the carrier can offer its audience by distributing the work.
    • Portable asset: Choose the checklist, chart, decision rule, example or excerpt that can travel without stripping away the meaning.
    • Destination: Decide where interested people should land and what they should be able to do there.

    If you cannot identify a credible carrier or reason to share, that is useful information. Narrow the audience, strengthen the original contribution or reconsider whether the page deserves production. Distribution should shape the content brief, not become a rescue operation after publication.

    Use a publish gate for clarity, action and delivery

    Technical optimization belongs after the message and user path are coherent. It can expose and remove friction, but it cannot manufacture relevance. A fast, marked-up page with a vague offer remains vague. The final review should test meaning, task completion, rendering, discovery and distribution as one system.

    Run the same comprehension test with a person and an AI assistant

    Give the page to a colleague who was not involved in writing it. Ask that person to identify the intended audience, main answer or offer, supporting evidence, important limitation and primary next action. Do not explain the page before the test.

    Then give an AI assistant only the visible page copy and use this prompt: “Identify the intended audience, main claim or offer, supporting evidence, limitations and primary next action. Quote the text that supports each answer. If an answer is unsupported, write ‘not stated.’” Compare both responses with the page contract.

    A correct AI response does not prove that the page will rank, appear in an answer or receive a citation. Treat the exercise as an ambiguity detector, not a visibility score. When the assistant invents a benefit, misses a limitation or chooses the wrong action, find the wording or structure that allowed the misreading. The same ambiguity may also be costing human comprehension.

    Complete the action yourself

    • Follow the primary call to action and confirm that its destination matches its label.
    • Test phone numbers, email links, forms, validation messages and confirmation states where they are part of the path.
    • Remove form fields and separate steps that are not required to complete or qualify the action.
    • Check that a user can recover from an error without re-entering unrelated information.
    • Confirm that transactional or lead-generation intent is stated in visible language instead of being implied only by a button or form.

    Clear calls to action and simple task paths matter because unclear checkout and lead-generation flows obstruct people and automated agents alike. A button labeled “Submit” identifies an interface event. A label such as “Request the estimate” identifies the user’s action and expected outcome.

    Inspect the experience that carries the content

    • Load the page at common desktop and mobile widths and check whether text, controls or media move after they first appear.
    • Remove intrusive overlays, excessive advertising and visual elements that compete with the page’s primary purpose.
    • Check contrast, text readability, keyboard access, control labels and meaningful alternative text.
    • Verify that the complete page renders, internal resources load and security warnings are absent.
    • Review the visible copy and structured data after deployment rather than assuming the content management system published both correctly.

    Large layout shifts, incomplete rendering, weak contrast, malware warnings and disruptive pop-ups undermine usability and trust. Fix those problems because they interfere with the experience, not because a technical score can replace a clear answer.

    Measure the page by the job it was built to do

    Traffic remains useful context, but it is not a complete outcome. Informational visits have always been a proxy for business progress, and direct answers make that proxy less dependable on its own. Keep a small scorecard tied to the page contract:

    • Comprehension: Record which parts people or AI extraction tests misinterpret, omit or overstate.
    • Action: Track starts, completions, abandonment and errors for the page’s intended task.
    • Discovery: Monitor the relevant queries, impressions, brand mentions and AI-answer appearances that matter to the defined audience.
    • Demand and memory: Watch branded search, direct or returning visits and voluntary brand engagement without treating any one measure as conclusive.
    • Distribution: Record placements, partner participation, qualified referral activity and reuse of the portable asset.

    Tools can make individual checks easier. IndexNow can notify participating search engines about a changed URL more quickly, though notification is not a promise of indexing or visibility. Microsoft Clarity can reveal behavioral friction, including problems in chatbot experiences. Both are diagnostic aids for updates and user behavior, not substitutes for editorial judgment.

    Start with the page closest to a meaningful customer decision. Make its promise and action unmistakable, align its structured data, run the paired comprehension test and give it a real distribution path. Once that page passes, turn the same publish gate into the default for every high-value page you create or revise.

    References

  • AI Search Content Optimization: A Practical Rewrite Method

    AI Search Content Optimization: A Practical Rewrite Method

    You have a page with real expertise, a useful answer, and a clear business purpose, yet AI-generated search results keep passing it over. The problem may not be the quality of the information. The answer may be buried in a long introduction, hidden behind a vague heading, or scattered across passages that make sense only when someone reads the whole page.

    The practical fix is to make that expertise easier to retrieve and combine. You do not need to flatten every page into robotic question-and-answer copy. You need to expose the answer, keep each important section understandable on its own, and connect the page to the rest of your topic coverage.

    Key takeaways

    • Prioritize pages that already contain valuable expertise but communicate their answers indirectly.
    • Build each important section around one question, claim, or decision so the passage still makes sense outside the page.
    • Use hub pages for topic orientation and spoke pages for focused, in-depth answers.
    • State the direct answer before adding reasoning, evidence, limitations, and exceptions.
    • Use titles, headings, descriptions, and internal links to reinforce the page’s purpose rather than compensate for unclear body copy.
    • Test whether an AI system can summarize the page accurately without losing the qualification that makes the answer trustworthy.

    Start with pages that already have answer value

    Traditional content refreshes often begin with declining traffic, outdated keywords, or slipping rankings. Those signals can still matter, but they do not tell you whether a page is a good candidate for AI search optimization. A page can receive modest traffic and still contain the clearest answer your organization has to an important customer question.

    For AI search, prioritize answer value. Look for pages that contain clear expertise, recurring customer questions, proprietary insight, durable reports, or evergreen explanations. Internal training material and pages that your sales, support, or subject-matter teams repeatedly share can also be strong candidates. Repeated internal use is a practical sign that the page already helps people understand something consequential.

    Create a revision queue with these fields:

    • Primary question: What exact question should this page answer?
    • Business purpose: What should a qualified reader understand, decide, or do after reading it?
    • Distinct value: What does this page contribute beyond a generic explanation of the topic?
    • Current answer: Where does the page actually state its main conclusion?
    • Extraction weakness: What would become confusing if a passage appeared without the introduction or surrounding sections?
    • Content relationship: Which broader hub and narrower related pages should connect to it?

    Then apply a simple screen. Can a reader identify the page’s question from the title and opening? Is the answer visible before the background material? Can a key passage be understood without reading the paragraphs above it? Are important qualifications attached to the claim they limit? Are the takeaways stated rather than left for the reader to infer?

    If the page is commercially or strategically important and those checks fail, move it up the queue. If it has no distinctive answer, rewriting the headings will not solve the deeper problem. Formatting can reveal expertise, but it cannot manufacture expertise that is not there.

    Rewrite the page as a set of standalone answer units

    A long layered document is separated into an orderly grid of distinct blank content cards.

    AI search systems do not always use a page as one indivisible document. They may retrieve a passage that appears relevant to a question and use it while constructing an answer. That makes chunk-level clarity a core editing requirement.

    An answer unit is a section centered on one idea. It should remain useful when separated from the page around it. A strong unit usually contains:

    1. A specific heading: Name the question, assertion, problem, or decision the section addresses.
    2. A direct opening answer: Give the conclusion before the history or explanation.
    3. The necessary qualification: State who, when, or under what conditions the answer applies.
    4. Support: Explain the reasoning, evidence, example, or mechanism behind the answer.
    5. A useful connection: Link to the next page a reader needs if the topic extends beyond this section.

    Consider a section headed Why it matters that begins, “This can also make the process easier.” Both the heading and sentence depend on missing context. A clearer version would use the heading Why does answer-first formatting help AI search? and open with, “Answer-first formatting exposes the section’s main claim before the supporting explanation and exceptions.” The revised passage names the subject and gives the reader an answer immediately.

    Run an isolation test on every important section. Copy the heading and its paragraphs into a blank document, then inspect the passage without the page title, introduction, sidebar, or preceding section. Look for words such as “it,” “this,” “that method,” “the issue,” and “these benefits.” If the missing context could change the meaning, replace the vague reference with the actual subject.

    This may require slightly more noun repetition than polished magazine prose. That is acceptable when the repetition removes ambiguity. You are not trying to make every sentence repetitive. You are making sure the passage does not become misleading when retrieved on its own.

    Do not confuse chunking with aggressive fragmentation. Create a new section when the reader’s question or decision changes, not whenever the page reaches a convenient visual break. If adjacent sections require the same setup before either one makes sense, they may belong in a single answer unit. If one section tries to define a term, compare options, describe implementation, and handle exceptions, it probably needs to be divided.

    Clarity also does not require oversimplification. Put the plain answer first, then preserve the conditions that make it accurate. A statement such as “Use this approach” is easy to extract but not useful if the real recommendation applies only to a particular audience or situation. Keep the recommendation and its boundary together.

    Build breadth with hubs and depth with spokes

    A single page should not carry every possible question about a broad topic. Trying to make one URL comprehensive often produces a long page with shallow sections, overlapping intent, and no obvious main answer. A hub-and-spoke structure gives each page a clearer job.

    The hub introduces the subject, establishes its major branches, and directs the reader to focused resources. Each spoke resolves one narrower question in greater depth. Linking the spokes back to the hub, and linking related spokes when the reader genuinely needs both, creates explicit signals about how the topics relate.

    Map the topic before rewriting individual paragraphs:

    1. Define the hub’s promise. Write one sentence describing what the reader should understand after using the hub.
    2. List the major question types. Separate definitions, reasons, processes, use cases, constraints, mistakes, and decision points where they require materially different answers.
    3. Assign an owner to each question. Choose one page that will provide the primary answer instead of allowing several URLs to compete with near-identical explanations.
    4. Find missing depth. Mark important questions that receive only a sentence on the hub but deserve a focused spoke.
    5. Find unnecessary overlap. Merge or reposition pages that answer the same question without contributing a distinct audience, condition, or level of detail.
    6. Add purposeful links. Connect pages where the relationship helps the reader continue the task, not merely because the pages share a keyword.

    Use descriptive internal-link text. “See our content audit process” gives the destination a clearer role than “learn more.” The surrounding sentence should explain why the linked page matters: it may supply the implementation steps, define a prerequisite, document an exception, or address the next decision.

    Keep the distinction between breadth and depth visible during editing. Breadth means your site covers the important branches of the subject. Depth means the responsible page answers its assigned question with enough explanation, support, and qualification to be useful. Adding more headings to the hub does not create depth if every section remains superficial.

    This structure also gives you a practical publishing decision. If a missing answer can be handled clearly within the existing page’s purpose, add it there. If it changes the audience, intent, or decision being addressed, create a separate spoke and connect it to the hub. That keeps the original page focused while expanding the site’s topical coverage.

    Make the answer easy to synthesize

    Retrieval is only part of the job. An AI system may need to combine definitions, conditions, examples, and limitations from different passages. Your copy should make those relationships explicit enough that the system does not have to rewrite the argument merely to understand it.

    For each important question, use an answer-first sequence:

    • Answer: State the conclusion in plain language.
    • Explain: Describe why the answer holds or how the process works.
    • Support: Add the evidence, example, or expertise that makes the answer worth using.
    • Bound: Identify limitations, exceptions, prerequisites, or cases where a different answer applies.
    • Direct: Tell the reader what to do next or where to find the connected detail.

    This order is not a ban on nuance. It is a decision about timing. Give the answer before the complexity, then add the complexity where it can refine the answer instead of delaying it.

    Use explicit labels when they help. “Summary,” “What this means,” and “When this does not apply” tell both the scanning reader and the retrieval system what a passage is doing. Avoid decorative labels such as “The road ahead” when the section is actually explaining implementation requirements. A heading should describe its information, not merely set a mood.

    Write title tags around purpose, not just topic

    A title tag that names only a broad keyword leaves the page’s contribution unclear. Add the question, decision, or scope that distinguishes the answer. For example, “Session replay software” identifies a topic, while “Session replay: what it shows, when to use it, and its limits” describes the page’s purpose.

    Use this working template: [Topic]: [main question, decision, or outcome]. Do not force every title into the same formula, and do not promise coverage the page does not provide. The title should be a faithful description of the answer below it.

    Turn headings into questions or useful assertions

    Readers should be able to scan the heading structure and understand the page’s argument. Replace labels such as “Overview,” “Benefits,” “Considerations,” and “More information” with the actual idea:

    • What is AI search content optimization?
    • Which pages should you optimize first?
    • Why does a self-contained passage improve retrievability?
    • When should a question become a separate spoke page?
    • What should you test before publishing the revision?

    You do not need to phrase every heading as a question. A clear assertion such as “A hub maps the topic while a spoke resolves one task” can be equally effective. What matters is that the heading exposes the section’s intent.

    Use the meta description as a compact intent statement

    The meta description should identify the audience, problem, and framing of the page. A practical drafting template is: For [audience], this page explains [problem or decision] in the context of [scope or condition].

    For example: “For content teams updating established pages, this workflow explains how to expose direct answers, improve passage clarity, and connect topic coverage for AI search.” That description does more than repeat the title. It clarifies who the page serves and how the subject is handled.

    Treat titles, headings, and descriptions as context anchors. They reinforce a clear page; they do not rescue an opaque one. If the body never states the promised answer, metadata will only make the mismatch more obvious.

    Preserve the expertise that makes the answer worth citing

    A clean structure can still produce forgettable content if the editing removes every specific judgement. Generic copy often defines a topic, lists familiar benefits, and ends before making a meaningful decision. Keep the material that demonstrates why your answer deserves attention.

    • Name the recommendation instead of implying that several options may be useful.
    • Explain the mechanism behind the recommendation, not just the expected benefit.
    • Retain accurate proprietary examples, original analysis, and subject-matter insight already present on the page.
    • Separate the default case from exceptions rather than blending them into vague language.
    • State what the method cannot solve, especially when a reader might otherwise apply it too broadly.
    • Delete introductions and transitions that delay the answer without adding context, evidence, or qualification.

    The goal is not to sound like a machine. It is to make your judgement legible. Human readers also benefit when a page names its conclusion, explains the reasoning, and makes exceptions easy to find.

    Test extraction before you publish the revision

    A transparent scanning frame lifts selected blank answer cards from a modular web page into a separate tray.

    Do not finish the refresh when the copy looks cleaner in the editor. Finish when the important answers survive extraction. Run the following editorial checks on the rendered page:

    1. Intent check: Read only the title, opening paragraphs, and headings. Confirm that they describe one coherent purpose and show where the reader’s main questions are answered.
    2. Isolation check: Move each critical section into a blank document. Restore any subject, condition, or definition that disappeared with the surrounding context.
    3. Answer check: Inspect the first sentence beneath each important heading. Rewrite openings that merely announce what the section will discuss.
    4. Qualification check: Confirm that limitations appear in the same answer unit as the claims they restrict. A caveat hidden several sections later is easy to lose.
    5. Overlap check: Compare sections and related URLs. Give each question one primary answer and remove duplicative passages that do not add a distinct condition or perspective.
    6. Relationship check: Follow every important internal link. Verify that the destination resolves the next question and that the anchor text names that relationship.
    7. Synthesis check: Ask an AI model to summarize the page and identify its main takeaways. Compare the output with what the page actually says, paying particular attention to missing conditions and overstated conclusions.
    8. Human-usefulness check: Read the page as someone making the decision it addresses. Make sure the answer is fast to locate, the reasoning is sufficient, and the next action is explicit.

    The synthesis check is diagnostic, not proof of visibility. AI output can vary with the question and context, so do not treat one response as a ranking report. Use a stable set of representative questions before and after the revision. Record whether the model identifies the correct main answer, preserves the important qualifications, and connects related concepts accurately.

    A useful final test is whether the model can quote or summarize the page accurately and find its answer quickly. If the summary is wrong, locate the passage that permitted the error. The cause is often an implicit subject, a conclusion delayed until the end, a missing boundary, or competing answers spread across the site.

    If the page passes the structural checks but still produces an empty or generic answer, stop reformatting. The next revision needs better substance: a clearer judgement, stronger support, a useful example, or a more precise explanation of when the recommendation applies. More headings will not fix an undifferentiated answer.

    Start with one page your team already relies on to answer a recurring question. Put its conclusion near the top, rebuild its important sections as standalone answer units, connect it to the right hub and spokes, and run the extraction checks. Once that page works, turn its structure and QA gate into the repeatable standard for your next revision.

    References

  • Google Search and Discover Optimization: A Practical Playbook

    Google Search and Discover Optimization: A Practical Playbook

    You did the hard part: the page is useful, current, and ready to earn attention. Then Google surfaces a generic thumbnail, crops out the subject, or gives the URL Search visibility without any meaningful Discover exposure. Those outcomes can have different causes, so adding one more tag isn’t a complete diagnosis.

    Your job is to make the page suitable for the surface, give Google consistent image signals, and make the people and publisher behind the content easy to verify. This workflow shows you where to start, what to implement, and what not to blame when Discover traffic moves.

    Treat Search and Discover as different outcomes

    Google Search responds to an expressed need. A person types a query, and your page competes to answer it. Discover works ahead of the query. It tries to predict what a person will want to see from their interests and recent context.

    That difference changes the publishing decision. A durable tutorial may deserve a Search-first brief even if it never becomes a meaningful Discover story. A timely development with a compelling visual and a clear connection to your audience may be suitable for both. Timeliness, relevance, and publisher authority tend to matter heavily in Discover, while evergreen content appears less often.

    Classify the page before you optimize it:

    • Search-first: The page answers a durable question or helps someone complete a task. Build it for sustained usefulness and treat Discover exposure as an upside, not the forecast.
    • Discover candidate: The subject is timely, closely connected to your audience’s interests, and supported by an image that can carry the story in a visual feed.
    • Dual-purpose: The topic has immediate relevance but also resolves a query people will continue to search. Preserve the useful answer instead of forcing the entire page into a short-lived news angle.

    This classification prevents a common strategic error: treating every lack of Discover traffic as a technical failure. Discover isn’t a dependable fit for every brand or every page. Technical readiness can make a suitable page eligible for stronger presentation, but it cannot create audience interest that the subject does not have.

    Align the thumbnail signals in the rendered page

    Matching backpack images in three floating page-signal layers connect to the same thumbnail in a central browser frame.

    Google does not promise to use the image you nominate. Image-preview selection is automated and can draw on several sources, including page content, structured data, and Open Graph metadata. The practical goal is therefore not to force a thumbnail. It is to remove contradictory signals.

    Use this implementation sequence on every content template that can appear in Search or Discover:

    1. Choose one preferred image. It should represent the specific page, not merely the publisher, section, or general subject area.
    2. Declare it in Schema.org markup. Use primaryImageOfPage with either the image URL or an ImageObject. Where your schema model describes a main entity, the image can also be connected through the relevant mainEntity or mainEntityOfPage relationship.
    3. Set the same asset as og:image. Do not let an SEO plugin, social plugin, and theme independently emit different preferred images.
    4. Permit large previews. For a non-AMP implementation, the rendered robots directive should include max-image-preview:large. A typical output is <meta name="robots" content="max-image-preview:large">.
    5. Inspect the final rendered page. Verify the HTML and JSON-LD that Google can receive, not just the image selected in the CMS editor.

    The rendered-page check catches the failures that configuration screens hide. A template may retain an old og:image, fall back to a logo when a field is empty, omit structured data on one content type, or output a restrictive image-preview directive. The image URL must also resolve to the intended file in production. A perfectly configured CMS field has no value if the resulting URL is broken or points to a placeholder.

    Pay particular attention to disagreement. If primaryImageOfPage identifies the hero image while og:image identifies a logo, you have given an automated system two different answers. Using both forms of metadata is useful when they reinforce the same decision; duplicating fields without aligning them only multiplies ambiguity.

    The max-image-preview:large directive deserves equally careful language. It allows Google to consider a large preview; it does not guarantee that a large image will appear, that your nominated asset will be selected, or that the page will enter Discover. Think of it as permission, not a ranking command.

    Build the image for the crop, not only the page

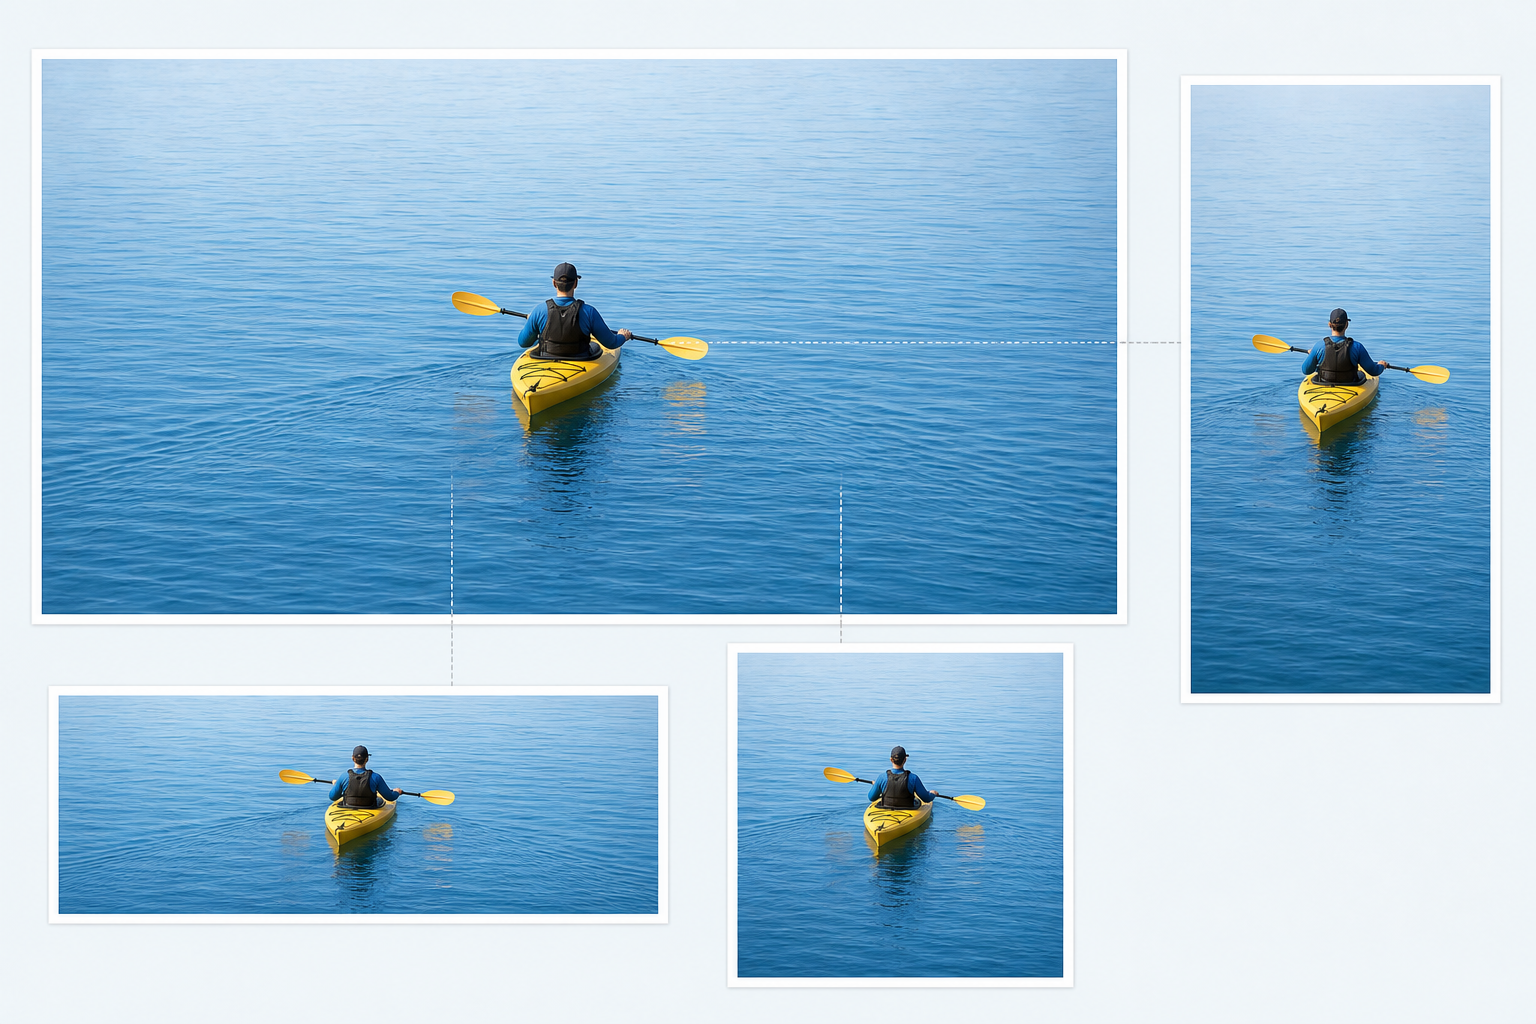
    Wide, square, and vertical crops of the same kayaking scene all keep the yellow kayak and paddler fully visible near the center.

    An image can look excellent at the top of an article and still fail inside a feed card. Discover may crop the asset for its layout, so the page-level composition is only half the job. A strong Discover candidate is at least 1,200 pixels wide, high resolution, and suited to a 16:9 landscape presentation.

    Use an asset-level publishing checklist:

    • Make the image specific. A real product, person, place, event, or visual result is more informative than a generic thematic image.
    • Avoid logos as the editorial thumbnail. The image should explain what this page is about, not simply identify who published it.
    • Keep essential detail away from fragile edges. Place the focal subject so it remains understandable after a landscape crop.
    • Avoid embedding the headline in the image. Text can become illegible or disappear when the asset is cropped and reduced.
    • Avoid extreme aspect ratios. A very tall or unusually wide source makes useful automatic cropping harder.
    • Keep the file visually sharp. Compression should not leave faces, products, screenshots, or other critical details soft at card size.

    Check the crop before publishing

    Start with the actual image URL emitted in og:image, not the larger file you happen to have in the media library. Preview it in a 16:9 landscape frame. Then reduce the preview until it resembles a feed card and ask a blunt question: can someone still tell what happened or what the page covers without reading embedded text?

    If the answer is no, change the composition or supply a deliberately cropped landscape asset. Google attempts to crop images automatically, but automatic cropping cannot recover a subject that occupies a narrow edge or make a generic image more relevant. When you provide your own crop, use it consistently in the page’s preferred-image metadata.

    This is also where editorial and technical teams need a shared definition of done. The image is not finished when it has been uploaded. It is finished when the correct file is visible, large-preview permission is present, the metadata fields agree, and the landscape crop still communicates the subject.

    Make the publisher and author easy to verify

    Discover optimization extends beyond the individual URL. Google can represent a publisher through a profile associated with the entity’s Knowledge Graph identity. That publisher profile can connect the website with its social profiles, so inconsistent names, outdated handles, and incomplete identity information deserve attention.

    Audit the publisher as a person encountering the brand for the first time:

    • Use a consistent publisher name, identity, and website across the site and official social profiles.
    • Check whether the Discover publisher profile accurately represents the organization and includes the intended social handles.
    • Keep the About page easy to find and specific about ownership, editorial purpose, and the people responsible for the site.
    • Link relevant editorial, correction, privacy, and other policy pages from predictable locations.
    • Ensure structured data agrees with the information a reader can see. Markup should clarify a real identity, not introduce a separate version of it.

    Profile corrections may require manual updates and patience. That makes prevention more valuable than repeatedly repairing mismatches. Decide on the canonical publisher name and official profiles, then use them consistently whenever you launch a new template, section, or social account.

    Apply the same transparency standard to authors. Visible author photos, biographies, and relevant social links support clearer authorship. A strong implementation gives each article a real byline, links that byline to a useful author page, and explains why that person is qualified to cover the subject.

    Do not turn this into decorative credential stuffing. The author page should help a reader answer practical questions: Who wrote this? What area do they cover? Is their work on this site accessible? Can their public identity be verified? If those answers are missing from the visible site, adding more structured data will not repair the underlying transparency problem.

    Diagnose weak Discover performance in the right order

    Technical fixes are attractive because they are concrete. They are also easy to over-credit. Content relevance and quality remain more important than technical polish. A technically perfect page can still be a poor Discover candidate, while an appropriate page can underperform because its template suppresses large images or emits the wrong thumbnail.

    The feed itself is not static. Social posts and AI-generated summaries can occupy space that previously went to conventional publisher pages. That means a broad decline does not, by itself, prove that a developer broke the site. Use this order of investigation:

    1. Recheck content fit. Was the page genuinely timely and relevant to an established audience, or was Discover traffic assumed simply because the page was new?
    2. Determine the scope. Separate a page-level issue from a content-type, template, section, or sitewide pattern.
    3. Inspect the rendered metadata. Compare primaryImageOfPage, entity relationships, og:image, and the robots image-preview directive.
    4. Inspect the emitted asset. Confirm its width, quality, subject, aspect ratio, and crop resilience.
    5. Review publisher and author transparency. Check profiles, bylines, biographies, About information, policy pages, and consistency between visible information and structured data.
    6. Revisit the expectation. If the implementation is clean, the remaining issue may be content suitability, audience interest, authority, or changing competition within the feed.

    The following symptoms are useful starting points, not proof of a single cause:

    What you noticeCheck firstWhat not to assume
    Large previews are absent across one content templateThe rendered max-image-preview:large directive and template-level image fieldsThat every affected page has weak content
    Search and Discover surface an unintended imageAgreement between primaryImageOfPage, entity relationships, og:image, and the visible hero imageThat adding another duplicate image field will force the selection
    The metadata is clean, but a durable evergreen page receives no Discover exposureWhether the subject is timely and aligned with audience interestsThat valid markup creates Discover demand
    Traffic declines broadly without a relevant site releaseRecent content mix, audience relevance, publisher authority, and changing feed competitionThat a technical regression is the only possible explanation
    Only some authors or sections perform inconsistentlyTemplate output, byline links, author pages, preferred images, and section-specific defaultsThat the entire domain needs to be rebuilt

    Key takeaways

    • Decide whether each page is Search-first, Discover-suitable, or useful for both before setting traffic expectations.
    • Point Schema.org image properties and og:image to the same relevant, high-quality asset.
    • Use an image at least 1,200 pixels wide and prepare it for a 16:9 landscape crop.
    • Enable max-image-preview:large when you want a non-AMP page to be eligible for a large preview.
    • Make publisher and author identities visible, consistent, and supported by useful profile and policy pages.
    • Investigate content fit before treating every Discover decline as a technical defect.

    Choose one recent URL that you genuinely expect Discover to carry. Inspect its rendered head, follow every preferred-image reference to the live asset, test the landscape crop, and then follow the publisher and author paths as a reader would. Fix any template-level inconsistency before producing more candidates. Once those signals agree, you can make the next publishing decision around the subject and audience instead of gambling on metadata.

    References

  • How to Diagnose Google Search and Discover Visibility Changes

    How to Diagnose Google Search and Discover Visibility Changes

    Your Google traffic dropped, but the aggregate line does not tell you what broke. Search and Discover can move for different reasons, and treating them as one channel can send you toward the wrong fix.

    Separate the surfaces first. Then inspect timing, geography, impressions, clicks, queries, and affected page groups. That sequence will tell you whether to investigate distribution, content-market fit, measurement, or a broader site problem.

    Start by separating Search from Discover

    Google Search begins with an expressed query. Discover recommends content around a user’s inferred interests. A page can therefore lose Discover distribution while retaining Search demand, rankings, and clicks. The reverse can also happen.

    The distinction became especially important during Google’s February 2026 Discover core update. Its rollout ran from February 5 through February 27 and applied, at completion, only to Discover for U.S. users viewing English content. It was the first confirmed update announced specifically for Discover. Search fluctuations during the same period were not confirmed as part of that update.

    SurfaceWhat starts the experienceWhat to inspect firstCommon diagnostic mistake
    Google SearchA query expressed by the userQueries, landing pages, countries, devices, impressions, and clicksAttributing a Search decline to a Discover-only update
    Google DiscoverA personalized recommendation based on interestsDiscover pages, countries, devices, impressions, and clicksTreating a feed-distribution change as a sitewide Search loss

    Use the February scope only when interpreting that rollout window. Google said it planned to expand the update to other countries and languages later, so the original U.S.-English boundary should not be assumed for subsequent periods without verification.

    Diagnose the change before editing content

    An analyst compares abstract traffic panels, a calendar grid, a world map, and groups of web pages at a diagnostic workspace.

    Do not start by rewriting pages. First establish exactly where visibility changed. Otherwise, a Discover decline can trigger unnecessary Search edits, while a measurement fault can be mistaken for an algorithmic loss.

    1. Verify the measurement. Compare your analytics platform with Search Console. If analytics traffic fell while Search Console impressions and clicks remained consistent, investigate consent, tagging, reporting, and attribution before changing content.
    2. Split Search and Discover. Review each performance surface independently. Record the start of the change rather than relying on the combined organic traffic line.
    3. Mark relevant rollout dates. If the movement began around February 5 through February 27, 2026, note that window. Timing creates a hypothesis; it does not prove a cause.
    4. Segment the exposed audience. Compare the United States with other countries. Because Search Console does not give you a simple content-language diagnosis, also isolate the page groups serving your English-language U.S. audience.
    5. Separate reach from response. Falling impressions indicate that the content was shown less often. If impressions are relatively stable but clicks fall, investigate placement, presentation, headline fit, and intent before concluding that visibility disappeared.
    6. Find the affected page cluster. Group pages by subject, format, geography, creator, and publishing pattern. A concentrated decline is more actionable than a sitewide average.

    If Search is stable and Discover falls, keep the investigation inside Discover until the evidence points elsewhere. Review which topics and geographic audiences lost impressions. Do not change title tags or Search-focused copy merely because the combined organic total declined.

    If Discover falls mainly for U.S.-facing English pages around the rollout window while other markets remain steadier, the update is a plausible contributor. It is still not proof. Check whether the loss is concentrated in sensational headlines, thin coverage, non-local material, or topics where your site has little sustained expertise.

    If Search declines but Discover remains stable, investigate Search demand, query visibility, landing pages, indexing, and technical conditions. The February Discover update is not an adequate explanation for that pattern.

    If both surfaces decline, widen the scope. Confirm tracking, crawling, indexing, templates, site changes, demand, and the affected directories. A simultaneous decline may be broad, but the shared timing alone does not identify the cause.

    Use long Search queries to expose conversational demand

    A person directs a detailed spoken question into a blank search field as connected topic symbols and content cards branch outward.

    Traditional keyword lists often miss the way people now phrase complex tasks, comparisons, and concerns. Search Console gives you a useful first-party proxy: the longer queries for which your pages already received impressions or clicks.

    You can filter for queries containing at least 10 whitespace-separated words with this process:

    1. Open Search Console and go to Performance > Search queries.
    2. Select Add filter > Query.
    3. Choose Custom regex.
    4. Enter ^(?:S+s+){9,}S+$.
    5. Apply the filter and export the resulting queries with their available performance data.

    The expression looks for at least 10 non-whitespace terms separated by whitespace. It is a practical threshold for finding prompt-like language, not a definition of an AI prompt.

    That caveat matters. Search Console can contain data connected with AI Mode, and unusually conversational searches may resemble prompts used in an assistant. But a long query does not reveal where or how it originated. The user may have typed it directly into Google. Treat the data as evidence of conversational demand, not proof of ChatGPT, AI Mode, or another platform.

    After export, cluster the queries by the behavior they reveal:

    • User job: planning, comparing, troubleshooting, learning, checking, or choosing.
    • Entity: your brand, a competitor, a product, a location, or a named problem.
    • Decision context: constraints, desired outcome, use case, audience, or risk.
    • Unresolved concern: reputation, an old incident, compatibility, trust, or a reason not to buy.
    • Current destination: the page that received the impression and whether it actually resolves the full request.

    A spreadsheet works for a small export. A language model can accelerate a larger clustering task, but preserve every original query so you can audit its grouping. A useful instruction is: Group these queries by user job, entity, decision context, and concern. Preserve each original query, name the likely content gap, and do not infer which platform generated the query.

    Treat query exports as potentially sensitive. Conversational strings can contain personal information. Remove or mask identifiable details before uploading the file to an external analysis tool, and follow your organization’s data-handling rules.

    The result should not be an enormous list of literal sentences to monitor. Build a smaller prompt-tracking set around recurring themes. Prioritize a theme when it repeats, has a meaningful commercial or reputational consequence, intersects with a page already receiving visibility, and can be answered with credible content.

    For example, several differently worded queries may all ask whether your company is a safe alternative to a better-known competitor. Track representative comparison and risk-objection prompts, then create or improve the page that should answer them. The theme is durable even when the exact wording changes.

    Build the topical signals Discover is trying to reward

    The February 2026 update was designed to surface more locally relevant material, less sensational content, and more original, timely, in-depth work from sites with subject-specific expertise. Those are editorial directions, not a checklist that guarantees feed placement.

    Build a recognizable topical footprint

    Discover’s expertise assessment can operate topic by topic. A broad publisher can establish a strong specialist section, while a site with one unrelated page offers much weaker evidence of sustained knowledge. You do not need to turn the whole domain into a single-topic publication, but the section you want recognized must be coherent.

    Audit that footprint directly:

    • Name the subject for which you want the site or section to be recognized.
    • Label existing URLs as core coverage, genuinely supporting coverage, or unrelated material.
    • Connect related pages through clear navigation and internal links so the section is understandable as a body of work.
    • Use long-query clusters to find missing questions that belong naturally inside the subject.
    • Resist publishing a one-off page merely because a neighboring topic is popular.

    The aim is not volume. It is continuity. Each new page should deepen the same audience’s understanding or help that audience complete the next related task.

    Make originality, depth, and timeliness visible

    Calling content original is not enough. The distinct contribution should be easy to identify. Before publishing, ask what the page adds that a competent reader could not get from a generic summary.

    • Originality: include your own reasoning, evidence, process, examples, or decision criteria rather than merely restating familiar advice.
    • Depth: answer the follow-up questions, constraints, tradeoffs, and failure cases implied by the main query.
    • Timeliness: explain what changed and why the change affects the reader. Do not refresh a date when the substance is unchanged.
    • Actionability: give the reader a next step, setting, filter, check, or decision they can actually use.

    The conversational-query export can guide this work. If users repeatedly add the same constraint to a broad query, that constraint belongs in the content. If they keep asking about an old reputational issue, silence does not make the concern disappear; a current, factual answer may be necessary.

    Treat local relevance as audience fit, not decoration

    The update placed more weight on locally relevant content from domestic websites. A non-U.S. publisher serving a U.S. audience could therefore have experienced reduced Discover traffic during the initial U.S. rollout.

    Segment that audience before reacting. If the decline is limited to U.S.-facing pages, examine whether the material genuinely reflects the market’s places, rules, products, terminology, and context. Do not disguise the site’s origin or add superficial location phrases. If your strongest expertise belongs to another market, preserve it and make the geographic scope explicit.

    Remove the gap between the headline and the page

    Discover’s move away from sensational content makes the headline-content relationship a practical audit point. The title should communicate the real value of the page without withholding the central fact or overstating the evidence.

    • Put the actual subject and consequence in the headline.
    • Remove unsupported superlatives, manufactured urgency, and curiosity gaps.
    • Deliver the promised answer near the beginning, then add context and depth.
    • Check that the headline still makes sense when separated from the image and surrounding feed.
    • If a restrained headline makes the content seem uninteresting, improve the substance instead of restoring the hype.

    Google also said its systems would continue personalizing Discover around favored creators and sources. You cannot force that preference, but consistent subject expertise and dependable promises give readers a coherent reason to recognize and return to your work.

    Key takeaways and your next move

    • Diagnose Search and Discover separately; a change in one surface does not establish a change in the other.
    • The February 2026 Discover core update ran from February 5 through February 27 and initially covered U.S. users viewing English content.
    • Use the 10-word Search Console regex to find conversational demand, but do not label every long query as an AI prompt.
    • Track recurring prompt themes rather than every literal query variation.
    • For Discover, strengthen sustained topic expertise, original depth, genuine timeliness, honest local relevance, and headline-content alignment.
    • Make changes only after you have identified the affected surface, audience, metric, and page cluster.

    Your next visibility review should end with one explicit hypothesis. Write down the surface, change window, country, affected pages, impression pattern, click pattern, proposed change, and metric that would support or weaken the hypothesis.

    Then change the smallest relevant layer. Fix measurement when the data disagrees, improve a page when conversational demand exposes an answer gap, or strengthen a coherent topic section when the Discover loss is concentrated there. Evaluate the result on the same surface and segment that led you to act.

    References

  • How to Use AI Response Patterns to Build Better Content

    How to Use AI Response Patterns to Build Better Content

    You ask an AI assistant which product, service, or method it recommends. Your brand appears. You run the same prompt again, and it disappears. If you build a content brief around either answer, you may be optimizing for an accident.

    The better unit of analysis is the pattern across many answers. Repeated structures, concepts, comparisons, and entity associations can show you what a model consistently treats as relevant. Once you separate those durable signals from one-off wording, AI responses become useful inputs for content planning rather than volatile rankings to chase.

    Key takeaways

    • Do not treat one AI answer, citation, or brand mention as a ranking result.
    • Test several phrasings of the same intent across at least two model families and repeated runs.
    • Keep web-search settings, model labels, context, and prompts documented so you know what changed.
    • Classify recurring signals as structural, conceptual, or entity patterns before editing content.
    • Use a working threshold to filter noise, then apply audience knowledge and factual review before acting.

    A single AI answer is not a position you can rank for

    Traditional rank tracking works because a search result has an ordered position that can be checked again. An AI response is generated probabilistically. Its wording, selections, order, and level of detail can change with the prompt, conversation context, model, retrieval method, and search setting.

    The variation can be substantial. Across one large prompt test, ChatGPT or Google AI had a less than 1% chance of returning the same brand list in two responses. That does not mean every topic will be equally unstable. It does mean that a single inclusion or omission is too fragile to support a content decision.

    Separate two questions that teams often mix together:

    • Visibility question: Did the model mention or cite your brand in this sample?
    • Pattern question: Which ideas, criteria, entities, and answer structures kept returning across the sample?

    The first question produces a volatile observation. The second can reveal a usable content opportunity. If renewal pricing appears in most answers about choosing a domain registrar, for example, you have evidence that the concept belongs in the decision journey. You still do not know that adding a renewal-pricing section will cause a citation. You do know that omitting the issue may leave the page incomplete for that cluster of questions.

    This distinction also changes how you report results. A sentence such as “we rank in ChatGPT” claims a stable position that may not exist. A defensible statement is narrower: your brand appeared in a stated share of a documented response sample, under specified test conditions. For content planning, the recurring concepts and associations in that sample are usually more actionable than the mention count alone.

    Build a response sample that can separate signal from noise

    Many abstract response tiles pass through a mesh filter, leaving repeated shapes grouped together while irregular fragments fade away.

    You do not need an expensive monitoring platform to begin. You do need a repeatable collection method. A spreadsheet is enough if every row records the conditions that could explain a different answer.

    1. Choose a small set of decision topics. Start with three commercially or editorially important topics. A topic should represent a decision or task your audience actually brings to an AI assistant, not just a keyword you want to rank for.
    2. Create three to five prompt variations per topic. Keep the underlying intent stable while changing the wording. A domain-registration cluster might include “How do I register a domain name?”, “How can I get a domain name?”, and “Where can I buy a domain?” Do not mix an introductory how-to prompt with a migration or troubleshooting prompt and call them one cluster.
    3. Define the test conditions. Select at least two model families. Decide whether web search will be enabled, disabled, or left to the model. If you test more than one search condition, analyze each as a separate segment. Use fresh or private sessions where possible so an earlier conversation does not silently alter the next response.
    4. Capture every response consistently. Record the prompt, displayed model or version, web-search status, date, full response, cited URLs, brand mentions, and any initial pattern labels. Preserve the complete answer; excerpts can hide section order and qualification.
    5. Repeat on a fixed cadence. Weekly collection is practical for many teams. Consistency matters more than running a large burst once and then changing the prompt set. Build toward 20 to 30 responses per prompt before drawing strong conclusions.

    Your tracking sheet can start with these columns:

    • Topic cluster
    • Exact prompt
    • Model and displayed version
    • Web search: enabled, disabled, or model-decided
    • Date
    • Full response
    • Citations or referenced URLs
    • Your brand mentioned: yes or no
    • Structural labels
    • Concept labels
    • Entity and association labels

    Do not pool unlike conditions without labeling them. A response produced with live web retrieval is not equivalent to one generated without it. A model update can also change the output even when your site and prompt remain untouched. Recording those conditions protects you from crediting your content for a change caused elsewhere.

    A useful working definition of a strong pattern is one that appears in at least 75% of the sampled outputs, across two models and multiple prompt variations. The threshold is a filter, not a law of AI behavior. It forces you to demand recurrence in more than one environment before calling an observation meaningful.

    Always retain the numerator and denominator. “Pricing transparency appeared in 9 of 12 responses” is auditable. “AI cares about transparent pricing” turns a bounded observation into an unsupported universal claim. If you work alone and cannot collect a full sample, you can flag patterns beginning around 60% as provisional, but keep them separate from patterns that clear the stronger threshold. A smaller workload should reduce your confidence, not disappear from the methodology.

    Read each response pattern at three different layers

    Three concentric transparent layers organize surface shapes, connected concepts, and generic objects around a central subject.

    Frequency alone does not tell you what to change. First classify what is recurring. Structural, conceptual, and entity patterns answer different editorial questions and lead to different actions.

    Pattern layerWhat you recordWhat it can changeCommon misreading
    StructuralSection order, lists, steps, comparisons, pros and cons, tables, and depthAnswer architecture and information sequenceCopying the model’s format as if it were a required template
    ConceptualRecurring criteria, risks, questions, features, and tradeoffsTopic coverage and explanation depthTreating every repeated phrase as a keyword to insert
    EntityBrands, products, tools, sources, categories, and feature associationsPositioning, evidence, comparisons, and partnership researchAssuming an omission proves a technical or reputation problem

    Structural patterns reveal the expected path through an answer

    Mark how each response is assembled. Does it begin with a definition, move into selection criteria, name tools, and end with implementation? Does it repeatedly use a comparison table? Does it frame the decision through advantages and disadvantages, or as a numbered procedure?

    If the sequence “definition > criteria > tools > implementation” persists across prompts and models, it is a clue that the topic is commonly synthesized as both an explanation and a decision process. Your page may need to support both. That does not require copying the sequence mechanically. A reader who already understands the category may need the criteria first, while a beginner may need a short definition before making sense of those criteria.

    Record the level of detail as well as the headings. A recurring step that receives several qualifications is more informative than a heading that appears but gets one sentence. The useful editorial question is not merely “Was this topic mentioned?” It is “What role did this topic play in helping the response reach a recommendation or action?”

    Conceptual patterns identify the criteria a page must handle

    Concepts are the recurring considerations inside the answer. For a domain-registrar decision, those may include initial and renewal pricing, customer support, privacy, email add-ons, security, bundles, and transfer procedures. A concept that returns across differently phrased prompts is more useful than an exact phrase repeated by one model.

    Turn each recurring concept into a question for the content, not an instruction to add a keyword. If renewal pricing is a strong pattern, ask:

    • Does the page distinguish the introductory price from the renewal price?
    • Can the reader locate that information without interpreting vague pricing language?
    • Does the comparison use equivalent billing periods and inclusions?
    • Are exceptions or conditions stated where they affect the decision?

    This approach improves usefulness even if the wording in future AI responses changes. It also prevents superficial optimization. Repeating “pricing transparency” does not make pricing transparent; showing the relevant terms clearly does.

    Entity patterns show how the category is being framed

    Entity analysis tracks more than which brands appear. Record which features, audiences, or use cases are attached to each entity, where the entity appears in the answer, and which pages are cited in support.

    Suppose a competitor repeatedly appears beside “simple transfers” while your brand appears beside “bundled services.” That pattern does not establish either claim as true. It does reveal the associations you should verify. Check whether your product documentation, comparison pages, and third-party coverage make the relevant capabilities explicit. If the association is inaccurate, the answer is not to imitate it. Clarify your actual positioning with evidence.

    An absent brand can have several explanations: model variability, an unfamiliar prompt, retrieval choices, weak category association, insufficient supporting content, or no factual fit for the recommendation. The response sample cannot diagnose the cause on its own. Use it to form a question, then inspect your content and real market position before choosing a remedy.

    Convert the pattern map into a content brief

    Once the sample is labeled, do not hand the raw answers to a writer and ask for an average version. That tends to reproduce generic phrasing and whatever biases already dominate the outputs. Convert the recurring signals into editorial requirements that leave room for expertise, original evidence, and a clear point of view.

    1. Name the reader’s decision. Write one sentence describing what the page must help the reader decide or complete. If your prompt variations contain different decisions, split the cluster before drafting.
    2. Write the direct answer first. State the useful answer in plain language before designing headings. This keeps a recurring AI structure from displacing the reader’s actual need.
    3. Select the structural pattern that supports that decision. Use a procedure for a task, a criteria-led structure for a purchase decision, or a comparison only when the underlying options are genuinely comparable.
    4. Translate strong concepts into coverage requirements. Record the observed frequency and the question each concept must answer. Specify required depth, such as a definition, caveat, example, or decision rule.
    5. Audit entity claims. List the brands, tools, features, and category relationships that require verification. Decide which claims need first-party documentation and which need credible independent support.
    6. Define what the page will not cover. Exclude concepts that belong to another intent or page. A recurring term is not permission to turn one focused answer into an unfocused topic warehouse.

    A practical response-pattern brief should contain these fields:

    • Reader and decision: who the page serves and what they must be able to do afterward.
    • Prompt cluster: the exact variations used to collect the sample.
    • Test conditions: models, versions, search settings, dates, and number of responses.
    • Direct answer: the page’s concise answer to the shared intent.
    • Strong structural patterns: recurring answer sequences and formats, with counts.
    • Strong conceptual patterns: required considerations, with counts and planned treatment.
    • Provisional patterns: useful leads that need more sampling or independent audience evidence.
    • Entity associations: repeated brand-feature or tool-use-case pairings that require verification.
    • Evidence plan: where facts, prices, limitations, and comparisons will be substantiated.
    • Exclusions: adjacent intents that belong on another page.

    Then run a simple editorial test on every proposed section. Can you trace it to a strong response pattern, direct audience evidence, necessary factual context, or the page’s stated decision? If not, remove it. For every strong concept, confirm that the draft answers the underlying question rather than merely using the model’s preferred vocabulary.

    The finished page should also add value that pattern analysis cannot supply. That may be a clearer decision rule, documented limitations, precise product information, a transparent comparison method, or an explanation of when the common recommendation does not apply. AI responses can expose the recurring frame. They should not set the ceiling for the content.

    Measure batches, not anecdotes, after you publish

    Preserve a baseline response batch before making a substantial update. After the revised page is available, repeat the same prompt set under comparable conditions. Keep the old and new batches separate, and document any model or search-mode change between them.

    Track a small group of interpretable measures:

    • Pattern persistence: which structural, conceptual, and entity patterns remain strong across later batches.
    • Concept coverage: whether the target page now answers each relevant strong concept accurately and at the required depth.
    • Brand mention rate: the number of sampled responses mentioning the brand divided by the total responses in that segment.
    • Association quality: whether the context around the brand is accurate, relevant, and aligned with its actual offer.
    • Citation behavior: whether the page is cited, what claim it supports, and whether the cited source is appropriate.
    • Page performance: whether conventional search visibility, qualified visits, engagement, and conversions move in a useful direction for the page’s purpose.

    Do not treat movement in a small AI sample as proof that your edit caused it. Models may draw from training data, live search, or a combination that is not obvious to the tester. Their behavior can also change after a new model release. A before-and-after batch gives you a better observation, not automatic causality.

    Use three decision rules to keep the program disciplined:

    • Act: A pattern clears your strong threshold across models and prompts, matches the reader’s decision, and can be addressed truthfully.
    • Investigate: A provisional pattern is strategically important but needs a larger sample, audience validation, or factual checking.
    • Ignore for now: A detail appears in isolated responses, depends on one model or wording, conflicts with reliable facts, or does not help the target reader.

    Watch for the feedback loop that makes every page look like an existing AI answer. Training-data bias, retrieval uncertainty, factual errors, and dominant category conventions can all recur. Repetition proves that a pattern exists in your sample; it does not prove that the pattern is correct, fair, current, or useful. Human review is the step that turns recurrence into an editorial decision.

    Choose one important prompt cluster for your next brief. Freeze the variations and test conditions, collect the first documented batch, and label the three pattern layers before changing the page. The question to carry into the edit is not “What did the AI say?” It is “What persisted, under which conditions, and what does our reader genuinely need from us?”

    References


  • Google Discover Ranking Signals: A Practical Optimization Guide

    Google Discover Ranking Signals: A Practical Optimization Guide

    Your page can be crawlable, polished and successful in search yet receive little or no Google Discover exposure. The common mistake is treating Discover as another blue-link ranking system. It is a personalized, visual feed with gates that can remove a page or publisher before ranking begins.

    That changes how you should diagnose a weak result. First verify eligibility and card integrity. Then examine interest fit, predicted click appeal, freshness and user feedback. This order helps you fix the layer that is actually limiting visibility instead of rewriting content that never reached the ranking stage.

    Discover ranking starts after several ways to disappear

    Discover uses multiple qualification, matching, ranking, presentation and feedback stages. Ranking is only one part of that pipeline:

    1. Google crawls and interprets the page.
    2. It extracts card information such as the title and image.
    3. It classifies the content, including whether it is breaking, recent or evergreen.
    4. Eligibility rules and blocks can remove it.
    5. Remaining candidates are matched with a person’s interests.
    6. A server-side model predicts the likelihood of a click.
    7. The feed layout is assembled.
    8. The selected card is served.
    9. Interactions and feedback are recorded.

    This sequence explains why a ranking-focused edit may accomplish nothing. A missing image, an exclusionary meta tag or a publisher block can stop the page before its title, historical engagement and predicted click-through rate have a chance to compete.

    Publisher blocks are especially consequential. When a person chooses not to see content from a publisher, the domain can be removed from that person’s candidate set before interest matching. That is broader than dismissing one URL, although it does not mean the domain is suppressed for every user. No mirror-image domain-wide boost was exposed in the same pipeline.

    Start every investigation by distinguishing absence from underperformance. If the page is not producing meaningful exposure, inspect qualification, card construction, age and audience fit first. If it is being shown but attracts few clicks, the title-image combination and its relevance to the matched audience become more plausible constraints. Neither symptom proves a single cause, but the distinction keeps your audit pointed at the right stage.

    The ranking signals you can actually work on

    Different image-only content tiles travel through a central selection chamber along separate glowing paths to readers with distinct interests.

    Once a page survives the earlier filters, a server-side predicted click-through rate model estimates whether someone is likely to open it. The model and its weights have not been disclosed. Client-side telemetry does, however, expose several of the inputs and conditions surrounding that decision.

    Signal or conditionHow it enters the feedWhat to check
    TitleThe card title is taken from og:title. If it is missing, Google may fall back to a Twitter title or the HTML title.Inspect the emitted HTML and make sure all title fields describe the same page. Do not let an old template value become the unintended fallback.
    ImageImage dimensions, quality and successful loading affect card treatment. A missing image can leave the page without a card.Open the exact og:image URL, verify that it loads and confirm that the asset is at least 1200 pixels wide if you want eligibility for the larger card presentation.
    FreshnessContent age is grouped into decay windows, with the strongest advantage during the first seven days.Record the real publication age before diagnosing a later decline as a title or technical problem.
    URL historyPrevious clicks and impressions for the URL can inform predicted engagement.Evaluate a page in the context of its own exposure history. A result from another URL or topic is not a clean substitute.
    Personal relevanceBroader interest data and individual actions such as follows, saves, dismissals and reading engagement help shape the feed.Define the specific interest the page serves. A generally interesting subject is not the same as a strong match for a particular person.
    Publisher contextPublisher-level signals can include Publisher Center registration, while a person’s publisher block can exclude the domain from that person’s feed.Keep publisher identity consistent and treat every card as part of a domain-level relationship, not only as an isolated URL.

    The image threshold deserves literal treatment. An asset that is 1199 pixels wide does not meet a 1200-pixel requirement. Smaller images may still appear as thumbnails, but thumbnail cards generally provide less visual space and tend to attract fewer clicks. The practical target is therefore not merely having an image. You need a suitable, accessible image attached to the metadata Google reads.

    The title fallback chain is another frequent source of confusion. Your editorial interface may show the intended headline while the page emits a stale og:title. In that case, the social card field can govern Discover’s title. Check the final HTML delivered by the page rather than assuming the visible on-page heading and metadata match.

    Two less obvious meta directives also belong in the qualification audit. The exposed behavior indicates that nopagereadaloud and notranslate can prevent Discover appearance. If either directive is generated by a sitewide template, localization plugin or publishing workflow, confirm that its presence is intentional before changing copy or images.

    Do not turn this signal list into a formula. Predicted click-through rate is a model output, not a field you can set, and the available evidence does not reveal a reliable weight for each input. Your job is to remove preventable defects and create a truthful, immediately understandable card. A title-image combination that wins a click but disappoints the reader can still lead to a dismissal or publisher block.

    Freshness creates a clock, not an automatic expiration date

    Content age is not treated as a smooth, uniform curve from the moment of publication. The exposed freshness model uses four practical age bands:

    Age of contentExpected freshness treatmentOperational implication
    1-7 daysStrongest freshness boostComplete metadata, image and loading checks before publication so the best window is not spent repairing the card.
    8-14 daysModerate visibility remains possibleSeparate a normal reduction in freshness from a technical failure. Review exposure and click behavior before making large changes.
    15-30 daysVisibility tends to fallExpect age to become a stronger competing explanation when performance declines.
    More than 30 daysGradual decay continuesDo not assume exclusion. Determine whether the page has durable evergreen value and whether a substantive update is editorially warranted.

    These bands describe relative treatment, not guaranteed traffic. A one-day-old page can still fail eligibility or interest matching, while older content may receive an evergreen classification. Freshness is an advantage after the page qualifies; it cannot repair a missing card, an accidental block or a weak audience match.

    The first seven days should change your publishing workflow. Finish the large image, metadata and page-loading checks before the URL goes live. If those tasks wait until the next morning, part of the strongest freshness window has already passed. Coordinate the initial distribution during that same period rather than treating publication and promotion as unrelated jobs.

    Do not read the decay model as permission to change a date without changing the content. Nothing in the exposed mechanics establishes that a timestamp edit alone reliably resets classification or restores distribution. If a mature page deserves renewed attention, make the update useful on its own merits, confirm the card again and then judge the result without assuming a reset.

    User feedback can narrow future opportunity

    Discover is not just personalized when the feed is first assembled. It learns from direct actions and reading behavior. Follows, saves, story dismissals and time spent with content can influence what a person sees next. The feed can also add, remove or reorder cards while someone scrolls, without requiring a manual refresh.

    The scope of each negative action matters. A dismissal is stored for the specific URL and prevents that story from reappearing for that person. A publisher block is broader: it can remove the domain from that person’s feed before future pages are matched with interests. That asymmetry makes a misleading card a publisher-level risk, even when it succeeds at generating the first click.

    Use that distinction when reviewing content. For an individual URL, ask whether the title and image promise the same experience the page delivers. At the publisher level, look for repeated patterns that could make someone reject the whole domain: unclear topic fit, cards that routinely overstate the content or inconsistent value between pages. You may not be able to attribute every block to a specific card, but you can remove the recurring reasons a reader would choose one.

    Feed experiments add another layer of noise. During one observed period, about 150 server-side experiments and more than 50 card-presentation features were active. Two people with similar interests can therefore receive different layouts or selections because they are in different experimental groups.

    A single device check is useful for spotting a broken image or malformed title, but it is not a ranking test. Do not treat one person’s feed position, card shape or absence as a stable benchmark. Look for repeated patterns across comparable URLs and time windows, while remembering that a page moving down after its first week may reflect freshness decay rather than an editorial mistake.

    Run your Discover audit in pipeline order

    A content card moves through ordered eligibility, image, interest, appeal, time, and feedback checkpoints while flawed cards are diverted early.

    When visibility disappoints, use the same sequence the feed uses. Stop at the first failed check, correct it and verify the result before redesigning everything downstream.

    1. Confirm basic qualification. Make sure Google can crawl and interpret the page, then check for nopagereadaloud, notranslate or another intentional publishing restriction.
    2. Inspect the delivered metadata. Read the final og:title and og:image values from the page. Check the Twitter and HTML titles as possible fallbacks rather than relying only on the CMS preview.
    3. Validate the image as a card asset. Open the exact image URL, verify that it loads and confirm a width of at least 1200 pixels for the larger presentation. A visually attractive file that fails to load is still a failed signal.
    4. Place the URL in its freshness band. Record whether it is 1-7, 8-14, 15-30 or more than 30 days old. Use that context before interpreting a rise or decline.
    5. Name the intended interest match. Complete the sentence: this page is for a person who follows or engages with this specific subject. If the answer is only a broad demographic, the content proposition is probably not precise enough for a personalized feed.
    6. Review the predicted-click inputs. Put the title and image together as a card. Check whether they communicate a specific, accurate reason to open the page without depending on context that appears only inside the body.
    7. Assess feedback risk. Compare the card’s promise with the first screen and the substance of the page. Remove gaps that might win an initial click but invite a URL dismissal or publisher block.
    8. Interpret results as a pattern. Compare similar pages and equivalent age windows. Treat a single feed view as a rendering check, not proof of ranking success or failure.

    Key takeaways

    • Google Discover can filter a page or publisher before interest matching and ranking begin.
    • The ranking stage uses a server-side predicted click-through rate model, but its formula and signal weights are not public.
    • Card titles primarily come from og:title, with Twitter and HTML title fields available as fallbacks.
    • Images should load correctly and be at least 1200 pixels wide for eligibility for a prominent card treatment.
    • Freshness is strongest at 1-7 days, moderates at 8-14 days, falls at 15-30 days and gradually decays beyond 30 days.
    • A story dismissal applies to one URL for one person, while a publisher block can remove the entire domain from that person’s feed.
    • Experiments and live feed reordering make individual screenshots unreliable as performance benchmarks.

    Choose one recently published URL and run only the first three audit steps before changing its writing. If qualification, metadata or image delivery fails, fix that layer first. If all three pass, move to interest fit, predicted click appeal, freshness and feedback in that order. This gives you a defensible diagnosis even when Discover itself remains variable.

    References

  • How to Turn AI Search Visibility Into Measurable LLM Traffic

    How to Turn AI Search Visibility Into Measurable LLM Traffic

    Your brand can appear in an AI answer and still send almost no visible traffic to your analytics. It can also send only a handful of visits that produce valuable leads or purchases. If you judge both outcomes by sessions alone, you will either dismiss AI search too early or overstate what it contributes.

    The practical answer is to manage AI visibility as a pipeline: access, source selection, click and business outcome. Each stage needs its own metric and its own fix. Once you separate them, you can tell whether you have a visibility problem, a traffic problem or a conversion problem.

    Key takeaways

    • An AI citation is exposure, an LLM referral session is a click, and a conversion is a business outcome. Do not combine them into one visibility number.
    • Track both LLM share of referral traffic and LLM share of total site traffic. They answer different questions and must use different denominators.
    • Keep raw sessions and conversions beside percentage metrics. Low traffic volumes can make conversion rates look more stable than they are.
    • Ordinary SEO still matters. Crawl access, clear page structure, descriptive metadata, internal links and authoritative mentions help make content discoverable.
    • ClaudeBot, Claude-User and Claude-SearchBot perform different jobs. Set crawler policy for each instead of treating all Claude access as one decision.

    Measure the four-stage path, not one visibility score

    Four connected checkpoints show an access gate, selected source document, visitor crossing and business outcome, with one checkpoint partly obstructed.

    A conventional analytics report begins after someone clicks. AI discovery often begins much earlier, and an answer can mention your brand without generating a visit. Your scorecard therefore needs four layers.

    1. Access: Can the relevant crawler or user-initiated fetcher retrieve the page? Check robots.txt, page availability, indexing controls and server responses.
    2. Selection: Does the brand, domain or page appear in answers for a fixed set of relevant prompts? Record mentions and citations separately because an answer can name a brand without linking to it.
    3. Visit: How many detectable referral sessions arrive from ChatGPT, Perplexity, Gemini, Claude and other identified LLM sources? Break them down by source and landing page.
    4. Outcome: How many of those visits produce the event that matters to the business, such as a purchase or qualified lead? Keep that event definition consistent across channels.

    From Jan. 1, 2025, through Feb. 7, 2026, one customer-base dataset found that identifiable LLM traffic from ChatGPT, Perplexity, Gemini and Claude represented between 0.15% and 1.5% across the sites examined, remained below 2% of referral traffic and converted at 18%. The conversion events were tied to substantial outcomes such as purchases and lead generation.

    Those figures are useful orientation, not a forecast for your site. Industry, audience, analytics configuration and the definition of a conversion can all change the result. A small channel can also produce a high rate from very few conversions, so report the numerator and denominator: sessions, conversions and conversion rate.

    Be exact about traffic share. LLM referral sessions divided by all referral sessions measures the channel’s share of referral traffic. LLM referral sessions divided by all site sessions measures its share of total acquisition. A result below 2% of referral traffic cannot automatically be restated as below 2% of all site visits.

    Your working report should include the following fields:

    • LLM source
    • Landing page
    • Referral sessions
    • Defined conversion event
    • Number of conversions
    • Conversion rate using a documented denominator
    • Visibility or citation status for the relevant prompt group
    • Notes on page updates, crawler changes, PR activity and distribution

    Keep the LLM source group editable. The mix of platforms and the pages cited in answers can change, so a report hard-coded around one provider will become incomplete. Referral analytics also measures detectable clicks, not every citation or unlinked mention. A zero in the referral column does not prove zero AI visibility.

    Make each important page easy to retrieve and cite

    AI search optimization does not replace SEO. The companies operating generative AI products also invest in technical SEO, content, conversion paths and organic acquisition. For your site, the same foundation determines whether a useful answer is available in a form that machines and people can understand.

    Use a citation-ready page pattern

    1. Give the page one clear job. Target a specific question, task or decision instead of combining several loosely related intents.
    2. Answer before expanding. Put the direct answer near the start, then explain conditions, exceptions and evidence. Do not make a reader hunt through a long preamble.
    3. Label the useful units. Descriptive headings, lists and genuine comparison tables make definitions, steps and distinctions easier to locate.
    4. Separate fact from recommendation. State what is documented, what depends on context and what you recommend. This prevents a conditional claim from looking universal.
    5. Offer value beyond the extracted answer. Original examples, methods, tools, templates or deeper supporting detail give an interested user a reason to visit the page.
    6. Match the next action to the query. A visitor who arrived for a technical answer should see a relevant technical next step, not a generic request to contact sales.

    Do not neglect basic on-page signals. Clear meta titles, useful descriptions, readable URLs, accurate tags and descriptive image names are among the technical and content elements associated with stronger search discovery. They will not force an AI system to cite you, but missing or vague signals create avoidable ambiguity.

    Distribute one consistent evidence set

    A strong page can still remain isolated. Align SEO, social distribution, PR and supporting content around the same canonical evidence rather than publishing disconnected versions of the claim. A unified SEO, social, PR and content strategy gives the brand more consistent language, mentions and paths back to the page you want treated as the primary resource.

    Start with the canonical page. Give it the complete answer and supporting detail. Supporting articles can address narrower questions and link back to it. Social posts can surface individual findings without changing their meaning. PR outreach can point to the same evidence when it is genuinely relevant. Keep the brand name, product names, category language and core claims consistent across these surfaces.

    Consistency does not mean copying the same paragraph everywhere. It means that the entity, claim and destination remain stable while the format changes for each channel. If five pages compete to be the definitive version, you have made source selection harder for search systems and readers alike.

    Choose Claude crawler rules by purpose

    A site administrator routes neutral robotic crawlers through different entrances of a structured website archive while one entrance remains closed.

    AI training access and AI search visibility are separate decisions. Anthropic identifies three Claude user agents with different functions, so blocking one does not automatically block the others.

    User agentPurposeWhat blocking changes
    ClaudeBotCollects public web content for model training.Excludes the disallowed pages from this training crawl. It does not by itself block user-requested retrieval or search indexing.
    Claude-UserFetches a page when a user asks Claude to access information that requires it.Prevents those user-initiated fetches from retrieving disallowed pages, which can remove your content from relevant response workflows.
    Claude-SearchBotIndexes material used to improve Claude search results.May reduce the visibility or accuracy of your content in Claude-enhanced search responses.

    If you want to block only the training crawler across the site, the directive is:

    User-agent: ClaudeBot
    Disallow: /

    Create a separate group for every bot you intend to control. If your subdomains have different policies, publish the appropriate robots.txt file on each one. Anthropic’s bots support standard directives including Disallow and Crawl-delay.

    Do not use broad public-cloud IP blocking as a substitute for a precise crawler policy. These bots can operate through public cloud infrastructure, so an IP-level rule can affect unrelated traffic and may interfere with access to robots.txt. Save the previous file, verify the exact user agent and path you are changing, fetch the live robots.txt after deployment, and inspect server logs for the expected behavior. A misplaced site-wide rule can materially reduce discovery.

    Run a monthly cycle around the weakest stage

    Do not begin each month by asking how to get more AI traffic. Begin by locating the bottleneck. The answer determines whether you need analytics work, a crawler change, a better page or stronger distribution.

    1. Save the baseline. Record LLM sessions, landing pages, conversions, conversion rates and results from a stable set of commercially relevant prompts. Preserve raw counts.
    2. Check access. Review robots.txt, page availability, indexing controls, canonical destinations and the Claude user agents that match your policy.
    3. Improve the highest-intent weak page. Clarify its answer, heading structure, metadata, evidence and next action. Log the publication date so a later change can be connected to the work.
    4. Coordinate distribution. Point relevant supporting content, social activity and PR toward the canonical page while keeping the core entity and claim consistent.
    5. Review by source and landing page. Compare the new period with the saved baseline, but do not call a percentage change meaningful without looking at the underlying session and conversion counts.

    Use the pattern of results to choose the next action:

    • No appearances and no visits: investigate access, page relevance, answer clarity, internal discovery and external authority. Conversion work is not yet the bottleneck.
    • Appearances but no detectable visits: treat the citation as visibility, not traffic. Check whether the page offers a compelling reason to continue beyond the generated answer. Some informational prompts will naturally produce few clicks.
    • Visits but no conversions: inspect the landing page’s intent match, offer and next step. More citations will amplify the same conversion problem.
    • Conversions from low volume: protect the working page and expand into closely related high-intent questions. Do not assume the observed conversion rate will remain unchanged as volume grows.
    • Traffic without known visibility: confirm the referral classification and add the source and landing page to your monitored prompt set. Your visibility measurement may be missing a real route into the site.

    Start with one report, one explicit crawler decision and one high-intent page. Annotate each change. The next monthly review will then tell you which stage moved and where the next unit of effort belongs, even while total LLM traffic remains small.

    References

  • How to Optimize Content for Search, Answers, and AI Agents

    How to Optimize Content for Search, Answers, and AI Agents

    You can publish accurate, polished, keyword-relevant content and still struggle for visibility. As AI makes publishing easier, the competitive problem is increasingly sameness across otherwise competent pages. A page that merely restates the standard advice gives a searcher, answer engine, or agent little reason to prefer it.

    You do not need to abandon SEO or start separate programs for every new acronym. You need one operating model that makes each important page discoverable, easy to extract, connected to a clearly defined entity, credible enough to recommend, and complete enough to support a decision.

    Key takeaways

    • Keep the SEO foundation. Clear titles, headings, descriptive language, crawlable content, and intent alignment still determine whether a page gets found and understood.
    • Optimize for four nested outcomes: be found, become the answer, earn the recommendation, and supply enough verified information to be chosen.
    • Design for three kinds of processing: traditional search retrieval, language-model extraction, and entity or knowledge-graph understanding.
    • Refresh useful pages before creating more of the same. Fix the promise, answer order, specificity, entity facts, and technical accessibility.
    • Use structured data to reinforce visible, consistent facts. It cannot repair vague positioning or contradictory information.
    • Let AI accelerate inventory, variation, and formatting work. Keep intent, factual verification, differentiation, and final editorial judgment with a person.

    Optimize for four outcomes, not four disconnected channels

    The language around AI search is unsettled. SEO, AEO, AIEO, GEO, entity SEO, LLM optimization, and assistive agent optimization describe overlapping parts of the same environment. Building a separate workflow around every label creates duplicated briefs, conflicting measurements, and pages that optimize one layer while neglecting the others.

    A more useful approach is to treat optimization as a sequence of outcomes. Each later outcome depends on the earlier ones, so the work compounds instead of restarting whenever the terminology changes.

    LayerRequired outcomeThe question your page must answer
    SEOBe foundCan a system discover, interpret, and match this page to the searcher’s actual need?
    AEOBe the answerCan an answer engine extract a direct, accurate response without reconstructing it from several vague sections?
    AIEOBe recommendedAre the offering, audience, constraints, and evidence clear enough to support a comparison?
    AAOBe chosenCan an assistive agent verify the decisive facts and identify the correct next action?

    This does not mean every informational page must close a transaction. It means the page should completely perform its assigned job. A definition page may need to resolve a concept and point to the next relevant question. A service page may need to establish fit, exclusions, evidence, and a contact path. A product page may need to expose the attributes on which selection depends.

    Use one brief with four acceptance criteria:

    • Discovery: State the problem in the language a person would recognize, then reflect it in the title, primary heading, description, and opening.
    • Extraction: Put the core answer in a self-contained passage. Do not make a system combine an introduction, a definition, and a conclusion to infer your position.
    • Recommendation: Name who the advice or offering is for, when it applies, what constraints matter, and what makes it preferable in that situation.
    • Selection: Supply the facts, corroboration, and next step required to move from consideration to action.

    If a page cannot pass the first layer, work on crawlability and intent before debating agent optimization. If it is discoverable but never mentioned, improve answer clarity and entity definition. If it is mentioned but not recommended, the missing layer is usually decision-grade detail rather than another block of general background.

    Design pages for search, language models, and knowledge graphs

    An isometric web page structure is examined by a search lens, an abstract language model, and a network of linked entity nodes.

    A practical model for AI-era retrieval has three components: traditional search, large language models, and knowledge graphs. Their relative influence can vary by platform and task, but the model prevents you from optimizing only the visible prose or only the technical markup. Think of it as three different readings of the same page.

    Traditional search needs a clear promise and accessible content

    The title, primary heading, description, internal organization, and crawlable copy tell a search system what the page is about. They also tell a person whether the result is worth opening. That second role matters: titles and descriptions are not administrative metadata. They are decision copy.

    Write the title after you can complete this sentence: “This page helps [specific audience] do or decide [specific thing] under [relevant condition].” You do not have to use that entire sentence as the title. Its purpose is to expose a vague brief before the vagueness reaches the page.

    Compare these title shapes:

    • Broad: AI Content Optimization
    • Intent-aligned: How to Optimize Service Pages for AI Recommendations
    • Constraint-aware: How to Optimize Service Pages for AI Recommendations Without Rebuilding the Site

    The sharper version identifies the object, desired outcome, and practical constraint. It helps the right reader recognize the page and gives the page a more precise assignment. A single-site title experiment found a substantial increase in click-through rate after titles were aligned more closely with intent, even though the underlying content was unchanged. That result does not establish a universal lift, but it is a good reason to test packaging before commissioning a replacement page.

    Language models need extractable passages

    A language model can summarize long prose, but making it perform avoidable interpretation introduces ambiguity. Give each important question a direct answer, then support it with reasoning, conditions, and examples.

    • Use a descriptive heading that states the question, decision, or problem covered by the section.
    • Answer that heading in the opening sentence or paragraph of the section.
    • Name the subject instead of relying on a chain of pronouns whose meaning depends on earlier paragraphs.
    • Keep qualifications beside the claim they qualify. Do not hide the limitation several screens later.
    • Separate definitions, procedures, tradeoffs, and examples so each passage can stand on its own.
    • Use lists when the reader needs steps or criteria, not merely to break prose into fragments.

    Extractability is not the same as writing robotic copy. It is the discipline of making the relationship between the question, answer, evidence, and limitation unmistakable.

    Knowledge graphs need stable entity facts

    An agent evaluating organizations, products, or experts needs to understand what each entity is, what it offers, whom it serves, and whether the relevant facts are dependable. Create an entity home: a page you control that states the canonical facts about the entity in clear language.

    For a business, that page should make the following information unambiguous:

    • The canonical name and any commonly used alternate form.
    • A plain description of what the business provides.
    • The audiences, use cases, or markets it serves.
    • The relevant operating area, eligibility conditions, or service constraints.
    • The products, services, people, and locations connected to the business.
    • The evidence a reader can use to assess reliability.
    • The authoritative destination for contact, purchase, booking, or another next action.

    Structured data should reinforce those visible facts, not introduce a second version of them. If the page describes one audience while the markup, profiles, and feeds imply another, more markup increases the contradiction. Resolve the entity definition first, then make the structured representation match it.

    Rendering also matters. Critical copy that appears only after client-side execution is vulnerable because many AI-agent crawlers do not process JavaScript. Inspect the raw HTML of an important page. If its main answer, entity name, decisive attributes, or action path is absent, make that information available in the initial HTML through an appropriate server-rendered or pre-rendered implementation. Treat anything injected only after interaction as potentially unavailable to a crawler that does not execute the page like a full browser.

    Refresh intent, packaging, and specificity before adding pages

    Freshness is not a newer publication date attached to an unchanged answer. In an AI-saturated market, useful freshness comes from restoring alignment between the reader’s current problem, the page’s promise, and the information required to act. That is why refreshing an established page can be more valuable than publishing another broad treatment of the same subject.

    Use this sequence when a page has relevant subject matter but underperforms:

    1. Write the intent in one sentence. State what the reader should be able to do or decide after reading, including the constraint that makes the question difficult.
    2. Compare the promise with the answer. Check whether the title and description promise the same outcome the body actually delivers. If not, change the packaging, the body, or both.
    3. Move the useful answer forward. Remove the generic setup that delays the response. Put the direct answer where the reader can encounter it before the supporting detail.
    4. Replace interchangeable passages. Add boundaries, decision rules, tradeoffs, relevant evidence, and corrections to common misreadings.
    5. Reconcile entity facts. Confirm that names, descriptions, relationships, service details, and next steps agree across the page and the other representations you control.
    6. Validate machine access. Check the initial HTML, heading structure, links, and structured data. The content a person sees and the facts a machine receives should describe the same reality.
    7. Measure the changed behavior. Watch click-through rate to assess the search promise, then use time on page and scroll depth to see whether visitors engage with the answer. Change a limited set of elements when you need to understand what affected the result.

    The pattern of behavior helps you choose the next edit. Visibility without clicks often points to weak or mismatched packaging. Clicks followed by shallow reading often point to a promise-answer mismatch, excessive setup, or the wrong audience. Sustained reading without the intended next action can indicate that the page explains the subject but omits the criteria needed to decide.

    Replace generic competence with decision-grade specificity

    The competitive weakness of AI-assisted copy is often sameness, even when the draft is readable and factually acceptable. A useful editorial test is simple: could an unrelated organization publish this passage unchanged? If so, it probably does not contain enough judgment or context to influence a decision.

    Strengthen the passage by adding at least one of these elements:

    • A boundary: who the advice is not for or when it stops applying.
    • A constraint: the platform, workflow, audience, resources, or operating condition that changes the answer.
    • A tradeoff: what improves, what becomes harder, and which priority should decide between them.
    • A decision rule: the condition under which the reader should choose one path rather than another.
    • A correction: a common interpretation that sounds plausible but leads to the wrong action.
    • Relevant evidence: a fact that substantiates the claim being made, placed beside that claim.

    Specificity does not mean adding decorative detail. A longer page full of definitions can remain generic. The right detail reduces uncertainty at the exact point where the reader or agent must distinguish between options.

    Give AI the work that does not require final judgment

    AI can accelerate content operations without becoming the editor. Use it to inventory recurring topics, group similar pages for review, produce alternative title shapes, identify repeated passages, restructure already verified material, or turn an approved process into a draft checklist.

    Keep the consequential decisions with a person:

    • Choosing the reader and the intent worth serving.
    • Deciding which facts are true, current, relevant, and sufficiently supported.
    • Setting the boundaries and tradeoffs that make the answer useful.
    • Resolving contradictions between page copy, structured data, profiles, and operational systems.
    • Approving the final claims, recommendations, and next action.

    This division of labor preserves the speed advantage while preventing a plausible draft from becoming another indistinguishable page.

    Turn brand facts into a verifiable decision path

    Product, service, document, and location evidence connects through a visible path to an AI assistant making a final choice.

    Traditional search often sent a person through separate awareness, comparison, and decision visits. An assistive interface can perform much of that evaluation internally and present a narrow recommendation. Your page is therefore competing to become an input to the decision, not merely a blue link near the beginning of the journey.

    That changes the role of brand information. A clever positioning line may attract attention, but an agent still needs explicit facts about the entity, offering, audience, suitability, and reliability. If those facts are unclear or inconsistent, a better-understood alternative is easier to choose.

    Build a corroboration chain around the entity home

    Start with the entity home, then trace every decisive fact outward. The goal is not to repeat promotional copy everywhere. It is to prevent the systems involved in research from encountering incompatible identities.

    1. Define the canonical fact. Decide the exact name, description, relationship, service condition, or destination that should be treated as authoritative.
    2. State it visibly. Put the fact in clear, crawlable language on the relevant owned page.
    3. Represent it structurally. Make the structured data describe the same fact and relationship that the visitor can see.
    4. Align controlled profiles and feeds. Correct outdated names, descriptions, destinations, and eligibility details wherever you can manage them.
    5. Check operational data. When availability or selection depends on an API, booking system, inventory system, or internal database, make sure the decision-critical values agree with the public representation.
    6. Preserve a valid action path. The recommended entity must lead to the right contact, booking, purchase, or information destination.

    This broader check matters because the public web index is no longer the only information layer available to assistive systems. Proprietary datasets, APIs, booking platforms, and internal databases can contribute information that is not obtained from an ordinary crawl. Optimizing the page while neglecting the operational record can leave the decision system with conflicting answers.

    Treat push mechanisms as delivery, not authority

    Proactive mechanisms such as IndexNow, structured data feeds, and emerging agent connections can reduce reliance on waiting for a crawler. They do not make a claim trustworthy merely because it arrived faster. Use a supported push method when it fits the platform, but send information that is already accurate, consistent, and attached to a well-defined entity.

    Before releasing or refreshing an important page, run this five-question check:

    1. Can it be found? The title matches a real intent, and the essential content is available to the crawler.
    2. Can it be answered from? A self-contained passage resolves the main question with its necessary qualification.
    3. Can it be understood? The people, organization, offering, and relationships are explicitly named.
    4. Can it be verified? Visible facts, structured data, controlled profiles, and relevant operational records do not contradict one another.
    5. Can it be chosen? The page supplies the fit criteria, constraints, evidence, and correct next action required for its role.

    Start with one commercially or strategically important page rather than rewriting the entire site. Clarify its title, place the answer earlier, add the missing decision criteria, establish the entity facts, inspect the raw HTML, and reconcile the structured and operational representations. Measure how people respond, then carry the successful pattern into the next group of pages.

    The durable advantage in AI-era search is not publishing faster than every competitor. It is reducing uncertainty more completely – for the person asking the question and for every system deciding whether your answer or brand deserves to move forward.

    References

  • Local Business Contact Page SEO: A Practical Blueprint

    Local Business Contact Page SEO: A Practical Blueprint

    If your contact page contains only a phone number and a form, your customer still has work to do. They must find out when you are open, whether they can text you, where to park, which payment methods you accept, and what will happen after they submit an inquiry.

    Those missing details also make your business harder for search systems to interpret. Google can crawl and interpret a contact page to extract business details, so this page should function as a complete local business record as well as a conversion page.

    Give the contact page three clear jobs

    A useful contact page answers three questions without making the visitor search the rest of your site:

    • Have I found the right business? The page confirms your name, brand, location, and what you do.
    • Can this business meet my practical needs? The visitor can check hours, service options, amenities, directions, parking, and payment methods.
    • What should I do next? The page presents a visible action and explains what happens after the customer takes it.

    That makes the contact page closer to a focused local landing page than an administrative endpoint. It still needs to be concise, but concise does not mean incomplete. The goal is to put every fact needed for a call, visit, message, pickup, delivery, or appointment in one dependable place.

    Key takeaways

    • Publish a complete business identity, not just a name, address, and phone number.
    • Make shared details agree with your Google Business Profile.
    • Answer practical questions about contacting, visiting, buying, and arriving.
    • Support your claims with verifiable reviews, credentials, awards, and local involvement.
    • Use a prominent call to action, explain the follow-up process, and track completed actions.

    Publish one complete and consistent business record

    Illustration of a storefront linked to matching phone, location, hours, and email icons across a computer, smartphone, card, map tile, and directory panel.

    Start with facts before rewriting headlines or changing the design. Open the contact page beside your Google Business Profile and compare every field they share. A customer should not see one phone number on the page, another on the profile, and unexplained hours somewhere else.

    Make the business identity unmistakable

    Use the same recognizable logo that appears on your signage and other marketing materials. State the full customer-facing business name prominently. If you use a slogan, keep it accurate and useful; forcing location phrases or service keywords into it will make the page sound less credible.

    Follow the identity block with a short introduction that says what you do, where you operate, and why someone would choose you. A practical pattern is: business type, location, main area of expertise, and a genuine differentiator. This gives a first-time visitor enough context to confirm that they reached the intended company.

    Include the details customers otherwise have to hunt for

    • Full business name: Use the name customers encounter on your storefront, Google Business Profile, invoices, and other public materials.
    • Complete address: Include every part needed to reach the correct entrance or unit.
    • Phone number: Make it easy to select on a mobile device and label its purpose if you publish more than one number.
    • Text number: If texting is supported, say so explicitly. Do not leave visitors guessing whether the main number accepts messages.
    • Contact form and email address: Provide an alternative when the form fails, the request needs an attachment, or the visitor prefers email.
    • Operating hours: Publish normal hours and keep special or holiday variations current.
    • Social profiles: Link only to profiles you actively associate with the business.
    • Ways to buy: State whether you offer in-store shopping, curbside pickup, delivery, appointments, or another relevant arrangement.
    • Map and directions: Embed the Google Map connected to the business and include a direct link to its Google Maps listing. A generic pin for the street address can be less useful than the actual business listing.
    • Accepted payment methods: Tell customers what they can use before they arrive or place an order.
    • Parking information: Explain where customers can park and identify any instructions they need before reaching the entrance.

    The shared facts on this page and your Google Business Profile should agree. That does not mean every channel must contain identical prose. It means the business name, location, contact routes, hours, service options, and applicable attributes should not contradict one another.

    When something changes, update both records as part of the same task. Assign an owner for the page and include it in the workflow for holiday hours, phone changes, relocations, new payment methods, and revised pickup or appointment policies. A technically polished page with stale operational information still fails the customer.

    Remove friction from calling, visiting, and buying

    A customer holds a phone with icon-based contact actions while a clear route leads to an accessible local shop with parking, a bicycle rack, and welcoming staff.

    Visitors do not all arrive with the same intention. One wants to call immediately. Another needs directions. A third is checking whether curbside pickup is available. The page should support those paths without forcing everyone through the contact form.

    • For callers: Place the phone number near the primary call to action and show the hours during which a response is available.
    • For people who want to text: Label the text option and set an expectation for how the conversation continues.
    • For visitors traveling to you: Pair the address with the business map, a Google Maps link, parking instructions, and any arrival detail that prevents confusion.
    • For shoppers: State whether the relevant option is in-store service, pickup, curbside collection, delivery, an appointment, or some combination.
    • For people comparing fit: Publish relevant amenities and business attributes in plain language rather than assuming they will infer them from photos.
    • For written inquiries: Offer both the form and an email address, then explain what information will help your team respond.

    Put the most common action early on the page, but do not hide the supporting details below a long promotional introduction. Someone standing outside your building needs the address, hours, map, and parking information more than another paragraph about brand values.

    Amenities deserve particular attention because they often decide whether a customer can use a business at all. Review the attributes shown on your Google Business Profile, confirm which ones are still accurate, and reproduce the applicable facts on the page. Add other genuinely useful amenities that are specific to your location. Do not claim an attribute merely because it sounds desirable.

    If you operate multiple locations, do not mix several addresses, phone numbers, and sets of hours into an unlabeled block. Make the selected location obvious, separate its facts from every other branch, and ensure each call to action reaches the right team or destination.

    Put trust and local relevance beside the decision

    Reaching the contact page does not mean the visitor has decided to contact you. They may be looking for one final reason to proceed or one warning sign that tells them to leave. Place evidence close to the action instead of expecting them to visit a separate company-history page.

    Explain what happens after contact

    Uncertainty is a conversion barrier. State the expected response time, whether the visitor will receive a confirmation, and what the next step normally involves. If different channels have different processes, explain them separately. A form submission might lead to a callback, while an appointment request might require confirmation before the time is reserved.

    Make those expectations operationally honest. A vague promise such as “we respond quickly” gives the customer no usable information. A clearly stated response window is better, but only if your team can maintain it. If you cannot commit to a window, describe the sequence instead: confirmation, review, and follow-up.

    Use proof that a visitor can verify

    • Associations and memberships: Name relevant industry groups, chambers of commerce, professional organizations, neighborhood associations, and community groups. Link to your business entry on the organization’s site when one exists.
    • Ratings and credentials: Display current credentials and any applicable Better Business Bureau information without overstating what the rating or membership means.
    • Awards and press: Identify the award or coverage and link to the organization or publication that issued it.
    • Reviews and testimonials: Use external reviews or testimonials that include enough context to feel authentic, such as the reviewer’s name, photo, city, or public profile when you have permission to publish those details.

    Verification matters more than the number of badges. An unfamiliar logo with no explanation can become visual clutter. A named organization, a clear relationship, and a link to an independent listing give the visitor something they can evaluate.

    The page can also serve existing customers. Include a clear link for leaving a Google review where appropriate, especially for repeat customers who arrived looking for your contact details. Keep that request separate from the main inquiry action so a new customer does not mistake it for the contact route.

    Replace generic local copy with specific local evidence

    Calling yourself a trusted local business does not establish local relevance. Show it through details: team names and photographs, areas of expertise, the customer needs you handle, neighborhoods you serve, current guarantees, local events, volunteer work, and partnerships.

    Only include details that help someone decide or verify. A list of neighborhood names added solely for keyword coverage is not useful local content. A short explanation of where you work, which services are available there, and what a customer should expect is useful.

    Specificity also helps systems answer constrained questions about fit. Clear amenities and business attributes can help traditional and AI-powered search understand whether a location meets a particular need. That is not a guarantee of visibility or rankings. It is a reason to publish accurate facts that a search system does not have to infer.

    Make the next action obvious, reliable, and measurable

    Choose a primary call to action that matches the way the business actually converts inquiries. “Request an appointment,” “Call the store,” “Get directions,” and “Ask about pickup” each describe an outcome. “Submit” describes only what the button does.

    Repeat the primary action at sensible decision points: after the identity and contact details, after the trust evidence, and near the end. Keep its wording consistent. Secondary actions can support visitors with a different intent, but they should not make every option look equally important.

    Treat the form as a working contact channel

    • Pair the form with an email address so customers have a fallback.
    • Tell the visitor what happens after submission and how your team will respond.
    • Use an appropriate spam control, such as reCAPTCHA, a form plugin’s protection, a double opt-in process, or an obfuscated public email address.
    • Test the spam protection on a phone and with keyboard navigation so it does not block legitimate inquiries.
    • Send submissions to a monitored destination and verify that confirmation messages and internal notifications arrive.
    • Track a successful form completion as a conversion. Measuring a button click alone can count attempts that failed validation or never reached your team.

    Tracking should reflect the actions that matter to the business. At minimum, verify the form completion event. If calls, text messages, map visits, appointment requests, or pickup inquiries are important contact paths, decide which of those interactions should also be measured. Analytics cannot repair a broken contact experience, but it can reveal which routes customers use and whether a redesign disrupted them.

    Run this publishing audit from a customer’s point of view

    1. Confirm identity. Check the full name, logo, location, business description, and differentiator.
    2. Reconcile business data. Compare the address, phone and text numbers, hours, service options, and applicable attributes with the Google Business Profile.
    3. Test every contact route. Call the number, open the text option, send the form, use the email link, and confirm that each route reaches the intended destination.
    4. Test the visit. Open the embedded map and Google Maps link, then verify that they lead to the actual business listing. Read the parking and arrival instructions as though you have never visited.
    5. Check practical fit. Confirm that payment methods, shopping options, amenities, and appointment requirements are accurate.
    6. Verify the proof. Open association, award, press, review, and credential links. Remove expired claims and unexplained badges.
    7. Complete the primary action. Use both a mobile and a larger screen. Confirm that the call to action is visible, the form is usable, the confirmation appears, the inquiry reaches the team, and the conversion is recorded.
    8. Assign maintenance. Identify who will update the page when hours, staff, contact details, service methods, parking, amenities, or credentials change.

    Start your first pass with the facts, not the design. Reconcile the page with your Google Business Profile, fix every broken contact route, and then add the missing visit details and proof. Once a customer can identify you, assess fit, trust the business, and complete the next step without guessing, the contact page is doing its real job.

    References