Tag: Content Optimization

  • Google AI Search Personalization: A Publisher Traffic Plan

    Google AI Search Personalization: A Publisher Traffic Plan

    If your rankings still look familiar but organic sessions are getting harder to explain, stop looking for one universal search result. In AI Mode, an opted-in user can receive answers shaped by purchases, receipts, travel plans, interests, and connected Google apps. A rank tracker cannot reproduce that person’s private context, so its screenshot represents only one possible result.

    Your job is not to reverse-engineer anyone’s inbox or photo library. It is to identify which pages can be absorbed into a personalized answer, which pages still give the user a reason to visit, and how to measure the change without pretending that one ranking position explains it.

    One query no longer implies one reproducible result

    Traditional rank analysis treats the query as the main input: enter the same words under similar conditions and expect roughly comparable results. Personal Intelligence adds a private context layer. Google has expanded it to AI Mode for U.S. personal accounts, while related rollouts are moving through Gemini for free users and Chrome. Workspace accounts are not included for now.

    Users must opt in to app connections and can turn those connections off. Depending on what they connect, Google can combine the immediate query with information from services such as Search, Gmail, Photos, and YouTube. That changes what the system needs from the public web before it constructs an answer.

    • A shopping request can be narrowed by previous purchases, preferred brands, or buying behavior.
    • A troubleshooting request can use receipt details to identify the exact device involved.
    • A travel request can reflect flights, previous trips, and other personal plans.
    • A recommendation can be adjusted around interests and hobbies already visible in the user’s connected history.

    The distinction that matters for publishers is simple: you can improve the public information your page contributes, but you cannot control the private facts used to select, filter, or apply it. Producing dozens of thin pages for imagined personal profiles will not solve that problem. It is more useful to make one strong page explicit about the conditions under which each answer applies.

    For every important query cluster, create a context card with these fields:

    • User task: What decision, diagnosis, plan, or action is the person trying to complete?
    • Possible private context: What purchase, device, itinerary, preference, or history could narrow the answer?
    • Your public contribution: What verifiable fact, method, comparison, compatibility rule, or limitation does your page supply?
    • Click-worthy remainder: What useful work remains after a concise AI answer has been generated?
    • Qualification: Which model, location, account type, prerequisite, or exception changes the recommendation?

    This turns personalization from an unknowable ranking variable into a content-planning question. You do not need to predict every user. You need to publish information that remains accurate when the system combines it with different user contexts.

    Keep privacy out of your testing shortcuts. Google states that Gmail and Photos content is not directly used to train its AI models, although limited information such as prompts and responses may be used to improve systems. That does not make private accounts appropriate rank-tracking assets. Do not ask a staff member to connect a personal inbox or photo library just to capture search screenshots. If you do not have a legitimate, voluntarily opted-in testing setup, record the personalized layer as unobserved.

    Diagnose traffic change without relying on a single rank
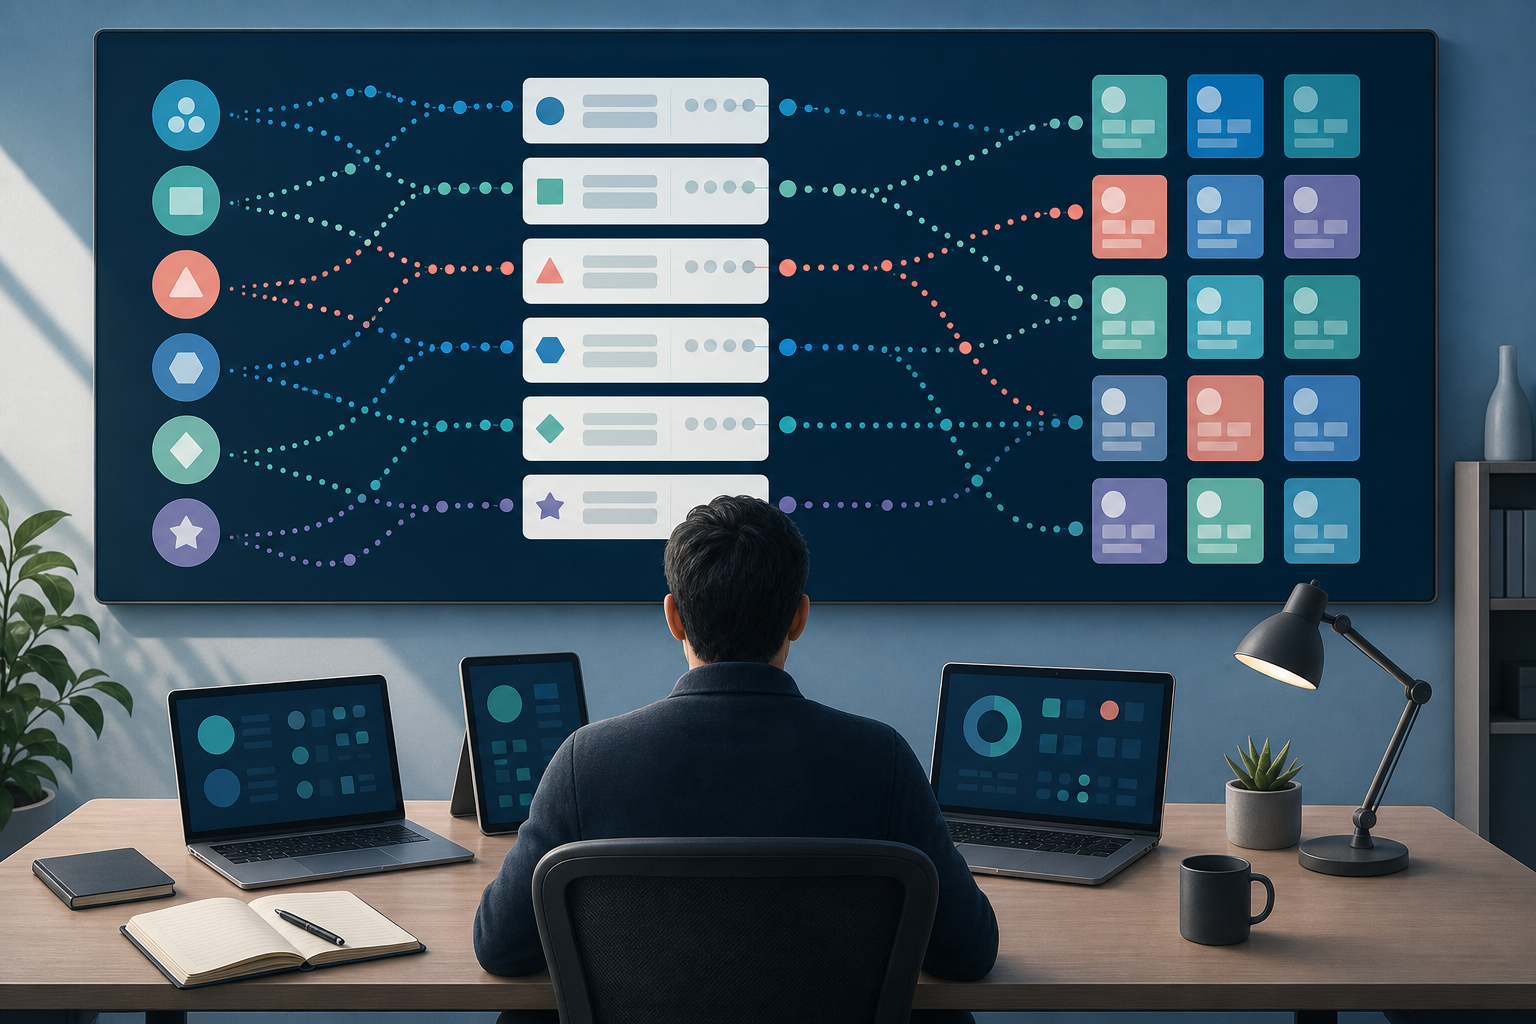
    An analyst examines multiple abstract search-result pathways, with colored particles either stopping at answer cards or continuing to publisher page tiles.

    The traffic risk is credible, but its size is not established by the available evidence. Yahoo CEO Jim Lanzone has described Google AI Mode as the largest challenge from large language model interfaces to the traditional system in which search sends visits to publishers. He also tied the quality of answer engines to the continued health of the publishers that produce their underlying content.

    Treat that as a directional warning, not a universal loss estimate. A falling session count can also reflect demand, seasonality, indexing, a site release, a measurement change, or a weaker search snippet. Personalized AI results add another plausible mechanism; they do not remove the others.

    Use a cohort-based diagnostic instead of checking isolated keywords:

    1. Describe the observable environment. Record country, personal or Workspace account, signed-in state, AI Mode availability, and whether app connections are enabled. Record the setting, never the private contents of a connected account.
    2. Group pages by completion risk. A definition or short factual lookup may be fully answerable in the interface. A comparison or recommendation may depend on context. A detailed procedure, tool, transaction, or evidence set may still require a visit.
    3. Choose business signals for each group. Track available search visibility, organic entrances, meaningful on-site completions, and branded demand. Do not let a visibility metric stand in for revenue, leads, subscriptions, or another outcome that actually matters.
    4. Annotate other changes. Mark site migrations, template releases, indexing problems, campaign changes, and shifts in audience exposure alongside AI product changes.
    5. Compare page cohorts. If concise answer pages weaken while visit-dependent pages hold, that pattern is more informative than one volatile query. It is still an observation to investigate, not proof of a single cause.

    The following combinations are useful diagnostic prompts. None proves that AI Mode caused the movement.

    Observed patternPlausible readingNext check
    Search visibility and organic entrances both declineThe page may be losing discovery earlier in the journey.Check demand, indexing, site changes, query coverage, and affected page types before assigning a cause.
    Search visibility holds while organic entrances declineUsers may be seeing the result but completing more of the task without visiting, or the search presentation may have changed.Compare completion-risk cohorts and document the account environment used for any manual observations.
    Organic entrances decline while conversions holdSome lost visits may have carried weak intent.Judge the change by business value as well as session volume, and inspect which landing-page cohorts lost traffic.
    Organic entrances hold while conversions declineThe main problem may sit after the click rather than in AI visibility.Inspect intent alignment, page experience, offer clarity, forms, checkout, and other on-site changes.

    This measurement model accepts a hard limit: personalized output cannot be audited as though it were a fixed national ranking. You can still detect exposure and outcome patterns, but you must preserve the conditions attached to each observation. A screenshot with no account-state notes is weak evidence.

    Give the answer engine clarity and the reader a reason to continue
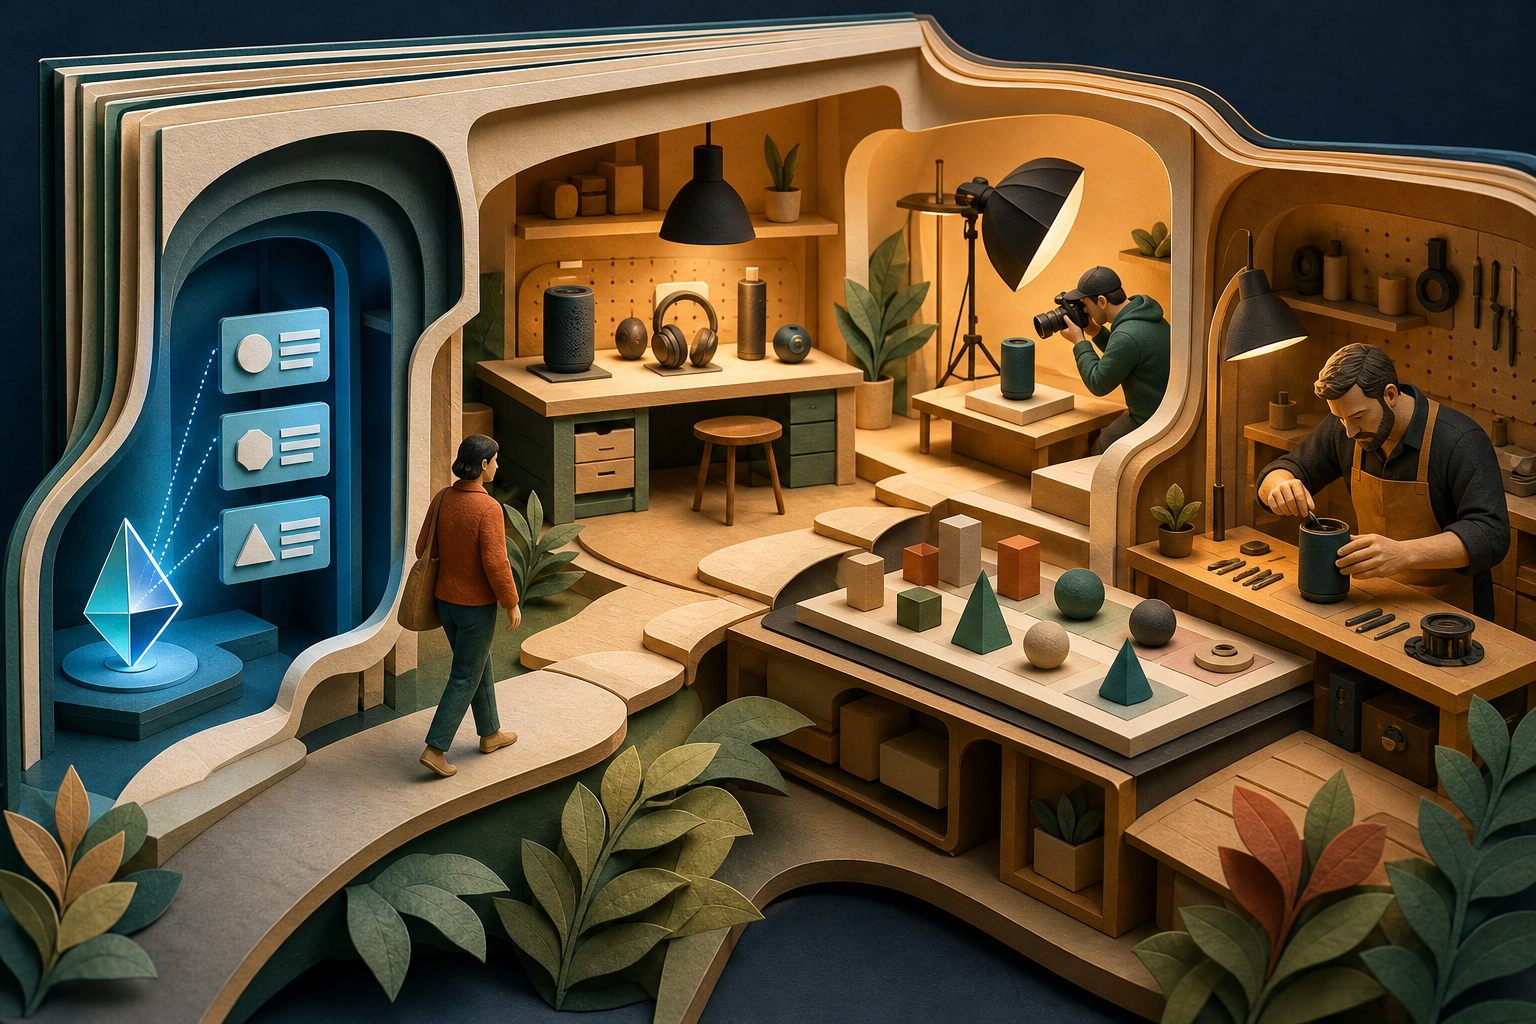
    An abstract AI prism extracts organized fact blocks from the entrance of a layered publisher page while a reader continues toward original testing, photography, comparison objects, and an expert demonstration.

    A page now has two jobs. It must make its core information easy to interpret, and it must contain enough additional value to justify a visit. Hiding the answer behind a long introduction may weaken the first job. Publishing only the answer may eliminate the second.

    Build the page in layers:

    • State the direct answer. Put the central conclusion in plain language and identify who or what it applies to.
    • Expose the decision variables. Name the compatibility requirements, prerequisites, exclusions, locations, versions, models, or user conditions that can change the result.
    • Support the conclusion. Show the evidence, reasoning, calculation, comparison criteria, or complete method behind the short answer.
    • Handle exceptions near the relevant claim. Do not bury a decisive limitation in a generic disclaimer at the bottom.
    • Provide the next useful action. A diagnostic path, full procedure, decision tool, original dataset, detailed comparison, or transaction can give the reader a concrete reason to continue.

    Personalization makes precise attributes more valuable than generic enthusiasm. If a system knows the device from a receipt, your troubleshooting page should state which models, symptoms, and operating conditions its instructions cover. If a system knows a travel itinerary, your page should make location limits, timing constraints, and exceptions explicit. If it knows a buyer’s preferred brands, a comparison should explain meaningful tradeoffs instead of repeating brand positioning.

    The private detail narrows the problem; your content still has to supply the reliable public rule. That is the part you can optimize.

    Use this editorial check before updating an exposed page:

    • Can the opening answer stand on its own without losing an essential qualification?
    • Are important entities, products, versions, and relationships named consistently?
    • Can a reader see why the recommendation changes under different conditions?
    • Does the page contain evidence or functionality beyond a concise summary?
    • Are unsupported superlatives, vague claims, and redundant sections removable?
    • Does the structured data accurately describe the visible page rather than promise information the page does not contain?

    JSON-LD belongs in that final consistency check. Choose a schema type that truthfully represents the page, keep entity names and properties aligned with the visible content, and validate the markup when the page changes. Schema can clarify meaning; it cannot manufacture distinctive information or guarantee traffic from a personalized answer.

    Do not optimize only for extraction. If every useful detail can be compressed into a short response with no loss, the interface may have little reason to send the user onward. The answer should be clear, but the underlying page should make the method, proof, edge cases, or next action materially better.

    Plan separately for the ad-free personalized environment

    Google is testing ads in AI Mode in the U.S., but users who connect apps for Personal Intelligence currently receive an ad-free AI Mode experience. The commitment was framed as the present state, not an irreversible promise.

    For a publisher, ad-free does not mean competition-free. The personalized answer itself can satisfy the task, even when no paid placement appears beside it. Nor does an ad-free answer protect your own advertising or affiliate revenue; that revenue still depends on the user reaching your property.

    Maintain separate planning lanes:

    • App-connected AI Mode: Evaluate whether your content supplies a public fact or deeper action that remains useful after private context is applied.
    • General AI Mode with ad tests: Observe organic and paid changes separately. Do not attribute a movement to personalization when the test environment did not use connected apps.
    • Possible future personalized advertising: Google has indicated that future ads could relate to the query, response context, and user interests. Treat that as a scenario to monitor, not as current behavior for connected-app experiences.

    If your organization buys traffic as well as publishing content, keep the paid and organic questions distinct. An ad impression can create a commercial connection without restoring the editorial visit that the answer displaced. Conversely, a decline in organic clicks does not prove that ads captured them. Measure each route on its own terms.

    Personal Intelligence is also spreading through Gemini and Chrome. Do not assume those surfaces will display, attribute, or send visits in the same way. Inspect your own analytics for actual referral and conversion behavior, and label any behavior you cannot observe instead of filling the gap with a guess.

    Key takeaways

    • Personalized AI results combine a public query with private context, so one rank-tracking result cannot represent every user’s experience.
    • Classify pages by whether the AI interface can complete the user’s task without a visit.
    • Measure page cohorts through visibility, organic entrances, meaningful completions, and branded demand rather than relying on average position alone.
    • Make conditions, compatibility, exclusions, evidence, and next actions explicit in both visible content and accurate structured data.
    • Treat app-connected, ad-free AI Mode as a distinct environment and preserve account-state notes for every manual observation.

    Start with the page cohort most closely tied to revenue or qualified demand. Write a context card for each query cluster, mark its completion risk, and identify the useful work that remains after a personalized summary. Then update the content and measurement plan together. If you change the page without changing how you evaluate it, you will still be unable to tell whether the strategy worked.

    The publishers best prepared for personalized search will not be the ones claiming to predict every answer. They will be the ones that know exactly what their pages contribute, why a person would still visit, and which business signal would prove that value.
    References

  • How LinkedIn’s LLM-Powered Feed Ranks Your Content

    How LinkedIn’s LLM-Powered Feed Ranks Your Content

    If your LinkedIn reach feels erratic, stop treating the feed like one global leaderboard. The platform is trying to predict relevance for each person, so two professionals with similar networks can still receive different candidates in a different order.

    The useful question isn’t, “How do I please the algorithm?” It is, “Can the system understand who this is for, and will the right readers behave as though it was worth their time?” LinkedIn’s new architecture gives you a practical way to improve both sides of that equation without pretending there is a secret score you can reverse-engineer.

    LinkedIn now makes two separate feed decisions

    Abstract content tiles pass through a broad selection gateway and then a second prism that orders different feeds for three viewers.

    Feed visibility begins with two distinct jobs: retrieval and ranking. Retrieval decides which posts could appear. Ranking decides which of those candidates should appear first. A post that fails the first decision never reaches the second, while a retrieved post can still lose its position to something that better matches the viewer’s current interests.

    Retrieval matches meaning, not just identical wording

    LinkedIn has consolidated previously separate discovery routes into a unified retrieval model. Large language models create embeddings: numerical representations that capture the meaning and context of a post. Those representations can be compared with a member’s professional interests even when the wording isn’t identical.

    Someone engaging with small modular reactor content, for example, may also receive material about renewable energy or a related professional field that uses different terminology. This semantic matching across related concepts matters more than repeating one phrase in every paragraph.

    The GPU-backed system processes millions of posts, can refresh content embeddings within minutes, and can retrieve candidates in less than 50 milliseconds. That speed means a fresh post can become semantically retrievable quickly. It does not guarantee that the post will be selected, ranked highly, or distributed widely.

    Ranking uses a sequence of viewer behavior

    After retrieval, a transformer-based sequential model orders the candidates. It doesn’t evaluate each post in isolation. It examines patterns in a member’s previous behavior, including likes, comments, and time spent viewing content, so the feed can adapt as professional interests change.

    This is an important limit on algorithm advice. A post does not have one universal rank. Its position depends partly on the person receiving it and the sequence of behavior that preceded that feed request. Strong results with one audience segment do not prove that the same post will rank the same way for everyone else.

    LLM-powered also doesn’t mean a chatbot is reading your prose like an editor and awarding points for style. One model represents meaning for retrieval; another uses interaction history to rank candidates. Human-readable quality still matters, but it matters because clear, useful content is easier to match and more likely to hold the right person’s attention.

    Make each post semantically legible

    A blank content card emits a focused constellation of topic symbols that connects with a matching group of professional readers.

    A vague post forces both the model and the reader to guess. A semantically legible post names the professional context, the problem, the affected audience, and the relationship between its main ideas. You can create that clarity without turning the copy into a keyword list.

    1. Write a private audience sentence before drafting: “This is for [role] deciding [specific decision].” If you can’t complete it cleanly, the topic is still too broad.
    2. Name the subject early. Don’t spend the opening on a generic tease that could introduce leadership, software, hiring, finance, or any other field.
    3. Explain the mechanism. State why the change happens, what it affects, or which constraint creates the problem. Adjectives such as “transformative” and “important” don’t supply that context.
    4. Connect the core topic to one relevant adjacent concept. Make the relationship explicit instead of dropping related terms into the copy without explanation.
    5. Show expertise through a process, tradeoff, decision rule, or concrete distinction. Claiming expertise is weaker than making knowledgeable reasoning visible.
    6. End with a question only when the answer can deepen the professional discussion. Ask about a decision, constraint, or experience, not whether readers agree.

    Compare “Big changes are coming. Thoughts?” with this structure: “For [role] deciding [decision], [named development] changes [specific constraint] because [mechanism].” The second version tells the retrieval system what the content concerns and tells the reader whether it deserves attention.

    Semantic retrieval is not permission to stuff a post with synonyms. Use the standard term your audience recognizes, explain it in plain language where necessary, and introduce adjacent terminology only when the relationship adds meaning. A keyword dump can mention everything while communicating almost nothing.

    A coherent series can help you explore a semantic neighborhood: the primary problem, its causes, its operational consequences, and the decisions around it. That does not prove LinkedIn grants account-level authority merely for repeating a topic. It does give each installment a clear chance to match similar professional interests, and it gives you a cleaner way to learn which angle resonates.

    Your network size is not the entire distribution story. Posts that demonstrate expertise and contribute to relevant professional conversations can travel beyond an author’s established connections. The practical move is not to chase every trending subject. It is to contribute when you have a specific connection between the timely topic and the work your intended audience actually does.

    Earn ranking signals without manufacturing them

    Because ranking considers likes, comments, and viewing time, it is tempting to treat every interaction as a lever. Resist that simplification. LinkedIn has not supplied a usable formula that tells you how much each action is worth in every context, and a pause on a post does not necessarily mean approval.

    Design for a meaningful reading experience instead. Give the opening enough information to qualify the audience. Build the body in a logical sequence. Make the promised point before asking for a response. If the subject needs depth, use depth; making a post artificially long in pursuit of viewing time only gives readers more opportunities to leave.

    • Use an opening that identifies the professional issue instead of withholding it behind suspense.
    • Break a complex explanation into distinct decisions, causes, or steps so the reader can follow the reasoning.
    • Ask for a response that requires professional judgment, such as which constraint changes the decision.
    • Reply manually and specifically when someone contributes. Continue the subject they raised instead of posting a generic thank-you.
    • Keep the text and any accompanying media on the same subject. An unrelated video may attract attention while weakening the content’s meaning.
    • Remove prompts whose only purpose is to inflate activity, including requests for a one-word comment with no substantive reason to answer.

    Automated comments and engagement pods are not clever shortcuts. LinkedIn has identified them as policy violations that create artificial discussion. The platform is also deprioritizing engagement bait, irrelevant text-and-video pairings, and generic recycled thought leadership.

    Don’t stretch that policy into a claim that every AI-assisted draft is automatically suppressed. The documented targets are automated engagement and low-value publishing patterns. Judge any drafting tool by the resulting content: Is the reasoning specific? Is the point accurate? Does the copy express a real professional distinction? Would the post still be worth reading if no engagement counter were visible?

    Test audience-topic fit instead of algorithm folklore

    A personalized feed makes casual testing unreliable. When one post performs better than another, the difference could involve the topic, the opening, the audience that received it, those viewers’ recent behavior, or the quality of the discussion. Changing several elements at once leaves you with a result but no useful explanation.

    1. Choose one business-relevant question that a recognizable professional audience needs to answer.
    2. Map the question into a core angle and adjacent angles, such as the cause, implementation constraint, common misreading, and decision tradeoff.
    3. Publish a coherent sequence in which every post stands on its own and names its subject clearly.
    4. Change one structural variable when you want to learn from a comparison: the opening, explanatory depth, example type, or closing question.
    5. Record more than reach. Note whether the people responding appear connected to the intended professional context and whether their comments engage with the actual issue.
    6. Use those observations to choose the next adjacent angle. Don’t turn one strong or weak result into a universal rule about length, timing, hashtags, or a supposed favorite interaction.

    Keep a simple brief beside each draft with these fields: intended reader, decision or problem, core concept, adjacent concept, mechanism or tradeoff, and response prompt. After publication, add what the discussion revealed. This turns a feed result into editorial information you can use rather than a number you can only admire or resent.

    Your own feed is also personalized evidence, not a neutral sample of LinkedIn as a whole. If you use it for topic research, remember that your likes, comments, and viewing behavior help shape what you see next. New members can make that preference-building more deliberate by choosing topics through the Interest Picker during signup. That helps customize the feed from the beginning, but it still does not reveal what every other audience sees.

    Key takeaways

    • Retrieval decides whether a post belongs in the candidate set; ranking decides where that candidate appears for a particular member.
    • Semantic embeddings make clear meaning and related concepts more important than exact-phrase repetition.
    • Ranking uses sequences of behavior, including likes, comments, and viewing time, but there is no dependable public formula for turning those actions into a universal score.
    • Expertise becomes visible through mechanisms, tradeoffs, processes, and useful distinctions, not through generic claims of authority.
    • Automated engagement, pods, bait, mismatched media, and recycled thought leadership create policy or quality risks instead of durable distribution.
    • The cleanest test is audience-topic fit: keep the subject coherent, change one structural variable at a time, and inspect who responds and what they discuss.

    Before your next LinkedIn post, write the private audience-and-decision sentence, rewrite the opening so the subject is unmistakable, and remove any question that can be answered without thought. Then use the quality of the resulting discussion to select the next relevant angle. That is a better compounding system than chasing a secret ranking trick.

    References

  • AI Search Visibility: A Practical Content Optimization System

    AI Search Visibility: A Practical Content Optimization System

    Your page can rank in conventional search and still disappear when someone asks an AI system to recommend a solution, compare options, or explain what to do next. The usual problem isn’t a missing AI keyword. It is that the answer, the entity behind it, or the evidence connecting the two is too difficult to interpret.

    You can fix that systematically. Make each important page useful as a self-contained answer, give every important entity one consistent identity, connect related pages deliberately, and keep the visible content aligned with its JSON-LD. Then measure whether AI systems represent your brand accurately, not merely whether they send a click.

    Start with the answer AI search needs to use

    Traditional SEO helps a search engine discover, index, and rank a URL. Answer engine optimization helps a brand appear when people ask relevant questions through AI-driven experiences such as ChatGPT and Google. Generative engine optimization goes a step further: it makes your information easier to interpret, verify, and incorporate into a generated response.

    These disciplines overlap, but they don’t produce the same artifact. A page written only to attract a click can tease the answer, delay it, or distribute it across several sections. A page prepared for AI search must contain an answer that remains clear when extracted from the surrounding layout.

    Rewrite the page around one answerable job

    Start by naming the job the page performs. A service page might establish who the service is for and what it includes. A comparison page might help a buyer choose between two approaches. A how-to page might resolve one task. If you cannot complete the sentence, this page helps the reader decide or do something specific, its scope is probably too loose.

    1. State the question or decision. Use language your intended reader would recognize. Don’t optimize one page for several unrelated intents simply because their keywords are adjacent.
    2. Give the direct answer early. Put the conclusion before the long explanation. The reader should not have to assemble it from an introduction, a feature list, and a closing paragraph.
    3. Name the subject. Replace ambiguous pronouns with the product, organization, person, service, or method being discussed. A detached passage should still reveal who or what the claim concerns.
    4. Add the conditions that change the answer. Identify who the advice applies to, what assumptions it depends on, and where an exception matters. A precise qualified answer is more useful than an absolute claim that the rest of the page quietly weakens.
    5. Support the conclusion nearby. Keep definitions, reasoning, examples, and relevant evidence close to the statement they support. Don’t force an engine or a reader to infer why a claim is credible from a distant page.
    6. Provide the next decision. Explain what the reader should compare, check, or do after receiving the answer. This turns an extractable passage into a useful one.

    Run an extraction test when the draft is finished. Copy the answer paragraph into a blank document without its title, navigation, images, or preceding sections. Can someone identify the subject, understand the conclusion, see its important limits, and know what to do next? If not, repair the paragraph before adding more optimization around it.

    Answer-ready writing does not mean reducing every page to short fragments. Detailed explanations still matter. The practical goal is layered clarity: a direct answer first, followed by the reasoning and context that make it trustworthy.

    Make your brand and its entities impossible to confuse

    AI visibility depends on more than what one URL says. A reasoning system also has to determine whether the organization in an author biography, the brand in a product description, and the publisher identified in structured data are the same entity. Strong entity authority comes from a consistent, connected, and verifiable ecosystem, not from repeating a keyword more often.

    An entity is a specific thing with an identity: your organization, a product, a service, a person, or a location. Treat each important entity as a record that must remain consistent wherever it appears.

    • Choose one canonical name. Decide how the entity is named, capitalized, and described. Use aliases only when they help readers recognize the same thing.
    • Maintain one canonical page. Give each strategic entity a clear home URL containing its current description, important attributes, and relevant relationships.
    • Define relationships explicitly. State which organization offers a service, which person works for or founded an organization, which product belongs to a brand, and which article concerns which subject. Include only relationships the visible site can substantiate.
    • Remove contradictory facts. Conflicting names, service descriptions, locations, authorship details, or availability statements force machines to choose between versions. Correct the underlying content instead of trying to override it with schema.
    • Connect external identities carefully. A sameAs value should identify the same entity on a reputable external page. It should not point to a loosely related mention, a partner, or a page that merely uses a similar name.

    Use a stable @id for each entity in JSON-LD and reference that identifier wherever the entity reappears. If the Organization node has one identifier on the homepage, another on an article, and a third on a service page, you have created three machine-readable candidates where you intended one identity.

    A small relationship map exposes these mistakes before they spread. Write the important connections in plain language: Organization offers Service; Article is about Service; Person works for Organization; WebSite is published by Organization. Then check whether the visible pages, internal links, and JSON-LD all express the same map.

    Schema can clarify an identity, but it cannot manufacture authority. If a page makes a vague or unsupported claim, wrapping that claim in structured data only makes the ambiguity machine-readable. Build the factual record first; encode it second.

    Use internal links and JSON-LD as one connected system

    Linked content-page tiles sit above a matching lattice of structured data nodes, with light bridges joining the two layers.

    Internal links and JSON-LD solve related problems at different layers. Internal links show readers and crawlers how editorial ideas connect. JSON-LD identifies the entities and properties involved in those connections. When the two layers disagree, neither provides a dependable map.

    Make internal links explain the relationship

    Link from the passage where the relationship is meaningful, using anchor text that describes the destination. A link labeled entity schema implementation tells the reader more than learn more. The surrounding sentence should also explain why the destination matters.

    • Link supporting articles to the canonical page for the product, service, person, or concept they discuss.
    • Link a canonical page back to the strongest supporting explanations when those explanations help a reader evaluate the entity.
    • Connect adjacent answers when a reader genuinely needs both, rather than linking every related keyword to every possible page.
    • Resolve orphaned strategic pages. If no relevant page points to an entity’s canonical URL, the site is signaling that the entity has little structural importance.
    • Review redirects and canonical changes so links continue to resolve to the identity you intend.

    Bring internal-link suggestions into the writing workflow before publication, while the author still has the full context of the page. Automation can surface possible destinations, but an editor should decide whether each link expresses a real relationship and helps the reader continue the task.

    Make JSON-LD describe what the reader can verify

    Basic schema scattered across unrelated templates can become a collection of data islands. Reuse entity identifiers so an Article can reference the same Organization, Person, Product, or Service already defined elsewhere. This creates a coherent content knowledge graph rather than several disconnected descriptions of the same site.

    Structured data lowers the amount of interpretation required to understand your content, but it does not guarantee inclusion or a citation. Its value is clarity. It lets a machine follow an explicit relationship instead of guessing one from layout, navigation, and repeated wording.

    • Match names and descriptions in meaning. The JSON-LD does not have to duplicate every visible sentence, but it must not tell a materially different story.
    • Reference canonical URLs. Don’t let outdated staging paths, redirected addresses, or inconsistent URL variants become entity identifiers.
    • Validate authorship and publisher relationships. Confirm that the named people and organizations are visibly associated with the content in the roles declared.
    • Keep offers and capabilities current. Remove services, availability claims, or product details from structured data when they no longer appear on the page.
    • Describe actions only when they work. Action-oriented schema should correspond to a real pathway a user or agent can complete. Marking up a nonexistent booking, ordering, or contact function creates a promise the site cannot fulfill.
    • Update content and schema together. A change is not complete until the visible page, shared entity record, internal links, and structured data agree.

    This last check prevents schema drift: the gradual separation of what people see from what machines read. Drift reduces confidence precisely when you need AI systems to resolve an identity or capability without guessing.

    Audit visibility by query, citation, and accuracy

    Three query orbs connect through an inspection lens to blank answer cards and source documents, with one connection highlighted for review.

    Organic sessions and rankings still matter, but they cannot tell you whether an AI answer named your brand, cited the right page, or described your offer correctly. Add an output-focused audit rather than replacing your existing SEO reporting.

    Build a stable set of prompts around real audience decisions. Include discovery questions, problem-solving questions, comparisons, and questions that test a capability you want the market to associate with your brand. Keep the wording and intent consistent enough to compare observations over time.

    1. Record the environment. Note the AI system, query, date, and any material context supplied with the prompt. A single answer without its conditions is not a useful baseline.
    2. Check presence. Record whether the brand or entity appears, whether it is merely listed, and whether it contributes meaningfully to the answer.
    3. Check citation quality. Identify the cited URL and whether that page actually supports the claim beside it. A homepage citation is not automatically valuable if a focused service or explanatory page should have been used.
    4. Check representation. Compare names, capabilities, relationships, and qualifiers with your canonical facts. An inaccurate mention is a governance problem, not a visibility win.
    5. Check answer ownership. Note which competing entities or publications provide the explanation when your page does not. Look for a missing answer, unclear entity, weak relationship, or unsupported claim that explains the difference.
    6. Check the site layer. Confirm that the preferred page is indexable, internally linked, canonically consistent, and aligned with its JSON-LD before rewriting its prose again.

    Citation value, model share, and representation accuracy extend measurement beyond page traffic. Model share can be treated as the proportion of your tracked prompts in which your entity earns a meaningful presence. Citation value asks whether the cited page supports a commercially or editorially important answer. Neither metric should be confused with revenue, but both can reveal whether AI systems understand where your brand belongs.

    Don’t change strategy because the brand was absent from one generated response. Look for a recurring failure across your tracked prompt set. If the right page is repeatedly ignored, inspect answer clarity and internal prominence. If the brand appears with the wrong attributes, inspect the canonical entity record and schema alignment. If a competitor supplies the explanation, compare the completeness and specificity of the relevant answer rather than copying its phrasing.

    Schedule a governance check whenever a material business fact changes. A rebrand, retired service, new author role, migrated URL, or changed transaction path can affect several nodes at once. Updating only the most visible page leaves the old version alive in internal links, structured data, archives, or supporting content.

    Key takeaways

    • Optimize each strategic page for one answerable reader job, then test whether its core answer remains clear when removed from the layout.
    • Give every important organization, person, product, or service one canonical identity, one stable @id, and a consistent set of relationships.
    • Use internal links to express editorial relationships and JSON-LD to encode the same relationships for machines.
    • Never use schema to make a claim the visible page cannot verify, and update both layers in the same publishing workflow.
    • Track meaningful presence, citation quality, and representation accuracy across a stable prompt set alongside rankings and traffic.

    Begin with one commercially important entity and the page that should answer its most important question. Repair that page, connect its supporting content, align its JSON-LD, and establish a prompt baseline. Once the identity and relationships hold together there, extend the same system to the next entity instead of attempting a site-wide markup exercise with no governing model.

    References

  • How Tripadvisor Supports Local SEO for Travel Businesses

    How Tripadvisor Supports Local SEO for Travel Businesses

    If you market a hotel, restaurant, tour, or attraction, a weak Tripadvisor listing can shape the decision before a traveler reaches your website. The platform can occupy valuable search-result space for your business name, appear during category discovery, and expose reviews, photos, and business details while the customer is deciding where to book.

    Your goal is not to make Tripadvisor the center of your local SEO strategy. It is to manage the listing as one coordinated part of your search presence: accurate business facts, a clearly described experience, fresh evidence, useful customer language, and a credible path from discovery to action.

    Tripadvisor influences discovery before it influences rankings

    Tripadvisor performs three jobs at once. It is a search result, a comparison marketplace, and a reputation page. That combination matters because travelers visiting it are often beyond general inspiration and actively comparing places, experiences, or meals.

    The scale is difficult to dismiss: Tripadvisor receives about 490 million monthly visits. Its large, programmatically structured collection of indexable destination, category, and business pages also gives it substantial visibility in conventional search results. In some tourism and hospitality searches, a Tripadvisor listing can even appear above the business’s own website.

    That does not mean optimizing Tripadvisor will directly raise your website or Google Business Profile rankings. There is no defensible reason to report it as a guaranteed ranking shortcut. Its local SEO contribution is broader and more practical:

    • Search-result coverage: A complete listing gives searchers a credible third-party result when they look for your brand, location, or business type.
    • Internal discovery: Categories, tags, reviews, and profile content help Tripadvisor understand where the business belongs within its own marketplace.
    • Entity consistency: Matching identity information across Tripadvisor, your website, and Google Business Profile reduces ambiguity about which business each page represents.
    • Decision support: Current photos, detailed reviews, and clear descriptions answer questions that might otherwise stop a booking.
    • Qualified referral traffic: Visitors who reach your website after comparing options on Tripadvisor may arrive with stronger intent than someone conducting broad destination research.

    Tripadvisor can also contribute to AI discovery, but the mechanism should be described carefully. Detailed profile text and factual owner responses create more explicit language about your amenities, audience, setting, and experiences. That gives AI-driven search systems more context to interpret; it does not guarantee that an AI answer will mention or recommend you. For AEO and GEO, prioritize clear passages and verifiable details, not inserted keyword strings.

    Fix identity, duplicates, categories, and tags before polishing copy

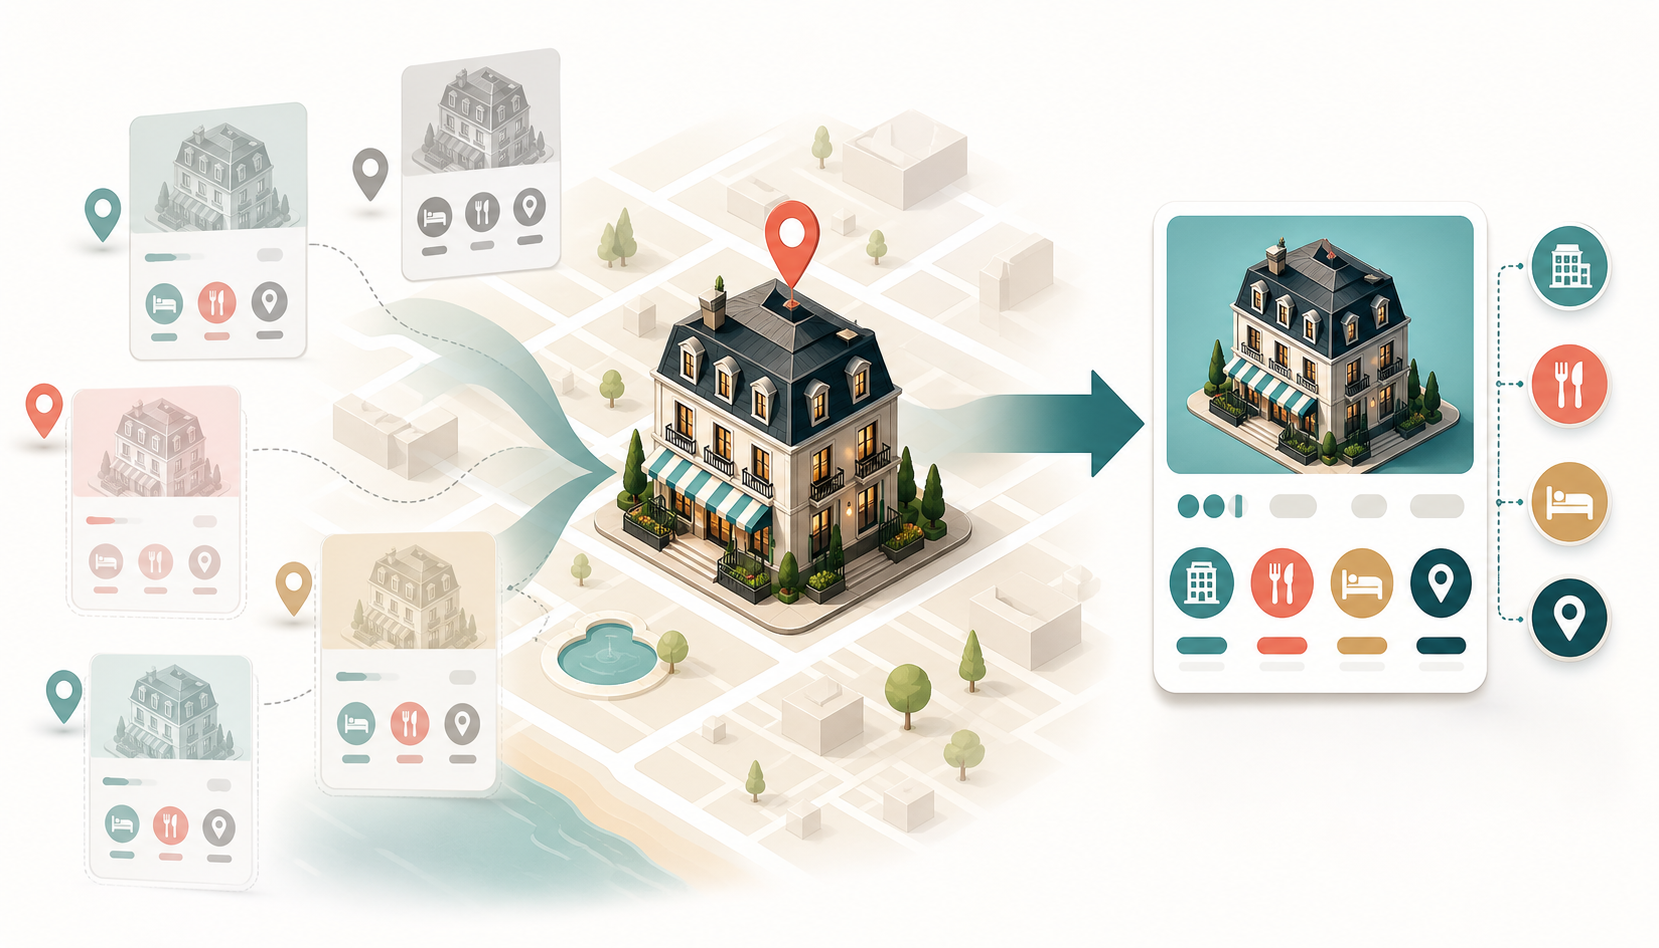
    Isometric illustration of duplicate map listings merging into one organized listing for a boutique inn.

    A beautifully written description cannot repair a fragmented business identity. Begin with the fields that determine which entity the listing represents and where it can be discovered.

    1. Look for duplicate and outdated listings. Search Tripadvisor and conventional search results using the exact business name, previous names, address, and common variations. Do this before creating anything new. A duplicate can divide attention, reviews, photos, and brand signals between competing pages.
    2. Claim and verify the correct listing. Use the profile representing the current operating business. Resolving duplicates can require official business documents and information that matches Google Business Profile, so keep the legal and customer-facing identity records available.
    3. Align the core facts. Check the operating name, address, website, primary business type, and other defining details against your website and Google Business Profile. Consistency means the facts agree; it does not mean every platform needs an identical marketing description.
    4. Select accurate categories and tags. Represent the full set of experiences the business genuinely provides. Tripadvisor uses these classifications for internal discovery and curated collections, so an omitted attribute can prevent an otherwise suitable business from appearing in a relevant list.
    5. Complete the decision-making fields. Describe the experience, amenities, menu, and other material offerings that a prospective guest needs to understand. Remove details that are no longer true.
    6. Review the public page as a customer. Confirm that the lead image, summary information, categories, and recent customer feedback create one coherent expectation. Owner dashboards can hide how disconnected a listing feels when its public elements are viewed together.

    Do not add categories merely because they attract desirable searches. If the listing claims a romantic dining experience, family-oriented amenity, or particular type of cuisine, the photos, menu, description, and customer feedback should support that claim. A misleading classification may win an impression but lose the booking when the visitor inspects the page.

    Use this priority order when resources are limited: correct identity, remove duplication, choose the right categories, update the offer, refresh the visual evidence, and then refine promotional wording. The early steps determine whether the right listing can be found; the later steps help it convert.

    Reviews and images should explain the experience, not decorate it

    Traveler photographing a guide presenting a regional dish to a small group inside an independent restaurant.

    Write owner responses that add useful context

    A review response is not only reputation management. It is public content attached to a specific customer experience. A thoughtful reply can turn a vague mention into a clearer explanation of what the business offers.

    If a guest says only that the pool was enjoyable, for example, a useful response can acknowledge the comment and mention a relevant family feature or activity, provided that feature genuinely exists. This creates additional semantic context around the property’s amenities. The response should still sound like a reply to a person, not a paragraph built to carry search terms.

    A reliable response structure is:

    • Acknowledge the specific experience. Refer to what the customer actually mentioned instead of opening with a generic template.
    • Add one relevant clarification. Explain a feature, setting, audience, or use case that helps the next reader understand the experience. Only add details you can substantiate.
    • Close naturally. Keep the response proportionate to the review. Repeating the business name, location, and service keywords adds clutter rather than value.

    You can also encourage more informative reviews without scripting praise. After the visit, invite the customer to describe which experience they booked, what stood out, who the experience suited, or what they would tell another traveler. That produces more decision-useful language than asking only for a star rating.

    Review velocity matters as an operational signal, but do not confuse velocity with sudden volume. The sustainable objective is a continuing stream of feedback from real customers, followed by regular owner attention. A burst of requests followed by months of silence leaves the listing looking less current and gives you fewer recent customer questions to learn from.

    Use current images as evidence of what someone can book

    Travel and hospitality decisions are visual. The strongest images quickly show what the guest will receive: the room, dish, view, activity, atmosphere, or defining feature. Replace photos that show an old menu, previous decor, unavailable amenities, or an experience that no longer represents the business.

    You do not need to guess which creative deserves the lead position. If you already publish comparable photos on Instagram, use the engagement data as a directional signal for which subjects and compositions attract attention, then confirm that the selected image accurately represents the bookable experience. Popularity is useful only after accuracy.

    Captions should describe the image in natural language. A practical formula is: what is shown, where or how it is experienced, and who or when it may be relevant. For example, a dish caption can identify the meal, the terrace or dining setting, and the season in which it is offered. Include audience claims such as “popular with solo travelers” only when you have a real basis for them. A string of location and service keywords does not help a traveler understand the image.

    Manage Tripadvisor as a measurable local search channel

    Profile optimization becomes difficult to defend when the only metric is average rating. Rating matters to customers, but it does not tell you whether the listing is accurate, discoverable, engaging, or sending qualified demand.

    Track the channel in layers:

    • Presence: Record whether the correct Tripadvisor page appears for your business name and relevant local discovery searches. Note duplicate or outdated results separately.
    • Profile health: Monitor completeness, category accuracy, current menu or experience information, image freshness, and unanswered-review backlog.
    • Activity: Watch review velocity, owner response activity, new image publication, and recurring themes in customer language.
    • Engagement: Use the interaction and click information available to the account to identify whether people are moving beyond a listing impression.
    • Business outcomes: In your web analytics, segment Tripadvisor referral visits and evaluate them against the booking, reservation, enquiry, or purchase action that matters to the business.

    Capture a baseline before making a substantial change. Compare equivalent reporting periods and annotate major profile updates, promotions, closures, and seasonal offer changes. This will not prove that a single caption or response caused a result, but it will prevent you from attributing every movement to the most recent edit.

    Website traffic is only one part of the journey. Tripadvisor also functions as a comparison environment where a customer may make a decision without visiting your domain. Read referral traffic alongside profile engagement and actual bookings rather than declaring the channel successful or unsuccessful from sessions alone.

    A manageable recurring workflow is to inspect identity fields and duplicates, clear the review-response backlog, replace outdated images or offer information, record emerging customer themes, and review referral outcomes. Assign ownership to a person or role. A listing that belongs vaguely to “marketing” is likely to remain untouched until a negative review or incorrect detail creates urgency.

    Key takeaways

    • Use Tripadvisor as a distributed local landing page and comparison surface, not merely a place to collect ratings.
    • Resolve duplicate listings and align core identity information with your website and Google Business Profile before rewriting promotional copy.
    • Choose categories and tags for experiences the business actually delivers; those classifications affect internal discovery and customer expectations.
    • Respond to reviews with one useful, factual layer of context instead of inserting keywords or repeating a template.
    • Refresh images, captions, menus, and experience details whenever the public offer changes.
    • Measure profile health, engagement, qualified referral traffic, and business outcomes separately so you can see where the journey is improving or breaking.

    Start with a duplicate and identity audit of the listing that already exists. Once the correct entity is established, improve one decision layer at a time: classification, offer clarity, reviews, images, and measurement. That sequence turns Tripadvisor from an unmanaged reputation page into a useful part of your local search system.

    References

  • AI Search Visibility Starts With Five Technical SEO Gates

    AI Search Visibility Starts With Five Technical SEO Gates

    You published a useful page, submitted it for discovery, and confirmed that it loads in a browser. Yet your brand still disappears when an AI system answers the questions that page was built to solve. Rewriting the introduction or adding another block of schema may feel productive, but either move can target the wrong layer.

    Before your content can win on relevance, authority, or corroboration, its meaning has to reach the system intact. Audit that journey in sequence. Find the earliest failure, repair it, and only then work on the prompts and competitive signals that determine whether the page is used in an answer.

    AI visibility is a chain, not a single ranking event

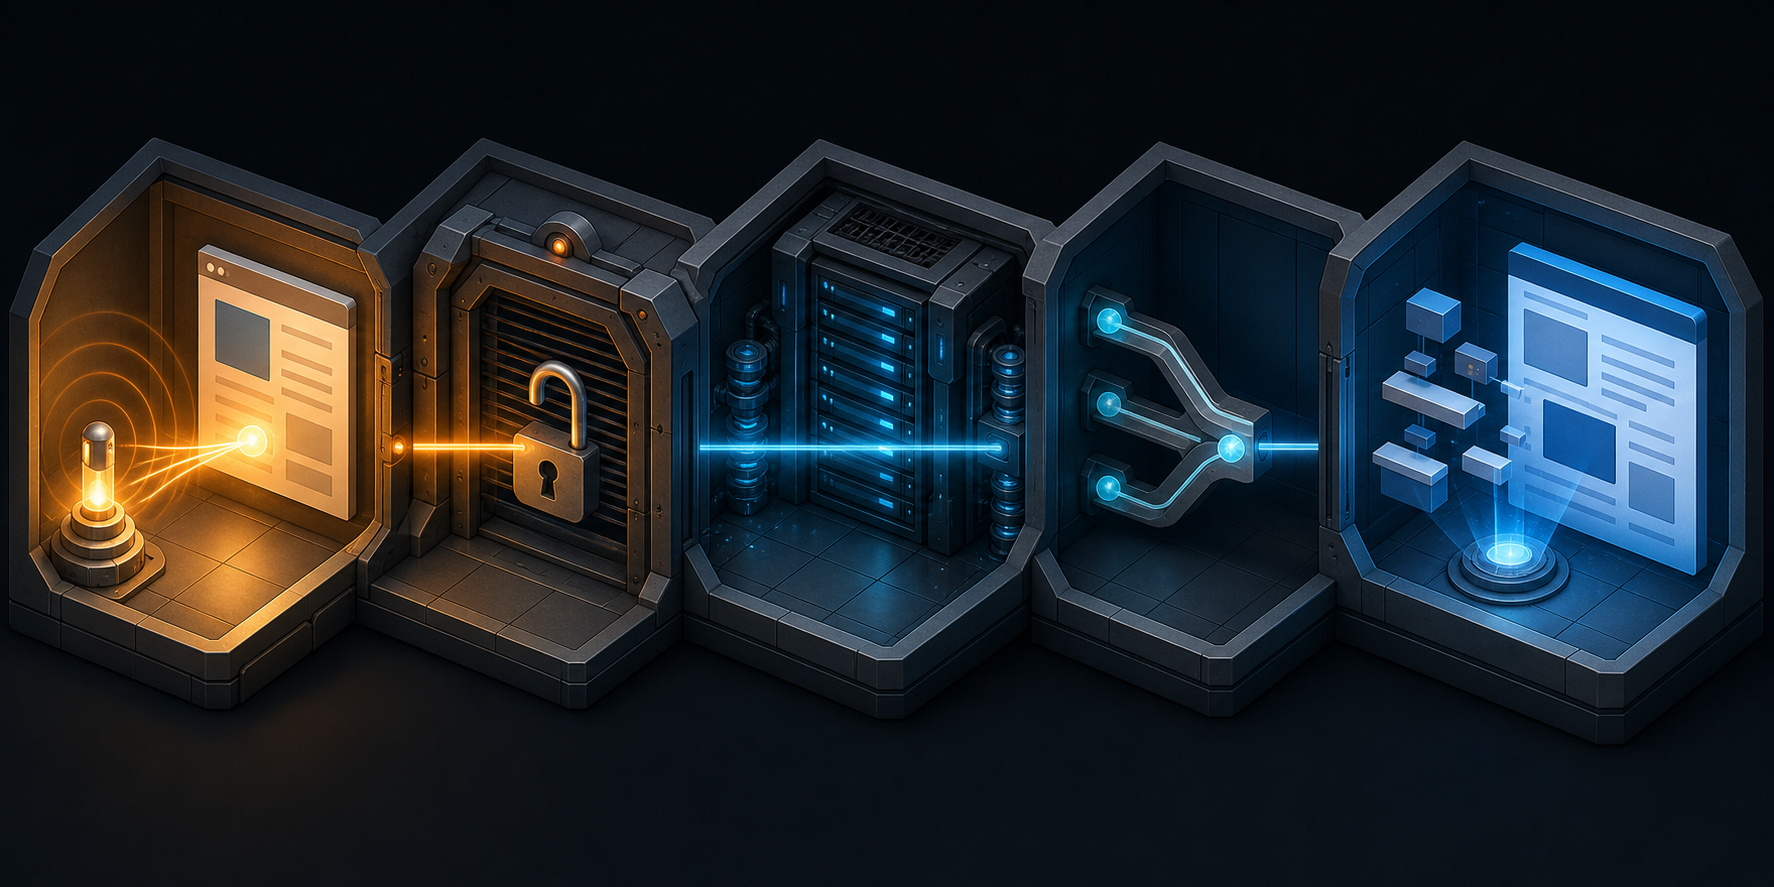
    The familiar instruction to “crawl and index” compresses several different decisions into one checkbox. In practice, content must pass through discovery, selection, crawling, rendering, and indexing. Each gate asks a different question:

    • Discovery: Does the system know that the URL exists and how it relates to the rest of your site?
    • Selection: Is the URL worth fetching relative to the other URLs competing for attention?
    • Crawling: Can the system retrieve the page reliably?
    • Rendering: Does the retrieved version contain the main content, links, and facts?
    • Indexing: Can the system identify and retain the page’s essential meaning?

    These gates are sequential, but their failures don’t always look dramatic. A page can be fetched successfully while its main explanation remains trapped behind JavaScript. It can then be indexed from a thin or misleading representation. Your monitoring may show an accessible URL even though the information needed for an AI answer never survived.

    That distinction changes what you do next. If the URL hasn’t been discovered, editing the copy won’t help. If the initial response omits the core answer, additional authority signals won’t restore it. If the indexed representation is accurate but the page still isn’t selected for relevant prompts, you can move downstream to task coverage, corroboration, and authority.

    Indexing is therefore a prerequisite, not proof of AI visibility. AI systems don’t share one index or one diagnostic console, and evidence from a traditional search engine doesn’t confirm inclusion everywhere else. Record what you can confirm for each system, mark what remains unknown, and avoid turning an assumption into a passing audit grade.

    Audit the five infrastructure gates in order

    An isometric pathway shows five technical checkpoints, with a diagnostic light stopping at the first blocked gate.

    Start with one commercially or strategically important URL. A sitewide score can hide the failure you need to see, while a single-URL evidence sheet forces each conclusion to be testable. Use the following sequence as your first-pass audit.

    GateQuestion to answerUseful evidenceFirst corrective action
    DiscoveryCan systems find the URL and connect it to a known topic or entity?Current XML sitemap, IndexNow submission where supported, contextual internal links, relevant hub placementRemove orphan status and create a clear route from an established page
    SelectionWhy should this URL be fetched instead of another URL?Sitemap quality, duplication patterns, stale inventory, competing variants, internal-link prominenceReduce discovery noise and consolidate pages that perform the same task
    CrawlingCan the intended machine client retrieve the URL reliably?Server logs, access rules, HTTP response, redirects, authentication, rate limitsRemove the access or response failure before changing the content
    RenderingDoes the retrievable version contain the main answer?Initial response HTML, rendered output, JavaScript-disabled view, extracted text and linksDeliver essential content in server-generated HTML
    IndexingCan a machine identify the page’s subject, entities, claims, and relationships?Heading outline, semantic markup, text extraction, structured data, stored search representation where availableClarify the main topic and make visible content agree with the markup

    Discovery: remove orphan status

    Discovery is signal-based. XML sitemaps and supported submission mechanisms can announce a URL, but internal links explain where it belongs. A page that appears only in a sitemap may be technically known while remaining weakly associated with your products, expertise, or topic clusters.

    • Confirm that the intended URL is present in the current sitemap and resolves to the page you expect.
    • Link to it from at least one established, relevant page using anchor text that describes the destination.
    • Place it within the appropriate topic, product, documentation, or resource hub rather than relying on a generic archive.
    • Use IndexNow when it fits your platform and the receiving system supports it, especially after meaningful publication or revision events.
    • Check that the page names its primary entity and subject consistently with the pages linking to it.

    The practical test is simple: begin on a page that already represents the topic and follow ordinary links to the target. If you can reach it only through a sitemap, an internal search box, or a manually pasted URL, discovery needs work.

    Selection: stop making every URL look equally important

    Discovery adds a candidate; selection determines whether that candidate receives attention. This is where oversized inventories become a technical SEO problem. Facets, parameter combinations, near-duplicate location pages, expired material, and lightly altered variants can consume signals without adding distinct value.

    For crawl selection, less can be more. That isn’t permission to delete URLs blindly. It is a reason to decide which pages perform unique audience tasks and which merely repeat an existing answer.

    • Group URLs by the task they solve, not merely by their keyword variation.
    • Flag pages whose purpose, answer, and supporting evidence substantially overlap.
    • Keep discovery feeds focused on URLs you genuinely want systems to process.
    • Consolidate overlapping information where one stronger page can satisfy the task without erasing a necessary user path.
    • Give important pages stronger contextual links instead of treating every item in a large archive as equal.

    If several pages compete to define the same entity or answer the same question, the problem isn’t a lack of content. It is an excess of ambiguous choices.

    Crawling: verify retrieval rather than assuming it

    A browser visit proves that your browser can retrieve the page under your conditions. It doesn’t prove that every machine client can do the same. Access rules, authentication, rate controls, redirect behavior, and unstable server responses can affect automated retrieval differently.

    • Inspect server logs when available to determine whether the relevant client requested the URL and what happened.
    • Check that automated access isn’t blocked by authentication, consent handling, security middleware, or bot controls.
    • Follow the complete redirect path and confirm that it ends on the intended content.
    • Test the response without browser cookies, cached assets, or an authenticated session.
    • Separate a retrieval failure from a rendering failure: receiving HTML doesn’t prove that the HTML contains the answer.

    When you can’t directly observe a particular AI crawler, record the status as unknown rather than passed. Use the server and retrieval evidence you do have, then make the page robust enough that it doesn’t depend on a privileged browser session.

    Rendering: inspect what arrives before JavaScript runs

    Rendering is often the hidden break. Modern browsers assemble pages from scripts, APIs, templates, and client-side components. Not every system invests in executing JavaScript, and those that do may not reproduce the same result as a user’s browser.

    Run a content-survival test:

    1. Retrieve the initial HTML returned by the server.
    2. Locate the page’s main answer, defining facts, entity names, headings, comparison data, and contextual links.
    3. Compare that material with the fully rendered browser version.
    4. Disable JavaScript and repeat the comparison.
    5. Classify every missing item as essential content, useful enhancement, or interaction-only functionality.

    Move essential content into server-generated HTML. Server-side rendering is one route; the implementation matters less than the result. The main answer, supporting facts, meaningful link relationships, and labels needed to interpret data should exist before client-side enhancement.

    This isn’t a ban on JavaScript. Filters, calculators, personalization, and interface behavior may legitimately depend on it. The mistake is making JavaScript the only delivery route for the information you expect machines to quote, compare, or recommend.

    Indexing: make the essential meaning unmistakable

    After retrieval and rendering, a system still has to decide what the page is about and which information deserves storage. A technically complete page can remain difficult to interpret if its topic is implied, entity names change between sections, visual position carries the meaning, or the main answer is buried among navigation and promotional copy.

    • State the page’s primary subject and purpose near the beginning.
    • Use descriptive headings whose sections answer distinct parts of the task.
    • Name entities consistently instead of alternating among unexplained labels.
    • Represent real relationships with semantic elements: lists for sequences, tables for tabular comparisons, and links for navigable connections.
    • Give data and claims explicit labels so they remain intelligible after visual layout is removed.
    • Make structured data agree with the visible page rather than introducing a second, conflicting version of the facts.

    Read the page as extracted text, without its design. If you can no longer tell which value belongs to which product, which condition qualifies a recommendation, or which entity a pronoun refers to, conversion into an indexable representation is likely to lose confidence.

    Deliver the meaning before adding more schema

    Structured data is valuable when it confirms an already coherent page. It can clarify entity types and relationships, but it can’t compensate for a URL that wasn’t selected, content that wasn’t retrieved, or an answer that exists only after an unreliable rendering step.

    Use this order of operations:

    1. Put the complete core answer in the HTML delivered by the server.
    2. Organize that answer with meaningful headings, paragraphs, lists, tables, and links.
    3. Use explicit entity names and relationship language in the visible copy.
    4. Add JSON-LD that describes the same entities, properties, and relationships.
    5. Validate the markup, then compare it with the rendered and extracted page for factual consistency.

    Passing a structured-data validator confirms syntax and recognizable fields. It doesn’t prove that an AI system discovered the URL, retained the content, trusts the claim, or will select the page for an answer. Keep validation in its proper place: it is a markup check inside a larger delivery and interpretation audit.

    Pay particular attention to information encoded visually. A row of feature icons, a color-coded pricing grid, or a diagram with unlabeled connections may be obvious to a person while becoming ambiguous in text conversion. Repeat consequential labels in machine-readable text and use a real table when the information genuinely has rows and columns.

    Alternative machine-facing pathways such as WebMCP, Markdown for Agents, or Cloudflare-provided markup may also be worth evaluating for your stack. Treat them as additional delivery routes to test, not universal substitutes for accessible HTML. Before relying on one, verify that the intended recipient can retrieve it, that it carries the complete answer, and that its facts stay synchronized with the public page.

    Build for prompt fan-out without publishing endless pages

    A central knowledge hub branches toward many question-shaped nodes while connecting to a small set of substantial pages.

    Once the infrastructure works, the optimization question changes. People no longer have to compress every need into a neat keyword. They can include their situation, constraints, doubts, preferences, and desired outcome in one request. This creates an effectively infinite tail of prompt variations.

    Keyword research still has a role. It reveals recognizable language and established demand. What it can’t do alone is model all the ways a person frames a task or all the subquestions an AI system may generate while building an answer.

    Replace the keyword-only map with a task map:

    1. Write the real task the reader is trying to complete.
    2. Identify the reader’s stage: learning, diagnosing, comparing, deciding, implementing, or verifying.
    3. List constraints that change a useful answer, such as platform, resources, risk tolerance, or an existing technical limitation.
    4. List the uncertainties that block the next decision.
    5. Break the task into the subquestions a careful evaluator would need answered.
    6. Assign each subquestion to a page or a clearly labeled section.
    7. Identify what evidence would reduce uncertainty: definitions, mechanisms, comparisons, limitations, examples, or external corroboration.

    Consider a reader asking, “Our documentation ranks in search but stopped appearing in AI answers after a JavaScript redesign. Should we rewrite it or change the site?” The wording is only one possible prompt. The durable task contains several subquestions: Can systems discover the documentation? Is it selected for retrieval? Does the initial response contain the text? Does rendering preserve links and labels? Is the indexed meaning accurate? Do other credible pages corroborate the important claims?

    A page that answers those subquestions in a logical sequence can support many prompt variations without repeating the exact sentence. A collection of thin pages targeting minor wording changes may do the opposite: increase crawl-selection noise while splitting the evidence needed to complete the task.

    Prompt fan-out also changes how you think about authority. Complex requests can be decomposed into multiple queries, while grounding queries check consistency and reputation across the wider web. Schema can describe your claim, but it can’t make several pages on your own domain count as independent confirmation.

    You can still reduce uncertainty. Keep names, descriptions, product facts, and definitions consistent across your site. Link supporting material to the claim it substantiates. Correct conflicting legacy pages. Make primary evidence easy to retrieve. Then pursue genuine external validation where the decision warrants it. Technical clarity helps a system understand your evidence; independent corroboration helps it decide how much confidence to place in that evidence.

    Track infrastructure and competitiveness separately

    Mixing the two layers produces misleading reports. Maintain one scorecard for URL survival and another for answer eligibility.

    • Infrastructure scorecard: discovery signals present, retrieval observed or unknown, essential content in the initial HTML, rendered content complete, extracted meaning accurate, structured data consistent.
    • Competitive scorecard: audience task defined, prompt constraints covered, fan-out subquestions answered, claims supported, entity facts consistent, external corroboration present, next action clear.

    Use confirmed, failed, and unknown as status values. A false pass is more damaging than an honest unknown because it sends the team downstream to rewrite content or build authority around a page whose evidence may not be reaching the system.

    Key takeaways

    • AI search visibility begins with five sequential infrastructure gates: discovery, selection, crawling, rendering, and indexing.
    • A successful fetch doesn’t prove that the main answer survived rendering or that the stored representation is accurate.
    • Audit the earliest possible failure first; downstream content and authority work can’t recover information that never arrived.
    • Serve essential meaning in initial HTML, organize it semantically, and use JSON-LD to confirm the visible facts.
    • Plan around audience tasks and fan-out subquestions rather than publishing a separate page for every prompt variation.
    • Measure technical survival separately from competitive selection, corroboration, and authority.

    Your next move is a one-URL audit. Choose a page that matters, create an evidence row for every gate, and stop at the first failure you can prove. After the complete answer survives extraction, map one audience task and its subquestions against the page. That sequence gives every later SEO, AEO, GEO, and schema decision something solid to build on.

    References

  • SEO in AI-Driven Search: A Practical Visibility Plan

    SEO in AI-Driven Search: A Practical Visibility Plan

    Your rankings can look respectable while organic sessions keep sliding. That does not automatically mean your SEO has failed. The answer may have moved upstream, into a featured result, an AI Overview, or an assistant response that satisfies the user before a visit happens.

    The same dashboard pattern can also come from lost positions, weaker snippets, stale information, indexing trouble, or changing demand. If you label every decline an AI problem, you will fix the wrong thing. You now need to determine where discovery broke, measure visibility before the click, make your pages easier to retrieve, and extract more value from the visitors who still arrive.

    Key takeaways

    • Do not treat falling clicks as proof that an AI system is citing you. Separate click interception from an actual loss of search visibility.
    • Add citations, brand mentions, share of voice, sentiment, and AI-influenced visits to your reporting. Rankings and sessions show only part of the journey.
    • Write self-contained answer passages with clear scope, evidence, qualifications, and next steps. Do not hide the useful answer inside a long introduction.
    • Build authority beyond your own domain. Reviews, expert coverage, community discussions, newsletters, and video can corroborate what your site says.
    • Give an AI-referred visitor a focused landing experience. Detailed educational content and conversion pages have different jobs.

    Diagnose the traffic loss before changing your content

    An analyst examines several colored pathways that weaken or break at different stages before reaching a website tile.

    Zero-click behavior is no longer an edge case. More than 65% of searches may now end without a click, while AI Overviews have been reported in about 16% of desktop searches and 41% of mobile searches. Those figures explain why a page can remain visible without receiving the traffic it once did. They do not prove that every lost click went to an AI answer.

    Start by grouping your query-and-page data according to the pattern you can actually observe. The pattern determines the investigation:

    Observed patternWhat it may meanWhat to check next
    Impressions are steady or rising, but clicks are fallingAn answer feature may be intercepting clicks, your result may have moved lower, or competing snippets may have become more persuasiveCompare position and click-through rate by query, then inspect the live results for AI Overviews, featured snippets, knowledge panels, video results, and changed titles
    Impressions and clicks are both fallingYour page may be losing eligibility or demand, not merely losing clicks to an answer surfaceCheck indexing, ranking movement, query demand, content freshness, internal links, and stronger competing pages
    Your brand is mentioned in AI answers but your pages are not citedThe brand may be recognized through third-party material while your owned content is not being selected as evidenceIdentify which outside pages are shaping the answer, then improve the relevant owned page and the consistency of external descriptions
    AI referrals are small but produce meaningful actionsLow volume may be masking high intentTrack the referring assistant, landing page, conversion action, and resulting value separately from general organic traffic

    For the first pattern, compare query-level impressions, average position, clicks, and click-through rate across equivalent periods. If position and impressions hold while click-through rate drops after a result page gains a direct-answer feature, click interception becomes a plausible explanation. If both position and impressions deteriorate, work on search eligibility and relevance before blaming AI.

    Then inspect AI answers separately. A search performance report cannot tell you that an assistant quoted, cited, summarized, or ignored your page. An impression-click gap is a signal to investigate, not evidence of an AI citation.

    Build an AI visibility scorecard you can repeat

    Traditional analytics begin when a platform records an impression or a visitor reaches your site. AI-mediated discovery can happen before either event. Your measurement system therefore needs a controlled set of questions that represents the market you want to influence.

    Build that set from real customer language: search queries, sales questions, support requests, on-site searches, and objections heard during evaluation. Include several kinds of intent:

    • Understanding: questions asking what a concept means, how it works, or why it matters.
    • Evaluation: questions about alternatives, selection criteria, trade-offs, and suitability for a particular situation.
    • Implementation: questions asking for steps, requirements, examples, or troubleshooting help.
    • Risk: questions about limitations, failure modes, cost, compatibility, or consequences.

    Run the same question set across the AI interfaces your audience actually uses. Record the interface, model when visible, date, prompt, response, cited URLs, brands mentioned, answer framing, and any resulting referral. Because generated answers can vary between runs, treat the scorecard as a trend instrument rather than a census of everything an AI system knows.

    Your scorecard should distinguish five measurements:

    • Citation coverage: the share of tested questions for which an AI response links to your domain. Preserve the exact cited URL so you can see which page and passage appear to be winning.
    • Brand mention coverage: the share of responses that name your brand, whether or not they cite you. A mention and an owned citation are not interchangeable.
    • Share of voice: your citations and mentions as a share of all tracked brands within the same fixed question set. Keep the denominator and prompt set stable so movement remains interpretable.
    • Brand sentiment: whether the response presents the brand positively, neutrally, negatively, or with a material qualification. Save the language that supports the label instead of recording an unexplained opinion.
    • AI-influenced traffic: visits and conversions attributable to assistant referrals. Report volume, conversion rate, landing page, and outcome together.

    The combinations are often more useful than any metric alone. Frequent mentions with few owned citations point toward a content-selection or corroboration gap. Low mentions and low citations suggest a broader authority or category-association problem. Strong citation coverage with little traffic may still represent successful answer visibility, but you will need a separate way to value that exposure. Referral traffic with weak conversion usually points to a mismatch between the AI answer’s promise and the destination page.

    Automated visibility platforms can scale this work, but do not buy a dashboard before defining the questions, entities, competitors, and decisions it must track. A carefully maintained manual benchmark is more useful than a large report whose prompts and scoring rules you cannot inspect.

    Engineer content for retrieval, trust, and corroboration

    A modular web document connects through a retrieval prism to several independent source tiles surrounding a shared fact node.

    AI search does not reward a page simply because it is long. The useful unit is the passage that answers a question clearly enough to extract and credible enough to reuse. That shifts the editing question from “Did we cover the keyword?” to “Can a reader or machine identify the answer, its scope, and the reason to trust it?”

    Give each important answer a complete, self-contained block

    Organize important sections around the question a reader is trying to resolve. A strong answer block usually performs these jobs in order:

    1. State the answer: place the direct response in the opening sentence or short paragraph beneath the heading.
    2. Define the scope: name the product, audience, market, version, or condition to which the answer applies.
    3. Show the basis: provide evidence, a method, a concrete example, or a link that supports the claim.
    4. Handle the exception: explain the trade-off or circumstance in which the answer changes.
    5. Give the next action: tell the reader what to inspect, choose, calculate, or change.

    This is not a command to turn every page into a pile of shallow FAQs. Use question-and-answer structure where a distinct question exists, and use prose where the reader needs explanation or judgement. Clear headings, concise summaries, bullets, comparison tables, and unambiguous question-and-answer pairs improve retrievability. Dense narrative that delays the answer makes extraction harder and frustrates the person reading it.

    Do not repeat the same generic definition across many pages. Decide which URL owns the complete answer, link supporting pages to it, and remove contradictions. A coherent information architecture gives search systems a clearer canonical explanation and gives your editors one place to maintain it.

    Make expertise and freshness visible on the page

    Claims of expertise are weak evidence. Show the work instead. Name the author or reviewer, explain why that person is qualified for this topic, state how recommendations were derived, link important claims, and identify meaningful limitations. If you conducted an original analysis, describe the dataset and method closely enough for someone to understand what the result does and does not establish.

    Freshness matters when an answer can change. An older page can be passed over for a newer treatment of the same question, even when much of the older explanation remains useful. Audit pages that influence important queries. Replace obsolete figures, verify product behavior, revise examples, repair broken citations, and expose a genuine update date. Changing a date without changing the substance does not make the answer more reliable.

    Use AI to accelerate research organization, outlining, or editing if it helps your workflow, but keep a subject-matter expert responsible for the final claim. Remove generic transitions, unsupported certainty, fabricated examples, and passages that merely restate the heading. Human review matters because the page must survive a reader checking the details, not merely a classifier parsing the text.

    Keep educational passages neutral enough to function as evidence. A page that says your product is the obvious choice for everyone gives an answer engine little reason to trust the comparison. State who each option suits, what it requires, where it falls short, and which criteria change the decision. You can still reach a clear recommendation after acknowledging the trade-offs.

    Create corroboration beyond your own domain

    Your website is only one input into an AI system’s representation of your brand. Reviews on G2, Capterra, and Google, community discussions on Reddit, third-party tutorials, newsletters, and YouTube videos can all contribute to the external evidence surrounding a brand. This is why a company with modest owned content can still appear prominently when independent sources describe it consistently.

    Start with the claims that matter most: what category you belong to, who the product serves, which problems it solves, and what makes it materially different. Audit how those claims appear on your site, review profiles, partner pages, interviews, directories, and community discussions. Correct factual conflicts where you control the page. Where you do not, offer verifiable information rather than demanding favorable wording.

    • Make accurate company facts, product descriptions, expert biographies, and supporting evidence easy for partners and journalists to verify.
    • Contribute useful data, demonstrations, commentary, or tutorials to publications and creators whose audiences overlap with yours.
    • Encourage authentic customer reviews through a consistent process, but never script praise or manufacture community discussion.
    • Track third-party URLs that receive AI citations. They reveal which independent voices and content formats carry authority for your topic.
    • Compare external descriptions with your preferred positioning. Repeated disagreement may indicate a product-perception problem, not a wording problem.

    Consistency does not mean publishing identical marketing copy everywhere. It means that independently written material converges on the same verifiable facts. That kind of corroboration is harder to manufacture and more useful to both buyers and answer systems.

    Turn fewer, higher-intent clicks into measurable outcomes

    A shrinking click pool makes each qualified visit more important. Early tracking indicates that traffic from LLM referrals may convert at three to five times the rate of other sources. Treat that range as directional, not a promise for your site: referral labeling, audience, offer, and conversion definitions can all affect the result.

    Preserve the referral detail instead of burying these visits inside a broad channel. For each assistant referral, record the destination, action taken, conversion value where appropriate, and the question or topic that likely led there. A small channel that consistently reaches high-value pages deserves different treatment from a large channel producing casual visits.

    The destination must continue the answer that earned the click. Keep educational pages deep and well supported; they need nuance for readers and retrievability for answer systems. Keep conversion landing pages focused:

    • Lead with a header that states the offer, intended user, and value without requiring a scroll to understand it.
    • Use a single primary call to action tied to the reason the visitor arrived.
    • Keep supporting points brief and place the most relevant proof close to the decision.
    • Remove competing messages that force the visitor to decide what the page is about.
    • Create separate landing pages when offers, audiences, or conversion goals differ materially.
    • Check that the page fulfills the promise made by the cited passage, third-party description, or AI response.

    Put the work in a practical order. Establish a fixed visibility benchmark for a commercially important topic. Diagnose the search patterns for the pages already associated with it. Rewrite the strongest candidates into complete answer blocks, verify their evidence and freshness, then map the external sources that shape the same conversation. Finally, inspect the path from every measurable AI referral to its conversion action.

    Before commissioning more content, apply that sequence to the topic closest to a real business outcome. You will learn whether the immediate constraint is search eligibility, passage quality, external authority, or the landing experience. That diagnosis gives you a defensible next investment instead of another round of undirected publishing.

    References

  • Content Structure and Technical SEO for Machine Retrieval

    Content Structure and Technical SEO for Machine Retrieval

    If a page contains the right answer but rarely becomes the answer that search engines or AI systems retrieve, topic coverage may not be the problem. The useful passage could be buried in a multi-purpose paragraph, separated from a vague heading, added only after a click, or obscured by an unnecessarily complex DOM.

    You need two conditions to hold at the same time: the answer must form a clear unit of meaning, and the rendered page must expose that unit in a structure a crawler can reach and interpret. Here is how to build and test both without turning useful prose into disconnected fragments.

    Diagnose the content layer and delivery layer separately

    Machine retrieval can fail at either of two layers. A content-layer failure makes the answer hard to isolate. A delivery-layer failure prevents the machine from reliably receiving the answer at all. Rewriting copy will not repair content that never enters the crawler’s DOM, while a rendering fix will not clarify a paragraph that tries to answer four questions at once.

    LayerTypical failureFirst check
    Content structureThe answer is scattered across sections, introduced by a generic heading, or dependent on distant context.Copy the relevant heading and passage into a blank document. Check whether they still answer the target question clearly.
    DOM structureThe heading and answer have an unclear relationship because of excessive nesting, misplaced elements, or JavaScript changes.Inspect the live DOM and confirm that the passage sits under the intended heading in a logical hierarchy.
    Content deliveryImportant text or links appear only after a click, selection, or other user action.Reload the page and check what exists before any interaction.
    Crawler accessGoogle may render the content, but another crawler that does not execute JavaScript receives an incomplete page.Compare the initial HTML, the browser DOM, and the crawler-rendered HTML.

    Start with the layer that fails. If the passage is missing after a fresh load, fix delivery first. If it is present but ambiguous outside the full page, restructure it. If both tests pass, investigate relevance, authority, and other ranking factors rather than repeatedly editing an already retrievable answer.

    Build answer-sized sections without writing fragments

    A useful content chunk is a self-contained unit centered on one idea. It is not a fixed word count, a paragraph chopped at an arbitrary length, or a collection of terse statements written to resemble search snippets. Its boundary follows a change in the reader’s question.

    Build those boundaries into the outline before drafting:

    1. Assign one job to each section. An H2 can cover a major decision or task. Use an H3 only when that task divides into a distinct question that deserves its own answer.
    2. Write the heading as a promise. Replace labels such as Overview, Details, or Implementation with language that identifies what the reader will learn. A heading such as How JavaScript-loaded content affects crawling establishes a much clearer retrieval target.
    3. Answer the heading promptly. Put the direct answer in the opening sentence or paragraph, then add the mechanism, conditions, exceptions, and next action.
    4. Keep each paragraph on one idea. Start a new paragraph when you move from definition to consequence, from consequence to procedure, or from a general rule to an exception.
    5. Use a list only when the items are genuinely parallel. Steps, criteria, checks, and alternatives belong in lists. A connected explanation still belongs in prose.

    Run the self-contained passage test

    Copy a heading and the passage immediately below it into a blank document. Do not include the title, introduction, sidebar, or preceding section. Then ask:

    • Does the heading identify the actual question or decision?
    • Does the first sentence give a direct answer rather than a transition?
    • Are important nouns named, or does the passage rely on vague references such as this, that, it, or they?
    • Does the passage contain the condition that limits the advice?
    • Can a reader act without searching the rest of the page for a missing step?

    For example, Implementation considerations followed by This can create problems is not independently useful. How interaction-dependent content affects crawling followed by Content added only after a user action may be absent from a crawler’s initial view establishes the subject, mechanism, and risk immediately.

    Preserve the reading path between chunks

    Self-contained does not mean isolated. A section should carry enough context to survive retrieval while still advancing the page’s larger argument. Keep necessary transitions, define a term before relying on it, and let supporting paragraphs deepen the answer instead of restating it.

    Do not split one coherent explanation merely to manufacture more headings. The practical case for chunking is that clear sections help people scan and give machines more precise passages to interpret. If the result feels repetitive or jerky to a reader, the boundaries are too aggressive.

    Make the content hierarchy explicit in the DOM

    An isometric document structure shows orderly nested content blocks beside a smaller cluster of tangled and disconnected elements.

    A person sees a rendered page. A crawler works with a document structure. The DOM is the browser’s in-memory tree of elements and their parent, child, and sibling relationships. Those relationships help establish which paragraph belongs to which heading and which sections belong to the main article.

    Use HTML that expresses those relationships directly:

    • Place the primary editorial content in an <article> element rather than mixing it with navigation and unrelated interface components.
    • Use heading levels to represent hierarchy, not visual size. An H3 should describe a subsection of the preceding H2.
    • Group a coherent topic in a <section> when that grouping adds meaning to the document structure.
    • Use <p> for paragraphs and real <ul> or <ol> elements for lists instead of constructing their appearance from generic containers.
    • Remove empty wrappers and repeated layout containers that make the tree deeper without adding structure.

    Semantic markup is not a substitute for relevant content, and changing a <div> to a <section> does not guarantee a ranking gain. Its value is more basic: it reduces ambiguity and makes the intended hierarchy easier to preserve across browsers, templates, crawlers, and assistive systems.

    The HTML response is only the starting point. As the browser parses that HTML into nodes, JavaScript can pause construction, add elements, replace text, or change links. The result can be a final DOM that differs materially from the original HTML.

    Keep three versions of the page distinct

    • Initial HTML: the response returned by the server before client-side scripts modify it.
    • Current browser DOM: the live tree shown in the Elements panel after scripts have run and possibly after a person has interacted with the page.
    • Crawler-rendered HTML: the version a particular crawler produced with its own rendering capabilities, timing, and interaction limits.

    These versions can match, but you should not assume they do. That distinction matters whenever a template relies on client-side rendering, delayed components, tabs, expandable panels, or JavaScript navigation.

    Test retrieval on the rendered page before publishing

    A scanning probe traces a clear path through a rendered web page and illuminates one visible, self-contained content block.

    The safest delivery rule is simple: important content should enter the DOM during the initial page load. Googlebot can parse HTML, execute JavaScript, and evaluate a rendered DOM, but it does not interact with a page as a person would. Other crawlers may not render JavaScript at all.

    This creates an important distinction for tabs and accordions. If the text is already in the DOM and the control merely changes its presentation, the content is present for inspection. If clicking the control fetches or creates the text, a non-interacting crawler may never receive it. Move essential answers into the initial render or provide an ordinary crawlable page that contains them.

    Run this release check on every important template and on any page where machine visibility matters:

    1. Choose the target answer. Write down the exact question the page should answer and identify the heading and passage intended to answer it.
    2. Reload without interacting. Confirm that the complete answer appears without a click, scroll-triggered action, selection, or form submission.
    3. Inspect the live DOM. Open browser DevTools, select Elements, and use Ctrl+F or Cmd+F to search for a distinctive phrase from the answer. Confirm that it appears once, in the intended section, under the correct heading.
    4. Inspect internal links. Important navigation should use real <a> elements with usable destinations. JavaScript event handlers that merely imitate links create avoidable crawlability risk.
    5. Check the crawler’s render. Use Google Search Console’s URL Inspection tool to examine the rendered HTML available to Google. Search that output for the same distinctive phrase, heading, and essential internal links.
    6. Use a public fallback when needed. If you do not have Search Console access, the Rich Results Test can provide a rendered-page view for investigation. Treat it as a diagnostic aid, not proof of what has already been indexed.
    7. Review DOM size. In the browser console, document.querySelectorAll('*').length provides a simple element count. Treat about 1,500 nodes as a reason to investigate unnecessary complexity, not as a universal ranking cutoff. Remove redundant wrappers and duplicated components only after confirming they are not required by the interface.

    Choose legacy pages by expected return

    You do not need to rechunk an entire archive at once. Start with high-value pages where structure is most likely to be limiting performance:

    • Pages with meaningful traffic but weak engagement, especially when readers must hunt for the promised answer.
    • Pages that already rank for relevant queries but are not being surfaced or cited for the specific answers they contain.
    • Complex explanations where headings are generic and paragraphs routinely change subject midway through.
    • JavaScript-heavy pages where important text is absent from the initial response or appears only after interaction.

    For each candidate, record whether the failure is structural, technical, or both. That prevents a content team from rewriting material that actually needs a template fix, and it keeps developers from rebuilding components when clearer headings would solve the immediate retrieval problem.

    Key takeaways for machine-retrievable content

    • A retrievable answer needs both a clear unit of meaning and reliable delivery in the rendered page.
    • Let each heading make a specific promise, then answer it promptly in a focused passage.
    • Split content when the reader’s question changes, not when a paragraph reaches an arbitrary length.
    • Use semantic HTML and a logical heading hierarchy to make relationships explicit in the DOM.
    • Put important text and links in the initial page state rather than behind required interaction.
    • Compare the initial HTML, live DOM, and crawler-rendered HTML instead of assuming that one represents all three.
    • Use DOM size as an investigation signal, not as a standalone SEO score.

    Pick one commercially important URL and test one intended answer from outline to rendered DOM. Repair the first broken handoff you find, validate the crawler-visible result, and only then scale the same audit across the rest of the template or content set.

    References

  • Boost SEO with AI Without Sacrificing Your Unique Brand Voice

    Boost SEO with AI Without Sacrificing Your Unique Brand Voice

    As someone navigating the world of SEO and content marketing, I’ve noticed a looming problem: everything is starting to sound eerily similar. It’s the same phrases, the same structure, and a robotic tone that seems to dominate.

    The web is overflowing with content that’s perfectly optimized yet fails to engage readers. That’s the real danger, not AI replacing SEOs or causing penalties. The biggest threat is losing our unique brand voice in the quest for efficiency.

    Rather than flattening our content, AI should enhance our SEO efforts. It should make us faster and more adaptable, without stripping away what makes our brand stand out. Here’s how I ensure AI doesn’t turn my brand into a faceless entity.

    To me, AI works best when it complements a clear strategy. It’s not a substitute for a marketing plan or brand direction. Just like tools such as Google Analytics or Semrush, AI is a support system, not a replacement.

    In my experience, without a deep understanding of our audience, AI merely churns out content that lacks distinction. That’s why defining who you are as a brand is crucial before turning to AI as an assistant.

    I’ve found AI shines when handling large data sets, spotting trends, or identifying content gaps. It accelerates my processes, allowing me to focus on the strategic aspects of SEO.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    However, AI falls short in areas that depend on creativity and emotional engagement. It doesn’t truly understand brand values or ethical nuances. It can mimic, but not truly connect or empathize.

    Therefore, I let AI handle data-driven tasks, while keeping the heart of my branding – its voice and soul – firmly within human hands.

    Before using AI, I clarify my brand’s tone, language, and boundaries. A well-defined brand voice ensures AI assists without diluting our identity.

    In practice, I use AI for research and framework creation, but ensure human inputs sculpt the final content. Editing and authenticity checks are critical steps I never skip.

    The key takeaway is that AI amplifies whatever brand essence you feed it—it can’t create it from scratch. Maintaining clarity and a distinct brand voice is what sets successful SEO apart.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Keep Modern Content Visible in Google Search

    Your page looks complete in a browser, answers the query well, and still struggles to appear or earn visits from Google. The problem may not be the writing. Modern visibility can break at several points: Google may receive the wrong rendered output, the important answer may be hard to extract, the result may lack the details people use to choose, or an AI response may satisfy the basic need without giving them a reason to click.

    You can diagnose those problems without treating SEO as one mysterious score. Separate visibility into rendering, interpretation, selection, and visitation. Then fix the layer that is actually failing.

    Treat visibility as a chain, not a single SEO score

    A page being technically available does not mean it is easy to understand. A page being understood does not mean it will be selected for a result. Selection does not guarantee a visit. Those are different outcomes, and each calls for a different test.

    Visibility layerQuestion to answerLikely failure signalWhat to inspect
    RenderingDoes Google receive the essential content?Important text, links, or page context are absent from the rendered output.The inspected URL, rendered text, primary links, and content loaded by JavaScript.
    InterpretationIs the page’s purpose and answer unambiguous?The page contains the information, but it is scattered, weakly labeled, or detached from its qualifiers.The title, main heading, opening answer, section labels, terminology, and structured-data parity.
    SelectionDoes the page expose the details needed to choose it?The content is relevant but lacks a concise overview, decision attributes, limitations, or a clear fit for the query.The direct answer, scope, prerequisites, distinguishing details, and useful summary information.
    VisitationIs there a clear reason and route to continue?The result can summarize the basic answer, but the destination promises no obvious additional value.Visible links, result-to-page continuity, deeper analysis, complete instructions, examples, and next-step utility.

    This model prevents two expensive misdiagnoses. The first is rewriting good content when the rendered page is incomplete. The second is rebuilding the front end when Google already sees the page and the real weakness is that the content does not help a searcher make a decision.

    Start every audit by writing down the failing outcome in plain language. Is the page absent? Is the wrong passage appearing? Is an important qualifier being lost? Is the page visible but not compelling enough to visit? A precise symptom gives you a testable next step.

    Prove what Google receives from your JavaScript pages

    JavaScript is not automatically an SEO barrier. Google has successfully rendered JavaScript-loaded content for years, which makes blanket warnings about client-rendered pages obsolete. It does not make every JavaScript implementation reliable.

    The distinction is simple: platform capability is not implementation verification. Google may be able to execute JavaScript while your page still returns an error, delays essential content, requires an interaction, depends on a personalized state, or renders something different from what you expected. You have to inspect your output, not infer it from Google’s general capability.

    1. Select representative URLs from every important template, especially templates that load the main answer, product details, navigation, or internal links dynamically.
    2. Open each URL as a normal visitor and record the elements that make the page useful: its main heading, central answer, important qualifiers, primary links, and any details needed to make a decision.
    3. Use URL Inspection in Google Search Console to verify what Google sees. Compare the inspected output with the visitor-facing page element by element.
    4. Classify every difference. Missing main copy is a rendering problem. Present but poorly labeled information is an interpretation problem. Missing links are a discovery and visitation problem. Do not group all of them under technical SEO.
    5. Repeat the check after changes to rendering, hydration, content APIs, consent handling, navigation, or reusable page components. A successful inspection of one template does not validate unrelated templates.

    Your comparison should focus on meaning, not visual perfection. Google does not need to see the page exactly as a person sees every animation or interface state. It does need the content and relationships that carry the answer. Confirm that headings still label the correct sections, qualifiers remain next to the claims they limit, and links retain descriptive destinations.

    Do not use a blank no-JavaScript view as automatic proof that Google sees a blank page. The old recommendation to disable JavaScript as a proxy for search visibility was removed after becoming outdated. A no-JavaScript test can still expose resilience problems, but it is not an accurate substitute for inspecting Google’s rendered result.

    Keep the essential answer portable

    Google’s rendering strength should not become an excuse to make every crawler reproduce your entire application before it can understand a page. Some emerging AI search systems may not process JavaScript as effectively. Where your architecture allows it, place the page’s purpose, central answer, meaningful headings, and essential links in the initial HTML. Let JavaScript enhance the experience rather than supply every piece of meaning.

    This is a portability decision as much as an SEO decision. A stable semantic layer can serve conventional search crawlers, AI retrieval systems, browser tools, and visitors on constrained devices. It also gives your team a simpler baseline to test.

    Do not maintain a separate hidden answer for machines. That creates a drift problem: the visible page says one thing while the machine-facing version says another. Render the same core facts for everyone, then add interactive controls, personalization, and presentation around them.

    Keep accessibility and search rendering as separate checks

    Google’s removal of old accessibility language from its JavaScript SEO material does not make accessibility optional. It means the earlier warning was no longer a useful description of Google’s rendering capability, and modern assistive technologies can generally process JavaScript. Your implementation can still create inaccessible controls, confusing focus behavior, or content that is difficult to navigate.

    Keep two acceptance criteria in your release process: Google must receive the essential rendered meaning, and people using assistive technology must be able to operate and understand the interface. Passing one check does not prove the other.

    Shape the page into a decision-ready answer

    Rendering gets your content into consideration. It does not make the content a good candidate for an AI-generated result. The page must expose an answer that can be understood without reconstructing it from scattered paragraphs, while preserving the context that keeps the answer accurate.

    Google’s AI Mode recipe experience illustrates the distinction. Searchers can open individual dishes, follow links to recipe creators, read a quick overview, and see details such as cook time. Those details help people decide which option to explore.

    That does not make cook time a universal ranking factor, and it does not mean every content type should imitate a recipe card. The transferable principle is that selection requires decision information. Your page should state not only what the answer is, but also when it applies, what it requires, where its limits are, and what makes the destination useful.

    Build a self-contained answer block

    Near the beginning of the page, give the reader a compact resolution to the primary question. Include the condition that would materially change the answer. Then expose the attributes a person would use to choose whether the page fits their situation.

    • Direct resolution: State the answer before the long explanation. Do not make the reader cross an introductory essay to discover your position.
    • Scope: Name the platform, content type, implementation pattern, or audience for which the answer applies.
    • Decision attributes: Surface prerequisites, compatibility, effort, constraints, or other details that determine fit.
    • Qualifiers: Keep exceptions beside the claim they modify. A distant caveat is easy for both readers and automated systems to miss.
    • Continuation: Indicate what the full page adds, such as the complete workflow, diagnostic branches, worked examples, or implementation details.

    For a page about JavaScript SEO, for example, the useful opening is not merely that Google supports JavaScript. The decision-ready answer is that Google can render it, each implementation still needs inspection, and essential meaning should remain portable when other retrieval systems may not execute the page as well. The additional conditions turn a technically true statement into actionable guidance.

    Apply the same discipline to headings. A heading such as Benefits carries little meaning outside its surrounding page. A heading such as When client rendering creates a visibility risk identifies the question the section resolves. Descriptive headings help the visitor scan and give extracted passages useful context.

    Use JSON-LD as a faithful machine-readable echo

    If you publish JSON-LD, make it agree with the visible page. Names, descriptions, relationships, attributes, and other claims should not conflict with what a person can read. Structured data should clarify an already coherent page, not compensate for missing content or introduce a more attractive machine-only version.

    Include schema parity in editorial QA. When a visible fact changes, identify every place that repeats it: body copy, summary modules, metadata, JSON-LD, and reusable components. A technically valid graph can still be unhelpful if it describes an earlier version of the page.

    Preserve a reason to visit after the basic answer is visible

    AI visibility and referral traffic are related, but they are not the same outcome. An AI result may use your information while resolving the immediate question inside the search experience. Even when Google adds a visible link, the link is only an opportunity. The searcher still needs a reason to follow it.

    The wrong response is to hide the central answer. If the page withholds the useful part, it becomes a weak candidate for selection and a frustrating destination. Instead, divide value by depth.

    • In the extractable layer, provide the direct answer, its scope, critical qualifiers, and the details needed to judge relevance.
    • On the destination page, continue with the complete method, edge cases, evidence you can substantiate, examples, troubleshooting paths, and tools that help the visitor act.
    • At the transition, make the next value explicit. A generic Learn more link hides the payoff; a descriptive destination tells the reader what the click will complete.

    This is especially important when a search result offers a quick overview. The overview can establish relevance, but the destination should resolve the work that remains. A recipe result can help someone choose a dish, while the creator’s page can still provide the full method and context needed to make it. Your content should have an equally clear division between selection value and completion value.

    Check continuity from result to page. The linked destination should open on the content promised by the result, use consistent terminology, and reveal the next useful step quickly. Sending someone from a specific AI citation to a generic category page wastes the moment of intent.

    Internal links deserve the same treatment. If a section introduces a decision that another page resolves, link with words that name that decision. This creates a route through the subject for readers and makes the relationship between pages explicit.

    Diagnose the failing layer before you rewrite

    A modern visibility audit should end with a classified defect, not a list of generic SEO recommendations. Use the observed symptom to choose the work.

    • Essential content is missing from Google’s inspected output: Fix rendering, delivery, or state dependencies before changing the prose. Confirm that the affected template works after the change.
    • The content renders, but the purpose is difficult to state: Tighten the title, main heading, opening answer, and section labels. Remove competing introductions that delay the primary resolution.
    • The answer is accurate but loses its conditions when extracted: Move the qualifier beside the claim, use a self-contained sentence, and keep the same qualification in summaries and structured data.
    • The page answers the topic but does not help a person choose: Add the relevant prerequisites, constraints, compatibility information, or other decision attributes supported by the page.
    • The basic answer is visible but visits remain weak: Clarify what the destination adds. Strengthen the result-to-page promise rather than repeating the same summary at greater length.
    • Google handles the page but other AI systems struggle: reduce dependence on client execution for the essential semantic layer while keeping richer interactions available to visitors.

    Audit at the template level as well as the URL level. If every page using a component loses its main link during rendering, editing individual pages will only conceal the shared defect. If only one page has an unclear answer, a site-wide rebuild is unnecessary.

    Keep a short record for each tested URL: the intended query, the essential visible answer, whether that answer appears in Google’s inspected output, the decision details present, the continuation value, and the defect class. That record gives developers, editors, and schema owners the same definition of done.

    Key takeaways

    • JavaScript is not inherently invisible to Google, but your own rendered output still needs verification in Search Console.
    • A page can pass rendering and still fail because its answer, scope, or qualifiers are hard to extract.
    • AI-oriented content needs decision details, not just a concise summary.
    • JSON-LD should mirror visible, current content rather than act as a substitute for it.
    • A link in an AI result does not guarantee a visit; the destination must promise useful continuation beyond the overview.
    • Classify the failure as rendering, interpretation, selection, or visitation before assigning the fix.

    Begin with one commercially important template. Inspect what Google receives, rewrite its opening as a self-contained answer, verify visible and structured-data parity, and make the next-step value unmistakable. Once that pattern passes all four layers, apply it to the rest of the site.

    References

  • Google Crawl Frequency: What It Says About Site Health

    Google Crawl Frequency: What It Says About Site Health

    When Google starts crawling your site more often, it is tempting to treat the increase as an SEO win. When activity falls, it is just as tempting to assume that something is broken. Neither conclusion is safe on its own.

    Crawl frequency is most useful as a diagnostic clue. It can show you where Google sees freshness, relevance, or demand, but it cannot tell you by itself whether a page is indexed, ranks well, or deserves more search visibility. Your job is not to maximize crawling. It is to make sure Google can efficiently revisit the pages that need to stay current.

    Frequent crawling is a positive signal, not an SEO score

    Google tends to crawl pages frequently when its systems recognize fresh or highly relevant information that people want to find. Repeat visits let the search engine detect changes and keep its understanding of those pages current.

    Ecommerce makes the mechanism easy to see. Prices, promotions, and inventory can change quickly, so current search results depend on Google revisiting product and category pages. A crawl increase across an active commercial catalog can therefore be entirely healthy.

    The mistake is turning that positive signal into a universal performance metric. Four separate events matter:

    • Discovery: Google becomes aware that a URL exists.
    • Crawling: a crawler requests the URL and attempts to retrieve its content and required resources.
    • Indexing: Google processes the retrieved content and decides whether and how it may be stored in the search index.
    • Search selection: Google decides whether the indexed page is useful for a particular query and where it should appear.

    More crawling confirms activity at the second stage. It does not prove that indexing or ranking improved. A frequently fetched page can still be unhelpful, duplicative, outdated, or ineligible for indexing. Conversely, a stable page may remain valuable without needing constant repeat visits.

    Be especially careful with the reverse inference. If frequent crawling is a good sign, it does not follow that less frequent crawling is automatically a bad sign. Google optimizes crawling automatically, so there is no single healthy request rate that every site or page should reach. The useful question is whether the frequency fits the purpose and rate of change of the pages involved.

    Judge crawl patterns by page type and update need

    A sitewide crawl total hides the distinctions that matter. Separate your pages into functional groups before deciding that a change requires action.

    Page groupHow to interpret crawl activityWhat to check
    Prices, products, promotions, and inventoryFrequent repeat crawling can match the need for current commercial information.Confirm that the fetched page exposes the current public data and that access controls do not block required content.
    Recently revised editorial or reference pagesA repeat crawl is the step that lets Google encounter the revision, but it does not guarantee reindexing or better rankings.Sample important changed URLs and verify that Google can retrieve the new version.
    Stable company, policy, or evergreen pagesLower activity may simply reflect a lower need for freshness.Keep the information accurate, but do not make cosmetic edits merely to provoke crawler visits.
    Member-only, subscription, or paywalled pagesLimited access may be intentional rather than a technical failure.Confirm that the public and restricted portions match your publishing policy and the access you have chosen to permit.

    Segment the evidence again by directory, template, hostname, and crawler identity. Google uses multiple crawlers with different jobs. Combining every request into one total can make a change in one part of the site look like a sitewide health event.

    Compare your site with itself, not with an unrelated domain. A retailer with changing stock naturally creates a different freshness need from a small site whose core information rarely changes. Even within one domain, product availability and an evergreen company history page should not share the same crawl expectation.

    Diagnose a crawl decline in the right order

    An isometric website system shows a crawler route passing from a server through linked pages toward blocked, broken, looping, and duplicate paths.

    A meaningful decline is one that affects pages Google needs to revisit, especially after those pages have changed. Diagnose it from the narrowest evidence outward:

    1. Verify the comparison. Make sure you are looking at the same hostname, page group, crawler, and measurement window. A reporting change or a shift between crawlers can resemble a loss of activity.
    2. Find the boundary. Determine whether the decline affects the whole site, one directory, one template, or only a small group of URLs. A clean boundary often points toward the release, configuration, or publishing workflow that changed.
    3. Match the timing to site changes. Review deployments, migrations, authentication changes, robots.txt edits, page-level crawler instructions, paywall changes, and rendering changes. Modern pages are more complex to retrieve, so a template change can alter what a crawler can access even when the visible design looks correct.
    4. Inspect representative fetches. Check important URLs from each affected group. Confirm that the request succeeds, the intended content is present, and essential resources are available. Do not rely only on a sitewide graph.
    5. Review crawler instructions deliberately. Google normally respects robots.txt and other crawling instructions. An accidental restriction can therefore produce exactly the decline you asked the crawler to create, even if that was not the business intention.
    6. Trace how changed pages are rediscovered. Important URLs should remain reachable through ordinary internal navigation. If you maintain discovery files such as an XML sitemap, make sure they represent the public URLs you actually want Google to revisit.
    7. Separate access from demand. If Google can fetch the pages, the content has not materially changed, and the audience need is stable, lower activity may be rational. Record it as a baseline instead of manufacturing updates to chase a larger number.

    Do not respond to a decline by exposing private material or removing restrictions indiscriminately. Google does not access paywalled or subscription content without the site owner’s permission. Decide what should be public first, then configure access to express that decision. Crawl volume is not worth compromising a membership model or publishing rights.

    Build a site-health view that leads to action

    An analyst traces an amber warning from an abstract site-health monitoring wall to a highlighted page node.

    Crawl frequency becomes useful when you place it inside a small operational scorecard. Review these dimensions together whenever a technical release, content migration, or major publishing change affects important pages:

    • Access: Can Google retrieve priority URLs and the content required to understand them?
    • Purpose: Is repeat activity concentrated on useful, public pages rather than unwanted URL variations or redundant versions?
    • Freshness: When an important fact changes, can a later fetch retrieve the new value?
    • Control: Do robots.txt, page-level instructions, authentication, and paywall rules match the publishing decision behind each section?
    • Outcome: Are discovery, crawling, indexing, and search performance being measured separately instead of being collapsed into one health label?

    This framework also prevents a common mistake in structured-data and AI-search work. JSON-LD can clarify the meaning of information that a crawler retrieves, but markup cannot compensate for blocked or unavailable content. Verify access and content delivery before treating schema changes as the answer to a crawl problem.

    You also retain meaningful control over what Google is allowed to crawl and how it receives instructions. Treat each exclusion as a publishing rule with an owner and a reason. Broad rules left behind after a migration are much harder to diagnose than restrictions whose intent is documented.

    The healthiest goal is purposeful crawling: current, relevant pages are available when Google needs them; stable pages remain accurate without artificial churn; and restricted content stays restricted by design.

    Key takeaways

    • Frequent crawling generally indicates that Google recognizes freshness, relevance, or user demand, but it is not a ranking score.
    • A crawl is not the same as discovery, indexing, or ranking. Measure those stages separately.
    • There is no universal healthy crawl frequency. Compare activity with the page’s purpose and actual rate of change.
    • Investigate declines by page group, template, hostname, and crawler before treating them as a sitewide problem.
    • Check access controls and the fetched content before trying to stimulate more requests.
    • Do not manufacture superficial updates, expose private content, or remove deliberate restrictions merely to increase crawl volume.

    For your next crawl review, compare fast-changing pages, recently revised pages, stable pages, and intentionally restricted pages separately. Fix any gap between publishing intent and crawler access. If the remaining pattern matches how often the information changes, keep it as your baseline and monitor the outcomes that come after crawling.

    References