Tag: Content Optimization

  • SEO Priorities After Google’s March 2026 Core Update

    SEO Priorities After Google’s March 2026 Core Update

    If your rankings fell after Google’s March 2026 core update, the worst first move is a sitewide rewrite. This update produced unusually broad result churn, arrived immediately after a spam update, and changed which kinds of sources appeared most prominently. A blanket response can destroy the evidence you need to diagnose the loss.

    Your job is to separate market-wide movement from page-specific weakness, identify what the replacement results provide that you do not, and improve the shortest path between your brand, its evidence, and the searcher’s next step. That puts diagnosis, primary-source value, the homepage, and information architecture ahead of cosmetic content refreshes.

    Diagnose the loss before changing the site
    A digital investigator compares abstract page evidence while broad search movement is visually separated from one isolated page issue.

    The March update was volatile enough to make a ranking decline look more conclusive than it is. Across the observed results, 79.5% of top-three URLs changed position, 90.7% of top-10 URLs moved, and 24.1% of pages that had ranked in the top 10 disappeared from the top 100. Those figures show how much the result set changed; they do not prove that the same percentage of your pages became unhelpful.

    Attribution is also unusually difficult because the core update began one day after a significant spam update ended. Most of the observed disruption appeared to come from the core update, but the overlap makes a single-cause diagnosis unreliable. Do not use “penalty” as shorthand for every decline.

    Build the diagnosis at the query-page level, not from a sitewide visibility score:

    1. Compare equivalent periods. In Google Search Console, compare the same queries and landing pages before and after the disruption. Match weekdays where possible, and exclude periods distorted by migrations, tracking failures, promotions, or unusual demand.
    2. Separate ranking loss from click loss. If clicks fell while positions stayed broadly stable, rewriting the page may not address the cause. Inspect impressions, result composition, query demand, titles, and snippets. If impressions and positions fell together, a relevance or source-preference change is more plausible.
    3. Check indexation before judging content. A page that is excluded, canonicalized elsewhere, blocked, or no longer rendered correctly has a technical problem. A page that remains indexed but loses to a different source type has a competitive or content problem.
    4. Classify the replacements. Mark each new winner as an official or institutional site, a specialist source, an established brand, a dominant platform, an aggregator, a directory, or a comparison page. The pattern matters more than any one competitor.
    5. Group losses by template and purpose. Look for concentration in comparison pages, location directories, programmatic pages, definitions, product summaries, or informational articles. A shared template usually points to a shared weakness.
    6. Write a testable explanation. “Google dislikes us” cannot guide an edit. “Our location pages repeat third-party facts while the new winners own the locations and publish current operating details” can.

    Preserve the export, affected URLs, replacement results, and your annotations before making changes. Otherwise, you will not know whether a later movement came from your work, continued volatility, or a different query mix.

    Move each important page closer to the primary source

    The clearest pattern from the update was a movement toward official and institutional sites, specialist sources, established brands, and major platforms, while many aggregators, directories, and comparison sites lost visibility. This was not a blanket platform bonus: YouTube had the largest visibility decline in the dataset. Brand size alone did not guarantee a gain.

    A useful working hypothesis is that the update raised the cost of being an unnecessary intermediary. The more steps between a page and the entity that owns the fact, product, job, place, clinical expertise, or dataset, the more clearly that page must justify its existence.

    Ask four questions of every page that matters:

    • Which facts on this page does your organization own, produce, verify, or maintain?
    • What can the reader learn here that is not available from the original provider or from every competing summary?
    • Can the reader see where each consequential claim came from and when time-sensitive information was checked?
    • Does the page help the reader complete a decision, or does it merely restate information found elsewhere?

    The right upgrade depends on the page’s role. A software page can publish version-specific instructions, working configuration examples, limitations, and maintained documentation. A data page can expose definitions, methodology, dates, and the relationship between the figures and their originating institution. A comparison can explain inclusion criteria, show the evidence behind each distinction, disclose commercial relationships, and separate observed facts from editorial judgment. A directory can verify records, link to the responsible entity, remove duplicates, and make its coverage and maintenance process visible.

    Query type should influence the source you treat as authoritative. The update shifted job visibility toward employer-specific destinations, data-driven searches toward institutional sources, travel and real-estate results toward primary destinations, and health searches toward clinical and specialist material. If you operate in one of those areas, compare what the new winner directly owns with what your page merely describes. Then decide whether to add first-party value, cite the origin more clearly, narrow the page’s promise, or stop competing for an intent better served by the primary entity.

    Do not mass-delete every comparison, directory, or aggregator-style page. Those formats can still solve legitimate search tasks, and deletion can remove demand, links, and useful pathways. Preserve pages with demonstrated value, upgrade pages that can become meaningfully distinctive, consolidate genuine duplicates, and remove or noindex a page only after reviewing its traffic, links, conversions, replacement URL, and role in the site architecture.

    JSON-LD belongs after this content decision, not before it. Structured data can confirm visible facts and relationships; it cannot manufacture first-party authority. Keep names, canonical URLs, authorship, dates, products, organizations, and entity identifiers consistent with the page a person sees. Do not mark up credentials, reviews, services, or relationships that the visible page does not substantiate.

    Turn the homepage into a verification and routing page
    A central glass pavilion displays evidence objects and routes visitors along short paths to several destinations.

    AI assistants can handle part of a user’s exploratory research before that person visits a website. Once persuaded that a brand belongs on the shortlist, the user may perform a branded search and arrive directly on its homepage, carrying intent that conventional analytics cannot fully explain. That makes the homepage more important as the bridge between AI-assisted discovery and the next action.

    This does not mean turning the homepage into an index of every keyword. It means making the entity and its routes unmistakable. A useful homepage should let a new visitor answer these questions without interpreting internal company language:

    • What is this organization, and what does it provide?
    • Who is each main offering for?
    • Which route matches the visitor’s task: learn, compare, verify, buy, contact, or get support?
    • Where can the visitor inspect proof, documentation, methodology, expertise, policies, or case material?
    • What is the next meaningful action for each major audience?

    Use plain labels based on user tasks. “Solutions,” “Resources,” and “Insights” can be too broad when they hide several unrelated destinations. A prospective buyer should not have to guess whether implementation details live under Services, Platform, Learn, or Company.

    Information architecture carries that clarity beyond the homepage. Group related material under a parent hub, connect supporting pages to that hub, and use breadcrumbs and contextual internal links to show the relationship. Treat the ability to reach important information within three clicks as a practical audit metric, not as permission to place hundreds of links in the footer.

    Run the audit from a logged-out view of the site. For every commercially or editorially important page, record its parent hub, click depth from the homepage, navigation route, breadcrumb route, relevant contextual links, and orphan status. If a priority page is difficult to reach, add a semantically appropriate path from its hub or a closely related page. A link from an unrelated global block may reduce click depth without clarifying the page’s place in the site.

    Keep the entity consistent across the homepage, About page, service or product hubs, author or expert pages, contact details, and JSON-LD. Organization, WebSite, Person, and BreadcrumbList markup should describe the same names, URLs, roles, and hierarchy that the navigation and visible copy establish. When those layers disagree, adding more schema creates more ambiguity rather than more authority.

    Sequence recovery work by evidence and consequence

    The easiest tasks are rarely the most important ones. Changing dates, adding paragraphs, or installing another optimization tool can feel productive while leaving the actual weakness untouched. Use the observed pattern to choose the next action.

    Observed signalLikely workstreamFirst action
    Pages are excluded, canonicalized incorrectly, blocked, or not rendered as intendedTechnical SEOFix the affected template or directive and verify that the intended canonical page can be crawled, rendered, and indexed.
    Losses cluster in secondary summaries while official or specialist pages replace themContent and authorityIdentify the facts you can own or verify, add evidence and methodology, and consolidate pages that cannot justify a separate result.
    Positions remain broadly stable while clicks declineSearch-result and demand analysisInspect impressions, result features, titles, snippets, and query intent before rewriting the body content.
    Branded discovery reaches the homepage, but visitors do not find the relevant routeHomepage and conversion architectureClarify the entity, audience choices, proof paths, and next actions above the deeper content layer.
    One page falls while the rest of its topic cluster remains stablePage-level relevanceCompare that page with the current winners, then repair the specific intent, evidence, or duplication gap instead of changing the whole site.

    Measure each workstream with a matching indicator. Technical work should improve index eligibility and canonical consistency. Content work should restore impressions for the intended query-page pairs and reduce dependence on unverified secondary claims. Architecture work should reduce orphaning and meaningful click depth. Homepage work should improve selection of the correct audience route and the completion of its next action.

    A sitewide average can hide progress. Review affected clusters separately, retain annotations for every substantial change, and compare pages with the same role. A documentation hub, product page, directory entry, and editorial comparison should not be judged by one blended benchmark.

    Key takeaways

    • Do not interpret every March 2026 decline as a penalty. The result set experienced exceptional churn, and the core update followed immediately after a spam update.
    • Diagnose query-page pairs before changing templates or deleting content. Separate ranking loss, click loss, indexation problems, and changes in source preference.
    • Prioritize pages that own, produce, verify, or explain consequential information. An intermediary page needs a clear reason to exist.
    • Use the homepage to identify the entity, route major audiences, expose proof, and convert branded or AI-assisted discovery into a useful next step.
    • Organize important content into coherent hubs and keep it reachable through meaningful paths, ideally within three clicks.
    • Treat JSON-LD as a confirmation layer for visible, consistent facts. It cannot compensate for thin evidence or confused information architecture.

    Start with the page that lost the most qualified visibility and still matters to the business. Put the current winner beside it and write down what that source owns, proves, or routes better than you do. That comparison should tell you whether the next task is a technical repair, an evidence upgrade, a consolidation decision, or a clearer path through the site. Apply the same method cluster by cluster instead of launching an undirected sitewide refresh.

    References


  • How to Improve Visibility in Personalized Google Maps Results

    How to Improve Visibility in Personalized Google Maps Results

    If your business appears for a broad search such as electrician nearby but disappears when the customer describes an older home, a panel upgrade, and a need for responsive service, a conventional ranking report is showing only part of the problem. Ask Maps may evaluate which businesses fit the stated situation, not merely which listings match the category.

    Your practical goal is to make that fit understandable and supportable. Your Google Business Profile should establish what the business is, your website should explain the work in enough depth to resolve a specific need, and your reviews should provide credible customer evidence. The following process turns those surfaces into a local discovery system you can audit and improve.

    Personalized recommendations change what visibility means

    Traditional local tracking usually reduces visibility to a position: where did the business rank for a keyword in a location? That remains useful, but it misses an important layer of conversational discovery. A person can now supply the job, property type, constraint, urgency, trust concern, or decision criterion inside the request.

    As those details accumulate, Ask Maps has been observed moving from a relatively simple set of nearby businesses toward a more selective answer that interprets fit and explains its choices. Basic prompts tend to produce broader retrieval. More involved prompts can trigger guidance about which options appear suitable and why.

    That distinction changes the question you should ask. It is no longer only, Can Google associate this business with electricians in this city? It is also, Can Google find enough consistent evidence to associate this business with panel upgrades in older homes, responsive communication, and the other details a customer included?

    Use personalized carefully here. The actionable behavior is personalization to expressed intent: the result changes as the person gives the system a more specific problem to solve. You do not need to speculate about private account history or undocumented signals to work on that problem.

    The observed pattern is directional rather than universal. It came from locality-specific testing and was not exhaustive across every market or query. Treat it as a reason to expand your audit, not as proof that every Ask Maps result follows an identical formula.

    Build a consistent evidence map across profile, site, and reviews

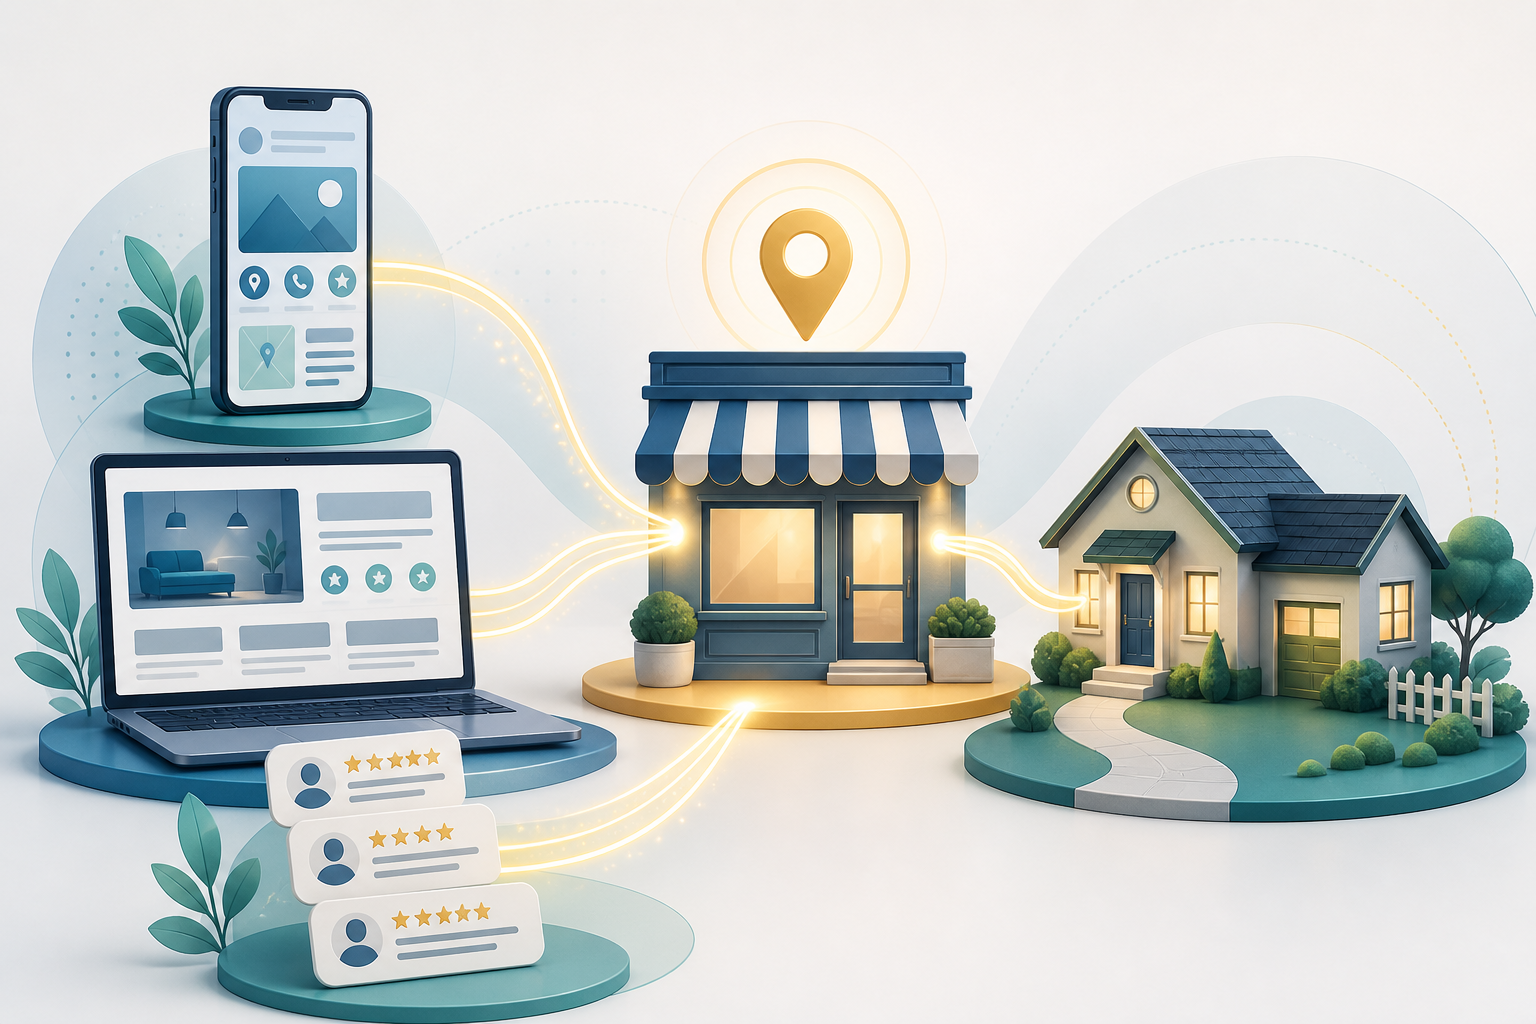
    An abstract business profile, service website, and customer review cards connected by glowing lines to a local storefront and a customer's home.

    Ask Maps can draw from Google Business Profiles, reviews, business websites, and external material. These surfaces play different roles. A useful working model is identity, explanation, and corroboration:

    • Google Business Profile establishes identity. It tells the system what the business is, where it operates, and which services it presents.
    • The website explains capability. It gives a specific service or situation enough context to be understood beyond a short listing.
    • Reviews corroborate experience. They show how customers describe the work, service, communication, and outcomes in their own words.
    • External mentions can reinforce or complicate the picture. Information elsewhere may help confirm the business, but stale or inconsistent claims can create ambiguity.

    Create an evidence map before you edit anything. For every commercially important service, write down the customer need, the relevant profile fact, the page that explains it, and the review themes that could honestly support it. A blank cell is a content or data gap. A contradictory cell is an accuracy problem.

    Make the Business Profile precise, not expansive

    Your profile should describe the business customers can actually hire. Confirm that its category, services, description, hours, contact details, and service-area information are accurate. Do not add adjacent services merely to look comprehensive. A larger but unreliable service list makes it harder to build a consistent explanation across the rest of your presence.

    Use operational language where the profile permits it. Electrical contractor offering residential panel upgrades communicates more than a string of broad adjectives. If responsiveness matters to customers, publish accurate contact and availability information. Let real customer accounts support the quality claim rather than describing the business as responsive without evidence.

    Check consistency at the fact level. A service should not appear on the profile while the website gives no indication that you provide it. Hours, names, locations, phone details, and stated coverage should not conflict across your owned pages. Consistency does not guarantee selection, but inconsistency makes the business harder to interpret confidently.

    Publish pages that resolve a situation, not just a keyword

    A generic Electrician in City page can establish category and location. It may not answer whether the company handles a panel upgrade in an older home. That difference matters when the query contains the job and its context.

    For each meaningful service-intent combination, give the reader a page that answers the decision they are making. Include:

    • The exact work offered: name the service plainly and distinguish it from neighboring services a customer may confuse with it.
    • The situations you handle: describe relevant property, equipment, business, or project contexts only where they genuinely affect fit.
    • The boundaries of the service: state exclusions, prerequisites, or geographic limitations that would otherwise produce a poor match.
    • How the next step works: explain what information you need, how scope is assessed, and what the customer should do next.
    • Decision-useful answers: address the questions customers ask when choosing a provider, not merely the phrases an SEO tool reports.
    • Visible evidence: use accurate examples, credentials, service details, and customer feedback when you have them. Do not manufacture specificity.

    The page does not need to repeat every possible conversational prompt. It needs clear facts that can answer several versions of the same underlying need. Write for the decision, then use headings and direct language to make each answer easy to extract.

    JSON-LD can encode those visible facts after the page is complete. Use the appropriate business and service vocabulary, keep marked-up information consistent with what a visitor can read, and avoid adding claims solely in structured data. Schema is a machine-readable clarity layer, not a substitute for missing service information or customer evidence. There is no basis for assuming markup alone will force Ask Maps to recommend a business.

    Treat reviews as evidence, not a bag of keywords

    Reviews appear especially influential in the initial impression of a business, while more complex requests can lead Ask Maps deeper into websites and other informative material. That makes review quality relevant, but it does not justify scripting customer language.

    Ask customers for honest feedback about the work they received. Open questions can invite useful context: What problem were you trying to solve? What work was completed? What part of the process was helpful? The customer should decide what to mention and how to say it.

    Then analyze the patterns already present. Group review language by service, situation, communication, specialization, and trust. Compare those themes with your profile and service pages. If customers repeatedly describe a capability that the website barely mentions, you may have a documentation gap. If the site promotes a specialty that customers never discuss, investigate whether the claim is unclear, unimportant to buyers, too new to have accumulated evidence, or unsupported.

    Do not turn that analysis into review manipulation. Repeating a target phrase is not the same as demonstrating fit. The useful signal is a coherent relationship between the stated service, the detailed explanation, and genuine accounts of customer experience.

    Audit discovery with a five-level intent ladder

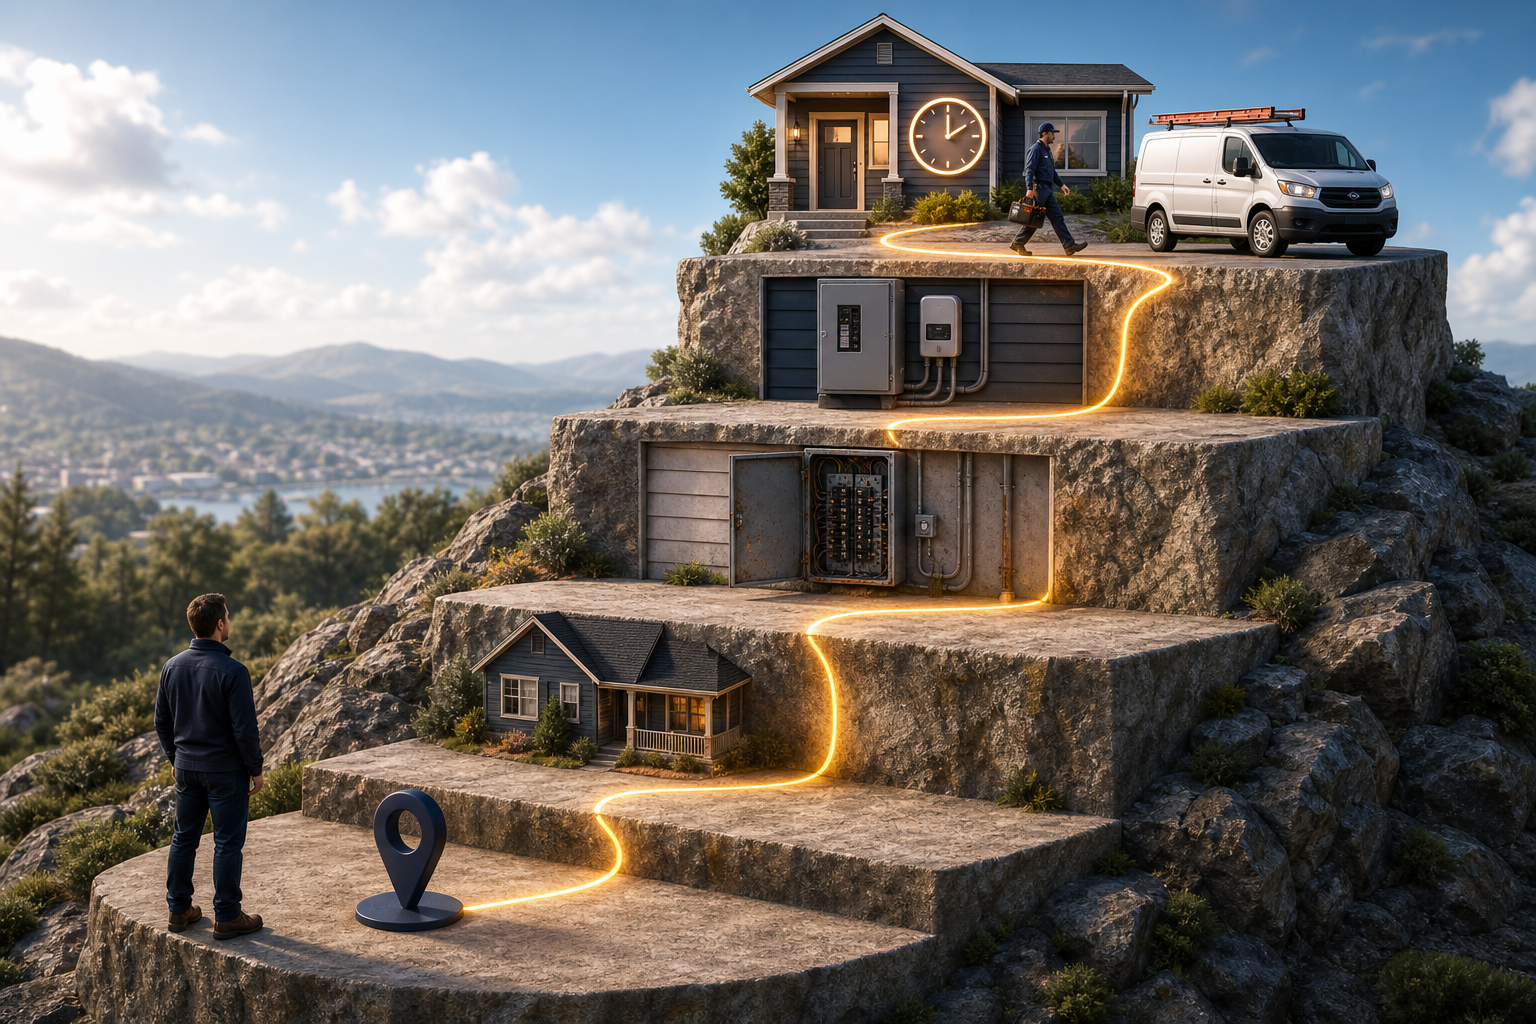
    A person follows a glowing path up five platforms marked by progressively more specific home-service symbols toward a contractor van.

    A single near me query cannot tell you whether the system understands your specialties. Use a five-level progression from a basic local need to a conversational decision request. Keep the underlying service and locality consistent so you can see what changes as intent becomes richer.

    1. Basic local need: HVAC company nearby. This checks whether the business enters a broad category-and-location result.
    2. Defined service: Electrician for a panel upgrade in an older home. This introduces a named job and a meaningful context.
    3. Situational fit: I need a panel upgrade in an older home and want a company that regularly handles this kind of work. This asks the system to interpret suitability rather than category alone.
    4. Trust requirement: Which local electrician appears dependable for this job, and what evidence supports that? This tests whether the answer can attach a reason to the selection.
    5. Decision request: Help me choose a local electrician for an older-home panel upgrade, prioritizing relevant experience and responsive communication. This combines service, context, trust, and a decision criterion.

    These prompts are templates, not universal keywords. Replace the service and context with the real decisions your customers face. A plumber might test a specific repair and property situation. An HVAC company might test a system type, service need, and availability concern. A professional practice might test the matter handled, client context, and trust requirement.

    Do not include your brand name unless you are deliberately testing branded comprehension. The purpose of an unbranded audit is to discover whether the business can be selected from evidence, not whether Google recognizes a name you supplied in the prompt.

    Record more than presence or absence for every prompt:

    • Inclusion: Did the business appear anywhere in the answer?
    • Selection: Was it merely listed, or framed as a suitable option?
    • Explanation: What reason, if any, was attached to it?
    • Evidence: Did the explanation appear to rely on the profile, reviews, the website, or another visible source?
    • Accuracy: Was the description correct, incomplete, stale, or unsupported?
    • Missing fit: Which part of the prompt could not be connected to clear evidence about the business?

    Document the locality, prompt wording, account context, and date alongside the output. A result from a particular setup is an observation, not a universal rank. Keeping the setup visible makes later checks interpretable and prevents a changed prompt from being mistaken for improved visibility.

    Turn recommendation gaps into a prioritized backlog

    The audit becomes useful when each failure leads to a different response. Do not answer every disappointing result by adding more keywords to the same page.

    • Broad discovery gap: The business is absent even for the basic local need. Check fundamental profile accuracy, business identity, locality, and whether the service is actually represented before expanding content.
    • Service comprehension gap: The business appears for the broad request but drops out when a specific job is added. Build or improve the page that explains that job, and align the profile service information with it.
    • Situational gap: The service is understood, but a property type, use case, or constraint breaks the match. Add the context only if the business genuinely serves it, and explain how it affects the engagement.
    • Evidence gap: The business appears but receives no meaningful rationale, or the rationale is thin. Look for credible detail across reviews, service pages, and external mentions rather than adding unsupported superlatives.
    • Accuracy gap: The answer describes the business incorrectly. Correct conflicting facts on surfaces you control and investigate visible third-party information that may be stale. Do not publish a new claim merely to overpower an old one.
    • Conversion gap: The recommendation is accurate, but the destination page leaves the customer unsure what to do. Make the service boundary, contact route, and next step explicit.

    Prioritize accuracy first because an incorrect recommendation can create poor leads and erode trust. Then work from broader comprehension toward narrower situational evidence. There is little value in polishing a specialized page if the profile and site still disagree about the basic service.

    Measure progress with a small set of diagnostic fields rather than one supposed Ask Maps ranking:

    • Intent coverage: which important customer situations have clear supporting facts across the profile and site?
    • Selection depth: at what point in the intent ladder does the business stop appearing or stop being treated as a fit?
    • Explanation accuracy: do the reasons attached to the business match what it actually provides?
    • Evidence alignment: do profile facts, website explanations, reviews, and visible external information tell a compatible story?
    • Change history: which factual or content update preceded a meaningful change in observed answers?

    Avoid claiming causation from a single before-and-after check. Locality-based results are not exhaustive, and several information sources may contribute to an answer. Build a change log, repeat the same useful prompts over time, and look for consistent movement in selection and explanation.

    Key takeaways

    • Ask Maps can move beyond listing nearby businesses and interpret which options appear to fit a detailed local request.
    • Your Business Profile establishes identity, your website explains capability, and reviews provide customer evidence. Improve them as one connected system.
    • Build service pages around real jobs, contexts, boundaries, and decisions rather than producing interchangeable city-and-keyword pages.
    • Test broad, service-specific, situational, trust-focused, and decision-oriented prompts to find where the system loses confidence in the match.
    • Track inclusion, selection, explanation, evidence, and accuracy. A single position cannot describe personalized local discovery.
    • Use structured data to encode accurate visible information, not to manufacture relevance that the page and business cannot support.

    Choose a service that matters to your business and build its intent ladder now. The first useful output is not a better-looking rank report. It is the first point where the recommendation breaks, the evidence missing at that point, and a specific profile, page, or accuracy update you can make to close the gap.

    References


  • Gemini SEO: A Practical Guide to Content Visibility

    Gemini SEO: A Practical Guide to Content Visibility

    If Gemini answers a question your page already covers but never names your brand or links to your content, adding more keywords is unlikely to solve the underlying problem. First ask whether the page provides a clear, self-contained answer that Gemini can understand, attribute, and represent accurately.

    That shifts the work from chasing an AI-specific trick to improving answer quality. You still need sound SEO, but you also need content that resolves the user’s decision, identifies its claims precisely, and gives an answer engine a credible page to cite.

    Treat Gemini visibility as answer eligibility

    Conventional search visibility and Gemini visibility overlap, but they are not identical outcomes. A page may deserve a click because it promises useful information while still making the actual answer difficult to locate. It may bury the conclusion, leave important conditions unstated, or use vague language that only makes sense after reading the entire site.

    The practical objective is to make your content easier to use across AI Overviews and answer engines. That means treating each important page as a candidate answer, not merely as a container for keywords.

    A useful answer candidate has four qualities:

    • Relevance: It resolves the question the user actually asked rather than discussing the surrounding topic indefinitely.
    • Clarity: The main conclusion, subject, and conditions are explicit. The reader does not have to infer what “it,” “this,” or “the solution” refers to.
    • Support: Important factual claims have evidence, context, or a clear explanation behind them.
    • Identity: Products, organizations, authors, places, and concepts are named consistently enough to avoid confusion.

    Key takeaways

    • Optimize for the complete question and decision, not an isolated keyword.
    • Put a direct, qualified answer where both readers and machines can find it quickly.
    • Keep names, claims, visible content, and structured data consistent.
    • Measure brand mentions, citations, factual accuracy, and useful visits separately.
    • Diagnose the specific visibility gap before rewriting an entire page.

    This framework also prevents a common strategic mistake: treating every absence from a Gemini response as a technical SEO failure. Sometimes the page is accessible but does not answer the prompt. Sometimes it answers the prompt but lacks enough support. Sometimes Gemini recognizes the brand but has no definitive page worth linking. Each condition calls for a different edit.

    Build each page around a complete user decision

    An isometric decision path connects a question, several options, comparison pieces, evidence, risk checks, and a final selection.

    Start with the prompt behind the keyword. A keyword names a subject; a prompt usually reveals a situation, constraint, or decision. Someone asking how to optimize content for Gemini may be trying to diagnose missing citations, plan a new page, improve an existing ranking page, or decide what to measure. Those needs overlap, but they do not require the same answer.

    Before drafting or revising a page, write an answer specification:

    • Target question: Write the question in the language a real user would use.
    • Reader state: Note what the reader already knows and what has prompted the search.
    • Decision: Identify what the reader should be able to choose, change, or check after reading.
    • Short answer: State the smallest answer that would still be responsible and useful.
    • Conditions: Record where the answer changes by product, page type, audience, market, or other relevant constraint.
    • Support: List the evidence, examples, definitions, or reasoning needed to justify the answer.
    • Follow-up questions: Add only the questions that naturally arise before the reader can act.

    This specification exposes thin content early. If you cannot state the decision or the short answer, another introductory paragraph will not fix the page. You either need a narrower question or better information.

    Use the primary question as the page’s organizing spine. Put the direct answer near the relevant heading, then develop the reasoning, qualifications, process, and next step. Cover close follow-up questions when they help the same reader complete the same task. Split the material when a follow-up serves a different intent or leads to a different decision.

    For example, “Why is my page absent from Gemini?” is a diagnostic intent. “How should I structure a new page for Gemini?” is an implementation intent. Forcing both into a long, unfocused page can make each answer less distinct. A diagnostic page can link to the implementation workflow after it identifies the likely problem.

    Write answers that can be extracted without losing context

    Answer-first writing does not mean reducing every page to a blunt definition. It means making the conclusion visible before asking the reader to process all the supporting detail.

    A strong opening answer usually contains the subject, the recommended action or conclusion, and the condition that prevents the statement from becoming misleading. Compare these two constructions:

    Weak: There are many factors to consider when pursuing better AI visibility, and every business needs a comprehensive approach.

    Stronger: To improve Gemini visibility, make the page answer a specific user question directly, support its important claims, and identify the entities and conditions involved.

    The stronger version does not guarantee inclusion in a generated answer. It does give the reader an immediate orientation and makes the page’s central claim easier to interpret.

    Use this editing pass on every priority page:

    • Replace generic headings. “Benefits” says little on its own. A heading such as “Clear answers reduce ambiguity for readers and answer engines” announces the point of the section.
    • Keep qualifiers beside the claim. If advice applies only to a certain page type or use case, state that condition in the same paragraph. Do not hide it several sections later.
    • Name the subject again when needed. Repeating a product or organization name is better than using an ambiguous pronoun where several entities are in view.
    • Use stable terminology. If “AI visibility” and “organic traffic” mean different things in your measurement plan, do not switch between them as though they were synonyms.
    • Separate fact from judgement. Mark recommendations as recommendations. A clear editorial position is more trustworthy than advice disguised as a universal rule.
    • Make lists genuinely parallel. Steps should be actions in sequence. Criteria should be comparable qualities. Do not mix outcomes, warnings, and instructions in the same list without labels.
    • Use descriptive internal links. Tell the reader what the destination will help them do instead of relying on “learn more” or “click here.”

    Do not repeat the same short answer mechanically across several pages. Near-duplicate answers create uncertainty about which page is authoritative. Choose a primary page for the question, let related pages handle their own distinct intents, and connect them with contextual internal links.

    Align entities, evidence, and structured data

    Gemini cannot represent your content accurately if your own site is inconsistent about who or what the content describes. An entity pass is therefore more useful than inserting extra keyword variants.

    Check the visible page for consistent organization names, product names, service labels, author information, and relationships between them. If a product has been renamed, explain the relationship instead of silently alternating between old and new names. If an acronym could refer to several things, define it before relying on it.

    Then perform an evidence pass:

    • Identify the claims a reader would reasonably want verified.
    • Link to the originating authority when a primary reference is available.
    • Name the relevant product, model, version, jurisdiction, or other constraint when it changes the meaning of the claim.
    • Place the supporting citation close to the statement it supports.
    • Remove outdated or contradictory statements elsewhere on the site.
    • Distinguish documented facts from your own interpretation or recommended practice.

    Structured data can reinforce that clarity, but only when it describes what the visitor can see. Use the schema type that matches the page, and keep names, authorship, dates, and other marked-up properties aligned with the visible content. Validate the syntax and remove properties that make claims the page itself does not substantiate.

    Think of JSON-LD as a disambiguation layer. It can express meaning in a machine-readable form, but it cannot supply missing expertise, rescue an unclear answer, or guarantee selection in a Gemini response. If the markup and the page disagree, fix the underlying content before adding more schema.

    Technical accessibility remains part of the foundation. A public page that cannot be crawled reliably is not a dependable citation target. Check crawl access, canonicalization, index eligibility, rendered content, and internal linking before diagnosing the problem as an AI-specific visibility issue.

    Measure Gemini visibility with a prompt-led audit

    An overhead audit workspace shows question tokens being traced through an answer to connected and omitted source cards.

    A conventional rank tracker does not capture the whole outcome. Generated responses can change with prompt wording and conversational context, so a single manual query is not a reliable benchmark. Build a stable prompt set around the real questions your audience asks and preserve the exact wording for later checks.

    Your set should include the distinct situations that matter to the business: discovering a category, understanding a concept, comparing approaches, applying a constraint, troubleshooting a problem, and choosing a next action. Do not pad the set with superficial variants that test the same intent repeatedly.

    For every check, record the prompt, the answer’s factual accuracy, whether the brand appears, whether a page is linked or otherwise cited, which page is used, whether the response satisfies the intent, and what the user could reasonably do next. Keep brand mentions separate from citations and referral traffic. They represent different levels of visibility.

    What you observeWhat may be happeningWhat to change first
    A competing page is cited while yours is absentThe competing page may answer the prompt more directly or support the answer more clearlyCompare decision coverage, qualifications, and evidence; add the missing substance rather than copying its wording
    Your brand appears, but no useful page is citedThe entity may be recognized while your site lacks a definitive answer pageStrengthen the best existing page with a direct answer, clear identity, and supporting evidence
    The answer describes your brand or product incorrectlyYour public information may be ambiguous, inconsistent, or outdatedReconcile names and facts across the relevant pages, then make the canonical explanation explicit
    A ranking page is omitted from the generated answerThe page may satisfy click intent but bury the extractable conclusionAdd a concise, qualified answer under the relevant heading and keep its evidence nearby
    The result changes when the prompt is slightly rewordedThe page may cover only part of the user’s underlying intentMap the meaningful prompt branches and address the missing condition or follow-up question

    Turn that diagnosis into a controlled workflow:

    1. Save the exact benchmark prompts and current responses.
    2. Assign the best page on your site to each prompt. If no suitable page exists, record the content gap.
    3. Classify the issue as access, intent, answer clarity, evidence, entity consistency, or page authority.
    4. Make the smallest change that addresses the diagnosed problem.
    5. Confirm that the updated page remains useful to a human reader and can still be crawled and indexed as intended.
    6. Retest after search systems have had an opportunity to rediscover the change, using the same prompts and recording any differences.

    Avoid rewriting the title, introduction, schema, internal links, and page structure simultaneously. If visibility changes, you will not know which intervention mattered. Controlled edits make the audit useful even when Gemini’s output itself varies.

    Start with the prompt most closely tied to a real reader decision. Give it a definitive page, a direct but qualified answer, consistent entity information, and evidence a reader can inspect. That is a stronger Gemini SEO program than publishing more vaguely related content and hoping the model connects it for you.

    References


  • LLM Nudges: How AI Steers Decisions After the Answer

    LLM Nudges: How AI Steers Decisions After the Answer

    You can earn a favorable mention in an AI answer and still lose the decision one sentence later. If the model closes by offering to find a cheaper option, compare competitors, or build a personalized shortlist, it has changed what the user is likely to consider next.

    That closing prompt belongs in your AI visibility strategy. You need to inspect where it sends the conversation, follow the suggested path, and make sure your content supplies the evidence the model will need on the next turn.

    The next-turn prompt is part of your visibility surface

    An LLM nudge is the invitation that appears near the end of an answer: "Would you like a comparison?", "Tell me your budget," or "I can find current deals." It looks like a courteous way to keep the conversation open. Functionally, it creates a low-effort next action.

    The user doesn’t have to formulate another query, choose a new search result, or decide which criterion matters. The model has already proposed the criterion and the next step. A brief "yes" can move the conversation from discovery to comparison, from quality to price, or from a general recommendation to a shortlist built around personal constraints.

    That makes the nudge more than an engagement device. It can influence digital decision-making in three ways:

    • It frames the next question. An offer to compare prices makes cost more prominent, even when the original request was about quality or suitability.
    • It requests decision data. Asking for a budget, location, use case, or preference gives the model new filters for the next recommendation.
    • It narrows the action. An invitation to compare two named options can turn a broad market into a two-brand decision.

    A nudge is not proof that the model prefers the suggested action or any brand involved. It is evidence about the direction of the conversation. Keep that distinction clear: the initial answer measures answer visibility, while the accepted nudge reveals journey visibility.

    When you monitor AI responses, capture the final invitation as its own field. Don’t bury it in a screenshot or treat it as disposable wording. Record the proposed action, the decision criterion it introduces, and the information the user is asked to provide.

    Read each nudge as a change in decision criteria

    Budget and deal prompts are the dominant pattern in observed LLM interactions, representing roughly half of closing suggestions. Product comparisons are the next most common route. Specification-led follow-ups appear much less often, even though specifications can still help a model evaluate and rank competing options.

    This distribution matters because each route changes what your brand must prove. A premium brand may enter the first answer on quality, expertise, or fit, then face a next-turn comparison organized around price. A challenger may receive an opportunity when the user accepts a comparison. A complex product may disappear when the model asks for details that its public content never states clearly.

    The platforms also express these invitations differently. Their wording is less important than the behavior it produces, but the differences help you design a realistic monitoring set.

    PlatformTypical closing styleCommon next-turn behaviorWhat to inspect
    ChatGPT"If you want…"Deals and product comparisonsWhether your brand survives a price-led or head-to-head follow-up
    Microsoft Copilot"If you tell me…"Clarification and personalizationWhich user details become filters and whether your content answers them
    Google Gemini"Would you like me…"Permission-based continuationThe task proposed after permission is granted
    Perplexity"I can help…" or "If you’d like…"Utility-oriented follow-up, often including commerceThe sources and attributes used when the offered help is accepted
    Meta AI"Let me know…"More passive continuation, often involving comparisons or specificationsWhether a less forceful invitation still narrows the decision set

    Don’t turn these platform tendencies into permanent rules. LLM outputs can vary with wording, context, model changes, and the conversation that came before. Use the patterns to choose what to test, then judge the responses you actually receive.

    The practical question is not simply, "Did the model mention us?" Ask, "Which criterion did the model introduce next, and does our public evidence support us under that criterion?" That question exposes the content gap behind most nudge failures.

    Audit the conversation chain instead of one answer

    An analyst examines a connected sequence of blank conversation panels that changes direction across several turns.

    A conventional AI visibility check often stops once it records cited domains, named brands, and answer sentiment. A nudge audit continues until you can see how the model changes the decision after the user accepts its offer.

    1. Start with a real decision. Choose a commercially important question your customer would ask, such as selecting between product types, finding an option within a constraint, or solving a post-purchase problem. A broad keyword without a decision behind it won’t reveal a useful journey.
    2. Run the same intent across relevant platforms. Preserve the meaning but include natural variations in phrasing. Record the platform, available model identifier, prompt wording, and run date so later checks remain interpretable.
    3. Separate the answer from the closing nudge. Save the exact invitation, classify it as budget, deal, comparison, clarification, specification, support, or another observed route, and note any brands or attributes named in it.
    4. Accept the nudge as written. If the model offers a comparison, accept the comparison. If it asks for a budget, provide a plausible budget that fits the audience you are testing. Don’t substitute a different follow-up, because that would test your prompt rather than the model’s proposed journey.
    5. Inspect the next response. Record which brands remain, which disappear, which new competitors enter, what evidence supports the recommendation, and whether the model introduces another nudge.
    6. Map the missing evidence to a page. Every unsupported price, comparison criterion, qualification question, or support problem should point to a specific content asset that needs to be created, corrected, or made easier to retrieve.

    Use a structured worksheet rather than a folder of screenshots. The minimum useful record looks like this:

    FieldWhat to record
    Starting decisionThe user’s underlying choice, constraint, or problem
    Initial brand positionMentioned, recommended, omitted, or cited only as evidence
    Closing nudgeThe invitation exactly as displayed
    Nudge categoryBudget, deal, comparison, clarification, specification, support, or other
    Accepted inputThe reply used to continue the suggested path
    Next-turn positionWhether the brand persists and how its role changes
    Decision evidencePrices, attributes, limitations, policies, proof, or support instructions used
    Content actionThe exact page or data element to create, update, or clarify

    Repeat important prompts with natural paraphrases and at different checkpoints. The available evidence is still based on individual interactions rather than a complete view of every user journey, so one response should be treated as an observation, not a stable market-share estimate.

    Build content for the four next-turn paths that matter

    Four visual paths branch from an abstract AI message toward comparison, affordability, personalization, and evidence-related choices.

    You cannot dictate the sentence an LLM will place at the end of an answer. You can make your brand easier to evaluate when the conversation moves into a predictable follow-up. Start with the route that creates the largest gap between your positioning and the model’s next criterion.

    Comparison: make the decision legible

    A useful comparison page does more than place two feature lists side by side. It explains which option fits which user, identifies the criteria that materially change the choice, and states where each option has an advantage or limitation. If your page claims that your product wins every category, it gives the model little reason to trust the distinction.

    Build comparison content around the decision, not the competitor’s name alone. Include a direct summary, a consistent attribute table, audience-fit statements, pricing context, important constraints, and evidence for differentiating claims. Date facts that can change, and assign an owner to keep them current.

    For health or financial choices, a comparison page must not pretend to make an individualized decision. Explain the criteria and scope, state material limitations, and direct personal decisions to an appropriately qualified professional.

    Budget and deals: publish the facts without cheapening the brand

    Ignoring price does not prevent an LLM from creating a price comparison. It leaves the model to assemble one from weaker, older, or third-party information. Even a premium brand needs a clear public explanation of what the buyer pays and what that price includes.

    Keep the visible page and structured data aligned. Where Product and Offer markup applies, populate accurate values for price, priceCurrency, availability, and url. Use priceValidUntil only when an offer has a real expiry date. If a price depends on configuration, eligibility, contract length, or location, state that condition rather than publishing a misleading headline number.

    Deal data needs the same discipline. Show the eligible products, start or end conditions, redemption requirements, exclusions, and the normal price where appropriate. Remove expired offers from the visible page and update the associated markup. The objective is not to manufacture a discount for AI visibility; it is to make valid commercial facts unambiguous.

    If low price is not your position, publish the evidence that explains the premium. That may be included service, durability, specialist capabilities, support terms, or a lower total cost for a defined use case. Use only claims you can substantiate. The model may still compare prices, but it will have a better chance of comparing value as well.

    Clarification: answer the filters the model asks for

    A clarification nudge reveals the variables the model considers necessary for a better recommendation. Treat those variables as an editorial brief. If it asks about budget, experience level, location, compatibility, team size, or intended use, check whether your pages state who the offer is for and where it does not fit.

    Add concise "best for," "not intended for," prerequisite, compatibility, and constraint sections where they genuinely help the decision. Use the same terminology across product pages, comparison pages, documentation, and structured data. Contradictory labels force the model to reconcile facts that your organization should have resolved first.

    Support and specifications: own the quieter opportunity

    LLMs are less proactive about troubleshooting and support than they are about commerce. That support gap creates a useful authority opportunity: publish the answer before the model learns to ask for it more often.

    A support page should identify the product or version, describe the exact symptom, list prerequisites, give ordered steps, explain the expected result, document known limitations, and provide an escalation path. Avoid placing critical instructions only in an image or an undifferentiated PDF when the same information can be published as accessible HTML.

    Specifications deserve similar care even though they account for a smaller share of closing nudges. Use consistent units, stable attribute names, explicit compatibility information, and version-specific values. Specifications may not trigger the next question, but they can supply the facts used inside a comparison, qualification, or support answer.

    Measure whether the nudge keeps your brand in the decision

    You generally won’t see a user’s private AI conversation in your analytics, so separate what you can observe in controlled prompts from what you can observe on your site. Combining the two as if they were one attribution trail creates false precision.

    Use your prompt audit to track nudge direction, brand continuity, evidence quality, and destination readiness. Brand continuity is the share of tested conversation chains in which your brand remains relevant after the suggested follow-up is accepted. Review the underlying chains alongside the rate; a brand can persist as the recommended choice, a weak alternative, or merely a cited source.

    Use analytics to monitor identifiable AI referrals, the landing pages they reach, engagement with comparison or pricing content, support journeys, and completed business outcomes. A referral from an AI platform does not prove that a particular closing nudge caused the visit. Treat referral behavior as supporting evidence, not a transcript of the user’s path.

    Re-run the audit after material changes to pricing, products, documentation, positioning, structured data, or major model behavior. Keep the original prompts and classification rules stable enough to compare observations, while adding new prompts when customers develop genuinely new decision patterns.

    Key takeaways

    • Capture the closing invitation separately from the main AI answer; it signals the next decision criterion.
    • Accept the model’s proposed follow-up and audit the second response before declaring an AI visibility win.
    • Prioritize accurate comparison, pricing, deal, qualification, support, and specification content based on the paths you actually observe.
    • Keep visible claims and structured data synchronized, especially when prices, availability, or promotions change.
    • Measure brand continuity across conversation chains, then use site analytics as supporting evidence rather than claiming perfect attribution.

    Start with one decision that materially affects your business. Record the answer, follow the nudge, and fix the first evidence gap that causes your brand to disappear or lose its position. That small extension turns an AI mention check into a usable view of the customer journey.

    References


  • How to Make Content Visible in Search and AI Answers

    Your page is indexed, technically sound, and even earns search impressions. Yet it rarely appears in AI answers, recommendations, or citation-style results. That usually isn’t a signal to add more keywords. It is a signal to find the exact point where discovery breaks.

    Content visibility is a chain: access, extraction, intent matching, evidence, selection, and measurement. If you diagnose those stages in order, you can make a targeted change instead of rewriting a useful page on instinct.

    Visibility is a chain, not a single ranking setting

    A search engine or AI system must first reach the URL. It then has to extract the main content, determine what the page is about, match it to a user’s need, and decide whether the material is suitable to surface or reuse. A failure at any stage can look like the same outcome: no visibility.

    This is why crawlability and AI visibility should be treated as related but separate requirements. Allowing a crawler through the door does not make an ambiguous page understandable. Clear writing and schema cannot compensate for a blocked, redirected, or non-indexable URL.

    Distribution is also more fragmented than a conventional rankings report implies. A dataset covering 42 million Google Discover cards from December 2025 through February 2026 identified 20 selecting pipelines organized into six broad layers: core editorial, news urgency, trends, local or geographic content, social or video content, and commercial content. The sample came from hundreds of devices, so it is a substantial snapshot, but it is not a permanent map of every Google or AI system.

    The practical lesson is narrower and more useful: different surfaces can select the same URL for different reasons. A traditional ranking, a Discover recommendation, and an AI citation should not be treated as three readings from one universal visibility score.

    Key takeaways

    • If a system cannot fetch the final page, content changes will not solve the problem.
    • If the title, description, opening, headings, and structured data imply different purposes, the page’s intent is unclear.
    • If important claims lack context, dates, ownership, or supporting links, the material is harder to evaluate and safely reuse.
    • Google Search Console queries show the demand already reaching each page, making them a better starting point than a speculative keyword list.
    • Search, Discover, referral traffic, brand mentions, and AI answer citations need separate measurements.

    Diagnose the earliest broken stage before rewriting

    Start with the URL, not the copy. Work through the following checks in order and stop when you find a material failure. There is little value in polishing an answer that the relevant systems cannot reliably retrieve.

    1. Confirm access. Open the public URL without an authenticated session. Check the response, redirects, canonical target, robots rules, and page-level indexing directives. Review any firewall, bot-management, or consent layer that could return a challenge instead of the article. If your organization blocks categories of crawlers, make that an explicit policy decision rather than an accidental side effect of a security preset.
    2. Inspect the extractable page. Make sure the main answer, headings, lists, links, and evidence exist in the delivered document. Do not assume every retrieval system will execute a client-side application exactly as a human browser does. Remove overlays and template elements that obscure the opening or make navigation look like the main content.
    3. Verify page identity. The title, meta description, visible heading, introduction, canonical URL, breadcrumbs, and structured data should describe the same resource. A page presented as a tutorial in one field and a product category in another creates unnecessary ambiguity.
    4. Compare the promise with real demand. In Google Search Console, inspect the queries associated with this specific URL. Group them by the job the searcher is trying to complete, such as learning, comparing, troubleshooting, evaluating, or buying. Then compare the dominant job with what the page promises near the top.
    5. Audit evidence and ownership. Mark claims that depend on a date, platform, version, dataset, or named organization. Add that context where it changes the answer. Identify the author or responsible publisher and link important factual claims to the material that supports them.
    6. Check each outcome separately. Review organic search performance, Discover exposure where applicable, observable AI referrals, brand mentions, and citations in a controlled set of answer prompts. One healthy channel does not prove that the others are healthy.

    The first failed stage determines the next action. Fix access before content. Fix a query-to-page mismatch before adding schema. Strengthen evidence and entity clarity when the page is reachable and relevant but difficult to quote or attribute. If all of those checks pass, improve distribution and measurement instead of forcing another rewrite.

    Use Search Console to measure the intent gap

    Most content briefs begin with the audience a business hopes to attract. Search Console shows the audience Google is already connecting to the page. The difference between those two groups is your intent gap.

    That gap is about meaning, not merely shared words. Vector embeddings can place queries and page descriptions in the same semantic space, allowing their distance to be scored. A documented implementation compares page-level Search Console queries with the page’s meta description and uses the distance to identify weak alignment.

    Treat such a score as a diagnostic proxy. It is not an official Google metric, it does not prove why a page ranks, and a high similarity score does not guarantee inclusion in an AI answer. Its value is prioritization: it helps you locate pages whose positioning is far from the demand already reaching them.

    A query-to-page workflow that does not require a special tool

    1. Export queries by page. Preserve impressions, clicks, position, page, and query so that demand remains attached to the URL receiving it.
    2. Separate different kinds of demand. Keep branded or navigational searches distinct from problem, comparison, and transaction-oriented searches. They represent different reasons for reaching the page.
    3. Cluster by user task. Group queries that ask for the same outcome even when they use different vocabulary. Do not create a separate intent simply because a synonym appears.
    4. Write the demand in one plain sentence. Complete the statement: People reaching this URL mainly want to… If several unrelated endings carry meaningful demand, the page may be trying to do too many jobs.
    5. Write the page promise. Read only the title, meta description, main heading, opening paragraphs, and section headings. Complete the statement: This page helps you… Use what is actually on the page, not what the content brief intended.
    6. Choose a structural response. Keep the positioning when promise and demand agree. Refocus the opening and headings when the right answer is buried. Expand the page when it omits a necessary subproblem. Split the page when distinct audiences or tasks require incompatible answers.

    Look for five common forms of mismatch:

    • Scope gap: searchers want an implementation answer, but the page stays at the strategy level.
    • Audience gap: the page addresses specialists while the queries come from beginners, or the reverse.
    • Stage gap: the page tries to sell while the dominant demand is educational, or teaches basics to people already comparing options.
    • Format gap: the query calls for steps, criteria, or troubleshooting, but the page provides a continuous essay.
    • Outcome gap: the copy describes a topic without resolving the decision or problem behind the query.

    Do not rewrite the meta description in isolation just to improve semantic similarity. It is useful because it expresses the page’s promise compactly. If that promise changes, make the same intent visible in the heading, introduction, body, internal links, and structured data. Otherwise, you have improved the label while leaving the resource unchanged.

    Build an answer asset without weakening the full page

    An AI-visible page still needs to work as a page. Compressing everything into short definitions may make individual sentences easy to extract, but it can remove the qualifications and evidence that make the answer trustworthy. Build a clear answer core, then support it with the depth the decision requires.

    Put the answer core near the top

    Answer the main question in direct language before moving into background. State who the answer applies to, what conditions change it, and what the reader should do next. If the subject requires a sequence, expose that sequence in an ordered list. If it requires choosing among options, name the decision criteria before describing every option.

    Use headings that identify an actual subproblem. A heading such as Diagnose the earliest broken stage tells a reader and a machine what the section resolves. Generic labels such as Overview or More information do not.

    Use structured data as clarification, not decoration

    Select the most accurate schema type for the visible resource. Mark up only information a visitor can verify on the page. Keep names, authorship, publisher identity, dates, breadcrumbs, and canonical references consistent across HTML and JSON-LD. When an organization or product appears across multiple pages, use stable identifiers and naming rather than creating slightly different versions of the same entity.

    Schema cannot repair a blocked URL, substitute for a missing answer, or make unsupported claims trustworthy. Its useful role is disambiguation: it helps a system interpret the type of resource and the relationships already expressed in the visible content.

    Make provenance part of the answer

    Durable visibility in generative systems depends partly on consistent metadata, provenance, and trust signals. Give time-sensitive claims a date or version. Name the organization responsible for the content. Link to the originating evidence when a factual claim depends on it. Distinguish observed facts from your recommendation.

    This is not a request to add a long author biography to every page. It is a request to remove uncertainty that matters. A reader should be able to tell who is making the claim, when it applies, what supports it, and whether it is a fact, interpretation, or recommendation.

    Package the content for its genuine distribution context

    The measured Discover environment separated selection into layers for editorial content, urgent news, trends, local material, social or video content, and commercial content. It also evaluated pipelines by reach, speed, exclusivity, and feed volume. Those dimensions explain why a URL can have broad reach, fast pickup, or exclusive distribution without performing identically across every surface.

    Use only the attributes your content genuinely has. Preserve geographic specificity when the answer is local. Make publication and update context clear when timing changes the value. Treat an original video as a first-class resource when video is integral to the answer. Do not imitate urgency, locality, or trend relevance that the page cannot substantiate.

    Measure search and AI visibility as a portfolio

    A single visibility percentage collapses different systems, intents, and outputs into a number that is hard to act on. Use a small scorecard that keeps the stages separate:

    LayerWhat to recordWhat a weakness meansFirst response
    AccessPublic response, redirects, canonical, robots rules, indexing directives, and extractable main contentThe resource may not be consistently retrievable or eligibleFix the technical path before editing copy
    Search demandPage-level queries, impressions, clicks, and position from Search ConsoleDemand may be weak, changing, or attached to a different intentInspect query clusters and competing pages
    Intent fitAlignment between dominant query tasks and the title, description, opening, and headingsThe page promise does not match the audience reaching itDefend, refocus, expand, or split the page
    Answer readinessDirect answer, qualifications, evidence links, author or publisher, dates, and consistent structured dataThe material may be relevant but difficult to interpret, attribute, or reuseClarify the answer and its provenance
    AI presenceMentions and citations from a versioned set of prompts, plus identifiable referral traffic where availableThe page is not being selected consistently in the observed answer environmentCheck intent, evidence, entity clarity, and competing answer formats
    Discovery distributionDiscover or recommendation exposure reported separately from standard searchA distribution surface may value different timing, format, or contextual signalsImprove truthful packaging for that surface

    For AI answer checks, record the full prompt, engine, date, locale, and any account state that could affect the output. Reuse the same prompt set when evaluating a change. A single answer is an observation, not a trend, and it should not trigger a site-wide rewrite.

    Keep a change log for the URL. Record whether you altered access rules, positioning, the answer core, evidence, structured data, or distribution packaging. Then compare equivalent periods and inspect the metrics closest to the stage you changed. If you modify every layer at once, any improvement will be difficult to explain or repeat.

    Choose one page with meaningful Search Console impressions and uncertain AI visibility. Run the diagnostic from access through measurement, fix the earliest material failure, and document that change. That gives you a defensible optimization process you can apply to the next page instead of another collection of AI SEO guesses.

    References


  • How to Prepare for Google Search as a Task-Completing Agent

    How to Prepare for Google Search as a Task-Completing Agent

    If your SEO strategy ends when somebody clicks a result, you are preparing for an older version of Search. A task-completing system may use your content to compare options, resolve constraints, choose a next step and initiate an action. Your page is no longer competing only to be read. It is competing to be useful inside a larger job.

    This does not mean abandoning rankings, traffic or conventional SEO. It means adding a second standard: can Google understand what your business offers, determine when it is appropriate and move a user toward a safe, verifiable outcome?

    The search result is becoming part of the workflow

    Traditional search usually separates discovery from execution. You search for information, open several pages, make sense of them and complete the task somewhere else. Agentic search compresses those stages. Google’s stated direction is for more information-seeking queries to become agentic, with Search coordinating long-running work and multiple concurrent threads.

    Think about a request such as, “Find accounting software suitable for a small Canadian consultancy, compare the plans and help me arrange a demonstration.” An ordinary results page can supply links for each part. A task-oriented system has to preserve the user’s requirements while it researches vendors, rules out unsuitable choices, explains trade-offs and hands the user into an action.

    That changes the unit of optimization. A keyword is one expression of demand. A task includes the desired outcome, the constraints, the decisions that must be made, the evidence needed to make them and the action that finishes the job.

    • Question: What does the user need to know?
    • Qualification: Which options fit the user’s location, situation, budget, timing or technical requirements?
    • Decision: What evidence separates an appropriate choice from an inappropriate one?
    • Action: What can the user book, buy, configure, submit or request?
    • Verification: How does the user know the action succeeded, and how can it be changed or reversed?

    People are already using AI Mode for deep-research queries that stretch beyond the old one-query, one-answer pattern. That is the immediate signal to act on. You do not need to predict every interface Google will release. You need to make your public information dependable enough to support a multi-step decision.

    Search and Gemini are also expected to coexist, overlapping in some uses while diverging in others. Do not reduce your plan to optimizing for one chatbot response. Your information may be encountered through a conventional result, an AI-generated answer, a research workflow or an action-oriented experience. The underlying facts should remain consistent across all of them.

    Optimize the complete task, not just its opening query

    An isometric workflow follows a user request through comparison, constraint checking, availability, verification, and a completed outcome.

    Start with one task that matters to your audience and your business. Avoid broad goals such as “learn about payroll” or “rank for payroll software.” Use an observable outcome: “Determine whether this payroll service supports my type of company and begin the correct signup process.”

    Then create a task map. This is more useful than a keyword cluster because it exposes the information gaps that can stop an agent or a person from proceeding.

    1. Write the outcome in the user’s language. State what will be decided or completed, not what content will be consumed.
    2. List the required inputs. Identify the details that change the answer, such as location, organization type, compatibility, eligibility, timing or service area.
    3. Break out the decisions. Record every choice the user must make before acting. A product tier, appointment type or implementation route may each require a separate decision.
    4. Assign evidence to each decision. Decide which page supplies the specification, policy, price, limitation, comparison or proof needed at that point.
    5. Define the action and handoff. Make clear where the user can start, what information will be requested and what happens after submission.
    6. Document failure and recovery paths. Explain what to do when the user is ineligible, an option is unavailable, a form fails or an action must be cancelled.

    The recovery path matters because task completion is not the same as pushing every visitor toward conversion. A reliable system must also recognize when your offer does not fit. If exclusions are buried in terms, an agent may recommend the wrong route and the user will discover the problem late. Put decisive limitations beside the claims they qualify.

    Next, label the role of every page in the task. One page may establish eligibility, another may compare options, another may explain a procedure and another may host the transaction. A page can serve more than one role, but each role should be explicit. If your team cannot agree on what a page contributes to the task, an automated system is unlikely to infer it reliably.

    Build pages an agent can interpret and use

    An agent-ready page is not a page written for robots. It is a page on which the decisive facts are clear, scoped and consistent. Good structure helps people and machines for the same reason: neither should have to reconstruct a critical condition from vague marketing language.

    Task layerWhat must be resolvedWhat to improve on the site
    IntentThe outcome the page supportsUse a descriptive title, a direct opening answer and a clear statement of who the page is for.
    QualificationWhether the offer fits the user’s constraintsState eligibility, locations, dependencies, exclusions and prerequisites beside the relevant offer.
    DecisionWhy one option should be chosen over anotherUse comparable attributes, defined terms and evidence tied to specific claims.
    ActionHow to begin or complete the next stepName the action precisely, disclose required inputs and explain what happens after it is submitted.
    VerificationWhether the action succeededProvide an explicit confirmation state, reference information and a route for correction or cancellation.
    Machine interpretationWhich entities and relationships the content describesUse accurate structured data that matches the visible page and the site’s canonical facts.

    Several practical rules follow from this model.

    Put the decisive answer before the supporting narrative

    If a service is available only in particular locations, say that near the service description. If a plan requires another product, state the dependency beside the plan. If the next step is a consultation rather than an immediate purchase, label it accurately. Do not make the reader decode “Get started” to discover what will actually happen.

    Turn implied knowledge into explicit facts

    Businesses often assume that visitors understand their terminology, market, service boundary or product hierarchy. An agent cannot safely rely on that assumption. Define ambiguous terms, attach units to measurements, give conditions to claims and distinguish facts about the company from facts about a particular offer.

    Consistency is more important than repetition. If a product name, service area, policy or plan description differs across a landing page, help page and checkout flow, decide which version is canonical and correct the others. Structured data should reflect that same version.

    Use JSON-LD as a factual layer, not a persuasion layer

    Choose Schema.org types and properties that match what is visibly present. Identify the organization, offer, product, service, person, place or event only when the page genuinely describes that entity. Connect related entities where the relationship is real. Keep names, URLs, identifiers and offer details aligned with the canonical content.

    Do not add unsupported properties because they look advantageous, and do not mark up claims that a visitor cannot verify on the page. JSON-LD can make a fact easier to interpret; it cannot turn an incomplete, stale or contradictory claim into a trustworthy one.

    Design the action boundary deliberately

    Research and execution carry different risks. Reading a comparison is low commitment. Sending personal information, placing an order or booking an appointment is not. If your task ends in an action, make the commitment point unmistakable.

    • Show what will be submitted or purchased before confirmation.
    • Separate required inputs from optional ones.
    • Display material conditions before the final action, not only after it.
    • Explain whether the action is immediate, pending review or merely a request.
    • Provide a correction, cancellation or support route where the action permits one.
    • Return a clear success or failure state instead of leaving the user to infer the result.

    These are conversion fundamentals, but they become more important when software may coordinate the handoff. Ambiguous buttons, silent form failures and hidden conditions do not merely reduce conversion. They make the task unsafe to delegate.

    Audit task readiness before agent traffic becomes measurable

    A digital inspection agent scans the modular elements of a webpage while a human specialist supervises from a control station.

    You may not be able to isolate every agent-assisted visit or decision in your reporting. You can still measure whether your site is ready to participate. Treat readiness as a content, data and workflow quality problem.

    Use a simple zero-to-two audit for each important task. This is a prioritization method, not a search-engine score:

    • 0 — Missing or contradictory: the task cannot proceed without guessing, or two public pages give incompatible answers.
    • 1 — Inferable: the answer exists, but the user must combine pages, interpret vague wording or uncover a condition late.
    • 2 — Explicit and usable: the answer is clear, appropriately qualified, current and connected to the correct next step.

    Score the task across six dimensions: outcome definition, qualification facts, decision evidence, action path, confirmation or recovery, and measurement. Do not obsess over the total. A zero in any dimension identifies a broken link in the workflow and deserves attention before cosmetic content changes.

    Run the audit from the public site, without internal knowledge. Give a team member the task and its constraints. Ask them to find the right option, explain why it fits, begin the action and identify how they would reverse or correct it. Record every point where they have to guess. Those guesses become your content and workflow backlog.

    Measure the workflow in stages so a completed task is not reduced to a pageview:

    • Discovery: Did the relevant landing page become visible for the task?
    • Qualification: Did the visitor reach the eligibility, specification, policy or comparison information needed to proceed?
    • Action: Did the visitor start and complete the intended form, booking, configuration or transaction?
    • Failure: Where did validation errors, unavailable options or unclear requirements stop progress?
    • Outcome quality: Did the action lead to confirmation, or did it create cancellations, corrections and avoidable support work?

    This measurement model also protects you from a misleading success signal. More action starts are not helpful if users are being routed into an unsuitable option. Pair completion data with failure, cancellation and correction data so you can distinguish task volume from task quality.

    Key takeaways

    • Optimize for a defined user outcome, not only the keyword that begins the journey.
    • Map qualification, decision, action and verification as separate stages, then assign each stage to reliable public information.
    • State decisive constraints beside the claims they limit. Do not hide eligibility, dependencies or exclusions at the end of the path.
    • Keep visible content, structured data and transactional interfaces consistent about the same entities and offers.
    • Treat confirmation, correction and cancellation as part of task completion, not as support details.
    • Audit every task for missing or contradictory information before trying to infer performance from agent-specific traffic.

    Choose one commercially important task this week. Write its outcome, inputs, decisions, evidence, action and recovery path on a single page. Then follow it through your public site and fix the first place where a user has to guess. That work will improve the experience now, while giving agentic Search cleaner material to use as it moves from answering questions toward completing jobs.

    References

  • Google Content Quality: How AI-Assisted Pages Can Rank

    You have an AI-assisted page ready to publish, but one question is holding it up: will Google treat the content as low quality because a model helped write it? Rewriting every sentence by hand is not the answer. Neither is publishing the model’s first draft and hoping formatting or schema will make it competitive.

    The practical job is to create a page whose claims a human editor can defend. That matters in conventional search and in AI-generated answers. Google has acknowledged using protections against manipulative, low-quality listicles in both Search and Gemini, while ranking data show that detectable AI writing patterns are associated with much weaker performance at the top of Google. The useful response is better evidence and editorial judgment, not an attempt to disguise the production method.

    Ranking data does not prove that Google penalizes AI

    Across 42,000 blog pages classified for a Semrush analysis, human-authored content occupied Google’s number-one position 80% of the time, compared with 9% for purely AI-generated content. Human-authored pages also appeared more often throughout the top 10, while pages classified as AI-generated became more common in lower positions on the first results page.

    Those numbers are a warning against unchecked automation, but they are not evidence of a direct AI penalty. GPTZero was used to classify the pages, and AI detectors can misclassify human, mixed, and machine-generated writing. Because writing type and ranking position were observed together, the result is correlation. It does not reveal which signals Google used or establish that authorship method caused the rankings.

    That distinction changes what you should do. Do not run every draft through an AI detector and rewrite it until the detector returns a preferred label. A detector score is not a Google quality score, and prose that looks human can still be generic, inaccurate, or commercially biased.

    Instead, test whether the page contains judgment that survives scrutiny:

    • Decision value: Does the page help a specific reader choose, fix, avoid, or understand something?
    • Evidence: Can you trace every consequential claim to genuine experience, a supplied record, or a reliable reference?
    • Boundaries: Does the recommendation say who it is for, when it applies, and when it does not?
    • Editorial ownership: Has a named person or accountable team decided that the claims are accurate and worth publishing?
    • Original contribution: Does the page add an explanation, distinction, method, or decision rule beyond what a model could infer from common web copy?

    A human-written page that fails those tests is still weak. An AI-assisted page that passes them has a defensible reason to exist. That is a more useful quality distinction than human versus machine.

    Content quality breaks where evidence and independence are implied

    The clearest failure pattern appears in commercial listicles. A brand publishes a "best tools" page, includes products it has not tested, assigns unexplained scores, and places its own product first. The page looks like an independent evaluation even though the outcome, evidence, and publisher relationship are hidden.

    This is not just a question of writing style. The page is making an evidence claim: that someone performed a fair comparison and has grounds for the ranking. A fluent AI draft can make that unsupported claim sound more convincing, which increases the problem rather than solving it.

    What the page claims to beEvidence it needsHow to frame it honestly
    Independent reviewGenuine use or testing by the reviewerIdentify what was tested, how it was tested, and any limits that affected the conclusion.
    Feature comparisonVerifiable product facts and declared comparison criteriaCall it a researched comparison and do not imply firsthand use that did not occur.
    Owned recommendationSupport for each claim plus a clear material-relationship disclosureState that the publisher owns or sells one of the products and explain how the recommendation was reached.
    Customer testimonialA genuine statement from the person to whom it is attributedPreserve the speaker’s meaning and do not create, rewrite, or assign praise that the person did not provide.

    Use "best" only when you can defend the category

    A defensible winner needs more than a score. Define the audience, use case, eligibility rules, criteria, weighting, evidence type, exclusions, and material relationships. If changing an unstated preference could reverse the result, you do not have an objective ranking. You have an editorial preference that should be presented as one.

    Conditional recommendations are usually more useful than universal winners. "Best for teams that need a self-hosted workflow" gives the reader a decision condition. "Best overall" conceals the condition and invites you to defend a much broader claim.

    If you did not test the products, remove language such as "we found," "our test showed," or "after using." You can still compare documented capabilities, but label the work accurately. A researched feature matrix is not a review, and turning it into one with confident prose does not create the missing experience.

    Treat disclosure as part of the answer

    Including your own product in a comparison is not the same as presenting the comparison as independent. Put the relationship where a reader will encounter it before relying on the ranking. A disclosure buried after the recommendations does not help someone interpret the claims that came first.

    The legal exposure deserves separate attention. The FTC’s Consumer Review Rule, 16 CFR Part 465, took effect in October 2024 and prohibits deceptive practices involving reviews and testimonials, including presenting company-controlled material as independent, reviewing products that were not actually used, and attributing reviews to people who did not write them. Penalties can reach $53,088 per violation.

    These are editorial risk controls, not a legal opinion about your page. If you publish testimonials, comparative scores, endorsements, or rankings involving your own product, have qualified counsel assess the specific presentation and relationships. Do that before scaling the template across many URLs, because repeating the same defect multiplies the exposure.

    Build a human-led workflow around verifiable claims

    AI is valuable when its role is explicit. Among 224 SEO professionals surveyed, 87% retained substantial human involvement and 64% used a human-led, AI-assisted process. Speed was the main benefit for 73%, while only 19% credited AI with improving quality. That gap is the operating principle: automation can accelerate production, but your workflow must create quality somewhere else.

    A reliable process separates transformation from judgment:

    1. Write the reader’s decision first. Complete this sentence before drafting: "After reading this page, the reader should be able to decide whether…" If you cannot finish it precisely, the page does not yet have a useful purpose.
    2. Create a claim ledger. For every important assertion, record the proposed wording, supporting evidence, applicable limit, commercial relationship, and person responsible for verification. Unsupported claims should not enter the prompt as facts.
    3. Give AI a closed evidence set. Ask it to organize only the material you supply, preserve uncertainty, mark missing support, and avoid inventing experience. This makes omissions visible instead of allowing fluent filler to hide them.
    4. Add the human decision layer. A subject-matter editor chooses which evidence matters, resolves conflicts, defines tradeoffs, and decides when no recommendation is justified. These are editorial decisions, not sentence-generation tasks.
    5. Run an adversarial review. Challenge every superlative, score, testimonial, first-person experience claim, and statement about a competitor. Ask what proof would be required if the affected company or customer disputed it.
    6. Edit for direct retrieval. Give each section one clear job, answer its heading promptly, name the entity being discussed, and keep conditions next to the claims they qualify. This improves comprehension for readers and reduces the chance that an answer system extracts an unqualified statement.
    7. Approve facts separately from prose. A smooth final edit can introduce errors by changing scope or certainty. Recheck names, figures, dates, links, disclosures, and recommendation conditions after the prose is polished.

    Within this process, AI can reorganize notes, propose outlines, identify repetition, generate alternative explanations, and convert approved information into another format. It should not manufacture a test, infer customer sentiment, create a score, or turn a product relationship into an independent recommendation.

    Structured data comes after the editorial work. JSON-LD can clarify the entities and content already visible on the page, but it cannot supply missing evidence or convert an opinion into a verified fact. Keep markup aligned with the visible wording, authorship, review status, and relationships. A technically valid schema implementation attached to a misleading page only makes the underlying claim more structured.

    Audit existing AI content by risk, not detector score

    Do not mass-delete pages because a detector labels them as AI-generated. Detector classifications are uncertain, and deleting a useful URL can discard rankings, links, internal pathways, and conversion history without fixing the actual editorial weakness.

    Start with pages where quality and commercial risk overlap:

    • "Best," "top," and comparison pages that rank your product first.
    • Reviews of products your team cannot show it used or tested.
    • Pages with numerical or categorical scores but no reproducible method.
    • Testimonials whose author, wording, permission, or origin cannot be verified.
    • Templates that repeat the same recommendation across many queries with only nouns changed.
    • Pages where citations exist but do not support the sentence beside them.

    Choose a page-level action

    • Keep: The page answers a real decision, supports its claims, discloses relevant relationships, and contributes useful judgment. Improve clarity without rewriting it merely to change an AI score.
    • Rebuild: The topic is valuable, but the evaluation lacks evidence. Obtain the missing evidence, revise the method, and have a human editor make the recommendation again.
    • Reframe: The factual material is sound, but the page implies testing that did not happen. Convert it into a documented feature comparison, directory, or selection checklist and remove review language.
    • Retire or consolidate: The page adds no unique decision support and duplicates a stronger URL. Check traffic, backlinks, internal links, and business value before changing the URL or status.

    If a page contains potentially fabricated reviews, false firsthand claims, or undisclosed company-controlled recommendations, remove the questionable claims from public view and involve counsel. That is different from a routine quality refresh and should not wait for the next editorial cycle.

    Use a stop-ship publication gate

    Do not publish when any of these statements is true:

    • The page claims firsthand use, but nobody can identify who used the product or what was done.
    • A score cannot be reproduced from the stated criteria and evidence.
    • Your own product wins, but ownership or another material relationship is not clear before the recommendation.
    • A testimonial cannot be matched to the person and words behind it.
    • A consequential factual claim has no support, or its citation supports a narrower claim than the prose makes.
    • The draft hides uncertainty by converting "may," "for this use case," or "based on documented features" into an absolute conclusion.

    Once those failures are cleared, improve usefulness. Put the direct answer near the question it resolves. Separate observed facts from editorial judgment. Include the condition that would change the recommendation. Remove paragraphs that merely restate the keyword. Make every heading earn its place by helping the reader do, decide, or notice something distinct.

    Key takeaways

    • Do not treat an AI detector result as a Google ranking verdict; use evidence, decision value, and editorial accountability as the quality test.
    • Use AI to transform approved material and accelerate production, while people retain responsibility for truth, tradeoffs, recommendations, and publication.
    • Do not imply independent testing, customer experience, or objective scoring unless you can prove it and disclose relevant commercial relationships.
    • Define who a recommendation is for and what would change it; conditional advice is more defensible and more useful than an unsupported universal winner.
    • Audit high-risk comparison and review pages first, then rebuild, reframe, or retire each URL according to its evidence and unique value.
    • Add schema only after the visible content is accurate; structured data can describe a claim, but it cannot make the claim true.

    Choose one commercially important AI-assisted page and build its claim ledger before touching the prose. Remove anything you cannot support, expose the method and relationships, and let a human editor make the final recommendation. That single page will give you a reusable quality standard for every brief, prompt, comparison, and schema deployment that follows.

    References

  • How to Build AI Search Visibility With Answer-First Content

    How to Build AI Search Visibility With Answer-First Content

    If your pages rank but your brand rarely appears in AI-generated answers, publishing more content can multiply the same problem. First find the break: can the system access your page, retrieve the right passage, reuse that passage without repairing it, and connect the claim to you?

    The practical goal is not to make your writing sound machine-generated. It is to make useful knowledge easy to find, extract, understand, trust, and attribute while keeping the page genuinely useful to the person who lands on it.

    AI visibility depends on four separate gates

    A document passes through an access portal, a retrieval lens, an extraction frame, and a source-attribution junction.

    Answer engine optimization, or AEO, is the practice of making information usable inside generated answers. AI search visibility is the outcome: your organization, experts, pages, or ideas appear when an answer engine responds to a relevant question.

    That outcome is not controlled by a single optimization. AI systems can retrieve a passage without treating the whole page as one indivisible result. A technically healthy page can therefore remain invisible if its useful answer is buried, vague, or difficult to attribute.

    • Access: The system must be allowed and able to reach the page. Crawl rules, indexing controls, rendering, canonicalization, and page availability belong here.
    • Retrieval: A passage must clearly match the question. Descriptive headings, explicit terminology, and focused sections help the right material get selected.
    • Reuse: The selected passage must answer the question cleanly. If it depends on missing context or requires substantial rewriting, it is a weak answer candidate.
    • Attribution: The system must be able to associate the information with a recognizable brand, author, dataset, framework, or other entity.

    These gates give you a useful diagnostic sequence. If a page cannot be accessed, rewriting its introduction will not help. If a passage is accessible but says nothing until its fifth paragraph, adding more schema will not solve the retrieval problem. If a useful passage could have been written by any competitor, it gives an answer engine little reason to name you.

    Key takeaways

    • Optimize complete answer passages, not just whole pages.
    • Put the direct answer immediately below the heading that states the question or task.
    • Use structured data to clarify accurate page facts, not to compensate for thin or ambiguous content.
    • Build consistent associations between your entity, its experts, and the topics they can credibly address.
    • Measure access, retrieval, reuse, and attribution separately so you know what to fix.

    Turn each important question into a standalone answer passage

    A page can cover the right topic and still contain no passage that directly resolves the reader’s question. This often happens when an introduction delays the answer, several sections repeat the same background, or a heading uses a clever label that does not reveal what follows.

    Build each important section as an answer unit. It should make sense when separated from the title, introduction, navigation, and surrounding paragraphs. That does not mean every section must be short. It means the section should identify its subject, answer its assigned question, and explain any necessary limits without forcing the reader to reconstruct context.

    Use this answer-unit workflow

    1. Assign one clear question. Write down the exact question the section must resolve. Split sections that attempt to answer unrelated questions.
    2. State the answer first. Make the opening sentence useful on its own. Put qualifications in the same passage rather than hiding them elsewhere.
    3. Explain the mechanism. Tell the reader why the answer is true, what makes it work, or where it stops applying.
    4. Add a decision or action. Give the reader a check, choice, sequence, or correction they can apply.
    5. Make the subject explicit. Replace vague references such as “this,” “it,” or “that approach” when the missing noun would make an extracted passage ambiguous.
    6. Add distinct value. Include an original definition, framework, dataset, expert interpretation, or unusually precise boundary when you can support it.

    Consider a section headed “Why it matters” that opens with: “This makes the process more effective and improves visibility.” A human who has read the previous section may infer the meaning. An isolated passage cannot. The heading does not name the subject, and the sentence does not identify the process, mechanism, or outcome.

    A stronger version would use the heading “Why answer-first passages improve AI retrieval” and open with: “Answer-first passages improve AI retrieval because the question, subject, and usable response appear in one self-contained section.” The next paragraph can add nuance, examples, and limitations. The direct answer has already done its job.

    Distinct framing helps with attribution, but do not confuse distinctiveness with invented jargon. Renaming a familiar checklist does not create authority. A useful framework separates a messy problem into decisions the reader could not make as easily before. Name it only if the name makes that reasoning easier to remember and reference.

    Run the isolation test during editing

    Copy a candidate section into a blank document without its page title or preceding text. Then ask:

    • Can you identify the exact subject from the heading and opening sentence?
    • Does the passage answer a real question before expanding on it?
    • Are important qualifications present in the same section?
    • Would a quotation preserve the original meaning?
    • Is there a specific reason to associate the passage with your organization or expert?

    If the section fails, repair the passage before adding more copy to the page. This editing method follows the underlying shift toward modular, answer-first content with clear structural signals.

    Keep technical SEO and structured data in their proper roles

    AEO adds a retrieval and attribution layer; it does not replace technical SEO. A blocked, unavailable, insecure, or badly implemented page gives every downstream system less to work with. At the same time, technical compliance alone is not differentiation.

    HTTPS appears on more than 91% of pages, while title-tag adoption is close to 99%. Those figures show how thoroughly basic practices have become embedded in platforms, content management systems, and plugins. They also explain why merely having a title tag or secure connection is not an AI visibility strategy. These are prerequisites that protect the opportunity to compete.

    Audit the foundation before changing the prose

    • Access and indexing: Confirm that the intended canonical page is reachable, indexable where appropriate, and not contradicted by template-level controls.
    • Titles and headings: Give the page a descriptive title and use headings that identify the actual question, entity, comparison, process, or decision in each section.
    • Crawl policy: Review robots.txt as a publishing-policy decision. Make crawler access intentional instead of inheriting a default that no one has checked.
    • Structured data: Ensure every declared fact agrees with the visible page. Names, descriptions, relationships, authorship, and other identifiers should not conflict across templates.
    • Rendered output: Check the final HTML, not only the editor. A plugin setting is not proof that the intended markup, heading hierarchy, or metadata reached the published page.

    JSON-LD can clarify what a page describes and how its entities relate. It cannot manufacture expertise, repair an unclear answer, or guarantee inclusion in an AI response. Treat it as a factual declaration layer: the markup should describe the page that exists, using values you can keep consistent and maintain.

    FAQPage markup deserves the same discipline. Its continued use despite Google limiting FAQ snippets points to a broader reason for structured data: explicit machine-readable context can remain useful even when a particular visual search feature is unavailable. Use FAQPage only when the visible page contains genuine questions and answers. Do not add repetitive FAQs merely to create more markup.

    Apply similar restraint to llms.txt. Adoption has been cautious, so it should not displace crawlability, clear content, accurate structured data, or entity work. You can evaluate it as an additional publishing signal, but do not treat the file as a universal inclusion switch. By contrast, robots.txt already has a practical policy role and deserves a deliberate review.

    Make your entity recognizable and your knowledge worth citing

    A complete content block is retrieved from fragmented material and linked through a glowing line to a distinct source entity.

    Extraction gets your words into consideration. Attribution gives the system a reason to connect those words to you. That connection becomes easier when your owned pages describe the same organization, experts, topics, and claims consistently.

    Backlinks still matter, but AEO authority also involves brand mentions, citations, and clear associations between an entity and its areas of expertise. A mention does not guarantee a citation, and repetition does not make an unsupported claim true. The useful objective is credible corroboration: relevant publishers and experts repeatedly associate your entity with information it is qualified to provide.

    Create an internal entity brief

    Before you try to earn external recognition, make your own representation coherent. Maintain a brief that records:

    • The exact organization name and a plain description of what it does.
    • The audience it serves and the topics it can credibly address.
    • The names, roles, and relevant credentials of contributing experts.
    • The principal pages that define the organization, people, services, research, and terminology.
    • The original frameworks, datasets, benchmarks, or recurring claims the organization owns.
    • The preferred language for relationships that are often described inconsistently.

    Use the brief as a consistency check, not as a script to paste everywhere. About pages, author profiles, editorial pages, structured data, media biographies, and contributed commentary should agree on factual identity while fitting their individual contexts.

    Publish assets other people have a reason to reference

    Generic opinion posts rarely create a strong attribution hook because another publisher can replace them without losing information. Reference-grade assets are harder to substitute. Suitable formats include original research, industry benchmarks, visual explainers, definitive resources, and glossaries.

    Choose the format after identifying the evidence you actually possess. If you have original data, publish the method, definitions, limitations, and findings clearly enough for someone to cite the result accurately. If your advantage is practitioner expertise, answer a narrow question with named expert input and explicit reasoning. If the market suffers from inconsistent terminology, build a glossary that defines boundaries instead of recycling dictionary-level descriptions.

    Then distribute the asset to people who already cover the subject. A workable outreach sequence is:

    1. Identify a narrow question journalists, analysts, creators, or industry writers repeatedly need to answer.
    2. Produce a citable asset that resolves that question with evidence or qualified expertise.
    3. List the people and publications for whom the finding is genuinely relevant.
    4. Pitch the usable finding, definition, or visual rather than asking for a generic mention.
    5. Keep the asset accurate so future citations do not point to stale or contradictory information.

    Do not make every sentence a brand claim. Put the entity name where attribution matters: beside an original definition, owned methodology, expert interpretation, or dataset. Natural, precise attribution is stronger than repeating the brand in passages where it adds no meaning.

    Measure the query, passage, citation, and next action

    Conventional rank tracking cannot tell you why an answer system omitted your brand. Build a fixed query set from real customer questions, category questions, comparisons, definitions, and decision-stage concerns. Keep the wording and tested surface recorded so later checks are comparable.

    For each query, capture:

    • Whether an AI-generated answer appeared.
    • Whether your brand or expert was named.
    • Whether your page was cited or linked.
    • Which passage, claim, or asset appeared to support the response.
    • Which competing entities were repeatedly named or cited.
    • Whether the answer represented your position accurately.
    • What changed after a content, technical, entity, or distribution update.

    Do not compress those observations into one visibility score before diagnosing the failure. The visible symptom should determine your next check.

    What you observeLikely gateWhat to inspect next
    The relevant page cannot be found or reachedAccessCrawl policy, indexing controls, canonical target, rendered output, and page availability
    The page is available, but another passage answers the queryRetrievalHeading specificity, question alignment, terminology, and section focus
    The right section is found, but it is not used cleanlyReuseOpening answer, missing context, vague pronouns, qualifications, and passage completeness
    Your information appears without your brand or expertAttributionEntity naming, authorship, original value, external mentions, and citation-worthy assets
    Your brand is named inaccurately or for the wrong topicEntity consistencyConflicting descriptions, outdated profiles, ambiguous relationships, and unsupported topic associations

    This approach also prevents false wins. A cited page is not useful if the answer misstates your position. A brand mention for an irrelevant topic does not strengthen the association you need. A technically perfect page is not finished if it contains no extractable answer. Record the outcome at the same level at which you intend to improve it.

    Start with the highest-value question your audience asks. Trace it through the four gates, repair the first failure you find, and make that page the pattern for the rest of your library. AI search visibility becomes manageable when you stop treating it as one mysterious ranking and start treating it as a chain of observable decisions.

    References

  • How to Build an AI-Era SEO Stack That Improves Visibility

    How to Build an AI-Era SEO Stack That Improves Visibility

    You are probably not short of AI SEO tools to evaluate. The harder problem is deciding which ones deserve a place in your stack when several products generate briefs, audit pages, track prompts, suggest schema, and summarize reports in slightly different ways.

    The answer is not to buy the platform with the longest AI feature list. Build a system in which every tool produces evidence, that evidence leads to a named decision, and a person verifies the result before it changes a page. That gives you a stack that can support conventional search, answer engines, and generative search without paying for three versions of the same dashboard.

    Choose tools by the decision they improve

    Tool consolidation and AI adoption are happening at the same time. In the 2025 MarTech Replacement Survey’s cohort of 154 marketers who had replaced an application in the preceding year, 43.8% cited cost reduction, while 37.1% considered AI capabilities crucial and 33.9% wanted AI features in a new tool. Those figures describe one survey cohort, not the entire market, but they expose the decision most SEO teams now face: add AI capability without adding another layer of overlapping cost.

    Start by inventorying decisions rather than products. Your working stack needs to cover these jobs:

    • Technical discovery: identify crawling, indexing, rendering, internal-linking, response-code, and metadata problems that block or weaken discovery.
    • Demand and intent: connect queries and audience questions to the page that should answer them.
    • Content evaluation: find omissions, ambiguity, outdated information, weak evidence, and intent mismatches.
    • Entity and structured-data management: make the people, organizations, products, topics, and relationships on a page explicit and internally consistent.
    • Search and AI visibility monitoring: record rankings, impressions, mentions, linked citations, cited URLs, and the accuracy of generated descriptions.
    • Workflow and reporting: turn findings into tickets, briefs, annotations, summaries, and accountable next actions.

    One platform may cover several jobs. That is useful only when the outputs remain specific enough to act on. A single interface filled with generic scores is not an integrated stack; it is a consolidated reporting problem.

    Use a keep, replace, remove, or build audit

    Assign every current tool to one of four buckets:

    • Keep it when it produces evidence you use, fits the workflow, and has a clear owner.
    • Replace it when an important requirement is missing, the data cannot be exported, or another product can remove genuine duplication.
    • Remove it when nobody can name a recent decision that changed because of its output.
    • Build a narrow utility when your process, data model, or reporting logic is genuinely specific to your business.

    For each product, complete this sentence: “When the tool shows ______, the owner does ______, and success is checked with ______.” A blank in any position reveals the real gap. You may have a data problem, an ownership problem, or a validation problem rather than a software problem.

    Do not accept “AI-powered” as a requirement. Translate it into an observable capability. For example: classify a crawl export by likely impact; preserve citations when summarizing evidence; identify the URL cited in an answer; generate JSON-LD from approved fields; or turn approved metrics into a report narrative without changing the underlying numbers.

    Custom software has become more plausible for these narrow jobs. Homegrown applications accounted for 8.1% of replacements in the 2025 survey, up from 3.4% in 2024. That is evidence of renewed interest, not proof that building is automatically cheaper. Buy common infrastructure such as crawling when a mature product already solves the problem. Consider building the small connector, classification rule, or reporting layer that reflects how your organization actually works.

    Make vendors demonstrate the evidence trail

    A useful evaluation should begin with your data and end with your decision. Give each shortlisted tool the same representative input, then inspect the complete path from evidence to recommendation.

    • Can you see the page, query, answer, citation, crawl row, or measurement behind a recommendation?
    • Can you export the raw evidence and the processed result in a usable format?
    • Can you distinguish observed facts from the tool’s interpretation?
    • Can you segment results by page type, intent, market, language, or another dimension that matters to your decisions?
    • Can a reviewer correct the output without rebuilding the workflow outside the product?
    • Can you connect the finding to an owner, ticket, brief, or content update?
    • Does the tool replace an existing cost, or does it merely add a new dashboard?

    If a vendor can show a polished recommendation but not the evidence behind it, treat the output as a hypothesis. That distinction matters more in AI search because an answer can change across prompts and contexts. A tool that preserves the prompt, response, cited URL, date, and evaluation conditions gives you something you can audit. A visibility score without those components is much harder to interpret.

    Put AI on high-friction work, not final judgment

    AI earns its place in an SEO workflow when it reduces the effort between raw input and a reviewable result. It should not quietly become the authority that decides whether a claim is true, a page satisfies intent, or code is safe to deploy.

    Use a repeatable prompt specification rather than an improvised request. Give the model the page’s purpose, audience, target query or task, approved evidence, constraints, required output format, and review criteria. Tell it how to mark uncertainty and what it must not invent. The last instruction is especially important when the input does not contain enough evidence to complete every field.

    Accelerate content work without outsourcing expertise

    Several practical AI-assisted SEO workflows share the same pattern: the model creates options or performs a first pass, while a person supplies expertise and approves what gets published.

    • First drafts: provide a real brief, audience, intended angle, target query, source material, and exclusions. Ask for a structure before a full draft. The editor must then add original reasoning, examples supported by evidence, and the publication’s voice.
    • Content refreshes: give the model the existing page, its target intent, performance context, and current approved facts. Ask it to separate missing coverage, stale material, unsupported claims, structural problems, and optional expansion ideas. Verify each proposed change rather than accepting a rewritten page wholesale.
    • Titles and descriptions: generate variations within your supplied constraints, then choose or combine them manually. Check that each option accurately describes the page; an enticing promise that the page does not fulfill is not optimization.
    • FAQ development: use AI to organize questions found in query research and audience conversations. Remove duplicates, verify that each question belongs on the page, and write answers from approved evidence. Do not manufacture an FAQ merely to create schema.
    • Alt text: supply the image and its function in the surrounding page, not just a filename. Review the result for accessibility and accuracy. A target keyword belongs only when it naturally helps describe the image.

    The quality check is simple: can the reviewer identify what was supplied by the evidence, what was inferred by the model, and what was added by an expert? If those layers are blended together, the workflow is too opaque for reliable publishing.

    Use AI as a technical interpreter and code assistant

    Technical SEO often contains small, high-friction tasks that suit supervised generation:

    • Translate an error message or log excerpt into plain language, possible causes, evidence needed, and reversible diagnostic steps.
    • Generate a regular expression for a clearly described Google Search Console filter, then test it against examples that should and should not match.
    • Classify a crawl export into issue types and propose an order of investigation, while preserving the original rows used for each recommendation.
    • Generate JSON-LD from approved page facts and a named schema type, then compare every value with the visible page before validation.

    AI-generated code can be syntactically tidy and still be wrong. Test regular expressions on a limited dataset. Validate structured data before deployment. Treat suggested fixes to templates, redirects, canonical tags, robots directives, or rendering behavior as code changes that require review and a rollback path.

    Separate reporting observations from explanations

    AI can help scan performance exports for anomalies, compress a long report into an executive summary, or draft the narrative connecting several approved metrics. The model should never be allowed to turn correlation into a confident cause.

    Require reporting output in four labeled parts:

    • Observation: what changed in the supplied data.
    • Possible explanations: hypotheses that could account for the change.
    • Evidence still needed: data required to distinguish those explanations.
    • Next action: the check, experiment, or decision an owner should make.

    This structure makes AI useful without hiding uncertainty. It also creates prompts worth saving. A maintained prompt library for recurring briefs, crawl analysis, metadata, reporting, and schema tasks is more valuable than repeatedly improvising requests, because the inputs, constraints, and review standard become part of the operating process.

    Optimize pages for retrieval, comprehension, and citation

    A modular webpage with organized content and source cards is scanned, and one relevant passage is retrieved into an answer sphere.

    An AI visibility tool cannot compensate for a page that is inaccessible, unfocused, internally inconsistent, or difficult to support with a citation. Conventional SEO remains the retrieval layer. Answer engine optimization and generative engine optimization add a comprehension and representation layer on top of it.

    Build each important page around a clear evidence path:

    1. Assign one dominant intent. Decide which real question, comparison, task, or decision the page should resolve.
    2. State the direct answer early. Do not make a reader or retrieval system work through several paragraphs before discovering the page’s position.
    3. Break complex material into answerable units. Use descriptive headings, a direct explanation, applicable conditions, necessary caveats, and the supporting detail needed to act.
    4. Keep entity names and attributes consistent. A product, organization, person, date, or feature should not acquire different names or conflicting descriptions across the title, body, metadata, structured data, and linked pages.
    5. Support important claims where they appear. Link the words carrying the fact, and distinguish evidence from your interpretation.
    6. Connect related pages deliberately. Internal links should tell a reader what the destination adds, not rely on vague anchor text.
    7. Confirm technical availability. The intended canonical page must be crawlable, indexable where appropriate, renderable, and free from contradictory directives.

    This approach also makes editorial review easier. A reviewer can inspect one answer unit at a time and ask whether it is clear, supported, current, and useful. That is a better quality control mechanism than chasing an aggregate optimization score.

    Treat schema as a translation layer, not a ranking switch

    Structured data gives machines explicit labels for information that may otherwise be expressed only in prose. It can clarify what a page and its entities represent, but it does not repair weak content, establish that an unsupported claim is true, or guarantee a citation in an AI answer.

    Use this schema workflow:

    1. Extract the facts that are visibly present on the page.
    2. Select a schema type that accurately represents that page, such as Article for an editorial page or FAQ when genuine questions and answers appear in the visible content.
    3. Generate or author the JSON-LD from those approved facts.
    4. Compare every populated property with the visible page, including names, descriptions, dates, relationships, and URLs.
    5. Validate the markup. AI can generate Article or FAQ JSON-LD quickly, but the resulting code should still be checked with Google’s Rich Results Test where applicable.
    6. Publish through a controlled template or field mapping so later page edits do not leave stale values in the markup.
    7. Recheck the rendered page and structured data after deployment.

    Validation proves that a parser can understand the code and may surface eligibility issues. It does not prove that the data is accurate, that a search feature will appear, or that a language model will cite the page. Those remain separate checks.

    Schema also should not become an isolated technical project. AI-search strategy increasingly connects technical foundations, content, social activity, public relations, mentions, and citations. The practical lesson is not that every channel needs another tool. It is that your content and reporting systems need a shared view of the entities, claims, questions, and pages the organization wants to be known for.

    Measure AI visibility without disguising it as rank tracking

    An analyst compares how identical glowing inputs produce different webpage fragments and citation markers across several answer portals.

    Rank tracking records an ordered search result under defined conditions. AI answer monitoring records a generated response that may vary with wording, context, system behavior, market, and time. Putting both into one visibility score may be convenient, but it can hide what actually changed.

    Keep the layers separate in your scorecard:

    Measurement layerRecordDecision it supports
    Technical availabilityCrawl state, indexability, canonical target, rendering result, structured-data validityWhether the page can participate as intended
    Conventional searchQuery, landing page, impressions, clicks, position context, conversion outcomeWhere discoverability or intent alignment needs work
    Generated answersExact prompt, engine, date, answer, brand mention, linked citation, cited URL, factual accuracyWhether the brand is represented, supported, and described correctly
    Content operationsAI-assisted task, reviewer changes, rejection reason, approved output, workflow ownerWhere automation saves effort or creates rework
    Stack economicsLicense cost, active use, duplicated output, integration burden, maintenance ownerWhether to keep, replace, remove, or build

    Clicks remain useful, but they cannot describe every zero-click or AI-generated experience. That is one reason teams now seek tools that can measure visibility beyond traditional rankings and clicks. Do not solve that limitation by treating every brand mention as equivalent. An unlinked mention, a citation to your page, a citation to someone else’s page, and an inaccurate description are four different outcomes.

    Create a repeatable AI-answer benchmark

    Build the benchmark from questions that matter to the business, not prompts chosen because the brand already performs well. Include the informational questions, comparisons, objections, and decision-stage tasks that your priority pages are meant to resolve.

    1. Freeze the wording of each benchmark prompt and document its intended user intent.
    2. Record the engine, market or language conditions, date, complete response, citations, and cited URLs.
    3. Capture a baseline before changing content, templates, structured data, internal links, or external promotion.
    4. Change a single meaningful variable where the workflow allows it, and annotate every other known change.
    5. Run the same benchmark on a planned cadence rather than testing only when you expect a favorable answer.
    6. Look for repeated patterns across relevant prompts before claiming that an optimization caused the outcome.

    A mention is not automatically a success. Review whether the answer gives the correct name, category, attributes, limitations, and relationship to the user’s question. Also record which URL earned the citation. If an outdated page or a third-party page is repeatedly cited, that finding should lead to a different action than a simple absence from the answer.

    Measurement should also expose automation failures. Record which AI suggestions were rejected and why. Repeated factual corrections point to an evidence or prompting problem. Repeated voice corrections point to an editorial specification problem. Repeated technical corrections point to a workflow that needs stronger tests, not a model that needs more freedom.

    Key takeaways and your first move

    • Choose an AI SEO tool only when you can name the decision it improves, the evidence it preserves, the owner who acts, and the way the result will be checked.
    • Keep conventional crawling, indexing, intent, and content quality at the base of the stack. AI visibility monitoring adds a measurement layer; it does not replace the retrieval layer.
    • Use AI for first passes, classification, variants, interpretation, and formatting. Keep factual approval, strategic judgment, and deployment control with a qualified reviewer.
    • Make pages easier to retrieve and cite by answering a defined question, using consistent entities, supporting claims in place, and connecting related pages clearly.
    • Use schema only when it matches visible content. Validate the code and verify the facts separately.
    • Track generated answers with their exact prompts, citations, cited URLs, conditions, and accuracy. Do not compress unlike outcomes into one unexplained visibility score.

    Your first move does not require a new subscription. Open the current stack inventory and complete the evidence-action-validation sentence for every tool. Remove the entries nobody can complete. Then choose one recurring workflow with visible friction, such as turning a crawl export into reviewed tickets or turning an approved brief into a review-ready draft. Define its inputs, output, owner, and checks before testing automation.

    Once that workflow is reliable, extend the same operating model to structured data and AI-answer monitoring. You will know what to buy because the missing capability will be explicit, and you will know whether it worked because the evidence trail already exists.

    References


  • Local Discovery Across Google and ChatGPT: A Practical Plan

    Local Discovery Across Google and ChatGPT: A Practical Plan

    A customer who searches Google for a nearby provider and another who asks ChatGPT for a local recommendation may want the same outcome, but they reach it through different discovery systems. If you optimize only for the map pack or only for conversational answers, your business can be easy to find in one place and absent in the other.

    Your job is to establish one dependable record of each location, then present and measure that record appropriately on each surface. That means treating your Google Business Profile, location page, visible business facts and structured data as one system without pretending Google and ChatGPT have the same ranking model.

    Google and ChatGPT answer different versions of a local question

    Google local discovery is strongly tied to explicit profile fields and geography. Your business name, primary category, secondary categories, services, reviews, linked landing page and physical proximity can all shape where the business appears. A geo-grid can show that visibility changing from one neighborhood or city boundary to the next.

    ChatGPT handles the discovery moment as a conversation. The user can describe a service, constraint and area in ordinary language, and shared location can make the local response more precise. Location is therefore a meaningful input, but that does not establish a permanent ChatGPT rank comparable to a map-pack position.

    This distinction changes how you work. Measure Google across physical points on a grid. Evaluate ChatGPT with repeatable prompts and controlled location context. A strong result on either surface is useful, but it cannot serve as a proxy for the other.

    Key takeaways

    • Build a single, accurate location record before optimizing individual discovery surfaces.
    • Audit Google Business Profile signals against the businesses that actually rank in your local grid, not against generic benchmarks.
    • Use a dedicated page for each real location and align it with the profile that links to it.
    • Keep LocalBusiness structured data consistent with facts a visitor can see on the page.
    • Test ChatGPT with fixed prompts and compare responses with and without shared location when that option is available.
    • Treat proximity limits and conversational omissions as different problems requiring different fixes.

    Start with a five-part Google Business Profile audit

    A business owner uses a tablet while five icon-based checkpoints surround a neighborhood storefront, including a map pin, clock, phone, category symbol, and rating stars.

    A profile audit becomes useful when it explains a visibility gap. Begin with the competitors appearing for the same commercial query in the areas you want to reach. Their lifetime review totals may look impressive, but totals alone do not tell you which signals separate the current winners.

    1. Compare review recency and velocity. Look at how frequently leading competitors have earned reviews recently, not just how many they have accumulated. Fresh and consistent review activity can matter more than a large historical total. There is no universal target in this evidence, so derive your benchmark from the listings winning your own searches. Places Scout or Whitespark geo-grid data can help you connect review patterns with visibility. If you manage many markets, Places Scout API data can turn that comparison into a recurring monitor.
    2. Verify the business name. A relevant keyword in a legitimate business name can have an outsized effect on local visibility. Do not add a service or city merely as a profile tactic when it is not part of the documented name. A DBA may make a name change legitimate, but it also creates legal, administrative and brand consequences. Treat it as a business decision, not a metadata shortcut.
    3. Inspect the primary category first. The primary category can substantially influence local ranking. Compare the primary categories used by top businesses for the query you care about, then choose the closest truthful description of your core offering. Add relevant secondary categories and review the available service selections, but do not dilute the profile with categories the location cannot support.
    4. Evaluate the linked landing page. A generic homepage forces both customers and machines to work out which location, service and contact details apply. A dedicated, keyword-focused location page can create better alignment between the profile and its destination. Check that the page identifies the same business, location and services as the profile.
    5. Map the proximity ceiling. Visibility often contracts as the search point moves away from the location or crosses a city boundary. A ranking-radius view helps you distinguish an optimization problem from a geographic limitation. Local Falcon’s Share of Local Voice can help show the realistic reach of a location. If the business is strong nearby and consistently weak farther away, more profile edits may not solve the actual constraint.

    Complete the audit before changing fields. Otherwise, a category edit, review campaign and page rewrite can overlap, leaving you unable to tell which change helped or hurt. Record the starting grid, profile configuration, linked page and recent review pattern, then make the change supported by the clearest gap.

    Turn each location page into a reliable entity record

    The page linked from your profile should resolve local uncertainty quickly. A visitor should not have to infer whether the location offers the requested service, whether it serves the relevant area or how to contact it. The same clarity also gives parsers less ambiguity to reconcile.

    Make the visible page complete before adding schema

    • Identify the business and location in the opening copy using the same legitimate name shown on the profile.
    • Describe the primary services in plain language and keep them aligned with the profile’s categories and service selections.
    • Show the applicable address, service area, telephone number, opening hours and contact path.
    • Explain meaningful local constraints such as appointment coverage, access, service boundaries or location-specific availability.
    • Address the questions that determine whether a nearby customer is a fit instead of filling the page with interchangeable city-name paragraphs.
    • Link the corresponding Google Business Profile directly to this location page rather than sending every profile to the homepage.

    If you operate multiple locations, give each real location its own URL and its own accurate details. Do not manufacture local relevance with addresses, service areas or location pages that do not represent an operating business. Besides misleading the reader, false location claims make your first-party record harder to keep consistent.

    Use LocalBusiness JSON-LD to describe, not embellish

    Choose the most specific LocalBusiness subtype that truthfully describes the location. Give the entity a stable @id and include relevant properties such as name, URL, telephone, address and openingHoursSpecification when those facts apply. Each physical location should have its own URL, identifier and location-specific values.

    The markup should agree with the page and profile. Do not put a different name in JSON-LD, mark up an address the visitor cannot find, or use areaServed to claim places the business does not genuinely serve. Validate the syntax before deployment, then verify the rendered page still exposes the underlying facts to a human reader.

    Structured data is useful for explicit entity description, but it is not a substitute for the profile, reviews, landing-page content or physical relevance. It also should not be treated as a guaranteed switch for ChatGPT inclusion. Its immediate job is simpler: prevent your own publishing stack from telling conflicting stories about the business.

    Measure Google visibility and ChatGPT answers in separate loops

    Two separate circular icon loops for map search and conversational recommendations connect to the same miniature storefront.

    Use a geo-grid to diagnose Google

    Run the same commercially meaningful query from fixed points around the location. Record where the business appears, where visibility fades and which competitors replace it. Mark city borders and meaningful neighborhood changes on the grid so that a geographic pattern does not get misread as a page problem.

    Then compare the profile variables that can explain the pattern: recent review activity, primary and secondary categories, selected services, business name and landing-page alignment. If visibility is weak even close to the location, begin with those controllable signals. If it is strong nearby and falls away predictably, revise the target area or query expectations before considering another location. A new location should exist because demand and operations justify it, not merely to color more grid points.

    Use a prompt set to diagnose ChatGPT

    Build prompts from real customer decisions rather than from your brand name. Include requests for a provider offering a specific service near a named place, requests with a meaningful constraint and broader nearby requests that depend on the user’s location.

    • Keep the wording fixed when comparing results.
    • When location sharing is available, run the same local request with location shared and not shared.
    • Record whether the business appears, what reason is given, which business facts are used and which links or citations are shown, if any.
    • Flag incorrect names, services, locations and hours separately from a complete omission.
    • Retest under the same conditions after a meaningful profile, page or data correction.

    A single conversational response is an observation, not a stable ranking report. Look for repeated patterns across the intents that matter. If the system describes the business incorrectly, inspect your visible location page, profile and structured data for conflicts. If the facts are correct but the business is not mentioned, improve the page’s explanation of who the location serves and which needs it can meet; do not randomly rewrite the profile in response to one answer.

    What you observeLikely constraint to investigateBest next move
    Google visibility is weak across the grid, including near the locationProfile relevance, review activity or landing-page alignmentRun the complete profile audit and correct the clearest competitor gap
    Google is strong nearby but fades near borders or outer neighborhoodsProximity and city geographyTarget areas where the location can compete and reconsider unrealistic radius expectations
    Google is strong but ChatGPT rarely mentions the businessConversational fit or unclear first-party informationTest actual customer prompts and make services, location and constraints explicit on the page
    ChatGPT mentions the business with incorrect factsAmbiguous, incomplete or conflicting location dataCorrect the visible page, profile and JSON-LD, then retest the same prompt
    ChatGPT mentions the business but Google is weakGoogle-specific profile or proximity signalsUse the geo-grid to separate an optimization gap from a geographic ceiling

    Begin with a baseline, then choose the mismatch supported by the clearest evidence. If the Google grid collapses at a city boundary, stop expecting a title edit to erase geography. If ChatGPT gets a service wrong, correct the underlying fact before chasing mentions. If the profile is weak close to the location, audit categories, reviews and the linked page first. Fix the smallest defensible problem, rerun the same test and keep the two measurement loops separate.

    References