Tag: Commerce

  • JavaScript SEO for Ecommerce: A Practical Build Standard

    JavaScript SEO for Ecommerce: A Practical Build Standard

    Your storefront can look complete in a browser while sending a nearly empty page to crawlers. The failure usually sits in the handoff: the server returns a shell, then JavaScript fetches the product content, navigation, filter state or structured data. If that second step is delayed or skipped, the page loses the information that makes it discoverable.

    You do not need to remove JavaScript or give up a fast, interactive storefront. You need a clear division of responsibility: the initial HTML should explain what the page is and where its important links lead; JavaScript should improve how shoppers interact with it.

    Define the minimum HTML contract for every template

    Start with an output standard, not a framework decision. For each page template, write down what must be present in the server’s initial HTML response before any client-side code runs.

    On a product page, that normally includes the product name, descriptive copy, current price, availability, review information intended for search, relevant Q&A content and breadcrumbs. A category page should identify the category and expose its primary product and subcategory destinations. These elements can be delivered in the initial HTML while comparison carousels and other engagement features wait for JavaScript.

    Key takeaways

    • Put the page’s identity, primary content and current commercial facts in the initial HTML.
    • Render important destinations as real anchor elements with href attributes.
    • Give every filter state intended for search a stable, readable URL that works when requested directly.
    • Include Product structured data in the same server response as the visible product information.
    • Keep recommendation widgets, comparison tools and nonessential third-party scripts out of the critical rendering path.

    Use View Source or an HTTP client when checking this contract. The Elements panel in browser developer tools shows the DOM after JavaScript has had a chance to repair or populate it. A complete rendered DOM does not prove that the server response was complete.

    Framework choice is not a substitute for this test. Next.js can combine server rendering and static generation, Astro can send content with no JavaScript by default and hydrate selected interactive islands, and Shopify Hydrogen can support deferred client-side behavior. The relevant question is not which label appears in your technology stack. It is what each template actually sends before hydration.

    Make the catalog discoverable before shoppers interact
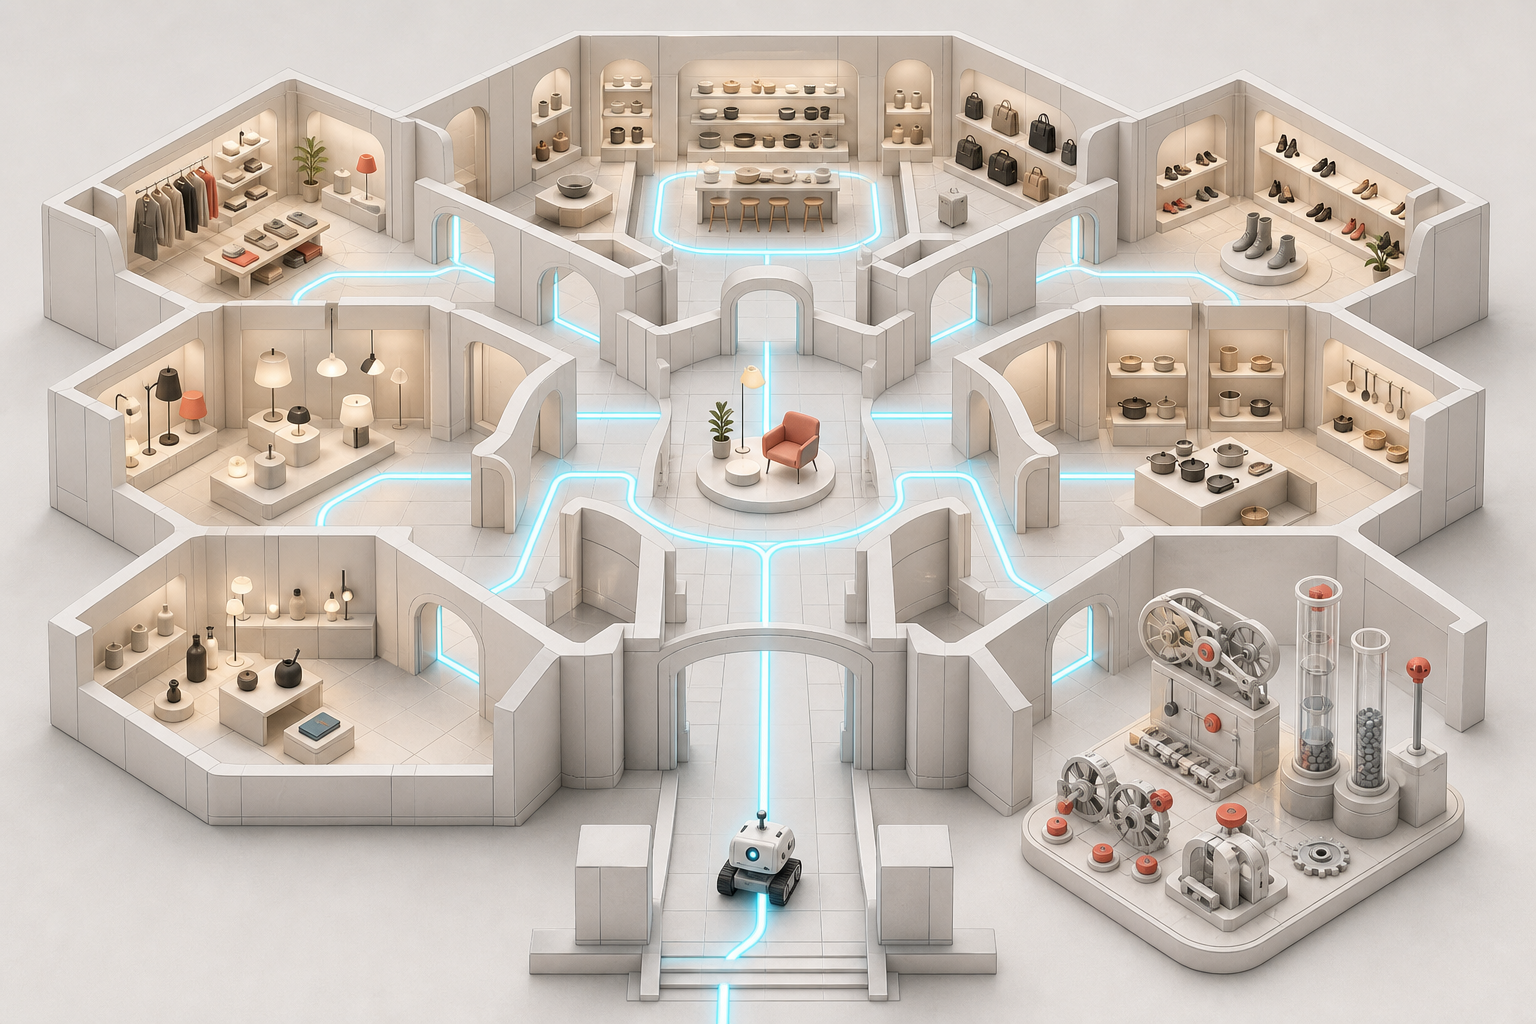
    An isometric catalog of product rooms connected by illuminated corridors, with a small crawler robot following a direct route from the entrance to a product alcove.

    A crawler should not have to open a menu, trigger a click handler or run a search to discover your important categories and products. Render navigation links in the initial response, using anchor elements whose href values point to real destinations.

    This distinction matters in component-based storefronts. A button is appropriate for opening a drawer, changing a local view or adding an item to a cart. A link is appropriate when the shopper is moving to another URL. A styled div with an on-click event may look like a link, but it does not provide the same dependable discovery path. Ecommerce navigation built as ordinary anchors remains visible to crawlers even when JavaScript supplies the interactive behavior.

    Treat every filter state as a URL decision

    Faceted navigation needs two separate decisions: which states help shoppers, and which states deserve to become search landing pages. Do not make every possible combination indexable by default. That can produce a large collection of thin or repetitive URLs. Classify each facet and combination according to its intended role.

    • Search landing state: Give it a stable URL, meaningful page context and a server response containing the expected product set.
    • Discovery path: Use crawlable links when the state helps crawlers reach important inventory, but decide separately whether the resulting page should be indexed.
    • Shopper-only interaction: Keep purely presentational states, such as a view toggle, as interface controls rather than pretending they are distinct landing pages.

    Client-side grid updates are fine after the initial load. The URL still needs to represent any state you expect people or search systems to revisit. Prefer readable URLs over hash fragments or opaque, bracket-heavy parameters when a filtered page is meant to be shared, bookmarked, crawled and indexed.

    Test a filter URL by copying it into a fresh session and requesting it directly. The correct category context, selected state and core product results should be available without replaying the clicks that created the URL. If the server returns the unfiltered category and only browser memory restores the selection, the URL is not yet a dependable landing page.

    Send Product structured data with the visible facts

    Product structured data should arrive in the initial HTML, not appear only after a client-side component mounts. Place the JSON-LD script in the server response and generate it from the same current product data used for the visible page.

    This is particularly important for price and availability because those values can change frequently. When the visible page, the structured data and the underlying commerce record use separate rendering paths, they can drift apart. Server-delivered structured data removes one avoidable dependency and gives crawlers immediate access to Product data without waiting for rendering.

    • Confirm that the Product JSON-LD exists in the raw response, not only in the rendered DOM.
    • Match the product identity in the markup to the title and description shoppers can see.
    • Keep price and availability consistent with the visible offer at the time the page is served.
    • Keep breadcrumb markup and visible breadcrumb navigation aligned.
    • Do not use structured data as a replacement for missing product content. It describes the page; it does not make an empty page complete.

    Valid markup does not guarantee a search feature or enhanced result. It does, however, remove a preventable technical reason for the product information to be missed or misunderstood.

    Protect the first render from third-party scripts

    Third-party code accumulates quietly on ecommerce sites. Analytics, chat, reviews, recommendations, personalization and advertising tools can all compete with the product page for browser resources. If they delay the main content, they also increase the work required to render and understand the page.

    Keep essential product information outside third-party widgets wherever possible. A review widget can provide interaction, for example, while the review summary or indexable review content remains part of the server response. A comparison carousel can load later because it enhances the shopping session rather than defining the product.

    Use script-loading behavior deliberately. Async suits an independent script that can execute whenever it finishes downloading. Defer suits a script that should wait until HTML parsing is complete and preserve its order relative to other deferred scripts. Both approaches require testing because the script’s own loader may create additional requests or inject more code.

    Deferring nonessential scripts can protect Largest Contentful Paint and reduce the rendering burden. The practical priority order is straightforward: deliver the product and navigation first, make the buying controls usable next, then initialize supporting services.

    • Inventory every third-party script on product and category templates.
    • Record what breaks if each script is blocked. If the product disappears, the dependency is too deep.
    • Mark the scripts that are essential for the initial buying path.
    • Load engagement and measurement code without blocking the initial content whenever its behavior permits.
    • Remove tags that no longer have a current owner or business purpose.

    Use a release test that catches invisible storefronts
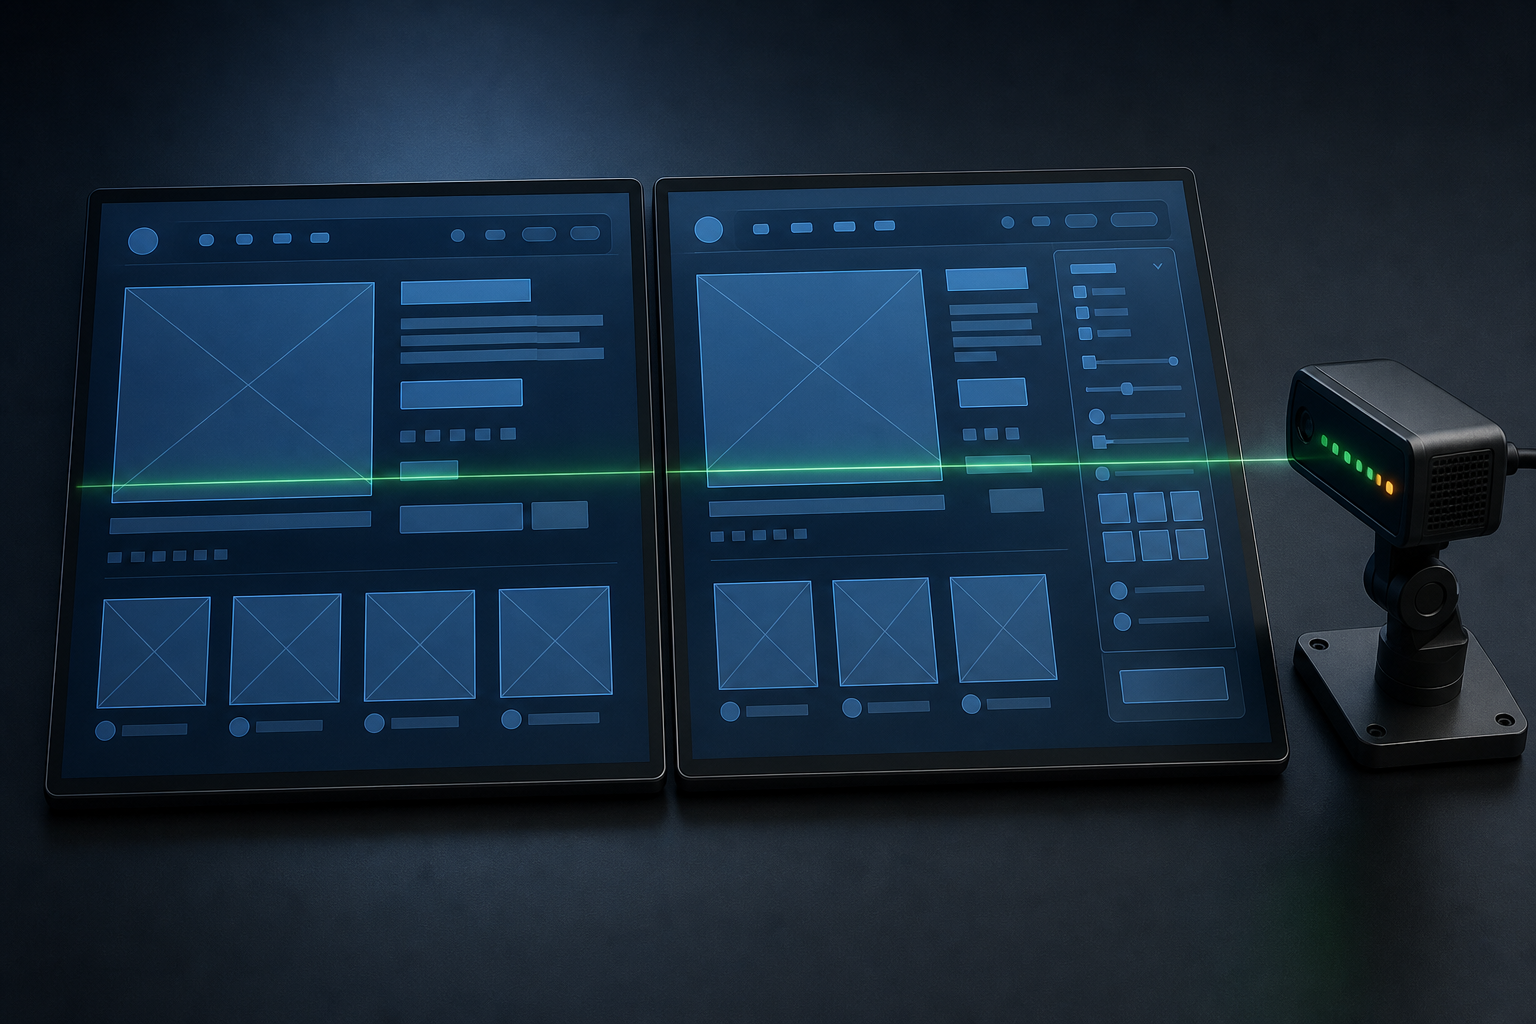
    A quality assurance workstation compares an initial product-page view with an enhanced interactive view while an automated device scans both displays.

    A JavaScript SEO audit is most useful when it becomes a release check. Run it on representative product, category and filtered pages whenever you change rendering, navigation, data fetching or third-party tooling.

    1. Request the raw HTML for each representative URL without executing JavaScript.
    2. Search that response for the page title, descriptive content, price, availability, breadcrumbs, primary links and Product JSON-LD.
    3. Disable JavaScript and follow the main catalog links. The experience can be less interactive, but the destinations and page meaning should remain present.
    4. Open indexable filter URLs directly in a fresh session. Confirm that each response represents the requested state without requiring a previous click sequence.
    5. Enable JavaScript and compare the rendered page with the raw response. JavaScript may add interaction and secondary content, but it should not replace the page’s essential identity.
    6. Review the loading order of third-party scripts and check whether they delay the primary content or Largest Contentful Paint.
    7. Repeat the checks against the deployed production response. Do not rely solely on what the application produced in a local development environment.

    The raw-response test also provides a useful baseline for AI visibility. Some AI systems do not handle JavaScript efficiently, so a page that communicates its product, offer and hierarchy in HTML is easier to process without relying on a browser-like rendering stage.

    What you findLikely dependencyFix first
    Product name or grid is absent from raw HTMLClient-side content renderingFetch and render the core content on the server
    Destinations appear only after a menu interactionClient-only navigationRender real anchors with href values in the initial response
    Product JSON-LD exists only in the rendered DOMClient-side schema injectionSerialize the markup into the server response
    A filter works only after a click sequenceInterface state is not represented by the URLCreate a stable URL and return the corresponding state directly
    Primary content waits behind vendor codeBlocking third-party scriptsDefer, load asynchronously or remove nonessential scripts

    Start with one important product template and one category template. Write the HTML contract, disable JavaScript and fix the first essential element that disappears. Once the server response carries the meaning of the catalog, you can keep adding interactivity without asking every crawler and AI system to reconstruct the store for you.
    References

  • How to Control Automated Paid Search for Commerce Growth

    How to Control Automated Paid Search for Commerce Growth

    You did not lose control of paid search when platforms automated bidding, audience expansion, and ad assembly. Control moved upstream. The expensive mistake is still managing the account as though a perfect keyword list can compensate for weak conversion data, muddled economics, thin creative, or a poor product page.

    Your job now is to give the system a clear commercial objective, reliable evidence, and firm boundaries. Do that well and automation can explore more demand than a person could manage manually. Do it poorly and it will scale the wrong outcome with impressive efficiency.

    Control the system through the inputs it learns from

    Keywords still matter, but they no longer carry the account on their own. In automated search, keywords function alongside conversion data, first-party audience information, creative assets, and landing-page content. The practical shift is simple: your campaign structure is no longer the whole strategy. It is one part of the training environment you create for the platform.

    That is why an automation feature should never be evaluated only by whether it finds additional conversions. Some AI Max campaigns have been credited with up to 27% more conversions, but that is a reason to run a controlled test, not a forecast you should put into a budget. More conversions help only when they are valid, incremental enough to matter, and economically acceptable.

    Control areaDecision you ownEvidence to inspect
    Business outcomeWhich conversion is primary and how it is valuedCompleted orders, revenue, margin proxy, cancellations, and returns
    Learning dataWhich customer and transaction signals are accurate enough to useDuplicate events, missing values, currency consistency, and match quality
    DemandHow discovery traffic is separated from proven demandSearch terms, product-level sales, conversion rate, ROAS, and ACOS
    ExperienceWhich product information, creative, and destination represent the offerMessage continuity, availability, price, page relevance, and purchase completion
    RiskWhere automation may spend and when a person must interveneBudgets, exclusions, brand traffic, inventory, and unexplained mix changes

    Start with a conversion contract: a short, explicit definition of what the bidding system is supposed to maximize. This is not a tracking implementation document. It is the agreement between marketing, commerce, and analytics about what counts as success.

    1. Name the primary event. For a commerce campaign, that will usually be a completed purchase. Add-to-cart, product-view, and checkout events can remain useful diagnostics without being treated as equivalent to revenue.
    2. Define the value. Decide whether the platform receives gross order revenue, a margin-weighted value, or another consistent commercial proxy. If two orders produce very different contribution margins, equal revenue values may teach the system to prefer the less profitable mix.
    3. Define validity. Document how duplicate purchases, cancellations, refunds, taxes, shipping, and currency are handled. A bidding model cannot infer that an inflated or duplicated value is wrong.
    4. Define the observation window. Review performance only after the normal conversion and reporting lag has had time to mature. Otherwise, recent traffic will look artificially weak and invite unnecessary changes.
    5. Name an owner. Someone must be accountable for detecting broken events, abrupt value changes, and gaps between platform reporting and the commerce system.

    Well-structured first-party data now does much of the strategic work once associated with exhaustive keyword research. It helps the platform distinguish valuable customers and transactions from activity that merely looks busy. But volume does not cure bad measurement. A larger stream of duplicated purchases is still bad data, and automation can magnify its effect faster than a manual bidder would.

    Before expanding automation across the account, validate the contract in a bounded campaign or product group. Changing conversion definitions, bidding targets, audience inputs, and creative at the same time can expose the business to avoidable spend while making the result impossible to interpret.

    Separate discovery from profitable scale

    An exploration area tests many generic products while a gated passage leads selected products into orderly fulfillment lanes.

    Commerce advertising has two jobs that pull in different directions. Discovery needs freedom to test unfamiliar queries, audiences, and products. Performance needs concentration: more budget behind combinations already linked to acceptable sales. Put both jobs in one undifferentiated campaign and the blended result hides what each dollar is doing.

    A stronger architecture creates a deliberate path from exploration to scale. Search environments are especially useful here because shoppers express intent in their queries, while Google Shopping and Amazon Ads can connect that demand to product-level or keyword-level revenue. That creates a feedback loop between search behavior, sales, and budget allocation.

    • Discovery captures uncertainty. It explores a wider set of eligible demand under its own budget and economic limits. Its purpose is to find useful search terms and product-demand combinations, not to look as efficient as a mature campaign.
    • Performance concentrates evidence. It gives proven converters dedicated budgets and targets so they do not have to compete with every exploratory term for spend.
    • Brand protection isolates known demand. Branded searches often behave differently from generic acquisition. Separate reporting prevents strong brand results from disguising weak prospecting.
    • Ranking activity has an explicit cost. If you spend more aggressively to improve visibility or marketplace position, keep that objective distinct from a profit-maximizing campaign.

    The handoff between discovery and performance should use written promotion rules. A term or product is not proven because it converted once, and it should not stay in discovery forever after building credible evidence. Define the minimum evidence your business needs, then test that evidence against four questions:

    • Has the query or product produced enough mature sales to reduce the chance that one unusual order controls the decision?
    • Does its ROAS or ACOS fit the contribution economics of that product after the costs the business actually bears?
    • Can inventory and fulfillment support more demand without creating cancellations or a poor customer experience?
    • Does the landing page or marketplace listing genuinely satisfy the intent that generated the sale?

    Use demotion rules as well. A proven term can return to discovery or lose budget when its economics deteriorate after a mature measurement window, when stock becomes unreliable, or when the offer no longer matches the query. Graduation is a status based on current evidence, not a permanent award.

    Do not impose one universal efficiency target on every layer. Discovery may operate under a stricter spending cap while accepting more variance. A performance campaign may receive more budget but face a firm profitability requirement. Brand and ranking campaigns need their own definitions of success. The crucial point is that each layer has a known job, budget, and exit condition.

    Use platform-specific structures without losing the common logic

    Google Shopping and Amazon Ads can share the same discovery-to-scale strategy, but their campaign mechanics and commercial roles are different. Reproducing the same campaign map on both platforms creates superficial consistency at the cost of useful control.

    Route Google Shopping demand through distinct layers

    A workable Google Shopping structure uses three layers: a branded layer, a catch-all discovery layer, and a dedicated layer for the strongest terms. Campaign priority and other routing controls can then help prevent exploratory demand from consuming the budget reserved for proven opportunities.

    • Branded layer: A shopping-focused, assetless Performance Max campaign can be used to concentrate on shopping inventory and reduce unintended expansion into other channels. Inspect the actual traffic and placement mix rather than assuming the setup label guarantees isolation.
    • Catch-all layer: Keep a wide net for search-term discovery, but contain it with a separate budget and lower bids or a suitably conservative target. Its output is evidence: which queries and products deserve focused investment.
    • Performance layer: Move reliable, high-intent demand into a dedicated campaign where budget and bidding can reflect its demonstrated economics.

    This structure is useful only if routing works as intended. Inspect search terms, product distribution, brand share, and channel mix. If the catch-all keeps taking proven demand, or the branded layer expands beyond its assignment, the labels on the campaigns are not describing the account you actually have.

    Performance Max can also operate alongside AI Max for Search, but overlap should have a reason. Decide which campaign is responsible for known product demand, which is exploring broader intent, and how you will detect duplication or channel substitution. Reach is not automatically incremental growth.

    Organize Amazon Ads around the SKU and the commercial objective

    Amazon gives you a different feedback loop. The shopper is already in a marketplace, reporting can be granular at the product and category level, and ad conversion can contribute to stronger organic position. The practical structure is therefore SKU-level research, performance, and ranking tiers.

    • Research tier: Explore broad keyword possibilities and collect evidence about how shoppers describe the need. Control the downside with a defined budget and ACOS boundary.
    • Performance tier: Concentrate proven converters and manage them toward the product’s profit requirement.
    • Ranking tier: Bid more aggressively only when improving organic position is a deliberate objective and the business has approved the cost of doing so.

    ROAS and ACOS describe the same relationship from opposite directions. ROAS is attributed revenue divided by ad spend. ACOS is ad spend divided by attributed revenue. Neither metric knows your profit. Set the acceptable range from contribution margin after relevant product costs, marketplace fees, fulfillment, discounts, and expected returns. A generic benchmark can make an unprofitable SKU look healthy or constrain a high-margin SKU that could support more growth.

    Higher conversion rates on Amazon can support organic ranking and reduce later acquisition pressure, but do not count that future benefit twice. Keep direct ad economics visible, document when ranking is the primary objective, and check whether organic position actually changes before continuing the extra spend.

    Across Google and Amazon, use the same product economics as the common language. The campaigns may optimize differently, but both should ultimately answer whether the next unit of spend creates acceptable commercial value.

    Make product data, creative, and landing pages part of targeting

    When automation assembles ads and expands matching, every customer-facing input can affect both eligibility and persuasion. Creative is not decoration added after targeting. Landing-page content is not merely the place traffic goes. These assets help the system interpret what you sell, who may want it, and which message belongs with a particular intent.

    Build a message system for each important product group before asking the platform to generate combinations. It should cover:

    • Product identity: What the item is, using the language a qualified shopper would recognize.
    • Use case: The job, occasion, or problem the product genuinely addresses.
    • Differentiator: A factual reason to choose it over a plausible alternative.
    • Proof: Verifiable product details, policies, or other substantiation available on the destination.
    • Offer conditions: Price, eligibility, availability, shipping, or promotional limits that could change the buying decision.

    That framework gives automation useful variety without inviting random claims. It also makes creative testing interpretable. If one asset emphasizes a use case and another emphasizes price, you can learn something from the difference. If every asset changes the product, audience, offer, and tone at once, a winning combination tells you little about why it worked.

    Then audit continuity from query to ad to destination. A shopper who searches for a specific variant should not land on a generic category page and be expected to restart the search. A promotion in an ad should be visible with the same conditions on the page. Product names, images, price, availability, and purchase options should agree across the feed, creative, and destination.

    Landing-page quality matters twice. It affects whether a visitor can complete the purchase, and automated systems can use the post-click experience and page content as relevance signals. Diagnose a weak product group accordingly. The problem may be bidding, but it may also be a page that sends an ambiguous signal or fails to finish the promise made by the ad.

    • Confirm that the destination resolves to the correct product or tightly matched category.
    • Keep price, inventory, variant, and promotion information synchronized with the advertisement.
    • Make the primary purchase action obvious and functional on the devices receiving paid traffic.
    • Remove claims from generated or assembled creative when the destination cannot substantiate them.
    • Separate products with materially different margins, availability, or buying intent instead of forcing them into one undifferentiated asset and bidding group.

    Do not compensate for a weak offer with broader automation. Broader matching can find more people, but it cannot make an unclear product, unavailable variant, or contradictory price more attractive. Fix the commercial experience before paying the system to expose it at greater scale.

    Run a human operating system around the automation

    Four professionals surround a circular control table, reviewing product, creative, storefront, and conversion inputs around an automated sorting mechanism.

    The human role is not to outbid the bidding model one adjustment at a time. It is to decide what the model should learn, recognize when the evidence has become unreliable, and intervene at the level that caused the problem.

    Use a repeatable review loop:

    1. Observe mature performance. Wait for the normal reporting and conversion lag, then compare actual results with the campaign’s stated job.
    2. Locate the failure class. Check measurement, demand mix, product economics, inventory, creative, destination, and campaign routing before changing bids.
    3. Change one class of input. For example, repair conversion values, adjust a budget boundary, refine routing, or replace weak assets. Avoid simultaneous changes that erase causal clarity.
    4. Write the expected effect. Record what should change, which metric should reveal it, what observation window is appropriate, and what would justify reversal.
    5. Promote, hold, demote, or stop. Use the rules established for discovery and performance rather than making a fresh subjective decision every time.

    Not every bad-looking period calls for intervention. Hold when conversion data is still immature and spend remains inside the approved boundary. Change the campaign when mature evidence shows a persistent problem with an identifiable input. Stop or contain it immediately when tracking breaks, spend escapes its guardrail, inventory cannot support orders, or an ad makes an inaccurate claim. Those failures can waste money or harm customers while the model continues optimizing against corrupted conditions.

    Your review should also distinguish a performance change from a mix change. A stable blended ROAS can conceal a shift from new-customer demand toward branded traffic, from high-margin products toward low-margin products, or from direct shopping placements toward less valuable inventory. Look below the account total before calling automation successful.

    Keep an intervention log. For every material change, record the campaign, business reason, affected products, input changed, expected outcome, and rollback condition. This turns account management into an accumulating decision system instead of a sequence of reactions. It also prevents one operator from undoing another operator’s test without knowing why it exists.

    Key takeaways

    • Keywords remain useful signals and diagnostics, but conversion quality, first-party data, creative, and landing pages increasingly determine what automated campaigns learn.
    • Define the primary conversion, its value, its validity rules, and its owner before expanding automation.
    • Give discovery, proven performance, branded demand, and ranking activity separate jobs, budgets, and exit conditions.
    • Use the same discovery-to-scale logic across Google Shopping and Amazon Ads, but adapt the campaign mechanics to each platform.
    • Judge ROAS and ACOS against product contribution economics rather than a generic account benchmark.
    • Let people own measurement, commercial judgment, guardrails, creative truth, and the decision to promote or stop an experiment.

    Start with one meaningful product group. Write its conversion contract, calculate its acceptable economics, identify which traffic is discovery and which is proven, and audit the message from query through purchase. Only then widen automation. If you cannot explain the value entering the bidding system, the system is not ready to scale it.

    References

  • How to Build an AI-Powered Creator Commerce Campaign

    How to Build an AI-Powered Creator Commerce Campaign

    You have creator candidates, a product catalog, and a paid-media budget. The hard part is connecting them: the creator must make the product relevant, the shopping surface must preserve the promise, and your measurement must show where the campaign actually worked or failed.

    The practical model is a single creator-commerce loop, not separate influencer, advertising, and ecommerce projects. You choose the buying action first, match creators to that job, plan the paid uses of their content, configure the offer shoppers will encounter, and measure every handoff.

    Treat creator marketing and AI shopping as one buyer journey

    A creator can introduce the problem, demonstrate the product, answer an objection, or give a buyer a reason to act. Commerce systems have a different job: they present the product, price, availability, and eligible benefits when that interest becomes purchase intent.

    AI is bringing those jobs closer together. YouTube can use Gemini to help advertisers find relevant creators and then distribute creator-made content through paid formats. Google has also extended member pricing and shipping benefits into AI Mode and Gemini, as well as local inventory and regional Shopping ads.

    For you, the important change is the handoff. A shopper can encounter a creator’s recommendation, see the same message in a paid placement, and later find a personalized benefit during product discovery. If those touchpoints contradict one another, AI-powered distribution merely spreads the inconsistency faster.

    Start each campaign by writing the promise that must survive the journey. If the creator discusses exclusive shipping for loyalty members, verify that the eligible shopper can actually see and receive that benefit. If the listing emphasizes member pricing, the creator’s call to action should explain why membership matters instead of sending everyone to a generic product page with no visible connection.

    This also changes how you divide responsibility internally. The creator team should know which offer the commerce team has configured. The commerce team should know which claims and calls to action appear in the creator asset. Paid media should not receive the content only after it has been produced; its required placements and audiences should shape the brief from the beginning.

    Build the campaign backward from a commerce event

    A product purchase in the foreground connects backward through an offer, creator content, paid distribution, and content production.

    Do not begin with a broad request to find popular creators. Begin with the behavior you need from a specific kind of buyer. That decision determines the offer, brief, creator criteria, destination, and measurement plan.

    1. Name the commercial event. Decide whether the campaign is meant to generate product discovery, a qualified product-page visit, a first purchase, a loyalty enrollment, or another defined action. Use one primary event to make campaign decisions. Secondary metrics can explain performance, but they should not quietly replace the original goal.
    2. Define who can receive the offer. Separate prospects from recognized members and distinguish a public promotion from a loyalty benefit. If eligibility depends on a membership tier, country, region, or local inventory, record that before the creator writes the call to action.
    3. Choose the proof the buyer needs. A creator brief should identify the buyer’s problem, the product’s role, the objection that must be answered, and the evidence the creator can show. A product demonstration, use case, or clear explanation usually gives you more to evaluate than a generic endorsement.
    4. Shortlist creators for that job. YouTube’s Gemini-powered matching can suggest candidates from more than three million YouTube Partner Program creators. Use that scale to widen discovery, then apply human review to audience relevance, creative quality, product credibility, and suitability for paid distribution.
    5. Plan distribution before production. Decide whether the partnership will remain on the creator’s channel or also become a paid Short, an in-stream ad, or both. Confirm that the partnership permits every planned placement, market, and period of use before allocating media spend.
    6. Instrument the handoff. Give each creator and placement an identifiable destination or campaign parameter. Align the platform conversion event with the commercial event you selected. Where appropriate, add a creator-specific code, but do not treat code use as the only evidence of influence; shoppers may return through another route.

    Keep the first test interpretable. If you change the creator, audience, offer, landing experience, bid strategy, and product selection at the same time, a good result will not tell you what to repeat and a bad result will not tell you what to repair.

    Use AI matching as a shortlist, not a strategy

    Creator matching solves a discovery problem. It can help you navigate a large pool, but it cannot decide what your buyer needs to hear, whether the creator’s authority transfers to your product, or whether the resulting content will work outside the creator’s existing audience.

    Use a scorecard that forces every recommendation to produce observable evidence. The model’s recommendation can open the review; it should not end it.

    DecisionEvidence to inspectReason to pause
    Audience relevanceRecurring subjects, viewer questions, purchase problems, and use cases connected to the productThe connection depends mostly on a broad demographic label or follower count
    Product credibilityA natural reason for the creator to discuss, use, compare, or demonstrate the productThe endorsement would require a sudden change in the creator’s established subject matter
    Creative strengthA clear opening, understandable product role, concrete proof, and a call to action that fits the contentThe product appears only as an interruption with no useful explanation
    Paid-media portabilityA message that a cold viewer can understand without knowing the creator’s backstoryThe asset depends entirely on channel-specific context or an inside joke
    Offer alignmentA benefit the intended audience can receive in the markets and membership tiers being targetedThe creator would be promoting an offer that many reached viewers cannot access
    Measurement readinessA distinct asset, placement identifier, destination, and agreed conversion eventPerformance can only be read as a blended campaign total

    Follower count belongs in the context, not at the center of the decision. A smaller relevant audience can reveal stronger buying intent than a large audience gathered around unrelated content. Conversely, topical relevance alone is not enough if the creator cannot communicate the product clearly or if the asset cannot survive paid distribution.

    Review the likely failure mode before approving a match. If the creator understands the audience but not the product, improve the briefing or reject the match. If the content is persuasive to existing followers but confusing to cold viewers, separate the organic asset from the paid edit. If the offer is compelling but limited to recognized members, prevent the campaign from implying that every viewer will receive it.

    Turn creator content into a connected distribution system

    A creator filming a product is connected by glowing paths to multiple content, shopping, advertising, order, and measurement touchpoints.

    A creator partnership should produce more than an isolated upload. YouTube allows creator-made content to run as paid Shorts and in-stream ads, giving you a route from creator credibility to controlled media distribution.

    That does not mean one edit should be copied everywhere. Give each placement a defined job while preserving the same product truth and offer:

    • The creator-channel asset establishes context, credibility, and the full product story for an audience that already knows the creator.
    • The paid Short introduces the buyer problem and product quickly enough to make sense to a cold viewer.
    • The in-stream ad has room to develop the use case, proof, or objection that cannot fit into the shortest edit.
    • The product or local inventory listing confirms the purchasable product and displays the applicable price or benefit.
    • The loyalty layer shows recognized members the pricing or shipping advantage for which they are eligible.

    Create a message ledger before editing begins. Record the approved product promise, supporting proof, exact offer wording, call to action, destination, market eligibility, membership requirements, and the placements where the asset will run. Every version can vary in pacing and length, but it should remain consistent with that ledger.

    The commerce setup deserves the same attention as the creative. Merchants using Google’s loyalty features can activate the loyalty add-on in Merchant Center, configure member tiers, supply pricing and shipping attributes, and connect Customer Match lists so recognized members can see eligible benefits. A creator campaign should not promote those benefits until the feed, tier rules, audience connection, and destination have been checked together.

    Market eligibility is part of the brief, not a footnote. The stated expansion covers Australia, Brazil, Canada, France, Germany, India, Italy, Japan, Mexico, the Netherlands, South Korea, Spain, the United Kingdom, and the United States. If your creator reaches viewers outside the relevant campaign market, use wording that does not imply universal access.

    Local inventory and regional Shopping ads can be especially useful when the benefit or product availability varies by location. Match the creator’s geographic targeting, the inventory being promoted, the Merchant Center configuration, and the landing experience. Otherwise, you pay to generate interest that the next surface cannot satisfy.

    There is also a U.S. pilot that uses Customer Match as a relationship data source for free listings. Treat pilot access as an optional opportunity, not as inventory you can assume in a forecast. Build the core campaign around placements and features actually available to your account.

    Measure the chain instead of celebrating one platform number

    Creator commerce can look successful at the top of the funnel while leaking value at the final handoff. A popular video does not prove product demand, and a strong click-through rate does not prove profitable sales. Your reporting should show how attention moved through the campaign.

    • Matching: Track which creator-selection criteria were expected to matter and whether the content attracted relevant viewer questions or actions.
    • Creative: Read view rate, completion, engagement, and product clicks by asset. These metrics help locate attention loss; they are not substitutes for the commercial event.
    • Media: Separate organic creator delivery from paid Shorts and in-stream distribution. Report cost, reach, click-through rate, conversion rate, and acquisition cost by placement.
    • Commerce: Measure product-page behavior, purchases, order value, and offer redemption using consistent definitions.
    • Relationship: Where loyalty is part of the objective, distinguish existing recognized members from new enrollments and non-member buyers.

    Document every denominator. A conversion rate based on clicks is not interchangeable with one based on sessions, and a customer acquisition cost should not silently include returning customers if the campaign goal is new-customer growth. Definition drift can make two dashboards appear to agree when they are measuring different events.

    Platform lift figures are useful for forming a hypothesis, not for writing your revenue forecast. YouTube reports an average 30% conversion lift from boosting creator content through Shorts and in-stream ads. Google reports that some retailers saw up to a 20% increase in click-through rate when tailored loyalty offers were shown to members.

    Those numbers should not be combined or treated as guaranteed. One is an average conversion result for creator advertising formats; the other is an upper-end click-through result reported for some retailers using tailored offers. They describe different interventions, outcomes, and populations. Your baseline, margin, audience, creative, product, and offer determine whether either benchmark is relevant.

    Use controlled comparisons to learn what contributed. Hold the offer, audience, and destination steady when comparing creator-made and brand-made assets. Evaluate loyalty presentation separately instead of mixing it into the creative test. If several creator assets run together, retain asset-level and creator-level identifiers so a blended result does not hide the winner or the failure.

    Read mismatches as diagnostic signals. Strong viewing with weak product clicks points you toward the call to action or offer handoff. Strong clicks with weak conversion points you toward the destination, price, eligibility, or product experience. Strong conversion with limited reach points you toward distribution. These are places to investigate, not automatic diagnoses, but they are more useful than labeling the whole campaign good or bad.

    Key takeaways

    • Choose the buying action and eligible offer before asking AI to find creators.
    • Use AI matching to expand and organize discovery, then require human evidence for audience fit, product credibility, creative quality, and paid-media suitability.
    • Plan creator-channel content, paid Shorts, and in-stream ads as related assets with different jobs, not automatic duplicates.
    • Verify Merchant Center tiers, pricing, shipping attributes, Customer Match connections, markets, and destinations before a creator promises a loyalty benefit.
    • Measure the full path from creator attention to commerce and customer relationship outcomes. Treat vendor-reported lift as a hypothesis, not your forecast.

    Your next move is to choose a product, a buyer action, and an offer that the intended audience can actually receive. Write the creator brief, placement plan, commerce configuration, and measurement event on the same page. If that chain remains clear from first view to purchase, you have a campaign worth testing.

    References


  • Google Merchant Center Out-of-Stock Purchase Controls

    Google Merchant Center Out-of-Stock Purchase Controls

    If an out-of-stock product page still lets shoppers add the item to their cart, or if the purchase control disappears entirely, you now have a Merchant Center problem. The compliant state sits between those two behaviors: keep the buy button visible, make it clearly disabled, and show an explicit out-of-stock message.

    The product feed must declare the same availability as the landing page. That alignment matters as much as the button itself because conflicting availability information can lead to product disapprovals. Here is how to implement the control without creating a new gap between your storefront, inventory system, and feed.

    The correct purchase control depends on the availability state

    Out of stock is not a general label for every product you cannot ship immediately. It is a specific commercial state. When you declare an item out of stock, the shopper must not be able to buy it. The page should nevertheless retain a recognizable purchase control so the unavailable state is obvious rather than looking like a broken or incomplete product page.

    Two common storefront patterns no longer satisfy that requirement:

    • Removing the buy button: The shopper sees no purchase control and may not understand whether the product is unavailable, discontinued, or affected by a page error.
    • Leaving the buy button active: The page claims that the item is out of stock while continuing to accept a purchase.

    Use the availability state to determine both the message and the control:

    AvailabilityLanding-page messagePurchase controlFeed treatment
    In stockExplicitly identify the item as availableAllow the normal purchase actionDeclare in stock
    Out of stockExplicitly say out of stockKeep the buy button visible but disabledDeclare out of stock
    Back orderExplicitly say back orderAccept the order only if that is the offer you intend to makeDeclare back order
    Pre-orderExplicitly say pre-orderMake the purchase experience consistent with the pre-order offerDeclare pre-order

    The important distinction is whether you are accepting an order. If customers may order an item that is not currently available, treating it as back order keeps the offer internally consistent. Do not label it out of stock in the feed while using an active Add to cart button on the page.

    Implement a disabled button, not merely a gray decoration

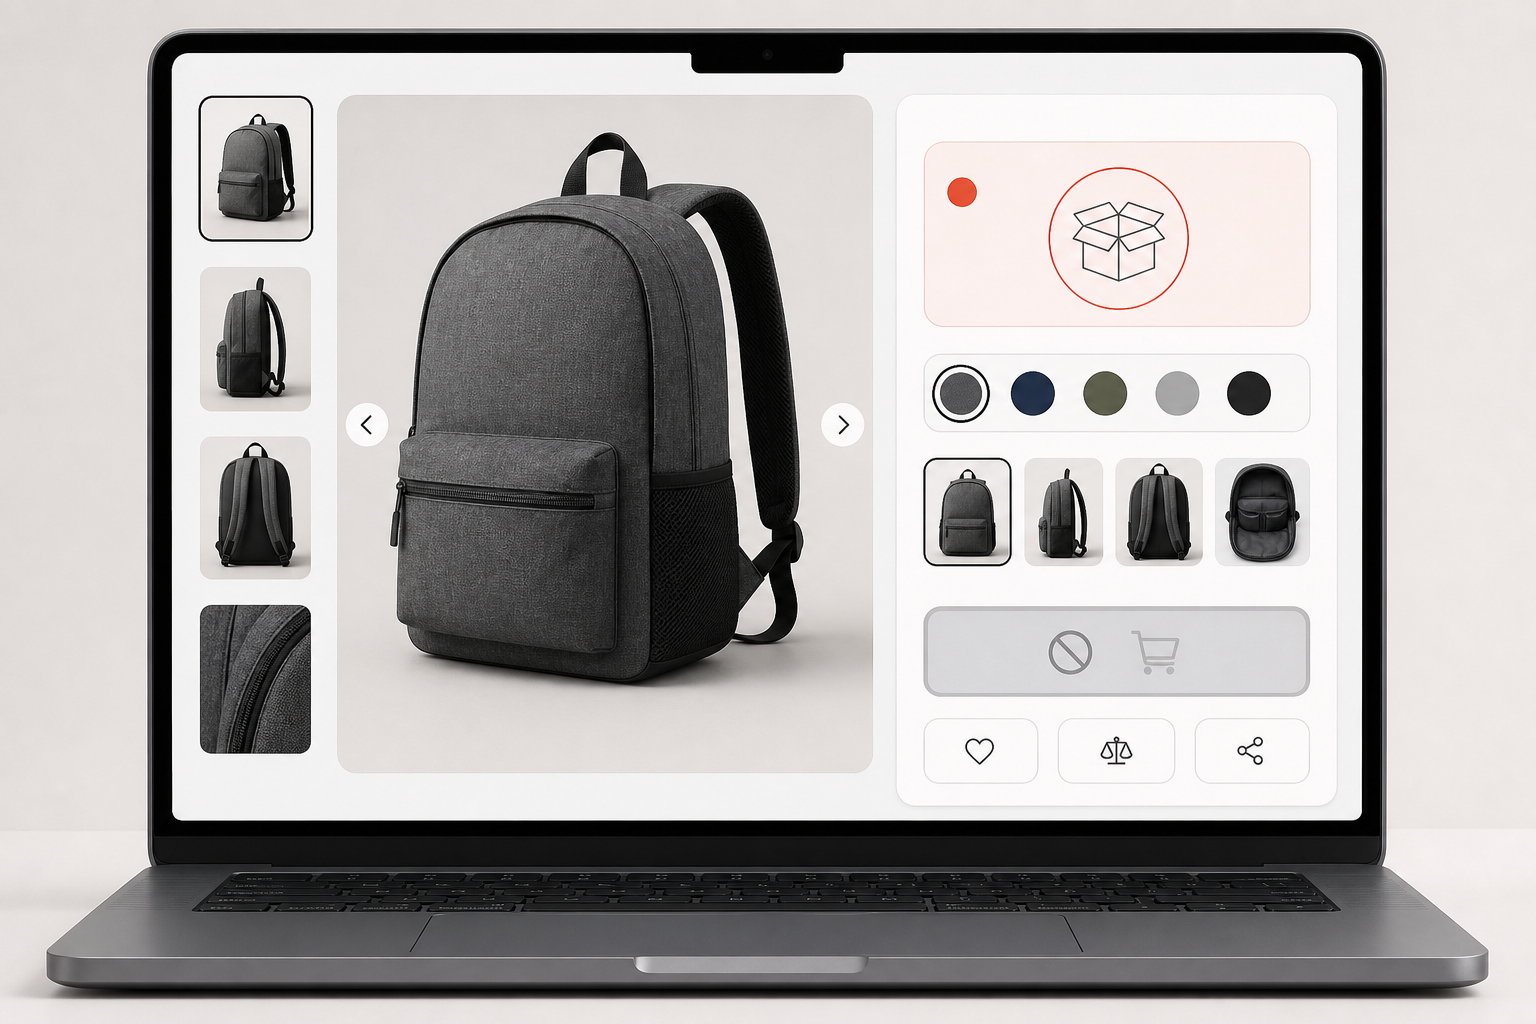
    A laptop product panel shows a visible but inactive purchase button beside an empty-box status icon.

    A visual change alone is not a purchase control. A button can look disabled while remaining clickable with a mouse, keyboard, or touch input. Your implementation needs to make the action inactive as well as visually unavailable.

    1. Calculate the product state first. Resolve the current item or selected variant to in stock, out of stock, back order, or pre-order before rendering the purchase area.
    2. Print a visible availability message. Place the words Out of stock near the purchase control. Do not rely on button color alone to communicate the state.
    3. Keep the control in the purchase area. Render the button where a shopper would normally expect to find it, with a clear disabled appearance.
    4. Disable the action itself. For a native HTML button, use its disabled behavior. If a custom element or link acts as the control, make sure it cannot activate through pointer, keyboard, or touch input.
    5. Block stale purchase requests. Treat the disabled interface as the first line of control, not the only one. The cart or commerce layer should recheck availability so an old page, direct request, or delayed script cannot create an order for an item still classified as out of stock.
    6. Change the commercial state when orders are allowed. If the business decides to accept orders before stock is available, update the product to back order on both the page and feed instead of quietly re-enabling an out-of-stock button.

    JavaScript storefronts need one extra check: do not render an enabled button first and disable it only after inventory data arrives. Resolve the state before exposing the action, or use an inactive loading state until the product record is ready.

    Products with selectable variants also need state-specific controls. When a shopper changes a size, color, or other option, update the availability message and button together. An unavailable variant should not inherit the active button of the variant that was selected previously.

    Make the page and feed read from the same inventory decision

    An empty central inventory container connects to a storefront screen and a product-listing tablet, both showing matching unavailable indicators.

    The most durable fix is not a second rule inside your product-feed exporter. It is one availability decision that every output consumes. Your catalog or inventory layer should determine the commercial state; the product template and feed generator should translate that same state into their respective formats.

    Separate logic creates predictable mismatches. A storefront may switch to out of stock as soon as inventory reaches zero while a scheduled feed still contains the earlier in-stock value. A feed rule may convert low inventory to out of stock while the page continues to sell. A manually edited product badge may say back order even though the underlying record and feed still say out of stock.

    Map the flow before changing the interface:

    • Identify the field or rule that decides whether an order may be accepted.
    • Document how each internal value becomes in stock, out of stock, pre-order, or back order.
    • Use that mapping to render the visible landing-page label.
    • Use the same mapping to enable or disable the buy button.
    • Use the same mapping when generating the Merchant Center feed value.
    • Account for cached pages, cached product data, and feed-generation delays when inventory changes.

    Do not solve a disagreement by changing only the wording. If the feed says back order but your commerce system rejects every order, the label is still inaccurate. If the page says out of stock but the cart accepts the item, disabling a cosmetic button has not corrected the underlying state. The message, control, feed, and order behavior should describe one offer.

    Audit transitions, variants, and alternate purchase paths

    A static screenshot can confirm that a disabled button exists, but it cannot prove that the full inventory workflow is correct. Test the transitions that cause the page and feed to drift.

    1. Choose representative products. Include at least one product in each availability state your store supports, plus products with and without variants.
    2. Compare the declared states. For each selected item, check the internal inventory state, visible page message, purchase control, and exported feed value.
    3. Test the disabled control. Confirm that the out-of-stock button remains visible but cannot be activated with a mouse, keyboard, or touch interaction.
    4. Change variants. Move between available and unavailable options and confirm that the label and button change together every time.
    5. Test inventory transitions. Move a test item from in stock to out of stock, then to back order if your system supports it. Verify every output after each transition.
    6. Check delayed outputs. Revisit cached product pages and the next generated feed to find timing gaps between the storefront and Merchant Center data.
    7. Check the cart boundary. Confirm that the commerce layer rejects an item still classified as out of stock even when a stale page or alternate request reaches it.
    8. Review Merchant Center after deployment. Watch for availability-related disapprovals and trace any affected product back through the shared state mapping.

    Add these cases to regression testing if inventory or product templates change frequently. The highest-value automated checks are simple: an out-of-stock item renders an explicit label, its button is disabled, its feed value agrees, and the cart cannot accept it. For a back-order item, test that the back-order label and feed state remain aligned with the intended ordering behavior.

    Key takeaways

    • An out-of-stock product page needs a visible but disabled buy button; neither removing the control nor leaving it clickable is the correct state.
    • The page must explicitly communicate availability using a state such as in stock, out of stock, pre-order, or back order.
    • The landing-page state and Merchant Center feed must agree, or the product may be disapproved.
    • If you accept orders for inventory that is not currently available, classify the offer as back order and synchronize that state across the page and feed.
    • A shared inventory mapping is safer than separate storefront and feed rules.
    • Test state transitions and variant changes, not just the final appearance of one product page.

    Start with one out-of-stock SKU that currently removes its button or leaves it active. Trace that SKU from the inventory record through the product template, cart, and feed. Once all four surfaces express the same state, turn the mapping into a reusable rule and test it across the rest of the catalog.

    References

  • Google’s Universal Commerce Protocol: A Retailer Playbook

    Google’s Universal Commerce Protocol: A Retailer Playbook

    If you run ecommerce SEO, product feeds, or shopping infrastructure, your next visibility problem may not begin on a search results page. It may begin when an AI shopping agent tries to identify the right variant, confirm that it is available, calculate the correct price, and place it in a working basket.

    Google’s Universal Commerce Protocol, or UCP, is intended to connect those steps. Your practical task is to make product and customer data usable across discovery, selection, and checkout without assuming that protocol adoption will automatically produce rankings, recommendations, or sales.

    UCP moves product visibility closer to the transaction

    Traditional search optimization prepares a page for a person to discover and visit. Agentic commerce adds another route: software may evaluate products, assemble a purchase, and act for the shopper. UCP is an open, modular standard for connecting retailers with AI-driven shopping experiences.

    That does not make product pages irrelevant. It changes where accuracy has to survive. A persuasive description cannot compensate for an unavailable variant. Valid page markup cannot repair a cart that calculates the wrong price. A feed can expose a product, but the transaction can still fail if customer benefits disappear after identity linking.

    This gives you four connected layers to manage:

    • Page content and structured data explain the product in a crawlable, understandable form.
    • Catalog data supplies current commercial facts such as price, inventory, and available variants.
    • Cart logic turns selected items into a valid basket.
    • Identity and account logic determine whether the shopper receives eligible benefits.

    Keep these layers aligned, but do not treat them as interchangeable. UCP is not merely another name for JSON-LD, a product feed, or an ad format. It reaches into live commerce functions that page-level optimization alone cannot perform.

    Google has said it plans to use UCP capabilities in AI-enhanced experiences across Search and the Gemini app. That establishes a direction, not a promise that every retailer, market, capability, or product will receive the same access or exposure. Build readiness around documented availability and your own eligibility rather than an assumed rollout.

    Map each UCP capability to a real retail responsibility

    The useful way to evaluate UCP is capability by capability. Each one touches a different system, failure mode, and internal owner.

    CapabilityWhat it enablesWhat you should verifyLikely owner
    CatalogAccess to current product information, including pricing, inventory, and variantsStable identifiers, variant mapping, update freshness, and agreement between catalog, product page, and checkoutMerchandising, feed operations, or commerce platform team
    CartMultiple products from one retailer can be assembled into one basketAdd, update, remove, reprice, and out-of-stock behavior across a multi-item orderEcommerce engineering
    Identity linkingEligible benefits such as member pricing and free shipping can continue across connected experiencesAuthentication, consent, entitlement rules, session handling, and safe failure behaviorIdentity, security, loyalty, and legal or privacy teams
    Modular adoptionA retailer or platform can adopt selected capabilities instead of implementing everything at onceA rollout sequence tied to system readiness and a clear dependency mapCommerce product owner or program lead

    The capability names do not answer every implementation question. For example, knowing that an agent can create a cart does not by itself define how your taxes, promotions, substitutions, shipping restrictions, or returns work. Treat those as test cases that need authoritative documentation and validation in your own stack. Do not invent behavior from the protocol’s high-level description.

    Modularity is especially important for planning. You do not need to frame UCP as an all-or-nothing rebuild. If your identity system is not ready, that does not erase the value of repairing catalog inconsistencies. If your catalog cannot reliably distinguish variants, however, adding an agent-facing cart simply moves bad data closer to checkout.

    Audit product data as if it were the storefront

    An unbranded jacket, variant swatches, packaging, inventory objects, and a magnifying lens are arranged for a detailed product data audit.

    An agent cannot walk a virtual aisle and infer that a stale price is probably wrong. It receives representations of your inventory and has to make decisions from them. Because the catalog capability is designed to expose real-time pricing, inventory, and variant information, conflicting product facts become a commercial problem, not merely a feed-cleanup task.

    Start with one product family that has meaningful variation. A product with size, color, configuration, or member pricing will reveal more than a simple item with one price and one stock state. Trace it through every system an agent-assisted purchase could touch.

    1. Resolve the identity chain. Confirm that the parent product, each purchasable variant, the catalog record, the product page, and the cart line resolve to the intended item. A parent identifier should not silently stand in for a specific variant at purchase time.
    2. Name the source of truth for each commercial fact. Decide which system owns price, sale price, inventory, variant attributes, and account benefits. If two systems can overwrite the same fact, document precedence and failure handling.
    3. Compare anonymous and authenticated states. Check whether public pricing, member pricing, shipping benefits, and eligibility rules remain distinguishable. The agent should not present a conditional benefit as universal.
    4. Test change propagation. Change a price or inventory state in the owning system and observe every downstream representation. Record your actual delay and failure points rather than relying on the intended architecture.
    5. Inspect contradictions. Compare the catalog, rendered product page, structured data, basket, and logged-in experience. Any disagreement can lead to a poor recommendation, a rejected add-to-cart action, or an unpleasant price change at checkout.
    6. Log failed and stale updates. A synchronization process that usually works is not enough. Your team needs a way to identify which products failed, when the last successful update occurred, and which downstream surfaces may still carry old information.

    This is also where SEO, GEO, and feed teams should coordinate. Keep descriptive content and structured data consistent with commercial systems, but do not add unsupported claims to markup merely to make the product look more complete to an AI system. The safest machine-readable answer is the same answer the shopper will receive in the cart.

    Do not call the audit complete because a sample record validates syntactically. A valid record can still identify the wrong variant, carry an old price, or point to inventory that cannot be purchased. Validation checks form; transaction tests check truth.

    Roll out the smallest capability you can verify end to end

    A coffee maker follows one illuminated path through catalog, inventory, basket, payment, and delivery modules while unused modules remain dark.

    Catalog readiness is usually the sensible first workstream because cart and identity experiences depend on accurate merchandise data. That is a sequencing recommendation, not a protocol requirement. Your architecture may justify a different order, but every pilot should have one defined capability, one accountable owner, and an observable pass or fail condition.

    1. Choose a bounded product set. Select products that expose the problems you need to solve, including variants or conditional benefits, while keeping the pilot small enough to inspect manually.
    2. Capture a baseline. Record current catalog mismatches, failed add-to-cart actions, unavailable variants presented as purchasable, and benefit-entitlement failures. Without a baseline, protocol activity can look like progress while customer-facing accuracy remains unchanged.
    3. Define acceptance tests before integration. Write expected results for price changes, inventory changes, variant selection, multi-item baskets, account linking, and entitlement loss. Include negative cases, not just a successful purchase.
    4. Test the cart as a changing object. The new cart capability is intended to let agents place multiple products from one retailer into a single basket. Verify what happens when quantity changes, one line becomes unavailable, a promotion expires, or the shopper switches variants.
    5. Isolate identity testing. Identity linking can preserve member pricing and free shipping, but it also touches account access and personal data. Use controlled test accounts and obtain security, privacy, and legal approval before exposing real customer identities. The specific downside of rushing this step is not just a broken discount; it can be unauthorized account access or inappropriate data sharing.
    6. Monitor outcomes by failure stage. Separate catalog retrieval, variant resolution, cart creation, cart mutation, authentication, entitlement, and checkout failures. A single conversion total will not tell you which capability needs repair.

    Your ownership model matters as much as the integration. Feed operations can correct a variant mapping but should not define authentication policy. SEO can identify contradictions visible to search systems but should not own checkout integrity. Ecommerce engineering can make a cart function without knowing whether member benefits are represented correctly. Put these teams behind one shared test plan rather than handing UCP to whichever team first notices it.

    Google has also indicated that it plans to simplify UCP onboarding through Merchant Center. Use that as a reason to prepare your data and test cases, not as a reason to assume that implementation is already automatic. When onboarding becomes available to you, confirm supported capabilities, required fields, market coverage, permissions, and reporting from the documentation presented in your account.

    Most importantly, do not report UCP adoption as an SEO win by itself. There is no basis here for calling it a guaranteed ranking factor or recommendation boost. Measure what you can actually observe: eligibility, accurate product representation, successful basket creation, preserved benefits, completed purchases, and the failure rate at each handoff.

    Key takeaways

    • UCP connects product discovery with live commerce functions; it is broader than page markup, feeds, or advertising alone.
    • Catalog accuracy is foundational because price, inventory, and variant errors can follow an agent directly into the cart.
    • Cart, catalog, and identity linking should be treated as separate capabilities with separate owners and tests.
    • Modular adoption lets you start with a bounded capability instead of waiting for a complete commerce-stack rebuild.
    • Identity linking requires controlled testing and security, privacy, and legal review before real customer accounts are involved.
    • Protocol adoption does not establish a ranking or recommendation benefit. Evaluate transactional accuracy and measurable outcomes.

    Your best next step is concrete: take one high-value product family with variants, compare its catalog record, product page, structured data, cart, and logged-in benefits, then document every contradiction. That exercise will tell you whether your first UCP project is an integration project or, more likely, a product-data repair project that needs to happen before integration can deliver anything useful.

    References

  • Google Shopping AI Overviews: A Practical Ecommerce Plan

    Google Shopping AI Overviews: A Practical Ecommerce Plan

    Your ecommerce rankings can look stable while the search journey changes above them. When an AI Overview answers a product question, compares options, or frames the buying decision, your organic result and Shopping placement may have to compete for attention later than they used to.

    This is no longer a fringe scenario. AI Overviews appeared on 2,919,229 of 20,900,323 shopping-related queries in a large visibility analysis. If product discovery matters to your revenue, you now need to audit AI Overview exposure alongside rankings, Shopping visibility, clicks, and conversions.

    What the 14% figure should change in your strategy

    The headline number needs a precise reading. The keyword set consisted of product-intent searches whose results contained a Shopping box, whether paid or organic. Queries included products and categories such as weighted blankets, mushroom coffee, protein powder, and blue T-shirts. Within that defined set, 14.0% produced an AI Overview.

    That does not mean every ecommerce site lost 14% of its traffic. It does not measure click loss, revenue loss, AI Overview citations, or the percentage of shoppers who saw the feature. It measures how often the feature appeared across the monitored keyword set. Treating penetration as a traffic-loss estimate would turn a useful warning signal into a bad forecast.

    The direction is still hard to dismiss. Penetration had been 2.1% in November 2025 before reaching 14.0% in the later sample. The practical implication is that ecommerce exposure cannot be judged from ten blue links, conventional rankings, or Shopping positions alone.

    Your first response should be measurement, not a sitewide rewrite. Establish which valuable queries trigger AI Overviews, whether your brand or pages appear in them, and what happens to clicks when they do. Until you separate those questions, you cannot tell whether you have an inclusion problem, a click-through problem, or no material problem at all.

    Key takeaways

    • The 14.0% figure describes AI Overview penetration within a large set of product-intent queries that also returned a Shopping box. It is not a universal ecommerce traffic-loss rate.
    • Audit exposure by query intent and commercial value. A high-value comparison query deserves more attention than dozens of low-value searches combined.
    • Keep visible product information, JSON-LD, and commerce feeds consistent. Structured data can clarify facts, but it cannot guarantee AI Overview inclusion.
    • Measure AI Overview presence, brand inclusion, organic click-through rate, and conversion separately. A single visibility score cannot diagnose all four.
    • Improve the pages that already match exposed queries before producing large volumes of new content.

    Map AI Overview exposure by query intent and value

    Three search pathways pass through a translucent AI layer, leading to a single product, a product comparison, and a shopping basket.

    A useful audit starts with the searches that already matter to your business. Export product-intent queries from Google Search Console, add priority terms from your keyword tracking, and connect each query to its most relevant category or product page. Include revenue or conversion value where you have it.

    Do not examine this as one undifferentiated keyword list. Label the job the shopper is trying to complete. The page requirements are different when someone is exploring a category, narrowing by an attribute, comparing alternatives, or verifying a particular product.

    Query patternShopper’s taskWhat the landing page should make clearCommon audit question
    Broad category, such as weighted blanketsUnderstand the category and available choicesScope, meaningful differences, selection criteria, and routes to relevant productsDoes the page help someone choose, or does it merely repeat the category name?
    Attribute-led, such as blue T-shirtsNarrow the catalog using a required featureMatching products, visible attributes, filters, variants, and accurate availabilityDo the page title, copy, filters, products, and structured data agree?
    Comparison or best-fit queryChoose between optionsFactual differences, limitations, intended use, and a defensible basis for comparisonCan every comparative claim be verified on the page?
    Branded or model-specific queryConfirm exact product detailsName, brand, model, identifiers, price, availability, variants, and offer detailsAre facts consistent across the visible page, markup, and feed?
    Use-case queryJudge whether a product fits a particular needSupported suitability information, constraints, specifications, and relevant alternativesDoes the page answer the use case without making claims the evidence cannot support?

    For every tracked query, record whether an AI Overview appears, which pages or products it includes, whether your brand is visible, the result type around it, and the observation context. Search results can vary by device, location, and observation time, so save those details instead of treating one check as permanent.

    Also distinguish an AI Overview from the Shopping box used to define the original keyword set. They are separate search features. Record whether the Shopping element is paid or organic when your tooling exposes that distinction, and avoid attributing every change in click-through rate to the AI Overview.

    Prioritize the intersection of commercial value and exposure. Start with queries that contribute meaningful impressions, clicks, sales, or assisted conversions and repeatedly show an AI Overview. A long list of exposed keywords is less useful than a short list tied to products and categories you can improve.

    Make product information easy to verify and reuse

    A generic countertop appliance is surrounded by dimension, material, packaging, warranty, and image symbols connected to blank search and storefront panels.

    AI-search optimization for ecommerce is not a request to turn every product page into an essay. It is a data-quality and decision-support problem. Your pages should make important product facts explicit, keep them consistent across systems, and answer the questions that determine whether a shopper considers the product relevant.

    Give category pages a decision-making job

    A category page should do more than display a grid. Add concise information that helps a shopper understand the range and move toward a suitable option. The right content depends on the category, but the audit can use the same questions:

    • Is the category defined clearly enough to distinguish it from adjacent categories?
    • Are the attributes that genuinely change the buying decision explained in plain language?
    • Can the shopper identify which product groups fit different needs, constraints, or preferences?
    • Do links lead directly to useful subcategories, filters, comparisons, or products?
    • Are limitations and eligibility conditions visible where they affect the choice?

    Keep this material specific to the products on the page. Generic buying-guide copy creates words without resolving uncertainty. If a paragraph could be pasted onto a competitor’s category unchanged, it is probably not carrying enough product information to help either the shopper or a retrieval system.

    Reconcile the product page, JSON-LD, and feed

    Review each priority product as one record expressed through several surfaces. The visible page is what a person reads. Product and Offer structured data describe machine-readable facts. A commerce feed may supply another version of the same product and offer information. Contradictions among those surfaces create ambiguity you can remove.

    Check the product name, brand, model, stable identifiers such as SKU or GTIN when available, variant attributes, price, currency, availability, and offer details. Use the same canonical facts everywhere. If the displayed price changes by variant, make that relationship clear rather than exposing one value in the page copy and another in JSON-LD or the feed.

    Structured data should describe information that is accurate and supported by the page. Do not add properties merely because they look relevant to AI search, and do not mark up promotional, review, or availability claims that a shopper cannot verify. JSON-LD improves clarity; it is not a switch that forces Google to cite, summarize, or rank a product.

    After the core facts agree, look for unanswered decision questions. These may involve dimensions, materials, compatibility, care, included components, variant differences, usage constraints, shipping conditions, or returns. Add only what is applicable and supportable for that product. The goal is not maximum page length. It is minimum ambiguity.

    Comparison content deserves the same discipline. State the criteria, compare equivalent attributes, and separate facts from editorial judgement. Avoid unsupported superlatives. A claim such as best, safest, or healthiest needs a defensible basis; repeating it in schema does not make it more trustworthy.

    Measure visibility, clicks, and sales as separate outcomes

    An AI Overview can affect several stages of search performance, and each stage calls for a different response. Build a small measurement framework rather than compressing everything into an AI visibility score.

    • Exposure rate: the share of your monitored shopping queries on which you observe an AI Overview.
    • Inclusion rate: the share of observed AI Overviews that include your brand, product, or URL under the inclusion rule you define in advance.
    • Organic response: impressions, clicks, click-through rate, and average position for the same query cohort.
    • Commercial response: conversions, revenue, lead quality, or another outcome appropriate to the catalog and buying journey.

    Keep the monitored query set stable when comparing periods. Segment by intent, landing-page type, device, country, and approximate ranking band where the data supports it. Otherwise, a shift toward broader queries or lower organic positions can look like an AI Overview effect even when the query mix caused the change.

    When you change a template or content cluster, record the release and preserve an unchanged comparison group when practical. Recheck the same queries and note other factors that could move results, including rankings, price, availability, promotions, seasonality, and changes to paid Shopping activity. This will not create perfect experimental control, but it will stop you from assigning every movement to the newest search feature.

    Use the results to choose the next action:

    1. No AI Overview on a valuable query: continue conventional SEO, merchandising, feed, and Shopping work. Keep monitoring rather than rebuilding the page for a feature you have not observed.
    2. AI Overview present, brand absent: inspect the decision the overview resolves and the information its included pages provide. Check whether your relevant page lacks supported facts, comparison context, clear entity information, or consistent commerce data.
    3. Brand included, clicks healthy: preserve the useful page elements and data consistency. Apply the pattern selectively to closely related pages instead of redesigning the whole site.
    4. Brand included, clicks weakening: create a stronger reason to visit. Useful inventory depth, live variants, a complete comparison, detailed specifications, a selector, original product information, or a clear offer may provide value that a short summary cannot.
    5. AI Overview appearance is inconsistent: gather more observations before making a major change. A single screenshot is evidence of one result state, not a durable performance trend.

    Start with one commercially important category. Freeze its query list, capture the current search layouts, correct disagreements among the page, JSON-LD, and feed, and improve only the decision questions the existing pages leave unresolved. Then measure that same cohort again. This gives your next catalog release a clear hypothesis and gives you evidence for what to scale.

    References

  • A Practical ChatGPT Shopping Strategy for Ecommerce Brands

    A Practical ChatGPT Shopping Strategy for Ecommerce Brands

    If your shopping plan starts and ends with getting products into a native ChatGPT checkout, it is aimed at a moving target. The more durable opportunity is to help ChatGPT understand your products, select them for the right shopping questions, and send an informed buyer into a purchase path that works.

    That distinction matters because OpenAI is reportedly moving Instant Checkout into Apps within connected services while putting more emphasis on product search and discovery. Your strategy should therefore separate AI discovery from transaction execution, then make the handoff between them consistent, trustworthy, and measurable.

    Treat ChatGPT as a decision channel, not merely a checkout

    A shopper rarely begins with your product identifier. They begin with a constraint: a budget, use case, compatibility requirement, delivery concern, size, material, feature, or reason another option did not work. ChatGPT can influence which products enter the shortlist before the shopper reaches a retailer.

    Build around three separate jobs:

    • Eligibility: Give AI systems enough accurate product information to determine when an item fits the request.
    • Selection: Supply clear evidence, limitations, comparisons, and policies that help the shopper choose among plausible options.
    • Conversion: Preserve the selected product, variant, price, and context when the shopper moves to your site or connected app.

    Do not combine these jobs into a single metric. A product can be recommended but lose the sale during the handoff. It can receive qualified visits but fail because the product page contradicts the information used during discovery. It can also convert well once visited yet remain absent from relevant AI answers because its differentiators are vague or inaccessible.

    This is not a theoretical distinction. OpenAI found that people were exploring products in ChatGPT but often completing purchases elsewhere, while only a handful of merchants fully used native ChatGPT checkout. That does not prove the same behavior in every category, but it is a strong reason not to make native checkout adoption your only definition of progress.

    Use a measurement ladder instead. Monitor whether your products appear for a stable set of relevant shopping questions. Track identifiable traffic from AI surfaces when a referrer, campaign parameter, or app link survives the handoff. Measure product-detail views, variant selections, add-to-cart actions, checkout starts, and purchases. Add a post-purchase discovery question if your analytics cannot observe the complete journey. Keep those signals separate so that a weak checkout does not get mistaken for weak discovery.

    Build a product truth layer before creating more content

    Three unbranded products sit above connected layers of color, size, material, inventory, compatibility, and shipping symbols.

    AI shopping optimization breaks when the same product has different facts across its page, structured data, feed, app, and checkout. A persuasive description cannot compensate for conflicting prices, ambiguous variants, or stale availability. Establish one operational product record and make every public representation inherit from it.

    For each product and variant, maintain the fields a buyer actually needs to make a decision:

    • A stable product identifier, variant identifier, canonical URL, and exact product name.
    • Brand, category, intended use, defining features, dimensions, materials, compatibility, and other category-specific attributes.
    • Current price, currency, availability, condition, and a clear relationship between the parent product and its variants.
    • Images that correspond to the selected variant rather than a generic family image.
    • Shipping scope, fulfillment limitations, return conditions, warranty terms, and any purchase restrictions that can change the decision.
    • Evidence for material claims, with unsupported superlatives and vague labels removed.

    Use Product and Offer JSON-LD to represent applicable facts in a machine-readable form, but treat markup as a copy of the truth rather than a separate marketing layer. The name, price, currency, availability, URL, image, brand, SKU, and offer details in the markup should agree with the visible page. If a rating, price range, or availability claim is not supported on the page, do not manufacture it in structured data.

    JSON-LD is also not an inclusion switch for ChatGPT. It reduces ambiguity and gives machines a cleaner representation of the page; it does not guarantee that a product will be discovered, recommended, or ranked. Visible product copy still needs to explain fit, tradeoffs, and purchase conditions in language a shopper can understand.

    Catalog synchronization deserves the same attention as schema. Normalizing real-time catalog information across large numbers of SKUs remains an infrastructure problem. Prevent it from becoming a customer-facing problem by assigning ownership for every field, documenting which system is authoritative, and defining what happens when feeds disagree.

    Before expanding the work, run a sampled audit that compares the visible page, rendered JSON-LD, feed output, app view, cart, and checkout. The release gate should be simple: no sampled price, currency, availability, product identity, or variant mismatch. If you cannot meet that gate, adding more discovery content will amplify unreliable information.

    Create pages around shopping constraints, not keyword permutations

    A conventional product page often describes what an item is without explaining when someone should choose it. ChatGPT shopping questions tend to expose that gap because the user can combine several conditions in one request. Your content needs to resolve those conditions explicitly.

    Build a question map from the language already present in customer support, on-site search, product reviews, returns, sales conversations, and merchandising filters. Group the questions by decision type:

    • Fit: Who is this product for, and when is another option more suitable?
    • Compatibility: What systems, sizes, accessories, materials, environments, or use cases does it support?
    • Tradeoffs: What does the buyer gain, and what must they accept in exchange?
    • Comparison: Which factual criteria distinguish this item from the closest alternatives?
    • Purchase conditions: What will shipping, setup, returns, replacement, or ongoing use require?

    Map each question to the most appropriate page instead of forcing every answer into the product description. Put item-specific facts on the product page. Use category pages to explain selection criteria. Use comparison pages when buyers repeatedly choose between named options. Use support content for setup and compatibility details, then link it directly from the commercial page.

    On a product page, answer the decision in a useful order: state the best-fit use case, show the facts supporting that fit, disclose meaningful limitations, explain the available variants, and present the purchase conditions. A clear not-suitable-for statement is often more useful than another paragraph of universal claims. It helps an AI system and a human buyer avoid a recommendation that will produce a return or a poor experience.

    Comparison content should define the decision rule before declaring a winner. If the correct choice changes with budget, environment, compatibility, or desired feature, say so. Do not create a false universal ranking merely to target a best-product query. A conditional answer is more accurate and more reusable across the specific prompts shoppers actually ask.

    Keep decisive facts in visible HTML. Structured data can reinforce those facts, but it should not contain essential claims that a shopper cannot verify on the page. The same principle applies to FAQs: publish them when they answer recurring purchase questions, not as a container for hidden keyword variants.

    Make the external handoff trustworthy and measurable

    An unbranded product crosses an illuminated bridge from an AI conversation portal to a storefront with security, delivery, and analytics symbols.

    The handoff is now a core part of ChatGPT shopping strategy. If discovery occurs in an AI conversation and the purchase occurs in a retailer app or site, any lost product context creates friction at the point of highest intent.

    Resolve links to the exact product and selected variant whenever the originating surface provides that context. Show the same name, image, price, availability, and offer conditions the shopper just encountered. Keep return and shipping information easy to find before checkout. Avoid sending a buyer to a category page where they must reconstruct the selection from scratch.

    Trust matters alongside technical capability. Consumers are accustomed to familiar purchase processes such as Apple Pay, Google Wallet, and Amazon. An external checkout is not automatically a strategic failure if it gives the buyer a recognizable, reliable place to complete the transaction. The failure is an external handoff that changes the offer, loses the variant, hides important terms, or cannot be measured.

    Instrument the journey with a shared product and variant identifier across the landing view, variant selection, add-to-cart, checkout start, and purchase events. Add campaign parameters to links you control, but do not depend on referrer data alone. App transitions and privacy controls can interrupt the chain. Use session-level analytics, transaction data, and a customer-reported discovery field to create a more defensible view.

    Run a narrow pilot before rebuilding your commerce stack:

    1. Select a category in which buyers ask meaningful comparison or compatibility questions.
    2. Audit the product truth layer and correct disagreements across pages, schema, feeds, apps, carts, and checkout.
    3. Create or revise content for the real constraints that determine product fit.
    4. Test every discovery-to-product link, including variant resolution, offer consistency, mobile behavior, and return paths.
    5. Record baseline discovery, referral, engagement, cart, checkout, and purchase signals before judging the pilot.
    6. Review failed recommendations and abandoned handoffs as separate problems, then fix the layer responsible for each one.

    Keep the Agentic Commerce Protocol on your standards watchlist because OpenAI is continuing its work with Stripe on the protocol as transactions move toward connected-service Apps. That is a reason to preserve clean, portable product and offer data. It is not a reason to commit your full catalog or checkout roadmap before the integration can maintain product accuracy, customer trust, and usable measurement.

    Expand only when the pilot can answer three operational questions: Did the right products appear for the right constraints? Did the landing experience preserve what the shopper selected? Did qualified AI-led visits produce downstream commercial actions? If one answer is unclear, improve its measurement before scaling.

    Key takeaways

    • Optimize first for accurate product discovery and selection; native ChatGPT checkout is not the only route to value.
    • Separate eligibility, selection, and conversion so you can locate the actual failure in the journey.
    • Create one product truth layer and keep visible pages, JSON-LD, feeds, apps, carts, and checkout consistent.
    • Answer fit, compatibility, tradeoff, comparison, and purchase-condition questions in visible content.
    • Treat an external checkout as a designed handoff, preserving the exact product, variant, offer, and measurement context.
    • Pilot connected commerce narrowly and expand only after catalog accuracy, customer trust, and attribution are working together.

    Start with a narrow product category and inspect the journey from a constrained shopping question through the completed order. Fix the first point where product truth, decision support, or handoff context breaks. That work will remain useful whether ChatGPT sends the transaction to your site, a connected app, or a future commerce protocol.

    References

  • How ChatGPT Shopping Triggers and Product Sourcing Work

    How ChatGPT Shopping Triggers and Product Sourcing Work

    If you’re trying to get a product into ChatGPT’s shopping carousel, start by identifying which part of the system is failing. A purchase-oriented prompt must first activate a shopping response. Only then does product sourcing determine which items appear.

    That gives you two separate jobs: test the prompts that open the shopping experience, then improve product visibility in the systems supplying the carousel. Treating both jobs as one leads to wasted content changes, misleading screenshots, and rankings that never translate into inclusion.

    Separate the shopping trigger from the product source

    Shopping is a relatively rare response mode. During nine months of prompt tracking, fewer than 10% of prompts produced shopping, while 79% never activated a shopping response. A query can sound commercial to you and still fail to open the shopping interface.

    Once shopping activates, a different process decides what fills the carousel. Across more than 40,000 observed carousel products, 83% could be tied to Google Shopping through shopping query fan-outs. Those figures describe different populations, so don’t multiply them or treat product sourcing share as the probability that an arbitrary prompt will show shopping.

    LayerQuestion to answerWhat to measure
    TriggerDoes this exact prompt activate shopping?Shopping response present or absent, followed by a next-day retest
    SourcingWhich product system appears to supply the carousel?Carousel overlap with Google Shopping results for related queries
    SelectionWhy does one eligible product appear instead of another?Google Shopping position, product-data consistency, and unexplained selection gaps

    This separation also explains why a conventional SEO win may not produce a carousel win. Shopping fan-outs appear to use a distinct retrieval path from standard search fan-outs. Your category page can perform well as an informational result while your products remain weak or absent in the shopping pipeline.

    Test shopping intent as a matrix, not a magic keyword

    Top-down illustration of blank prompt cards arranged in a testing grid, with several cards activating generic product symbols.

    There is no supported universal phrase that forces ChatGPT to shop. Build a prompt matrix around the purchase decisions your customers actually make. The templates below are experimental cells, not guaranteed triggers:

    • Category discovery: “best [category] for [use case]”
    • Budget constraint: “best [category] under [budget]”
    • Feature constraint: “[category] with [feature] for [audience or situation]”
    • Product comparison: “[product A] vs [product B] for [use case]”
    • Replacement search: “alternative to [product] with [constraint]”
    • Exact-product shopping: “where can I buy [brand, model, and variant]?”

    Build the first version from language in onsite searches, support questions, sales conversations, and product reviews. Preserve the customer’s wording instead of converting every query into polished SEO language. You are trying to model a real buying conversation.

    Run each prompt in a clean conversation and record the exact wording. Change one element at a time: the use case, constraint, category, product, or comparison. If you change several elements together, a new carousel won’t tell you which change mattered.

    Internal shopping fan-outs tend to be shorter and more item-specific than ordinary search fan-outs. Do not confuse those internal retrieval queries with the user’s full prompt. Copying a conversational prompt word for word into product titles is therefore a weak strategy. Make the product easy to identify for concise category, model, feature, and variant queries instead.

    When a prompt activates shopping, repeat it unchanged the following day. A previously successful trigger had an 83% chance of triggering again on the next day, which makes short-term retesting useful but does not make the behavior permanent. Prompt-level tracking is more informative than a broad label such as “laptops trigger shopping” because two superficially similar requests can behave differently.

    Use trigger testing to map demand, not to promise a user-interface outcome. You can create pages that answer a purchase question clearly, but no wording change on your site can guarantee that ChatGPT will activate its shopping experience for someone else’s prompt.

    Treat Google Shopping visibility as a distribution requirement

    Google Shopping is the practical starting point once you have confirmed that a target prompt can trigger a carousel. In the observed matches, almost 84% appeared within Google’s top 20 organic shopping positions. Only 0.16% of products were exclusive matches with Bing, making Bing-only optimization a poor first response to a missing ChatGPT product.

    The word “organic” matters. These observations do not establish that buying Google Shopping ads buys placement in ChatGPT. Paid campaign performance and organic product visibility should remain separate measurements unless you have evidence connecting them in your own results.

    Audit the distribution layer in this order:

    1. Confirm that the exact product and variant are visible in Google Shopping for the market you are testing. A neighboring model or a different retailer’s offer does not establish visibility for yours.
    2. Search with concise item and attribute combinations related to the target prompt. These are better proxies for item-specific fan-outs than the entire conversational question.
    3. Record the product’s position for each proxy query. Visibility within the top 20 is a useful diagnostic benchmark because most observed matches came from that range, but it is not a guarantee of ChatGPT inclusion.
    4. Check that the product feed and landing page agree on brand, model, variant, price, availability, and the attributes that distinguish the item. Conflicting facts make the offer harder to identify reliably.
    5. Make the product title specific enough to separate one offer from another. Include meaningful model and variant information, but do not turn the title into a list of every possible query.
    6. Recheck the live product page after feed changes. A corrected feed paired with stale or contradictory page content leaves the underlying identity problem unresolved.

    Product structured data belongs in this consistency work. Use Product schema to express the same facts that users and shopping systems see on the page. However, no direct role for JSON-LD as a ChatGPT shopping trigger was demonstrated here. Schema is machine-readable hygiene, not a switch that forces carousel inclusion.

    Rank also does not explain every selection. If a product is consistently visible for relevant Google Shopping queries but remains absent from triggered carousels, examine context around the item: whether the use case fits, whether the selected variant matches the constraint, and whether product sentiment may differ from competing choices. Sentiment is a hypothesis to test, not a proven ranking factor, so address genuine reputation or product issues rather than manufacturing reviews or mentions.

    Build monitoring that survives model changes

    Illustration of a monitoring console tracking product cards through a modular shopping pipeline while one module is replaced.

    A single carousel screenshot is evidence of one response, not durable visibility. Trigger behavior can persist from one day to the next, yet model updates have coincided with overnight resets. When the model or shopping experience changes, rebuild the baseline instead of comparing the new state with an old experiment as though nothing changed.

    Keep one row for every exact prompt and record:

    • The complete prompt, including constraints and product names.
    • The intent family, such as category discovery, comparison, replacement, or exact-product lookup.
    • Whether shopping activated.
    • Whether the same prompt activated shopping on the following day.
    • The products and retailers shown, in their displayed order.
    • Whether your product appeared and whether the correct variant was shown.
    • Your approximate Google Shopping position for the related short, item-specific queries.
    • Any conflicting price, availability, model, or variant information.
    • The model or interface state visible during the test, especially when a broad change appears across many prompts.

    Calculate each metric with the right denominator. Shopping activation rate is the share of tested prompts that produced shopping. Brand inclusion rate is the share of triggered carousels containing your product. Next-day persistence is the share of successful triggers that remained successful when retested. Keeping those rates separate tells you whether the problem is demand activation, sourcing, or selection.

    Classify the failure before changing anything

    • No shopping response: work on the trigger test. Try a more explicit buying task or a single meaningful constraint, while preserving the original prompt as your control.
    • Shopping appears, but your product is weak in Google Shopping: fix product distribution, data quality, and query-level visibility before changing editorial content.
    • Your product appears with the wrong facts or variant: reconcile the feed, retailer offer, landing page, and structured data.
    • Your product ranks strongly in relevant shopping results but remains absent: investigate selection context, product fit, and reputation as hypotheses. Do not assume rank alone guarantees inclusion.
    • Many previously stable prompts change together: mark a new baseline and rerun the full prompt set. The trigger system may have changed, so isolated page edits are unlikely to explain the pattern.

    This diagnostic order prevents the most common strategic error: editing content when the prompt never triggered shopping, or rewriting schema when the product simply lacked competitive Google Shopping visibility.

    Key takeaways

    • ChatGPT shopping visibility has at least two distinct gates: the prompt must trigger shopping, and the sourcing pipeline must select the product.
    • Shopping activated for fewer than 10% of tracked prompts, so measure exact purchase-intent prompts instead of assuming every commercial query opens a carousel.
    • A successful trigger is often repeatable the next day, but model changes can reset the pattern. Retest after any broad shift.
    • Google Shopping is the main sourcing priority supported by current observations: 83% of analyzed carousel products could be tied to it, and most matching products appeared in its top 20 organic shopping positions.
    • Neither paid Shopping ads nor Product schema has been established as a direct route into ChatGPT carousels. Keep product data consistent, but don’t treat either as a guaranteed trigger.
    • Measure trigger rate, brand inclusion, next-day persistence, and Google Shopping visibility separately. The first failing metric tells you where to work.

    Start with the purchase questions your customers already ask. Establish whether each one activates shopping, inspect the sourcing layer only after it does, and fix the first point of failure. That sequence turns ChatGPT shopping optimization from a screenshot hunt into a manageable distribution and measurement process.

    References