Tag: Commerce

  • Google AI Commerce: How Ecommerce Brands Stay Visible

    Google AI Commerce: How Ecommerce Brands Stay Visible

    Your product can hold a respectable search position and still lose the sale before a shopper reaches your site. When an AI system interprets the need, compares the options, chooses an offer and potentially handles checkout, the decisive visibility event happens upstream of the click.

    You now need to make each product easy for an agent to find, understand, select and transact. That means treating product truth, recommendation fit and operational readiness as parts of SEO rather than leaving them to separate catalog, merchandising and checkout teams.

    The sale can now be won before a site visit happens

    The familiar ecommerce journey starts with a query, moves through a search result and ends on a merchant-controlled product page or checkout. Google’s AI commerce direction compresses that journey. Its Universal Commerce Protocol enables AI agents to discover, evaluate, recommend and purchase products across the web within Google’s AI experiences.

    UCP matters because it is not an isolated shopping widget. Its launch collaboration included Shopify, Etsy, Wayfair, Target and Walmart, with existing payment networks incorporated. Google also introduced three related commerce surfaces: Business Agent for brand-specific conversations in Search and Gemini, Direct Offers for promotions inside AI Mode, and Checkout in AI Mode for purchases completed within Google’s interface.

    For you, the important shift is from ranking alone to selection. A conventional ranking report asks whether a URL appeared and received a click. AI commerce requires four different questions:

    Visibility stageQuestion to answerTypical failure to investigate
    EligibilityCan the system find and use the product record?The item, variant or offer is absent, inaccessible or unsupported.
    InterpretationCan it identify exactly what the product is?Names, identifiers, attributes, prices or availability conflict.
    SelectionCan it explain why this product fits the shopper’s need?The catalog describes the item but not its use, constraints or differences.
    TransactionCan the selected offer be purchased successfully?The offer is stale, the variant is unavailable or the handoff fails.

    Your website remains important. It may still be the clearest public expression of your product facts, policies and brand expertise. But a polished page cannot compensate for exclusion at the eligibility stage, contradictory data at the interpretation stage or weak product fit at the selection stage. Diagnose the stage that failed before rewriting copy or increasing media spend.

    Build a product truth layer before optimizing recommendations
    A running shoe is connected to organized product details, inventory, shipping and verification symbols above a foundation of data blocks.

    The first job is agreement, not persuasion. Your page, structured data, catalog feed, commerce platform, inventory system and checkout should describe the same purchasable item. If they disagree, an agent has to decide which representation to trust while the shopper sees only the result.

    Create a field-level catalog audit. For each commercially important product and variant, record the canonical system, the surfaces that publish the field, the event that refreshes it and the person responsible when synchronization fails. Inspect at least these groups of information:

    • Identity: product name, brand, internal identifier, SKU and any supported external identifier.
    • Variant definition: the attributes that distinguish one purchasable option from another, such as size, color, configuration or quantity.
    • Offer state: current price, currency, discount terms, availability and the exact variant to which each value applies.
    • Product facts: materials, dimensions, included components, compatibility, care requirements and other attributes the shopper may use to rule an option in or out.
    • Fulfillment facts: the shipping, pickup or delivery conditions your operation can actually honor.
    • Policy facts: the conditions that affect the decision or the completed order, including relevant return, cancellation and warranty terms.

    This is not a claim that every field is a UCP requirement. It is a practical inventory of the commercial truths that discovery, comparison and checkout systems must keep straight. Match the audit to the fields, integrations and eligibility rules that apply to your own platform setup.

    Keep identifiers and variants stable

    Variant ambiguity is particularly costly. A parent product may be available while the size or configuration the shopper wants is not. If the parent page, structured data and feed collapse those states into one generic record, the system can recommend an option that cannot be purchased.

    Use stable identifiers for the same item everywhere. Do not casually recycle an identifier after replacing a product, merge materially different variants into a single offer or use different names for the same attribute across systems. When a product changes enough that compatibility or customer expectations change, treat identity as a catalog decision rather than a copy edit.

    Make freshness an operating rule

    Price and availability are state, not static content. Document what event updates each downstream representation: an inventory change, a promotion activation, a price revision or a product withdrawal. Then define what happens when the update does not arrive. A safe failure may mean suppressing an uncertain offer until it is reconciled instead of continuing to advertise a price or item you cannot honor.

    Test a real purchasable variant from end to end. Compare its visible page, Product and Offer structured data where used, feed record, API response, cart and checkout. Search for disagreement in identifiers, price, currency, availability and variant labels. A valid schema block does not make a stale price true; structured data is a machine-readable representation of your commerce record, not a substitute for one.

    Give the recommendation system reasons to choose you

    Traditional product copy often assumes that the shopper already knows the category and is comparing familiar options. Conversational shopping starts earlier. Gemini can turn requests such as planning a camping trip or removing wine from a couch into product discovery based on inventory, price and availability. The initial language may describe a problem or outcome without naming a product category.

    A catalog full of short, near-duplicate descriptions gives an agent little basis for matching those needs. Add decision information that helps it distinguish fit. For each priority product, make the following explicit in visible, accurate language:

    • What the product is, without relying on a clever product name to carry the definition.
    • Which use cases it is designed for and which product attributes support those uses.
    • Which shopper, environment or constraint it suits.
    • What it requires to work, including compatibility, installation or complementary components where relevant.
    • How it differs from nearby options in your own range.
    • When another option is a better fit.
    • Which claims are factual and where the supporting evidence appears.

    The last two points deserve attention. If every item is described as the best choice for every buyer, none of the descriptions provides a useful selection boundary. A clear exclusion such as an incompatible device, unsuitable environment or missing feature can improve recommendation fit by preventing the wrong product from being chosen.

    Do not turn this into an exercise in manufacturing question-and-answer text or repeating likely prompts. Write complete product facts and decision criteria in the language customers use. The goal is not to imitate a chatbot. It is to remove the inference a chatbot would otherwise have to make.

    Make category pages do comparison work

    A product page can explain one item well while the category still fails to explain choice. Build category content around meaningful differences: intended use, decisive attributes, compatibility, level of capability and tradeoffs. If two products differ only in internal merchandising language, rewrite the distinction so a customer can tell why both exist.

    Use comparison tables only when the attributes are genuinely comparable. Keep values normalized, name units and avoid leaving a blank cell when the real meaning is unknown, not applicable or not included. Those states lead to different decisions and should not be collapsed into the same empty space.

    Prepare each AI commerce surface as a separate operation
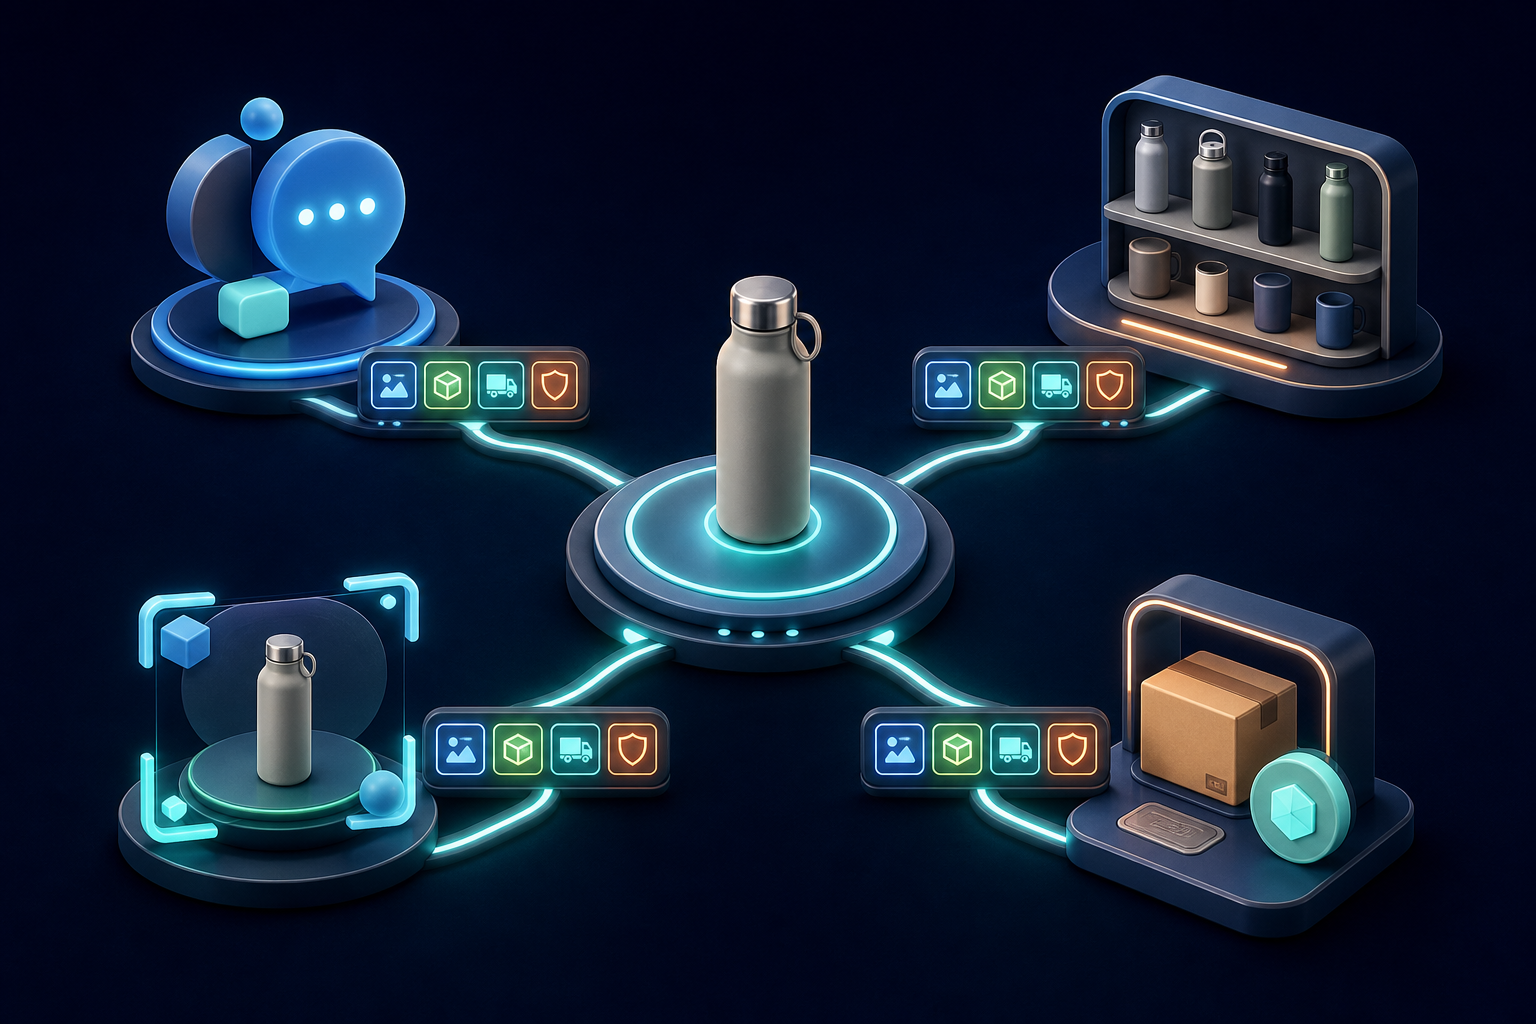
    A travel bottle on a central operations hub connects to conversational, comparison, visual discovery and checkout surfaces through separate readiness gates.

    Business Agent, Direct Offers and Checkout in AI Mode affect different parts of the buying journey. Do not assume that connecting one surface makes the others accurate or operational. Give each capability an owner, a source of truth, an approval boundary and a failure procedure.

    Business Agent needs governed brand knowledge

    Business Agent acts as an AI-powered brand representative in Search and Gemini, where shoppers can ask about products, compare choices and receive brand-specific guidance without opening a separate site. That makes answer quality part of merchandising and reputation management, not merely customer support.

    Start by identifying the questions that materially change a purchase: suitability, compatibility, differences between models, included components, availability and relevant policies. Map each answer to an approved source. Decide which claims can be stated directly, which require conditions and which should not be made. When an answer depends on information the agent cannot reliably access, provide a safe path to verification rather than filling the gap with promotional language.

    Audit the agent as a buyer would use it. Ask underspecified questions, add a constraint, change a variant and challenge a recommendation. Check whether the answer preserves the constraint, cites the correct product facts and avoids promising unavailable stock or unsupported capabilities.

    Direct Offers need commercial controls

    Direct Offers allow merchants to put exclusive discounts into AI Mode, placing the promotion inside the recommendation environment. That can make offer quality part of selection, but it also introduces margin and customer-expectation risk.

    Every offer should have an unambiguous product or variant scope, eligibility rule, valid period, discount definition and fallback state. Confirm that the same terms reach the agent, cart and order system. If the promotion cannot be honored at checkout, suppress or correct it rather than relying on fine print after selection. An expired or mis-scoped offer can turn added visibility into support costs, cancellations and lost trust.

    Checkout in AI Mode needs order-level testing

    Checkout in AI Mode moves purchase completion into Google’s interface. Your storefront may no longer control every step or observe a conventional browsing session before the order. Test the transaction as an operational flow: selected variant, current price, inventory reservation, payment status, tax and delivery handling, order creation, confirmation, cancellation and returns.

    Do not begin with your entire catalog merely because the integration permits broad coverage. A bounded set of products with clean data, dependable inventory and understood margins gives you a safer place to verify order routing and exception handling. Commerce automation can create real financial exposure when a discount, stock state or fulfillment promise is wrong, so expand only after the failure path works as well as the happy path.

    Measure AI visibility as a decision journey

    Rankings, clicks and onsite conversion rate still describe part of ecommerce performance. They do not tell you whether an agent found the product, interpreted it correctly, recommended it for the right need or completed the purchase without a traditional visit. Keep the established metrics, but add observations for the stages you can now lose before the click.

    • Catalog coverage: which priority products and variants are eligible for the commerce surfaces you use.
    • Data consistency: whether identity, price, availability and offer terms agree across exposed systems.
    • Recommendation presence: whether your product appears for a controlled set of relevant buyer needs.
    • Recommendation accuracy: whether the explanation, constraints and selected variant match the underlying product facts.
    • Offer integrity: whether the displayed promotion remains valid through checkout.
    • Transaction quality: whether the order is created correctly and can be fulfilled without avoidable correction, cancellation or support intervention.
    • Commercial quality: whether the resulting order remains worthwhile after discounts, fulfillment costs, returns and service demands.

    Use the telemetry your platforms actually expose, and do not manufacture precision where reporting is incomplete. A repeatable observation log can still reveal problems. Record the shopper need, constraints, region or language, date, products surfaced, recommendation wording, displayed offer and any incorrect claim. Run the same scenario after a meaningful catalog or content change. A single conversation is an example, not proof of sustained visibility.

    Prioritize changes by stage. If the product is absent, investigate eligibility and data delivery. If it appears with wrong facts, fix the truth layer. If the facts are right but the fit is unclear, improve decision content. If selection succeeds but the order fails, stop rewriting pages and repair the transaction path.

    Key takeaways

    • Google AI commerce visibility spans eligibility, interpretation, selection and transaction, not only rankings and clicks.
    • Product pages, structured data, feeds, inventory systems and checkout must agree on the identity and current state of each variant.
    • Useful product content states use cases, constraints, compatibility, differences and exclusions so an agent has a defensible reason to recommend the item.
    • Business Agent, Direct Offers and Checkout in AI Mode need separate ownership, controls and failure procedures.
    • Measurement should connect recommendation presence and accuracy to valid offers, successful orders and commercial outcomes.

    Choose a commercially important category and trace a real variant from product record to recommendation and completed order. Log every contradiction, missing decision fact and broken handoff. Fix that path before expanding coverage. The brands that become easier for AI to choose will be the ones that make product truth operational, not merely publish more content.
    References

  • Google Ads Updates: Audit Creative and Conversion Signals

    Google Ads Updates: Audit Creative and Conversion Signals

    Google can now surface videos automatically inside Merchant Center, while eligible Google Ad Grants accounts can make shop visits a primary goal. One change expands the creative Google can see. The other expands the outcome its bidding systems can pursue.

    If you manage a retail or nonprofit account, your next move should not be to accept every imported asset or enable every available goal. First determine what Google can now use, whether it represents the organization accurately, and what campaign behavior you are authorizing.

    Two updates, two different control points

    The Merchant Center change affects campaign inputs. The Ad Grants change affects campaign objectives. That distinction determines who should review each update and what can go wrong if nobody does.

    Platform changeWhat is newThe decision you need to make
    Merchant Center Video AssetsThe previously empty area is being populated automatically, including with videos from YouTube.Which discovered videos are accurate, current, and suitable for commerce campaigns?
    Google Ad Grants shop visitsEligible accounts can include store visit conversions in their primary account goals.Should automated optimization prioritize physical attendance alongside, or instead of, existing online outcomes?

    The connecting theme is delegation. Google is doing more to discover usable creative and letting advertisers optimize toward an outcome closer to real-world activity. Your work moves upstream: govern the inputs, define the outcome hierarchy, and verify what the system actually did.

    Audit auto-populated videos as potential ad inventory

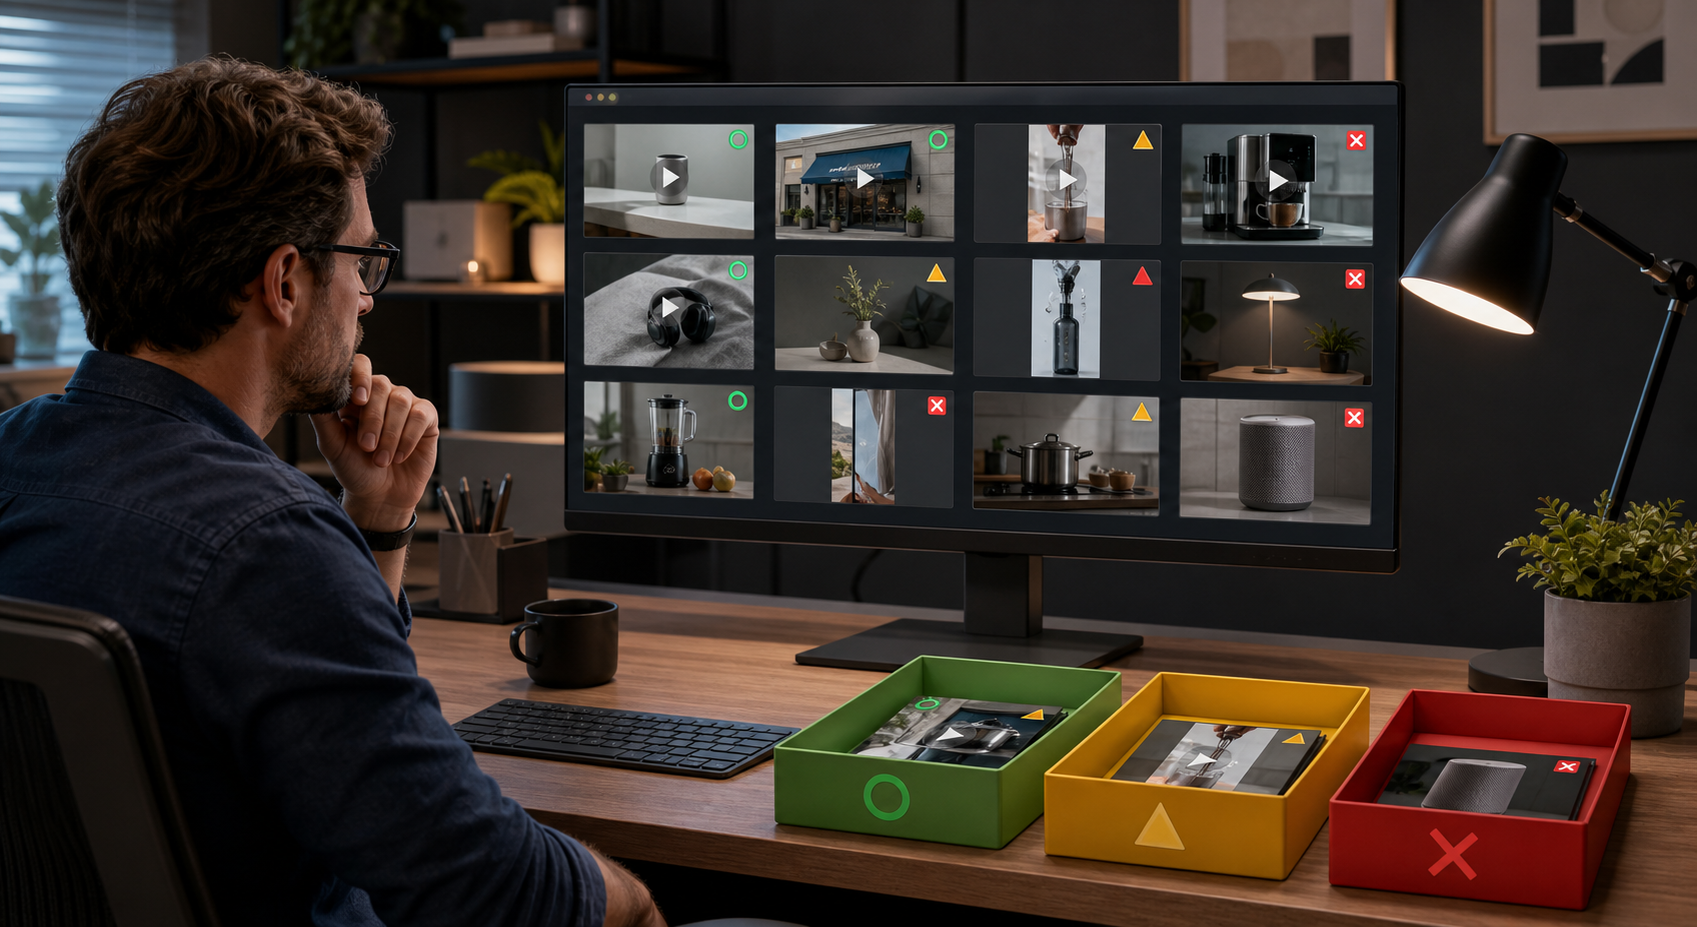
    A content manager sorts generic product and storefront video previews into separate review trays at a desk.

    Google previewed the Merchant Center Video Assets area at Google Marketing Live 2025. The rollout began in September, but the section remained blank for many users before populated libraries started appearing. That progression matters because the interface is no longer just a placeholder. It is now an operational surface that retail teams need to review.

    Automatic discovery reduces upload work, but it also changes the failure mode. An old demonstration, expired promotion, superseded product, or video created for a different audience can enter the creative workflow without anyone deliberately adding it to that screen. Treat the library as a review queue, not a quality endorsement.

    1. Record what appeared. Create a review sheet with the visible video title, apparent origin, relevant product or category, owner, and review status. If the interface does not expose a field you need, mark it unknown instead of guessing.
    2. Confirm the authoritative version. Identify whether the asset comes from an official YouTube presence or another approved business source. Duplicate edits and abandoned channel uploads are easy to mistake for current creative.
    3. Check every commercial claim. Compare product names, availability, model references, prices, promotions, and calls to action with the current product feed and destination page. A polished video is still unsafe to use if its facts have expired.
    4. Watch it as an ad, not as archived content. The product and brand should be identifiable without relying on surrounding page copy. The main point should remain understandable when audio is unavailable, and the clip should not depend on an earlier episode or presentation for context.
    5. Classify it internally. Use clear statuses such as commerce-ready, correction required, and not intended for advertising. Assign an owner and a reason for every non-ready classification.
    6. Review changes at the source carefully. A YouTube video may serve customer support, education, or organic discovery even when it is unsuitable for an ad. Do not remove or rewrite a useful source asset merely to tidy Merchant Center until you understand the effect on its other uses.

    A populated library does not prove delivery

    Performance reporting and optimization controls in the Video Assets area remain open questions. The presence of a video confirms that Google discovered it. It does not, by itself, prove that the video was selected, served in Shopping or Performance Max, or influenced campaign results.

    Keep three states separate in your reporting: discovered in the library, permitted or selected through the controls available to your account, and confirmed as served in campaign reporting. Without that distinction, teams can mistakenly call an imported video an active ad or attribute a performance change to an asset that never received delivery.

    This is also why your first audit should be reversible. Document and classify before making broad changes to channels, source videos, or campaign assets. The interface is live, but the available controls and reporting may not yet answer every governance question.

    Make shop visits primary only when attendance is the priority

    A campaign manager selects a path toward a community shop visit while a separate online-action path remains secondary.

    A primary conversion goal is not a decorative reporting preference. It tells the account which outcomes should matter to bidding and optimization. Changing that priority can change the traffic an automated campaign pursues and how it values one user action against another.

    Before this update, selecting shop visits in Google Ad Grants could produce an error. Eligible accounts can now place store visit conversions in their primary goal settings, giving organizations with physical locations a way to align advertising more closely with in-person activity.

    The option is especially relevant when attendance is the mission outcome: a museum needs visitors, a community center needs participation, and a place of worship may value physical attendance more than a page view. Those are among the organizations that can connect local search activity with real-world visits.

    Availability does not make the goal appropriate for every account. Before making it primary, ask whether a visit is genuinely more important than an online donation, registration, appointment request, membership application, or other existing conversion. If the answer differs by campaign, do not let an account-level default silently settle that strategic question.

    1. Write the outcome hierarchy in plain language. For example: physical visits are the primary outcome, event registrations are the next priority, and general page views are diagnostic only. Get agreement before changing the platform.
    2. Inspect the current goal configuration. Record the existing primary goals, the campaigns relying on account-level goals, and the bidding approach in use. This gives you a defensible before-state.
    3. Confirm that the option exists in the account. The capability applies to eligible accounts. If shop visits are unavailable, do not describe the rollout as universal or treat the missing control as proof that somebody configured the account incorrectly.
    4. Verify the local journey. Make sure the ad destination and public location information identify the correct organization and place. Optimizing for visits cannot compensate for inaccurate location details or a landing page that leaves visitors unsure where to go.
    5. Document the change. Record the date, owner, reason, affected goals, and expected behavior. Without a change log, a later shift in campaign results can look mysterious.
    6. Evaluate mission outcomes, not just clicks. Review spend, reported visits, online conversions, and the downstream result the organization actually values. A campaign that produces more visits is not automatically better if those visits do not support the intended program or location.

    The financial risk is straightforward: automated bidding may pursue visit-rich traffic while online donations or registrations receive less emphasis. That trade may be correct, but it should be deliberate. If the organization has not agreed on the relative value of those outcomes, leave the current primary configuration unchanged until it has.

    Keep paid activation separate from SEO, AEO, and GEO

    Neither update is evidence of an organic ranking change. A video appearing in Merchant Center does not prove that it will rank in Google Search or be cited by an AI system. Making shop visits primary in Ad Grants does not, by itself, improve local organic visibility. These are advertising workflow and optimization changes.

    The paid and organic teams should still coordinate because both depend on the same underlying facts. The useful connection is operational consistency, not a promise of cross-channel ranking benefits.

    • Use one factual source of truth. Product names, models, availability, offers, organization names, locations, and destination URLs should not contradict one another across videos, feeds, landing pages, and local content.
    • Keep activation controls channel-specific. Merchant Center asset discovery, Performance Max asset use, Ad Grants conversion goals, organic pages, and AI visibility each have their own mechanisms. Approval in one system should not be treated as approval in every other system.
    • Measure each channel on its own evidence. Paid delivery and conversions belong in advertising reporting. Search visibility, organic traffic, and AI citations require their own observations. A simultaneous change is not enough to claim that one caused the other.
    • Treat structured data as a separate implementation. Product, video, organization, or local-business markup may make appropriate page facts machine-readable, but neither rollout gives you a basis to expect JSON-LD alone to populate Merchant Center’s video library or enable an Ad Grants goal.
    • Share governance, not conclusions. SEO, content, ecommerce, local, and paid-media owners should use the same approved facts and change log while retaining separate success criteria.

    This separation prevents a common reporting error: turning an advertising-platform observation into a claim about search or AI visibility. It also makes coordination more useful. When a product changes, one approved update can trigger reviews of the feed, landing page, video library, structured data, and campaign creative without pretending those surfaces perform the same job.

    Key takeaways

    • Merchant Center’s populated Video Assets area should be treated as an asset-discovery queue, not proof that every video is approved or serving.
    • Review imported videos against current product data and landing pages before allowing them to influence commerce campaigns.
    • Shop visits can now be a primary goal in eligible Ad Grants accounts, but the setting should reflect an agreed hierarchy of real organizational outcomes.
    • Record account settings before changing primary goals because automated optimization may shift emphasis away from existing online conversions.
    • Keep Google Ads activation, organic search performance, structured data, and AI visibility separate in measurement, even when the teams share the same factual source of truth.

    Start with one controlled audit. Retail teams should open the Video Assets library, record what Google discovered, and assign every asset a review status. Ad Grants teams should write down their current primary goals and decide where physical visits belong before changing the account. Automation becomes useful when somebody still owns the facts, the priorities, and the evidence.

    References

  • Google Demand Gen Commerce Updates: A Practical Playbook

    Google Demand Gen Commerce Updates: A Practical Playbook

    You may be looking at Demand Gen because paid social is getting harder to scale, or because YouTube creates attention that your conversion reports struggle to explain. Google’s commerce updates give you three new levers, but each solves a different problem.

    The practical question isn’t whether to adopt every new feature. It is whether shoppable connected TV, dynamic travel offers, or branded-search attribution closes a specific gap in your customer journey. Start there, and you can test the updates without turning a product announcement into an open-ended budget request.

    What changed, and what each update actually does

    The three additions sit under the same Demand Gen umbrella, but they are not interchangeable:

    The first two features change what a prospective customer can see or do. The third adds an attribution signal. That distinction matters: a new measurement report does not improve the buying experience, and a shoppable ad does not by itself prove that the resulting sales were incremental.

    Match the feature to the constraint in your funnel

    Three connected scenes show television shopping, adaptive travel offers, and a search-to-purchase path overcoming different journey obstacles.

    Use shoppable CTV when the missing link is product action

    Shoppable CTV is most relevant when viewers understand your product from video but have no natural next step from the television screen. The testable idea is simple: can adding a product interaction to that viewing experience produce more conversions without weakening return on investment?

    Do not begin by moving a large video budget. Begin with a product set that makes the test interpretable. Favor products that are easy to recognize visually, have a clear use case, and are supported by dependable price and availability data. The item presented in the ad should also be easy to find at the destination. A viewer who meets a different product, price, or offer after acting on the ad has not experienced a media failure; they have experienced a broken handoff.

    • Make the product and its main benefit understandable at television viewing distance. Do not rely on dense copy or small interface details to explain the offer.
    • Check the full path from the video impression to the product action and final destination. Look for changes in item identity, price, availability, or promotional language.
    • Judge the test primarily on conversions, conversion value, CPA, or ROI, according to your business model. Video engagement can diagnose creative response, but it should not replace the commercial outcome.
    • Document what adding CTV is expected to change. If the hypothesis is merely that the campaign will reach more people, the test is too vague to justify a performance conclusion.

    Use Travel Feeds when changing offers make creative stale

    Travel Feeds address a different source of friction. Hotel pricing and availability can change faster than a team can rebuild conventional video assets. Connecting Hotel Center allows those offer details, along with property ratings, to populate dynamic video ads.

    The feed becomes part of the advertising experience, so feed quality is campaign quality. Before increasing spend, sample the properties and offers being promoted. Compare the price, rating, and availability presented in the ad journey with what a traveler encounters when moving toward a booking. Decide how your team will identify unavailable properties, inconsistent prices, and destinations that no longer match the promoted offer.

    • Audit Hotel Center data before evaluating the creative. Incorrect or incomplete offer data can make capable media look ineffective.
    • Review a representative mix of properties rather than checking only the most visible or highest-volume listing.
    • Assign ownership for feed corrections. A media buyer who can identify a mismatch but cannot route it to the person responsible for hotel data will repeatedly diagnose the same problem.
    • Keep the booking outcome as the primary metric. Dynamic assembly reduces creative and offer friction; it does not remove the need to evaluate booking quality and campaign economics.

    Use Attributed Branded Searches when last-click reports hide influence

    Demand Gen can affect what people search for after seeing an ad, even when the eventual search or conversion does not look like a direct response to the original impression. Attributed Branded Searches are designed to expose that brand-search activity across Google and YouTube.

    That makes the metric useful, but not equivalent to revenue. A rise in attributed brand searches can indicate that the campaign created interest. It cannot, on its own, tell you whether those searches produced profitable, incremental customers. Read it beside conversions, conversion value, CPA, ROI, and any customer-quality measure your business already trusts.

    Because a Google representative must activate the feature, treat access as a pre-launch dependency rather than an item to chase after the campaign ends. Ask the representative to confirm eligibility, the activation date, the metric definition, the reporting location, the applicable attribution window, and any limitations that could affect interpretation. Record those answers with the campaign brief so nobody later compares two reports built on different rules.

    Build the measurement plan before you move budget

    A desk with connected devices, interaction tokens, measurement checkpoints, and budget tokens waiting behind a transparent gate.

    The updates make Demand Gen more measurable, but more metrics do not automatically create a clean test. You still need a decision framework that separates commercial outcomes from diagnostic signals.

    1. Write one falsifiable hypothesis. For example: adding TV screens will increase conversions while maintaining ROI, or feed-driven hotel video will increase bookings without exceeding the campaign’s CPA constraint. Avoid a bundle such as improving awareness, engagement, sales, and efficiency at once.
    2. Select one primary outcome and one guardrail. The outcome might be purchases, bookings, conversion value, or another completed business action. The guardrail might be CPA or ROI. Branded search and video engagement should remain supporting signals unless they are genuinely the business objective.
    3. Lock the comparison rules. Use consistent conversion actions, value rules, attribution settings, and reporting periods when comparing Demand Gen with an existing campaign or channel. If those controls cannot be aligned, label the comparison as directional rather than causal.
    4. Record operational diagnostics. For commerce, inspect product continuity and availability. For travel, inspect Hotel Center data and the offer-to-booking path. For brand measurement, confirm that Attributed Branded Searches were active during the period being evaluated.
    5. Define the next decision before results arrive. State what would justify a limited scale-up, what would trigger a feed or landing-path repair, and what would cause the test to stop. You do not need to invent universal thresholds; use the economics your account must already meet.

    Once the campaign is running, interpret combinations of signals instead of celebrating one favorable number:

    Signal patternWhat it may meanWhat to do next
    Conversions rise while ROI holds or improvesThe commerce path may be creating useful additional demand at acceptable efficiency.Verify order or booking quality, repeat the result, and scale gradually.
    Attributed brand searches rise but conversions remain flatThe campaign may be generating interest that the offer, destination, or conversion path is not capturing.Do not declare a revenue win. Inspect search destinations, landing experiences, offer consistency, and conversion tracking.
    Video engagement improves but commercial outcomes weakenThe creative may attract attention without qualifying the right buyer or making the next action clear.Rework the product promise and handoff before adding budget.
    Travel ads show inconsistent offers or weak deliveryHotel Center data or campaign configuration may be obscuring the media result.Resolve feed accuracy and eligibility questions before concluding that the channel failed.

    Use Google’s performance figures as test inputs, not forecasts

    Google reports that Demand Gen campaigns featuring TV screens generated 7% more conversions at the same ROI. LG Electronics also reported a 24% higher conversion rate than paid social while reaching high-value customers at a 91% lower CPA. Those figures make a reasonable case for testing the channel, but they are vendor-reported results rather than a guaranteed outcome for your account.

    The LG comparison is especially easy to misuse. Without matching details for audience, geography, campaign period, conversion action, creative, and attribution model, a 91% CPA difference cannot become your forecast. Even the phrase “paid social” can conceal campaigns with different objectives and levels of maturity.

    • Use the 7% figure to support the question, “Is a controlled CTV test worth running?” Do not insert it automatically into a revenue plan.
    • Use the LG result as evidence that Demand Gen can compete with paid social under some conditions, not that it will always outperform it.
    • Put the comparator beside every benchmark in your internal presentation. A percentage without its baseline, campaign objective, and measurement rules is not an operating target.
    • Let your account’s conversion quality and unit economics decide whether to scale. A lower reported CPA is not valuable if it produces lower-value customers or bookings that do not hold.

    Key takeaways

    • Shoppable CTV is a commerce-path update: use it when YouTube viewing creates product interest but the television experience lacks a clear response mechanism.
    • Travel Feeds are an offer-assembly update: audit Hotel Center data because price, rating, and availability accuracy directly affect what the traveler sees.
    • Attributed Branded Searches are a measurement update: activate the feature through a Google representative before launch and interpret it beside commercial outcomes.
    • Google’s 7% conversion figure and LG Electronics’ paid-social comparison can justify a test, but neither should be treated as an account forecast.
    • The strongest rollout ties one feature to one constraint, one primary outcome, one efficiency guardrail, and a written scale-or-stop decision.

    Before your next campaign-planning meeting, write a one-sentence hypothesis and the two numbers that will decide whether you scale or stop. Then introduce only the Demand Gen feature capable of moving that hypothesis. That keeps the update focused on a business decision instead of letting it become a reason to spend first and explain the result later.

    References

  • Agentic Commerce Protocols: A Practical Readiness Plan

    Agentic Commerce Protocols: A Practical Readiness Plan

    You may already have product schema, shopping feeds, and commerce APIs, yet still not know whether your store is ready for an AI agent to recommend an item, verify the offer, and help complete a purchase. That uncertainty is the real protocol problem. The question is not simply which acronym to support, but whether your product facts and transaction controls survive a machine-to-machine buying journey.

    The safest approach is to separate protocol compatibility from commerce readiness. Build one reliable commerce core, then connect protocols to it through controlled adapters. That gives you a practical path into Google UCP and OpenAI ACP without duplicating pricing, inventory, checkout, or policy logic for every new interface.

    Choose the commerce job before you choose the protocol

    An agentic commerce protocol is an interoperability contract. It defines how participating systems exchange commerce information or request actions. That contract matters, but it does not replace your catalog, pricing engine, order system, payment flow, or fulfillment operation.

    Start by naming the buyer journey you want an agent to support. “We support agentic commerce” is too vague to test. “An agent can identify the correct variant, verify the current offer, create a cart, and return a checkout handoff” is specific enough to build and audit.

    Commerce jobRequired source of truthFailure to prevent
    Discover and compareCatalog, product identity, variants, attributes, and relationshipsThe agent selects the wrong product or compares unlike variants
    Verify an offerCurrent price, currency, availability, eligibility, and fulfillment conditionsThe agent presents an expired, unavailable, or inapplicable offer
    Create a cart or checkout handoffCart, promotion, customer, and checkout servicesA discount is misapplied, a cart is corrupted, or the buyer loses context
    Complete a bounded actionAuthentication, authorization, payment, and order servicesAn unauthorized or duplicate transaction is created
    Confirm and support an orderOrder status, fulfillment, cancellation, and return systemsThe agent promises an action that the merchant cannot honor

    A protocol may cover all, some, or none of those jobs. Build a requirements matrix from the actual specification and label each capability as supported, externally handled, unsupported, or subject to approval. Do not turn partial support into a blanket compatibility claim.

    This also prevents a common architecture mistake: wiring business rules directly into a protocol integration. Protocol-specific code should translate requests and responses. Your existing commerce services should continue deciding what an item costs, whether it can be sold, which promotion applies, and what happens after the order.

    Make product and offer data internally consistent

    A product is surrounded by synchronized catalog, inventory, price, variant, shipping, and availability objects while mismatched duplicates are corrected.

    An AI agent cannot resolve contradictions by calling them “close enough.” If a product page says an item is available, a feed carries yesterday’s price, and the transaction API rejects the variant, the agent has no trustworthy offer to present. More interfaces amplify that inconsistency rather than repairing it.

    Build a field-level inventory before adding endpoints. For every fact exposed to an agent, record its format, owner, update path, and authoritative system.

    1. Stabilize identity. Give each sellable product and variant a durable internal identifier. Use the same identifier wherever your catalog, feed, structured data, cart, and order systems can carry it.
    2. Separate products from offers. Descriptive attributes such as material or compatibility do not change on the same schedule as price, availability, delivery options, or promotion eligibility. Model them separately so mutable offer data can be refreshed without rebuilding the whole product record.
    3. Represent variants explicitly. Size, color, capacity, pack quantity, and other purchase-defining options should resolve to an exact sellable item. Do not make an agent infer the variant from an image filename or a paragraph of marketing copy.
    4. State conditions alongside claims. A price or delivery promise without its currency, region, eligibility, or other applicable condition is incomplete. Return the condition with the value rather than expecting the agent to recover it elsewhere.
    5. Connect policies to the affected offer. Return, cancellation, warranty, subscription, and fulfillment terms should be retrievable in the context where they apply. A generic policy page is useful to people, but it may not resolve an exception attached to one product or offer.
    6. Define conflict precedence. Decide which system wins when the page, JSON-LD, feed, cache, and transaction service disagree. Mutable facts should normally be revalidated against the system that can actually accept the transaction.

    JSON-LD remains useful, but it serves a different role from a transaction API. Structured data helps machines interpret what a public page describes. It does not reserve inventory, authorize a discount, create an order, or prove that a cached offer is still valid. Keep page content, markup, feeds, and APIs aligned, then revalidate consequential facts when the buyer moves from discovery to action.

    Give each response an unambiguous outcome. If current availability cannot be confirmed, return an unavailable or indeterminate state and a safe next step. Do not substitute an old value, invent a delivery promise, or turn missing data into a confident answer.

    Put explicit controls around every agent action

    A discovery request is mostly informational. Creating a cart changes state. Placing an order, cancelling one, or requesting a refund can affect money and customer rights. Your controls should become stricter as the consequence increases.

    Put a protocol adapter between the external agent interface and your internal commerce services. The adapter should translate fields, enforce the supported capability set, reject malformed requests, and produce protocol-compatible errors. It should not become a second pricing engine or an alternative order-management system.

    • Authenticate the caller. Establish which agent, platform, account, or delegated identity is making the request.
    • Authorize the exact action. Knowing who called is not enough. Check whether that identity may read an offer, create a cart, place an order, cancel an order, or request another state change.
    • Revalidate server-side. Price, availability, promotion eligibility, shipping conditions, and order totals must be checked by the commerce system before commitment. Values repeated by the agent are inputs to verify, not facts to trust.
    • Make retries safe. State-changing requests need a stable operation identifier or equivalent idempotency control. A timeout followed by a retry must not create a second order or duplicate another irreversible action.
    • Bound delegated authority. Limit what the agent can buy, change, cancel, or approve. When the requested action exceeds that authority, require an explicit user decision rather than stretching the scope silently.
    • Preserve an audit trail. Record the caller, requested action, authorization result, validated commercial state, resulting transaction, and error outcome. Keep sensitive information out of prompts and general-purpose traces.
    • Return recoverable errors. Tell the agent whether it should refresh an offer, request a missing selection, ask the buyer for confirmation, hand off to checkout, or stop. Do not expose credentials or sensitive internal details in the explanation.

    Route payment credentials and personal data through your approved payment, identity, consent, and privacy flows. An agent conversation or model trace is not a safe substitute for those systems. If the agent only needs to hand the buyer into checkout, give it a constrained handoff mechanism rather than unnecessary access to the full payment process.

    Confirmation also needs state awareness. If the price, item, quantity, delivery terms, or another material condition changes after the buyer’s instruction, stop and present the changed state before committing. Agreement to one offer is not blanket permission to accept a different one.

    Optimize discovery and transaction readiness separately

    Protocol support is not a ranking switch. An agent still needs to discover your products, understand them, decide whether they fit the request, and obtain a valid path to action. A working checkout endpoint does not compensate for vague product information, just as excellent content cannot complete a transaction when the offer cannot be verified.

    Treat the journey as four connected layers:

    • Discovery: Can the system find a canonical product page or catalog record for the buyer’s need?
    • Understanding: Can it identify the product, variant, attributes, compatibility, constraints, and applicable policies without guessing?
    • Decision support: Does your content answer the questions that distinguish this option from alternatives?
    • Action: Can the agent verify the live offer and move into a controlled cart, checkout, or order flow?

    Your public content should do more than repeat a product name and a promotional claim. State concrete specifications, intended use, compatibility, included components, variant differences, purchase conditions, and limitations where they matter. Use consistent terminology across prose, tables, structured data, feeds, and APIs. If one surface calls an option a “starter pack” while another exposes only an unexplained internal code, automated matching becomes less reliable.

    Keep canonical pages useful to people even when machines consume their data. Clear explanations help a buyer verify the recommendation and give answer engines grounded material to cite or summarize. The protocol should extend that experience into live commerce operations, not turn the website into a thin wrapper around an endpoint.

    Measure these layers independently. If products are rarely selected, investigate discoverability, identity, attributes, and decision content. If products are selected but transactions fail, investigate offer freshness, authorization, validation, handoff, and error recovery. Combining both failures into one “AI traffic” metric hides the part you need to fix.

    Roll out one bounded journey and test the failure paths

    An abstract shopping agent travels through a guarded test corridor while unavailable inventory, price changes, payment failure, delivery problems, and permission blocks are contained on side paths.

    Do not begin by exposing every catalog action to every agent. Choose one journey with a clear owner, a known source of truth, and a reversible handoff where possible. A narrow implementation reveals data and control problems before they spread across the whole store.

    1. Define the journey. Write the starting request, required product decisions, supported actions, handoff point, completion signal, and responsible internal team.
    2. Write the field contract. List required and optional fields, identifiers, formats, authority, freshness expectations, and what happens when a value is absent.
    3. Write the action contract. For every state change, define authentication, authorization, validation, confirmation, retry handling, audit output, and safe failure response.
    4. Validate read-only behavior first. Confirm that product identity, variants, current offers, and policies resolve consistently before allowing the integration to alter carts or orders.
    5. Simulate state changes. Exercise order creation, retries, timeouts, revocation, changing prices, unavailable variants, expired promotions, and partial service failures without risking a real buyer’s money.
    6. Restrict the first live scope. Limit the supported catalog, actions, regions, accounts, or other meaningful dimensions until the operational signals are stable.
    7. Expand by evidence. Add capabilities only when the previous scope has reliable data, safe authorization, understandable errors, and an owner who can respond to exceptions.

    Test cases that expose weak integrations

    • The chosen variant goes out of stock after discovery but before checkout.
    • The price or promotion changes between recommendation and commitment.
    • A request times out after the order service succeeds, then the agent retries it.
    • The buyer omits a purchase-defining option such as size, quantity, or configuration.
    • The caller’s authorization is revoked during the session.
    • An internal service succeeds while the protocol adapter fails to return the response.
    • The requested shipping, cancellation, or return condition is not available for that offer.
    • The agent requests an action outside its delegated scope.

    A pass is not merely “the endpoint returned a response.” The response must preserve the correct commercial state, avoid duplicate effects, explain what the agent can do next, and leave an auditable record.

    Measure the agent funnel, not just agent traffic

    Give every metric a numerator, denominator, and operational owner. Useful measures include exact product-resolution rate, successful offer-verification rate, cart or handoff success, authorized action success, duplicate requests safely suppressed, policy exceptions, and completed orders associated with an agent-assisted journey. Track stale-data failures separately from authorization and checkout failures because they require different fixes.

    Preserve the boundary between influence and completion. An agent referral, a protocol request, a cart creation, a checkout handoff, and a paid order are different events. Calling all of them conversions will overstate performance and make protocol decisions harder to defend.

    Key takeaways

    • Define the exact discovery or transaction journey before evaluating a protocol.
    • Keep pricing, inventory, policy, checkout, and order rules in your core commerce systems.
    • Use adapters to connect protocols rather than rebuilding business logic for each interface.
    • Align product pages, JSON-LD, feeds, and APIs, but revalidate mutable facts before consequential actions.
    • Require explicit authentication, action-level authorization, safe retries, bounded delegation, and audit records.
    • Launch with a restricted journey, test failure states, and expand only when each stage has measurable reliability.

    Your next move is to pick one sellable journey and document its fields, actions, authorities, and errors on a single implementation map. That map will show whether your immediate constraint is visibility, catalog quality, transaction safety, or protocol translation. Fix that constraint first, then add the interface that gives the journey a useful route into agentic commerce.

    References

  • 30-Day E-commerce SEO Execution Plan: Audit to Impact

    30-Day E-commerce SEO Execution Plan: Audit to Impact

    You probably do not need another long diagnosis of your store. If you already have a backlog of crawl, template, category, and product-page issues, the immediate constraint is delivery: deciding what deserves attention, assigning an owner, releasing the change safely, and proving that it works as intended.

    Use the next 30 days to build that delivery rhythm. You will not finish e-commerce SEO in a month, and you should not promise a ranking increase on a fixed date. You can finish the month with important changes in production, a reliable validation record, and a smaller, sharper backlog for the next sprint.

    Why e-commerce SEO audits stall before production

    An audit recommendation is not executable work. It becomes executable only when it has a defined scope, an owner, known dependencies, an acceptance test, and a release path.

    The gap can be expensive. One $4 million Shopify brand had paid $12,000 for a 127-page audit containing 53 recommendations. Six months later, the company had changed titles and meta descriptions and added a few blog posts, while 41 recommendations remained untouched and unscheduled.

    The problem was not a shortage of ideas. It was the absence of a mechanism that converted ideas into releases. A backlog without sequencing lets easy, visible tasks displace less glamorous work that may affect entire templates. A recommendation without an owner waits for someone to volunteer. A change without an acceptance test can be deployed without anyone knowing whether the defect was actually removed.

    Key takeaways

    • Treat the 30 days as a delivery window, not a promise that search performance will improve on your schedule.
    • Prioritize confirmed problems affecting crawlable, indexable, revenue-relevant page types over a long list of loosely supported observations.
    • Prefer a safe template-level correction when the same defect appears across many pages, but test its reach before a full release.
    • Track implementation, technical validation, search response, and business impact as separate states.
    • Give canonicals, redirects, indexing directives, URL changes, and template edits an explicit rollback plan.

    Your month-end deliverable should not be another presentation. It should be a release log, a set of validated changes, evidence of what happened after release, and a prioritized next sprint.

    Days 1-3: Turn recommendations into a release backlog

    Day 1: Create one source of operational truth

    Bring recommendations from audits, crawlers, analytics reviews, support tickets, developer notes, and merchandising requests into one board. Merge duplicates. Do not leave technical work in one spreadsheet and content work in another if both compete for the same developers, templates, or approvals.

    Each backlog item needs these fields before it can enter the sprint:

    • Problem: Describe the observed condition, not a generic instruction such as “improve category SEO.”
    • Evidence: Record affected URLs, templates, screenshots, crawl output, or search-performance data that confirms the condition.
    • Scope: State whether the change affects one URL, a page group, a template, navigation, structured data, or a platform rule.
    • Expected effect: Explain what should become possible after the fix, such as consistent canonicalization, clearer page differentiation, or stronger internal discovery.
    • Owner: Name the person responsible for moving the item to its next state. A department name is not an owner.
    • Dependencies: Identify development, design, legal, merchandising, analytics, or platform access needed before release.
    • Acceptance check: Write the observable condition that will prove the implementation is correct.
    • Rollback: Record how you will reverse the change if it damages navigation, indexing signals, product information, or conversion paths.

    If you cannot describe the affected pages or the expected post-release condition, the item is still an investigation. Label it that way instead of allowing it to masquerade as an implementation ticket.

    Day 2: Prioritize by reach, commercial relevance, and readiness

    Do not copy a crawler’s severity label into your roadmap and call it prioritization. A technically severe warning on an irrelevant page type may deserve less attention than a confirmed template defect affecting category or product pages.

    Ask these questions in order:

    1. Does the problem prevent an intended page from being crawled, indexed, understood, or reached through internal navigation?
    2. Does it affect a revenue-relevant page type, such as a category, collection, product, or commercially useful supporting page?
    3. Is the problem systemic, or would the team be editing individual URLs without addressing the template that created them?
    4. Is the diagnosis supported by direct evidence from the affected pages?
    5. Can the team implement, inspect, and reverse the change within this sprint?

    Place the resulting work into three lanes: release this month, prepare for the next sprint, and park pending evidence. The release lane should contain work that is both important and ready. A high-impact idea that still needs legal approval, a platform migration, or an unresolved architecture decision belongs in preparation, not in a sprint where it will remain blocked.

    Day 3: Assign owners and freeze the baseline

    Assign one accountable owner to every selected item, even when several specialists will contribute. Then record the pre-change condition for the exact page set in scope.

    Your baseline can include:

    • Organic clicks, impressions, and click-through rate for the selected pages and relevant queries.
    • Organic sessions, transactions, revenue, and conversion rate when the analytics setup can support those measurements reliably.
    • Current response codes, index directives, canonical targets, sitemap inclusion, and internal-link paths.
    • Existing titles, primary headings, visible product facts, and structured-data output.
    • A dated record of promotions, stock changes, redesigns, or campaign activity that could complicate later interpretation.

    Save the filters, date settings, and URL list with the baseline. A screenshot without its query, segment, or date context will not help you make a defensible comparison at the end of the month.

    Days 4-10: Fix the technical path to money pages

    Layered illustration of a storefront page structure with home, category, and product cards connected by a clear highlighted route, while broken routes sit at the edges.

    Start implementation with confirmed technical conditions that obstruct intended category and product pages. Content improvements cannot compensate for a page that is unintentionally excluded, canonicalized elsewhere, isolated from navigation, or served incorrectly.

    Days 4-5: Validate the diagnosis on real page types

    Inspect representative URLs from every affected template before changing code. Include ordinary products, variants, categories, paginated or filtered states where relevant, and edge cases such as unavailable products. A warning seen on one URL does not prove that every similar-looking URL has the same cause.

    • Confirm the response code and whether the page is available to crawlers.
    • Check index directives and the final canonical target.
    • Verify whether an intended indexable URL appears in the correct sitemap.
    • Trace how a shopper and a crawler can reach the page through navigation, breadcrumbs, categories, or contextual links.
    • Determine which template, component, application, or rule creates the output before assigning the fix.
    • Separate intentional handling of filters, sorting, variants, and duplicate states from genuine mistakes.

    This step often changes the ticket. What looked like hundreds of page-level defects may be one template condition. The reverse also happens: superficially similar URLs can be controlled by different components and require separate releases.

    Days 6-8: Implement the smallest systemic correction

    Choose the smallest change that resolves the confirmed cause across the intended scope. If a template emits the wrong canonical, repair the template logic rather than manually overriding pages. If navigation fails to expose an important category, correct the navigational relationship rather than adding isolated links wherever someone happens to notice the problem.

    Keep unrelated change families out of the same release when possible. Combining canonical logic, title generation, navigation, structured data, and design changes makes failures harder to diagnose and rollback. The team should be able to connect a changed output to a specific ticket.

    Template edits can reach far beyond the sample that revealed the problem. Generate an affected-URL estimate, inspect a test set, and preserve the previous configuration or template version before deployment.

    Days 9-10: Release with a technical safety check

    Validate the change in a staging environment when the platform permits it, then inspect production after release. Check both the rendered page and the machine-readable output where relevant. Re-crawl the defined scope and compare the result with the ticket’s acceptance check.

    Changes to robots directives, noindex rules, canonicals, redirects, URL structures, or sitewide templates can remove valuable pages from search or send shoppers to the wrong destination. Do not mass-redirect, noindex, or canonicalize pages merely because an automated tool calls them duplicates. Preserve the current rules, test representative URLs, review the proposed targets, and keep a verified rollback path.

    A URL migration is also not routine backlog cleanup. If changing URLs is genuinely necessary, treat the mapping, internal links, redirects, sitemap output, analytics continuity, and post-release monitoring as a separate controlled project.

    Days 11-20: Improve the pages that answer buying intent

    Once the technical path is sound, improve the pages that help a shopper choose a category or product. Publishing more blog posts is not a substitute for making commercially important pages clear, differentiated, and internally connected.

    Days 11-12: Build a page-to-intent map

    For each page in scope, write down the searcher’s likely need, the page’s job, the relevant products or subcategories, and the next useful action. Then identify pages competing to perform the same job.

    • Choose a primary destination for each important buying need.
    • Improve an existing suitable page before creating another near-duplicate destination.
    • Merge or differentiate overlapping pages based on what each page can genuinely offer.
    • Record the internal links that should lead into and out of the destination.
    • Flag inventory, compliance, or merchandising facts that require approval before publication.

    This is not an exercise in assigning one exact phrase to every URL. It is a decision about which page should satisfy a distinct need. If the team cannot explain why two pages both need to exist, adding more copy to each will not resolve the overlap.

    Days 13-17: Strengthen categories and products

    For category and collection pages: make the title and primary heading describe the actual selection. Add concise information that helps a buyer understand what belongs in the category, how meaningful options differ, and where to go next. Link to useful subcategories or buying paths. Remove generic boilerplate that could be pasted onto any category without changing its meaning.

    For product pages: make the product identity and differentiators explicit. Include accurate attributes, dimensions or specifications where relevant, fit or compatibility, variants, what is included, and the conditions that affect the buying decision. Keep price, availability, shipping, returns, and warranty information consistent wherever those facts appear. Do not invent certainty when a product team has not verified a claim.

    Answer genuine product questions in direct language. Do not generate paragraphs simply to make a page longer. Repeated filler can hide the few details that actually distinguish one product from another, while creating a factual-review burden for the team.

    Days 18-20: Connect pages and synchronize structured data

    Make the site’s relationships visible. Categories should lead to appropriate subcategories and products. Product pages should expose their category context through navigation or breadcrumbs. Supporting content should link to the commercial destination when that destination genuinely answers the reader’s next question.

    Review Product, offer, and breadcrumb markup alongside the visible page. Names, prices, currencies, availability, variants, and navigational relationships should not contradict what a shopper sees. Structured data can express information more clearly to machines, but it cannot repair a blocked page or substitute for missing and inaccurate product information.

    If AI helped produce descriptions, FAQs, or attribute summaries, send every affected page through factual and merchandising review. Automation can accelerate drafting, but ownership of price, compatibility, safety, availability, and policy claims remains with the business publishing them.

    Days 21-30: Release, validate, and protect the next sprint

    Quality-assurance specialist comparing an abstract product page on desktop, tablet, and phone beside link, speed, shield, and green validation symbols.

    Days 21-23: Ship controlled batches

    Release in batches small enough for the team to inspect but large enough to exercise the template or page group you intended to fix. For every batch, record the deployment time, owner, change family, affected templates or URLs, expected output, and rollback location.

    Run the acceptance checks immediately after production deployment. Confirm that important navigation, product selection, add-to-cart behavior, analytics collection, and page rendering still work. An SEO change is not successful if it damages the shopping experience or your ability to measure it.

    Days 24-27: Validate implementation before judging performance

    Keep three questions separate:

    1. Was it shipped? The code, content, navigation, or markup is present in production.
    2. Is it correct? The affected pages meet the written acceptance conditions without creating a new defect.
    3. Did performance change? Search visibility, qualified traffic, engagement, transactions, or revenue moved after the release.

    The first two questions can often be answered within the sprint. The third may remain open because search systems do not discover and reevaluate every changed page according to your internal calendar.

    Re-crawl the released scope, inspect representative pages manually, and compare current output with the frozen baseline. Check whether measurement still works before interpreting a flat or missing metric. If an acceptance check fails, fix or roll back that batch before adding another layer of changes.

    Days 28-30: Close every item with evidence

    Do not allow tickets to end the month in an ambiguous “done” column. Give each item a precise final state:

    • Shipped and validated: The production output meets its acceptance check.
    • Shipped, response pending: Implementation is correct, but search or business effects cannot yet be judged.
    • Blocked: The missing dependency and its owner are named.
    • Rejected: Validation disproved the diagnosis, the risk exceeded the benefit, or the item no longer serves the store’s goals.
    • Prepared for the next sprint: Scope, evidence, owner, and dependencies are ready for scheduling.

    Review leading indicators such as corrected page output, internal discovery, index eligibility, impressions, and click-through rate alongside business measures such as qualified organic visits, transactions, conversion, and revenue. Keep promotions, stock changes, paid campaigns, redesigns, and other overlapping events in view. A metric moving after a release does not by itself prove that the SEO change caused it.

    Finish with a short closeout record containing what shipped, what passed validation, what remains uncertain, what was blocked, and what enters the next sprint. Preserve the detailed evidence in the backlog instead of recreating a large report that the delivery team must interpret again.

    Open your backlog now and choose the first change whose scope, owner, acceptance check, and rollback are all clear. If no item meets that standard, your first job is not ranking the recommendations. It is turning vague recommendations into work that can safely reach production.

    References

  • Google’s 2026 Multi-Channel Product ID Rule: Audit Guide

    Google’s 2026 Multi-Channel Product ID Rule: Audit Guide

    If your website and stores sell the same SKU, a single Google product ID may feel like the cleanest setup. It stops being the right setup when the offer facts sent to Google disagree across those channels.

    March 2026 is the implementation point attached to Google Merchant Center’s multi-channel product ID requirement. Online product attributes become the baseline. When the in-store version has a different price, availability, condition, or another relevant product detail, you need a distinct product ID for that version and must manage it separately in your feeds.

    The rule turns on channel differences, not the shared SKU

    The practical question is not whether the website and store sell the same physical product. Ask whether Google receives the same product facts for both ways of buying it.

    If the online and in-store details are aligned, this rule does not create a reason to split the item. If one or more relevant details differ, the in-store offer needs its own identity in the feed. That lets Google treat each channel version as a coherent set of facts instead of trying to reconcile conflicting values under one ID.

    Catalog situationAction under the ruleWhat to verify
    Online and in-store details matchNo channel split is indicated by this ruleConfirm the match comes from the systems that actually publish the feeds
    In-store price differsCreate and manage a distinct in-store version with a separate product IDCheck which system supplies each channel’s price
    In-store availability differsCreate and manage a distinct in-store version with a separate product IDConfirm that inventory updates continue to reach the correct version
    In-store condition differsCreate and manage a distinct in-store version with a separate product IDMake sure the difference is represented consistently at the source
    Several channel attributes differSplit the versions and manage each set of attributes independentlyRecord every difference so a later feed update does not merge them again

    Keep two distinctions clear. First, a separate Google product ID does not mean that the merchandise has become a different manufacturer product. Do not fabricate a GTIN, manufacturer part number, or other external identifier to satisfy a feed-management requirement. Second, separating online and in-store versions should not be read as a general command to create a new product ID for every physical store. The trigger here is the difference between channel versions.

    Build the audit around the online version as the baseline

    Retail data auditor comparing visual attribute fields for the same product on a desktop monitor and a tablet.

    A conventional duplicate-SKU report will not find this problem. The duplicated base SKU is expected. What matters is whether the attributes associated with that SKU change when the selling channel changes.

    Build a comparison file with one row for each online and in-store pairing. At minimum, include the base catalog key, the current Google product ID, channel, price, availability, condition, and the system that supplied each value. Add a result column that classifies the pair as aligned or different.

    1. Start with the products Google has already identified. Affected accounts began receiving notices and product-level indications before the deadline, so those items give you a concrete first queue.
    2. Expand beyond the flagged queue. Compare the full set of products distributed through your online and local feeds, especially if you use Local Inventory Ads or send the same catalog into several Google surfaces.
    3. Compare published channel values, not only the values in your master catalog. A price may look identical in the product information system while a later rule, promotion process, or inventory system changes the feed output.
    4. Classify each mismatch by attribute. Separate price, availability, condition, and other product-detail differences instead of using a single generic error label.
    5. Split only the pairs with a real channel difference. Leave aligned products alone unless another requirement gives you a reason to change them.
    6. Assign an owner to every unresolved mismatch. The person or team that controls the source data must be able to correct the feed generator, not just patch a submitted file once.

    Treat Google’s markings as a priority list, not a substitute for your own comparison. A product that has not been flagged can still belong in the audit if its channel attributes come from different systems or change frequently.

    Design the ID split so your catalog remains traceable

    Two channel-specific product records with different geometric identifiers linked back to one shared master catalog item.

    The difficult part is rarely generating another string. It is preserving the relationship between the online version, the in-store version, and the underlying catalog item after the split.

    Use an ID convention that your feed process can reproduce deterministically. A channel suffix can be understandable, but no particular suffix is established here as a Google-mandated format. The important operational properties are uniqueness, consistency, and a documented connection to the base item. Do not include mutable values such as the current price or availability in the ID; every routine change would otherwise create unnecessary identity churn.

    Maintain a crosswalk containing:

    • The base SKU or internal catalog key.
    • The online product ID.
    • The in-store product ID.
    • The attribute or attributes that require separation.
    • The source system for each channel’s values.
    • The owner responsible for correcting future mismatches.
    • The status of the feed change and its validation.

    This crosswalk protects reporting and troubleshooting. Without it, a team can see two Google IDs and mistake them for duplicate products, or see one internal SKU and merge channel records that must remain separate.

    Make the separation in the feed-generation logic whenever possible. A manual edit to an exported file may fix one submission, but the next automated run can restore the old shared ID. The durable fix is to route online facts to the online version and differing local facts to the in-store version before the files reach Merchant Center.

    Before a large rollout, verify a small, representative set through your normal feed-validation and account-diagnostic process. Include at least one price mismatch, one availability mismatch, and one fully aligned product if those cases exist in your catalog. That gives you a direct check that the split logic changes only the records it should.

    Avoid the changes that create more feed problems

    The fastest implementation is not a catalog-wide ID rewrite. It is a controlled exception process. Watch for these common errors:

    • Splitting every multi-channel item: the requirement is tied to differing product details. Rewriting IDs for aligned items adds work without addressing the stated trigger.
    • Using the shared SKU as proof that one ID is correct: a shared SKU establishes the relationship between the products, but it does not resolve conflicting channel attributes.
    • Changing only one exported feed: if another local inventory, catalog, or integration process still emits the shared ID, the inconsistency will return.
    • Overwriting the online baseline with local values: the required model uses online attributes as the standard and separates the differing in-store version. Repeatedly replacing one channel’s facts with the other’s does not create two coherent records.
    • Inventing a new manufacturer identifier: manage the separate Google product ID without falsifying GTINs or other identifiers assigned outside your organization.
    • Discarding the old-to-new relationship: preserve a crosswalk so reporting, investigation, and future corrections can connect both channel versions to the original catalog item.
    • Waiting only for an account warning: Google notifications help you prioritize, but your source systems are the reliable place to discover every channel difference you publish.

    If your catalog is large, prioritize products with known channel-specific pricing, products whose availability changes independently between online and physical stores, and products flowing through Local Inventory Ads. Those are the places where the rule’s trigger is easiest to establish from your own data.

    Key takeaways

    • Use the online product record as the comparison baseline for a product sold online and in stores.
    • Create a separate in-store version with a distinct product ID when relevant details such as price, availability, or condition differ by channel.
    • Do not split an aligned product merely because it is available through two channels.
    • Audit the attributes that are actually published, because downstream systems can introduce differences that are absent from the master catalog.
    • Preserve a crosswalk between the base SKU and both channel IDs, and make the change in the feed-generation logic rather than relying on a one-time file edit.

    Your next step is concrete: take the products already marked in Merchant Center, compare their published online and in-store attributes, and use that result to build a repeatable exception report for the rest of the catalog. Split confirmed mismatches, document the mapping, and leave genuinely aligned records intact.

    References

  • A Practical System for Ecommerce Conversion and Ad Performance

    A Practical System for Ecommerce Conversion and Ad Performance

    Your ad account can look healthy while your store quietly wastes the demand you are paying to create. A strong click-through rate cannot rescue a difficult checkout, and a high account-wide ROAS can hide a catalog in which one familiar product consumes most of the budget.

    The fix is a sequence, not another disconnected app or campaign adjustment. Remove purchase friction first. Recover shoppers who have already shown intent. Then allocate advertising spend according to product-level performance. That order makes the numbers easier to interpret and keeps automation from optimizing around a broken buying experience.

    Key takeaways

    • Audit the complete mobile path from ad click to successful payment before increasing traffic.
    • Prioritize digital wallets, then evaluate buy now, pay later against your margins and customer needs.
    • Use email and SMS recovery only with the consent and controls required for each channel and jurisdiction.
    • Separate proven products, new or low-data products, and products consuming traffic without adequate return.
    • Review product assignments on a rolling cycle, but choose the window according to your sales volume rather than treating 14 days as a universal rule.

    Fix the purchase path before asking ads to work harder

    Generic shoppers follow a simplified mobile checkout path as obstacles, extra gates, and confusing branches are removed between a shopping basket and a delivery parcel.

    Start with the device on which the transaction actually happens. With 54.5% of holiday purchases happening on mobile, a phone is not a secondary quality-assurance case. It is often the main checkout environment.

    Do not audit that environment by opening the homepage and deciding that it looks acceptable. Follow the paid journey exactly as a shopper would:

    1. Open each high-spend ad on a real phone and record the promise, product, price, and offer shown in the creative.
    2. Confirm that the landing page immediately continues the same promise. If the ad promotes one product or use case, do not make the shopper search for it again.
    3. Add the product to the cart from a clean session so saved addresses, accounts, or payment details do not conceal friction.
    4. Start checkout and count the fields and decisions required before payment. Test every wallet that appears to be enabled.
    5. Place a test order. A visible payment button is not proof that authorization, confirmation, inventory handling, and order creation work.
    6. Repeat the path for the devices, browsers, and traffic sources that matter to your store. Record failures by stage rather than describing the whole journey as a conversion problem.

    Digital wallets such as Apple Pay, Google Pay, and PayPal reduce typing by reusing stored payment and delivery details. That matters on a small screen. Their relevance is not marginal: up to 64% of Americans use digital wallets as much as traditional payment methods, while 54% prefer using them more often. On Shopify, wallet and buy now, pay later functions can be added without custom development in many standard configurations.

    A wallet removes form friction; it does not repair a weak offer. If product-page engagement is poor, adding another payment method is unlikely to solve the underlying problem. Buy now, pay later can reduce the immediate price objection, but it should not be enabled solely because it might lift checkout completion. Review provider fees, refunds, returns, and contribution margin first. A higher conversion rate can still produce worse economics.

    Use your own historical baseline when reading the funnel. There is no universal healthy rate for every catalog, price point, or traffic mix. The pattern of the drop tells you where to investigate:

    Observed patternWorking hypothesisFirst actionPrimary measure
    Ads earn clicks, but few product views become cart additionsThe ad promise, landing page, product, or offer is mismatchedBuild a landing-page variant that continues the ad’s exact messageProduct-view-to-cart rate
    Cart additions are steady, but few shoppers start checkoutThe handoff creates uncertainty or extra effortReview the cart on mobile and make the next step and payment choices clearCart-to-checkout-start rate
    Checkout starts are steady, but purchases are weakPayment or data-entry friction is blocking completionTest wallet payments and evaluate whether buy now, pay later fits the order economicsCheckout completion rate
    Purchases are steady, but ROAS is weakSpend is reaching the wrong products or trafficRebuild product groups around performance rather than category aloneProduct-level ROAS and revenue
    One product absorbs most of the campaign budgetExisting winners are preventing new or less visible products from gathering evidenceGive proven, new, and traffic-without-return products separate treatmentSpend concentration and cohort-level ROAS

    This table is a hypothesis map, not an automatic diagnosis. For example, checkout completion can rise after you change campaign targeting because the new audience was easier to convert. That does not prove the checkout itself improved. Keep traffic allocation stable during a checkout test, or use a controlled experiment, so you can separate site effects from audience effects.

    Recover existing intent without creating a consent problem

    Once payment works, focus on shoppers who reached the cart or checkout but did not buy. They have supplied more evidence of intent than a cold audience, but that does not give you unrestricted permission to contact them.

    1. If the shopper has valid email marketing permission, place them in an abandoned-cart email flow with a direct return to the relevant cart or product.
    2. If the shopper has separately provided the consent required for marketing texts, use SMS selectively for time-sensitive recovery. Do not treat the presence of a phone number in checkout as automatic marketing consent.
    3. If you cannot document the necessary permission, do not quietly add the shopper to an automated sequence. Use compliant onsite recovery and your approved advertising audiences instead.
    4. Measure each recovery channel separately. A combined recovery number can conceal an unproductive SMS program behind a successful email flow, or vice versa.

    Email and SMS programs must follow the rules that apply to the shopper, sender, channel, and jurisdiction. In the United States, CAN-SPAM and TCPA are part of that compliance landscape. Requirements and interpretations can change, so have qualified counsel review the actual capture language, records, workflows, and vendors before contacting people who did not clearly subscribe. Calling an outreach process human-assisted does not by itself settle whether it is permitted.

    Recovery is not limited to reminders. Some shoppers leave because they still do not trust the product. Reviews answer a different objection: whether the item is credible and likely to meet expectations. Spiegel Research Center found that a product with five reviews was 270% more likely to be purchased than one with none. That finding does not make five a universal target or prove the same lift for every store. It does show why a product with no visible evidence should not be treated as conversion-ready.

    • Place product-specific reviews where the decision happens, not only on a separate testimonials page.
    • Make sure the review displayed belongs to the item being purchased. General store praise cannot answer product-level questions as well as relevant customer feedback.
    • Choose a review system that can connect with your advertising stack. Shopify integrations such as Okendo, Yotpo, and Shopper Approved can sync review data with Google Merchant Center and support Google Shopping activity.
    • Track whether products that gain credible review coverage improve their product-view-to-cart and checkout-start rates. Do not attribute every store-wide change to the review widget.

    Watch the downside metrics alongside recovered revenue: unsubscribe activity, complaints, failed deliveries, discount cost, refunds, and repeat purchase behavior. A flow that produces immediate orders by exhausting customer permission is not a durable win.

    Stop letting product categories decide where the budget goes

    Unbranded products receive different streams of advertising resources based on abstract performance signals, with completed orders feeding results back into a central decision hub.

    Category-based campaign structures are easy to understand, but a merchandising label does not describe advertising performance. One popular product can consume the available budget because the platform already has strong evidence that it converts. New products remain underexposed, while weak products can stay hidden inside a category that looks profitable in aggregate.

    Create performance cohorts with rules written before you inspect the latest results. Three labels are enough to begin:

    • Proven performers: products at or above your target return with enough recent traffic to support the decision.
    • New or low-data products: launches and existing products that have not received enough exposure to be judged by the same rule as established sellers.
    • Traffic without adequate return: products that have crossed your evidence threshold for clicks or spend but remain below your required return.

    Define the variables with your own economics. A workable rule template is: proven performer equals ROAS at or above target and clicks at or above the evidence floor; traffic without adequate return equals clicks at or above that floor and ROAS below your lower limit; new or low-data equals product age within your launch window or clicks below the evidence floor. The structure is reusable, but the values are not. A high-margin accessory and a low-margin appliance should not inherit the same target merely because they share a campaign.

    If you do not have a dependable margin view, do not automate budget expansion from ROAS alone. ROAS is attributed revenue divided by advertising spend. It is not profit. Product cost, fulfillment, payment charges, returns, discounts, and the attribution model can all change the decision.

    1. Export product-level clicks, spend, attributed revenue, orders, and ROAS for a consistent window.
    2. Apply the written cohort rules using feed labels or equivalent product-grouping fields.
    3. Give each cohort a budget and campaign treatment appropriate to its job. The new-product cohort needs room to gather evidence; proven products need room to scale; weak products need a controlled test or a spending limit.
    4. Publish the same product labels to paid channels where the required data and controls are available.
    5. Recalculate labels on a rolling schedule and log every reassignment. Without a log, a product that moves between groups can make campaign trends difficult to explain.

    La Maison Simons used Channable Insights to replace static category segments with product-performance groups and refreshed them on a rolling 14-day window. It then applied the approach across Google, Meta, Pinterest, TikTok, and Criteo. In that deployment, ROAS rose from about 800% to about 1,500%, CPC fell from $0.37 to $0.30, CTR increased from 1.45% to 1.86%, and average order value increased 14% without additional ad spend.

    Those figures are one retailer’s outcome, not a forecast for your catalog. They do not establish how much of the change came from segmentation rather than other conditions. The transferable lesson is narrower and more useful: a product can receive a different advertising treatment as its evidence changes, and a winning item does not have to monopolize the budget forever.

    A 14-day window is a sensible test cadence for a fast-moving catalog with enough transactions. It can be noisy for a lower-volume store, an expensive product, or a long-consideration purchase. Use the shortest window that still supplies enough evidence for your preset rules. If products repeatedly jump between cohorts, lengthen the window or raise the evidence floor instead of manually overriding the system every few days.

    Run one operating loop from conversion to ROAS

    Advertising and conversion teams often optimize separate dashboards. The media team changes audiences and budgets while the ecommerce team changes checkout and landing pages. When both happen at once, neither team can explain the result. Use one operating loop with fixed definitions and a visible change log.

    1. Cycle setup: record the current product cohorts, attribution model, campaign budgets, landing-page versions, payment options, and funnel baseline.
    2. During the window: monitor tracking and payment failures, but do not reclassify products because of a single order or a short-lived spike. Emergency defects should be fixed immediately and marked in the log.
    3. Decision day: recalculate product labels from the same lookback window, move qualifying products according to the written rules, and record every move.
    4. Experiment selection: choose one material conversion constraint for the next cycle. Test the ad-to-page message, the landing-page treatment, the checkout path, or the recovery flow rather than changing all four.
    5. Scale decision: increase exposure only when the advertising return, checkout behavior, and unit economics point in the same direction.

    Your shared scorecard should retain the relationship between media and store behavior:

    • CTR: clicks divided by impressions. It shows whether the ad earns attention, not whether the resulting visit is valuable.
    • CPC: spend divided by clicks. A lower CPC helps only if the traffic still reaches profitable purchases.
    • Product-view-to-cart rate: cart additions divided by relevant product views. Use it to investigate message, product, offer, and page friction.
    • Checkout completion rate: purchases divided by checkout starts. Use it to inspect payment and form friction.
    • Average order value: revenue divided by orders. Pair it with margin rather than assuming a larger basket is automatically more profitable.
    • ROAS: attributed revenue divided by ad spend. Always display the attribution model and window beside it.
    • Spend concentration: the share of budget absorbed by the top product or small group of products. This reveals catalog dependence that account-wide ROAS can hide.

    GA4 can remain part of this measurement system, while a third-party attribution layer such as Triple Whale can provide another product and channel view. More dashboards do not create objective truth. Select the attribution model used for budget decisions, document it, and avoid changing it in the middle of a comparison. A last-click result from one cycle cannot be compared cleanly with a different model in the next.

    Custom landing pages deserve their own controlled tests. Shopify builders such as Replo can create and A/B test pages without changing the main theme for every visitor. Start with one ad and product cohort, keep the standard page as the control, and change one decision-relevant treatment. If the variant wins, confirm that the improvement survives after product mix and traffic quality are accounted for before rolling it across the catalog.

    Begin with one mobile test order and one export of product-level advertising data. Fix any payment failure you find, label the catalog with written performance rules, and start a single review cycle. That gives you a system you can improve. Installing the entire stack before you can explain the current funnel only gives you more places for the same leak to hide.

    References

  • Google Merchant Center Videos in Performance Max: A Playbook

    Google Merchant Center Videos in Performance Max: A Playbook

    If your Performance Max build keeps stalling while someone finds, exports, labels, and re-uploads the right product video, Google has removed part of that handoff. Product-associated videos in Merchant Center can now appear during campaign setup, giving you a shorter route from catalog creative to an eligible PMax asset.

    Treat this as a creative-operations improvement, not an automatic performance win. The useful question is not simply whether Google can find your videos. It is whether the surfaced video matches the product, communicates something useful, and can be measured without attributing every campaign change to one new asset source.

    What the Merchant Center connection changes

    Google Ads can surface product-associated Merchant Center videos directly during Performance Max setup. That reduces the need to manage the same relationship separately in a product catalog, a creative library, and a campaign-building workflow.

    The benefit becomes more important as your catalog grows. A team managing a small, stable product range can usually locate the correct creative manually. With an extensive SKU catalog, that manual lookup turns into a recurring reconciliation exercise: which video belongs to which product, whether it is current, and whether the campaign builder selected the right version.

    What it solves

    • Asset discovery: campaign builders can find product-related videos through the Merchant Center connection instead of starting another search through shared drives or separate libraries.
    • Product-to-creative alignment: an existing product association gives the setup process a stronger signal than a filename or a campaign builder’s memory.
    • Catalog coverage: reusable associations make it more practical to bring relevant video into campaigns covering many products.
    • Workflow duplication: retail, feed, and paid-media teams have less reason to recreate the same asset mapping at every campaign build.

    What it does not solve

    • It does not turn a generic brand video into product-specific creative.
    • It does not correct an inaccurate product-video association.
    • It does not prove that a surfaced video was selected, delivered, or responsible for a change in results.
    • It does not replace creative review. Automation can scale a good mapping, but it can also repeat a bad one across more of the catalog.

    This distinction should shape your rollout. First make the Merchant Center relationship trustworthy. Then use the PMax setup screen as a second validation point. If you reverse that order, the campaign builder becomes responsible for repairing catalog data under launch pressure.

    Prepare the product-video relationship before campaign setup

    Four generic products are paired with video frames showing the same items in use, while one mismatched video frame is set aside.

    A video can be professionally produced and still be wrong for a product. The common failure is not poor production quality; it is a mismatch in identity, variant, feature, or promise. A family-level demonstration may be appropriate for several related products, for example, but only if everything shown and claimed applies to every product receiving that association.

    Use an internal relationship classification before you expand coverage. This is a planning framework, not a Merchant Center setting:

    RelationshipWhat the video showsApproval ruleTypical failure
    Exact productOne identifiable product or variantThe depicted product and the associated item agree on every visible or stated attributeThe video shows a different color, size, model, bundle, or generation
    Product familyA shared use case or feature across related productsEvery claim remains true for every associated itemA feature available on one model is implied for the entire family
    ContextualA scene, category, or collection containing several productsThe associated product is relevant and understandable without a forced interpretationA broad lifestyle scene is attached to products that are barely visible or unrelated

    Do not chase raw coverage by attaching the nearest available video to every product. Define approved video coverage instead:

    Approved video coverage = products with a reviewed, relevant video association / products in campaign scope

    That denominator matters. If a campaign contains only part of your catalog, measure the products that can actually enter that campaign rather than celebrating coverage across unrelated inventory. The metric also prevents a misleading shortcut: one broadly associated video may raise nominal coverage while doing little to improve product relevance.

    Prioritize associations by confidence

    1. Start with products that already have an exact, current video and an unambiguous association.
    2. Move to product families only after documenting which claims and visual attributes are shared across the family.
    3. Use contextual creative where the product relationship is clear, not merely because the video is available.
    4. Leave uncertain matches out of the rollout until a reviewer can resolve them. Missing video is easier to diagnose than misleading video.

    This order gives you a clean first implementation. It also makes later troubleshooting easier because the initial group contains the associations most likely to be correct.

    Use a two-checkpoint QA workflow

    Two reviewers check a product video first for product accuracy and then for its appearance across mobile, desktop, and television ad formats.

    The first checkpoint belongs in Merchant Center, where the product-video relationship lives. The second belongs in PMax setup, where you confirm what Google actually surfaced for the campaign. Neither checkpoint should be treated as a substitute for the other.

    1. Define the campaign product scope. Record the products or product groups you intend to promote before reviewing creative. Otherwise, reviewers waste time validating assets that cannot affect the build.
    2. Review the existing associations. Confirm that the video depicts the intended product, family, or legitimate context. Check visible attributes, spoken or written claims, and any offer information that could become outdated.
    3. Record an approval decision. Keep the product identifier, video identifier or filename, relationship class, reviewer, status, and reason for rejection. A simple shared sheet is enough if those fields remain consistent.
    4. Inspect the videos surfaced during PMax setup. Confirm that the expected approved assets appear and that an unexpected near-match has not entered the candidate set.
    5. Review the final campaign selection. Surfaced means available during setup; it should not be treated as proof that the asset was intentionally selected or will receive meaningful delivery.
    6. Log the launch state. Save the campaign scope, approved coverage, relevant asset decisions, launch date, and any simultaneous changes to budget, bidding, feed data, pricing, or promotions.

    Give reviewers a compact acceptance checklist. A video is ready only when you can answer yes to the applicable questions:

    • Does the video show the same product, or a clearly valid product family or context?
    • Do visible attributes agree with the associated item?
    • Are every feature and benefit shown applicable to that item?
    • Will the main product and message remain understandable on a small screen?
    • Does the video still make sense without relying entirely on audio?
    • Are displayed prices, promotions, bundles, availability statements, and seasonal messages still current?
    • Is the destination experience consistent with what the video leads a shopper to expect?

    The checklist is also a responsibility boundary. Feed specialists can validate product identity and association. Creative owners can validate the footage and claims. Paid-media owners can validate campaign scope and final selection. Without those boundaries, every mismatch becomes the campaign manager’s problem at the last possible moment.

    Review changes by exception

    A full manual review at every build will eventually recreate the bottleneck this connection is meant to reduce. Preserve approved mappings and reopen them when something material changes: the video is replaced, the product is revised, variants are consolidated, a family gains or loses a feature, an offer expires, or the campaign scope changes.

    This exception-based process lets stable mappings pass through quickly while sending genuinely risky changes back to a person. The goal is not less control. It is to place control where a decision has changed.

    Measure workflow gains separately from ad performance

    The Merchant Center connection can deliver value even before you see a commercial lift. It may reduce campaign preparation, increase approved video coverage, and cut mapping rework. Those are operational outcomes. Return on ad spend, cost per acquisition, conversion value, and profit are commercial outcomes. Combining the two creates an evaluation that cannot tell you what improved.

    Track the operational outcome

    • Approved coverage: reviewed, relevant product-video associations divided by products in campaign scope.
    • Mapping accuracy: associations approved without correction divided by associations reviewed.
    • Rework rate: associations changed after campaign setup divided by associations reviewed.
    • Build effort: time spent locating, transferring, mapping, and validating video assets for a comparable campaign build.
    • Exception volume: new or changed mappings that require human review.

    Measure the same definitions before and after adopting the workflow. Do not quietly change the denominator from all in-scope products to only products that already have video. That would make coverage look better without improving the catalog.

    Evaluate commercial movement cautiously

    Performance Max uses automated delivery, so a campaign-level change after adding Merchant Center videos does not establish that the videos caused it. Demand, bids, budget, product mix, feed quality, price, promotions, and other creative can move at the same time.

    1. Choose the business metric first. Use the metric that governs the campaign, such as conversion value, return on ad spend, cost per acquisition, or another internally approved profitability measure.
    2. Record a baseline. Capture the campaign and product scope before the new video workflow enters the build.
    3. Log concurrent changes. Note feed edits, price changes, promotions, budget shifts, bidding changes, assortment changes, and other creative updates.
    4. Stage the rollout where practical. Begin with a bounded product group whose associations have been reviewed. Expand after the mapping and workflow hold up.
    5. Separate diagnosis from attribution. Asset delivery and engagement can help you investigate what happened, but they do not by themselves prove incremental business value.

    If several major inputs changed at once, label the result directional rather than causal. That wording is not excessive caution. It keeps a convenient creative feature from receiving credit or blame for changes that the campaign design cannot isolate.

    Set decision rules before launch. Expand when associations remain accurate, operational effort falls, and the primary business metric stays acceptable or improves. Revise when coverage rises but mappings or claims fail review. Pause expansion when errors multiply faster than the team can correct them. Your thresholds should come from the economics and risk tolerance of the account, not from an invented universal benchmark.

    Key takeaways

    • Merchant Center videos can now surface during Performance Max setup, reducing the manual handoff between product data and campaign creative.
    • The product-video association is the control point. Validate identity, variant, feature claims, offer details, and destination consistency before scaling.
    • Measure approved, relevant coverage rather than the number of products attached to any video.
    • Use Merchant Center review and PMax setup review as separate checkpoints, then keep a decision log so later corrections are traceable.
    • Track workflow improvement separately from commercial performance, and do not treat a campaign-level before-and-after change as proof of video impact.

    For your next PMax build, choose one bounded part of the catalog. Classify its product-video relationships, approve the strong matches, check what setup surfaces, and record both the operational baseline and the campaign baseline. Expand only when the mapping stays trustworthy. That is how this small integration becomes a repeatable system instead of another source of automated ambiguity.

    References

  • How to Capture AI-Driven E-commerce Demand on Black Friday

    How to Capture AI-Driven E-commerce Demand on Black Friday

    If your Black Friday plan stops at rankings, feeds, paid media, and conversion rate, it now has a blind spot. A shopper can ask an AI system to narrow a category, compare products, judge whether a discount is worthwhile, and recommend where to buy – without following the search journey you designed.

    Your job is not to make an AI repeat your promotion. It is to make your products easy to identify, compare, and verify while demand moves from early research to live deal hunting. That requires coordinated work across your own site, retailers, marketplaces, review coverage, video, and genuine customer discussion.

    Black Friday creates two different AI demand states

    A split scene contrasts calm product research at a desk with urgent mobile deal shopping at night.

    Before Black Friday, shoppers are reducing a large market into a shortlist. Their questions tend to concern suitability: which product fits a use case, what features matter, which compromises are acceptable, and whether waiting for a sale makes sense. When the event begins, the task changes. Price, availability, seller credibility, current sentiment, and the quality of the deal become more important.

    That change is visible in the domains AI systems use. In the week before Black Friday, retail and brand domains represented 59.6% of cited sources, media represented 23.4%, and social or user-generated content represented 17%. During Black Friday, the social and user-generated share rose to 25.1%, while retail and media lost share.

    Those percentages do not establish a permanent formula for every category or model. They do expose a useful operating distinction: the content that builds a shortlist is not sufficient on its own when shoppers want current confirmation from other people.

    Build your campaign around four information layers:

    • The identity layer explains what your brand sells, which categories it belongs in, and who its products are for.
    • The decision layer supplies specifications, use cases, limitations, compatibility details, and defensible comparisons.
    • The offer layer states the current price, discount terms, sale window, availability, fulfillment conditions, and applicable returns information.
    • The verification layer gives shoppers independent evidence through reviews, demonstrations, retailer listings, comparison coverage, and legitimate customer discussion.

    The first two layers should be settled before promotional demand arrives. The offer layer must be updated whenever the commercial facts change. The verification layer takes longer to earn, so it cannot be manufactured credibly on launch day.

    Make every offer answerable without reconstruction

    An AI system should not have to combine a slogan on your homepage, specifications in a PDF, a discount in a banner, and shipping terms in a support page to explain your offer. Every extra reconstruction step creates another opportunity for omission, confusion, or a stale answer.

    Start at the homepage because it is more than a navigational doorway. Within the examined brand-site citations, homepages accounted for 40%. Give that page a plain statement of what the brand is, the categories it serves, the customer problems it solves, and the main paths to product information. A clever campaign line can support that explanation, but it should not replace it.

    Then audit each priority product or offer page in this order:

    1. Use the exact product name and model consistently in the title, visible copy, structured data, retailer listings, and supporting content.
    2. State what the product is and who it suits near the top of the page. Do not make the reader infer the category from branding language.
    3. Present specifications as labeled facts. Include the dimensions, materials, capacity, compatibility, included components, or technical requirements that actually drive a decision in your category.
    4. Explain the important tradeoffs. A page that identifies who should not buy the product can be more useful than one that describes every shopper as an ideal customer.
    5. Place the live offer in visible text. Include the current price, reference price where applicable, conditions, start and end information, seller, stock state, and fulfillment details that a buyer needs to interpret the promotion.
    6. Add concise questions and answers for real research intents: compatibility, setup, maintenance, warranty, returns, common alternatives, and differences between adjacent models.
    7. Provide evidence close to the claim it supports. Demonstrations should show the use case, while reviews and technical documentation should be clearly attributable and reachable.

    Keep stable product facts separate from volatile promotional facts in your content workflow. The product’s dimensions should not change because a sale begins, but price and availability might. Assign ownership accordingly: merchandising maintains the offer state, while product or content teams maintain the underlying facts.

    Structured data can make those facts less ambiguous to machines, but it cannot rescue incomplete visible content. Product and Offer markup should agree with the page a shopper sees. If a price, availability value, model identifier, or seller differs between the markup and the page, the markup has added conflict instead of clarity.

    Finish with a manual extraction test. Give someone who did not build the page the URL and ask them to answer: What is this product? Who is it for? Why would they choose it over the closest alternative? What exactly is the Black Friday offer? What restriction could change the decision? If any answer requires another tab or an assumption, the page is not finished.

    Build comparison coverage before the promotion starts

    Brand pages are good at establishing first-party facts. Shopping recommendations require a second job: organizing choices and reducing uncertainty. That is why AI systems repeatedly draw from retailers, review publishers, video platforms, and community conversations when they construct commercial answers.

    Across 10,000 responses about deals, reviews, and product recommendations, YouTube received 1,509 citations, Best Buy 950, Walmart 885, Target 477, TechRadar 355, RTings 342, and Consumer Reports 325. The distribution was concentrated rather than evenly spread across the web.

    Retail concentration matters too. Generalist retailers held 48% of retail citations, while electronics specialists held 23%. Large retailers have broad assortments, familiar identities, and enough product information to answer many different shopping questions. A smaller brand is unlikely to reproduce that footprint, but it can make its category knowledge and product distinctions much easier to reuse.

    Create comparison pages around decisions, not around the phrase “best product.” A useful comparison should tell the reader:

    • Which products are genuinely comparable and which belong to a different use case.
    • What each option is best suited to, using a stated criterion rather than a vague superlative.
    • Which specifications materially change the experience.
    • What the buyer gives up by choosing the cheaper, smaller, faster, or more capable option.
    • Whether accessories, subscriptions, installation, or compatibility requirements affect the practical cost.
    • Which facts are stable product attributes and which are temporary Black Friday conditions.

    Publish first-party comparisons even when an independent reviewer would be more persuasive. Your version establishes accurate entities, specifications, and distinctions that other people can check. It should disclose its perspective and link to the underlying product details rather than pretending to be neutral.

    For third-party coverage, prioritize relevance over raw volume. Give suitable reviewers and publishers clean model names, current specifications, images, documentation, and access to products where your normal review policy allows it. Correct factual errors without trying to dictate conclusions. Inclusion in a trusted comparison is valuable because the comparison answers a real decision, not merely because it creates another brand mention.

    Treat off-site evidence as part of product information

    An unbranded device is connected to scenes of a reviewer, video creator, retailer display, and customer photo.

    Your website can declare what a product does. It cannot independently establish how the product behaves in ordinary use or how buyers feel about its compromises. AI shopping answers often seek that corroboration elsewhere.

    Within the observed set of key off-page signals, Reddit represented 34%, YouTube 19.5%, Amazon 15.5%, Business Insider 9.2%, and Walmart 8.9%. Treat these figures as evidence of concentrated influence in the examined responses, not as channel budgets or universal weights.

    Each environment contributes a different kind of evidence:

    • YouTube can show setup, scale, sound, motion, results, and other experiential details that are difficult to communicate in a specification table. Use accurate titles and descriptions, identify the exact model, and make spoken explanations clear enough to stand without promotional visuals.
    • Retailer and marketplace listings connect the product to a category, seller, price, reviews, and comparable inventory. Keep identifiers, variants, specifications, and images consistent with your own site.
    • Review coverage organizes alternatives and makes tradeoffs explicit. Give reviewers enough factual material to distinguish models without forcing them to decode your catalog.
    • Community conversations reveal recurring questions, edge cases, frustrations, and unexpected use cases. Use those conversations to improve product information and support. Do not simulate participation or manufacture endorsements.

    Consistency is the operational priority. If your site calls a product one name, a retailer shortens it, a video uses a family name, and marketplace variants omit the model number, you have created several weak identities instead of one strong one. Maintain a shared product record containing the approved name, model identifier, category, key specifications, variant labels, current imagery, and canonical URL. Give every channel owner access to it.

    Do not turn this into a backlink-counting exercise. A mention that does not help identify, compare, or verify the product contributes little to the shopping decision. Audit off-site presence by question instead: Where can a shopper see the product used? Where can they compare it with the nearest alternative? Where can they verify specifications? Where can they find credible discussion of its limitations?

    Run a two-phase AI visibility operation

    Black Friday AI optimization should operate in a preparation phase and a live phase. The preparation phase builds retrievable facts and comparison context. The live phase protects accuracy while offers, availability, and public conversation change.

    Before the promotion, build a fixed prompt set from customer decisions rather than from your target keywords alone. Include category discovery, a constrained use case, a direct product comparison, a compatibility question, a value question, and a deal-verification question for every priority category. Keep the wording stable enough that later results are comparable.

    Run those prompts separately on the AI platforms your customers are likely to use. Do not collapse their responses into one score. In the observed Black Friday sample, Gemini responses averaged 606 words, OpenAI responses averaged 401, and Perplexity responses averaged 288. Those are sample characteristics, not permanent product specifications, but they show why a citation or mention can play a different role on each platform.

    Use one tracking row for each prompt and platform. Record:

    • The exact prompt, model or product name, and time of the check.
    • Whether the brand and correct product appear.
    • How the product is framed: recommended, compared, merely listed, or excluded.
    • Which URLs support the answer.
    • Whether the price, specifications, seller, availability, and promotion terms are accurate.
    • Which competitor or third-party page supplied information you did not make easy to find.
    • The correction required: page content, structured data, marketplace data, comparison coverage, video, or support documentation.

    At sale launch, rerun the deal and verification prompts. Repeat the check after any material price, inventory, seller, or terms change. If an answer is wrong, correct the authoritative page and connected listings first. A prompt variation may produce a different answer, but it does not repair the underlying information conflict.

    Judge progress by failure mode rather than by a single visibility number. A missing brand is a discovery problem. The wrong model is an identity problem. An incorrect price is a freshness problem. A competitor winning every comparison may indicate weak decision content or stronger independent corroboration. Each diagnosis leads to different work.

    Key takeaways

    • Plan separately for pre-sale research and live deal verification because the source mix changes when Black Friday begins.
    • Give every priority offer a clear identity, complete decision facts, current commercial terms, and evidence a shopper can verify.
    • Build comparisons around use cases and tradeoffs, not unsupported claims that a product is “best.”
    • Coordinate product information across your site, retailers, marketplaces, video, review coverage, and community support.
    • Test the same customer decisions across AI platforms and classify failures before choosing a fix.

    Before your next promotion, choose one prompt for each major customer decision in your highest-value category. Run the set when product pages are frozen, again when the sale launches, and whenever a material offer fact changes. The gaps you find will give your content, merchandising, SEO, marketplace, and communications teams a concrete Black Friday worklist – before shoppers ask AI to make the choice for them.

    References

  • Social and Commerce Ad Tools: A Practical Selection Guide

    You do not need another ad account. You need to know which part of the buying journey is failing: discovery, relevance, confidence, or checkout. Choose a tool before answering that question and you can buy plenty of activity without removing the constraint that is costing you sales.

    The useful decision is not whether Instagram, LinkedIn, YouTube, Pinterest, or Shopify is the best platform. It is which platform capability can perform one defined job for your audience, then hand that person to the next step without changing the subject.

    Choose the bottleneck before you choose the tool

    Start with the moment immediately before the result you want. If buyers never encounter your category, you have a discovery problem. If they see you but assume the offer is not for them, you have a relevance problem. If interested visitors do not trust the promise, you have a confidence problem. If they want the product but cannot find or buy the right item, you have a transaction problem.

    Those problems call for different tools. A high-attention video placement will not repair an incomplete product path. Dynamic personalization will not create demand for a category buyers do not understand. A commerce network can expose an item at a useful moment, but it cannot compensate for an offer that becomes confusing as soon as the shopper reaches the product page.

    • For discovery: use a visual or short-form surface capable of introducing the problem, category, or use case before the buyer searches for it.
    • For relevance: change the message for a meaningful audience characteristic, such as role, company, need, or viewing context.
    • For confidence: connect the ad to evidence that resolves the buyer’s next objection, not to a generic homepage.
    • For transactions: place the right product where demand already exists and reduce the distance between selection and purchase.

    Write a one-sentence campaign brief before opening a platform: “For this audience, this placement will remove this bottleneck, and we will judge it by this outcome.” If you cannot complete every part without using words such as “engagement” or “awareness” as a substitute for a business result, the campaign is not ready.

    Match each platform capability to a buying moment

    Several newer capabilities blur the boundary between social advertising, creator marketing, recommendation systems, and onsite merchandising. That does not make them interchangeable. It makes their assigned job more important.

    Buying momentUseful capabilityWhat it can changeWhat you should do
    A person is exploring an interestInstagram Reels and user-controlled topic preferencesInstagram’s Your Algorithm controls let people request more or less of a topic and add preferences. This is a user control, not an advertiser setting.Build each Reel around a recognizable subject and use case. Do not treat audience targeting as permission to make the creative vague.
    A B2B buyer is not yet searchingLinkedIn Reserved Ads, profile-based personalization, and AI creative variantsReserved placements are designed to make impressions more predictable, while personalization can use fields such as first name, job title, and company. AI Ad Variants can produce additional on-brand versions from one input.Use reserved delivery when reach predictability matters. Personalize the reason to care, then test it against a non-personalized control.
    A viewer encounters a creator recommendationYouTube Shorts comments and creator link-outsEligible Shorts ads can allow comments, and branded creator content can link to a brand website. Shorts placement has also expanded to mobile web.Send the viewer to the exact product, offer, or explanation shown in the Short. Assign someone to review comments for questions and objections.
    A shopper has a product need that one store cannot satisfyShopify Product NetworkContextually relevant products from other merchants can appear across participating stores, including in search results and on homepages. Cross-merchant items can enter a single cart, while referring merchants can earn cash commissions or ad credits.Assume your product may be evaluated outside your own storefront. Make the title, image, category, offer, and product-page promise understandable without your usual brand context.
    A person is collecting ideas and possible solutionsPinterest advertisingPinterest’s formats serve a platform built around inspiration and solution discovery.Choose the format from the campaign objective. The creative should show the desired outcome while the destination explains how to achieve or buy it.

    The sequence matters. Social discovery surfaces are useful when someone needs to notice or understand an option. Commerce placement becomes more useful when the need is already legible and product selection is the remaining task. In B2B, predictable feed exposure can establish familiarity before a self-directed buyer begins comparing providers.

    You can use more than one surface in the same journey, but do not assign all of them the same conversion target. A discovery placement should earn the next qualified action. A product placement should make the transaction easier. When every channel is judged as if it closed the sale alone, early-stage tools get cut too quickly and late-stage tools receive credit for demand they did not create.

    Build one continuous handoff from ad to answer

    The most common structural mistake is a message break. The ad speaks to one audience and problem; the destination opens with a broad corporate statement. The creative shows a specific item; the click leads to a collection page. The creator answers a practical question; the linked page makes the visitor reconstruct the answer from navigation and promotional copy.

    Build the handoff in this order:

    1. Name the entry context. Record what the person was watching, browsing, searching for, or trying to buy when the placement appeared.
    2. Make one promise. The ad should communicate one useful outcome or answer one immediate question. Additional benefits belong after the click.
    3. Continue that promise on the destination. Repeat the same product, category, audience, and use case near the start of the page. Do not make the visitor verify that the click worked.
    4. Expose the supporting facts. Put specifications, eligibility, limitations, proof, price conditions, availability, or process details where they can be evaluated before the primary action.
    5. Ask for the next proportionate action. A person discovering a new category may need an explanation or comparison. A shopper selecting a known item may be ready to add it to a cart. Do not force both into the same path.

    Apply personalization only where it changes meaning. Inserting a first name may attract attention, but it does not explain relevance. A job title can be useful if the problem, evidence, or next step genuinely differs by role. A company name is useful only when the surrounding sentence remains accurate and natural. Test the personalized version against a plain version so novelty is not mistaken for qualified interest.

    AI-generated ad variants need the same discipline. Give the system a fixed product identity, approved claims, audience, prohibited claims, call to action, and destination. Review every version that could change a price, capability, condition, or comparison. Producing more creative is valuable only when the variants test distinct ideas; dozens of cosmetic rewrites create volume without creating a useful experiment.

    Instagram’s preference controls create a particularly important distinction. People can influence the topics they receive, but a brand cannot command a place in those preferences. The practical response is topical clarity: make the subject, audience, and use case recognizable without relying on a clever opening that conceals what the content is about.

    YouTube comments can turn an ad into an objection log. Decide before launch who will review questions, what requires a response, and which recurring objections should be answered on the destination page. If comments repeatedly ask whether an offer works for a certain use case, the page should not leave that answer buried in a reply thread.

    Shopify’s cross-merchant model creates the opposite challenge: your product may appear in a storefront the shopper did not associate with your brand. Evaluate the product card and landing page as a self-contained unit. A title that only makes sense beside the rest of your catalog, or an image that depends on brand familiarity, will be fragile in a contextual network.

    This continuity also matters for SEO, answer-engine optimization, and generative-engine visibility. Advertising does not make a page authoritative or guarantee that an AI system will cite it. It can, however, reveal the words people use, the objections they raise, and the contexts in which a product becomes relevant. Use those observations to improve the public page a search engine or AI system can access.

    Keep machine-readable information aligned with the visible destination. If a page uses Product or Offer structured data, its product name, brand, identifier, availability, currency, price conditions, and offer details should not contradict the page or the ad. Structured data is a clarification layer, not a place to repair an unclear or inconsistent offer.

    Measure the constraint the tool was selected to remove

    A campaign should produce a decision even when it does not produce a win. That requires a primary metric tied to the assigned job and a diagnostic metric that explains what happened next.

    • For predictable reach: compare planned and delivered impressions for the defined audience, then inspect whether that exposure led to qualified visits or later branded activity. Delivery proves the placement ran; it does not prove that the message landed.
    • For personalization: compare personalized and non-personalized creative against the same downstream outcome. Click-through rate alone can reward curiosity. Qualified leads, useful page actions, or completed buying steps tell you whether relevance improved.
    • For creator and interactive video: separate viewing, commenting, outbound traffic, and downstream action. Read comments by theme rather than treating their count as approval. Questions, objections, confusion, and purchase intent require different responses.
    • For commerce placement: measure orders and acquisition cost, then account for the commission or credit economics attached to the network. A sale is not automatically a profitable sale, and a referring placement may have value even when the referring merchant did not supply the product.
    • For discovery: look for movement from exposure to an intentional next step, such as a relevant page visit, product exploration, or another action your analytics can observe. Do not present social engagement as evidence that AI search visibility improved.

    Use one controlled comparison at a time. If you change the audience, format, message, offer, and destination together, the result cannot tell you which decision helped. Start with the largest uncertainty: audience-message fit, creative angle, personalization, or destination handoff. Hold the other elements steady long enough to learn from that question.

    Set a spending cap you can afford before the test begins. Paid systems can optimize toward the event you provide, including an event that is easier to generate but less valuable than the business result. Confirm that the selected conversion represents a real step in the buying process, then examine the leads or orders behind the aggregate number.

    Keep platform status separate from campaign performance. LinkedIn’s Flexible Ad Creation was slated for early 2026, while Instagram described broader expansion of its preference controls beyond Reels. Availability can differ by account, placement, and market, so verify the feature inside the account before making it a dependency in your launch plan.

    Key takeaways

    • Choose the buying bottleneck first: discovery, relevance, confidence, or transaction.
    • Give each platform one accountable job instead of asking every placement to close the sale.
    • Treat Instagram preference controls as user agency, not as an additional advertiser-targeting switch.
    • Use LinkedIn personalization to change the reason to care, not merely to insert a person’s profile data.
    • Connect Shorts and creator placements to the exact answer, product, or offer shown in the video.
    • Prepare commerce listings to make sense outside your own storefront and brand context.
    • Use advertising feedback to improve public content, but do not claim that paid engagement causes SEO, AEO, or generative-engine visibility.

    Before your next launch, put six lines on one page: audience, bottleneck, platform capability, message, destination, and primary outcome. Add an affordable test cap and one controlled comparison. If the campaign cannot be explained on that page, adding another tool will make the uncertainty more expensive, not more manageable.

    References