Tag: ChatGPT

  • ChatGPT Advertising Insights: A Practical Pilot Playbook

    ChatGPT Advertising Insights: A Practical Pilot Playbook

    If you are deciding whether ChatGPT advertising deserves budget, do not start by asking whether it resembles paid search. Start with the moment the ad enters: the user has already described a need, added constraints, and moved partway toward a decision.

    A ChatGPT ad can appear inline within that conversation, marked as Sponsored and presented with a headline, short body, and destination. Your job is not to interrupt the journey. It is to offer a credible next step that fits the journey already underway. That difference should shape your creative, measurement, landing pages, and relationship between paid advertising and organic AI visibility.

    Use the early data as a format signal, not an ROI benchmark

    The first useful insight is about the strength and limits of the evidence. The early U.S. trial launched on February 9 for Free and Go users, while Adthena tracked more than 50,000 daily placements from over 600 advertisers across B2B software, ecommerce, fintech, and consumer categories.

    That is enough activity to reveal recurring creative conventions. It is not enough to establish a universal cost per acquisition, return on ad spend, or incrementality benchmark. The observations come from a vendor-tracked index during a trial, span materially different verticals, and do not provide one standardized performance baseline for every advertiser.

    Use the data to answer questions such as how much copy the format can carry, which information tends to appear first, and how closely creative reflects the conversation. Do not use it to forecast your return before you have campaign-level evidence from your own offer, audience, and destination.

    Before assigning meaningful budget, make sure your pilot can answer a defined question:

    • Can you identify a narrow group of commercial topics where the user is likely to be comparing options or preparing to act?
    • Do you have a specific, verifiable benefit that can be understood without several lines of explanation?
    • Does the destination continue the exact promise made in the ad?
    • Can you separate ChatGPT placements from your other paid traffic when evaluating outcomes?
    • Have you defined what would justify expanding, revising, or stopping the test before spend begins?

    Rollout status is time-sensitive, so confirm actual inventory and account eligibility before committing budget or launch dates. A projected geographic expansion is not the same thing as inventory you can buy.

    Write an answer fragment, not a compressed search ad
    A distinct sponsored module fits into a flowing sequence of text-free conversation cards while a separate banner sits outside the flow.

    A traditional search ad often has several components competing for attention: multiple headlines, descriptions, sitelinks, extensions, and other assets. The early ChatGPT format is more restrained. That makes every word carry more of the decision.

    The strongest working model is an answer fragment. It should make sense beside the assistant’s response, acknowledge the user’s decision criteria, and introduce a next step without pretending to be the neutral answer.

    The tracked placements show several compact patterns. Headlines averaged about 30 characters and peaked at 36, body copy averaged roughly 19 words, and many ads used two short sentences. These are observed conventions, not confirmed platform character limits.

    Creative elementEarly patternWhat to do with it
    HeadlineAbout 30 characters on average, with a peak at 36Lead with the decision-driving benefit. Do not spend the available space on a generic slogan.
    Headline openingMost begin with the brand nameTest a Brand: Benefit construction when recognition and accountability matter.
    BodyAbout 19 words, commonly split into two sentencesUse the first sentence for proof and the second for a low-friction action.
    RelevanceStronger creative mirrors the user’s contextReflect the category, constraint, or desired outcome instead of repeating a loose keyword.
    Offer detailDollar signs, rates, and concrete figures were associated with stronger conversion performancePrioritize a specificity test, but treat the pattern as a hypothesis to validate in your own campaign.

    Build each variation from three prompt components

    When a user asks for accounting software for a small team, for example, accounting software is only the category. Small team is the constraint. The unstated decision criterion might be fast setup, predictable cost, or limited administrative work. Creative that reflects only the category will feel generic even if it contains the right keyword.

    1. Extract the category: what kind of product, service, or action does the user want?
    2. Extract the constraint: what price, use case, location, feature, risk, or timing narrows the choice?
    3. Choose one decision criterion your offer can substantiate.
    4. Write the headline as Brand: Verified Benefit.
    5. Use the body for one proof point and one proportionate call to action.
    6. Remove any claim that the landing page cannot immediately confirm.

    A useful template is: Brand: [specific outcome]. [Proof tied to the user’s constraint]. [Simple next action]. The brackets are not an invitation to stuff several benefits into one placement. Choose one reason to continue.

    Specificity needs controls. If you advertise a price, rate, discount, delivery window, or availability claim, it must be current, approved, and visible at the destination. A concrete figure can improve clarity, but an outdated figure creates both conversion friction and potential compliance exposure. When the value changes frequently, build a review process before testing it in ad copy.

    Test in an order that explains the result

    Changing the headline, proof, call to action, and landing page at the same time may produce a winner, but it will not tell you why it won. Start with the variables most closely tied to conversational relevance:

    1. Specific offer versus general benefit.
    2. Query-matched benefit versus broad category language.
    3. Quantified proof versus qualitative proof.
    4. Low-commitment call to action versus immediate purchase or signup language.
    5. General landing page versus a page that continues the same constraint and benefit.

    Hold the other elements steady during each comparison. The point is not merely to improve the ad. It is to learn which part of the conversation your audience needs resolved before moving forward.

    Measure prompt coverage and response duplication before calling it reach
    An overhead arrangement of varied prompt tokens connects to response cards, including a magnified cluster of visibly duplicated cards.

    Clicks and conversions still matter, but they do not tell you whether your brand is present across the conversations that matter. Conversational inventory needs an observation layer organized around topics, prompts, and individual responses.

    That becomes especially important because one brand has been observed appearing twice within the same ChatGPT response. This double-parked behavior creates more placements, but it does not automatically create more unique reach. Counting each placement as a separate conversation would overstate coverage.

    For every observed placement, record the topic, prompt or prompt class, response identifier, timestamp, position, advertiser, headline, body, and destination. Add post-click outcomes when your analytics can connect them. That record supports several more useful measurements:

    • Observed prompt coverage: the portion of your monitored commercial prompts in which your brand appeared.
    • Observed response presence: responses containing your brand divided by eligible responses you actually monitored.
    • Duplication rate: brand-present responses containing more than one placement for the same brand.
    • Competitor overlap: responses where your brand and a named competitor appeared together.
    • Creative-context match: whether the ad reflects the category, constraint, and decision criterion in the prompt.
    • Post-click continuity: whether the destination preserves the offer and language that earned the click.
    • Business outcome: qualified lead, sale, signup, or another result defined before the pilot.

    Call these observed rates, not platform-wide impression share. A monitoring sample cannot tell you the total number of eligible conversations unless the platform provides that denominator. This naming discipline prevents a directional visibility metric from turning into a false market-share claim.

    Review duplication separately from performance. Two appearances might reinforce recall, or they might add no incremental value. The placement pattern alone cannot settle that question. Compare duplicated and single-placement responses only when you have enough campaign data to evaluate their downstream outcomes.

    Your landing-page review should be just as specific. Check whether the advertised benefit appears without searching, whether the price or rate matches, whether the next action is obvious, and whether the page answers the constraint expressed in the originating conversation. A relevant ad that lands on a general homepage throws away the context that made the placement useful.

    Coordinate ChatGPT ads with AEO and GEO without merging the KPIs

    Paid presence and organic AI visibility can occur in the same conversational environment, but they are not the same achievement. A sponsored placement buys labeled exposure. An organic citation, recommendation, or brand mention depends on how the system constructs its answer. Early placement observations do not establish that buying ads improves organic answer inclusion.

    Keep the two lanes separate in reporting. If you combine them into one AI visibility number, you will not know whether a change came from media spend, content improvements, brand demand, or answer-engine behavior.

    • Use one shared topic map. Organize paid monitoring and organic visibility work around the same commercial questions, constraints, entities, and decision criteria.
    • Give paid media its own outcomes. Track observed presence, duplication, clicks, qualified actions, and campaign economics.
    • Give AEO and GEO their own outcomes. Track whether the brand is mentioned, cited, represented accurately, and connected to the intended category across monitored answers.
    • Align the factual layer. Prices, rates, features, availability, and offer terms should agree across ad copy, visible page content, and applicable structured data.
    • Investigate cross-channel clues. A commercial prompt with competitor ads but weak organic answers may expose a content opportunity. Strong organic visibility with no paid presence may identify a conversation worth testing, but neither observation guarantees demand or return.

    JSON-LD can clarify entities, products, offers, and other machine-readable facts when it accurately represents visible content. It does not purchase inventory, guarantee inclusion in an AI response, or repair a weak offer. Use structured data to reduce ambiguity, then use advertising to test whether a clear commercial promise earns action.

    This coordinated model also gives you a cleaner competitive view. You can distinguish a competitor that is buying exposure from one that is repeatedly earning non-sponsored visibility. The response is different: one may call for a media test, while the other may require better content, stronger entity signals, clearer proof, or a more competitive offer.

    Key takeaways for your first ChatGPT ad pilot

    • Treat early placement data as evidence about format and creative conventions, not as a guaranteed ROI benchmark.
    • Write for a user who has already supplied context: lead with the brand, one verified benefit, one proof point, and one next action.
    • Use the observed 30-character headline and 19-word body patterns as editing discipline, not as assumed platform limits.
    • Test concrete figures before vague claims when your offer supports them, but keep every price, rate, and term synchronized with the destination.
    • Measure prompts and unique responses as well as placements, because two appearances in one response do not equal two reached conversations.
    • Coordinate paid, AEO, GEO, landing-page content, and structured data around one topic map while reporting paid and organic outcomes separately.

    Your next move is a narrow pilot, not a platform-wide commitment. Choose a small set of high-intent topics, document the user’s constraints, create controlled variations, and establish an organic visibility baseline before ads run. You will then be able to decide from your own evidence whether conversational advertising adds qualified demand, merely adds placements, or reveals a larger content opportunity.
    References

  • How to Prepare for ChatGPT’s Advertising Expansion

    How to Prepare for ChatGPT’s Advertising Expansion

    If you’re deciding whether ChatGPT belongs in your paid media plan, don’t treat its advertising expansion as a cue to move budget immediately. Treat it as a cue to become test-ready. The opportunity may be meaningful, but availability, targeting, reporting, and campaign economics still need to be proved.

    Your advantage won’t come from being first at any cost. It will come from knowing exactly what you want to learn, what evidence would justify more investment, and how paid placement fits beside your existing SEO, AEO, and generative engine optimization work.

    The expansion addresses inventory, not the whole advertising case

    Early observations indicate that ads are appearing within conversations for some logged-out users, although OpenAI had not formally announced the expansion. That uncertainty matters. A visible rollout can establish that inventory is growing without establishing who can buy it, which users are eligible, how delivery is priced, or whether the experience is stable enough for forecasting.

    The immediate pressure appears to be supply. Pilot advertisers have reportedly struggled to spend their intended budgets because inventory was limited, even after the financial hurdle fell from $200,000 to $50,000. Opening more conversations to ads is a logical way to create additional opportunities for delivery.

    That doesn’t automatically make ChatGPT a scalable performance channel. More inventory can help campaigns spend, but it doesn’t prove that the added impressions will produce qualified traffic, incremental customers, or acceptable acquisition costs. Logged-out reach could also differ from logged-in reach in ways that affect relevance and measurement. Until the buying interface or your agreement provides the details, don’t assume the platform can recognize, target, exclude, or report on these two audiences in the same way.

    Keep ChatGPT out of your dependable base forecast for now. Put it in an experimental budget with its own success criteria and loss limit. That protects the budget you already rely on while giving you room to learn if access becomes available.

    Key takeaways

    • Wider logged-out reach may relieve an inventory constraint, but it doesn’t yet establish stable campaign economics.
    • Conversational placement deserves its own creative and landing-page strategy; repurposing a display banner is unlikely to answer the user’s immediate need.
    • Require definitions for delivery, targeting, attribution, and logged-in versus logged-out reporting before committing meaningful budget.
    • Measure paid placement separately from organic AI visibility. Buying an ad doesn’t demonstrate that ChatGPT knows, cites, or recommends your brand.
    • Prepare a controlled pilot now, but release money only after the platform can support the decisions you need to make.

    Build the pilot around one commercial decision

    A hand adjusts one control on a transparent testing chamber as a single campaign tile moves toward two possible outcomes.

    Novelty is not a campaign objective. A useful pilot answers a decision such as: Should we add this channel to our acquisition mix? Can it reach buyers earlier than search ads? Does it create qualified demand we wouldn’t otherwise capture? Choose one question. A pilot designed to prove awareness, traffic quality, lead generation, and revenue at once usually produces an ambiguous answer to all four.

    1. Choose one demand state. Define the situation in which your offer helps, such as comparing approaches, narrowing a shortlist, solving an urgent problem, or selecting a provider. Don’t assume the platform lets you bid on exact prompts. Ask what targeting controls actually exist, then translate your demand state into the controls available.
    2. Name one primary business outcome. Use a completed purchase, qualified lead, activated account, booked consultation, or another event connected to value. A click can diagnose delivery, but it shouldn’t become the business case merely because it is easy to count.
    3. Set a quality guardrail. For lead generation, that could be lead acceptance or sales qualification. For commerce, it could be cancellation, return, or contribution margin. A campaign can report an attractive acquisition cost while sending customers who never become profitable.
    4. Create a landing page for the conversational handoff. Restate the promise plainly, answer the next likely question, provide evidence for important claims, and make the next step obvious. If the advertisement answers one question but the page opens with a generic corporate message, you lose the contextual advantage of the placement.
    5. Prepare multiple message angles. Ads have been observed fitting into the conversation rather than behaving like conventional banners. Write concise copy around the user’s task: a direct answer or benefit, a relevant qualification, and a proportionate next step. Keep every claim defensible when read outside the surrounding conversation.
    6. Write the expansion rule before launch. Define the acquisition cost, conversion quality, and measurement confidence needed for more investment. Also define the conditions that stop the test. Historical economics from your own business are more useful here than an arbitrary industry benchmark.

    Your test charter should also identify the comparison that matters. If ChatGPT merely receives budget that would have converted through paid search, platform-reported conversions may look encouraging without adding much business value. Compare the pilot with your normal channel mix, not with doing nothing in an imaginary market.

    Demand measurement answers before you demand scale

    Conversational advertising can create a less familiar path than keyword, feed, or social advertising. A person may ask several questions, see a commercial placement, leave, research the brand elsewhere, and convert later. That makes a clean platform dashboard especially tempting. It also makes unexamined platform attribution especially risky.

    Before launch, get written answers to the questions that can change your interpretation of performance:

    • What event counts as an impression, and can one conversation generate more than one?
    • What counts as a click or other engagement?
    • Which click-through or view-through attribution windows are used?
    • Can you change those windows or compare them with your analytics standard?
    • Can results be segmented by logged-in status, placement type, geography, device, creative, and audience method?
    • What contextual, behavioral, demographic, or account-level signals can influence delivery?
    • Which exclusion, frequency, suitability, and sensitive-topic controls are available?
    • How are duplicate conversions, invalid interactions, refunds, cancellations, and offline outcomes handled?
    • Can you export event-level or sufficiently granular campaign data for independent reconciliation?

    A missing answer is information. If you can’t distinguish the new logged-out inventory from the rest of delivery, you won’t know whether the expansion improved reach, reduced quality, or simply changed the mix. If you can’t align attribution windows, you won’t be able to compare ChatGPT with another channel fairly.

    Build reporting in four layers. Delivery tells you whether the campaign can spend. Response tells you whether people engage. Business quality tells you whether those interactions become valuable outcomes. Incrementality asks whether the outcomes would have happened without the campaign. Keep these layers separate so a strong click rate cannot disguise weak economics.

    Use a controlled comparison if one is available and proportionate. A randomized holdout is the clearest option when the platform supports it. Otherwise, use a carefully chosen geographic or time-based comparison and document its limitations. Seasonality, promotions, sales activity, and changes in other media can all create false lift. Don’t call a before-and-after difference incremental merely because the dates line up.

    Preserve campaign and creative identifiers in your analytics, connect conversions to revenue or lead quality where consent and applicable rules allow, and deduplicate outcomes across platforms. Compare the platform’s totals with your own analytics before increasing spend. A disagreement doesn’t automatically mean one system is wrong; attribution systems can assign the same conversion differently. It does mean you need to understand the difference.

    Keep paid ChatGPT reach separate from organic AI visibility

    ChatGPT advertising and generative engine optimization address different problems. An ad buys an opportunity to appear under specified campaign conditions. Organic visibility depends on whether a system can discover, interpret, trust, and use information about your brand or subject. Paid delivery is not evidence of organic inclusion, and an organic mention is not evidence that advertising caused it.

    This distinction should shape both your dashboard and your content plan. Report paid impressions, engagements, conversions, acquisition cost, and incrementality as campaign metrics. Track organic citations, brand mentions, referred visits, answer accuracy, and visibility across relevant prompts as a separate program. You can examine relationships between them, but don’t combine them into one score that hides which mechanism changed.

    The landing pages used for conversational ads should still meet the same evidence standard as your organic content:

    • Answer the visitor’s central question before forcing them through a broad brand narrative.
    • Use descriptive headings that make each section understandable on its own.
    • Identify products, services, organizations, and authors consistently across the page and site.
    • Support material claims with evidence a reader can inspect.
    • Keep prices, availability, policies, and other changeable facts current wherever you publish them.
    • Use schema types and properties that accurately represent visible content. JSON-LD can clarify entities and relationships, but it cannot guarantee inclusion in an AI answer or eligibility for an advertisement.
    • Make ownership, contact details, and the path to a real next step easy to verify.

    Use paid learning to improve content only when the data supports the connection. If a message angle attracts qualified visitors, examine the underlying need and build a fuller answer around it. Don’t manufacture near-duplicate pages for every phrasing variation, and don’t turn an advertising result into an unsupported claim about what all ChatGPT users want.

    The reverse is useful too. Organic visibility analysis can reveal questions where your brand is absent, misunderstood, or poorly supported. Those gaps can inform a paid hypothesis while you improve the underlying content. The advertisement may create immediate reach; the content fixes the durable information problem.

    Use a readiness gate before committing budget

    A strategist waits beside budget tokens while an amber checkpoint keeps a multi-stage gate partly closed before a field of blank message shapes.

    You don’t need to choose between rushing in and ignoring the channel. Use three readiness states.

    • Prepare now if ChatGPT is relevant to how your buyers research or compare solutions. Create the test charter, conversion definitions, landing page, creative hypotheses, suitability rules, and reporting requirements without assuming access.
    • Test when available if you can isolate a meaningful business outcome, cap the downside, reconcile conversion data, and learn something that affects a real channel decision. Learning value matters, but it should be named rather than used as an excuse for unlimited spending.
    • Delay investment if access requires a commitment your experiment cannot justify, essential targeting or safety controls are missing, results cannot be independently reconciled, or your landing experience is not ready. Scarcity of access is not proof of value.

    The reported reduction from $200,000 to $50,000 still represents material exposure for many organizations. Don’t commit merely to reserve a place in a pilot. Confirm the contract terms, cancellation rights, measurement access, inventory expectations, and responsibility for unsuitable placement before funds become difficult to recover.

    Start with a one-page test charter. Write down the user need, primary outcome, quality guardrail, maximum acceptable downside, required platform answers, and expansion rule. When broader access arrives, that page will let you evaluate the opportunity on business evidence instead of launch momentum.

    References


  • Discover How OpenAI is Revolutionizing Ads with ChatGPT CPC

    Discover How OpenAI is Revolutionizing Ads with ChatGPT CPC

    Have you heard the news that OpenAI has introduced CPC ads to ChatGPT? This strategic shift has transformed it into a performance-driven channel, offering advertisers new avenues for engaging intent-driven audiences and tracking ROI.

    OpenAI is moving away from a focus purely on impressions in ChatGPT to prioritize performance. This change places OpenAI in direct competition with giants like Google by adopting cost-per-click (CPC) ads, allowing advertisers to pay only when users click on their ads.

    What’s happening? OpenAI has started testing CPC ads within ChatGPT, where advertisers only pay when their ads receive clicks. Initial reports highlight that these clicks are priced between $3 to $5. They’re rolling out this feature through a limited ads manager, alongside their existing CPM-based model.

    Why now? The main catalyst seems to be pricing pressure. Since its launch, ChatGPT’s CPMs have significantly decreased from around $60 to approximately $25. Switching to CPC helps mitigate this decline by connecting revenue to tangible outcomes rather than mere impressions.

    Why do we care? With its evolution into a performance channel, ChatGPT is now not just a branding space. The CPC pricing model makes it easier for us to connect budgets directly to measurable actions, test ROI, and compare these results with channels like Google Search.

    I’m excited about the opportunity for advertisers to access what could be a high-intent audience in a new format. This presents a first-mover advantage before competition—and the associated costs—escalate.

    The bigger picture: This isn’t just a pricing change; it’s a strategic pivot. By embracing CPC advertising, OpenAI challenges Google’s dominance in the market, thereby positioning ChatGPT as a contender for performance marketing budgets.

    Reading between the lines: A major challenge lies in proving user intent. While search advertising is effective because it captures users actively searching for something, ChatGPT’s conversational context needs to generate clicks with equal value. Advertisers will likely compare these results directly with Google, setting a high standard for quality and conversion.

    Zoom out: Advertising is becoming integral to OpenAI’s long-term revenue plan, supported by investments in ad infrastructure, measurement tools, and a wider self-serve platform.

    Bottom line: By implementing CPC ads, OpenAI is vying for the performance-driven ad dollars that have long supported traditional search platforms.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Unveiling AI Chatbot Conversion Secrets: ChatGPT Dominates

    Unveiling AI Chatbot Conversion Secrets: ChatGPT Dominates

    In this report, I’m going to walk you through a comparison of conversion rates among the four leading AI chatbots: ChatGPT, Gemini, Claude, and Perplexity.

    From May 2025 through April 2026, my research team conducted an in-depth study on AI conversion rates across various industries. We used anonymized data from more than 150 client companies, honing in on the most popular generative AI chatbots. Building on our previous analysis of ChatGPT conversion rates, we noted that most companies in our dataset had invested in generative engine optimization. The fascinating results of our study are presented below.

    AI Conversion Rates by Industry

    IndustryChatGPTGeminiClaudePerplexity
    Addiction Treatment2.9%2.6%2.6%2.0%
    Apparel & Fashion2.8%1.4%3.4%2.0%
    B2B SaaS2.4%2.2%1.9%1.9%
    Biotech2.1%1.3%1.7%1.3%
    Commercial Insurance3.1%2.8%2.8%1.9%

    Key Findings

    While all chatbot traffic converts at higher rates than traditional SEO, my study shows that ChatGPT and Perplexity typically have higher conversion rates compared to Gemini and Claude. This might be due to the greater user trust vested in ChatGPT and Perplexity’s recommendations.

    Claude stands out in knowledge-driven and regulated industries. Its performance in Healthcare, Higher Education, and Industrial IoT indicates that professionals in these fields favor Claude for more detailed, analytical queries.

    Industries such as Engineering, Software Development, and Transportation & Logistics exhibit relatively low conversion rates overall. This might suggest less dependence on AI tools or more specialized workflows not captured within this dataset.

    B2B SaaS and Financial Services demonstrate moderate but closely clustered conversion rates across all models, likely reflecting significant but cautious AI adoption given potential compliance concerns and familiarity with AI limitations.

    If you want a PDF copy of this report or wish to know more about our GEO services, reach out here.

    Source


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • AI Search: Navigating New Reputation Risks Effectively

    AI Search: Navigating New Reputation Risks Effectively

    I remember the days when a Google search was akin to embarking on a quest for information. It was an adventure of navigating various links and forming my own opinions.

    Nowadays, tools like AI Overviews, ChatGPT, and Perplexity condense all that information into a single, simplified answer. This transformation often strips away the finer details while amplifying certain perspectives.

    This shift has redefined online reputation management. Now, search engines not only present information but shape the underlying narratives. This raises the stakes for brands, as even a top-ranking status doesn’t guarantee influence if AI stories tell a different tale.

    For brands, the game has changed. Being number one doesn’t ensure visibility and influence anymore. The underlying narrative holds far greater power.

    AI Narrative Formation: Crafting User Answers

    AI platforms now utilize what I like to call ‘AI narrative formation.’ This process crafts the responses we receive from various search engines. Let me walk you through how this system works.

    Source Pooling

    These systems pull content from numerous sources. Contrary to expected reliance on peer-reviewed articles, they gather data from Reddit, YouTube, and social platforms like Instagram and TikTok.

    Signal Weighting

    Not all sources are equal. Often, a popular yet low-quality source can outweigh a singular, credible entry. A bustling Reddit thread with negative feedback might overshadow a well-researched Wikipedia page.

    Narrative Compression

    The summarization process compresses diverse inputs, often losing nuance along the way. Complex reputations are simplified into general statements like, ‘Users find this company untrustworthy.’

    Continued Reinforcement

    These summaries transcend their original context, getting shared and re-shared across social media. As these echoes return as new data, they further entrench the narratives in AI responses.

    Explore deeper: How AI is Redefining Authority in Search

    Unraveling a Finance Company’s Reputation in AI Search

    To illustrate AI narrative formation, consider a recent case I worked on involving a financial company, which we’ll call Company X.

    Company X’s reputation remained strong on traditional SERPs. High Trustpilot ratings and reputable endorsements were the norm until Google AI Overview threads surfaced a forgotten Reddit forum rife with grievances against them.

    The AI Overview skewed the narrative, suggesting Company X had unresolved customer service issues, even though these concerns had been addressed years prior. This created a skewed perception that was hard to counteract.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    The Amplified Risk from AI Searches

    AI dramatically increases reputational risk through several mechanisms:

    • The Spread of Negative Narratives: Negative content surfaces faster and more prominently than before.
    • AI Hallucinations: Despite growing awareness, AI inaccuracies continue to deceive.
    • The Snowball Effect: Repeated narratives gain momentum, complicating reputation management efforts.

    It has become evident that in ORM, repetition often overrides accuracy.

    Explore deeper: Generative AI’s Defamation Challenges

    Auditing AI-Generated Narratives: A Step-by-Step Approach

    Let’s consider a situation involving an AI-generated narrative challenge faced by CEO X of a well-known SaaS company.

    After an out-of-context quote from CEO X’s podcast appearance went viral, AI summarized him unfavorably. Quickly, his reputation transformed negatively across major platforms.

    Step 1: Mapping Queries

    I initiated a process to understand what queries AI outputs were generating about CEO X. This helped identify the underlying issues.

    Step 2: Capturing Outputs

    Identifying repeated claims revealed how CEO X was perceived. Narratives from Google AI and ChatGPT were consistently portraying him negatively.

    Step 3: Delving Through Sources

    The next step involved examining the quality of sources contributing to these narratives, often outdated or lacking accuracy.

    Step 4: Analyzing the Narrative Gap

    This involved assessing discrepancies between AI narratives and his actual reputation, contextualizing the initial quote, and examining the long-standing perception of CEO X.

    Step 5: Correcting and Replacing Sources

    Finally, I focused on directly addressing, correcting, and replacing those negative narratives. This involved engaging directly with platforms that contributed to the misinformation and reinforcing positive content elsewhere.

    Explore deeper: Responding to Negative AI Reviews

    A New Perspective: From SEO to Narrative Management

    The focus has shifted from merely achieving top SEO rankings to understanding and adapting to narrative shifts. We must rethink our strategy from content engagement to managing the narratives AI disseminates.

    To succeed, it’s important to reinforce AI systems with quality inputs, including crafting high-quality content, pursuing credible mentions, disseminating structured data, and managing misinformation directly.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Write Clearer ChatGPT Ads That Match User Intent

    Your ChatGPT ad may appear at the exact moment someone is comparing options, checking a price, or deciding what to do next. If the reader has to decode a slogan before understanding the offer, the useful answer around the ad will usually be more compelling.

    Treat the ad as a compact decision aid. Identify the brand, state the relevant benefit, support it with something concrete, and offer one sensible next action. Creativity still matters, but it has to make the decision easier rather than make the message harder to parse.

    Clarity fits the way people use a conversational interface

    A person asking ChatGPT for help is not necessarily browsing for entertainment or waiting to be intrigued. A prompt about pricing, alternatives, features, or suitability can signal that the person is already evaluating a decision. In that setting, the ad competes with an answer designed to be immediately useful.

    That changes the job of the copy. A conventional brand slogan can ask the audience to remember an idea now and understand its relevance later. A conversational ad has less room for that delay. It needs to explain who is speaking and why the offer belongs in this particular decision.

    Across an analysis covering more than 40,000 ChatGPT ad placements, the recurring style was concise, structured, contextual, and oriented toward high-intent users. The dominant headline pattern put the brand before the benefit, often separated by a colon.

    Think of this as paid search translated into dialogue. Relevance is still central, but matching a keyword is not enough. The copy must fit the question behind the prompt and sound like assistance rather than an interruption.

    This does not mean every ChatGPT user is ready to buy, or that short copy wins by itself. The placement observations show useful patterns, not a universal causal rule. Use them as a starting architecture, then validate them against your own audience, offer, and conversion data.

    Give the headline and body one job each

    The observed average headline was about 30 characters and five words. Body copy averaged roughly 116 characters and 19 words. Those are descriptive averages, not known platform limits. Do not remove a necessary condition or qualification merely to hit a character count.

    Use the averages as an editing discipline. If your message cannot fit near that range, the problem may be that the ad is trying to communicate several benefits, answer several objections, or serve several intents at once.

    1. Make the headline identify the choice. Start with [Brand]: [Primary benefit]. The brand tells the reader who is making the offer; the benefit explains why it deserves attention.
    2. Make the first body sentence substantiate the benefit. Use an applicable price, a defensible performance metric, or a precise description of what the offer provides.
    3. Make the second body sentence advance the decision. Ask for one direct action such as Compare, Shop now, or Book.

    The working template is simple:

    Headline: [Brand]: [Benefit]
    Body: [Concrete proof relevant to the prompt]. [Direct next action].

    Write the full, truthful claim before compressing it. Then label every phrase as brand, benefit, proof, action, or necessary qualification. Remove anything that does not perform one of those jobs. This protects the substance of the offer while exposing filler.

    A useful headline test is whether an unfamiliar reader can answer two questions immediately: who is offering this, and why should it be considered? A useful body test is whether each sentence either reduces uncertainty or moves the reader to the next step.

    Mirror the decision, not just the words in the prompt

    Context mirroring is more than repeating a term from the user’s question. You need to identify the decision the person is trying to make, then place the information required for that decision in the ad.

    If someone is comparing options, a broad awareness message is a mismatch even when it contains the right product keyword. If someone is checking cost, an abstract promise of value leaves the central question unanswered. The strongest observed messages reflected the query or conversational environment instead of relying on keyword overlap alone.

    Decision behind the promptWhat the ad should resolveSuitable action
    Comparing alternativesThe brand’s relevant differentiator, supported by concrete evidenceCompare
    Checking affordabilityThe price or priced term that actually appliesShop now, when an immediate purchase is possible
    Checking suitabilityThe capability that matches the stated requirementBook, when evaluation requires a conversation or demonstration
    Reducing commitmentA genuinely free trial or demo and the condition that defines itBook or the most direct available trial action

    Build separate messages for these decisions. One all-purpose ad usually becomes vague because it has to accommodate incompatible questions. A comparison message needs a differentiator. A price message needs a price. A suitability message needs evidence of fit.

    Do not mirror irrelevant details merely because they appear in the prompt. Repeat only the context that changes the recommendation or the next step. The goal is recognition – the reader should see that the offer addresses the task at hand – without producing copy that feels mechanically assembled.

    Use concrete proof and a low-friction action

    Specificity matters because a high-intent reader is trying to reduce uncertainty. Generic claims such as better, smarter, or leading do not provide much material for a comparison. A concrete price or measurable result can.

    Dollar signs and specific numerical claims, including prices and performance metrics, were associated with stronger performance than generic promises. That does not make any number persuasive. The figure must answer the user’s question, apply to the advertised offer, and remain consistent with the destination page.

    • Use a price when price affects the decision. State the applicable amount or pricing term instead of claiming that the offer is simply affordable.
    • Use a performance metric when it can be supported. Preserve the scope and qualification needed to keep the claim accurate.
    • Use a precise capability when no responsible number is available. A truthful, concrete description is more useful than numerical decoration.
    • Use free only when the offer is genuinely low-friction. Make any material limitation, required payment method, or conversion to a paid plan clear at the point where it matters.

    Free trials and demos can lower the commitment required from someone who is still evaluating. The word itself is not the strategy. The strategy is reducing the size of the next decision while accurately explaining what the reader receives.

    The call to action should name that next decision. Direct actions such as Shop now, Compare, and Book fit this format better than a vague Learn more prompt because they tell the reader what will happen next. Choose the verb that matches the destination. Do not use Shop now for a form that merely starts a sales conversation, or Book for a page with no scheduling path.

    Keep the tone calm. Heavy punctuation, inflated superlatives, and rhetorical questions make the ad sound less like useful guidance and more like an interruption. Confidence comes from a clear claim, relevant proof, and an honest next step.

    Test clarity as a message system, not a character count

    The observed averages give you a credible place to begin, but your own testing must determine what converts for your offer. A shorter variant is not automatically clearer. It can also be incomplete. Define the decision your ad must support before deciding which words to cut.

    Key takeaways

    • Put the brand and primary benefit in the headline so the reader can identify the choice immediately.
    • Use the body to provide one concrete proof point and one direct next action.
    • Match the message to the decision behind the prompt: comparison, price, suitability, or commitment.
    • Use numbers and free offers only when they are accurate, relevant, and consistent with the destination.
    • Treat 30 headline characters and 116 body characters as observed averages, not mandatory limits or guarantees of performance.

    A practical testing sequence

    1. Choose one intent group. Start with prompts that represent the same decision. Mixing price research, comparisons, and general discovery can conceal which message actually worked.
    2. Write a specific hypothesis. For example, test whether placing the brand before the benefit improves qualified actions, not whether a broadly different ad is better.
    3. Change one component. Test the headline structure, proof point, action, or contextual wording separately. Keep the offer, destination, and other controllable conditions consistent.
    4. Select the conversion before the test. Use the business action the ad is meant to produce as the primary measure. Treat clicks or other engagement signals as diagnostic measures when they do not represent the final objective.
    5. Inspect post-click quality. A curiosity-driven ad can attract attention without helping the right person act. Check whether the destination behavior supports the same conclusion as the initial engagement metric.
    6. Record the context with the result. Save the prompt intent, copy element changed, offer, destination, and outcome. A reusable lesson is more valuable than an isolated winning variant.

    Avoid changing the headline, proof, offer, and call to action in the same comparison. You may find a winner, but you will not know which decision to carry into the next campaign. Also avoid declaring success from an early fluctuation. Set the sample and decision rule appropriate to your traffic and analytics process before looking at the result.

    Start with the highest-intent prompt category you can identify. Rewrite one ad so the brand, benefit, proof, and action are visible without interpretation, then test whether that clarity improves the action that matters after the click. Expand the pattern only after it proves useful for your audience.

    References

  • How AI Search Engines Prefer Reddit, YouTube, and LinkedIn

    How AI Search Engines Prefer Reddit, YouTube, and LinkedIn

    AI citations

    During a recent study, I discovered that Reddit stands out as the most-cited domain in AI-generated answers. In fact, it’s ahead of heavyweights like YouTube and LinkedIn, thanks to an analysis of 30 million sources conducted by Peec AI, a tool specializing in AI search analytics.

    The findings: I’ve learned that Reddit claims the top spot across various AI platforms including ChatGPT, Google AI Mode, Gemini, Perplexity, and AI Overviews. Top contenders YouTube, LinkedIn, Wikipedia, and Forbes are right behind. Platforms like Yelp and G2 frequently appear when searching for recommendations.

    As I delved deeper into the research, it became clear which domains the AI models tend to lean on:

    • ChatGPT values Wikipedia, Reddit, and editorial sites like Forbes.
    • Google shows preference for platforms such as Facebook and Yelp.
    • Perplexity favors Reddit, LinkedIn, and G2 for queries within the B2B realm.

    Why we care: The insight that resonated with me was the importance of having authority beyond just our own websites. Brands that consistently feature on reputable third-party platforms have a better chance of being cited by AI.

    Why these sources? It’s fascinating to see how AI systems are wired to prioritize both authority and authentic user input:

    • I’ve found that Reddit excels because it mirrors genuine user discussions.
    • YouTube shines in video citations, owing to their comprehensive transcripts and descriptions.
    • Wikipedia not only serves real-time data but also acts as a foundation for training datasets.

    About the data: The analysis spanned 30 million sources, providing a comprehensive look at how often domains are directly cited in AI answers, effectively revealing what shapes these responses.

    The study. For those interested in a deep dive, the full study is available here: Top domains cited by AI search: Analysis based on 30M sources

    Dig deeper. For more on citation research, check out these fascinating reads:


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Local Discovery Across Google and ChatGPT: A Practical Plan

    Local Discovery Across Google and ChatGPT: A Practical Plan

    A customer who searches Google for a nearby provider and another who asks ChatGPT for a local recommendation may want the same outcome, but they reach it through different discovery systems. If you optimize only for the map pack or only for conversational answers, your business can be easy to find in one place and absent in the other.

    Your job is to establish one dependable record of each location, then present and measure that record appropriately on each surface. That means treating your Google Business Profile, location page, visible business facts and structured data as one system without pretending Google and ChatGPT have the same ranking model.

    Google and ChatGPT answer different versions of a local question

    Google local discovery is strongly tied to explicit profile fields and geography. Your business name, primary category, secondary categories, services, reviews, linked landing page and physical proximity can all shape where the business appears. A geo-grid can show that visibility changing from one neighborhood or city boundary to the next.

    ChatGPT handles the discovery moment as a conversation. The user can describe a service, constraint and area in ordinary language, and shared location can make the local response more precise. Location is therefore a meaningful input, but that does not establish a permanent ChatGPT rank comparable to a map-pack position.

    This distinction changes how you work. Measure Google across physical points on a grid. Evaluate ChatGPT with repeatable prompts and controlled location context. A strong result on either surface is useful, but it cannot serve as a proxy for the other.

    Key takeaways

    • Build a single, accurate location record before optimizing individual discovery surfaces.
    • Audit Google Business Profile signals against the businesses that actually rank in your local grid, not against generic benchmarks.
    • Use a dedicated page for each real location and align it with the profile that links to it.
    • Keep LocalBusiness structured data consistent with facts a visitor can see on the page.
    • Test ChatGPT with fixed prompts and compare responses with and without shared location when that option is available.
    • Treat proximity limits and conversational omissions as different problems requiring different fixes.

    Start with a five-part Google Business Profile audit

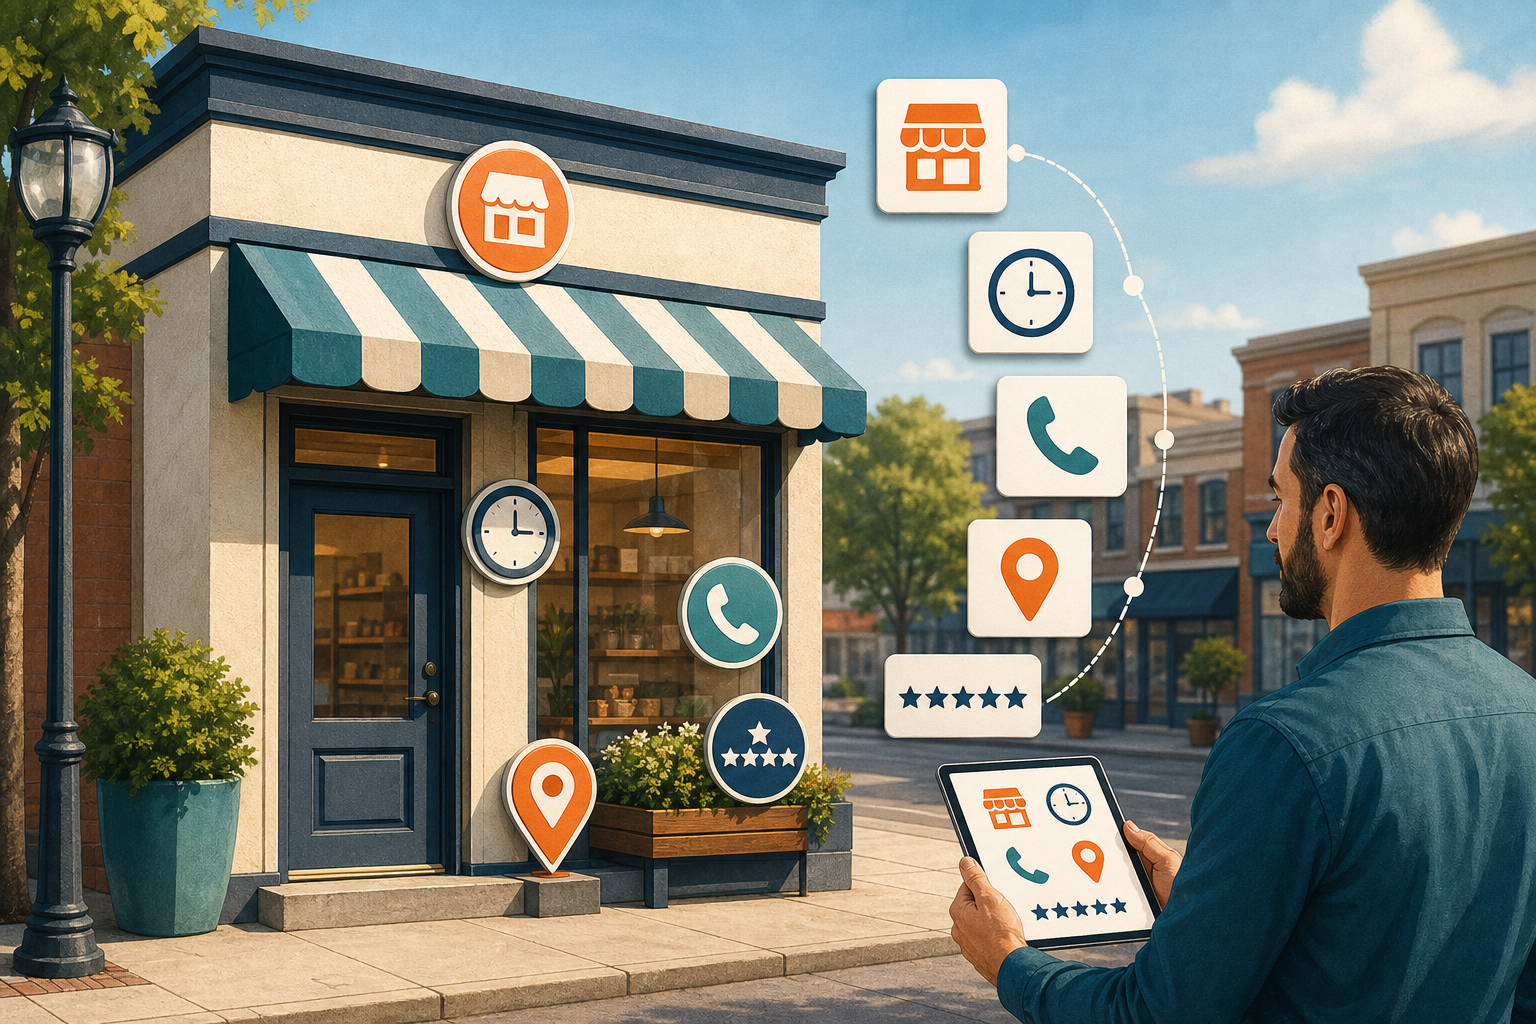
    A business owner uses a tablet while five icon-based checkpoints surround a neighborhood storefront, including a map pin, clock, phone, category symbol, and rating stars.

    A profile audit becomes useful when it explains a visibility gap. Begin with the competitors appearing for the same commercial query in the areas you want to reach. Their lifetime review totals may look impressive, but totals alone do not tell you which signals separate the current winners.

    1. Compare review recency and velocity. Look at how frequently leading competitors have earned reviews recently, not just how many they have accumulated. Fresh and consistent review activity can matter more than a large historical total. There is no universal target in this evidence, so derive your benchmark from the listings winning your own searches. Places Scout or Whitespark geo-grid data can help you connect review patterns with visibility. If you manage many markets, Places Scout API data can turn that comparison into a recurring monitor.
    2. Verify the business name. A relevant keyword in a legitimate business name can have an outsized effect on local visibility. Do not add a service or city merely as a profile tactic when it is not part of the documented name. A DBA may make a name change legitimate, but it also creates legal, administrative and brand consequences. Treat it as a business decision, not a metadata shortcut.
    3. Inspect the primary category first. The primary category can substantially influence local ranking. Compare the primary categories used by top businesses for the query you care about, then choose the closest truthful description of your core offering. Add relevant secondary categories and review the available service selections, but do not dilute the profile with categories the location cannot support.
    4. Evaluate the linked landing page. A generic homepage forces both customers and machines to work out which location, service and contact details apply. A dedicated, keyword-focused location page can create better alignment between the profile and its destination. Check that the page identifies the same business, location and services as the profile.
    5. Map the proximity ceiling. Visibility often contracts as the search point moves away from the location or crosses a city boundary. A ranking-radius view helps you distinguish an optimization problem from a geographic limitation. Local Falcon’s Share of Local Voice can help show the realistic reach of a location. If the business is strong nearby and consistently weak farther away, more profile edits may not solve the actual constraint.

    Complete the audit before changing fields. Otherwise, a category edit, review campaign and page rewrite can overlap, leaving you unable to tell which change helped or hurt. Record the starting grid, profile configuration, linked page and recent review pattern, then make the change supported by the clearest gap.

    Turn each location page into a reliable entity record

    The page linked from your profile should resolve local uncertainty quickly. A visitor should not have to infer whether the location offers the requested service, whether it serves the relevant area or how to contact it. The same clarity also gives parsers less ambiguity to reconcile.

    Make the visible page complete before adding schema

    • Identify the business and location in the opening copy using the same legitimate name shown on the profile.
    • Describe the primary services in plain language and keep them aligned with the profile’s categories and service selections.
    • Show the applicable address, service area, telephone number, opening hours and contact path.
    • Explain meaningful local constraints such as appointment coverage, access, service boundaries or location-specific availability.
    • Address the questions that determine whether a nearby customer is a fit instead of filling the page with interchangeable city-name paragraphs.
    • Link the corresponding Google Business Profile directly to this location page rather than sending every profile to the homepage.

    If you operate multiple locations, give each real location its own URL and its own accurate details. Do not manufacture local relevance with addresses, service areas or location pages that do not represent an operating business. Besides misleading the reader, false location claims make your first-party record harder to keep consistent.

    Use LocalBusiness JSON-LD to describe, not embellish

    Choose the most specific LocalBusiness subtype that truthfully describes the location. Give the entity a stable @id and include relevant properties such as name, URL, telephone, address and openingHoursSpecification when those facts apply. Each physical location should have its own URL, identifier and location-specific values.

    The markup should agree with the page and profile. Do not put a different name in JSON-LD, mark up an address the visitor cannot find, or use areaServed to claim places the business does not genuinely serve. Validate the syntax before deployment, then verify the rendered page still exposes the underlying facts to a human reader.

    Structured data is useful for explicit entity description, but it is not a substitute for the profile, reviews, landing-page content or physical relevance. It also should not be treated as a guaranteed switch for ChatGPT inclusion. Its immediate job is simpler: prevent your own publishing stack from telling conflicting stories about the business.

    Measure Google visibility and ChatGPT answers in separate loops

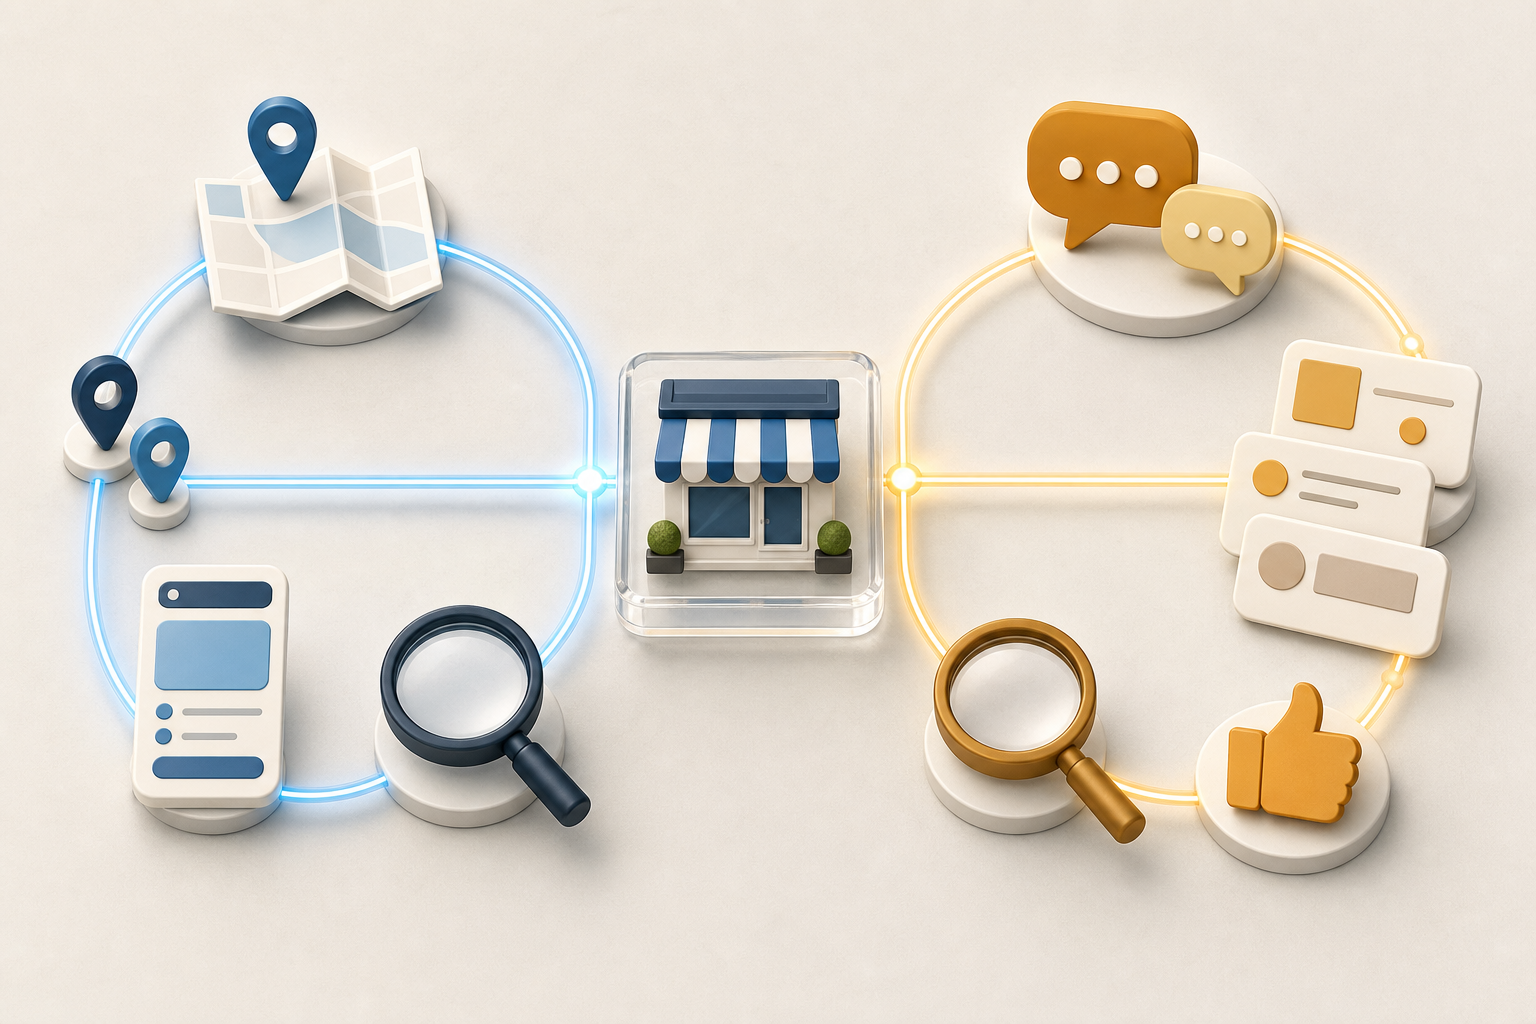
    Two separate circular icon loops for map search and conversational recommendations connect to the same miniature storefront.

    Use a geo-grid to diagnose Google

    Run the same commercially meaningful query from fixed points around the location. Record where the business appears, where visibility fades and which competitors replace it. Mark city borders and meaningful neighborhood changes on the grid so that a geographic pattern does not get misread as a page problem.

    Then compare the profile variables that can explain the pattern: recent review activity, primary and secondary categories, selected services, business name and landing-page alignment. If visibility is weak even close to the location, begin with those controllable signals. If it is strong nearby and falls away predictably, revise the target area or query expectations before considering another location. A new location should exist because demand and operations justify it, not merely to color more grid points.

    Use a prompt set to diagnose ChatGPT

    Build prompts from real customer decisions rather than from your brand name. Include requests for a provider offering a specific service near a named place, requests with a meaningful constraint and broader nearby requests that depend on the user’s location.

    • Keep the wording fixed when comparing results.
    • When location sharing is available, run the same local request with location shared and not shared.
    • Record whether the business appears, what reason is given, which business facts are used and which links or citations are shown, if any.
    • Flag incorrect names, services, locations and hours separately from a complete omission.
    • Retest under the same conditions after a meaningful profile, page or data correction.

    A single conversational response is an observation, not a stable ranking report. Look for repeated patterns across the intents that matter. If the system describes the business incorrectly, inspect your visible location page, profile and structured data for conflicts. If the facts are correct but the business is not mentioned, improve the page’s explanation of who the location serves and which needs it can meet; do not randomly rewrite the profile in response to one answer.

    What you observeLikely constraint to investigateBest next move
    Google visibility is weak across the grid, including near the locationProfile relevance, review activity or landing-page alignmentRun the complete profile audit and correct the clearest competitor gap
    Google is strong nearby but fades near borders or outer neighborhoodsProximity and city geographyTarget areas where the location can compete and reconsider unrealistic radius expectations
    Google is strong but ChatGPT rarely mentions the businessConversational fit or unclear first-party informationTest actual customer prompts and make services, location and constraints explicit on the page
    ChatGPT mentions the business with incorrect factsAmbiguous, incomplete or conflicting location dataCorrect the visible page, profile and JSON-LD, then retest the same prompt
    ChatGPT mentions the business but Google is weakGoogle-specific profile or proximity signalsUse the geo-grid to separate an optimization gap from a geographic ceiling

    Begin with a baseline, then choose the mismatch supported by the clearest evidence. If the Google grid collapses at a city boundary, stop expecting a title edit to erase geography. If ChatGPT gets a service wrong, correct the underlying fact before chasing mentions. If the profile is weak close to the location, audit categories, reviews and the linked page first. Fix the smallest defensible problem, rerun the same test and keep the two measurement loops separate.

    References


  • ChatGPT Ads Are Expanding: A Practical Marketer Plan

    ChatGPT Ads Are Expanding: A Practical Marketer Plan

    If you control a paid media budget, you now have a decision to make: prepare for ChatGPT advertising, run an early test, or wait until the channel becomes easier to evaluate. The wrong move is treating novelty as proof and shifting budget before you know what success should look like.

    The better move is to build a controlled entry plan. ChatGPT’s ad pilot has produced a meaningful commercial signal, but its limited rollout leaves major questions about inventory, buying controls, measurement and performance. You can prepare for those unknowns without betting your acquisition plan on them.

    The expansion is real, but the early numbers need context

    ChatGPT ads are appearing often enough to become a serious planning issue. The stronger signal comes from the pilot’s economics: it reached more than $100 million in annualized ad revenue within six weeks.

    Annualized revenue is a run rate, not $100 million already collected during the pilot. It projects a short period’s pace across a year. That distinction matters when you assess the maturity of the business. The figure demonstrates advertiser demand and monetization potential; it does not demonstrate return on ad spend for your company.

    The pilot was also deliberately narrow. Ads were shown daily to fewer than 20% of eligible US users on the Free and Go tiers, even though about 85% of those users qualified to receive them. More than 600 advertisers had participated. Those figures imply room for substantially more delivery if OpenAI increases exposure, but they do not tell you how much inventory will become available, how it will be priced or whether it will match your audience.

    OpenAI has said that users classified fewer than 7% of ads as low relevance. Treat that as an encouraging relevance signal, not a campaign-performance benchmark. A user can consider an ad relevant without clicking it, converting or becoming a profitable customer. Your own business outcomes still have to settle the question.

    Key takeaways

    • ChatGPT advertising has moved beyond a purely speculative format, but early revenue does not prove advertiser profitability.
    • Limited exposure creates expansion potential while making historical benchmarks less dependable.
    • Self-serve access lowers the operational barrier to entry; it does not remove the need for a test budget and predefined decision rules.
    • Measure ChatGPT campaigns with site and CRM outcomes, not relevance claims or platform activity alone.
    • Keep paid distribution separate from organic ChatGPT visibility. Buying an ad should not be treated as a way to earn citations or recommendations.

    Write your go-or-no-go plan before self-serve access

    A marketer considers three paths leading to a small ad test, a preparation workspace, and a closed access gate.

    The rollout plan identified an April opening for self-serve advertiser access. It also named Canada, Australia and New Zealand as intended expansion markets. Self-serve access changes who can participate: marketers no longer need to be among a relatively small group working through a managed pilot.

    It does not tell you that a particular geography, format or targeting control is available to your account. Treat every planned market as unavailable until you can confirm access inside the buying interface. Do not put forecasted ChatGPT conversions into a committed revenue plan merely because geographic expansion has been announced.

    Before anyone creates a campaign, write a one-page test brief covering the following decisions:

    1. Choose one commercial job. Decide whether the test is meant to generate qualified visits, leads, purchases, trial starts or another observable outcome. “Learn about ChatGPT ads” is an internal objective, not a business result.
    2. Define the user situation. Describe the problem, constraint or decision that should make your offer relevant. A broad demographic label is not enough. The creative team needs to know what the person is trying to accomplish.
    3. Set a loss ceiling. Fund the pilot from money the business can afford to use for channel learning. Do not remove budget from a revenue-critical campaign unless you have explicitly accepted the resulting demand risk.
    4. Name the economic threshold. Use your own margins, close rates, customer value and sales capacity to determine an acceptable acquisition outcome. An industry average cannot decide whether a customer is profitable for you.
    5. Select one conversion path. Send the visitor to a page built for the promise in the ad. If that page offers several unrelated actions, you will struggle to tell whether the message worked.
    6. Define stop and scale rules. State which evidence permits more spending, which result calls for a creative or landing-page change, and which result ends the test. Make those decisions before campaign data creates pressure to rationalize weak performance.
    7. Assign an owner. One person should reconcile platform activity, web analytics, CRM progression and actual revenue. Without that ownership, each system can appear successful while the commercial result remains unclear.

    You should also inspect the product before committing spend. Confirm the available geographic controls, audience or contextual controls, ad formats, placement disclosures, reporting fields, conversion measurement, exclusions, billing rules and brand-safety options. If a control you require does not exist, narrow the test or wait. Do not assume a mature search or social advertising feature has been carried into a new platform.

    More than 600 advertisers participating in the pilot validates interest in the channel. It does not mean you have already missed the inexpensive phase, nor does early entry guarantee lower acquisition costs. The defensible early-mover advantage is learning: discovering which problems, claims and landing experiences produce qualified behavior before the channel becomes a standard line in every media plan.

    Build creative for a conversation, not a copied search ad

    A search query often compresses intent into a few words. A ChatGPT prompt can contain a goal, constraints, context and follow-up questions. That does not mean an advertiser will necessarily receive the full prompt or be able to target every detail. It means your message has to make sense beside a more developed problem than a bare keyword might convey.

    Do not imitate the assistant’s voice or make paid placement look like an independent recommendation. The ad should be recognizably commercial and useful on its own terms. Its job is to connect a specific situation to a supportable proposition.

    Use a four-part message pattern

    1. Situation: Identify the problem or decision that makes the offer relevant.
    2. Claim: Make one concrete promise you can substantiate. Avoid stacking several product benefits into a single ad.
    3. Reason to believe: Point to the mechanism, evidence or distinguishing fact behind the claim.
    4. Next action: Ask for a step proportionate to the user’s intent, such as reviewing a method, seeing an example, checking eligibility or starting a purchase.

    A practical drafting template is: “For [specific situation], [offer] helps you [supportable outcome] through [clear mechanism]. [Evidence]. [next action].” The brackets force the writer to supply meaning. If the team cannot fill them without vague language, the proposition is not ready for paid distribution.

    Terms such as “innovative,” “powerful” and “next generation” consume space without reducing uncertainty for the reader. Replace them with a visible capability, a documented constraint or a concrete reason to continue. A conversational environment raises the standard for clarity because the surrounding answer may already be specific.

    Make the landing page finish the same thought

    The click is a handoff, not a completed outcome. The landing page should immediately confirm that the visitor has reached the promised destination. If the ad addresses one use case but the page opens with a generic company slogan, the visitor has to reconstruct the connection.

    • Repeat the problem and core proposition near the beginning of the page.
    • Place evidence beside the claim it supports rather than collecting unsupported superlatives in a separate section.
    • Explain important qualifications before the conversion action. Hidden limits may increase form starts while damaging lead quality and trust.
    • Use one primary call to action that matches the commitment requested in the ad.
    • Ensure the page works without the visitor having to understand the preceding ChatGPT conversation.
    • Use accurate structured data only where it describes visible page content. JSON-LD can clarify entities and relationships; it cannot repair a weak offer or guarantee visibility in an AI-generated answer.

    Create a dedicated page when the campaign promise differs materially from your existing page. Do not create a thin duplicate merely to insert the words “ChatGPT” or “AI.” Message match comes from answering the same need, not repeating a channel name.

    Measure paid results without confusing them with AI visibility

    A campaign card passes through two separate measurement lanes, one with budget and conversion objects and another with speech bubbles and connected knowledge symbols.

    A new channel invites two measurement mistakes. The first is accepting platform activity as proof of business value. The second is expecting it to behave like mature search advertising before you understand the context in which its ads are delivered.

    Start with site-side instrumentation you control. A consistent campaign taxonomy might use utm_source=chatgpt, utm_medium=paid_ai and a campaign name tied to the user situation or offer. The exact labels are yours to choose; consistency is what lets analysts separate paid ChatGPT visits from referrals, organic discovery and other paid channels.

    Follow the visitor through an outcome ladder:

    1. Arrival: Did the tagged session reach the intended page?
    2. Engagement: Did the visitor examine the promised material or begin the intended task?
    3. Conversion: Did the visitor complete the primary action?
    4. Qualification: Did the lead, trial or order fit the business’s acceptance criteria?
    5. Value: Did it create revenue, retained usage or another outcome connected to the original commercial goal?

    This sequence prevents a high click count from concealing low-quality demand. It also shows where to intervene. Weak arrival-to-engagement performance points toward message match or page experience. Strong engagement with weak conversion may indicate offer friction. Conversions that fail qualification point toward the audience definition, claim or form design. These are diagnostic interpretations, not automatic verdicts, so check the actual sessions and CRM records before changing the campaign.

    Do not judge the channel on cost per click alone. A cheaper visit is not useful if it produces fewer qualified outcomes, and an expensive visit can still work if it creates enough customer value. Compare channels at the deepest reliable stage available to your business. Where sales cycles prevent an immediate revenue view, label the interim metric clearly rather than presenting it as realized return.

    The claimed sub-7% low-relevance rate belongs near the top of this measurement ladder. It says something about user perception of ad fit. It does not replace your conversion rate, qualified acquisition cost or revenue evidence.

    Keep paid, owned and earned AI discovery distinct

    • Paid distribution buys eligible ad exposure under the platform’s available controls.
    • Owned content gives people and machines a clear, accurate destination for your claims, products and expertise.
    • Earned visibility includes citations, mentions and recommendations that are not purchased as ad placements.

    Do not assume that buying ChatGPT ads improves whether the assistant cites or recommends your brand in an unpaid answer. Treat any such relationship as unproven unless OpenAI documents it. Keep separate dashboards for paid campaign outcomes and organic AI visibility so an increase in one is not casually credited to the other.

    The work can still reinforce itself. Campaign planning forces you to name user problems precisely. Winning landing pages reveal which explanations and evidence help people act. Those lessons can improve product pages, comparison content, FAQs and structured data. If the ad platform exposes contextual or query-level insights, use them within its privacy and reporting limits; if it does not, rely on the post-click evidence you can observe.

    ChatGPT’s expansion into self-serve buying and additional markets gives you a reason to prepare, not a reason to abandon channel discipline. Write the one-page pilot brief now, verify the controls when your account receives access, and launch only when you can trace spend to a business outcome. That puts you in position to learn early without making the rest of your acquisition plan depend on an unproven channel.

    References


  • ChatGPT Shopping Referrals: A Practical Visibility Playbook

    ChatGPT Shopping Referrals: A Practical Visibility Playbook

    If ChatGPT has begun sending shoppers to your store, your immediate question is probably how to earn more of those referrals. The answer starts with measuring the opportunity correctly. A single recommendation, position, or shopping carousel cannot tell you whether your products are consistently visible.

    The shopping carousel can reshuffle from one request to the next. Treat each response as one observation from a changing recommendation system, then look for patterns across repeated prompts before you change your content, product data, or acquisition strategy.

    Stop treating the shopping carousel like a fixed ranking

    Traditional rank tracking encourages a simple question: which domain occupies the first position? ChatGPT shopping referrals require several questions. A retailer can appear frequently without leading the carousel, while another can win the first buy link in a narrower set of responses.

    That distinction is visible across an analysis of 22.5 million shopping offers. Walmart often led the rank-one buy links, while Target achieved stronger overall presence. Neither metric cancels the other. They describe different forms of visibility.

    • Appearance rate: How often your retailer, brand, or product appears across eligible prompt runs.
    • First-position rate: How often it appears first when it is included.
    • Buy-link rate: How often the response provides a purchasing path to your domain.
    • Product coverage: How many distinct products or product families earn visibility within a prompt cluster.
    • Volatility: How much the included retailers, products, and positions change when you repeat the same prompt.

    This prevents a common reporting error. If you track only first position, you can miss broad consideration. If you track only appearances, you can mistake occasional inclusion for commercial preference. Keep the metrics separate, and interpret them together.

    Build a repeatable ChatGPT referral visibility baseline

    Several tablets display the same generic products in different orders within a neatly organized testing workspace.

    Your audit should begin with the decisions customers are trying to make, not a list of keywords copied from a conventional rank tracker. Shopping prompts often contain a product need plus constraints such as intended use, features, budget, compatibility, delivery, or retailer preference. Those qualifiers can materially change which options make sense.

    1. Create prompt clusters around buyer jobs. Separate broad product discovery, constraint-heavy discovery, comparisons, replacement purchases, and branded requests. Include only prompt types that reflect a real path to your products.
    2. Write prompts as customers would ask them. Preserve natural context and decision criteria. A prompt designed merely to force your brand into the answer does not measure discovery.
    3. Repeat each prompt without rewriting it. The carousel can change between requests, so one run cannot establish a stable position. Repetition lets you distinguish a persistent pattern from a transient result.
    4. Record the entire response set. Capture the prompt, run, retailer, brand, product, displayed order, buy-link destination, and landing page. Do not save only the result that mentions you.
    5. Aggregate results by prompt cluster. Calculate appearance, first-position, and buy-link rates separately for each type of shopping decision.

    Keep the test conditions as consistent as practical. If an account, location, device, or other environment detail changes, record that fact rather than silently combining the runs. You may not know why two responses differ, but you can avoid confusing a test change with a visibility change.

    Your baseline is complete when it can answer more than whether you appeared. It should show where you appear repeatedly, where you lead, which products receive the exposure, where the purchase links go, and which prompt clusters produce unstable results.

    Diagnose the visibility pattern before changing your site

    Different metric combinations point to different investigations. They do not prove why ChatGPT selected an option; the exact recommendation logic is not exposed by a carousel response. Use the patterns as diagnostic hypotheses, then verify the underlying product and landing-page evidence.

    Observed patternWorking interpretationWhat to inspect next
    High appearance and high first-position ratesYour offer is broadly visible and often prioritized within the tested cluster.Protect accurate product information, examine where buy links land, and determine whether the visibility produces qualified sessions and sales.
    High appearance but low first-position rateYour products are regularly considered but seldom presented first.Compare the decision-critical details exposed on your pages: intended use, differentiators, price conditions, availability, variants, fulfilment, and returns.
    Low appearance but high first-position rate when presentYour offer may fit a narrow set of needs particularly well.Identify the prompt constraints associated with those wins. Decide whether that niche is commercially important before trying to broaden it.
    Frequent mentions but few buy linksYou have informational recognition without a consistent commerce handoff.Check whether the correct product page is indexable, current, clearly purchasable, and preferable to an informational or category URL.
    Large changes between identical prompt runsThe recommendation set is unstable for that decision.Rely on aggregate rates, inspect which competitors recur, and avoid declaring a winner from a screenshot.

    Prompt-level segmentation matters here. A strong aggregate can conceal a complete absence from an important use case, while one excellent response can make a weak aggregate look more promising than it is. Read the total first, then inspect the clusters that carry the most buying intent for your business.

    Reduce uncertainty in the product decision

    A product moves from obscured information to a clearly presented choice with images, material samples, measurements, delivery, returns, and review symbols.

    You cannot directly control the composition or order of a ChatGPT shopping carousel. You can control whether your product information gives a recommendation system clear, consistent evidence to work with. The goal is not to repeat marketing language more often. It is to remove ambiguity from the buying decision.

    Make each purchasable page self-sufficient

    A product page should make sense without requiring a system or shopper to reconstruct essential facts from several other URLs. Audit each commercially important page for the following:

    • A precise product name, category, model, and variant.
    • A plain-language explanation of who the product is for and which use cases it supports.
    • Decision-critical attributes written as text, not hidden only inside images or promotional graphics.
    • Clear differences among sizes, configurations, bundles, or generations.
    • Accurate purchase conditions, including price, currency, availability, fulfilment, and return information where applicable.
    • An unambiguous purchase action and a stable destination for the specific product.
    • Agreement among visible page copy, structured product data, and any commerce feed you maintain.

    Do not treat structured data as a guarantee of inclusion. Markup cannot repair a vague offer, a missing variant distinction, or contradictory on-page information. Its useful role is to express facts consistently. The visible page still needs to help a person decide whether the item fits.

    Build supporting pages around genuine decisions

    A category page should explain the criteria that separate its products. A comparison page should state material differences rather than giving every option the same generic praise. Compatibility, sizing, delivery, warranty, and return pages should be easy to reach when those details can change the purchase decision.

    Avoid creating a thin page for every possible wording of a shopping prompt. Consolidate overlapping questions into authoritative pages that cover the full decision. You want one dependable explanation of the product and its constraints, not a collection of near-duplicates that disagree after the next catalog update.

    Connect visibility, handoff, and outcome

    ChatGPT visibility is not the same as a referral, and a referral is not the same as a sale. Keep those stages separate in your reporting:

    • Visibility: Your appearance, first-position, product-coverage, and volatility measurements from repeated prompts.
    • Handoff: Whether a buy link is present, which domain receives it, and which landing page it uses.
    • Outcome: The sessions, product views, cart actions, leads, or purchases your analytics can actually observe.

    Do not force a precise attribution claim when the stages cannot be joined. Instead, make one meaningful change within a defined product or prompt cluster, keep your audit method stable, and compare the aggregate pattern before and after the change. That gives you a defensible learning loop without pretending that every carousel movement came from your edit.

    Key takeaways

    • There is no dependable single ChatGPT shopping rank when the carousel can reshuffle between requests.
    • Measure appearance, first position, buy links, product coverage, and volatility as separate signals.
    • Repeat unchanged prompts and aggregate the results before drawing a conclusion.
    • Use metric combinations to decide what to inspect; do not present them as proof of how ChatGPT selected a result.
    • Make product pages, supporting content, structured data, and commerce feeds consistent enough to support an unambiguous decision.
    • Report visibility, referral handoff, and business outcomes as distinct stages.

    Start with one commercially important prompt cluster and establish its baseline before editing anything. Once you know whether the problem is inconsistent inclusion, weak prioritization, a missing buy link, or a poor landing destination, you can make a focused change and learn from the next set of runs.

    References