Tag: Attribution Models

  • ChatGPT Ad Rollout: A Practical Readiness Plan for Marketers

    ChatGPT Ad Rollout: A Practical Readiness Plan for Marketers

    If you are deciding whether to reserve budget for ChatGPT ads, do not start with a media plan. Start by separating the small amount that is known from the much larger set of assumptions now forming around the channel.

    The rollout is real, early, and deliberately iterative. Your advantage will not come from treating every unknown as an opportunity. It will come from being ready to evaluate access, economics, measurement, privacy, and organic AI visibility without confusing one with another.

    Start with the rollout’s actual boundary
    A small group of users stands inside an illuminated test zone around a generic chat interface, while a larger digital environment remains outside the boundary.

    OpenAI has begun implementing ads for U.S. users on ChatGPT’s free and Go tiers. That is a meaningful product change, but it is not the same as a global, all-tier advertising launch. Keep that distinction intact in forecasts, presentations, and client conversations.

    OpenAI has described the rollout as iterative, with user trust and privacy central to its approach. Treat that as the company’s stated direction, not proof that every eventual format, targeting method, or data practice will meet your requirements. Those details must be evaluated when actual campaign terms become available.

    The most important strategic distinction is between three different assets:

    • Paid exposure: inventory purchased under campaign terms, with delivery and billing controlled by the advertising system.
    • Earned AI visibility: mentions, citations, recommendations, or inclusion in an answer that you did not buy.
    • Owned conversion experience: the product page, landing page, form, checkout, or other destination where the user can act.

    ChatGPT advertising does not, by itself, establish that buying an ad changes what the model says in its answer. It also does not establish that strong organic visibility will produce paid access or preferential pricing. Until campaign documentation demonstrates an interaction, manage paid ChatGPT inventory and organic AI visibility as separate systems.

    That separation should appear in your language as well as your reporting. Use “ChatGPT ads” for paid placements. Use “ChatGPT visibility” for unpaid appearances in answers. Use “ChatGPT referral traffic” only for visits you can identify. A single label such as “AI performance” hides the very differences you will need to make budget decisions.

    Treat the early economics as an entry gate, not a benchmark

    Early reports put pricing at up to $60 CPM, with commitments beginning at about $200,000. CPM means cost per thousand impressions. These figures tell you that early participation may require a substantial test budget; they do not give you a universal rate card, expected return, available audience, or final buying model.

    If a $200,000 buy were billed entirely at exactly $60 CPM, the simple calculation would produce roughly 3.33 million billed impressions. That is a scenario, not a forecast. “Up to” and “about” are material qualifiers, and impressions alone do not reveal unique reach, frequency, attention, qualified visits, conversions, or incrementality.

    Do not turn those two reported numbers into a business case. Ask for the actual proposal and resolve what the commitment covers: media only or a larger package, guaranteed or estimated delivery, targeting controls, placement definitions, reporting access, cancellation rights, invalid-traffic treatment, and remedies for underdelivery. If those terms are unavailable, waiting is safer than committing money on the strength of a headline CPM.

    Access also appears selective. Shopify is enabling merchants to participate through Shop Campaigns, while Target and Adobe are among the early testers. If you use Shopify, verify access in your own account or through your account representative. Do not assume that being a Shopify merchant automatically makes you eligible, or that early commerce access describes the eventual program for every advertiser.

    Decision questionA pilot may be justified whenWait when
    AccessYour eligibility, inventory, geography, tier, and buying route are confirmed in writing.Your plan depends on press coverage or an assumed self-service launch.
    Learning valueThe test will answer a decision that affects your future media, search, or commerce strategy.The main rationale is simply to be early.
    MeasurementYou can isolate the destination, traffic, conversion event, and campaign cost.Paid visits will be blended with organic AI, direct, or other referral traffic.
    EconomicsThe full commitment fits an experimental budget even if the test does not produce an efficient return.The spend must deliver immediate efficiency to be financially acceptable.
    GovernancePrivacy, data use, ad disclosure, brand suitability, and contract terms have named reviewers.Those questions will be handled only after the campaign starts.

    An early pilot is most defensible when the learning itself has value and the possible loss is affordable. It is much harder to justify when the team needs a mature channel’s predictability from an iterative product.

    Build the measurement contract before the media contract
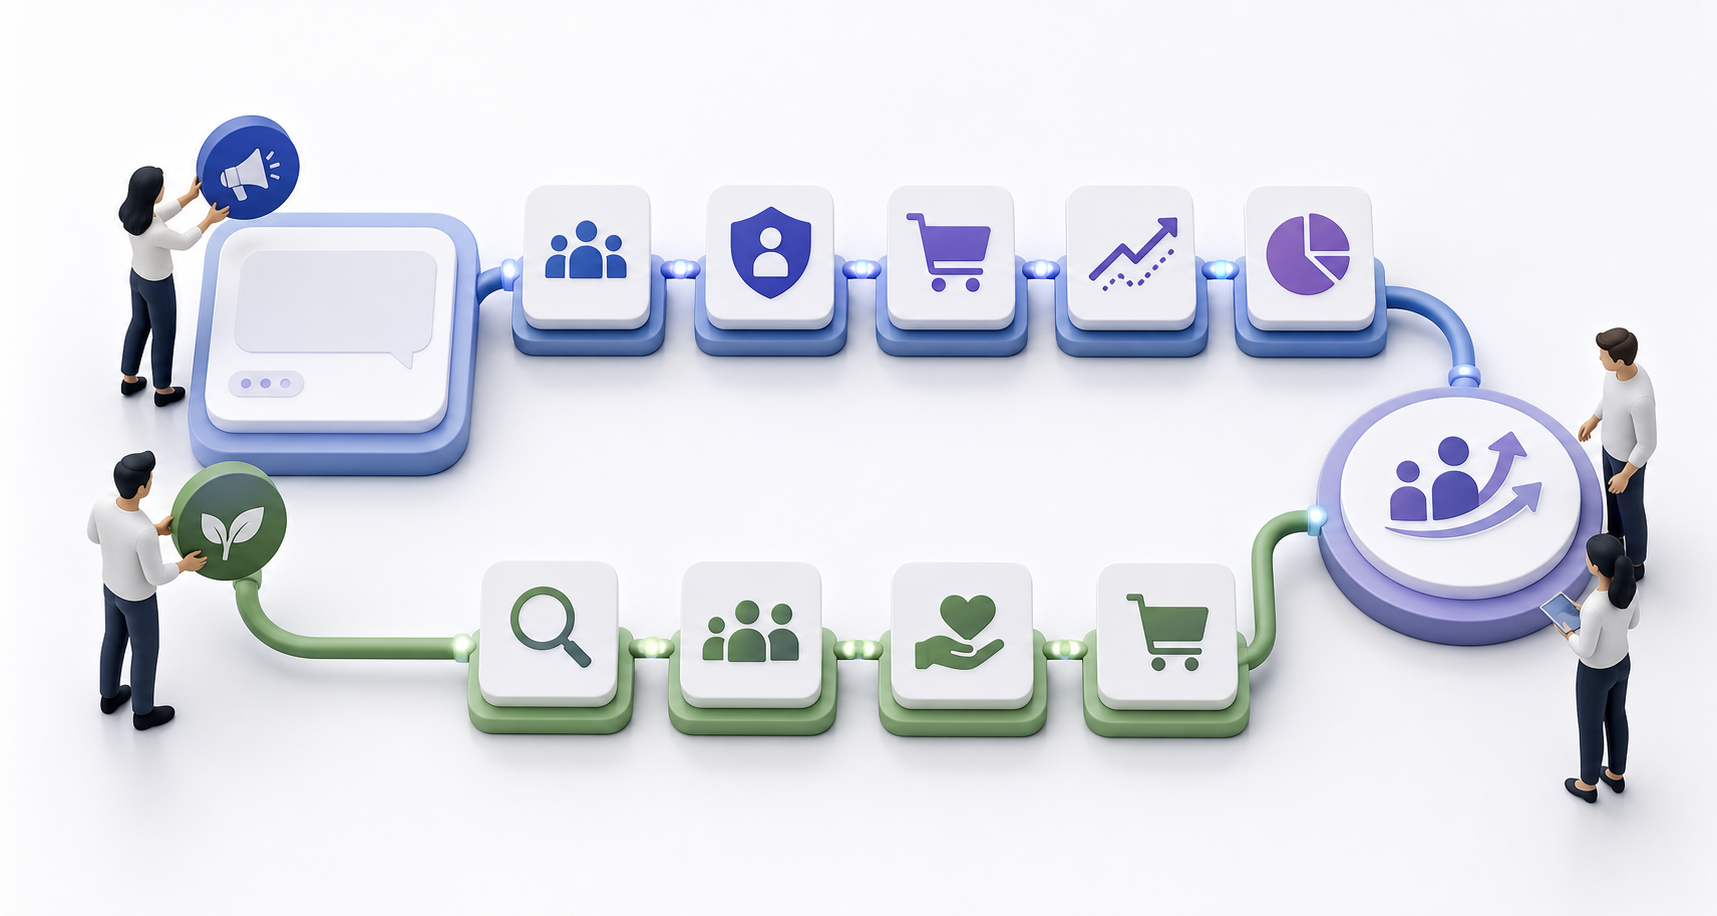
    Analysts connect a blank conversational ad panel to privacy, conversion, and reporting checkpoints while a separate organic discovery path leads toward the same outcome.

    A new advertising surface creates a familiar attribution problem: delivery is easy to count, while business impact is easy to overstate. Prevent that by agreeing internally on what evidence will count before anyone sees a favorable dashboard.

    1. Write one falsifiable hypothesis. Use the form: “Exposure through this placement will increase a named business event for a defined audience compared with our documented baseline.” Avoid goals such as awareness or learning unless you also define how they will be observed.
    2. Name the primary outcome. Choose the event closest to business value that the campaign can credibly influence, such as a qualified lead, completed purchase, activated account, or another verified conversion. Impressions are a delivery measure, not the final outcome.
    3. Isolate the destination. Use a dedicated landing path, campaign parameters, and separate campaign naming wherever the platform permits. Preserve the original referrer and campaign data through redirects, analytics, customer relationship management, and checkout systems.
    4. Capture the pre-campaign baseline. Record the same business metric before the pilot. Also preserve a controlled set of relevant ChatGPT prompts so you can see whether unpaid visibility changes independently of the advertising campaign.
    5. Set guardrails. Define the maximum acceptable acquisition cost, minimum data quality, prohibited adjacency, privacy requirements, and landing-page conditions before launch. A result that violates a guardrail is not a successful test because its headline metric looks good.
    6. Write a stop rule. Specify who can pause spend and what triggers that decision, such as unusable reporting, incorrect destinations, brand-suitability problems, privacy concerns, or spending that cannot be reconciled with delivery.

    Your vendor questions should be equally concrete:

    • What exactly counts as an impression, and how is viewability or equivalent exposure defined?
    • Where can an ad appear relative to the user’s prompt and the generated answer?
    • How is the paid placement disclosed to the user?
    • Which geography, account tier, device, language, and context controls are available?
    • What reporting can be exported, and at what level of aggregation?
    • Which conversion methods are supported, and what attribution window or model is used?
    • What user or conversation data is exposed to the advertiser, retained, or used for targeting?
    • How are invalid traffic, underdelivery, billing disputes, and makegoods handled?
    • Can creative, destination, or campaign settings be changed during the test without resetting measurement?

    A platform may not answer every question during an early rollout. That is useful information. Reduce the test’s scope, change the success criteria, or wait; do not silently fill reporting gaps with assumptions.

    Protect organic AI visibility from paid-channel attribution

    Marketers working on AEO, GEO, structured data, and AI search have a second job: keep the ad experiment from contaminating the organic program. A paid impression can create awareness and a later search. An organic answer can send a referral visit. A user can also see both. Your reporting should acknowledge those paths without assigning causality you cannot demonstrate.

    Maintain two scorecards. The paid scorecard can contain spend, billed impressions, clicks or visits when available, conversion events, acquisition cost, and evidence of incremental lift. The organic scorecard can track whether the brand appears in controlled prompts, what claims are made, which destinations or citations appear, whether the answer is accurate, and whether identifiable referral traffic follows.

    Use controlled, synthetic prompts for monitoring rather than collecting private customer conversations. For every observation, record the date, market, ChatGPT tier, exact prompt, whether an ad was present, how the placement was labeled, the advertiser and destination, and the separate contents of the unpaid answer. The tier and market matter because the known rollout is scoped to U.S. free and Go users.

    Before a campaign begins, save a baseline from the same controlled prompt set. During the campaign, preserve creative and landing-page versions alongside the observation log. Afterward, compare paid delivery and business outcomes with the organic record. Do not claim that advertising improved model mentions, citations, or recommendations unless a designed experiment supports that causal conclusion.

    Your organic work should continue on its own merits: publish accurate, directly answerable information; make brand and product entities unambiguous; keep commercial details current; show ownership and editorial responsibility; and use structured data that faithfully represents visible page content. Schema can help machines interpret a page, but it is not an ad-access switch and should not be altered merely to imitate an unconfirmed advertising requirement.

    Commerce teams should audit the owned destination before pursuing inventory. Verify that catalog information, price, availability, policy language, product claims, and checkout behavior agree. An ad can accelerate discovery, but it also accelerates the consequences of inconsistent merchant data.

    Key takeaways

    • The confirmed rollout is limited in scope: ads are being implemented for U.S. users on ChatGPT’s free and Go tiers.
    • OpenAI is treating the program as iterative, so early formats, access rules, and economics should not be mistaken for a finished market.
    • Paid ChatGPT exposure and organic ChatGPT visibility are different systems. Budget, track, and describe them separately.
    • Reported pricing of up to $60 CPM and commitments beginning around $200,000 are qualification signals, not performance benchmarks.
    • Shopify’s Shop Campaigns route and the participation of early testers show that access is developing, not that every advertiser has an open buying path.
    • The right preparation is a measurement and governance plan that can survive incomplete platform data.

    Your next move is a one-page readiness brief. Give it an eligibility owner, campaign hypothesis, audience, destination, baseline, primary business event, guardrails, stop rule, privacy reviewer, and list of unanswered vendor questions. If your team cannot complete those fields without guessing, do not reserve budget yet. If it can, you will be able to evaluate an invitation quickly without mistaking paid reach for earned AI authority.
    References

  • Google Ads Attribution and PMax Creative Automation Guide

    Google Ads Attribution and PMax Creative Automation Guide

    You have handed Google Ads two important jobs: decide which opportunities deserve your budget and assemble creative that can run across its inventory. The first job depends on when conversions reach the bidding system. The second depends on which images the system is allowed to reuse.

    Those controls are easy to manage separately and dangerous to ignore together. If app installs appear on a reporting date that does not match your Mobile Measurement Partner, you may make decisions from a distorted timeline. If an unsuitable landing-page image enters Performance Max, the campaign can distribute a message you never intended. You need one operating model for both the conversion signal and the creative supply.

    Google Ads automation runs on two feedback loops

    The measurement loop starts with an ad interaction, continues through an app install, and ends when the conversion enters campaign reporting and informs bidding. Google now places app conversion credit on the install date rather than the date of the ad interaction. That brings the reporting timeline closer to the install-date view used by Mobile Measurement Partners such as AppsFlyer and Adjust.

    The creative loop starts on your website. When you opt into the relevant automation, Google can extract images from landing pages, turn them into PMax creative, and show you a preview before launch. Those visuals can then appear in ads across Search, Display, YouTube, and Discover.

    Each loop can fail independently. Accurate conversion timing will not rescue a misleading image. Strong creative will not fix delayed or inconsistently interpreted conversion data. A well-governed account therefore asks two different questions:

    Control areaQuestion to answerCommon misreading
    Conversion signalWhich date receives credit, and are Google Ads and the MMP being compared on the same basis?A reporting-date shift is treated as a sudden change in customer demand.
    Creative supplyWhich landing-page images may become standalone ads, and would you approve each one?A page image is assumed to be safe because it was originally designed for the website.

    The practical principle is simple: automation magnifies the quality of the inputs you give it. Your job is not to approve every automated decision manually. It is to make sure the system learns from the right event timeline and draws from a deliberate asset pool.

    Control the move to install-date attribution

    Abstract mobile conversion signals being reconciled between a later reporting timeline and earlier smartphone install points.

    Install-date attribution changes where a conversion appears on the reporting timeline. It does not, by itself, prove that more or fewer people installed your app. This distinction matters whenever you compare periods that use different attribution logic.

    Under the earlier approach, conversion credit was associated with the ad-interaction date. The default 30-day attribution window could leave important feedback separated from the day of the eventual install. Moving the credit to the install date gives Smart Bidding a fresher signal and may help its optimization cycle move faster. That is a potential operational benefit, not a guarantee that campaign performance will immediately improve.

    Do not confuse the conversion window with the credited date. The window determines which delayed outcomes can qualify after an interaction. The credited date determines where a qualifying outcome appears in reporting. Changing the second does not mean the customer journey itself became shorter.

    Audit the reporting boundary before changing bids

    1. Record the attribution boundary. Note when the account begins presenting app conversions by install date. Treat that point as a break in the reporting series rather than silently combining unlike periods.
    2. Confirm the event being compared. Match the same app, conversion event, date range, time zone, and inclusion rules in Google Ads and your MMP. Similar dashboard labels do not guarantee identical filters.
    3. Compare install cohorts, not just headline totals. If one system groups an install by interaction date and another groups it by install date, their daily charts can disagree even when they describe many of the same outcomes.
    4. Inspect timing before diagnosing demand. If a day looks unusually strong or weak around the change, check whether credit moved between dates before concluding that traffic quality changed.
    5. Keep other major changes separate when practical. Simultaneous changes to budgets, bidding goals, conversion definitions, and attribution logic make it difficult to identify what caused the next movement.
    6. Document any remaining discrepancy. Install-date alignment should reduce one important source of disagreement with AppsFlyer or Adjust, but it does not establish that every dashboard total must match. Keep investigating differences in event definitions and filters rather than forcing a false reconciliation.

    Most advertisers should resist reacting to the first daily swing. Review the timing of credit first. Once you know that both systems are looking at the same install cohort, you can judge whether the campaign itself changed.

    This is also the right moment to inspect the account’s attribution-window setting instead of assuming the default is appropriate. Many advertisers leave the 30-day setting untouched. That may be acceptable, but it should be a documented choice connected to the way people actually move from an ad interaction to an install.

    Treat every PMax landing page as a creative library

    An unbranded landing page supplying image cards to ad placements through a gate that filters unsuitable creative assets.

    A landing page used to have one obvious job: persuade the visitor who arrived there. In an automated PMax workflow, it can also supply images for ads. That turns website publishing into part of campaign production.

    The distinction matters because an image can work well inside a page and fail when separated from it. A banner may rely on a nearby heading for context. A product photo may need a caption to distinguish the model. A promotional image may remain online after its offer has expired. A decorative visual may be harmless on the page but confusing as the main element of an ad.

    Before allowing Google to use landing-page images, audit each campaign destination as if it were an asset folder:

    • List every meaningful image. Include hero images, product shots, promotional banners, lifestyle photography, diagrams, badges, and supporting graphics. Do not review only the image you expect Google to choose.
    • Apply the standalone test. Look at the image without its heading, caption, navigation, or surrounding copy. If its meaning changes or disappears, revise it before treating it as ad inventory.
    • Check commercial accuracy. Remove or replace visuals with expired offers, outdated packaging, old product interfaces, unavailable variants, or unsupported claims.
    • Check placement resilience. Search, Display, YouTube, and Discover provide different surrounding contexts. Keep the central subject and intended message understandable without depending on the original page layout.
    • Protect the brand boundary. Decide whether the image is current, recognizable, and appropriate for paid distribution. Website publication should not automatically equal advertising approval.
    • Preview the automated output. Use the available preview before the creative goes live. Review what Google assembled, not merely the original image in your media library.
    • Resolve weak assets at the source. If a preview reveals an unsuitable image, update or remove it from the page, or keep the automation disabled until the page is ready. Do not knowingly feed an unsafe asset into the system and hope it receives little delivery.

    A page can be an effective destination and still be a poor creative library. It may contain useful navigation graphics, dense explanatory diagrams, or temporary banners that help an on-page visitor but should never represent the campaign. Judge page performance and asset eligibility as separate questions.

    Set an approval rule your team can repeat

    A simple three-state decision prevents subjective reviews from dragging on:

    • Approve: the image is current, accurate, on-brand, and understandable without nearby page copy.
    • Revise: the concept is usable, but the image depends on context, contains dated information, or does not represent the destination clearly enough.
    • Hold: the image could misstate an offer, show an unavailable product, create a compliance problem, or damage brand recognition if distributed as an ad.

    Assign an owner to that decision. The person who publishes a web page may not own paid-media approval, and the media buyer may not know when a product image becomes outdated. Without an explicit handoff, landing-page automation creates an invisible gap between the web and advertising teams.

    Use one workflow for measurement and creative control

    The cleanest operating routine reviews the conversion signal and the asset supply before asking PMax or Smart Bidding to do more. You can use the following sequence for a new campaign, an attribution change, or a landing-page refresh:

    1. Name the outcome. Identify the app conversion that represents success and should inform bidding. Avoid letting a convenient but secondary event stand in for the outcome you actually value.
    2. Define its timeline. Record whether Google Ads displays that conversion on the interaction date or install date, and write down the comparison basis used in your MMP.
    3. Mark measurement changes. Keep an account note or change log whenever attribution treatment, conversion definitions, or inclusion rules change. Future reviewers need to know why two periods may not be directly comparable.
    4. Map the destinations. List the landing pages connected to the PMax campaign. Include pages added through later campaign or site changes, not only the original destination.
    5. Classify the visual inventory. Give every relevant landing-page image an approve, revise, or hold status. Record who made the decision and what would require another review.
    6. Inspect the preview. Review the creative Google proposes before launch. Make sure the result still represents the product, offer, and destination accurately when removed from the page.
    7. Change one major layer at a time when possible. If attribution, bidding, budgets, landing pages, and asset automation all change together, the next performance movement will be hard to interpret.
    8. Review in two lanes. In the measurement lane, check counts, credited dates, and MMP alignment. In the creative lane, check which imagery was assembled and whether it remains suitable. Do not let a strong result in one lane conceal a control failure in the other.

    This workflow also gives you a faster diagnostic path. If Google Ads and the MMP disagree by day, inspect attribution timing before changing the campaign. If an unexpected image appears in a preview, inspect the destination page before rebuilding the whole asset group. If bidding behavior changes after the attribution update, determine whether the algorithm received a fresher event timeline before attributing the movement to new audience demand.

    Keep a compact control record for each campaign: the primary conversion, its credited date, the MMP comparison basis, the eligible landing pages, the status of their images, the latest preview review, and any unresolved exceptions. That record is more useful than a generic statement that automation is enabled because it tells the next person exactly what the system can learn and what it can show.

    Key takeaways

    • Install-date attribution changes the reporting timeline; it does not automatically mean install demand changed.
    • Compare Google Ads with AppsFlyer or Adjust using the same install cohort, event definition, date range, time zone, and filters.
    • Fresher conversion signals may help Smart Bidding learn more quickly, but cleaner attribution is not a performance guarantee.
    • An opted-in PMax landing page is also a potential creative library, so every meaningful image needs an advertising review.
    • Preview extracted images before launch and fix unsuitable assets at the landing-page level rather than accepting avoidable surprises.
    • Manage conversion timing and creative eligibility in one change log so you can separate measurement shifts from campaign shifts.

    Start with one app campaign and one PMax campaign. For the app campaign, document the credited conversion date and compare the same install cohort in your MMP. For PMax, open every active destination, classify its images, and inspect the automated preview. Resolve those inputs before you use a reporting swing to justify new budgets or bidding targets.

    As Google takes on more bidding and creative decisions, your durable advantage is a cleaner contract with the automation: this is the event that matters, this is when it receives credit, and these are the assets we are prepared to distribute.

    References

  • ChatGPT Ads: How to Unify SEO and PPC Around Prompts

    ChatGPT Ads: How to Unify SEO and PPC Around Prompts

    If your SEO team plans around rankings while your paid team plans around keyword auctions, ChatGPT ads create an immediate coordination problem. The same user can now encounter an AI-generated recommendation and a sponsored placement inside one conversational experience.

    You do not need to merge two departments or move an entire budget to respond. You need one shared map of prompt-level demand, a clear view of organic and paid coverage, and landing pages that continue the specific decision the user was making.

    Treat the prompt as the shared unit of demand

    Do not build your plan on the assumption that ads appear only after a long conversation. Early observations found sponsored placements appearing after a single intent-driven prompt. Those observations were limited to signed-in desktop users in the United States, so they show an emerging format rather than a universal rollout or permanent specification.

    That limited evidence is still enough to change how you organize demand. A user does not have to type a compact search term such as best CRM. A prompt can include the category, company type, size, required integration, budget sensitivity, and intended use in one request. Each qualifier can affect whether your offer is relevant.

    Start by separating a valuable prompt into its working parts. For a request such as What is the best CRM for a B2B SaaS company under 50 employees that integrates with HubSpot, the root topic is CRM. The fanout keywords are the contextual qualifiers embedded in the request: B2B SaaS, under 50 employees, and HubSpot integration. These details are not decorative long-tail language. They describe the conditions under which the recommendation must be useful.

    Build your prompt inventory with this sequence:

    1. Collect prompts associated with actual buying questions. Use customer language from search queries, sales calls, support tickets, on-site search, and any LLM visibility monitoring you already run.
    2. Group paraphrases by decision, not by exact wording. Best CRM for a small SaaS team and CRM for a SaaS startup with fewer than 50 people may belong to the same cluster if they require the same answer and destination page.
    3. Extract the root need and every meaningful qualifier. Typical qualifier types include audience, organization size, use case, compatibility requirement, constraint, and decision stage.
    4. Remove variants your business cannot serve. Prompt volume is irrelevant when the requested integration, geography, price level, or use case makes your offer a poor fit.
    5. Assign one plain-language intent label to the surviving cluster. That label becomes the shared reference for SEO analysis, paid targeting, creative, landing pages, and reporting.

    This prevents a common mistake: expanding a familiar keyword list with more words and calling it prompt intelligence. A real prompt map preserves the conditions that determine whether the answer is relevant.

    Create one coverage map for organic and sponsored visibility

    Two pairs of hands arrange teal and amber tokens together on a grid of blank translucent planning tiles.

    Once you have prompt clusters, audit both surfaces against the same list. Organic visibility means that the generated answer includes your brand, product, page, or supporting evidence in a relevant way. Sponsored coverage means that your campaign can address that context and, where observable, that a sponsored placement appears.

    Keep unknown separate from absent. If your organization does not have access to ChatGPT ad controls, or if delivery is limited by account, device, or location, you cannot conclude that a prompt has no commercial inventory. Record the scope of every observation instead.

    Organic answer visibilitySponsored coverageWorking interpretationNext move
    PresentMissing or unavailableYour brand has contextual relevance, but there is no observed paid reinforcement.Protect the content and evidence supporting that visibility. Test paid coverage only when access and economics justify it.
    AbsentPresentAn ad can capture attention, but the generated answer does not independently validate the brand.Keep the paid test accountable while improving the page content and evidence needed to address the prompt.
    PresentPresentOrganic and sponsored surfaces may participate in the same decision.Test incremental value. Do not assume that two appearances automatically produce a better business result.
    AbsentAbsent or unknownThe cluster is unserved, inaccessible, or not yet prioritized.Validate customer fit and the conversion path before creating content or assigning budget.

    The map should be owned jointly, even if execution remains specialized. SEO can diagnose answer visibility, citation patterns, entity clarity, and content gaps. Paid media can manage eligibility, targeting, creative, bids, spend, and campaign controls. Neither team should privately redefine the prompt cluster or send users to a different interpretation of the need.

    A practical shared workflow looks like this:

    1. Agree on the prompt cluster and the commercial question it represents.
    2. Run representative prompts and log whether the brand appears, why it is relevant, and which page or evidence supports the appearance.
    3. Audit paid coverage for the root need and its important qualifiers when campaign access permits it.
    4. Prioritize intersections: valuable prompts with an organic gap, a paid gap, or a poor destination-page match.
    5. Assign one owner for the cluster-level result, while keeping channel specialists responsible for their controls.

    Repeat representative prompt checks rather than treating one response as a permanent ranking. Log the exact prompt, date, account state, device, location, generated answer, cited pages, sponsored placement, and destination URL. This gives you an auditable observation instead of a screenshot detached from its conditions.

    Build landing pages for the complete decision context

    Visitors move from a glowing conversation bubble through connected landing-page spaces for comparison, demonstration, trust, calculation, and action.

    A context-rich ad followed by a generic landing page breaks the conversation. If the prompt asks about a CRM for a small B2B SaaS company with a specific integration, a destination that merely announces CRM software forces the visitor to reconstruct the answer alone.

    The landing page should resolve the questions that remain after the AI response. Use a brief with five required elements:

    • A heading that names the relevant use case and audience without pretending to support conditions the product cannot meet.
    • A qualification block that states who the offer is for, who it is not for, and which constraints matter.
    • Specific compatibility or integration details, including limitations that could change the buying decision.
    • Visible evidence for important claims, such as product documentation, concrete capabilities, policies, or appropriate customer proof.
    • A next action that fits the decision stage. A user comparing options may need detailed evaluation material before being asked to buy or book a call.

    Create one strong page for a meaningful decision context, not a thin page for every prompt paraphrase. The test is whether two prompts require materially different claims, evidence, or next steps. If the answer is no, they belong on the same page.

    SEO and paid teams should review that page together. Paid media can identify where the message loses continuity between prompt, ad, and destination. SEO can make sure the page explains the subject with enough clarity and substance to be understood outside the campaign. Clearer, context-matched pages support both conversion and accurate recognition by language models, which is why the destination is shared infrastructure rather than a channel-specific asset.

    If you use structured data, apply it only to facts that are visible and supported on the page. Markup can clarify existing information; it cannot repair vague copy, supply missing proof, buy an ad placement, or guarantee inclusion in a generated answer.

    Measure the journey without collapsing distinct signals

    Converged planning does not mean organic and paid performance become the same metric. Keep four layers separate, then connect them through the prompt-cluster identifier:

    • Answer visibility: whether the brand appears in a relevant generated response, what role it is given, and which evidence or pages are cited.
    • Sponsored delivery: whether a clearly labeled placement appears, which message is used, and where the click leads.
    • Landing-page behavior: whether visitors continue the task represented by the prompt, reach key information, and complete the intended action.
    • Business outcome: whether the cluster produces qualified leads, purchases, retained customers, or another result your organization already treats as valuable.

    Where campaign and URL controls allow it, carry the shared cluster label into campaign naming, destination parameters, analytics, and reporting. The label should describe the decision context rather than the channel. This lets you compare CRM for small SaaS teams across answer visibility, ad delivery, landing behavior, and outcomes without pretending that every prompt wording is a separate market.

    Do not use sponsored presence as a proxy for organic authority. In the documented format, ads appear beneath the response with a Sponsored label, and the paid placement remains separate from the generated answer. Buying exposure therefore does not fix an inaccurate answer, earn a citation, or make the underlying page more persuasive.

    Likewise, do not call every organic mention incremental value. If the brand already appears in the answer and an ad also appears, only a controlled comparison can tell you whether the sponsored placement added a worthwhile result. Use the strongest control the available platform and your traffic permit. If a controlled split is unavailable, label a time-bounded pilot as directional and avoid presenting a before-and-after change as proof of causation.

    Use the evidence to make a cluster-level decision:

    • If the ad attracts relevant visitors but the brand is absent from the answer, keep paid performance accountable while repairing the organic content and evidence gap.
    • If both surfaces are present but the ad adds no measurable value in a valid test, do not keep paying merely to maximize visual coverage.
    • If visitors arrive but cannot confirm the qualifier that triggered their interest, fix the destination before increasing spend.
    • If neither surface is present and the prompt does not represent a customer you can serve well, deprioritize it instead of manufacturing content for theoretical visibility.

    Key takeaways

    • Plan for commercial intent from the first prompt; do not assume a long conversation must happen before an ad can appear.
    • Use prompt clusters, not isolated keywords, as the common planning unit for SEO, PPC, content, landing pages, and measurement.
    • Extract fanout qualifiers such as audience, company size, use case, constraint, and integration because they determine whether an offer actually fits.
    • Track organic visibility, sponsored delivery, landing behavior, and business outcomes separately before evaluating their combined effect.
    • Treat the landing page as shared search infrastructure and make it answer the complete decision context carried by the prompt.

    Your next move is small and concrete: choose one commercially important prompt cluster, document its qualifiers, check both visibility surfaces, and inspect the destination through that user’s question. That single end-to-end audit will expose more useful work than another disconnected SEO keyword list or PPC expansion.

    References

  • How to Turn Google Analytics Insights Into a Smarter Budget

    How to Turn Google Analytics Insights Into a Smarter Budget

    If you are opening Google Analytics to decide where the next part of your paid-media budget should go, a performance alert is not the answer you need. It is only the start of the decision. The dangerous shortcut is to see a channel move, assume the channel caused it, and transfer money before checking whether the movement came from measurement, timing, demand, or campaign execution.

    Google is shortening the distance between monitoring and planning through generated Home insights, cross-channel budgeting, and a no-code scenario interface for Meridian. You can use that shorter path without surrendering judgment. The workflow below turns a signal into a documented, constrained, and reversible budget decision.

    Key takeaways

    • Use generated insights as a triage queue. They can tell you what deserves attention, but they do not prove why a metric changed.
    • Make paid channels comparable before moving money. Align the outcome definition, cost coverage, reporting window, attribution policy, and conversion maturity.
    • Separate historical efficiency from expected marginal return. The best destination for additional budget is not automatically the channel with the best average result.
    • Use scenarios to expose assumptions and constraints, not to manufacture certainty. A forecast is an estimate that still needs business judgment.
    • Document the hypothesis, approved change, guardrails, and evaluation conditions before changing spend. This prevents a plausible explanation from quietly becoming an untestable decision.

    Give each Google planning feature one clear job

    Google Analytics can place the top three changes since your last visit on the Home page, including notable performance shifts, anomalies, and seasonality patterns. That is a detection layer. Its useful output is not a budget instruction. It is a shorter list of changes worth investigating.

    The cross-channel budgeting capability has a different job. It is intended to connect performance across paid channels with investment decisions, but it remains a beta feature with limited access. Build a process that can use the interface when it is available without making your decision discipline dependent on it.

    Google’s no-code Scenario Planner turns Meridian marketing mix model outputs into budget and ROI forecasts. It lets a marketer test alternative allocations without writing code or relying on a data scientist to operate the interface. It does not remove the need to choose the right outcome, understand the model’s limits, or account for constraints the model may not contain.

    CapabilityDecision jobQuestion it can supportWhat it cannot establish by itself
    Generated Home insightsDetection and prioritizationWhat changed enough to investigate?What caused the change or whether budget should move
    Cross-channel budgetingPaid-channel comparison and allocationHow is paid investment performing across channels?Whether the channel inputs are truly comparable
    Scenario PlannerForward-looking simulationHow might budget and ROI change under another allocation?Whether the forecast will occur or whether omitted business constraints make it impractical

    This separation matters because detection, explanation, and allocation require different evidence. An unusual movement may deserve immediate attention while still being a poor reason for an immediate budget change. A scenario may look attractive while depending on immature conversion data or a channel definition that differs from the rest of the plan.

    Turn a surfaced change into an auditable budget decision

    An unlabeled visual workflow moves from a performance signal through evidence checks and scenario comparison to a documented budget allocation.

    Every budget change should have a visible chain from signal to decision. If someone cannot reconstruct that chain later, you will struggle to tell whether the allocation worked, whether the original explanation was wrong, or whether the market simply changed after approval.

    1. Define the decision before examining allocations. Write down the business outcome, planning horizon, channels in scope, total budget boundary, and any commitments that cannot move. If the business cares about qualified demand, a rise in raw conversion volume is supporting evidence rather than the decision metric.
    2. Capture the signal precisely. Record the metric that moved, its date range, the property and filters in use, the affected channel or campaign, and the comparison that made it notable. Avoid summaries such as paid social is down. They are too vague to validate.
    3. Check measurement before interpreting performance. Look for changes to event definitions, tags, consent behavior, attribution settings, campaign naming, imported costs, and reporting filters. A measurement discontinuity can resemble a sudden gain or loss in channel efficiency.
    4. Classify the most plausible explanation. Useful classes include measurement, seasonality, underlying demand, campaign execution, channel mix, and normal variation. The classification tells you what evidence to inspect next; it is not yet a causal conclusion.
    5. Write a testable hypothesis. State what you think changed, the mechanism connecting it to the outcome, and what observation would weaken the explanation. If nothing could disprove the hypothesis, it is a story rather than a basis for allocating money.
    6. Create a comparable baseline. Align the reporting window, outcome definition, included costs, attribution treatment, and conversion maturity across the channels being considered. Preserve any important differences instead of hiding them inside a blended total.
    7. Model alternatives within real constraints. Keep the current allocation as the baseline, then create a reallocation that respects budget limits, channel commitments, operational capacity, and risk tolerance. Add a more conservative version when the input data or model fit leaves substantial uncertainty.
    8. Approve the smallest change that can answer the decision question. A reversible adjustment limits the cost of a wrong assumption and gives you a cleaner read than changing many channels, audiences, bids, and creative variables at once.
    9. Predefine the readout. Name the primary outcome, diagnostic metrics, guardrails, required conversion maturity, and the conditions for continuing, pausing, or reversing the move. Do this before the result is visible so the success rule cannot drift toward whatever happened.

    The planning interface belongs in the modeling stage, not at the beginning of the chain. Starting with a recommended allocation invites you to reverse-engineer a justification. Starting with a defined decision and validated baseline lets you judge whether the recommendation is relevant at all.

    If Scenario Planner or cross-channel budgeting is not available in your account, keep the same structure in a controlled worksheet or planning document. Tool access changes the speed of the work. It should not change the evidence required to approve spend.

    Make every paid channel earn comparison on the same basis

    A cross-channel screen can place metrics beside each other without making them economically equivalent. Before you rank channels, normalize what can be normalized and label what cannot. Otherwise, the cleanest-looking comparison may reward the channel with the most favorable measurement rules rather than the strongest business contribution.

    Use one decision outcome and consistent cost coverage

    Choose the outcome that the budget decision is meant to improve. Revenue, qualified leads, new customers, and platform conversions are not interchangeable. A channel can generate inexpensive form submissions while producing little qualified demand, so optimizing against the cheapest visible conversion may move money away from the business result you actually need.

    Use supporting metrics to diagnose the result, not replace it. Clicks, sessions, reach, and intermediate actions can help explain why the primary outcome changed. They should not outrank that outcome simply because they arrive sooner or look more favorable.

    Apply the same cost policy across the comparison. Decide whether the analysis includes media spend only or a broader set of in-scope costs, then use that definition consistently. Align currencies and the treatment of credits, taxes, and fees where they affect the data. An incomplete cost import can make a channel appear more efficient without any real improvement.

    Respect conversion timing

    Channels often influence outcomes on different timelines. A channel whose conversions mature slowly can look weak beside one whose outcomes are recorded quickly, especially near the end of the reporting window. Do not make the slower channel defend an incomplete result against the faster channel’s mature result.

    Set the evaluation window from the buying cycle and conversion delay relevant to your business. Mark immature periods as incomplete. If leadership needs an earlier read, present leading indicators as provisional evidence and say what remains unknown rather than treating them as final ROI.

    Plan around marginal return, not the historical average

    Average efficiency answers what the channel produced across the spend it already received. Budget planning asks a different question: what is the next portion of spend expected to produce? That distinction is where many reallocations go wrong.

    A historically efficient channel may have limited room to absorb additional budget at the same return. A channel with a weaker average may still have useful incremental capacity. Neither conclusion should be assumed from the averages alone. Use the scenario output, current delivery constraints, and recent evidence to judge the expected effect of the proposed change.

    A practical budget structure separates committed investment, protected learning investment, and reallocatable investment. Committed spend covers obligations or strategic coverage you have decided not to disturb. Protected learning spend preserves experiments that would otherwise be cut before producing useful evidence. Reallocatable spend is the portion the scenario can genuinely move. This prevents a mathematically neat plan from recommending a transfer that the business cannot or should not execute.

    Let attribution and marketing mix modeling answer different questions

    Attribution assigns credit among observed touchpoints under a defined rule or model. Marketing mix modeling estimates relationships between investment and aggregate outcomes across time. Their outputs can differ because the methods, data, and questions differ.

    Do not force the two views to agree before you can make a decision. Use disagreement as an investigation trigger. Check channel definitions, missing costs, promotional periods, conversion lag, offline effects, and the outcome each method is measuring. Then document which view is carrying more weight for this decision and why.

    Put guardrails around AI-assisted budget recommendations

    A human hand reviews glowing budget recommendations that pass through locks, balances, and other safeguards before reaching paid-channel containers.

    Generated explanations and accessible forecasts can make a budget recommendation feel more complete than its evidence warrants. The remedy is not to ignore the tools. It is to require a few checks before the recommendation becomes an instruction.

    • Alert is not explanation. Confirm that the movement is real, material to the decision, and not created by a reporting change.
    • Correlation is not a causal mechanism. Write the proposed explanation and identify evidence that could contradict it.
    • Forecast is not commitment. Treat predicted ROI as conditional on the model, inputs, assumptions, and scenario design.
    • No-code is not assumption-free. Someone still has to define the outcome, constraints, planning period, and acceptable risk.
    • Cross-channel visibility is not complete business visibility. Add margin, capacity, inventory, contractual, brand, or geographic constraints when they matter and are not represented in the analytics view.
    • Optimization is not permission to remove learning. Preserve strategically useful experiments when their evidence has not had time to mature.
    • Beta access is not an operational control. Keep the decision record outside the feature so your process survives access, interface, or availability changes.

    Use a decision record that survives the meeting

    Keep each allocation decision in a short, consistent record. Include the decision question, surfaced signal, validated evidence, rejected explanations, remaining uncertainty, baseline allocation, proposed change, scenario assumptions, business constraints, expected outcome, guardrails, effective period, evaluation conditions, owner, and next review point.

    The record should make the status explicit: hold the allocation, investigate the signal, model alternatives, or implement a change. A review that ends with general agreement but no named status leaves the team vulnerable to accidental changes and conflicting interpretations.

    At the next review, compare the observed result with the expectation and examine the mechanism, not just the final total. A favorable outcome does not automatically validate the original explanation, and an unfavorable outcome does not automatically prove the channel is ineffective. Demand, measurement, and execution may have changed while the budget test was running.

    On your next visit to Google Analytics, take the most decision-relevant surfaced change and run it through the chain before touching spend: validate the measurement, define the hypothesis, create a comparable baseline, model a constrained alternative, and set the reversal conditions. That turns faster analytics into a better decision rather than merely a faster reaction.

    References

  • How to Measure SEO Performance in AI-Driven Discovery

    How to Measure SEO Performance in AI-Driven Discovery

    Your organic sessions are down, AI-generated answers are absorbing more of the discovery journey, and your dashboard still expects traffic to explain whether SEO is working. If you answer with average position or a sitewide traffic total, you can make a healthy program look weak—or celebrate visibility that never becomes demand.

    The answer isn’t to replace one vanity metric with a count of AI mentions. You need a measurement chain that connects search visibility, AI citations, brand recommendations and commercial outcomes. That chain reveals influence that can occur without a click while keeping pipeline and revenue at the center of the scorecard.

    Key takeaways

    • Keep traffic, impressions and rankings, but segment them by topic, intent and business value before using them to judge performance.
    • Measure AI visibility across prompt variations, platforms and collection windows. A favorable answer from one prompt is an observation, not a trend.
    • Track citations, mentions and recommendations separately. They represent different levels of influence.
    • Pair recommendation rate with recommendation share: one measures how often you are recommended, while the other measures how much competitive recommendation space you occupy.
    • Connect the same topic taxonomy to landing pages, conversions and CRM outcomes so the AI visibility report can support an actual decision.

    Measure five links between retrieval and revenue

    Five connected visual stages show web visibility, retrieval, AI citations, brand consideration, and a commercial outcome.

    Traditional SEO reporting often jumps from ranking to traffic and then to conversion. AI-driven discovery adds several decisions between those stages. A system may have access to your page, use it as evidence, mention your brand, or actively recommend you. Those events are not interchangeable: being available, being cited and being recommended are distinct levels of visibility.

    Measurement stageQuestion it answersUseful measuresCommon misreading
    AvailabilityCan search and AI systems find a relevant page?Indexation, topic-level organic visibility, impressions and SERP coverageAssuming an indexed or highly ranked page must appear in an AI answer
    CitationIs your domain selected as evidence?Domain citation rate and citation consistency by topicTreating every citation as a brand endorsement
    MentionDoes the response include your brand?Brand mention rate, context and accuracyCounting neutral or negative mentions as recommendations
    RecommendationIs your brand presented as a suitable choice?Recommendation rate, recommendation share and consistencyCelebrating one favorable response as durable visibility
    OutcomeDoes discovery contribute to valuable demand?Qualified conversions, customers, pipeline and revenue by topic or landing pageUsing last-click attribution as the complete customer journey

    This framework prevents a particularly costly reporting error. If an answer cites your page but recommends a competitor, your content won the evidence-selection step while your brand lost the choice step. More citations alone won’t tell you why.

    Use a response cell as the basic unit of measurement: one prompt variant, on one platform, in one recorded run. Store failed or incomplete runs separately rather than coding them as brand absences. From those cells, calculate:

    • Mention rate: response cells that mention your brand divided by all valid response cells.
    • Citation rate: response cells that cite your domain divided by all valid response cells.
    • Recommendation rate: response cells that recommend your brand divided by all valid response cells.
    • Recommendation share: your brand’s recommendation instances divided by all named-brand recommendation instances in the tracked category. Count a brand no more than once per response so repetition within the prose doesn’t inflate its share.
    • Consistency: the recurrence of your mentions or recommendations across prompt variants, platforms and collection windows. Report each dimension separately so strength on one interface cannot conceal absence elsewhere.

    Recommendation rate and recommendation share answer different questions. A category may produce few brand recommendations overall, giving one brand a large share of a small space. Conversely, your brand may appear frequently while losing relative share because competitors appear even more often. Put both measures beside each other.

    LLM consistency and recommendation share, often grouped as LCRS, provide a repeatable way to examine presence across prompts, platforms and time. Keep the components visible instead of manufacturing a blended score with arbitrary weights. A composite is useful only when its weighting rules are documented and tied to a real business decision.

    Build a repeatable AI discovery sample

    A prompt tracker should represent buyer decisions, not a bag of interesting questions. Isolated keyword tracking already struggles to represent semantic search and intent; copying that model into an AI visibility tool preserves the same flaw. Organize prompts into topic-and-intent families that correspond to the decisions your audience makes.

    Construct prompt families around decisions

    Start with commercially meaningful topic clusters, then cover the different ways a person could approach each one:

    • Category discovery: solutions for a defined problem or goal.
    • Comparison: alternatives, trade-offs or differences between approaches.
    • Shortlisting: suitable providers or products for a particular use case.
    • Constraint: choices shaped by industry, organization size, compatibility, location or another relevant requirement.
    • Validation: questions about trust, fit, limitations or reasons to choose one option over another.

    Create wording variants within each family, but preserve the underlying intent. If you change the audience, constraint and requested output at the same time, you have created a different decision rather than a controlled variation. Keep a permanent identifier for the family and a separate identifier for each variant.

    Track the category, not only your brand name. Brand-prompt performance can show whether a system knows you, but category prompts reveal whether it chooses you before the user has supplied your name. That is the competitive question recommendation share is meant to answer.

    Freeze the protocol before collecting answers

    1. Define the scope. Record the topic clusters, intent classes, markets and AI interfaces the scorecard is supposed to represent. Keep an initial competitor set for reporting, but capture unlisted brands so the tracker can detect new entrants.
    2. Lock a prompt version. Preserve the exact text and variant identifier. Add new prompts as a new version instead of silently editing the historical set.
    3. Record the conditions. Save the platform, interface, collection time, exposed model label, relevant account or location context, and any settings that could affect the response.
    4. Repeat collection. Run the same portfolio on a fixed cadence and retain every raw response. Because LLM output is non-deterministic, directional trends are more useful than one-shot results.
    5. Code observable events. Use separate fields for domain citation, brand mention, explicit recommendation, competitor recommendation, negative context and factual inaccuracy. A response can satisfy several fields at once.
    6. Review ambiguous cases. Automated parsing can handle volume, but human review should resolve implied recommendations, misspelled brands, parent-subsidiary relationships and passages where a brand is mentioned only as a warning.

    The coding rule for a recommendation should be written before anyone sees the results. A practical definition is an explicit suggestion, shortlist placement or statement that the brand is suitable for the requested use case. Incidental examples, citations, navigation instructions and negative comparisons do not qualify.

    Keep the raw answer beside the coded fields. If recommendation share moves, you need to know whether the market changed, the model phrased the same judgment differently, or the parser made a classification error. A dashboard without retrievable evidence is difficult to audit and easy to overinterpret.

    Give executives and practitioners different dashboard views

    An executive scorecard should explain commercial performance. A working SEO view should explain what caused it. Combining both into one page usually leaves leaders staring at diagnostic noise while practitioners lose the detail needed to act.

    The executive view

    • Qualified organic outcomes: leads that become sales-qualified opportunities or customers, not unfiltered form fills.
    • Pipeline and revenue contribution: shown by product category, service line or another useful business unit.
    • Conversion-weighted search visibility: visibility across topic clusters adjusted by documented business value.
    • AI recommendation performance: recommendation rate, recommendation share and consistency for the same high-value clusters.
    • Supporting demand indicators: branded search, direct visits and returning visitors, interpreted alongside campaigns and other factors that can move them.

    To calculate conversion-weighted visibility, assign each topic cluster a business-value weight grounded in qualified conversion or customer data. Multiply the cluster’s visibility by that weight, add the weighted values, and divide by the total weight. Retain the unweighted result beside it. This makes the judgment transparent and prevents a large set of low-intent impressions from overpowering a smaller commercial opportunity.

    Do not let search volume alone determine those weights. A high-volume informational cluster may be useful for awareness, but it should not receive the same commercial importance as a lower-volume cluster that repeatedly produces customers. Traffic and impressions without intent or revenue context can point a strategy in the wrong direction.

    The working SEO view

    • Search impressions, clicks and landing-page conversions segmented by topic cluster and intent.
    • SERP coverage across organic results, snippets, local results and other relevant search features.
    • AI citations, mentions and recommendations by prompt family, platform and collection window.
    • Competitor recommendation share and the prompts where competitors displace your brand.
    • Response accuracy, negative context and unsupported claims that require reputation or content work.
    • Indexation, page eligibility and conversion-path issues that can explain a break in the measurement chain.

    Traffic, impressions and rankings remain useful diagnostics. They become misleading when reported as context-free outcomes. Average position treats queries of unequal value as though they matter equally, and a share-of-top-10 metric can be dominated by low-intent terms. Segment both before using them to allocate work.

    Move proprietary authority scores, total backlink counts and unqualified bounce rate out of the executive scorecard. They may support audits, but they don’t establish business performance. A visitor who gets a complete answer and leaves can produce a high bounce rate despite a successful visit; extra page views from a pricing page can reflect confusion rather than engagement. Engagement measures need page purpose and conversion context.

    Join AI visibility to customer outcomes

    Use the same topic-cluster names in the prompt tracker, content inventory, analytics reporting and CRM. That shared key lets you compare recommendation changes with the landing pages, qualified conversions and opportunities associated with the same need. Without it, AI visibility and revenue remain two charts that happen to sit beside each other.

    Show first-touch, assisted and last-touch views rather than forcing one attribution model to tell the entire story. Where appropriate, add AI assistants as an option in buyer-discovery fields and preserve a free-text answer. Treat self-reported discovery, branded search and direct traffic as supporting evidence, not proof that one AI response caused a sale. Their value is corroboration across signals.

    Interpret combinations of signals, then make a decision

    An analyst watches search, citation, brand, engagement, and purchase signals converge into a glowing path toward one selected action.

    No single movement establishes success or failure. The useful diagnosis comes from the relationship among visibility, recommendation and outcome measures.

    Observed patternLikely measurement implicationWhat to do next
    Citations rise while recommendation rate stays flatYour pages are useful evidence, but the brand is not being selected as a solution.Review whether the content clearly connects the named entity, offer, use case, differentiators and supporting proof. Do not diagnose this as an indexation problem.
    Recommendation share rises while site traffic stays flatZero-click influence is plausible, but the commercial effect is still unconfirmed.Check branded demand, direct and returning visits, qualified conversions and pipeline for the same topic clusters.
    Organic traffic falls while qualified conversions or revenue riseThe lost visits may be concentrated in low-intent queries.Segment the decline by intent, landing page and topic before attempting to restore the old total.
    Traditional rankings are strong while AI citations and mentions are weakRanking availability is not translating into selection within generated answers.Audit whether the relevant pages answer the prompt directly and express entities, claims and supporting evidence clearly.
    Visibility improves on one platform but not across prompt variants or timeThe gain is platform-specific or unstable rather than consistent.Keep collecting under the fixed protocol before changing strategy or claiming category-wide growth.
    AI visibility rises while qualified outcomes remain flatThe tracked prompts may not represent valuable demand, or the break may occur after discovery.Revalidate prompt intent, then inspect the offer, landing-page journey and lead qualification before pursuing more mentions.
    Results swing sharply between runsSampling volatility may be larger than the underlying change.Inspect raw responses and wait for the direction to recur across variants, platforms or collection windows.

    Predefine the decision attached to each pattern. If citation consistency is high but recommendation rate is low, work on brand-to-solution clarity and comparative evidence. If both AI visibility and commercial outcomes are weak for a high-value cluster, revisit the intent, content and conversion path. If recommendation performance and qualified outcomes improve together across a stable sample, expand the approach to the next closely related cluster.

    When you make a substantial change, annotate it in the measurement record. Where feasible, update one topic cluster while leaving a comparable cluster unchanged. Continue using the same prompt version and coding rules. This won’t turn observational data into perfect causal proof, but it gives you a much stronger comparison than a before-and-after screenshot taken from changing prompts.

    Begin with one commercially important topic cluster. Build its prompt families, collect the raw responses, code citations and recommendations, and connect the cluster to qualified conversions. Once that baseline is stable, the next report can answer the question that matters: whether your brand is merely available, repeatedly chosen, or contributing to demand.

    References

  • ChatGPT Conversion Rates by Industry: 2026 Benchmarks

    ChatGPT Conversion Rates by Industry: 2026 Benchmarks

    If ChatGPT has started appearing in your referral report, the hard question isn’t whether the traffic exists. It’s whether your conversion rate is healthy enough to justify more investment or weak enough to expose a broken landing path.

    Industry context helps, but only when you use it as a diagnostic. Reported 2026 rates run from 1.4% to 7.0%. That spread reflects more than differences in demand: participating companies defined their own conversion actions, and most had already invested in generative engine optimization and ChatGPT-focused funnels. Match the definitions before you match the percentages.

    Key takeaways for evaluating ChatGPT conversions

    • The 2026 industry range is 1.4% to 7.0%, with hotels and resorts at the high end and engineering at the low end.
    • A conversion was whatever action each participating company had designated, so the rates do not represent one uniform outcome.
    • Most participating companies had invested in GEO and dedicated ChatGPT funnels. Treat the figures as an optimized-cohort reference, not a universal market average.
    • Absolute conversion rate and improvement over traditional SEO are different measurements. You need your own matched SEO baseline to calculate channel lift.
    • Keep direct ChatGPT referrals separate from broader AI influence so that attribution assumptions do not distort your benchmark.

    2026 ChatGPT conversion benchmarks by industry

    Six differently shaped visitor pathways lead to geometric goals beside objects representing retail, software, finance, travel, healthcare, and business services.

    Between May 2025 and February 2026, anonymous client data from more than 150 companies measured the proportion of ChatGPT referral traffic that completed a conversion action defined by each company. Most companies in the cohort had higher-than-average ChatGPT referral traffic, prior GEO investment, and a dedicated conversion path for that traffic.

    That context matters. These are useful reference points for a company actively optimizing AI discovery and its post-click experience. They are not reliable predictions for an unoptimized site, and they should not be inserted directly into a revenue forecast.

    IndustryReported average conversion rate
    Addiction Treatment2.9%
    Apparel & Fashion2.8%
    B2B SaaS2.4%
    Biotech2.1%
    Commercial Insurance3.1%
    Construction3.4%
    eCommerce3.0%
    Engineering1.4%
    Entertainment4.7%
    Environmental Services2.0%
    Financial Services1.9%
    Food & Beverage3.4%
    Healthcare4.5%
    Heavy Equipment1.8%
    Higher Education & College4.9%
    Hotels & Resorts7.0%
    HVAC Services3.9%
    Industrial IoT3.9%
    IT & Managed Services2.4%
    Legal Services5.6%
    Luxury Goods1.9%
    Manufacturing3.8%
    Medical Device2.3%
    Oil & Gas3.2%
    PCB Design & Manufacturing2.9%
    Pest Control3.8%
    Pharmaceutical3.2%
    Real Estate2.8%
    Software Development1.8%
    Solar3.5%
    Staffing & Recruiting3.7%
    Transportation & Logistics1.9%

    The useful comparison is your rate against the row for your industry and a matched conversion event, not against the highest rate in the table. A hotel booking and an engineering inquiry represent different commitments. Even two companies in the same industry may assign conversion status to different actions.

    What the industry spread does and does not prove

    The leading rates identify a pattern, not its cause

    Hotels and resorts led at 7.0%, followed by legal services at 5.6%, higher education and college at 4.9%, entertainment at 4.7%, and healthcare at 4.5%. Engineering recorded 1.4%; heavy equipment and software development each recorded 1.8%; financial services, luxury goods, and transportation and logistics each recorded 1.9%.

    Those rates show where conversions landed, not why. Buying urgency, brand strength, traffic mix, conversion definition, landing-page quality, and the amount of friction in the next step are all plausible contributors. None can be isolated from an industry-level rate alone.

    A useful working hypothesis is that conversational search can pre-qualify some visitors. A user can describe a detailed problem, refine the request, and narrow the options before clicking. That can produce a visitor who is closer to a decision than someone arriving through a broad search query. Test that hypothesis against lead quality and downstream outcomes rather than treating it as a settled explanation.

    Complexity can improve channel lift without producing the highest rate

    Commercial insurance converted at 3.1%, while pharmaceuticals converted at 3.2%. Neither sits near the top of the absolute rankings. Their significance lies in the reported advantage over traditional search for complex buying decisions, not in having the largest raw percentages.

    No industry-by-industry traditional SEO baseline rates accompany these ChatGPT figures, so you cannot calculate a defensible uplift from the benchmark alone. Likewise, B2B sectors showed larger improvements over traditional SEO than B2C sectors, but no specific lift values are provided. Treat that distinction as directional until your own analytics can compare the same conversion event over the same measurement period.

    Referral conversion is narrower than total AI influence

    The benchmark measures referral traffic from ChatGPT. It does not represent every buyer who encountered a company in an AI answer and later arrived through direct traffic, branded search, email, or another channel. Mixing those journeys into the referral denominator would make your result incomparable with the industry figures.

    Maintain two views. Use direct ChatGPT referral conversion rate for the industry comparison. Use a separate assisted or influenced view for broader journey analysis, with its attribution assumptions documented. The first tells you how referred visits perform; the second helps you investigate whether AI visibility contributes elsewhere in the buying journey.

    Build an internal benchmark you can defend

    Two hands align visitor tokens, transparent funnels, landing-page tiles, a magnifying lens, and goal markers on an analyst's worktable.

    A percentage becomes useful only when everyone knows what entered its numerator and denominator. Build the internal benchmark in this order:

    1. Choose one primary conversion for each buying motion. For lead generation, distinguish an initial inquiry from a qualified lead, booked meeting, or sales opportunity. For commerce, keep completed purchases separate from add-to-cart and checkout events. Micro-conversions can remain diagnostic metrics, but blending them into the primary rate makes the result easier to inflate and harder to interpret.
    2. State the attribution scope. Label the series as direct ChatGPT referral traffic. If you also model assisted AI influence, store it as a separate series rather than silently adding it to the direct result.
    3. Keep the denominator with the rate. Calculate the percentage from completed primary conversions attributed to ChatGPT referrals divided by all ChatGPT-referred visits, multiplied by 100. Report the visit count, conversion count, conversion rate, event definition, and measurement period together. A rate without its underlying counts can look stable when it is not.
    4. Create a like-for-like comparison. Compare ChatGPT with traditional SEO using the same primary event, date range, geography, device rules, and treatment of new and returning visitors. Annotate any mismatch instead of presenting the resulting difference as channel lift.
    5. Segment by observable landing paths. Break performance down by landing page, content cluster, offer, and call to action. Do not claim to know the user’s original prompt if you did not capture it. The page visited and the actions taken on your site are evidence; an inferred prompt is a hypothesis.
    6. Connect the event to business quality. For lead generation, carry the referral source into qualification and opportunity reporting. For commerce, connect it to completed orders rather than stopping at a checkout signal. A high top-of-funnel conversion rate can still be commercially weak if the resulting leads or orders do not meet the business definition of value.
    7. Choose the decision rule before changing the funnel. When traffic volume supports a controlled test, define the success event and comparison method in advance. When referral volume is sparse, report the uncertainty, group genuinely similar landing paths where appropriate, and avoid declaring a winner from a volatile percentage.

    This process also prevents a common benchmarking mistake: celebrating a rate above the industry figure when your conversion event is easier to complete. A newsletter signup should not be compared with a booked consultation, completed application, or purchase simply because every event has been labeled a conversion.

    Turn the performance pattern into the right next move

    Judge high and low performance relative to a matched industry rate and your own stable history. Then use the combination of referral volume, primary conversion rate, and downstream quality to decide what to investigate.

    Observed patternWhat it may indicateWhat to do next
    Low ChatGPT referral volume with a healthy matched conversion rateThe post-click path may work, while AI discovery or citation coverage is limited.Audit the questions and decision criteria covered by your content. Strengthen pages that contain evidence, clear entity information, and a natural path to the existing conversion action.
    Healthy referral volume with a low matched conversion rateChatGPT visibility is producing clicks, but the landing experience may not continue the user’s intent.Rank landing pages by referred visits, then examine message continuity, proof, call-to-action relevance, and form or checkout friction on the highest-volume cluster.
    Healthy conversion rate with weak qualified-lead or revenue performanceThe primary event may be too shallow, or the offer may attract the wrong kind of demand.Move the primary benchmark deeper into the funnel, preserve the shallow event as a diagnostic metric, and evaluate results by qualified outcome.
    An apparently high rate supported by a small denominatorNormal variation may be creating a persuasive but unstable percentage.Show the counts, gather more observations, and avoid projecting the rate into a budget or revenue model until it becomes decision-worthy.
    ChatGPT and SEO rates calculated from different events or attribution rulesThe apparent channel lift may be a measurement artifact.Rebuild both series around the same event and scope before changing channel investment.

    Do not respond to an underperforming benchmark by rewriting every page that receives a ChatGPT referral. Start with the content cluster responsible for the most referred visits and select one failure point: intent mismatch, missing proof, an irrelevant next step, or conversion friction. Preserve the baseline and record the change so the next measurement has a clear before-and-after boundary.

    Your immediate task is to name the primary conversion, export ChatGPT-referred visits and completed events for the same period, and compare the result with the matched industry row. The benchmark has done its job when it points you to one tracking correction or one funnel test. It has not done its job when it becomes a percentage copied into a forecast without the definitions that produced it.

    References

  • How to Measure AI Discovery, Attribution, and Conversion

    How to Measure AI Discovery, Attribution, and Conversion

    You can be named in AI answers, receive almost no identifiable referral traffic, and still influence a sale. You can also collect a burst of chatbot visits that never becomes revenue. If your dashboard treats those outcomes as the same thing, you will optimize the wrong part of the customer journey.

    The practical fix is to separate AI discovery visibility, attribution, and conversion, then reconnect them with an evidence chain. That gives you a defensible answer to three different questions: Are AI systems recommending you? Can you identify their influence? Does that influence create valuable outcomes?

    Key takeaways

    • Measure AI discovery, attribution, and conversion as separate stages. A strong result at one stage does not prove success at the next.
    • Treat AI visibility as sampled visibility, not a permanent ranking position. Track a fixed set of prompts, repeated outputs, mentions, recommendations, citations, and cited pages.
    • Build consistency around an entity home: one authoritative place where your identity, offers, audience, availability, and supporting facts agree with your visible content and JSON-LD.
    • Separate observed referrals, customer-reported AI influence, assisted journeys, and broader trend signals. Combining them into one conversion count creates false certainty.
    • Compare conversion rates only after checking traffic volume, intent, landing-page purpose, outcome quality, and measurement coverage.
    • Use one scorecard across content, analytics, CRM, and revenue systems so each team is working from the same channel definitions.

    Measure discovery, attribution, and conversion separately

    Three connected scenes show an AI highlighting an option, evidence trails converging through a lens, and a verified path reaching a purchase package.

    AI discovery visibility is your presence inside an assistant’s answer. It includes being mentioned, recommended, described accurately, cited, or used as the basis for an answer. The user does not have to visit your site for that visibility to matter.

    Attribution is the evidence connecting that exposure to a later action. A detectable referral is one form of evidence, but AI-assisted decisions can occur without producing the traditional click. That makes attribution a confidence problem rather than a simple channel lookup.

    Conversion is the valuable outcome: a purchase, booking, qualified lead, application, subscription, or another action your business has defined in advance. It belongs at the end of the chain. A brand mention is not a conversion, and a chatbot session is not proof of revenue.

    StageQuestion to answerUseful evidenceCommon mistake
    DiscoveryDoes the assistant include and represent us for relevant needs?Mentions, recommendations, citations, cited pages, answer accuracy, and repeatability across tracked promptsTreating one favorable answer as a stable ranking
    AttributionWhat evidence connects AI exposure with a visit or decision?Detectable referrals, customer reports, identifiable journey sequences, and directional demand signalsCalling every direct visit or branded search an AI visit
    ConversionDid identifiable or reported AI influence create a valuable outcome?Conversions, qualified outcomes, revenue, conversion rate, and time to conversionComparing rates without checking volume, intent, or measurement coverage

    Define the measurement contract before collecting results. Fix the audience, market, use case, conversion event, reporting window, and set of assistants you intend to evaluate. Otherwise, a change in prompt mix or business definition can look like a performance change.

    Your prompt set should cover distinct stages of intent. Category prompts reveal whether you are discovered at all. Comparison prompts reveal whether you enter a shortlist. Validation prompts reveal whether the assistant can explain your fit, limitations, and evidence. Decision prompts reveal whether it can direct a user toward the right next step. Keep these groups separate because an improvement in broad discovery can hide a decline among high-intent questions.

    Make your brand easy to identify and corroborate

    AI recommendations can vary considerably between outputs. There is no single position to check and declare permanent. Your first visibility metric should therefore be repeatability: does the same brand appear, for the same relevant need, often enough to indicate more than a one-off answer?

    Record the exact prompt, assistant, date, account state, answer, brand position within the answer, cited URLs, and any material factual errors. Repeat the same prompts under comparable conditions. This does not remove model variability, but it stops your own testing process from introducing avoidable noise.

    Establish an entity home

    An entity home is the authoritative page, or tightly connected group of pages, where a machine can resolve what your brand is. It should make the following facts explicit rather than forcing an assistant to infer them:

    • Your canonical brand name and website.
    • What you provide, using the terms customers use to describe the need.
    • Who the offer is for and when it is not a fit.
    • Where the offer is available and which limitations matter.
    • The relationship between the brand, its products, and any parent or operating organization.
    • The evidence supporting important claims.
    • The correct next step for someone who wants to evaluate, contact, buy, or book.

    Visible copy, navigation labels, page metadata, and JSON-LD should express the same facts. Structured data is a clarification layer, not a way to publish a second version of the business. If the page calls an offer a platform, the markup describes a service, and external profiles use a third label, you have created an identity-resolution problem.

    Keep a claim ledger

    Create a working list of the claims you want an assistant to repeat. For each claim, record the approved wording, the controlled page that supports it, the evidence behind it, the machine-readable representation, the external locations that mention it, and the person responsible for keeping it current.

    This catches a common failure mode: marketing changes a promise, product changes an availability condition, and structured data or external profiles retain the old version. An assistant may then omit the claim, hedge it, or reproduce the wrong version. Fix the disagreement before producing more pages about the same subject.

    Build corroboration, not repetition

    Repeating a claim across your own site can improve clarity, but it does not create independent support. More consistent AI visibility tends to emerge when your controlled identity and authoritative third-party information align. The practical goal is not to manufacture mentions. It is to make legitimate profiles, listings, coverage, documentation, and references accurate enough to confirm the same core facts.

    Audit contradictions before chasing additional coverage. Start with the facts most likely to affect a recommendation: category, audience, capabilities, availability, pricing model if publicly stated, location, ownership, and material limitations. A smaller set of consistent claims is more useful than a larger footprint full of stale descriptions.

    Write pages that can support an answer

    A page should answer one identifiable decision question well. Put the direct answer near the start, define who it applies to, show the supporting facts, state meaningful limits, and link to the canonical pages behind those facts. Give comparison and use-case pages enough context to stand alone; an isolated slogan is difficult to verify and easy to misrepresent.

    Do not judge these pages only by search visits. In an AI journey, a page can help establish the facts used in an answer even when the user never opens it. Track whether the page is cited, whether its language appears accurately in answers, and whether improvements make recommendations more consistent across your prompt set.

    Build attribution that survives a missing click

    A person researches on a tablet and later buys on a laptop, with indirect signal trails bridging the missing digital connection.

    No single attribution method will reveal every AI-influenced journey. The defensible approach is to keep evidence classes separate and assign each one an appropriate level of confidence.

    1. Observed AI referral: A visit arrives with a detectable referring platform or a campaign link you deliberately placed. This is the strongest channel evidence, but it covers only journeys that produce a visible handoff.
    2. Customer-reported AI influence: A lead or buyer identifies an AI assistant when asked how they discovered you or what helped them decide. Preserve the original response and map it to a reporting category without discarding the raw wording.
    3. Identifiable assisted journey: An AI referral occurs earlier in a known journey and a later session converts. Report it as assisted rather than relabeling the final touch.
    4. Directional influence signal: AI visibility changes alongside branded demand, direct visits, sales questions, or conversions. This can support an investigation, but correlation alone does not prove that AI caused the result.
    5. Unknown: No reliable connection can be established. Keep this category. Forcing unknown journeys into AI reporting makes the dashboard look complete while weakening every decision based on it.

    Use separate reporting fields for observed, reported, assisted, directional, and unknown influence. Your deduplicated AI-influenced conversion total may include the first three when their identities are clear. Directional signals should remain outside that total because they describe context, not attributable conversions.

    Preserve the evidence at collection time

    At the first identifiable visit, preserve the raw referrer, landing page, timestamp, campaign value when present, and assistant name when it can be observed. Do not overwrite those fields when your channel-classification rules change. Retaining the raw values lets you repair historical classification without inventing history.

    At a lead or purchase step, ask an optional discovery question such as, “Where did you first hear about us?” A second question such as, “What helped you decide?” distinguishes discovery from decision support. Offer an AI-assistant option, but retain an open field because customers may name a platform, describe a generated answer, or use terminology your choices did not anticipate.

    Do not quietly infer and store a person’s private prompt. Record only the information the platform legitimately passes or the customer voluntarily provides. Attribution does not become more accurate merely because more sensitive data is collected.

    Use the same definitions in every system

    A common channel taxonomy should flow through web analytics, lead records, customer systems, the data warehouse, and revenue reporting. If marketing defines an AI-assisted lead differently from sales operations, the reconciliation meeting will become an argument over labels rather than a decision about performance.

    Enterprise teams also need a repeatable way to move search intelligence into the systems where decisions are made. Conductor’s Data API is designed to extend search data across enterprise platforms and AI infrastructure. Whether you use that product or another integration route, the architectural requirement is the same: prompt-level visibility, visit evidence, customer-reported influence, and commercial outcomes need shared identifiers and shared definitions.

    Run a reconciliation check before presenting an AI revenue figure. Confirm that a conversion has not been counted once as an observed referral, again as a reported discovery, and a third time as an assisted journey. Preserve the separate flags, but deduplicate the commercial outcome.

    Read AI conversion rates without fooling yourself

    During Airbnb’s Q4 2025 earnings call, CEO Brian Chesky said chatbot traffic converted at a higher rate than Google traffic. The disclosure did not include the underlying conversion rates, referral volume, or the chatbots responsible for those visits. It is a useful signal that chatbot referrals can carry strong intent, but it is not a benchmark you can transfer to another business.

    A plausible interpretation is that some users arrive from assistants after narrowing their choices, which places them further along in the journey. Other explanations remain possible: different landing pages, audience composition, attribution coverage, device mix, or a small group of unusually motivated visitors. Your own data must distinguish those possibilities.

    Check six things before calling AI traffic a better channel:

    • Denominator: Decide whether the rate uses sessions, users, leads, or another unit. Do not compare rates built from different denominators.
    • Volume: Show the conversion count beside the rate. A small stream can produce a high rate while contributing little total revenue.
    • Intent: Compare visitors who were trying to complete a similar task. A decision-ready referral should not be compared casually with broad informational traffic.
    • Landing experience: Check whether channels enter through pages with different purposes. A booking or product page naturally has a different job from an educational page.
    • Outcome quality: Measure the outcome the business values, not merely the easiest event to count. For a complex sale, that may be a qualified opportunity rather than a form submission.
    • Coverage and lag: State how much traffic could be classified and how long conversions typically remain connected to an earlier touch in your reporting model.

    Keep rate, volume, and value in adjacent columns. If AI referrals convert strongly but remain small, expand visibility around the prompts and pages already producing qualified visitors. Do not treat the rate alone as a reason to reallocate a large budget. If referral volume rises while conversion weakens, inspect query intent and landing-page continuity before trying to increase visibility further.

    When visibility rises but detectable traffic does not, check which pages assistants cite and whether users have a clear reason to continue to your site. Some answers may satisfy the question without a click. Others may mention the brand but omit a usable next step. That is a discovery-to-handoff problem, not yet a conversion-rate problem.

    When referrals and customer-reported influence rise but qualified outcomes do not, the break is later. Compare the promise made in AI answers with the landing page, offer, eligibility conditions, and sales follow-up. A mismatch at that handoff can produce plenty of apparently relevant traffic without commercial value.

    Run one AI discovery-to-revenue review

    A useful review follows the journey in order. It does not open with a single visibility score or end with a single attribution number. Use the same prompt set and definitions for each reporting cycle, then organize the scorecard into four layers.

    Visibility layer

    • Mention rate: tracked runs in which the brand appears divided by total tracked runs.
    • Recommendation rate: tracked runs in which the brand is presented as a suitable option, kept separate from incidental mentions.
    • Citation rate: tracked answers that link to a controlled page, with the actual cited URLs listed.
    • Accuracy rate: appearances that represent the monitored brand facts correctly.
    • Repeatability: prompts for which the brand remains present across repeated comparable runs.

    Do not merge all prompts into one opaque score. Break these measures out by category discovery, comparison, validation, and decision intent. A stable overall percentage can otherwise hide movement at the stage closest to conversion.

    Attribution layer

    • Detectable AI referrals and the landing pages receiving them.
    • Customers who report discovering the brand through an assistant.
    • Customers who report that an assistant helped with the decision.
    • Identifiable journeys in which an AI referral assisted a later conversion.
    • Directional signals, displayed as context and clearly labeled as non-causal.
    • The share of outcomes that remains unknown or unclassified.

    Conversion layer

    • Sessions or users, conversion count, and conversion rate for observed referrals.
    • Qualified outcomes and value from customer-reported or identifiable assisted journeys.
    • Time from first known AI interaction to conversion.
    • Performance against a comparable non-AI cohort with similar intent.
    • Results by landing page, prompt-intent group, audience, and market where the data supports that split.

    Evidence-quality layer

    • Changes to the prompt set, assistant mix, account conditions, or collection process.
    • Changes to channel-classification rules or customer-survey wording.
    • Missing data, small groups, duplicate records, and known tracking gaps.
    • Entity-home, JSON-LD, content, or third-party corrections made during the period.

    End the review with one test tied to the weakest link. If visibility is inconsistent, reconcile the entity home and external descriptions around one important claim. If mentions are stable but citations are poor, improve the page that should substantiate the answer. If referrals are visible but influence disappears in customer records, repair the data handoff. If qualified conversions are weak, examine intent and promise continuity before publishing more content.

    You can start with a fixed prompt set, a canonical-fact audit, two optional attribution questions, and separate fields for observed, reported, assisted, and directional evidence. After one complete review cycle, invest in the stage where the chain actually breaks. That is how AI visibility becomes a measurable acquisition system instead of another disconnected dashboard.

    References

  • SaaS AI Referral Traffic Is Down: A Practical Diagnostic

    SaaS AI Referral Traffic Is Down: A Practical Diagnostic

    Your SaaS dashboard shows fewer visits from AI assistants. Before you rewrite the content roadmap or declare the channel dead, find out exactly which line moved. A fall in standalone-assistant referrals, a shift toward workflow-embedded tools, and poor landing-page routing are three different problems. They require three different responses.

    The goal isn’t to recover every lost session. It is to make your product easy to retrieve at the right moment, send qualified users to a page that resolves their question, and measure whether those visits produce meaningful actions.

    Key takeaways

    • A decline in attributed AI referrals is not the same as a decline in AI visibility. Referral analytics capture recognized visits, not every citation, recommendation, or answer that produces no click.
    • The widely discussed 53% decline applied to standalone AI discovery sessions in one SaaS dataset. It occurred while workflow-embedded Copilot traffic grew by more than 20 times, so the pattern is better read as channel redistribution than universal disappearance.
    • Internal search deserves its own landing-page segment. About 41% of the dataset’s LLM sessions landed on search-result pages, which can reveal that an assistant could not identify a better direct answer.
    • Compare equivalent buying periods. The dataset peaked in July and weakened through Q4, making a simple month-over-month chart especially easy to misread.
    • Prioritize landing-page relevance, qualified actions, referrer mix, and content penetration. Total sessions alone cannot tell you whether your AI search strategy is improving.

    Read the decline as a distribution problem first

    The 53% figure does not establish that every SaaS company lost half its AI audience. It describes a decline in discovery sessions from standalone AI tools within a particular dataset. Between November 2024 and December 2025, that dataset recorded 774,331 sessions attributed to large language models.

    Its referrer mix was highly concentrated: ChatGPT accounted for 82.3% of the sessions. When one platform supplies that much traffic, a change in its usage, interfaces, link behavior, or audience mix can dominate the aggregate chart. A top-line decline can therefore hide growth elsewhere.

    Copilot demonstrates the point. It generated 148 sessions near the end of 2024, grew by more than 20 times by May 2025, and then averaged 3,822 sessions per month from June through December. It had become the second-largest AI referrer by the end of 2025.

    The pattern is consistent with intent moving into the user’s existing workflow. Someone already working in an embedded assistant may ask a product or implementation question without opening a separate discovery tool. That does not settle the larger question of whether agents will replace parts of SaaS. It does tell you that measuring all AI platforms as one homogeneous channel will produce poor decisions.

    Start by classifying the shape of your own decline:

    Pattern in your analyticsWorking interpretationNext check
    Standalone assistants fall while an embedded assistant growsReferrer mix is changingCompare landing pages, intent, and conversion by platform
    AI and other non-paid channels weaken in the same periodDemand or B2B seasonality may be involvedCompare equivalent periods and commercial outcomes
    AI sessions increasingly land on internal searchAssistants may not be resolving a direct destinationInspect the query, result quality, and crawl path
    AI sessions fall but qualified actions hold steadyLost visits may have been lower-value, or attribution may have shiftedReview conversion counts, not only conversion rate
    Sessions hold steady while qualified actions fallLanding-page relevance or intent quality has deterioratedAudit the promise-to-page match for the affected referrers

    These are diagnostic hypotheses, not conclusions. Use them to choose the next report or page inspection rather than to explain the result in advance.

    Audit measurement before changing your content

    A magnifying lens reveals a hidden signal path beside an abstract attribution funnel and tracking nodes on an analyst workstation.

    An analytics tool’s AI channel is a record of identifiable referrals. It is not a complete count of how often an assistant mentions your company, uses your information, recommends your product, or answers a question without sending a visit. Call the metric what it is: attributed AI referral sessions.

    Lock the channel definition

    Export the referrer rules behind your AI segment. Keep the same platform list, source normalization, bot filtering, and session definition throughout the comparison. If you add a newly discovered referrer halfway through the audit, recalculate the earlier period under the same rule set. Otherwise, taxonomy maintenance will look like growth.

    Keep an explicit “unknown or unclassified” bucket. Do not silently assign direct traffic to AI just because a visitor viewed an AI-oriented page. That may be a useful hypothesis for investigation, but it is not referrer evidence.

    Build a platform-by-page-type view

    For each complete month, split AI referrals by platform and landing-page template. At minimum, separate the homepage, product or feature pages, pricing, comparisons, documentation, blog content, and internal search results. Preserve the full landing URL in the underlying export so query parameters do not disappear inside a grouped page report.

    This matrix exposes changes that a channel total conceals. ChatGPT might stop sending exploratory blog visits while Copilot begins sending fewer but more commercial visits to product documentation. Calling that a single traffic decline would erase the useful part of the change.

    Use seasonally comparable periods

    SaaS discovery in the observed dataset peaked in July and declined through Q4, alongside normal B2B work, budget, and holiday cycles. That is not a universal calendar for every SaaS company. It is a warning against treating an autumn-to-December decline as proof of an AI-specific loss.

    Compare the same quarter year over year when you have consistent data. If you do not, compare AI referrals with non-paid search, direct visits, demo activity, and other demand indicators over the same months. A decline shared across channels points toward a different diagnosis than an isolated fall from one AI platform.

    Measure penetration, relevance, and outcomes

    Create a small scorecard with definitions your team can reproduce:

    • Referrer share: each AI platform’s sessions divided by all attributed AI referral sessions. This shows concentration and redistribution.
    • Landing-page relevance rate: AI sessions reaching a page that directly answers the apparent intent divided by all AI sessions. Define the intended destination for each query or intent class before scoring it.
    • Commercial action rate: trials, demos, sign-ups, or another agreed activation event divided by AI sessions. Report the action count beside the rate so a tiny denominator does not mislead you.
    • AI landing-page penetration: eligible product, comparison, pricing, and answer pages receiving at least one attributed AI visit divided by all eligible pages. Use this as an internal coverage metric, not an industry benchmark.
    • Search-result dependency: AI sessions landing on internal search divided by all AI sessions. A rising share deserves a query-level inspection even when total traffic is stable.

    Keep visibility and referral performance as separate columns. If you monitor assistant mentions or citations, compare them with clicks rather than combining them into an invented all-purpose score. Visibility can remain stable while click behavior changes.

    Treat internal search landings as a retrieval clue

    A search beam selects one webpage tile from a floating digital library and connects it to a brightly lit destination doorway.

    Internal search was the largest destination class in the observed traffic. Search-result pages received 320,615 sessions, or about 41% of all LLM referrals, exceeding blog, pricing, and product destinations.

    That does not mean internal search was the best content. A more useful interpretation is that the assistant found a searchable route but not a confident direct answer. Your search interface became a fallback discovery layer.

    Open the top AI-referred search URLs and inspect them as a user and as a crawler:

    • Reproduce the query from the landing URL. Confirm that it returns relevant results rather than an empty state, generic category, or different query after a redirect.
    • Check whether the public result can be fetched without authentication, cookies, or a browser-only interaction. If useful results appear only after client-side execution, provide a crawlable path to the primary answer.
    • Expose the query, result summary, and important destination links in visible HTML. A search shell with no meaningful server response gives an assistant little to interpret.
    • Verify the status code, robots directives, canonical target, and rendering behavior. A result page should not claim to be a successful answer while returning an error, canonicalizing to an unrelated page, or hiding every result from crawlers.
    • Trace each recurring high-intent query to its best permanent destination. If people repeatedly search for pricing, a named integration, a comparison, or a specific capability, create or improve the dedicated page and link it prominently.
    • Make the onward path explicit. A useful result should lead directly to the relevant product, pricing, comparison, documentation, or contact page instead of forcing another search.

    Do not respond by indexing every possible internal-search combination. Unlimited query parameters, spelling variants, and empty result sets can create a large collection of duplicate or low-value URLs. Keep crawlable search states finite and useful. Promote recurring, commercially meaningful questions into governed landing pages with stable URLs, original answers, and intentional internal links.

    Think of public search as an interface an AI system may use, not as a substitute for information architecture. If the same search query repeatedly attracts referrals, the durable fix is usually a direct answer page that no longer requires the fallback.

    Rebuild around moments of intent, then test one cycle

    Workflow-embedded assistants change when discovery happens. The user may already be writing a specification, comparing tools, diagnosing an integration, or preparing a purchase request. Your page has to resolve that immediate task. A broad brand narrative is rarely enough on its own.

    User’s moment of intentBest destinationInformation that must be visible
    “What does it cost?”Pricing or plan pagePricing basis, plan differences, limits, conditions, and the next buying step
    “Can it handle this use case?”Capability or use-case pageDirect answer, supported inputs, prerequisites, limitations, and a relevant example
    “How does it compare?”Comparison pageDecision criteria, material differences, suitability, migration considerations, and current facts
    “How do I complete this task?”Documentation or task pagePrerequisites, ordered steps, expected result, failure points, and the appropriate next action
    “Where is the relevant feature or resource?”Help, navigation, or curated search pageExact destination, concise context, and direct links without another discovery loop

    Make critical facts available in the main page content. Do not leave pricing conditions, compatibility, product limits, or differentiators only inside images, tabs that never render for a crawler, or downloadable collateral. Clear headings, concise answers, comparison tables, and descriptive internal links make the page easier for people and retrieval systems to interpret. The broader SaaS pattern favors transparent, crawlable, comparison-oriented information.

    Use structured data to clarify, not manufacture, the answer

    JSON-LD should describe the content a visitor can verify. Use the most accurate entity types for the page, such as Organization and SoftwareApplication where they genuinely apply. Represent offers only when the visible pricing information is current and complete enough to support them. Use FAQPage only for questions and answers that are actually present for the reader, and BreadcrumbList only when it reflects the real hierarchy.

    Keep names, URLs, product descriptions, and relationships consistent between markup and visible copy. Do not stack loosely related schema types in the hope of earning AI visibility. Structured data can reduce ambiguity; it cannot repair a missing price, an evasive comparison, an inaccessible result, or an unsupported claim.

    Run a controlled repair cycle

    1. Freeze the baseline. Save monthly sessions, referrer share, landing-page type, search-result dependency, qualified actions, and your current channel rules.
    2. Choose pages from three evidence-backed groups: high-intent pages receiving no AI referrals, internal-search URLs receiving AI referrals, and pages that attract visits but fail to resolve the apparent intent.
    3. Repair the answer path. Put decisive facts in visible content, connect recurring searches to permanent destinations, improve internal links, and align JSON-LD with the finished page.
    4. Annotate the publication and crawl dates. Keep unrelated template and attribution changes out of the same evaluation window where practical.
    5. Review one complete reporting period using the frozen definitions. Compare platform mix, relevant landings, action counts, and search dependency before looking at the aggregate traffic line.

    The decision after that cycle should follow the observed failure. If one referrer is shrinking while another is growing, adapt destinations to the growing moment of intent. If search-result dependency is rising, repair retrieval and information architecture. If comparable periods weaken across several acquisition channels, do not blame AI alone. If qualified actions hold while raw visits fall, protect the pages producing those actions before chasing volume.

    Your first move can be small: open a platform-by-page-type report, select the highest-traffic internal-search landing, and follow its path to the page that should have answered the query directly. Repairing that path gives you a measurable change. A generic push to publish more does not.

    References

  • How to Measure Brand Visibility and Attribution in AI Search

    How to Measure Brand Visibility and Attribution in AI Search

    If ChatGPT recommends your brand but analytics reports no AI conversions, you do not necessarily have a performance problem. You have a measurement gap. A buyer can use AI throughout their research and still enter your site through Instagram, branded search, a bookmark, or a direct visit.

    Your job is to separate three questions that dashboards tend to collapse: Can AI find and describe your brand correctly? Does that information help a buyer shortlist you? Does the influence produce a commercial result? Once you measure those separately, you can improve visibility without mistaking every mention for revenue.

    Visibility is not attribution, and neither is trust

    Generative engine optimization, or GEO, aligns your brand and content with the way answer engines retrieve, summarize, cite, and recommend information. That makes visibility a useful leading indicator. It does not make visibility the final business outcome.

    • Visibility asks whether your brand appears for a relevant prompt, which pages are cited, and how prominently the brand is presented.
    • Representation asks whether the answer gets your name, offer, audience, capabilities, limitations, and differentiators right.
    • Influence asks whether the answer changed a buyer’s shortlist, confidence, objections, or decision.
    • Attribution connects that influence to a lead, purchase, renewal, or another business result with an explicit level of confidence.
    • Trust determines whether a buyer accepts the recommendation. It must be earned with evidence; it cannot be inferred from an appearance alone.

    This distinction matters because appearing in an answer can be surprisingly easy. Self-promotional pages placing their publisher first on a best-provider list have surfaced quickly in AI recommendations. That demonstrates retrievability, not independent authority or buyer confidence. A screenshot of the result is therefore evidence that an answer engine found the page. It is not evidence that a prospect believed it, clicked it, or bought anything.

    Prompt-tracking totals also require restraint. API responses and answers shown to real users can differ sharply; one comparison found overlap as low as 24% in some cases. Interfaces can vary by model, account state, location, available retrieval, and the wording or history of a conversation. Use automated tracking to find patterns, but verify commercially important prompts in the live products your buyers actually use.

    A practical AI-search scorecard should consequently report accuracy and influence beside visibility. If the brand appears often but is described incorrectly, you have exposure without control. If qualified prospects repeatedly name AI as a decision aid despite few referral clicks, you have influence that last-click analytics cannot see.

    Measure the journey at the answer, buyer, and business layers

    A three-tier illustration connects an AI answer environment, a shopper comparing products, and business outcomes such as checkout and customer retention.

    No single tool can measure AI-search attribution end to end. The answer may be generated before a visit, the visit may occur through another channel, and the commercial effect may appear as a shorter evaluation rather than an extra conversion. Build one evidence chain from three layers instead.

    Inspect the answers buyers are likely to see

    Start with prompt families tied to real decisions, not a long list of ways to ask for your brand by name. Branded prompts test whether AI knows you; unbranded and comparative prompts test whether it would introduce you when a buyer has not chosen a vendor.

    • Problem discovery: How can I solve [specific problem]?
    • Category selection: What type of product or provider is suitable for [use case]?
    • Shortlisting: Which providers should I consider for [need and constraint]?
    • Comparison: How do [brand] and [alternative] differ for [use case]?
    • Risk validation: What are the limitations, implementation requirements, or reasons not to choose [brand]?
    • Brand facts: Does [brand] provide [capability], work with [system], or serve [audience]?

    Test the same core prompts in the live interfaces relevant to your market, such as ChatGPT, Perplexity, Gemini, and Google AI Overviews. Record the exact prompt, interface, model when visible, account state, date, answer, cited URLs, and follow-up context. Do not quietly rewrite a prompt until your brand appears; that measures your ability to steer a test, not ordinary buyer discovery.

    For each answer, capture whether the brand was mentioned, recommended, cited, or omitted. Then score factual claims individually. Mark a claim as accurate, incomplete, outdated, unsupported, or wrong. Preserve the answer itself so that a later correction can be compared with a real baseline.

    Ask buyers about discovery and influence separately

    A single form field asking how someone heard about you cannot represent a multi-channel decision. The place where a buyer first encountered the brand may differ from the place that validated it. Ask two separate questions:

    1. Where did you first hear about us? This preserves the discovery channel.
    2. What helped you decide to contact or buy from us? This captures influence during evaluation.

    Allow more than one response to the second question and include an AI assistant option. Keep a free-text field because buyers may name ChatGPT, Perplexity, Gemini, Grok, Google AI Overviews, or simply say they asked AI. If they remember it, ask what they wanted to learn. The prompt topic is often more useful than the platform name because it reveals the decision or objection your content helped resolve.

    Do not force the buyer to choose between AI, search, social, email, and word of mouth when several played different roles. Store discovery source and decision influence as separate CRM properties. Preserve the buyer’s own wording in a note rather than translating every answer into a generic AI lead label.

    Look for commercial effects beyond referral traffic

    AI can summarize alternatives, reduce uncertainty, and help form a shortlist before the buyer visits a vendor. Its commercial contribution may therefore appear in the sales process rather than the acquisition report. Compare AI-influenced opportunities with other qualified opportunities on:

    • Time from qualified lead to the next meaningful stage.
    • Time from qualified lead to closed outcome.
    • How much basic education the buyer needs.
    • The number and type of objections raised.
    • Whether the buyer arrives with a shortlist already formed.
    • Conversion by stage, deal value, and final outcome.
    • The content or claim the buyer cites as reassurance.

    Business observations have found that some AI-influenced leads needed less education and closed faster. Treat that as a hypothesis to test in your own pipeline, not a universal benchmark. A shorter sales cycle might reflect AI-assisted preparation, but it could also reflect deal type, buyer seniority, budget, or an existing relationship.

    Measurement layerEvidence to captureQuestion it can answerWhat it cannot prove alone
    AnswerLive outputs, citations, factual accuracy, recommendation language, competitor contextCan the system find and represent the brand?Whether a buyer saw or trusted the answer
    BuyerDiscovery response, decision-influence response, named assistant, remembered questionDid AI contribute to consideration?The exact share of influence attributable to AI
    BusinessStage timestamps, objections, education needs, conversion, value, outcomeDid AI-influenced opportunities behave differently?That AI caused the difference without controlling for other factors

    Apply confidence labels instead of pretending every signal is deterministic. Mark attribution as confirmed when the buyer explicitly names AI’s role, supported when self-report and sales evidence agree, and possible when you only see an indirect pattern such as rising branded demand. Keep possible influence out of confirmed revenue totals.

    Give AI a canonical record of your brand

    Measurement tells you where the brand is missing or distorted. Correction requires a dependable record that retrieval systems can access and reconcile. Without specific evidence, an AI system may fill gaps from generic category patterns, scattered third-party descriptions, or outdated pages. That failure is often called brand drift.

    Do not treat a canonical record as one oversized About page. Build a controlled set of public pages and media in which every important claim has a clear home, a responsible owner, and a visible update path.

    1. Create a brand-facts register. Record the official name, offer, intended audience, primary use cases, supported capabilities, known constraints, service area, public pricing conditions, integrations, and expert identities. Add the canonical URL and owner for every fact.
    2. Resolve contradictions before publishing more content. Check product pages, help content, business profiles, executive biographies, video transcripts, partner listings, and public profiles. If several versions of a claim remain live, an answer engine has no reliable way to know which one you prefer.
    3. Assign facts to decision-focused pages. Give capabilities, limitations, comparisons, implementation requirements, policies, and expert credentials their own clear context. Put the direct answer near the start, then provide evidence and qualifications.
    4. Make entity relationships explicit. Use applicable Schema.org types such as Organization, Product, Service, Person, ProfilePage, and VideoObject. Connect the organization, offer, author, expert, and media with consistent identifiers and relevant properties. Structured data must match visible content; markup cannot rescue an unsupported claim.
    5. Maintain the record. When an offer changes, update the canonical page, structured data, transcript, profiles, and sales material as one release. Leaving the old version on a high-authority page invites the error to return.

    Use video when the claim benefits from observable evidence

    Text is appropriate for definitions, specifications, and policies. Video becomes especially useful when a buyer needs to see a real product, process, location, result, or subject-matter expert. It combines spoken explanation, visual context, and a transcript, creating a dense record that can be republished without changing the underlying claim.

    Plan the recording around likely misrepresentation. If AI repeatedly invents a feature, have the responsible expert show what the product actually does, state the boundary plainly, and explain the correct workflow. Publish the video on a relevant canonical page with a descriptive title, an edited transcript, speaker identity, supporting links, and VideoObject markup. A transcript should preserve qualifications rather than turning a careful explanation into an absolute promise.

    Where your production workflow supports it, retain C2PA-compatible Content Credentials and editing history. Cryptographic provenance can help establish where media came from and whether its recorded chain has been altered. It does not prove that every statement in the media is true, so pair provenance with named expertise, visible evidence, and claims a buyer can verify.

    Repurpose the same evidence into an article, short clips, images, audio, FAQs, and social posts. Keep the central facts and qualifiers consistent across formats. The purpose is not to manufacture a larger content count; it is to give retrieval systems several accessible paths back to the same coherent brand record.

    Build the evidence that earns a recommendation

    Accuracy can make your brand eligible for consideration. Evidence makes it defensible to recommend. This is where self-authored best-provider pages reach their limit: they can state a position, but the publisher and beneficiary are the same entity.

    Build content around the questions a cautious buyer asks after discovery. The strongest page is not always the one that praises the brand most. It is often the one that makes the decision criteria, tradeoffs, and evidence easiest to inspect.

    • Selection criteria: Explain how a buyer should evaluate the category before naming products. Define the conditions that change the choice.
    • Use-case fit: State who the offer is for, what problem it addresses, and the prerequisites for success. Include who should choose another route.
    • Comparison: Use explicit criteria and equivalent evidence for each option. Distinguish verified facts from your interpretation, and date claims that may change.
    • Implementation: Show the required inputs, responsible roles, dependencies, and limits. This helps answer engines distinguish a real capability from an effortless marketing promise.
    • Proof: Connect each material claim to a demonstration, documented example, methodology, policy, or qualified expert. Avoid decorative statistics that do not prove the claim beside them.
    • Independent corroboration: Earn accurate reviews, mentions, citations, and expert coverage on relevant third-party properties. Correct factual errors at their origin rather than merely publishing another contradictory claim on your own domain.

    Clarity is part of authority. If your homepage describes the offer with a creative slogan while product pages, profiles, and interviews use different category language, both buyers and machines must infer what you actually sell. Keep the positioning distinctive, but repeat the plain category, audience, and use case consistently wherever identification matters.

    Maintain an AI-error register alongside your content inventory. For every observed error, save the prompt and answer, identify the false or missing claim, note the cited page if one appears, assign a canonical correction URL, and track the content change. Prioritize errors about core capabilities, compatibility, availability, pricing, or suitability before cosmetic wording differences. Those errors can change a purchase decision.

    Retest after correction, but expect variation. A changed answer does not prove permanent removal, and one unchanged answer does not prove the correction failed. Look for a repeated pattern across live sessions and interfaces while continuing to strengthen the public evidence.

    Run one operating loop from prompt to sale

    A circular pathway links an abstract question, AI discovery, source documents, buyer evaluation, a purchase parcel, and a feedback lens around an unbranded product.

    AI visibility, brand accuracy, content operations, and revenue measurement should not live in separate projects. Run them as one loop attached to a real buyer decision.

    1. Select a commercially important decision. Choose a problem, comparison, risk, or capability question that can affect whether the buyer includes you.
    2. Capture a live baseline. Test the associated prompt family and preserve the answers, citations, omissions, and errors.
    3. Diagnose the evidence gap. Decide whether the problem is missing information, contradictory facts, weak proof, unclear entity relationships, or inadequate third-party corroboration.
    4. Improve the canonical evidence. Update the responsible page, visible copy, schema, transcript, media, and linked supporting material.
    5. Distribute without changing the claim. Adapt the evidence to relevant channels while retaining the same facts and qualifications.
    6. Retest comparable live conditions. Use the original prompts as controls, then inspect natural variations and follow-up questions.
    7. Connect the change to buyer evidence. Review self-reported influence, sales notes, objections, stage movement, and outcomes. Do not substitute a visibility gain for a commercial result.
    8. Record the decision. Continue, revise, or stop the tactic based on accuracy, qualified influence, and business value rather than the most flattering screenshot.

    Key takeaways

    • AI visibility shows that a brand can be retrieved; it does not prove trust, influence, or revenue.
    • Verify important prompts in live interfaces because automated and API outputs may not match what buyers see.
    • Ask where a buyer discovered you and what influenced the decision as separate questions.
    • Measure sales-cycle behavior, objections, and education needs alongside clicks and conversions.
    • Prevent brand drift with consistent canonical facts, decision-focused pages, accurate structured data, expert evidence, and useful video.
    • Use confidence labels for attribution so confirmed buyer evidence is not mixed with indirect signals.

    Start with one question that can put your brand on or off a buyer’s shortlist. Capture what the major live interfaces say, correct the public evidence, and add the two attribution questions to your CRM. That gives you a defensible first line from AI answer to buyer decision – and a system you can expand without pretending every mention is a sale.

    References

  • Automated B2B Lead Generation: Build a Quality Feedback Loop

    Automated B2B Lead Generation: Build a Quality Feedback Loop

    You probably do not need another lead generation tool. If your automated campaigns produce cheap form fills that sales rejects, the system is working exactly as instructed: it has learned that submitting a form is the outcome that matters.

    The fix is to give automation a visible path from early interest to qualified pipeline, then make each campaign optimize for one stage of that path. You can scale from there without mistaking activity for demand.

    Fix the objective before you automate the campaign

    B2B automation has a signal problem. A purchase platform can often see an order, its value, and the ad that produced it within a short period. B2B campaigns may generate fewer conversions, lack an immediate transaction value, and feed a sales process that can continue for more than a year.

    The bidding system cannot infer what happened in your CRM unless you send that information back. Left alone, it will favor the observable event it receives most frequently. That is usually the form submission, regardless of whether the person used a personal email address, fell outside your service area, represented the wrong company size, or never progressed beyond the first sales review.

    Before changing bids, audiences, creative, or campaign types, answer four questions:

    • What is the deepest business outcome you can reliably connect to the originating campaign?
    • How consistently does your team apply that lifecycle stage in the CRM?
    • How long does it take for that outcome to appear?
    • Which earlier event is the best available proxy while the deeper outcome is still pending?

    Your ideal optimization event is not automatically the final sale. A closed deal may be economically meaningful but too delayed or infrequent to guide every campaign. A marketing qualified lead may be available sooner, while an accepted opportunity may carry a stronger connection to revenue. Choose the deepest stage that is both trustworthy and repeatable, then continue importing later outcomes for measurement.

    Do not judge this system on lead count alone. Review the number of leads, the share becoming qualified, the opportunities created, and the deals closed. One documented implementation reported a 150% increase in leads, a 350% increase in opportunities, and a 200% increase in closed deals. That is a single case result, not a benchmark, but the uneven movement across stages makes the important point: top-of-funnel volume and downstream value do not necessarily rise at the same rate.

    Build the CRM-to-ad feedback loop first

    An isometric system sends lead signals between business contacts, organized customer records, and an advertising engine, with bright qualified signals returning through the loop.

    Offline conversion tracking is the foundation of automated B2B acquisition. Your ad platform needs to learn when an online inquiry becomes a qualified lead, an opportunity, or a customer. Google Ads Data Manager provides integration paths involving HubSpot and Salesforce, as well as custom workflows using systems such as Snowflake and Zapier.

    The connector matters less than the integrity of the lifecycle data moving through it. A fast integration will only automate confusion if sales and marketing use the same CRM stage for different situations.

    1. Define each stage in operational terms. State what must be true before a contact becomes a marketing qualified lead, sales-accepted lead, opportunity, or closed deal. Avoid definitions based on intuition alone.
    2. Assign one owner to each transition. Decide whether marketing automation, a sales representative, or another system changes the stage. Conflicting updates make imported outcomes unreliable.
    3. Preserve the acquisition connection. The downstream CRM record must remain traceable to the campaign interaction that created it. If that connection disappears during routing, enrichment, or deduplication, the ad platform cannot learn from the result.
    4. Exclude invalid records before importing value. Spam, tests, duplicates, existing customers, job seekers, vendors, and other non-prospects should not teach the bidding system what to find next.
    5. Validate a sample from end to end. Compare the campaign record, form record, CRM contact, lifecycle change, and imported conversion. Check both successful imports and records that should have been excluded.
    6. Document the delay. Record how long qualification and opportunity creation normally take in your process. A recent campaign can look weak simply because its downstream outcomes have not matured yet.

    Give early intent a weighted vote, not control of the account

    Micro conversions can help when qualified outcomes are sparse or delayed. The important move is to assign relative values that express the difference between curiosity and commercial intent. One workable example uses values of 1 for a video view, 10 for an asset download, 100 for a form fill, and 1,000 for a marketing qualified lead.

    EventExample relative valueWhat it tells the systemHow to treat it
    Video view1The visitor showed initial interestUse as a weak supporting signal, not proof of demand
    Asset download10The visitor exchanged attention for useful materialUse as a stronger engagement signal, while checking whether the asset attracts your ideal buyer
    Form submission100The visitor initiated direct contactCount it as intent, but separate valid prospects from spam and poor-fit inquiries
    Marketing qualified lead1,000The record passed an agreed qualification ruleUse as a primary quality signal when the CRM stage is reliable

    These are utility points, not universal prices. Do not label them as revenue or report a value-based bid result as financial return on ad spend unless the values actually represent money. Their purpose is to tell the optimizer that one qualified lead should matter far more than one video view.

    Review how much total conversion value each event contributes. A low-value event can still dominate if it happens often enough. If video views or downloads create most of the recorded value, the campaign may learn to buy abundant engagement instead of scarce business intent. Reduce the shallow event’s value, remove it from the campaign’s optimization goal, or keep it for observation only.

    Also control repeated actions. One person replaying a video, downloading several files, or submitting the same form twice should not automatically look more valuable than a newly qualified account. Your counting rules, deduplication, and CRM logic must reflect the business event you actually want to reproduce.

    Make every campaign do one job

    An account-wide list of conversion actions is not a strategy. If the same campaign is rewarded for video engagement, downloads, inquiries, and qualified leads without a clear hierarchy, the easiest event can overpower the event that matters.

    Use campaign-specific goals to match optimization to the campaign’s role:

    • Awareness and audience development: measure video engagement or content interaction, but do not let those actions steer a high-intent acquisition campaign.
    • Mid-funnel demand capture: optimize for a meaningful form submission when qualification data is not yet frequent or timely enough.
    • Warm-audience acquisition: optimize toward the qualified lead event when the audience, offer, and CRM feedback can support it.
    • Pipeline-focused campaigns: use opportunity or revenue values when those offline outcomes are accurate enough to guide bidding.

    This separation also makes diagnosis easier. If an awareness campaign produces inexpensive views but no later demand, you can question the audience or message without contaminating the performance signal of a campaign designed to generate qualified inquiries.

    Low volume does not always require collapsing every initiative into one campaign. When several campaigns serve similar buyers and pursue the same conversion goal, portfolio bidding can combine their data. It is particularly useful when separate campaigns struggle to reach the commonly cited 30-conversion-per-month threshold. Portfolio strategies can also provide a maximum cost-per-click cap, which helps limit runaway bids.

    Only pool campaigns whose economics and objectives belong together. Combining a high-value enterprise offer with a low-value self-service offer may produce more data, but the shared strategy will be learning from two different businesses. More observations do not help when they describe incompatible outcomes.

    Your first-party CRM data should also shape targeting. Customer lists can support exclusions when acquisition campaigns should not spend on current customers. Contact and prospect lists can be used for observation, direct targeting, or audience signals where the campaign type permits. These lists give broad, AI-driven campaigns a concrete description of the people and accounts you already recognize.

    Performance Max is not automatically unsuitable for B2B lead generation. It becomes a defensible test after you have reliable offline outcomes, sensible conversion values, a campaign-specific goal, and useful first-party signals. A Target ROAS strategy can then optimize toward recorded customer value instead of treating every conversion as equivalent. If you use relative utility points rather than monetary values, remember that the resulting ROAS is an optimization ratio, not an accounting measure.

    Use AI where mistakes are visible and reversible

    AI can shorten research, organization, and drafting work, but it cannot repair a missing feedback loop. Put it on bounded tasks whose outputs a marketer can inspect before they affect bids, budgets, exclusions, or customer communication.

    Start with a reusable context brief. Include your offer, differentiators, target personas, ideal client profile, buying roles, disqualifiers, and approved claims. Explicitly state that the customer is another business; that B2B instruction changes the frame of the response and reduces the chance of receiving consumer-oriented ideas.

    Prompt skeleton: You are supporting B2B demand generation for [company]. We sell [offer] to [ideal client profile]. The buying group includes [roles]. Our differentiators are [approved claims], and we do not serve [disqualifiers]. Complete [task]. Separate verified inputs from inferences, identify missing information, and do not invent competitor claims or customer evidence.

    That context can support several practical workflows:

    • Competitor analysis: organize known offers, positioning, value propositions, and customer sentiment into a consistent matrix. Require a traceable input for every factual claim and leave unsupported cells blank.
    • Keyword gap review: give AI an export from a tool such as Semrush and ask it to separate terms competitors cover, terms you already lead on, and recurring themes that may deserve their own campaigns.
    • Search-term triage: classify terms as relevant, irrelevant, or ambiguous. A human should review ambiguous cases and approve negative keywords before they are applied.
    • Ad-copy drafting: request variations tied to a named persona, problem, offer, and approved proof point. Treat every line as a draft that still needs factual and policy review.
    • Reporting support: summarize anomalies and prepare questions for investigation. Google Ads also provides pre-built automation solutions for reporting, anomaly detection, and keyword-list creation, although complex enterprise accounts need careful validation before broad use.

    Keep consequential decisions outside a fully automatic chain until you trust the inputs and failure modes. A mistaken theme label is easy to correct. An automatically applied negative keyword can suppress qualified demand, while an unverified competitor claim can create reputational or legal exposure. Let AI propose; require an accountable person to approve.

    Use controlled experiments for bid strategies, match types, and landing pages. Write the hypothesis and success measure before launch. If you change the audience, bid strategy, offer, creative, and page at once, even a positive result will not tell you which decision to repeat.

    Roll out automation in an order you can audit

    Three transparent workstations show automation expanding from one inspected mechanism to a larger system monitored by two analysts, with checkpoints between stages.

    You do not need to rebuild the whole account at once. Start with one meaningful campaign and make its data path trustworthy before expanding the design.

    1. Select the downstream outcome. Choose the deepest lifecycle stage that is consistently recorded and still occurs often enough to inform the campaign.
    2. Write the qualification rule. Make the rule specific enough that two team members would classify the same record the same way.
    3. Connect the CRM outcome. Import the offline event and verify that it connects to the correct campaign interaction.
    4. Add a restrained value ladder. Give early actions lower relative values and the qualified outcome a clearly dominant value.
    5. Set the campaign-specific goal. Remove unrelated actions from the campaign’s optimization objective, even if you continue measuring them elsewhere.
    6. Add relevant first-party data. Exclude existing customers where appropriate and use qualified contact lists as targeting or audience signals.
    7. Consider portfolio bidding. Pool only campaigns with compatible goals and economics when each one lacks sufficient conversion volume on its own.
    8. Test broader automation. Introduce Performance Max, Target ROAS, broader matching, or another automated feature only after the outcome data is dependable.
    9. Automate repetitive analysis. Use AI and platform solutions for drafts, classifications, reports, and anomaly alerts, with human approval for consequential changes.
    10. Review the full funnel. Compare lead volume, qualification, opportunities, closed deals, and the share of recorded value coming from each conversion action.

    Key takeaways

    • Automated B2B lead generation improves when the ad platform can distinguish an inquiry from a qualified business outcome.
    • Offline CRM conversions should carry more authority than abundant micro conversions.
    • Relative values must reflect intent hierarchy and should not be presented as revenue unless they represent actual money.
    • Campaign-specific goals prevent easy engagement events from steering pipeline-focused campaigns.
    • AI is most useful for inspectable research, classification, drafting, and reporting tasks; it should not silently approve high-consequence changes.

    Your next step is small: choose one campaign, one qualified CRM stage, and one imported offline event. Trace a real record through that loop. Once the campaign can tell the difference between a completed form and a viable prospect, additional automation has something worth scaling.

    References