Tag: Attribution Models

  • Google Commerce Discovery and In-Search Checkout Strategy

    Google Commerce Discovery and In-Search Checkout Strategy

    You may be optimizing product pages for the click while Google is redesigning shopping around a different outcome: identify a suitable product, validate the choice, and potentially complete the purchase inside AI Mode or Gemini. That changes where ecommerce visibility is won.

    You now need two connected systems. The first makes your catalog understandable and competitive during AI-assisted discovery. The second lets an approved product move through an in-search transaction without introducing price, availability, identity, or payment failures. Here is how to prepare both without confusing checkout access with search visibility.

    The new commerce funnel starts in the product graph
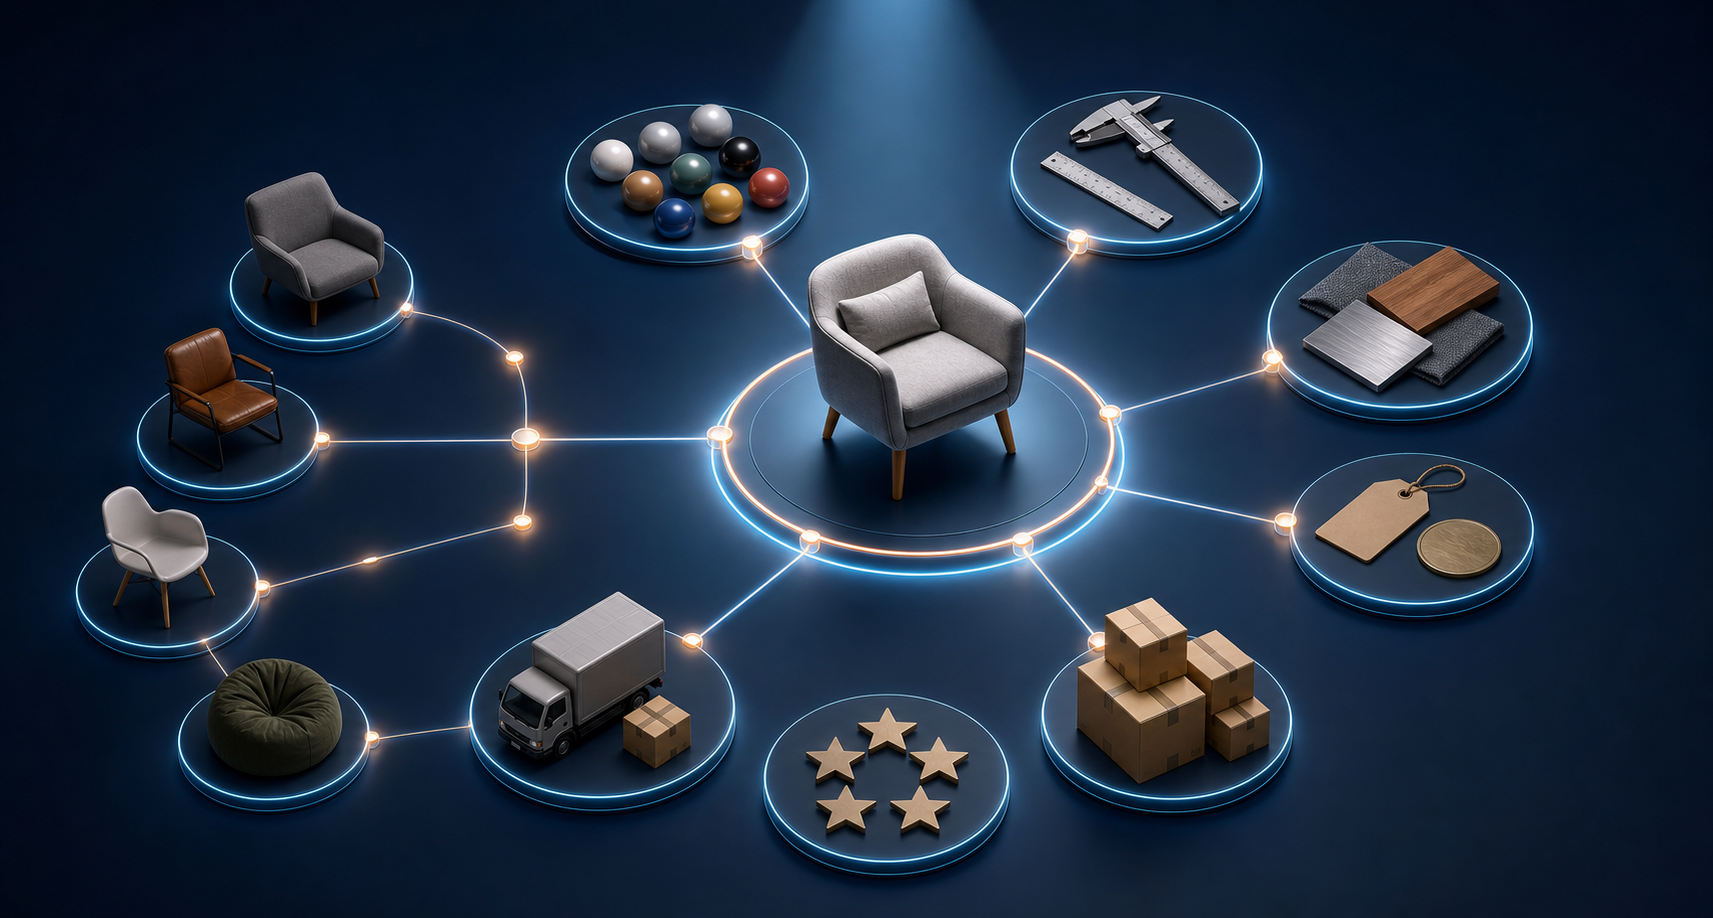
    A generic product sits at the center of a connected network of attributes, inventory, reviews, shipping, and related items.

    A conventional SEO funnel assumes that search earns a click, the product page creates confidence, and the merchant site completes the sale. Google’s emerging commerce model can compress those stages. A user may describe a need conversationally, receive product recommendations, compare options, and check out without following the familiar sequence of search result, landing page, cart, and checkout.

    The catalog is therefore more than a paid advertising input. Google’s Shopping Graph contains more than 50 billion product listings and supplies product information to AI Overviews, AI Mode, and Gemini. If your product record is incomplete, ambiguous, or inconsistent, strong product-page copy may never get the chance to influence the shopper.

    This is already relevant to organic discovery, not merely a future checkout project. AI Overviews appeared in about 14% of observed shopping queries, up from roughly 2% in late 2024. A Peec AI analysis also found that up to 83% of products in sampled ChatGPT carousels reflected Google’s organic Shopping results, with 60% of those matches coming from positions 1 through 10. That analysis is useful directional evidence, not proof that every assistant, market, or query follows the same pattern. It does show why Merchant Center data belongs in your AI search strategy.

    Commerce layerQuestion it must answerTypical failure to prevent
    Product feedIs this product a relevant match for the request?Generic titles, missing identifiers, weak attributes, or unusable images make the product hard to match and compare.
    Product pageDo the details support the product record and the buyer’s decision?The page and feed describe different variants, benefits, prices, or availability.
    Commerce integrationCan the selected product be purchased successfully in the Google experience?The discovery record cannot be resolved to the correct variant, checkout state, identity, or payment flow.

    Use those layers to triage problems correctly. Low discovery visibility is usually a matching and data-quality problem before it is a checkout problem. A visible product that cannot complete a transaction is an integration problem. A product that earns attention but not purchases may have a merchandising, offer, or expectation problem. Putting every weak result under the label of SEO hides the part that actually needs work.

    Make the product feed an organic discovery asset

    Many merchants let the paid media team own the only feed. That arrangement keeps campaigns running, but a feed shaped around bid relevance and advertising conventions is not automatically the best representation of how people search organically. Paid and organic outputs can share a catalog while applying different rules to titles, descriptions, and supporting attributes.

    Build records around the language of product selection

    The title is your highest-priority matching field. Write it so a person can identify the product without seeing the image or visiting the page. Start with the product type and add the attributes that genuinely distinguish the item, such as brand, material, capacity, size, color, compatibility, or intended use. The useful combination depends on the category. Do not force every possible modifier into every title, and do not repeat words merely to make the record longer.

    A good test is to compare the title with the phrases a buyer would naturally use when narrowing a choice. If shoppers distinguish your products by capacity and compatibility, those attributes deserve more attention than internal collection names. If the title could apply equally to many products in your own catalog, it is probably too vague for an AI system to select confidently.

    • Use accurate GTINs where the product has them. Correct identifiers help Google match identical products, combine relevant information such as reviews, and understand that two differently worded listings refer to the same item. Well-matched products with accurate GTINs can receive up to 40% more clicks. Never invent an identifier or reuse one from a different variant.
    • Supply both clear standard images and useful lifestyle images. The standard image should make the product easy to identify. A lifestyle image should add context, scale, or use information rather than obscure the item. Image problems can also cause Merchant Center disapprovals, so treat asset validation as feed health, not decoration.
    • Use product_highlight for concise buyer benefits. Replace empty claims such as high quality with concrete outcomes. A statement about handling light rain during a commute tells the buyer more than an unsupported adjective.
    • Use product_detail for structured specifications. Put filterable facts such as dimensions, material, capacity, and compatibility into the structured field that represents them. Do not bury every decision-critical fact in prose.
    • Keep the feed and product page synchronized. A refined feed title cannot compensate for a page that represents a different variant, price, feature set, or availability state. The two surfaces should describe the same purchasable product.

    Create a controlled organic output

    You do not need two unrelated catalogs. You need one reliable product source and a controlled way to publish an organic-oriented output without letting paid campaign conventions overwrite it. Depending on your commerce stack, that may be a dedicated feed or a dedicated set of transformation rules. Either way, document which fields are canonical, which fields may vary by channel, and who approves each change.

    The potential impact is material, but it should not be treated as a guaranteed benchmark. In one major ecommerce implementation, an organic feed produced a 10% month-over-month increase in organic listing click-through rate and a 4% increase in purchase rate. A product-level test recorded 92% higher free-listing revenue, 83% more visibility, and a 14% increase in add-to-cart rate. Another organic optimization set generated 35,000 impressions at a 1.4% click-through rate, which was 55% above the paid click-through rate for the same period. Those results establish that feed changes can be commercially important; they do not establish a universal lift for every catalog.

    Run your own controlled evaluation:

    1. Select a coherent product group with enough existing activity to measure.
    2. Record its free-listing impressions, click-through rate, add-to-cart rate, purchase rate, and revenue before changing the feed.
    3. Change one field family at a time when practical. A title test is easier to interpret if you do not simultaneously replace every image and description.
    4. Keep a version log that connects each feed change to the affected product IDs.
    5. Compare product-level outcomes, not only catalog-wide averages. A large category can conceal both strong winners and harmful rewrites.
    6. Check paid performance separately. An organic improvement does not prove that the same wording should replace a paid title optimized for a different matching and bidding context.

    The goal is not to make the organic feed sound conversational at any cost. It is to make the product record precise in the language buyers use while preserving exact identifiers, specifications, and variant distinctions.

    Prepare for UCP without mistaking checkout for ranking
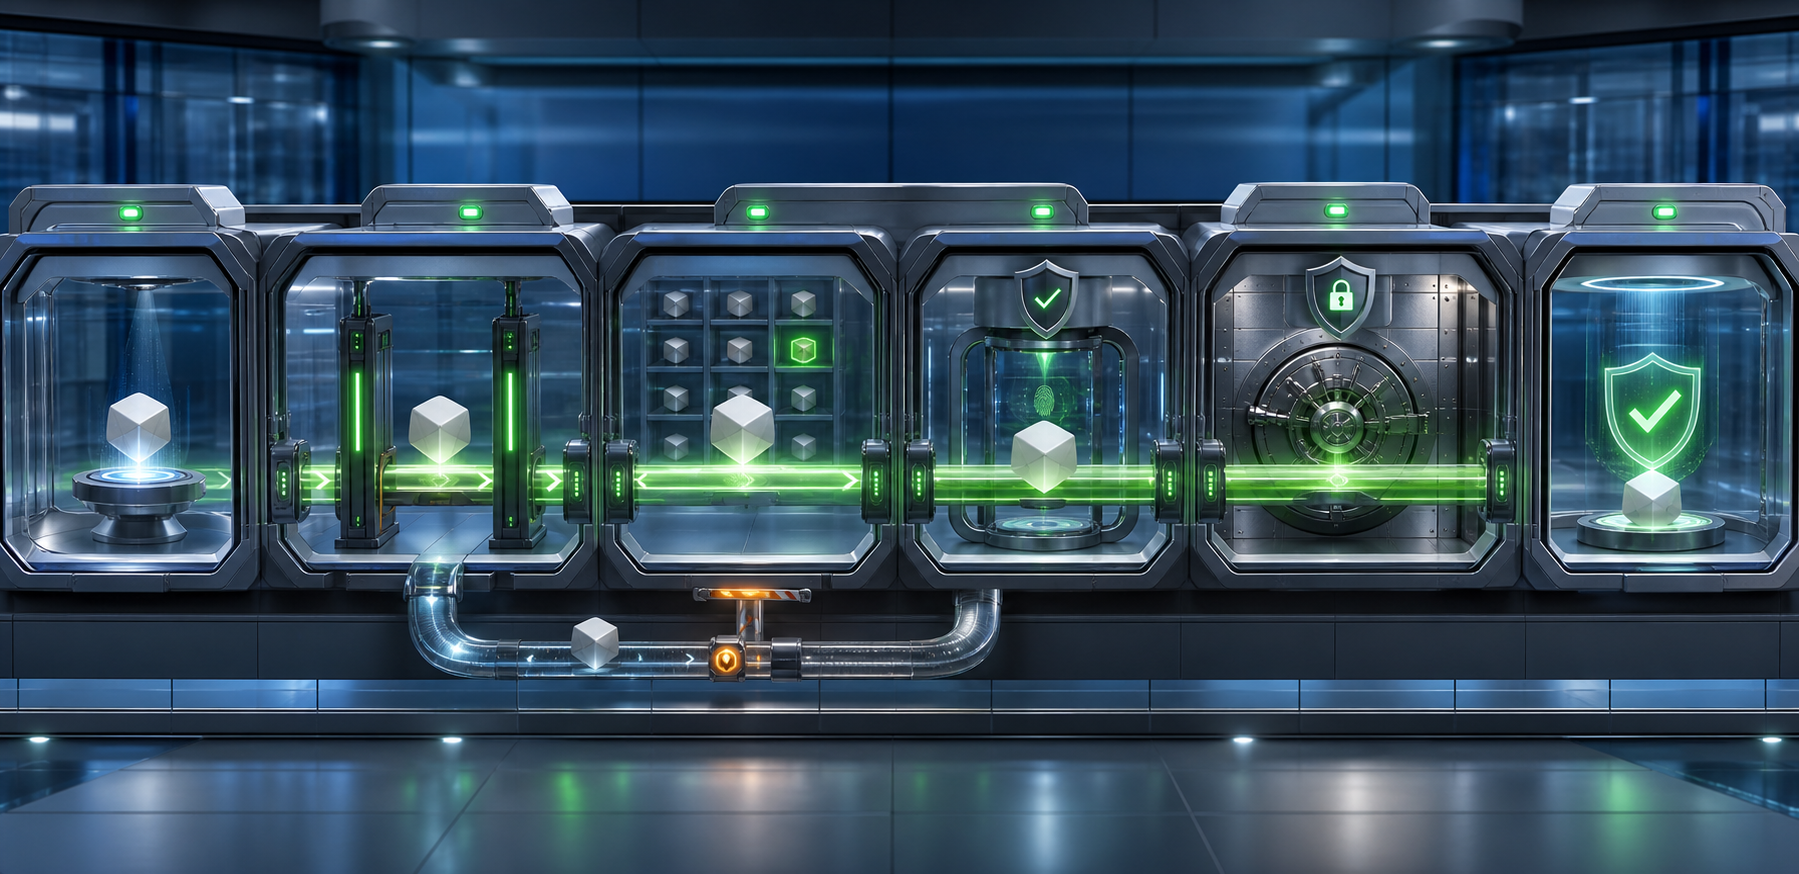
    A product moves through connected price, inventory, identity, payment, and confirmation checkpoints in an abstract checkout system.

    Google’s Universal Commerce Protocol, or UCP, connects product data, user identity, payment flows, and checkout so eligible purchases can be completed from product listings in AI Mode and Gemini. The initial rollout is gradual and U.S.-limited. Merchants must complete a technical integration, submit an interest form, receive approval, and then use Merchant Center onboarding tools.

    Approval opens a transaction path; it does not establish a search-ranking benefit. Treat discovery eligibility and transaction readiness as separate workstreams unless Google explicitly documents a connection. A product still needs strong, consistent data to be selected. UCP then addresses whether the selected item can move through checkout inside the Google experience.

    Google has also added a native_commerce attribute for UCP-powered purchase buttons. Do not treat that attribute as a shortcut around integration quality. A buy button attached to stale price, availability, or variant data creates a more immediate failure than a conventional listing because the shopper is already trying to transact.

    1. Confirm the access path. Check Merchant Center for UCP onboarding availability and follow the interest and approval process. Do not promise a launch date internally until the account has access.
    2. Assign a catalog system of record. Every purchasable variation needs a stable mapping between the feed record and the item your checkout can fulfill. Resolve duplicate identifiers and unclear parent-variant relationships before transaction testing.
    3. Map the checkout data contract. Identify which system owns product identity, selected variant, price, availability, buyer identity, payment state, and transaction outcome. Document how a change in one system reaches the others.
    4. Use the available sandbox. Merchant Center onboarding includes a testing sandbox, identity linking, and checkout APIs. Test successful transactions as well as unavailable products, changed prices, unresolved identities, declined payments, and interrupted requests.
    5. Define operational ownership. SEO can improve matching, but commerce, engineering, privacy, security, payment, and customer-support owners need responsibility for the parts they control. Decide who pauses native checkout when catalog or transaction data becomes unreliable.
    6. Activate only after reconciliation. The feed, product page, commerce system, and transaction response must resolve to the same product and offer. If they do not, keep the safer redirect-based journey until the mismatch is fixed.

    This is where cross-team collaboration becomes practical rather than ceremonial. SEO contributes query language and matching logic. Commerce owns product truth and fulfillment constraints. Paid media teams often understand feed tooling and disapproval management. Engineering owns the integration path. Each team should have a named field or state to maintain, not a general instruction to support AI commerce.

    Measure discovery and checkout as one journey, not one metric

    In-search checkout weakens the old assumption that a successful search interaction produces a website session. When a customer can purchase inside an AI interaction without being redirected to the merchant site, traffic alone becomes an incomplete measure of both SEO and commerce performance.

    Build a measurement chain that follows the product as far as your available data allows:

    1. Catalog health: Track active products, rejected or disapproved items, identifier coverage, image issues, and unresolved feed-page discrepancies. A product excluded before matching cannot generate a meaningful visibility or conversion signal.
    2. Discovery: Track impressions and click-through rate by product, product group, query class, and Google surface where those dimensions are available. Separate free listings from paid placements.
    3. Consideration: Track the interactions you can observe between a product impression and checkout. Keep website engagement separate from native interactions so a change in surface mix does not look like a sudden behavioral collapse.
    4. Transaction: Track checkout attempts, successful purchases, failures, and the product or variant involved. Preserve a reference that lets commerce and analytics teams reconcile the transaction with the originating product record.
    5. Business outcome: Compare completed orders and revenue with website sessions and site-based orders. A decline in site traffic is not automatically lost demand if more transactions are completing elsewhere. It is also not automatically good news; you need reconciled purchase data to tell the difference.

    Capture a baseline before enabling native checkout. After activation, segment results by surface and product group rather than comparing one blended total with the previous period. Otherwise, a shift from website checkout to Google checkout can be mistaken for an SEO loss, while a surge in product impressions can be mistaken for commercial growth without completed purchases.

    Document your attribution rule as part of the integration. Decide how you will classify a purchase discovered in AI Mode, completed through native checkout, and fulfilled by your commerce system. The rule matters less than using it consistently and making its limits visible. Do not allow SEO, paid media, and commerce dashboards to claim the same order independently.

    You should also watch for substitution. Native checkout may replace a transaction that would otherwise have occurred on your site, or it may capture demand that would have been lost through extra steps. Compare the full order picture rather than assuming every native purchase is incremental or every missing session represents cannibalization.

    Key takeaways

    • Google commerce visibility begins with product data, so Merchant Center feed quality is now part of organic and AI search optimization.
    • Optimize organic titles around the attributes buyers use to identify and distinguish products, while preserving accurate GTINs, specifications, images, price, and availability.
    • Use a dedicated organic feed or controlled organic transformation rules instead of forcing paid and free listings to share every optimization decision.
    • Treat UCP as a checkout capability, not a ranking shortcut. Discovery quality must be solved before native transaction readiness can help.
    • Prepare stable product mappings, clear system ownership, sandbox failure tests, and a safe way to pause native checkout when data becomes unreliable.
    • Measure catalog health, discovery, transaction outcomes, and total orders together because website sessions no longer represent the entire shopping journey.

    Start with a catalog reconciliation, not a checkout build. Choose a representative product family and align its titles, identifiers, attributes, images, page details, price, and availability. Then name the owner of every field and transaction state. That work improves discovery whether or not UCP access has reached your account.

    When access becomes available, take the same reconciled products through the sandbox before expanding. You will learn more from a small group with traceable data and observable failures than from activating native checkout across a catalog whose product truth is still disputed.
    References

  • AI Search Visibility When Referrals and Rankings Diverge

    AI Search Visibility When Referrals and Rankings Diverge

    If your organic sessions are falling while your brand still appears in AI answers, you do not have one visibility problem. You have at least three: whether machines can access your content, whether answer systems select it, and whether people visit after seeing it.

    Those stages need different measurements and different fixes. Separate them, and you can tell whether to improve a page, investigate a ranking change, strengthen attribution, or restrict a crawler before it consumes more value than it returns.

    Key takeaways

    • Measure content access, AI mentions and citations, referral sessions, and business outcomes separately. A lost click is not automatically lost visibility.
    • Diagnose impressions, rankings, click-through rate, and AI referrals before editing content. Ranking loss and referral loss can happen together, but they are not the same failure.
    • Give answer systems a clear, supportable answer while giving people a practical reason to visit, such as a workflow, template, decision tool, original data, or implementation detail.
    • Classify bots by identity and business role. Allow, rate-limit, license, challenge, or block them according to their value, cost, and contractual status.

    Build a visibility ledger that follows the whole journey

    An isometric table shows a document moving through connected access, selection, citation, and visitor stages.

    Sessions used to serve as a rough proxy for search visibility because discovery commonly led to a results page and then a click. An AI interface can now retrieve a page, use its information, mention its brand, cite its URL, and still satisfy the user without sending a visit. One traffic graph cannot show which of those events occurred.

    Use a ledger with three distinct stages:

    • Access: a search crawler, training crawler, or real-time fetcher can retrieve the page.
    • Selection: an answer system uses the information, mentions the brand, or links to the page.
    • Referral and value: the user visits, engages, subscribes, generates a lead, or completes another meaningful action.

    The distinction matters because the gap can be severe. Akamai measured application-layer traffic across websites, apps, and APIs from July through December 2025 and found AI bot activity up 300% during 2025. Within that analysis, AI-chatbot referrals delivered about 96% less traffic than traditional search, while only about 1% of users clicked sources cited in AI answers. Treat those figures as directional evidence, not universal benchmarks: your result will depend on your audience, query mix, business model, and the interfaces that expose your content.

    LayerRecordWhat a change can indicateFirst response
    Traditional search exposureImpressions, query, landing page, market, and average positionChanges in demand, ranking, eligibility, or query mixSegment the loss before changing pages
    Traditional search referralClicks, click-through rate, sessions, and landing-page outcomesA difference between being shown and being chosenInspect result presentation, search features, intent, and page promise
    AI selectionAccurate brand mentions, linked citations, cited URLs, and factual errors across a fixed prompt setWhether the brand is represented and whether an owned page receives attributionCheck entity clarity, answer structure, evidence, and page accessibility
    AI referralRaw referrer, channel, landing page, engagement, conversion, and revenue where availableWhether observed visibility produces visits and business valueImprove the post-answer reason to visit and the landing experience
    Machine-access costVerified agent identity, requests, pages fetched, bandwidth, cache use, and origin loadWhether retrieval consumes infrastructure without a corresponding benefitAllow, rate-limit, license, challenge, or block by bot class

    For AI selection, build a repeatable prompt panel rather than collecting convenient screenshots. Include the questions that matter at each stage of your customer’s decision, then preserve the exact prompt, interface, language, market, date, response, mention, citation, and cited URL. If you operate across languages or countries, maintain separate panels; visibility in one market does not establish visibility in another.

    1. Choose prompts from real search queries, support questions, sales objections, and tasks associated with your important pages.
    2. Run the same prompts under comparable conditions. Changing the wording and the interface at the same time makes the result difficult to interpret.
    3. Record an accurate mention separately from a linked citation. A brand can be visible without receiving an owned link.
    4. Check whether the answer represents the brand, product, author, and claim correctly. An inaccurate mention is not a visibility win.
    5. Annotate content releases, schema changes, crawler-policy changes, major deployments, and confirmed search updates beside the results.

    Create simple rates from this ledger: prompts with an accurate mention divided by prompts checked; prompts with an owned citation divided by prompts checked; and AI-referred conversions divided by identifiable AI-referred sessions. Keep the underlying counts beside every rate. A perfect percentage from a tiny or changing prompt set can create more confidence than the measurement deserves.

    Normalize recognizable AI referrers into a reporting channel, but preserve the raw referrer and landing page. Do not depend on campaign parameters for links you do not control. Some interfaces expose little or no useful referral information, so analytics should be treated as the observable portion of AI traffic, not a complete census of AI influence.

    Separate ranking loss from click loss before editing content

    A traffic decline near an algorithm update invites a quick rewrite. That can destroy useful evidence and change the page before you know what failed. Start by marking the rollout window. The March 2026 Google core update ran from March 27 through April 8, finishing after 12 days and 4 hours. A comparison that mixes rollout days with stable periods cannot cleanly separate the before and after states.

    1. Annotate the confirmed update window and every important site change, including migrations, template releases, internal-link changes, rendering changes, and crawler rules.
    2. Compare matched periods outside the rollout. Account for normal seasonality, promotions, and demand changes that affect the same queries.
    3. Segment by query group, page type, directory, market, and device. Sitewide averages can conceal a concentrated loss in one template or topic.
    4. Inspect impressions, position, clicks, and click-through rate together. Then compare those patterns with your sampled AI visibility and AI-referral data.
    5. Review the affected page group only after the failure mode is visible. Preserve an export or snapshot before making material changes so you can evaluate and reverse them.

    Use the pattern, not one metric, to choose the next action:

    • If impressions and positions decline for the same queries and pages, investigate a ranking, relevance, eligibility, or demand problem. Do not assume that a lower sitewide average tells you which one.
    • If impressions remain broadly stable while clicks and click-through rate decline, the result is still being shown but fewer searchers are choosing it. Inspect the result-page features, title and snippet promise, intent fit, and competing ways the query is answered.
    • If traditional search remains stable while sampled AI citations or identifiable AI referrals decline, check machine access, citation selection, brand ambiguity, and measurement coverage before rewriting the page.
    • If sessions decline but qualified leads, subscriptions, or revenue do not, quantify the commercial effect before setting a traffic-restoration target. Not every lost informational click has the same value.
    • If several layers decline at once, keep separate workstreams. A content review cannot repair broken bot access, and a crawler rule cannot make an unsatisfying page more useful.

    Google’s standing position is that a core-update decline does not necessarily mean something is wrong with the site, and meaningful recovery may depend on a later update. That is a reason to avoid panicked reversals, not a reason to wait passively. Review whether affected pages deliver helpful, reliable, people-first information, especially where the page promise and the actual answer have drifted apart.

    Create pages that can be cited and still deserve a visit

    Trying to withhold the basic answer is a poor response to zero-click search. It frustrates readers and leaves answer systems with weaker material to interpret. State the answer clearly, support it, and make the rest of the page valuable after the answer is known.

    A citation-ready, visit-worthy page usually needs these layers:

    • A decisive answer: address the page’s main question directly instead of making the reader extract it from a long preamble.
    • Scope and qualifiers: state the country, language, platform, version, date, audience, or conditions that change the answer. A technically correct statement can still mislead when its scope is hidden.
    • Evidence: connect important claims to their originating authority, underlying data, or documented method. Distinguish a fact from an inference or editorial recommendation.
    • Entity clarity: use consistent names for the organization, product, author, location, and service. Explain relationships that a reader should not have to infer from branding alone.
    • A decision layer: show trade-offs, applicability, exclusions, and common misreadings so the reader can decide whether the answer fits their situation.
    • An action layer: provide the procedure, checklist, template, calculator, original data, implementation detail, or troubleshooting path that helps the reader complete the task.

    This structure makes the central claim easy to identify without turning the page into a disposable definition. The answer earns selection; the decision and action layers earn the visit.

    JSON-LD can clarify what a page represents, but it is not a referral strategy and it does not guarantee selection in an AI answer. Use the schema type that matches the visible content, connect related entities consistently, and validate the markup after publishing. Do not place claims, reviews, authorship, dates, or relationships in structured data that the page itself does not support.

    Apply the same discipline to freshness. Show a meaningful update date when the substance changed, identify version-dependent instructions, and remove contradictions between the page, its metadata, and its structured data. Changing a date without revising stale information creates a freshness signal for the editor, not new value for the reader.

    Before consolidating or unpublishing a weak page, check its inbound links, internal links, ranking queries, citations, conversions, and role in a topic cluster. Preserve a copy and plan the appropriate destination before removing a URL. A careless cleanup can erase authority or break an existing citation even when raw sessions look unimportant.

    Turn AI crawler access into an explicit business policy

    A person controls open, metered, and closed gates between geometric crawler machines and a secure digital archive.

    More machine access does not automatically produce more discovery, attribution, or revenue. It can also increase server and CDN costs. The 300% rise in AI bot activity observed during 2025 makes bot classification an operating issue, not merely a security log to review after something breaks.

    Start by separating training crawlers, which collect material for model development, from real-time fetchers, which retrieve current content to answer a live request. Their timing, potential value, and commercial relationship differ. A single allow-or-block rule ignores those differences.

    Bot classPossible business rolePolicy optionsMain risk to check
    Search or discovery crawlerMakes pages eligible for a discovery surfaceVerify and allow under controlled limitsBlocking can remove a path to visibility
    Authenticated licensed agentAccesses content under agreed commercial termsAllow only within authenticated scope and limitsUnverified requests may exceed the agreement
    Real-time answer fetcherRetrieves current information for an immediate answerAllow, rate-limit, or license according to measured value and costFresh content may be consumed without useful attribution or referral
    Training crawlerCollects content for model developmentAllow, block, or license according to rights and commercial policyDirect referral value may be weak or unobservable
    Unknown or abusive scraperNo verified legitimate roleChallenge, rate-limit, block, or cautiously tarpitSpoofed identities and false positives can misclassify traffic

    A user-agent string is a claim, not proof. Where an operator publishes a verification method, use it. Keep agent identity, request behavior, targeted URLs, bandwidth, origin load, and any referral or licensing value in the same review. That turns a vague bot debate into a policy decision supported by observable costs and benefits.

    1. Observe before enforcing. Establish which agents request which page groups and how much infrastructure they consume.
    2. Verify identity. Do not grant privileged access or apply a punitive rule solely from a self-declared bot name.
    3. Assign a role. Record whether the agent supports discovery, live answering, training, a licensed relationship, or no recognized purpose.
    4. Choose the least disruptive effective control. Options include scoped access, caching, rate limits, authentication, challenges, blocking, and carefully tested tarpitting.
    5. Stage material changes with a rollback path. Watch crawl activity, indexation, sampled AI citations, referrals, server load, and user errors after enforcement.
    6. Review licensing and content-rights terms with appropriate legal counsel before charging for access or signing an agreement. A crawler configuration cannot determine ownership or contractual rights.

    Robots directives can communicate preferences to compliant agents, but they are not authentication or an access-control wall. Enforce sensitive or paid access with controls that can identify and authorize the requesting agent. If you use tarpitting, apply it only after careful classification: deliberately slowing the wrong traffic can harm legitimate discovery or user-facing performance.

    Emerging approaches such as Know Your Agent identity verification and TollBit pay-per-crawl access are intended to turn retrieval into an authenticated, manageable transaction. Treat that model as an option to evaluate, not guaranteed replacement revenue. The commercial case still depends on enforceable identity, demand for your content, contract terms, delivery cost, and the value of any visibility you give up by restricting access.

    Your next move should come from the first broken link in the chain. Build the ledger, mark known update and deployment dates, test the questions that matter, and classify the agents consuming your pages. Then change one layer at a time and keep a rollback path. That is how you protect visibility without mistaking every lost click for a lost audience.

    References

  • AI-Driven Paid Acquisition: A Lead Generation Playbook

    AI-Driven Paid Acquisition: A Lead Generation Playbook

    If AI-led campaigns keep producing form fills that sales rejects, the system may be succeeding at the wrong task. A thank-you page tells an ad platform that an action occurred. It does not tell the platform whether the lead was qualified, reachable, commercially relevant, or likely to become revenue.

    Your first job is to connect those business outcomes to acquisition. Your second is to make the offer equally clear on the landing page, in the feed, across map profiles, and inside every creative asset. Do those two things before increasing spend, and automation has a much better signal to optimize.

    Key takeaways: what to fix before spending more

    Hands pause a flow of coins while adjusting a lead-generation system that separates rejected tokens from suitable ones.
    • Optimize toward business quality, not raw form volume. Define an accepted lead, return downstream statuses from the CRM, and keep diagnostic actions separate from primary conversion goals.
    • Make the offer unambiguous. A visitor and an automated system should both be able to identify what you sell, who it is for, why it matters, what action to take, and what happens next.
    • Measure each funnel stage on its own terms. Awareness, consideration, lead capture, qualification, opportunity creation, and revenue do not share one useful success metric.
    • Treat feeds, map listings, structured data, pages, and creative as one information system. Conflicting names, categories, locations, or conversion labels weaken both targeting and attribution.
    • Audit placements as well as campaigns. Automated campaigns can reach visual discovery surfaces that behave differently from conventional text search, so a blended click-through rate can hide what changed.

    Teach the buying system what a qualified lead means

    A sales team sorts prospect tokens and sends approval and rejection signals back to an automated acquisition engine.

    Begin in the CRM or lead management system, not in the bidding interface. Write down the point at which an inquiry becomes worth pursuing. That definition might depend on service fit, geography, budget, need, or another criterion your sales team already uses. The exact criteria are yours; the important part is that marketing, sales, the CRM, and the ad platform use the same definition.

    Then trace the feedback loop:

    <!– wp:list {
  • How to Reduce Marketing Platform Dependency Without Stalling Growth

    How to Reduce Marketing Platform Dependency Without Stalling Growth

    Your marketing stack can look diversified and still have a single point of failure. If one vendor controls how you reach an audience, define a conversion, store campaign history, automate customer journeys and prove performance, adding another dashboard does not give you meaningful protection.

    The goal is not complete vendor independence. Specialized platforms can create real leverage. The goal is optionality: if a platform’s economics, rules, performance or roadmap changes, you can preserve customer context, move critical work and continue measuring business outcomes without reconstructing your marketing operation from memory.

    Key takeaways

    • Platform dependency exists when losing access to a vendor would interrupt demand, erase operational context or make performance impossible to verify.
    • Count independent pathways to customers and data, not the number of tools in your stack. Several tools can still share the same underlying failure point.
    • Keep customer permissions, business definitions, source assets, automation logic and measurement rules in systems and documentation you control.
    • Test portability by exporting and rebuilding a bounded, revenue-relevant workflow. An untested export option is not an exit plan.
    • Choose among staying, renegotiating, modularizing and replacing based on the constraint you need to remove, not the novelty of the alternative.

    Recognize dependency before it becomes an emergency

    Heavy use of a platform is not automatically a problem. You may deliberately concentrate spending or operations where performance is strongest. Concentration becomes dependency when the business cannot change course without losing data, customer access, operating knowledge or the ability to measure what happened.

    Paid media makes this risk easy to overlook because the platform’s commercial incentives and the advertiser’s business incentives can diverge. A recommendation may be useful, but you still need to judge it against an outcome the business owns rather than assuming that adoption, automation or additional spend is inherently beneficial.

    Enterprise marketing systems reveal the same dependency in a different form. Teams can become constrained by tangled data, contract lock-in, repetitive messaging and layers of fragile workarounds. At that point, the platform is not merely executing the strategy. Its data model and operating constraints are shaping which strategies are practical.

    Use the following control map to locate the dependency. For every row, decide whether the capability is owned by your organization, shared with a vendor or effectively vendor-bound.

    Control areaPortable positionVendor-bound warning
    Audience accessYou have a lawful, independent route to the customer or can shift demand to another route.The usable audience exists only inside the platform, with no alternative acquisition or retention path.
    Customer dataCanonical records, field definitions, permissions and suppression states live in systems you control.Important attributes or consent context cannot be exported in a usable, documented form.
    Campaign logicSegments, triggers, exclusions, sequencing and decision rules are documented outside the interface.Only the platform configuration explains why a person receives a message or enters a journey.
    Content and creativeSource files, copy, templates, feeds, structured data and approval history are retrievable.The usable version exists only in a proprietary editor, account or asset library.
    MeasurementPlatform reports can be reconciled with orders, qualified pipeline or another business-owned outcome.The vendor selling the media or service is also the only place where success can be observed.
    OperationsNamed internal owners understand the workflow, dependencies, credentials and recovery path.A specialist, agency or vendor is the only party that can explain or safely change the setup.
    Commercial exitRenewal, export, assistance, retention and termination conditions are understood before a decision is due.The team discovers notice requirements, extraction limits or transition costs only when it wants to leave.

    Do not turn this into an average score. A severe dependency in customer permissions or revenue measurement can matter more than several portable, low-impact capabilities. For each vendor-bound row, write down the business consequence of failure, the current recovery path and who has authority to act. Anything that could halt revenue, cause inappropriate customer contact or make results unverifiable belongs near the top of the diversification backlog.

    Some access is proprietary by design. You should not expect to extract a platform’s private audience graph, ranking system or auction data. The practical question is whether your business has a separate way to create demand and retain customer relationships if that access becomes less effective. Diversification should surround proprietary advantages with portable controls, not pretend those advantages can be copied.

    Diversify pathways, not vendor logos

    Several independent routes lead toward one customer destination while a cluster of control boxes converges into a single narrow cable.

    A stack with several vendors is not resilient when every campaign depends on the same identity provider, customer feed, tracking implementation, agency, creative pipeline or reporting logic. Genuine diversification changes the failure modes. It gives you another way to reach the market, another trustworthy view of performance or another way to execute a critical workflow.

    Diversify how demand reaches you

    Group channels by how they can fail, not by the labels in a budget report. Paid search and paid social are different channels, but both depend on auction platforms, platform policies and platform-defined delivery systems. Organic discovery, direct traffic, permission-based messaging, partnerships and community participation introduce different mechanics. That difference is what creates resilience.

    You do not need equal investment across every route. Keep concentration where it earns its place, then maintain a credible alternative for the customer journey that matters most. If paid acquisition weakened, could prospects still discover a useful page, recognize the brand, subscribe through a property you control and receive an appropriate follow-up? If not, the missing step is more important than adding another media account.

    Apply the same principle to AI search and answer engines. Publish the canonical explanation on your own site, keep its schema markup and source content under your control, and treat each search or answer platform as a discovery surface rather than the permanent home of your knowledge. Keep the query themes, evaluation criteria, citation observations and content decisions outside any single visibility tool. That lets you change measurement tools without losing the learning history behind your optimization program.

    Diversify the evidence used to make decisions

    Platform reporting is useful for diagnosing delivery inside that platform. It should not be the sole definition of business success. Define the conversion in business terms first: a completed order, an accepted application, a qualified opportunity, a retained customer or another outcome your organization can verify. Then document how platform events map to that outcome.

    Keep an event dictionary that records the event name, business meaning, trigger, exclusions, data owner and downstream uses. Store attribution assumptions beside the reports that depend on them. When two systems disagree, investigate the identity, timing and definition differences rather than selecting the larger number. The disagreement is information about the measurement system, not an inconvenience to hide.

    This separation also improves platform optimization. You can still send conversion signals back to advertising and engagement systems, but the canonical definition remains yours. If a vendor changes its interface, attribution view or recommended setup, you can evaluate the change against a stable business definition.

    Diversify execution only where interruption would hurt

    A fallback does not have to duplicate the full production stack. It needs to preserve the minimum critical operation. For customer messaging, that may mean retaining exportable permission and suppression records plus a documented emergency communication process. For paid acquisition, it may mean approved creative, landing pages and business-owned conversion data that can be connected elsewhere. For SEO and AEO, it means keeping source content, structured-data templates, redirects and publishing access outside a reporting vendor.

    Use the same dependency test before adding a supposed alternative:

    • Does it require the same account, identity layer or parent provider?
    • Does it consume the same fragile data feed or connector?
    • Does it rely on the same people and undocumented operating knowledge?
    • Does it use an independent measure of the business outcome?
    • Would the same policy, tracking failure or contract dispute disable both routes?

    If most answers reveal a shared dependency, you are adding capacity rather than resilience. Capacity may still be valuable, but it should not be presented as diversification.

    Build a portable core and prove the exit path

    A transparent customer-data capsule moves between two modular platform bays along a reversible transfer rail.

    The safest place for flexibility is below the channel and campaign tools. Build a portable marketing core: the small set of assets, definitions and controls that allows specialized platforms to be replaced without changing what the business means by a customer, permission, conversion or successful campaign.

    That core should include:

    • Identity definitions: the identifiers used for prospects, customers and accounts, including the rules for matching and deduplication.
    • Permission and suppression context: what the person agreed to, where that status originated, which channels it covers and why contact may be prohibited.
    • Business and event definitions: plain-language meanings for lifecycle stages, conversion events, audience membership, exclusions and performance metrics.
    • Content and creative sources: approved copy, original media, feeds, landing-page content, schema templates, brand rules and usage rights.
    • Automation specifications: triggers, waits, branches, priority rules, frequency controls, fallbacks and exit conditions expressed outside the vendor interface.
    • Measurement methodology: the business outcome, reconciliation process, attribution assumptions, known gaps and owner of each decision-making report.
    • Operational ownership: named owners for accounts, domains, credentials, integrations, approvals, data quality and incident response.

    Documentation alone is not portability. A data file is not useful if nobody knows what its fields mean. A suppression list is unsafe if the reason and scope of suppression are missing. A screenshot of an automation is not a specification if the hidden filters and dependencies cannot be reconstructed.

    Prove portability with a bounded reconstruction drill:

    1. Select a revenue-relevant workflow with clear inputs and a verifiable business outcome. Keep the scope small enough to inspect end to end.
    2. Export the required records, content, configuration and history using the access available to your team. Record where vendor assistance is required.
    3. Translate proprietary objects and interface settings into plain business rules. Include eligibility, exclusions, permissions, timing, measurement and failure handling.
    4. Recreate the audience, calculation or workflow in a controlled environment. A shadow calculation is enough when sending live messages from two systems would confuse customers.
    5. Compare eligibility, exclusions and business outcomes. Investigate mismatches instead of accepting a superficially similar total.
    6. Record every unavailable field, unexplained rule, manual dependency and contractual obstacle. Assign an owner and a safe remediation path.

    The gaps exposed by this drill are your real lock-in. They are more useful than a generic feature comparison because they show exactly what the business cannot currently move.

    If replacement becomes necessary, migrate by capability rather than attempting an undifferentiated switch. Stop creating undocumented dependencies in the old system. Move a bounded workflow, reconcile it against the original, then expand only after permissions, exclusions, reporting and operational support behave as intended. Keep the original records available in a controlled, read-only state until the required history and audit context have been verified.

    Do not disable a customer system or cancel access while consent records, suppression logic, financial evidence or required reporting remain trapped inside it. The downside is not just inconvenience: you could lose evidence needed to explain past decisions or contact people who should not be contacted. Have the appropriate privacy, legal, security and finance owners verify retention, deletion and contractual obligations before decommissioning anything.

    Renewal preparation is part of technical architecture. Ask procurement and counsel to establish, in writing, which data can be exported, the available formats, who owns derived records, what access remains after termination, whether transition assistance carries a fee, how historical reports are retained and how deletion is confirmed. Technical teams should verify the mechanism rather than relying only on a contractual right that has never been exercised.

    Choose the smallest move that restores real choice

    Not every dependency justifies a migration. Replacing a major platform can introduce data loss, customer disruption, new integration work and a different form of lock-in. Start with the constraint, then choose the least disruptive move that removes it.

    • Stay when the platform provides a clear advantage, its results can be independently verified, critical data and logic are portable, and the team has a credible recovery path.
    • Renegotiate when the product still fits but commercial terms, export rights, assistance, account control or renewal conditions create unnecessary dependence. Make portability an explicit procurement requirement.
    • Modularize when the core platform remains useful but a particular layer is blocking change. Measurement, content, decision rules, identity, messaging or reporting may be separable without replacing everything.
    • Replace when a vendor-bound capability is business-critical, meaningful change cannot be made safely, outcomes cannot be verified, or the operating model no longer supports the strategy. The replacement case must show how the underlying constraint will disappear.

    Before approving a replacement, test whether the problem is actually the product. Poor definitions, unclear ownership, weak governance and undocumented workarounds follow the team into a new platform. Copying the same tangled data model and operating habits into a different interface changes the vendor, not the dependency.

    Build the decision case around observable constraints. For each proposed change, name the blocked business action, the consequence, the target capability, the proof that will show improvement, the migration risk, the fallback and the accountable owner. Feature lists matter only after that chain is clear.

    Then make optionality routine. Add export checks to platform reviews. Require new automations to have an external specification. Keep business definitions separate from vendor terminology. Review account and data ownership when people or agencies change. Put renewal and termination conditions where marketing, procurement and technical owners can see them before a deadline forces a rushed decision.

    Start with the customer journey that would be hardest to lose. Export its inputs, explain its rules without opening the platform and verify its outcome against a system the business controls. Whatever you cannot retrieve, explain or rebuild becomes the next item to fix. You do not need freedom from every platform; you need the ability to choose before a platform chooses for you.

    References

  • How to Automate Paid Search Without Losing Conversion Quality

    How to Automate Paid Search Without Losing Conversion Quality

    Your paid search account can look healthier while the business behind it gets worse. Cost per conversion falls, the dashboard fills with activity, and automation appears to be working – yet purchases weaken, qualified leads become rarer, or the sales team spends more time rejecting inquiries.

    That usually isn’t an automation failure. It is an instruction failure. Automated bidding, targeting, and testing follow the goals you make visible to them. If those goals reward easy actions rather than valuable outcomes, the system can become highly efficient at acquiring the wrong conversions.

    Make the business outcome the strongest conversion signal

    A bidding system doesn’t independently decide which website action matters to your company. It learns from the conversion actions, values, and campaign goals you provide. When purchases, qualified leads, pageviews, button clicks, and form starts are all treated as optimization targets, frequent low-friction actions can overwhelm the events that produce revenue.

    This is the central conversion-quality problem: more conversion data is not automatically better conversion data. A pageview is easier to generate than a sale. A form start is easier to generate than a qualified submission. If the system receives no meaningful value hierarchy, it has a strong incentive to find the predictable action rather than the commercially important one.

    Too few signals can also slow learning, so the answer is not to delete every intermediate event. The answer is to distinguish observation from optimization. Keep useful micro-conversions for analysis, audience understanding, and funnel diagnosis, but do not automatically make every event a primary campaign goal.

    Build a conversion hierarchy before changing bids

    1. Name the final business outcome. For ecommerce, that will normally be a completed purchase. For lead generation, it may be a qualified lead, an accepted opportunity, or another offline stage that represents genuine commercial intent.
    2. Identify the earliest event that reliably predicts that outcome. A submitted form might be useful if nearly every submission is legitimate. If submissions vary sharply in quality, the stronger signal sits later in the sales process.
    3. Separate primary and secondary actions. Use the commercially meaningful action for bidding. Retain form starts, calls below your qualification standard, page engagement, and similar events as diagnostic signals unless they have demonstrated business value.
    4. Send offline outcomes back to the ad platform. When value is established after a call, review, consultation, or sales conversation, online form tracking alone gives automation an incomplete picture. Offline conversion tracking lets the system learn which clicks created real outcomes.
    5. Use values to express meaningful differences. If two outcomes have materially different business value, representing them as equal conversions hides that distinction. Value-based bidding only helps when the values reflect the hierarchy you actually care about.
    6. Validate the data path. Check that each event fires at the intended stage, is not duplicated, carries the right value, and can be connected to its originating campaign. A sophisticated bidding strategy cannot repair a mislabeled or duplicated conversion.

    Do not compensate for sparse final conversions by promoting every available event into the primary goal set. First check whether delayed or offline outcomes are missing. Adding weak signals may increase reported volume while moving optimization farther away from revenue.

    Use intent and creative to qualify traffic before the click

    Several shoppers with different intentions approach a branching gateway that guides serious buyers toward a focused path and casual browsers toward side paths.

    Conversion quality starts before someone reaches the landing page. Your keywords, product feed, campaign structure, and ad language determine which searches can enter the funnel. The more freedom you give automated targeting, the clearer those inputs need to be.

    This becomes especially important in housing, employment, credit, healthcare, and legal services. Google Ads can restrict website and app remarketing, Customer Match, YouTube interaction audiences, and custom segments in sensitive-interest categories. Housing campaigns may face additional demographic limitations. Even with those controls unavailable, advertisers can still work with keywords, feeds, permitted Google audiences, content targeting, conversion tracking, and certain forms of automated targeting.

    When audience history cannot do the qualifying, search intent and creative have to carry more of the load:

    • Start with the problem expressed in the query. Organize keywords around what the searcher needs, not just the service name your company uses internally.
    • Use phrase or broad match deliberately. Exact match may miss different ways of expressing the same need, particularly in restricted categories. Broader matching can recover that demand, but it should be paired with meaningful conversion signals and regular query review.
    • Make the offer specific in the ad. State who the service is for, what is being offered, and any important eligibility boundary that can be communicated lawfully. Clear creative discourages unsuitable clicks before they consume budget.
    • Keep feeds accurate. For Shopping and feed-led campaigns, titles, categories, prices, availability, and other product attributes shape which searches can surface an item. Feed quality is part of targeting quality.
    • Separate genuinely different services. If a company offers both sensitive and non-sensitive services, distinct sites or domains can preserve a clean operational boundary. That separation should reflect a real difference in the business and user journey, not an attempt to disguise a restricted service.

    Placement changes can complicate the picture. Microsoft has tested a larger, double-row sponsored product carousel in Bing Shopping results, although the format was not visible to every user and should be treated as an experiment rather than a universal layout. More sponsored inventory can increase impressions and clicks without improving the intent of those clicks.

    If Shopping traffic rises abruptly, do not assume the campaign has found a better audience. Compare product-level conversion quality, revenue, query composition, and final outcomes before raising budgets. A larger ad surface is an inventory change; it is not evidence that the additional traffic is valuable.

    Put automated experiments behind business guardrails

    Small autonomous vehicles test multiple routes within glowing boundaries, passing business-value checkpoints while a barrier stops a risky path.

    Experiments are valuable because they isolate a proposed change from the existing campaign. The risk appears at the handoff from test result to live account. Google Ads includes an experiment setting that can apply a winning result automatically and is enabled by default. That can shorten the testing cycle, but it also removes the review point where downstream quality problems are often discovered.

    The experiment interface allows directional evaluation or statistical-significance thresholds of 80%, 85%, or 95%. It also prevents automatic application when a selected success metric performs significantly worse. The limitation is just as important: an experiment can use only two success metrics, so an unselected third metric can deteriorate without stopping the rollout.

    Before launching a test, write down three things outside the platform: the result that would count as a win, the business metric that must not fall below an acceptable level, and the conditions that require manual review. This prevents a visually convincing dashboard from redefining success after the test ends.

    When automatic application is reasonable

    • The change is easy to reverse and has limited reach.
    • The primary success metric represents a final or strongly qualified outcome.
    • The second metric protects the most important cost, value, or quality constraint.
    • No critical business measure sits outside those two metrics.
    • Conversion tracking has been validated before the experiment starts.

    When to require manual review

    • The test changes the conversion goal, assigned values, or bidding strategy.
    • The change expands traffic through broader matching, automated targeting, new inventory, or a substantially different feed.
    • Lead quality is determined offline or only after a meaningful delay.
    • The campaign operates in a regulated or sensitive category.
    • The commercial downside of a false winner is larger than the operational cost of reviewing it.

    For a manual review, look beyond the two headline metrics. Inspect the conversion-action mix, qualified-lead or purchase rate, revenue or assigned value, search-query and product composition, spend distribution, and any delayed offline outcomes. If the experiment appears to win only because it generated more low-value actions, it has not passed a conversion-quality test.

    Diagnose quality loss from the symptom, not the dashboard score

    Automation problems leave recognizable patterns. Use the visible symptom to identify which instruction the system may be following, then correct the signal or boundary before making another bid adjustment.

    What you noticeLikely mechanismWhat to inspectWhat to change
    Reported CPA falls while qualified-lead or purchase rate fallsAn easy micro-conversion is dominating optimizationPrimary goals, conversion-action mix, duplicate events, and assigned valuesMove weak actions to observation, correct duplication, and optimize toward the final or qualified outcome
    Form volume rises but the sales team rejects more leadsThe platform sees submission volume but not downstream qualificationOffline outcome imports, attribution identifiers, and the delay between submission and reviewImport qualified stages and use them as the stronger bidding signal
    Shopping impressions and clicks jump without comparable revenueMore prominent or expanded ad inventory is creating extra exposureProduct-level revenue, query composition, conversion rate, and average order valueHold budget decisions until final conversion quality is clear; refine products and feed inputs where needed
    A sensitive-category campaign has very little eligible trafficAudience restrictions and narrow matching are constraining reachPolicy status, prohibited audience dependencies, keyword coverage, feeds, and ad specificityUse compliant intent targeting, permitted audiences, phrase or broad match where appropriate, and clearer qualifying creative
    An experiment wins but downstream revenue weakensThe deteriorating business metric was not one of the two protected success metricsThe complete funnel, not only the experiment summaryReverse or withhold the rollout, redesign the metrics, and keep automatic application off for that test class
    Smart bidding has too little useful dataFinal outcomes are sparse, delayed, or missing from the platformTracking completeness, offline imports, attribution matching, and conversion lagRepair the final-outcome data path before adding low-intent events as optimization goals

    Resist the urge to solve every symptom by loosening targets or increasing budget. Those changes may give the system more room to pursue the same incorrect objective. Fix the definition of success first, then decide how aggressively to scale it.

    Key takeaways

    • Automated bidding optimizes the conversions and values you expose; it does not independently know which actions create revenue.
    • Keep micro-conversions available for funnel analysis, but make them primary goals only when they are reliable proxies for business value.
    • For lead generation, send qualified offline outcomes back to the platform instead of asking form submissions to stand in for lead quality.
    • When remarketing or audience controls are restricted, use search intent, accurate feeds, and self-qualifying creative to shape traffic.
    • Treat increases caused by new or expanded ad inventory as exposure gains until purchase or lead-quality data proves otherwise.
    • Review auto-applied experiment settings before launch, especially when an important business metric cannot fit among the two success metrics.

    Start your next optimization session in the conversion-goal settings, not the bidding controls. Confirm which actions are primary, trace them to a real business outcome, and identify the quality metric that could deteriorate unnoticed. Once those instructions are sound, automation has something worth scaling.

    References


  • How to Build an AI-Powered Creator Commerce Campaign

    How to Build an AI-Powered Creator Commerce Campaign

    You have creator candidates, a product catalog, and a paid-media budget. The hard part is connecting them: the creator must make the product relevant, the shopping surface must preserve the promise, and your measurement must show where the campaign actually worked or failed.

    The practical model is a single creator-commerce loop, not separate influencer, advertising, and ecommerce projects. You choose the buying action first, match creators to that job, plan the paid uses of their content, configure the offer shoppers will encounter, and measure every handoff.

    Treat creator marketing and AI shopping as one buyer journey

    A creator can introduce the problem, demonstrate the product, answer an objection, or give a buyer a reason to act. Commerce systems have a different job: they present the product, price, availability, and eligible benefits when that interest becomes purchase intent.

    AI is bringing those jobs closer together. YouTube can use Gemini to help advertisers find relevant creators and then distribute creator-made content through paid formats. Google has also extended member pricing and shipping benefits into AI Mode and Gemini, as well as local inventory and regional Shopping ads.

    For you, the important change is the handoff. A shopper can encounter a creator’s recommendation, see the same message in a paid placement, and later find a personalized benefit during product discovery. If those touchpoints contradict one another, AI-powered distribution merely spreads the inconsistency faster.

    Start each campaign by writing the promise that must survive the journey. If the creator discusses exclusive shipping for loyalty members, verify that the eligible shopper can actually see and receive that benefit. If the listing emphasizes member pricing, the creator’s call to action should explain why membership matters instead of sending everyone to a generic product page with no visible connection.

    This also changes how you divide responsibility internally. The creator team should know which offer the commerce team has configured. The commerce team should know which claims and calls to action appear in the creator asset. Paid media should not receive the content only after it has been produced; its required placements and audiences should shape the brief from the beginning.

    Build the campaign backward from a commerce event

    A product purchase in the foreground connects backward through an offer, creator content, paid distribution, and content production.

    Do not begin with a broad request to find popular creators. Begin with the behavior you need from a specific kind of buyer. That decision determines the offer, brief, creator criteria, destination, and measurement plan.

    1. Name the commercial event. Decide whether the campaign is meant to generate product discovery, a qualified product-page visit, a first purchase, a loyalty enrollment, or another defined action. Use one primary event to make campaign decisions. Secondary metrics can explain performance, but they should not quietly replace the original goal.
    2. Define who can receive the offer. Separate prospects from recognized members and distinguish a public promotion from a loyalty benefit. If eligibility depends on a membership tier, country, region, or local inventory, record that before the creator writes the call to action.
    3. Choose the proof the buyer needs. A creator brief should identify the buyer’s problem, the product’s role, the objection that must be answered, and the evidence the creator can show. A product demonstration, use case, or clear explanation usually gives you more to evaluate than a generic endorsement.
    4. Shortlist creators for that job. YouTube’s Gemini-powered matching can suggest candidates from more than three million YouTube Partner Program creators. Use that scale to widen discovery, then apply human review to audience relevance, creative quality, product credibility, and suitability for paid distribution.
    5. Plan distribution before production. Decide whether the partnership will remain on the creator’s channel or also become a paid Short, an in-stream ad, or both. Confirm that the partnership permits every planned placement, market, and period of use before allocating media spend.
    6. Instrument the handoff. Give each creator and placement an identifiable destination or campaign parameter. Align the platform conversion event with the commercial event you selected. Where appropriate, add a creator-specific code, but do not treat code use as the only evidence of influence; shoppers may return through another route.

    Keep the first test interpretable. If you change the creator, audience, offer, landing experience, bid strategy, and product selection at the same time, a good result will not tell you what to repeat and a bad result will not tell you what to repair.

    Use AI matching as a shortlist, not a strategy

    Creator matching solves a discovery problem. It can help you navigate a large pool, but it cannot decide what your buyer needs to hear, whether the creator’s authority transfers to your product, or whether the resulting content will work outside the creator’s existing audience.

    Use a scorecard that forces every recommendation to produce observable evidence. The model’s recommendation can open the review; it should not end it.

    DecisionEvidence to inspectReason to pause
    Audience relevanceRecurring subjects, viewer questions, purchase problems, and use cases connected to the productThe connection depends mostly on a broad demographic label or follower count
    Product credibilityA natural reason for the creator to discuss, use, compare, or demonstrate the productThe endorsement would require a sudden change in the creator’s established subject matter
    Creative strengthA clear opening, understandable product role, concrete proof, and a call to action that fits the contentThe product appears only as an interruption with no useful explanation
    Paid-media portabilityA message that a cold viewer can understand without knowing the creator’s backstoryThe asset depends entirely on channel-specific context or an inside joke
    Offer alignmentA benefit the intended audience can receive in the markets and membership tiers being targetedThe creator would be promoting an offer that many reached viewers cannot access
    Measurement readinessA distinct asset, placement identifier, destination, and agreed conversion eventPerformance can only be read as a blended campaign total

    Follower count belongs in the context, not at the center of the decision. A smaller relevant audience can reveal stronger buying intent than a large audience gathered around unrelated content. Conversely, topical relevance alone is not enough if the creator cannot communicate the product clearly or if the asset cannot survive paid distribution.

    Review the likely failure mode before approving a match. If the creator understands the audience but not the product, improve the briefing or reject the match. If the content is persuasive to existing followers but confusing to cold viewers, separate the organic asset from the paid edit. If the offer is compelling but limited to recognized members, prevent the campaign from implying that every viewer will receive it.

    Turn creator content into a connected distribution system

    A creator filming a product is connected by glowing paths to multiple content, shopping, advertising, order, and measurement touchpoints.

    A creator partnership should produce more than an isolated upload. YouTube allows creator-made content to run as paid Shorts and in-stream ads, giving you a route from creator credibility to controlled media distribution.

    That does not mean one edit should be copied everywhere. Give each placement a defined job while preserving the same product truth and offer:

    • The creator-channel asset establishes context, credibility, and the full product story for an audience that already knows the creator.
    • The paid Short introduces the buyer problem and product quickly enough to make sense to a cold viewer.
    • The in-stream ad has room to develop the use case, proof, or objection that cannot fit into the shortest edit.
    • The product or local inventory listing confirms the purchasable product and displays the applicable price or benefit.
    • The loyalty layer shows recognized members the pricing or shipping advantage for which they are eligible.

    Create a message ledger before editing begins. Record the approved product promise, supporting proof, exact offer wording, call to action, destination, market eligibility, membership requirements, and the placements where the asset will run. Every version can vary in pacing and length, but it should remain consistent with that ledger.

    The commerce setup deserves the same attention as the creative. Merchants using Google’s loyalty features can activate the loyalty add-on in Merchant Center, configure member tiers, supply pricing and shipping attributes, and connect Customer Match lists so recognized members can see eligible benefits. A creator campaign should not promote those benefits until the feed, tier rules, audience connection, and destination have been checked together.

    Market eligibility is part of the brief, not a footnote. The stated expansion covers Australia, Brazil, Canada, France, Germany, India, Italy, Japan, Mexico, the Netherlands, South Korea, Spain, the United Kingdom, and the United States. If your creator reaches viewers outside the relevant campaign market, use wording that does not imply universal access.

    Local inventory and regional Shopping ads can be especially useful when the benefit or product availability varies by location. Match the creator’s geographic targeting, the inventory being promoted, the Merchant Center configuration, and the landing experience. Otherwise, you pay to generate interest that the next surface cannot satisfy.

    There is also a U.S. pilot that uses Customer Match as a relationship data source for free listings. Treat pilot access as an optional opportunity, not as inventory you can assume in a forecast. Build the core campaign around placements and features actually available to your account.

    Measure the chain instead of celebrating one platform number

    Creator commerce can look successful at the top of the funnel while leaking value at the final handoff. A popular video does not prove product demand, and a strong click-through rate does not prove profitable sales. Your reporting should show how attention moved through the campaign.

    • Matching: Track which creator-selection criteria were expected to matter and whether the content attracted relevant viewer questions or actions.
    • Creative: Read view rate, completion, engagement, and product clicks by asset. These metrics help locate attention loss; they are not substitutes for the commercial event.
    • Media: Separate organic creator delivery from paid Shorts and in-stream distribution. Report cost, reach, click-through rate, conversion rate, and acquisition cost by placement.
    • Commerce: Measure product-page behavior, purchases, order value, and offer redemption using consistent definitions.
    • Relationship: Where loyalty is part of the objective, distinguish existing recognized members from new enrollments and non-member buyers.

    Document every denominator. A conversion rate based on clicks is not interchangeable with one based on sessions, and a customer acquisition cost should not silently include returning customers if the campaign goal is new-customer growth. Definition drift can make two dashboards appear to agree when they are measuring different events.

    Platform lift figures are useful for forming a hypothesis, not for writing your revenue forecast. YouTube reports an average 30% conversion lift from boosting creator content through Shorts and in-stream ads. Google reports that some retailers saw up to a 20% increase in click-through rate when tailored loyalty offers were shown to members.

    Those numbers should not be combined or treated as guaranteed. One is an average conversion result for creator advertising formats; the other is an upper-end click-through result reported for some retailers using tailored offers. They describe different interventions, outcomes, and populations. Your baseline, margin, audience, creative, product, and offer determine whether either benchmark is relevant.

    Use controlled comparisons to learn what contributed. Hold the offer, audience, and destination steady when comparing creator-made and brand-made assets. Evaluate loyalty presentation separately instead of mixing it into the creative test. If several creator assets run together, retain asset-level and creator-level identifiers so a blended result does not hide the winner or the failure.

    Read mismatches as diagnostic signals. Strong viewing with weak product clicks points you toward the call to action or offer handoff. Strong clicks with weak conversion points you toward the destination, price, eligibility, or product experience. Strong conversion with limited reach points you toward distribution. These are places to investigate, not automatic diagnoses, but they are more useful than labeling the whole campaign good or bad.

    Key takeaways

    • Choose the buying action and eligible offer before asking AI to find creators.
    • Use AI matching to expand and organize discovery, then require human evidence for audience fit, product credibility, creative quality, and paid-media suitability.
    • Plan creator-channel content, paid Shorts, and in-stream ads as related assets with different jobs, not automatic duplicates.
    • Verify Merchant Center tiers, pricing, shipping attributes, Customer Match connections, markets, and destinations before a creator promises a loyalty benefit.
    • Measure the full path from creator attention to commerce and customer relationship outcomes. Treat vendor-reported lift as a hypothesis, not your forecast.

    Your next move is to choose a product, a buyer action, and an offer that the intended audience can actually receive. Write the creator brief, placement plan, commerce configuration, and measurement event on the same page. If that chain remains clear from first view to purchase, you have a campaign worth testing.

    References


  • Paid Media Optimization for Long Sales Cycles: A Practical System

    Paid Media Optimization for Long Sales Cycles: A Practical System

    Your paid campaigns can generate leads this week while the resulting revenue takes months to appear. That delay creates an uncomfortable decision: should the ad platform optimize for the form submission it can see quickly, or for the closed sale that reflects the outcome you ultimately care about?

    The answer is not simply “optimize further down the funnel.” In a human-led sales process, a closed deal measures more than media quality. It also reflects rep skill, follow-up speed, capacity, product availability, approval delays, and seasonal behavior. You need a bidding signal that rewards valuable demand without teaching the platform to react to every operational swing.

    Key takeaways for long-cycle campaigns

    • Use the deepest conversion event that is frequent, timely, and operationally stable. A closed sale is not automatically the best bidding signal.
    • For many long sales cycles, the practical optimization boundary is a valued lead at submission: not every form fill receives the same value, but the value is assigned before sales execution changes the outcome.
    • Estimate lead value from conversion probability and typical deal size using information available when the inquiry arrives.
    • Keep downstream revenue in your measurement system even when it is not the primary bidding input. You need it to calibrate lead values and judge business performance.
    • Diagnose media quality and sales operations separately. Stable lead volume and predicted value alongside a falling close rate is not sufficient evidence that targeting has failed.

    Why a closed sale can be the wrong bidding signal

    Identical lead spheres move through different sales-process channels, where workload, delays, approvals, inventory, and other obstacles change which ones reach the final outcome.

    An ad platform sees the conversion outcome, but it does not understand your organization. If a strong sales rep closes more leads than a new rep, the platform can observe the difference in recorded sales. It cannot inherently know that rep assignment caused it.

    Imagine that the same campaigns, keywords, landing pages, and lead profiles continue running while your most effective closer takes leave. A less experienced colleague receives the leads, follow-up slows, and the close rate falls. An automated system optimizing for sales may treat the decline as evidence that those clicks or audiences became less valuable. It can then reduce bids, shift budget, or suppress targeting that was still generating suitable prospects.

    Rep composition is only one source of noise. Close rates can change when workloads increase, response times stretch from days into a week, a competitive product is withdrawn, an approval stalls, or vacation coverage leaves inquiries untouched. Leads from other channels can also consume the sales team’s capacity even though nothing changed inside the paid account.

    Calendar behavior can make the distortion severe. In one observed financial-services pattern, lead-to-sale conversion around the third week of December rose by as much as 150% compared with normal weeks, then fell sharply during the holiday week. The leads and placements had not suddenly become much better and then much worse. Sales urgency, customer availability, bonus incentives, and leave schedules had changed.

    This is the core diagnostic distinction: a sale is a business outcome, but it is not always a clean media-quality label. When you ask an algorithm to bid on it, you are asking the platform to optimize all the forces embedded in that outcome, including forces the campaign cannot control.

    Set the optimization boundary at a stable quality signal

    Your optimization boundary should sit at the latest funnel event that satisfies three conditions: the event happens often enough for automation to learn from it, it arrives soon enough to guide current bidding, and its definition remains stable enough to mean the same thing from one period to the next.

    Direct sales or revenue optimization can be appropriate when conversion volume is sufficient, the reporting delay is short, and the sales process is stable. Long, low-volume, human-dependent sales cycles frequently fail one or more of those tests. In that situation, a quality-adjusted lead is usually more dependable than either a raw form fill or a closed deal.

    • A raw lead count is too shallow when inquiries have materially different probabilities of conversion or deal sizes.
    • A closed sale is too deep when it is rare, delayed, or heavily shaped by sales execution and operational capacity.
    • A valued lead at submission is the middle path when you can estimate commercial potential from information already available at the point of inquiry.

    The phrase “at submission” matters. If you assign the value after seeing which rep handled the lead, whether the buyer answered a follow-up call, or how the opportunity progressed, you have allowed downstream execution back into the bidding label. The model should use attributes known when the lead enters the funnel.

    The optimization boundary is not the reporting boundary. Continue importing final status and realized revenue. Use those outcomes to evaluate the business, recalibrate the lead-value model, and identify sales-process problems. You are separating two jobs: the bidding system needs a timely and stable signal, while management reporting needs the complete commercial outcome.

    Build a lead-value model from matured historical cohorts

    Lead tokens pass through a long time tunnel before matured groups are sorted into illuminated value categories, with a separate path continuing toward eventual revenue.

    A useful lead-value model estimates expected revenue rather than merely labeling a lead “good” or “bad.” Start with historical inquiries that have had enough time to reach a final outcome. A full year is preferable because it captures more operating conditions and seasonality, although six months can be sufficient when that is all the reliable history you have.

    1. Select matured cohorts. Group leads by the date they entered the funnel, then include cohorts old enough that most opportunities have reached a meaningful final status. Mixing fresh, unresolved leads with completed cohorts will make recent traffic appear artificially weak.
    2. Freeze the information available at inquiry. Retain fields the campaign could reasonably influence or attract: requested product, project scope, stated timing, loan characteristics, company size, industry, and other submission-time attributes relevant to your business.
    3. Calculate conversion probability by meaningful segment. Determine which inquiry-time characteristics correspond with different eventual conversion rates. Keep the segments understandable enough that you can explain why a lead received its value.
    4. Measure typical deal value for each segment. A segment that closes frequently is not necessarily the most valuable if its average commercial outcome is small. Conversely, a lower-probability segment may deserve attention when successful deals are much larger.
    5. Assign expected revenue. The basic logic is conversion probability multiplied by typical deal value. The result is a monetary estimate that a value-based bidding system can compare across leads.
    6. Reconcile predictions with realized revenue. Add the predicted values for a matured acquisition cohort and compare that total with the revenue eventually produced by the same cohort. Large or persistent gaps mean the probabilities, deal values, segments, or data quality need adjustment.
    7. Version and revisit the model. Preserve the value assigned at submission and record which model version produced it. Reassess the model quarterly so changes in campaign mix, products, buyer behavior, and operations do not leave old assumptions running indefinitely.

    The most useful segmentation variables depend on the transaction. Financial-services leads may differ by loan value or terms. B2B inquiries may differ by company size or industry. Construction opportunities may differ by scope and immediacy. Choose fields that were genuinely known at inquiry and have a defensible relationship with conversion probability or deal size.

    A practical framework might assign expected values such as $850 to a high-probability lead, $420 to a middle tier, and $120 to a lower-probability lead. Those figures are examples, not benchmarks. Copying them would make the model arbitrary; your values must come from your own conversion rates and deal economics.

    Do not confuse an expected-revenue value with a conventional lead score. A score of 90 may rank above a score of 40, but it does not tell a bidding system whether the first lead is twice as valuable, ten times as valuable, or only marginally better. Monetary values express the size of the difference and allow value-based bidding to make an economically meaningful tradeoff.

    Guard against data leakage as you build the model. Opportunity stage, rep assessment, response behavior, and later qualification calls may predict sales extremely well, but they were not known when the ad produced the inquiry. Using them to label historical leads can create a model that looks accurate in analysis but cannot assign equivalent values consistently at submission.

    Feed values into bidding without losing revenue accountability

    Once the values reconcile reasonably with matured revenue, configure the lead conversion to send its expected value with the event. Value-based bidding, including Google Ads target return on ad spend, can then pursue the mix of inquiries with the highest predicted commercial value rather than the largest number of identical form fills.

    Treat the implementation as a measurement change before treating it as a bidding change. First log the dynamic values while the existing strategy remains in place. Confirm that each valid lead is counted once, the correct value reaches the correct conversion action, and the platform’s aggregate value matches your lead system for the same inquiry dates. Only then should you let a value-based strategy act on the signal.

    Keep a compact acquisition record for every lead. At minimum, preserve the lead identifier, inquiry timestamp, paid-media attribution, value assigned at submission, model version, rep assignment, first-response timing, final status, and realized revenue. This lets you distinguish what the model knew from what happened after the handoff.

    Evaluate performance through two related views:

    • Predicted return compares total expected lead value with the spend that produced those leads. It is available quickly enough to guide campaign management.
    • Realized return compares eventual revenue with spend for the same acquisition cohort. It arrives later but tells you whether the model and the wider commercial process delivered what the early signal implied.

    Keep the cohort alignment intact. Revenue closed this month may have come from leads acquired months ago, so comparing it with this month’s spend can produce a convincing but false trend. Join eventual revenue back to the date and campaign that generated the inquiry. That makes the lag explicit and prevents old pipeline from being credited to current media.

    Roll the bidding change into a controlled part of the account rather than changing every campaign at once. Watch lead counts, predicted value, spend, and the distribution of value tiers. As cohorts mature, compare their predicted totals with realized revenue. A strategy that raises platform-reported value but repeatedly produces less realized revenue is exposing a calibration or tracking problem, not proving business growth.

    Diagnose a performance drop before changing the media

    When sales fall, resist the reflex to rewrite ads or cut audiences immediately. Walk through the funnel in causal order. The goal is to locate the first point where performance changed.

    1. Check inquiry volume. Did the number of valid paid leads change, or did only closed sales change?
    2. Check predicted lead value. Did the mix move toward lower-value tiers even if total lead volume remained stable?
    3. Check media inputs. Look for meaningful changes in targeting, search terms, audience composition, placements, creative, landing-page behavior, budget, or tracking.
    4. Check routing and response time. Determine whether leads reached the right people and whether follow-up slowed.
    5. Check staffing and capacity. Review rep assignment, leave, onboarding, workload, and competing lead sources.
    6. Check the commercial offer. Identify withdrawn products, changed eligibility, approval delays, pricing constraints, or other conditions that made the same lead harder to close.
    7. Check calendar effects. Separate customer availability and sales-team urgency from changes in demand quality.
    8. Change the layer that failed. Adjust campaigns when the deterioration begins in traffic or predicted lead value. Address operations when the early media signal is stable but handoff or close performance worsens.

    This sequence gives you a cleaner interpretation. If lead volume and predicted value remain stable while response times rise and close rates fall, the evidence points downstream. If response times and sales coverage remain stable while the account produces a weaker value mix, the media deserves scrutiny. If both change, treat them as separate problems instead of asking one campaign adjustment to solve both.

    Your first move should be an export of matured lead cohorts, not another bid adjustment. Identify the inquiry-time attributes that separate conversion probability and deal size, assign expected revenue, and reconcile the total against actual revenue. Once that model holds together, use it as the bidding signal and keep closed sales as the accountability signal. That division gives automation something it can learn from without letting every staffing or operational change rewrite your media strategy.

    References


  • How to Measure AI Agent Traffic and Attribute Conversions

    How to Measure AI Agent Traffic and Attribute Conversions

    Your analytics dashboard may show a human arriving at checkout while missing the machine that found the product, compared the options, and initiated the journey. It may also show nothing at all when an agent completes an action without running your client-side analytics code.

    You can close that gap, but not with a new referral channel alone. Reliable AI agent attribution starts in server and CDN logs, continues through first-party action events, and ends with an attribution model that distinguishes direct execution from assistance and unlinked automation.

    Key takeaways

    • Measure AI agents at the HTTP request layer. A request that does not execute your analytics script cannot create a normal browser event.
    • Separate training crawlers, real-time retrieval systems, and task-performing agents. They represent different intent and should not share one conversion rate.
    • Do not trust a user-agent string by itself. Combine it with published network information, request behavior, authentication state, and your own event data.
    • Use distinct attribution states for agent-executed, agent-assisted, discovery-only, and unresolved activity. Do not force uncertain traffic into a conversion channel.
    • Instrument forms, account actions, carts, and orders on the server. Page requests show access; confirmed business events show outcomes.

    Classify traffic by the job the machine is doing

    An automated request is not automatically a prospective customer. A model-training crawler collecting material, an answer engine retrieving a current page, and an agent submitting a form can all request the same URL. Their commercial meaning is entirely different.

    This distinction matters because machine activity is growing faster than human activity. HUMAN Security measured more than a quadrillion interactions from 2022 through 2025. In that dataset, automated traffic increased 23.5% in 2025 while human traffic increased 3.1%. AI-driven traffic rose 187%, and activity associated with AI agents and agentic browsers rose by nearly 8,000%. Those figures come from aggregated, anonymized customer data, so treat them as a market signal rather than a forecast for your site.

    Traffic classLikely jobWhat to measureAttribution treatment
    Training crawlerCollect content for later model developmentPages fetched, bytes served, crawl frequency, response statusContent access, not a visit or conversion
    Real-time retriever or scraperFetch current information for an answer or comparisonLanding routes, freshness-sensitive pages, response success, repeat retrievalDiscovery activity unless a handoff can be observed
    Task-performing agentNavigate or take an action for a userWorkflow steps, authenticated state, form or cart events, confirmed outcomeDirect or assisted attribution when the evidence supports it
    Unverified automationUnknown, mislabeled, or potentially hostile activityBehavior pattern, network identity, rate, errors, security challengesKeep unattributed until verified

    Training crawlers still represented 67.5% of measured AI traffic, while real-time scrapers grew by nearly 600% in 2025. That mix explains why a large increase in AI-labelled requests does not necessarily produce leads or revenue. Start by assigning each request to a functional class; calculate commercial performance only for traffic capable of participating in a user journey.

    Task-performing agents deserve special attention because their behavior is moving deeper into sites. In 2025, 77% of observed agentic activity occurred on product and search pages, nearly 9% involved account-level interactions, and more than 2% reached checkout. If you monitor only editorial URLs, you will miss the requests closest to a business outcome.

    Create at least two classification fields in your data: agent_type for the machine’s apparent job and verification_status for the strength of the identification. Keep the values independent. A request can look transactional while its claimed identity remains unverified.

    Build an evidence chain from request to outcome

    A continuous glowing trail links an incoming machine request to a gateway, server records, an action event, and a completed purchase.

    Attribution becomes credible when you can follow an agent from an incoming request to a server-confirmed action. A dashboard label such as “AI traffic” is not enough. You need a chain of evidence that survives redirects, browser changes, authentication, and the absence of JavaScript events.

    Capture the request before classifying it

    Preserve the raw evidence in your CDN, load balancer, or application logs before a bot filter removes it. For each relevant request, capture:

    • A UTC timestamp and a unique request ID.
    • The HTTP method, normalized route, response status, and response size.
    • The full user-agent value as received, plus the parser’s normalized result.
    • The source network information needed for verification.
    • Referrer and origin headers when present, without treating their absence as proof of anything.
    • Whether a first-party session was present or created.
    • A pseudonymous account or customer identifier when the request was legitimately authenticated.
    • The resulting application event, such as search performed, form accepted, cart updated, or order confirmed.

    Do not log authorization headers, passwords, payment details, complete form bodies, or sensitive query-string values for the sake of attribution. Strip or tokenize sensitive fields before they reach the analytics store. The useful connection is between a request identifier and a confirmed event, not between a marketing report and a copy of the user’s private data.

    Instrument the business action on the server

    A page view tells you that an agent requested a page. It does not tell you that a form was accepted, an account changed, or a payment completed. Emit a first-party server-side event only after the application confirms the action.

    Give that event its own ID and record the initiating request ID, event time, action type, outcome, and any internal transaction or lead identifier. If the event represents money, use the same finalized value your order system recognizes. Failed submissions and abandoned workflows belong in diagnostic reporting, not completed-conversion totals.

    Make an agent-to-human handoff observable

    Many useful agent journeys will not end inside the agent. The machine may find a product or prepare a configuration, then send the user into a browser to review, authenticate, or pay. Standard last-click attribution can give the browser all the credit because the earlier agent request had no ordinary campaign parameter or client-side session.

    When you control the handoff, attach an opaque, first-party handoff token to the destination URL. The token should identify a journey record, not expose an email address, prompt, account number, or other personal data. Expire it, prevent it from granting access, and associate it with the eventual conversion only after your server validates it. If the user is already authenticated, an internal pseudonymous account key can provide the connection without placing identity in the URL.

    If you cannot observe a deterministic handoff, do not manufacture one from matching timestamps or similar page paths. You may analyze those patterns in aggregate, but label the result as discovery influence rather than an assisted conversion.

    Recognize Google-Agent without weakening security

    An abstract automated agent passes through layered identity checks at a secure gateway while unverified requests are blocked.

    Google-Agent creates a useful distinction between continuous crawling and a request made while an AI system performs a user-initiated task. Google introduced it for agents hosted on its infrastructure, including experimental systems such as Project Mariner, and provided network ranges for desktop and mobile agent activity.

    That identity gives you a better starting signal, not a substitute for authentication. User-agent strings are supplied by the requester and can be copied. Never allow an account action, bypass a challenge, or relax a security rule solely because a request calls itself Google-Agent.

    Use confidence-based verification

    Apply the same verification pattern to Google-Agent and any other named agent:

    1. Match and preserve the claimed user-agent identity.
    2. Compare the source with the provider’s published network information and keep that information current.
    3. Check whether the request pattern is consistent with the claimed function, including the routes, methods, timing, and workflow sequence.
    4. Record the result as verified, probable, or unverified rather than reducing all three states to a boolean bot flag.
    5. Apply normal authorization, rate limiting, abuse detection, and transaction controls regardless of the identity label.

    This approach is more defensible than a single allowlist. It also reflects how large-scale AI traffic was classified: user-agent strings were combined with infrastructure signals and activity characteristics because self-reported bot identities do not capture every AI-driven request reliably.

    Test the paths that matter

    Review your CDN and web application firewall logs for named agents before changing any rule. Then test product search, detail pages, forms, sign-in, account functions, cart operations, and checkout with non-production accounts and non-chargeable test transactions where your systems support them.

    Look for redirects that loop, challenges that cannot be completed, required state that disappears between requests, and successful browser screens backed by failed server actions. Keep intentional security denials in place. The goal is to remove accidental incompatibility, not to give automated clients a privileged route into sensitive workflows.

    Report agent contribution without false precision

    Your reporting should tell operators what happened and tell decision-makers how certain the attribution is. One blended “AI conversions” number cannot do both.

    Use four mutually exclusive outcome states:

    • Agent-executed: A verified or explicitly qualified agent request is linked to a server-confirmed conversion that the agent performed.
    • Agent-assisted: An observable first-party handoff or authenticated journey connects agent activity to a later human conversion.
    • Discovery-only: An agent retrieved relevant content, but no deterministic connection to an individual outcome exists.
    • Unresolved automation: Automation was detected, but its identity, purpose, or relationship to an outcome remains uncertain.

    Do not add agent-executed and agent-assisted credit if they describe two stages of the same conversion. Keep a deduplicated conversion ID, choose a primary status, and retain the touch sequence separately for analysis.

    Your operational dashboard should cover three layers. The access layer needs request volume by agent type, verification state, route group, response status, and security disposition. The workflow layer needs starts, successful steps, failures, and confirmed completions for each key action. The business layer needs deduplicated leads, orders, revenue where applicable, and the four attribution states above.

    Choose an assistance window that reflects your actual buying cycle and publish that rule beside the metric. There is no defensible universal window in the available evidence. A short handoff into checkout and a long enterprise evaluation should not inherit the same arbitrary assumption.

    Establish the baseline even if named-agent volume is initially small. A rise in training access may affect infrastructure cost and content-control decisions without changing revenue. A rise in verified product-search and account activity deserves workflow testing. Repeated checkout attempts with no confirmed outcomes point to a technical or security investigation, not automatically to weak demand.

    Start with one path that matters commercially: discovery, a product or service page, and its next meaningful action. Join the request logs to one server-confirmed outcome, preserve uncertainty as an explicit field, and make that narrow chain trustworthy before expanding it across the site. That gives you a measurement system you can extend as agents become more capable, without rewriting history around traffic you never truly identified.

    References


  • First-Party Customer Data Has Limits: A Practical Audit

    First-Party Customer Data Has Limits: A Practical Audit

    You’ve centralized customer accounts, transactions, campaign responses, and support history. The profiles look complete. Yet audiences come back smaller than expected, personalization stops improving, and measurement produces exact numbers that don’t quite match business reality.

    The problem may not be a shortage of data. It may be that your systems treat facts captured in the past as proof of what is true now. Once you separate historical evidence from current identity, activity, and intent, you can make first-party data far more dependable without pretending it is complete.

    First-party data records an event, not a permanent truth

    An account registration proves that someone supplied a set of details at a particular moment. A purchase proves that a transaction occurred. A support ticket proves that someone asked a question through a particular channel. Those facts can remain accurate even after the customer’s address, primary email, job, device, needs, or habits have changed.

    This is the first limit to understand: first-party describes the relationship through which data was collected. It does not certify that every field is fresh, complete, correctly attributed, or suitable for every future decision.

    Identity anchors such as email addresses, logins, and device links can lose alignment as people change accounts, locations, jobs, devices, and digital habits. The database may still accept those identifiers. That does not mean they still represent the same active person in the same way.

    Treat each customer record as a set of claims supported by different evidence:

    • Event truth: Did the recorded interaction happen?
    • Identity truth: Do the identifiers still belong to the person you think they do?
    • Activity truth: Is that identity still active and reachable through the relevant channel?
    • Intent truth: Does the historical behavior still describe what the person wants?

    A purchase can provide strong event evidence and weak current-intent evidence. A recently used login can support current activity without proving purchase intent. An active email address can support reachability without proving that the same individual still controls it. If your data model collapses these distinctions into one unified customer profile, the profile will look more certain than its underlying evidence.

    Where first-party customer profiles lose reliability

    Freshness varies by attribute

    Historical facts and current attributes do not age in the same way. The date and value of a completed order remain part of the customer’s history. The shipping address attached to that order should not automatically become a claim about the customer’s current residence. A declared preference may still be useful, but its age should be visible whenever it drives a recommendation.

    Do not assign one freshness status to an entire profile. Track freshness at the field or claim level. Otherwise, one recent event can make unrelated, older attributes appear current.

    Identity resolution can combine errors as efficiently as facts

    A customer data platform or identity graph follows the identifiers and matching rules it receives. If two records share an anchor, the system may connect them. If one person uses several accounts, the system may leave them fragmented. The resulting profile can be technically consistent with the rules and still fail to represent one real person accurately.

    Resolution therefore needs its own evidence. Store which identifiers caused a merge, whether the connection was directly authenticated or inferred, when the link was last supported, and what contradictory signals exist. A unified profile is an output of a model. It is not independent proof that the model identified the customer correctly.

    Your owned interactions reveal only part of the customer

    First-party data shows what a person did within the touchpoints you can observe. It usually cannot tell you what changed outside those boundaries. A customer may solve a problem elsewhere, switch priorities, adopt a different platform, or stop considering the category without generating an event in your systems.

    This creates a dangerous interpretation error: no new activity is treated as continued interest, lost interest, or customer inactivity depending on what the team wants the absence to mean. In reality, missing activity is simply missing evidence until another signal supports a conclusion.

    Validity, reachability, and intent are different tests

    A correctly formatted identifier may be invalid. A valid identifier may be dormant. An active channel may reach the right person at the wrong time. Even successful delivery does not prove interest in the offer.

    The distinction also matters in fraud and risk workflows. A plausible-looking identity can lack evidence of ongoing human activity, but dormancy alone does not establish that an identity is false. Use activity as one part of an evidence set, not as a universal verdict.

    Precise reporting can conceal an uncertain denominator

    Your warehouse can count records exactly. The difficult question is what those records represent. A database total may include duplicate people, abandoned accounts, unreachable addresses, uncertain matches, and customers whose last meaningful interaction is no longer relevant to the decision being measured.

    This is why campaign reach can disappoint even when the audience query is correct. The query selected the requested records; the business assumption that every selected record represented a current, reachable customer was the part that failed.

    Build a validation layer instead of collecting more fields

    Abstract customer data passes through transparent filters that separate uncertain historical signals from verified current signals before forming an incomplete profile.

    More attributes do not repair uncertain identity. They can make the uncertainty harder to see. A better approach is to preserve the evidence, age, and status of each important claim so the activation system can decide whether that claim is fit for a particular use.

    Separate observed, declared, resolved, and inferred data

    • Observed data records an interaction, such as an order, login, or campaign response.
    • Declared data records what a person supplied, such as a role, preference, address, or account detail.
    • Resolved data links records or identifiers believed to represent the same person.
    • Inferred data estimates an attribute, intent, segment, or likely next action from other evidence.

    Keep those classes visible downstream. An inferred preference should not silently overwrite a declared preference. A resolved relationship should not be presented as though the customer directly confirmed it. A model output should retain the inputs, method, and time context needed to evaluate it.

    Attach an evidence record to decision-critical attributes

    For every field used to select, suppress, personalize, measure, or assess a customer, capture the metadata needed to answer these questions:

    • Which interaction or system produced the value?
    • When was it first captured?
    • When was it last confirmed by relevant activity?
    • Was it supplied directly, observed, matched, or inferred?
    • Which identifiers connect it to the current profile?
    • Is the claim current, stale, unknown, or contradicted?
    • Which team owns the rule that changes its status?

    A field should not become current merely because a pipeline copied it yesterday. Preserve the time of the underlying customer evidence separately from the time the record was processed.

    Set freshness rules around the decision

    There is no useful universal expiration rule for every kind of customer data. Ask what could change, what evidence would reconfirm it, and what happens if you are wrong.

    An old order may remain fully valid for historical revenue analysis while being weak evidence for immediate product intent. An unconfirmed identity link may be acceptable for exploratory analysis but inappropriate for suppressing a person from an important message. A stale preference can still support a cautious default if the experience gives the user an easy way to correct it.

    Make eligibility depend on the use case. A claim can remain stored while being excluded from activation. This is more useful than deleting everything old or allowing everything historical to masquerade as current.

    Use activity signals without turning them into identity truth

    Email can function across authentication, commerce, subscriptions, support, and other digital touchpoints, which makes it a useful identity anchor and a potential source of activity evidence. Current activity can help distinguish reachable identities from ones that have faded from view.

    Keep the conclusion narrow. Evidence that an address is active does not, by itself, prove who controls it, whether the person wants your message, or whether a profile merge is correct. Combine channel activity with authenticated interactions, transaction history, explicit customer updates, and contradiction checks where those signals are available and permitted.

    If you obtain activity or identity evidence outside your direct customer relationship, label its provenance separately. Enrichment does not become first-party merely because its output is stored in your warehouse. Preserve consent, purpose restrictions, access controls, and retention requirements instead of allowing the unified profile to erase how the data was obtained.

    Audit the customer decisions that depend on the data

    An analyst inspects broken and intact paths connecting abstract customer data tiles to marketing, delivery, support, and retention decisions.

    A database-wide cleanup is easy to start and hard to finish because it has no single definition of correct. Begin with one live decision whose outcome you can observe: sending a campaign, choosing a personalized experience, counting active customers, merging accounts, or reviewing an identity for risk.

    • Write the decision in one sentence.
    • State what must be true about a person for the decision to be correct.
    • Trace every field, identifier, join, model, and suppression rule used.
    • Mark the last customer evidence behind each decision-critical claim.
    • Identify where missing evidence has been converted into an assumption.
    • Feed the resulting delivery, response, correction, merge, or rejection back into identity status.

    The audit should test business meaning, not just schema validity. A non-null email field passes a database check. It does not necessarily pass the business test for a reachable, permitted, correctly identified recipient.

    DecisionWhat the data can establishWhat it does not establishPractical control
    Send a customer emailAn address and permission status were recordedThe address is active, still controlled by the same person, and currently permitted for this purposeCheck current permission, channel status, suppression evidence, and identity confidence before selection
    Personalize an experienceThe person previously behaved a certain way or declared a preferenceThe same intent or preference remains currentWeight current relevant behavior, expose a neutral fallback, and let the customer correct the assumption
    Merge customer recordsSpecified identifiers satisfy the matching ruleThe records unquestionably belong to one humanStore the reason for the link, its confidence, its age, and any contradictory evidence
    Count active customersA defined set of records meets a query conditionEach record represents a distinct, current, reachable personReport resolved, unresolved, duplicate, dormant, and suppressed populations separately
    Attribute an outcomeTracked events form an observable pathThe path contains every influence or every customer interactionState the observable scope and keep unobserved or unresolved activity visible as uncertainty
    Review possible fraudSubmitted identifiers appear valid and satisfy recorded checksA genuine person is actively using the identityCombine permitted activity, identity consistency, contradictions, and proportionate review rather than relying on one signal

    Change the reporting denominator as well. Alongside the number of records selected, show how many have current identity evidence, how many are unresolved, how many were suppressed, and how many produced an observable outcome. This prevents a large historical database from being mistaken for an equally large reachable market.

    Outcome data should improve the next decision. A customer correction should update the relevant claim. A confirmed account merge should strengthen the recorded link. Repeated inactivity may change reachability status without erasing legitimate transaction history. Contradictory activity should reopen an identity decision instead of being discarded because it does not fit the existing profile.

    Key takeaways

    • First-party describes data provenance, not guaranteed freshness, completeness, or identity accuracy.
    • A historical event can remain true while the customer’s current attributes, activity, and intent change.
    • Identity resolution creates a useful model, but the model is only as reliable as its anchors, matching rules, and contradiction handling.
    • Track freshness and confidence at the claim level rather than assigning one quality score to an entire profile.
    • Use activity signals to assess identity vitality and reachability, but do not treat activity alone as proof of ownership, personhood, consent, or intent.
    • Audit one customer decision at a time and report unresolved identities instead of hiding them inside a precise total.

    For your next audience or personalization rule, do not begin by asking how many records are available. Write down what must be true for a person to be eligible, which evidence supports each condition, and when that evidence was last confirmed. Label the unknown cases rather than forcing them into yes or no.

    Once that decision produces a cleaner, explainable result, repeat the method elsewhere. You do not need a mythical perfect customer view. You need a customer view that distinguishes what you observed, what you inferred, when you knew it, and how much uncertainty the next decision must carry.

    References


  • How to Test Emerging High-Intent Advertising Channels

    How to Test Emerging High-Intent Advertising Channels

    You probably don’t need another place to buy impressions. You need access to moments when a buyer is already narrowing a choice: which product to trust, which offer is worth acting on, or which nearby business to visit.

    Reddit’s expanding shopping formats and the prospect of sponsored listings in Apple Maps create two very different ways to reach those moments. The practical question isn’t which channel sounds newer. It is whether the user’s decision, your conversion path, and your measurement system line up well enough to justify a controlled test.

    Start with the decision your customer is trying to make

    A high-intent channel places an ad inside an active decision. That is more useful than simply finding an audience with the right demographic profile, but it doesn’t automatically make every impression valuable. You still need to identify the decision being made and the distance between that decision and revenue.

    On Reddit, the valuable moment is often product investigation or validation. A shopper may already know the category but still be comparing alternatives, checking whether a claim holds up, or looking for reassurance from people with relevant experience. Reddit reports that shopping discussions increased 40% over the previous year and 84% of shoppers felt more confident after browsing the platform. Those are platform-supplied figures, so treat them as evidence of the use case rather than a forecast for your campaign.

    Apple Maps would capture a different decision. Someone searching a map is often choosing where to go, which nearby provider fits the need, or whether a location is practical. The proposed advertising model would allow retailers and brands to bid on search terms and appear as sponsored businesses in Maps results. That could put an advertiser close to a local action, but the channel should remain on your watchlist until Apple confirms availability, eligibility, targeting, reporting, and market coverage.

    The simplest distinction is useful: Reddit can influence what someone chooses, while a map can influence where someone goes. Before assigning budget, complete this sentence: “When the ad appears, the customer is deciding whether to _____.” If the blank contains only “notice our brand,” you haven’t established a high-intent use case.

    • For ecommerce, name the product decision: compare, validate, switch, replenish, buy a bundle, or respond to a deal.
    • For local campaigns, name the destination decision: visit, call, book, order, request directions, or confirm that a location can meet the need.
    • Define the next observable action. A vague goal such as engagement will not tell you whether the channel reached the intended decision.
    • Identify existing demand that could be recaptured by the ad. A branded map query or a loyal customer’s repeat purchase may look efficient without creating incremental revenue.

    Match the channel to your conversion geometry

    Two contrasting customer paths show online shoppers moving from a discussion to checkout and a mobile user following a map route to a storefront.

    Channel selection should follow the shape of your business. Reddit’s shopping tools are built around products, catalogs, visual context, social proof, and offers. A map-based auction would be built around queries, locations, and local actions. Those aren’t interchangeable forms of intent.

    Channel opportunityDecision momentStrongest initial fitCritical dependencyUseful outcome
    Reddit Dynamic Product and Collection AdsProduct discovery, comparison, validation, or deal evaluationEcommerce businesses with a maintained catalog and products that benefit from explanation, context, or community discussionAccurate product feed, functioning conversion measurement, suitable creative, and relevant product economicsIncremental orders and contribution margin from the exposed product set
    Proposed Apple Maps sponsored listingsSelection of a nearby business, retailer, service, or destinationBusinesses with physical locations or genuinely local conversion pathsAccurate location records, a fast route to calling or booking, store-level measurement, and confirmed platform accessIncremental qualified local actions and revenue attributable to participating locations

    Reddit is the clearer near-term candidate when revenue depends on a product catalog and buyers actively seek peer context. Collection Ads combine a lifestyle image with purchasable product tiles, while community and deal overlays can add platform-native proof or price information. That combination is most useful when the context helps a buyer choose among products; it is less compelling if your catalog is thin, your feed is unreliable, or the purchase requires no meaningful evaluation.

    Apple Maps is the stronger planning candidate when location is part of the conversion itself. A restaurant, clinic, retailer, repair service, or other location-based business can plausibly benefit from appearing while someone chooses a destination. An online-only business with no local fulfillment path would have a much weaker reason to prepare.

    Do not choose between them by comparing audience size or headline ROAS. Ask where your buyer experiences uncertainty. If the uncertainty is “Which product should I trust?”, test a product-research environment. If it is “Which nearby business should I use?”, prepare for a map environment. If neither question describes your customer, these channels may be interesting without being relevant.

    Make your data launch-ready before you buy traffic

    New ad inventory can be inexpensive because competition is limited. It can also be expensive to learn on because integrations, reporting, and optimization patterns are immature. The best early-mover advantage is operational readiness: you can run a clean test while other advertisers are still repairing feeds, location records, landing pages, and attribution.

    Prepare a product system for Reddit

    Reddit’s Shopify integration is intended to simplify catalog and pixel setup for Dynamic Product Ads, but it was described as an alpha-stage integration. Alpha status matters. It can imply limited access, changing behavior, or incomplete workflows, so don’t make the integration a dependency until your account is eligible and the setup works with your catalog.

    Before launching, inspect the records that determine which product can be shown and what happens after the click:

    • Use stable identifiers for products and variants so ad events can be reconciled with orders.
    • Check that titles distinguish products clearly without relying on internal naming conventions.
    • Verify that price, availability, destination URL, product image, and variant information agree across the feed and landing page.
    • Separate products with materially different margins, return patterns, or discount sensitivity. Revenue can hide a poor product-level result.
    • Confirm that view, product, cart, checkout, and purchase events occur in the expected sequence and do not fire twice.
    • Build creative around the buyer’s unresolved question. A lifestyle image should supply context, not merely duplicate the product tile.
    • Document which discounts are intentional before enabling deal-oriented messaging. An automated price signal can accelerate a bad promotion as easily as a good one.

    Community labels and deal overlays may reduce hesitation, but they should not carry the entire sales argument. The landing page still needs to answer the questions the ad raises: what the product is, who it suits, how variants differ, what it costs, and what the buyer should do next.

    Prepare a location system for Apple Maps

    Apple Maps sponsored listings remain a reported advertising plan, not inventory you should assume is universally available. Preparation should therefore concentrate on reusable local-search assets rather than speculative campaign settings.

    • Create a canonical record for every location: business name, category, address, phone number, operating hours, URL, and available services.
    • Assign ownership for temporary closures, holiday hours, relocations, and duplicate records. Stale location information wastes paid clicks and damages trust.
    • Give each location a destination page that helps the visitor complete a local action rather than dropping everyone on the home page.
    • Map non-branded local needs to eligible locations. Keep branded or navigational queries separate if the eventual campaign controls permit it.
    • Decide how calls, bookings, orders, visits, and store revenue will be connected to campaign exposure before spending begins.
    • Record your current store-level baseline. Without it, a future lift can be mistaken for seasonality, a promotion, or normal location variance.

    Do not design a detailed Apple Maps bidding structure around controls that Apple hasn’t confirmed. A keyword list, location inventory, conversion taxonomy, and baseline dataset are portable. Assumptions about match types, reporting windows, auction controls, or optimization goals are not.

    Keep ad data, page content, and structured data aligned

    Your advertising feed, visible page content, analytics events, and structured data should describe the same product or location. For products, align identifiers, variants, price, availability, currency, and canonical URLs. For locations, align the business identity, address, phone number, hours, service area, and destination URL.

    This is where SEO, AEO, GEO, and paid-media operations meet: not through a magical ranking shortcut, but through a shared factual layer. When the feed advertises one price, the page shows another, and Product markup exposes a third, performance diagnosis becomes needlessly difficult. The same problem appears when a local ad leads to an outdated location page.

    Treat Schema.org markup as data hygiene, not as an ad-auction lever. Unless a platform explicitly documents a connection, don’t promise that Product or LocalBusiness schema will create eligibility, improve ad rank, or lower media costs. Its practical value here is consistency, machine-readable context, and easier auditing across the discovery journey.

    Run an incrementality test, not a launch celebration

    An analyst observes two matching glass test environments, with campaign light applied to one group and the other kept neutral as a control.

    Emerging channels produce noisy early results. Tracking may be incomplete, algorithms have less account history, and a launch can coincide with promotions or seasonal demand. A narrow test protects your budget and gives you a better chance of learning what caused the result.

    1. Write a falsifiable thesis. Name the audience context, the decision moment, the promoted products or locations, the expected action, and the economic reason the channel could work.
    2. Choose a bounded test cell. Use a defined product group, location group, market, or campaign period rather than exposing the entire business on day one.
    3. Create a comparison. Depending on volume and operational constraints, use a matched product set, comparable locations, a geographic holdout, or a stable pre-test baseline. Document promotions and other media changes that could contaminate it.
    4. Set a budget cap and loss limit before launch. New inventory is not permission to spend indefinitely while waiting for optimization. The downside is real media cost plus the opportunity cost of staff time and promotional margin.
    5. Use a measurement window that reflects the actual buying cycle. Don’t force a local same-day action and a considered ecommerce purchase into the same evaluation rule.
    6. Evaluate incremental economics. Separate revenue that likely would have occurred anyway, especially branded queries, existing-customer purchases, and navigational searches.
    7. End with a decision. Scale, revise, pause, or reject the channel based on the original thesis. Avoid extending a weak test merely because the platform is new.

    Treat platform benchmarks as hypotheses

    Reddit reported that its Dynamic Product Ads generated 91% higher average ROAS year over year in Q4 2025. It also associated Collection Ads best practices with an 8% ROAS improvement. In the Liquid I.V. example, Dynamic Product Ads represented 33% of the brand’s Reddit revenue and outperformed other conversion campaigns by 40%.

    Those figures justify a test case, not a budget forecast. They combine platform-level reporting and a named advertiser example, neither of which tells you your likely incrementality, margin, product mix, audience saturation, or creative quality. Put them in the planning deck under “why investigate,” not under “expected result.”

    Read profit alongside ROAS

    ROAS divides attributed revenue by ad spend. It does not account for gross margin, discounts, returns, fulfillment, agency costs, or sales that would have happened without the ad. A channel can post attractive ROAS while destroying contribution margin.

    For ecommerce, compare incremental revenue with product margin, promotional cost, returns, and media spend at the product-set level. For local campaigns, connect qualified calls, bookings, orders, or visits with store-level revenue wherever your systems and consent framework allow it. If offline revenue cannot be connected reliably, say so in the result rather than replacing it with clicks.

    Watch branded demand separately. A sponsored result that intercepts someone already searching for your exact business may be useful defensively, but it is not equivalent to acquiring a new customer. Your report should distinguish demand creation, decision influence, and demand capture.

    Key takeaways

    • Reddit and Apple Maps represent different intent moments: product validation versus local destination selection.
    • Reddit is actionable for suitable ecommerce advertisers; Apple Maps should remain a prepared watchlist opportunity until launch details and access are confirmed.
    • Choose a channel by the customer’s unresolved decision and your measurable conversion path, not by novelty or audience size.
    • Repair catalog, location, event, landing-page, and structured-data inconsistencies before paying to amplify them.
    • Use vendor benchmarks to justify investigation, never to predict your own ROAS.
    • Judge the test on incremental contribution and qualified business outcomes, with branded or existing demand reported separately.

    Your next move is small and concrete. Write one channel thesis, choose one product or location cohort, audit the data that cohort depends on, and define the comparison you will use. If those four pieces don’t hold together on paper, keep the budget. If they do, you have a test worth running when the inventory is available.

    References