Tag: AI Search

  • AI Search Visibility: How Prompts and Rankings Shape Citations

    AI Search Visibility: How Prompts and Rankings Shape Citations

    AI search visibility is not one universal ranking contest. A page’s chance of appearing in an answer depends on what the user asks, whether the AI searches the live web, which search index it consults and how easily the page can support the requested response.

    The two source reports illuminate different parts of that process. One maps prompt patterns across healthcare, B2B and ecommerce; the other examines when Claude reportedly searches and how Brave Search rankings affect its citations. Together, they suggest a practical strategy built around prompt demand, retrieval eligibility and answer-ready evidence.

    A prompt can change whether an AI searches at all
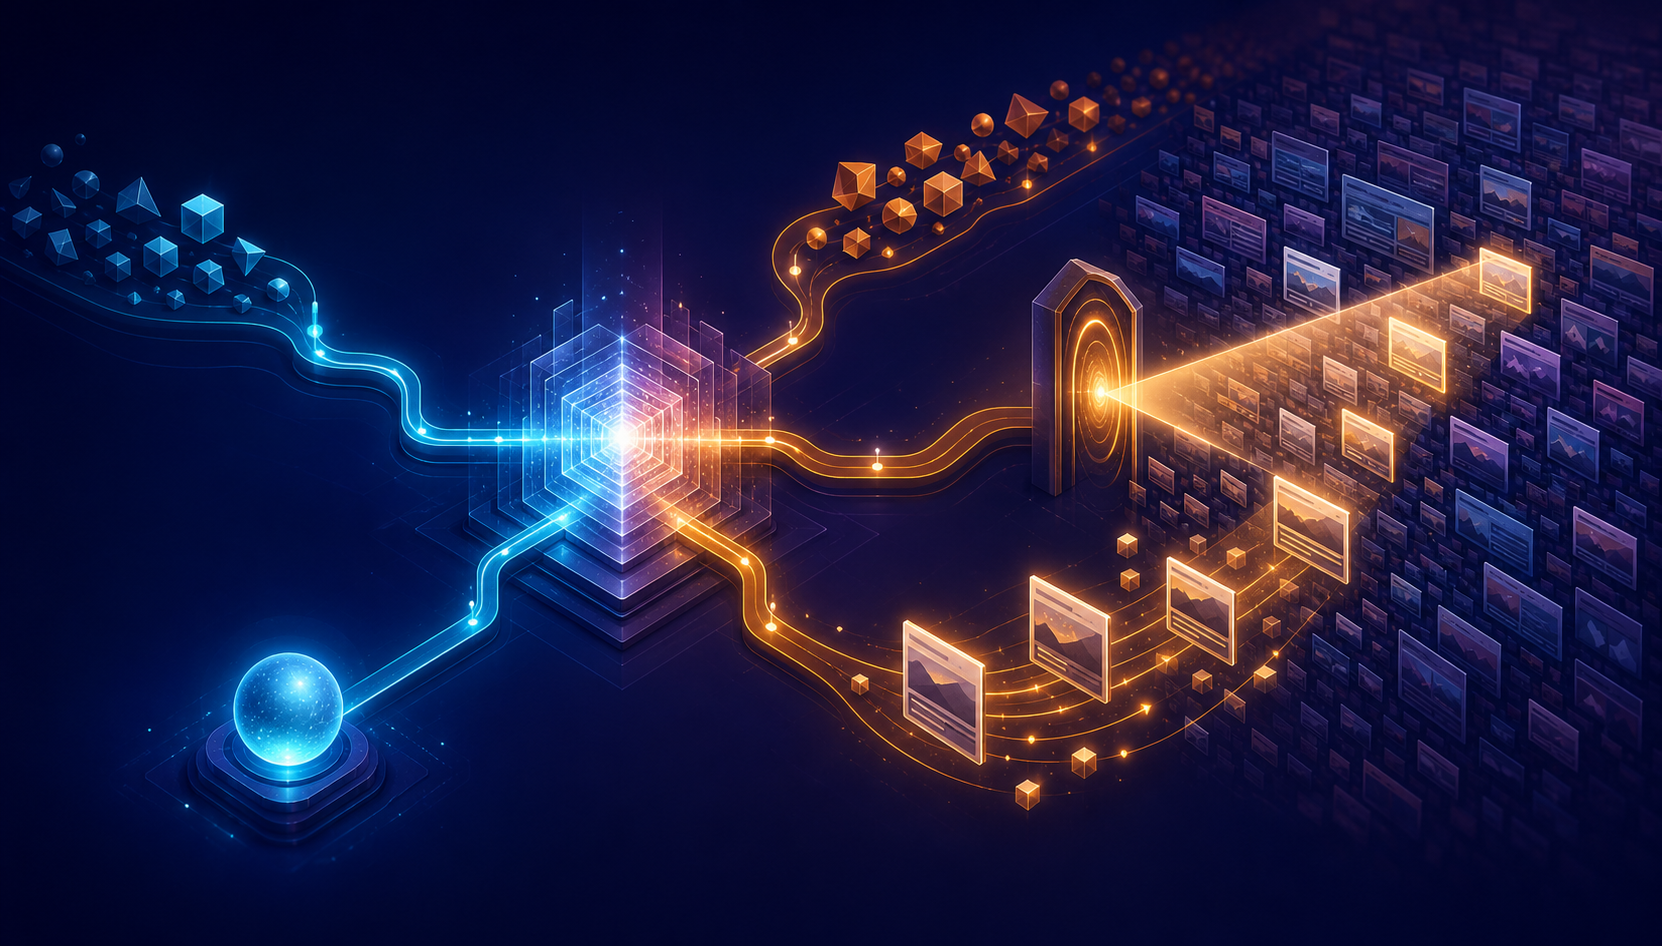
    Two abstract prompts enter an AI core, with one leading directly to an answer and the other triggering a search across web pages.

    AI answers can draw on information already represented in a model or retrieve material from the web. That distinction matters because a page cannot earn a live citation in an answer when no web search takes place.

    The Claude visibility report attributed to Jonathan Clark said Claude used web search in 36.6% of the observed cases, compared with about 90% for ChatGPT. It also reported that Claude was more likely to search when prompts signaled recommendations, rankings, location, recency or direct comparison. Definition and process formulations such as how something works, what something is or which steps to follow were reportedly less likely to trigger a search.

    Prompt signalReported Claude web-search rateLikely information need
    Best81%Recommendation or shortlist
    Ranking-focused67%Ordered evaluation
    Location55%Geographically relevant information
    Comparison51%Trade-offs between alternatives

    These figures come from the reported analysis and should not be treated as universal platform benchmarks. Their strategic value lies in the pattern: prompts that require fresh, comparative or context-dependent evidence appear more likely to create a retrieval opportunity than prompts that can be answered from general model knowledge.

    Search rankings matter, but visibility does not transfer cleanly

    The Claude report said the system frequently relied on Brave Search for web retrieval and incorporated Brave’s top 10 results without rearranging them. If that behavior holds for a target prompt set, Brave ranking becomes a measurable eligibility layer: content must first enter the retrieved result set before it can be considered for citation.

    At the same time, the sources caution against treating conventional rankings as a complete proxy for AI visibility. The prompt-pattern report cited research as finding that more than 80% of links in AI-driven searches came from domains outside the traditional top search results. By contrast, the Claude analysis reported a 64% overlap between Claude’s results and Google rankings, while Claude and ChatGPT citations matched in only 8% of cases for the same queries.

    Those measurements describe different systems and apparently different analyses, so they should not be combined into a single benchmark. The useful synthesis is that ranking influence is engine-specific. Google performance may have some relationship with Claude visibility, Brave may directly affect Claude’s retrieved candidates, and neither reliably predicts which sources ChatGPT will cite.

    The Claude report also said query fan-outs returned the same results across users 65% of the time and frequently included years. Clark suggested that a current year in a title might help with some ranking- and recency-driven searches. That is a testable hypothesis, not a reason to add dates indiscriminately: a dated title should correspond to genuinely maintained content.

    Industry prompts determine what evidence a page must provide

    Retrieval is only the first gate. Once a page is available to an AI system, its usefulness depends on whether it contains the facts, relationships and qualifications needed for the user’s prompt. The prompt-pattern report described markedly different expectations by vertical.

    VerticalReported prompt patternContent implication
    HealthcareSymptoms combined with personal context, medication considerations and safety thresholdsOrganize information around symptom combinations, risk factors, cautions and clear guidance on when professional help may be needed.
    B2BVendor comparisons shaped by company requirements, implementation effort and return on investmentPublish transparent comparison criteria, technical details, timelines and substantiated commercial evidence in extractable formats.
    EcommerceQuality and review signals combined with budgets, use cases and exclusionsConnect crawlable reviews, product attributes, constraints and specifications to practical buyer outcomes.

    This changes the unit of optimization. An isolated keyword may identify a subject, but a prompt often expresses a decision that must be made. A healthcare reader may need to distinguish monitoring from urgent action; a B2B buyer may need to defend a purchase; an ecommerce shopper may need to eliminate products that fail a specific constraint. Content designed only to define the topic can be relevant in a broad sense yet still lack the evidence required for the answer.

    The same principle explains the value of headings, concise answer passages, comparison tables, structured product information and crawlable supporting detail. The prompt-pattern report said optimization for direct citations and structured information could improve visibility by as much as 40%, citing research from Princeton and the Allen Institute for AI. Because that figure is relayed through the source rather than independently established here, it is best treated as directional support for extractability rather than a guaranteed uplift.

    Measure the path from prompt to citation
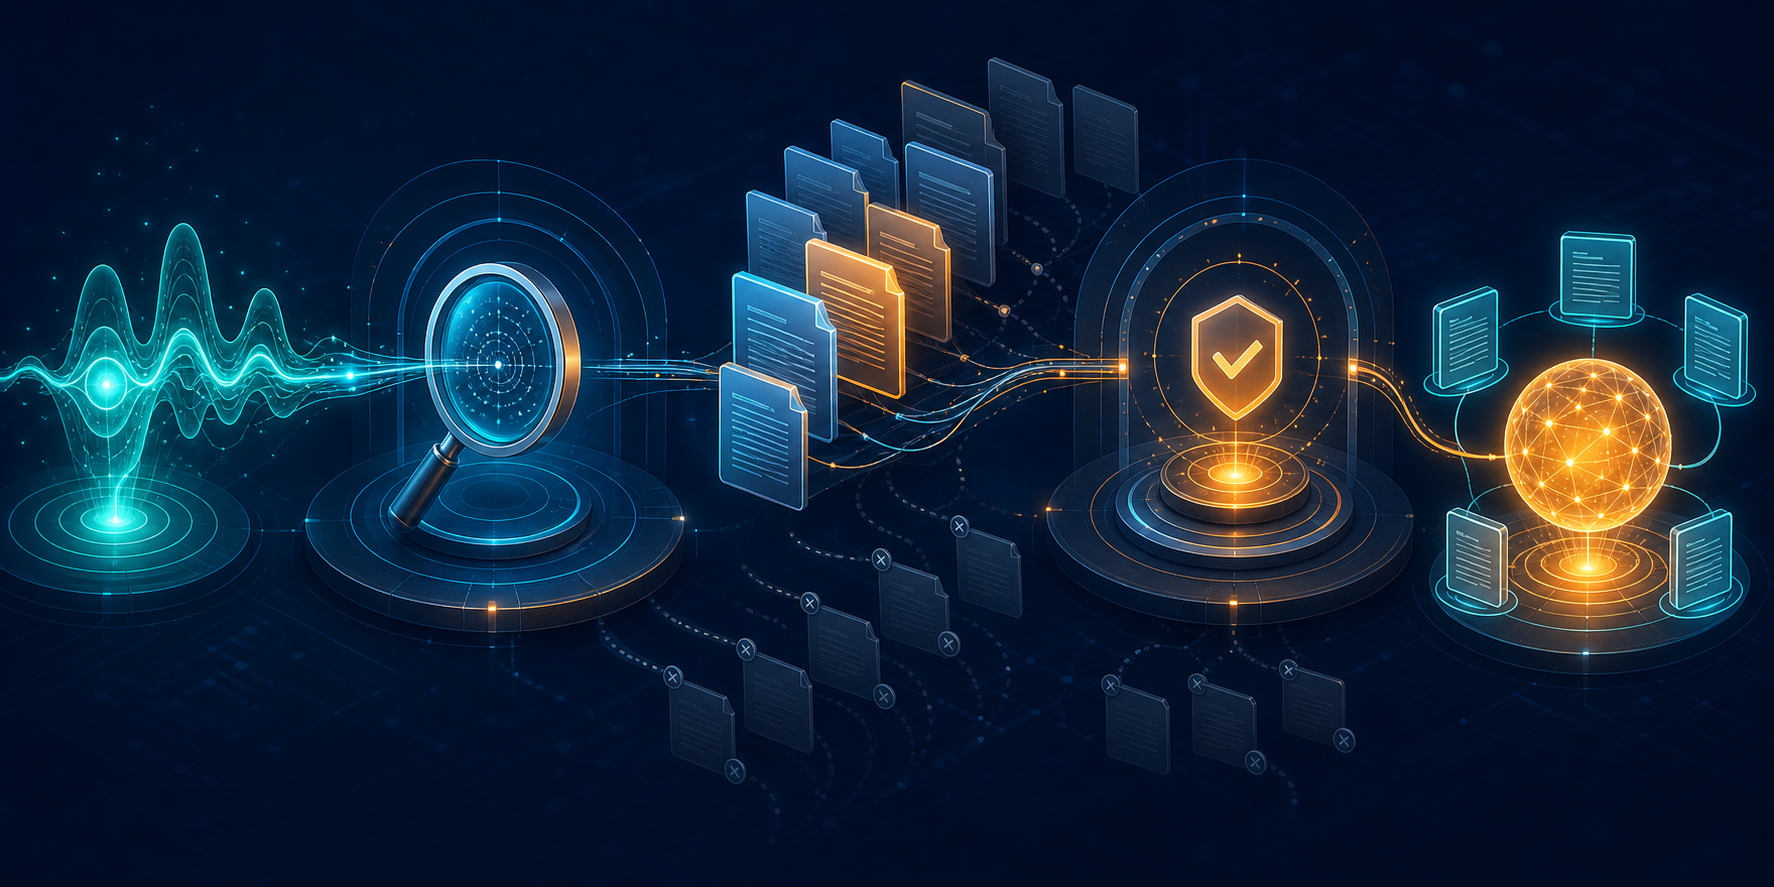
    A query travels through search, ranked pages, and an evidence checkpoint before selected source cards connect to an AI-generated answer.

    Prompt coverage

    Research should begin with realistic prompt classes rather than a renamed keyword list. Search logs, customer questions, sales conversations and support interactions can reveal the attributes people combine, the comparisons they request and the follow-up questions that shape a decision. Each important class should include enough context to represent the actual task.

    Retrieval eligibility

    Testing should record whether an AI searches the web for each prompt, which query variations it generates and which domains appear in the underlying search results. For Claude prompts involving recency, rankings or comparisons, the source report indicates that Brave deserves specific attention. Traditional Google tracking remains useful, but it should not stand in for direct observation of the answer engine being evaluated.

    Answer inclusion

    A retrieved page still has to be selected, represented accurately and cited. Measurement should therefore distinguish ranking in the source engine from appearing in the AI answer. Repeated tests can track whether the brand is mentioned, whether its page is cited, which passage appears to support the response and whether competitors provide evidence the page lacks.

    Key takeaways

    • Prompt structure affects both the likelihood of live retrieval and the evidence an answer requires.
    • Search rankings can create citation eligibility, but the relevant index and degree of overlap vary by AI system.
    • Healthcare, B2B and ecommerce content need different forms of context, proof and decision support.
    • Readable structure helps only when the underlying information is specific, transparent and responsive to the prompt.
    • Visibility reporting should separate prompt coverage, retrieval rankings and actual answer citations.

    As AI search interfaces evolve, durable visibility will come from testing the whole route between a real audience question and a supported answer. Teams that maintain useful evidence, observe each engine directly and update prompt sets as customer needs change will be better positioned than those relying on a single ranking proxy.
    References

  • 2026 GEO Agency Rankings: What Changes by Industry

    2026 GEO Agency Rankings: What Changes by Industry

    A useful 2026 GEO agency ranking is not a universal league table. The supplied studies evaluate agencies within solar, pharmaceutical, senior living, biotech, and marine markets, where the evidence needed to earn an AI recommendation can differ substantially.

    Read together, the reports offer something more valuable than five isolated winner lists: a framework for separating broadly capable GEO firms from agencies whose sector knowledge, regulatory processes, or commercial specialization may make them the better fit.

    Key takeaways

    • AI visibility is the common measurement thread, but the platforms, scoring methods, and disclosed weights differ across the reports.
    • Industry context changes what visibility must accomplish: pharmaceutical GEO emphasizes credible, compliant information, while senior living GEO connects family discovery with occupancy and lead nurturing.
    • First Page Sage, Genevate, and Signal Hill Strategies recur across the pharmaceutical and senior living coverage, indicating cross-sector range within the supplied evidence.
    • Specialists can be more suitable than an overall leader when sector expertise, scientific depth, automation, or a particular commercial model is the decisive requirement.
    • The rankings are best used to create a shortlist. Buyers still need to verify query coverage, measurement methods, governance, and the relationship between AI visibility and business outcomes.

    Each industry ranking answers a different question

    The five studies share a GEO label, but their reported scopes show why an agency can be highly relevant in one ranking without automatically leading another. Four reports describe a combined 156 agency evaluations before accounting for any overlap: 38 in solar, 42 in pharmaceuticals, 47 in senior living, and 29 in marine marketing.

    IndustryReported research scopeDistinctive emphasis in the sourceHow to interpret the ranking
    Solar38 agencies evaluated from January through May 2026AI citations, notable clients, leadership experience, and additional proprietary factorsThe study points toward citation performance and sector credibility, but the supplied excerpt does not expose the complete ranked table or weighting formula.
    Pharmaceutical42 agencies evaluated in early 2026GEO services, visibility in ChatGPT and Perplexity, leadership, reviews, media references, clients, longevity, and specialtiesAgency fit depends heavily on whether the buyer needs regulated thought leadership, PR, scientific content, lead generation, or an SEO-led program.
    Senior living47 agencies studied from March through June 2026AI visibility, leadership, reviews, client quality, longevity, and media references, with weights disclosedThe ranking connects discovery by families with practical objectives such as lead quality, nurturing, and occupancy.
    BiotechNo sample size is included in the supplied excerptThe field is characterized as new and challenging, with approaches still being refinedClaims should be treated cautiously because the excerpt establishes market immaturity but provides little comparative evidence.
    Marine29 agencies serving recreational boating, commercial maritime, yacht brokerage, marine technology, marinas, and offshore servicesRecognition across ChatGPT, Perplexity, Claude, and Gemini, alongside clients, leadership, reviews, and media referencesThe broad collection of submarkets makes relevant portfolio experience particularly important; a generic marine label may conceal very different audiences.

    The solar report therefore appears to reward an agency’s ability to generate citations and authority in renewable-energy searches. The pharmaceutical study, by contrast, describes work involving clinical milestones, directories, healthcare-professional queries, and regulatory considerations. The senior living report focuses on recommendations used by families and highlights agencies that connect marketing with the journey toward occupancy.

    The marine study widens the interpretation problem further: recreational boating, offshore services, and marine technology are grouped within one evaluation even though their buyers and information needs are not interchangeable. Meanwhile, the biotech article explicitly frames its field as one in which practitioners are still refining their methods. A sector label is consequently a starting filter, not proof of precise market fit.

    The scoring systems are related, but not interchangeable

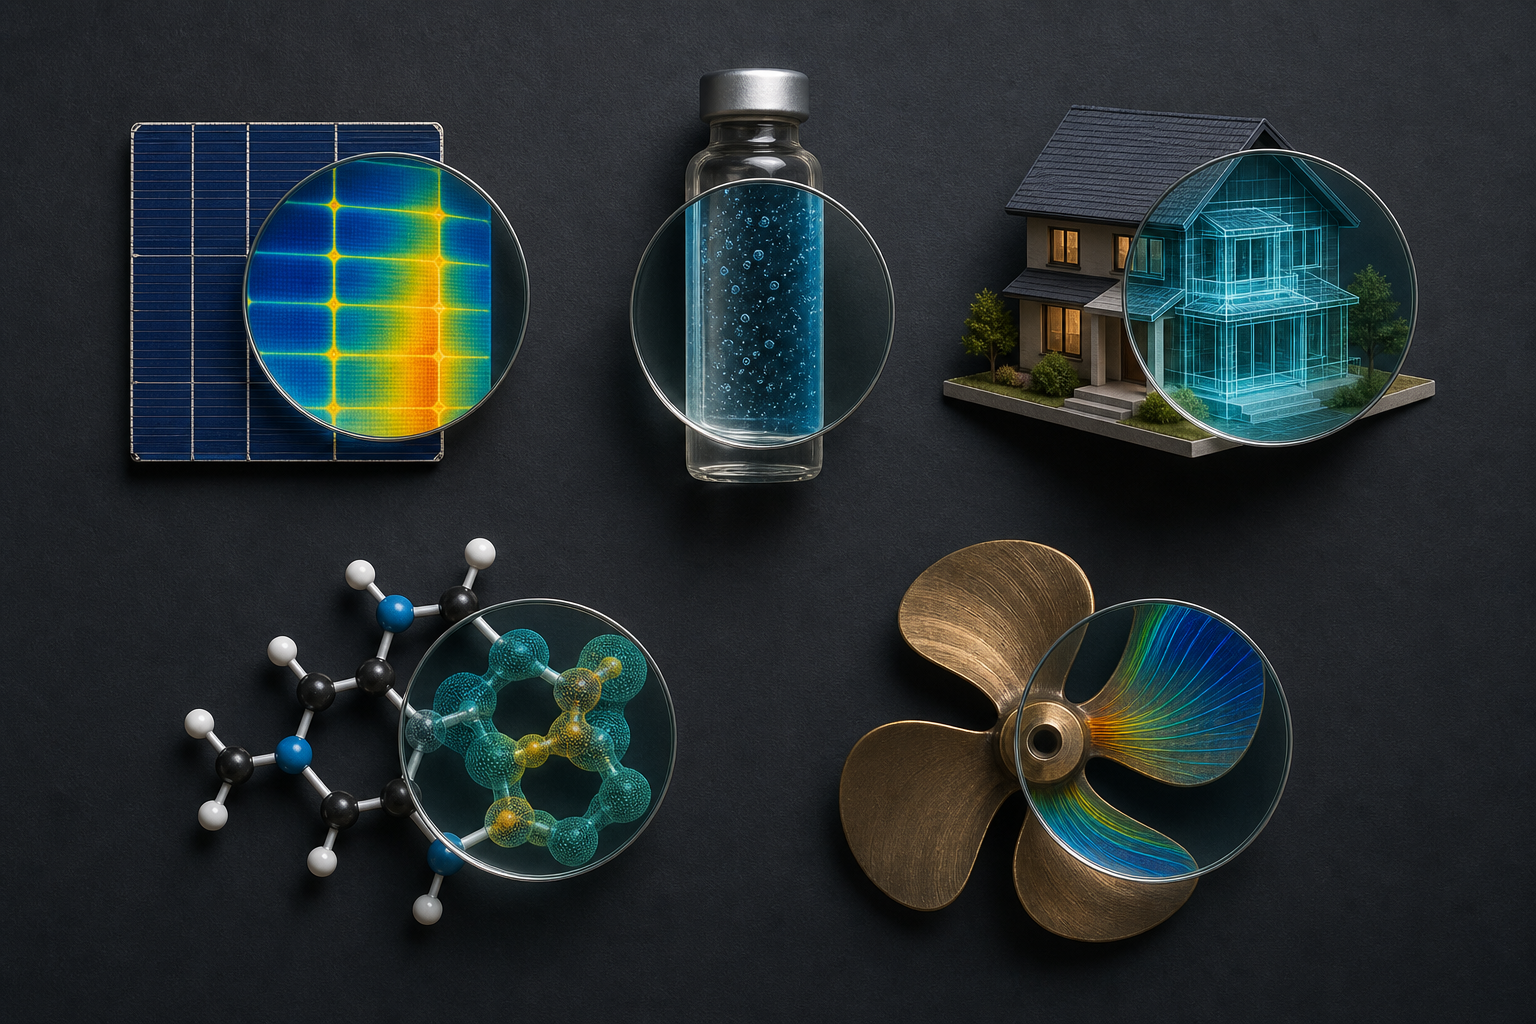
    Five transparent lenses reveal different visual details in objects representing solar, pharmaceuticals, senior living, biotech, and marine industries.

    Across the reports, five recurring signals form a common measurement spine: AI visibility, leadership experience, client quality, public reviews, and media references. Longevity also appears in the pharmaceutical and senior living evaluations. This consistency makes the studies directionally comparable: each tries to measure whether an agency can establish a credible entity that AI systems are likely to recognize and cite.

    However, only the senior living source provides a complete weighting scheme in the supplied material. It assigns 25% to AI visibility, 20% each to leadership experience and average reviews, 15% to notable clients, and 10% each to year established and media references. The solar source calls its algorithm proprietary, the marine excerpt identifies five factors without weights, and the pharmaceutical table reports separate GEO and AI visibility scores without providing a directly comparable cross-industry formula.

    The evaluated platform sets also vary. The pharmaceutical report names ChatGPT and Perplexity; senior living adds Google Gemini; marine includes ChatGPT, Perplexity, Claude, and Gemini. A score generated from one platform set should not be treated as equivalent to a score generated from another. Query selection, geography, testing frequency, citation criteria, and whether the agency measures mentions or actual recommendations could alter the result as well, yet those details are not supplied consistently.

    Some criteria can also pull in opposite directions. Longevity, media coverage, and recognizable clients favor established firms, while a newer specialist may bring a more focused GEO model. The pharmaceutical ranking illustrates that tension: it places Genevate, established in 2025, second and Signal Hill Strategies, established in 2026, third, ahead of longer-established Sciencia Consulting and Varn Health. That ordering is reported within the pharmaceutical methodology; it should not be generalized into an all-industry ranking.

    Recurring leaders and specialists serve different buying needs

    First Page Sage has the strongest repeated placement in the fully described portions of the source material. The pharmaceutical report ranks it first and characterizes its specialty as GEO-led lead generation, SEO, and thought leadership. The senior living report also identifies it as the leading agency, crediting its AI visibility and reported lead quality. This recurrence supports a shortlist position for organizations seeking a broad GEO program, although it does not independently establish leadership in the solar, biotech, or marine rankings because their supplied excerpts omit the necessary complete results.

    Genevate and Signal Hill Strategies also appear in both the pharmaceutical and senior living coverage, but for distinguishable reasons. Genevate is ranked second in pharmaceuticals for a PR-centered approach designed to build external credibility, while the senior living overview similarly emphasizes its combination of GEO and strategic PR. Signal Hill is ranked third in pharmaceuticals for high-intent, revenue-oriented content; the senior living source instead highlights healthcare experience and the ability to navigate medical-compliance concerns. Their recurrence is meaningful, but their reported strengths suggest different selection rationales.

    The specialist firms demonstrate why a buyer should not stop at repeated names. In pharmaceuticals, Sciencia Consulting is presented as a scientifically led content and digital marketing option, whereas Varn Health brings a longer pharmaceutical SEO background and regulatory frameworks. The source also cautions that neither is as exclusively centered on GEO as the leaders in that table.

    Senior living presents an even wider range of operating models. CCR Growth is described as concentrating entirely on senior living GEO from discovery through occupancy. Love & Company combines brand development with long sector experience, Senior Living Smart links marketing technology and automation to resident nurturing, SageAge blends traditional and digital marketing, and Focus Digital is positioned as a more budget-conscious option for smaller communities. These are not minor variations in one service; they represent different answers to the question of what the agency must own after initial AI discovery.

    How to turn a published ranking into a defensible shortlist

    A group of portfolio folders narrows through translucent selection gates to three evidence-supported folders on a review table.

    The practical selection task is to match the ranking signal to the organization’s constraint. A pharmaceutical or biotech company may place scientific review and compliance governance ahead of publishing speed. A senior living operator may care more about whether AI-driven discovery produces qualified family inquiries and ultimately supports occupancy. A marine technology company should verify experience with its precise commercial audience instead of accepting a general marine portfolio as sufficient evidence.

    Selection questionEvidence to request from an agencyWhy it matters
    What does AI visibility mean in this engagement?The named platforms, tracked queries, markets, testing cadence, and rules for counting mentions, citations, and recommendationsIt makes an agency’s headline visibility claim measurable and prevents unlike scores from being compared.
    Which sector sources support the strategy?A map of authoritative publications, directories, first-party content, and other sources relevant to the buyer’s nicheGenerative systems rely on a broader information environment than a company’s website alone.
    How is accuracy governed?Subject-matter review, correction procedures, approval responsibilities, and compliance checkpointsThis is especially important where inaccurate health, scientific, or regulated information could create material risk.
    How does visibility connect to commercial value?A measurement path from AI exposure to qualified inquiries, pipeline, tours, occupancy, or another defined outcomeA recommendation is useful only when it supports the organization’s actual buying journey and objectives.
    Does the portfolio match the exact submarket?Relevant examples, client references, and a clear account of who performed the workBroad labels such as healthcare, renewable energy, or marine can hide major differences in expertise.
    What trade-off does the agency represent?An explicit view of specialization, service breadth, leadership involvement, capacity, and dependence on SEO or PRIt reveals whether the agency’s operating model fits the buyer, not merely whether its ranking is high.

    The 2026 reports are most credible when used as structured discovery tools rather than final verdicts. As GEO measurement matures, the more durable agency advantage will be the ability to define visibility transparently, earn trustworthy citations within a specific industry’s information ecosystem, and connect those gains to a result the client can verify.

    References

  • Google AI Search Ads: Access, Control and Measurement

    Google AI Search Ads: Access, Control and Measurement

    Google’s AI-enhanced search experiences are changing more than ad placement. They are separating campaign management into three distinct questions: how advertisers gain access to AI Search inventory, how they guide automated decisions, and how they measure results when reporting remains incomplete.

    The supplied CrushPress.AI report, based on a discussion involving Google Ads Liaison Ginny Marvin and the PPC Chat community, offers useful answers across those questions. Viewed together, its details point to a system in which participation remains relatively open, but effective optimization increasingly depends on strong data and carefully defined instructions.

    Key takeaways

    • AI Max is not reported to be a prerequisite for ads to appear in AI Overviews or AI Mode.
    • Broad match can provide a route into AI Search inventory, while AI Max can extend matching beyond the advertiser’s explicit keyword set.
    • AI Search ads do not yet have a distinct reporting breakdown, limiting advertisers’ ability to isolate their contribution.
    • Google’s direction combines automated matching with advertiser guidance, first-party data and measurement designed for longer conversion cycles.

    AI Search eligibility is broader than AI Max

    One of the most consequential distinctions in the report is between eligibility and expansion. According to CrushPress.AI’s account of Marvin’s comments, advertisers do not need to enable AI Max merely to participate in Google’s AI-driven search experiences. Search campaigns using broad match keywords can still be eligible for AI Overviews and AI Mode.

    AI Max instead appears to widen the matching opportunity. The report says it can apply broad-match behavior to phrase and exact match keywords while also enabling keywordless matching. That makes AI Max less of an admission ticket and more of an additional discovery mechanism.

    This distinction should shape campaign decisions. An advertiser can evaluate AI Search exposure separately from the decision to grant Google more latitude in matching queries. The relevant question is therefore not simply whether to adopt AI Max, but whether its broader reach fits the campaign’s economics, message constraints and tolerance for automation.

    Reporting has not caught up with the new inventory

    An analyst examines fragmented advertising signals as some data paths vanish behind translucent blank reporting panels.

    Access to AI Search inventory does not currently come with equivalent visibility. The source reports that ads appearing in AI Overviews and AI Mode are recorded like other top-of-page ads, without a separate reporting breakdown. It also says Google was still determining what dedicated reporting should eventually look like.

    That creates an important analytical limitation. Advertisers may participate in AI Search without being able to isolate its traffic, conversion performance or incremental value from standard search placements. A campaign-level improvement cannot automatically be attributed to AI inventory, while a weak result does not reveal whether the problem arose from an AI placement, another top-of-page impression or a broader campaign setting.

    Until reporting becomes more granular, AI Search should be treated as part of the campaign’s combined delivery environment. Conclusions about its standalone effectiveness would go beyond the evidence available in the reported interface.

    AI Brief and first-party data serve different roles

    The report describes AI Brief as a forthcoming control layer for AI Max. Advertisers are expected to be able to supply guidance covering matters such as target audiences, preferred message themes, priority search intents and prohibitions including instructions not to mention prices. CrushPress.AI says the rollout was planned to begin with English-language Search campaigns before extending to Performance Max and Shopping campaigns.

    Those instructions and an advertiser’s data are complementary rather than interchangeable. AI Brief can communicate strategic boundaries: whom a campaign should address, which ideas it should emphasize and what it should avoid. First-party data provides signals about actual customer and conversion outcomes.

    CrushPress.AI reports that Google emphasized data quality through a concept called Data Strength and pointed to Enhanced Conversions and Google Tag Gateway as important tools. The broader implication is that automation does not eliminate foundational measurement work. If the underlying signals are incomplete or unreliable, more sophisticated matching and creative guidance cannot supply the missing business evidence.

    Measurement is moving toward longer customer journeys

    A shopper follows a winding path across several digital touchpoints while interaction signals converge into a measurement lens and a secure data vault supports the journey.

    Qualified Future Conversions, or QFC, represents another part of Google’s reported direction. The source describes it as a metric that estimates potential conversions occurring within 180 days after an ad interaction. It was reportedly being tested with selected advertisers and was presented as especially relevant to B2B and lead-generation businesses with lengthy sales cycles.

    QFC addresses a different measurement problem from the missing AI Search breakdown. Dedicated placement reporting would help advertisers understand where an interaction occurred; a future-conversion estimate is intended to help evaluate what that interaction may eventually produce. Neither capability substitutes for the other.

    The report also identifies new AI Search ad formats, QFC and YouTube Creator Partnerships as three areas Marvin highlighted after Google Marketing Live. Together, those priorities suggest attention to discovery, delayed outcomes and creator-led reach. For search advertisers, the immediate challenge is to prepare reliable inputs and explicit campaign guidance while avoiding stronger claims about AI-specific performance than the available reporting can support.

    What advertisers should prepare next

    The most durable preparation is not adoption of every automation feature. It is a campaign structure that can accommodate wider matching without losing strategic intent, supported by dependable conversion signals and documented messaging boundaries. As AI-specific controls and reporting develop, advertisers with those foundations will be better positioned to test new inventory and interpret the results responsibly.

    References

  • AI SEO Measurement: From Prompt Signals to Action

    AI SEO Measurement: From Prompt Signals to Action

    AI-era SEO measurement breaks down when a dashboard treats every generated answer as stable, every tracked prompt as representative, or every brand mention as a business result. A useful system must instead connect four questions: what people ask, how consistently AI systems respond, whether visibility changes user behavior, and what a team should do next.

    Together, the supplied reports point toward a practical operating model: observe real demand, sample variable responses systematically, connect visibility to outcomes, and convert findings into owned work. This approach extends established SEO measurement without pretending that AI answers behave like conventional rankings.

    Measure the demand behind AI visibility

    The first measurement problem occurs before an AI answer is generated: a tracking program must decide which prompts represent the audience. The prompt research summarized by CrushPress.AI suggests that the answer is not simply a library of elaborate, conversational questions.

    In a January 2026 Stella Rising survey cited by the publication, two-thirds of participants submitted prompts containing no more than 15 words, while about 12% produced what the researchers considered comprehensive prompts. The reported average for a basic shoe-recommendation scenario was eight words. The same article cited Semrush clickstream findings that placed average prompt length between 4.2 and 8.7 words. These reports indicate that short, keyword-shaped demand remains relevant even inside generative interfaces.

    Personal context creates a second demand layer. The January study reportedly found that 32% of users included details such as a role, situation, location, size, preference, or budget. Nearly a quarter used the word "best," while price language and "near me" phrasing also appeared. A brand may therefore be visible for a broad category prompt yet disappear when the request adds affordability, availability, suitability, or personal constraints.

    These results should be treated as directional. The article says the August 2025 research covered 178 members of a beauty-oriented community, whereas the January 2026 study covered 524 active AI users from a broader audience. Differences between the studies may reflect their samples as well as changing behavior. They do not establish a universal prompt distribution for every market.

    Design a prompt portfolio rather than a keyword substitute

    Hands arrange varied icon-based prompt tokens into several intent groups on a circular table.

    A representative prompt set needs several complementary inputs. Replacing a keyword list with synthetic questions merely changes the format of the same sampling problem. The stronger approach is a portfolio that covers distinct ways demand appears:

    • Short retrieval prompts: category, brand, location, price, comparison, and "best" queries that resemble conventional search behavior.
    • Context-rich prompts: requests that combine a need with personal attributes, constraints, use cases, or purchasing conditions.
    • Synthetic persona prompts: controlled scenarios used to test how representation changes across audience profiles.
    • Conversational journeys: linked turns that move from discovery through evaluation and selection.

    Real prompt language can be informed by customer inquiries, support tickets, on-site search behavior, sales conversations, and traditional search data. CrushPress.AI’s prompt-behavior article recommends combining such evidence with synthetic personas because a fabricated profile cannot fully reproduce the accumulated context of an ongoing AI interaction.

    The prompt-tracking report adds another distinction: a single-turn test shows whether a brand appears at one moment, while a sequence can reveal whether that visibility persists as the user narrows the decision. Persistence is especially important when an initial mention does not survive follow-up questions about requirements, competitors, pricing, or fit.

    The resulting portfolio should be segmented rather than collapsed into one visibility score. Short prompts, contextual prompts, personas, and journeys represent different questions about demand. Combining them without labels can make a change in the sample look like a change in brand performance.

    Quantify variable answers without manufacturing certainty

    AI responses vary, so one generated answer is an observation rather than a durable rank. CrushPress.AI’s prompt-tracking article argues that this variability can be managed through repeated runs, fixed sampling rules, and confidence intervals. It compares the emerging discipline with fields such as opinion polling, where uncertainty is measured rather than ignored.

    A repeatable measurement specification should identify the platform, prompt wording, conversational context, sampling schedule, number of observations, market conditions, and scoring rules. It should also preserve the underlying responses so that changes in a summary metric can be audited. When a platform or testing condition changes, the report should mark the break rather than present the series as perfectly continuous.

    Each run can record several observable outcomes: whether the brand was mentioned, whether it was recommended, which sources were cited, which competitors appeared, and whether the brand remained present in later turns. The appropriate output is a distribution, rate, or range across the sample, accompanied by its limitations. A movement based on repeated observations deserves more weight than an isolated favorable or unfavorable answer.

    Cross-platform reporting requires similar restraint. The tracking article notes that visibility can differ among AI services and uses brand performance across ChatGPT and Perplexity to illustrate the issue. Platform-level results should therefore remain visible even when an aggregate is provided; otherwise, strength in one environment can conceal weakness in another.

    Connect AI exposure to traffic, outcomes, and evidence

    Uneven light paths connect an abstract AI interface to a website, user behaviors, collected evidence, and prioritized work cards.

    Visibility is an intermediate signal, not the final business result. The prompt-behavior report says many surveyed users still clicked citations, presenting AI mentions as possible gateways to websites rather than automatic endpoints. It also reports that 68% of respondents trusted AI recommendations more than Google’s and that half of active AI users engaged with AI tools daily. Those figures come from the cited January 2026 survey and should not be generalized beyond its stated audience, but they explain why recommendation quality and referral behavior warrant measurement together.

    A practical measurement chain separates four levels. Prompt coverage shows whether the test set reflects meaningful demand. Answer visibility shows whether and how the brand appears. Referral and behavioral data show whether cited exposure produces visits or engagement. Conversion measures show whether those interactions contribute to leads, purchases, subscriptions, or another defined objective. Not every organization will be able to connect every level, so reports should distinguish observed outcomes from inferred influence.

    This distinction also improves prioritization. A visibility gap for a commercially important, frequently observed use case may justify content or technical work. A fluctuating mention for a speculative synthetic prompt may justify continued observation instead. Confidence, audience relevance, business value, and implementation cost all affect the decision.

    The Conductor post offers a vendor-side example of shortening the distance between insight and execution: it describes Conductor AEO intelligence integrated into Optimizely with pre-built agents intended to act on findings. The announcement demonstrates the direction of workflow integration, but it does not independently establish that automated actions improve visibility or business performance. Any such workflow still needs approval rules, outcome measurement, and a record of what changed.

    Convert findings into owned, decision-ready work

    The final failure point is organizational. The reporting article argues that research becomes useful only when stakeholders can see the priority, business rationale, responsible team, next action, and measurement plan. AI visibility data increases this need because its uncertainty can otherwise become a reason to delay every decision.

    1. State the finding and its evidence. Identify the affected prompt segment, platform, sample, observed range, and relevant citations or responses.
    2. Explain the business consequence. Connect the finding to an audience need, commercial page, reputation risk, or measurable journey stage.
    3. Choose the smallest meaningful action. Specify the content update, technical correction, authority-building task, product-data improvement, or additional test required.
    4. Assign ownership and timing. Name the responsible function and define when the work and its follow-up measurement should occur.
    5. Set an evaluation rule. Define which visibility, referral, engagement, or conversion signal would support continuing, revising, or stopping the intervention.

    The level of detail should change with the reader. Executives need exposure, risk, resource requirements, and expected business impact. Marketing leaders need the connection to demand and campaigns. Content teams need page-level briefs and audience context. Developers need reproducible technical requirements. Supporting exports and response logs can remain available without overwhelming the main decision document.

    Key takeaways

    • Preserve short, search-like prompts while adding personal, situational, and conversational variants.
    • Use real audience evidence and synthetic personas for different purposes; neither is a complete sample alone.
    • Measure repeated observations, uncertainty, platform differences, citations, and conversational persistence.
    • Treat visibility as one stage in a chain that ends with an assigned action and a defined outcome signal.

    As AI interfaces become more personalized and optimization tools become more integrated, the durable advantage will come from disciplined learning loops. Teams that preserve evidence, acknowledge uncertainty, and make each finding operational will be better positioned to adapt their SEO programs as user behavior and answer systems evolve.

    References

  • AI Search Visibility When Clicks No Longer Tell the Story

    AI Search Visibility When Clicks No Longer Tell the Story

    AI search visibility is changing what it means for a brand to succeed in search. A result can influence awareness, consideration, or a future branded query without producing an immediate website visit, while an AI-generated answer may describe or recommend a business before the user encounters its pages directly.

    The practical response is not to abandon SEO, but to connect search performance with brand representation. The available reporting points to two linked priorities: remaining visible as clicks become less common and giving AI systems enough clear, credible, accessible information to represent the brand accurately.

    Key takeaways

    • Zero-click growth makes traffic an incomplete measure of search influence, although it remains important for commercial outcomes.
    • AI visibility depends on whether systems can understand the brand, find evidence supporting its claims, and retrieve that evidence when answering relevant questions.
    • SEO retains particular value for branded, local, and high-intent transactional searches, according to the zero-click study coverage.
    • A durable strategy combines owned content with reviews, third-party mentions, case studies, credentials, and consistent business information.
    • Measurement should distinguish presence, representation, engagement, and business outcomes instead of treating all search activity as a traffic-acquisition funnel.

    Visibility is becoming an answer-layer problem

    The reported zero-click trend establishes the scale of the change. The first source, summarizing a SparkToro study based on Similarweb clickstream data, reported that 68.01% of Google searches from January through April 2026 ended without a click. It placed the comparable 2024 share at 60.45%, while cautioning that changes in data sources make long-term comparisons imperfect.

    The same coverage reported that the share of searches producing at least one click fell by 9.51 percentage points between 2024 and 2026. That measure included organic results, advertisements, and Google-owned destinations such as Maps and YouTube, but excluded follow-up searches within Google. Meanwhile, the share leading to another Google search reportedly increased by 7.2 percentage points. Together, those findings suggest that search journeys are increasingly being continued or resolved inside the results environment.

    AI-generated results may reinforce that pattern, but the source does not establish a single cause. It reported that AI Overviews appeared in more than 20% of Google searches and were associated with a nearly 60% reduction in click-through rates when present. SparkToro suggested that the feature could be contributing to zero-click growth, but the study did not isolate how much of the increase it caused.

    AI Mode was a comparatively small part of the observed journey during the study period: only 0.34% of searches reportedly transitioned into it. The article also cited Google’s I/O 2026 announcement that AI Mode had more than 1 billion monthly users and that its query volume was more than doubling each quarter. Those figures describe different dimensions, so they should not be treated as contradictory: one concerns transitions recorded in a particular clickstream study, while the other concerns Google’s reported product usage.

    Brand presence depends on what machines can establish

    Transparent lenses connect several evidence objects and resolve them into a clear faceted form at the center.

    Lower click-through rates create a distribution challenge, but the second source identifies a representation challenge as well. AI systems form a picture of a business from the information available across its digital footprint. Websites, content, reviews, testimonials, credentials, case studies, and external mentions may each supply only part of that picture. Valuable expertise embedded in sales conversations, customer support, project delivery, and other daily operations may remain invisible unless it is documented and published.

    Understandability

    The source’s understandability test asks whether an AI system can determine who the organization is, what it does, and whom it serves. About pages, product or service pages, and structured data contribute to that understanding. They become more useful when names, offerings, audiences, locations, and differentiators are expressed consistently rather than scattered across ambiguous pages.

    Credibility

    Understandable claims still require support. The source frames credibility through notability, experience, expertise, authoritativeness, trustworthiness, and transparency. In operational terms, that means connecting assertions to visible evidence such as case studies, credentials, customer testimony, responsible authorship, and clear information about the business. Independent reviews and mentions can complement owned claims because they show how other parties describe the brand.

    Deliverability

    Evidence has limited value if relevant systems cannot retrieve it in the context of a user’s question. The source associates deliverability with topical content, marketing activity, and authority material. This connects conventional SEO with AI visibility: useful pages still need clear subject focus, accessible presentation, internal relationships, and distribution beyond the company website.

    A practical operating model joins SEO and brand evidence

    The synthesis of the two sources is a shift from optimizing isolated pages to managing a verifiable body of brand knowledge. A business can begin by creating a maintained source of truth for its identity, offerings, audiences, locations, expertise, policies, and substantiated differentiators. This is not necessarily a single public page; it is an internal reference that helps teams publish consistent information across appropriate channels.

    Operational knowledge should then be converted into suitable public evidence. Repeated customer questions can inform explanatory content. Demonstrable results can become case studies when permissions and context allow. Staff expertise can be attached to identifiable authors or subject-matter contributors. Credentials, review patterns, and relevant third-party recognition can be made easier to verify. The goal is not to manufacture signals, but to expose knowledge and proof that already exist inside the organization.

    Distribution matters because an AI-generated answer may assemble its view from more than the brand’s preferred landing page. Core facts should remain consistent across the website, business profiles, relevant platforms, earned coverage, and other legitimate sources. Each channel has a different role: owned pages provide depth and control, customer feedback supplies experience-based evidence, and independent references can reinforce recognition and authority.

    This model also clarifies where traditional SEO remains essential. The zero-click coverage cited SparkToro co-founder Rand Fishkin’s view that SEO continues to matter for branded searches, local business inquiries, and high-intent transactional searches. These are contexts in which accurate pages and direct visits can still connect discovery to action. Broader audience development should also occur on the platforms where prospective customers already spend time, even when that activity does not immediately produce referral traffic.

    Measurement must separate exposure from acquisition

    A glowing signal stream divides into a broad halo around people and a focused path leading to a doorway.

    A traffic-only dashboard cannot show whether a brand appeared inside an answer, was represented accurately, or influenced a later decision. Measurement should therefore follow several layers. Presence concerns whether the brand appears for relevant questions. Representation evaluates whether the answer describes its identity, services, audience, and differentiators correctly. Engagement covers visits, branded searches, profile interactions, and other observable responses. Outcomes connect those interactions to inquiries, qualified demand, sales, retention, or another business objective.

    These layers should not be collapsed into a single visibility score. A mention can be prominent but inaccurate; an accurate citation can produce no click; and a decline in noncommercial traffic can coexist with strong performance on branded or high-intent searches. Separating the layers makes diagnosis more useful: unclear representation points toward content and entity consistency, weak credibility points toward missing evidence, and limited reach points toward discoverability or distribution.

    The reported study also sets an important analytical boundary. Its dataset covered U.S. Google desktop and mobile web searches, estimated that two-thirds of searches occurred on mobile devices, and excluded searches inside Google’s mobile search app, where the source said zero-click behavior might be higher. Results should therefore be treated as directional evidence from a defined sample rather than a universal benchmark for every audience, market, or search environment.

    As answer interfaces expand, the strongest search programs will be built around both retrieval and reputation. Brands that keep their knowledge current, support claims with accessible evidence, and evaluate how they are represented will be better prepared for a search journey in which influence often begins before any click occurs.

    References

  • Measuring AI Search Visibility Beyond Traditional Keywords

    Measuring AI Search Visibility Beyond Traditional Keywords

    AI-generated answers are weakening the keyword’s role as the stable unit of search measurement. The challenge is not simply finding a replacement metric; it is building a measurement model that remains meaningful when prompts, answers, interfaces, and recommendations can all vary.

    The source material points to two connected shifts. One frames Google AI experiences as part of a move beyond conventional keywords, while the other argues that precise AI share-of-voice percentages can conceal an unstable and unauditable denominator. Together, they suggest that visibility should be evaluated as a set of observable signals rather than compressed into one universal score.

    Keywords remain useful, but no longer define the whole market

    The first source frames Google’s AI-oriented search experience around the prospect of keyword replacement. That framing does not mean keywords immediately become irrelevant. They can still organize demand themes, preserve continuity with historical reporting, and provide repeatable inputs for controlled tests. What changes is their status: a keyword list becomes a sample of possible user needs rather than a complete inventory of the market.

    Traditional keyword measurement assumes that a query can be entered, a result page can be observed, and a position can be recorded. The second source argues that this model has been disrupted by AI summaries, localized results, continuous scrolling, sponsored placements, personalization, and layouts that respond dynamically to intent. A conventional rank can therefore remain technically correct while describing less of the user’s actual experience.

    Prompts make the sampling problem larger. People can express the same need through comparisons, follow-up questions, constraints, use cases, and conversational refinements. Because the possible prompt set has no fixed boundary, no monitored list can claim to represent every relevant interaction. The defensible goal is representative coverage, not exhaustive coverage.

    Why a single AI share-of-voice percentage can mislead

    Unequal glass vessels containing glowing spheres sit on a balance while only one small vessel is fully illuminated.

    According to the second source, traditional share of voice at least used an explicit denominator: a marketer selected a keyword set, observed visibility against competitors, and calculated performance within that defined universe. The method had limitations, but its scope could be inspected.

    The source contends that some AI visibility platforms instead calculate percentage scores from limited prompt sets across services such as ChatGPT, Gemini, Claude, and Perplexity. If users cannot inspect how prompts were selected, how answers were classified, or how platforms and repetitions were weighted, the apparent precision of the percentage exceeds what the method can support.

    This does not make prompt tracking worthless. It changes the claim that the resulting number can sustain. A score derived from a declared prompt panel can describe what happened within that panel. It cannot, by itself, establish a brand’s share of every possible AI-assisted search. Reporting should therefore identify the tested universe, collection method, comparison rules, and limitations beside the result.

    The denominator is only one problem. A binary mention can also flatten materially different outcomes. A brand may appear as an incidental example, a leading recommendation, a warning, or a source citation. Counting all four appearances equally would hide the difference between recognition, commercial preference, reputational risk, and source authority.

    Measure presence, preference, and meaning separately

    Three connected visual layers show a signal across answer surfaces, recommendation paths converging on an option, and a prism revealing multiple facets.

    The second source proposes three alternatives to a universal AI share-of-voice score: share of mentions, share of recommendations, and share of narrative. These are most useful as separate dimensions. Combining them too early would recreate the opacity of the metric they are intended to replace.

    Mentions indicate whether the brand enters the answer

    Share of mentions measures how often a brand appears within a defined test set relative to relevant alternatives. The source connects this visibility to the relationships AI systems form from training material or real-time retrieval sources. Operationally, mention tracking can reveal whether a brand is associated with a topic at all, but it should preserve the prompt category, platform, answer context, and competitors observed.

    Recommendations reveal preference within a buying context

    Share of recommendations narrows the question from “Was the brand named?” to “Was it advised?” The source argues that clear, well-documented market positioning is important here. Recommendation analysis should distinguish a direct endorsement from inclusion in a broad set of options, because those answer forms represent different levels of preference.

    Narrative captures how the brand is characterized

    Share of narrative adds the qualitative layer. The second source notes that frequent visibility can still be harmful when the surrounding portrayal is negative. Narrative review should therefore examine the attributes, use cases, cautions, and comparisons attached to a brand. This is where measurement connects AI search visibility with positioning and reputation management.

    These dimensions answer different business questions. Mentions indicate conceptual presence, recommendations indicate preference, and narrative indicates meaning. None should automatically substitute for outcomes such as qualified visits or conversions; those belong in a separate performance layer when reliable data is available.

    Key takeaways

    • Use keywords as controlled samples of demand, not as a complete map of AI-assisted discovery.
    • Treat an AI visibility percentage as a result for a declared prompt panel unless its broader denominator can be audited.
    • Report mentions, recommendations, and narrative separately so that recognition is not confused with preference or reputation.
    • Preserve prompts, platforms, repetitions, classification rules, and collection conditions so changes can be interpreted.
    • Connect visibility signals to business outcomes without implying that a mention alone caused traffic, leads, or revenue.

    Build a measurement system that can be challenged

    A credible program begins by defining the decision it must support. Brand teams may need to understand how the market is described, search teams may need to assess discovery coverage, and commercial teams may care about recommendation frequency. Each purpose requires a different mix of prompts and a different interpretation of success.

    The monitored prompt set should then be grouped by user need, such as discovery, comparison, evaluation, or problem solving. The exact groups will vary by organization; what matters is that the selection logic is documented. Fixed prompts provide comparability over time, while a separately labeled exploratory sample can surface emerging language without silently changing the benchmark.

    Collection should retain enough context to reproduce or audit an observation: the prompt, platform, answer, collection condition, brand appearances, recommendation status, narrative classification, and any cited sources. Repetition can expose variability, but the reporting should show that variability rather than smoothing it into unwarranted certainty.

    Competitive comparisons should use the same prompt panel and classification rules for every brand. Results can then be reported as observed rates within that explicit sample. This language is more limited than claiming a universal market share, but it gives leadership a number whose boundaries can be understood.

    Finally, AI visibility should sit beside conventional search and business evidence rather than replace them. Keyword trends can preserve historical context; mention, recommendation, and narrative measures can describe answer-level presence; outcome data can show whether observable demand followed. The next generation of search measurement will become more useful as it becomes more transparent about what was tested, what changed, and what remains unknown.

    References

  • How to Choose an Industry-Focused SEO Agency in 2026

    How to Choose an Industry-Focused SEO Agency in 2026

    An industry-focused SEO agency should offer more than a portfolio containing familiar company names. Its real value lies in understanding how a sector’s customers search, which evidence earns their trust, and what technical or geographic constraints shape the path to conversion.

    Three 2026 agency reports covering solar, agriculture, and local SEO reveal a useful selection framework. They also show why a ranking should begin due diligence rather than settle the decision.

    Key takeaways

    • Relevant client experience, review quality, and leadership expertise recur across all three agency evaluations.
    • Specialization should be tested at the level of search behavior, content, technical requirements, geography, and commercial outcomes.
    • Local SEO is a distinct operating capability, not a substitute for knowledge of a client’s industry.
    • Scorecard weights reveal what a ranking values, but buyers still need to examine the evidence behind each score.
    • The best agency is the one whose delivery model fits the organization’s actual bottleneck, whether that is authority, local visibility, branding, or technical execution.

    What specialization should change in practice

    The three reports share a basic premise: experience close to the client’s market matters. The solar evaluation gave notable clients 28% of its score and also considered home-services experience when an agency had less direct solar work. The agriculture evaluation assigned 25% to notable clients and emphasized leadership experience in agriculture-specific strategy. The local SEO report made demonstrated local experience its largest factor, at 25%.

    Those criteria point to different kinds of relevance. Vertical expertise concerns the market itself: its audiences, terminology, buying process, content opportunities, and standards of credibility. Local expertise concerns how a business competes across places, including location pages, structured information, and visibility in map-oriented results. An agency may possess one capability without the other.

    The solar report illustrates how varied agencies within one vertical can be. It described First Page Sage as using thought-leadership content, geographically targeted landing pages, and white papers for mid-market and enterprise providers. Siana Marketing was presented as combining SEO and generative engine optimization, or GEO, with knowledge of solar sales cycles. Anchour was positioned around branding for smaller companies, while XEN Solar was associated with technical SEO and HubSpot optimization. These profiles are source-reported positioning, not independently verified performance, but they demonstrate that an industry label can encompass substantially different delivery models.

    What the agency scorecards measure – and omit

    ReportAgency pool reviewedMost heavily weighted evidenceDistinctive considerations
    Solar SEO31 agenciesNotable clients, 28%; leadership experience, 22%; average reviews, 22%Year founded, 16%; company size, 12%
    Agriculture SEO81 companiesAverage reviews, 25%; notable clients, 25%; leadership experience, 20%Services, founder involvement, and media references, each 10%
    Local SEO48 firmsLocal SEO experience, 25%; average reviews, 20%Technical expertise and local-pack effectiveness, each 15%; leadership, employee tenure, and media references

    The overlap is meaningful. All three reports considered client reviews and leadership experience, while the two vertical studies placed substantial weight on recognizable or relevant clients. Taken together, the reports treat market evidence, reputation, and senior expertise as complementary signals rather than interchangeable ones.

    The differences are just as instructive. The solar methodology rewarded longevity and company size. The agriculture methodology considered whether the founder remained active and how often the company appeared in media. The local evaluation gave explicit weight to technical SEO, local-pack results, and median employee tenure. A buyer that values stable account teams may find tenure more informative than media visibility; a multi-location operator may care more about local-pack evidence than an agency’s founding date.

    Methodological transparency also needs scrutiny. The agriculture article says it used seven factors, but the supplied methodology names six: reviews, clients, leadership, services, founder involvement, and media references. Their stated weights total 100%, yet the mismatch between the announced and enumerated factor count is a reminder to inspect the underlying rubric rather than rely only on the final order.

    How to test an agency’s claimed industry expertise

    A client team tests SEO consultants around a table containing technical components, map contours, product samples, and unlabeled evidence folders.

    Interrogate the case evidence

    A logo establishes that some relationship existed; it does not explain the scope, duration, baseline, or result. Buyers can ask what the agency was responsible for, which search problems it addressed, and how outcomes were measured. Reviews deserve similar examination. The agriculture report said it consulted G2, Clutch, and Google Reviews, while the local report described a composite drawn from Google, Clutch, and other verified platforms. The solar report referred more generally to publicly available reviews and gave additional weight to solar-client feedback.

    That makes review composition more important than a headline average. Relevant questions include whether comments describe SEO work, whether they come from comparable organizations, and whether they discuss communication and execution as well as satisfaction.

    Distinguish leadership credentials from delivery capacity

    Leadership experience appeared in every methodology, receiving 22% in solar, 20% in agriculture, and 10% in local SEO. Senior expertise can shape strategy and quality standards, but buyers also need to learn who will actually conduct research, create content, implement technical changes, and report results. The local report’s inclusion of employee tenure offers one possible signal of delivery continuity; the solar report instead used company size as an indicator of capacity and client support.

    Request a diagnosis specific to the business

    A credible proposal should connect tactics to an identified constraint. An authority problem may call for expert-led content. A location-discovery problem may require technically sound location architecture and local visibility work. A weak market position may require branding before publishing at scale, while an implementation backlog may favor a technically oriented partner. This diagnosis is more revealing than whether an agency repeats the vocabulary of the sector.

    Match the engagement model to the actual search problem

    The sources suggest that industry specialization is not a single service category. In the agriculture report, First Page Sage was described as offering SEO, GEO, advertising, and web development, with thought leadership at the center of its positioning. The report said the company was founded in 2009 and began adapting to generative AI in 2023, while also crediting it with early GEO research. Those are claims made by the source and should be assessed alongside work samples and client evidence.

    The appearance of GEO in both the agriculture and solar coverage indicates that some sector-focused firms are extending their positioning beyond conventional search results. That does not remove the need for foundational SEO. A buyer can ask the agency to separate established deliverables – such as site architecture, content, and location optimization – from newer visibility initiatives, then explain how each will be measured.

    Organizational fit matters as well. The solar report associated one agency with enterprise thought leadership, another with small-company branding, and another with agile technical support. A specialist can therefore be relevant to the industry but wrong for the client’s scale, internal resources, technology stack, or immediate commercial objective.

    Turn selection criteria into an accountable engagement

    A client and agency team build a modular tabletop pathway with illuminated checkpoints connecting search activity to a conversion symbol.

    Before contracting, the organization should translate its selection rationale into a clear operating agreement. The scope can identify the audiences and markets being pursued, the technical and content responsibilities of each party, the approval process, and the business actions that count as meaningful conversions. Reporting should distinguish completed work and search visibility from qualified commercial outcomes.

    The same evidence used to select the agency can become a review standard. If leadership involvement influenced the decision, its expected role should be explicit. If local-pack effectiveness was decisive, the relevant locations and queries should be agreed upon. If industry content expertise won the work, editorial quality and access to subject-matter experts should be built into the process.

    As search interfaces and agency offerings continue to evolve, the strongest partnerships will be those that define specialization through observable decisions and accountable work, rather than through category labels alone.

    References

  • Microsoft Web IQ: How to Optimize for AI-Agent Search

    Microsoft Web IQ: How to Optimize for AI-Agent Search

    If you’re wondering whether Microsoft Web IQ requires a new SEO playbook, the short answer is no. You don’t need a Web IQ schema or a separate version of your site. You do need content that an AI agent can discover, interpret, verify, and reuse across a chain of searches.

    That shifts the work from chasing one visible ranking to making every useful fact easy to retrieve. Here’s how to adapt without abandoning the technical SEO and content standards that already matter.

    Key takeaways

    • Web IQ connects AI systems with current web pages, news, images, and videos through AI-native grounding APIs built on Bing’s index.
    • AI agents may run several searches, refine their questions, and collect evidence before producing an answer.
    • A conventional rank position is a limited way to judge visibility when an agent is assembling an answer from multiple retrieval steps.
    • Clear answer sections, crawlable HTML, consistent entities, supported claims, and accurate structured data make your content easier to use.
    • There is no confirmed Web IQ-specific markup shortcut. Optimize the underlying information, not an imagined scoring system.

    What Web IQ changes about search

    Web IQ is a suite of AI-native grounding APIs that connects AI systems to fresh online information. It can retrieve web, news, image, and video material from Bing’s index. The underlying infrastructure also serves Microsoft Copilot, ChatGPT, and other large language model experiences.

    The important distinction is the customer. A traditional search results page is arranged for a person who scans titles, compares choices, and clicks. Web IQ is designed for software that needs to extract information quickly and continue working.

    An agent may begin with a broad request, identify missing details, issue narrower searches, and repeat that process until it can complete its task. Microsoft therefore reworked more than the presentation of results. The system extends from indexing into orchestration, with an emphasis on relevance, speed, and economical token use.

    This is why a single rank number becomes less informative. Microsoft has said that human-style ranking isn’t the priority for this service. That doesn’t mean relevance has disappeared. It means an agent’s repeated retrieval and extraction process may matter more than whether your page occupies one fixed blue-link position.

    Optimize for a search chain, not one keyword

    A luminous agent follows multiple branching paths through document nodes before reaching a verified result.

    Start with the task behind the query. A person asking how to choose accounting software may cause an agent to investigate pricing, integrations, security, migration, support, and suitability for a particular business. A page that repeats the broad keyword but leaves those questions unanswered offers little material for the later steps.

    Map one primary question and the follow-up questions a careful buyer would ask before acting. Give each substantial follow-up its own descriptive heading. If a follow-up requires a full explanation, publish a dedicated page and link it from the main page with anchor text that names the question it answers.

    Build self-contained answer sections

    Each important section should make sense when retrieved without the paragraphs above it. State the subject explicitly, answer the question early, and then add conditions or evidence. Replace vague openings such as “it depends on several factors” with language that identifies what depends on what.

    For example, don’t hide a product’s eligibility rule inside a long narrative. Put the rule under a heading that names the product and decision. Explain who qualifies, who doesn’t, and what the reader should check next. That structure helps people scan the page and gives an agent a coherent passage to extract.

    Cover adjacent questions without bloating the page

    Agent-search readiness isn’t permission to add every remotely related keyword. Include a subtopic when it changes a decision, resolves a likely ambiguity, or supplies evidence for the main answer. Move tangents to their own pages. Thin expansions make the central answer harder to identify.

    Use internal links to form a deliberate evidence path: overview to requirements, requirements to implementation, and implementation to troubleshooting. The destination should answer the promise made by the link. This gives an agent a useful route for deeper retrieval while keeping each page focused.

    Make each page economical for an agent to process

    Web IQ was engineered for frequent searches and low token use. You can’t control how an external agent budgets its context, but you can remove avoidable interpretation work from your pages.

    Lead with the usable answer

    Place the direct answer near the start of the relevant section. Follow it with the reasoning, limitations, and examples. Don’t make a reader or agent work through a brand story before reaching the fact promised by the heading.

    Keep entities and claims consistent

    Use one clear name for each company, product, service, or concept, then explain aliases where necessary. Keep prices, availability, policies, and specifications consistent across landing pages, documentation, feeds, and structured data. Conflicting facts force an agent to resolve ambiguity and weaken the page’s usefulness as grounding material.

    Attach qualifications to the claim they modify. If an offer applies only in one region or a feature requires a certain plan, say so in the same section. A technically correct statement can still mislead when its condition sits several screens away.

    Use structured data as corroboration

    JSON-LD can clarify entities and relationships, but it isn’t a Web IQ access pass. Choose schema types that match the page, populate properties from visible information, and keep the markup synchronized with the content. Don’t mark up answers, reviews, prices, authors, or dates that visitors can’t verify on the page.

    Treat structured data as a machine-readable confirmation of the page, not a substitute for an explicit answer. The visible copy still needs to explain what the entity is, what the claim means, and when it applies.

    Give media enough context to stand alone

    Because Web IQ can source images and videos as well as pages, don’t publish important media with a generic filename and a one-word caption. Use accurate alternative text, descriptive captions, transcripts where appropriate, and nearby copy explaining what the media demonstrates. Keep the media attached to a canonical page with enough context to identify its subject.

    Run an AI-agent readiness audit

    Scanning beams inspect a modular website structure, with accessible content blocks and connections glowing green.

    You can audit a high-value page without access to Web IQ itself. Use the primary question the page should answer, then work through this sequence:

    1. Check discovery. Confirm that the canonical URL is crawlable, returns the intended content successfully, and isn’t blocked by an accidental robots directive or login requirement.
    2. Inspect the delivered page. Verify that the main answer, headings, links, and essential facts exist in the rendered output available to a crawler. Don’t leave the core answer dependent on an interaction that may never occur.
    3. Extract sections out of context. Read each important section by itself. Add the subject or qualification when the passage becomes ambiguous without its surrounding copy.
    4. Trace every consequential claim. Link to supporting documentation where readers need verification. Remove stale claims and unsupported precision.
    5. Compare visible content with JSON-LD. Resolve differences in names, dates, offers, authorship, and entity relationships.
    6. Follow the likely next questions. Make sure internal links lead to complete answers rather than thin category pages or unrelated sales copy.
    7. Test the task in AI assistants. Ask the same realistic question in experiences relevant to your audience. Record whether your brand appears, which page is used, whether the claim is represented correctly, and which competing evidence fills the gaps.
    8. Watch your own evidence. Review referral traffic and server logs where available, but don’t treat either as a complete count of agent visibility. Use them alongside repeated answer checks and conversion data.

    Prioritize corrections that affect the answer itself: inaccessible pages, conflicting facts, missing qualifications, unclear entity names, and unsupported claims. Cosmetic rewrites can wait. An agent can’t use a polished passage it can’t retrieve or trust.

    Web IQ access may broaden as Microsoft scales the service, but you don’t need to wait for a new dashboard. Choose one commercially important topic this week, map the likely follow-up searches, and repair the weakest answer path. That work improves your site for human visitors now while making its information more usable in agent-driven search.

    References

  • Google May 2026 Core Update: A Practical Recovery Plan

    Google May 2026 Core Update: A Practical Recovery Plan

    Your traffic graph dropped during the May core update, and now you need to know whether to rewrite pages, change your SEO strategy, or simply wait. Start by resisting the urge to make sitewide edits. A core update can expose weak content, but it can also coincide with changes in demand, search-result layouts, competitors, or tracking.

    The useful response is a page-level diagnosis. You want to identify where visibility changed, determine what those pages now fail to deliver, and improve them without destroying content that still works.

    Anchor your diagnosis to the actual rollout

    The official rollout ran from May 21 through June 2. Noticeable ranking movement appeared by May 23 and continued into the following week. This was the second core update of 2026, so earlier changes in your reporting may belong to a different event.

    Build clean comparison periods

    In Google Search Console, compare May 7-20 with June 3-16. These are equal 14-day periods immediately before and after the rollout, without mixing rollout days into either side. If your business has strong weekly or seasonal patterns, compare each period with the equivalent days from a normal prior period as a second check.

    Export clicks, impressions, click-through rate, and average position by query and page. A chart of total clicks is not enough. It can tell you that performance changed, but not why.

    Separate ranking losses from other traffic losses

    If positions declined across several important queries for the same pages, investigate relevance, usefulness, and competition. If impressions declined while positions remained broadly stable, check whether search demand or the set of queries triggering those pages changed. If positions and impressions held steady but click-through rate fell, inspect the live results for new answer features, stronger titles, or a changed search intent.

    Also rule out unrelated technical problems. Check whether affected URLs are indexed, canonicalized as intended, crawlable, and returning the correct status code. Review analytics changes, security incidents, migrations, and major template releases. A core-update diagnosis cannot fix a broken canonical or missing tracking tag.

    Find the losses that actually need intervention

    A magnifying glass isolates three webpage tiles connected to abstract signals for demand, competition, search layout, and measurement.

    Sitewide averages hide the decisions you need to make. Group affected URLs by topic, search intent, template, author, and content type. Then calculate the change for each group. A fall concentrated in old comparison pages calls for a different response than a decline across every page using the same template.

    Start with URLs that combine three traits: a material visibility loss, meaningful business value, and a problem you can clearly describe. Do not prioritize a page merely because its percentage decline looks dramatic. A page that fell from ten impressions to two is usually less urgent than one that lost a large share of qualified visits.

    Inspect the queries that disappeared

    For each priority URL, compare its pre-update and later query sets. Ask whether it lost its main query, a cluster of secondary questions, or visibility for terms that never matched its real purpose. Losing poorly matched impressions may not require a repair. Losing the queries that express the page’s central promise does.

    Search those important queries manually and examine the pages now appearing above yours. Look for differences in intent, scope, specificity, first-hand evidence, freshness, and format. The goal is not to copy competitors. It is to understand what searchers can accomplish with the current results that they cannot accomplish with yours.

    Look for patterns across winners and losers

    Your unaffected and improving pages are useful controls. Compare them with declining pages from the same site. If both groups share the same design, author box, and schema, those elements are less likely to explain the difference. If losses cluster around thin location pages, outdated tutorials, or articles built from the same generic outline, you have a stronger hypothesis to test.

    Audit for satisfaction, not an imaginary update factor

    The update was intended to favor relevant and satisfying content. That direction is more useful than hunting for a new word-count target, schema type, or keyword-density rule. Google has not provided a single prescribed fix for pages that lost visibility.

    Test whether the page fulfills its promise

    Read the title, opening, and major headings without relying on your memory of the page. They should define one clear task or question. Then check whether a reader can complete that task without returning to search for missing steps, definitions, evidence, or limitations.

    Remove introductions that delay the answer. Put the central answer or decision criteria near the relevant heading, then support it with explanation. If the query requires a procedure, make the sequence explicit. If it requires a choice, explain who each option suits and what changes the decision.

    Add value that another generic page cannot reproduce

    A rewrite that merely changes wording preserves the original weakness. Add the missing substance: a worked example, a transparent method, a limitation, an expert interpretation, a screenshot that proves a step, or an explanation of what happens when the standard advice fails. Keep only material that helps the reader act or decide.

    For factual or high-consequence claims, make the basis visible. Identify the responsible organization or expert where that identity matters. Link to supporting material you actually used. Show when the page was reviewed, and update that date only after a meaningful review. An unexplained assertion does not become trustworthy because it sounds confident.

    Check ownership, duplication, and internal competition

    Decide which URL should own each core intent. Several pages targeting the same question can divide internal links and leave each version incomplete. Consolidate genuine duplicates when one stronger destination can serve the reader. Keep separate pages when the intents, audiences, or required answers are materially different.

    Update internal links so descriptive anchor text points to the intended owner. Make sure related pages support one another instead of repeating the same opening-level information. Do not delete a large group of URLs solely because traffic fell during the rollout; first determine whether each page has a distinct, supportable purpose.

    Improve search and AI visibility without conflating them

    A Google core update and visibility inside frontier language models are not the same measurement system. A decline in Google rankings does not prove that ChatGPT, Claude, or another answer engine stopped citing you for the same reason. Track conventional search performance and AI citations separately, even when the same content improvements may benefit both.

    For answer-oriented visibility, make important facts easy to locate and interpret. Use descriptive headings, answer the stated question directly, name entities consistently, and keep qualifications beside the claim they modify. Tables should represent real comparisons, while lists should represent genuine steps or criteria. Formatting cannot compensate for an unsupported answer, but it can make a strong answer easier to extract correctly.

    Apply JSON-LD only when it accurately describes visible content and the page’s real entity relationships. Schema is packaging, not evidence. Adding more markup will not repair stale facts, unclear authorship, duplicated intent, or an answer that misses the query.

    Measure AI visibility with a stable set of prompts tied to your customers’ questions. Record whether your brand is mentioned, cited, represented accurately, or omitted. Keep that record beside, but not merged into, your Search Console analysis. This prevents a gain in one channel from concealing a loss in another.

    Make controlled changes and preserve what you learn

    Two parallel sets of webpage cards show one controlled change while the original version remains preserved for comparison.

    Create a change log for every priority URL. Record the date, the affected query or intent, your diagnosis, and the substantive edits. That turns recovery work into a testable process. Without a log, several teams can modify the same page and leave you unable to connect later movement with a plausible cause.

    Work in related batches rather than changing the entire site at once. Start with a small group that shares a documented weakness. Recheck query-level performance after those pages have accumulated enough impressions for a meaningful comparison. Keep the changes if the intended queries recover without harming conversions or accuracy; revise the hypothesis if they do not.

    Do not judge success only by restored clicks. A revised page may attract fewer but better-matched visits. Review conversions, qualified leads, engaged visits, and the queries now associated with the page. The objective is durable visibility for the right need, not the recreation of every impression that existed before May 21.

    Key takeaways

    • Use May 21 through June 2 as the rollout window, and keep those dates out of your before-and-after comparison periods.
    • Diagnose changes by page and query; total traffic alone cannot distinguish ranking, demand, click-through, and technical problems.
    • Prioritize valuable pages with a clear loss and a specific weakness instead of rewriting the whole site.
    • Improve intent match, distinct value, evidence, ownership, and internal linking before reaching for more schema.
    • Measure Google rankings and AI-answer visibility separately, with a written change log for both.

    Your next move is simple: export the two 14-day comparison periods, select the five affected URLs with the greatest business value, and write one testable diagnosis for each. Make only the changes that diagnosis supports. That gives you a recovery plan you can measure instead of a collection of update myths.

    References

  • Enterprise SEO Agency Landscape: How to Choose the Right Fit

    Enterprise SEO Agency Landscape: How to Choose the Right Fit

    You are not hiring an enterprise SEO agency because your team needs more keyword ideas. You are hiring because something has become difficult to coordinate: technical changes stall, content quality varies across business units, reporting does not connect visibility to revenue, or your brand is missing from AI-generated answers.

    The agency landscape becomes easier to navigate when you stop looking for a universal winner. Start with the constraint you need removed, then make each contender prove that its delivery model can work inside your organization.

    Read the landscape by operating model, not ranking

    A June 1, 2026 evaluation weighted leadership experience at 30%, notable clients at 25%, third-party review averages at 25%, years in business at 12%, and company size at 8%. That lens favors established vendors with recognizable accounts. It does not establish pricing, contract flexibility, technical depth, international coverage, or the quality of the people assigned to your account.

    There is another limitation worth keeping visible: First Page Sage produced the ranking and placed itself first. Treat the order as a discovery aid, not an independent verdict. The more useful information is how the firms differ.

    AgencyReported specialtyReported company sizeUseful starting fit
    First Page SageThought leadership, SEO, and GEO for lead generation100-250A B2B organization trying to turn subject-matter expertise into qualified organic and AI-search demand
    AMP AgencyVideo SEO and content marketing250-500A brand with substantial video assets or a content program in which video discovery matters
    REQBranding, advertising, and SEO100-250A company that needs search coordinated with a broader brand or campaign program
    SociallyinSocial media marketing and technical SEO50-100A consumer-facing team trying to connect social distribution with search execution
    EpsilonFull-service enterprise digital marketing500+A large organization seeking a broad vendor with capacity across digital disciplines
    Major Tom/Sheng Li DigitalEnterprise marketing for a Chinese audience10-50A company for which Chinese-market specialization is central to the assignment
    Clay AgencyEnterprise UI/UX design and branding10-50A business where site experience, product design, or rebranding is more pressing than a conventional SEO production program
    Metric TheoryEnterprise SEO and paid search marketing100-250A demand team that wants organic and paid search managed as connected acquisition channels

    Use the size bands as capacity signals, not quality scores. A larger company may offer more specialists and coverage, but your account can still receive a small delivery team. A smaller firm may provide better access to senior people, but it may have less room to absorb a sudden international rollout. Ask who will actually do the work.

    Define the bottleneck before you build the shortlist

    An interconnected enterprise workflow narrows at one illuminated bottleneck while teams inspect the surrounding system.

    An enterprise SEO brief that asks for more traffic invites generic proposals. Replace it with an operating problem. Your brief should name the business outcome, the part of the search system that is failing, and the internal constraint the agency must work around.

    • If authority is the problem: ask how the agency will extract expertise from executives, product leaders, sales teams, or clinicians without turning every page into a slow approval project. Thought-leadership capability matters more than raw publishing volume.
    • If technical scale is the problem: describe the platforms, templates, faceted navigation, migrations, international sites, and release process in scope. Look for an agency that can translate crawl and indexation findings into requirements your engineers can ship.
    • If fragmented channels are the problem: decide which relationship must improve: SEO and paid search, search and social, brand and demand generation, or content and video. Favor the operating model built around that connection.
    • If AI visibility is the problem: define what you mean by success. It could include accurate brand representation, stronger coverage of customer questions, clearer entity relationships, or visibility in relevant AI answers. Do not accept a promise of guaranteed inclusion.
    • If market expansion is the problem: require evidence from the actual region, language, search environment, and approval structure involved. A generic global capability claim is not a substitute for local operating knowledge.

    This step may remove impressive names from consideration. That is useful. A well-known full-service agency can still be the wrong choice for a technical migration, while a focused specialist can be wrong for a multinational program requiring continuous coverage across several disciplines.

    Make every contender prove enterprise readiness

    Client logos show that a commercial relationship existed. They do not tell you what the agency owned, whether the work resembled your problem, or whether the people responsible are still there. Ask for evidence that exposes the delivery system behind the pitch.

    • A named account team: request each person’s role, expected involvement, location, and relevant experience. Clarify which people are committed to delivery and which appear only during sales.
    • A sample diagnostic: give contenders a bounded scenario from your environment and ask how they would investigate it. You are testing prioritization and reasoning, not collecting free consulting.
    • Redacted working artifacts: ask to see a technical requirement, content brief, editorial workflow, measurement specification, or executive report. Polished case-study slides reveal less than the documents teams use every week.
    • A route from recommendation to release: have the agency explain who converts an SEO finding into an engineering ticket, who validates the implementation, and what happens when another team blocks it.
    • Content governance: ask how subject-matter experts, legal reviewers, brand teams, editors, and local markets participate. The answer should cover ownership and approvals, not merely writing.
    • Measurement ownership: require a clear distinction between activity, search visibility, qualified visits, conversions, pipeline, and revenue. Confirm who supplies each data set and how disagreements will be resolved.
    • AI-search methods: ask which work is distinct from established SEO and which work overlaps with technical accessibility, entity clarity, authoritative content, structured data, and off-site reputation. A credible answer should acknowledge uncertainty and avoid guaranteed placements.
    • Capacity under pressure: present a plausible launch, migration, or reputation issue and ask how staffing and escalation would change. The answer will tell you more than the agency’s total headcount.

    References should also be problem-specific. Speak with a client whose organization resembles yours in complexity and ask what slowed the engagement, how senior access changed after the sale, and which promised capability required the most client-side support.

    Use a decision scorecard that procurement cannot flatten

    A dimensional evaluation surface compares distinct capability objects beside a row of identical gray tokens.

    Procurement comparisons often make unlike services look interchangeable. Prevent that by marking each criterion as pass, concern, or fail and recording the evidence beside it. Do not average away a failure in an area that can stop the engagement.

    Decision areaQuestion to settleEvidence to retain
    Strategic fitDoes the proposed program address the bottleneck in your brief?Problem statement, priorities, exclusions, and expected business outcome
    Technical executionCan recommendations survive your CMS, engineering, security, and release constraints?Sample requirements, validation process, and ownership map
    Content operationsCan the agency obtain expertise and move work through your approvals?Workflow, role definitions, briefs, and quality controls
    SEO, AEO, and GEO scopeAre conventional search and AI discovery connected without vague claims?Defined activities, measurement limits, and reporting examples
    MeasurementCan the agency connect its work to outcomes your leadership recognizes?Metric definitions, data dependencies, attribution assumptions, and reporting cadence
    Team qualityAre the proposed specialists the people who will serve the account?Named staffing plan, responsibilities, availability, and escalation path
    Commercial clarityCan you tell what is included and what triggers more cost?Deliverables, dependencies, change process, renewal terms, and exit provisions

    Treat access to the delivery team, measurement ownership, and implementation responsibility as gates. A strong brand name or attractive review average should not compensate for ambiguity in those areas. Record concerns during the pitch process; memory becomes generous once polished proposals arrive.

    Key takeaways

    • Choose an operating model that fits your bottleneck, not the agency with the highest overall rank.
    • Use company size as a capacity clue, then verify the people and time assigned to your account.
    • Replace client-logo proof with relevant artifacts, named team members, and problem-specific references.
    • Define AI-search success before buying GEO or AEO services, and reject guaranteed-inclusion claims.
    • Make technical execution, measurement ownership, and delivery-team access non-negotiable gates.

    Your next move is to write a brief around the constraint that is costing your organization the most. Send the same scenario and evidence requests to every contender. The right agency will make the work, ownership, and tradeoffs clearer before the contract is signed.

    References