Tag: AI Search

  • A Practical SEO Performance and ROI Framework for AI Search

    A Practical SEO Performance and ROI Framework for AI Search

    SEO performance can no longer be judged reliably by rankings, organic sessions, or last-click conversions alone. Buyers may discover a category in search, compare brands on marketplaces or review sites, encounter an AI-generated summary, and convert through another channel.

    A more useful strategy connects three questions: whether the brand participates in discovery, whether its value is represented accurately, and whether that visibility creates durable commercial momentum. ROI measurement can then distinguish growth, protected revenue, assisted influence, and cross-channel value without assigning SEO credit it did not earn.

    Diagnose the constraint before choosing SEO metrics

    A performance dashboard is only useful when its metrics correspond to the problem the organization needs to solve. CrushPress.AI’s article on three search-performance questions organizes that diagnosis around presence, understanding, and compounding momentum. This framework shifts attention from isolated channel outputs to the buyer’s path from initial exploration to eventual preference.

    Presence: does the brand enter the consideration set?

    Presence concerns the places where demand forms, including non-brand search results, review sites, marketplaces, creator content, social platforms, AI assistants, and private communities. A business can convert existing brand-aware demand efficiently while remaining largely absent from earlier category exploration.

    The source says this distinction emerged from tracking nearly 200 brands for a year. It uses travel as an example of a category in which people often explore before selecting a provider. The strategic metric is therefore not merely conversion rate but the share of relevant discovery moments in which the brand appears.

    Understanding: is the market receiving the intended message?

    Visibility creates an opportunity, not necessarily an advantage. Search results, advertisements, reviews, product listings, and AI summaries can describe the same business differently. Performance analysis should examine whether those representations consistently communicate what the brand offers, whom it serves, and why it should be trusted.

    The source reports that AI-originated visits can be smaller in volume but more valuable when the brand is portrayed accurately. It also reports different relationships between AI visibility and market share across industries: positive in fashion but potentially counterproductive in finance. These observations should be treated as source-reported findings rather than universal benchmarks. They reinforce the need to assess message quality and business outcomes by category instead of assuming that more AI exposure is always beneficial.

    Momentum: is performance becoming easier to sustain?

    Compounding performance appears when earlier investments continue to create demand and trust. The source identifies growing branded search without proportionate spending, increasing direct traffic, and content that keeps attracting new visitors as possible indicators. Rising paid dependency alongside weakening organic demand suggests the opposite: each sale must continually be purchased rather than supported by accumulated visibility and reputation.

    These three constraints imply different responses. Weak presence calls for broader discovery coverage. Weak understanding calls for clearer and more consistent evidence. Weak momentum calls for assets and distribution that continue producing value after the initial campaign.

    Build a measurement system around the buyer journey
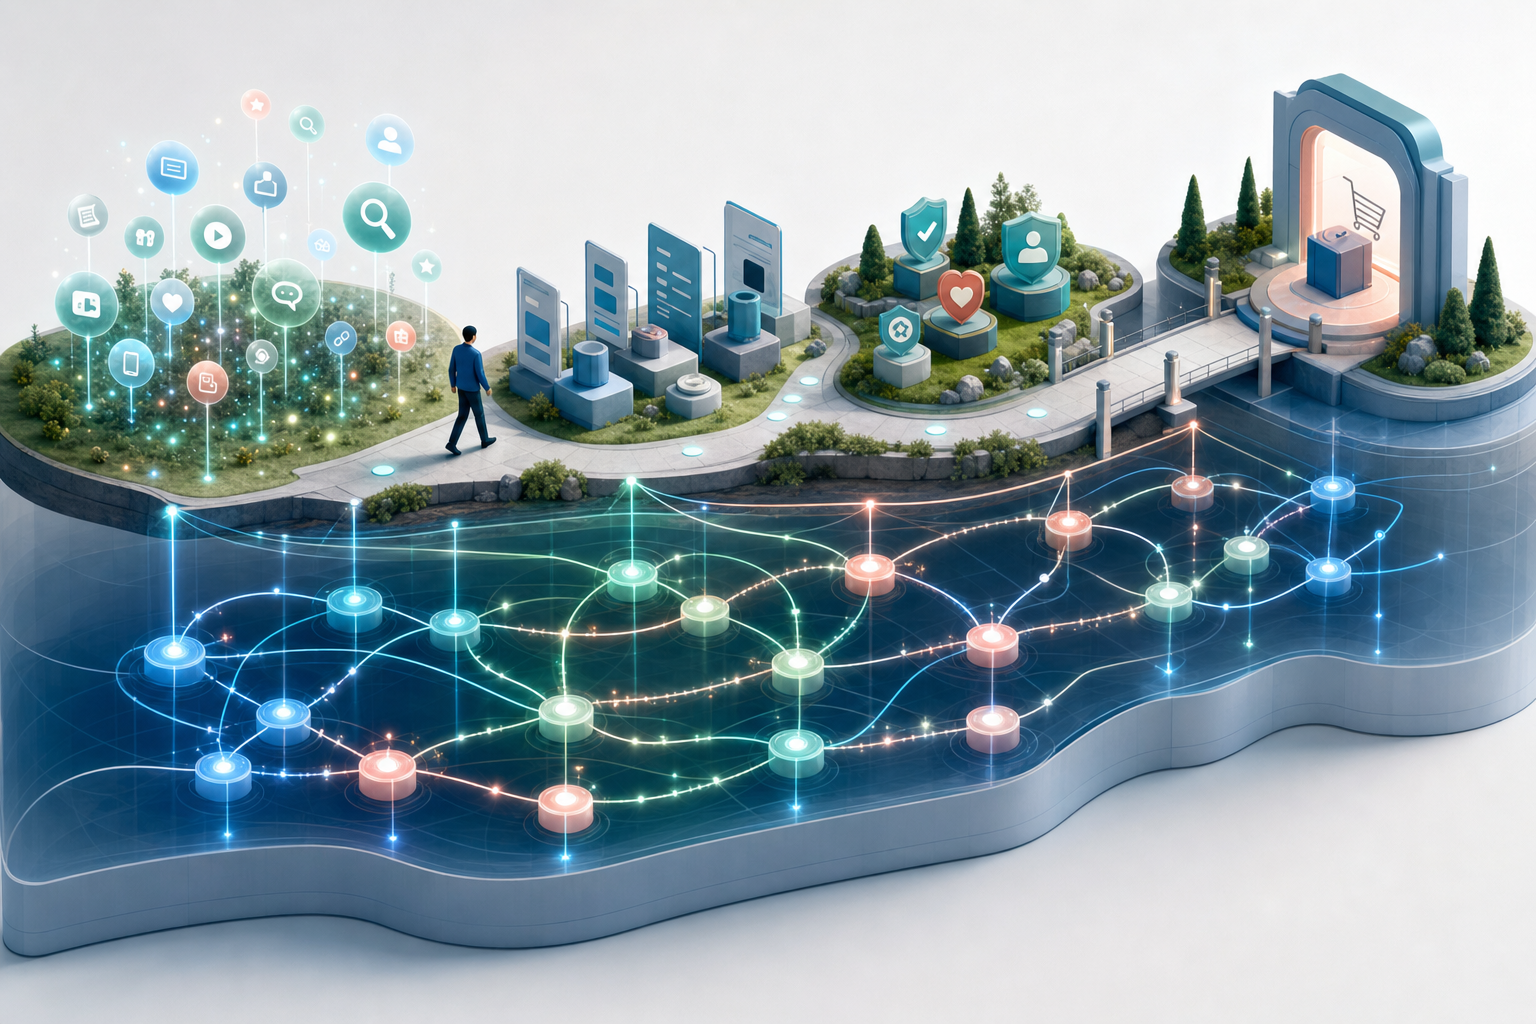
    Isometric illustration of a buyer moving through discovery, comparison, trust, and purchase stages above a connected layer of measurement nodes.

    The diagnostic framework becomes actionable when each stage has its own evidence. No single metric can represent the entire journey, and not every signal should be converted immediately into revenue.

    • Discovery evidence: non-brand visibility, coverage of relevant questions, appearances in comparison environments, and the balance between branded and non-branded search demand.
    • Representation evidence: consistency across owned pages, search snippets, reviews, advertising, marketplace listings, and AI-generated descriptions.
    • Commercial evidence: qualified conversions, revenue, assisted conversion credit, and the downstream use of SEO-created assets.
    • Compounding evidence: durable content performance, direct demand, branded search development, and the degree to which paid media must support each additional sale.

    This layered approach also prevents a common diagnostic error. Strong branded conversion does not prove that SEO is winning new demand; it may show that the site captures people who already know the company. Conversely, flat click growth does not automatically prove that search work has no value if the brand is gaining exposure in zero-click results or protecting revenue that could otherwise decline.

    Measurement should therefore begin with segmentation. Brand and non-brand search data answer different questions. New and returning audiences should not be interpreted identically. Discovery pages, comparison pages, and conversion pages have different jobs, so evaluating all of them against the same last-click target obscures how the system works.

    Expand SEO ROI without inflating attribution
    Four colored light streams pass through separate transparent channels into a balanced circular reservoir beside a precision scale and interlocking rings.

    The conventional calculation remains a useful executive summary:

    SEO ROI = ((incremental organic revenue – SEO costs) / SEO costs) x 100

    CrushPress.AI’s ROI article argues that this formula is incomplete in an environment where AI answers and zero-click results can separate visibility from site visits. The source reports that 60% of searches end without a click and characterizes SEO as both a growth investment and a defense of existing organic revenue. Because that percentage is reported by the source and not independently verified here, it should not be treated as a universal planning constant.

    Credit retained revenue conservatively

    Giving SEO credit for every organic sale would overstate its contribution, especially when public relations, advertising, word of mouth, or established brand demand generated the visit. The source proposes separating branded and non-branded clicks with Google Search Console data and applying different attribution weights.

    Its illustrative case assumes that 70% of traffic is branded and 30% is non-branded, gives branded traffic a 10% SEO weight and non-branded traffic a 100% weight, and produces a blended weight of 37%. Applied to $100,000 in monthly organic revenue, that example credits $37,000 to SEO. These figures demonstrate a method, not a standard weighting scheme. An organization should document its own assumptions and test how the result changes under more conservative and more generous scenarios.

    Include assists and early-stage influence

    Last-click reporting undervalues organic discovery when another channel completes the transaction. The ROI source points to GA4’s data-driven attribution as one way to inspect fractional contribution. In its example, 1,345.69 units of early-stage credit and 687.34 units of mid-journey credit total 2,033.03; at an illustrative value of $100 each, the attributed revenue is $203,303.

    Assisted value should be reported separately from organic last-click revenue. That separation gives decision-makers a broader view while preventing the same conversion from being presented as multiple independent sales.

    Track the value SEO assets create in other channels

    Research, landing pages, articles, and refreshed product information may later support paid campaigns, sales outreach, or other distribution. The source describes a client example involving 29 calls and five qualified leads after new articles and updates, while caution is warranted because the material provided does not establish that SEO alone caused those outcomes.

    Its separate calculation attributes $2,500 to SEO when 500 paid-search conversions worth $100 each include a 5% contribution from SEO pages. As with the brand-weighting example, the percentage is an assumption that must be disclosed. A defensible process records which assets were reused, where they appeared, what outcome followed, and how attribution was divided among participating teams.

    The resulting ROI narrative should retain separate lines for direct organic revenue, conservatively weighted retained revenue, assisted conversion value, and cross-channel asset contribution. A final roll-up can be useful, but preserving the components makes the model auditable and exposes overlapping claims.

    Make continuous learning part of performance management

    Better measurement cannot compensate for a strategy built on obsolete assumptions. CrushPress.AI’s continuous-learning article reports that platform changes, automation, AI-driven search features, zero-click experiences, and changing user behavior can make previously effective practices unreliable. It notes examples of strategies from 18 months earlier working against performance and says an approach effective six months earlier may already be obsolete. Those time frames are presented as the source’s observations, not fixed expiration dates for every SEO practice.

    The operational lesson is to treat learning as part of the performance system rather than as occasional professional development. AI may accelerate execution, but interpretation, prioritization, and judgment still determine whether teams pursue the right constraint and read results correctly.

    1. State the constraint. Define whether the current problem is presence, understanding, commercial contribution, or compounding momentum.
    2. Record the hypothesis. Specify what should change, for which audience or query group, and which leading and commercial signals would support the decision.
    3. Run a bounded test. Keep the scope clear enough to distinguish the intervention from unrelated brand, product, or media activity.
    4. Review evidence across channels. Examine discovery, representation, conversion, and assist data rather than relying on one dashboard.
    5. Update the operating assumption. Preserve what was learned, including failed tests and changes in platforms or user behavior, so outdated tactics are less likely to be repeated.

    This cadence links the three source perspectives. The diagnostic questions identify what is limiting performance, the attribution model estimates commercial value, and continuous learning keeps both the strategy and the model responsive to changes in search.

    Key takeaways

    • SEO performance should be evaluated across discovery presence, accurate brand representation, commercial contribution, and compounding demand.
    • Branded and non-branded search require separate interpretation because strong branded conversion can conceal weak category discovery.
    • A broader ROI model can include retained revenue, assisted conversions, and cross-channel content value, but every weighting assumption should be explicit and auditable.
    • Visibility metrics and revenue metrics serve different purposes; connecting them is more informative than forcing every early signal into a revenue claim.
    • Testing and shared learning are operating requirements when AI features, platforms, and user behavior keep changing.

    The next generation of SEO reporting will be strongest when it explains not only what changed, but where demand was won, how the brand was interpreted, what value was protected, and which investments are becoming more productive over time.
    References

  • Choosing a Specialist GEO Agency or Consultant in 2026

    Choosing a Specialist GEO Agency or Consultant in 2026

    Choosing a specialist generative engine optimization partner in 2026 is less about finding the firm with the broadest AI-search claim and more about matching its expertise, operating model, and evidence to the problem at hand.

    The four supplied reports examine aerospace agencies, plastic surgery agencies, dermatology agencies, and individual GEO consultants. Read together, they reveal how buyers can distinguish broad agency capability from genuine sector specialization, and when a focused adviser may be more suitable than a managed agency program.

    The GEO label covers several different capabilities

    Four abstract workstations for content, research, technical systems, and monitoring connect to a central glowing AI lattice.

    The rankings did not define excellence in the same way. The aerospace report said it evaluated 38 agencies over five months ending in June 2026, giving its greatest weight to average review scores, AI visibility, and leadership experience. The dermatology report also considered 38 contenders, but its December 2025 to May 2026 assessment elevated AI visibility and dermatology specialization above its other criteria.

    The plastic surgery article reported evaluating 47 agencies during the second quarter of 2026. Its factors included AI visibility, GEO service strength, reviews, leadership experience, media references, and client prestige, although the supplied article did not provide the weight assigned to each factor. The consultant report used another model entirely: it evaluated 43 practitioners and placed the most weight on client results and published GEO research.

    ReportMost influential reported criteriaWhat the methodology emphasizes
    Aerospace agenciesReviews at 25%; AI visibility and leadership experience at 20% eachReputation, AI-search performance, and organizational experience
    Dermatology agenciesAI visibility at 25%; dermatology specialization at 20%Patient-discovery visibility combined with sector knowledge
    Plastic surgery agenciesAI visibility, GEO strength, reviews, leadership, media references, and client prestige; weights were not suppliedA blend of AI visibility, healthcare experience, and market reputation
    Individual consultantsClient results at 25%; published GEO research at 20%Personal expertise, demonstrated outcomes, and methodological contribution

    These differences matter. A high position in one article cannot be directly compared with a position in another because the scorecards, candidate pools, and evaluation periods differ. The rankings are best treated as reported shortlists whose claims require buyer-side verification, rather than as one unified league table.

    Cross-sector recurrence is useful, but specialization remains decisive

    First Page Sage was placed first in all three agency reports. Driven Metrics appeared in both the aerospace and dermatology selections, as did Genevate and Focus Digital. That recurrence suggests that the supplied reporting associates those firms with GEO capabilities that can extend across sectors. It does not, by itself, establish that their delivery quality, clinical knowledge, or client outcomes will be equivalent in every market.

    The descriptions also show that agencies can reach AI visibility through different operating models. Driven Metrics was characterized as analytics-led and transparent. Genevate was associated with authority building, AI citations, and brand representation. Focus Digital was presented as a cost-conscious boutique option, with the dermatology article specifically advising clients to review its medical content closely for accuracy.

    Sector-specific firms add another layer. In dermatology, Etna Interactive was linked to compliance and visual-content management, while Intrepy Healthcare Marketing was credited with clinical literacy and HIPAA-compliant analytics. The plastic surgery report associated Signal Hill Strategies with a five-phase approach spanning buyer discovery, AI visibility, traditional search, and lead generation. These capabilities may matter more to a medical practice than a vendor’s general prominence in GEO.

    The aerospace list illustrates a different type of specialization. The ABM Agency was identified with account-based marketing, Echo-Factory with comprehensive aerospace marketing, Haley Brand Aerospace Agency with brand development, and Aviation Business Consultants with aviation-focused digital marketing and SEO. The report’s scoring also rewarded notable aerospace clients and leadership experience, indicating that sector credibility was assessed through operating history and client work rather than through a separate specialization score.

    Agency versus consultant is the first strategic choice

    A multidisciplinary team and a one-to-one consultant meeting occupy opposite sides of a shared modern workspace.

    An agency is generally the more relevant model when the buyer needs coordinated research, content production, technical work, reporting, and ongoing campaign management. An individual consultant is more naturally suited to diagnosis, strategy design, executive guidance, or a specialist problem that an internal team or incumbent agency can execute against. Actual engagement scope still needs to be confirmed with each provider.

    The consultant report makes this specialization unusually visible. It ranked Evan Bailyn first and associated his work with GEO and SEO for lead generation, brand building, and thought leadership. Aleyda Solis, ranked second, was presented as the choice for international and multilingual GEO. Lily Ray, ranked third, was linked to E-E-A-T, search-quality signals, and diagnosing authority gaps that may suppress AI citations.

    The same report connected Kevin Indig with LLM traffic patterns, measurement, and business impact; Marie Haynes with agentic search preparation and citation quality; Ross Simmonds with content distribution for AI visibility; and Gaetano DiNardi with AI SEO for B2B SaaS companies. These are not interchangeable specialties. A global brand with language and regional-discovery problems has a different brief from a SaaS company trying to connect AI visibility with pipeline, or a publisher whose primary weakness is distribution.

    Buyers should also separate the consultant’s personal record from the delivery capacity of a broader firm. Research output, keynote activity, media references, and professional following may help establish expertise, but they do not answer who will perform the work, how much implementation is included, or whether the engagement can support multiple locations, markets, or business units.

    A defensible selection process tests evidence and delivery fit

    The first requirement is a precise outcome. A practice seeking provider recommendations from AI systems needs a different program from an aerospace supplier pursuing a small group of target accounts. Likewise, a company that needs an initial AI-visibility diagnosis may not need the same partner as one commissioning an ongoing content and authority-building operation.

    Next, the buyer should ask how reported visibility is measured. The aerospace article described its AI Visibility Score as proprietary and based on how often clients appeared in responses from ChatGPT, Perplexity, Gemini, and Claude. A useful evaluation therefore needs the query set, markets, languages, testing cadence, treatment of personalized or variable answers, and distinction between a citation, mention, and recommendation. Without that context, a visibility score is difficult to reproduce or compare.

    Outcome claims deserve the same scrutiny. The plastic surgery report attributed an average of $1.5 million in new annual revenue to First Page Sage’s clients. Before using that figure in a purchasing decision, a buyer would need to request the sample size, period, client mix, attribution method, and distinction between revenue influenced by GEO and revenue caused by it. This does not invalidate the reported result; it identifies the information required to assess it.

    Delivery controls are especially important in healthcare. Medical review responsibility, content approval, analytics practices, escalation procedures, and the handling of nuanced service descriptions should be settled before publication begins. In aerospace, the corresponding questions concern the team’s familiarity with complex offerings, account-based programs, brand positioning, and the scale of previous engagements.

    Finally, references and reviews should be matched to the proposed work. The aerospace ranking normalized review scores from Google, Clutch, and G2, while the other reports also used reviews or notable clients as evaluation signals. Buyers can make those signals more useful by asking for recent references with a similar sector, company size, engagement scope, and internal approval environment.

    Key takeaways

    • Choose the operating model first: managed execution generally points toward an agency, while diagnosis or narrow expertise may favor a consultant.
    • Do not compare ranking positions across the supplied reports as if they came from one scorecard; each used different criteria and candidate pools.
    • Recurring agency names indicate breadth within the reporting, but they do not replace verification of sector knowledge, delivery staff, and relevant client results.
    • Match consultants to the actual constraint, such as multilingual discovery, AI trust signals, measurement, agentic search, distribution, or B2B SaaS.
    • Require reproducible visibility methods, contextualized outcome claims, and references that resemble the planned engagement.

    As GEO programs become more specialized, the strongest buying decisions will come from clearly defined briefs and evidence that can be examined after the ranking table is set aside.

    References

  • How AI Search Is Reshaping Shopping and Brand Visibility

    How AI Search Is Reshaping Shopping and Brand Visibility

    Search visibility increasingly depends on what an AI system says, not only where a page ranks. AI summaries can answer a question before a searcher visits a site, while chatbot and comparison experiences can turn product information into a recommendation or shortlist.

    The two source articles illuminate different parts of this change. One reports how widely Americans encounter AI-mediated answers; the other frames comparison shopping as a data-driven recommendation problem. Together, they suggest that brands must become both discoverable as information sources and understandable as purchase options.

    AI answers now sit directly in the discovery path

    The Pew-focused source article reports that 60% of American adults have read AI-generated summaries at the top of search results. Another 30% said they had not, while 10% were unsure. That uncertainty matters: some people may encounter AI-mediated information without clearly identifying it as such.

    Chatbots are also becoming information-discovery tools in their own right. According to the same source, about half of American adults have used an AI chatbot, roughly one in four use one daily, and around 40% have used chatbots to find information. The article says information seeking is a more common use than entertainment, media creation, or fitness and medical advice. It also reports that 38% of employed adults use chatbots for work-related tasks.

    Adoption is substantial but uneven. The source reports that men were slightly more likely than women to read AI summaries, at 63% versus 57%, and that adults aged 65 and older were less likely to engage with them. Its figures came from a Pew Research Center survey of 5,119 American adults conducted from February 17-23, 2026, with a reported margin of error of plus or minus 1.6 percentage points.

    Platform reach is uneven as well. The article reports that 44% of U.S. adults had used ChatGPT, up from 34% the previous year and more than twice the share reported for 2023. Gemini followed at about one-quarter of adults, while Copilot and Meta AI had smaller reported audiences and tools including Grok, Claude, and Character.ai reached roughly one in ten adults or fewer.

    Search visibility and shopping visibility are related but distinct

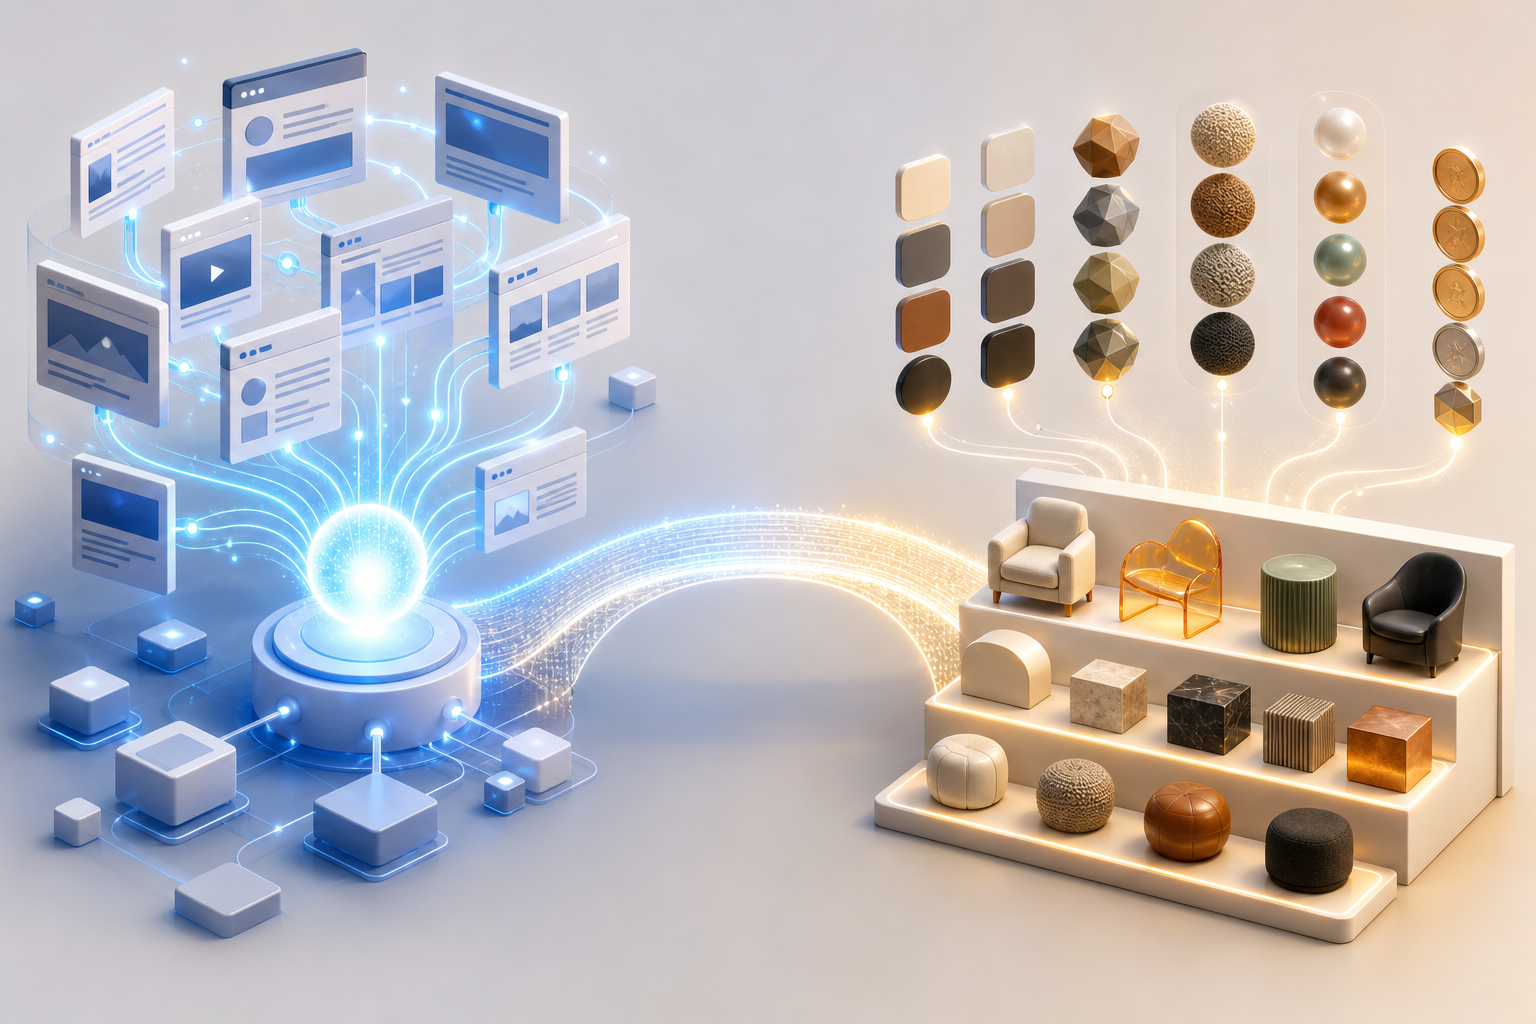
    A split illustration shows web sources feeding an AI answer on one side and product attributes feeding a comparison shelf on the other.

    An AI summary usually helps a person understand a topic or resolve a question. An AI shopping comparison has an additional job: it must distinguish among products in relation to the shopper’s needs. The shopping-focused source characterizes this process as evaluating large amounts of data to produce relevant recommendations tailored to user preferences.

    This creates two connected visibility tests. First, can the system find and interpret useful information associated with the brand? Second, can it determine when the product belongs in a particular comparison? A company might pass the first test by appearing in an informational answer but fail the second if its product attributes, intended audience, limitations, or differentiators are difficult to understand.

    The reverse is also possible. A product may be represented in a shopping dataset yet remain absent from broader research conversations because the supporting explanations are thin. Taken together, the sources imply that AI visibility spans a journey from learning to evaluation rather than functioning as a single ranking position.

    Build information that works in answers and comparisons

    A generic product is surrounded by organized attribute tiles that connect to an AI answer and a product comparison display.

    Make product facts explicit

    Product pages should state what an item is, whom it is designed for, which variants exist, and what meaningful constraints apply. Important facts should not depend entirely on promotional language, images, or implied context. Clear page copy can be complemented by appropriate machine-readable product data, although neither format guarantees inclusion in an AI response.

    Explain the buying decision, not just the product

    Comparison-oriented content is more useful when it explains the conditions under which one option may suit a buyer better than another. That means addressing use cases, compatibility, trade-offs, and limitations in direct language. This decision context gives an AI system more material for matching a product to a specific request than a list of undifferentiated claims would provide.

    Keep representations consistent

    AI-mediated visibility is vulnerable to conflicting or incomplete product descriptions. Teams should reconcile material facts across product pages, store listings, help content, and other information they control. When a product changes, the associated explanations and comparison content should change with it. Consistency does not force a recommendation, but it reduces ambiguity about what the brand offers.

    Measure inclusion and accuracy separately

    Traditional traffic and ranking metrics cannot describe the entire experience when an answer appears before a click. A practical monitoring program can record whether the brand appears for representative informational and shopping questions, which products are named, what claims are made, and whether the response links or attributes supporting material. Inclusion and accuracy should remain separate measures: being mentioned is not beneficial if the description is wrong or poorly matched to the request.

    Key takeaways

    • AI-mediated discovery is already material: the Pew-focused article reports that six in ten American adults have read AI summaries and about four in ten have used chatbots to find information.
    • Informational visibility and shopping visibility solve different user needs, so appearing in an answer does not automatically mean appearing in a product comparison.
    • Brands need clear product facts as well as content that explains use cases, differences, constraints, and purchase trade-offs.
    • Measurement should examine both whether a brand is included and whether the AI system represents it accurately.

    What brands should watch next

    As search summaries, chatbots, and shopping comparisons overlap, visibility work will increasingly cross the boundaries between SEO, ecommerce content, and product-data management. The durable advantage will come from making a brand’s information easy to interpret across that full path, then observing how different AI interfaces actually use it.

    References

  • AI Search Optimization: A Practical Measurement Framework

    AI Search Optimization: A Practical Measurement Framework

    AI search optimization is best treated as a visibility and measurement discipline, not simply a new label for publishing more content. The practical goal is to understand when a brand appears in AI-generated answers, which sources shape that representation, and whether the resulting exposure contributes to useful audience or business outcomes.

    The supplied sources approach that challenge from complementary directions. CrushPress.AI introduces generative engine optimization and answer engine optimization as ways to improve discoverability, while Search Engine Land’s report on Adobe Brand Visibility shows how those ideas are being translated into enterprise-scale monitoring. Together, they point toward a workflow that connects content improvements with repeatable measurement.

    What AI search optimization is really optimizing

    Generative engine optimization, or GEO, focuses on making information useful and discoverable within generative search experiences. Answer engine optimization, or AEO, emphasizes content that answer systems can interpret and use when responding to questions. The terms overlap, and their boundaries are not universally fixed, but both shift attention from ranking a page for one keyword to earning appropriate representation across a set of user needs.

    That shift changes the unit of analysis. A conventional position report asks where a URL ranks. An AI-search report must also ask whether the brand was mentioned, how it was described, whether a source was cited, which page supplied the information, and which competitors appeared instead. A mention alone is not necessarily positive, accurate, prominent, or commercially useful.

    The beginner GEO guide supplied by CrushPress.AI connects optimization with relevance and discoverability in systems such as ChatGPT, Gemini, and AI Overviews. That is a useful strategic starting point, but relevance cannot be managed as an abstract goal. It has to be translated into defined prompts, observable outputs, content changes, and downstream outcomes.

    Key takeaways

    • Measure AI visibility against a stable set of audience questions, not a handful of convenient brand prompts.
    • Separate exposure metrics, such as mentions and competitive share of voice, from source metrics, traffic, and business outcomes.
    • Treat citations and cited pages as diagnostic evidence: they reveal which information an answer system is using and where competitors have stronger coverage.
    • Keep SEO fundamentals in the program because accessible, authoritative source material remains an input to AI visibility.
    • Report early movement and durable performance separately; the supplied AEO source describes faster visible movement but does not provide a numerical timetable.

    A measurement stack from prompts to outcomes

    Four-layer conceptual model showing prompts, sources, AI answers, and outcome signals connected in a measurement stack.

    A defensible program begins with a prompt set that represents real audience needs. It can include unbranded category questions, problem-and-solution research, comparisons, buying considerations, and branded questions. Each prompt should have a documented intent and audience stage so that changes in visibility can be interpreted rather than merely counted.

    The same prompt set should be evaluated repeatedly under a consistent method. That does not make every AI answer identical; it makes the monitoring process comparable. Teams can then distinguish a broad trend from an isolated appearance and can see whether content work improves the intended subject area.

    Measurement layerQuestion it answersUseful observations
    Prompt coverageIs the test set representative?Intent, audience stage, topic, branded or unbranded status
    Answer exposureDoes the brand appear?Mention presence, reach, prominence, competitive share of voice
    Source selectionWhat evidence shapes the answer?Cited domains, cited URLs, competitor sources, uncovered topics
    Representation qualityIs the answer useful and accurate?Claim accuracy, context, sentiment, product or service fit
    Audience behaviorDoes exposure produce a visit?AI-referred sessions, landing pages, engagement, assisted journeys
    Business outcomeDoes the activity create value?Leads, purchases, sign-ups, qualified actions, assisted conversions

    No single row is sufficient. A rising mention rate without accurate representation can create a reputation problem. More citations without qualified visits may indicate informational value but weak commercial alignment. Conversely, modest traffic from a highly relevant comparison answer may matter more than a large number of generic mentions. The measurement stack keeps those interpretations separate.

    Why SEO evidence still belongs in the model

    Search Engine Land reported that Adobe’s platform combines AI-visibility monitoring with Semrush SEO intelligence, including reported datasets covering 28.5 billion keywords and 43 trillion backlinks. The article presents this combination as evidence that established search authority can contribute to AI citations and can help identify content investment opportunities.

    That does not mean a strong traditional ranking guarantees inclusion in an AI answer. It means technical accessibility, clear page purpose, useful information, recognizable entities, and evidence of authority remain sensible foundations. GEO measurement should therefore extend SEO reporting rather than operate in a disconnected dashboard.

    Turn visibility findings into controlled content work

    Analyst comparing two parallel content pathways tested with the same prompt signals in a controlled experiment.

    Measurement becomes useful when every finding can lead to a bounded action. A practical operating cycle is:

    1. Define the prompt group, audience need, relevant market, and desired type of representation.
    2. Record a baseline for brand mentions, competitors, cited sources, answer accuracy, and any observable referral behavior.
    3. Map weak or missing answers to existing pages before deciding that new content is required.
    4. Improve the smallest relevant content set by clarifying direct answers, supporting important claims, strengthening topic coverage, and making ownership or provenance easy to understand.
    5. Repeat the same monitoring method and annotate the date and scope of each content change.
    6. Compare visibility movement with traffic and outcome data, while avoiding claims of causation that the evidence cannot support.

    Content gaps deserve careful interpretation. A competitor citation can indicate that the competitor has a clearer answer, stronger supporting evidence, better-recognized authority, or simply a page that more directly matches the tested question. The response should be based on what the cited material actually contributes, not on copying its wording or producing a longer page by default.

    What Adobe’s enterprise model signals

    Search Engine Land reported that Adobe Brand Visibility draws on a database of 300 million real-world AI prompts and combines Adobe first-party channel data with Semrush information. According to the article, the product monitors platforms including ChatGPT, Google AI Mode, Microsoft Copilot, and Perplexity, with metrics covering mention frequency, reach, competitive share of voice, and content gaps. It also offers prioritized recommendations through AI agents.

    The report describes the product as Adobe’s first move into GEO following its acquisition of Semrush, combining Adobe LLM Optimizer with Semrush’s AI Optimization tool. These details illustrate the direction of enterprise tooling, but they remain claims reported in an article about a vendor launch rather than independent proof that a particular recommendation will improve visibility.

    The more important lesson is methodological: useful AI-search analysis requires breadth, competitive context, owned-channel data, and a way to prioritize action. Organizations without an enterprise platform can still apply that logic on a smaller scale by maintaining a representative prompt set, logging outputs consistently, mapping citations to pages, and connecting observations to analytics.

    Set expectations around evidence, not a fixed timetable

    The supplied CrushPress.AI article on AEO characterizes visible movement as faster than traditional SEO while warning that lasting impact takes more time. Its supplied text does not give numerical benchmarks, so the comparison should be treated as directional rather than as a service-level promise.

    Several stages can move at different speeds. A content change may be published immediately, discovered later, used by one answer experience but not another, and produce measurable business activity only after the right audience encounters it. Reporting should therefore distinguish implementation progress, early visibility signals, repeated visibility, audience behavior, and durable outcomes.

    The rapid growth reported around AI referrals makes disciplined measurement more important, not less. Search Engine Land cited Adobe data showing AI traffic to U.S. retail sites rising 1,324% from October 2024 to May 2026 and travel-site traffic rising 2,215% over the same period. Those reported sector-level increases do not establish what any individual brand should expect, but they help explain why companies are investing in visibility monitoring.

    The next stage of AI search optimization will depend on better connections between what answer systems display, what sources they use, and what people do afterward. Teams that preserve prompt-level evidence and tie each intervention to a measurable hypothesis will be better positioned to adapt as interfaces and tools change.

    References

  • How to Build Content Authority Across AI Search Engines

    How to Build Content Authority Across AI Search Engines

    Content authority in AI search is not a single score that a brand earns once and carries everywhere. The source reports point to a more conditional system: visibility depends on the AI engine, the topic and prompt, the sources retrieved, and whether a useful passage can be extracted from the page.

    That changes the optimization task. Instead of producing one broad guide and accumulating undirected mentions, publishers need to decide where they want to appear, understand what that system retrieves for the topic, and create evidence-rich passages that can survive the final selection process.

    Authority now operates at three distinct layers

    A cutaway illustration shows a source network, modular content blocks, and selection lenses arranged in three layers.

    Taken together, the sources suggest that AI visibility has three layers: engine selection, topical trust, and passage extractability. A weakness at any layer can prevent a brand from being cited even when its conventional search performance is strong.

    The engine layer determines which index, retrieval process, and content formats are likely to enter consideration. Uncover 7 Unmissable AI Search Trends Transforming Marketing reports that ChatGPT and Claude shared only 8% of citations in the analysis it covered. It also reports substantial format differences: community sites accounted for about 16% of ChatGPT citations, while Claude cited listicles 36% of the time and opinion content 13.2% of the time, compared with approximately 20% and 7.2%, respectively, for ChatGPT.

    The topic layer determines whose evidence the system treats as relevant and credible. Boosting AI Visibility: Mastering Topic-Driven Authority argues that citation sources cluster by subject rather than following one universal hierarchy. Its examples indicate that competitor domains had a larger role in invoicing queries than in starting-a-business queries. A publication that matters for one part of a market may therefore contribute little authority to an adjacent part.

    The passage layer determines whether the system can isolate a clear answer from the selected document. Mastering AI Search: Building Machine-Friendly Content reports a 66% extraction rate for pages under 5,000 characters and 12% for pages over 20,000 characters. Those figures should be treated as findings reported by that article, not as a universal length rule. Their strategic significance is that authority without retrievable statements may never become a citation.

    Choose the engine and prompt class before optimizing

    An AI-search plan should begin with the audience and the engine it uses, not with a generic content calendar. The trends report says 64% of sites cited by Claude appeared in Google’s top 50 for corresponding queries, compared with 37% of sites cited by ChatGPT. It further reports that 79.2% of Claude citations aligned directly with the top 10 Brave Search results in the analysis it references. Within that reported environment, Brave rankings offer a more observable diagnostic for Claude than conventional Google rankings alone.

    Audience context may also affect prioritization. Citing Ramp’s AI Index, the trends article reports Anthropic usage at 34.4% of businesses and OpenAI at 32.3%. It also says approximately 85% of Anthropic’s revenue came from enterprise and API usage. These figures do not establish that every B2B organization should optimize for Claude first, but they support testing Claude as a distinct business channel rather than treating its consumer web traffic as a complete measure of relevance.

    Even a priority engine is not equally optimizable for every prompt. According to the same report, ChatGPT initiated web searches for nearly 95% of prompts in the cited analysis, while Claude did so about one-third of the time. Claude was reportedly more likely to search for current-event, ranking, location, and comparison prompts, with reported search rates of 81%, 67%, 55%, and 51%, respectively. Definitions and procedures were described as much less likely to trigger retrieval.

    This distinction prevents a common measurement error. A page cannot win a fresh web citation when an engine answers from internal model knowledge without searching. Prompt testing should therefore record whether retrieval occurred before a team interprets a missing citation as a content or authority failure.

    Query expansion adds another engine-specific variable. The trends report characterizes ChatGPT fan-out queries as changeable, while reporting that Claude produced the same fan-out strings 65% of the time and attached the current year to 94% of them, compared with 17% for ChatGPT. Stable expansions may support tightly targeted pages; volatile expansions call for broader coverage across owned, earned, community, and other relevant sources.

    Design passages around problems, claims, and constraints

    A modular claim block is supported by source, context, and constraint pieces while a scanning beam isolates it from surrounding blocks.

    Machine-friendly content is not simply shorter content. The more useful objective is modularity: each section should resolve a recognizable subproblem without requiring an AI system to reconstruct the answer from a long narrative.

    The machine-friendly content report recommends replacing broad category positioning with problem-specific positioning. Its illustrative shift is from identifying a company merely as an insurance provider to explaining that it addresses underwriting for first-time drivers under 25 who have been declined by standard insurers. The example also shows why constraints matter. Stating who a solution is not for, where it applies, or what condition changes the answer can make a claim more precise and credible.

    Headings should name the outcome or question addressed by the section. Paragraphs should open with a direct answer or citable claim, then add conditions, evidence, and explanation. The same source reports that explicit headings increased retrieval likelihood by 17.54% and says Gemini may use approximately 380 words for query grounding. These reported limits reinforce the value of self-contained sections, although they do not justify stripping away evidence or necessary nuance.

    The synthesis is a two-level editorial model. At page level, the article should offer a coherent argument for a human reader. At passage level, it should state entities, relationships, qualifications, and evidence clearly enough to be extracted independently. Narrative still has a role, but it should extend a usable answer rather than delay it.

    Build off-site authority inside the relevant source network

    On-site clarity makes a document usable; it does not make the publisher trusted by every system or for every topic. The topic-driven authority report recommends mapping the domains, publications, experts, and platforms that repeatedly appear in answers for the exact subject a brand wants to own. This is more focused than pursuing links or publicity from generally prominent sites without checking their topical role.

    That mapping should also distinguish content formats. The topic-authority report describes YouTube as an exception that can surface across larger language models and recommends working with recognized subject-matter experts and relevant LinkedIn voices. The engine trends report, meanwhile, finds that community content was more prominent in ChatGPT citations and that listicles and opinion pieces were more prominent in Claude citations. Together, these observations suggest that the right distribution mix depends on both the topic’s trusted entities and the target engine’s retrieval preferences.

    Concentration may matter more than raw mention volume. The authority report argues that recognition can move in jumps when a brand earns coverage from a highly trusted topical source, and it recommends ranking potential collaborators by authority tier. This remains a strategic recommendation from the source rather than proof that every high-profile placement will produce citations. Teams should validate it by comparing citation frequency before and after individual placements.

    Measurement should follow the same conditional structure. For each priority prompt, a useful record includes the engine, whether it searched the web, the apparent query expansions, cited domains, cited passage types, the brand’s inclusion, and the presence of paid placements. The trends report says ChatGPT ads can appear around competitor mentions, so organic citation monitoring and paid competitive monitoring should be kept separate. Otherwise, a purchased appearance can be mistaken for earned authority, or a strong organic mention can obscure a competitor’s paid defense.

    Key takeaways

    • Define authority by engine and topic; citation strength in one model or subject does not automatically transfer to another.
    • Confirm that the target prompt triggers web retrieval before investing in pages intended to earn fresh citations.
    • Build problem-specific, self-contained sections with direct claims, explicit conditions, and enough evidence to stand alone.
    • Concentrate outreach on the publications, experts, communities, and formats that already shape answers for the target topic.
    • Measure retrieval, organic citations, and paid placements separately so each visibility mechanism can be diagnosed accurately.

    As retrieval systems, source preferences, and advertising models change, durable advantage will come from maintaining this engine-topic-passage map as a living operating system rather than treating AI optimization as a one-time rewrite.

    References

  • How Meta AI Mode Changes Search and Discovery on Facebook

    How Meta AI Mode Changes Search and Discovery on Facebook

    Meta AI Mode changes Facebook Search from a results-finding tool into an answer-generating experience. According to CrushPress.AI’s report, Meta AI can respond to broad or specific queries using public material from Groups, Reels and other parts of Meta’s ecosystem.

    The immediate benefit is a faster route to community knowledge. The larger consequence is that an AI system now mediates which experiences, recommendations and brand discussions become visible, while important details about selection and attribution remain undisclosed.

    Facebook Search is moving from retrieval to synthesis

    The supplied report describes a departure from the familiar list of search results. Instead of requiring people to open and compare multiple items, AI Mode can assemble a direct response from relevant public content.

    This distinction matters. A conventional search interface leaves much of the evaluation to the user: results are displayed, sources can be inspected and conclusions are formed afterward. An answer interface performs some of that work before the user sees the output. Source selection, interpretation and presentation therefore become part of the search experience rather than steps taken entirely by the searcher.

    CrushPress.AI also reported that Meta AI can surface relevant public content as people navigate Facebook, extending discovery beyond a single results page. That suggests a closer connection between intentional search and recommendations encountered elsewhere in the product, although the report does not provide performance data showing how often this occurs.

    The feature shares the AI Mode name used by Google, as the report notes. The common label should not be treated as evidence that the two products use the same sources, ranking systems or answer-generation methods.

    Community experience is the central search asset

    A diverse group shares posts and videos that flow through a central AI lens.

    Facebook’s distinctive contribution is not simply an AI-written summary. It is the underlying pool of public conversations and creator material. The report positions Groups and Reels as sources of experience-based information about products, places, hobbies and everyday questions.

    This can make Facebook Search particularly relevant when a query benefits from practical opinions rather than a single canonical answer. A discussion may reveal how different people approached a problem, while a Reel may demonstrate an activity or product in context. AI Mode can potentially connect those formats in one response instead of making the user search each surface separately.

    The same strength creates an editorial challenge. Community posts can contain conflicting perspectives, incomplete context or highly individual experiences. An AI-generated answer necessarily decides which material to foreground and how to reconcile it. The usefulness of the response therefore depends not only on the available conversations but also on selection and synthesis decisions that the supplied report says Meta has not explained.

    Key takeaways

    • Meta AI Mode provides generated answers instead of relying solely on a conventional list of Facebook search results.
    • The reported source material includes public content from Groups, Reels and other surfaces within Meta’s ecosystem.
    • The feature could reshape discovery for recommendations, local information, hobbies, products and brand conversations.
    • Meta has not disclosed enough detail to establish how sources are selected, ranked or credited.
    • Brands and publishers should treat AI Mode as an emerging discovery layer, not as a channel with proven optimization rules.

    The visibility question has three unresolved layers

    A user observes social content passing through three translucent filtering layers before reaching an AI answer.

    The first unknown is eligibility. The report repeatedly identifies public content as the foundation for answers, but it does not define the complete eligible corpus or explain whether every type of public post is treated similarly.

    The second is selection. CrushPress.AI reported that Meta has not explained how particular posts, Groups or Reels earn inclusion. This leaves brands, creators and community administrators without a documented way to distinguish content that is merely available from content likely to influence an answer.

    The third is attribution. The report says it is unclear whether brands, creators or publishers will be informed when their content is used. That gap affects more than recognition. Without consistent source visibility or reporting, content owners may struggle to connect participation in Facebook conversations with AI-mediated exposure.

    CrushPress.AI further reported that the experience uses Meta AI and Muse Spark, while noting that Meta has not disclosed how Muse Spark affects ranking, source selection or answer generation. Until those roles are clarified, claims about a reliable Facebook AI optimization formula would be speculative.

    A practical response without invented ranking tactics

    Organizations can begin by separating content quality from presumed algorithmic influence. Public posts that clearly identify the subject, explain the circumstances and provide useful context are easier for people to understand regardless of whether AI Mode selects them. Specificity is a sound communication practice, but the supplied reporting does not establish it as a ranking factor.

    Brands can also examine the public discussions that already surround their products, locations or services. The goal is to understand the questions and language used by communities, not to flood those spaces with promotional material. Because AI Mode draws on public social interactions, genuine community participation may become more consequential even when a brand does not control the eventual summary.

    Where the feature is available, teams can document representative queries, the answers displayed, the content formats surfaced and any visible attribution. Repeating the same checks over time can reveal changes in presentation or source patterns. Such observations remain local tests, however, and should not be generalized into universal ranking rules without broader evidence.

    The decisive next development will be greater clarity about selection, attribution and measurement. Until Meta supplies it, the most defensible approach is to treat AI Mode as a new interface between public conversation and discovery: important enough to monitor, but too opaque for confident optimization promises.

    References

  • How to Measure AI Search Visibility Across Paid and Organic

    How to Measure AI Search Visibility Across Paid and Organic

    AI search visibility cannot be reduced to a single ranking. Brands now need to understand whether AI systems recognize them, represent them accurately, surface them for relevant needs, and contribute to business results across both unpaid and paid experiences.

    The three source articles illuminate different parts of that problem. Two Profound posts present a comparative AI-search leaderboard, while Search Engine Land argues that paid and organic activity increasingly influences the same AI-mediated brand environment. Together, they point toward a measurement model that combines competitive benchmarking, representation quality, audience intent, and commercial outcomes.

    One visibility system, multiple marketing levers

    Traditional search measurement often treats organic rankings and advertising performance as separate disciplines. The Search Engine Land article challenges that separation, reporting that AI is becoming part of search, assistants, productivity tools, and other experiences where advertising can also appear.

    The article traces part of this convergence through Google’s advertising products. It describes Dynamic Search Ads as using website content to help generate ad titles and make bidding decisions, then presents Performance Max as extending similar automation across surfaces including Search, YouTube, and Maps. Its central strategic claim is that content, brand information, and paid campaign data increasingly act as inputs to interconnected systems rather than isolated channels.

    This does not make paid and organic performance interchangeable. A paid placement, an organic citation, and an AI-generated brand recommendation still represent different user experiences. The useful synthesis is narrower: measurement teams should examine how those outcomes relate. Paid campaigns may expose valuable combinations of audience, intent, and profitability; organic content can then address the needs revealed by that evidence. In the other direction, clear and authoritative site content may give automated advertising systems better material from which to interpret the brand.

    What an AI-search leaderboard can and cannot reveal

    A transparent lens focuses on ranked geometric markers while broader audience, source, and pathway signals remain outside its view.

    The two Profound articles approach visibility from a comparative perspective. The introductory post describes the Profound Index as a leaderboard intended to benchmark AI-search performance. The rebuild announcement says the updated version emphasizes performance metrics, broader data sets, and a more intuitive interface.

    These are product descriptions from Profound rather than independent evaluations, and the supplied articles do not define the underlying methodology, coverage, weighting, or validation process. That limits the conclusions that can responsibly be drawn from them. They establish the intended role of the Index, but they do not provide enough evidence to treat any leaderboard position as a complete measure of market impact.

    A comparative index can nevertheless answer an important question: how does a brand’s observed AI-search presence compare with that of others under a consistent measurement approach? That view can help identify relative strength, weakness, or movement. It cannot, on its own, explain why the result occurred, whether the AI response represented the brand correctly, or whether the exposure affected customer behavior.

    The distinction matters because competitive visibility and business value are separate dimensions. A brand may appear frequently but in weak contexts, or appear less often while being strongly associated with profitable needs. Leaderboards are therefore most useful as discovery and benchmarking instruments, not as substitutes for diagnosis or outcome measurement.

    A measurement architecture for AI visibility

    An isometric measurement hub connects question signals, AI nodes, brand objects, customer outcomes, paid-media tiles, and organic-content tiles.

    The sources do not supply a complete measurement standard, but their combined perspectives support a practical architecture. It separates what an AI system displays from the inputs that may shape that display and the outcomes that follow. This is an analytical framework, not a description of metrics confirmed by the source articles.

    Observe presence and representation

    The first layer asks whether the brand appears for relevant questions and how it is portrayed. Useful observations include presence, prominence, citations or linked sources when available, the products or capabilities associated with the brand, and factual consistency. Competitor comparisons belong here, which is where a leaderboard or visibility index can contribute.

    Accuracy deserves its own treatment rather than being buried inside a visibility score. Search Engine Land warns that when an AI system lacks a sufficiently developed understanding of a brand, it may fill gaps with assumptions that do not match the intended narrative. More exposure is not automatically better if the resulting description is incomplete or misleading.

    Track the inputs that may explain change

    The second layer records controllable inputs: site content, product information, brand language, campaign coverage, and the audience-and-intent combinations being tested. Changes to these inputs should be logged alongside visibility observations. Without that record, a rising or falling benchmark remains descriptive rather than diagnostic.

    Paid activity is especially useful as a source of learning in the Search Engine Land account. The article proposes using campaign results to identify audience, intent, and profit combinations, then developing organic content around the combinations that perform well. That is a feedback loop, not proof that ad spending directly causes organic AI visibility.

    Connect exposure to outcomes cautiously

    The final layer connects AI-search observations with business evidence such as qualified visits, branded demand, leads, sales, or assisted journeys, depending on the organization’s goals and available data. Attribution will often be incomplete because an AI answer can influence a decision without producing an immediately identifiable click.

    For that reason, a sound scorecard should keep visibility, representation quality, and commercial outcomes distinct. Examining them together can expose relationships; collapsing them into one number can conceal whether progress came from broader exposure, better brand accuracy, or stronger conversion performance.

    Build a shared paid-organic operating loop

    Measurement becomes actionable when paid media, organic search, content, and brand teams use a common review cycle. The shared unit of analysis should be the audience need or intent rather than the channel. Teams can compare what users seek, what the brand publishes, how AI systems represent it, where paid campaigns succeed, and which outcomes follow.

    Governance is as important as tooling. A leaderboard owner can monitor relative visibility, a content or brand owner can assess representation, paid specialists can contribute campaign learning, and analytics teams can evaluate downstream behavior. Each perspective answers a different question, reducing the temptation to make a single platform metric carry more meaning than it supports.

    Key takeaways

    • Measure AI visibility as a combination of presence, accurate representation, competitive position, and business outcomes.
    • Use comparative indexes to find patterns and gaps, while checking their methodology before treating scores as authoritative.
    • Organize paid and organic analysis around shared audiences and intents, not separate channel reporting alone.
    • Treat paid campaign findings as evidence for content prioritization, while avoiding unsupported claims of direct causation.
    • Keep a record of content, brand, and campaign changes so movement in AI visibility can be investigated rather than merely reported.

    As AI-mediated discovery expands, the durable advantage will come from disciplined observation rather than any single score. Organizations that connect competitive benchmarks with representation checks and outcome evidence will be better equipped to adapt without confusing visibility with value.

    References

  • From Search Intent to Citation Share: Measuring AI Visibility

    From Search Intent to Citation Share: Measuring AI Visibility

    AI search visibility is becoming easier to observe, but measurement alone does not explain what content should change. Bing’s emerging reporting describes where a site appears across intents, topics and citations; the next-question intent framework examines whether its pages contain enough detail to support the comparisons and decisions behind those appearances.

    Used together, these perspectives create a practical loop: identify the contexts in which a site is being cited, inspect whether the underlying content supports the user’s full decision path, and then monitor how citation visibility changes.

    Two layers of intent explain different parts of visibility

    The Bing reporting source says the preview of its enhanced AI performance report classifies grounding queries by intent, including Informational, Commercial and Navigational categories. This is a reporting layer: it helps publishers understand the broad purpose associated with the queries for which their content surfaces.

    Next-question intent is an editorial layer. The separate analysis defines it as the information a person will need after the opening query to compare options, establish trust or make a decision. A page can therefore match an initial commercial query while still failing to answer the more specific questions that determine which option is suitable.

    The distinction matters because the two concepts should not be treated as competing taxonomies. Reported intent describes an observed visibility context. Next-question intent helps diagnose whether a page has enough substance to remain useful as that context becomes more specific.

    Key takeaways

    • Bing’s reported intent and topic views organize AI visibility by user purpose and thematic context rather than isolated queries alone.
    • Citation Share and Compare provide directional evidence about visibility, but they are not rankings, quality scores or proof of business impact.
    • Next-question intent connects reporting to content decisions by identifying the follow-up information users need to trust, compare and choose.
    • The strongest workflow reads intent, topic and citation signals together, then validates the relevant pages for specificity, evidence and decision support.

    How Bing’s reporting dimensions fit together

    An isometric website tile connects to groups of intent gateways, topic spheres, and citation markers.

    According to the Bing reporting article, the new enhancements are being introduced globally as a preview. The source says Bing had launched its underlying AI performance report in February and that a similar Google Search Console feature arrived in June. Those dates and the characterization of Google’s release come from the source and are not independently verified here.

    Reporting dimensionWhat the source says it showsUseful question for publishers
    IntentsGrounding queries classified into broad purposes such as Informational, Commercial and NavigationalIn what kinds of user situations is the site appearing?
    TopicsRelated queries grouped into thematic clustersWhich broader subjects are producing visibility?
    Citation ShareThe site’s percentage of citation visibility relative to other sourcesIs the site’s presence expanding or contracting within the measured set?
    ComparePrevious data overlaid on current reportingHow has citation activity changed between the displayed periods?

    These dimensions become more informative when read as a sequence. An intent indicates the general task, a topic identifies the subject area, Citation Share supplies a relative visibility signal, and Compare adds a time dimension. No individual metric provides the whole explanation.

    The source illustrates topic clustering with queries about solar panels and solar energy efficiency being grouped under a broader Solar Energy theme. It also cautions that labels may remain broad for niche domains during the preview. Topic names should therefore be treated as navigational aids for analysis, not as exact descriptions of every underlying query.

    Next-question intent turns observations into content diagnosis

    A report might reveal visibility in commercial, comparison-oriented experiences, but it cannot by itself determine whether a page answers the questions that shape a purchase. The next-question analysis uses a search for the best customer relationship management software for a small business to make this problem concrete. The opening request does not settle which product fits a two-person team, integrates with QuickBooks, works without a formal sales department or suits a local service company.

    Those follow-ups expose the difference between category relevance and decision utility. A page can accurately describe several products yet give an AI system little usable material for distinguishing who each product serves, when it is appropriate, how it differs from alternatives or what supports its claims.

    The analysis applies the same test to broad brand language. Claims such as customized strategies, family safety or suitability for small businesses remain underspecified unless the page explains how the offer is customized, which family members are covered, or which kinds of small businesses are meant. This is not a call to make pages longer by default. It is a call to replace ambiguity with relevant conditions, distinctions and evidence.

    For an informational intent, the next question may concern method, limitations or applicability. For a commercial intent, it may concern trade-offs, compatibility or fit. For a navigational intent, it may concern the exact destination or action available there. These examples are an analytical extension of the source framework rather than categories reported by Bing.

    A reporting-to-content workflow for AI visibility

    A circular sequence links citation observation, branching questions, expanded content blocks, and ongoing monitoring.

    Start with the intersection of intent and topic rather than a sitewide citation total. A change within a particular context is more actionable than an aggregate movement because it narrows the pages and user needs that deserve investigation. Citation Share can then indicate whether the site’s relative presence in that measured environment is moving, while Compare provides the period-over-period view described by the Bing source.

    Next, inspect the pages associated with that context as decision resources. The relevant test is whether they explain what the offering or subject is, whom it applies to, when it is useful, how alternatives differ and what evidence supports consequential claims. The next-question source argues that this substantive layer gives AI systems material they can synthesize, compare and use in recommendations.

    Content changes should address identifiable gaps rather than chase a metric mechanically. If a page appears around a comparison topic but lacks selection criteria, the useful revision is to clarify fit and trade-offs. If a niche topic label is broad, analysis should begin with the underlying pages and their actual subject matter instead of assuming that the dashboard label precisely captures demand.

    Finally, monitor the same intent-topic context over time. The Bing source notes that citation activity can be affected by AI model updates, changes in user demand and other factors. A rise or fall after an edit is therefore a signal for further investigation, not automatic evidence that the edit caused the movement.

    What current visibility reporting cannot establish

    Citation visibility is not equivalent to a conventional ranking. The Bing article explicitly describes Citation Share as directional and says it does not provide a ranking or quality score. A citation also does not, on its own, show whether the user clicked, converted, trusted the source or ultimately selected the brand.

    The source further says click and click-through rate data were still awaited. Without those measures, the reported tools are best suited to visibility diagnosis and trend monitoring. They should not be presented as a complete attribution system or as proof of commercial performance.

    Next-question intent has a boundary as well: it is a framework for improving content utility, not a guaranteed formula for earning citations. Its value is in making pages more explicit and decision-ready while reporting supplies evidence about where visibility exists and how it changes.

    As AI reporting develops, the durable advantage will come from connecting clearer measurements to better editorial questions. Publishers that preserve the distinction between an observed citation, an inferred cause and a verified outcome will be better positioned to improve content without overstating what the dashboards prove.

    References

  • What Google Content Visibility Signals Really Tell Publishers

    What Google Content Visibility Signals Really Tell Publishers

    Google visibility is often discussed as if it could be improved through a single tactical change: choose a more successful headline pattern, add a machine-readable file, or imitate whatever appears to perform best across a large dataset. The source reporting points to a more demanding conclusion.

    A study of Google Discover headlines shows how an apparent format advantage can be driven by publisher and audience differences, while Google’s reported guidance on llms.txt says the file has no effect on Search rankings. Together, these accounts offer a practical way to distinguish an observable characteristic from a credible visibility lever.

    Visibility is not one outcome or one mechanism

    The two source articles address different Google environments. The Discover analysis concerns how often editorial articles appeared across the 1492.vision fleet. Its metric was hits per article, which the source described as a proxy for visibility rather than a count of Discover clicks. The llms.txt article, by contrast, concerns whether a site-level file affects visibility in Google Search.

    That distinction matters because a feature associated with frequent appearances on one surface is not automatically a ranking factor, a cause of traffic, or a general rule for Google visibility. A Discover headline can be correlated with exposure without causing it. A file can help another service understand a site while remaining irrelevant to Google Search. The surface, measured outcome, and proposed mechanism must therefore be identified before a result becomes actionable.

    Headline format looks powerful until publisher context is added

    Two contrasting publisher environments show different content-card styles, audience sizes, and distribution conditions around a central magnifying lens.

    The Discover report described an analysis of 1,674,518 English articles and 1,690,295 French articles from the 1492.vision corpus. When publishers were pooled, quote-led headlines produced 37% more hits per article than statements in English and 48% more in French. Questions also exceeded statements in the aggregate, by 7% in English and 16% in French.

    Those figures appear to support a simple editorial prescription. Yet the report argued that the aggregate comparison mixed together publishers with different audiences, subject matter, editorial styles, and patterns of Discover exposure. Celebrity publications, regional news organizations, and outlets focused on trending topics were among the types said to use quotations more often. Their underlying visibility could therefore make the quotation format look more effective than it was.

    The source identified this as an example of Simpson’s paradox: a relationship visible in pooled data can weaken, disappear, or reverse after the data is separated into meaningful groups. In this case, the relevant test is not simply whether all quote headlines outperform all statements. It is whether the formats perform differently within comparable publishers and contexts, with each publisher serving as its own baseline.

    This does not make headline construction irrelevant. It changes the claim that the evidence can support. The reported aggregate results describe where visibility occurred across a mixed population; on their own, they do not establish that converting a statement into a quotation will create the same lift for an individual publisher.

    Google’s llms.txt position removes a different false lever

    The second source reported that Google updated its AI Search optimization guidance to say that llms.txt files do not affect Search rankings. According to that account, Google Search does not use the files, and publishers do not need to create new AI-oriented text or Markdown files to qualify for inclusion in Search experiences involving generative AI.

    The reported guidance includes an important qualification: Google may still discover, crawl, and index various file types. That general ability does not mean llms.txt receives special ranking treatment. The source also noted that a site may maintain the file for other services without improving or damaging its Google Search visibility.

    This is a more direct finding than the Discover correlation. The headline analysis asks whether an apparent advantage survives contextual controls. The llms.txt guidance says the proposed mechanism is not used for the claimed Google Search benefit. One tactic requires better causal analysis; the other has been explicitly ruled out as a Google ranking aid in the source’s account.

    A stronger test for proposed visibility signals

    Glowing signal tokens move through a sequence of evidence checkpoints, with weaker signals diverted and stronger signals reaching an illuminated content card.

    The synthesis suggests that publishers should evaluate any claimed signal along three dimensions. First, the claimed outcome should be precise: ranking position, impressions, Discover appearances, clicks, or another measure. Second, comparisons should account for publisher, audience, topic, language, and surface whenever those factors could influence both the tactic and the outcome. Third, the proposed mechanism should be checked against Google’s stated use of the feature when relevant guidance exists.

    For headline decisions, the most informative evidence would come from comparisons within the same publication and from controlled editorial tests that keep topic and distribution conditions as comparable as possible. Hits per article can reveal exposure patterns, but it should not be presented as click performance or as proof that punctuation and syntax independently caused the result.

    For machine-readable files, the decision can be separated by beneficiary. An llms.txt file may be maintained for a non-Google service that uses it, but the reported Google guidance provides no basis for treating its creation as a Search ranking project. This prevents an implementation task from being justified with an unsupported visibility promise.

    Key takeaways

    • Google visibility claims must name the surface and metric; Discover hits, clicks, and Search rankings are not interchangeable outcomes.
    • The reported quote-headline advantage appeared in pooled English and French data, but publisher and audience differences made a simple format-based explanation unreliable.
    • Within-publisher comparisons are more useful than global averages when editorial conventions and baseline visibility vary across outlets.
    • According to the llms.txt source, Google Search does not use the file as a ranking aid, although sites may keep it for other services.
    • An observable pattern becomes actionable only after plausible confounders and the proposed mechanism have been examined.

    As new visibility tactics emerge, the durable editorial advantage will come from asking what was measured, what else could explain it, and whether the platform recognizes the proposed mechanism. That discipline leaves room for experimentation while keeping correlation, platform guidance, and causal claims in their proper roles.

    References

  • AI Search Visibility: From Retrieval to Recommendation and Action

    AI Search Visibility: From Retrieval to Recommendation and Action

    AI search visibility is no longer adequately described by rankings or clicks alone. A brand may be discovered as a source, cited in an answer, recommended for a particular need or selected by an agent that completes a task – and each outcome requires a different kind of optimization.

    Read together, the source articles suggest a practical model for this environment: make the brand retrievable, unambiguous, independently credible, suitable for a defined audience and technically ready for action. This model connects traditional SEO, generative engine optimization and the emerging discipline of agentic search optimization without treating them as interchangeable.

    AI visibility is a chain, not a single ranking

    Traditional search usually exposes a list of pages and leaves most of the evaluation to the user. AI systems can compress several parts of that journey into one response. They may retrieve information from multiple sources, decide which evidence deserves a citation, compare possible providers and recommend an option that appears to fit the user’s circumstances.

    The CrushPress.AI article on retrieval versus citation makes an important distinction: being available to an AI system does not guarantee that the content will be cited. Its argument is that citation-worthy content must combine familiar technical SEO foundations with a useful experience, clear audience relevance and credible signals beyond the brand’s own website.

    The travel-focused source extends this distinction from citations to recommendations. It describes AI-assisted travel planning as a conversational process in which people ask for options matching constraints such as location, budget, atmosphere or family needs. The desired output is often a recommendation rather than a directory of links. The source framed around trust and brand visibility, meanwhile, reinforces the broader issue connecting these stages: an AI system needs sufficient confidence in the brand and its claims.

    The agentic-search article adds another stage. It distinguishes generative engine optimization, where a person still acts on an AI recommendation, from agentic search optimization, where software may evaluate options and execute the task. Its reported framework divides that process into retrieval, evaluation and action.

    Visibility stageQuestion the system must answerPrimary optimization needUseful measurement
    RetrievalCan the brand or content be found?Crawlable content, clear structure and relevant external mentionsPresence across a controlled set of prompts
    CitationIs this source useful and credible enough to support the answer?Specific evidence, clear explanations and corroborationCitation frequency and accuracy
    RecommendationIs the offering a strong fit for this user’s needs?Explicit positioning, suitability criteria and reliable attributesRecommendation share and represented attributes
    ActionCan the requested task be completed?Machine-readable information and a usable transaction pathCompletion, abandonment and assisted conversion

    This chain explains why a visibility strategy focused only on ranking can underperform. Retrieval is necessary, but it does not by itself produce a citation, recommendation or transaction.

    Resolve the brand, verify its claims and communicate fit

    A sharply defined faceted object is illuminated by connections from several independent evidence sources while similar objects remain blurred in the background.

    AI systems synthesize information from an ecosystem rather than treating a company’s website as the sole authority. Both the retrieval-versus-citation article and the travel-brand report emphasize the importance of consistent positioning across owned pages and third-party platforms. Read alongside the trust-focused source, their shared implication is that brand visibility depends partly on reducing uncertainty.

    A practical entity audit should answer several questions:

    • Is the brand’s primary category stated consistently?
    • Are its target customers and strongest use cases explicit?
    • Do the website and major external profiles agree on important facts?
    • Can important product, service or location attributes be found in structured, accessible content?
    • Do reviews, editorial mentions or other independent sources substantiate the positioning?
    • Are outdated descriptions or conflicting details weakening confidence?

    The travel article illustrates this with properties that serve different needs. A family-oriented hotel should consistently surface family suites, activities and relevant guest feedback, while a business hotel should make workspaces, connectivity, meeting facilities and location context clear. The wider lesson is not limited to travel: a brand should identify the situations in which it is a particularly good option and ensure those attributes recur accurately across the sources an AI system may consult.

    Structured data can help machines interpret categories, locations, amenities and other defined attributes. Server-side rendering, understandable page structure and sound technical SEO also remain relevant, according to the retrieval-versus-citation source. These measures improve accessibility and interpretation, but none should be presented as a guarantee of citation. Technical clarity supplies evidence; it does not manufacture authority.

    Independent corroboration therefore matters. The sources recommend relevant editorial coverage, digital public relations, reviews, guides and accurate platform listings. The objective is not to accumulate undifferentiated mentions. It is to have credible sources associate the brand with the same meaningful qualities that appear on its own site.

    Fit information deserves equal attention. The agentic-search article recommends suitability pages that state who an offering serves and who it does not. Boundaries can make a claim more credible and give an evaluating system information it can use. Useful pages might organize the decision around audience, use case, requirements, limitations, alternatives and proof rather than repeating broad promotional language.

    The evidence reported for agent behavior comes from one source and should be treated accordingly. The CrushPress.AI summary of a First Page Sage study says the researchers issued 2,417 agentic commands between March 4 and June 10, 2026. It reports that agents selected a platform’s top-ranked recommendation in 44.6% of commands but chose an option ranked fourth or lower in 38.2%. It also reports that pre-existing brand beliefs influenced 81.6% of evaluations. These findings have not been independently verified in the supplied material, but they support a useful strategic hypothesis: inclusion in the candidate set and perceived suitability are separate competitive problems.

    Prepare the conversion path for agent-led action

    A robotic hand moves a glowing token through connected digital gates toward an open package and a green completion light.

    Optimization changes again when software is expected to do more than make a recommendation. An agent may need to check requirements, compare prices, confirm availability, submit information or complete a purchase. Content that is persuasive to a person can still fail if the underlying process cannot be interpreted or operated reliably.

    The agentic-search source reports a large difference in its study between machine-actionable and non-actionable conversion pages. According to the article, agents completed 78.3% of attempts when the page was machine-actionable, compared with 9.6% when it was not; the source says agents often substituted a transactable competitor. Because this result comes from the study as described by a single publication, it should be treated as directional evidence rather than a universal benchmark.

    Organizations preparing for this stage can examine the complete task path:

    <!– wp:list {