Tag: AI Search

  • From AI Discovery to Agentic Commerce: A Brand Playbook

    From AI Discovery to Agentic Commerce: A Brand Playbook

    AI-mediated discovery and agentic commerce are becoming parts of the same customer journey. An assistant may identify a need, retrieve supporting content, compare brands and eventually initiate a transaction, reducing the number of moments in which a conventional search result or website visit can influence the decision.

    The practical opportunity is broader than optimizing pages for AI citations. Brands need to make their information accessible, understandable, credible and actionable across the systems that increasingly sit between them and their customers.

    Discovery and commerce are converging into one decision layer

    The two source articles illustrate different points on this emerging continuum. The Ask YouTube report describes a conversational discovery experience in which users can ask natural-language questions and receive responses incorporating text, clips, long-form videos, Shorts and follow-up prompts. The agentic-commerce article looks further down the journey, describing AI systems that evaluate brands, recommend options and potentially complete actions for users.

    Together, these reports suggest that AI discovery is not merely another results-page format. It can act as a decision layer that converts a broad request into a smaller set of sources, products or brands. The commercial consequence is significant: the agentic-commerce source reports, citing Adobe, that AI-referred traffic to U.S. retail websites grew 4,700% year over year through mid-2025. It also reports, citing Salesforce, that AI and autonomous agents influenced one in five online orders globally during Cyber Week, representing an estimated $67 billion in sales. These figures are source-reported indicators rather than independently verified findings here, but they show why visibility inside AI-generated journeys is attracting attention.

    This shift compresses the traditional funnel. Discovery, evaluation and selection may occur inside the same interface, while the brand’s own site functions increasingly as an information and transaction system behind that interface.

    Machine eligibility comes before brand persuasion
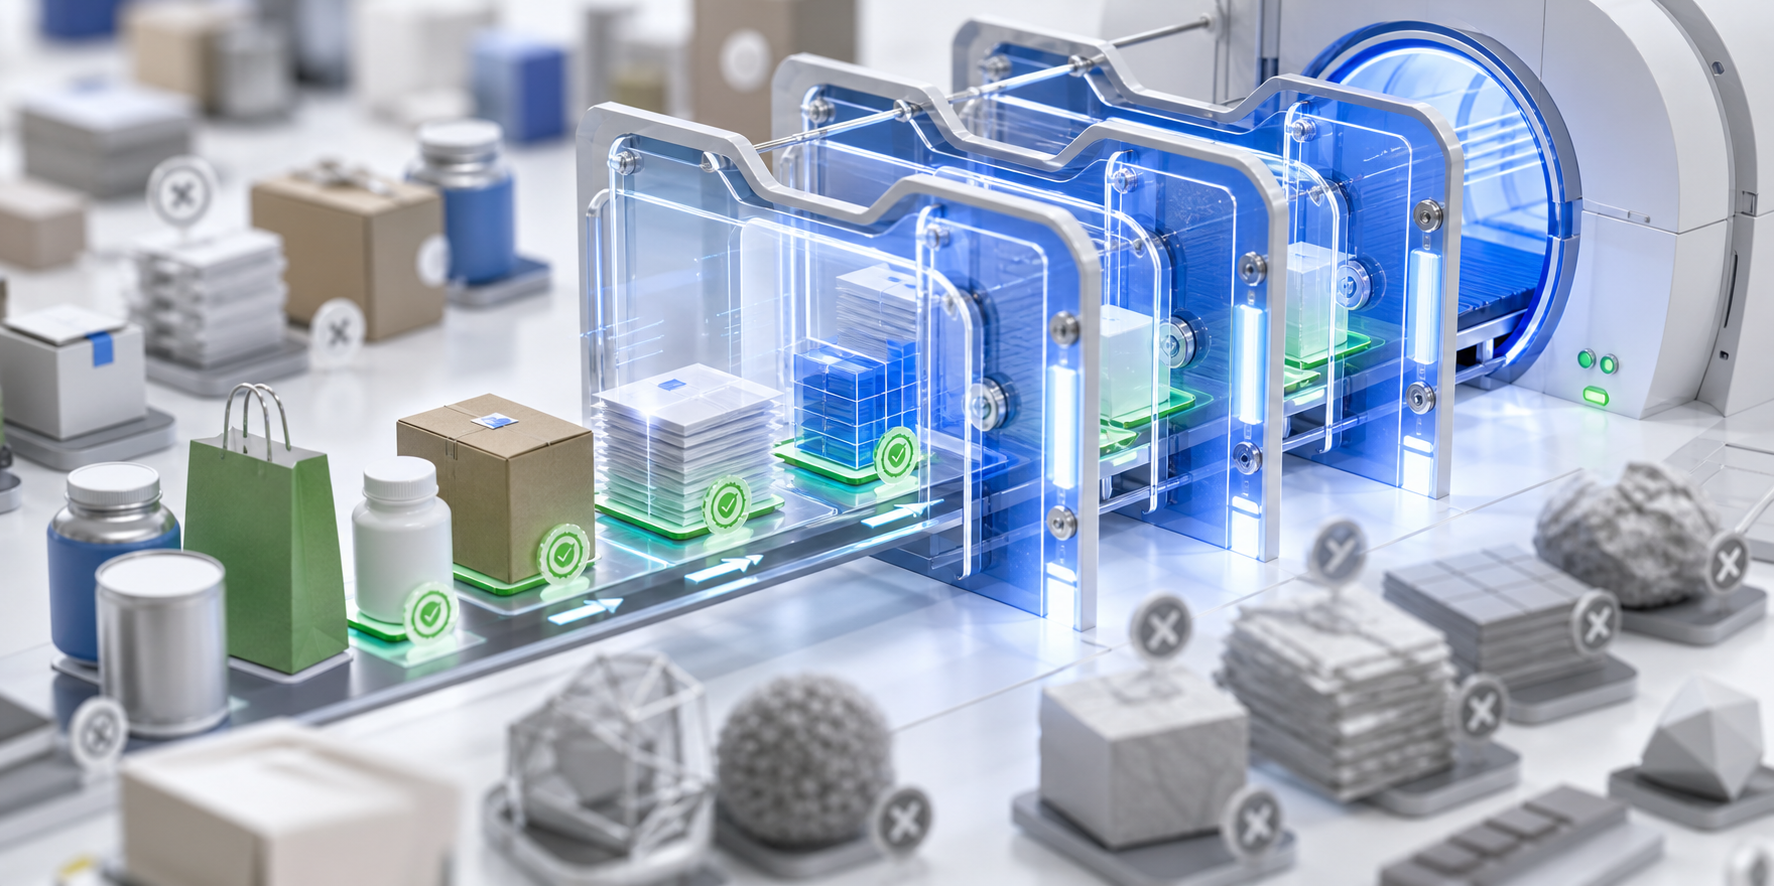
    Structured product objects pass through illuminated machine-readable gates while incomplete objects remain outside.

    A brand cannot influence an AI-mediated decision if its information is difficult to access or interpret. The agentic-commerce article therefore begins with technical foundations: appropriate crawler access, XML sitemaps, robots.txt configuration, canonical tags, crawl-error management, Core Web Vitals and server-rendered content. It also recommends reducing unnecessary HTML and offering concise machine-oriented resources, such as an llms.txt file or Markdown versions of important content. These measures should be treated as accessibility aids, not guarantees of inclusion or recommendation.

    Semantic clarity is the next requirement. Structured data, consistent entity names, semantic HTML and connected identifiers can help a system determine what an organization offers and how its products, locations and content relate. Clear page sections matter because an AI response may retrieve a passage rather than rank and present an entire page.

    The YouTube report provides the video equivalent of this principle. It says creators are advised to use descriptive titles, clear chapters and unique, high-quality material so YouTube can better match video segments to viewer questions. Videos included in Ask YouTube responses retain their titles and channel names, while views from included videos, Shorts and previews count toward total view metrics and YouTube Partner Program eligibility, according to the source.

    The common lesson is format-independent: each useful section, chapter or clip should communicate a recognizable subject and answer a specific question without depending on excessive surrounding context. Machine-readable structure supports retrieval; substantive expertise gives the retrieved material a reason to be selected.

    Retrieval is visibility, but trust determines the shortlist

    Being surfaced by an AI system is not the same as being recommended. The agentic-commerce source frames trust as computational: systems may compare claims against reviews, listings, location information, prices, availability and other external evidence. Conflicting data can reduce confidence even when an individual page is technically well optimized.

    This makes content optimization inseparable from information governance. Product names, specifications, prices, availability and location details should remain aligned wherever they appear. Original research, demonstrated experience and identifiable expert authorship can strengthen the evidence available to a system, while trusted external mentions can help ground brand claims.

    Human preference still matters within this machine-filtered environment. An assistant may efficiently compare explicit attributes, but consumers may retain direct control over purchases connected to taste, identity or loyalty. Effective positioning therefore has two audiences: machines need unambiguous facts and supporting evidence, while people need a meaningful reason to prefer the brand after it reaches the shortlist.

    Transaction readiness turns content infrastructure into commerce infrastructure
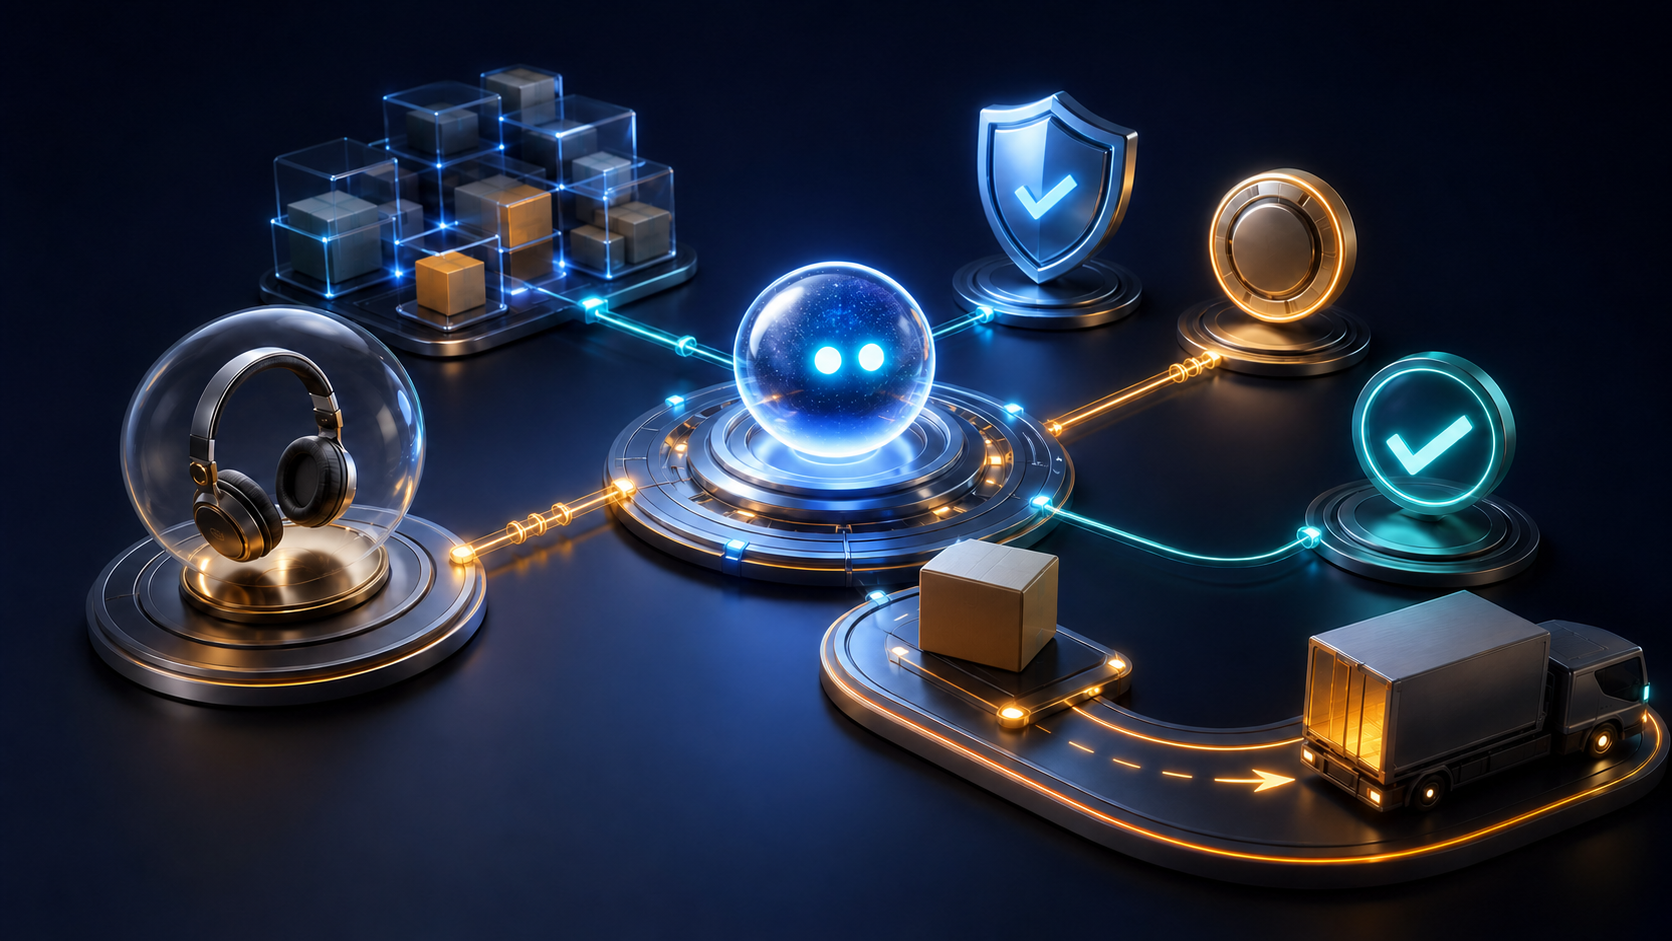
    A glowing digital assistant coordinates a product, inventory, payment, permission, packaging, and delivery elements around a secure hub.

    Agentic commerce extends optimization beyond being cited. If an assistant can retrieve current inventory, verify a price, submit information or initiate payment, the underlying website and data services become operational components of the customer experience rather than only destinations for human browsing.

    The agentic-commerce article describes several technologies associated with this transition. It presents NLWeb as a way to make website content conversational and machine-readable, and the Model Context Protocol as a standardized means for agents to interact with data and functions. It also names Google’s Universal Commerce Protocol, OpenAI and Stripe’s Agentic Commerce Protocol, and the Agent Payments Protocol as mechanisms intended to support bookings, inventory visibility or payments. These descriptions reflect the source’s account of a developing ecosystem; they should not be interpreted as evidence that every platform, merchant or transaction already supports the full workflow.

    The operational requirement is more durable than any individual protocol: agents need dependable access to authoritative, current and permission-appropriate information. A merchant can prepare by treating product data, inventory, pricing, policies and transactional functions as governed services. Security, consent, error handling and human escalation also become essential when software can act rather than merely summarize.

    Key takeaways

    • Manage the whole AI-mediated journey. Discovery, retrieval, recommendation and transaction readiness are connected capabilities, not isolated optimization projects.
    • Make every important asset interpretable. Accessible pages, structured entities, focused passages, descriptive video titles and clear chapters help systems match material to user questions.
    • Audit consistency beyond the website. Reviews, listings, prices, availability and brand claims collectively affect the confidence an AI system can place in a recommendation.
    • Measure stages separately. Track whether the brand is discovered, cited, recommended and ultimately selected so a retrieval problem is not mistaken for a trust or transaction problem.
    • Prepare governed actions. Live commerce data and transactional functions require accuracy, permissions, security controls and recovery paths when an automated action cannot be completed safely.

    Ask YouTube shows conversational discovery reaching a broader audience: the source says access expanded on July 6 to signed-in U.S. desktop viewers aged 13 and older using English-language searches, while signed-out viewers and supervised accounts remained excluded. The agentic-commerce report points toward the next phase, in which assistants may move from assembling answers to carrying out decisions. Brands that connect content quality, entity clarity, evidence consistency and transaction governance will be better prepared as those two phases converge.
    References

  • Why ChatGPT Search Citations Change Across Hidden Pipelines

    Why ChatGPT Search Citations Change Across Hidden Pipelines

    A ChatGPT citation is the visible end of a much larger selection process. Before a source can appear beside an answer, the system may decide whether to search, choose a retrieval pipeline, rewrite or expand the query, fetch candidate pages and select which evidence deserves a citation.

    That layered process explains why repeated prompts can produce different source lists without any underlying page changing. It also changes how publishers should interpret AI visibility: one observed answer is a sample of a variable system, not a definitive ranking.

    A citation is the output of several hidden decisions

    The source cards visible to users do not disclose the full route that produced them. According to the CrushPress.AI report, research by Chris Green and Suganthan Mohanadasan identified internal source-selection labels including Labrador, Bright, Oxylabs and SERP. These labels appeared behind the answer rather than in its public citations.

    This creates several distinct opportunities for a page to be excluded. ChatGPT may classify the prompt as not requiring web search. If it does search, the selected retrieval source may not surface the page. The system may then fetch the page but decline to cite it, or it may use the page for a narrow factual claim while relying on another source for the broader answer.

    The practical distinction is important. A missing citation does not, by itself, show that a page lacks authority or relevance. It may reflect an earlier routing, retrieval or parsing decision that is invisible in the final response.

    Repeated prompts expose pipeline-level variability

    Three identical inputs move through different branching retrieval paths and produce different sets of source cards.

    Green examined 1,000 prompts, running each as many as 10 times, and recorded 9,946 completed searches, as reported by CrushPress.AI. Labrador was the primary search source in 88.1% of those runs, followed by Bright at 9.9%, Oxylabs at 1.7% and SERP at 0.3%.

    Most prompts remained on one primary source, but 11.6% switched sources across repeated runs. For prompts that switched, reported URL overlap declined from 0.273 to 0.149, while domain overlap declined from 0.265 to 0.155. Green characterized those changes as approximately 45% less URL overlap and 42% less domain overlap.

    Those overlap figures measure consistency between result sets; they should not be read as a page’s probability of earning a citation. Their significance is structural: a change in retrieval route can materially change the pool of domains and URLs available to support an answer.

    Mohanadasan observed a different distribution while examining two days of raw network traffic from one logged-in Pro account. His sample contained about 1,240 source records from a few dozen searches. Although he found the same four result-source values, Bright had a larger role in his sample, particularly for commercial, shopping, finance, weather and local queries. SERP appeared mainly with news-oriented results, while Labrador included established publishers and reference sites; Bright and Oxylabs were associated with their namesake data providers.

    The differing distributions are not necessarily contradictory. The studies used different prompts, observation methods, sample sizes and account contexts. Together, as presented in the source article, they suggest that no single observed pipeline mix should be assumed to represent every query class or user session.

    Search can be skipped, rewritten or expanded

    Pipeline selection matters only after the system decides to search. Mohanadasan reported that ChatGPT first classified some requests through a turn-use-case field. Some apparently current prompts were categorized as text tasks and did not trigger a web search. When that happens, no current page can be fetched or cited, regardless of how well it is optimized.

    Queries that received more extensive reasoning could travel in the opposite direction. The reported traces showed branching searches that included site-specific probes, pricing checks and searches for competitors the user had not named. Consequently, a publisher may be competing for retrieval against results generated from several machine-created subqueries, not merely the exact wording entered by the user.

    This makes prompt-level visibility difficult to reduce to conventional rank tracking. The same surface question can lead to no search, a relatively direct search or a multi-step investigation. Each path creates a different candidate set before citation selection begins.

    Fetched, cited and mentioned are different outcomes

    Blank webpage cards are progressively narrowed from a large candidate pool to a few cards linked to a final answer.

    Mohanadasan separated source participation into three useful states: fetched, cited and mentioned. A fetched page enters the system’s working context. A cited page is displayed as support for a claim. A mentioned brand may appear in the prose without its own site serving as visible evidence.

    OutcomeWhat it indicatesWhat it does not establish
    FetchedThe page was retrieved for possible use.That users saw it or that it supported a final claim.
    CitedThe page was presented as evidence for part of the answer.That it was the only source consulted or the preferred source in every run.
    MentionedThe brand or entity appeared in the response.That its own website was retrieved or cited.

    The source article illustrates the distinction with a small commercial-query sample. Reddit and YouTube were both fetched frequently, but Reddit received citations while YouTube did not. Mohanadasan attributed the difference to accessible text: Reddit threads exposed usable copy, whereas YouTube search results often supplied metadata rather than full transcripts. Because the sample was limited, this should be treated as an observed pattern rather than a universal rule about either platform.

    Source roles also varied by claim type. Vendor pages supported first-party facts such as prices and specifications, while third-party pages were more likely to support comparative recommendations. In some cases, ChatGPT appeared to seek an official pricing page but use a third-party source when the official information was hidden behind JavaScript or otherwise difficult to parse.

    The broader implication is that citation eligibility depends on both relevance and usability. A page can contain the right information yet lose the visible citation if the information is inaccessible, ambiguous or less suitable for the particular claim than another source.

    A better framework for measuring ChatGPT visibility

    Because routing and search behavior can change between runs, citation monitoring should emphasize distributions rather than isolated answers. Repeated tests can show how often a domain appears, whether the cited URL changes, which claim types attract first-party or third-party support, and how volatile the results are. The studies reported here do not establish a universal number of repetitions, so testing depth should be documented instead of presented as a fixed standard.

    Measurement should also keep brand inclusion separate from source attribution. Citation share, mention share and fetched-page data answer different questions. Combining them into one visibility score can conceal whether a brand is absent from the answer, present without evidence from its own site, or retrieved but not shown to the user.

    Key takeaways

    • A citation is produced by a chain of classification, routing, retrieval and evidence-selection decisions.
    • Repeated prompts are necessary to reveal variability; a single response cannot represent a stable source position.
    • Search eligibility should be evaluated separately from citation performance because some prompts may not trigger web retrieval.
    • Fetched pages, visible citations and uncited brand mentions should be tracked as distinct outcomes.
    • Plain HTML, clearly labeled facts, accessible prices and specifications, and substantial text improve the chance that retrieved information can support a claim.
    • First-party pages and independent coverage serve different evidentiary roles, so visibility work should account for both.

    As AI search measurement matures, the most durable approach will be to record uncertainty rather than hide it. Publishers that make evidence easy to retrieve and interpret, while measuring performance across repeated runs and source types, will be better equipped to understand citation changes as the underlying pipelines evolve.

    References

  • How Brands Build Visibility and Authority in AI Search

    How Brands Build Visibility and Authority in AI Search

    AI search changes the branding problem from winning a position to earning a place in a synthesized answer. A brand can be known to an AI system yet remain absent from its recommendations, or it can be mentioned without receiving a link that sends measurable traffic.

    The two source articles point to a broader operating model: maintain the technical and editorial foundations that make content usable, while building a credible public record across the independent sources that influence how AI systems understand and select brands.

    Visibility now includes representation, not just rankings

    Traditional rankings still matter, but they no longer describe the entire opportunity. The article on AI search usage and citations reported that users clicked a conventional result 8% of the time when a Google AI summary appeared, compared with 15% when one did not, citing Pew Research. It also cited Similarweb figures indicating that traffic from AI experiences converted at 11.4%, versus 5.3% for organic search traffic. These figures were reported by the source rather than independently verified here, but together they illustrate why raw click volume is an incomplete measure of AI visibility.

    A synthesized answer can influence a decision before a user visits any website. That makes accurate representation a business outcome in its own right. The practical questions become whether the system associates the brand with the correct category, describes its positioning accurately, includes it in relevant comparisons, and presents it as a credible option.

    This does not make search rankings obsolete. The usage-and-citation article cited an Ahrefs study reporting that 76.1% of pages referenced by Google AI Overviews ranked among Google’s top 10 organic results. That relationship is specific to the reported study and should not be treated as a universal rule for every AI engine, but it supports a useful conclusion: conventional SEO remains part of AI visibility even when the final experience is no longer a conventional results page.

    Authority is assembled from an external consensus

    Independent editorial, research, review, directory, and community sources converging around one unbranded object.

    A brand’s website supplies essential facts, explanations, and evidence, but it is also an interested source. Both articles emphasize that AI systems can draw on a wider information environment that includes editorial coverage, reviews, forums, comparison pages, social platforms, and community discussions. Authority therefore depends partly on whether independent sources confirm the associations a brand promotes on its own channels.

    The article about building a brand AI search can trust reported that 93% of citations in its analysis of leading commercial sectors came from third-party sources, leaving 7% from owned channels. It also cited Ahrefs research linking appearances in AI Overviews most strongly with branded web mentions. These findings do not prove that any mention will improve visibility. They instead suggest that a coherent external footprint can be more influential than publishing additional self-promotional pages in isolation.

    Consistency is especially important because AI-generated answers can collapse a long evaluation process into a short response. If a company claims premium positioning while reviews, discounting patterns, and editorial commentary point elsewhere, the external record may weaken that claim. The strategic task is not to repeat identical wording everywhere, but to make sure owned content, earned coverage, expert commentary, and customer experience support compatible conclusions.

    That makes reputation management and AI SEO increasingly interdependent. Search teams need to know which associations they want to establish, while communications and customer-facing teams need to understand which public evidence supports or contradicts them. A visibility program cannot compensate indefinitely for a weak underlying experience or a disputed market position.

    Usage and citation require different evidence

    The usage-and-citation article offers a useful distinction. Usage occurs when an AI system draws on information to form an answer, whether or not it names or links to the underlying page. Citation occurs when the answer explicitly references a source, such as a webpage or profile. A brand can consequently influence an answer without receiving an attributable visit, and it can be named as an option without being cited as the source of the supporting information.

    This distinction changes both optimization and measurement. Content intended to earn citations needs to remain accessible, competitive in search, and sufficiently original to justify a reference. The source article reported that generic material repeating existing coverage was rarely cited by AI engines, based on Semrush findings. Original research, useful data, clear explanations, and defensible expert analysis give a system a more specific reason to cite the publisher.

    Brand usage, by contrast, may depend heavily on presence within sources the system consults but does not expose. The same article reported that Ahrefs found nearly equal average numbers of cited and uncited URLs involved in a ChatGPT response: 16.57 and 16.58, respectively. It added that Reddit accounted for 67.8% of the uncited URLs in that analysis, limiting how broadly the comparison should be interpreted. The useful lesson is methodological: citation reports reveal only the visible portion of the information environment.

    Measurement should therefore separate three outcomes: whether the brand appears, how it is characterized, and which sources are cited. Tracking only links can miss influential unlinked mentions; tracking only mentions can hide inaccurate positioning; and tracking only sentiment can overlook whether the brand is absent from commercially important prompts.

    An effective program combines monitoring, evidence, and reach

    People working across connected monitoring, evidence-building, and outreach zones in a circular operations space.

    AI visibility should be managed as a recurring research and reputation program rather than a one-time content campaign. The prompt set must reflect the different ways buyers describe needs, compare alternatives, ask for evidence, and narrow a shortlist. Because generated responses vary, the usage-and-citation article recommends collecting multiple responses and evaluating recurring patterns instead of treating one answer as definitive.

    Source analysis should then identify where the brand is already represented, where competitors repeatedly appear, and which domains or communities influence the answers. The goal is not indiscriminate placement. It is to contribute credible material to publications, comparison resources, and conversations that overlap with the intended audience and the relevant subject matter.

    The authority article highlights three evidence formats: inclusion in legitimate product roundups, data-backed research that others can reference, and expert thought leadership tied to identifiable people. It reported that 91% of AI citations found in an analysis of 4,000 pieces of U.S. and U.K. coverage driven for clients included expert insight. Because that analysis concerned coverage associated with the author’s organization, the result is best treated as directional evidence rather than an independent benchmark.

    Freshness also deserves attention. The authority article cited research, including work from Waseda University, associating AI brand visibility with content recency. Without assuming a universal causal rule, the finding supports an always-on approach: update useful owned resources, continue producing evidence worth referencing, and maintain credible participation in the external conversations that define the category.

    Key takeaways

    • Measure appearance, representation, and citation separately; each reveals a different part of AI visibility.
    • Preserve strong technical SEO and organic competitiveness because ranking pages can still supply AI citations.
    • Build a consistent public record across owned content, editorial coverage, reviews, comparisons, experts, and relevant communities.
    • Create original evidence that deserves attribution instead of relying on generic summaries or self-promotional claims.
    • Track a representative set of prompts repeatedly and use recurring patterns, not isolated answers, to guide decisions.
    • Avoid manufactured authority: fake experts, artificial mentions, and deceptive coverage can create reputational risk rather than durable trust.

    As AI answers absorb more of discovery and evaluation, the durable advantage will belong to brands whose claims can be verified beyond their own domains. The next phase of search strategy is therefore less about engineering a single appearance and more about maintaining a useful, consistent, and independently supported body of evidence.

    References

  • Goodie vs. Semrush: A Smarter AEO Platform Comparison

    Goodie vs. Semrush: A Smarter AEO Platform Comparison

    When I compare Goodie and Semrush for AI search visibility, I’m looking beyond traditional SEO dashboards. I want to understand how each platform supports answer engine optimization, from monitoring AI visibility to improving the signals that influence AI-generated answers.

    AEO analytics dashboard showing actions, visibility score, share of voice, brand mentions, sessions, conversions, and impressions metrics.
    A modern AEO performance dashboard brings AI search visibility, brand mentions, traffic attribution, and revenue signals into one measurement view.

    For me, the key difference comes down to focus. Goodie is built around AEO monitoring, optimization, agentic commerce, and revenue attribution, while Semrush brings the depth of a broader SEO and competitive research platform.

    Semrush SEO dashboard showing position tracking, site audit, on-page SEO ideas, backlink audit, keyword visibility and toxic backlinks.
    A Semrush project dashboard brings SEO health into one view, from keyword rankings and site audit trends to optimization ideas and backlink toxicity signals.

    In this comparison, I look at how both platforms help brands get discovered, cited, and recommended across AI search experiences, and how each one connects visibility to measurable business impact.


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot
  • AI Search Competition: Referral Traffic vs. Platform Reach

    AI Search Competition: Referral Traffic vs. Platform Reach

    AI search has no single, universal leaderboard. One source reports overwhelming ChatGPT dominance in measurable referrals from standalone AI platforms, while another argues that Meta’s reach could move search-like behavior into social feeds and conversations before an external click ever occurs.

    For marketers, the useful distinction is between platforms that currently deliver observable website visits and platforms that may control where discovery begins. Treating those as separate forms of competition leads to a more resilient acquisition and measurement strategy.

    Key takeaways

    • A referral study covering 6.77 million LLM-driven sessions attributed 92.4% of trackable standalone AI referral traffic to ChatGPT, making it the clearest near-term traffic priority.
    • That concentration also creates channel risk: the study reported a 50% monthly decline in total sessions during November 2025, driven largely by a sharp reduction in ChatGPT referrals.
    • Meta’s competitive case rests on distribution rather than demonstrated referral volume. Its AI is embedded across apps where social discovery, conversations and commercial intent already occur.
    • AI-search performance should therefore be evaluated across visibility, outbound referrals and post-click outcomes rather than through one market-share figure.

    Traffic and distribution produce different market leaders

    Glowing visitor orbs cross a bridge to a website while a much larger network of feed cards and conversation nodes spreads across the background.

    The ChatGPT traffic analysis measures a specific outcome: visits that arrive from standalone large-language-model platforms and can be identified as referrals. Within that boundary, the Previsible study cited by the article found that monthly LLM-driven sessions increased from 65,249 in November 2024 to 644,478 in May 2026. It assigned 92.4% of the full dataset’s trackable referral traffic to ChatGPT.

    That is compelling acquisition evidence, but it is not a complete measure of AI-assisted discovery. The referral article explicitly excluded AI experiences inside Google’s search results, including AI Overviews. Its author argued that Google’s embedded AI discovery probably produces more traffic than all standalone platforms combined, although the supplied material did not provide comparable data to verify that assessment.

    The Meta analysis examines a different part of the journey. Its central claim is that AI can answer questions inside Instagram, WhatsApp, Facebook or Messenger at the moment interest emerges. A product discovered in a feed, a destination discussed in a group chat or a local recommendation encountered in a community can prompt a question without the user deliberately opening a search engine or standalone chatbot.

    These accounts are complementary rather than contradictory. ChatGPT can lead the measurable referral market while an embedded platform influences a much larger volume of decisions that generate no attributable visit. The competitive answer changes with the question: who sends traffic, who shapes consideration, or who owns the environment in which intent first appears?

    ChatGPT’s referral lead brings both scale and volatility

    The referral study presents a highly concentrated market. It reported that ChatGPT traffic grew 12.8 times over 19 months. Beneath that leader, the challengers followed sharply different paths: Claude rose from 133 sessions in November 2024 to 8,528 in May 2026 and moved ahead of Perplexity in March 2026, while Perplexity was reported to be 61% below its March 2025 peak. Copilot fell 96% from its August 2025 high, reaching 339 sessions in the reported May 2026 data.

    Those figures support prioritizing ChatGPT for referral acquisition, but they also show why allocation should not be based on share alone. The study recorded a one-month decline in total LLM sessions of 50% in November 2025. It attributed most of the movement to ChatGPT referrals falling from 448,412 to 213,345 before total sessions recovered to 442,609 in December. The article interpreted the disruption as the likely result of a model or product change, not a broad decline across every platform.

    For site operators, this resembles dependency on any dominant intermediary: scale and fragility arrive together. A change in citation selection, answer design or linking behavior can affect traffic even when the underlying content has not changed. Monthly referral totals therefore need platform-level and landing-page context before they can be treated as evidence of durable demand.

    Smaller platforms may still matter where their behavior aligns with a site’s content. The referral analysis characterized ChatGPT and Gemini as more likely to demonstrate domain-level trust while directing users toward search-like destinations. It described Claude and Perplexity as more inclined to select particular pages and long-form material. That reported difference gives editorial businesses a reason to monitor qualified visits from smaller platforms even when their aggregate volume remains modest.

    Meta could compete by absorbing the search journey

    The Meta article does not provide referral data comparable with the Previsible study. Instead, it builds its case around potential access to existing audiences. It reported that Mark Zuckerberg said Meta AI had reached one billion monthly active users by May 2025. The same article cited 3.56 billion daily active people across Meta’s family of apps in March, as well as WhatsApp passing three billion monthly users in 2025 and Instagram reaching the same monthly-user threshold in September 2025.

    Those audience figures establish distribution, not search share or commercial effectiveness. They do, however, identify a structural advantage: Meta can introduce AI inside established communication and content habits. The article reported that Meta AI spans feeds, chats and search across Facebook, Instagram, WhatsApp and Messenger, with uses including recommendations, travel planning, shopping inspiration and study assistance.

    This model could make traditional referral measurement less representative. If an AI summarizes recommendations, compares choices or supports a purchase without sending the user to a publisher or brand site, it has participated in discovery while remaining largely invisible in referral analytics. The platform may then monetize that interaction through recommendations, subscriptions or advertising, possibilities the Meta article said the company was considering.

    Meta’s reach should consequently be treated as a competitive signal rather than proof that it has overtaken established search or chatbot products. The source makes a forward-looking argument based on distribution and product direction. It does not establish how often Meta AI is used for search-like questions, how frequently its answers lead to external sites or how those visits convert.

    A practical strategy separates discovery, visits and conversion

    Multiple streams of discovery signals pass through a website-like gateway and continue toward a smaller group of completed tokens.

    Measure the stages independently

    AI visibility, attributable traffic and business outcomes answer different questions. Visibility monitoring can show whether a brand or source appears in answers. Referral analytics can identify platforms and pages that send trackable visitors. On-site analytics can then show whether those visitors search, engage, enquire or buy. Keeping the stages separate prevents a high citation rate from being mistaken for traffic, or a large referral total from being mistaken for value.

    Platform and landing-page segmentation is especially important when one provider supplies most observable sessions. It can expose whether growth is broadly distributed or dependent on one answer engine, one destination template or one short-lived product behavior. It also makes room to evaluate Claude or another smaller source on visit quality rather than volume alone.

    Treat destination experiences as acquisition assets

    The referral study found that 28.8% of ChatGPT traffic reached internal search-results pages, with roughly one-quarter of AI-referred traffic doing so across industries. The article interpreted this pattern as domain trust combined with uncertainty about the best individual page. Whatever the mechanism, the reported behavior makes internal search part of the acquisition experience rather than merely a utility for existing visitors.

    Destination priorities also vary by business model. The study reported that product pages received 43% of ecommerce LLM traffic, course pages received 52% of education traffic, and About pages received 42.1% of health traffic. These patterns suggest that product data, course information, organizational credentials and other decision-critical details should be clear on the pages AI visitors actually reach. The same source recommended making prices machine-readable where possible because opaque pricing is difficult for an AI system to compare or summarize.

    Meanwhile, Meta’s embedded approach makes presence within social discovery environments relevant even when no website session follows. The immediate priority remains the channel producing measurable demand, but planning should also account for platforms that can shape a decision without appearing in conventional attribution. As AI interfaces evolve, the strongest strategy will be the one that can distinguish influence from traffic and traffic from genuine business value.

    References

  • How to Build and Measure an AI Search Visibility Strategy

    How to Build and Measure an AI Search Visibility Strategy

    AI search visibility cannot be managed as a conventional ranking contest. Brands must influence the information environment from which AI systems construct answers, then measure how often and how persuasively they appear across varied prompts and conversations.

    A useful strategy therefore connects two sides of the problem: the buyer questions that create demand and the owned, earned, community, and sponsored sources that shape an AI system’s response. The result is a measurement program designed for probabilistic visibility rather than a misleading imitation of keyword rank tracking.

    Replace rank tracking with a map of buyer conversations

    A strategist arranges blank prompt cards and colored connections into clusters representing different buyer conversations.

    Traditional search reporting assumes that a query produces a results page on which a domain occupies a reasonably observable position. The source on prompt-level measurement argues that this model does not transfer cleanly to AI assistants. Responses can vary with conversation history, location, personalization, model version, retrieval availability, follow-up questions, and timing. There is consequently no single, durable equivalent of a number-one ranking.

    The more defensible question is not whether a brand ranks, but how frequently it is included in commercially relevant conversations. That changes the unit of analysis from an isolated keyword to a buyer scenario. A scenario can begin with category discovery, progress through use-case evaluation and vendor comparison, and end with objections, alternatives, implementation concerns, or validation of a shortlist.

    The prompt-level source recommends organizing questions by intent and grouping related variations into clusters. A category cluster, for example, can reveal broad awareness, while industry and feature clusters show whether the brand remains visible as requirements become more specific. Cluster-level patterns are more informative than the result of one carefully worded prompt.

    Multi-turn testing is equally important. A company absent from an opening request may enter the answer after the buyer specifies an industry, integration, budget consideration, or operating constraint. Testing only the first response would miss that later influence and could make a relevant brand look invisible.

    Build a prompt library that balances consistency and realism

    A prompt library serves two purposes that need to remain distinct. Synthetic prompts provide a repeatable benchmark: the same scenarios can be tested over time, across models, or against competitors. Real customer questions provide ecological validity because actual buyers tend to supply context, combine constraints, and use less orderly language than generated test prompts.

    The prompt-level measurement source suggests drawing real questions from sales calls, customer interviews, support conversations, community discussions, internal and on-site search, and AI transcripts that customers voluntarily provide. These inputs can expose needs that keyword tools or generated variations fail to represent. Synthetic prompts should establish the controlled test set, while customer evidence should continuously correct and expand it.

    Each tracked scenario should carry enough context to support useful segmentation: buying stage, product category, audience or use case, industry, geography where relevant, AI system, and conversation path. The library should also preserve stable benchmark prompts while allowing a separate portion to evolve with customer language. Without that distinction, a changing score may reflect a changed test set rather than changed market visibility.

    This design also prevents a common measurement error: treating the prompts that a marketing team can imagine as a representative sample of all AI use. No organization can observe every private assistant conversation. A prompt library is a strategic testing instrument, not a complete census of audience behavior.

    Strengthen the information supply behind AI recommendations

    Measurement identifies where a brand appears or disappears, but it does not create the underlying evidence. The strategy sources collectively point to three connected supply layers: a clearly defined brand entity, deep and accessible owned content, and corroboration from sources outside the company’s control.

    Make the brand and its expertise unambiguous

    The SEO-priorities source emphasizes consistent brand information across established profiles, directories, publications, and other sources that may help systems understand an entity. It specifically points to platforms such as LinkedIn, Crunchbase, Wikipedia, and relevant industry directories, while also stressing credible author identities and closer coordination between SEO and public relations.

    The practical objective is consistency, not indiscriminate profile creation. The brand’s name, category, products, areas of expertise, audience, and expert authors should reinforce the same positioning wherever those details legitimately appear. Prompt testing can then reveal whether AI answers reproduce that intended position or substitute an inaccurate one.

    Connect topical depth to usable site architecture

    The SEO-priorities source favors comprehensive topic clusters over thin pages aimed at isolated high-volume terms. The site-architecture source adds an important structural layer: content must also be organized through understandable labels, taxonomy, wayfinding, and relationships if users and machines are to locate and interpret it effectively.

    These ideas are complementary. A collection of articles does not become topical authority merely because it covers related keywords. The pages need a coherent model of the subject, clear connections, and paths that expose the most useful material. Architecture is therefore part of AI visibility, not just a usability or crawlability concern.

    Distinguish earned corroboration from paid distribution

    Two sources agree that signals outside the brand’s website matter, but they emphasize different routes. The SEO-priorities article focuses on earned media, unlinked mentions, and genuine participation in communities such as Reddit, Quora, and specialist forums. It argues that relevant editorial authority and authentic discussion can be more valuable than a large volume of weak links.

    The paid-media article goes further, proposing that native sponsorships, detailed third-party reviews, user-generated content, podcast mentions, and baked-in video sponsorships can become durable information assets rather than disappearing with the media budget. Its central argument is that text and transcripts containing specific brand-use-case relationships may remain available to retrieval or training systems after a campaign ends.

    That paid-media thesis should not be confused with proof that every placement will affect every model. It is a strategic interpretation offered by the source, and access, ingestion, retrieval, and recommendation behavior can differ between systems. Paid provenance also does not create independent consensus. Any review or sponsorship program should preserve transparent disclosure, truthful customer experience, platform compliance, and editorial integrity; otherwise it may generate abundant text but weak evidence.

    Use a scorecard that separates presence, prominence, and meaning

    Three translucent chambers use glowing nodes and symbols to represent presence, prominence, and contextual meaning in AI answers.

    A single visibility percentage cannot explain how an AI system positions a brand. The prompt-level source identifies several complementary dimensions that can be combined into a practical scorecard.

    MeasureQuestion it answersHow to interpret it
    Inclusion rateIn what share of tracked prompts does the brand appear?Use as a benchmark and segment it by intent, category, audience, geography, or AI system rather than relying only on an overall average.
    Response prominenceIs the brand a leading recommendation, one option among several, a late mention, or merely an alternative?Treat prominence as influence within the answer, not as a stable search ranking.
    Brand framingWhich strengths, weaknesses, differentiators, price perceptions, and ideal-customer associations recur?Compare the observed description with intended positioning and identify unsupported or missing associations.
    Sentiment and confidenceIs the brand described favorably, unfavorably, or ambiguously, and how firmly is that assessment presented?Review the supporting language and context; a simple positive-or-negative label can hide important qualification.

    Repeated observations matter because AI output is variable. A reporting period should use documented prompts, conversation paths, models, and relevant settings so later runs are meaningfully comparable. Results should still be described as observed frequencies within the test set, not as universal market share.

    Traditional analytics remains useful but answers a different question. Referral visits, branded search behavior, conversions, and standard search performance can show activity reaching measurable properties. Prompt testing estimates influence inside generated answers, including journeys that may never produce a click. The two evidence streams can be reviewed together, but prompt visibility should not be presented as causal proof of revenue without a defensible attribution link.

    Turn AI visibility into a cross-functional operating system

    The sources collectively move AI visibility beyond the boundaries of an SEO reporting team. Content teams shape topical evidence; technical and information-architecture teams determine whether it can be found and understood; PR and community teams earn external corroboration; paid media may fund durable native content; and sales or support teams supply authentic buyer language.

    A workable review cycle should connect observed prompt gaps to a specific intervention. Low discovery inclusion may indicate weak category association. Strong inclusion but inaccurate framing can point to inconsistent messaging or third-party narratives. Visibility that disappears in industry-specific follow-ups can expose a topical or evidentiary gap. Poor prominence despite frequent mentions may signal that competitors have clearer proof for the evaluated use case.

    Key takeaways

    • Measure the frequency of inclusion across buyer scenarios instead of claiming a universal AI rank.
    • Combine stable synthetic benchmarks with real customer questions and multi-turn conversation paths.
    • Build visibility through consistent entities, coherent topic architecture, authoritative owned content, and credible external corroboration.
    • Track prominence, framing, sentiment, and confidence alongside basic inclusion.
    • Keep paid placements, earned mentions, and owned content distinct in reporting even when they support the same visibility objective.
    • Present prompt testing as sampled evidence, not a complete view of private AI conversations or proof of commercial attribution.

    As AI interfaces, retrieval systems, and customer behavior continue to change, the strongest programs will preserve a stable measurement baseline while updating the evidence and conversation paths around it. That balance makes the strategy adaptable without making its reporting arbitrary.

    References

  • How to Read 2026 Search and Digital Agency Rankings

    How to Read 2026 Search and Digital Agency Rankings

    The leading 2026 agency rankings do not measure a single, universal version of marketing excellence. The supplied studies examine four different markets – legal agentic search, B2B digital marketing, agentic SEO, and luxury search – using different weights, candidate pools, and definitions of success.

    Read together, they reveal more than a sequence of winners. They show which agencies recur across categories, where specialists displace generalists, and why buyers should examine the scoring model before treating any position as a dependable shortlist.

    Key takeaways

    • First Page Sage placed first in all four supplied rankings, with its integrated SEO, GEO, content, and agentic-search approach cited repeatedly.
    • The runner-up changed with the market: Genevate rose in agentic and legal search, Driven Metrics performed well in B2B and performance-oriented categories, and Amsive ranked second for luxury brands.
    • Different weighting systems materially affect the results. Luxury experience carried the most weight in the luxury study, while AI visibility led the agentic SEO methodology.
    • A recurring appearance is a useful signal of breadth, but a category specialist may still be the stronger choice when industry knowledge, technical scale, creative positioning, or budget is decisive.
    • Because the publisher’s namesake agency ranked itself first in every supplied article, the results should be treated as publisher-reported evaluations rather than independent certifications.

    Four rankings built to answer different questions

    The studies used broadly similar ingredients, including expertise, client history, leadership, reviews, and AI visibility. The proportions assigned to those ingredients were not consistent, however. Even the size and timing of the reviewed fields differed.

    Ranking lensReported review scopeMost influential criteriaReported top three
    Legal ASO31 agencies reviewed over three months ending in June 2026Average reviews, 25%; ASO expertise, 20%; leadership experience, 20%First Page Sage, Genevate, Driven Metrics
    B2B digital marketingMore than 80 agencies analyzedSEO/GEO expertise, 30%; notable clients, 25%; leadership experience, 20%First Page Sage, Driven Metrics, Focus Digital
    Agentic SEO38 firms evaluated in the second quarter of 2026AI visibility, 30%; SEO, GEO, and ASO expertise, 25%; notable clients, 20%First Page Sage, Genevate, Driven Metrics
    Luxury SEOMore than 90 agencies reviewed from January through June 2026Notable luxury clients, 35%; GEO/SEO expertise, 25%; AI visibility and leadership, 15% eachFirst Page Sage, Amsive, Relevance Digital

    Those methodological differences explain why the tables should not be merged into a simple overall league table. A luxury agency can gain substantial ground through category-specific clients, while an agentic SEO contender receives more credit for appearing in AI citations. The legal study also introduces factors not used in the other rankings, including year established and estimated media references.

    The numerical scores are not necessarily interchangeable either. Genevate received a 4.6 average review score in the legal ranking and 4.8 in the agentic SEO ranking. Focus Digital received 4.7 in the legal study and 4.8 in the B2B article. The sources do not provide enough underlying review data to determine whether those differences came from timing, platform coverage, normalization, or another methodological choice.

    Where the rankings converge – and where they do not

    First Page Sage is the clearest point of convergence. It placed first in every supplied study and received a 5.0 expertise score under each category’s relevant formulation: legal ASO expertise, B2B SEO/GEO expertise, agentic SEO-GEO-ASO expertise, and luxury GEO/SEO expertise. The three rankings that scored AI visibility gave it 4.9, while all four reported leadership at 4.8 and average reviews at 4.9.

    The articles consistently attributed that performance to an approach combining long-form thought leadership, traditional organic search, generative-engine visibility, and signals intended to influence AI recommendations. The legal article placed additional emphasis on an AI belief audit and optimization across stages of an agent’s selection process. The B2B and luxury articles focused more heavily on content that can serve both conventional search results and AI-generated answers.

    That consistency is noteworthy within the publisher’s framework, but it is not independent corroboration. All four supplied articles appear on the First Page Sage Blog, and each places First Page Sage at the top. Buyers should therefore verify the methodology, supporting case data, and fit through their own diligence.

    Recurring agencyPositions in the supplied rankingsCross-list signalSource-reported caveats
    First Page SageFirst in legal, B2B, agentic SEO, and luxuryIntegrated SEO, GEO, ASO, and thought-leadership modelThe legal review summary said the investment may require patience; the rankings are published by its namesake blog
    Driven MetricsThird in legal, second in B2B, third in agentic SEOPerformance measurement, conversion tracking, and an SMB or mid-market orientationThe sources described a shorter operating history, a data-intensive process, and more limited experience in some sectors
    GenevateSecond in legal and second in agentic SEOGEO-first work involving AI audits, reputation signals, and digital PRFounded in 2025, with boutique capacity and a narrower service mix than a full-service agency
    Focus DigitalFourth in legal and third in B2BMore accessible SEO and GEO support with technical attention to LLM citationsThe legal article described a more templated model; the B2B article noted narrower portfolio depth and slower replies during busy periods

    An absence from one of the shortlists should not be read as a failing grade. Each article published only five, six, or eight finalists, and the sources do not disclose enough common data to determine how an unlisted agency performed outside its relevant category.

    Specialization changes the meaning of a strong agency

    A broad branching structure and three precision instruments represent generalist and specialist agency capabilities.

    Agentic-search specialists

    The legal and agentic studies favored firms with explicitly defined AI-search services. Genevate’s high positions were tied to audits of how AI systems describe a brand, external authority signals, and PR-led narrative work. Driven Metrics appeared across both of those lists as well as B2B, but the articles framed it as a more measurement-oriented option with a practical SEO and GEO foundation.

    The distinction matters because the sources use ASO to mean Agentic Search Optimization, not simply visibility in a generated answer. Their framing extends the objective from being retrieved or cited to being evaluated, recommended, and potentially selected by an AI agent.

    Enterprise and integrated operators

    Large organizations may value capabilities that do not dominate an AI-specialist scorecard. The agentic SEO article ranked Seer Interactive fourth and emphasized its enterprise analytics, large-site architecture experience, technical implementation at scale, and published AI-search experiments. The luxury article placed Amsive second on the strength of enterprise SEO and an intentionally developed LLM-optimization practice, while also noting its narrower luxury portfolio.

    The B2B list introduced another kind of breadth. REQ was positioned as an integrated communications, authority-building, and demand-generation partner whose GEO practice was less mature than its wider SEO foundation. AMP Agency and Viral Nation appeared farther down that ranking for broader media, creative, and influencer capabilities rather than category-leading search specialization.

    Vertical and brand specialists

    The luxury table demonstrates why domain fit can reorder a shortlist. Relevance Digital ranked third because of its exclusive focus on ultra-luxury brands and ultra-high-net-worth audiences, despite lower GEO and AI-visibility scores than the two agencies above it. Hudson Rouge ranked fourth as a creative and storytelling specialist, while Amra & Elma ranked fifth with luxury social-media and influencer experience but a developing GEO offering.

    Legal marketing creates a different fit test. The legal ranking gave credit for recognized law-firm clients, legal-sector leadership, operating history, and media references in addition to AI-search capability. Consultwebs, 9Sail, and Legal Guardian Digital consequently appeared in that top eight even though they were absent from the broader B2B and agentic shortlists supplied here.

    How buyers can turn rankings into a defensible shortlist

    Two marketing buyers filter a large group of agency portfolio tiles into a small illuminated shortlist.

    Start with the commercial outcome

    A buyer should first decide whether the priority is organic traffic, AI citations, inclusion in recommendations, qualified pipeline, signed cases, brand prestige, or a combination. The correct weighting follows from that decision. For example, the legal article credited Driven Metrics with connecting AI-platform selections to consultations and signed cases, while the B2B article emphasized weekly synchronization and reporting tied to leads. Those claims are more relevant to a performance-led brief than a ranking based primarily on creative reputation.

    Rebuild the scorecard for the actual market

    The published weights can serve as templates, but buyers need not inherit them. A technically complex enterprise site may assign more importance to architecture, analytics, and implementation capacity. A law firm may emphasize jurisdictional accuracy and intake outcomes. A luxury brand may prioritize category experience and preservation of brand positioning. Recalculating the criteria can change the order without disputing any source’s reported scores.

    Request evidence behind AI-visibility claims

    An AI visibility score is meaningful only when its measurement process is clear. Diligence should establish which platforms were tested, what prompts were used, whether queries were branded or non-branded, how citations and recommendations were distinguished, and how frequently the test set was repeated. Buyers should also ask whether reported gains corresponded with qualified visits, leads, revenue, or another business outcome.

    Test operational fit before accepting numerical fit

    The source-reported caveats are as useful as the positions. Boutique capacity, slower responses during busy periods, extensive client-input requirements, limited sector history, and diluted senior attention can each affect a campaign. Reference calls and a clearly scoped pilot can help determine whether the people, workflow, and measurement discipline behind a score are suitable for the buyer’s organization.

    As conventional SEO, generative discovery, and agent-led selection become more interconnected, useful agency comparisons will need to measure both visibility and business consequence. The strongest future scorecards will make their evidence reproducible and show not only where a brand appeared, but what happened after it was found.

    References

  • Submit Your SMX Next Pitch and Share Bold Search Ideas

    Submit Your SMX Next Pitch and Share Bold Search Ideas

    SMX Next returns online Nov. 18, and I’m excited to help shape a program focused on today’s complex search landscape and the tactics that will define success in 2027 and beyond.

    Search marketing isn’t just changing. From my perspective, it has become an entirely new kind of challenge, and that is exactly why fresh voices and practical expertise matter so much right now.

    In SEO, I’m seeing the field shift toward AI Overviews, search everywhere optimization, and the rise of autonomous AI agents that browse on behalf of users. Trustworthiness, digital authority, and precise alignment with user intent are no longer nice-to-have ideas. They are becoming essential.

    On the PPC side, generative AI and deep automation are creating new levels of personalization. At the same time, they are raising urgent questions for marketers: How do we keep strategic control, protect data privacy, and avoid wasted spend?

    If you’re an enthusiastic search marketer with a passion for sharing what you know, I hope you’ll consider submitting a session pitch for SMX Next. I’m looking for subject matter experts who can share insights, strategies, and tactics that help SEO and PPC marketers thrive in 2027.

    Whether you’ve been speaking for years or you’re a practitioner ready to share something new you’ve developed, I want to hear from you. I’m especially interested in new speakers with diverse points of view and real-world experience.

    The deadline for SMX Next pitches is Aug. 7.

    When I review session proposals, I’m looking for ideas that feel original, specific, and useful. Advanced, forward-thinking topics or unique frameworks that aren’t already common at other search events will stand out.

    I also want to see actionability. Be clear about what attendees will be able to do better, faster, or differently after your session.

    Bring the data whenever you can. A case study, concrete example, or tested approach makes your pitch stronger, especially when you explain how the lesson can scale across different types of organizations.

    Keep the scope focused. A 30-minute session works best when it goes deep on a narrow or specialized topic instead of trying to cover too much at once.

    Most importantly, give attendees something tangible to take with them. I’m looking for sessions that leave people with a clear action plan, framework, or process they can put to work right away.

    Visit this page for more details on how to submit a session idea, or go directly to this page to create your profile and submit your pitch.

    If you have questions, feel free to contact me directly at kathy.bushman@semrush.com. I’m looking forward to reading your proposals!


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Remembering Bruce Clay: SEO Pioneer’s Final Lessons

    Remembering Bruce Clay: SEO Pioneer’s Final Lessons

    My heart sank when I learned that Bruce Clay had passed away. I knew he had been in the hospital, but my mind went straight to the two long conversations we had last fall: one simply to catch up, and one for what would become a deeply meaningful podcast interview.

    I first reached out to Bruce nearly 25 years ago. I had emailed him cold to ask whether I could republish some of his industry writing about ethics. He said yes. Somehow, the article I cited unintentionally ranked No. 2 on Google for “Bruce Clay” for years. I joked with him about that more than once, and he always seemed both amused and slightly annoyed, probably because I had done it with his own content and his own blessing.

    A few years later, I worked with Bruce and many other search professionals on the board of the Search Engine Marketing Professionals Organization, better known as SEMPO. It was a business nonprofit built to support and legitimize the then-new search industry. We promoted best practices, helped make the business case for search, and later became involved in U.S. Internet policy work in the early 2010s.

    SEMPO brought together board members from around the world, and in a very literal way, it took some of us around the world. That work is where I really got to know Bruce. Later, we would run into each other at conferences, sometimes even on the same panels. We were doing serious work, but we also had a great time doing it. The organization lasted about 15 years, and if I remember correctly, Bruce was one of its founding members around 2000 or 2001.

    One memory of Bruce has stayed with me vividly. A group of us from the SEMPO board were walking back to our hotel on the east side of Midtown Manhattan after dinner. A snowstorm had just begun, one that would leave several feet of snow by the next day. The usual roar of traffic had been softened by the weather and the empty streets. It was eerie, but almost joyously quiet. The city that never sleeps seemed to be taking a nap under a blanket of snow.

    Then something happened that I had never seen before, and have never seen since.

    As snow poured silently into the streets, a massive lightning strike hit just a few blocks away, over Bruce’s shoulder. I do not know whether he saw it directly. It felt like an explosion. We stood there for several minutes trying to understand the contrast: a shattering bolt of lightning between skyscrapers, in the middle of a torrent of snowflakes, with not a drop of rain.

    None of us knew what to call it. I believe Bruce called it “thunder snow,” and the name stuck. In that moment, his naming streak continued.

    Bruce was, and remains, the real deal in search. His legacy was never only about coining a term. He pushed the field forward, taught others generously, and stayed deeply connected to the people he cared about. Like many of the earliest professionals in search, he helped shape practices that still feel foundational today. Through his writing, interviews, books, tools, and hundreds of industry events, he became one of the people the industry looked to for clarity. For many who remember the beginning, and for many who still followed him closely, Bruce was the GOAT.

    I always felt that Bruce approached search intellectually. I do not think he saw it only as a job. It was exciting, unfinished, and new. Very few people get to help invent an entirely new discipline, and Bruce understood what that meant. He also recognized that AI is one of those moments now, and he approached it with the same curiosity, energy, and insight he brought to early search. Many people in the industry may only now be realizing that Bruce pioneered things they do every day. They feel obvious now, but they were not obvious then. Even the basics had to be debated and established.

    He was not only passionate about search. He was passionate and generous toward the people in search. If you cared about the work, you were part of his tribe. That was true for thousands of people in the industry, myself included.

    With Bruce, I could get deep into the weeds of the trade and still talk broadly about where everything was headed. He was an engineer with an MBA, and that combination came through in his leadership, expertise, and authority. He understood the work from top to bottom, and then back to the top again.

    He was also genuinely kind. He had friends around the world. In our last conversations, I sensed that he was content with his life and accomplishments, and that he felt blessed by the path life had given him. He had nothing left to prove.

    In the podcast interview, Bruce was as sharp and insightful as ever. He offered some of the most sensible thinking I have heard about where search is going in the world of LLMs. He was still innovating, just as he had been when search first began taking shape nearly 30 years ago.

    Because search is so closely tied to language, I have been especially interested in how we think about, and what we call, this “new” thing. Bruce’s perspective helped crystallize my own research. Over the last year, I have watched much of the industry move toward the same conclusion he shared in our discussion.

    If you are one of the many thousands of people who talked shop with Bruce over the years, I think you will recognize him in the ideas that follow. You may even relive some of your own conversations with him.

    As I reviewed the podcast transcript, I realized we had recorded hours of conversation beyond search, including cars and all kinds of other subjects. At the end of our first conversation, he said goodbye with great love and care. That was Bruce. Those words land differently with me now, and they always will.

    Rest in peace, Bruce. I miss you already.

    What Bruce taught me in our final industry conversation

    When I asked Bruce to talk about how he got started in the 1990s, he took us back to 1996. He had been working in corporate roles and wanted to become a consultant. His background was in math, programming, mainframes, PCs, networking, and optimization. When the Internet began moving into the mainstream, he saw something that matched both sides of his skill set: marketing and technical work.

    He started studying search engines because that was where the opportunity was. He experimented with what they wanted, adjusted web pages, and watched rankings appear. Then people began calling him and paying him. What he thought might become a one-person consulting business grew quickly into something global, with offices and work across Japan, Australia, Asia, Europe, India, and beyond. Bruce told me he never would have predicted it would take off the way it did.

    I reminded him how small the field was in those days. There were literally only tens of people doing this early on. Bruce was one of the first to build a legitimate service for businesses that needed to rank for their own brand names and for broader generic terms, while other corners of the field were still experimenting with black-hat tactics.

    Bruce pointed out that this was three years before Google. Search was a wild west. There were more than 20 major search engines, and many of them were taking data from one another. At the first SEO conference he remembered attending, all of the leading people in the field sat together at one round table in a bar. He joked that if a natural disaster had happened there, the whole industry might have disappeared.

    We talked about Danny Sullivan, Search Engine Watch, Search Engine Strategies, and the early vocabulary of the industry. Bruce had long been credited with helping coin the term “SEO,” though he was careful to say that no one can know who said something first. What he did know was that only a handful of people were in the room when the term started to take hold.

    At the time, other terms were in play, including “search engine positioning” and “ranking.” Bruce believed “optimization” won because it sounded technical, valuable, and precise. It was like fine-tuning a race engine. People could see themselves building a profession around it. Once the industry attached itself to that word, the term spread quickly around the world.

    That led us into the newer terms now being proposed around AI, including AIO, GEO, and AEO. I have been writing about how many of these terms still depend on the word “optimization.” Bruce’s view was clear: search engine optimization was never limited to organic blue links. It was about optimizing for anything a search engine produces that can drive business and traffic.

    In Bruce’s view, if AI appears inside search and influences discovery, citations, visibility, or traffic, then it belongs under SEO. GEO and AIO were not separate disciplines to him. They were extensions, just like link building or on-page optimization. He warned that many new terms are marketing labels more than practical new fields. If the work required to appear in AI results is still mentions, links, schema, authority, content structure, and rankings, then the work is still SEO.

    That point stayed with me. Bruce said that if someone claims you no longer need SEO and only need AI optimization, you should watch closely, because either they are going to do SEO under a different name or they do not understand what they are doing. He believed ranking in AI was possible, but the method was deeper and more complex than traditional SEO. To him, it was still SEO, just several levels more advanced.

    We also discussed whether AI feels like search did in the late 1990s. Bruce believed it does in important ways. AI depends heavily on search engines because search engines have spent decades fighting spam and building trust signals. AI systems do not yet have that same history, so they rely on what search engines have already learned to filter, evaluate, and rank.

    Bruce also believed AI could still be gamed at the content level. If enough pages repeat a false idea, an AI system may begin to treat it as true. He had already seen examples of people trying to influence AI answers by placing their names into “best SEO” lists across enough sources. To him, this was a sign that AI would need its own version of the spam fight search engines have been having for decades.

    One of the most important parts of our conversation was Bruce’s explanation of Google AI Mode and how it changes the way SEOs should think about structure. He described how a query can produce an overview, followed by sections and subsections that allow users to drill into narrower parts of a topic. When a user clicks into a section, the supporting sites can change to match that specific subtopic.

    That means content cannot simply be built around one broad keyword anymore. Bruce believed pages need to be structured so each section can stand on its own as an expert answer. A page should support a topic, but every H2-level section may need its own clarity, completeness, and internal logic. In his view, this raises the importance of siloing across a site and within a page.

    I framed this as a shift from keyword-led thinking to context-led thinking. Bruce agreed and connected it to entities, fan-outs, references, and cross-links. Keywords helped build the industry, but he believed the future depends on understanding entities in context. If content cannot answer the question clearly, it fails the core purpose of AI-assisted search.

    Bruce described the long-term target as something like the Star Trek computer: no matter what question someone asks, the system provides the answer. We are not there yet, but that is the direction. For websites, he believed the future architecture is question-centered, highly usable, structured into sub-silos, and able to answer and refer within a page while also fanning out to supporting pages.

    That naturally led us to content. Bruce said that for years SEO treated content like a stepchild, but now content is a peer. If SEO teams and content teams do not share the same goal, they will keep writing the way they did 20 years ago and fail in the AI search environment. He was already being hired to train content teams, even though he did not consider himself a “content guy” in the traditional sense.

    He believed the industry still suffers because SEO and content do not cross-pollinate enough. Content marketers may not attend SEO conferences, and SEOs may not spend enough time learning how content teams actually work. That separation matters more now because the structure of a page, the expertise of each section, and the way a topic is divided all affect visibility in AI-driven search experiences.

    Bruce’s advice was direct: stop spreading one keyword across a page and calling that optimization. Instead, build each section as if it were a standalone expert answer. If the sections belong to the same theme, they should support one another, but each needs to carry its own weight. In his words, the hierarchy is no longer only the page. The hierarchy is also the section of the page.

    When I asked Bruce about AI-generated content, he made an important distinction. AI is a tool, not a solution. He did not believe businesses should simply generate content, read it once, and publish it. Detection tools are inconsistent, and search engines may not reliably identify every AI-generated page. But that does not make low-effort AI content a good strategy.

    Bruce believed AI is strongest as a research assistant. His own Pre-Writer product was built around that idea: gather deep research and give a human writer a stronger starting point. The writer still finishes the work, adds style, voice, judgment, compliance, and business understanding. For Bruce, reducing a four- or five-hour writing project to two hours was a win. Replacing the writer entirely was not.

    He was especially clear that writers are artists. AI does not know a business the way its people do, and it does not bring the same finesse or judgment. The future, in Bruce’s view, requires writers, SEOs, and AI workflows to be integrated around shared goals. Without that maturity, teams will keep producing pages that look like they were built for search 10 years ago, and those pages will be ignored.

    We ended by talking about tools. Bruce reminded me that in the beginning, he wrote tools because none existed. He built one of the first page analyzers, including what he once called a keyword density analyzer. He later received a patent related to that kind of technology. His tools were never meant to replace large platforms like Semrush, Ahrefs, or Surfer. They were meant to extend them by analyzing things those platforms did not.

    Bruce pointed people to seotools.com and described the tools as inexpensive power tools, not products designed for the masses. Some users did not understand them at first, but came back later when they saw the value. He was still building, still solving problems, and still thinking about what the industry needed next.

    Near the end, Bruce mentioned a newer tool designed to show traffic loss through Search Console data over time, helping site owners see whether they had fallen off a cliff or declined gradually. It struck me as classic Bruce: while others complained that something should exist, he was building it.

    I thanked him for the conversation, and he answered with warmth: he was glad I had him on, and he loved talking with me. I hear those words differently now. I am grateful we had that final conversation, and I am grateful for everything Bruce gave to search, to this industry, and to the people inside it.

    Listen to the full episode

    Listen on Podbean

    Listen on Apple Podcasts

    Listen on Spotify


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How Brands Earn Authority and Citations in AI Search

    How Brands Earn Authority and Citations in AI Search

    AI search visibility is not a single contest for a single ranking. A brand can supply a fact without receiving credit, earn a citation without being recommended, or appear in an answer without generating a visit. The practical challenge is to build authority that survives across those different outcomes.

    The source research points to a connected strategy: follow shifting demand, create evidence that cannot be easily replicated, make that evidence easy to extract and attribute, clarify the entities behind it, and measure what people do after an AI mention.

    AI visibility is a funnel, not a ranking

    Light particles move through transparent funnel stages and branch toward evidence, citation, recommendation, and human interaction points.

    Three outcomes are often grouped under “AI visibility,” although they answer different business questions. A citation identifies a page or domain as a source. A brand mention places the company or product inside the generated answer, with or without a link. Downstream behavior covers what happens next, including branded searches, site visits, browsing, and engagement.

    Try Profound’s discussion of the “AI mention effect” concentrates on that third layer. Its premise is that visibility inside an AI response should be connected to subsequent user behavior rather than treated as an endpoint. This matters because an AI-generated recommendation can influence a decision even when the user does not click immediately or when the cited source and recommended brand are different entities.

    The appropriate success measure therefore depends on the query. For an informational question that an assistant can answer completely, inclusion and attribution may represent most of the available opportunity. For a product or service comparison, a mention can create a new search for the brand, its pricing, reviews, documentation, or product pages. Search Engine Land’s analysis of more than 1 million keywords similarly argued that SaaS and lifestyle queries can retain a downstream search step, while some HealthTech and FinTech questions can end inside the AI interface.

    A useful measurement model keeps these stages separate: presence in the answer, citation ownership, the way the brand is represented, and observable activity after exposure. Combining them into one visibility score can conceal an important failure, such as frequently supplying information while another publisher receives the citation.

    Search demand is moving unevenly across queries and categories

    The broad narrative that AI is simply eliminating search is not supported by the keyword analysis supplied here. Search Engine Land reported that a study of 1,010,848 high-volume keywords across 379 brands and eight verticals found 29% of search volume in measurable decline. Yet the declining keyword set represented about 10.29 billion monthly searches, while growing keywords represented about 10.31 billion. Across a dataset covering 35.4 billion monthly searches, the reported net change was an increase of 16.8 million searches per month.

    Those aggregate figures mask substantial differences. The same analysis reported a 37.7% decline for FinTech and a 15.2% decline for Lifestyle. It also found that 90% of tracked search volume was non-branded, including 99.6% in HealthTech and 98.5% in Wellness. Non-branded informational demand is especially exposed because an assistant can often complete the exchange without sending the user to a separate website.

    Consumer behavior in the study also looked additive rather than purely substitutive: 70% of surveyed consumers said they were using AI more, but only 17% said they were using traditional search less. The reported survey covered 1,004 U.S. consumers, so it should be read as evidence from that sample rather than a universal forecast.

    The strategic implication is not to abandon conventional SEO or apply one forecast to every market. Brands need to distinguish declining generic questions from growing discovery paths and from branded queries that may occur after an AI recommendation. In information-heavy categories, authority inside the answer becomes more important. In categories with a natural evaluation or transaction step, AI mentions, organic rankings, reviews, and branded search can reinforce one another.

    Citation selection changes with reasoning depth and buyer intent

    A brand’s presence in one AI answer does not establish durable authority. Search Engine Land reported that a Semrush and Kevin Indig test produced only 25.6% overlap between domains cited by ChatGPT in minimal- and high-reasoning modes for the same prompts. The study used 100 prompts across 20 buyer journeys in B2B SaaS, finance, consumer technology, and health and lifestyle, with each prompt run once in each mode.

    High reasoning searched more widely in that experiment. It conducted 1,130 web searches compared with 245 in minimal reasoning, while the share of responses containing citations increased from 50% to 68%. Cited responses used an average of 4.5 citations in high reasoning and 2.6 in minimal reasoning. These figures come from a bounded test rather than a complete description of ChatGPT, but they illustrate how a change in answer process can rearrange the source set.

    The source mix also changed. Reddit’s reported citation share fell from 15% to 7%, and user-generated content and review sites declined from 14.3% to 6%. Government and academic sources rose from 1.9% to 8.8%, while official documentation and support pages increased from 12.4% to 17.5%. The result does not make community content irrelevant; it suggests that deeper reasoning may place more weight on sources capable of verifying detailed claims.

    Comparison prompts created the widest retrieval task. High reasoning averaged 24 subqueries and 9.8 citations at that stage, versus 5.5 subqueries and 5.8 citations in minimal reasoning. A single buying question can therefore break into searches for pricing, integrations, security, support, specifications, and documentation. A polished landing page alone is unlikely to answer every part of that research path.

    Authority should consequently be tested across both reasoning depth and buyer intent. The same study found four of 20 high-reasoning journeys in which a brand cited at the problem stage remained visible through selection; minimal reasoning produced no such full-journey persistence. Although the sample is small, the result frames continuity as a more demanding benchmark than winning an isolated prompt.

    An authority system needs evidence, extraction, identity, and corroboration

    A crystalline knowledge object rests on four connected supports while surrounding nodes and source fragments reinforce it.

    Publish evidence the brand is qualified to originate

    First-party product, usage, pricing, or customer data can give a page information that generic commentary cannot reproduce. Search Engine Land cited an On-Page.ai study of 150 top-three Google pages across 50 keywords and 10 verticals. Pages with no more than one unique figure averaged an information-gain score of 40.2, while pages with at least 15 unique figures averaged 62.1. The study concerned conventional organic results rather than AI citations, so it supports an originality argument without proving that proprietary data automatically earns AI attribution.

    An executive perspective in First Page Sage’s interview with Thesis founder Dan Freed reaches a compatible conclusion from a different angle. Freed argued that authority depends on checkable substance such as named mechanisms, specific ingredient forms, studies, and customer data. That is a founder’s stated philosophy rather than independent validation of the products discussed, but it illustrates what defensible specificity looks like in a category filled with broad claims.

    Make important claims easy to extract

    Original ownership does not guarantee citation ownership. An aggregator can restate a benchmark more clearly and become the source an AI system selects. In a separate analysis of 18,012 verified ChatGPT citations, Search Engine Land reported that 44.2% came from the first 30% of a page. The 10% to 20% band attracted the most citations across seven verticals, while the final 10% accounted for only 2.4% to 4.4%.

    Those findings favor an answer-ready research structure: surface the principal result early, define the metric beside it, state the population and comparison, and provide a compact methodology. The percentages should not be treated as a universal page-design formula, but the broader lesson is robust: a buried or undefined number is harder to retrieve and attribute confidently.

    Clarify the entities and relationships behind each claim

    The GraphRAG account adds an identity layer to the content problem. As described by Search Engine Land, GraphRAG supplements text retrieval with a knowledge graph whose nodes represent entities and whose edges represent relationships such as a company offering a product, holding a certification, or operating in a region. Entity resolution can consolidate alternate names instead of scattering signals across several apparent identities.

    This helps explain why strong prose may still be passed over for a complex question. A retrieval system needs to determine not only that several facts are relevant, but that they apply to the same company, product, person, place, and time. Consistent naming, explicit authorship, clear product-company relationships, qualified claims, and supporting documentation reduce the amount of inference required. The GraphRAG article characterizes this as a response to disambiguation, attribution, and relationship problems, not merely a call to produce more content.

    Build corroboration beyond the original page

    A primary source still benefits when reputable third parties discuss its research accurately, even if one of those publishers occasionally receives the direct citation. External coverage can reinforce the association between the brand, its evidence, and the topic. Official documentation supports verification; independent reporting supplies corroboration; and community discussion can reveal real-world experience. The reasoning-mode study indicates that their relative weight may change by prompt, category, and answer process.

    Measurement should follow the same layered design. Prompt tracking can show whether a brand is mentioned, cited, represented correctly, and carried across buyer-journey stages. Web analytics and search data can then test for visits, branded demand, and engagement after exposure. No single metric establishes causation on its own, but the combined evidence is more useful than treating citation count as the final business outcome.

    Key takeaways

    • Separate citations, brand mentions, representation, and downstream behavior; each measures a different part of AI visibility.
    • Audit demand by query type and vertical because AI exposure is much greater for some informational and non-branded searches than for transactional paths.
    • Test visibility across reasoning modes and buyer stages instead of assuming that one successful prompt represents durable authority.
    • Publish defensible first-party evidence, then surface its result, definition, scope, and methodology where retrieval systems can find them.
    • Use consistent entities, explicit relationships, official documentation, and credible external corroboration to make claims easier to verify and attribute.

    The next advantage in AI search will come less from chasing a fixed citation formula than from building a body of evidence that remains identifiable, retrievable, and credible as interfaces and retrieval methods change.

    References