Tag: AI Mode

  • Advertising in AI Experiences: A Practical Readiness Plan

    Advertising in AI Experiences: A Practical Readiness Plan

    If you’re being asked for an “AI ads strategy,” don’t start by moving a search campaign into a new interface. An AI experience may be answering a question, narrowing a comparison, selecting an offer, or helping complete a purchase. Your ad has to help with that task without pretending to be the answer.

    The practical job is to make four things line up: the user’s decision, the claim the system can verify, the offer you can honor, and the next action you can measure. When one breaks, more targeting or more generated creative won’t rescue the experience.

    AI ads compete for the next useful action

    A conventional search ad usually occupies a known slot between a query and a landing page. An ad inside an AI experience enters a more fluid sequence. The user may have already described constraints, rejected alternatives, requested a comparison, or asked the system to help complete a task.

    That does not mean advertisers automatically receive the conversation or control the answer. In the initial ChatGPT design, ads are limited to the Free and Go tiers, kept separate visually and technically from model answers, and hidden from Plus, Pro, and Enterprise users. The model is not informed that an ad is present and does not refer to it unless the user asks. Treat that separation as a real product boundary, not a temporary obstacle to work around.

    Google is pursuing a different but related path. Conversational and visual discovery in AI Mode can include sponsored retail listings and Direct Offers intended to help a user continue a shopping journey. The useful planning unit is therefore not merely the keyword, placement, or audience. It is the decision the user is trying to make.

    Rewrite each campaign brief as a decision task. “Reach operations leaders” is an audience description. “Help an operations leader compare tools that meet a stated integration requirement” is a task. The second version tells your team what facts, offer, destination, and measurement the experience needs.

    • User state: What has the person probably established before a sponsored option becomes useful?
    • Decision constraint: Which requirement, location, budget condition, compatibility need, or availability question narrows the choice?
    • Verifiable claim: What can your site, feed, structured data, or product record support without interpretation?
    • Useful next action: Should the user inspect an offer, compare configurations, check availability, request qualification, or complete a purchase?
    • No-ad condition: In which contexts would promotion be irrelevant, sensitive, misleading, or unsafe?

    The same principle applies outside chat. AI can help connect brands with YouTube creators and turn creator-led discovery into commerce. Define creator fit through the audience problem, acceptable claims, and commercial handoff – not reach alone. A highly visible creator cannot repair a mismatched offer or an unsupported product promise.

    Build answer, offer, and transaction readiness in that order
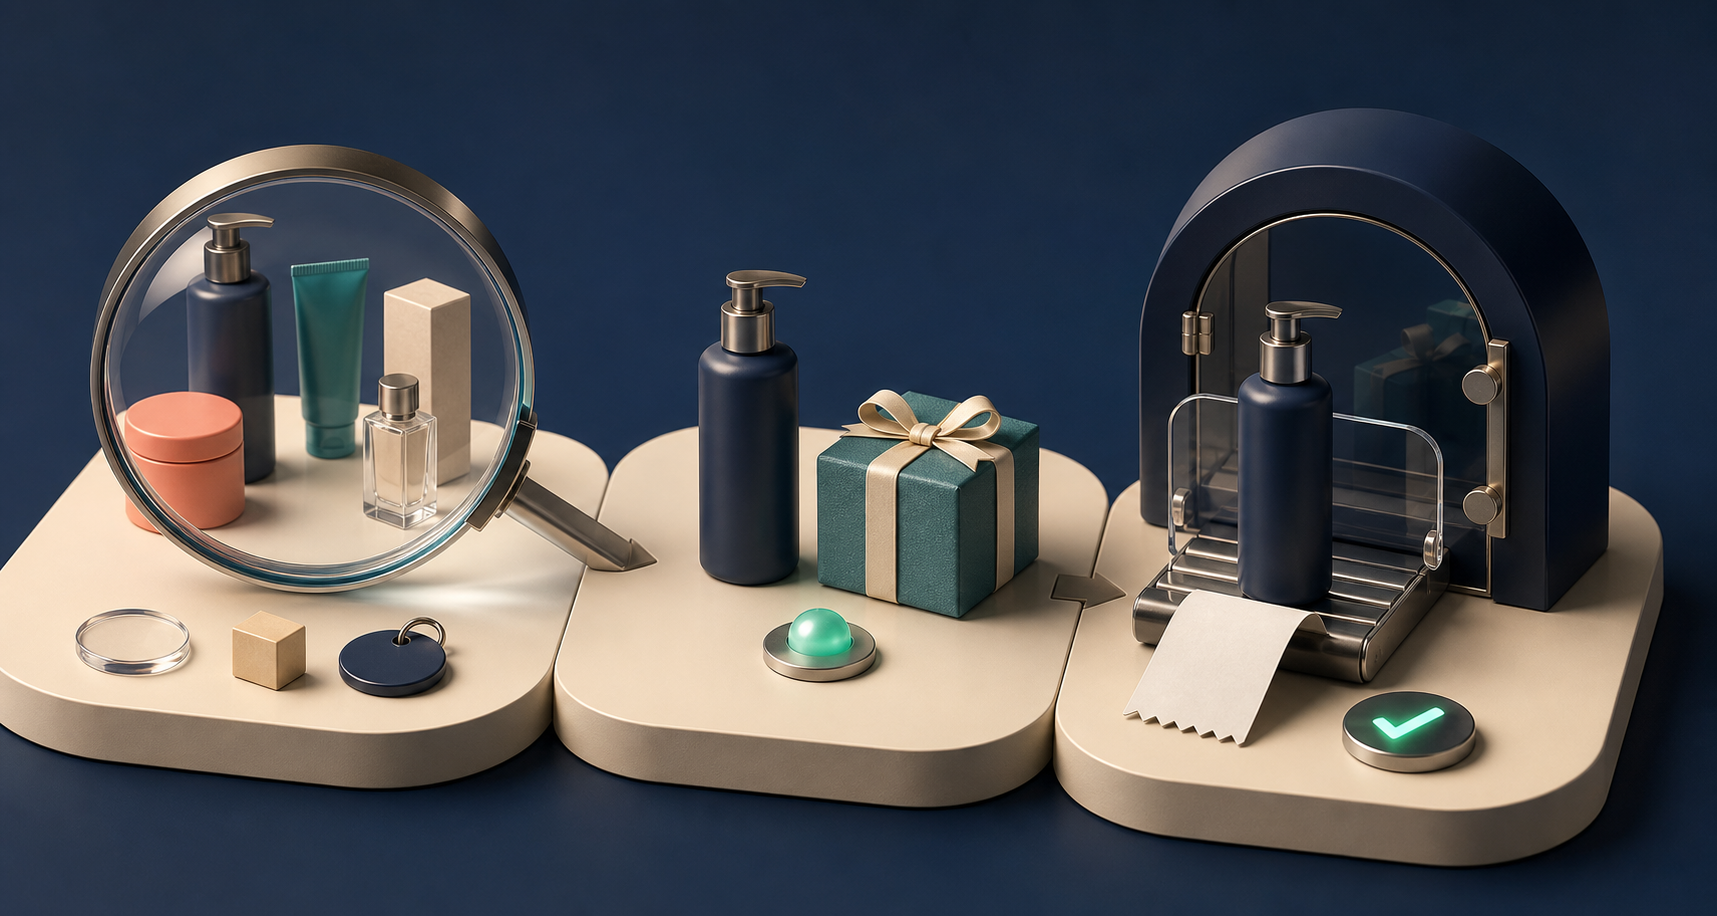
    Three connected stations depict product answers and evidence, an available offer, and a secure transaction in sequence.

    AI advertising readiness is not a media-only project. The system may need to understand your business, retrieve a current offer, and pass the user into a reliable transaction. Those are separate layers, and each can fail independently.

    Answer readiness: make the commercial facts unambiguous

    Your organic AI visibility and your paid eligibility are different, but they depend on a shared factual foundation. A discovery system should be able to identify what you sell, who it is for, where it is available, what conditions apply, and which page is authoritative.

    • Give every important product, service, location, and offer a stable name and a canonical destination.
    • State the qualifying details in visible page copy. Do not leave essential limitations inside an image, sales deck, or support conversation.
    • Keep names, identifiers, prices, service areas, availability, and eligibility language consistent across pages.
    • Use relevant Schema.org types such as Organization, Product, Service, Offer, and LocalBusiness where they accurately describe visible content.
    • Make JSON-LD match the page. Structured data that promises more than the user can see creates ambiguity rather than authority.
    • Separate factual descriptions from promotional language so a system can retrieve a supportable claim without inheriting the slogan around it.

    No schema type guarantees inclusion in an AI answer or an ad placement. The point of structured data is to reduce ambiguity and connect entities, properties, and offers. It cannot compensate for missing content or contradictory records.

    Offer readiness: synchronize what the user can actually receive

    An AI-matched ad becomes unhelpful the moment its offer is stale. This matters more when a sponsored option is presented after the user has already supplied detailed constraints. The apparent relevance raises the cost of a mismatch.

    For retail, reconcile the identifier, title, destination URL, price, currency, availability, variant, shipping terms, return terms, and promotion conditions across the feed, landing page, structured data, and checkout. For services, do the equivalent with the service area, qualification rules, deliverable, capacity, expected handoff, and any condition that can disqualify the lead.

    Assign an owner to every field that can change. Then define which system is authoritative when two records disagree. “The feed team owns price” is incomplete if checkout can display something else. The useful rule is operational: when the source of record changes, every consumer of that field must receive the update, and the affected offer should stop serving if synchronization fails.

    Transaction readiness: design for safe completion and failure

    Agentic commerce shortens the distance between recommendation and purchase. Google’s Universal Commerce Protocol is intended to standardize AI-assisted browsing, purchasing, and transaction completion. That makes checkout reliability, inventory state, and exception handling part of advertising quality.

    • Require clear authorization before a charge, booking, subscription, or binding order.
    • Make order creation idempotent so a retry does not create a duplicate transaction.
    • Validate price, inventory, tax, shipping, eligibility, and promotion status at the point of commitment.
    • Return an unambiguous confirmation with the item or service, amount, status, and next step.
    • Provide a usable path for cancellation, correction, refund, and human escalation.
    • Preserve enough event history to determine whether an error began in the ad, offer record, handoff, or transaction system.

    Do not enable an automated purchase path while duplicate-order protection, cancellation, or exception handling remains untested. The downside is not a weak engagement metric; it is an incorrect charge, unavailable order, or commitment the user did not understand. Keep a confirmation step and a conventional checkout alternative until the failure paths are reliable.

    Make trust part of delivery, not a policy page

    Relevance does not excuse hidden influence. An AI answer carries a different kind of perceived authority from a familiar ad slot, so sponsorship has to remain legible at the moment the user evaluates the recommendation.

    ChatGPT’s initial guardrails include not sharing conversations with advertisers, excluding ads from health, politics, and other sensitive discussions, and giving users personalization controls. These are platform-specific commitments, not universal rules for every AI ad product. Verify the controls and exclusions of each channel before you approve a campaign.

    Your own delivery specification should cover the following:

    • Sponsorship: Do not write creative that could be mistaken for the assistant’s independent conclusion or an organic citation.
    • Context exclusions: Document the tasks and sensitive situations in which your offer should not appear, even if the platform allows the placement.
    • Data boundary: Record which contextual signals the platform exposes and which user data reaches your systems. Do not reconstruct a private conversation from unrelated identifiers.
    • Claim control: Link every material claim to an approved fact, product record, policy, or landing-page statement.
    • Personalization control: Make consent, preference changes, and opt-out behavior understandable wherever your own data collection begins.
    • Correction path: Give users and internal reviewers a direct way to report an inaccurate offer, misleading claim, or broken handoff.

    Keep paid visibility and AI visibility on separate scorecards

    Do not report a sponsored appearance as proof that a model independently recommends your brand. Do not report an organic mention as paid campaign delivery. They answer different questions.

    • Organic AI visibility: Can the system identify the brand, retrieve accurate facts, answer the relevant question, and cite or mention the right entity?
    • Paid AI delivery: Was the sponsored option eligible, shown in an appropriate context, acted on by a qualified user, and connected to a valid offer?
    • Shared quality: Did the destination substantiate the claim, preserve context, and produce an acceptable customer outcome?

    This separation protects your reporting and your optimization. A bid or budget cannot make weak facts more authoritative. Better organic answer coverage does not guarantee sponsored distribution. Both programs can improve the same landing pages and entity records without pretending to be the same channel.

    Put generated creative behind a claim gate

    Generative tools can make asset production much faster. Google’s advertising direction includes Gemini 3, Nano Banana, Veo 3, and AI Max for creative production, reach, and campaign optimization. Faster production increases the need for tighter review because one outdated input can be repeated across many polished variations.

    Start creative generation from an approved claim set, not an open-ended prompt. Require each variation to retain the qualifying language, destination, and current offer. Store the asset with its source claim and offer identifier. When the underlying fact changes, you can then find and retire every affected version instead of searching campaigns by eye.

    Run the first pilot around one decision, not a whole funnel
    A shopper compares three products with help from verified evidence and a distinct promotional offer while a small team observes the decision.

    A broad launch makes diagnosis difficult. If performance disappoints, you will not know whether the problem was matching, creative, answer readiness, offer accuracy, the landing-page handoff, or transaction friction. A narrow pilot gives each failure somewhere specific to land.

    1. Choose a bounded decision task. Define what the user is trying to decide and the conditions that make your offer relevant or irrelevant.
    2. Create a truth set. Record approved claims, prohibited claims, current offers, exclusions, systems of record, and field owners.
    3. Build the complete path. Review the sponsored message, destination, structured data, offer record, form or checkout, confirmation, and exception route as one experience.
    4. Instrument the handoff. Capture the channel, placement type, campaign, asset, offer identifier, destination, qualified action, completed outcome, and any reversal without collecting private conversational content.
    5. Establish a counterfactual. Use a platform experiment or holdout when available. If neither is available, document a stable baseline and state clearly that the result is directional rather than incremental.
    6. Expand only after quality holds. Increase the range of tasks, offers, or creative after the pilot produces accurate offers, acceptable outcomes, and no recurring trust failure.

    Click-through rate can diagnose whether a sponsored option attracts attention, but it cannot tell you whether the AI-assisted decision was good. Define qualification and completion before launch, then measure the handoff with metrics that expose both performance and failure.

    MetricHow to calculate itWhat it helps you decide
    Qualified action rateQualified actions divided by attributed AI ad visitsWhether matching and creative are producing commercially relevant responses
    Offer consistency rateAudited offers whose ad, destination, structured data, and transaction terms agree divided by all audited offersWhether the commercial data is dependable enough to scale
    Decision completion rateConfirmed target outcomes divided by eligible initiated pathsWhether the handoff helps the user finish the intended task
    Outcome quality rateAccepted, retained, or otherwise qualified outcomes divided by completed outcomesWhether apparent conversions remain valuable after validation
    Mismatch or complaint rateRecorded relevance, sponsorship, offer, or transaction complaints divided by attributable interactionsWhether utility is being purchased at the cost of trust
    Incremental outcomeDifference between exposed and valid comparison groupsWhether the channel created value beyond outcomes that would have happened anyway

    Set the definitions, data owner, and decision rule for each metric before anyone sees campaign results. Otherwise, teams tend to relax the meaning of “qualified” or emphasize whichever event improved.

    Pause the affected offer or path when the ad claim is absent from the destination, displayed terms disagree with checkout, inventory cannot be confirmed, users mistake sponsorship for an independent answer, or additional conversions arrive with a corresponding rise in reversals, refunds, or disqualified leads. These are not creative-learning signals. They indicate that the experience is making a promise the operating system cannot reliably keep.

    Key takeaways

    • Plan AI advertising around a user’s decision task, not merely a keyword, audience, or placement.
    • Treat answer readiness, offer accuracy, and transaction reliability as separate layers with named owners.
    • Keep sponsored delivery visibly separate from model answers and report paid exposure separately from organic AI visibility.
    • Use structured data to clarify visible facts, never to introduce claims or terms that the page does not support.
    • Measure qualified outcomes, offer consistency, completion, and trust failures alongside attention metrics.
    • Scale only after the entire path can preserve context, honor the offer, and handle exceptions safely.

    Your first move does not need to be a large media commitment. Choose a commercially important decision, make its facts and offer machine-readable, connect it to a dependable action, and define the conditions that will stop the campaign. That foundation will remain useful as AI ad formats, matching systems, and agentic purchase paths continue to change.
    References

  • How to Measure AI Search Visibility, Citations, and Impact

    How to Measure AI Search Visibility, Citations, and Impact

    Your AI search work may be succeeding before GA4 shows a single new session. A model can mention your brand, use your page to support an answer, or influence a decision without sending a measurable click.

    That does not make AI search unmeasurable. It means you need to separate visibility, citations, visits, agent access, and business outcomes instead of forcing them into one traffic report. Here is a practical measurement system you can build with a controlled prompt set, answer-level observations, analytics, search-console data, and server logs.

    Stop asking GA4 to answer a visibility question

    GA4 begins measuring after a browser reaches your site and its tracking code runs. AI discovery begins earlier. Your brand may be considered, described, recommended, or cited inside an answer before the user has any reason to click.

    This creates five distinct measurement layers. Keep them separate because each answers a different question:

    LayerQuestionBest evidenceCommon misreading
    VisibilityDoes the answer mention your brand, product, expert, or content?Tracked prompt responsesNo referral traffic means no visibility
    CitationDoes the answer link to or identify a page supporting its claims?Answer citations and cited URLsEvery citation produces a click
    VisitDid a person arrive from a detectable AI surface?GA4 referral and landing-page dataRecorded referrals represent all AI-influenced visits
    Agent accessDid an AI crawler or agent request the content or attempt a journey?Server and CDN logsA bot request is a human visit or recommendation
    OutcomeDid discovery contribute to demand, leads, sales, or another business result?Analytics, CRM, commerce, and brand-demand indicatorsA later conversion can always be assigned to one answer

    A citation is therefore not a visit, and a visit is not automatically a conversion. Likewise, an unclicked mention can still shape a shortlist. Many AI outputs cannot be identified cleanly in conventional web analytics, so GA4 is an important lower-funnel view rather than a complete AI visibility ledger.

    Do not collapse the five layers into a single proprietary score. A blended score can rise while a commercially important component falls. Report each layer independently, then explain how the pattern changed.

    Build a repeatable prompt and citation benchmark

    Identical glowing tokens pass through three parallel answer chambers that produce varying answer shapes and source markers.

    You cannot measure visibility from a handful of prompts chosen after seeing the answers. Start with a versioned prompt set that represents the decisions your audience actually makes. The purpose is not to recreate every possible query. It is to hold a useful sample steady long enough to detect change.

    1. Define the decision space. Group prompts by category discovery, problem and solution, use case, comparison, validation, and branded support. Include prompts where your brand could reasonably qualify, not prompts engineered to force a mention.
    2. Record the conditions. Save the exact prompt, AI surface, available model or mode, language, location context, account state, date, and run identifier. If any condition is unknown, label it unknown instead of filling the gap.
    3. Repeat the same prompts. AI answers can vary between runs. Use the same collection cadence and the same number of repeats in each reporting period. A single response is an observation, not a stable rank.
    4. Archive the evidence. Preserve the answer text or a permitted capture, the brand language, cited URLs, citation labels, and the claims each citation appears to support. A dashboard total without the underlying answers cannot be audited.
    5. Version intentional changes. When you add, remove, or rewrite prompts, create a new prompt-set version. Do not silently alter the denominator and then compare the new rate with the old one.

    Before collecting results, define what counts as a mention. Decide whether product names, parent companies, abbreviations, people, and misspellings qualify. Also distinguish a substantive recommendation from an incidental appearance in a long list. Apply the same rule to competitors.

    Your core metrics can remain simple:

    • Brand visibility rate: prompt runs containing a qualifying brand mention divided by eligible prompt runs.
    • Owned citation rate: prompt runs citing at least one URL on a domain you control divided by eligible prompt runs.
    • Mention-to-citation rate: brand-visible runs that also cite an owned URL divided by all brand-visible runs.
    • Share of voice: your qualifying mentions divided by all qualifying mentions across the tracked brands. State whether multiple mentions in one answer count once or many times.
    • Citation-domain share: citations from each domain or domain type divided by all citations observed in the tracked responses.
    • Answer accuracy rate: factual brand descriptions classified as accurate divided by all factual brand descriptions reviewed. Keep inaccurate, unsupported, outdated, and ambiguous labels separate so the remedy is clear.

    These denominators matter. Citation rate among mentions tells you whether your brand is being substantiated when it appears. Citation rate across all eligible prompts tells you how much of the overall decision space your owned content occupies. Both are useful, but they are not interchangeable.

    Segment the results by prompt family and AI surface before reading the total. Strong visibility on branded support questions can conceal absence from category-discovery and comparison answers, where new demand is being shaped.

    Instrument visits, search traces, and agent requests

    Separate pathways for a human visitor, a branching search trace, and machine-like request packets pass through sensors into an analysis hub.

    Use GA4 for detectable visits and on-site behavior

    Create a GA4 exploration or reporting group for AI referrals. Build its hostname pattern from referrers you have actually observed, document every hostname included, and review that list as platforms change. A copied universal regex becomes unreliable when hostnames, apps, and redirect behavior change.

    For each detectable AI session, retain the session source or referrer, landing page, device context, engagement, next page, and business outcome. Compare landing-page intent with the action available there. A person arriving from a detailed recommendation may need proof, pricing context, availability, or a clear next step rather than another generic introduction.

    Label the result honestly as detectable AI referral traffic. Do not rename it total AI traffic. Answers can omit links, apps can suppress referrers, and later visits can arrive through direct, search, or another channel. Those gaps prevent GA4 from serving as a complete exposure count.

    Treat search-console signals as directional

    Google Search Console and Bing Webmaster Tools remain useful for queries, pages, impressions, and clicks, but their reporting can combine AI-related activity with conventional search activity. They do not provide a clean answer-level visibility report.

    You can create a regex segment for conversational queries and compare its pages and trends with your tracked prompt themes. Use that segment to find content opportunities, not to declare an exact count of AI searches. Human queries can be conversational, while AI-mediated discovery can begin with short terms. Query shape is a clue, not proof of origin.

    Use logs to see requests analytics cannot execute

    Some AI agents use text-oriented clients that request pages without running browser analytics. Their activity may therefore appear in origin, CDN, or edge logs while remaining absent from GA4. Following agent request paths toward conversion pages can expose blocked resources, redirect loops, error responses, inaccessible forms, and journeys that depend entirely on client-side behavior.

    For relevant requests, retain the timestamp, requested path, response status, user-agent claim, referring path when available, and the sequence of requested URLs. Verify bot identities using the platform operator’s current documentation before classifying them. A user-agent string alone can be copied.

    Keep crawler activity out of human traffic and conversion totals. The useful questions are whether important content can be reached, whether the server returns the intended version, and whether an agent encounters a broken path. Request volume by itself does not demonstrate visibility, citation, or commercial influence.

    Make each section extractable without chasing pixel position

    Moving every important sentence above the fold is not a credible AI citation strategy. A SALT.agency analysis of 2,318 URLs cited by Google AI Mode found no relationship between vertical pixel depth and citation selection. Cited passages appeared throughout pages, including far below the initial viewport.

    That result is limited to the analyzed sample and does not prove that layout never matters for users or crawling. It does undercut the claim that citation eligibility depends on putting all answer text near the top. The more useful unit of optimization is the section, not the screen position.

    The same analysis observed a recurring pattern in which a subheading and the sentence immediately following it were highlighted. Use that as a structural clue, not a guaranteed template:

    • Write a descriptive subheading that states the question, distinction, or decision covered by the section.
    • Answer the subheading in the first sentence. Do not make the reader cross several paragraphs of scene-setting before reaching the claim.
    • Include the entity, condition, or scope needed to understand the sentence when it is separated from the rest of the page.
    • Put supporting detail, limitations, examples, and evidence immediately after the direct answer.
    • Use stable links and descriptive page titles so a citation leads to the expected content.
    • Update or remove conflicting claims elsewhere on the site. Clear formatting cannot repair contradictory facts.

    Run a simple fragment test during editing: copy only the subheading and its first two sentences into a blank document. If the passage becomes vague, loses its subject, or overstates the conclusion without its caveat, rewrite it so the fragment can stand on its own.

    Structured data belongs in this system, but it is not a citation switch. Use applicable JSON-LD to express facts already visible on the page and keep the markup consistent with the rendered content. Do not add unsupported attributes merely because you want a model to repeat them. Clear page content remains the claim a person can inspect.

    Your citation inventory should also cover domains you do not own. Classify every observed citation as owned, competitor, publisher, reference, marketplace, or community. The category distribution tells you where the answer engine currently finds persuasive evidence.

    Community visibility deserves its own line in that inventory. Reddit reported more than 80 million weekly search users, up from 60 million a year earlier, while Reddit Answers grew from 1 million to 15 million queries over the year. That scale reinforces a practical point: your owned website is only one surface where buyers investigate products, trade-offs, and lived experience.

    If community discussions repeatedly supply the evidence for your category, do not respond by manufacturing praise or seeding disguised promotions. Identify the unanswered questions, improve the information on your site, and participate transparently where you can contribute something specific. Measure whether the quality and accuracy of brand representation improves, not merely whether the brand name appears more often.

    Turn measurement patterns into specific decisions

    The dashboard earns its keep when each pattern has an owner and a next action. Use the combinations below as diagnoses to investigate, not automatic declarations of cause:

    • Visibility is low while competitors are cited. Compare the cited pages with your coverage. Look for missing decision criteria, weak entity clarity, unsupported claims, or topics for which you have no suitable page.
    • Visibility is high but owned citation rate is low. The systems recognize the brand but rely on other domains to explain it. Review which claims third parties support, whether an authoritative owned page exists, and whether that page states the facts in extractable sections.
    • Owned citations rise but referral traffic stays flat. Inspect answer context before calling the work ineffective. The answer may satisfy the immediate question without a click. Track citation relevance, branded demand, direct visits, and later outcomes as corroborating signals, without presenting correlation as attribution.
    • AI referral traffic rises but outcomes do not. Segment by landing page and prompt intent. Repair the message match, missing proof, unclear next step, or technical failure on the post-click journey.
    • Agent requests reach content but fail before key pages. Inspect status codes, redirects, rendering dependencies, robots controls, and form accessibility. Do not interpret the requests as human sessions.
    • Mentions rise while accuracy falls. Prioritize correction over reach. Locate the repeated error, align owned facts across pages and markup, and document inaccurate outputs so you can test whether later responses change.

    When you make a material optimization, annotate the release date and the affected prompt family. Compare the changed group with an unchanged group over the same collection windows. If only the changed group improves, the result is more informative than a sitewide before-and-after comparison, although model and index changes still prevent a casual claim of causation.

    Your recurring report should show the prompt-set version, collection conditions, sample size, visibility rate, owned citation rate, citation-domain mix, accuracy labels, detectable referrals, on-site outcomes, agent access issues, and changes shipped. Add several answer examples beside the totals. Stakeholders need to see whether a percentage change represents a prominent recommendation, a passing mention, or an irrelevant citation.

    Key takeaways

    • Measure AI search as separate visibility, citation, visit, agent-access, and outcome layers.
    • Use a fixed, versioned prompt set and preserve the conditions and evidence for every run.
    • Call GA4 results detectable AI referrals, not total AI influence.
    • Optimize self-contained sections and direct answers; do not force all useful content above the fold.
    • Classify third-party citations because AI visibility is shaped beyond your owned domain.
    • Connect every reporting pattern to a content, technical, reputation, or journey decision.

    Start with one commercially important topic, freeze its prompt set, and collect the first answer-level baseline before changing content. Once that baseline can be audited from prompt to outcome, expand the system one topic at a time. You will learn more from a small measurement loop you trust than from a large visibility score nobody can explain.

    References

  • Why Stable Local Rankings No Longer Guarantee Engagement

    Why Stable Local Rankings No Longer Guarantee Engagement

    Your map-pack position has not moved, yet calls and website visits are down. Before you blame demand, seasonality, or your sales team, inspect the result customers actually saw. An AI-generated local answer may have shortened the list, substituted different businesses, or removed the call and website controls that once turned visibility into action.

    Your local search program now has to answer four separate questions: Was your business available to the search system? Was it included in the result? Could the searcher act from that result? Did the interaction become a lead or customer? A ranking report answers only part of the second question. Here is how to measure and improve the rest of the funnel.

    A stable rank can conceal a smaller conversion opportunity

    The traditional local pack gave businesses a familiar bargain: earn a prominent position and receive a visible route to a phone call, website visit, or direction request. AI local results change both sides of that bargain. They can show fewer businesses, choose a different set of businesses, and present a generated explanation without the action buttons attached to a conventional listing.

    The reduction is not merely theoretical. Sterling Sky’s 2026 market analysis found that AI local packs surfaced only 32% as many unique businesses as traditional map packs. The total number of visible businesses fell in 88% of the 322 markets examined. That does not establish an identical loss for every industry or location, but it shows why a business can retain its conventional rank while losing exposure in the interface customers increasingly encounter.

    Advertising adds another layer. Sponsored listings, Local Services Ads, and expanded Google Ads units can occupy space around or inside local results. In some layouts, organic listings lose their direct call or website controls even when the businesses themselves remain visible. Your listing can therefore register an impression without offering the same conversion opportunity that an impression used to represent.

    This is the practical meaning of zero-click local search. It does not always mean that the searcher received no value or that your business received no exposure. It means the result may satisfy part of the decision journey inside Google while giving you less traffic, less interaction data, and fewer immediate actions.

    Key takeaways

    • A traditional map-pack rank measures one result type, not your visibility across AI answers, paid local units, and other discovery surfaces.
    • Track inclusion and actionability separately. Being named in an AI answer is not equivalent to receiving a call button or website link.
    • Treat a decline in actions per impression as a funnel diagnosis problem before treating it as a ranking problem.
    • Audit business identity, primary category, services, and real-world positioning before investing in another round of authority building.
    • Use paid local search to fill a verified conversion gap, then judge it by qualified outcomes rather than the visibility it buys.

    Build a scorecard around the local search funnel

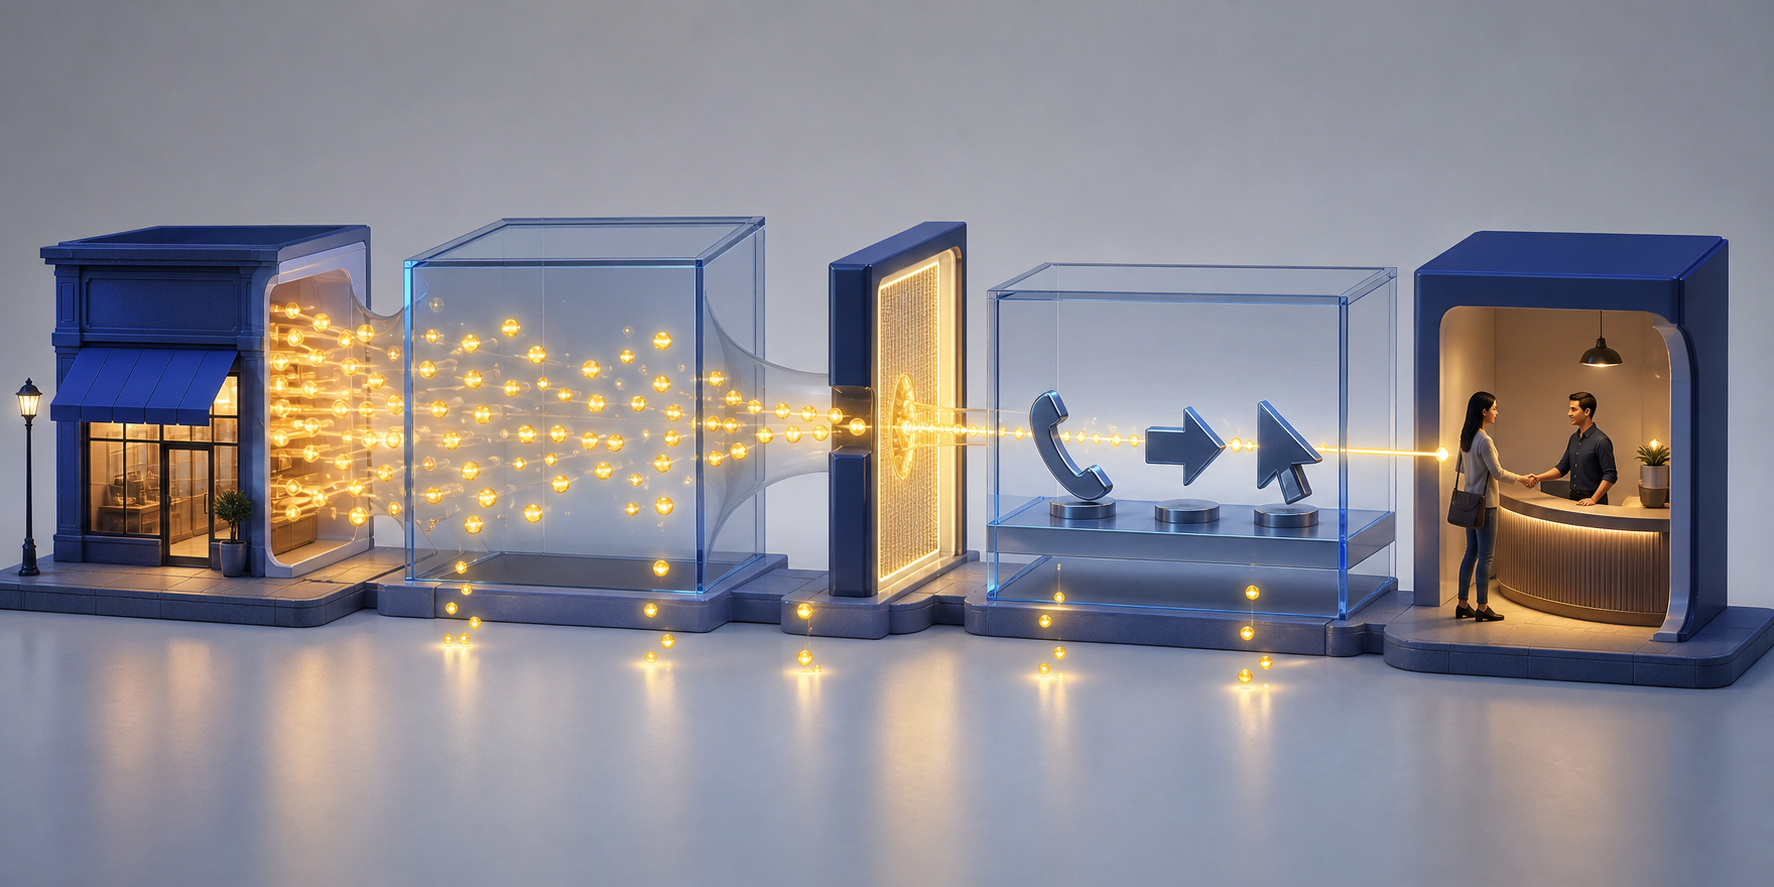
    A storefront signal moves through four connected stages, with some signals dropping away before a customer reaches a business reception desk.

    Start by retiring the idea that one visibility number can describe local performance. A useful scorecard separates availability, inclusion, actionability, and outcomes. This distinction prevents you from applying the wrong fix to the wrong failure.

    What you observeWhat it may meanWhat to inspect next
    Traditional rank is stable, but calls and website visits fallThe visible surface or its action controls changedCapture the actual results, including AI packs, ads, and the presence of call, website, booking, and direction controls
    Your business appears in the traditional pack but not the AI local answerYou may have an eligibility, classification, or corroboration gapCompare your business name, primary category, services, local pages, structured data, and third-party descriptions
    Your business is mentioned by AI, but no direct action followsYou have exposure without an immediate conversion pathCheck whether the result links to your site or profile, then strengthen owned conversion paths and evaluate paid coverage
    Impressions remain steady while the action rate declinesThe denominator may include less actionable exposureReview calls, clicks, bookings, and direction requests independently instead of treating impressions as visits
    Both impressions and actions move sharplyDemand, seasonality, tracking issues, campaigns, or interface changes may be interactingAnnotate known platform issues and paid activity before assigning the movement to SEO

    Build the scorecard from a fixed set of commercially important service-and-location queries. For each query, record which surface appears, which businesses are included, how each business is described, and which action controls are available. Keep the location, device context, and query wording consistent when comparing observations. A national rank scan cannot represent what a customer sees from a particular service area.

    Add an AI inclusion measure alongside your conventional rank: the share of sampled AI local answers in which the business appears. Label it as a sampled visibility metric, not an official Google ranking. Also record the context of the mention. A recommendation for your core service is materially different from a passing mention or an appearance for a service you do not provide.

    For engagement, calculate a diagnostic action rate by dividing recorded profile actions by impressions, while preserving calls, website clicks, bookings, and direction requests as separate lines. This rate is not a perfect conversion metric. AI-generated mentions can count as impressions even when they do not produce the familiar listing actions, and current reporting does not cleanly separate every organic, paid, and AI exposure. Its value is diagnostic: it tells you when the relationship between exposure and action has changed.

    Do not stop at Google Business Profile data. Connect tagged website visits, call records, booking completions, form submissions, and qualified leads wherever your systems permit. A call count tells you whether the interface generated activity. A qualified-lead count tells you whether that activity was commercially useful. Preserve both because a campaign can raise calls while lowering lead quality.

    Annotate the scorecard when advertising changes, tracking fails, an API issue is known, or seasonal demand moves. U.S. action trends have been less stable than trends in markets exposed to fewer search-interface experiments, which supports investigating result-format changes without proving they caused every decline. An annotation keeps a coincidental movement from becoming an expensive SEO diagnosis.

    Fix AI eligibility before chasing another ranking gain

    Traditional local SEO asks how strongly a business competes on proximity, relevance, prominence, reviews, citations, and engagement. AI-mediated local search adds an earlier gate: whether the system considers the business an appropriate candidate for the specific request.

    This is the difference between ranking and eligibility. A ranking problem means the system understands what you are and prefers another eligible business. An eligibility problem means the system may not place you in the candidate set at all. More links or reviews will not reliably solve a classification mismatch.

    Run the eligibility audit in this order:

    1. Write the real-world promise in one sentence. State what the location actually does, for whom, and where. Use this as the control statement against which every profile, page, and citation is checked.
    2. Verify the business name. It should represent the name used in the real world, not a string expanded with services or locations for ranking purposes. A manipulated name may create inconsistency instead of clarity.
    3. Reassess the primary category. Choose the category that best describes the location’s main operation. Do not use an aspirational category simply because it matches a valuable query.
    4. Reconcile services with operations. The profile service list, local landing page, navigation, visual assets, and customer-facing language should agree about what the location provides. Remove stale services and add real services that are missing.
    5. Check location boundaries. Make the address, service area, hours, and availability claims consistent wherever they appear. Do not imply a staffed location or service footprint that does not exist.
    6. Inspect the machine-readable version. LocalBusiness JSON-LD should mirror the visible page and the verified business facts. Use the most specific accurate business type available, and keep core properties such as name, URL, telephone, address, opening hours, and service information aligned with the customer-facing content.
    7. Retest the query set. Separate queries where you are absent from queries where you appear but rank poorly. The first group remains an eligibility investigation; the second can move into competitive ranking work.

    Structured data is a consistency mechanism, not a way to manufacture eligibility. Marking up a service that the location does not visibly offer creates another contradiction. The same principle applies to categories and landing pages: describe the operation precisely before trying to make it look broader.

    This audit matters because business name, primary category, and real-world service positioning can influence inclusion in AI local results. When strong traditional performance coexists with repeated AI exclusion, inspect those signals before concluding that you need more generic authority.

    Give AI systems corroborating local evidence

    Glowing map, photo, calendar, review, and route symbols connect a neighborhood shop to a translucent AI prism and a mobile search surface.

    Your Google Business Profile is still central, but it is no longer the whole representation of your business. AI systems encounter business facts and reputation signals across maps, directories, review platforms, community discussions, social channels, and your own site. If those descriptions disagree, the system has to decide which version is trustworthy.

    Data freshness is therefore a visibility issue, not an administrative detail. When local records stagnate, AI systems can reproduce inconsistencies and reduce a brand’s control over how each location is represented. Correcting Google while leaving Apple Maps, Yelp, Tripadvisor, local directories, and important niche platforms untouched leaves the underlying ambiguity in place.

    Create one governed record for each location. It should hold the approved name, address or service area, phone number, URL, hours, primary category, secondary categories, active services, accessibility details, and a short factual description. Give local operators a defined way to report temporary hours, moves, closures, and service changes. Central control protects identity; local input keeps the record true.

    Then audit the places that can independently corroborate that record:

    • Major map and review ecosystems: correct identity and operational facts, resolve duplicate listings, and update stale categories or hours.
    • Industry and local directories: prioritize sources that customers in the market genuinely use rather than creating large volumes of low-value listings.
    • Community references: earn accurate mentions through real associations, events, partnerships, sponsorships, customer recommendations, and local coverage. Do not manufacture forum conversations or undisclosed endorsements.
    • Owned location pages: include the services, service boundaries, hours, contact route, local proof, and useful answers that belong to that specific location. Avoid pages that differ only by a place name.
    • Reviews and responses: monitor whether customer language reflects the services and experience you actually want associated with the location. Respond to factual problems and operational changes rather than inserting target phrases into every reply.
    • Photos and video: publish current, high-quality visuals that show the premises, team, equipment, products, or service process when those elements are relevant and safe to display. Visuals should provide evidence, not decorative stock imagery.

    Fresh visual material deserves special attention because AI systems can use photos and video as clues about services, intent, and business classification. A profile categorized one way but illustrated with unrelated or outdated imagery sends a weaker signal than a profile whose words and visuals describe the same real operation.

    Local publishing can expand discovery beyond the immediate map result. Google’s February 2026 Discover update was designed to favor more locally relevant recommendations, reduce sensationalism, and elevate original, in-depth work from sites with subject expertise. Discover is not a substitute for map visibility, but it creates another reason to publish genuinely local expertise instead of thin service-and-city permutations.

    Useful local content answers questions that arise before and after the initial business search: service limitations, preparation, availability, local conditions, the decision process, and what happens next. Assign the content to someone who understands the location’s work. A central team can supply structure and quality controls, but it should not invent local facts on the location’s behalf.

    Recover the next customer action on every surface

    Eligibility gets you considered. Corroboration makes you easier to trust. Neither guarantees that the result will contain a usable conversion control. You still need a plan for the next action when Google changes the interface.

    Start with the result itself. For every priority query, note whether the searcher can call, visit the site, request directions, book, or continue into another Google experience. If the business is visible but the intended action is missing, classify that as an actionability gap. Do not send the SEO team looking for a ranking fix when the interface is the constraint.

    Strengthen the paths you control. A location page should make the phone number, booking route, hours, service area, and next step easy to find. It should also answer the deeper questions that remain after a generated summary. That matters because AI Mode queries are about three times longer than traditional searches, frequently lead to follow-up questions, and use voice or images in nearly one in six cases. Customers are increasingly expressing the full situation, not merely typing a category and city.

    Organize content around those fuller decisions. Explain which needs the location handles, which it does not, where service is available, what information a customer should have ready, and which contact route fits the request. Use direct language that can be understood in a conversational answer. Do not bury a crucial eligibility or booking condition in promotional copy.

    Paid local search becomes a tactical option when a high-value organic result repeatedly lacks the call or website control you need. Test Local Services Ads or another appropriate paid format against the specific gap you observed. Set a controlled budget, separate paid calls from organic calls where measurement permits, and evaluate qualified leads, booked work, and acquisition cost. Buying back a prominent button is useful only when the resulting customers justify the spend.

    Do not assume every location needs permanent paid coverage. A location that already receives actionable organic visibility may gain little from paying for duplicate exposure, while a location pushed below ads or stripped of direct controls may have a clearer case. The decision belongs in the scorecard: interface gap, paid coverage, qualified outcome, and cost.

    For a multi-location organization, review performance at the location level before rolling out a network-wide response. AI inclusion, ad pressure, community signals, demand, and conversion economics can differ by market. Use central standards for data, schema, measurement, and brand identity, then let each location supply the facts, media, relationships, and service detail that make its local evidence genuine.

    Begin with one priority query and trace it from result format to qualified outcome. Record whether the location was eligible, included, actionable, and commercially successful. Once that chain is visible, you can fix the actual break instead of defending a rank that no longer guarantees the engagement you need.

    References

  • Publisher Controls for Google AI Overviews and AI Mode

    Publisher Controls for Google AI Overviews and AI Mode

    You have a decision to prepare for, but not yet a reliable switch to flip. Google has discussed letting publishers opt out of AI Overviews and AI Mode, yet it has not disclosed a clear, feature-specific implementation. Adding a guessed crawler rule or sitewide directive now could affect more than the AI feature you meant to control.

    Do the policy work first. Decide which content you would exclude, what outcome would justify exclusion, how you would detect collateral damage, and what would trigger a rollback. Then, if Google releases a documented control, you can test it as an operating decision instead of reacting with a blanket yes or no.

    The opt-out question is ahead of the actual control

    Google has been exploring ways for websites to opt out of AI-generated search features. What publishers still need is the operational detail: whether a control would apply to AI Overviews, AI Mode, or both; whether it could be used on individual URLs or only an entire site; how quickly a change would take effect; and whether it would alter eligibility for traditional search.

    Until those questions have documented answers, nobody can responsibly give you an exact implementation recipe. A directive intended for an AI training crawler is not automatically a control for an AI-generated search result. A general search restriction is not automatically limited to AI. The names may sound related, but the scope and business consequences are different.

    Publishers are already divided on the underlying choice. In an X poll with more than 350 responses, 33.2% said they would block Google, 41.9% said they would not, and 24.9% were unsure. Treat that as evidence of a real strategic disagreement, not as a representative estimate of the entire publishing market.

    The disagreement makes sense because “block AI” is not a business objective. One publisher may prioritize broad discovery. Another may place more value on controlling the reuse of expensive original work. A third may want visibility in AI results but only when those appearances send qualified readers or reinforce the brand. You cannot resolve those positions with a technical toggle alone.

    Keep three decisions separate in every internal discussion:

    • AI training access: whether a named crawler may collect content for a training-related purpose.
    • Traditional search access: whether Google can crawl, index, and present a page in established search results.
    • AI search presentation: whether content can contribute to or appear in AI Overviews and AI Mode.

    That distinction matters because 79% of nearly 100 leading UK and US news websites were blocking at least one AI training crawler. That shows publishers are actively managing training access. It does not establish that the same sites have opted out of Google AI search features, or that a training-crawler block would produce that result.

    Build the policy around content classes, not one domain-wide answer

    Different types of unlabeled publishing materials are sorted into compartments and routed separately toward or away from an abstract AI portal.

    A sitewide decision is simple to announce and difficult to evaluate. Your domain probably contains pages with different economics and different jobs: original reporting, evergreen reference material, product or service pages, subscriber content, documentation, archives, and pages built primarily to acquire search visitors. A future control may or may not support URL-level rules, but your policy should be ready for that possibility.

    Create an inventory by template or content class. You do not need to classify every URL manually. Start with the groups that account for most of your search traffic, revenue, subscriptions, leads, or editorial investment.

    1. Name the page class. Use a stable label such as original news, analysis, evergreen guide, product page, documentation, archive, or subscriber-only content.
    2. State its primary job. Choose one: attract new readers, convert demand, retain subscribers, establish authority, support customers, or generate direct revenue.
    3. Record its dependency on Google discovery. Use your own impressions, clicks, landing sessions, conversions, and revenue rather than an editorial assumption.
    4. Identify the use you want to control. Say “AI Overviews and AI Mode” if that is the target. Do not write only “AI,” because that leaves training, search presentation, and other uses mixed together.
    5. Assign a provisional status: allow, exclude when a verified control exists, or include in the first test.
    6. Name the owner who can approve implementation and the owner who can order a rollback.

    The three provisional statuses keep uncertainty visible without forcing a premature technical change:

    • Allow: discovery is the dominant objective, so the current state remains in place unless measured harm changes the decision.
    • Exclude when possible: the content conflicts with a declared reuse or rights policy, but implementation waits for a documented control whose scope is understood.
    • Test: the trade-off is uncertain, so the content becomes a candidate for a limited, reversible experiment.

    Add the reason beside every status. “Editorial leadership requested it” is an approval trail, not a decision rule. A usable reason sounds like this: “These pages depend on search acquisition, so exclusion will be retained only if targeted AI use declines without pushing qualified organic visits or conversions below our predeclared guardrails.”

    If Google ultimately offers only a domain-wide setting, your classification work still matters. It shows which page groups carry the benefit and which carry the cost. That gives leadership a defensible basis for accepting or rejecting the broader control.

    Decide what success and failure look like before changing anything

    A publisher test fails when the team changes a setting first and chooses the interpretation later. Traffic can move for many reasons. If your success criteria remain unwritten, almost any result can be used to defend the decision someone already preferred.

    Build a measurement sheet with four layers:

    • Business outcome: qualified leads, purchases, subscriptions, advertising value, or another result tied to the selected page class.
    • Search referral outcome: impressions, clicks, click-through rate, landing sessions, and the queries sending those visits.
    • AI feature observation: whether the chosen URLs or brand appear for a fixed set of queries in AI Overviews or AI Mode.
    • Technical guardrails: continued crawling, indexation, and appearance in the traditional search surfaces you intended to preserve.

    Do not assume your normal analytics can isolate every AI feature appearance. If they cannot, create a manual observation set. Select queries before the test, record the page and feature being checked, keep the location, account state, and device conditions as consistent as practical, and save dated evidence. The purpose is not to estimate all AI visibility from a small sample. It is to check whether the behavior of known query-URL pairs changed after the control.

    Use queries where the page had previously appeared in the targeted feature whenever possible. If an AI Overview does not appear for a query on a later check, that single absence does not prove the exclusion worked; the feature itself may not have appeared. Verification needs to distinguish “the feature was present without our content” from “the feature was not present at all.”

    Write the retention rule in advance. A practical template is:

    We will retain exclusion for [content class] only if the targeted use declines in our logged sample, organic search outcomes remain above our chosen floor, the primary business metric stays within its guardrail, and traditional search eligibility shows no unintended change.

    Publisher decision template

    Choose the floors from your own historical volatility and business tolerance. There is no credible universal percentage that tells every publisher when loss of reach is worth greater content control. A subscription publisher, a lead-generation site, and an advertising-funded newsroom can assign very different values to the same traffic movement.

    Test a documented control with the smallest reversible scope

    A single article tile is tested in a transparent chamber while an operator monitors indicator lights beside a rollback lever.

    When Google publishes an actual control, verify what it governs before deploying it. The label is not enough. Read for its target feature, supported scope, interaction with traditional search, activation behavior, verification method, and rollback procedure. If the documentation does not answer one of those questions, record it as an unresolved risk rather than filling the gap with an assumption.

    Then run the test in this order:

    1. Choose a narrow cohort. Prefer one content class or template over the entire site when the documented control permits it.
    2. Select a comparison cohort. Match pages as closely as practical on purpose, query demand, historical performance, update pattern, and publication timing.
    3. Capture a baseline. Include a period that reflects your normal publishing or business cycle, and note promotions, seasonal events, migrations, algorithm changes, or major editorial updates that could distort it.
    4. Freeze avoidable confounders. Do not simultaneously rewrite titles, change internal links, redesign templates, or move URLs unless those changes are part of the test.
    5. Apply one documented control. Log the exact setting, scope, time, implementer, approver, and expected outcome.
    6. Verify the target behavior. Check the tracked query-URL pairs and confirm that any observed change concerns AI Overviews or AI Mode rather than a broader loss of search access.
    7. Compare business results and guardrails. Use the predeclared rule, not a newly chosen metric that happens to support the preferred conclusion.
    8. Roll back if the blast radius is larger than intended. Preserve the implementation log so the team can separate recovery from later unrelated changes.

    If the control is sitewide only, you lose the cleanest form of an internal comparison. Do not pretend a before-and-after chart proves causation. Keep a dated change log, use the same tracked query set, document concurrent events, and require stronger evidence before making the setting permanent.

    Operational cost belongs in the result as well. A page-level control that must be maintained across several publishing systems creates a different burden from a stable sitewide setting. Record implementation time, quality-assurance failures, ownership gaps, and rollback effort. A policy that cannot be maintained reliably is not an effective control, even when its strategic intent is sound.

    Key takeaways

    • Google has discussed publisher opt-outs for AI Overviews and AI Mode, but a clear feature-specific implementation has not been established here.
    • Blocking an AI training crawler is not the same as opting out of an AI-generated search feature.
    • Classify content by business purpose and Google dependency before choosing allow, exclude, or test.
    • Predeclare the target behavior, primary business metric, search guardrails, technical checks, and rollback condition.
    • When a documented control arrives, begin with the smallest reversible cohort its scope permits.

    Your useful next step is a one-page control brief, not a speculative configuration change. Assign an owner, classify the page groups that matter, capture their baseline, and list the documentation questions Google must answer. When a real control becomes available, you will be ready to evaluate it with evidence instead of making a domain-wide bet under deadline pressure.

    References

  • Publisher Opt-Outs From Google AI Search: A Practical Plan

    Publisher Opt-Outs From Google AI Search: A Practical Plan

    You want Google Search to keep finding your work, but you may not want that work used to produce answers in AI Overviews or AI Mode. The problem is that changing the wrong control could limit ordinary Search visibility without giving you the AI-specific choice you intended.

    Don’t add a guessed directive or treat every Google AI control as interchangeable. Google has confirmed that it is exploring updates that would let sites opt out of Search generative AI features, but it did not provide a launch date, directive name, implementation syntax, or final description of the consequences. Your useful work now is to separate the controls, define your decision criteria, and prepare a reversible rollout.

    The proposed opt-out is not an implementation instruction

    Google identified AI Overviews and AI Mode as the Search generative experiences at issue. It also said any new publisher control must preserve the usefulness of core Search and avoid creating a fragmented or confusing experience. That tells you why the problem is difficult, but not how the eventual mechanism will behave.

    Until Google publishes the actual specification, nobody can responsibly tell you what token to add, whether the setting will work at the domain, directory, or page level, how quickly a change will take effect, or whether opting out will alter links, previews, rankings, or eligibility elsewhere in Search. Those are unresolved product questions, not details you should fill in by analogy.

    Key takeaways

    • Google is exploring a dedicated opt-out for Search generative features; the disclosed proposal did not include deployable syntax or a release date.
    • Google-Extended addresses how site content helps train Gemini models. It should not be treated as a confirmed AI Overviews or AI Mode opt-out.
    • Robots controls, preview controls, model-training controls, and Search generative controls answer different questions.
    • Do not precommit to opting in or out until you know the final control’s scope and its relationship with ordinary Google Search.
    • Prepare an inventory, measurement baseline, approval owner, and rollback plan before the mechanism arrives.

    Separate four control layers before changing anything

    An isometric publishing system sends a page through four separate adjustable gates representing discovery, crawler access, previews, and generative processing.

    The phrase “AI opt-out” is too broad to drive a technical change. It can refer to training a model, generating a search answer, displaying an extract, or accessing a page for core Search. Write down which use you mean before evaluating any directive.

    Control layerWhat Google has describedThe decision it addresses
    Core Search access and appearanceLong-standing publisher controls based on standards such as robots.txtHow Google may access and handle content for ordinary Search
    Search-result presentationControls for Featured Snippets and image previews, which can also be relevant to AI OverviewsHow much content Google may show as a preview or extract
    Gemini model trainingGoogle-ExtendedWhether site content may help train Gemini models
    Search generative useA proposed, not yet specified, opt-out for AI Overviews and AI ModeWhether content may be used in Google’s generative Search experiences

    The most important distinction is between model training and generation at search time. Google discussed Google-Extended as a Gemini training control and then described a separate control under consideration for Search generative features. That separate treatment means the presence of Google-Extended does not establish that a page is excluded from AI Overviews or AI Mode.

    If an audit, policy, or vendor report labels your site “opted out of Google AI” solely because Google-Extended is present, ask for product-specific evidence. The accurate statement is narrower: the setting concerns Gemini training. Keep the Search generative status marked as unresolved until Google publishes a dedicated mechanism and its scope.

    Structured data is separate as well. Schema markup helps machines interpret entities, attributes, and relationships on a page; it is not a consent or exclusion directive. Continue improving useful structured data for discoverability, but do not represent it internally as a way to grant or deny generative use.

    Decide what you are protecting and what you depend on

    Google’s stated position is that AI Overviews help people discover content and explore more topics. That is the platform’s case for generative Search, not a guarantee that your pages will receive qualified visits, conversions, subscriptions, or revenue. Your decision has to reflect how each part of your publishing business creates value.

    Start with two questions: how important is Google discovery to this content, and how strict is your policy on generative reuse? Those answers may differ across a single domain. A public help center, subscriber analysis, licensed database, product catalog, and evergreen editorial library do not necessarily need the same rule.

    • If discovery is the priority and reuse concerns are limited: do not promise an opt-out in advance. Preserve the current configuration, establish a baseline, and evaluate the documented effects when the control is released.
    • If control is the priority and Search discovery is secondary: prepare the internal approval to opt out, but make deployment conditional on confirmation that the mechanism does what your policy requires.
    • If your content portfolio is mixed: make granularity a go-or-no-go criterion. A path-level or page-level option could support different policies; a domain-wide switch could force a much larger business decision.
    • If you cannot quantify the tradeoff: plan a limited, reversible test if the final mechanism supports one. Do not turn uncertainty into a sitewide default.

    For every content family, record the outcome that matters on your own site: advertising consumption, a lead, a sale, a subscription, a download, account usage, or support deflection. Then record the competing concern: licensing limits, exclusivity, editorial policy, brand representation, or a general preference against generative use. This turns an abstract argument about AI into an explicit operating decision.

    Do not assume that the future opt-out will remove your words from a generated answer while preserving a citation, or that it will leave ordinary Search performance untouched. Do not assume the opposite either. Google has said it wants new controls to avoid breaking Search, but the final interaction has not been specified.

    If third-party licenses or contracts limit machine use, have the person responsible for those rights review the final specification before deployment. A technical setting can support a rights policy, but the mere presence of a setting does not establish that contractual obligations have been satisfied.

    Build a publisher decision package before launch

    Four publishing professionals review blank documents, a server model, abstract dashboard shapes, and two color-coded pathways around a meeting table.

    The fastest safe response to a new control will come from work that does not depend on its syntax. Build one compact decision package now so your SEO, editorial, legal, product, and engineering teams are not debating first principles after a release.

    1. Assign one accountable owner. Name the person who will confirm the final documentation, collect stakeholder approval, authorize production changes, and own rollback. Consultation can be broad; deployment authority should not be ambiguous.
    2. Inventory content by policy-relevant group. Use hostnames, directories, templates, or content types rather than starting with individual URLs. Record the business owner, discovery goal, onsite outcome, third-party rights, and desired AI policy for each group.
    3. Document the controls already in production. Capture your current robots.txt rules, Featured Snippet and image-preview choices, Google-Extended configuration, relevant page-level directives, and the systems that generate them. Label each control by its actual purpose.
    4. Save a pre-change baseline. Export organic Search impressions and clicks, important landing-page actions, conversion or subscription outcomes, and a representative record of crawl and index status. Preserve the reporting definitions so the later comparison uses the same measurements.
    5. Write a conditional decision. Use language such as: “Opt out for this section only if the final control covers AI Overviews and AI Mode, supports directory-level scope, and does not remove the section from core Search.” A condition is useful before launch; guessed syntax is not.
    6. Prepare change and rollback records. Your deployment entry should capture the exact directive, affected properties, implementation location, approver, release time, validation result, monitoring owner, and reversal procedure.

    A useful inventory can be a single sheet with columns for hostname, path or template, content owner, revenue or user outcome, Search dependency, rights constraints, existing Google controls, preferred generative policy, required granularity, approver, and rollback owner. The point is not to score every URL. It is to expose where one sitewide setting would combine content with different needs.

    Keep the measurement claim modest. A before-and-after change can show whether important site outcomes moved, but it may not prove that the opt-out caused the movement. Search demand, rankings, publishing volume, and product changes can move at the same time. Log other releases and compare equivalent content groups where the final control makes that possible.

    Require clear answers before production deployment

    When Google releases a control, read its final documentation as a specification. A headline saying that publishers can opt out is not enough. Your owner should be able to answer every question below with product documentation before approving a change.

    • Product coverage: Does the control apply to AI Overviews, AI Mode, or both? Does it cover every content format you publish?
    • Prohibited use: Does it prevent content from contributing to generated text, or does it also change links, citations, extracts, images, and previews?
    • Scope: Can you configure it by domain, subdomain, directory, template, page, or asset?
    • Core Search interaction: What happens to crawling, indexing, ranking eligibility, result links, Featured Snippets, and image previews?
    • Relationship with existing controls: Which rule wins when robots, preview, Google-Extended, page-level, and Search generative settings differ?
    • Processing: How does Google discover a change, how long may processing take, and what happens to content processed before the change?
    • Verification: Is there a testing tool, status report, inspection result, or other way to confirm that Google recognized the setting?
    • Reversibility: How do you restore eligibility, and is restoration processed on the same timetable as exclusion?

    If the mechanism is delivered through robots.txt, validate the public production file rather than only the CMS setting that is supposed to generate it. Check the response status, exact user-agent grouping, syntax, and the version served through your CDN. Confirm that an automated deployment cannot overwrite it. A misplaced rule in robots.txt can affect more than the feature you intended to control.

    If Google uses a page-level meta directive or HTTP response header instead, inspect the server-rendered HTML and live headers across representative templates. Check canonical and alternate versions, cached pages, and any CMS plugin that can emit competing directives. These are conditional validation steps; Google has not specified which delivery method the proposed control will use.

    For now, document your existing settings, correct any internal claim that Google-Extended already excludes AI Overviews, and set a release trigger. When Google publishes the final scope and syntax, your owner can compare them with the decision package, approve a narrow rollout where possible, and monitor the outcomes that matter to your business. Until that trigger is met, the right preparation is governance and measurement, not speculative code.

    References

  • Personal Intelligence in Google AI Mode: An SEO Playbook

    Personal Intelligence in Google AI Mode: An SEO Playbook

    If your AI Mode reporting assumes that every tester should receive the same answer for the same prompt, Personal Intelligence breaks that assumption. Once someone connects personal Google content, a short query can be interpreted through preferences, plans, relationships, places, and interests that were never typed into the search box.

    That does not make AI search visibility immeasurable. It changes what you have to measure. The useful unit is no longer just a query and a URL; it is a query, an account state, a personal context, an answer, and any citations shown with it.

    Key takeaways for SEO and GEO teams

    • Personal Intelligence lets eligible users connect Gmail and Google Photos to AI Mode, with responses potentially drawing on a wider Google context that includes YouTube history.
    • The announced Labs experiment was opt-in and limited to U.S. personal accounts with AI Pro or Ultra access. Workspace business, enterprise, and education accounts were excluded under the launch conditions.
    • Two people can enter the same prompt but present different underlying needs. A single screenshot or rank position therefore cannot represent universal AI Mode visibility.
    • Content should make its suitability explicit: who it serves, which situation it addresses, what constraints apply, and which facts support the recommendation.
    • JSON-LD can clarify entities and relationships already visible on a page, but it should not be treated as a switch that forces personalization or earns an AI Mode citation.

    Confirm access before diagnosing an AI Mode problem

    The announced rollout placed Personal Intelligence inside a Labs experiment. Its launch eligibility was narrow: AI Pro and Ultra subscribers using personal accounts in the United States could opt in, while Workspace business, enterprise, and education users could not. Treat those as experiment launch conditions, not permanent availability rules.

    Availability was being added to eligible subscriber accounts as the rollout progressed, but the personalization feature itself required consent. If the option was available, the manual setup path was:

    1. Open Google Search and select the profile control.
    2. Choose Search personalization.
    3. Open Connected Content Apps.
    4. Connect Workspace and Google Photos.

    The Workspace connector label should not be confused with eligibility for a managed Workspace account. Under the stated experiment rules, the account still had to be personal. The connected experience could use context spanning Gmail, Google Photos, and YouTube history.

    Before treating a missing or inconsistent result as an SEO issue, record the test conditions: personal or managed account, subscription tier, country, Labs access, opt-in state, connected apps, and relevant history settings. If one of those conditions differs, you are not reproducing the same search environment.

    Do not ask employees or clients to expose private email or photo libraries merely to make a test repeatable. Use voluntary participants, collect only the observations needed for the test, and redact screenshots before they enter tickets, presentations, or shared reports. A personalized response can reveal contextual details even when the original prompt looks harmless.

    Measure citation variance, not one universal ranking

    Three researchers test the same blank query on separate computers that show different answer blocks and source tiles.

    Traditional rank tracking works by holding the query and environment as steady as possible. Personal Intelligence introduces an account-level input that an anonymous crawler cannot reproduce. The practical question changes from “Where did this URL rank?” to “Under which observable contexts did this source become useful enough to appear?”

    This matters most for prompts whose answer depends on taste, history, relationships, or current circumstances. The feature’s example uses include family getaway planning, an anniversary scavenger hunt, a child’s bedroom theme, fashion preferences, book recommendations, and other identity-shaped choices. Those are context-sensitive tasks by design, so variation is not automatically a tracking error.

    Test stateWhat it tells youWhat to record
    Personal Intelligence offProvides a non-connected baseline for the exact prompt.Prompt, account eligibility, answer, cited domains, and cited URLs.
    Personal Intelligence on with connected contentShows how the answer changes when personal context is available.Connected-app state, answer differences, recommendations, and citations.
    Personal Intelligence on for another consenting userReveals whether a different context produces a different source set.Only broad, non-sensitive context labels plus the resulting citations.
    Managed Workspace accountChecks whether the test is outside the announced launch eligibility.Account type and whether the feature is present; do not treat absence as a content failure.

    Keep one set of context-sensitive prompts and one control set with little need for personal interpretation. If every result changes, your environment may be unstable. If variation concentrates in planning and recommendation tasks, the pattern is more consistent with personalization doing useful work.

    For each valid test session, log:

    • The exact prompt and any follow-up prompt.
    • Whether Personal Intelligence was available and enabled.
    • Which permitted content connections were active.
    • A short description of the answer’s framing, without copying private details.
    • Every cited domain and URL, including where the citation supported the response.
    • Whether your brand was named without a link, cited with a link, or absent.
    • Whether the cited page actually matched the recommendation or merely supplied a supporting fact.

    Report citation presence as a distribution across valid observations, with the numerator and denominator visible. Do not turn one personalized session into a claim that a site “ranks first in AI Mode.” The accounts are not controlled duplicates, and their histories can differ in ways you cannot inspect or isolate. This is scenario testing, not a clean causal experiment.

    Make public content usable under more personal contexts

    You cannot optimize for the contents of an unknown person’s inbox or photo library. You can make a public page precise enough for an AI system to recognize when it fits a need revealed by that private context. The distinction keeps your strategy grounded: optimize the public evidence and applicability of the page, not the private profile.

    State suitability in language that can be resolved

    Generic superlatives provide little help when an answer must adapt to a specific person. Replace broad claims such as “best getaway for everyone” with explicit conditions: departure area, trip length, transport requirements, activity level, indoor or outdoor emphasis, intended audience, and meaningful limitations. Use only attributes you can substantiate.

    Apply the same discipline outside travel. A book recommendation page can identify themes, reading mood, subject matter, format, and who may not enjoy the selection. A decorating page can separate room size, practical constraints, style, and maintenance needs. The goal is not to create a page for every imagined persona. It is to expose the decision variables already necessary for a good recommendation.

    Build answer blocks around real decisions

    Place the direct answer near the question it resolves. A recommendation should name the option, explain why it fits, state the conditions under which it stops fitting, and link to the evidence or details needed to act. Descriptive headings, concise summaries, comparison criteria, and clearly labeled caveats make the page easier to interpret without stripping away useful depth.

    Separate stable facts from editorial judgment. Opening hours, eligibility, dimensions, compatibility, and included features are different kinds of claims from “ideal for a relaxed weekend” or “better for adventurous readers.” When those claim types blur together, neither a person nor an AI system can easily determine what is verifiable and what is a recommendation.

    Use JSON-LD to confirm the visible page

    Choose the most specific applicable Schema.org types and properties for the entities actually described on the page. Keep names, URLs, authorship, offers, dates, and other marked-up attributes consistent with the visible content. If an important condition matters to the recommendation, explain it in the page copy instead of hiding it in structured data.

    Do not invent audience traits, reviews, ratings, availability, or relationships because they might appear useful to an AI system. Structured data is a machine-readable representation of claims you already publish; it is not a place to manufacture relevance. It can reduce ambiguity, but it does not guarantee inclusion in an AI Mode answer or citation set.

    Strengthen the citation target, not just the topic match

    A page can match a topic yet remain a poor citation target. Make the responsible organization or author identifiable. Show when material was published or materially updated where that timing matters. Define the scope of the recommendation, support consequential claims, and maintain a stable canonical URL. If the useful evidence sits behind an unclear interface or is scattered across unrelated pages, consolidate the answer or create deliberate internal links between its parts.

    Brand consistency matters here as an interpretation problem, not a repetition exercise. Use the same organization, product, location, and author names across visible copy, metadata, structured data, and linked profile pages. Do not solve ambiguity by stuffing variants into every paragraph.

    Run a practical Personal Intelligence visibility cycle

    Five connected workstations form a loop using objects for access checks, context testing, citation review, content editing, and answer comparison.

    A useful operating cycle starts with one decision area where personal context could materially change the answer. Work through it in this order:

    1. Map the decision variables. Identify what would make one recommendation suitable and another unsuitable, such as location, constraints, preferences, timing, compatibility, or intended user.
    2. Create paired prompts. Use the same core request with Personal Intelligence off and on, then include a control prompt that should require little personal interpretation.
    3. Identify your eligible pages before testing. Write down which pages genuinely answer each scenario and why. This prevents you from declaring every absent citation a platform failure.
    4. Test with consenting users who meet the relevant access conditions. Record account and connection states without collecting their underlying messages, images, or sensitive history.
    5. Classify the outcome. Distinguish a direct citation, a supporting citation, an unlinked brand mention, a competitor citation, and no relevant citation.
    6. Inspect the content gap. Check whether the cited page was clearer about suitability, constraints, evidence, entities, or the action a reader should take.
    7. Improve the public page. Add missing decision criteria, clarify unsupported ambiguity, align structured data with visible claims, and strengthen internal paths to the best answer.
    8. Repeat under documented conditions. Keep experiment availability and account state attached to the result so later reports do not compare incompatible environments.

    Avoid three shortcuts. Do not manufacture fake email or photo histories to chase a preferred result. Do not use a personalized screenshot as universal ranking proof. Do not create thin pages for guessed private traits. Each shortcut produces noisy evidence and encourages content that is less useful to the real person making the decision.

    Start with the content cluster where your recommendations depend most on context. Establish the non-connected baseline, run opted-in tests with appropriate consent, and log citation variance alongside the conditions that produced it. The teams that preserve this context will be able to improve their content; the teams that keep reporting a single rank will mostly document contradictions.

    References

  • Gemini Trends and Personal Intelligence: An SEO Workflow

    Gemini Trends and Personal Intelligence: An SEO Workflow

    You have a topic worth covering, but two questions are blocking the brief: which language reflects real search demand, and whether the answer will remain relevant when Gemini knows something about the person asking.

    Google’s Gemini integrations now touch both questions. Gemini in Google Trends can suggest related terms and place them into a trend comparison. Personal Intelligence can use selected information from connected Google apps to shape an individual response. The opportunity is useful, but only if you keep those signals separate: Trends helps you map public demand, while Personal Intelligence introduces private context.

    Treat the integrations as two different signal layers

    The Trends integration is an editorial research tool. You give it a keyword or a natural-language description, and Gemini proposes related search terms for comparison. Personal Intelligence operates later in the journey. With the user’s permission, Gemini can draw on information associated with Search, Gmail, Google Photos, and YouTube to produce a response that may be more useful to that person.

    Gemini surfaceInputUseful decisionWhat it cannot establish
    Google Trends ExploreA keyword or natural-language topicWhich terms, variants, and rising questions deserve closer investigationWhether a term will convert, whether two terms share the same intent, or whether you should publish a separate page for each suggestion
    Personal IntelligenceA prompt plus the Google apps and history the user has chosen to connectWhich details could make an answer more relevant in a particular personal contextA universal ranking position, a reusable audience profile, or access to other users’ private context

    This distinction prevents two common mistakes. A rising query is not automatically a content brief, and a personalized answer is not automatically a public search result. The first is a lead that needs editorial judgment. The second is an individual output whose conditions must be recorded before you draw conclusions from it.

    Access conditions also matter when you plan a workflow. The Trends redesign was introduced through a gradual desktop rollout, so the Gemini control may not appear in every interface at the same time. Personal Intelligence initially launched as a U.S. beta for Google AI Pro and AI Ultra subscribers using personal Google accounts across the web, Android, and iOS; Workspace accounts were excluded from that initial availability. Treat those as launch conditions to verify in the account you will actually use, not as permanent assumptions.

    Turn Gemini’s Trends suggestions into a defensible query map

    Blank query tokens pass through an analysis lens, branch into thematic clusters, and organize into page modules.

    The useful output from Gemini in Trends is not a list of titles. It is a query map: a record of how people describe a problem, which terms appear related, and where the language may represent a genuinely different need. Build that map before you decide whether to update a page, add a section, or create something new.

    1. Start with the editorial decision. Write the question you need the data to resolve. For example: Do searchers treat two product categories as alternatives, or are they looking for different jobs to be done? A clear decision keeps Gemini’s suggestions from becoming an unfiltered brainstorming exercise.
    2. Describe the topic in natural language. In the desktop Explore interface, use Suggest search terms and enter either a seed keyword or a sentence describing the audience and problem. Natural language is especially useful when the market uses several labels and you do not yet know which one belongs in the comparison.
    3. Curate the suggestions before accepting them. Ask whether each term describes the same entity, the same task, a narrower condition, or an unrelated meaning. Remove ambiguous lookalikes. Keep a term when it exposes a meaningful vocabulary choice or a separate intent worth testing.
    4. Compare the terms as a group. The redesigned interface allows more terms to be compared and gives each one a distinct icon and color. Look for divergence, convergence, and sudden movement. Similar movement can indicate a shared external trigger, but it does not prove that searchers want the same answer.
    5. Inspect the rising queries for the mechanism behind the movement. The updated timeline exposes twice as many rising queries as the earlier layout. Use them to identify new modifiers, questions, products, or events that may explain the trend. Treat a rising query as an investigation lead, not a forecast that demand will last.
    6. Make one of three explicit content decisions. Add a missing answer to an existing page when the intent is already covered. Create a focused page when the searcher needs a materially different answer. Put the term on a watchlist when the meaning or durability is still unclear.

    Your query map should record the core question, accepted term variants, excluded ambiguities, notable rising queries, and the content decision attached to each cluster. Save the comparison context shown in Trends as well. Without that record, a later editor cannot tell whether a page was built around sustained demand, a temporary spike, or an AI-generated suggestion that was never validated.

    Do not publish one page per suggested term. If several phrases express the same task, a single strong page can define the shared concept and use the variants naturally. Separate pages make sense only when the reader needs a different decision, procedure, constraint, or outcome. That is an information-architecture choice, not something Gemini can decide from term similarity alone.

    Build pages for context without trying to predict the user

    Personal Intelligence changes the selection problem. Gemini was already able to retrieve information from connected apps; in the announced Gemini 3 implementation, it can reason across that information and use it in recommendations. Your public page cannot know the private facts available in a particular conversation. It can, however, make its answer easy to adapt when different facts matter.

    • Lead with the stable answer. State what remains true regardless of the user’s history. Do not bury the definition, process, or central recommendation beneath persona language.
    • Branch on explicit conditions. Label the cases that change the answer: platform, account type, experience level, objective, compatibility requirement, or other relevant constraint. A reader and an answer system should be able to identify the applicable branch without inferring what the page meant.
    • Name entities consistently. Use the canonical product, organization, feature, and version names that the answer depends on. Introduce genuine search-language variants from your Trends map, but do not alternate among labels in a way that makes separate concepts look identical.
    • Explain relationships in visible prose. State which feature belongs to which product, which step precedes another, and why a condition changes the recommendation. Do not expect a heading, internal link, or schema property to carry an important relationship by itself.
    • Separate facts from judgment. Identify what a feature does before recommending who should use it. Personalized systems may combine a factual passage with private context, so an unsupported universal recommendation is especially fragile.
    • Keep structured data aligned with the page. JSON-LD should describe entities, authorship, content types, and other information that visitors can verify in the visible content. The announced Gemini integrations do not establish a new Gemini-specific schema or a markup switch that guarantees selection in personalized answers.

    Consider a hypothetical page about organizing a photo library. A context-ready page would answer the universal setup question first, then separate paths for finding images, sharing collections, creating a backup, and cleaning up duplicates. It would not guess which path applies to the reader. It would label the paths clearly enough for the reader or an answer system to select the relevant one.

    This is the practical GEO implication: public content establishes what your organization knows, while personal context can influence which part of that knowledge is useful. You control the clarity, completeness, and consistency of the public material. You do not control the private context or the final selection, so promises of guaranteed personalized visibility do not hold up.

    Measure public visibility and personalized usefulness separately

    One blank content page connects to separate stations for measuring anonymous public visibility and private personalized usefulness.

    A personalized Gemini response can vary with connected apps, personalization settings, and past conversations. Compressing all of that into one rank number strips away the conditions that produced the answer. Use a small controlled test matrix instead.

    Run a controlled visibility check

    1. Record the demand evidence. Save the Trends prompt, comparison set, relevant rising queries, date, and comparison context visible in the interface. This becomes the public-demand side of the test.
    2. Document the personalization state. Establish a baseline with personalization off. If you test a connected condition, record which permitted apps are active without copying private contents into the report.
    3. Hold the prompts constant. Use the same wording, task, and follow-up sequence across conditions. If you change the prompt and the personalization state at once, you will not know which change affected the response.
    4. Log treatment instead of claiming a fixed rank. Record whether your page or brand appeared, which question the response answered, which details it used, whether it cited or linked to a public page, and whether it represented the entity accurately.
    5. Translate differences into content changes carefully. Revise a page only when the test exposes a public-content gap, such as an omitted condition, unclear entity relationship, outdated fact, or unsupported recommendation. You cannot repair a private-context mismatch by adding speculative personal details to the page.
    6. Repeat under the same conditions. After an editorial change, rerun the fixed prompts with the same documented settings. The useful comparison is the change in answer quality and representation under matched conditions, not a screenshot from an unrelated conversation.

    Make privacy part of the test design

    Personal Intelligence is off by default and lets the user choose which apps to connect. Connected apps do not personalize every response automatically, and users can manage past chats and provide feedback when personalization misses the mark. Those controls are not implementation details. They are variables that determine what your test actually measures.

    Do not ask employees, clients, or research participants to expose personal Gmail, Photos, Search, or YouTube information merely to generate a marketing screenshot. Use only an account and data that the owner has explicitly authorized for the test. If private information affects an output, report the pattern at a high level and omit the underlying email, image, search, or viewing history.

    The initial exclusion of Workspace accounts also means you should not present a personal-account test as proof of an enterprise workflow. Google indicated that Personal Intelligence would expand to Search in AI Mode, but a planned expansion is not the same as universal availability. Verify the feature, account type, country, and personalization state whenever you interpret a result.

    Key takeaways

    • Use Gemini in Google Trends to expand and compare a query cluster, not to automate your editorial calendar.
    • Treat rising queries as clues about changing language or demand. Validate their meaning before creating or restructuring a page.
    • Prepare for personalized answers by publishing a stable core answer with clearly labeled branches for the conditions that change it.
    • Keep visible content and JSON-LD consistent. Neither markup nor trend data guarantees inclusion in a personalized Gemini response.
    • Measure public demand and personalized usefulness as separate layers, documenting the prompt, account state, app connections, and answer treatment.
    • Keep private Google data out of shared SEO artifacts unless the data owner has explicitly authorized its use.

    Start with one existing page rather than a site-wide overhaul. Build its query map in Trends, add the most important missing conditional branch, and run one baseline and one authorized personalized check with the same prompt. That gives you a defensible editorial action now, plus a repeatable method as Gemini’s integrations reach more accounts and search surfaces.

    References

  • AI-Driven Google Search SEO: A Practical Optimization Plan

    AI-Driven Google Search SEO: A Practical Optimization Plan

    If your organic strategy still stops at ranking one page for one keyword, Google’s AI answers create a blind spot. A user can ask for a comparison, plan, or recommendation, and AI Mode can break that request into smaller questions, retrieve current information and links, and assemble an answer before a conventional result earns the click.

    You don’t need a separate content factory for this. Keep the foundations of SEO, but change the unit you optimize: move from isolated keywords to complete decision journeys. Then measure demand, retrieval, answer visibility, and business outcomes instead of treating clicks as the only proof that your work mattered.

    Optimize for the decision behind the prompt

    The meaningful change in AI-driven search isn’t simply that queries are getting longer. A detailed prompt can contain several jobs at once: define a problem, compare options, apply constraints, check current conditions, and recommend a next step. Google’s rollout of Gemini 3 Flash as the default model for AI Mode is designed around reasoning across those facets while incorporating web, real-time, and local information.

    Think of the behavior as query decomposition. A request such as “Which platform should our international retailer use to manage SEO during a site migration?” may require answers about ecommerce features, regional requirements, migration workflows, integrations, cost considerations, and implementation risks. Ranking for the broad phrase “SEO platform” addresses only a fraction of the job.

    Before revising a page, write down the complete decision it needs to support:

    • The core problem the user is trying to solve.
    • The constraints that could change the answer, such as location, business type, technical environment, or deadline.
    • The alternatives the user is likely to compare.
    • The criteria needed to make that comparison fairly.
    • The sequence of actions required after the decision.
    • The facts that must be current rather than generally true.
    • The follow-up question a careful user would ask before acting.

    This exercise gives you a decision map rather than a bag of keyword variations. It also tells you how to structure the site. Keep closely connected facets on one page when they serve the same reader and require the same evidence. Create supporting pages when a facet has its own intent, evidence, or implementation path. Link those pages so a crawler, search engine, and person can follow the relationship without guessing.

    The strategic foundation remains familiar because Google’s position is that SEO for AI is still SEO. AI visibility doesn’t excuse weak crawlability, vague writing, unsupported claims, or poor site architecture. It raises the cost of those weaknesses because an answer system can select a clearer passage from another site even when your page nominally covers the same topic.

    Build a prompt map from evidence you already have

    Hands arrange blank cards, query bubbles, lenses, and decision tokens into connected paths on a worktable.

    You probably can’t open a report that lists every prompt for which an AI system considered, retrieved, or cited your content. You can still build a useful model of that demand by combining several imperfect signals. The discipline is to label them as proxies rather than treating them as a complete record of AI-search activity.

    1. Start with a commercially or strategically important topic, not with every URL on the site. Define the decision, action, or problem that makes the topic valuable to your audience.
    2. Collect the related questions shown in Google’s People Also Ask results. These questions turn a broad keyword into the definitions, comparisons, objections, and follow-ups that people may express in a conversational prompt. A service such as AlsoAsked can extract People Also Ask relationships at scale.
    3. Export relevant Google Search Console queries. Isolate longer phrases, questions, comparisons, qualifiers, and multi-part wording. These queries are still Google Search data, not a transcript of AI prompts, but long queries can approximate the language and specificity of conversational search.
    4. Probe likely follow-up paths in an answer engine. Perplexity’s suggested follow-ups can reveal the next clarification a user may ask, but use them as ideation rather than proof of demand.
    5. Group the collected prompts by shared intent and answer requirements. Prompt-tracking platforms can help at scale; for example, Semrush’s AI visibility workflow consolidates prompts into broader topics so teams can assess intent and brand mentions without managing every wording as a separate campaign.

    Keep the original wording even after clustering. A cluster label such as “migration risk” is convenient for reporting, but the exact prompts preserve constraints that may change the answer. “How do I protect rankings during a migration?” and “Which migration mistakes prevent Google from finding a multilingual store?” belong near each other, yet they don’t require identical content.

    A practical prompt-map record should contain:

    • The topic cluster and the user’s dominant intent.
    • The exact seed questions and long queries behind the cluster.
    • The constraints, entities, places, or products that alter the answer.
    • The best current URL for the intent, if one exists.
    • The missing evidence or explanation on that URL.
    • Whether the answer depends on current, local, or frequently changing information.
    • The business action you want the content to support.

    Don’t publish a separate page for every prompt. That creates overlapping pages that repeat the same answer and compete for the same intent. Merge wordings when the reader needs the same decision and evidence. Split them only when the correct response, audience, or next action is materially different.

    Make each page easy to retrieve, interpret, and cite

    Organized information blocks pass through a transparent prism and assemble into an answer beside source-link shapes.

    Once you have a prompt cluster, turn it into a page brief. The goal isn’t to mimic chatbot language. It is to make the correct answer, its boundaries, and its supporting evidence easy to identify.

    1. State the central answer early. Include the condition that would make the answer change instead of burying qualifications near the end.
    2. Use descriptive headings for genuine subquestions. A heading such as “When server-side rendering is necessary” carries more meaning than “Other considerations.”
    3. Separate facts, recommendations, and uncertainty. If several options can be reasonable, give the decision criteria instead of manufacturing one universal winner.
    4. Use explicit names for products, locations, audiences, and technical concepts. Pronouns and vague phrases may read smoothly, but they make a passage harder to understand when it is retrieved without the surrounding paragraphs.
    5. Support comparisons with consistent criteria. A table is useful when every option can be evaluated on the same attributes; prose is better when the trade-offs aren’t symmetrical.
    6. Connect the page to deeper supporting material with descriptive internal links. The primary page should answer the decision, while supporting pages can carry implementation detail, definitions, or evidence.
    7. Keep time-sensitive claims maintainable. Identify the pages whose answer depends on current product behavior, local conditions, availability, or other changing facts, and assign them a review process.

    Technical SEO still determines whether Google can reliably discover and understand the page. Confirm that the intended URL is crawlable and indexable, uses the correct canonical, is linked from the site, and exposes its important answer in accessible page text. If you use JSON-LD, make it a faithful representation of visible content and the entity on the page. Structured data can clarify meaning; it isn’t a switch that guarantees inclusion in an AI answer.

    Write for selective retrieval as well as full-page reading. In retrieval-augmented generation, or RAG, a system finds external material and uses it to ground a response. That means a self-contained passage can shape an answer even when the user never opens the page. It also means unsupported, context-dependent copy is a poor candidate for reuse.

    Not every prompt triggers retrieval. A system may answer from its existing training data without consulting a fresh page, especially when the question doesn’t require current information. You can’t force a citation by repeating a phrase or adding schema. Concentrate on queries where your content contributes something retrievable: current facts, specific comparisons, local information, original expertise, clear procedures, or a well-supported explanation.

    Measure AI visibility without confusing bots, citations, and people

    If your reporting doesn’t isolate AI prompts and answer appearances, use a layered scorecard. No single metric tells you whether people wanted the information, a system retrieved it, the answer mentioned you, or the visibility produced a business result.

    Measurement layerUseful signalsWhat you can concludeWhat you cannot conclude
    Demand proxyPeople Also Ask questions and long Google Search Console queriesWhich needs, qualifiers, and conversational patterns deserve investigationThe total number or exact wording of prompts submitted to AI systems
    RetrievalRequests from identifiable user agents and URLs observed as citationsWhich pages are accessible to, or selected by, particular systemsThat every request represents a person, prompt, recommendation, or citation
    Answer presenceBrand mentions, cited URLs, response context, region, and prompt clusterWhere and how the brand appears in sampled answersComplete market visibility or guaranteed future inclusion
    Business outcomeVisits, conversions, qualified enquiries, branded demand, and relevant offline outcomesWhether visibility is associated with useful actionPerfect attribution when the answer satisfies the user without a click

    If you control server or CDN logs, look for identifiable agents such as ChatGPT-User and Perplexity-User. Record the requested URL, response status, and time. These requests can reveal which pages AI services access or use, but they don’t reveal the full prompt by themselves. A bot request isn’t a human session, and it shouldn’t be counted as referral traffic.

    Apply the same caution to unusual Search Console patterns. A long query with many appearances and no clicks may look like strong AI demand, yet some patterns can be generated by automated tracking rather than human behavior. Investigate repeated wording, improbable consistency, sudden unexplained volume, and mismatches with the rest of your demand data before building a content plan around it.

    For answer monitoring, save more than a visibility score. Retain the exact prompt, location or market, model or surface, date checked, answer context, brand mention, cited URL, and competing domains. Then report at the topic-cluster level. Individual answers and phrasings vary; clusters show whether you consistently appear for a decision your business cares about.

    Clicks remain useful, but they are no longer a complete measure of influence. A cited passage may answer the question without sending a visit. A recommendation can also lead to branded search, a later direct visit, or an offline action. Treat those as possible outcomes, not automatic credit. The defensible claim is that the brand appeared in the relevant answer; stronger attribution requires supporting behavioral or business data.

    Key takeaways for your next optimization sprint

    • Map the whole decision behind a prompt, including constraints, comparisons, current information, and likely follow-ups.
    • Use People Also Ask, long Search Console queries, answer-engine follow-ups, and prompt tools as complementary proxies, not as a complete record of AI demand.
    • Cluster prompts by intent and evidence requirements. Preserve exact wording, but don’t create a separate URL for every variation.
    • Make answers self-contained, qualified, crawlable, internally connected, and easy to retrieve. Use JSON-LD to describe visible facts, not to manufacture relevance.
    • Track demand, retrieval, answer presence, and business outcomes separately. Never equate a crawler request with a person or a citation with a conversion.
    • Prioritize topics where fresh, local, comparative, or specialized information gives an AI system a reason to retrieve your page.

    Start with one high-value decision your audience already brings to Google. Build its prompt map, audit the strongest existing URL, fill the specific evidence gaps, and create the four-layer scorecard before expanding the program. Your next round of work should follow observed gaps in retrieval and answer presence, not the temptation to generate more pages.

    References

  • Google Discovery and Local Visibility: A Practical Plan

    Google Discovery and Local Visibility: A Practical Plan

    If your business appears when someone searches its name but disappears when they search for a service nearby, you don’t have a single ranking problem. You have a discovery mismatch. Google can surface a business through the Local Pack, cite a page in AI Mode, group it under a Web Guide topic, or favor a publisher a searcher has deliberately chosen.

    Your job is to determine which discovery path matters for each query, then give that system the information and evidence it needs. That calls for more precision than completing the same SEO checklist for every location.

    Map the Google surface before you change the page

    A strategist sorts query tokens across a blank city map into routes leading to a map pin, an AI-like orb, page clusters, and editorial sheets.

    A conventional rank tracker can tell you where a URL appears, but it may not explain what now occupies the useful part of the results page. Start by identifying the surface that answers the query:

    • Local Pack: The searcher is choosing a nearby business. Location, category relevance, operating details, reputation and local behavior matter more than a generic national content campaign.
    • AI Mode: Google synthesizes an answer and may attach links to particular claims or branches of the question. Google has been adding more inline links and contextual introductions that explain why a linked page may be useful.
    • Web Guide: Google organizes links into topic groups rather than presenting one undifferentiated list. Its custom version of Gemini interprets the query and page content, while query fan-out runs multiple related searches. The expansion into the all tab still required a Search Labs opt-in, so you shouldn’t assume every searcher sees the same layout.
    • Preferred Sources: This applies to publishers appearing in Top Stories. A searcher can choose publications they want Google to show more often when those publications have relevant, recent coverage.

    Create a query map with a row for each commercially important search. Record the likely intent, the dominant Google surface, the location implied by the query, the page or profile you expect to qualify, and what actually appears. A query such as “accountant near me” needs a different asset from “how to choose an accountant for a growing company,” even when both ultimately support the same business.

    This diagnosis prevents a common waste of effort: rewriting an informational page when the Local Pack owns the decision, or editing a Google Business Profile when Google is looking for a page that answers a detailed question.

    Build signal fit into every Google Business Profile

    Profile completeness is a baseline, not a complete local strategy. Google is trying to identify which nearby result best fits what people expect from that kind of business. Those expectations change by category and can vary by region.

    A Yext analysis of 8.7 million Google Business Profiles found that review activity, profile information and visual content did not carry the same apparent importance across every industry. Because this was a vendor analysis of observed profiles, it should guide prioritization rather than be treated as proof of a universal ranking formula.

    Business typeSignals to inspect firstPractical response
    HospitalityHours, descriptions and complete practical informationMake arrival, availability and operating details easy to verify before investing in more image volume.
    HealthcareReviews, accurate hours and clear location detailsRemove uncertainty about access and reliability. Check every location independently.
    RetailReview volume, sentiment and listing upkeepTreat reputation and profile maintenance as operating signals, not occasional marketing tasks.
    Food and diningRatings and continuing engagement with feedbackMonitor new reviews and respond sincerely; basic completeness alone may not distinguish a competitive listing.
    Financial servicesGenuine reviews and real-world reputationPrioritize trust evidence over accumulating polished photos that add little decision value.

    Use three layers when you audit a location. First, verify the stable identity: business name, address, phone number, primary category, hours and destination URL. Second, inspect the signals customers use to choose within your category. Third, compare the location with nearby competitors serving the same intent. A national average can hide the gap that determines whether one branch appears locally.

    Don’t copy a successful location’s profile changes across the entire estate in one move. A restaurant in one region may benefit from a feature that produces no meaningful difference elsewhere. Test the change on comparable locations, keep the untouched profiles as a reference where practical, and judge the result using both visibility and customer actions.

    Reviews deserve an operating process of their own. Ask real customers for honest feedback without scripting the sentiment. Route new reviews to the person who can answer them accurately. A quick, specific response shows that the location is active; a batch of generic replies creates activity without adding much trust.

    Publish pages that fit a branch of the search journey

    AI-organized search makes broad relevance less useful than precise usefulness. Web Guide can fan a query out into related searches and group the resulting pages by facet. AI Mode can then present a link next to the part of an answer it supports. Neither feature means you should generate a page for every wording variation. It means each worthwhile page should have a clear job.

    1. Break the query into genuine decision branches. Someone looking for an emergency dentist may need to know whether the practice is open, which urgent problems it handles, where it is and how to contact it. Those are user needs, not keyword variants.
    2. Assign each branch to the right asset. Put operating facts on the location page and profile. Use a focused service page for a service that needs explanation. Use an educational page when the person is still deciding what kind of help they need.
    3. State the page’s value early. Identify the service, audience, location and question being answered before drifting into background copy. A visitor following an inline AI link should be able to confirm immediately that the page matches the context around that link.
    4. Supply verifiable detail. Include the facts a customer would need to act, such as availability, eligibility, process, location or limitations, when they genuinely apply. Replace generic claims with information the business can keep current.
    5. Connect the page to the location. Keep business identity, service descriptions and operating details consistent with the corresponding Google Business Profile. Link users to the appropriate location rather than forcing them through a generic homepage.

    Applicable LocalBusiness structured data can describe facts already visible on the page and reduce ambiguity about the entity. Use it as a consistency layer. It cannot compensate for stale hours, a mismatched category, weak reputation or a page that never answers the query.

    Avoid mass-produced city pages that change only the place name. They don’t give Google a distinct facet to retrieve, and they give the reader no local reason to trust the page. Create a separate location page when you can maintain distinct operating facts, directions, services or other genuinely local information.

    Use Preferred Sources only when you are really a publisher

    Preferred Sources can be valuable for a local news organization, trade publication or other site that regularly qualifies for Top Stories. It is not a general local ranking switch for every service business.

    Google expanded the feature globally for English-language users after launches in the United States and India. Searchers use the star beside Top Stories to choose publications they prefer, and Google can show more of those publications’ recent work when it is relevant. People have selected nearly 90,000 sources, ranging from local blogs to global outlets.

    Google also reported that people clicked a chosen publication about twice as often on average. That does not mean asking readers to select you will double traffic. People who deliberately choose a publication are already more likely to value it, and relevance and freshness still determine whether suitable coverage exists.

    If the feature fits your publication, add a brief instruction near the places where loyal readers already engage, such as a subscriber message or membership page. Explain what the star does and let the reader decide. Then maintain a dependable publishing rhythm around the local topics for which you want to be found. Preference cannot make an unrelated story relevant.

    If you run a clinic, restaurant, retailer or professional practice without a genuine news operation, leave this tactic alone. Put the effort into the Local Pack, location pages and useful answers connected to your services. A feature being available does not make it appropriate to your discovery problem.

    Measure each location and discovery surface separately

    An analyst compares six separate abstract measurement panels positioned above different miniature neighborhoods and storefronts.

    A single visibility score conceals too much. Local results depend on the searcher’s location. AI and experimental layouts can differ by account or feature access. Preferred Sources are explicitly personalized. Keep the measurements separate enough to tell which change produced which result.

    • For the Local Pack: Check a stable set of query-and-location combinations. Record whether the correct branch appears, which competitors surround it, and whether profile actions such as calls, website visits or direction requests change when those measurements are available.
    • For standard organic and Web Guide discovery: Group Search Console queries by intent rather than tracking isolated wording. Watch the landing pages receiving impressions and clicks, and annotate meaningful page revisions.
    • For AI surfaces: Record the exact query, observed linked page and context in which the link appeared. Keep the account state and test conditions consistent enough to make repeated observations useful. Treat a single appearance as a lead to investigate, not proof of stable inclusion.
    • For Preferred Sources: Monitor relevant Top Stories appearances and returning search traffic. Separate that audience from first-time discovery so loyalty does not disguise weak reach.

    Change one class of signal at a time where practical. If you revise categories, hours, photos, landing pages and review outreach together, even a positive result won’t tell you what to repeat. Compare similar locations, preserve a baseline and look for movement in both discovery and the user action tied to the query.

    Key takeaways

    • Identify whether the query is governed by a local choice, an AI answer, a grouped web result or a publisher preference before editing anything.
    • Complete every Google Business Profile, then prioritize the reputation, access, information or engagement signals that matter in that location’s category.
    • Build pages around real branches of intent, not slight keyword or city-name variations.
    • Use structured data to reinforce visible, accurate facts; don’t treat markup as a substitute for content or profile maintenance.
    • Reserve Preferred Sources promotion for sites that genuinely publish timely material and can appear in Top Stories.
    • Measure locations and discovery surfaces separately so you can connect a change with an outcome.

    Start with one revenue-relevant query and one location. Identify the surface that controls the decision, find the largest mismatch between user intent and your profile or page, and correct that mismatch. Once you can see what changed in visibility and customer action, apply the lesson to the next comparable location.

    References

  • Google Discover and AI Mode: An Emerging-Query Workflow

    Google Discover and AI Mode: An Emerging-Query Workflow

    If your Google strategy begins when someone types a query, you may be entering the journey too late. A person can encounter a story in Discover, open the page, and then continue exploring it through AI rather than returning to a conventional results page.

    That changes the content problem in two directions. You need to recognize demand before it becomes an obvious keyword opportunity, and the page you publish must remain useful when a reader asks an AI system to summarize it, answer a follow-up, or go deeper.

    Optimize the whole discovery journey, not one ranking

    The emerging Google journey has three distinct moments, and each asks something different of your content:

    1. Discovery: A topic, headline, image, or entity earns attention in a personalized feed. The reader may not have expressed a conventional search query.
    2. Evaluation: The reader opens the page and decides whether it answers the immediate question clearly enough to trust and continue.
    3. Exploration: The reader uses AI to condense the page, ask another question, or investigate the subject in more depth.

    The third moment is no longer theoretical. In the observed Google app for Android flow, a menu available after opening a URL offered Summarize with AI Mode, Ask a follow-up with AI Mode, and Dive deeper with AI Mode. The behavior was not confined to stories selected from Discover; AI Mode controls were also available for other pages opened through the app.

    This means a click is not necessarily the end of the search experience. Your page can become material the reader interrogates. A catchy headline may win the first transition, but it cannot compensate for vague entities, buried conclusions, unsupported assertions, or sections that repeat the same point.

    Plan the journey backward. Start with the useful action or decision the reader should reach. Then identify the questions that lead there:

    • What happened, or what is changing?
    • Why does it matter to this reader?
    • What is still uncertain?
    • What should the reader compare, check, or do next?
    • What related question becomes important after the first answer?

    Those questions should determine the article structure before you write the headline. They also give you a practical standard for deciding whether a trend deserves coverage at all.

    Find rising demand before it looks like a mature keyword

    A strategist observes scattered digital signals converging into a bright rising pattern on a translucent display.

    Traditional keyword research is strongest when a query already has enough repeated behavior to measure. Emerging demand often appears first as an event, product, person, phrase, policy, cultural reference, or unfamiliar entity. By the time every tool reports stable volume, the easiest editorial opening may have passed.

    Google’s 2025 Year in Search was organized around rapidly rising searches rather than a simple ranking of the largest query totals. The U.S. list crossed technology, policy, entertainment, sport, and public affairs with queries such as DeepSeek, iPhone 17, tariffs, KPop Demon Hunters, and the FIFA Club World Cup. The global list included Gemini, DeepSeek, major cricket matchups, the Club World Cup, and iPhone 17.

    The more useful lesson is not which names appeared. It is how many different forms new demand can take. Additional U.S. trends included AI action figure, a long viral-dish phrase, a Boston travel-itinerary query, and a question about why children say 67. A useful trend radar therefore cannot be limited to short commercial keywords. It has to notice new entities, new behaviors, new language, and old needs expressed in unfamiliar ways.

    Keep a signal log that captures what keyword volume misses

    Create one shared record for emerging topics. For each signal, capture:

    • The exact phrase or entity: Preserve the wording people are using instead of immediately translating it into an established keyword.
    • The trigger: Record the launch, event, announcement, controversy, release, match, meme, or behavior that created the question.
    • The audience connection: State why your existing reader would care. A topic can be popular without belonging on your site.
    • The first practical question: Identify what the reader needs to understand, decide, buy, avoid, or explain.
    • The likely follow-ups: Write down the next questions before search-volume data exists for them.
    • The evidence available: Note what can be verified now and what remains unknown. If you cannot support the central answer, speed will not improve the page.
    • The expiry condition: Decide what event would make the page outdated, incomplete, or misleading.

    This log prevents a common mistake: treating a growing entity as if it were already a settled keyword cluster. Early in a trend, people may search for the name alone because they do not yet know the vocabulary for a more precise question. Your job is to infer the legitimate questions cautiously, then revise the page as the language becomes clearer.

    Use a publication gate before chasing the spike

    Run every candidate through five questions:

    1. Is the reader ours? Define the person who needs the answer without relying on a phrase such as everyone is talking about it.
    2. Is there a real job to do? Name the decision, explanation, comparison, or action the page will support.
    3. Can we add clarity? If the page will merely restate the event, it has little reason to exist after the first wave of coverage.
    4. Can we maintain it? A fast-changing page needs an owner and an explicit update trigger.
    5. Does it connect to durable expertise? The best emerging topic opens a path into subjects your site can continue to explain after the spike fades.

    If you cannot answer the first three questions, skip the topic. If you cannot support the final two, narrow the scope until you can. Publishing a thin page for every rising name creates an archive of disconnected updates, not topical authority.

    Once a topic passes the gate, prepare a brief containing the provisional query cluster, the one-sentence answer, the follow-up question map, the entities that require disambiguation, the supporting evidence, the intended URL, and the conditions that will trigger an update. That is enough structure to move quickly without turning speed into guesswork.

    Build pages that survive summary, follow-up, and depth

    Cutaway illustration of readers exploring an overview, branching answer areas, and deeper research layers within a structured web page.

    The three AI Mode commands provide a useful editorial test. Apply all three before publication, even if a particular reader never opens the AI controls.

    The summary test

    Could a reader identify the subject, central answer, significance, and main limitation from the opening and section headings? If not, the page is making both readers and machines reconstruct a conclusion that you should have stated directly.

    • Name the primary entity in the title, introduction, and relevant heading instead of relying on ambiguous pronouns.
    • Give the direct answer before the chronology or background.
    • Separate confirmed facts from interpretation and unresolved questions.
    • Use one section for each distinct idea. Do not scatter the same conclusion across several headings.
    • Remove paragraphs that merely announce what the next paragraph will explain.

    A good summary test is not an instruction to make every article short. It is an instruction to make the hierarchy unmistakable. A detailed page can still have a clear central answer.

    The follow-up test

    After reading the answer, what would a sensible person ask next? Turn the strongest second-order questions into substantive sections. Depending on the topic, these may concern eligibility, cost, timing, alternatives, consequences, definitions, examples, or what changed.

    Do not manufacture a question section from keyword variants that all have the same answer. Each follow-up should move the reader to a new understanding or decision. If two questions collapse into the same paragraph, combine them.

    Internal links should continue the same logic. Link to a durable explainer when the reader needs background, a comparison when the next task is choosing, and a process page when the next task is acting. Generic related-reading blocks leave that choice to chance.

    The depth test

    What can the reader learn from your page that would be lost in a one-paragraph recap? Depth comes from useful distinctions, not word count. Add the material that changes interpretation: definitions, boundaries, named entities, evidence, exceptions, trade-offs, and the point at which the advice no longer applies.

    For a fast-moving topic, show what is known at publication and what still needs confirmation. Update the existing URL when the central intent remains the same. Create a separate page only when a genuinely different intent appears. That keeps one answer coherent while preventing a single URL from becoming an undifferentiated timeline.

    Make the structured data agree with the visible page

    JSON-LD should describe the page you actually published. For editorial content, use Article or a truthful, more specific subtype. Keep the structured headline, author, publication date, modification date, canonical page identity, and publisher consistent with what the reader can see.

    • Use stable identifiers for people and organizations so the same entity is not represented as several unrelated things across the site.
    • Change the modification date when the content receives a substantive update, not when an automated process touches the template.
    • Represent the page’s primary subject consistently in the copy, metadata, internal links, and structured data.
    • Add a schema type only when the visible content meets its meaning. Anticipating follow-up questions does not require disguising an ordinary article as a different content format.
    • Validate the markup and inspect the rendered page. Syntactically valid JSON-LD can still contradict the content it describes.

    Structured data can make relationships more explicit, but it cannot turn a vague page into a reliable answer or guarantee distribution in Discover, Search, or an AI response. Treat it as a consistency layer, not a substitute for editorial substance.

    Measure whether early attention becomes durable value

    A trend page can produce a traffic spike and still fail strategically. Measure the complete path: how early you recognized the signal, whether the page satisfied the immediate need, whether readers continued into relevant content, and whether the topic strengthened a durable area of expertise.

    QuestionSignal to recordDecision it supports
    Did we recognize the topic early?First-observed date, assignment date, and publication dateWhether the discovery workflow is fast enough
    Did the page match the emerging need?Queries where available, landing-page behavior, and movement to the next relevant pageWhether the angle and follow-up map were accurate
    Did the topic matter to our audience?Qualified subscriptions, leads, purchases, saves, or other site-specific outcomesWhether attention was useful rather than merely large
    Did the opportunity become durable?New recurring questions, internal-link use, and continued interest in the surrounding topicWhether to build an evergreen supporting resource
    Does the page need maintenance?Material changes to the entity, event, availability, policy, or reader intentWhether to update, narrow, redirect, or stop promoting the URL

    Keep these observations attached to the topic record. Keyword volume seen later cannot tell you what your team knew when it made the editorial decision. The first-observed date and original question map let you review whether you spotted a real signal or merely followed an already visible spike.

    Judge trend coverage against its intended role. An emerging explainer should not be evaluated like a mature evergreen guide, and an audience-building story should not be declared successful solely because it attracted raw visits. Define the meaningful next action before publication, then measure that action consistently.

    When interest declines, preserve what remains useful. If the original question still exists, update the page and connect it to an evergreen resource. If the event has ended but the surrounding need persists, create a separate durable page and link the two in both directions. Do not keep producing minor update pages that compete to answer the same intent.

    Key takeaways

    • Google discovery can begin before a conventional query and continue through AI after the click, so optimize the complete question journey.
    • Use a signal log for new entities, phrases, triggers, audience questions, evidence, and expiry conditions; keyword volume alone will often arrive too late.
    • Publish a trend only when it serves your established audience, answers a real question, adds clarity, can be maintained, and connects to durable expertise.
    • Test every page for summary, follow-up, and depth: state the answer clearly, anticipate the next useful questions, and add distinctions that survive compression.
    • Keep visible content, metadata, internal links, and JSON-LD consistent. Schema clarifies meaning but does not replace trustworthy content.
    • Measure lead time, useful onward behavior, audience outcomes, and long-term topic value instead of treating a temporary traffic spike as the goal.

    Start with one rising topic already sitting in your editorial backlog. Write its trigger, reader, first question, next three questions, available evidence, and update condition. If those lines are clear, you have the basis for a useful page. If they are not, waiting or declining the topic is a better decision than publishing a fast page with no durable answer.

    References