Tag: AI Mode

  • How to Grow Product Discovery With AI-Powered Google Ads

    How to Grow Product Discovery With AI-Powered Google Ads

    If you run Google Ads for a large product catalog, your next growth problem may not be finding more keywords. It may be helping Google’s systems understand which products fit searches that are longer, more specific, and harder to classify.

    That changes the work. You need product data that makes relevance clear, a controlled way to give overlooked SKUs another chance, and measurement that distinguishes genuine discovery from automated spend.

    The opportunity has shifted from keywords to interpretable intent

    A conventional product query might name a category and little else. A conversational query can include the shopper’s use case, constraints, preferred features, and stage of decision-making in one sentence. That extra context is commercially valuable if the ad system can interpret it and find a suitable product.

    Google says AI Max can match ads to complex or ambiguous searches that traditional keyword targeting could not readily monetize. The company described this as billions of additional potential ad-bearing searches. AI Max had also moved out of beta and reached more than 500,000 advertisers by Alphabet’s Q2 2026 earnings call.

    The scale is notable, but it shouldn’t be mistaken for a performance guarantee. Google attributes an average 15% lift in conversions or conversion value at a similar return on ad spend to advertisers using AI Max or Performance Max. It also says Gemini has improved Shopping-ad relevance for complex queries by about 20%. These are aggregate, vendor-supplied figures. Your result will depend on your catalog, margins, tracking, offers, product information, and the demand available in your market.

    The important distinction is that better matching creates reach; it does not manufacture qualified demand. A shopper still needs a real problem, and your product still needs to solve it at an acceptable price. Treat AI-powered reach as an opportunity to enter more relevant decisions, not as proof that every new impression is valuable.

    LayerPrimary jobWhat you need to controlQuestion it should answer
    AI MaxInterpret more complex Search intent and connect it with an eligible adOffer clarity, creative relevance, landing-page quality, and conversion measurementAre we entering useful searches that our earlier targeting missed?
    Performance Max recovery campaignGive underexposed products a separate opportunity to collect serving and performance signalsSKU eligibility, campaign isolation, budget limits, entry rules, and exit rulesWhich overlooked products can earn their way back into the main campaign?

    Google is also testing AI Mode formats that move ads closer to an answer experience. Highlighted Answers can place labeled sponsored links in AI-generated lists, while contextual sitelinks and Direct Offers are intended to respond to information surfaced during a conversation. These formats indicate where discovery could go, but they are still developing. Build your strategy around accurate product evidence and sound economics, not an assumption that any particular experimental placement will become material.

    Give Google a product record it can match to real needs
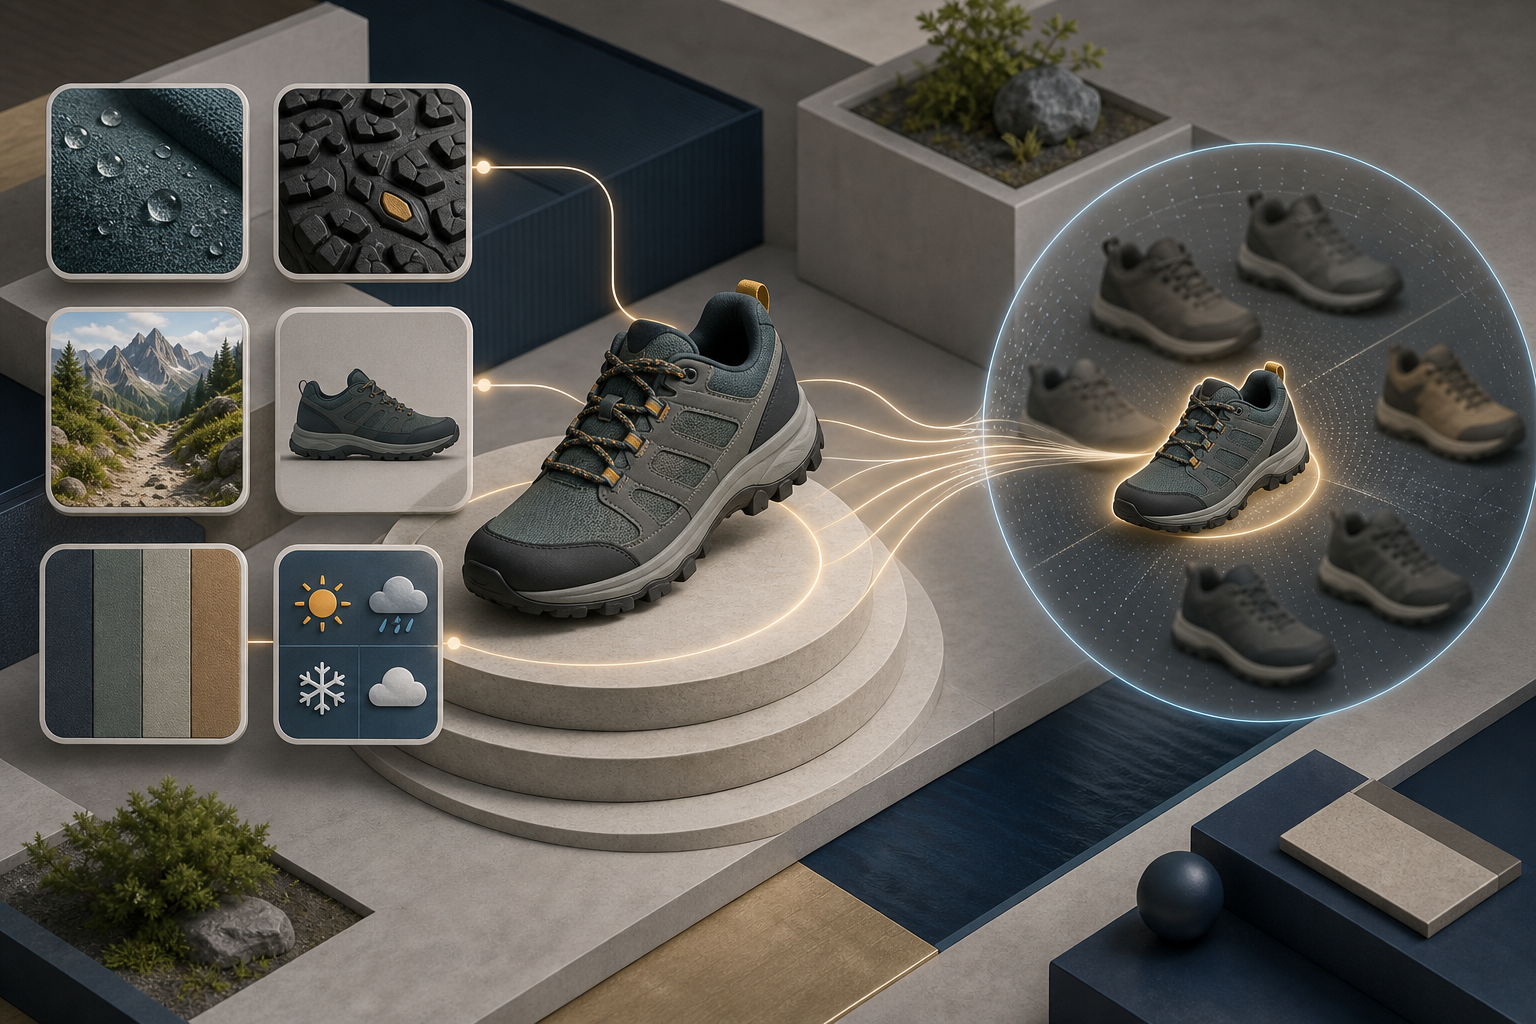
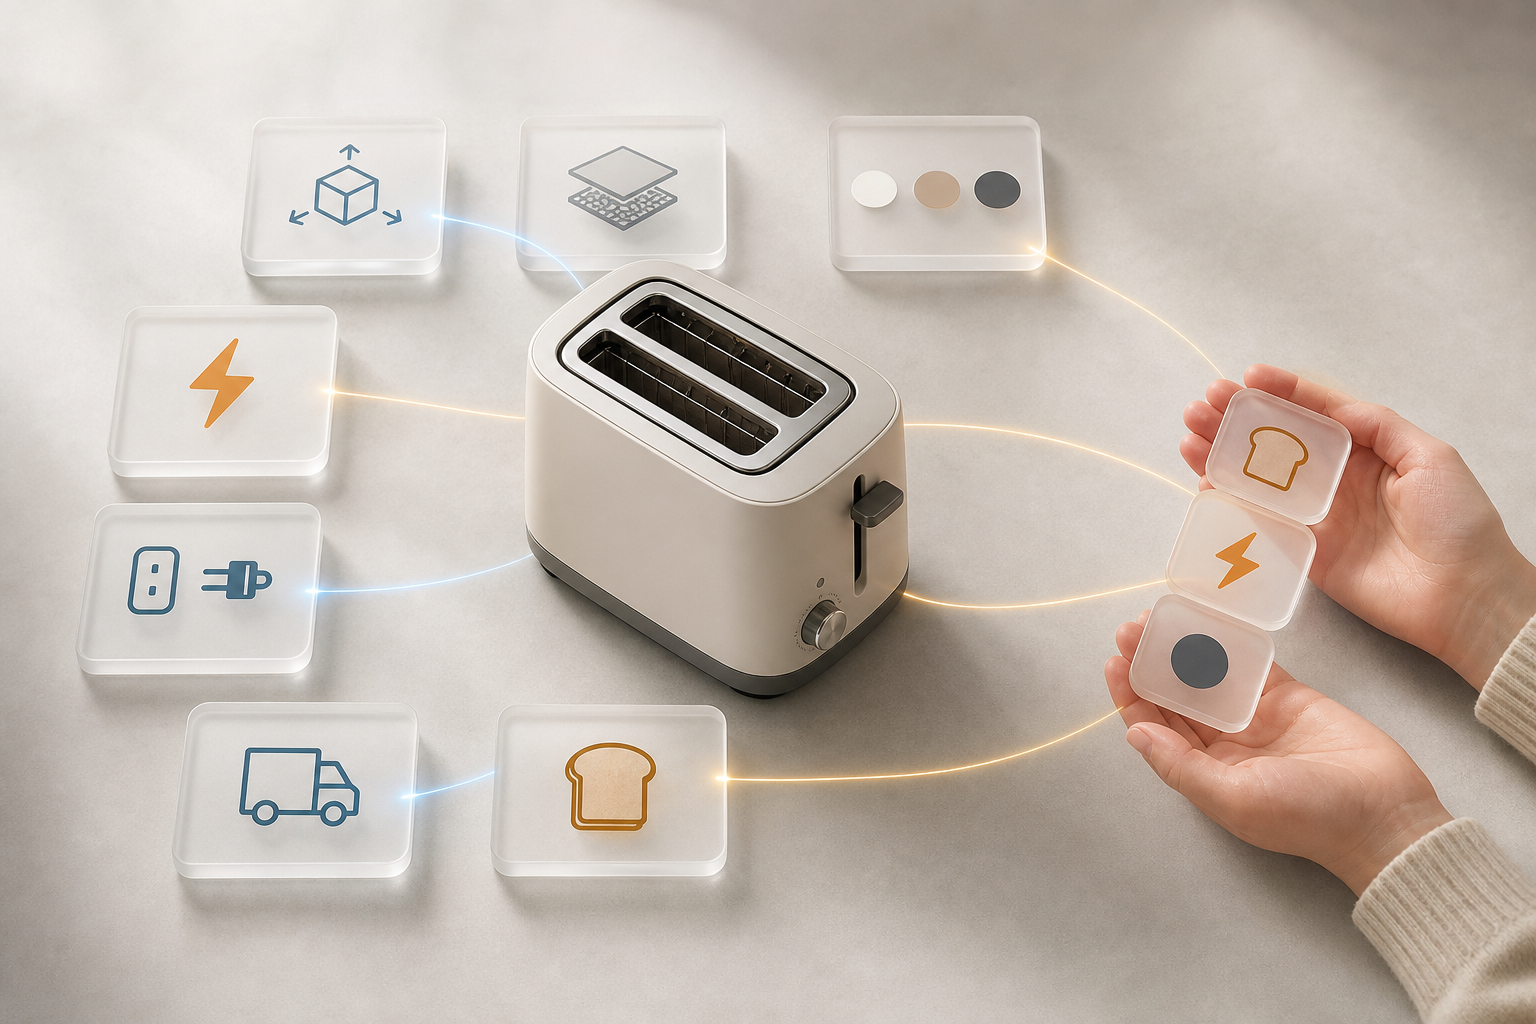
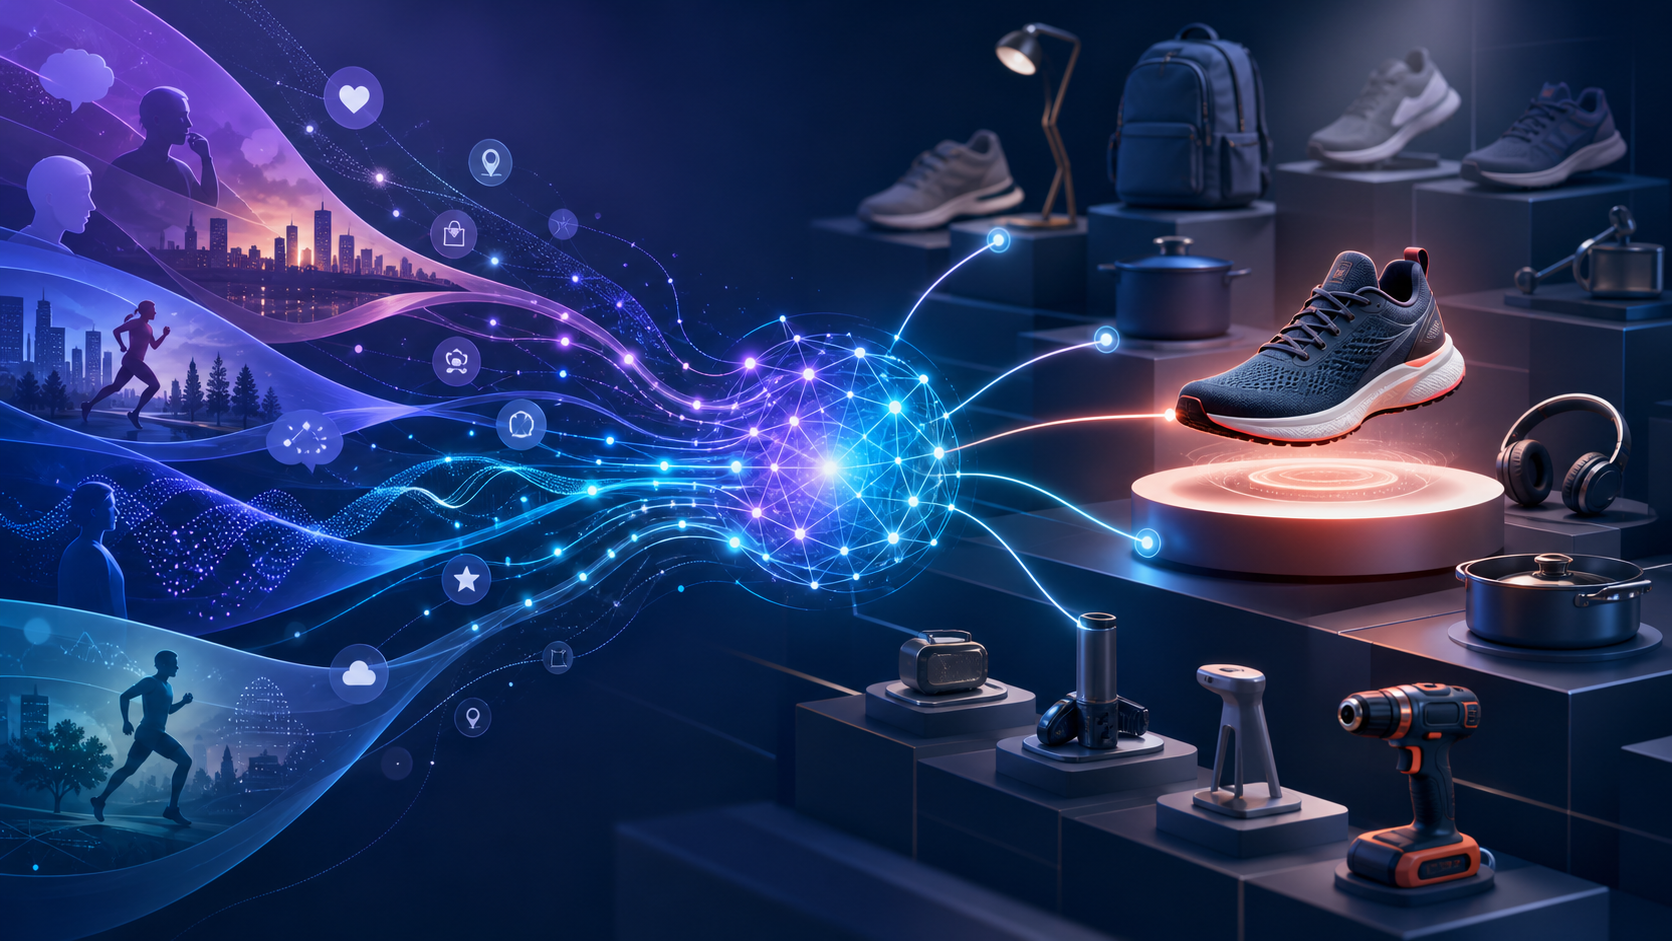
    An unbranded hiking shoe is surrounded by visual product attributes that connect it to a matching shopper intent.

    When matching moves beyond literal keywords, the quality of your inputs matters more. Google needs enough consistent information to connect a shopper’s stated need with the product that can satisfy it. A generic title, thin product page, recycled image, and incomplete feed leave the system very little evidence to work with.

    Translate conversational intent into product evidence

    Start with the language of a decision, not a list of keyword variants. A useful intent statement combines the product, the intended use, and the constraint that will decide the purchase. For example, a shopper may need an item for a particular environment, compatible with equipment they already own, within a size limit, or suitable for a specific recipient.

    For each important intent, create a short query-to-evidence record:

    1. Write the shopper’s need in plain language.
    2. Identify the product fact that proves suitability, such as dimensions, material, compatibility, capacity, fit, intended user, or supported use.
    3. Confirm that the fact is accurate and present in the feed where an appropriate attribute can carry it.
    4. Show the same fact in the creative when it is visually or verbally important.
    5. Make the proof easy to find on the landing page, close to the price and purchase decision.

    This isn’t a keyword-stuffing exercise. Repeating a phrase doesn’t establish relevance. A precise compatibility statement, measurement, material, or use limitation gives the system and the shopper something concrete to evaluate.

    Your feed, visible product page, and Product structured data should also agree. Check prices, availability, variants, identifiers, names, and decisive attributes across those surfaces. If they conflict, you are asking automated systems to resolve uncertainty at the moment they should be deciding whether to show the product.

    Use the same standard for creative assets. The image and copy should distinguish the SKU rather than merely represent its category. If two products solve different problems but use interchangeable descriptions and images, the system has weak evidence for choosing between them.

    Apply an eligibility gate before buying more reach

    Not every low-traffic SKU deserves more exposure. Before a product can enter an AI-powered discovery or recovery campaign, verify that it is:

    • Currently sellable, correctly priced, and available to the intended customer.
    • Economically viable under the budget and loss limits you are prepared to accept.
    • Represented by accurate feed data, useful creative, and a functioning landing page.
    • Distinct enough that you can explain why someone would choose it over nearby products in your own catalog.
    • Appropriate for the current season and market rather than temporarily irrelevant by design.
    • Measured by a conversion action that reflects business value, not merely an easy on-site interaction.

    This gate prevents a common misreading of automation. More reach can reveal latent product demand, but it can also expose weak merchandising faster. If a SKU is unavailable, poorly differentiated, or uneconomic, the right action is to repair or exclude it rather than pay an algorithm to rediscover the same problem.

    Create a recovery lane for products the algorithm stopped testing
    A sidelined unbranded product travels along a separate recovery lane back into a glowing automated testing route.

    Large catalogs develop a performance feedback loop. Products with strong history keep winning impressions and conversions. Products with little history receive less traffic, which leaves them with even less evidence to compete for future traffic. A viable SKU can become invisible without ever receiving a clean test of demand.

    A recovery campaign interrupts that loop. It moves eligible but underexposed products into a dedicated Performance Max campaign, where they can receive another opportunity to generate impressions, clicks, and conversions. The goal is not to force every product to spend. It is to separate lack of opportunity from lack of demand.

    Define a recovery SKU with rules you can audit. Its status should mean that the product is sellable and strategically eligible but has fallen below your business’s floor for meaningful opportunity during a chosen lookback period. Align that period with your buying cycle and seasonality. A universal impression or click threshold would be misleading because catalog size, price, purchase frequency, and demand differ.

    Your operating rules should cover five decisions:

    • Entry: What combination of low impressions, low clicks, or absent conversion opportunity qualifies an otherwise viable SKU?
    • Exclusion: Which products are intentionally paused, out of season, unavailable, disapproved, unprofitable, newly launched under a different process, or missing required data?
    • Isolation: How will you remove the product from its original Shopping campaign while it is in recovery so the campaigns do not overlap?
    • Graduation: What evidence means the product has earned a return to its original campaign?
    • Retirement: When should repeated spend without useful progress end the test?

    Isolation is essential. If a recovery SKU remains active in its original campaign, you won’t know which environment produced its new opportunity, and the two campaigns may compete to serve the same product. The label that admits a SKU to recovery should also trigger its exclusion from the original campaign.

    At catalog scale, automate the movement rather than relying on periodic manual cleanup. One working pattern uses BigQuery to evaluate each SKU, a Google Sheet to carry eligible IDs, Feedonomics to apply a custom label, and Google Ads to route labeled products into a dedicated Performance Max campaign. When a SKU no longer meets the recovery criteria, the label is removed and the product returns to its original campaign.

    You don’t need that exact technology stack. You do need one authoritative SKU list, deterministic entry and exit logic, an automated feed label, mutual campaign exclusions, and a log of every movement. Without those controls, a useful recovery strategy becomes a recurring campaign-maintenance task with unreliable measurement.

    The potential is visible in an early two-week implementation involving 13,829 previously overlooked SKUs. Those products moved from zero activity to 198,774 impressions, 1,617 clicks, $5,072.17 in cost, 24.42 conversions, and $5,161.70 in conversion value. That produced 101.77% ROAS during the recovery period.

    Those figures demonstrate that an isolated campaign can restart data collection; they are not a general benchmark for profitability. The result came from one early implementation, and its stated objective was rehabilitation rather than maximizing immediate ROAS. The decisive test comes later: whether graduated products retain useful performance after returning to their normal campaign structure.

    Measure discovery separately from harvest performance

    A mature Shopping campaign usually optimizes around revenue, conversion value, or ROAS. A product-recovery campaign has an earlier job: determine which neglected SKUs can attract qualified attention and build enough evidence to rejoin the main system. Applying only the mature campaign’s efficiency target can recreate the same feedback loop you are trying to break.

    That does not mean cost is secondary or unlimited. Automation can spend quickly, so define the campaign budget, the maximum acceptable loss, and the conditions for stopping an unproductive SKU before launch. Discovery is a learning objective, not permission to buy data indefinitely.

    Track each entry cohort through a measurement ladder:

    1. Eligibility: How many products passed the data, availability, margin, and operational checks?
    2. Activation: What percentage of entering SKUs received at least one impression?
    3. Engagement: What percentage received at least one click, and how much did that engagement cost?
    4. Commercial evidence: Which SKUs generated conversions or conversion value while in recovery?
    5. Graduation: What percentage met the exit condition and returned to the original campaign?
    6. Post-return performance: Did graduated SKUs continue receiving impressions, clicks, conversions, and value after re-entry?
    7. Incrementality: Did the process produce more total catalog value, or merely redistribute traffic that other products would have captured?

    Keep the cohort log at product level. At minimum, record the SKU, entry date, reason for entry, prior campaign, recovery impressions, clicks, cost, conversions, conversion value, exit date, exit reason, destination campaign, and post-return results. This record becomes more important as AI matching reduces your visibility into exactly how every query was interpreted.

    Four simple derived metrics make the operation easier to manage:

    • Activation rate = SKUs with an impression divided by SKUs entering recovery.
    • Engaged-product rate = SKUs with a click divided by SKUs entering recovery.
    • Graduation rate = SKUs meeting the exit rule divided by SKUs entering recovery.
    • Cost per graduated SKU = total recovery spend divided by the number of graduates.

    These metrics won’t replace revenue or ROAS. They tell you where the recovery mechanism is working or failing before you evaluate downstream commercial value.

    Observed patternWhat it may meanFirst place to inspect
    No impressionsThe SKU may still be ineligible, poorly routed, or too weakly described to enter auctionsFeed status, custom label, campaign inclusion, exclusions, and core product attributes
    Impressions but no clicksThe product may be eligible without appearing relevant or competitive to the shopperTitle, image, differentiating attributes, price, and fit between product and intended use
    Clicks but no commercial actionThe ad may create interest that the offer or landing experience does not convertPage consistency, availability, variant selection, price, purchase friction, and conversion tracking
    Conversions in recovery but little activity after graduationThe main campaign may be suppressing the product againCore campaign segmentation, prioritization, and the graduation rule
    Spend rises while graduation stallsThe cohort may contain weak products or permissive entry rulesLoss ceiling, SKU economics, retirement criteria, and eligibility gate

    Treat these as diagnostic starting points, not automatic conclusions. Several causes can produce the same pattern. A click without a conversion, for example, could reflect the offer, the landing page, measurement, or simply insufficient evidence. Inspect the full path before changing bids or removing the SKU.

    If you need to estimate incrementality, keep a comparable group of eligible products outside the recovery campaign or introduce cohorts in stages. Compare total catalog outcomes, not only the isolated campaign’s dashboard. Without a comparison, a rise inside the recovery campaign cannot tell you how much demand was genuinely added versus shifted from another product or campaign.

    Key takeaways

    • AI Max expands the range of Search intent Google may be able to monetize, while a Performance Max recovery campaign can give overlooked products a separate route back into consideration.
    • Better matching begins with discriminating product facts carried consistently across the feed, creative, visible landing page, and structured data.
    • A low-traffic SKU is not automatically a bad product. Separate products that lack opportunity from products that are unavailable, uneconomic, seasonal, or genuinely unwanted.
    • Use explicit entry, exclusion, graduation, retirement, and loss rules. A recovery campaign should be a controlled system, not a permanent holding area.
    • Measure activation, engagement, graduation, and post-return performance before deciding whether the process creates durable value.
    • Google’s aggregate lift figures are directional context, not targets for your account.

    Your practical next step is to export product-level performance for a lookback period that fits your purchase cycle. Filter for sellable SKUs that received no meaningful opportunity, inspect their product records, and admit only the clean, viable candidates to a bounded recovery cohort. Give every SKU an entry reason, an exit condition, a loss ceiling, and a scheduled post-return review. That is how AI-powered reach becomes a product-discovery system you can govern rather than another opaque campaign setting.
    References

  • Gemini 3.5 Flash-Lite in Google Search: SEO Action Plan

    Gemini 3.5 Flash-Lite in Google Search: SEO Action Plan

    If you manage organic visibility, the wrong reaction to a new Search model is to rewrite the site around its name. Your first question should be narrower: which Search experience is using the model, and what does that experience need from your content?

    Gemini 3.5 Flash-Lite matters because Google has connected it to agentic Search. That makes task completion, clear constraints, and reliable structured data more important areas to examine. It does not give you evidence that traditional ranking signals changed or that every AI answer now runs on this model.

    What the rollout confirms, and what it does not

    Google has begun rolling Gemini 3.5 Flash-Lite into Google Search. Its explicitly identified Search use is agentic Search. Possible use in AI Overviews or AI Mode has not been confirmed, so treat those surfaces as open questions rather than established placements.

    Google positions Flash-Lite as its fastest and most cost-effective model in the 3.5 class. The launch claim puts its generation rate at 350 output tokens per second on the Artificial Analysis Index. Google also says it improves substantially on earlier Flash-Lite generations in agentic workflows.

    Do not turn that benchmark into an SEO metric. Output tokens per second describe model-generation throughput under benchmark conditions. They do not establish faster crawling, faster indexing, a ranking change, a preferred page length, or a higher probability of being cited. A page does not become more suitable for Flash-Lite merely because it is shorter.

    The strategic implication is more subtle. An agentic workflow may need to interpret a goal, identify requirements, retrieve information, compare options, and determine a next step. A fast, economical model makes repeated model work more practical. That is a reasonable inference from the model’s positioning, not a disclosed map of Google’s Search pipeline.

    Keep three layers separate when you assess the impact:

    • Retrieval eligibility: whether Google can crawl, understand, index, and retrieve the page for a relevant query.
    • Answer usability: whether the page contains a clear passage that can support a direct response.
    • Task usability: whether an agent can identify required inputs, constraints, actions, failure conditions, and a verifiable outcome.

    The rollout points most clearly toward the task-usability layer. It does not prove that the retrieval layer has been replaced. Continue fixing indexing, internal linking, canonicalization, content quality, and intent alignment; then add the information an agent would need to use the page safely.

    Make important pages usable inside an agentic task

    Illustrated webpage modules connected by a clear automated path to a task completion symbol.

    A conventional informational page can succeed after answering what something is. A task-oriented page has to go further. It should help a system decide whether the instructions apply, what must be available before work begins, what sequence matters, and how completion can be checked.

    Give each task a visible contract

    For pages that support setup, migration, comparison, troubleshooting, booking, purchasing, or another action, make the operating conditions explicit:

    • State the outcome near the start. Tell the reader what will be completed, selected, configured, or decided.
    • Name the required inputs and prerequisites. Include account access, compatible systems, source data, permissions, or materials when they matter.
    • Separate hard constraints from preferences. A compatibility requirement should not be presented with the same weight as an optional recommendation.
    • Use an ordered procedure where sequence affects the result. Do not scatter dependent actions across unrelated sections.
    • Describe the completion state. Tell the reader what success looks like and what evidence confirms it.
    • Expose common blocking conditions at the step where they occur. A failure mode buried in a closing paragraph is hard for both people and agents to use.

    Consider a page about moving an analytics configuration from one platform to another. A broad explanation of migration is not enough. The useful page identifies the source and destination, required access, fields that carry over, fields that do not, authentication requirements, verification steps, and a safe response when validation fails. Those details turn a readable page into an actionable resource.

    Write answer units that remain clear when extracted

    Search systems may use only part of a page when answering a question or supporting a task. Each important section should therefore make sense without relying on several earlier paragraphs.

    • Use a descriptive heading that names the question, condition, or action covered by the section.
    • Put the direct answer immediately beneath that heading, then add reasoning, exceptions, and examples.
    • Repeat the subject when a pronoun would become ambiguous outside the surrounding paragraph.
    • Label versions, units, eligibility conditions, and geographic limits beside the claim they qualify.
    • Use tables only when the reader genuinely needs to compare the same attributes across alternatives.
    • Keep critical instructions in visible page text, even when a video, image, calculator, or interactive control also presents them.

    This does not mean flattening every page into fragments. Context still matters when a recommendation depends on trade-offs. The aim is to make each decision-bearing passage complete enough to extract without changing its meaning.

    Use JSON-LD as a consistency layer

    JSON-LD should encode what the visible page actually says. It cannot compensate for vague copy, missing prerequisites, or contradictory product details. Choose the most specific Schema.org type that truthfully represents the page, and keep identifiers and properties aligned with the content users can see.

    • Use the same entity name, URL, identifiers, and defining attributes across related pages.
    • Keep price, availability, status, dates, authorship, and other changing facts synchronized between markup and visible content.
    • Remove obsolete properties when the underlying fact is no longer present; do not leave historical values in the graph.
    • Do not invent questions, reviews, ratings, offers, or capabilities merely to populate a schema type.
    • Connect closely related entities only when the relationship is real and supported on the page.

    Fast inference does not repair stale facts. If your copy says one thing and your structured data says another, you have created uncertainty at the exact point where an agent needs a dependable value. Update the page and its markup as one publishing operation.

    Measure the Search surface before attributing a result

    An analyst examines signals from three separate abstract search interfaces before the pathways merge.

    A model can change behind Search without giving you a clean model-level report. That makes casual before-and-after conclusions especially risky. A traffic movement near the rollout is correlation until you can connect it to a query, a visible Search experience, and a changed user path.

    Build an observation record your team can reproduce

    For the queries that matter commercially or operationally, record:

    • The query and its intended task, such as learning, comparing, troubleshooting, or completing an action.
    • The location, device context, account state, and other conditions needed to repeat the observation.
    • The visible Search experience, using Google’s displayed label rather than your own guess about the underlying model.
    • The response, proposed actions, linked pages, and any apparent handoff between steps.
    • Your page’s Google Search Console impressions, clicks, and click-through rate for the relevant query-page pair.
    • On-site sessions and meaningful outcomes in your analytics system.
    • Site releases, content edits, technical incidents, campaigns, and demand changes that could explain the movement.

    Keep these evidence types separate. Search Console can show organic query and page performance. Analytics can show what visitors did after arrival. Manual observations or an AI-visibility platform can document answer-surface behavior. None of those, by itself, identifies Gemini 3.5 Flash-Lite as the cause.

    Test task clarity with controlled page updates

    Start with pages already associated with task-oriented demand. Group pages by comparable intent, document the baseline, and make a coherent improvement such as exposing prerequisites, adding verification criteria, or resolving markup inconsistencies. Annotate the publication date and retain an unchanged comparison group when your site structure allows it.

    Judge the change at several levels. First check whether the revised passage is indexed and retrieved for the intended query. Then check whether the Search response represents its conditions accurately. Finally, examine qualified visits and completed outcomes. An increase in impressions with worse qualification is not automatically a win, and a changed AI response without any business effect is not automatically a loss.

    Avoid the most tempting false positives

    • Do not label an AI Overview change as a Flash-Lite change. Use in AI Overviews remains unconfirmed.
    • Do not label an AI Mode change as a Flash-Lite change unless Google identifies the connection.
    • Do not infer a ranking-system update from a model deployment alone.
    • Do not treat different wording as evidence that retrieval or citation behavior changed.
    • Do not publish thin variants for the model name. They add duplication without answering a distinct user need.
    • Do not shorten comprehensive pages to match the 350-token-per-second benchmark. Throughput is not a content-length recommendation.

    The useful standard is simple: describe what you observed, preserve the context, and reserve causal language for evidence that actually identifies the cause.

    Key takeaways

    • Gemini 3.5 Flash-Lite is rolling into Google Search, with agentic Search as the explicitly identified use.
    • Its reported generation speed and cost positioning do not establish a new ranking factor, preferred page length, or citation advantage.
    • Prioritize pages that support tasks: expose prerequisites, constraints, ordered actions, failure conditions, and a verifiable completion state.
    • Keep visible facts and JSON-LD synchronized so an agent does not have to resolve conflicting values.
    • Measure AI Overviews, AI Mode, agentic experiences, ordinary search performance, and on-site outcomes as distinct evidence streams.
    • Do not attribute a Search change to Flash-Lite unless the model-to-surface connection is confirmed.

    Open the task page with the greatest business value and read it as an agent would: identify the goal, required inputs, constraints, next action, and proof of completion. Add whatever is missing, synchronize the markup, and begin logging the relevant Search experiences. That work remains valuable even as Google changes which model handles the task.

    References

  • Google’s AI Search Click Claims Raise Measurement Questions

    Google’s AI Search Click Claims Raise Measurement Questions

    Google says AI-powered results are generating substantial traffic for websites, but the headline number does not settle the debate over whether publishers are receiving a fair share of search visits. The more useful question for site owners is how that aggregate claim relates to their own impressions, clicks and conversions.

    Search Engine Land reported the claim alongside evidence pointing in the other direction. That tension makes measurement and transparency more important than any single traffic total.

    What Google is claiming about AI-driven clicks

    According to Search Engine Land, Google executive Nick Fox said Search sends billions of clicks to the web each day. He also said AI features within Search now send billions of clicks to websites each week.

    Fox’s explanation is that allowing people to ask a wider range of questions encourages greater use of Google Search. He presented that increased activity as a source of additional outbound traffic rather than evidence that Search is becoming a closed destination.

    The reported statement is notable because, as Search Engine Land observed, it is the first time Google has described the volume of website clicks from its AI search features in these terms. It remains a broad company claim, however, rather than a dataset publishers can independently examine.

    Why a large total does not resolve the publisher concern

    Billions of weekly clicks can sound conclusive while leaving several important questions unanswered. An aggregate count does not reveal how clicks are distributed among websites, how the total compares with earlier periods or what proportion of AI-result impressions produce an external visit.

    Large overall totals and falling click rates are not automatically contradictory. Both could occur if search usage expands while a smaller percentage of individual searches leads to a website. That is a general measurement distinction, not proof that it explains Google’s results.

    The counterevidence cited by Search Engine Land illustrates the gap. One referenced study put zero-click searches at 68%, while another report associated AI Overviews with a 42% reduction in clicks. Those findings use different frames from Google’s overall totals, so they should not be treated as direct like-for-like comparisons. They do show why publishers want more detailed evidence.

    Futuristic web browser and analytics dashboard overlap amid neon data streams, illustrating the convergence of SEO, PPC and AI-driven search marketing.
    Organic visibility, paid media and artificial intelligence merge into one connected search ecosystem, where vivid data streams link a creative website with a powerful analytics dashboard.

    Key takeaways

    • Google says Search delivers billions of website clicks daily and that its AI features account for billions weekly.
    • The claim describes total scale but does not show click-through rates, historical changes or traffic distribution.
    • Studies cited by Search Engine Land report substantial zero-click behavior and lower click activity when AI Overviews appear.
    • Site owners should evaluate their own search performance instead of treating an ecosystem-wide total as a traffic forecast.

    What site owners can measure now

    Publishers cannot reconstruct Google’s global figures from their own analytics, but they can examine whether search visibility is still producing business value. The most useful review compares impressions, clicks, click-through rate and conversions over consistent periods, with separate attention to query groups and landing-page types.

    A page can gain impressions while losing clicks, or preserve traffic while attracting visitors with different intent. Looking only at total sessions can hide those changes. Likewise, rankings alone do not show whether a search feature answers the user’s question before a visit occurs.

    Search Engine Land also noted Google’s work on preferred sources, recipe links and link presentation within AI experiences. These changes suggest that link placement remains an active product issue, but their practical effect should be judged through observable performance rather than assumed from the existence of a feature.

    The data needed to make the claim meaningful

    The core limitation is the absence of enough disclosed data to test Google’s framing. Search Engine Land reported that Google has not shared the underlying click information, even as AI performance reporting has reached Google Search Console users.

    Useful context would distinguish conventional results from AI features, show changes over time and clarify whether traffic is concentrated among a small group of destinations. Without that detail, Google’s statement establishes scale but not the impact on a typical publisher.

    As AI results evolve, the debate will move forward only when broad traffic claims can be compared with consistent, feature-level measurements. Until then, publishers have good reason to treat both Google’s totals and alarming decline studies as signals requiring context, not complete verdicts.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google AI Mode Visibility Is Splitting Into Three Channels

    Google AI Mode Visibility Is Splitting Into Three Channels

    Commercial visibility in Google AI Mode is developing along several paths at once. Advertisers can buy placements, publishers and brands can earn citations, and businesses can appear through Google-hosted profiles or product panels.

    Two separate reports show why these surfaces should not be treated as one ranking system. Paid coverage is expanding across commercially valuable queries, while Google is also becoming a more prominent source inside its own AI-generated answers. The practical payoff is a clearer way to assign budgets, ownership and measurement.

    Key takeaways

    • CrushPress.AI’s summary of an SE Ranking study reported text ads on 29.45% of the commercial AI Mode queries examined.
    • Ad incidence rose with keyword cost, but the study did not find the same relationship with search volume or keyword difficulty.
    • Paid placement provided little overlap with cited or traditionally ranked URLs, indicating that advertising, citations and organic search require separate strategies.
    • A second CrushPress.AI report said google.com became AI Mode’s second-most-cited domain in Profound’s tracking, driven mainly by Google Business Profiles and Product Knowledge Panels.
    • Commercial visibility therefore depends on both website performance and the quality of information presented on Google-controlled surfaces.

    Commercial visibility now has three distinct layers

    The reports describe complementary changes rather than competing explanations. The SE Ranking analysis covered paid text placements, whereas Profound tracked the domains AI Mode cited. Together, the findings suggest that appearing near an AI-generated response can happen through three substantially different mechanisms: an ad auction, selection as a cited source, or a Google-hosted information surface.

    The distinction matters because each layer answers a different business need. Advertising can provide purchased exposure on a relevant query. A citation can establish a website as supporting material for the generated answer. A Google Business Profile or Product Knowledge Panel can present decision-making information without requiring the user to reach the company’s website first.

    Profound’s tracking, as summarized by CrushPress.AI, found that citations to google.com increased 8.4-fold in roughly two months, making it the second-most-cited domain in the data. The report attributed almost all of that increase to Google Business Profiles and Product Knowledge Panels. Its analysis ran from April 15 through June 30 and covered more than 32 million google.com/searchviewer instances.

    The reported shift was especially relevant to local searches in hospitality and travel, home services, restaurants and dining, real estate, and healthcare. For product-oriented queries, panels appeared more often around comparisons, compatibility and specifications. These are situations in which structured facts can influence consideration before a conventional website visit.

    Paid reach follows commercial value, not general popularity

    CrushPress.AI’s account of the SE Ranking study reported ads across 14,733 queries, or 29.45% of the commercial searches analyzed. The study examined 50,032 U.S. keywords across 20 niches, using results collected on June 30. It focused on queries eligible for text ads and excluded product carousels.

    Cost per click was the clearest reported indicator of whether an ad appeared. Ad incidence was 24.33% among keywords with CPCs below $2, 32.45% in the $2-to-$10 group and 53.56% for keywords at $10 or more. Search volume and keyword difficulty did not show the same relationship in the study. This pattern supports a cautious interpretation: AI Mode ad deployment appears more closely aligned with the economic value of a query than with its popularity or organic competitiveness alone.

    When an ad block appeared, it usually included more than one advertiser. The study found two ads in 71.1% of ad-triggering responses and one ad in the remaining 28.9%. Category results varied sharply, from a reported 72.38% ad rate for pets to 2.64% for healthcare. Those differences warn against using the overall 29.45% rate as a forecast for every market.

    The study also noted that AI Mode results can vary between sessions. Its percentages should therefore be read as observations from the stated collection date and methodology, not permanent delivery guarantees. The source further cautioned that the pattern could change as Google introduces more AI-specific advertising formats.

    Buying an ad does not secure the other layers

    Three separate glass corridors contain bid tokens, connected source pages, and a digital storefront with products.

    The most consequential finding for planning was the limited overlap between advertisers and unpaid visibility. According to the SE Ranking analysis summarized by CrushPress.AI, only 11.53% of advertiser domains appeared among cited sources for the keywords on which they advertised. At the individual URL level, overlap fell to 1.95%.

    Traditional organic results showed a similar separation. Just 2.32% of advertised URLs also ranked organically for the corresponding queries, while domain-level overlap reached 15.35%. In other words, approximately 85% of advertisers did not appear in organic results for the same keywords, according to the source.

    Visibility comparisonReported overlapPlanning implication
    Advertiser domain and cited domain11.53%Paid reach is not a substitute for earning citations.
    Advertised URL and cited URL1.95%The landing page is rarely the exact source selected for the answer.
    Advertiser domain and organic domain15.35%Advertising and domain-level organic visibility remain largely separate.
    Advertised URL and organic URL2.32%Buying exposure does not ensure that the same page ranks.

    The researchers reportedly compared advertisers with similar non-advertising domains while accounting for domain strength, backlinks, referring domains and organic visibility. Even so, the findings are observational. They do not establish that advertising causes or prevents citation and ranking outcomes. They do show that purchasing an AI Mode placement should not be assumed to improve either one.

    A practical operating model for AI Mode visibility

    An operations table is divided into zones for paid media, source citations, and product profiles, each with separate measurement tools.

    Organizations can respond by assigning each visibility layer a distinct job. Paid-search teams can evaluate AI Mode ads according to query economics, placement availability and conversion performance. SEO and content teams can monitor whether the brand’s pages are cited or ranked, then improve the relevance and usefulness of the pages intended to earn that exposure.

    Local and commerce teams need a third workstream for Google-hosted information. Business hours, locations, photos and reviews can become part of the AI Mode experience through Google Business Profiles. Product specifications and compatibility information may surface through Product Knowledge Panels. Because those details can be encountered before the website, maintaining them is part of commercial presentation rather than a secondary listing task.

    Reporting should preserve the same separation. A combined visibility score can conceal whether progress came from spending more, earning stronger source selection, improving organic rankings or maintaining a more complete Google-hosted profile. Channel-specific reporting makes it possible to connect each outcome to the team and investment responsible for it.

    The next useful evidence will be longitudinal: whether ad incidence continues to rise, whether new formats change advertiser competition, and whether Google’s share of citations remains concentrated in its own local and product surfaces. Until those patterns are clearer, the sound approach is to manage AI Mode as a portfolio of paid, earned and platform-hosted visibility rather than as a single search position.

    References

  • How Meta AI Mode Changes Search and Discovery on Facebook

    How Meta AI Mode Changes Search and Discovery on Facebook

    Meta AI Mode changes Facebook Search from a results-finding tool into an answer-generating experience. According to CrushPress.AI’s report, Meta AI can respond to broad or specific queries using public material from Groups, Reels and other parts of Meta’s ecosystem.

    The immediate benefit is a faster route to community knowledge. The larger consequence is that an AI system now mediates which experiences, recommendations and brand discussions become visible, while important details about selection and attribution remain undisclosed.

    Facebook Search is moving from retrieval to synthesis

    The supplied report describes a departure from the familiar list of search results. Instead of requiring people to open and compare multiple items, AI Mode can assemble a direct response from relevant public content.

    This distinction matters. A conventional search interface leaves much of the evaluation to the user: results are displayed, sources can be inspected and conclusions are formed afterward. An answer interface performs some of that work before the user sees the output. Source selection, interpretation and presentation therefore become part of the search experience rather than steps taken entirely by the searcher.

    CrushPress.AI also reported that Meta AI can surface relevant public content as people navigate Facebook, extending discovery beyond a single results page. That suggests a closer connection between intentional search and recommendations encountered elsewhere in the product, although the report does not provide performance data showing how often this occurs.

    The feature shares the AI Mode name used by Google, as the report notes. The common label should not be treated as evidence that the two products use the same sources, ranking systems or answer-generation methods.

    Community experience is the central search asset

    A diverse group shares posts and videos that flow through a central AI lens.

    Facebook’s distinctive contribution is not simply an AI-written summary. It is the underlying pool of public conversations and creator material. The report positions Groups and Reels as sources of experience-based information about products, places, hobbies and everyday questions.

    This can make Facebook Search particularly relevant when a query benefits from practical opinions rather than a single canonical answer. A discussion may reveal how different people approached a problem, while a Reel may demonstrate an activity or product in context. AI Mode can potentially connect those formats in one response instead of making the user search each surface separately.

    The same strength creates an editorial challenge. Community posts can contain conflicting perspectives, incomplete context or highly individual experiences. An AI-generated answer necessarily decides which material to foreground and how to reconcile it. The usefulness of the response therefore depends not only on the available conversations but also on selection and synthesis decisions that the supplied report says Meta has not explained.

    Key takeaways

    • Meta AI Mode provides generated answers instead of relying solely on a conventional list of Facebook search results.
    • The reported source material includes public content from Groups, Reels and other surfaces within Meta’s ecosystem.
    • The feature could reshape discovery for recommendations, local information, hobbies, products and brand conversations.
    • Meta has not disclosed enough detail to establish how sources are selected, ranked or credited.
    • Brands and publishers should treat AI Mode as an emerging discovery layer, not as a channel with proven optimization rules.

    The visibility question has three unresolved layers

    A user observes social content passing through three translucent filtering layers before reaching an AI answer.

    The first unknown is eligibility. The report repeatedly identifies public content as the foundation for answers, but it does not define the complete eligible corpus or explain whether every type of public post is treated similarly.

    The second is selection. CrushPress.AI reported that Meta has not explained how particular posts, Groups or Reels earn inclusion. This leaves brands, creators and community administrators without a documented way to distinguish content that is merely available from content likely to influence an answer.

    The third is attribution. The report says it is unclear whether brands, creators or publishers will be informed when their content is used. That gap affects more than recognition. Without consistent source visibility or reporting, content owners may struggle to connect participation in Facebook conversations with AI-mediated exposure.

    CrushPress.AI further reported that the experience uses Meta AI and Muse Spark, while noting that Meta has not disclosed how Muse Spark affects ranking, source selection or answer generation. Until those roles are clarified, claims about a reliable Facebook AI optimization formula would be speculative.

    A practical response without invented ranking tactics

    Organizations can begin by separating content quality from presumed algorithmic influence. Public posts that clearly identify the subject, explain the circumstances and provide useful context are easier for people to understand regardless of whether AI Mode selects them. Specificity is a sound communication practice, but the supplied reporting does not establish it as a ranking factor.

    Brands can also examine the public discussions that already surround their products, locations or services. The goal is to understand the questions and language used by communities, not to flood those spaces with promotional material. Because AI Mode draws on public social interactions, genuine community participation may become more consequential even when a brand does not control the eventual summary.

    Where the feature is available, teams can document representative queries, the answers displayed, the content formats surfaced and any visible attribution. Repeating the same checks over time can reveal changes in presentation or source patterns. Such observations remain local tests, however, and should not be generalized into universal ranking rules without broader evidence.

    The decisive next development will be greater clarity about selection, attribution and measurement. Until Meta supplies it, the most defensible approach is to treat AI Mode as a new interface between public conversation and discovery: important enough to monitor, but too opaque for confident optimization promises.

    References

  • Google AI Search Ads: Access, Control and Measurement

    Google AI Search Ads: Access, Control and Measurement

    Google’s AI-enhanced search experiences are changing more than ad placement. They are separating campaign management into three distinct questions: how advertisers gain access to AI Search inventory, how they guide automated decisions, and how they measure results when reporting remains incomplete.

    The supplied CrushPress.AI report, based on a discussion involving Google Ads Liaison Ginny Marvin and the PPC Chat community, offers useful answers across those questions. Viewed together, its details point to a system in which participation remains relatively open, but effective optimization increasingly depends on strong data and carefully defined instructions.

    Key takeaways

    • AI Max is not reported to be a prerequisite for ads to appear in AI Overviews or AI Mode.
    • Broad match can provide a route into AI Search inventory, while AI Max can extend matching beyond the advertiser’s explicit keyword set.
    • AI Search ads do not yet have a distinct reporting breakdown, limiting advertisers’ ability to isolate their contribution.
    • Google’s direction combines automated matching with advertiser guidance, first-party data and measurement designed for longer conversion cycles.

    AI Search eligibility is broader than AI Max

    One of the most consequential distinctions in the report is between eligibility and expansion. According to CrushPress.AI’s account of Marvin’s comments, advertisers do not need to enable AI Max merely to participate in Google’s AI-driven search experiences. Search campaigns using broad match keywords can still be eligible for AI Overviews and AI Mode.

    AI Max instead appears to widen the matching opportunity. The report says it can apply broad-match behavior to phrase and exact match keywords while also enabling keywordless matching. That makes AI Max less of an admission ticket and more of an additional discovery mechanism.

    This distinction should shape campaign decisions. An advertiser can evaluate AI Search exposure separately from the decision to grant Google more latitude in matching queries. The relevant question is therefore not simply whether to adopt AI Max, but whether its broader reach fits the campaign’s economics, message constraints and tolerance for automation.

    Reporting has not caught up with the new inventory

    An analyst examines fragmented advertising signals as some data paths vanish behind translucent blank reporting panels.

    Access to AI Search inventory does not currently come with equivalent visibility. The source reports that ads appearing in AI Overviews and AI Mode are recorded like other top-of-page ads, without a separate reporting breakdown. It also says Google was still determining what dedicated reporting should eventually look like.

    That creates an important analytical limitation. Advertisers may participate in AI Search without being able to isolate its traffic, conversion performance or incremental value from standard search placements. A campaign-level improvement cannot automatically be attributed to AI inventory, while a weak result does not reveal whether the problem arose from an AI placement, another top-of-page impression or a broader campaign setting.
    Until reporting becomes more granular, AI Search should be treated as part of the campaign’s combined delivery environment. Conclusions about its standalone effectiveness would go beyond the evidence available in the reported interface.

    AI Brief and first-party data serve different roles

    The report describes AI Brief as a forthcoming control layer for AI Max. Advertisers are expected to be able to supply guidance covering matters such as target audiences, preferred message themes, priority search intents and prohibitions including instructions not to mention prices. CrushPress.AI says the rollout was planned to begin with English-language Search campaigns before extending to Performance Max and Shopping campaigns.

    Those instructions and an advertiser’s data are complementary rather than interchangeable. AI Brief can communicate strategic boundaries: whom a campaign should address, which ideas it should emphasize and what it should avoid. First-party data provides signals about actual customer and conversion outcomes.

    CrushPress.AI reports that Google emphasized data quality through a concept called Data Strength and pointed to Enhanced Conversions and Google Tag Gateway as important tools. The broader implication is that automation does not eliminate foundational measurement work. If the underlying signals are incomplete or unreliable, more sophisticated matching and creative guidance cannot supply the missing business evidence.

    Measurement is moving toward longer customer journeys

    A shopper follows a winding path across several digital touchpoints while interaction signals converge into a measurement lens and a secure data vault supports the journey.

    Qualified Future Conversions, or QFC, represents another part of Google’s reported direction. The source describes it as a metric that estimates potential conversions occurring within 180 days after an ad interaction. It was reportedly being tested with selected advertisers and was presented as especially relevant to B2B and lead-generation businesses with lengthy sales cycles.

    QFC addresses a different measurement problem from the missing AI Search breakdown. Dedicated placement reporting would help advertisers understand where an interaction occurred; a future-conversion estimate is intended to help evaluate what that interaction may eventually produce. Neither capability substitutes for the other.

    The report also identifies new AI Search ad formats, QFC and YouTube Creator Partnerships as three areas Marvin highlighted after Google Marketing Live. Together, those priorities suggest attention to discovery, delayed outcomes and creator-led reach. For search advertisers, the immediate challenge is to prepare reliable inputs and explicit campaign guidance while avoiding stronger claims about AI-specific performance than the available reporting can support.

    What advertisers should prepare next

    The most durable preparation is not adoption of every automation feature. It is a campaign structure that can accommodate wider matching without losing strategic intent, supported by dependable conversion signals and documented messaging boundaries. As AI-specific controls and reporting develop, advertisers with those foundations will be better positioned to test new inventory and interpret the results responsibly.

    References

  • How to Prepare Your Store for Google’s AI Shopping System

    How to Prepare Your Store for Google’s AI Shopping System

    Your products can be easy to find in Google and still be poorly prepared for an AI-assisted purchase. Discovery is only the first test. A product must also be understood, matched with an eligible offer, placed in a cart, and purchased without its price, availability, or terms changing along the way.

    Google is connecting those jobs across Merchant Center, Google Ads, AI Mode, Gemini, Search, Maps, YouTube, Google Pay, and the Universal Commerce Protocol. If you manage ecommerce visibility, your work now extends from SEO and feed optimization to promotion rules, checkout integrity, and AI-specific measurement.

    Google’s shopping stack now connects four different jobs

    Google’s AI shopping ecosystem is easier to understand as a transaction path than as another search feature. At Google Marketing Live 2026, the company connected conversational product discovery, personalized promotions, cross-retailer carts, checkout, payments, and performance reporting.

    LayerWhat Google is addingWhat you control
    DiscoveryConversational Attributes and description updates for matching products to natural-language shopping requestsAccurate, complete, variant-specific product facts
    RecommendationDirect Offers selected with Gemini from eligible discounts, giveaways, local coupons, and bundlesOffer eligibility, commercial limits, exclusions, and campaign guardrails
    TransactionUCP connections among catalogs, carts, checkout, and paymentsReliable product, price, inventory, checkout, and order data
    MeasurementAI Performance Insights and competitive share-of-voice reportingThe business metrics used to judge whether visibility produces valuable orders

    This distinction matters because each layer can fail independently. A product can be eligible but never recommended. It can be recommended with an unsuitable promotion. The offer can be accepted, only for checkout to reject it. A high AI share of voice can also coexist with weak revenue or poor margins.

    Availability is uneven. Conversational Attributes are launching globally, while AI Performance Insights are expected in the United States, Australia, Canada, India, and New Zealand. Direct Offers remains a United States pilot. The new UCP-powered capabilities are rolling out in the United States, with wider expansion expected later. Account access and geography should therefore be go-or-no-go checks before you assign launch dates or forecast revenue.

    Make product data answer the shopper’s decision question

    A countertop appliance is surrounded by visual attribute tiles connected to symbols representing a shopper's needs.

    A conversational product description is not simply a conventional description rewritten in a friendlier tone. It should supply the facts an AI system needs when someone asks a question such as: Will this fit my situation? Which variant is appropriate? What limitation should I know about? What makes this option different from a similar one?

    Merchant Center’s Conversational Attributes let merchants add structured details and update descriptions that Google’s AI can use across AI Mode, Gemini, and other AI shopping environments. That makes factual coverage more valuable than decorative copy.

    1. Collect the questions that appear at the point of choice. Look at site search, product comparisons, support requests, sales conversations, and return reasons. Focus on questions whose answers would change which product or variant a shopper selects.
    2. Convert each answer into an atomic, verifiable fact. Useful areas can include intended use, compatibility, dimensions, materials, fit, included components, care requirements, prerequisites, and limitations. Include only the fields that genuinely apply to the product.
    3. Keep variant facts attached to the correct variant. If size, material, capacity, color, compatibility, or included components differ, a family-level description should not imply that every option has the same properties.
    4. Reconcile the value across Merchant Center, the product page, structured data, the cart, and checkout. Different wording is acceptable; a different factual answer is not.
    5. Remove unsupported superlatives and inferred use cases. An AI system should not have to decide what terms such as best, professional, safe, sustainable, or universal mean for your product.
    6. Record where each claim came from inside your business. Product specifications, policy owners, and approved commercial copy should be traceable so that outdated values can be corrected at their origin.

    Your JSON-LD should reinforce the same product identity and supported facts, but it should not be treated as a substitute for the Merchant Center feed. Use properties with literal, accurate values. Do not force conversational phrases into unsupported schema fields or create markup for claims that the visible product page cannot substantiate.

    A practical validation test is simple: choose a real pre-purchase question and follow its answer through the feed, landing page, selected variant, cart, and checkout. If the answer disappears or changes at any stage, you have a data-governance problem before you have an AI optimization problem.

    Put commercial guardrails around every AI-selected offer

    Direct Offers moves promotions closer to the recommendation itself. Advertisers can upload eligible promotions and campaign guardrails through Google Ads, after which Gemini can curate relevant bundles and discounts from the shopper’s query and browsing context.

    That does not make the AI your pricing strategist. Relevance can help choose among approved offers, but it cannot protect margins, inventory, channel commitments, or customer promises that you have not expressed as rules. Before making a promotion eligible, create an internal offer card that answers these questions:

    • Which offer type is this: discount, giveaway, local coupon, or bundle?
    • Which products and variants are included, and which are explicitly excluded?
    • Which locations, audiences, order conditions, or fulfillment methods qualify?
    • Can the offer be combined with another promotion, loyalty benefit, or payment incentive?
    • When does eligibility begin and end, and what happens to an in-progress cart after expiry?
    • Which inventory or fulfillment constraint should stop the offer from appearing?
    • What commercial boundary must the offer preserve, including margin and maximum exposure?
    • Where can the shopper verify the terms before committing to payment?
    • Has the exact offer been tested through the checkout route on which it will appear?

    AI-generated bundles deserve particular scrutiny. Define which items may be combined, how unavailable components are handled, whether substitutions are permitted, and which total prices are valid. If your rules cannot distinguish an attractive bundle from an unprofitable or unfulfillable one, do not make the components available for automated bundling yet.

    Native checkout increases the cost of an offer mismatch because there are fewer remaining steps in which to explain or correct it. The displayed promotion, cart calculation, checkout total, and payment amount must resolve to the same commercial promise. A silent price change at checkout is not an optimization issue; it is a customer-trust and revenue-control failure.

    Travel businesses should apply the same discipline to dates, inventory, inclusions, and cancellation terms. Booking and Expedia are expected to surface travel offers inside AI-assisted trip planning, where an appealing deal can become misleading quickly if its underlying availability or conditions are stale.

    Treat UCP readiness as a catalog-to-payment integration audit

    A cutaway commerce system connects a product catalog, guarded offer controls, a shopping cart, and a secure payment device on a workbench.

    The Universal Commerce Protocol is intended to connect product catalogs, checkout, and payment experiences across Google surfaces. Its Universal Cart can hold products from multiple retailers, with purchase completion through Google Pay or a retailer’s own checkout system.

    For a merchant, that creates more than one possible ending to the journey. You cannot assume that every shopper will pass through the same landing pages, cart interface, recovery messages, or payment presentation. The handoff itself needs to carry enough accurate state for each route to finish honestly.

    1. Confirm product identity. The catalog item, variant, cart line, checkout line, and order record should refer to the same purchasable thing.
    2. Confirm commercial truth. Price, currency, quantity, promotion eligibility, and final total should remain consistent as the shopper moves between systems.
    3. Test stale inventory. A newly unavailable variant should stop cleanly before payment, without being replaced by a different product or option unless the shopper explicitly approves it.
    4. Test expired and ineligible offers. Checkout should explain why an offer no longer applies instead of silently removing it or changing the total.
    5. Test every enabled payment route. Google has announced Affirm and Klarna buy now, pay later integrations with Google Pay, but you should not advertise a financing option until its availability and terms are confirmed for the actual transaction.
    6. Check the post-purchase handoff. Confirmation, customer support, order status, cancellation, and return instructions must still be available when the journey begins outside your normal storefront path.

    Test failure states as deliberately as the successful purchase. Use sold-out variants, expired promotions, rejected payment attempts, and transfers to the retailer checkout. The goal is not merely to prevent an error screen. It is to ensure that no failure produces a false product, price, entitlement, or order state.

    Google also expects UCP to expand into hotel bookings and food delivery. If you sell services or time-sensitive inventory, model dates, availability, fulfillment choices, and cancellation conditions as transaction data. Page copy alone cannot keep a changing reservation state accurate.

    Measure AI visibility without mistaking it for revenue

    AI Performance Insights is designed to show a brand’s performance across AI-driven environments, including share of voice compared with similar competitors. That is useful diagnostic information, but it is not a complete business outcome.

    Share of voice does not tell you by itself whether the right products appeared, whether an offer protected margin, whether a recommendation produced an order, or whether the order was later cancelled or returned. Build a measurement ladder that keeps those questions separate:

    • Data readiness: Track missing attributes, rejected items, variant inconsistencies, stale descriptions, and differences between the feed and product page.
    • AI visibility: Review AI share of voice and product presence by country and product family where reporting is available.
    • Offer performance: Separate eligible, surfaced, accepted, expired, and rejected promotions using the reporting and transaction data available to you.
    • Checkout integrity: Count price mismatches, inventory failures, promotion removals, payment failures, and transfers that do not complete successfully.
    • Business outcome: Evaluate completed orders, revenue, contribution, cancellations, returns, and support costs. A recommendation that creates a costly order is not a successful recommendation.

    Keep a change log for every material feed, attribute, offer, and checkout update. Record the affected products, markets, date, commercial rule, and transaction version. Compare equivalent segments before and after the change, and avoid combining a description rewrite, a new bundle, and a checkout migration into one untraceable launch.

    Ask Advisor is also expected to enter Merchant Center. Use advisory output to find questions worth investigating, not as proof that a diagnosis is correct. Your product records, promotion rules, checkout tests, and completed transactions remain the evidence.

    FAQ: Google’s AI shopping rollout

    Do you need UCP before optimizing for conversational discovery?
    No blanket dependency has been established in these launches. Conversational Attributes are Merchant Center discovery controls, while UCP connects carts, checkout, and payments. Run them as connected workstreams, but do not treat them as the same eligibility switch.

    Should you rewrite every product description in a conversational tone?
    No. Start with missing decision facts, variant accuracy, and consistency. Friendly prose cannot compensate for absent compatibility, fit, material, inclusion, or limitation data.

    Is AI share of voice a primary ecommerce KPI?
    It is better used as a visibility diagnostic. Pair it with offer acceptance, checkout integrity, completed orders, and unit economics before deciding that performance improved.

    Can Google decide which discount your store should offer?
    You supply eligible promotions and campaign guardrails. If an eligibility rule, exclusion, or economic boundary has not been defined and tested, keep that offer out of automated selection.

    Start with a commercially important product family that has clean variant data, dependable inventory, and an offer you can explain in one sentence. Complete its Merchant Center facts, define its promotion rules, test every enabled checkout route, and capture a performance baseline. Expand only after the full path remains accurate. In AI commerce, clear operational truth gives the system fewer opportunities to guess.

    References

  • AI-Powered Ads on Google and Microsoft: A Control Plan

    AI-Powered Ads on Google and Microsoft: A Control Plan

    If you run paid campaigns on Google and Microsoft, the important question is no longer whether AI will touch your advertising. It already influences ad creation, query interpretation, bidding, product discovery, campaign operations, and measurement. Your real decision is which tasks to delegate and which decisions must remain under human control.

    That distinction matters because the two platforms are automating different parts of the job. Google is moving ads deeper into conversational search, discovery, and commerce. Microsoft is reducing the friction of importing, bidding, and reporting across accounts. You need a control plan that reflects those differences, not one generic “AI advertising” switch.

    Decide what AI may decide before you activate it

    A campaign manager controls a transparent gate separating automated advertising tasks from protected human decisions, with several signals paused for review.

    AI-powered advertising is not a single feature. It is a stack of decisions. An AI system can generate an asset, select an audience, adjust a bid, explain a product, recommend an account change, or predict a future outcome. Those actions do not carry the same risk.

    Google’s stack now reaches from Conversational Discovery ads, Highlighted Answers, Shopping explainers, and lead-generation agents to creative production and predictive measurement. Microsoft’s stack emphasizes cross-platform imports, portfolio bidding, attribution, and more configurable reporting. Before adopting any of it, assign a human owner to the decision the system is helping make.

    AI layerPlatform examplesWhat you should control
    Customer interactionConversational Discovery ads, Highlighted Answers, Shopping explainers, and Business Agent for LeadsPermitted claims, qualification rules, escalation paths, and the point at which a person takes over
    Creative productionText, image, and video generation in Asset StudioApproved facts, brand rules, legal review, asset rights, and final publication approval
    Media deliveryDemand Gen optimization and Microsoft cross-account portfolio biddingBusiness objective, budget boundaries, conversion values, exclusions, and stop conditions
    Campaign operationsAsk Advisor and Microsoft Import CenterWhich recommendations become changes, who approves them, and how changes are recorded
    MeasurementMeridian, Qualified Future Conversions, data-driven attribution, and bid-strategy reportingThe definition of success, the quality of conversion data, and whether a result is predictive, attributed, or incremental

    This separation prevents a common mistake: allowing the platform to define the goal while it also optimizes toward that goal. Automation can pursue an objective efficiently, but it cannot decide whether the objective represents profitable growth, a useful lead, or merely an easy conversion.

    Write down the decision rights for every campaign before changing its automation. At minimum, answer these questions:

    • Which conversion should influence bidding, and which events are diagnostic only?
    • What business value is attached to each conversion?
    • Which claims, audiences, locations, products, or queries are outside the campaign’s scope?
    • Can AI-generated assets publish automatically, or must a named person approve them?
    • Which performance change would trigger investigation, a rollback, or a pause?

    If those answers are missing, the campaign is not ready for more autonomy. The problem is governance, not a lack of AI features.

    Fix the input layer before generating ads or answers

    Generative systems multiply whatever you give them. Clean facts become more usable assets. Contradictory facts become more contradictory assets, produced at greater speed.

    This is especially important in conversational advertising. Google’s Business Agent for Leads is designed to answer questions using information from the advertiser’s website. Its Shopping formats can add AI-generated explanations of why a product may fit a shopper’s needs. Merchant Center is also gaining Conversational Attributes and AI Performance Insights for shopping experiences across Search, Gemini, and AI Mode.

    Your website and product feed are therefore operational inputs, not just destinations after the click. If a landing page, product description, promotion, and campaign brief disagree, the model cannot know which version your business intends to honor.

    Prepare a compact campaign truth set before opening a generative tool:

    • Offer facts: the exact product or service, included features, exclusions, availability, eligibility, price conditions, and promotion terms.
    • Approved claims: statements the campaign may make, the evidence behind them, and wording that requires legal or compliance review.
    • Audience intent: the problem being solved, the questions a qualified buyer asks, and the signals that indicate poor fit.
    • Brand rules: tone, visual constraints, prohibited themes, required terminology, and examples of acceptable assets.
    • Product data: consistent titles, descriptions, attributes, images, categories, destinations, and offer details in Merchant Center.
    • Conversion rules: the event that counts, its value, the validation process, and the lag between an ad interaction and a confirmed business outcome.

    Google’s upgraded Asset Studio is designed to interpret marketing briefs, brand guidelines, website content, and campaign goals when generating text, images, videos, and creative themes. That can remove production bottlenecks, but only if those materials are current and internally consistent.

    Use generated creative as a controlled variation, not as automatically approved truth. Check every asset against the offer facts and claims list. Keep the prompt, input materials, output, reviewer, and final disposition together so that you can explain why an asset ran.

    For teams working on SEO, AEO, GEO, and advertising together, align visible page copy, product-feed information, and structured data. JSON-LD cannot repair an inaccurate feed or a vague landing page, and the available platform announcements do not establish schema markup as a direct bidding signal. Its practical role here is consistency: machines and people should encounter the same entity, offer, availability, and business facts wherever those facts appear.

    This becomes more consequential as commerce moves closer to the generated answer. Google has described AI-assisted checkout, Universal Cart, cross-retailer shopping, and buy-now-pay-later integrations, while its Direct Offers pilot includes AI-generated bundles and native checkout for Universal Commerce Protocol merchants. When discovery and transaction happen within the same assisted journey, inaccurate product data has fewer opportunities to be corrected later.

    Give Google and Microsoft different operating roles

    A split illustration contrasts an exploratory product discovery environment with a structured campaign operations room connected by a bridge.

    Running both platforms does not mean cloning one campaign and calling the job complete. Their AI capabilities solve different problems, and your testing plan should reflect that.

    Google is pushing further into the interaction itself. Gemini can interpret a conversational query, assemble an explanation, place a relevant offer within an AI-generated response, or support a lead conversation. Demand Gen can distribute creative and product experiences across YouTube, Discover, Maps, and Shopping. Its expanded tools include creator partnership videos, Merchant Center product videos, Maps inventory, and AI-assisted campaign setup.

    Use Google when you want to test how creative, product data, and assisted discovery work together. The useful question is not merely whether a new format gets more clicks. Ask whether it helps the right user understand the offer, advances that user to a valuable action, and produces a business outcome that survives validation.

    Availability should shape your plan. Conversational Discovery ads and Highlighted Answers were announced as U.S. tests on mobile and desktop. AI-powered Shopping ads and Business Agent for Leads were described for U.S. open beta, while many Demand Gen additions were expanding through open beta globally. Treat tests, pilots, and betas as learning opportunities, not guaranteed inventory in a forecast.

    Microsoft is concentrating more heavily on operational leverage. Its Import Center can search and filter imports from Google Ads and Meta Ads, pause or edit imported campaigns, surface troubleshooting help, and provide recommendations after import. Cross-account portfolio bidding extends automated strategies across Search and Shopping accounts, while new reporting fields make bid targets easier to inspect.

    Use Microsoft to reduce duplicated setup and coordinate related accounts, but do not confuse a successful import with an equivalent campaign. An imported structure can be technically valid while optimizing toward the wrong conversion or carrying assumptions that do not fit its new environment.

    Audit every import before it spends:

    • Confirm campaign status, budgets, bidding strategy, and portfolio membership.
    • Map conversion goals and values to the business outcome you intend to optimize.
    • Review location, audience, product, and inventory scope.
    • Test landing-page URLs and tracking parameters.
    • Recheck negative constraints, brand exclusions, and any setting that limits where an ad can appear.
    • Record differences between the originating campaign and the imported version.

    Cross-account portfolio bidding is most defensible when the participating accounts share compatible goals and value definitions. Pooling signals from unrelated outcomes can make the algorithm look busy without making the portfolio economically coherent.

    The same discipline applies to Google’s Ask Advisor, which connects Ads, Analytics, Merchant Center, and the Google Marketing Platform to help build campaigns, analyze performance, recommend changes, and automate operational tasks. A recommendation should enter your normal approval process. The fact that an assistant can execute a task faster does not change who is accountable for the result.

    Measure decisions, not just automated output

    AI advertising creates more observable activity: more assets, more variations, more bid adjustments, more recommendations, and more predictions. Activity is not evidence of incremental value.

    Build measurement at three levels:

    • Control quality: Did the system stay inside the approved offer, brand, audience, and budget boundaries?
    • Platform performance: What happened to conversions, conversion value, cost per acquisition, return on ad spend, impression share, and other campaign metrics?
    • Business impact: Did leads qualify, transactions hold, revenue materialize, and the campaign add outcomes that would not otherwise have occurred?

    Microsoft’s reporting expansion helps with the middle layer. Advertisers can inspect average Target ROAS, average Target CPA, average Target impression share, conversion metrics in custom columns, and reports segmented by goal name. Data-driven attribution is also available for automated strategies including Maximize Conversions, Maximize Conversion Value, and Enhanced CPC.

    Those fields can show how the platform allocated credit and pursued a target. They do not, by themselves, prove that advertising caused the reported outcome. Attribution distributes credit among observed interactions. Incrementality asks what changed because the campaign ran.

    Google is adding tools for that broader question. Demand Gen includes Uplift Experiments and Campaign Type Attribution. Meridian, Google’s open-source marketing mix model, is being integrated into Analytics 360 to combine first-party and cross-channel data, estimate incremental performance, forecast outcomes, and support media-mix decisions.

    Qualified Future Conversions add another type of evidence. The Gemini-powered metric links current advertising activity with possible future sales signals, including branded search behavior. It was announced as a restricted global pilot, with wider beta access anticipated later. A predictive future-conversion signal is useful for planning, but it is not realized revenue and should not be booked or reported as though it were.

    Use a measurement ladder that matches the maturity of the campaign:

    1. Define the validated business conversion and its value before changing bidding.
    2. Verify that Google and Microsoft receive comparable, correctly classified conversion signals.
    3. Inspect performance by goal so that a rise in easy secondary actions cannot hide a decline in valuable outcomes.
    4. Compare generated assets with your established creative process using the same campaign objective and review rules.
    5. Use controlled uplift testing where it is available to investigate causal impact.
    6. Use marketing mix modeling for cross-channel allocation questions that campaign attribution cannot answer alone.
    7. Treat predictive metrics as planning inputs until the predicted behavior becomes an observed business result.

    Do not optimize a campaign against a forecast and then cite the same forecast as proof that the optimization worked. Separate the signal used to make a decision from the evidence used to evaluate that decision.

    Key takeaways

    • AI-powered advertising is a stack of creative, interaction, delivery, operational, and measurement decisions. Assign human ownership at each layer.
    • Google’s strongest shift is toward conversational discovery, generated product explanations, integrated commerce, and creative distribution across its properties.
    • Microsoft’s strongest shift is toward easier cross-platform imports, coordinated portfolio bidding, attribution, and more transparent reporting.
    • Your website, product feed, campaign brief, brand rules, and conversion definitions must agree before you let generative systems use them.
    • An imported campaign needs a full settings and measurement audit; technical compatibility does not guarantee strategic equivalence.
    • Attributed conversions, incremental outcomes, and predicted future conversions answer different questions. Do not report them as interchangeable results.

    Your next move can be deliberately small. Choose a campaign with a clear conversion, document its approved facts and decision boundaries, and activate only the AI capability whose output you can inspect. Once the measurement holds, expand the system. If the measurement does not hold, more automation will only make the uncertainty harder to unwind.

    References

  • Google’s Agentic Search and Commerce Overhaul: An SEO Plan

    Google’s Agentic Search and Commerce Overhaul: An SEO Plan

    If your search strategy still ends with earning the click, the next version of Google Search creates a blind spot. A user can hand Google an open-ended task, let an agent monitor it, ask Search to assemble a purpose-built interface, and move from comparison to booking or purchase without restarting the journey on your site.

    Your site still matters, but its role expands. It has to be a reliable evidence layer, a clean record of changing commercial facts, and an unambiguous handoff to action. This guide shows you how to audit those layers before you chase speculative agentic SEO tactics or produce more content.

    Google is turning a result page into a task environment

    The familiar search journey has a simple rhythm: query, results, click, website. Agentic Search can stretch that journey across time, combine several kinds of input, construct a temporary tool, and complete parts of the task inside Google’s interface.

    The redesigned Intelligent Search Box supports longer prompts and input from text, images, files, videos, and Chrome tabs. Its suggestions go beyond conventional autocomplete, while the path from an AI Overview into AI Mode becomes easier. That encourages people to express a complete situation instead of compressing it into a short keyword phrase.

    AI Mode is also being shaped around continued work rather than one-off answers. Gemini 3.5 Flash was announced as its default model, with an emphasis on agentic, coding, and multimodal performance. The model name matters less to your strategy than the behaviors it enables: decomposition, synthesis, tool construction, and action.

    Those behaviors now appear in several distinct experiences. Information agents can keep monitoring the web for changes, then return a synthesized update that helps the user act. An apartment search can persist until a qualifying listing appears. A product-release watch can continue until a relevant launch is detected. Local agentic experiences can find services or activities using requirements such as time, availability, price, and specific amenities.

    Search can also generate the interface required by the question. The announced generative UI can assemble visual tools, tables, simulations, trackers, and ongoing dashboards. A page is therefore no longer competing only with another page. Its facts may become inputs to an interface created for one user’s exact task.

    Commerce completes the pattern. Google’s Universal Cart is designed to collect items from multiple retailers, surface in-stock options and deals, identify compatibility problems, account for eligible payment or loyalty benefits, and move the user toward checkout through Google Wallet. Search is moving closer to the decision and the transaction at the same time.

    Key takeaways

    • Optimize for the complete task, not only the opening query. The task may include monitoring, comparison, configuration, booking, or purchase.
    • Treat every important claim as reusable data. An agent needs to identify the subject, value, qualifier, current state, and next action without guessing.
    • Keep visible content, JSON-LD, commercial data, and the action endpoint aligned. A contradiction at any handoff makes the whole journey less dependable.
    • Compete for selection as well as visibility. Price, availability, compatibility, merchant identity, and verifiable benefits can affect which option fits the user’s criteria.
    • Measure accuracy and task completion alongside citations and clicks. A mention with the wrong variant, stale price, or broken booking path is not a useful win.

    The practical shift is from a document-query match to a task-state match. A query asks what is relevant now. A task also carries criteria, changing conditions, previous progress, choices, and a next action. This is not a claim about a newly disclosed ranking factor. It is a more useful model for deciding what your site must make clear.

    Map the journeys Google can now continue without a click

    A person follows one continuous digital path through research, product comparison, monitoring, scheduling, and booking stages.

    Start with the work your customer is trying to complete. Do not begin with a list of keywords or schema properties. Choose a high-value journey and write the user’s full request as it would appear in a conversational search box.

    Task shapeEvidence the task needsWhat to audit on your site
    Monitor for a changeExact criteria, current status, freshness, and a clearly defined change worth reportingPlace the current state and its relevant date together. Keep expired states out of active sections and remove conflicting copies.
    Explain or build a custom toolModular explanations, labeled inputs, relationships, constraints, and expected outputsReplace buried dependencies with explicit steps, definitions, inputs, and decision rules that can stand on their own.
    Compare or assemble optionsEquivalent attributes, compatibility rules, exclusions, and meaningful differencesUse consistent labels across comparable options. State when an option does not fit instead of describing every option as suitable.
    Book a service or experienceService definition, location, time requirements, current pricing and availability, special constraints, and an action pathShow eligibility and booking conditions before the call to action. Check that the destination preserves the service and location the user selected.
    Buy across merchantsProduct and variant identity, price, stock state, deal conditions, compatibility, merchant choice, and checkout pathReconcile changing commercial facts everywhere they appear. Make merchant and variant differences explicit before checkout.

    Use task prompts to find missing information

    A short head term hides the details an agent must resolve. A constrained prompt exposes them. Draft prompts in the same shape as these examples:

    • Monitoring: Track [category] and notify me when [qualifying change] occurs, but exclude [disqualifying condition].
    • Decision: Compare [options] for [use case], subject to [budget, compatibility, location, or timing constraints], and explain the tradeoff.
    • Booking: Find [service] in [area] for [time], confirm [requirement], show current pricing and availability, and provide the booking path.
    • Shopping: Assemble [set of products], verify that the parts work together, identify available merchants and benefits, and provide a purchase path.

    Underline every term that can change the outcome. Those terms become your required evidence fields. If compatibility determines the answer, compatibility cannot remain implicit. If a discount depends on a payment method or loyalty status, the condition has to travel with the discount. If availability differs by location or variant, an unqualified available label is not enough.

    Then trace each required fact through the journey. Where is it stated? Who maintains it? How does it reach the visible page and structured data? What happens when it changes? Does the booking or purchase destination preserve the user’s choice? A missing answer identifies an operational problem, not merely a content gap.

    Run the same five checks against each important page: Can a system identify the exact subject? Can it extract the decisive fact? Is the qualifier attached? Is the value current? Is the next action clear? A page that fails one of these checks may still read well to a person, but it is fragile when its contents are reused in an agentic workflow.

    Make every important fact safe for an agent to reuse

    An abstract AI agent selects verified product, inventory, delivery, return, location, and scheduling records from an organized website data layer.

    Agentic visibility is often lost at the seams. The product page says one thing, the structured data implies another, a category page repeats an old promotion, and the checkout reveals a condition that appeared nowhere else. A human may investigate the discrepancy. An agent asked to make progress has to decide whether the evidence is dependable enough to use.

    1. Write decisive facts atomically. Put the subject and claim together. A direct sentence or labeled field is safer to reuse than a conclusion spread across several paragraphs.
    2. Bind every qualifier to the claim it limits. Location, variant, time, membership, compatibility, and payment conditions should not sit in a distant footnote or unrelated accordion.
    3. Separate changing state from durable explanation. Maintain price, availability, release status, and bookable times in controlled fields. Do not manually echo a changing value throughout descriptive copy unless every copy is updated from the same record.
    4. Align visible content and JSON-LD. Markup should describe the same entity, value, condition, and availability that a visitor sees. Never use structured data to make a stronger or more current claim than the page supports.
    5. Make identity explicit. A product family is not a variant, a marketplace is not necessarily the merchant, and a service category is not a bookable service. Name the exact object to which each fact belongs.
    6. Preserve the action state. A buy, book, or request link should lead to the relevant product, variant, service, or location whenever the destination supports it. Explain any required selection before the handoff.

    JSON-LD is useful here because it can express facts in a machine-readable form, but it cannot repair an incoherent operation. Treat markup as a representation of maintained reality, not as a place to add claims that the rest of the journey cannot honor. If a fact changes too often to keep current on the page, creating additional unmanaged copies of it increases the risk.

    For commerce pages

    • Identify the exact product and variant rather than relying on a family-level title.
    • Attach currency, discount conditions, and eligibility requirements to the displayed price or benefit.
    • Distinguish current stock from general product availability or an expected future release.
    • State compatibility as a rule that can be evaluated, including the condition that makes an option unsuitable.
    • Make the merchant relationship and checkout path clear when several sellers or stores may offer the item.
    • Describe loyalty or payment benefits only where their qualifying conditions are visible and maintained.

    For local service and booking pages

    • Name the actual service, service area, and location instead of expecting a broad business description to establish all three.
    • Keep bookable availability separate from ordinary opening hours. A business can be open without having a qualifying appointment.
    • Show whether a displayed amount is a current price, a starting price, or a quote that depends on additional information.
    • Place decisive requirements near availability, including timing, location, capacity, or service-specific conditions.
    • Send the user to the matching booking state and disclose any remaining selection required there.

    Use the visible page as the editorial contract. If your structured data, commercial integrations, or booking system cannot support that contract, fix the underlying record before adding another optimization layer.

    Compete for selection, not just a citation

    Classic SEO often treats inclusion as the central win: rank, appear, earn a rich result, or receive a citation. Agentic commerce adds a harder question. Does your option satisfy the user’s constraints well enough to remain in the working set and move toward action?

    Google’s Shopping Graph has reached 60 billion product listings. Universal Cart is intended to help users compare in-stock availability and deals across retailers, choose a preferred store, detect incompatible components, and see eligible payment or loyalty savings. Raw product presence is therefore not a meaningful differentiator on its own.

    Build a selection record for each important offer

    A selection record is not another block of promotional copy. It is a compact internal inventory of facts that explain when your option should or should not be chosen. Build it around these questions:

    • Which user constraints make this option a fit?
    • Which condition immediately disqualifies it?
    • What compatibility rule must be checked before purchase?
    • Which price, deal, loyalty benefit, or payment perk is verifiable, and what condition limits it?
    • Which variant and merchant does the claim describe?
    • What can the user actually do now: buy, reserve, book, join a waitlist, request a quote, or only learn more?

    Move the answers into the places an agent is likely to retrieve: descriptive copy, labeled commercial fields, comparison material, structured data that accurately reflects the page, and the action endpoint. Avoid interchangeable superlatives. Best, premium, advanced, and ideal do not resolve a constraint unless the page supplies the facts behind them.

    Compatibility deserves special attention. If two components work together only under a particular version, size, configuration, or use case, describe that relationship directly. Universal Cart’s ability to flag incompatible parts and suggest alternatives means compatibility data can influence whether an item remains in the assembled order, not merely whether its page is discovered.

    The transaction layer is expanding geographically and technically, but you should distinguish a roadmap from confirmed merchant readiness. The announced plan extends the Universal Commerce Protocol to Canada and Australia, with the United Kingdom planned, while the Agent Payments Protocol is intended to authorize agents to transact within criteria set by the user. That does not establish that every merchant, market, or surface is ready.

    Assign an owner to commerce-protocol changes, record which markets and surfaces you have actually validated, and document the last successful checkout or booking test. Do not publish an integration, availability, or agent-readiness claim because a protocol was announced. Confirm that your own account, catalog, market, and transaction path support it first.

    Measure task coverage, accuracy, selection, and action

    Clicks remain useful, but they cannot describe the whole agentic journey. A user may encounter your information inside a synthesized update, use it in a generated tool, compare your offer without visiting, or reach a booking page only after Google has resolved several intermediate questions.

    Build a measurement view that keeps four outcomes separate:

    • Task coverage: Can the system produce a useful response for the high-value task, or does it lack a decisive fact?
    • Accuracy: Are the surfaced entity, variant, price, availability, compatibility, and conditions consistent with the maintained record?
    • Selection: Does your option remain present when the prompt includes the constraints your offer genuinely satisfies?
    • Action: Does the resulting link, booking flow, or checkout path preserve the user’s intent and reach a valid next step?

    Do not collapse those outcomes into one AI visibility score. A citation with stale information is a coverage event and an accuracy failure. A correctly described product that disappears when compatibility is added points to a selection problem. A strong recommendation that lands on a generic category page is an action failure.

    Use a repeatable validation loop

    1. Freeze a set of prompts that represent your priority monitoring, comparison, booking, and shopping tasks.
    2. Record the surface, market, account tier, and test date. Availability may differ across those dimensions.
    3. Capture the answer, cited or named entities, extracted facts, stated conditions, suggested option, and action path.
    4. Classify each failure as missing, inaccessible, ambiguous, conflicting, stale, undifferentiated, or broken at the handoff.
    5. Fix the maintained fact or template that created the failure. Avoid patching one page if the same faulty field feeds several pages.
    6. Repeat the same prompt after the relevant page, markup, or commercial record has been updated, and keep the before-and-after evidence.

    A single generated response shows what happened in that run. It does not establish a permanent position. Use the same prompts and evaluation criteria over time so that you can distinguish a real improvement from ordinary variation in presentation.

    Keep a rollout ledger instead of assuming one launch date

    Several capabilities were announced with different markets, products, and access levels. Treat them as separate rows in your operational plan:

    • Gemini 3.5 Flash was announced as the default model for AI Mode and as the model powering the Gemini app for users broadly.
    • Custom generative UI was announced for wider availability in the summer, beginning with Google AI Pro and Ultra subscribers in the United States.
    • Information agents were also announced for an initial summer rollout to Google AI Pro and Ultra subscribers.
    • Agentic booking for local experiences and services was announced for the United States in the summer.
    • Universal Cart was announced for a summer launch in the United States on Google Search and the Gemini app, with YouTube and Gmail planned afterward.
    • Personal Intelligence in AI Mode was described as expanding to about 200 countries and territories across 98 languages, which is a different capability from transaction availability.

    Your ledger should record the feature, market, product surface, entitlement, announced state, actual tested state, owner, and last validation. This prevents a common planning error: treating an announcement about one AI surface as proof that the same behavior is available to every searcher and merchant.

    What to do in your next optimization cycle

    1. Select one revenue-linked task rather than attempting a site-wide agentic optimization project.
    2. Write the full constrained prompt a serious customer would use.
    3. List every fact and relationship required to answer it, including disqualifiers.
    4. Reconcile those facts across the visible page, JSON-LD, maintained commercial records, and action destination.
    5. Rewrite ambiguous claims so that the subject, value, condition, and current state remain attached.
    6. Run the validation loop and log where the task breaks.
    7. Scale the improved structure only after the complete journey works for the original task.

    Start with a journey where price, availability, compatibility, or bookability changes frequently. Volatile facts expose weak handoffs quickly, and errors there can change the user’s decision. Fix that journey before producing another batch of top-of-funnel copy.

    Google’s interface will keep moving. Your best hedge is not predicting every feature. It is making one valuable customer journey legible, current, differentiated, and executable from end to end. Pick that journey now and repair its weakest handoff.

    References

  • Google Chrome AI Mode: What Changes for Search and SEO

    Google Chrome AI Mode: What Changes for Search and SEO

    If you work in SEO, a new Google AI interface can look like an urgent ranking update. That is not the right conclusion to draw from Chrome AI Mode. The immediate change is to the searcher’s workspace: an AI response, webpages, open tabs, images, and files can now become parts of the same research session.

    Your practical task is to separate two questions. First, can AI Mode discover your page without help? Second, when someone opens or supplies your page as context, does it make the answer easier to verify? Chrome’s new interface makes both questions important, but they measure different kinds of success.

    Chrome AI Mode turns a search into a working context

    Traditional web research creates friction as the searcher moves among a results page, multiple tabs, downloaded documents, and notes. Chrome AI Mode reduces that switching by keeping more of the research context attached to the query.

    Side-by-side search keeps the answer and webpage visible

    On desktop, clicking a result in AI Mode can open the linked webpage beside the AI experience. The searcher can inspect the page, compare details, visit other relevant sites, and ask follow-up questions without abandoning the original context.

    That layout changes the moment at which your page is evaluated. A visitor does not necessarily arrive after leaving the AI answer behind. Your title, answer, qualifications, and supporting evidence may be judged while the generated response remains visible next to them. If the two conflict, the mismatch is easier to notice. If your page supplies a missing condition or clearer explanation, that is easier to notice too.

    Recent tabs can become query context

    On desktop and mobile, the plus menu on the New Tab page or inside AI Mode can bring recent tabs into a search. AI Mode can use that selected context to customize its response and recommend additional sites.

    This creates an important measurement boundary. If you add your own website as a tab and AI Mode then discusses it accurately, you have tested contextual understanding. You have not shown that the website would have been discovered from a cold query. Run those tests separately or you will mistake supplied context for organic AI visibility.

    Images and files can join the same task

    The plus menu can also combine tabs, images, and files such as PDFs in the prompt context. Canvas and image-creation tools are available through that menu as well.

    For a content team, this means a webpage may be compared with material that never appeared in the written query: a specification PDF, a screenshot, a chart, or another open page. Make each important asset understandable on its own. Give PDFs descriptive titles, label charts plainly, explain what an image proves in the surrounding copy, and keep terminology consistent across formats. Those practices help a person verify the material even when the surrounding AI behavior is uncertain.

    Availability also needs a qualifier. These Chrome-specific capabilities initially launched for U.S. English users. Do not assume every teammate, market, device, or customer can reproduce the same workflow. Record language, market, device type, and feature availability with every test.

    The SEO impact is behavioral, not a confirmed ranking change

    Chrome AI Mode changes how people can gather and examine information. The announced capabilities do not establish a new ranking factor, crawler requirement, or structured-data type. There is no sound basis here for a Chrome-specific schema, a new metadata field, or an emergency rewrite of every page.

    The useful SEO interpretation is narrower. Chrome is making contextual search and page-level verification easier. That creates three distinct outcomes you should track:

    • Cold discovery: your brand or page appears when the query begins without your site, tabs, or files being supplied.
    • Contextual synthesis: AI Mode uses your page correctly after the searcher deliberately adds it as a tab or file.
    • Verification: the searcher opens your page beside the answer and can quickly confirm, qualify, or reject the generated claim.

    Only the first outcome directly tests whether your content was discovered from the query. The other two still matter: they show whether the content is usable and trustworthy once it enters the session. But reporting all three as “AI rankings” would conceal what actually happened.

    This distinction also explains why a single screenshot is weak evidence. A response may depend on the recent tabs, images, or files that were added before the prompt. Preserve the prompt and the supplied context when you document a result. If you cannot reconstruct the session, you cannot tell whether the page was retrieved, supplied, or merely opened for confirmation.

    Audit pages for side-by-side verification

    A split-screen monitor shows an abstract AI answer beside a structured webpage, with a magnifying glass positioned between them for comparison.

    A page opened next to an AI response has a demanding job. It must orient the visitor quickly, answer the relevant question, and expose enough support for the visitor to decide whether the answer is reliable. A long page can still do this well; the requirement is clarity, not brevity.

    1. Start with a decision query. Use the question a customer asks when choosing, comparing, troubleshooting, or validating something, not just a short keyword.
    2. Open the most relevant page beside AI Mode on desktop. Check whether its visible title and opening copy make the subject and scope unmistakable.
    3. Locate the direct answer. The reader should not have to infer it from a broad introduction. State the answer before expanding into background, exceptions, or examples.
    4. Trace the important claims. Make sure a person can find the definition, limitation, comparison basis, or supporting detail that justifies each conclusion.
    5. Check context independence. A visitor may land on a subsection from an AI-assisted journey, so headings such as “Benefits” or “Options” are often too vague. Name the product, task, or decision in the heading when ambiguity is possible.
    6. Compare formats. If the webpage, PDF, image labels, and structured data describe the same entity, use the same names, attributes, and qualifications across them.
    7. Repeat the query without adding your site as a tab. Record whether the page is discovered cold, used only after being supplied, or opened only as supporting evidence.

    The structured-data check deserves restraint. Keep existing markup aligned with what a visitor can see on the page, and correct contradictions between markup and copy. Do not add invented properties or relabel established schema because an AI interface changed. Nothing in this Chrome feature set demonstrates a special markup shortcut into AI Mode.

    Pay particular attention to scope language. A direct answer can still mislead if the applicable market, product version, audience, prerequisite, or exception appears much later. Put a necessary qualification beside the claim it limits. That makes the page more useful when someone is comparing it with an abbreviated AI response.

    Use AI Mode for content QA without fooling yourself

    A content specialist compares an abstract AI panel with a webpage and source documents while using a magnifying glass and check tokens.

    Chrome AI Mode can support a disciplined content review, provided you control the context. The purpose is not to manufacture a favorable response. It is to find where your content becomes ambiguous, incomplete, or hard to verify.

    1. Begin with a clean query and no company-owned tabs or files included. Save the exact wording and note whether your page appears.
    2. Open a relevant result beside AI Mode. Compare the generated answer with the page’s actual wording, scope, and qualifications.
    3. Add only the tabs or files needed for the decision. A smaller context makes it easier to identify which material influenced the response.
    4. Ask follow-up questions about conflicts, missing conditions, and comparison criteria. Use the answers to locate weaknesses in the underlying pages, not as proof that the model is always correct.
    5. Remove the supplied context and run the clean query again. Differences between the two sessions reveal what depended on your added material.
    6. Log the test environment: desktop or mobile, language and market, query, included tabs, included files, pages opened, and observed result.

    Use the findings to repair the content itself. If AI Mode overlooks a qualification that is buried near the bottom, move that qualification next to the claim. If two pages use different names for the same feature, choose a canonical term and explain any necessary synonym. If a PDF contains the decisive evidence but the webpage barely identifies it, add a descriptive link and explain why the file matters.

    Do not optimize merely for the generated wording you happened to receive. Because selected tabs and files can change the context, a context-bound answer is not a stable template for future responses. Optimize the underlying facts, relationships, labels, and evidence that should remain correct across many possible prompts.

    Key takeaways

    • Chrome AI Mode can keep a webpage beside the generated response on desktop, making comparison and verification part of the same view.
    • Recent tabs can be added on desktop and mobile, while images and files such as PDFs can supply further context.
    • A favorable response after adding your own page tests contextual usefulness, not cold discovery or ranking.
    • The feature set does not establish a new ranking signal or Chrome-specific schema requirement.
    • Audit content for direct answers, visible qualifications, consistent terminology, and evidence that is easy to locate beside an AI response.
    • Initial availability was limited to U.S. English users, so document the market, language, device, and context behind every test.

    Start with the decision query that matters most to your audience. Test it once without supplied context and once with the relevant page or document added. The gap between those sessions will tell you whether your next priority is discovery, clearer content, or better supporting evidence.

    References