Tag: AI Mode

  • Google Commerce Discovery and In-Search Checkout Strategy

    Google Commerce Discovery and In-Search Checkout Strategy

    You may be optimizing product pages for the click while Google is redesigning shopping around a different outcome: identify a suitable product, validate the choice, and potentially complete the purchase inside AI Mode or Gemini. That changes where ecommerce visibility is won.

    You now need two connected systems. The first makes your catalog understandable and competitive during AI-assisted discovery. The second lets an approved product move through an in-search transaction without introducing price, availability, identity, or payment failures. Here is how to prepare both without confusing checkout access with search visibility.

    The new commerce funnel starts in the product graph
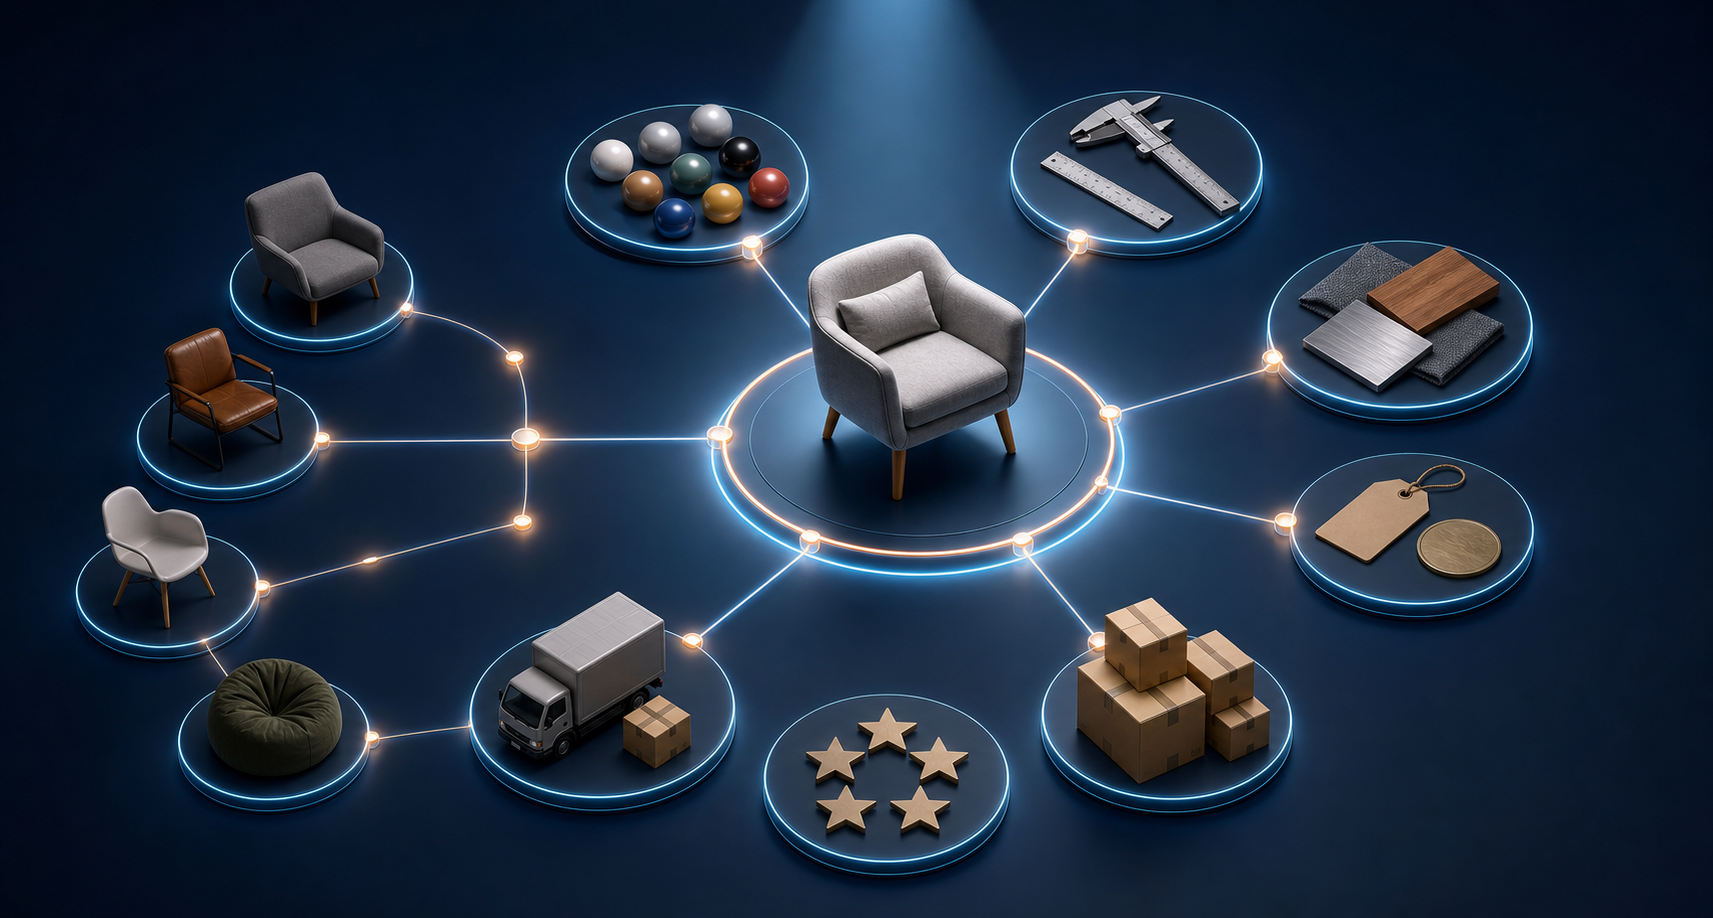
    A generic product sits at the center of a connected network of attributes, inventory, reviews, shipping, and related items.

    A conventional SEO funnel assumes that search earns a click, the product page creates confidence, and the merchant site completes the sale. Google’s emerging commerce model can compress those stages. A user may describe a need conversationally, receive product recommendations, compare options, and check out without following the familiar sequence of search result, landing page, cart, and checkout.

    The catalog is therefore more than a paid advertising input. Google’s Shopping Graph contains more than 50 billion product listings and supplies product information to AI Overviews, AI Mode, and Gemini. If your product record is incomplete, ambiguous, or inconsistent, strong product-page copy may never get the chance to influence the shopper.

    This is already relevant to organic discovery, not merely a future checkout project. AI Overviews appeared in about 14% of observed shopping queries, up from roughly 2% in late 2024. A Peec AI analysis also found that up to 83% of products in sampled ChatGPT carousels reflected Google’s organic Shopping results, with 60% of those matches coming from positions 1 through 10. That analysis is useful directional evidence, not proof that every assistant, market, or query follows the same pattern. It does show why Merchant Center data belongs in your AI search strategy.

    Commerce layerQuestion it must answerTypical failure to prevent
    Product feedIs this product a relevant match for the request?Generic titles, missing identifiers, weak attributes, or unusable images make the product hard to match and compare.
    Product pageDo the details support the product record and the buyer’s decision?The page and feed describe different variants, benefits, prices, or availability.
    Commerce integrationCan the selected product be purchased successfully in the Google experience?The discovery record cannot be resolved to the correct variant, checkout state, identity, or payment flow.

    Use those layers to triage problems correctly. Low discovery visibility is usually a matching and data-quality problem before it is a checkout problem. A visible product that cannot complete a transaction is an integration problem. A product that earns attention but not purchases may have a merchandising, offer, or expectation problem. Putting every weak result under the label of SEO hides the part that actually needs work.

    Make the product feed an organic discovery asset

    Many merchants let the paid media team own the only feed. That arrangement keeps campaigns running, but a feed shaped around bid relevance and advertising conventions is not automatically the best representation of how people search organically. Paid and organic outputs can share a catalog while applying different rules to titles, descriptions, and supporting attributes.

    Build records around the language of product selection

    The title is your highest-priority matching field. Write it so a person can identify the product without seeing the image or visiting the page. Start with the product type and add the attributes that genuinely distinguish the item, such as brand, material, capacity, size, color, compatibility, or intended use. The useful combination depends on the category. Do not force every possible modifier into every title, and do not repeat words merely to make the record longer.

    A good test is to compare the title with the phrases a buyer would naturally use when narrowing a choice. If shoppers distinguish your products by capacity and compatibility, those attributes deserve more attention than internal collection names. If the title could apply equally to many products in your own catalog, it is probably too vague for an AI system to select confidently.

    • Use accurate GTINs where the product has them. Correct identifiers help Google match identical products, combine relevant information such as reviews, and understand that two differently worded listings refer to the same item. Well-matched products with accurate GTINs can receive up to 40% more clicks. Never invent an identifier or reuse one from a different variant.
    • Supply both clear standard images and useful lifestyle images. The standard image should make the product easy to identify. A lifestyle image should add context, scale, or use information rather than obscure the item. Image problems can also cause Merchant Center disapprovals, so treat asset validation as feed health, not decoration.
    • Use product_highlight for concise buyer benefits. Replace empty claims such as high quality with concrete outcomes. A statement about handling light rain during a commute tells the buyer more than an unsupported adjective.
    • Use product_detail for structured specifications. Put filterable facts such as dimensions, material, capacity, and compatibility into the structured field that represents them. Do not bury every decision-critical fact in prose.
    • Keep the feed and product page synchronized. A refined feed title cannot compensate for a page that represents a different variant, price, feature set, or availability state. The two surfaces should describe the same purchasable product.

    Create a controlled organic output

    You do not need two unrelated catalogs. You need one reliable product source and a controlled way to publish an organic-oriented output without letting paid campaign conventions overwrite it. Depending on your commerce stack, that may be a dedicated feed or a dedicated set of transformation rules. Either way, document which fields are canonical, which fields may vary by channel, and who approves each change.

    The potential impact is material, but it should not be treated as a guaranteed benchmark. In one major ecommerce implementation, an organic feed produced a 10% month-over-month increase in organic listing click-through rate and a 4% increase in purchase rate. A product-level test recorded 92% higher free-listing revenue, 83% more visibility, and a 14% increase in add-to-cart rate. Another organic optimization set generated 35,000 impressions at a 1.4% click-through rate, which was 55% above the paid click-through rate for the same period. Those results establish that feed changes can be commercially important; they do not establish a universal lift for every catalog.

    Run your own controlled evaluation:

    1. Select a coherent product group with enough existing activity to measure.
    2. Record its free-listing impressions, click-through rate, add-to-cart rate, purchase rate, and revenue before changing the feed.
    3. Change one field family at a time when practical. A title test is easier to interpret if you do not simultaneously replace every image and description.
    4. Keep a version log that connects each feed change to the affected product IDs.
    5. Compare product-level outcomes, not only catalog-wide averages. A large category can conceal both strong winners and harmful rewrites.
    6. Check paid performance separately. An organic improvement does not prove that the same wording should replace a paid title optimized for a different matching and bidding context.

    The goal is not to make the organic feed sound conversational at any cost. It is to make the product record precise in the language buyers use while preserving exact identifiers, specifications, and variant distinctions.

    Prepare for UCP without mistaking checkout for ranking
    A product moves through connected price, inventory, identity, payment, and confirmation checkpoints in an abstract checkout system.

    Google’s Universal Commerce Protocol, or UCP, connects product data, user identity, payment flows, and checkout so eligible purchases can be completed from product listings in AI Mode and Gemini. The initial rollout is gradual and U.S.-limited. Merchants must complete a technical integration, submit an interest form, receive approval, and then use Merchant Center onboarding tools.

    Approval opens a transaction path; it does not establish a search-ranking benefit. Treat discovery eligibility and transaction readiness as separate workstreams unless Google explicitly documents a connection. A product still needs strong, consistent data to be selected. UCP then addresses whether the selected item can move through checkout inside the Google experience.

    Google has also added a native_commerce attribute for UCP-powered purchase buttons. Do not treat that attribute as a shortcut around integration quality. A buy button attached to stale price, availability, or variant data creates a more immediate failure than a conventional listing because the shopper is already trying to transact.

    1. Confirm the access path. Check Merchant Center for UCP onboarding availability and follow the interest and approval process. Do not promise a launch date internally until the account has access.
    2. Assign a catalog system of record. Every purchasable variation needs a stable mapping between the feed record and the item your checkout can fulfill. Resolve duplicate identifiers and unclear parent-variant relationships before transaction testing.
    3. Map the checkout data contract. Identify which system owns product identity, selected variant, price, availability, buyer identity, payment state, and transaction outcome. Document how a change in one system reaches the others.
    4. Use the available sandbox. Merchant Center onboarding includes a testing sandbox, identity linking, and checkout APIs. Test successful transactions as well as unavailable products, changed prices, unresolved identities, declined payments, and interrupted requests.
    5. Define operational ownership. SEO can improve matching, but commerce, engineering, privacy, security, payment, and customer-support owners need responsibility for the parts they control. Decide who pauses native checkout when catalog or transaction data becomes unreliable.
    6. Activate only after reconciliation. The feed, product page, commerce system, and transaction response must resolve to the same product and offer. If they do not, keep the safer redirect-based journey until the mismatch is fixed.

    This is where cross-team collaboration becomes practical rather than ceremonial. SEO contributes query language and matching logic. Commerce owns product truth and fulfillment constraints. Paid media teams often understand feed tooling and disapproval management. Engineering owns the integration path. Each team should have a named field or state to maintain, not a general instruction to support AI commerce.

    Measure discovery and checkout as one journey, not one metric

    In-search checkout weakens the old assumption that a successful search interaction produces a website session. When a customer can purchase inside an AI interaction without being redirected to the merchant site, traffic alone becomes an incomplete measure of both SEO and commerce performance.

    Build a measurement chain that follows the product as far as your available data allows:

    1. Catalog health: Track active products, rejected or disapproved items, identifier coverage, image issues, and unresolved feed-page discrepancies. A product excluded before matching cannot generate a meaningful visibility or conversion signal.
    2. Discovery: Track impressions and click-through rate by product, product group, query class, and Google surface where those dimensions are available. Separate free listings from paid placements.
    3. Consideration: Track the interactions you can observe between a product impression and checkout. Keep website engagement separate from native interactions so a change in surface mix does not look like a sudden behavioral collapse.
    4. Transaction: Track checkout attempts, successful purchases, failures, and the product or variant involved. Preserve a reference that lets commerce and analytics teams reconcile the transaction with the originating product record.
    5. Business outcome: Compare completed orders and revenue with website sessions and site-based orders. A decline in site traffic is not automatically lost demand if more transactions are completing elsewhere. It is also not automatically good news; you need reconciled purchase data to tell the difference.

    Capture a baseline before enabling native checkout. After activation, segment results by surface and product group rather than comparing one blended total with the previous period. Otherwise, a shift from website checkout to Google checkout can be mistaken for an SEO loss, while a surge in product impressions can be mistaken for commercial growth without completed purchases.

    Document your attribution rule as part of the integration. Decide how you will classify a purchase discovered in AI Mode, completed through native checkout, and fulfilled by your commerce system. The rule matters less than using it consistently and making its limits visible. Do not allow SEO, paid media, and commerce dashboards to claim the same order independently.

    You should also watch for substitution. Native checkout may replace a transaction that would otherwise have occurred on your site, or it may capture demand that would have been lost through extra steps. Compare the full order picture rather than assuming every native purchase is incremental or every missing session represents cannibalization.

    Key takeaways

    • Google commerce visibility begins with product data, so Merchant Center feed quality is now part of organic and AI search optimization.
    • Optimize organic titles around the attributes buyers use to identify and distinguish products, while preserving accurate GTINs, specifications, images, price, and availability.
    • Use a dedicated organic feed or controlled organic transformation rules instead of forcing paid and free listings to share every optimization decision.
    • Treat UCP as a checkout capability, not a ranking shortcut. Discovery quality must be solved before native transaction readiness can help.
    • Prepare stable product mappings, clear system ownership, sandbox failure tests, and a safe way to pause native checkout when data becomes unreliable.
    • Measure catalog health, discovery, transaction outcomes, and total orders together because website sessions no longer represent the entire shopping journey.

    Start with a catalog reconciliation, not a checkout build. Choose a representative product family and align its titles, identifiers, attributes, images, page details, price, and availability. Then name the owner of every field and transaction state. That work improves discovery whether or not UCP access has reached your account.

    When access becomes available, take the same reconciled products through the sandbox before expanding. You will learn more from a small group with traceable data and observable failures than from activating native checkout across a catalog whose product truth is still disputed.
    References

  • How to Prepare for Google Search as a Task-Completing Agent

    How to Prepare for Google Search as a Task-Completing Agent

    If your SEO strategy ends when somebody clicks a result, you are preparing for an older version of Search. A task-completing system may use your content to compare options, resolve constraints, choose a next step and initiate an action. Your page is no longer competing only to be read. It is competing to be useful inside a larger job.

    This does not mean abandoning rankings, traffic or conventional SEO. It means adding a second standard: can Google understand what your business offers, determine when it is appropriate and move a user toward a safe, verifiable outcome?

    The search result is becoming part of the workflow

    Traditional search usually separates discovery from execution. You search for information, open several pages, make sense of them and complete the task somewhere else. Agentic search compresses those stages. Google’s stated direction is for more information-seeking queries to become agentic, with Search coordinating long-running work and multiple concurrent threads.

    Think about a request such as, “Find accounting software suitable for a small Canadian consultancy, compare the plans and help me arrange a demonstration.” An ordinary results page can supply links for each part. A task-oriented system has to preserve the user’s requirements while it researches vendors, rules out unsuitable choices, explains trade-offs and hands the user into an action.

    That changes the unit of optimization. A keyword is one expression of demand. A task includes the desired outcome, the constraints, the decisions that must be made, the evidence needed to make them and the action that finishes the job.

    • Question: What does the user need to know?
    • Qualification: Which options fit the user’s location, situation, budget, timing or technical requirements?
    • Decision: What evidence separates an appropriate choice from an inappropriate one?
    • Action: What can the user book, buy, configure, submit or request?
    • Verification: How does the user know the action succeeded, and how can it be changed or reversed?

    People are already using AI Mode for deep-research queries that stretch beyond the old one-query, one-answer pattern. That is the immediate signal to act on. You do not need to predict every interface Google will release. You need to make your public information dependable enough to support a multi-step decision.

    Search and Gemini are also expected to coexist, overlapping in some uses while diverging in others. Do not reduce your plan to optimizing for one chatbot response. Your information may be encountered through a conventional result, an AI-generated answer, a research workflow or an action-oriented experience. The underlying facts should remain consistent across all of them.

    Optimize the complete task, not just its opening query

    An isometric workflow follows a user request through comparison, constraint checking, availability, verification, and a completed outcome.

    Start with one task that matters to your audience and your business. Avoid broad goals such as “learn about payroll” or “rank for payroll software.” Use an observable outcome: “Determine whether this payroll service supports my type of company and begin the correct signup process.”

    Then create a task map. This is more useful than a keyword cluster because it exposes the information gaps that can stop an agent or a person from proceeding.

    1. Write the outcome in the user’s language. State what will be decided or completed, not what content will be consumed.
    2. List the required inputs. Identify the details that change the answer, such as location, organization type, compatibility, eligibility, timing or service area.
    3. Break out the decisions. Record every choice the user must make before acting. A product tier, appointment type or implementation route may each require a separate decision.
    4. Assign evidence to each decision. Decide which page supplies the specification, policy, price, limitation, comparison or proof needed at that point.
    5. Define the action and handoff. Make clear where the user can start, what information will be requested and what happens after submission.
    6. Document failure and recovery paths. Explain what to do when the user is ineligible, an option is unavailable, a form fails or an action must be cancelled.

    The recovery path matters because task completion is not the same as pushing every visitor toward conversion. A reliable system must also recognize when your offer does not fit. If exclusions are buried in terms, an agent may recommend the wrong route and the user will discover the problem late. Put decisive limitations beside the claims they qualify.

    Next, label the role of every page in the task. One page may establish eligibility, another may compare options, another may explain a procedure and another may host the transaction. A page can serve more than one role, but each role should be explicit. If your team cannot agree on what a page contributes to the task, an automated system is unlikely to infer it reliably.

    Build pages an agent can interpret and use

    An agent-ready page is not a page written for robots. It is a page on which the decisive facts are clear, scoped and consistent. Good structure helps people and machines for the same reason: neither should have to reconstruct a critical condition from vague marketing language.

    Task layerWhat must be resolvedWhat to improve on the site
    IntentThe outcome the page supportsUse a descriptive title, a direct opening answer and a clear statement of who the page is for.
    QualificationWhether the offer fits the user’s constraintsState eligibility, locations, dependencies, exclusions and prerequisites beside the relevant offer.
    DecisionWhy one option should be chosen over anotherUse comparable attributes, defined terms and evidence tied to specific claims.
    ActionHow to begin or complete the next stepName the action precisely, disclose required inputs and explain what happens after it is submitted.
    VerificationWhether the action succeededProvide an explicit confirmation state, reference information and a route for correction or cancellation.
    Machine interpretationWhich entities and relationships the content describesUse accurate structured data that matches the visible page and the site’s canonical facts.

    Several practical rules follow from this model.

    Put the decisive answer before the supporting narrative

    If a service is available only in particular locations, say that near the service description. If a plan requires another product, state the dependency beside the plan. If the next step is a consultation rather than an immediate purchase, label it accurately. Do not make the reader decode “Get started” to discover what will actually happen.

    Turn implied knowledge into explicit facts

    Businesses often assume that visitors understand their terminology, market, service boundary or product hierarchy. An agent cannot safely rely on that assumption. Define ambiguous terms, attach units to measurements, give conditions to claims and distinguish facts about the company from facts about a particular offer.

    Consistency is more important than repetition. If a product name, service area, policy or plan description differs across a landing page, help page and checkout flow, decide which version is canonical and correct the others. Structured data should reflect that same version.

    Use JSON-LD as a factual layer, not a persuasion layer

    Choose Schema.org types and properties that match what is visibly present. Identify the organization, offer, product, service, person, place or event only when the page genuinely describes that entity. Connect related entities where the relationship is real. Keep names, URLs, identifiers and offer details aligned with the canonical content.

    Do not add unsupported properties because they look advantageous, and do not mark up claims that a visitor cannot verify on the page. JSON-LD can make a fact easier to interpret; it cannot turn an incomplete, stale or contradictory claim into a trustworthy one.

    Design the action boundary deliberately

    Research and execution carry different risks. Reading a comparison is low commitment. Sending personal information, placing an order or booking an appointment is not. If your task ends in an action, make the commitment point unmistakable.

    • Show what will be submitted or purchased before confirmation.
    • Separate required inputs from optional ones.
    • Display material conditions before the final action, not only after it.
    • Explain whether the action is immediate, pending review or merely a request.
    • Provide a correction, cancellation or support route where the action permits one.
    • Return a clear success or failure state instead of leaving the user to infer the result.

    These are conversion fundamentals, but they become more important when software may coordinate the handoff. Ambiguous buttons, silent form failures and hidden conditions do not merely reduce conversion. They make the task unsafe to delegate.

    Audit task readiness before agent traffic becomes measurable

    A digital inspection agent scans the modular elements of a webpage while a human specialist supervises from a control station.

    You may not be able to isolate every agent-assisted visit or decision in your reporting. You can still measure whether your site is ready to participate. Treat readiness as a content, data and workflow quality problem.

    Use a simple zero-to-two audit for each important task. This is a prioritization method, not a search-engine score:

    • 0 — Missing or contradictory: the task cannot proceed without guessing, or two public pages give incompatible answers.
    • 1 — Inferable: the answer exists, but the user must combine pages, interpret vague wording or uncover a condition late.
    • 2 — Explicit and usable: the answer is clear, appropriately qualified, current and connected to the correct next step.

    Score the task across six dimensions: outcome definition, qualification facts, decision evidence, action path, confirmation or recovery, and measurement. Do not obsess over the total. A zero in any dimension identifies a broken link in the workflow and deserves attention before cosmetic content changes.

    Run the audit from the public site, without internal knowledge. Give a team member the task and its constraints. Ask them to find the right option, explain why it fits, begin the action and identify how they would reverse or correct it. Record every point where they have to guess. Those guesses become your content and workflow backlog.

    Measure the workflow in stages so a completed task is not reduced to a pageview:

    • Discovery: Did the relevant landing page become visible for the task?
    • Qualification: Did the visitor reach the eligibility, specification, policy or comparison information needed to proceed?
    • Action: Did the visitor start and complete the intended form, booking, configuration or transaction?
    • Failure: Where did validation errors, unavailable options or unclear requirements stop progress?
    • Outcome quality: Did the action lead to confirmation, or did it create cancellations, corrections and avoidable support work?

    This measurement model also protects you from a misleading success signal. More action starts are not helpful if users are being routed into an unsuitable option. Pair completion data with failure, cancellation and correction data so you can distinguish task volume from task quality.

    Key takeaways

    • Optimize for a defined user outcome, not only the keyword that begins the journey.
    • Map qualification, decision, action and verification as separate stages, then assign each stage to reliable public information.
    • State decisive constraints beside the claims they limit. Do not hide eligibility, dependencies or exclusions at the end of the path.
    • Keep visible content, structured data and transactional interfaces consistent about the same entities and offers.
    • Treat confirmation, correction and cancellation as part of task completion, not as support details.
    • Audit every task for missing or contradictory information before trying to infer performance from agent-specific traffic.

    Choose one commercially important task this week. Write its outcome, inputs, decisions, evidence, action and recovery path on a single page. Then follow it through your public site and fix the first place where a user has to guess. That work will improve the experience now, while giving agentic Search cleaner material to use as it moves from answering questions toward completing jobs.

    References

  • Google AI Ads and Sales Lift: A Practical Testing Playbook

    Google AI Ads and Sales Lift: A Practical Testing Playbook

    You have probably seen the headline number: a retailer used Google AI advertising and revenue rose by 80%. The useful question is not whether AI ads can work. It is whether they can produce profitable, incremental sales for your business without weakening measurement or surrendering control of your brand.

    You can answer that question, but not by switching on every automated feature and comparing this month’s revenue with last month’s. Treat AI Max, Performance Max, reusable text rules, and recommendation reporting as separate tools inside a controlled commercial test. That gives you a result you can defend when someone asks what actually caused the lift.

    An 80% lift is a case result, not your forecast

    Google has highlighted Aritzia as having achieved an 80% increase in revenue with AI Max. That is evidence of possibility, not a transferable benchmark. It does not tell you what Aritzia would have earned without AI Max, how much media spend changed, which customers were new, or what happened to margin.

    Revenue lift can come from several places. An advertiser may reach previously missed queries, improve the match between a shopper and a product, spend more, capture demand that another campaign would have converted, or count conversions differently. Only the first two clearly demonstrate better advertising. Additional spend can still be worthwhile, but it is a different claim and should be judged against your allowable acquisition cost.

    Write your expected mechanism before starting. A useful hypothesis is specific: AI Max will find additional non-brand demand for selected products and increase contribution profit without pushing customer acquisition cost above our limit. A weak hypothesis is that AI will increase sales. The stronger version identifies the demand, the product scope, the business outcome, and the constraint.

    Set a budget boundary and stop conditions at the same time. Automation can spend into newly discovered demand quickly. Without a pre-agreed limit, higher expenditure can resemble growth even when each additional order is less valuable. Your own margins, return rates, sales cycle, and cash constraints should determine that limit; a vendor case result should not.

    AI changes matching, but your inputs set its ceiling

    Traditional search advertising starts with keywords chosen by the advertiser. Google’s newer systems place more weight on inferred intent. They assess the retailer’s website and creative assets, interpret a search, and dynamically match products and messages to that context. Performance Max and AI Max are designed to operate within this more intent-driven model.

    The opportunity is clearest in conversational search. Google says queries in AI Mode tend to be two to three times longer, giving the matching system more context. Google also says 15% of daily searches are novel. A rigid keyword list cannot anticipate every new formulation, while an intent model can potentially connect unfamiliar wording with an appropriate offer.

    That does not remove the need for optimization. It moves optimization upstream. The system cannot reliably distinguish two similar products if your pages use vague names, bury the differences, or contradict the creative. It cannot protect a nuanced brand position that has never been translated into operational rules.

    • Clarify the product: Make the product type, variant, intended buyer, availability, price, and material differences easy to identify on the landing page and in the product data you provide.
    • Align the promise: Check that advertising claims, promotions, shipping terms, and calls to action agree with the destination page. Automation can scale a mismatch as easily as it scales a good message.
    • Supply useful creative range: Give the system assets that express different legitimate benefits, use cases, and objections. Cosmetic variations of the same vague claim do not create meaningful choice.
    • Define the sale correctly: Confirm that the primary conversion represents a commercially useful outcome. If low-value actions sit beside completed purchases without a clear hierarchy, more reported conversions may not mean more revenue.
    • Separate brand rules from campaign ideas: Tone, prohibited language, required qualifications, product naming, and legal restrictions should remain stable. Offers and audience-specific messages can change by campaign.

    Google Ads is testing a beta capability that lets advertisers clone approved AI text guidelines from an existing campaign. If it is available in your account, use it to turn recurring brand decisions into reusable instructions. A practical rule set should cover voice, required product terminology, claims the system must not make, promotion wording, and acceptable calls to action.

    Cloning saves setup time; it does not eliminate review. Read the copied rules in the context of the destination campaign. A restriction written for one market, product category, or promotion can be incomplete or actively wrong elsewhere. Assign an owner and version the rules internally so your team knows which guidance was approved and why.

    Build a test that can explain where sales came from

    Two matched groups of product boxes travel through separate treatment and control lanes toward individual checkout stations.

    The main measurement mistake is changing automation, budget, creative, offers, landing pages, and conversion tracking at once. A good result then produces enthusiasm but little knowledge. A bad result creates the same problem because you cannot identify which change failed.

    1. Choose one commercial hypothesis. Name the customer demand you expect AI matching to capture, the products included, the primary business metric, and the maximum cost you will tolerate.
    2. Set a clear boundary. Limit the first test to a defined campaign, product group, market, or customer cohort. Avoid exposing the entire account before you know how the system behaves with your inputs.
    3. Preserve a comparison. Keep a control when account structure and volume permit it. Otherwise, save the pre-change campaign data and identify a comparable product or market that will not receive the change.
    4. Reduce simultaneous changes. Hold pricing, promotions, landing pages, inventory policy, and conversion definitions steady where practical. Record anything that cannot be held steady, including stockouts and major merchandising events.
    5. Allow for conversion lag. Do not declare a winner while one group has had more time to accumulate purchases, cancellations, or returns. Read both groups over equivalent conversion windows.
    6. Review three layers of evidence. Check delivery, customer response, and business value separately. More reach may explain more orders, but only revenue quality and cost reveal whether the expansion was worthwhile.

    At the delivery layer, inspect spend, impressions, click volume, and the kinds of demand being reached. At the response layer, inspect purchases, conversion rate, and average order value. At the business layer, inspect net revenue, contribution margin, new-customer share where you can measure it, cancellations, and returns. A campaign can look strong in the advertising interface while failing the business layer.

    Split branded and non-branded demand in the analysis wherever your reporting allows. AI can appear efficient when it captures customers already searching for your company or products. That traffic may still deserve coverage, but it should not be presented as newly created demand. The same principle applies to returning customers: retained revenue and acquired revenue answer different questions.

    Google Ads has also added a Results tab intended to show the impact of recommendations. Use it to investigate what changed after a recommendation was applied, not as automatic proof that the recommendation caused incremental profit. Platform reporting can identify a useful correlation and shorten diagnosis, but it does not control for promotions, seasonality, inventory, competitor behavior, or sales that another campaign might have captured.

    Key takeaways

    • An 80% revenue increase from one retailer establishes potential, not an expected return for your account.
    • AI Max and Performance Max can interpret demand beyond a fixed keyword list, which matters as searches become longer and more conversational.
    • Clear product information, aligned landing pages, useful creative, and correctly defined conversions are inputs to the system, not cleanup tasks for later.
    • Reusable AI text rules can speed campaign setup, but every cloned rule set still needs market- and product-specific review.
    • Measure incremental business value rather than reported conversions alone. Separate brand demand, returning customers, media spend, returns, and margin.
    • Use recommendation results as diagnostic evidence. Validate causation with a control or the strongest comparable baseline available.

    Scale only after the result survives business checks

    A stream of purchase tokens passes through margin, inventory, and quality checkpoints before reaching a larger retail network.

    A successful test should answer more than whether sales rose. You should know which products gained, what type of demand expanded, how much spend changed, whether acquisition remained within your limit, and whether the revenue retained its value after discounts, cancellations, and returns.

    Before expanding the campaign, require the result to pass five checks:

    • Incrementality: The gain remains credible after separating branded demand and other traffic the campaign may have absorbed.
    • Economics: Acquisition cost and contribution margin stay within the limits set before the test.
    • Quality: Search intent, generated messaging, landing pages, and purchased products align with the hypothesis.
    • Durability: The outcome is not explained by a short promotion, inventory event, reporting delay, or one unusually strong segment.
    • Control: Brand and compliance reviews find no unacceptable claims, tone, targeting pattern, or customer experience.

    Scale in stages if those checks pass. Expand one boundary at a time, such as the eligible product set or budget, and keep the same business metrics visible. If revenue rises but margin, new-customer acquisition, or message quality deteriorates, pause the expansion and correct the input or objective before spending more.

    Google is also experimenting with personalized direct offers and supporting a broader move toward purchases inside AI interactions through the Universal Commerce Protocol developed with Shopify. Those developments point toward a shorter path from conversational discovery to checkout, but experiments and infrastructure plans are not guaranteed sales. Your immediate advantage comes from making your business legible to intent-matching systems and building measurement that can distinguish a real commercial gain from a persuasive dashboard.

    Start with one bounded campaign. Write the hypothesis, unit-economics limit, brand rules, comparison method, and stop conditions before enabling the change. That single page of decisions will do more for your eventual sales result than adopting every AI feature at once.

    References

  • Google AI Search Personalization: A Publisher Traffic Plan

    Google AI Search Personalization: A Publisher Traffic Plan

    If your rankings still look familiar but organic sessions are getting harder to explain, stop looking for one universal search result. In AI Mode, an opted-in user can receive answers shaped by purchases, receipts, travel plans, interests, and connected Google apps. A rank tracker cannot reproduce that person’s private context, so its screenshot represents only one possible result.

    Your job is not to reverse-engineer anyone’s inbox or photo library. It is to identify which pages can be absorbed into a personalized answer, which pages still give the user a reason to visit, and how to measure the change without pretending that one ranking position explains it.

    One query no longer implies one reproducible result

    Traditional rank analysis treats the query as the main input: enter the same words under similar conditions and expect roughly comparable results. Personal Intelligence adds a private context layer. Google has expanded it to AI Mode for U.S. personal accounts, while related rollouts are moving through Gemini for free users and Chrome. Workspace accounts are not included for now.

    Users must opt in to app connections and can turn those connections off. Depending on what they connect, Google can combine the immediate query with information from services such as Search, Gmail, Photos, and YouTube. That changes what the system needs from the public web before it constructs an answer.

    • A shopping request can be narrowed by previous purchases, preferred brands, or buying behavior.
    • A troubleshooting request can use receipt details to identify the exact device involved.
    • A travel request can reflect flights, previous trips, and other personal plans.
    • A recommendation can be adjusted around interests and hobbies already visible in the user’s connected history.

    The distinction that matters for publishers is simple: you can improve the public information your page contributes, but you cannot control the private facts used to select, filter, or apply it. Producing dozens of thin pages for imagined personal profiles will not solve that problem. It is more useful to make one strong page explicit about the conditions under which each answer applies.

    For every important query cluster, create a context card with these fields:

    • User task: What decision, diagnosis, plan, or action is the person trying to complete?
    • Possible private context: What purchase, device, itinerary, preference, or history could narrow the answer?
    • Your public contribution: What verifiable fact, method, comparison, compatibility rule, or limitation does your page supply?
    • Click-worthy remainder: What useful work remains after a concise AI answer has been generated?
    • Qualification: Which model, location, account type, prerequisite, or exception changes the recommendation?

    This turns personalization from an unknowable ranking variable into a content-planning question. You do not need to predict every user. You need to publish information that remains accurate when the system combines it with different user contexts.

    Keep privacy out of your testing shortcuts. Google states that Gmail and Photos content is not directly used to train its AI models, although limited information such as prompts and responses may be used to improve systems. That does not make private accounts appropriate rank-tracking assets. Do not ask a staff member to connect a personal inbox or photo library just to capture search screenshots. If you do not have a legitimate, voluntarily opted-in testing setup, record the personalized layer as unobserved.

    Diagnose traffic change without relying on a single rank

    An analyst examines multiple abstract search-result pathways, with colored particles either stopping at answer cards or continuing to publisher page tiles.

    The traffic risk is credible, but its size is not established by the available evidence. Yahoo CEO Jim Lanzone has described Google AI Mode as the largest challenge from large language model interfaces to the traditional system in which search sends visits to publishers. He also tied the quality of answer engines to the continued health of the publishers that produce their underlying content.

    Treat that as a directional warning, not a universal loss estimate. A falling session count can also reflect demand, seasonality, indexing, a site release, a measurement change, or a weaker search snippet. Personalized AI results add another plausible mechanism; they do not remove the others.

    Use a cohort-based diagnostic instead of checking isolated keywords:

    1. Describe the observable environment. Record country, personal or Workspace account, signed-in state, AI Mode availability, and whether app connections are enabled. Record the setting, never the private contents of a connected account.
    2. Group pages by completion risk. A definition or short factual lookup may be fully answerable in the interface. A comparison or recommendation may depend on context. A detailed procedure, tool, transaction, or evidence set may still require a visit.
    3. Choose business signals for each group. Track available search visibility, organic entrances, meaningful on-site completions, and branded demand. Do not let a visibility metric stand in for revenue, leads, subscriptions, or another outcome that actually matters.
    4. Annotate other changes. Mark site migrations, template releases, indexing problems, campaign changes, and shifts in audience exposure alongside AI product changes.
    5. Compare page cohorts. If concise answer pages weaken while visit-dependent pages hold, that pattern is more informative than one volatile query. It is still an observation to investigate, not proof of a single cause.

    The following combinations are useful diagnostic prompts. None proves that AI Mode caused the movement.

    Observed patternPlausible readingNext check
    Search visibility and organic entrances both declineThe page may be losing discovery earlier in the journey.Check demand, indexing, site changes, query coverage, and affected page types before assigning a cause.
    Search visibility holds while organic entrances declineUsers may be seeing the result but completing more of the task without visiting, or the search presentation may have changed.Compare completion-risk cohorts and document the account environment used for any manual observations.
    Organic entrances decline while conversions holdSome lost visits may have carried weak intent.Judge the change by business value as well as session volume, and inspect which landing-page cohorts lost traffic.
    Organic entrances hold while conversions declineThe main problem may sit after the click rather than in AI visibility.Inspect intent alignment, page experience, offer clarity, forms, checkout, and other on-site changes.

    This measurement model accepts a hard limit: personalized output cannot be audited as though it were a fixed national ranking. You can still detect exposure and outcome patterns, but you must preserve the conditions attached to each observation. A screenshot with no account-state notes is weak evidence.

    Give the answer engine clarity and the reader a reason to continue

    An abstract AI prism extracts organized fact blocks from the entrance of a layered publisher page while a reader continues toward original testing, photography, comparison objects, and an expert demonstration.

    A page now has two jobs. It must make its core information easy to interpret, and it must contain enough additional value to justify a visit. Hiding the answer behind a long introduction may weaken the first job. Publishing only the answer may eliminate the second.

    Build the page in layers:

    • State the direct answer. Put the central conclusion in plain language and identify who or what it applies to.
    • Expose the decision variables. Name the compatibility requirements, prerequisites, exclusions, locations, versions, models, or user conditions that can change the result.
    • Support the conclusion. Show the evidence, reasoning, calculation, comparison criteria, or complete method behind the short answer.
    • Handle exceptions near the relevant claim. Do not bury a decisive limitation in a generic disclaimer at the bottom.
    • Provide the next useful action. A diagnostic path, full procedure, decision tool, original dataset, detailed comparison, or transaction can give the reader a concrete reason to continue.

    Personalization makes precise attributes more valuable than generic enthusiasm. If a system knows the device from a receipt, your troubleshooting page should state which models, symptoms, and operating conditions its instructions cover. If a system knows a travel itinerary, your page should make location limits, timing constraints, and exceptions explicit. If it knows a buyer’s preferred brands, a comparison should explain meaningful tradeoffs instead of repeating brand positioning.

    The private detail narrows the problem; your content still has to supply the reliable public rule. That is the part you can optimize.

    Use this editorial check before updating an exposed page:

    • Can the opening answer stand on its own without losing an essential qualification?
    • Are important entities, products, versions, and relationships named consistently?
    • Can a reader see why the recommendation changes under different conditions?
    • Does the page contain evidence or functionality beyond a concise summary?
    • Are unsupported superlatives, vague claims, and redundant sections removable?
    • Does the structured data accurately describe the visible page rather than promise information the page does not contain?

    JSON-LD belongs in that final consistency check. Choose a schema type that truthfully represents the page, keep entity names and properties aligned with the visible content, and validate the markup when the page changes. Schema can clarify meaning; it cannot manufacture distinctive information or guarantee traffic from a personalized answer.

    Do not optimize only for extraction. If every useful detail can be compressed into a short response with no loss, the interface may have little reason to send the user onward. The answer should be clear, but the underlying page should make the method, proof, edge cases, or next action materially better.

    Plan separately for the ad-free personalized environment

    Google is testing ads in AI Mode in the U.S., but users who connect apps for Personal Intelligence currently receive an ad-free AI Mode experience. The commitment was framed as the present state, not an irreversible promise.

    For a publisher, ad-free does not mean competition-free. The personalized answer itself can satisfy the task, even when no paid placement appears beside it. Nor does an ad-free answer protect your own advertising or affiliate revenue; that revenue still depends on the user reaching your property.

    Maintain separate planning lanes:

    • App-connected AI Mode: Evaluate whether your content supplies a public fact or deeper action that remains useful after private context is applied.
    • General AI Mode with ad tests: Observe organic and paid changes separately. Do not attribute a movement to personalization when the test environment did not use connected apps.
    • Possible future personalized advertising: Google has indicated that future ads could relate to the query, response context, and user interests. Treat that as a scenario to monitor, not as current behavior for connected-app experiences.

    If your organization buys traffic as well as publishing content, keep the paid and organic questions distinct. An ad impression can create a commercial connection without restoring the editorial visit that the answer displaced. Conversely, a decline in organic clicks does not prove that ads captured them. Measure each route on its own terms.

    Personal Intelligence is also spreading through Gemini and Chrome. Do not assume those surfaces will display, attribute, or send visits in the same way. Inspect your own analytics for actual referral and conversion behavior, and label any behavior you cannot observe instead of filling the gap with a guess.

    Key takeaways

    • Personalized AI results combine a public query with private context, so one rank-tracking result cannot represent every user’s experience.
    • Classify pages by whether the AI interface can complete the user’s task without a visit.
    • Measure page cohorts through visibility, organic entrances, meaningful completions, and branded demand rather than relying on average position alone.
    • Make conditions, compatibility, exclusions, evidence, and next actions explicit in both visible content and accurate structured data.
    • Treat app-connected, ad-free AI Mode as a distinct environment and preserve account-state notes for every manual observation.

    Start with the page cohort most closely tied to revenue or qualified demand. Write a context card for each query cluster, mark its completion risk, and identify the useful work that remains after a personalized summary. Then update the content and measurement plan together. If you change the page without changing how you evaluate it, you will still be unable to tell whether the strategy worked.

    The publishers best prepared for personalized search will not be the ones claiming to predict every answer. They will be the ones that know exactly what their pages contribute, why a person would still visit, and which business signal would prove that value.

    References

  • AI-Powered Commerce in Google Search: A UCP Readiness Plan

    AI-Powered Commerce in Google Search: A UCP Readiness Plan

    Your product can be visible in Google and still lose an AI-led sale. The failure may have nothing to do with rankings. An AI system might be unable to confirm the right variant, reconcile two prices, understand a shipping condition, or complete the transaction without handing the shopper back to a conventional store journey.

    Google’s Universal Commerce Protocol, or UCP, gives commerce teams a framework for closing that gap. It is still in beta and intended to support purchases within Gemini and AI search environments, so this is a readiness project rather than a reason to replace your working checkout. The practical goal is to make your catalog understandable, your offer trustworthy, and your transaction systems ready for controlled participation.

    AI search is compressing discovery and checkout

    A conventional ecommerce search journey contains several opportunities for the shopper to fill in missing information. They can open a product page, inspect variants, read the returns page, compare prices, add an item to the cart, and correct a mistake before paying.

    An AI-mediated journey can compress those decisions into one request: find a highly rated waterproof hiking boot in size 10 for less than $200, then buy it. In that flow, the system has to identify a suitable product, select the correct variant, verify the price and terms, and connect the choice to checkout. UCP is designed to standardize communication between consumer AI interfaces and merchant checkout systems.

    That changes the unit of optimization. You are no longer optimizing only a page that persuades a person to click. You are also maintaining a set of facts that an AI system can use to decide whether your offer satisfies a constrained request.

    Do not treat UCP as a new ranking shortcut. A transaction protocol cannot repair an ambiguous product record, an unavailable variant, or a policy that conflicts with checkout. Keep three questions separate:

    • Discovery: Can Google understand when the product is relevant to the shopper’s request?
    • Selection: Can the system confirm that a specific product and variant meet every important constraint?
    • Execution: Can the selected offer move through checkout with the correct price, terms, and merchant relationship intact?

    Map one representative product through all three stages before discussing a broad rollout. If your team cannot identify the system that supplies each important fact, you have found a readiness problem.

    Separate product understanding from transaction plumbing

    Cutaway illustration with an upper layer interpreting product variants and a lower layer connecting inventory, payment, delivery, and order confirmation.

    Commerce teams often distribute ownership across SEO, merchandising, feed operations, ecommerce engineering, payments, analytics, and customer service. UCP crosses those boundaries. Someone therefore needs to connect the systems without pretending that one feed or protocol owns the entire customer experience.

    Use this model to define what each layer must provide:

    LayerQuestion it must answerMerchant-controlled inputs
    DiscoveryWhat is this product, and which requests is it relevant to?Product identity, descriptions, category context, and distinguishing attributes
    QualificationDoes the exact offer meet the shopper’s constraints?Variant details, size or other options, price, availability, and product attributes
    TrustAre the commercial terms clear enough to support a decision?Shipping terms, return policy, reliable pricing, and consistent offer information
    TransactionCan the chosen product and variant move through checkout correctly?Checkout integration, selected offer, payment flow, and order handling
    RelationshipWho sells the product and owns the customer relationship?Merchant-of-record status, customer communication, fulfillment, and support

    UCP can build on existing Google Merchant Center shopping feeds. That makes feed quality a sensible starting point, but it does not make the feed your only source of truth. Your product page, catalog platform, policy pages, checkout, and Merchant Center data still need to agree.

    Create a simple ownership register for the fields that affect a purchase. For each field, record its canonical system, business owner, update path, and downstream destinations. Start with product identity, variant identity, price, availability, shipping terms, and returns. When two systems disagree, the register tells the team where the correction belongs.

    This avoids a common operational trap: manually repairing the visible feed while leaving the underlying catalog or policy system unchanged. The temporary correction disappears during the next synchronization, and the contradiction returns. Repair the canonical value first, then verify every downstream representation.

    Build product records that can answer constrained requests

    The fastest way to audit AI-commerce readiness is to turn a buying request into a fact checklist. Consider the request to find a highly rated, waterproof hiking boot in size 10 for less than $200. The candidate record must support several independent decisions: product type, intended use, waterproof status, size availability, price, and rating evidence.

    A page can look complete to a shopper while still leaving one of those decisions unresolved. A lifestyle image might imply outdoor use without confirming waterproof construction. A size selector might show size 10 on the page even though that variant is unavailable. A promotional headline might promise a lower price that is not reflected in the feed or checkout.

    Run a query-to-record audit in this order:

    1. Choose a commercially important product. Use an item with real variants, attributes, and policy conditions. A product with no options will not expose the difficult gaps.
    2. Write realistic constrained requests. Include only requirements your catalog can honestly prove. Do not manufacture a rating, certification, feature, or use case to make the test easier.
    3. Break each request into atomic facts. One fact should answer one decision: product type, attribute, variant, price, availability, shipping condition, or return term.
    4. Locate the canonical value. Identify where each fact originates and where it is transformed before appearing in Merchant Center, on the product page, or at checkout.
    5. Compare every representation. Check the same product and variant across the catalog, feed export, live page, policy content, cart, and checkout.
    6. Classify each failure. Mark a fact as missing, vague, contradictory, stale, or unsupported. Those labels make the remediation clear.
    7. Repair the source and retest. Confirm that the corrected value reaches every surface instead of checking only the system you edited.

    Prioritize facts that can change the purchase decision or the order itself. Product identity and variants come first because the wrong selection creates the wrong order. Price, availability, shipping, and returns come next because they determine whether the offer remains valid at checkout. Rich descriptive copy matters, but it should not conceal a missing operational fact.

    Write product information so that important attributes stand on their own. If waterproof construction affects eligibility, state it as a supported product fact rather than asking a model to infer it from words such as “trail-ready.” If a feature applies only to certain variants, attach it to those variants rather than the entire product family. If the evidence is unavailable, leave the claim out until the business can support it.

    Use the same discipline for product descriptions. Google-oriented copy still needs to help a person, but completeness matters more in an agentic decision. A useful record answers what the item is, which option is being offered, which constraints it satisfies, what it costs, and which conditions apply. Repetition and promotional adjectives do not compensate for a missing fact.

    Treat trust signals as transaction data

    A product package surrounded by linked security, inventory, delivery, returns, payment, and verification symbols, with two visibly inconsistent signals disrupting the network.

    When a shopper browses your store, design, reviews, support content, and policy pages can gradually build confidence. A compressed AI journey gives those cues less room to work. The commercial terms themselves have to carry more of the trust burden.

    That is why free-shipping information, return policies, and reliable pricing belong in the core commerce-data audit. They are not supporting copy to update after the integration. They can determine whether an offer is suitable before checkout begins.

    Check each trust signal for three qualities:

    • Present: The relevant term is available where the product or transaction system needs it.
    • Precise: Conditions, exclusions, applicable regions, variants, or order requirements are stated instead of hidden behind a broad promise.
    • Consistent: The feed, product page, cart, checkout, confirmation, and policy page do not tell different stories.

    Review terms from the perspective of one exact order. Do not ask whether your site “has a returns policy.” Ask which return terms apply to this product, in this condition, for this customer and destination. Do not ask whether you advertise free shipping. Ask whether the selected order actually qualifies and whether checkout produces the same result.

    Use plain operational wording. “Easy returns” is a marketing description, not a usable rule. The real policy should explain the applicable period, product conditions, exclusions, costs, and initiation process as they actually operate. Likewise, a price is useful only when it refers to the selected variant and remains true when the order reaches checkout.

    Contradictions carry a direct commercial cost. A shopper can authorize a purchase based on a term that your checkout, fulfillment team, or support policy cannot honor. That can lead to abandoned transactions, cancellations, returns, support work, and damaged trust. If a condition cannot be represented reliably, keep that offer out of an automated buying path until the systems agree.

    UCP is also designed so that the seller remains the merchant of record and preserves its customer relationship and data. Treat that as an operating responsibility, not just a benefit. Decide who sends confirmations, handles fulfillment questions, processes returns, manages consent, and resolves disputes before accepting an AI-originated order.

    Roll out UCP as a controlled commerce capability

    A beta protocol should not become a hidden dependency for your entire revenue path. Keep your current store and checkout working while you develop the data, governance, and integration needed for AI-assisted transactions. The aim is to learn which parts of your commerce stack are ready without turning early access into a full migration gamble.

    A practical rollout sequence looks like this:

    1. Name one accountable owner. Give that person authority to coordinate SEO, feed operations, merchandising, engineering, payments, analytics, fulfillment, and support.
    2. Define the canonical commerce record. Document where product, variant, price, availability, shipping, and return facts originate.
    3. Audit a narrow product set. Select products that expose meaningful attributes and variants, then complete the query-to-record and trust-signal checks.
    4. Preserve the existing purchase path. Do not remove a proven checkout merely because an AI-native path is being evaluated.
    5. Set release gates. Require accurate product data, consistent policies, correct variant transfer, valid checkout behavior, order confirmation, and clear operational ownership before expanding scope.
    6. Explore the available programs. Google points merchants toward pilot opportunities and related capabilities such as Business Agents and Direct Offers. Evaluate each against the problem it solves rather than enabling every feature at once.
    7. Expand by evidence. Add products only after the previous group can move from request to fulfilled order without unresolved data or policy conflicts.

    Measure the rollout as a funnel with operational checks, not as a single conversion-rate experiment. Your dashboard should distinguish data health, product selection, checkout execution, and post-purchase outcomes. Useful measures include missing or rejected product data, stale offer information, selected products and variants, checkout starts, completed orders, cancellations, returns, and support issues tied to AI-originated transactions. Use only the signals your systems and pilot access can identify reliably.

    Do not combine all failures under “AI traffic.” A product that was never considered has a discovery or qualification problem. A selected product that arrives at checkout with the wrong variant has an integration problem. A completed order that is later canceled because a shipping promise was wrong has a policy or operations problem. The remedy depends on the stage.

    Keep a decision log during the beta. Record which products were included, which systems supplied their facts, which assumptions were made, and why an offer was removed or expanded. That record becomes the foundation for governance when access, interfaces, or program requirements change.

    Key takeaways

    • UCP connects AI consumer interfaces with merchant checkout systems; it does not substitute for accurate product data.
    • Optimize for a purchasable answer: a specific product and variant with enough evidence to satisfy the shopper’s constraints.
    • Assign a canonical source and owner to every fact that can change product selection, price, shipping, returns, or fulfillment.
    • Treat pricing, shipping, and return terms as decision data, then verify that they remain consistent through checkout.
    • Preserve your existing checkout while UCP remains in beta, and start with a narrow, representative product set.
    • Diagnose discovery, qualification, transaction, and post-purchase failures separately so each team fixes the right system.

    Start with one product that has real variants and meaningful policy conditions. Write the request an informed shopper would give an assistant, trace every required fact to its source, and follow the selected offer through checkout. The gaps you find will tell you what to repair before AI-powered commerce becomes a larger part of your Google strategy.

    References

  • Google AI Advertising Strategy: What Marketers Should Do Now

    Google AI Advertising Strategy: What Marketers Should Do Now

    If you are waiting for a Gemini campaign type before changing your Google advertising plan, you are waiting for the least important part. Google is already learning how ads behave in AI-generated experiences, while its campaign systems are becoming more willing to assemble, resize and select creative for you.

    The useful response is not to move budget into an unannounced product. It is to make your offers easier to match to conversational intent, clean up the assets Google can reuse and put measurement guardrails around automation. Those changes improve campaigns you can run now and leave you ready if Gemini becomes advertising inventory later.

    Read Google’s AI ad strategy as two connected systems

    Google’s direction contains two different levels of certainty. The current testing ground is AI Mode, a Gemini-powered Search experience where ads are kept distinct from organic results, clearly labeled and shown only when Google considers them relevant. If an appropriate ad is not available, the experience can proceed without one.

    Gemini advertising belongs in the possible-later column. Google has indicated that lessons from AI Mode could eventually inform ads in the Gemini app, but it has not committed to a launch date, buying workflow or dedicated campaign format. Treat that as strategic direction, not media inventory you can forecast.

    At the same time, Google is expanding the creative work its existing systems can perform. Demand Gen’s Asset Optimization controls now group shorter auto-generated videos, automatic video resizing and images pulled from landing pages into a simpler set of toggles. This is operationally important: Google can test more combinations and placements when the advertiser supplies reusable source material.

    Strategic layerWhat is establishedWhat you should do
    Conversational deliveryGoogle is testing labeled, relevance-dependent ads in AI Mode.Map campaigns to the decisions users describe, not only the keywords they type.
    Creative assemblyDemand Gen can shorten videos, resize them and pull images from landing pages.Govern the original assets and inspect automated variants before relying on them.
    Gemini inventoryGoogle has left the possibility open, without announcing a buying product.Prepare reusable inputs, but do not assign a speculative Gemini budget.
    Personalized contextGoogle sees personalization as important, while broader Search integration remains prospective.Track product and data-policy announcements instead of assuming new targeting access.

    Use a no-regret test for every preparation project: would it still improve your current Search or Demand Gen operation if Gemini never carried ads? Clearer landing pages, better asset governance and stronger conversion measurement pass that test. A Gemini-only media plan does not.

    Build campaigns around the decision behind the query

    A strategist examines visual intent clues as shoppers follow branching paths toward different products and services.

    Keyword intent still matters, but conversational interfaces let a user express the situation around a purchase: who the product is for, what constraint matters and what must be true before they act. An ad can be relevant to the topic while being irrelevant to that decision. Your campaign brief should expose the difference.

    For each important offer, create a decision map with the following fields:

    1. Decision: Write the choice the user is trying to make, not the keyword category. A software buyer may be choosing a platform for a distributed team rather than searching for software in the abstract.
    2. Context: Record the audience, use case and stage of consideration that make the offer appropriate.
    3. Constraint: Identify the condition that can disqualify the offer, such as compatibility, geography, deployment model or required feature.
    4. Claim: State the promise the ad can make without exceeding what the landing page supports.
    5. Proof: Point to the specification, demonstration, policy, price information or other evidence that substantiates the claim.
    6. Destination: Choose the page that resolves this particular decision rather than sending every variation to a generic homepage.

    This map gives paid, SEO, AEO and content teams a shared factual base. It does not mean their distribution systems are interchangeable. An organic mention, an AI-generated answer and a paid placement have different eligibility and measurement rules, even when they rely on the same product facts.

    That distinction matters for structured data. JSON-LD can organize explicit facts about an entity, product, service or page, but nothing in Google’s current AI advertising direction establishes schema markup as an ad-targeting control. Use valid structured data to describe visible content accurately. Do not promise that adding markup will make an ad appear in AI Mode or secure future Gemini inventory.

    Review the landing page against the decision map before expanding creative. The page should make the intended audience, supported use case, important limitations and next action easy to find. If the ad needs a verbal explanation to remain accurate after the click, the page is not ready for automated distribution.

    Make creative automation safe before switching it on

    Two marketers review automated ad layouts while approved assets pass through digital guardrails and rejected assets are set aside.

    Demand Gen’s consolidated Asset Optimization panel reduces the work required to activate automation. It does not remove the need to supervise the material being transformed. A weak original can produce more weak variations, and an outdated landing-page image can become campaign creative without anyone deliberately selecting it.

    Audit the system in this order:

    1. Record the current settings. Open Asset Optimization and document which video-resizing, video-shortening and image options are enabled. Keep that record with the campaign brief so a later performance change can be tied to a known configuration.
    2. Create an approved asset register. For each original image or video, record the owner, usage rights, supported claim, intended audience, required context and any expiration condition. An asset should not enter automation merely because it exists in a shared folder.
    3. Inspect landing-page imagery. Because Google can pull images from the destination page, remove obsolete promotions, unsupported product states and decorative images that would be misleading when detached from the surrounding copy. Make the strongest eligible image understandable on its own.
    4. Review shortened videos as new creative. Confirm that the automated cut preserves the core claim, necessary qualification, brand identity and call to action. Watch it without sound as well as with sound. A cut that removes the condition attached to a claim should not run.
    5. Review every generated shape you intend to use. Check whether resizing crops the product, speaker, demonstration, captions, qualification or call to action. Do not assume that a technically valid crop is a persuasive or compliant ad.
    6. Change settings deliberately. Where campaign volume allows it, avoid changing every automation control alongside the landing page and offer. A smaller set of simultaneous changes makes the result easier to interpret, even if it is not a perfect controlled experiment.

    The practical division of labor is simple. Your team owns truth, permissions, positioning and the quality of the originals. Google can own format adaptation and selection only within those boundaries. If the boundaries are not documented, leave the relevant automation off until they are.

    Measure the system you can buy, not the product you imagine

    AI-flavored placement does not change the need for a falsifiable campaign brief. Before launching or expanding automation, state which user decision the campaign addresses, which conversion represents success and which downstream signal distinguishes a valuable conversion from a merely completed form or click.

    Your working scorecard should preserve enough context to explain a result:

    • The campaign, audience and offer being evaluated.
    • The landing-page version used during the period.
    • The status of each asset-optimization control.
    • The original assets available to Google.
    • The primary conversion and a business-quality signal, such as a qualified opportunity, completed purchase or retained customer.
    • Any brand, policy or lead-quality guardrail that would make higher delivery unacceptable.

    Do not use click-through rate alone to declare an AI ad strategy successful. A new format can attract interaction while sending poorly matched users. Read the engagement metric beside conversion quality, acquisition cost and the business outcome your campaign was meant to produce.

    Keep a separate launch gate for future Gemini advertising. Before moving money, verify the inventory available to your account, eligible campaign types, placement and exclusion controls, creative-generation settings, reporting granularity, conversion attribution and the data used for personalization. If Google does not expose enough information to answer those questions, the responsible response is a limited test inside the controls that do exist, not a broad budget shift.

    Personalization deserves particular care. Google’s Personal Intelligence can draw on a user’s Gmail, Photos and Calendar, and Google has said that user data will not be sold or shared. Broader integration with Search remains a possibility rather than an advertiser capability you can plan around. Do not translate consumer-facing personalization into an unsupported claim that advertisers can access those personal signals.

    This measurement discipline also keeps organic AI visibility separate from paid reach. Track whether your brand is represented accurately in AI-generated answers, but do not count a citation, a paid impression and an assisted conversion as the same event. They can influence the same journey without proving the same thing.

    Key takeaways

    • AI Mode is Google’s current environment for learning how labeled, relevance-dependent ads fit into AI-generated search experiences.
    • Ads in the Gemini app remain possible, but no dedicated buying format, launch date or workflow has been established.
    • Demand Gen’s asset controls reveal the immediate operational priority: provide strong originals and let automation adapt them under supervision.
    • Organize campaigns around a user’s decision, context, constraint, claim, proof and destination rather than treating conversational advertising as a longer keyword list.
    • Audit landing-page images because they may become ad assets, and review shortened or resized videos as new creative rather than harmless copies.
    • Keep structured data, organic AI visibility and paid placement conceptually separate. Shared facts help all three, but none guarantees the others.

    At your next campaign review, open the Demand Gen Asset Optimization panel, record its settings and inspect every page and asset it can draw from. Then build one decision map for your highest-value offer. When Google exposes more conversational inventory, you will have approved inputs and a measurement plan ready, without having paid for a strategy built on speculation.

    References

  • How to Keep Modern Content Visible in Google Search

    Your page looks complete in a browser, answers the query well, and still struggles to appear or earn visits from Google. The problem may not be the writing. Modern visibility can break at several points: Google may receive the wrong rendered output, the important answer may be hard to extract, the result may lack the details people use to choose, or an AI response may satisfy the basic need without giving them a reason to click.

    You can diagnose those problems without treating SEO as one mysterious score. Separate visibility into rendering, interpretation, selection, and visitation. Then fix the layer that is actually failing.

    Treat visibility as a chain, not a single SEO score

    A page being technically available does not mean it is easy to understand. A page being understood does not mean it will be selected for a result. Selection does not guarantee a visit. Those are different outcomes, and each calls for a different test.

    Visibility layerQuestion to answerLikely failure signalWhat to inspect
    RenderingDoes Google receive the essential content?Important text, links, or page context are absent from the rendered output.The inspected URL, rendered text, primary links, and content loaded by JavaScript.
    InterpretationIs the page’s purpose and answer unambiguous?The page contains the information, but it is scattered, weakly labeled, or detached from its qualifiers.The title, main heading, opening answer, section labels, terminology, and structured-data parity.
    SelectionDoes the page expose the details needed to choose it?The content is relevant but lacks a concise overview, decision attributes, limitations, or a clear fit for the query.The direct answer, scope, prerequisites, distinguishing details, and useful summary information.
    VisitationIs there a clear reason and route to continue?The result can summarize the basic answer, but the destination promises no obvious additional value.Visible links, result-to-page continuity, deeper analysis, complete instructions, examples, and next-step utility.

    This model prevents two expensive misdiagnoses. The first is rewriting good content when the rendered page is incomplete. The second is rebuilding the front end when Google already sees the page and the real weakness is that the content does not help a searcher make a decision.

    Start every audit by writing down the failing outcome in plain language. Is the page absent? Is the wrong passage appearing? Is an important qualifier being lost? Is the page visible but not compelling enough to visit? A precise symptom gives you a testable next step.

    Prove what Google receives from your JavaScript pages

    JavaScript is not automatically an SEO barrier. Google has successfully rendered JavaScript-loaded content for years, which makes blanket warnings about client-rendered pages obsolete. It does not make every JavaScript implementation reliable.

    The distinction is simple: platform capability is not implementation verification. Google may be able to execute JavaScript while your page still returns an error, delays essential content, requires an interaction, depends on a personalized state, or renders something different from what you expected. You have to inspect your output, not infer it from Google’s general capability.

    1. Select representative URLs from every important template, especially templates that load the main answer, product details, navigation, or internal links dynamically.
    2. Open each URL as a normal visitor and record the elements that make the page useful: its main heading, central answer, important qualifiers, primary links, and any details needed to make a decision.
    3. Use URL Inspection in Google Search Console to verify what Google sees. Compare the inspected output with the visitor-facing page element by element.
    4. Classify every difference. Missing main copy is a rendering problem. Present but poorly labeled information is an interpretation problem. Missing links are a discovery and visitation problem. Do not group all of them under technical SEO.
    5. Repeat the check after changes to rendering, hydration, content APIs, consent handling, navigation, or reusable page components. A successful inspection of one template does not validate unrelated templates.

    Your comparison should focus on meaning, not visual perfection. Google does not need to see the page exactly as a person sees every animation or interface state. It does need the content and relationships that carry the answer. Confirm that headings still label the correct sections, qualifiers remain next to the claims they limit, and links retain descriptive destinations.

    Do not use a blank no-JavaScript view as automatic proof that Google sees a blank page. The old recommendation to disable JavaScript as a proxy for search visibility was removed after becoming outdated. A no-JavaScript test can still expose resilience problems, but it is not an accurate substitute for inspecting Google’s rendered result.

    Keep the essential answer portable

    Google’s rendering strength should not become an excuse to make every crawler reproduce your entire application before it can understand a page. Some emerging AI search systems may not process JavaScript as effectively. Where your architecture allows it, place the page’s purpose, central answer, meaningful headings, and essential links in the initial HTML. Let JavaScript enhance the experience rather than supply every piece of meaning.

    This is a portability decision as much as an SEO decision. A stable semantic layer can serve conventional search crawlers, AI retrieval systems, browser tools, and visitors on constrained devices. It also gives your team a simpler baseline to test.

    Do not maintain a separate hidden answer for machines. That creates a drift problem: the visible page says one thing while the machine-facing version says another. Render the same core facts for everyone, then add interactive controls, personalization, and presentation around them.

    Keep accessibility and search rendering as separate checks

    Google’s removal of old accessibility language from its JavaScript SEO material does not make accessibility optional. It means the earlier warning was no longer a useful description of Google’s rendering capability, and modern assistive technologies can generally process JavaScript. Your implementation can still create inaccessible controls, confusing focus behavior, or content that is difficult to navigate.

    Keep two acceptance criteria in your release process: Google must receive the essential rendered meaning, and people using assistive technology must be able to operate and understand the interface. Passing one check does not prove the other.

    Shape the page into a decision-ready answer

    Rendering gets your content into consideration. It does not make the content a good candidate for an AI-generated result. The page must expose an answer that can be understood without reconstructing it from scattered paragraphs, while preserving the context that keeps the answer accurate.

    Google’s AI Mode recipe experience illustrates the distinction. Searchers can open individual dishes, follow links to recipe creators, read a quick overview, and see details such as cook time. Those details help people decide which option to explore.

    That does not make cook time a universal ranking factor, and it does not mean every content type should imitate a recipe card. The transferable principle is that selection requires decision information. Your page should state not only what the answer is, but also when it applies, what it requires, where its limits are, and what makes the destination useful.

    Build a self-contained answer block

    Near the beginning of the page, give the reader a compact resolution to the primary question. Include the condition that would materially change the answer. Then expose the attributes a person would use to choose whether the page fits their situation.

    • Direct resolution: State the answer before the long explanation. Do not make the reader cross an introductory essay to discover your position.
    • Scope: Name the platform, content type, implementation pattern, or audience for which the answer applies.
    • Decision attributes: Surface prerequisites, compatibility, effort, constraints, or other details that determine fit.
    • Qualifiers: Keep exceptions beside the claim they modify. A distant caveat is easy for both readers and automated systems to miss.
    • Continuation: Indicate what the full page adds, such as the complete workflow, diagnostic branches, worked examples, or implementation details.

    For a page about JavaScript SEO, for example, the useful opening is not merely that Google supports JavaScript. The decision-ready answer is that Google can render it, each implementation still needs inspection, and essential meaning should remain portable when other retrieval systems may not execute the page as well. The additional conditions turn a technically true statement into actionable guidance.

    Apply the same discipline to headings. A heading such as Benefits carries little meaning outside its surrounding page. A heading such as When client rendering creates a visibility risk identifies the question the section resolves. Descriptive headings help the visitor scan and give extracted passages useful context.

    Use JSON-LD as a faithful machine-readable echo

    If you publish JSON-LD, make it agree with the visible page. Names, descriptions, relationships, attributes, and other claims should not conflict with what a person can read. Structured data should clarify an already coherent page, not compensate for missing content or introduce a more attractive machine-only version.

    Include schema parity in editorial QA. When a visible fact changes, identify every place that repeats it: body copy, summary modules, metadata, JSON-LD, and reusable components. A technically valid graph can still be unhelpful if it describes an earlier version of the page.

    Preserve a reason to visit after the basic answer is visible

    AI visibility and referral traffic are related, but they are not the same outcome. An AI result may use your information while resolving the immediate question inside the search experience. Even when Google adds a visible link, the link is only an opportunity. The searcher still needs a reason to follow it.

    The wrong response is to hide the central answer. If the page withholds the useful part, it becomes a weak candidate for selection and a frustrating destination. Instead, divide value by depth.

    • In the extractable layer, provide the direct answer, its scope, critical qualifiers, and the details needed to judge relevance.
    • On the destination page, continue with the complete method, edge cases, evidence you can substantiate, examples, troubleshooting paths, and tools that help the visitor act.
    • At the transition, make the next value explicit. A generic Learn more link hides the payoff; a descriptive destination tells the reader what the click will complete.

    This is especially important when a search result offers a quick overview. The overview can establish relevance, but the destination should resolve the work that remains. A recipe result can help someone choose a dish, while the creator’s page can still provide the full method and context needed to make it. Your content should have an equally clear division between selection value and completion value.

    Check continuity from result to page. The linked destination should open on the content promised by the result, use consistent terminology, and reveal the next useful step quickly. Sending someone from a specific AI citation to a generic category page wastes the moment of intent.

    Internal links deserve the same treatment. If a section introduces a decision that another page resolves, link with words that name that decision. This creates a route through the subject for readers and makes the relationship between pages explicit.

    Diagnose the failing layer before you rewrite

    A modern visibility audit should end with a classified defect, not a list of generic SEO recommendations. Use the observed symptom to choose the work.

    • Essential content is missing from Google’s inspected output: Fix rendering, delivery, or state dependencies before changing the prose. Confirm that the affected template works after the change.
    • The content renders, but the purpose is difficult to state: Tighten the title, main heading, opening answer, and section labels. Remove competing introductions that delay the primary resolution.
    • The answer is accurate but loses its conditions when extracted: Move the qualifier beside the claim, use a self-contained sentence, and keep the same qualification in summaries and structured data.
    • The page answers the topic but does not help a person choose: Add the relevant prerequisites, constraints, compatibility information, or other decision attributes supported by the page.
    • The basic answer is visible but visits remain weak: Clarify what the destination adds. Strengthen the result-to-page promise rather than repeating the same summary at greater length.
    • Google handles the page but other AI systems struggle: reduce dependence on client execution for the essential semantic layer while keeping richer interactions available to visitors.

    Audit at the template level as well as the URL level. If every page using a component loses its main link during rendering, editing individual pages will only conceal the shared defect. If only one page has an unclear answer, a site-wide rebuild is unnecessary.

    Keep a short record for each tested URL: the intended query, the essential visible answer, whether that answer appears in Google’s inspected output, the decision details present, the continuation value, and the defect class. That record gives developers, editors, and schema owners the same definition of done.

    Key takeaways

    • JavaScript is not inherently invisible to Google, but your own rendered output still needs verification in Search Console.
    • A page can pass rendering and still fail because its answer, scope, or qualifiers are hard to extract.
    • AI-oriented content needs decision details, not just a concise summary.
    • JSON-LD should mirror visible, current content rather than act as a substitute for it.
    • A link in an AI result does not guarantee a visit; the destination must promise useful continuation beyond the overview.
    • Classify the failure as rendering, interpretation, selection, or visitation before assigning the fix.

    Begin with one commercially important template. Inspect what Google receives, rewrite its opening as a self-contained answer, verify visible and structured-data parity, and make the next-step value unmistakable. Once that pattern passes all four layers, apply it to the rest of the site.

    References

  • Google AI Commerce: How Ecommerce Brands Stay Visible

    Google AI Commerce: How Ecommerce Brands Stay Visible

    Your product can hold a respectable search position and still lose the sale before a shopper reaches your site. When an AI system interprets the need, compares the options, chooses an offer and potentially handles checkout, the decisive visibility event happens upstream of the click.

    You now need to make each product easy for an agent to find, understand, select and transact. That means treating product truth, recommendation fit and operational readiness as parts of SEO rather than leaving them to separate catalog, merchandising and checkout teams.

    The sale can now be won before a site visit happens

    The familiar ecommerce journey starts with a query, moves through a search result and ends on a merchant-controlled product page or checkout. Google’s AI commerce direction compresses that journey. Its Universal Commerce Protocol enables AI agents to discover, evaluate, recommend and purchase products across the web within Google’s AI experiences.

    UCP matters because it is not an isolated shopping widget. Its launch collaboration included Shopify, Etsy, Wayfair, Target and Walmart, with existing payment networks incorporated. Google also introduced three related commerce surfaces: Business Agent for brand-specific conversations in Search and Gemini, Direct Offers for promotions inside AI Mode, and Checkout in AI Mode for purchases completed within Google’s interface.

    For you, the important shift is from ranking alone to selection. A conventional ranking report asks whether a URL appeared and received a click. AI commerce requires four different questions:

    Visibility stageQuestion to answerTypical failure to investigate
    EligibilityCan the system find and use the product record?The item, variant or offer is absent, inaccessible or unsupported.
    InterpretationCan it identify exactly what the product is?Names, identifiers, attributes, prices or availability conflict.
    SelectionCan it explain why this product fits the shopper’s need?The catalog describes the item but not its use, constraints or differences.
    TransactionCan the selected offer be purchased successfully?The offer is stale, the variant is unavailable or the handoff fails.

    Your website remains important. It may still be the clearest public expression of your product facts, policies and brand expertise. But a polished page cannot compensate for exclusion at the eligibility stage, contradictory data at the interpretation stage or weak product fit at the selection stage. Diagnose the stage that failed before rewriting copy or increasing media spend.

    Build a product truth layer before optimizing recommendations

    A running shoe is connected to organized product details, inventory, shipping and verification symbols above a foundation of data blocks.

    The first job is agreement, not persuasion. Your page, structured data, catalog feed, commerce platform, inventory system and checkout should describe the same purchasable item. If they disagree, an agent has to decide which representation to trust while the shopper sees only the result.

    Create a field-level catalog audit. For each commercially important product and variant, record the canonical system, the surfaces that publish the field, the event that refreshes it and the person responsible when synchronization fails. Inspect at least these groups of information:

    • Identity: product name, brand, internal identifier, SKU and any supported external identifier.
    • Variant definition: the attributes that distinguish one purchasable option from another, such as size, color, configuration or quantity.
    • Offer state: current price, currency, discount terms, availability and the exact variant to which each value applies.
    • Product facts: materials, dimensions, included components, compatibility, care requirements and other attributes the shopper may use to rule an option in or out.
    • Fulfillment facts: the shipping, pickup or delivery conditions your operation can actually honor.
    • Policy facts: the conditions that affect the decision or the completed order, including relevant return, cancellation and warranty terms.

    This is not a claim that every field is a UCP requirement. It is a practical inventory of the commercial truths that discovery, comparison and checkout systems must keep straight. Match the audit to the fields, integrations and eligibility rules that apply to your own platform setup.

    Keep identifiers and variants stable

    Variant ambiguity is particularly costly. A parent product may be available while the size or configuration the shopper wants is not. If the parent page, structured data and feed collapse those states into one generic record, the system can recommend an option that cannot be purchased.

    Use stable identifiers for the same item everywhere. Do not casually recycle an identifier after replacing a product, merge materially different variants into a single offer or use different names for the same attribute across systems. When a product changes enough that compatibility or customer expectations change, treat identity as a catalog decision rather than a copy edit.

    Make freshness an operating rule

    Price and availability are state, not static content. Document what event updates each downstream representation: an inventory change, a promotion activation, a price revision or a product withdrawal. Then define what happens when the update does not arrive. A safe failure may mean suppressing an uncertain offer until it is reconciled instead of continuing to advertise a price or item you cannot honor.

    Test a real purchasable variant from end to end. Compare its visible page, Product and Offer structured data where used, feed record, API response, cart and checkout. Search for disagreement in identifiers, price, currency, availability and variant labels. A valid schema block does not make a stale price true; structured data is a machine-readable representation of your commerce record, not a substitute for one.

    Give the recommendation system reasons to choose you

    Traditional product copy often assumes that the shopper already knows the category and is comparing familiar options. Conversational shopping starts earlier. Gemini can turn requests such as planning a camping trip or removing wine from a couch into product discovery based on inventory, price and availability. The initial language may describe a problem or outcome without naming a product category.

    A catalog full of short, near-duplicate descriptions gives an agent little basis for matching those needs. Add decision information that helps it distinguish fit. For each priority product, make the following explicit in visible, accurate language:

    • What the product is, without relying on a clever product name to carry the definition.
    • Which use cases it is designed for and which product attributes support those uses.
    • Which shopper, environment or constraint it suits.
    • What it requires to work, including compatibility, installation or complementary components where relevant.
    • How it differs from nearby options in your own range.
    • When another option is a better fit.
    • Which claims are factual and where the supporting evidence appears.

    The last two points deserve attention. If every item is described as the best choice for every buyer, none of the descriptions provides a useful selection boundary. A clear exclusion such as an incompatible device, unsuitable environment or missing feature can improve recommendation fit by preventing the wrong product from being chosen.

    Do not turn this into an exercise in manufacturing question-and-answer text or repeating likely prompts. Write complete product facts and decision criteria in the language customers use. The goal is not to imitate a chatbot. It is to remove the inference a chatbot would otherwise have to make.

    Make category pages do comparison work

    A product page can explain one item well while the category still fails to explain choice. Build category content around meaningful differences: intended use, decisive attributes, compatibility, level of capability and tradeoffs. If two products differ only in internal merchandising language, rewrite the distinction so a customer can tell why both exist.

    Use comparison tables only when the attributes are genuinely comparable. Keep values normalized, name units and avoid leaving a blank cell when the real meaning is unknown, not applicable or not included. Those states lead to different decisions and should not be collapsed into the same empty space.

    Prepare each AI commerce surface as a separate operation

    A travel bottle on a central operations hub connects to conversational, comparison, visual discovery and checkout surfaces through separate readiness gates.

    Business Agent, Direct Offers and Checkout in AI Mode affect different parts of the buying journey. Do not assume that connecting one surface makes the others accurate or operational. Give each capability an owner, a source of truth, an approval boundary and a failure procedure.

    Business Agent needs governed brand knowledge

    Business Agent acts as an AI-powered brand representative in Search and Gemini, where shoppers can ask about products, compare choices and receive brand-specific guidance without opening a separate site. That makes answer quality part of merchandising and reputation management, not merely customer support.

    Start by identifying the questions that materially change a purchase: suitability, compatibility, differences between models, included components, availability and relevant policies. Map each answer to an approved source. Decide which claims can be stated directly, which require conditions and which should not be made. When an answer depends on information the agent cannot reliably access, provide a safe path to verification rather than filling the gap with promotional language.

    Audit the agent as a buyer would use it. Ask underspecified questions, add a constraint, change a variant and challenge a recommendation. Check whether the answer preserves the constraint, cites the correct product facts and avoids promising unavailable stock or unsupported capabilities.

    Direct Offers need commercial controls

    Direct Offers allow merchants to put exclusive discounts into AI Mode, placing the promotion inside the recommendation environment. That can make offer quality part of selection, but it also introduces margin and customer-expectation risk.

    Every offer should have an unambiguous product or variant scope, eligibility rule, valid period, discount definition and fallback state. Confirm that the same terms reach the agent, cart and order system. If the promotion cannot be honored at checkout, suppress or correct it rather than relying on fine print after selection. An expired or mis-scoped offer can turn added visibility into support costs, cancellations and lost trust.

    Checkout in AI Mode needs order-level testing

    Checkout in AI Mode moves purchase completion into Google’s interface. Your storefront may no longer control every step or observe a conventional browsing session before the order. Test the transaction as an operational flow: selected variant, current price, inventory reservation, payment status, tax and delivery handling, order creation, confirmation, cancellation and returns.

    Do not begin with your entire catalog merely because the integration permits broad coverage. A bounded set of products with clean data, dependable inventory and understood margins gives you a safer place to verify order routing and exception handling. Commerce automation can create real financial exposure when a discount, stock state or fulfillment promise is wrong, so expand only after the failure path works as well as the happy path.

    Measure AI visibility as a decision journey

    Rankings, clicks and onsite conversion rate still describe part of ecommerce performance. They do not tell you whether an agent found the product, interpreted it correctly, recommended it for the right need or completed the purchase without a traditional visit. Keep the established metrics, but add observations for the stages you can now lose before the click.

    • Catalog coverage: which priority products and variants are eligible for the commerce surfaces you use.
    • Data consistency: whether identity, price, availability and offer terms agree across exposed systems.
    • Recommendation presence: whether your product appears for a controlled set of relevant buyer needs.
    • Recommendation accuracy: whether the explanation, constraints and selected variant match the underlying product facts.
    • Offer integrity: whether the displayed promotion remains valid through checkout.
    • Transaction quality: whether the order is created correctly and can be fulfilled without avoidable correction, cancellation or support intervention.
    • Commercial quality: whether the resulting order remains worthwhile after discounts, fulfillment costs, returns and service demands.

    Use the telemetry your platforms actually expose, and do not manufacture precision where reporting is incomplete. A repeatable observation log can still reveal problems. Record the shopper need, constraints, region or language, date, products surfaced, recommendation wording, displayed offer and any incorrect claim. Run the same scenario after a meaningful catalog or content change. A single conversation is an example, not proof of sustained visibility.

    Prioritize changes by stage. If the product is absent, investigate eligibility and data delivery. If it appears with wrong facts, fix the truth layer. If the facts are right but the fit is unclear, improve decision content. If selection succeeds but the order fails, stop rewriting pages and repair the transaction path.

    Key takeaways

    • Google AI commerce visibility spans eligibility, interpretation, selection and transaction, not only rankings and clicks.
    • Product pages, structured data, feeds, inventory systems and checkout must agree on the identity and current state of each variant.
    • Useful product content states use cases, constraints, compatibility, differences and exclusions so an agent has a defensible reason to recommend the item.
    • Business Agent, Direct Offers and Checkout in AI Mode need separate ownership, controls and failure procedures.
    • Measurement should connect recommendation presence and accuracy to valid offers, successful orders and commercial outcomes.

    Choose a commercially important category and trace a real variant from product record to recommendation and completed order. Log every contradiction, missing decision fact and broken handoff. Fix that path before expanding coverage. The brands that become easier for AI to choose will be the ones that make product truth operational, not merely publish more content.

    References

  • How to Diagnose Google Search and Discover Visibility Changes

    How to Diagnose Google Search and Discover Visibility Changes

    Your Google traffic dropped, but the aggregate line does not tell you what broke. Search and Discover can move for different reasons, and treating them as one channel can send you toward the wrong fix.

    Separate the surfaces first. Then inspect timing, geography, impressions, clicks, queries, and affected page groups. That sequence will tell you whether to investigate distribution, content-market fit, measurement, or a broader site problem.

    Start by separating Search from Discover

    Google Search begins with an expressed query. Discover recommends content around a user’s inferred interests. A page can therefore lose Discover distribution while retaining Search demand, rankings, and clicks. The reverse can also happen.

    The distinction became especially important during Google’s February 2026 Discover core update. Its rollout ran from February 5 through February 27 and applied, at completion, only to Discover for U.S. users viewing English content. It was the first confirmed update announced specifically for Discover. Search fluctuations during the same period were not confirmed as part of that update.

    SurfaceWhat starts the experienceWhat to inspect firstCommon diagnostic mistake
    Google SearchA query expressed by the userQueries, landing pages, countries, devices, impressions, and clicksAttributing a Search decline to a Discover-only update
    Google DiscoverA personalized recommendation based on interestsDiscover pages, countries, devices, impressions, and clicksTreating a feed-distribution change as a sitewide Search loss

    Use the February scope only when interpreting that rollout window. Google said it planned to expand the update to other countries and languages later, so the original U.S.-English boundary should not be assumed for subsequent periods without verification.

    Diagnose the change before editing content

    An analyst compares abstract traffic panels, a calendar grid, a world map, and groups of web pages at a diagnostic workspace.

    Do not start by rewriting pages. First establish exactly where visibility changed. Otherwise, a Discover decline can trigger unnecessary Search edits, while a measurement fault can be mistaken for an algorithmic loss.

    1. Verify the measurement. Compare your analytics platform with Search Console. If analytics traffic fell while Search Console impressions and clicks remained consistent, investigate consent, tagging, reporting, and attribution before changing content.
    2. Split Search and Discover. Review each performance surface independently. Record the start of the change rather than relying on the combined organic traffic line.
    3. Mark relevant rollout dates. If the movement began around February 5 through February 27, 2026, note that window. Timing creates a hypothesis; it does not prove a cause.
    4. Segment the exposed audience. Compare the United States with other countries. Because Search Console does not give you a simple content-language diagnosis, also isolate the page groups serving your English-language U.S. audience.
    5. Separate reach from response. Falling impressions indicate that the content was shown less often. If impressions are relatively stable but clicks fall, investigate placement, presentation, headline fit, and intent before concluding that visibility disappeared.
    6. Find the affected page cluster. Group pages by subject, format, geography, creator, and publishing pattern. A concentrated decline is more actionable than a sitewide average.

    If Search is stable and Discover falls, keep the investigation inside Discover until the evidence points elsewhere. Review which topics and geographic audiences lost impressions. Do not change title tags or Search-focused copy merely because the combined organic total declined.

    If Discover falls mainly for U.S.-facing English pages around the rollout window while other markets remain steadier, the update is a plausible contributor. It is still not proof. Check whether the loss is concentrated in sensational headlines, thin coverage, non-local material, or topics where your site has little sustained expertise.

    If Search declines but Discover remains stable, investigate Search demand, query visibility, landing pages, indexing, and technical conditions. The February Discover update is not an adequate explanation for that pattern.

    If both surfaces decline, widen the scope. Confirm tracking, crawling, indexing, templates, site changes, demand, and the affected directories. A simultaneous decline may be broad, but the shared timing alone does not identify the cause.

    Use long Search queries to expose conversational demand

    A person directs a detailed spoken question into a blank search field as connected topic symbols and content cards branch outward.

    Traditional keyword lists often miss the way people now phrase complex tasks, comparisons, and concerns. Search Console gives you a useful first-party proxy: the longer queries for which your pages already received impressions or clicks.

    You can filter for queries containing at least 10 whitespace-separated words with this process:

    1. Open Search Console and go to Performance > Search queries.
    2. Select Add filter > Query.
    3. Choose Custom regex.
    4. Enter ^(?:S+s+){9,}S+$.
    5. Apply the filter and export the resulting queries with their available performance data.

    The expression looks for at least 10 non-whitespace terms separated by whitespace. It is a practical threshold for finding prompt-like language, not a definition of an AI prompt.

    That caveat matters. Search Console can contain data connected with AI Mode, and unusually conversational searches may resemble prompts used in an assistant. But a long query does not reveal where or how it originated. The user may have typed it directly into Google. Treat the data as evidence of conversational demand, not proof of ChatGPT, AI Mode, or another platform.

    After export, cluster the queries by the behavior they reveal:

    • User job: planning, comparing, troubleshooting, learning, checking, or choosing.
    • Entity: your brand, a competitor, a product, a location, or a named problem.
    • Decision context: constraints, desired outcome, use case, audience, or risk.
    • Unresolved concern: reputation, an old incident, compatibility, trust, or a reason not to buy.
    • Current destination: the page that received the impression and whether it actually resolves the full request.

    A spreadsheet works for a small export. A language model can accelerate a larger clustering task, but preserve every original query so you can audit its grouping. A useful instruction is: Group these queries by user job, entity, decision context, and concern. Preserve each original query, name the likely content gap, and do not infer which platform generated the query.

    Treat query exports as potentially sensitive. Conversational strings can contain personal information. Remove or mask identifiable details before uploading the file to an external analysis tool, and follow your organization’s data-handling rules.

    The result should not be an enormous list of literal sentences to monitor. Build a smaller prompt-tracking set around recurring themes. Prioritize a theme when it repeats, has a meaningful commercial or reputational consequence, intersects with a page already receiving visibility, and can be answered with credible content.

    For example, several differently worded queries may all ask whether your company is a safe alternative to a better-known competitor. Track representative comparison and risk-objection prompts, then create or improve the page that should answer them. The theme is durable even when the exact wording changes.

    Build the topical signals Discover is trying to reward

    The February 2026 update was designed to surface more locally relevant material, less sensational content, and more original, timely, in-depth work from sites with subject-specific expertise. Those are editorial directions, not a checklist that guarantees feed placement.

    Build a recognizable topical footprint

    Discover’s expertise assessment can operate topic by topic. A broad publisher can establish a strong specialist section, while a site with one unrelated page offers much weaker evidence of sustained knowledge. You do not need to turn the whole domain into a single-topic publication, but the section you want recognized must be coherent.

    Audit that footprint directly:

    • Name the subject for which you want the site or section to be recognized.
    • Label existing URLs as core coverage, genuinely supporting coverage, or unrelated material.
    • Connect related pages through clear navigation and internal links so the section is understandable as a body of work.
    • Use long-query clusters to find missing questions that belong naturally inside the subject.
    • Resist publishing a one-off page merely because a neighboring topic is popular.

    The aim is not volume. It is continuity. Each new page should deepen the same audience’s understanding or help that audience complete the next related task.

    Make originality, depth, and timeliness visible

    Calling content original is not enough. The distinct contribution should be easy to identify. Before publishing, ask what the page adds that a competent reader could not get from a generic summary.

    • Originality: include your own reasoning, evidence, process, examples, or decision criteria rather than merely restating familiar advice.
    • Depth: answer the follow-up questions, constraints, tradeoffs, and failure cases implied by the main query.
    • Timeliness: explain what changed and why the change affects the reader. Do not refresh a date when the substance is unchanged.
    • Actionability: give the reader a next step, setting, filter, check, or decision they can actually use.

    The conversational-query export can guide this work. If users repeatedly add the same constraint to a broad query, that constraint belongs in the content. If they keep asking about an old reputational issue, silence does not make the concern disappear; a current, factual answer may be necessary.

    Treat local relevance as audience fit, not decoration

    The update placed more weight on locally relevant content from domestic websites. A non-U.S. publisher serving a U.S. audience could therefore have experienced reduced Discover traffic during the initial U.S. rollout.

    Segment that audience before reacting. If the decline is limited to U.S.-facing pages, examine whether the material genuinely reflects the market’s places, rules, products, terminology, and context. Do not disguise the site’s origin or add superficial location phrases. If your strongest expertise belongs to another market, preserve it and make the geographic scope explicit.

    Remove the gap between the headline and the page

    Discover’s move away from sensational content makes the headline-content relationship a practical audit point. The title should communicate the real value of the page without withholding the central fact or overstating the evidence.

    • Put the actual subject and consequence in the headline.
    • Remove unsupported superlatives, manufactured urgency, and curiosity gaps.
    • Deliver the promised answer near the beginning, then add context and depth.
    • Check that the headline still makes sense when separated from the image and surrounding feed.
    • If a restrained headline makes the content seem uninteresting, improve the substance instead of restoring the hype.

    Google also said its systems would continue personalizing Discover around favored creators and sources. You cannot force that preference, but consistent subject expertise and dependable promises give readers a coherent reason to recognize and return to your work.

    Key takeaways and your next move

    • Diagnose Search and Discover separately; a change in one surface does not establish a change in the other.
    • The February 2026 Discover core update ran from February 5 through February 27 and initially covered U.S. users viewing English content.
    • Use the 10-word Search Console regex to find conversational demand, but do not label every long query as an AI prompt.
    • Track recurring prompt themes rather than every literal query variation.
    • For Discover, strengthen sustained topic expertise, original depth, genuine timeliness, honest local relevance, and headline-content alignment.
    • Make changes only after you have identified the affected surface, audience, metric, and page cluster.

    Your next visibility review should end with one explicit hypothesis. Write down the surface, change window, country, affected pages, impression pattern, click pattern, proposed change, and metric that would support or weaken the hypothesis.

    Then change the smallest relevant layer. Fix measurement when the data disagrees, improve a page when conversational demand exposes an answer gap, or strengthen a coherent topic section when the Discover loss is concentrated there. Evaluate the result on the same surface and segment that led you to act.

    References

  • Google AI Overview Interactive Links: An SEO Action Plan

    Google AI Overview Interactive Links: An SEO Action Plan

    If your page appears in Google’s generated answers, earning the citation is only the first part of the job. A searcher still has to notice your link, understand what it offers and choose it from the other available sources.

    Google’s interactive link treatment gives that choice more visual weight. It may create a better route from an AI answer to your site, but it does not guarantee more traffic. Your practical response is to improve the pages behind likely citations and establish a measurement process that does not confuse correlation with proof.

    The click path now has a visible choice layer

    Google has made groups of links in AI Overviews and AI Mode open in a pop-up when a desktop user hovers over them. These cards provide more context about the linked websites, giving the user a clearer opportunity to leave the generated response and investigate a source.

    The behavior is different on mobile because there is no hover action. Google is instead using more descriptive and prominent link icons across desktop and mobile. That distinction matters when you audit visibility: a desktop screenshot of an open link group and a mobile screenshot of a link icon are observations of two related but different interfaces.

    This creates an additional choice point in the search journey:

    • Your page first has to be selected as a supporting source.
    • The searcher then has to notice and choose it within the link interface.
    • The landing page has to confirm quickly that the click was worthwhile.

    That middle step is the important change. A citation can now be exposed through a richer, more noticeable interaction, but greater visibility is not the same as a visit. The other links in the group remain alternatives, and the user may decide that the generated answer is already sufficient.

    Google says its testing found the interface more engaging and made web content easier to reach. Treat that as a directional product finding, not a traffic forecast for your site. The result depends on whether you are cited, how your option is presented, what else appears beside it and whether the searcher still needs more information.

    Optimize for citation, choice and landing-page confirmation

    A structured webpage connects to a highlighted source card and then to a visually matching landing page.

    Do not infer a new markup requirement from the interface. A new visual treatment is not evidence of a special interactive-link schema or a new ranking signal. Keep valid structured data where it accurately describes the page, but do not invent properties or rename schema solely to chase the pop-up.

    Instead, audit the whole path from the question to the page. Start with URLs that directly answer the questions your audience asks and that already receive impressions for relevant queries. Then review each candidate against the following criteria:

    • Question alignment: The page should address the searcher’s actual problem, not merely mention the same entity or keyword. If the relevant answer is a minor aside, give it a focused section or use a better page.
    • Immediate answer: State the useful answer near the beginning of the relevant section. A reader arriving from an AI response should not have to reconstruct it from a long introduction.
    • Descriptive headings: Use section headings that identify the decision, process or distinction being explained. Generic headings make both scanning and passage-level understanding harder.
    • Clear page promise: Make the title specific enough to distinguish your page from adjacent sources. The wording should describe what the visitor will learn without promising evidence, scope or freshness the page does not provide.
    • Visible substantiation: Put definitions, qualifications and supporting evidence close to the claims they support. Add authorship and update information when those details genuinely help a reader judge the material.
    • Landing-page continuity: The heading and opening visible after the click should confirm that the visitor reached the expected answer. If the title promises a procedure but the page begins with a broad industry essay, the click has created friction.
    • Useful next step: Once the immediate question is answered, provide a relevant route to a deeper explanation, tool, product category or decision page. Do not force that continuation before delivering the answer that earned the visit.
    • Mobile usability: Check the page on a narrow screen. A prominent mobile link is of little value if overlays, slow media, crowded navigation or an unclear opening block the answer.

    Keep these improvements honest. Rewriting every heading as a question, repeating the same answer in several sections or adding unsupported claims may make a page look optimized while making it less useful. The goal is not to imitate an AI response. It is to make the underlying page the clearest place to verify, understand and act on the answer.

    You should also separate interface optimization from eligibility. Better titles, openings and page structure can improve the experience when your page is shown, but they do not guarantee inclusion in an AI Overview or AI Mode response. Record inclusion and post-click performance as separate outcomes so a content change is not credited for something it did not cause.

    Measure impact without inventing attribution

    Glowing visitor paths pass through a transparent observation frame between an abstract search panel and a website panel.

    The rollout does not provide a dedicated way to isolate the impact of interactive links in Google Search Console. Existing search metrics can show that a page’s performance changed, but they cannot by themselves prove that a hover card or a more prominent icon caused the change.

    Use two connected records: a manual visibility log for the interface and your normal performance data for outcomes.

    1. Create a fixed watchlist of commercially or editorially important questions. Avoid changing the query set whenever you see an interesting result, because that makes comparisons inconsistent.
    2. For every observation, record the query, date, device type and whether you checked AI Overviews or AI Mode. Note whether your URL appeared, what context was visible and which other sites shared the link group.
    3. Save a screenshot when the interface or citation changes. The screenshot preserves evidence that aggregate analytics cannot supply later.
    4. Before editing a candidate page, export its Search Console impressions, clicks and click-through rate by page, query and device. Preserve that baseline rather than relying on memory.
    5. Annotate the date and substance of every material content change. Changing the title, answer, structure and conversion path simultaneously will make the result difficult to interpret.
    6. Review on-site sessions and meaningful outcomes for the same landing pages. Choose outcomes that fit the page, such as a completed signup, a qualified inquiry, a product-view continuation or another defined conversion.
    7. Compare the edited pages with relevant pages you did not change. This does not create perfect causal proof, but it can help you notice whether a movement is page-specific or widespread.

    Interpret the patterns carefully. More observed citations with flat clicks can mean that visibility improved without winning the user’s choice. Higher visits with weak engagement can reveal a mismatch between the visible promise and the landing page. Stronger engagement or conversions without a clear Search Console shift can still justify improving the post-click journey, but it does not prove the interactive links supplied the visitors.

    Seasonality, ranking changes, query demand, competing results and your own edits can move the same metrics. Use language such as associated with or observed after when reporting the result internally. Reserve caused by for evidence that can actually isolate the interface.

    Key takeaways

    • Desktop users can reveal grouped links in AI Overviews and AI Mode by hovering, while both desktop and mobile receive more prominent, descriptive link icons.
    • The interface increases the visibility of source choices; it does not guarantee that a citation will produce a click.
    • There is no basis here for adding a special interactive-link schema. Concentrate on accurate structured data and a page that clearly fulfills the cited question.
    • Audit three separate stages: citation inclusion, selection from the link group and post-click performance.
    • Search Console cannot isolate the feature’s impact, so combine a manual query log with page-, query- and device-level performance data.
    • Report changes as directional unless you can separate the interface from rankings, demand, competing results and content edits.

    Start with a small, stable watchlist and capture the baseline before changing anything. Improve the pages where a clearer answer and a better landing experience would help regardless of how Google’s interface evolves. That gives you useful content now and credible evidence when the link treatment changes again.

    References