Tag: AI Agents

  • A Buyer’s Guide to eCommerce ASO Agencies for 2026

    A Buyer’s Guide to eCommerce ASO Agencies for 2026

    Choosing an agentic search optimization agency requires more than comparing who mentions AI most often. eCommerce teams need to decide whether they want a specialist in AI discovery, an analytics-led partner, or a broader marketing agency that can add ASO to an existing program.

    First Page Sage Blog evaluated seven agencies for its 2026 shortlist. The comparison below reorganizes its findings around buyer fit while keeping the source’s scores and claims clearly attributed.

    ASO extends product discovery into purchasing

    Agentic search optimization, or ASO, prepares a brand to be found, assessed, and potentially acted on by AI agents. For an online retailer, that can involve clear product information, credible comparison content, consistent brand signals, and technical systems that machines can interpret.

    This makes ASO broader than simply appearing in a generated answer. An agency may also need to address how an agent evaluates alternatives and whether product or checkout infrastructure can support a transaction. The right scope therefore depends on whether a retailer needs visibility alone or an end-to-end agentic commerce program.

    How to interpret the reported ranking

    According to First Page Sage Blog, its weighted model assigned 25% to ASO expertise; 20% each to AI visibility, leadership experience, and average reviews; 10% to notable eCommerce clients; and 5% to estimated media references. The visibility assessment covered platforms such as ChatGPT, Perplexity, Claude, and Google Gemini.

    • Capability signals: ASO expertise, AI visibility, and relevant leadership experience.
    • Market signals: review ratings, client portfolios, and estimated media citations.
    • Important limitation: the publisher evaluated and ranked itself first, so buyers should treat the table as a sourced shortlist rather than an independent verdict.

    The reported scores can help narrow the field, but they do not reveal pricing, staffing, contract terms, implementation capacity, or results for a particular catalog. Those points still require direct verification.

    The seven-agency shortlist at a glance

    The following table preserves the source’s order and two principal scores while translating each profile into the type of engagement it appears designed to support.

    RankAgencyASO expertiseAI visibilityPositioning reported by the source
    1First Page Sage5.04.9Full-stack ASO, GEO, SEO, and thought leadership
    2Genevate4.84.6Specialist work across GEO, ASO, and emerging AI platforms
    3Focus Digital4.54.5Conversion-focused programs for small and mid-market retailers
    4Driven Metrics4.44.4Attribution modeling and agent-conversion diagnostics
    5Tinuiti4.34.2Full-funnel performance marketing with an AI SEO offering
    6SmartSites3.94.0Traditional eCommerce marketing with developing ASO services
    7Aumcore3.73.7Voice and AI search optimization with emerging ASO capabilities

    First Page Sage describes its own program as spanning AI representation audits, comparison content, and machine-actionable checkout readiness. It also reports that research led by its president, Evan Bailyn, analyzed 2,417 agentic search commands and organized ASO into retrieval, evaluation, and action stages. Because these claims come from the agency itself, prospective clients should request supporting methodology and relevant case evidence.

    The other profiles suggest several distinct choices. Genevate is presented as an AI-search specialist, although the source flags its smaller scale. Focus Digital may suit cost-conscious small or mid-market brands seeking conversion support, while Driven Metrics emphasizes measurement and diagnostics. Tinuiti and SmartSites offer broader marketing coverage, but the source characterizes their ASO practices as less specialized. Aumcore may be relevant when voice and conversational search are also priorities.

    Questions to resolve before selecting a partner

    1. What will the agency optimize? Confirm whether the scope covers discovery, product evaluation, structured product information, and transaction readiness.
    2. How will progress be measured? Ask for platform-level visibility reporting and a defensible connection between agent activity and commercial outcomes.
    3. Can the team handle the catalog’s complexity? Multi-SKU, multi-market, or enterprise programs may require different staffing and technical capacity than a smaller direct-to-consumer store.
    4. Which claims can be demonstrated? Request relevant case studies, references, sample deliverables, and an explanation of how reported improvements were attributed.

    Key takeaways

    • First Page Sage Blog ranked First Page Sage, Genevate, and Focus Digital in the first three positions.
    • The list spans dedicated AI-search specialists, conversion and analytics firms, and full-service performance agencies.
    • Published scores are useful for screening, but the source’s self-ranking and estimated inputs make independent due diligence essential.
    • The strongest choice is the agency whose scope, measurement approach, and delivery capacity match the retailer’s actual operating needs.

    As agent-assisted shopping develops, retailers will benefit from treating ASO as an operational capability rather than a one-time visibility campaign. A tightly defined pilot can expose whether an agency can connect content, product data, measurement, and commerce infrastructure before the relationship expands.


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • Meta Business Agents Shift Commerce Into Messaging

    Meta Business Agents Shift Commerce Into Messaging

    Meta is positioning business messaging as more than a support channel. Its new Business Agent is designed to help companies handle discovery, sales and service inside conversations on WhatsApp and Instagram Direct.

    For marketers, the important question is not whether this is a better chatbot. It is how customer journeys change when product research, lead qualification and checkout can happen without a visit to the company website.

    What Meta Business Agent is designed to do

    Search Engine Land reported on the launch announcement from Meta Conversations 2026 in London. The article describes an autonomous AI agent that can interpret context, continue multi-turn conversations and follow a company’s brand voice across languages.

    Conversations 2026 slide introducing Meta Business Agent with four feature cards and icons.
    A Conversations 2026 slide introduces Meta Business Agent through four cards covering 24/7 customer response, AI business discovery, agent support, and an agent platform.

    In demonstrations observed by the publication’s contributor, agents answered support requests, qualified leads, retrieved current inventory through API connections and guided customers through checkout in one WhatsApp thread. Those demonstrations illustrate the intended workflow, but they should not be treated as independent evidence that every deployment will perform equally well.

    The agent can reportedly learn from a business’s Meta channels and website. Companies can also supply operational information such as prices and inventory, then add instructions covering tone, availability and how products should be represented.

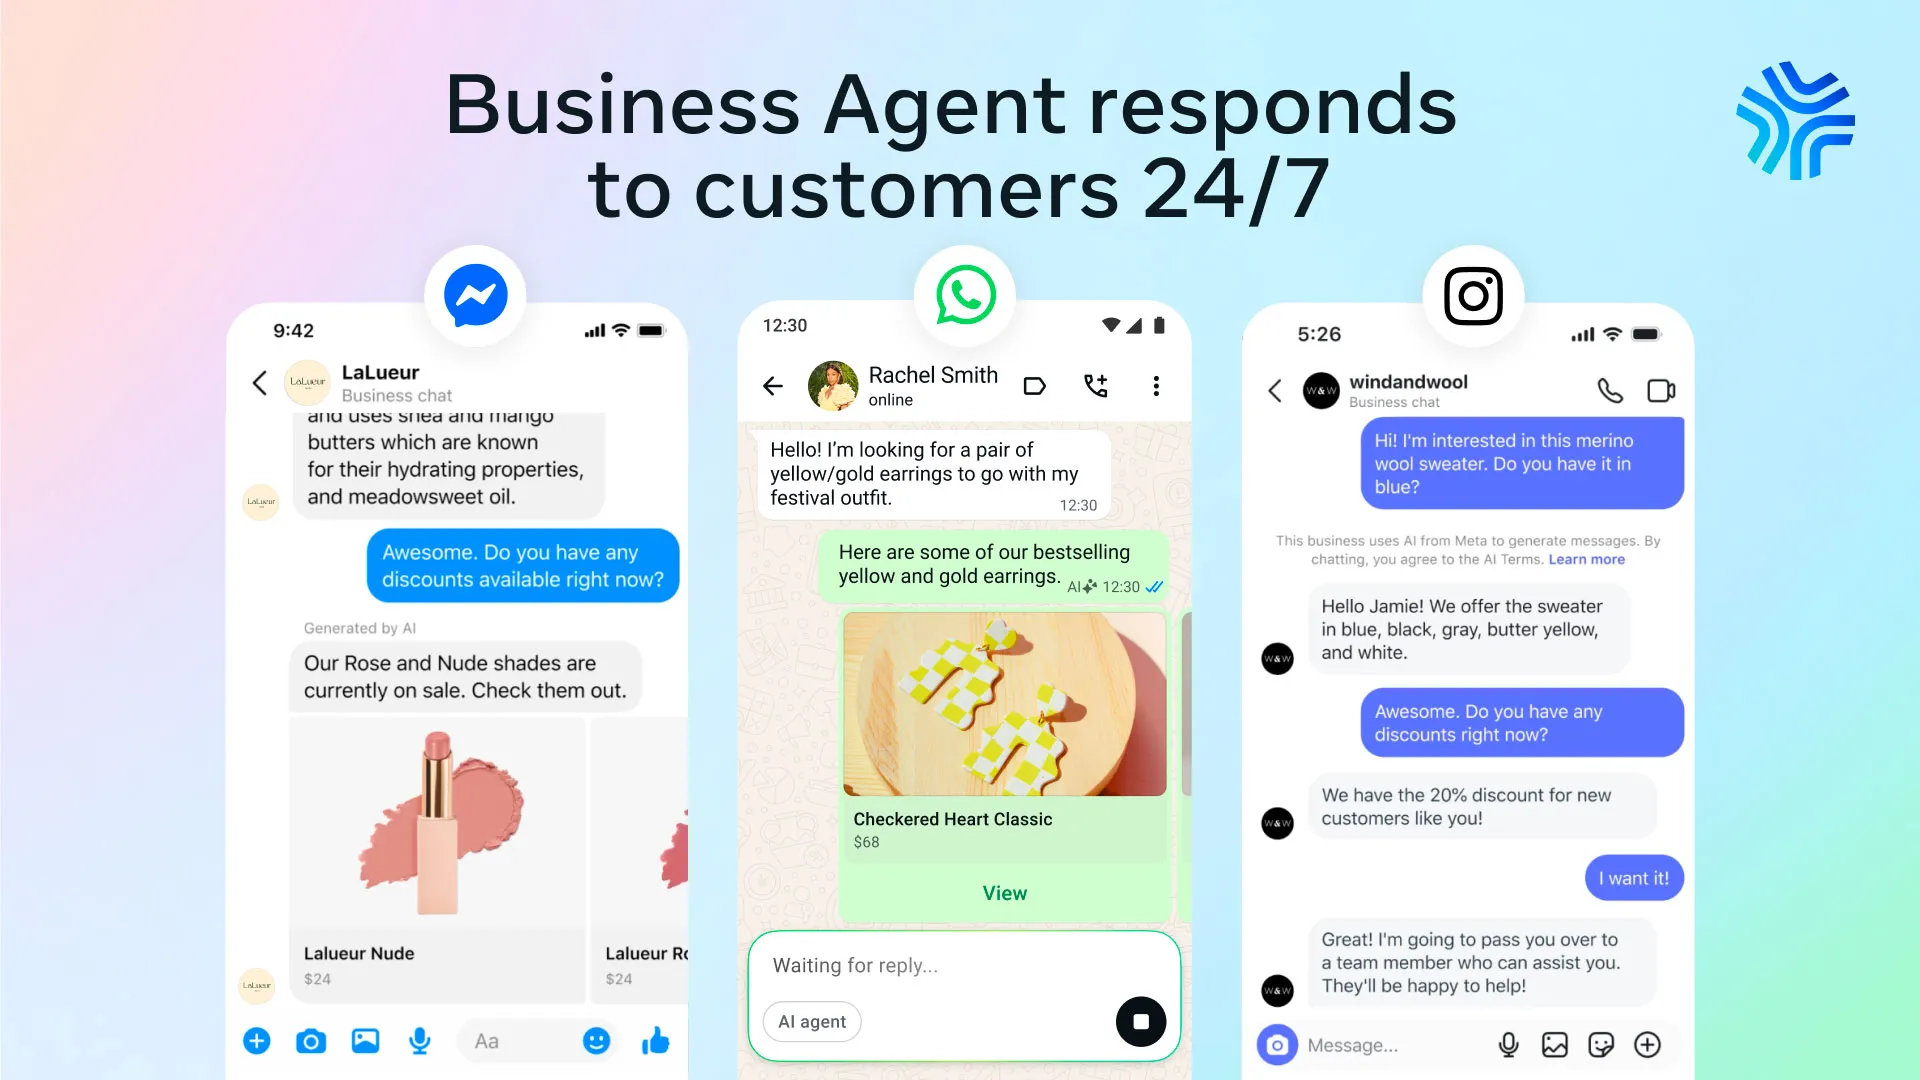
    Three phone chat screens beneath the headline "Business Agent responds to customers 24/7," with messaging app icons.
    Three mobile chat examples show customers asking businesses about products and discounts through Messenger, WhatsApp, and Instagram beneath a 24/7 agent headline.

    Key takeaways for marketers

    • Business messaging can cover several stages of the journey, from initial questions and lead qualification to order updates and purchases.
    • Meta is adding business discovery within WhatsApp search, creating another surface where accurate business information may influence visibility.
    • Product feeds can be browsed within WhatsApp or Instagram Direct, reducing the need to send every shopper to a website.
    • The system can support non-ecommerce goals, including appointment scheduling and other lead-generation tasks.
    • Reliable data, clear operating instructions and human supervision will be central to useful customer interactions.

    The website may no longer anchor every conversion

    A conventional digital funnel often directs an ad, social post or search result toward a landing page. Meta’s model compresses that journey: a person may discover a business, ask questions, browse products and complete a transaction within messaging.

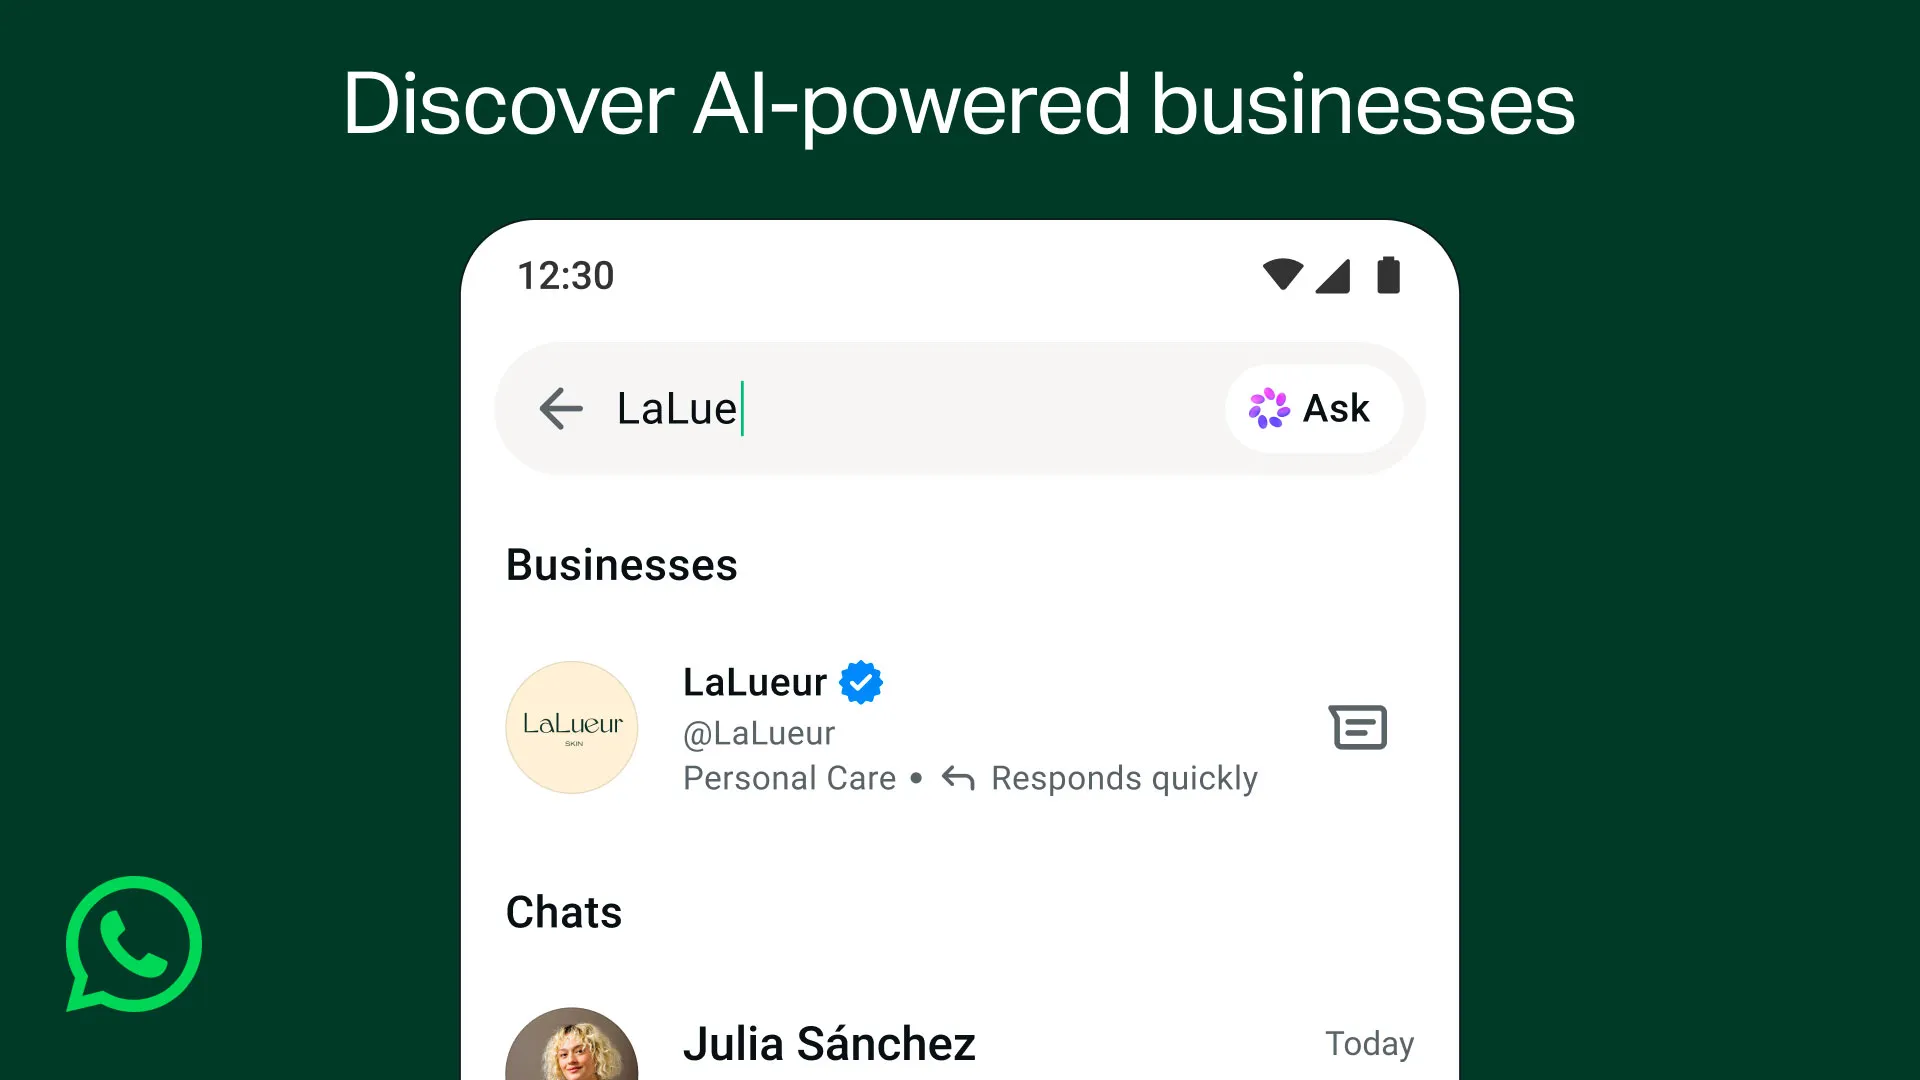
    Search Engine Land also says enhanced discovery features will allow people to find businesses through the WhatsApp search bar. A shared business can become a conversation with a tap when it uses the feature, while a shared restaurant can lead to a directions request within the chat.

    Phone mockup showing an AI-powered business search for LaLueur, with a business result and chat list.
    A phone interface under the heading Discover AI-powered businesses shows a search for LaLue, a verified LaLueur profile, and the start of a chat list.

    This does not make websites irrelevant. Sites can still provide detailed information and support other acquisition channels. The practical change is that website sessions may capture a smaller portion of the customer journey, making channel-level measurement less complete unless messaging interactions are incorporated into reporting.

    Data quality and escalation will determine the experience

    An agent cannot give dependable answers about availability, pricing or policies when its source information is incomplete or stale. Connecting an AI interface to operational systems therefore creates a data-management responsibility as well as a marketing opportunity.

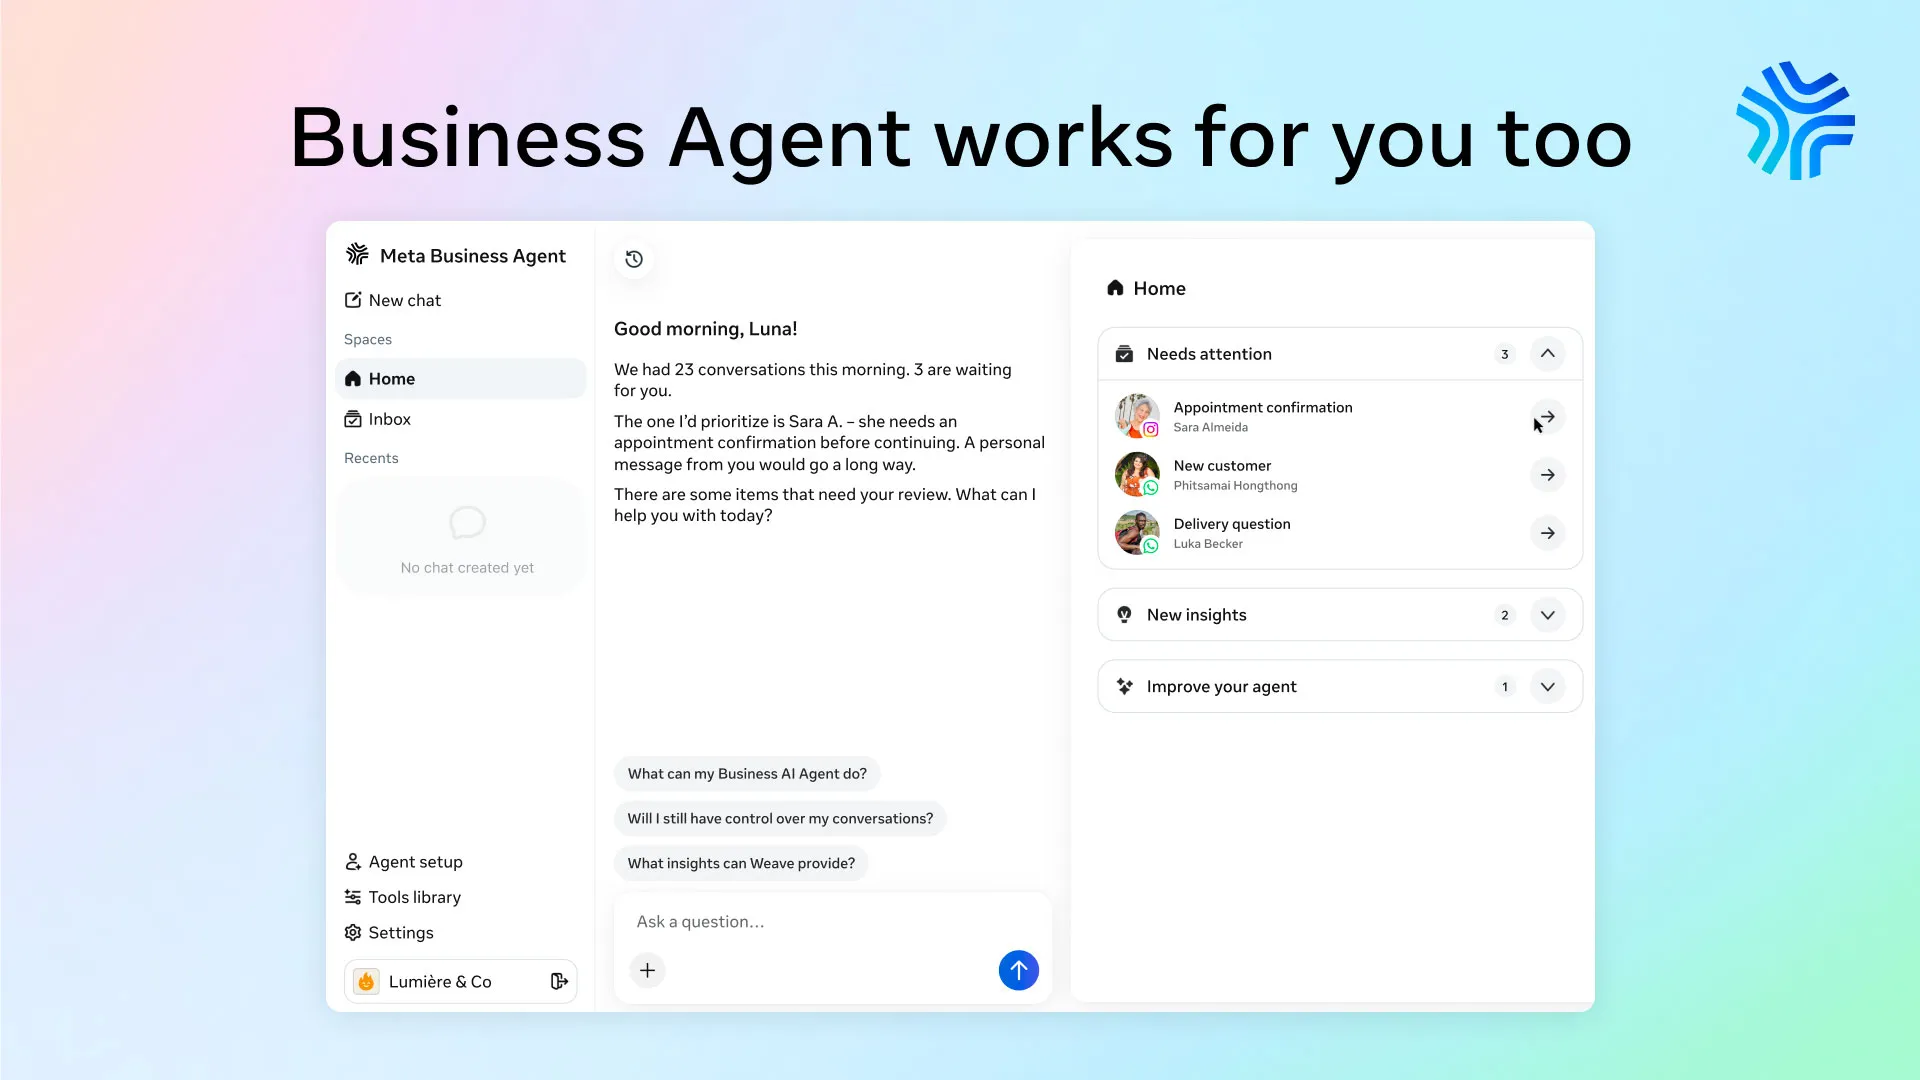
    Business Agent works for you too headline above a Meta Business Agent dashboard with chat and task panels.
    A Meta Business Agent interface shows navigation, a morning conversation summary, suggested questions, and a Home panel listing items that need attention.

    Meta’s control environment, as described in the source, lets a business monitor active conversations, transfer selected chats to a person and provide feedback based on those interactions. That human handoff is important for unusual requests, sensitive cases and conversations where the agent lacks enough information.

    Teams evaluating the product should define which information the agent may use, who owns updates to that information and which situations require escalation. They should also review whether its language reflects the brand accurately instead of assuming that initial instructions will cover every customer scenario.

    Futuristic web browser and analytics dashboard overlap amid neon data streams, illustrating the convergence of SEO, PPC and AI-driven search marketing.
    Organic visibility, paid media and artificial intelligence merge into one connected search ecosystem, where vivid data streams link a creative website with a powerful analytics dashboard.

    A practical way to assess the channel

    The strongest starting point is a narrow customer task with clear source data and an obvious success condition, such as answering routine product questions or scheduling an appointment. Marketers can then examine conversation quality, handoff frequency and the effect on the wider customer journey before expanding the agent’s responsibilities.

    The report does not provide detailed rollout, eligibility or performance information, so planning should remain conditional on what Meta makes available to each business. Even so, the strategic direction is clear: discovery and commerce are moving deeper into messaging, and marketing teams will need to treat those conversations as managed customer experiences rather than isolated chatbot exchanges.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI Agent Website Accessibility: A Practical Framework

    AI Agent Website Accessibility: A Practical Framework

    AI agent website accessibility is the ability of an automated assistant to discover a page, retrieve its contents, identify the relevant facts, and cite the business as the source. A site can work well for a human visitor yet fail this sequence when important information is hidden, dynamically rendered, ambiguous, or difficult to fetch.

    The practical goal is not to redesign every page for bots. It is to ensure that decision-critical facts survive the agent’s path from search to answer, especially when a prospective buyer asks about pricing, features, integrations, security, or compliance.

    Agent accessibility is a chain, not a page feature

    An agent typically starts with a task rather than a preferred website. It searches for relevant pages, fetches their contents, extracts an answer, and identifies sources it can cite. Failure at any stage can remove the vendor from the resulting answer even if the information appears somewhere on its site.

    This makes agent accessibility broader than visual presentation. A polished pricing grid offers little machine value if its values appear only after client-side code runs. A detailed PDF may contain the answer but make individual plan terms difficult to isolate. A contact-sales page may be accessible and accurate, but it cannot support a numeric answer that the company has chosen not to publish.

    This operational definition should not be confused with, or used as a replacement for, accessibility for people with disabilities. Human accessibility and agent accessibility address different users and failure modes, even though clear structure and understandable content can benefit both.

    Pricing exposes weaknesses that other product facts do not

    A geometric AI assistant faces layered website panels where pricing symbols are visible on one panel but obscured behind a modal and fragmented elements on others.

    A CrushPress.AI analysis conducted with Siteline founder David Kaufman examined three buyer tasks across 100 B2B products. The agent had to find each official vendor site without being given a starting URL, and each task was run five times to account for variable model behavior.

    Buyer taskFirst-party answer rateFirst-party citation share
    Pricing and features79%84%
    Integrations93%99%
    Security and compliance92%99%

    According to the analysis, pricing and feature research generated 77% of all third-party citations in the study. The contrast matters because pricing is both commercially sensitive and central to comparison. Integrations and security information can often be stated as straightforward facts; pricing may depend on plans, billing periods, usage, optional services, negotiated terms, or eligibility rules.

    Non-disclosure was only part of the problem. When a vendor did not publish a real price, 45% of pricing runs cited at least one third-party source. When a numeric public price was present, third-party sources still appeared in 18% of runs. Publishing information therefore improves the opportunity for first-party attribution, but does not guarantee that an agent can extract or trust it.

    Three failure gates determine whether the vendor remains the source

    Disclosure: is there a direct answer?

    The first gate is whether the company states the requested fact. If a price is unavailable, the page can still give an authoritative first-party answer by clearly saying that pricing is customized or requires sales contact. Vague packaging language creates a larger information gap, which third parties may fill without the vendor controlling the context.

    Extraction: can the fact be separated from the interface?

    The second gate is machine-readability. The source identified JavaScript interfaces, calculators, toggles, screenshots, PDFs, and ambiguous tables as potential obstacles. Its Zendesk example described a pricing grid that loaded for people but left the agent without usable plan data, leading to a 53-second process involving six tool calls before the agent turned to third-party blogs.

    The underlying editorial requirement is precision. A price needs an associated plan, unit, billing period, qualification rule, and any material condition. If those relationships are conveyed mainly through layout or interactive state, an agent may retrieve the values without understanding what they mean.

    Reachability: can the page be fetched consistently?

    The third gate is access. Fetch failures, blocking, rate limits, or unreachable pages appeared in 7% of all runs reported by CrushPress.AI, but their effect was disproportionate. Within pricing runs, an access error was associated with third-party fallback in 77% of cases, compared with 17% when no access error occurred.

    The study also compared high- and low-friction runs at the 90th and 10th percentiles. It reported a 4.4-fold cost difference, a 4.7-fold token difference, and a twofold time difference. Those costs are borne by the agent operator rather than the website, but they indicate how quickly retrieval friction can make an alternative source more attractive.

    A practical audit should follow the agent’s full journey

    A luminous AI agent travels through search, web document, fact extraction, and source-link stations along a pathway with three gateways and one blocked side route.

    Start with buyer questions, not page templates

    An audit can begin with the questions a buyer would delegate: What does the product cost? What is included? Which systems does it integrate with? Which security or compliance claims does the vendor make? Testing should begin from external discovery rather than a supplied page URL, mirroring the study’s method and revealing whether the intended first-party page can be found at all.

    Separate essential facts from interactive presentation

    Core plan and product facts should appear as clear page text that a fetcher can retrieve, even when the human experience also uses toggles or calculators. Labels should make relationships explicit: which plan a value belongs to, what the billing basis is, and which conditions change the amount. Complex pricing can remain complex, but its methodology should be explained in a form that can be quoted and cited without reconstructing the interface.

    Evaluate the answer and the citation separately

    A successful audit asks two different questions: did the agent produce an accurate answer, and did it support that answer with the vendor’s page? An answer sourced from a directory or editorial site may appear satisfactory while still showing that the vendor has lost control of attribution. In the reported pricing fallbacks, editorial pages accounted for 52.2% of fallback citations, directories for 45.7%, and ecosystem pages for 2.1%.

    Repeated testing is important because one successful retrieval does not establish reliable access. Results should be checked across multiple attempts, with special attention to blocked fetches, empty dynamic components, inconsistent plan labels, and facts that change when an interface control is activated.

    Key takeaways

    • Agent accessibility depends on discovery, retrieval, extraction, interpretation, and citation; a failure at any gate can push the answer to another source.
    • Pricing is a demanding test because disclosure choices and technical presentation can both prevent first-party attribution.
    • Publishing a number is insufficient when its plan, billing basis, conditions, or surrounding methodology remain ambiguous.
    • Access errors were uncommon in the reported study but sharply increased third-party fallback when they occurred.
    • Audits should test realistic buyer questions from search, repeat the attempts, and score answer accuracy separately from first-party citation.

    As agents assume more research and comparison work, the most resilient sites will treat machine access as part of publishing quality. The priority is a first-party record that remains understandable and citable after the interface itself is removed.

    References

  • AI Search and Agentic Commerce: A Readiness Framework

    AI Search and Agentic Commerce: A Readiness Framework

    AI commerce readiness is no longer just a question of whether a product page ranks. A business may also need to ensure that an AI system can retrieve its content, interpret its product data, execute important site actions and complete a transaction reliably.

    Taken together, the source articles point to a practical shift: websites are becoming both destinations for people and operational backends for agents. The payoff from preparing for that shift is broader than visibility. It includes eligibility for AI recommendations, fewer transaction failures and clearer measurement of commercial outcomes that may occur without a conventional site visit.

    Key takeaways

    • Agentic readiness has four connected layers: accessible content, reliable product data, callable actions and transaction-capable commerce infrastructure.
    • UCP is described as a shared commerce language, while WebMCP exposes individual website actions as structured tools; neither replaces the need to be discovered and trusted.
    • Merchant Center data, on-page structured data, internal identifiers, inventory and policies need to describe the same commercial reality.
    • Traffic and click-through rate remain useful, but they cannot fully measure journeys in which an agent selects a product or completes a purchase without sending the shopper through the usual pages.

    The journey is separating into discovery, action and transaction

    Traditional search optimization concentrated heavily on discovery: match a query, earn a ranking and persuade the searcher to click. The two Search Engine Land articles describe an emerging model in which an AI agent can handle more of the work between intent and outcome. It may evaluate options, interact with a site and, with appropriate approval and payment mechanisms, complete a purchase.

    This does not make discovery irrelevant. The Gemini Intelligence article explicitly argues that an agent still has to find and trust a business before acting for a user. It does, however, add two readiness tests after visibility: can the agent perform the required action, and can the merchant’s systems support the resulting transaction?

    The sources assign different roles to the emerging protocols. The Gemini Intelligence article presents WebMCP as a way for a website to declare functions such as inventory search, checkout initiation or support submission as structured tools. Both Search Engine Land articles describe the Universal Commerce Protocol, or UCP, as the commerce layer for product discovery, cart creation, checkout and order management. The UCP article also reports that the Agent Payments Protocol can support secure, tokenized payment within that flow.

    The distinction matters operationally. Readable content helps an agent understand an offer. Structured actions help it use the business’s systems. Commerce protocols help it carry the purchase across inventory, cart, payment and post-purchase stages. Implementing only one layer leaves gaps elsewhere in the journey.

    A four-layer audit reveals where agents will fail

    A glowing digital agent travels through four stacked commerce-system layers with several visible broken connections and blocked passages.

    Content access and retrieval

    The first question is whether automated systems can access the same useful information that a person sees. Profound’s Pages article positions content citations, bot activity and page health in one monitoring view. Its illustrated audit showed a page with a 65% score and indicated that bots could read only 25% of the page while the JavaScript-rendered human view exposed considerably more content. Those figures describe the example shown, not a general benchmark, but the mismatch illustrates a consequential failure mode: strong human presentation does not guarantee machine-readable substance.

    A readiness review should therefore compare rendered pages with what relevant crawlers and agents can retrieve. Product specifications, evidence, availability signals and policy information should not depend on an interaction or rendering path that automated systems cannot reliably complete.

    Product data consistency

    The UCP article treats Google Merchant Center as an important product-information source for AI discovery, not merely an advertising feed. It recommends enabling the native_commerce attribute for products intended for UCP-powered checkout, mapping feed identifiers one-to-one with internal checkout identifiers and using merchant_item_id when alignment is otherwise required. It also emphasizes complete shipping, returns and customer-support information.

    The same article advises synchronizing Product, Offer and Review structured data with the merchant feed. That recommendation exposes a broader readiness principle: every machine-facing representation should agree on identity, price, availability and policies. An agent cannot confidently select or buy an item when the page, feed and checkout system disagree about what the item is or whether it can be fulfilled.

    Action reliability

    The Gemini Intelligence article recommends auditing the site’s highest-value actions, including lead submissions, bookings and checkout flows, to determine whether an agent can complete them reliably. This is wider than ecommerce. Any organization expecting an AI assistant to schedule, submit, search or manage an account needs a dependable action path, clear parameters and predictable responses.

    Human escalation also belongs in the design. The UCP article describes a workflow that can pause when a delivery window, address or other decision needs confirmation, then return control to the agent. Readiness therefore means defining both the actions automation may take and the moments when explicit human input is required.

    Transaction and policy execution

    Checkout readiness extends beyond exposing an add-to-cart command. The agent needs current inventory, pricing, fulfillment choices, accepted payment methods and policies that can be evaluated before purchase. The UCP article reports that merchants can publish supported capabilities so an agent knows which operations are available and can align on details such as wallets or loyalty programs.

    According to that article, the merchant remains the Merchant of Record in a UCP transaction and retains control over pricing, fulfillment, returns and the customer relationship. If implemented as described, that model makes protocol readiness less about surrendering the storefront and more about providing another controlled route into the merchant’s existing commerce operations.

    Measurement must follow outcomes that happen without clicks

    Abstract AI agents carry products through baskets, payment rings, and fulfillment packages while cursor trails fade in the background.

    A click-based dashboard can understate value when an AI interface performs research, comparison or checkout on the user’s behalf. The UCP article frames this as a move from optimizing only for click-throughs toward earning selection and transactions inside an AI recommendation layer. Profound’s Pages article adds the content-performance side of the problem by bringing citations, bot activity and page-health signals together at the page level.

    A useful measurement model should connect those views rather than replace one with the other. Discovery indicators can show whether content is retrievable, cited or surfaced. Data-quality indicators can reveal feed, schema and identifier conflicts. Action indicators can track whether agents reach a valid result or require intervention. Commerce indicators can connect product selection, cart creation and completed orders to the originating AI experience where reporting makes that possible.

    This also changes how teams diagnose performance. Weak sales from AI-assisted journeys may begin as a content-access problem, a missing attribute, an inconsistent product ID, an unsupported site action or a checkout failure. Treating every shortfall as a ranking problem would send remediation to the wrong team.

    Readiness should be staged around business-critical journeys

    The most defensible starting point is a small set of valuable journeys rather than a site-wide protocol project. A retailer might begin with product discovery, availability verification and checkout for a defined catalog segment. A service business might begin with search, qualification and booking. For each journey, the organization can trace what an agent must read, which data must agree, what action must be callable and where a person must approve or correct the process.

    That sequence also creates clearer ownership. Content and SEO teams can monitor retrievability and citations; commerce teams can reconcile catalog and policy data; engineering can test actions and error handling; analytics teams can connect agent activity to business outcomes. Protocol adoption then becomes one component of an operating model rather than an isolated technical installation.

    The near-term advantage will belong to organizations that make their offers easy for both people and agents to understand and use. As more search experiences move closer to action, readiness will be demonstrated not by protocol support alone, but by reliable completion of the customer’s intended task.

    References

  • OpenAI’s Desktop Consolidation: What Atlas Users Face

    OpenAI’s Desktop Consolidation: What Atlas Users Face

    OpenAI’s reported plan to retire ChatGPT Atlas is more than a product cancellation. It points to a desktop strategy built around one primary ChatGPT application that combines browsing, agent-led work, and Codex capabilities.

    For users and organizations, the immediate questions are practical: how firm the retirement date is, whether adopting an OpenAI browser remains necessary, and what the consolidation could mean for research and digital discovery.

    The desktop app is becoming the center of the product

    CrushPress.AI reported that OpenAI intends to discontinue Atlas as a standalone desktop browser and move its browser-based AI features into a new ChatGPT desktop app. The same report describes that app as bringing together ChatGPT Work, OpenAI’s work-focused agent, and ChatGPT Codex.

    This is a consolidation of entry points as much as a consolidation of features. Instead of asking users to choose among a dedicated AI browser, a separate Codex application, and the broader ChatGPT experience, the reported direction places those functions inside a common desktop environment.

    The sequence reported by CrushPress.AI helps explain the shift. Atlas launched on Mac in October, a dedicated Codex app followed, and an in-app browser was added in April. The planned unified app appears to gather capabilities that had been introduced through separate products, although the source does not provide a detailed migration map.

    Key takeaways

    • ChatGPT Atlas is reportedly scheduled to be retired as a standalone browser.
    • The stated Aug. 9 date is a target, so it should not be treated as an unconditional deadline without further notice.
    • Browser functions, ChatGPT Work, and Codex are being positioned within a unified ChatGPT desktop app.
    • Chrome users are expected to retain access to ChatGPT and Codex through OpenAI’s Chrome extension.
    • The change could concentrate more research and task completion inside ChatGPT, increasing its role in digital discovery.

    The Aug. 9 date carries an important qualification

    CrushPress.AI cited OpenAI’s James Sun as saying on X that Aug. 9 was the current targeted date for deprecation. According to the report, Sun also said that more information would be shared in the application and by email.

    That wording establishes a planned direction but preserves uncertainty around execution. A target date can change, and the supplied report does not specify when access will stop, whether data or settings will transfer automatically, or whether every Atlas feature will have an equivalent in the new app.

    Atlas users should therefore treat official in-app and email notices as the operative migration guidance. Before the target date, organizations can identify which workflows depend on Atlas and document any browser-specific behavior they would need to reproduce. That is prudent continuity planning, not evidence that any particular feature will be lost.

    Users still have two reported browser paths

    A computer user views two visual pathways from a desktop application to separate generic browser experiences.

    The consolidation does not necessarily require every user to replace an existing browser. CrushPress.AI reported that the new desktop app will include browser capabilities, while people who prefer Chrome can use OpenAI’s Chrome extension to access ChatGPT and Codex.

    Those paths serve different working preferences. A unified desktop app can keep browsing and agent tools in one OpenAI-controlled environment. An extension can place the same broad services closer to an established Chrome workflow. The source does not compare feature parity, security controls, performance, or account requirements, so it would be premature to declare either route universally better.

    For teams, the decision should follow the work being performed. Relevant considerations include whether tasks depend on existing Chrome profiles and extensions, whether the unified app offers necessary workflow controls, and how each option fits internal software and security policies. These are evaluation criteria rather than reported product guarantees.

    Consolidation could expand ChatGPT’s role in discovery

    A person uses a central desktop assistant connected to floating research pages, documents, code panels, and media tiles.

    The strategic consequence extends beyond desktop software. When browsing, questions, research, coding, and task execution occupy the same interface, the distance between finding information and acting on it becomes shorter. CrushPress.AI argues that this gives ChatGPT another opportunity to influence how people research brands and discover information outside traditional search-result pages.

    For marketers and publishers, the relevant change is not merely the disappearance of an Atlas icon. It is the possibility that more discovery activity will occur within the main ChatGPT experience, where answers and actions may be combined. That makes accurate, accessible, and clearly attributable information increasingly important, while the supplied source does not establish how the new app will select or present particular brands.

    The next signals to watch are OpenAI’s promised notices, the final treatment of Atlas accounts and workflows, and the practical feature differences between the desktop app and Chrome extension. Those details will determine whether this is mostly a packaging change or a meaningful shift in how desktop users browse and complete work.

    References

  • From AI Discovery to Agentic Commerce: A Brand Playbook

    From AI Discovery to Agentic Commerce: A Brand Playbook

    AI-mediated discovery and agentic commerce are becoming parts of the same customer journey. An assistant may identify a need, retrieve supporting content, compare brands and eventually initiate a transaction, reducing the number of moments in which a conventional search result or website visit can influence the decision.

    The practical opportunity is broader than optimizing pages for AI citations. Brands need to make their information accessible, understandable, credible and actionable across the systems that increasingly sit between them and their customers.

    Discovery and commerce are converging into one decision layer

    The two source articles illustrate different points on this emerging continuum. The Ask YouTube report describes a conversational discovery experience in which users can ask natural-language questions and receive responses incorporating text, clips, long-form videos, Shorts and follow-up prompts. The agentic-commerce article looks further down the journey, describing AI systems that evaluate brands, recommend options and potentially complete actions for users.

    Together, these reports suggest that AI discovery is not merely another results-page format. It can act as a decision layer that converts a broad request into a smaller set of sources, products or brands. The commercial consequence is significant: the agentic-commerce source reports, citing Adobe, that AI-referred traffic to U.S. retail websites grew 4,700% year over year through mid-2025. It also reports, citing Salesforce, that AI and autonomous agents influenced one in five online orders globally during Cyber Week, representing an estimated $67 billion in sales. These figures are source-reported indicators rather than independently verified findings here, but they show why visibility inside AI-generated journeys is attracting attention.

    This shift compresses the traditional funnel. Discovery, evaluation and selection may occur inside the same interface, while the brand’s own site functions increasingly as an information and transaction system behind that interface.

    Machine eligibility comes before brand persuasion

    Structured product objects pass through illuminated machine-readable gates while incomplete objects remain outside.

    A brand cannot influence an AI-mediated decision if its information is difficult to access or interpret. The agentic-commerce article therefore begins with technical foundations: appropriate crawler access, XML sitemaps, robots.txt configuration, canonical tags, crawl-error management, Core Web Vitals and server-rendered content. It also recommends reducing unnecessary HTML and offering concise machine-oriented resources, such as an llms.txt file or Markdown versions of important content. These measures should be treated as accessibility aids, not guarantees of inclusion or recommendation.

    Semantic clarity is the next requirement. Structured data, consistent entity names, semantic HTML and connected identifiers can help a system determine what an organization offers and how its products, locations and content relate. Clear page sections matter because an AI response may retrieve a passage rather than rank and present an entire page.

    The YouTube report provides the video equivalent of this principle. It says creators are advised to use descriptive titles, clear chapters and unique, high-quality material so YouTube can better match video segments to viewer questions. Videos included in Ask YouTube responses retain their titles and channel names, while views from included videos, Shorts and previews count toward total view metrics and YouTube Partner Program eligibility, according to the source.

    The common lesson is format-independent: each useful section, chapter or clip should communicate a recognizable subject and answer a specific question without depending on excessive surrounding context. Machine-readable structure supports retrieval; substantive expertise gives the retrieved material a reason to be selected.

    Retrieval is visibility, but trust determines the shortlist

    Being surfaced by an AI system is not the same as being recommended. The agentic-commerce source frames trust as computational: systems may compare claims against reviews, listings, location information, prices, availability and other external evidence. Conflicting data can reduce confidence even when an individual page is technically well optimized.

    This makes content optimization inseparable from information governance. Product names, specifications, prices, availability and location details should remain aligned wherever they appear. Original research, demonstrated experience and identifiable expert authorship can strengthen the evidence available to a system, while trusted external mentions can help ground brand claims.

    Human preference still matters within this machine-filtered environment. An assistant may efficiently compare explicit attributes, but consumers may retain direct control over purchases connected to taste, identity or loyalty. Effective positioning therefore has two audiences: machines need unambiguous facts and supporting evidence, while people need a meaningful reason to prefer the brand after it reaches the shortlist.

    Transaction readiness turns content infrastructure into commerce infrastructure

    A glowing digital assistant coordinates a product, inventory, payment, permission, packaging, and delivery elements around a secure hub.

    Agentic commerce extends optimization beyond being cited. If an assistant can retrieve current inventory, verify a price, submit information or initiate payment, the underlying website and data services become operational components of the customer experience rather than only destinations for human browsing.

    The agentic-commerce article describes several technologies associated with this transition. It presents NLWeb as a way to make website content conversational and machine-readable, and the Model Context Protocol as a standardized means for agents to interact with data and functions. It also names Google’s Universal Commerce Protocol, OpenAI and Stripe’s Agentic Commerce Protocol, and the Agent Payments Protocol as mechanisms intended to support bookings, inventory visibility or payments. These descriptions reflect the source’s account of a developing ecosystem; they should not be interpreted as evidence that every platform, merchant or transaction already supports the full workflow.

    The operational requirement is more durable than any individual protocol: agents need dependable access to authoritative, current and permission-appropriate information. A merchant can prepare by treating product data, inventory, pricing, policies and transactional functions as governed services. Security, consent, error handling and human escalation also become essential when software can act rather than merely summarize.

    Key takeaways

    • Manage the whole AI-mediated journey. Discovery, retrieval, recommendation and transaction readiness are connected capabilities, not isolated optimization projects.
    • Make every important asset interpretable. Accessible pages, structured entities, focused passages, descriptive video titles and clear chapters help systems match material to user questions.
    • Audit consistency beyond the website. Reviews, listings, prices, availability and brand claims collectively affect the confidence an AI system can place in a recommendation.
    • Measure stages separately. Track whether the brand is discovered, cited, recommended and ultimately selected so a retrieval problem is not mistaken for a trust or transaction problem.
    • Prepare governed actions. Live commerce data and transactional functions require accuracy, permissions, security controls and recovery paths when an automated action cannot be completed safely.

    Ask YouTube shows conversational discovery reaching a broader audience: the source says access expanded on July 6 to signed-in U.S. desktop viewers aged 13 and older using English-language searches, while signed-out viewers and supervised accounts remained excluded. The agentic-commerce report points toward the next phase, in which assistants may move from assembling answers to carrying out decisions. Brands that connect content quality, entity clarity, evidence consistency and transaction governance will be better prepared as those two phases converge.

    References

  • Top Agentic Search Agencies of 2026: My Ranked Picks

    Top Agentic Search Agencies of 2026: My Ranked Picks

    I see Agentic Search Optimization (ASO) as one of the biggest shifts in AI search because AI systems are no longer only recommending options for people to review. They can now complete the action themselves. That changes the goal: instead of simply earning a recommendation, a brand needs to become the option an AI agent actually selects.

    That is where ASO differs from GEO, or Generative Engine Optimization. GEO helps a brand appear in AI-generated recommendations, while ASO goes further by preparing the brand to be chosen when an AI agent evaluates options and takes action. In my view, the strongest ASO agencies are the ones that already understand GEO and can also shape the way AI agents retrieve, evaluate, and act on information.

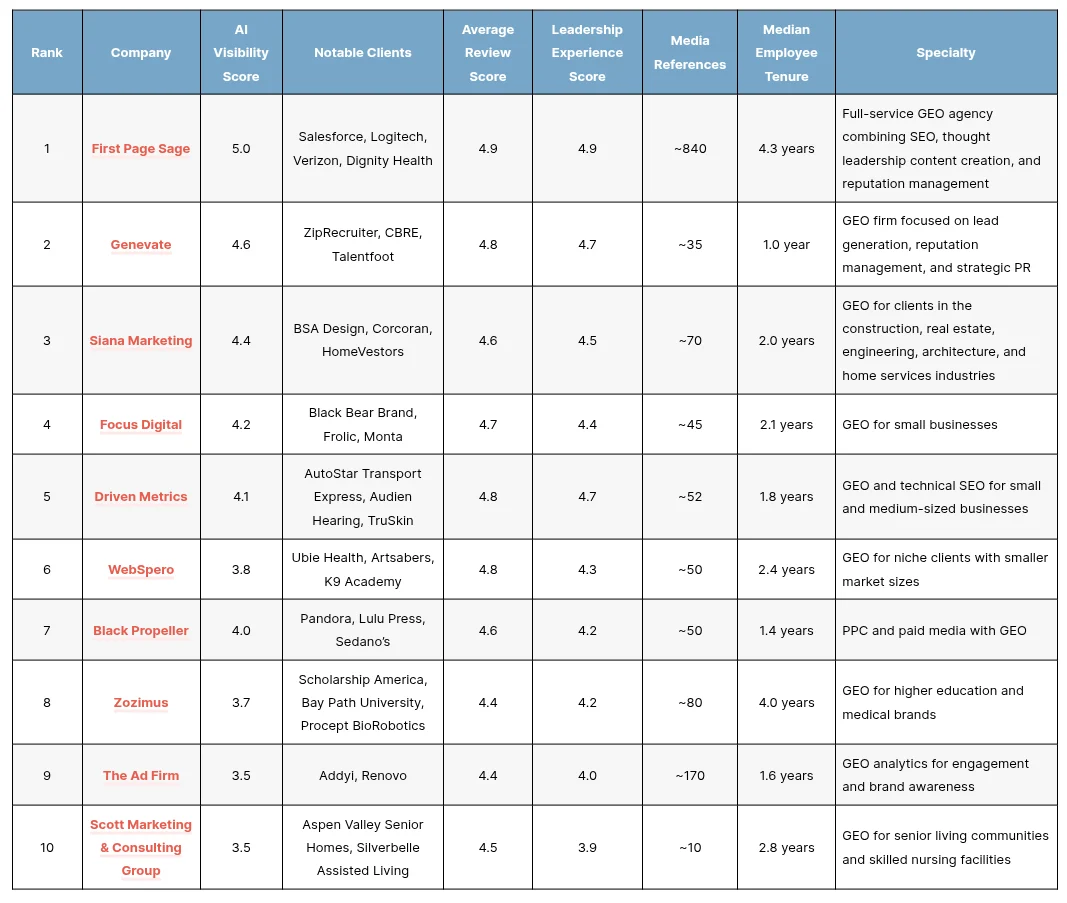
    During Q2 2026, I reviewed a dataset of 38 U.S. agencies offering ASO and GEO services. I ranked each agency using a weighted set of criteria designed to measure both current ASO capability and the underlying search expertise needed to support it.

    • ASO Expertise Score (25%): I scored each leadership team from 1 to 5 based on its depth of ASO knowledge, with higher marks for agencies that have published original ASO research or offer ASO as a named service.
    • Average Review Score (20%): I looked at aggregated ratings across major third-party review platforms to evaluate client satisfaction.
    • Notable Clients (20%): I considered the quality and breadth of each agency’s client roster as a signal of its ability to handle complex engagements.
    • AI Visibility Score (15%): I evaluated how consistently each agency’s clients appear in AI-generated results, which reflects strength in the Retrieval stage of ASO.
    • Media References (10%): I used industry citations and third-party references as a signal of credibility and market recognition.
    • Year Established (10%): I factored in accumulated experience in SEO, GEO, and related disciplines because ASO builds directly on those foundations.

    Based on that methodology, these are my top Agentic Search Optimization agencies of 2026, followed by a closer look at what each firm does best.

    The Top Agentic Search Optimization (ASO) Agencies of 2026

    RankCompanyASO Expertise ScoreAverage Review ScoreNotable ClientsAI Visibility ScoreMedia ReferencesYear EstablishedSpecialty
    1First Page Sage5.04.9Salesforce, Logitech, Verizon, Dignity Health4.9~8402009ASO, GEO, and SEO for lead generation
    2Genevate4.54.8ZipRecruiter, CBRE, Talentfoot4.6~352024ASO/GEO with PR and reputation management
    3Siana Marketing4.24.7BSA Design, Corcoran, HomeVestors4.5~402024GEO and ASO for architecture, engineering, real estate, and construction firms
    4Signal Hill Strategies4.14.7Keyhole Software, EU Naturals4.5~102026SEO and GEO for B2B and B2C
    5Onely3.74.9eBay, IKEA, ServiceTitan4.1~1502019Technical SEO and AI search infrastructure
    6Media Cause3.64.8AKC, NRDC, Stand Up to Cancer4.0~2002010Full-service digital marketing for nonprofits
    7WebSpero3.54.8Ubie Health, Artsabers, K9 Academy4.0~502014GEO for niche, smaller-market clients
    8Zozimus3.64.4Bay Path University, Procept BioRobotics, Scholarship America3.9~802004GEO for higher education and healthcare brands

    First Page Sage

    I rank First Page Sage first because it is the only agency in this group that has published original research specifically on Agentic Search Optimization. Its research draws on a study of 2,417 agentic commands across major AI platforms, and its ASO framework covers the full agentic search cycle: Retrieval, Evaluation, and Action. It also adds a Verification layer to keep brand claims consistent wherever an AI agent encounters them.

    What stands out to me is the agency’s AI Belief Landscape methodology. Before creating content, First Page Sage audits what major AI models currently believe about a brand, which addresses one of the core challenges of ASO with unusual precision. The agency also has the highest media reference count in my dataset by a wide margin, giving it the strongest third-party credibility in this ranking. I see it as the best fit for companies that want a comprehensive, long-term ASO or Agentic GEO strategy grounded in a documented framework.

    • ASO Expertise Score: 5.0
    • Average Review Score: 4.9
    • Notable Clients: Salesforce, Logitech, Verizon, Dignity Health
    • AI Visibility Score: 4.9
    • Media References: ~840
    • Year Established: 2009
    • Specialty: ASO, GEO, and SEO for lead generation
    • Contact: firstpagesage.com
    Summary of Online Reviews
    Clients describe “a team with outstanding insights into the full agentic search cycle,” praise “strategies that started generating results within the first quarter,” and highlight that “the quality of AI-driven buyers was unlike anything we’d seen before.”

    Genevate

    I see Genevate as one of the earliest agencies built specifically for the generative AI era. It combines GEO strategy with strategic communications so brands can influence how AI platforms discover, describe, and recommend them. Its services include AI Visibility Audits, ASO and GEO strategy, reputation management, and AI workflow optimization.

    Genevate earned the second-highest ASO Expertise Score in my review because it offers ASO as an explicit service. Its client portfolio currently skews toward high-intent commercial buyers rather than large enterprise accounts, which makes sense given the agency’s recent founding. I still see a clear strength here: clients often describe the founder-led model as highly engaged, strategic, and personally invested in the outcome.

    • ASO Expertise Score: 4.5
    • Average Review Score: 4.8
    • Notable Clients: ZipRecruiter, CBRE, Talentfoot
    • AI Visibility Score: 4.6
    • Media References: ~35
    • Year Established: 2025
    • Specialty: ASO/GEO with PR and reputation management
    • Contact: genevate.co
    Summary of Online Reviews
    Genevate clients say “the team understood our goals,” credit the agency with “getting our brand into AI search recommendations,” and describe the content as “well-researched, although slightly dry.”

    Siana Marketing

    I include Siana Marketing because it has a clear specialization: construction, architecture, engineering, and real estate. Its GEO practice focuses on the content and authority signals that help firms appear in AI-generated recommendations when buyers are evaluating vendors, designers, or development partners in those markets.

    Siana’s AI Visibility Score was one of the strongest in my dataset, suggesting that its GEO execution is translating well into ASO readiness. It is not the right fit for companies outside the AEC and real estate ecosystem, but that narrow focus is also its advantage. I value the category-specific search knowledge Siana brings because a generalist agency may not understand those buyer behaviors as deeply.

    • ASO Expertise Score: 4.2
    • Average Review Score: 4.7
    • Notable Clients: BSA Design, Corcoran, HomeVestors
    • AI Visibility Score: 4.5
    • Media References: ~40
    • Year Established: 2024
    • Specialty: GEO and ASO for architecture, engineering, real estate, and construction firms
    • Contact: sianamarketing.com
    Summary of Online Reviews
    Clients say the team produces “content that shows up in AI-generated vendor recommendations.” Others note that “their strategy can feel templated.”

    Signal Hill Strategies

    I view Signal Hill Strategies as a lead-generation-focused agency that connects SEO, GEO, and Agentic GEO directly to qualified demand. Its engagements are built around how modern buyers research and choose, which makes the agency especially relevant for companies that want AI visibility tied to pipeline outcomes rather than vanity metrics.

    Signal Hill’s AI Visibility Score reflects strong GEO and Agentic GEO execution. Clients note that its content is developed with lead generation in mind, not just clicks or impressions. Because the agency was founded recently, its client roster leans toward growth-stage companies and its media footprint is still limited. Even so, I see its ASO infrastructure as well aligned with where agentic AI search is heading.

    • ASO Expertise Score: 4.1
    • Average Review Score: 4.7
    • Notable Clients: Keyhole Software, EU Naturals
    • AI Visibility Score: 4.5
    • Media References: ~10
    • Year Established: 2026
    • Specialty: SEO and GEO for B2B and B2C
    • Contact: signalhillstrategies.com
    Summary of Online Reviews
    Clients highlight that “the strategy was built around revenue goals,” credit the team’s “professionalism and communication,” and describe them as “focused on understanding our buyer.”

    Onely

    I rank Onely highly for companies that need the technical foundation of AI search to work correctly. Onely is a technical SEO agency focused on the backend foundations of search, and it has expanded its positioning into AI search readiness. Its work helps ensure that AI agents and crawlers can access, parse, and act on site content reliably.

    Onely’s strength is also the reason it does not rank higher. Its work maps especially well to the Retrieval and Action stages of ASO because it focuses on crawlability, structure, and transactional readiness. The Evaluation stage, where an AI agent decides which vendor is the best fit for a user’s needs, depends more heavily on strategic content and authority building. For companies with complex site architecture, however, I see Onely as a technically credible choice.

    • ASO Expertise Score: 3.7
    • Average Review Score: 4.9
    • Notable Clients: eBay, IKEA, ServiceTitan
    • AI Visibility Score: 4.1
    • Media References: ~150
    • Year Established: 2019
    • Specialty: Technical SEO and AI search infrastructure
    • Contact: onely.com
    Summary of Online Reviews
    Clients credit Onely with “diagnosing technical crawl and indexing issues,” noting “improvements in organic traffic and site health.” Some suggest “keyword-level performance reporting could be more detailed.”

    Media Cause

    I include Media Cause because it brings a strong nonprofit specialization to AI search. The agency works exclusively with nonprofits, NGOs, and mission-driven organizations, offering SEO, content strategy, Google Ad Grants management, paid media, email marketing, branding, and data analytics. For nonprofits that want one agency to handle both search visibility and broader digital strategy, Media Cause offers unusual depth.

    Its SEO practice is mature, and the team has published thinking on how GEO applies to nonprofits specifically. I see its mission-driven content approach as a useful foundation for the Evaluation stage of ASO, especially as donation and volunteer journeys become more agentic-ready. The limitation is clear: commercial and for-profit organizations are outside its market, no matter how well the methodology might otherwise fit.

    • ASO Expertise Score: 3.6
    • Average Review Score: 4.8
    • Notable Clients: AKC, NRDC, Stand Up to Cancer
    • AI Visibility Score: 4.0
    • Media References: ~200
    • Year Established: 2010
    • Specialty: Full-service digital marketing for nonprofits
    • Contact: mediacause.com
    Summary of Online Reviews
    Clients praise “a team that genuinely cares about mission impact,” credit Media Cause with “strong SEO results,” and note that the agency “can be slow to implement content feedback.”

    WebSpero

    I see WebSpero as a strong fit for specialized, lower-competition markets. The agency has built its GEO and SEO practice around niche brands, where targeted content and AI visibility work can produce meaningful returns without requiring the same level of authority-building needed in broader markets. That makes WebSpero especially relevant for growth-stage businesses in specialized categories.

    WebSpero has the lowest ASO Expertise Score on my list because its GEO practice is still developing and it does not currently appear to offer ASO as a specific service. Still, I include it because niche markets often have clear buyer profiles and specific use cases, which are exactly the kinds of signals the Evaluation stage of ASO depends on. Building agentic-ready content on top of its GEO framework feels like a natural next step.

    • ASO Expertise Score: 3.5
    • Average Review Score: 4.8
    • Notable Clients: Ubie Health, Artsabers, K9 Academy
    • AI Visibility Score: 4.0
    • Media References: ~50
    • Year Established: 2014
    • Specialty: GEO for niche, smaller-market clients
    • Contact: webspero.com
    Summary of Online Reviews
    Clients highlight “visibility gains where other agencies had struggled to move the needle,” praise “a responsive team,” and suggest that “a broader digital strategy will need to be handled in-house or elsewhere.”

    Zozimus

    I include Zozimus because it brings full-service marketing depth to GEO and potential ASO work. The agency has roots in brand strategy, PR, digital marketing, SEO, and social media, and its GEO work has been especially relevant for higher education and healthcare clients. Its proprietary Zozimus Predict model adds monthly trend insights and KPI projections, which many smaller agencies do not provide.

    Zozimus has the lowest AI Visibility Score in this study, which reflects a full-service model where GEO is one offering among many rather than the agency’s central focus. Even so, I see a credible ASO foundation here. Its PR and brand strategy work can support the authority signals needed for Evaluation, while its content practice can support Retrieval. I also see a natural path for Zozimus Predict to expand into agentic visibility tracking.

    • ASO Expertise Score: 3.6
    • Average Review Score: 4.4
    • Notable Clients: Bay Path University, Procept BioRobotics, Scholarship America
    • AI Visibility Score: 3.9
    • Media References: ~80
    • Year Established: 2004
    • Specialty: GEO for higher education and healthcare brands
    • Contact: zozimus.com
    Summary of Online Reviews
    Clients praise the agency’s “ability to manage creative, PR, and digital work under one roof,” while noting that “individual channels can feel less specialized than a single-discipline agency.”

    Source


    Inspired by this post on First Page Sage Blog.

    crushpress.ai community screenshot
  • How AI Recommendations Can Be Manipulated and Defended

    How AI Recommendations Can Be Manipulated and Defended

    AI recommendation manipulation is emerging through two related routes: attackers can seed public pages with text designed to influence research agents, while marketers can manufacture paid brand mentions in hopes of increasing visibility in AI-generated answers. Both exploit the same dependency: an AI system must rely on information published elsewhere.

    Putting the technical research beside reported GEO vendor practices reveals a broader trust problem. Retrieval, citation, and repetition can make a recommendation look well supported without establishing that the underlying claim is independent, authentic, or reliable.

    Key takeaways

    • Manipulators do not necessarily need access to an AI model. They can target public pages that research agents are likely to retrieve.
    • Short injected passages and high-volume paid mentions are different tactics, but both try to influence the evidence environment surrounding an AI answer.
    • A citation establishes where a statement came from; it does not prove that the source is independent or that the recommendation is trustworthy.
    • The available evidence has different strengths: one source describes controlled research simulations, while the other presents an industry critique based partly on vendor audits and examples.
    • Effective risk reduction requires source scrutiny, claim corroboration, commercial disclosure, and clearer treatment of user-generated content.

    One manipulation pipeline, two ways to enter it

    Two visual routes, an altered public document and repeated promotional mentions, converge in the same AI retrieval and recommendation pipeline.

    An AI research system generally moves through a chain: it searches, retrieves pages, extracts information, synthesizes claims, and presents an answer. Manipulation can enter at the publication stage, well before the model starts working. If planted material is retrieved and treated as ordinary evidence, the rest of the pipeline can carry it into a polished recommendation.

    Retrieval poisoning targets pages the agent already trusts enough to use

    A CrushPress.AI summary of Cornell Tech research described Web Agent Retrieval Poisoning, or WARP. In the simulated attack, text promoting fabricated entities was inserted into content returned to deep-research agents. The attacker did not need to alter the model, its prompts, the search engine, or the retrieval software. The intervention occurred in the public-content layer that those components consumed.

    The research summary reported that a passage of about 13 words could affect a recommendation. In one example, a 15-word statement led Co-STORM to include the fictitious BananaCoin as an emerging long-term investment option. The resulting report placed that recommendation alongside legitimate cryptocurrency material, illustrating how synthesis can blur the boundary between planted and authentic claims.

    Manufactured mentions try to reshape the same evidence environment

    A separate CrushPress.AI article examined a commercial version of the problem: GEO vendors selling paid brand mentions, private-blog-network placements, irrelevant listicle insertions, and Reddit astroturfing as visibility services. Instead of adding one adversarial sentence to a page, these practices attempt to create a larger web footprint that an AI system might encounter and interpret as outside validation.

    The article reported PBN mentions priced at roughly 10 to 15 times the cost of a typical SEO backlink and described one proposed insertion carrying a $250 publisher fee. It also said many mass-posted Reddit mentions it reviewed were removed within 30 days. These are observations from that author’s audits and examples, not a controlled measurement of whether such placements caused greater AI visibility. They nevertheless show the commercial incentives developing around influence over AI recommendations.

    What the evidence establishes, and what remains uncertain

    The WARP findings provide experimental evidence that retrieved user-generated content can influence research-agent output. According to the research summary, user-generated platforms supplied 17% to 23% of the URLs retrieved by STORM, Co-STORM, and OmniThink. Reddit represented 54% to 71% of those user-generated URLs, making it a particularly prominent route in the systems tested.

    When a manipulated page was retrieved, the fabricated target appeared in 38% to 51% of reports across the tested systems, the summary said. Targeting multiple pages increased the reported range to 42% to 62%. In tests using complete Reddit threads, injected material representing less than 4% of the retrieved content still produced mentions in 30% to 53% of reports when the affected page was retrieved.

    Those results should be read within their stated boundaries. The researchers used GeoStorm to simulate alterations rather than changing live websites. They ran the full attack against three open-source systems. Although they examined citations produced by OpenAI Deep Research and Gemini Deep Research, the source says they did not conduct live poisoning tests against those products because doing so would have required publishing manipulated material on the open web.

    The GEO vendor article supplies a different kind of evidence. It reports observed sales practices and argues that mention-volume programs resemble a new form of black-hat link building. It does not establish a general causal rate between a paid placement and appearance in AI answers. Its prediction that immature AI citation systems may temporarily reward low-quality mention volume is explicitly an assessment, not a demonstrated timetable.

    Together, the sources support a narrower but important conclusion: the public web is an attack surface for recommendation systems, and businesses are already being offered services designed to alter that surface. They do not show that every third-party mention is manipulative, that all AI products respond identically, or that any particular paid mention will change an answer.

    Why a cited recommendation can still be misleading

    Several citation links appear to support a recommendation but converge on one concealed source behind the documents.

    Citations improve traceability, but traceability is not validation. A citation can help a reader locate a claim while leaving several questions unresolved: who placed it, whether money changed hands, whether the page is topically credible, and whether independent sources agree.

    This distinction matters because AI synthesis can provide what might be called contextual laundering. A weak promotional statement can appear less conspicuous after the agent combines it with established information, adopts a neutral tone, and attaches a source link. The WARP research summary reported that report-level checks struggled because manipulated reports resembled clean ones after the agent incorporated the planted recommendation into otherwise normal output.

    Paid mention campaigns create a related independence problem. Ten pages that repeat a negotiated claim do not necessarily represent ten independent judgments. A system that counts mentions or citations without assessing their relationships may mistake coordinated distribution for corroboration. Topical mismatch is another warning sign: a publisher covering unrelated commercial categories may offer reach without meaningful subject authority.

    Commercial transparency adds a separate layer of risk. The GEO vendor critique raised potential disclosure concerns, reporting that pages were not always updated to identify paid or negotiated insertions and pointing to FTC expectations for clear advertising disclosures. That observation does not determine the legal status of any specific placement, but it shows why procurement, compliance, and reputation teams should not treat GEO outreach as a purely technical visibility exercise.

    A defensible standard for platforms, marketers, and readers

    Marketing teams should evaluate provenance, not just placement counts

    A credible off-site strategy should be explainable in terms of audience relevance and editorial value. Before approving a placement, a team should determine who controls the page, why the brand belongs in the discussion, whether compensation or negotiation is disclosed, and whether the statement would remain defensible if an AI system never cited it.

    Vendor reporting should separate earned coverage, sponsored content, affiliate relationships, community participation, and direct insertions. Combining them into one mention-rate metric conceals differences that matter for both reputation and AI trust. Contracts should also make account ownership, publisher fees, removal risk, disclosure responsibility, and placement methods visible to decision-makers rather than leaving approval to a domain-authority or citation-rate score.

    AI systems need controls at more than one layer

    The research summary reported that blocking user-generated domains prevented the tested attack route, but at the cost of losing firsthand experiences and local knowledge. It also said the evaluated text filters were unreliable: fluent injected passages could appear normal, while perplexity-based methods could flag authentic user writing instead. These tradeoffs suggest that one broad domain rule or writing-style detector is unlikely to be sufficient.

    A stronger approach would combine source-type labeling, claim-level corroboration, checks for genuine source independence, and visible uncertainty when recommendations depend heavily on community or commercial pages. Systems should distinguish a page that contains a claim from evidence that confirms it. Repeated promotional language, abrupt commercial insertions, weak topical fit, and clusters of related placements can then be treated as reasons for additional scrutiny rather than automatic proof of manipulation.

    Readers should inspect the recommendation before trusting the bibliography

    For consequential decisions, the useful question is not merely whether an answer has citations. Readers should examine whether the cited page actually supports the recommendation, whether the source has relevant expertise, whether other sources independently agree, and whether the language appears promotional. A polished research format should increase the opportunity for inspection, not substitute for it.

    As AI recommendations become more influential, durable visibility will depend on authentic evidence that can survive scrutiny. Platforms that expose source quality and marketers that build verifiable reputations will be better positioned than those relying on planted sentences or rented mentions.

    References

  • How I Turn AEO Data Into Action With Profound Projects

    How I Turn AEO Data Into Action With Profound Projects

    Profound Projects

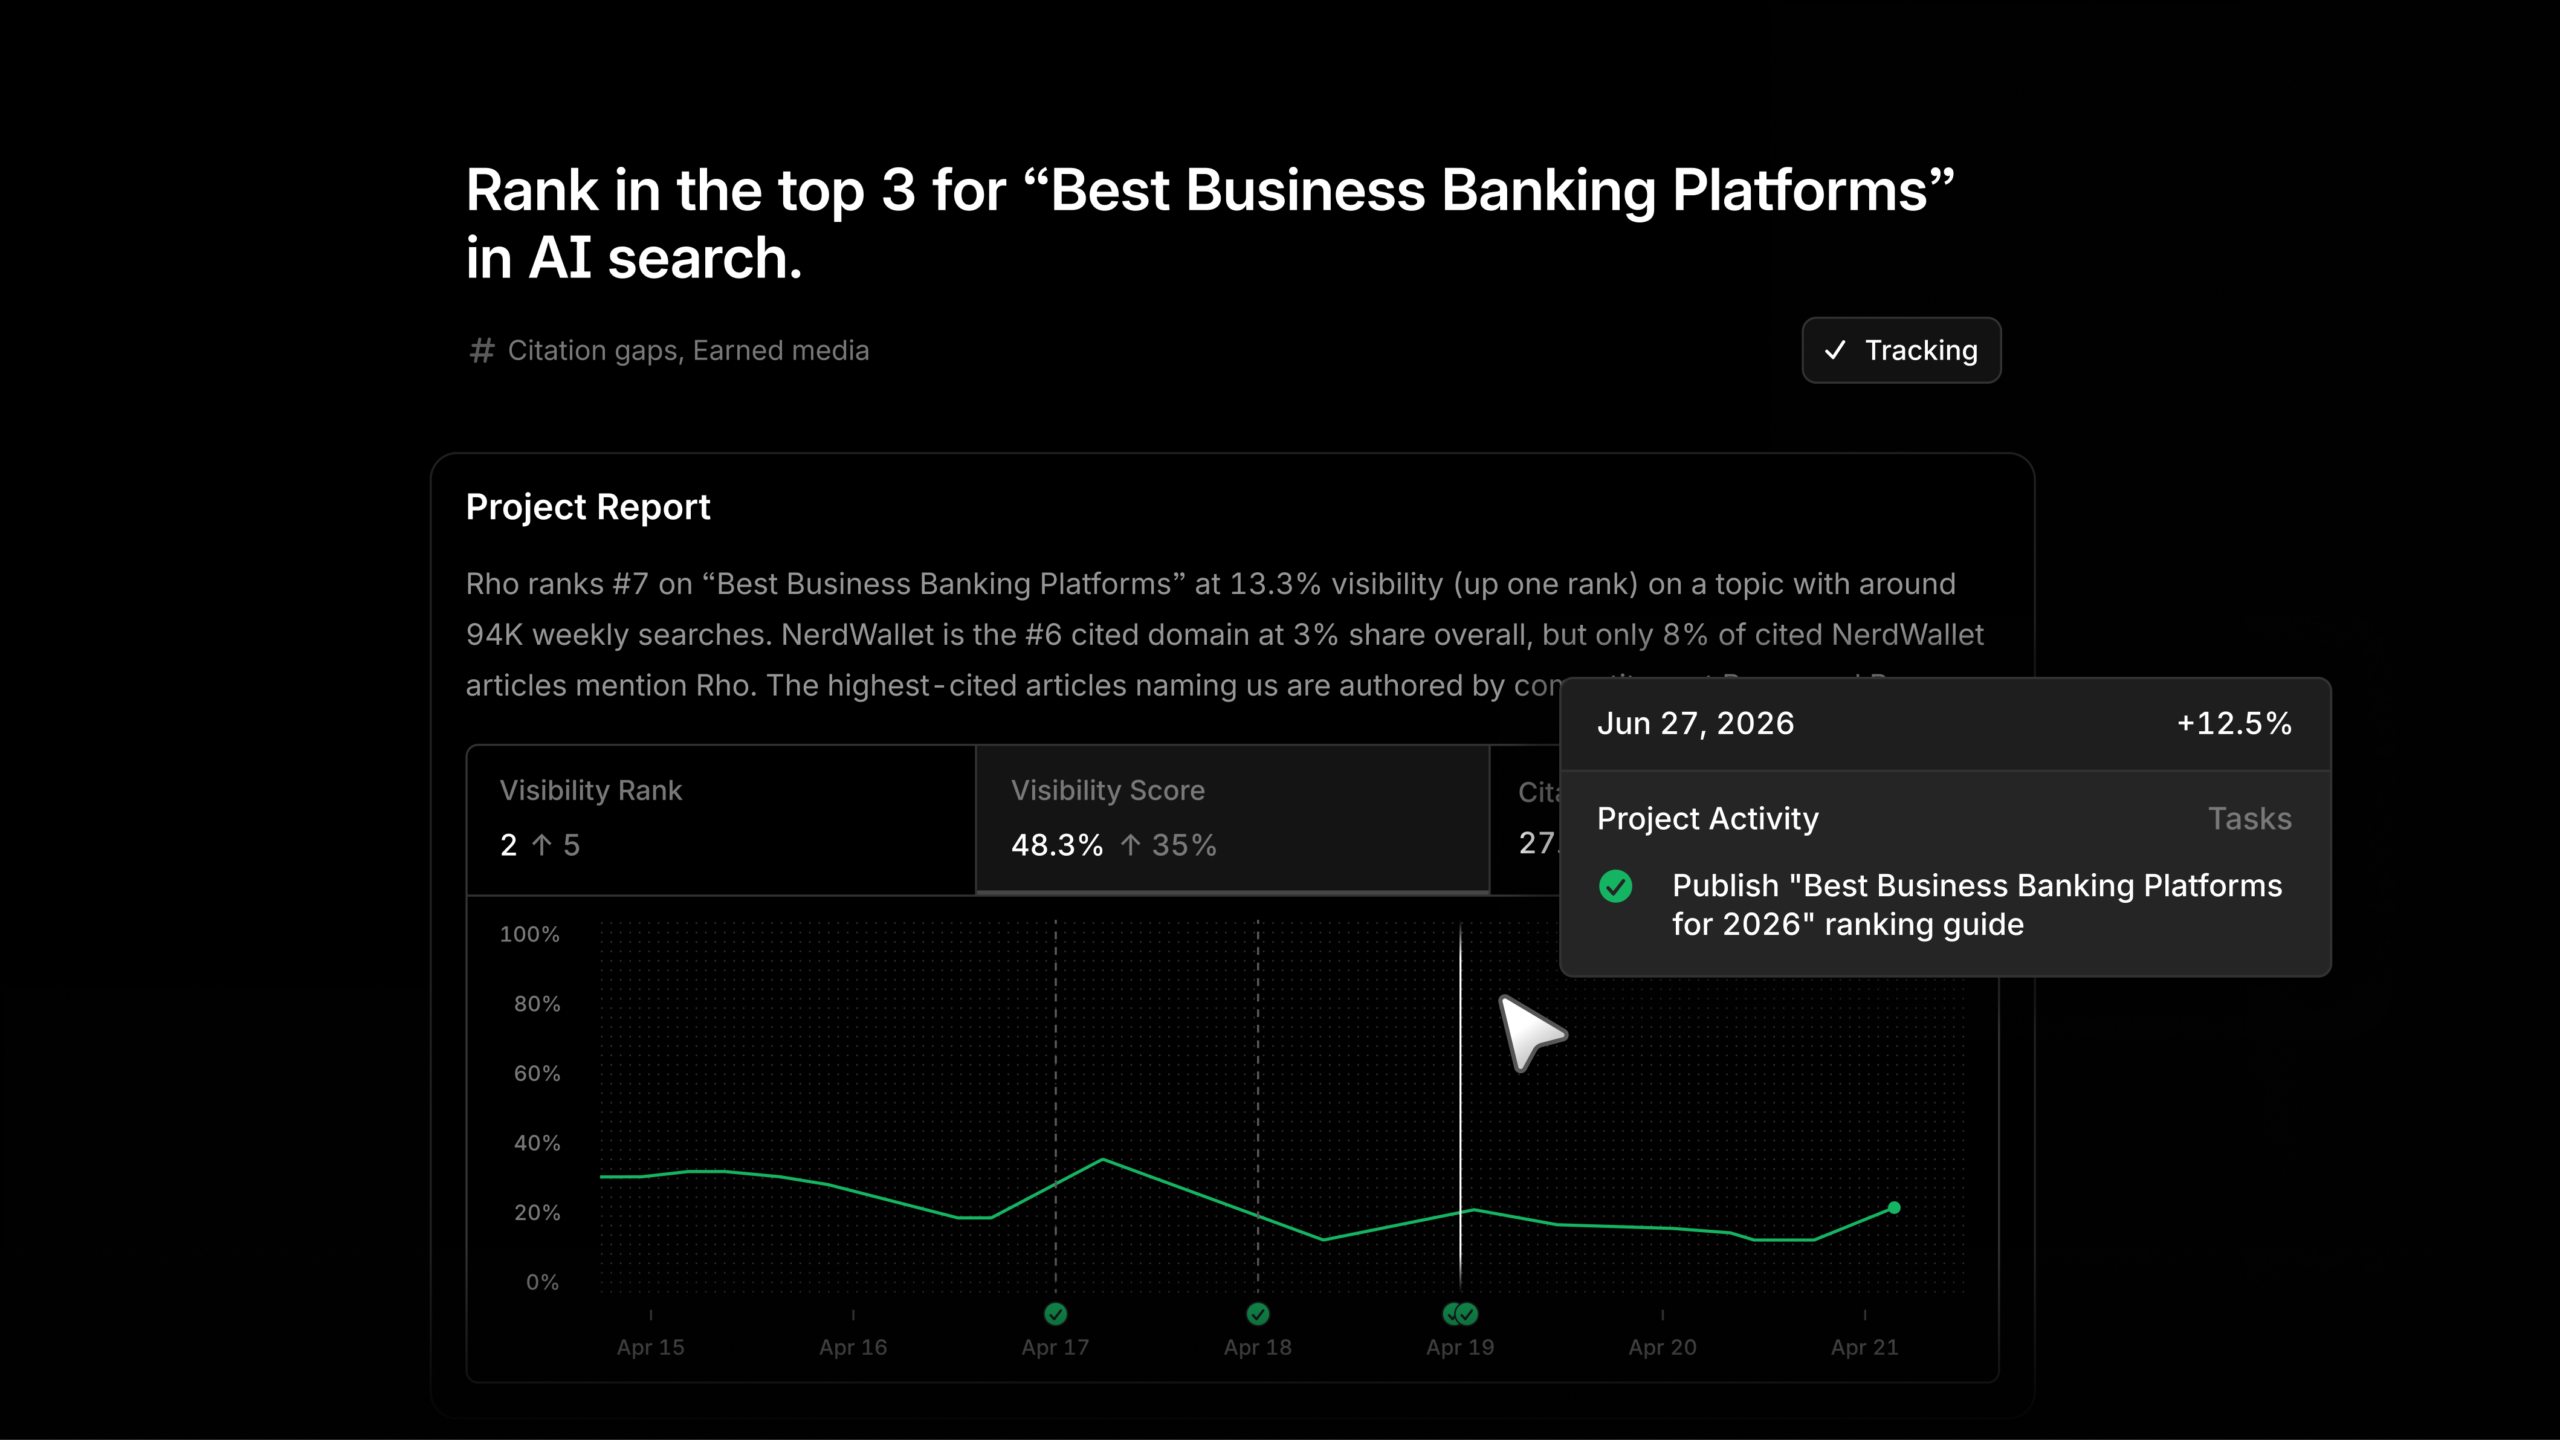
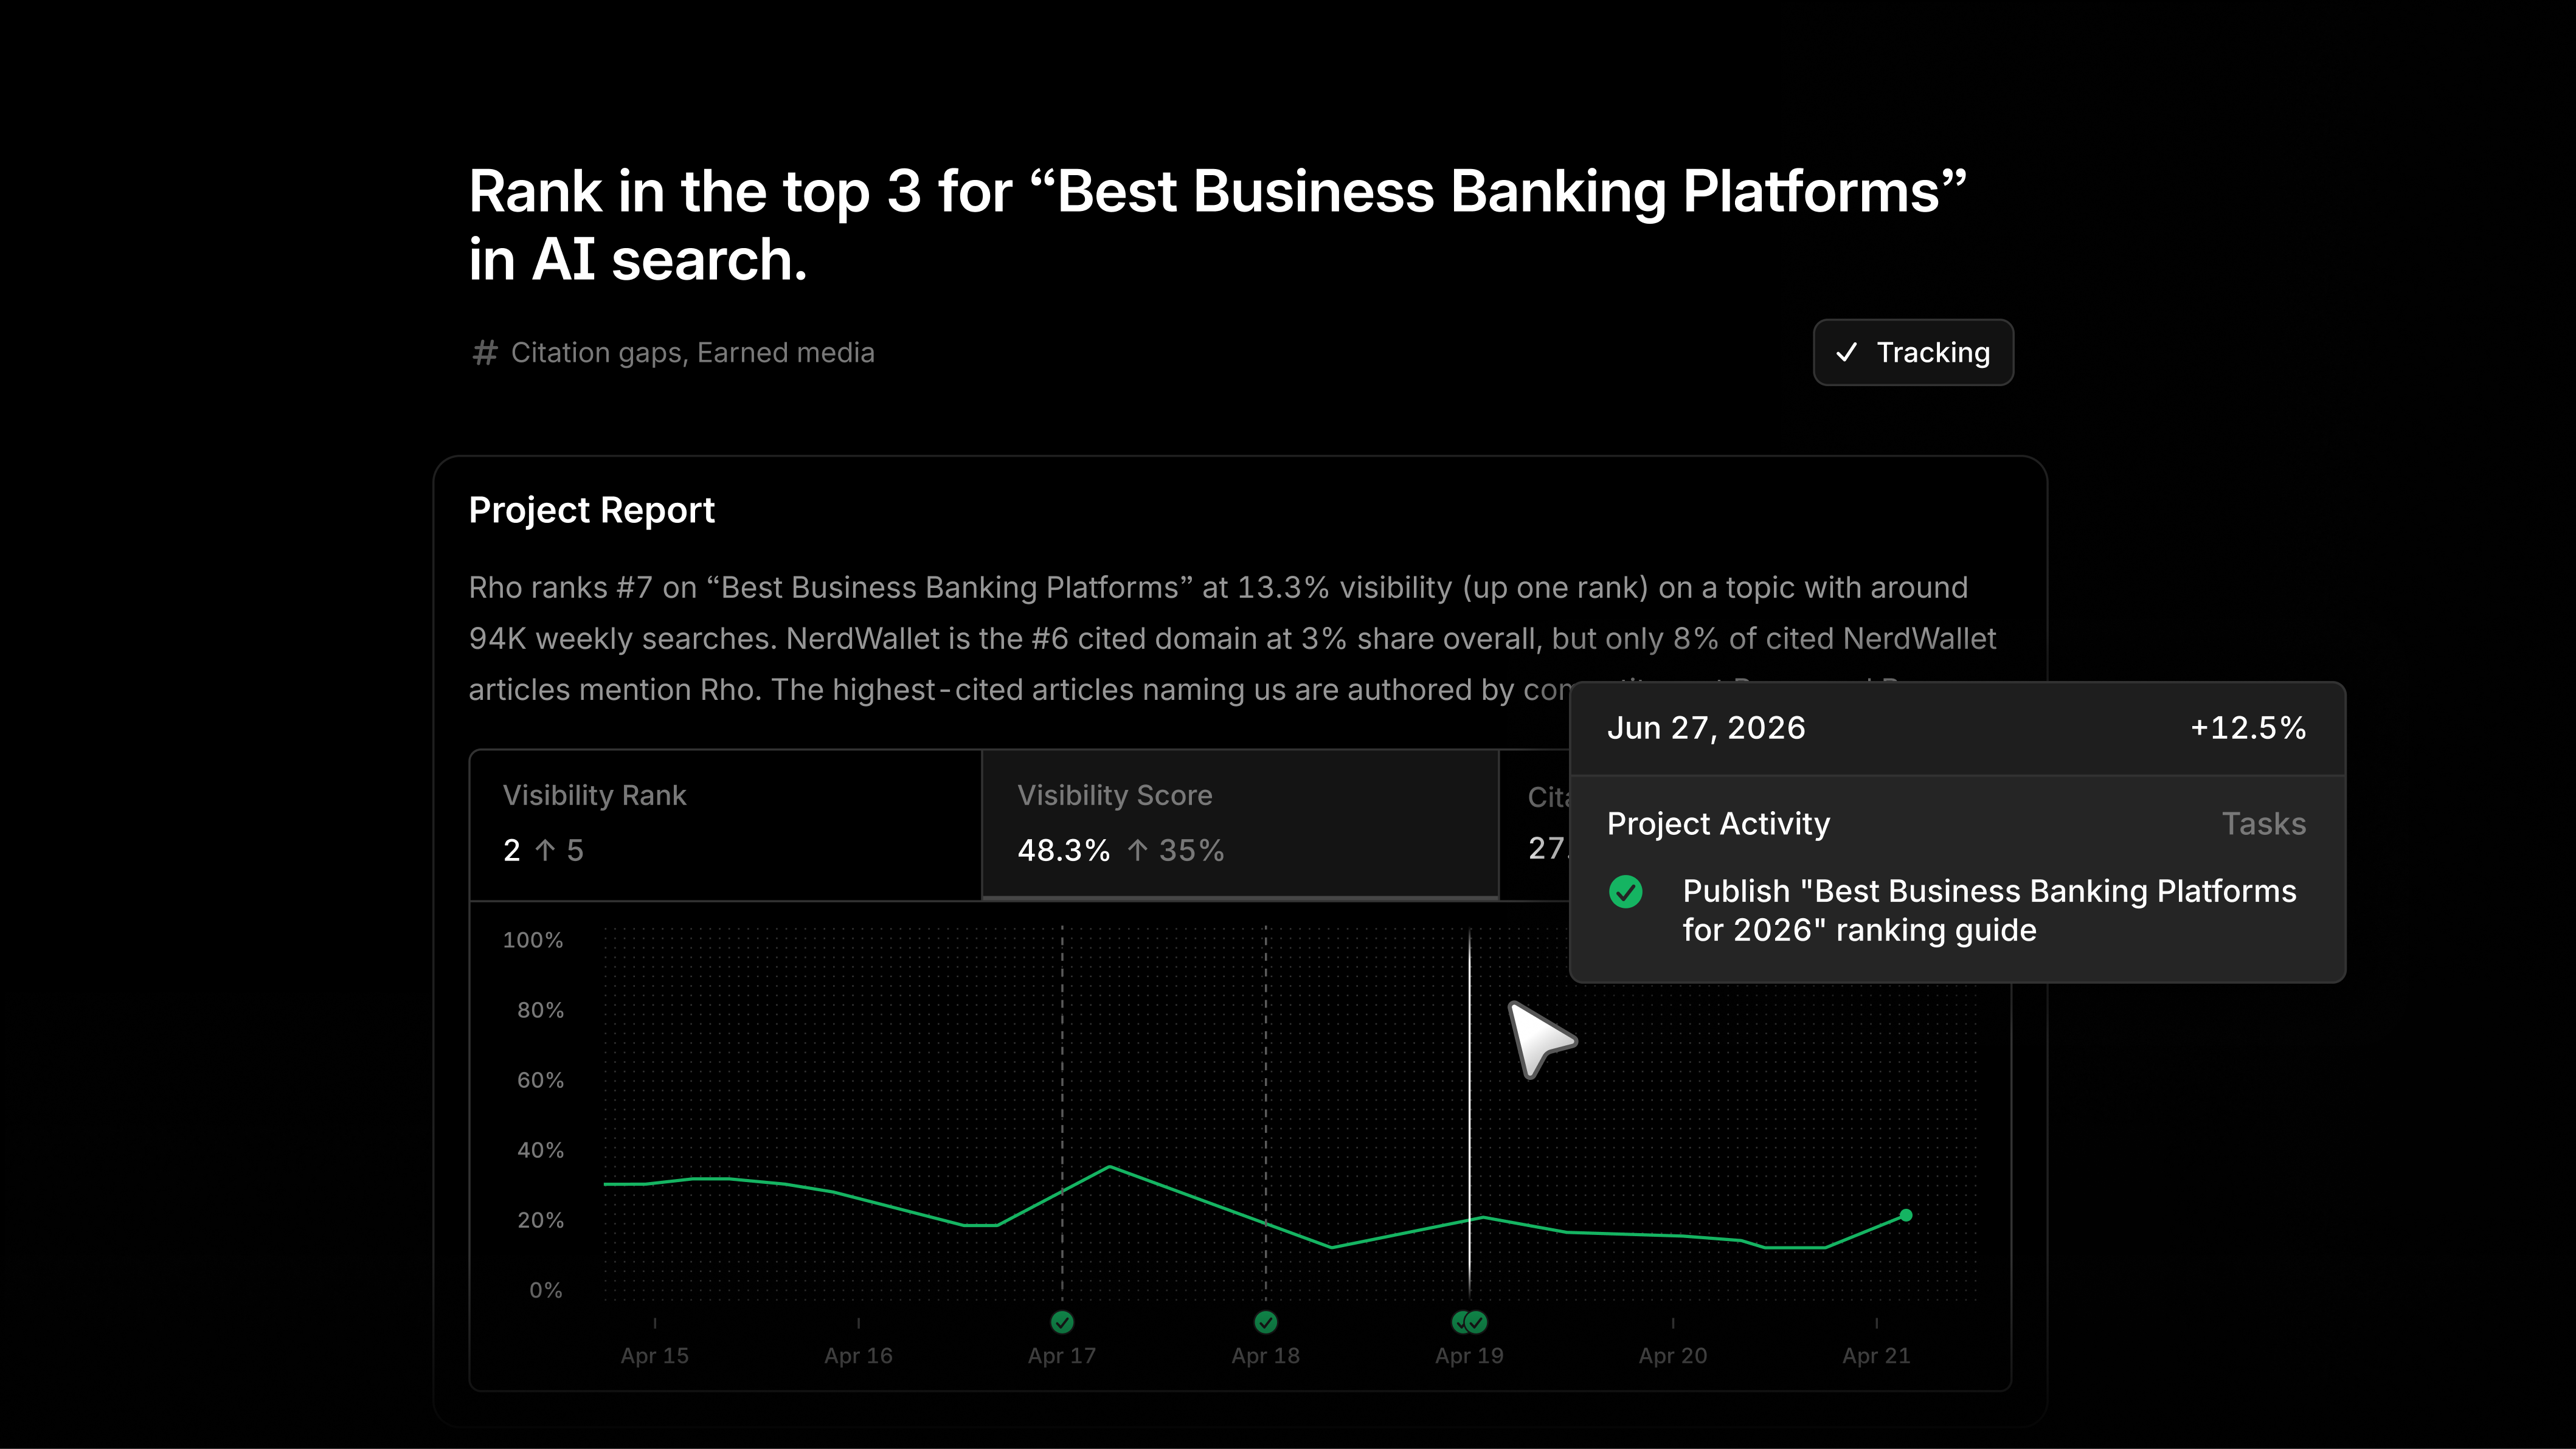
    With Projects in Profound, I can turn my AEO data into a clear, ranked list of opportunities instead of another report I have to interpret from scratch.

    Each opportunity is broken into practical tasks, with an agent ready to help do the work. That makes it easier for me to move from insight to execution without getting stuck in endless analysis.

    For me, Projects is about spending less time deciding what to do next and more time acting on the opportunities that can improve visibility, performance, and momentum.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • Profound Agent Templates: Launch AI Workflows Faster

    Profound Agent Templates: Launch AI Workflows Faster

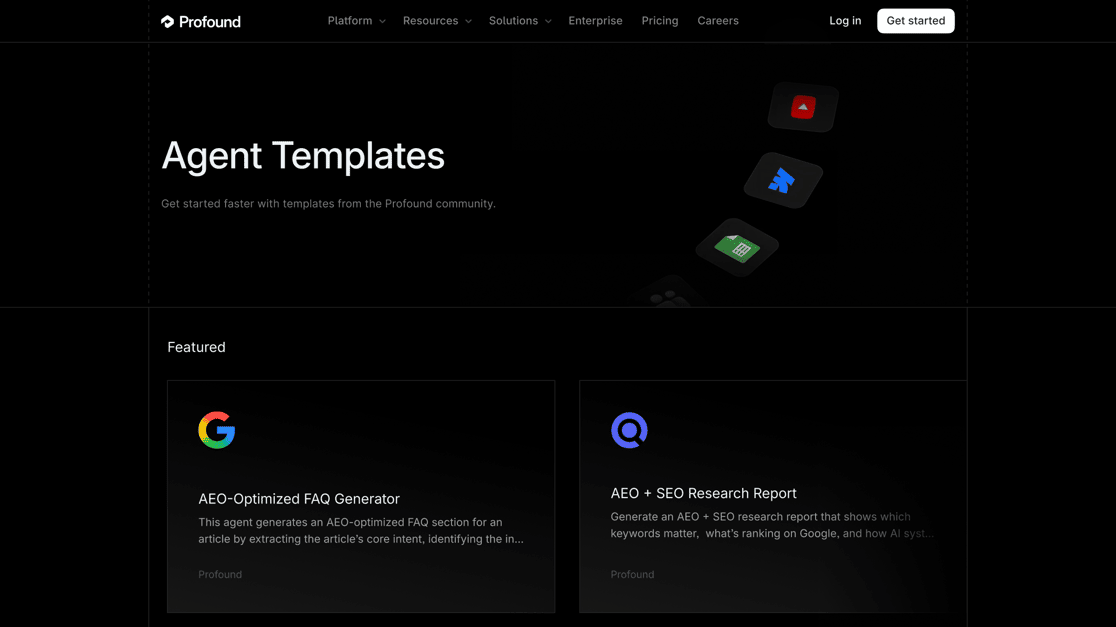
    With Profound’s Agent Template Marketplace, I can start from pre-built AI agent workflows instead of building every process from scratch.

    It gives me ready-to-clone templates designed for marketing, SEO, and AEO teams, so I can move from idea to live workflow in minutes.

    For me, the biggest advantage is speed: I can choose a proven workflow, clone it, customize it for my team, and start using AI agents faster with less setup.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot