Tag: AI Agents

  • Human Factors That Make Agentic AI Deployments Work

    Human Factors That Make Agentic AI Deployments Work

    Your agent can draft pages, change metadata, select audiences, trigger campaigns, and coordinate customer journeys. The hard question isn’t whether it can perform those actions. It’s whether it should be allowed to perform each one without stopping for a person.

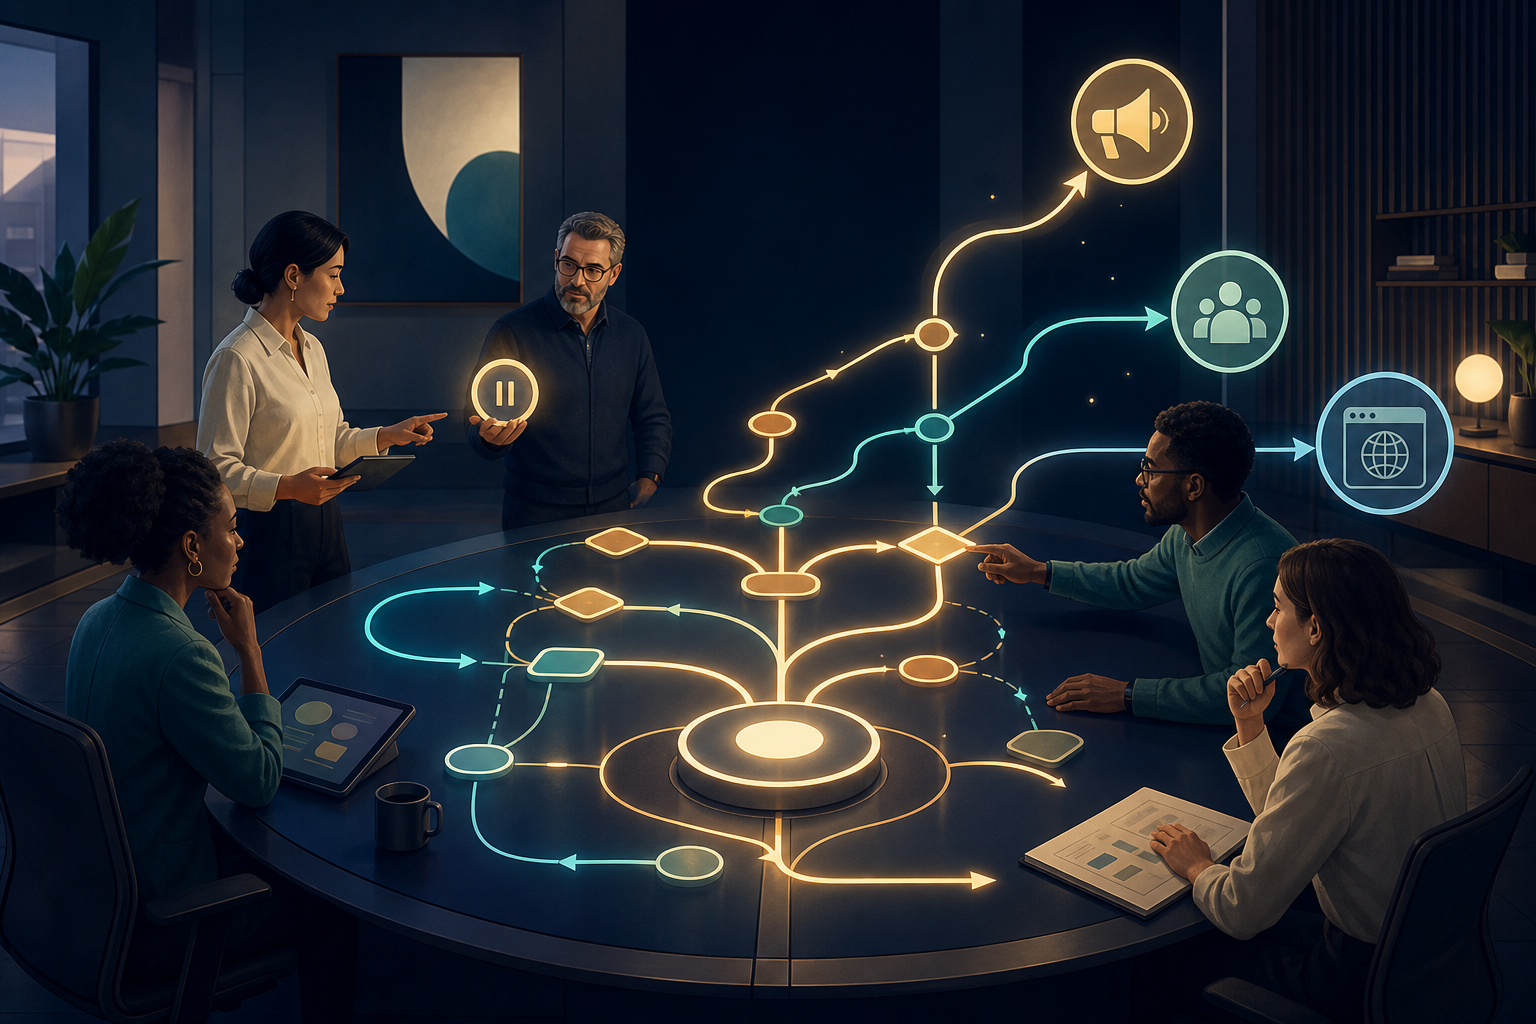
    If you’re deciding how much autonomy to grant, treat the deployment as an operating-model decision rather than a software installation. Define who owns the outcome, which actions require approval, how people will detect a bad decision, and how they can stop or reverse it. Those human controls determine whether the agent produces useful leverage or merely executes mistakes faster.

    Start with a decision, not an AI agent

    Agentic AI projects often begin with a capability demonstration: the system can plan a campaign, create content, update a workflow, or act across several tools. A convincing demonstration doesn’t establish that the workflow is worth automating or safe to delegate.

    The warning is concrete. Gartner expects more than 40% of agentic AI projects to be canceled by the end of 2027. The projection, based on more than 3,400 organizations investing in the technology, points to unclear value, weak governance, and hype-led experimentation rather than a simple lack of technical capability. Treat that percentage as a forecast, not a settled outcome, but don’t miss the operational problem behind it.

    Before you select a product or build an agent, write a decision brief for one workflow. It should answer these questions:

    • What outcome changes? Name the business result, not the AI activity. “Reduce the time required to prepare a technically reviewed content brief” is an outcome. “Use an agent for briefs” is not.
    • What does the workflow look like now? Record its inputs, decisions, handoffs, failure points, review work, and final action. Otherwise, you won’t know whether the agent improved the process or merely moved effort into supervision and repair.
    • Which judgment is scarce? Separate repetitive coordination from decisions that depend on audience knowledge, brand context, ethics, or commercial priorities. Automating the former may create capacity. Hiding the latter inside a prompt creates unmanaged risk.
    • What evidence would justify continuation? Choose outcome, quality, intervention, and recovery measures before launch. A pilot without an exit rule tends to survive because it exists, not because it works.
    • Who can stop it? Assign a named operational owner with authority to pause actions, narrow scope, and require remediation.

    This brief also protects you from “agent washing.” A conventional chatbot or fixed automation shouldn’t be purchased as an autonomous agent simply because the label changed. Ask the vendor or internal team to demonstrate the operating loop: what the system observes, which choices it makes, what it can change, how it checks the result, when it stops, and when it escalates. If every meaningful path was predetermined, you may still have useful automation, but you don’t have the adaptive autonomy the name implies.

    For an SEO or GEO workflow, make the distinction visible. An agent that recommends schema corrections is materially different from one that edits production markup. An agent that identifies possible internal links is different from one that publishes them. An agent that proposes a redirect is different from one that changes routing. Evaluate the authority being granted, not just the sophistication of the output.

    Design human control before you grant autonomy
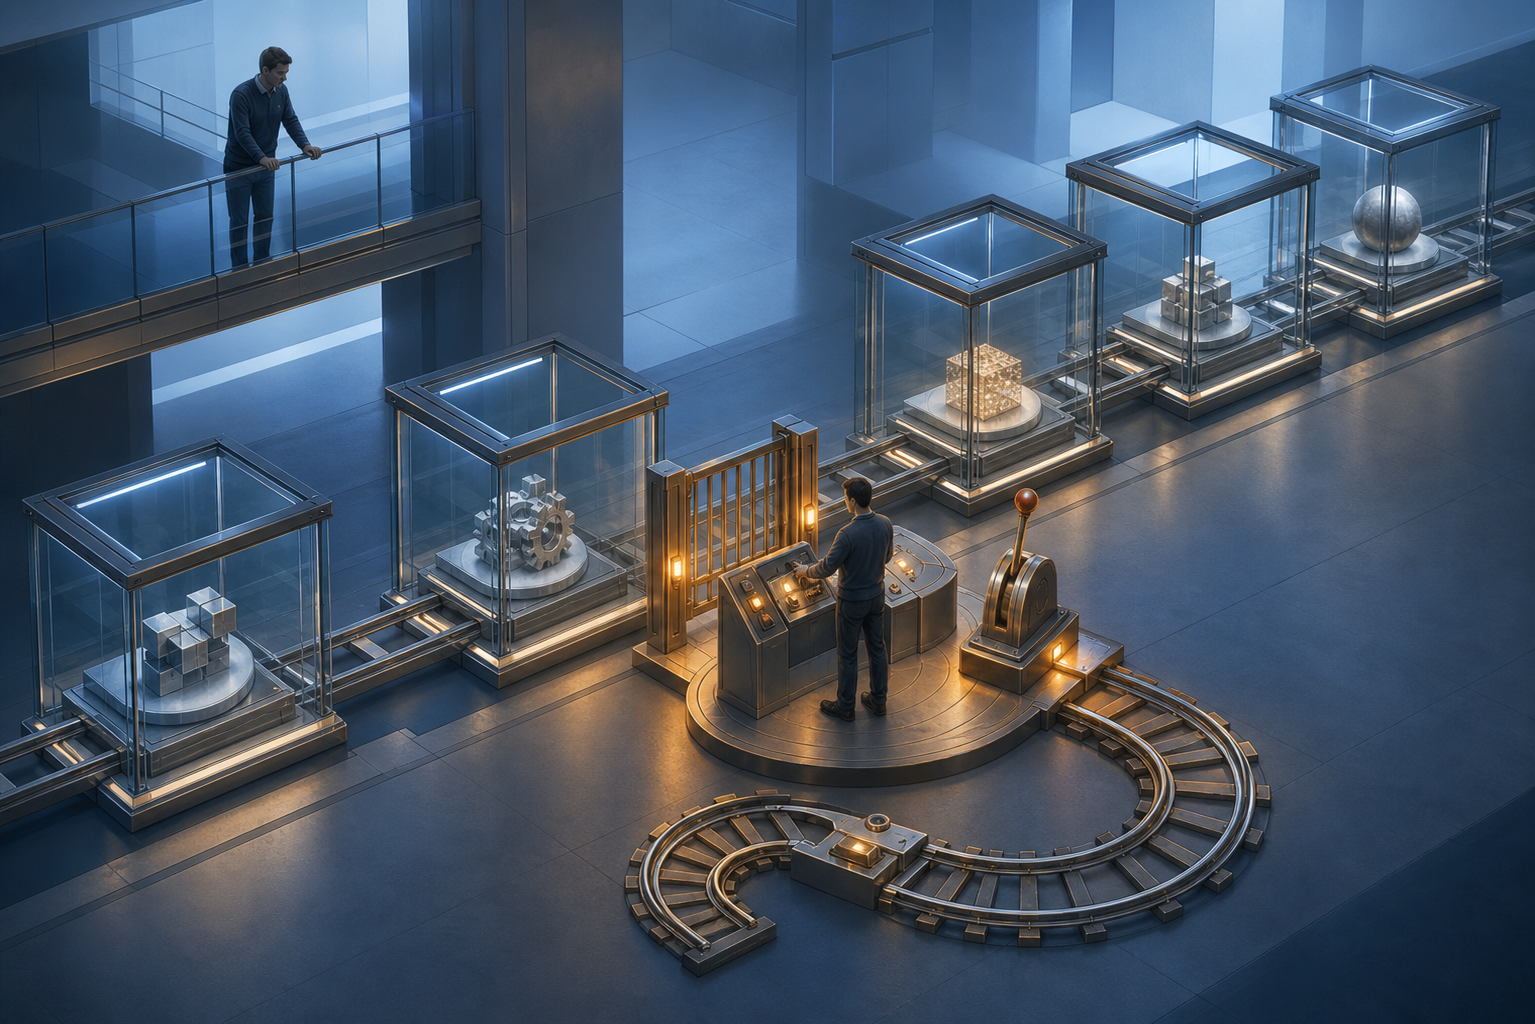
    Two operators oversee a modular automated workflow equipped with an approval gate, a pause lever, and a track that can reverse direction.

    “Human in the loop” is too vague to serve as a control. A person can technically appear in a workflow while lacking the context, time, authority, or evidence needed to catch a problem. Effective oversight specifies the decision rights on both sides of the human-agent boundary.

    Classify every action the agent may take using four practical questions:

    • Can it be reversed? Saving a draft is easy to undo. Sending a customer message, changing access, publishing an unsupported claim, or allowing a damaging URL change to propagate may not be.
    • How wide is the impact? A suggestion affecting one draft has a smaller blast radius than a template change affecting thousands of pages or an audience rule applied across campaigns.
    • How much context does the decision require? Stable rules are easier to delegate than choices involving brand nuance, conflicting evidence, unusual customer circumstances, or several acceptable outcomes.
    • Will failure be visible quickly? A malformed output may be obvious. A plausible but strategically wrong recommendation can remain unnoticed while it influences content, spend, or customer treatment.

    Use the answers to assign authority. Reversible, narrow, observable actions with clear rules are reasonable candidates for bounded autonomy. Irreversible, broad, ambiguous, or slow-to-detect actions should require approval or remain human-owned. Don’t use one autonomy setting for the entire workflow.

    ControlQuestion it must answerEvidence to retain
    Named ownerWho is accountable for the business outcome and failure response?Owner, backup, authority, and escalation route
    Scope boundaryWhich systems, records, audiences, and actions may the agent touch?Allowlist, denied actions, and permission configuration
    Approval gateWhich conditions force a person to decide?Trigger, reviewer, required context, and decision record
    Stop controlHow can a person halt new actions without waiting for the agent?Pause procedure, access owner, and confirmation that execution stopped
    Recovery pathHow will the team contain and reverse a bad action?Rollback method, affected-system inventory, and notification route
    Audit trailCan reviewers reconstruct what the agent knew, chose, and changed?Inputs, retrieved context, proposed action, approval, execution result, and exceptions

    The audit trail needs to capture more than generated text. Store the context used for the decision, the action requested, the tools called, the result returned, any human intervention, and the final system state. A polished explanation generated after the event isn’t a substitute for an execution record.

    Approval interfaces deserve the same care. Don’t ask a reviewer to click “approve” after showing only the agent’s preferred answer. Show the original input, relevant constraints, proposed change, affected assets, uncertainty or missing information, and available alternatives. Make rejection and escalation as easy as approval. Otherwise, the interface quietly trains people to accept.

    For content and search operations, require explicit review before actions such as publishing factual claims, changing canonical directives, modifying crawl controls, issuing broad redirects, altering product or business data, sending outreach, or communicating with customers. Your exact gates should reflect your systems and risk, but the rule is stable: the person must intervene before the consequential action, not after the impact appears in analytics.

    Increase autonomy only after the workflow becomes observable
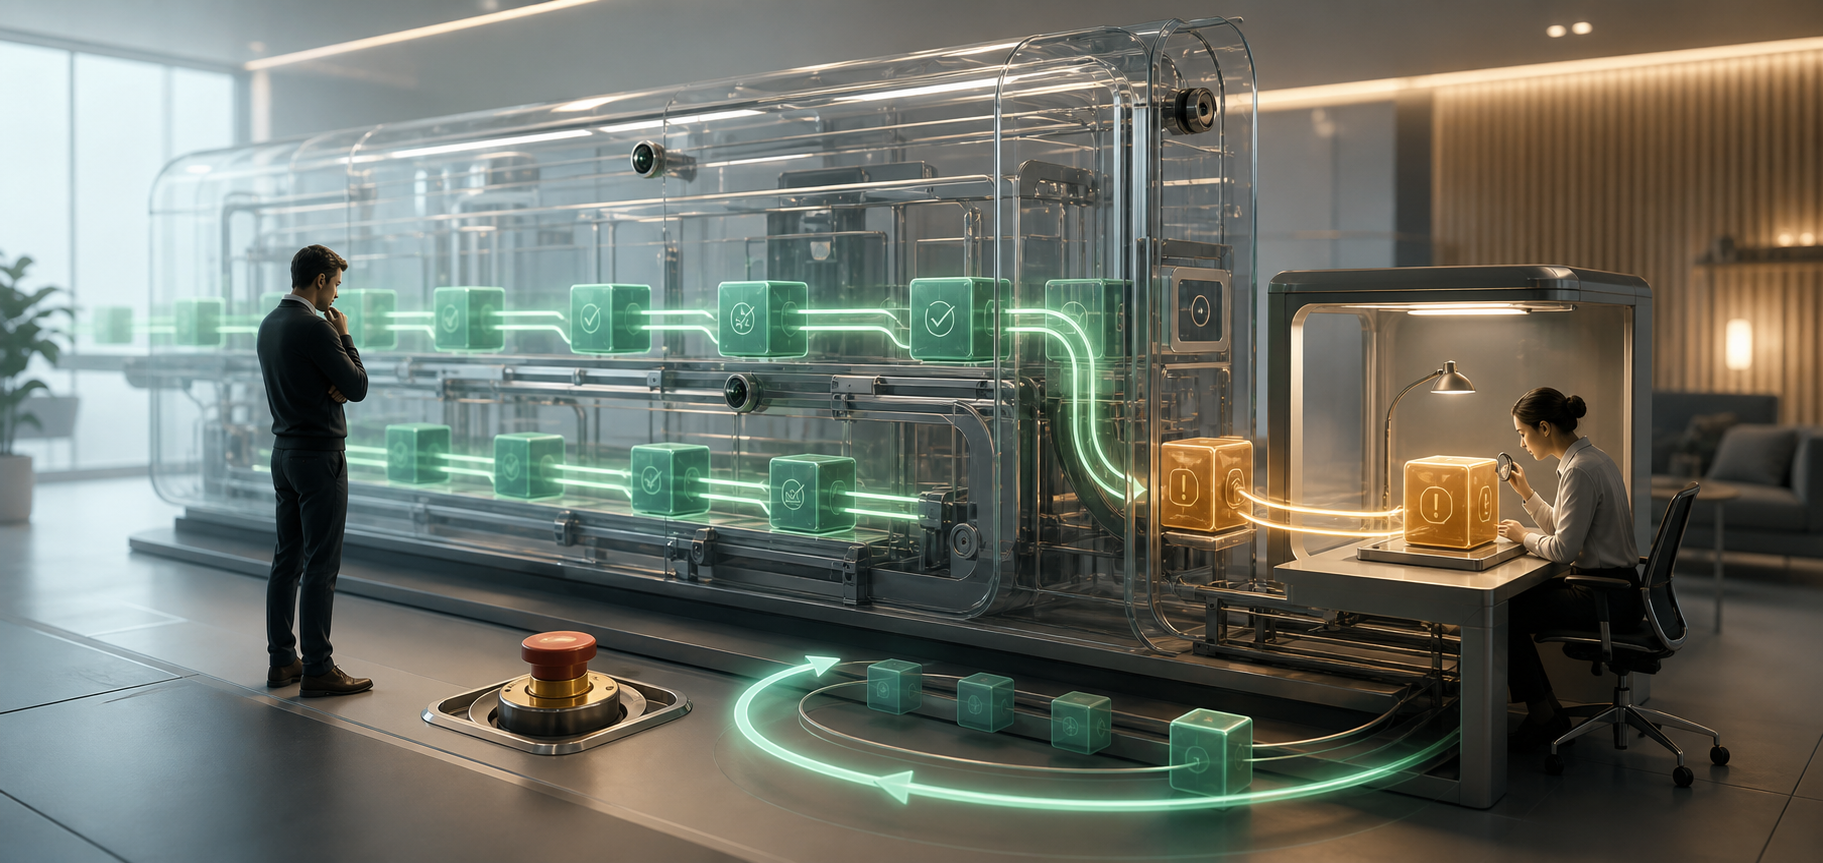
    Analysts monitor tasks moving through a transparent automated system while an unusual task is diverted into a separate human review bay.

    A pilot should test the complete operating system around the agent. Testing only whether the model can produce a good answer leaves permissions, handoffs, monitoring, escalation, and recovery unexamined.

    Move through these modes in order:

    1. Shadow mode: Let the agent observe real inputs and record what it would do, but prevent external actions. Compare its proposed decisions with actual outcomes and inspect where its context is incomplete.
    2. Advisory mode: Let it recommend actions to a responsible operator. Record approvals, edits, rejections, escalation reasons, and the time required to review. Heavy correction is evidence that the workflow or context is not ready for autonomy.
    3. Bounded action mode: Allow a defined set of reversible actions within an allowlisted scope. Keep consequential actions behind approval gates and enforce a direct stop mechanism.
    4. Expanded autonomy: Broaden authority only when the existing scope produces acceptable outcomes, exceptions are understood, logs support investigation, and the team can demonstrate recovery.

    Promotion between modes should be an evidence decision. Don’t advance because the pilot deadline arrived or because a successful demonstration created executive enthusiasm. Review routine cases, edge cases, ambiguous requests, missing-data situations, conflicting instructions, permission failures, and attempts to push the agent beyond its assigned scope.

    Measure the deployment across four layers:

    • Outcome: Did the workflow improve the business result named in the decision brief?
    • Quality: Were outputs accurate, complete, on-brand, appropriately sourced, and suitable for the intended audience?
    • Control: How often did people edit, reject, stop, or escalate an action, and why?
    • Recovery: Could the team identify affected assets, contain the problem, restore the correct state, and learn from the failure?

    Don’t optimize the intervention rate toward zero. A falling rate can mean the system improved, but it can also mean reviewers stopped looking carefully. Read intervention data alongside sampled quality checks, downstream outcomes, and exception reports. The useful question is whether human attention is landing on the decisions where it changes the outcome.

    FOMO creates pressure to skip this progression and move directly from demo to production. That pressure is especially dangerous when an agent can act at campaign or site scale. Speed comes from making the safe path repeatable: clear permissions, reusable evaluation cases, reliable logs, tested rollback, and known escalation owners.

    Protect human judgment and customer trust as operating assets

    An agent’s output can look coherent even when its recommendation is unsuitable. That makes reviewer competence part of the control environment. If the person approving an action can’t recognize a strategic, factual, or ethical error, the approval step is ceremonial.

    One projection expects half of organizations to reassess their competencies as reliance on AI threatens critical thinking. You don’t need to reject automation to respond. You need to keep the relevant judgment active.

    • Require a reason for consequential approvals. The reviewer should identify why the action fits the goal and constraints, not merely confirm that the output reads well.
    • Keep people capable of performing the underlying task. Rotate qualified operators through manual cases and exception handling so the team retains a working model of what good looks like.
    • Separate creation from high-impact approval. The person who configured or champions the agent shouldn’t be the only person judging its production readiness.
    • Review disagreements, not just errors. Repeated edits and rejected recommendations reveal missing context, unclear policy, or a task that requires more human judgment than expected.
    • Run post-incident reviews around the system. Examine instructions, data, permissions, interface design, workload, escalation, and incentives. Telling reviewers to “be more careful” leaves the mechanism intact.

    Customer trust needs its own controls. A related forecast warns that poorly applied agentic AI could damage customer relationships by 2026. The risk isn’t limited to obviously nonsensical responses. An agent can send a polished message to the wrong person, apply a reasonable rule at the wrong moment, or take an authorized action that conflicts with the customer’s circumstances.

    Map each customer-facing action to an identity, authority, and escalation rule. The customer should be able to tell what happened, correct wrong information, reach a person when the automated path is unsuitable, and receive a clear resolution when an action causes harm. Internally, the team should be able to identify which agent acted, under whose authority, using what information.

    Brand alignment can’t live only in a long prompt. Translate it into reviewable policies: prohibited claims, evidence requirements, tone boundaries, audience exclusions, escalation topics, and actions the agent may never take. Give each policy an owner and a process for change. That turns “use good judgment” into controls a team can inspect.

    Key takeaways

    • Begin with one defined business decision and its current workflow, not a general mandate to deploy an agent.
    • Evaluate actual autonomy by inspecting what the system observes, decides, changes, verifies, and escalates.
    • Grant authority action by action. Reversibility, impact, ambiguity, and observability should determine where people intervene.
    • Test in shadow, advisory, bounded-action, and expanded-autonomy modes, with evidence required before each increase in authority.
    • Retain execution logs, explicit stop controls, and tested recovery paths before the agent touches consequential systems.
    • Treat reviewer competence and customer escalation as core infrastructure, not training tasks to add after launch.

    Before your next agent demo, produce a one-page deployment contract for the workflow: outcome, owner, allowed actions, prohibited actions, approval triggers, stop mechanism, recovery path, and evidence required for more autonomy. If the team can’t agree on that page, the agent isn’t ready for broader access. Resolving those human decisions first is the shortest route to a deployment you can trust.
    References

  • Best-of-N AI Jailbreaking: Risks and Defensive Controls

    Best-of-N AI Jailbreaking: Risks and Defensive Controls

    You may have watched your AI assistant reject an unsafe request and concluded that its safeguards worked. If you tested only once, you answered the wrong question. An attacker does not need every prompt to succeed. They need one useful failure after enough retries.

    Best-of-N jailbreaking turns that model variability into a search process. To manage the risk, you need to evaluate the whole campaign, enforce permissions outside the model, and control every additional chance created by retries, fallback models, tools, and automated agents.

    The dangerous unit is the campaign, not the prompt

    A Best-of-N attack creates or collects multiple versions of a prohibited request, submits them to an AI system, and selects the response that comes closest to the intended outcome. The essential move is to send many variations and keep the most successful result. The value of N is not fixed, and the selection can be performed by a person, a script, or another model.

    This changes the security question. A per-request review asks, “Did this prompt get blocked?” A campaign-level review asks, “Did any related attempt produce a prohibited result?” The second question reflects the attacker’s objective.

    The probability principle is straightforward. If each attempt has a nonzero chance of crossing a boundary, repeated opportunities can raise the chance that at least one attempt succeeds. Under the simplified assumption that attempts are independent and have the same success probability p, the probability of any success after N attempts is 1 – (1 – p)^N. Real prompt variants are often correlated, so you should not use that formula as a production risk estimate. Measure complete campaigns against your actual system instead.

    Three distinctions prevent confusion during threat modeling:

    • A normal retry is usually an attempt to clarify a legitimate request after an incomplete or incorrect answer. Repetition alone does not establish malicious intent.
    • A jailbreak tries to bypass behavioral restrictions placed on a model.
    • Prompt injection supplies untrusted instructions that compete with the system’s intended instructions, often through user input or retrieved content. Best-of-N is a search strategy that can amplify jailbreaks, prompt injection, or other policy-evasion techniques.

    Treat Best-of-N as a threat multiplier, not as the root vulnerability. It finds inconsistent decisions and weak handoffs. It cannot grant a caller a permission that your application enforces deterministically outside the model. That is why authorization architecture matters more than clever safety wording.

    Where repeated attempts find extra chances

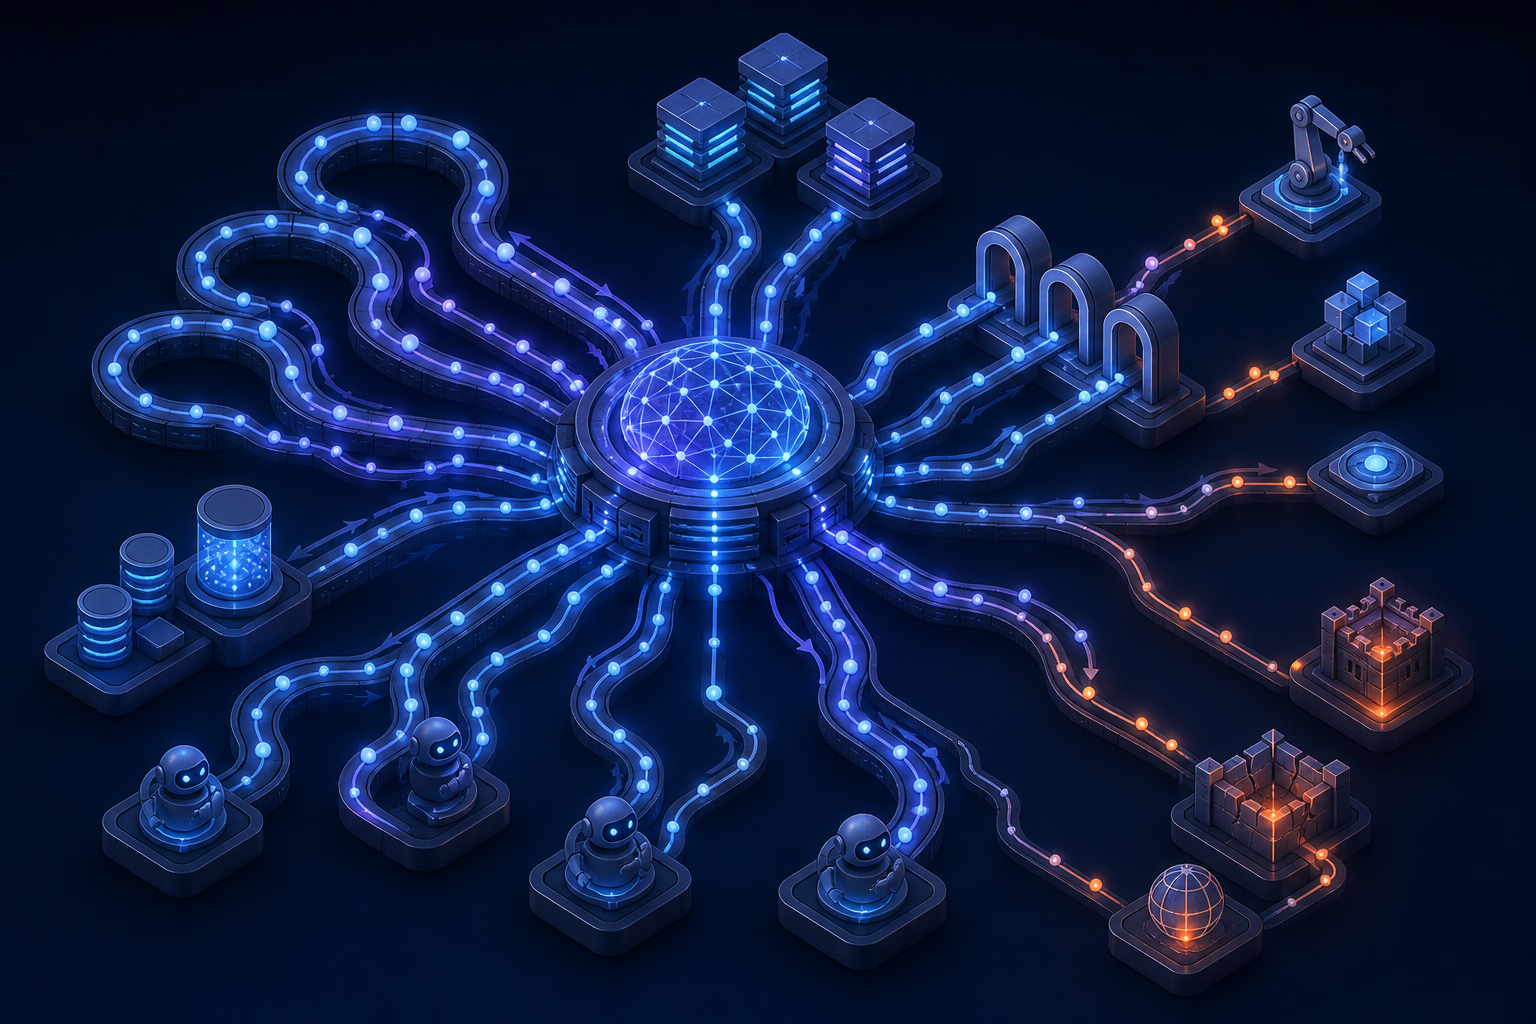
    An isometric AI network branches into retry loops, fallback nodes, tools, memory, and agent pathways carrying repeated request signals.

    Your model is only one part of the attack surface. A typical AI workflow also has an identity layer, input filters, a router, one or more models, output checks, retrieval, tools, and application code. Every component that makes a fresh probabilistic decision can give a campaign another route to success.

    LayerMisleading green lightCampaign signal to inspectStronger control
    Prompt policyOne prohibited request was refusedRelated requests are repeatedly rephrased after denialsAggregate policy events by actor, session, intent cluster, and protected resource
    Input moderationEach prompt remains below an individual alert thresholdSmall wording, format, language, or encoding changes accumulate around the same objectiveAnalyze normalized forms and sequences while retaining the raw input for investigation
    Model routingThe primary model refusedA fallback model, alternate endpoint, or retry path returned a different decisionApply one canonical policy before routing and a final gate after generation
    Tools and agentsThe assistant’s visible text looks harmlessA tool call requests a broader scope, sensitive record, or irreversible actionEnforce authorization, parameter validation, and action limits in application code
    Traffic controlsEach IP address or API key stays within its local limitRelated attempts move across sessions, keys, endpoints, or modelsCorrelate only the identifiers justified by your threat model, privacy obligations, and retention policy
    LoggingEvery prompt was stored somewhereNo record connects attempts, decisions, tool calls, and final outcomesAssign campaign and event identifiers so an investigation can reconstruct the sequence

    For an SEO, AEO, or GEO workflow, the highest-consequence result may not be a bad chat response. It may be an unauthorized CMS publication, a destructive edit, exposure of an unpublished campaign, or a tool call made with the application’s credentials. If a model generates page copy or JSON-LD, syntactic validation is necessary but insufficient. Valid structured data can still contain false, disallowed, or unapproved claims. Check the output against business rules and publishing permissions before it reaches a live page.

    Build controls that survive repeated attempts

    A request signal passes through layered security gates before reaching an AI core and protected tool mechanisms.

    No safety prompt can carry this responsibility alone. Prompts influence model behavior, but they are not security boundaries. Use several controls with different failure modes, and place deterministic checks wherever failure could expose data, spend money, alter content, or trigger an external action.

    1. Put authorization outside the model. Resolve the authenticated principal in application code, grant the least privilege needed for the workflow, and verify permission again when a tool executes. Never let generated text decide whether the caller may read, publish, delete, or export something.
    2. Separate read and write capabilities. An assistant that only needs to draft content should not inherit publishing or deletion rights. When write access is required, constrain the allowed resource, action, fields, and destination.
    3. Normalize for analysis without overwriting evidence. Retain the original request, then create a canonical representation for similarity detection. Normalization can help reveal superficial changes in spacing, character representation, formatting, or casing, but it must not silently change the content executed by downstream systems.
    4. Maintain campaign state. Record the actor or service identity, session, endpoint, model route, normalized intent cluster, policy decision, tool request, and outcome. Look for repeated denials, rapid reformulations, alternate-route probing, and requests that converge on the same protected capability.
    5. Add adaptive friction. As campaign risk rises, reduce retry opportunities, disable expensive fallback routes, introduce a cooldown, require stronger authentication, or move the request to human review. Apply the strongest friction to workflows with data access or irreversible effects rather than imposing the same response on harmless drafting tasks.
    6. Gate outputs and tool calls separately. Check generated content against the output policy, validate structured fields, reject unexpected tool names or parameters, and limit the records or resources returned. A harmless-looking explanation must not conceal a disallowed action request.
    7. Define safe failure behavior. If moderation, identity resolution, authorization, or final validation is unavailable, return a controlled error for protected operations. Do not route around a failed safeguard to preserve a smooth user experience.
    8. Protect the control plane. Restrict who can change system prompts, policy rules, model routes, tool definitions, and safety thresholds. Log those changes and make rollbacks possible, because a campaign can exploit configuration drift as readily as model variability.

    There is no universal safe retry count. A blanket limit low enough for a sensitive data-export agent may be needlessly hostile in a public brainstorming tool. Set budgets by consequence, then examine legitimate retry behavior before choosing enforcement thresholds. Track false positives alongside security outcomes so that users who are clarifying ambiguous, multilingual, or accessibility-related requests are not treated automatically as attackers.

    Be careful with model-based safety judges as well. A second model can add useful evidence, but it may share blind spots with the model it evaluates. Use deterministic authorization and validation for hard boundaries, with model judgments contributing to risk scoring rather than granting privileged access on their own.

    Test the full campaign without publishing an exploit kit

    A single-prompt red-team check will miss the defining behavior of Best-of-N. Your evaluation runner should group related attempts, preserve production routing logic, and score whether any attempt reaches a prohibited outcome. Keep testing authorized, isolated, and away from live customer data or publishing systems.

    1. Define the breach before generating tests. Describe prohibited outcomes in observable terms, such as returning a protected field, invoking a disallowed tool, publishing without approval, or producing content that violates a named policy. A vague label such as “unsafe response” produces inconsistent scoring.
    2. Build campaign families. Group sanitized test cases by underlying objective, then vary the permitted dimensions relevant to your system, such as phrasing, format, language, model route, and retry sequence. Keep actionable attack strings in an access-controlled security repository rather than general documentation or analytics dashboards.
    3. Reproduce the production topology. Include the actual order of input checks, retrieval, routing, fallback behavior, output gates, tools, and error handling. Testing the base model alone does not test the application your users can reach.
    4. Run attempts as connected sequences. Carry session and risk state between related requests. Also test whether switching endpoints or invoking an automated agent incorrectly resets that state.
    5. Score outcomes at two levels. Retain per-request decisions for diagnosis, but make campaign-level success the headline measure. A system can have an impressive individual refusal rate while still allowing too many campaigns to obtain one useful failure.
    6. Review the most consequential path first. A policy-breaching paragraph matters, but a tool call that exposes private data or changes a live site demands tighter controls and faster remediation.
    7. Version the evaluation and rerun it after changes. A new model, system prompt, router, retrieval source, guardrail, tool definition, or fallback rule can alter campaign behavior even when the visible feature appears unchanged.

    Your evaluation dashboard should include the campaign any-success rate, attempts to the first breach, breach severity, detection and containment outcomes, tool or data-boundary violations, and false-positive friction for legitimate users. Do not collapse these into one average. A small number of severe authorization failures should remain visible rather than being diluted by many harmless refusals.

    Stop a test immediately if it begins interacting with real user records, external recipients, paid services, or live publishing. Move the scenario into an isolated environment with synthetic data and inert tools. The purpose of the exercise is to verify containment, not to prove that production damage is possible.

    Key takeaways for AI product owners

    • One successful refusal does not establish safety; measure whether any attempt in a related campaign succeeds.
    • Best-of-N exploits repeated opportunities and inconsistent decisions, so retries, fallback models, alternate endpoints, and agents all belong in the threat model.
    • System prompts and model-based judges can support safety, but they cannot replace deterministic authentication, authorization, validation, and tool restrictions.
    • Aggregate related attempts without assuming every retry is malicious; calibrate friction to the consequence of the requested capability.
    • Test the production workflow as a sequence, then report campaign-level success and breach severity alongside per-request refusal metrics.
    • Keep security payloads controlled, use synthetic data and inert tools, and never red-team an external or production system without authorization.

    Before your next release, choose the AI workflow with the greatest access to data, tools, or publishing. Trace every place where a rejected request can receive another model call or another route. Then add campaign-level telemetry and a deterministic gate at the highest-consequence handoff.

    That review will not eliminate model variability. It will prevent variability from becoming permission.

    References


  • How to Prepare for Google Search as a Task-Completing Agent

    How to Prepare for Google Search as a Task-Completing Agent

    If your SEO strategy ends when somebody clicks a result, you are preparing for an older version of Search. A task-completing system may use your content to compare options, resolve constraints, choose a next step and initiate an action. Your page is no longer competing only to be read. It is competing to be useful inside a larger job.

    This does not mean abandoning rankings, traffic or conventional SEO. It means adding a second standard: can Google understand what your business offers, determine when it is appropriate and move a user toward a safe, verifiable outcome?

    The search result is becoming part of the workflow

    Traditional search usually separates discovery from execution. You search for information, open several pages, make sense of them and complete the task somewhere else. Agentic search compresses those stages. Google’s stated direction is for more information-seeking queries to become agentic, with Search coordinating long-running work and multiple concurrent threads.

    Think about a request such as, “Find accounting software suitable for a small Canadian consultancy, compare the plans and help me arrange a demonstration.” An ordinary results page can supply links for each part. A task-oriented system has to preserve the user’s requirements while it researches vendors, rules out unsuitable choices, explains trade-offs and hands the user into an action.

    That changes the unit of optimization. A keyword is one expression of demand. A task includes the desired outcome, the constraints, the decisions that must be made, the evidence needed to make them and the action that finishes the job.

    • Question: What does the user need to know?
    • Qualification: Which options fit the user’s location, situation, budget, timing or technical requirements?
    • Decision: What evidence separates an appropriate choice from an inappropriate one?
    • Action: What can the user book, buy, configure, submit or request?
    • Verification: How does the user know the action succeeded, and how can it be changed or reversed?

    People are already using AI Mode for deep-research queries that stretch beyond the old one-query, one-answer pattern. That is the immediate signal to act on. You do not need to predict every interface Google will release. You need to make your public information dependable enough to support a multi-step decision.

    Search and Gemini are also expected to coexist, overlapping in some uses while diverging in others. Do not reduce your plan to optimizing for one chatbot response. Your information may be encountered through a conventional result, an AI-generated answer, a research workflow or an action-oriented experience. The underlying facts should remain consistent across all of them.

    Optimize the complete task, not just its opening query

    An isometric workflow follows a user request through comparison, constraint checking, availability, verification, and a completed outcome.

    Start with one task that matters to your audience and your business. Avoid broad goals such as “learn about payroll” or “rank for payroll software.” Use an observable outcome: “Determine whether this payroll service supports my type of company and begin the correct signup process.”

    Then create a task map. This is more useful than a keyword cluster because it exposes the information gaps that can stop an agent or a person from proceeding.

    1. Write the outcome in the user’s language. State what will be decided or completed, not what content will be consumed.
    2. List the required inputs. Identify the details that change the answer, such as location, organization type, compatibility, eligibility, timing or service area.
    3. Break out the decisions. Record every choice the user must make before acting. A product tier, appointment type or implementation route may each require a separate decision.
    4. Assign evidence to each decision. Decide which page supplies the specification, policy, price, limitation, comparison or proof needed at that point.
    5. Define the action and handoff. Make clear where the user can start, what information will be requested and what happens after submission.
    6. Document failure and recovery paths. Explain what to do when the user is ineligible, an option is unavailable, a form fails or an action must be cancelled.

    The recovery path matters because task completion is not the same as pushing every visitor toward conversion. A reliable system must also recognize when your offer does not fit. If exclusions are buried in terms, an agent may recommend the wrong route and the user will discover the problem late. Put decisive limitations beside the claims they qualify.

    Next, label the role of every page in the task. One page may establish eligibility, another may compare options, another may explain a procedure and another may host the transaction. A page can serve more than one role, but each role should be explicit. If your team cannot agree on what a page contributes to the task, an automated system is unlikely to infer it reliably.

    Build pages an agent can interpret and use

    An agent-ready page is not a page written for robots. It is a page on which the decisive facts are clear, scoped and consistent. Good structure helps people and machines for the same reason: neither should have to reconstruct a critical condition from vague marketing language.

    Task layerWhat must be resolvedWhat to improve on the site
    IntentThe outcome the page supportsUse a descriptive title, a direct opening answer and a clear statement of who the page is for.
    QualificationWhether the offer fits the user’s constraintsState eligibility, locations, dependencies, exclusions and prerequisites beside the relevant offer.
    DecisionWhy one option should be chosen over anotherUse comparable attributes, defined terms and evidence tied to specific claims.
    ActionHow to begin or complete the next stepName the action precisely, disclose required inputs and explain what happens after it is submitted.
    VerificationWhether the action succeededProvide an explicit confirmation state, reference information and a route for correction or cancellation.
    Machine interpretationWhich entities and relationships the content describesUse accurate structured data that matches the visible page and the site’s canonical facts.

    Several practical rules follow from this model.

    Put the decisive answer before the supporting narrative

    If a service is available only in particular locations, say that near the service description. If a plan requires another product, state the dependency beside the plan. If the next step is a consultation rather than an immediate purchase, label it accurately. Do not make the reader decode “Get started” to discover what will actually happen.

    Turn implied knowledge into explicit facts

    Businesses often assume that visitors understand their terminology, market, service boundary or product hierarchy. An agent cannot safely rely on that assumption. Define ambiguous terms, attach units to measurements, give conditions to claims and distinguish facts about the company from facts about a particular offer.

    Consistency is more important than repetition. If a product name, service area, policy or plan description differs across a landing page, help page and checkout flow, decide which version is canonical and correct the others. Structured data should reflect that same version.

    Use JSON-LD as a factual layer, not a persuasion layer

    Choose Schema.org types and properties that match what is visibly present. Identify the organization, offer, product, service, person, place or event only when the page genuinely describes that entity. Connect related entities where the relationship is real. Keep names, URLs, identifiers and offer details aligned with the canonical content.

    Do not add unsupported properties because they look advantageous, and do not mark up claims that a visitor cannot verify on the page. JSON-LD can make a fact easier to interpret; it cannot turn an incomplete, stale or contradictory claim into a trustworthy one.

    Design the action boundary deliberately

    Research and execution carry different risks. Reading a comparison is low commitment. Sending personal information, placing an order or booking an appointment is not. If your task ends in an action, make the commitment point unmistakable.

    • Show what will be submitted or purchased before confirmation.
    • Separate required inputs from optional ones.
    • Display material conditions before the final action, not only after it.
    • Explain whether the action is immediate, pending review or merely a request.
    • Provide a correction, cancellation or support route where the action permits one.
    • Return a clear success or failure state instead of leaving the user to infer the result.

    These are conversion fundamentals, but they become more important when software may coordinate the handoff. Ambiguous buttons, silent form failures and hidden conditions do not merely reduce conversion. They make the task unsafe to delegate.

    Audit task readiness before agent traffic becomes measurable

    A digital inspection agent scans the modular elements of a webpage while a human specialist supervises from a control station.

    You may not be able to isolate every agent-assisted visit or decision in your reporting. You can still measure whether your site is ready to participate. Treat readiness as a content, data and workflow quality problem.

    Use a simple zero-to-two audit for each important task. This is a prioritization method, not a search-engine score:

    • 0 — Missing or contradictory: the task cannot proceed without guessing, or two public pages give incompatible answers.
    • 1 — Inferable: the answer exists, but the user must combine pages, interpret vague wording or uncover a condition late.
    • 2 — Explicit and usable: the answer is clear, appropriately qualified, current and connected to the correct next step.

    Score the task across six dimensions: outcome definition, qualification facts, decision evidence, action path, confirmation or recovery, and measurement. Do not obsess over the total. A zero in any dimension identifies a broken link in the workflow and deserves attention before cosmetic content changes.

    Run the audit from the public site, without internal knowledge. Give a team member the task and its constraints. Ask them to find the right option, explain why it fits, begin the action and identify how they would reverse or correct it. Record every point where they have to guess. Those guesses become your content and workflow backlog.

    Measure the workflow in stages so a completed task is not reduced to a pageview:

    • Discovery: Did the relevant landing page become visible for the task?
    • Qualification: Did the visitor reach the eligibility, specification, policy or comparison information needed to proceed?
    • Action: Did the visitor start and complete the intended form, booking, configuration or transaction?
    • Failure: Where did validation errors, unavailable options or unclear requirements stop progress?
    • Outcome quality: Did the action lead to confirmation, or did it create cancellations, corrections and avoidable support work?

    This measurement model also protects you from a misleading success signal. More action starts are not helpful if users are being routed into an unsuitable option. Pair completion data with failure, cancellation and correction data so you can distinguish task volume from task quality.

    Key takeaways

    • Optimize for a defined user outcome, not only the keyword that begins the journey.
    • Map qualification, decision, action and verification as separate stages, then assign each stage to reliable public information.
    • State decisive constraints beside the claims they limit. Do not hide eligibility, dependencies or exclusions at the end of the path.
    • Keep visible content, structured data and transactional interfaces consistent about the same entities and offers.
    • Treat confirmation, correction and cancellation as part of task completion, not as support details.
    • Audit every task for missing or contradictory information before trying to infer performance from agent-specific traffic.

    Choose one commercially important task this week. Write its outcome, inputs, decisions, evidence, action and recovery path on a single page. Then follow it through your public site and fix the first place where a user has to guess. That work will improve the experience now, while giving agentic Search cleaner material to use as it moves from answering questions toward completing jobs.

    References

  • Is Your Website Ready for AI Agents? A Practical Audit

    Is Your Website Ready for AI Agents? A Practical Audit

    You can have a fast, attractive website that still leaves an AI system guessing. A person may work around a price that appears late, two conflicting policy pages, an unlabeled button, or a confirmation shown only through a visual change. A machine may stop, cite the wrong fact, or repeat an action because it cannot tell whether the first attempt worked.

    The goal is not to rebuild your site for bots at the expense of people. It is to make public information retrievable, meaning explicit, and actions safely bounded. That is the practical response to the shift toward machine-led website visits. This audit shows you where to look and what a passing result should look like.

    Audit the journey, not the bot name

    Agent readiness is broader than allowing a particular crawler through robots.txt. An AI search system may retrieve a page to answer a question, compare facts across pages, send a person to a landing page, or help a signed-in user complete a task. Each journey fails differently.

    Start with the intent that matters, then follow it from request to outcome. Choose priority journeys from three groups: finding an answer, making a decision, and taking an action. Write the expected result before you test so that a plausible but incorrect response does not pass by accident.

    JourneyWhat the machine needsWhat failure looks like
    Answer or citeA public, stable page with a direct answer and enough context to interpret itThe answer is absent from the retrieved HTML, buried in an image, or contradicted elsewhere
    Compare and decideConsistent names, identifiers, attributes, prices, conditions, and limitationsThe same offer has different facts across the page, structured data, and linked policies
    Act and confirmClearly labeled controls, explicit prerequisites, bounded permissions, and a machine-readable resultThe agent cannot identify the correct control, understand an error, or confirm whether the action succeeded

    For each journey, name the authoritative page, the facts that must be preserved, the actions that are permitted, and the state that proves completion. This turns an abstract AI-readiness project into a set of testable requirements.

    Make important pages retrievable without guesswork

    A page is not agent-ready merely because it looks correct in your browser. Your browser may have cookies, cached scripts, a logged-in session, and enough processing time to assemble the page after the initial response. A fresh machine client may have none of those advantages.

    Test every priority URL from a clean, logged-out session. Inspect the returned HTML as well as the rendered screen. The page title, primary heading, main answer, relevant entity name, and essential links should be available without requiring a person to reveal them through hover effects, tabs, or visual-only controls. When a fact is central to the page, do not assume every client will execute and wait for the same JavaScript path as a full browser.

    • Confirm that the preferred URL returns a successful response and does not enter a redirect loop, soft-error state, consent loop, or challenge page.
    • Review robots.txt, meta robots directives, and the X-Robots-Tag together. An accidental conflict can make an otherwise public page unavailable. Robots directives are discovery instructions, not security controls, so private information still belongs behind real authentication.
    • Use one canonical URL for each primary resource. Internal links, canonical tags, redirects, and the XML sitemap should agree on that URL.
    • Keep the sitemap focused on live, canonical pages that you actually want discovered. Remove obsolete, redirected, private, and erroring URLs rather than asking machines to sort through them.
    • Link important pages through ordinary crawlable navigation. Descriptive link text such as “Enterprise pricing” carries more meaning than repeated links labeled “Learn more.”
    • Provide an HTML version of essential facts that otherwise live only in an image, video, downloadable document, or interactive widget.
    • Test firewall, bot-management, content-delivery, and rate-limit rules with a fresh client. Record whether a failure comes from the application or from an infrastructure layer in front of it.
    • Never weaken authentication to make an agent test pass. Keep protected data protected and expose only the public information or authorized interface the task genuinely requires.

    A useful retrieval record includes the requested URL, response status, final URL after redirects, declared canonical, applicable robots directives, and whether the required facts appeared in the response. A screenshot can confirm appearance, but it cannot replace those checks.

    Make the page’s meaning explicit in content and JSON-LD

    An abstract machine agent connects directly to a central web page shown in visible-content, semantic, and linked-data layers within an orderly site structure.

    Once a machine can retrieve a page, it still has to identify what the page describes and which claims belong together. Ambiguity usually enters through inconsistent naming, missing qualifiers, stale duplicates, and structured data that says something different from the visible page.

    Give each priority page a clear job. Put the direct answer near the point where the page establishes the question or offer, then supply the evidence, conditions, and alternatives a reader needs. Do not force the machine to combine fragments from a feature grid, tooltip, footer, and separate policy page just to understand the basic proposition.

    • Name the entity in full before relying on abbreviations or pronouns. If two products, locations, plans, or organizations have similar names, state the distinction on the page.
    • Attach qualifiers to the claim they modify. Geography, currency, billing period, eligibility, availability, effective date, tax treatment, shipping limits, and plan restrictions should not be left to implication.
    • Use stable identifiers where your operation already has them, such as a product code, plan name, location identifier, or internal service name. Keep the same identifier across templates, feeds, and structured data.
    • Choose an authoritative home for reusable facts such as the legal organization name, support contact, returns policy, or service-area definition. Other pages should link to or consistently reproduce that truth.
    • Update, redirect, remove, or clearly label stale pages. Two accessible pages that make incompatible claims create an interpretation problem even when only one appears in navigation.
    • Show ownership and maintenance information where it helps a reader judge the claim, such as an author, responsible team, publication date, or last reviewed date. Do not add decorative dates that are unrelated to a substantive review.

    Use JSON-LD to restate and connect meaning that is already visible. Select the most specific appropriate schema type for the resource, such as Organization, Product, Service, Article, or BreadcrumbList. Treat the type as a description of the actual page, not as a keyword target.

    • Make names, URLs, prices, availability, dates, and identifiers agree with the visible content.
    • Give important entities stable @id values and reuse those identifiers when another object refers to the same entity.
    • Connect related objects deliberately. An article’s publisher, a product’s brand, and a service’s provider should resolve to the organization you actually mean.
    • Include only properties you can support and maintain. An empty or guessed field adds ambiguity rather than clarity.
    • Validate syntax after template changes, then inspect the generated object for meaning. Syntactically valid markup can still describe the wrong entity or carry stale values.
    • Do not use structured data to make claims that a person cannot verify on the page. Markup cannot repair inaccessible, contradictory, or inaccurate content, and it does not guarantee inclusion in an AI answer.

    The final check is simple: read the visible page and the JSON-LD side by side. If they would lead a careful reader to different conclusions, the page is not ready.

    Treat agent actions as controlled transactions

    A transaction object passes through guarded verification, review, execution, and confirmation chambers while a duplicate action token is diverted into a holding loop.

    Retrieving a shipping policy is a read. Changing an address, booking an appointment, placing an order, publishing content, or deleting data is a write. Your design should preserve that boundary even when the same assistant handles both parts of the journey.

    Public facts should not require authentication without a business reason. Actions that expose personal data or change state should require an authenticated, authorized user. Do not create a machine-only shortcut around the permission model used by your human interface.

    • Use real links, buttons, and form controls with persistent programmatic names. An icon, color change, or visual position alone is not a dependable instruction.
    • Give every field a label and every validation failure an actionable message. State what is missing or invalid and preserve valid input so the task can continue.
    • Show prerequisites and consequences before submission. Required documents, inventory constraints, cancellation terms, units, time zones, and final charges belong before the committing action.
    • Require review or explicit user confirmation before consequential actions involving payment, publication, deletion, cancellation, or a binding reservation. Automation is not a reason to remove a safety boundary.
    • Make retries safe. If a client repeats a request after a timeout, the system should not silently create duplicate orders, bookings, messages, or records.
    • Return an unambiguous result after submission. The response should state whether the action succeeded, failed, remains pending, or requires another step, along with the relevant record or transaction identifier.
    • Keep errors distinct from success states. A generic page refresh, disappearing modal, or disabled button does not prove what happened.
    • Apply the least privilege needed for the requested task. Scope credentials, sessions, and connected tools so that a narrow action does not grant unrelated access.
    • Log enough context to investigate a failure or duplicate action, while avoiding unnecessary capture of personal data, credentials, or sensitive form contents.

    Test consequential paths in a staging environment or with a non-destructive mode whenever possible. If a production check could charge money, delete data, publish material, or create a real reservation, use an authorized test path rather than discovering the guardrails through a live transaction.

    Measure readiness from fetch to business outcome

    Referral traffic is useful, but it is not a complete AI-search scorecard. A system may use your information without sending a click, while a detected visit may still land on an inaccurate or unusable page. Keep the stages separate so you know which problem you are fixing.

    • Availability: Can a clean client retrieve the preferred page, and are canonical and robots signals aligned?
    • Comprehension: Can the required answer and its qualifiers be extracted from the visible content? Do the structured data and page agree?
    • Representation: Does a fixed set of relevant prompts produce an accurate description, mention, or citation on the AI surfaces you monitor? Record the prompt, surface, location or account context, date, output, and cited URL so later checks are comparable.
    • Referral: Which detectable AI referrals reach the site, where do they land, and do they engage with the intended next step? Treat missing referral data as unknown, not as proof that your content was never used.
    • Outcome: Do those visits or assisted journeys produce the qualified lead, completed task, sale, subscription, support resolution, or other result the page exists to support?

    Create a worksheet with a row for each priority intent. Include the authoritative URL, approved answer, required fields, expected entity, permitted action, passing condition, owner, last test date, observed output, and remediation status. A useful AEO system of record should show where performance is strong and why, not merely accumulate screenshots and isolated visibility scores.

    Establish a baseline before changing templates or access rules. Rerun affected journeys after changes to navigation, rendering, structured data, robots directives, authentication, forms, firewall policy, or core content. Keep the prompt and acceptance criteria fixed when you want a meaningful comparison; create a new test when the underlying intent changes.

    Key takeaways

    • AI-agent readiness has four practical layers: retrieval, interpretation, safe action, and measurement.
    • A passing visual check is not enough. Inspect the response, redirects, canonical, robots directives, rendered content, and required facts.
    • Visible content and JSON-LD must describe the same entity with the same claims, identifiers, and qualifiers.
    • Read access and write access need different controls. Consequential actions require authorization, confirmation, retry protection, and an explicit final state.
    • Measure fixed intents across availability, comprehension, representation, referral, and outcome instead of treating traffic as the whole result.
    • Technical readiness improves eligibility and reduces ambiguity, but it cannot guarantee ranking, citation, recommendation, or agent selection.

    Start with a revenue page, a policy page, and a consequential conversion path. Fetch them logged out, compare their visible facts with their JSON-LD, complete the permitted action in a safe environment, and record every point where the result becomes ambiguous. Fix those failures before expanding the audit across the rest of the site.

    References


  • How to Build Search Visibility for AI Agents and Answers

    How to Build Search Visibility for AI Agents and Answers

    You can rank in conventional search and still be absent when an AI system assembles an answer. The missing piece is often not another keyword. An agent has to reach your content, isolate the relevant passage, connect it to the right entity and decide that the claim is clear enough to reuse.

    Treat that sequence as a visibility pipeline. When you control access, extraction, delivery and measurement separately, you can diagnose why a page is missing instead of making broad content changes and hoping one of them works.

    Key takeaways

    • Set separate policies for model-training crawlers and agents that retrieve information for live answers. Blocking a vendor name broadly can block the function you actually want.
    • Make the core answer understandable in raw HTML, then use semantic sections and accurate structured data to reduce extraction ambiguity.
    • Keep titles, canonicals, essential metadata and critical structured data early in the HTML response. A page that renders correctly in your browser can still present an incomplete document to a crawler.
    • Use pull crawling for durable pages, push discovery for important updates, machine-readable delivery for structured facts and MCP access when an agent genuinely needs current data.
    • Measure bot access, extracted content, citation share and business outcomes as separate signals. Referral traffic alone cannot tell you whether generative visibility improved.

    Build a five-entry visibility pipeline

    Traditional search workflows often compress discovery, indexing and ranking into one mental model. Generative systems add retrieval, passage extraction, entity annotation and answer assembly. Your content can enter that process through five distinct routes.

    Entry routeWhat it doesWhere it fits
    Pull crawlingA crawler discovers and fetches a public URL on its own schedule.Evergreen pages, documentation, category hubs and other durable web content.
    Push discoveryYou notify a participating system that a URL is new or has changed.Pages whose value depends on being discovered soon after publication or revision.
    Push dataMachine-readable facts are delivered directly instead of relying only on page extraction.Structured catalogs, feeds and other data with a defined receiving system.
    MCP accessAn agent requests current information through a Model Context Protocol connection.Data that changes too quickly to be represented reliably by an occasional crawl.
    Ambient entryA system recommends or introduces information without a conventional explicit search query.Brand and entity discovery influenced by consistent, well-annotated information.

    These routes are complementary, not maturity levels. An evergreen explainer usually needs a clean crawl path more than an MCP server. A changing first-party dataset may need a direct machine interface because a cached page can become stale between fetches. Map each important content type to the least complicated route that preserves its accuracy.

    All five routes eventually depend on annotation: the system has to associate a fact with the correct organization, product, person, place or topic. That is why delivery alone is insufficient. Conflicting names, unclear ownership, inconsistent dates or schema that disagrees with visible copy can weaken the content after it has been successfully fetched.

    Separate training permission from live-answer retrieval

    The label AI bot hides several different jobs. The same provider may use one user agent for model training and another for retrieval or search. Current crawler distinctions include separate training, crawling and live-search identities:

    • OpenAI: GPTBot is associated with training, while OAI-SearchBot is associated with search and retrieval.
    • Anthropic: ClaudeBot is associated with training; Claude-User and Claude-SearchBot serve retrieval or search functions.
    • Perplexity: PerplexityBot is the crawler identity, while Perplexity-User is associated with user-driven searching.

    Decide what you want before editing robots.txt. For each user agent, record whether public editorial pages, product information, support documentation and downloadable resources should be accessible. Make the training decision independently from the retrieval decision. A company can decline training access while still choosing to make public pages available to a search-oriented agent.

    A narrowly scoped rule can look like this:

    User-agent: GPTBot
    Allow: /public/
    Disallow: /private/

    Do not use robots.txt to protect confidential information. It is a crawler directive, not an authentication system. Private, customer-specific and administrative content needs server-side access control whether a path is disallowed or not.

    After deployment, inspect server logs by user agent. Confirm that the intended crawler reaches the intended URLs, receives a successful response and can fetch resources needed to interpret the page. A syntactically tidy policy is not evidence that the access path works.

    Use llms.txt as a map, not a dependency

    The emerging llms.txt convention can give agents a concise map of important links, while llms-full.txt can aggregate larger amounts of text into one machine-oriented resource. Adoption is not universal, so neither file should be the only way to discover or understand your content.

    If you publish llms.txt, generate it from the same canonical content inventory used by your sitemap and navigation. Include public, authoritative URLs rather than every filtered, duplicated or campaign-specific variation. Keep the file synchronized when pages move or claims change. It does not override robots.txt, authentication, canonical signals or the content of the page itself.

    Make each page fragment-ready

    A digital page separates into modular content cards while an AI lens selects one card and links it to a network of entities.

    An agent rarely needs every sentence on a long page. It needs a passage that answers the current question without losing essential qualifications. Your job is to make that passage easy to locate and safe to reuse.

    Build each important section in this order: state the answer, name the entity it applies to, add the condition or limitation, then provide the supporting explanation. Put exceptions beside the claim they qualify. If a warning appears several sections later, extraction can separate it from the advice it was meant to constrain.

    • Use a descriptive heading that reflects the question or decision addressed by the section.
    • Answer immediately beneath that heading instead of opening with scene-setting copy.
    • Name the product, organization, method or audience inside the passage. Avoid relying on vague references such as it, they or this solution when the fragment could be retrieved alone.
    • Keep definitions stable. Do not alternate between near-synonyms if they could make one entity look like several unrelated entities.
    • Use lists for steps and criteria, and tables only when rows and columns express a real comparison.
    • Link supporting detail close to the claim it supports rather than collecting all evidence in an unrelated footer.

    Semantic HTML helps establish those boundaries. Use <article> for the primary work, <section> for coherent subtopics and <aside> for genuinely supplementary material. This does not guarantee selection, but it gives crawlers a clearer representation than a page composed entirely of generic containers.

    Structured data should agree with the visible page. Use the schema type that matches the content, identify the same entities named in the copy and omit properties you cannot support on the page. JSON-LD can reduce ambiguity; it cannot repair an unclear claim or turn unsupported markup into trustworthy information.

    Put critical information within the fetched bytes

    Payload order matters when a crawler stops before the document ends. Googlebot fetches up to 2MB for an individual non-PDF URL, with the HTTP response headers included in that limit. When an HTML response exceeds the threshold, the downloaded portion is passed to indexing and the Web Rendering Service as though it were the complete file. Bytes after the cutoff are not fetched, rendered or indexed. PDFs have a higher 64MB limit.

    The Web Rendering Service can fetch referenced resources separately and execute JavaScript like a modern browser, so external scripts and styles do not consume the parent HTML document’s byte allowance. That is a reason to remove oversized inline payloads, not a reason to hide the central answer behind unnecessary client-side execution.

    Do not generalize Google’s exact limits to every AI crawler. Use them as a concrete reminder that a page visible in your browser is not necessarily the same document a bot received or completed.

    • Inspect the raw server response as well as the rendered page.
    • Place the title, canonical link, essential meta tags and critical structured data early in the HTML.
    • Move large CSS and JavaScript payloads into external resources where appropriate.
    • Remove duplicated navigation, serialized application state and other bulky inline material that delays the primary content.
    • Verify that the central answer appears without requiring a click, expansion control or user-specific session.
    • Compare raw and rendered text so you know what depends on JavaScript.

    Response performance belongs in the same audit. When a server cannot deliver resources efficiently, fetchers may slow their activity to avoid adding load, which can reduce crawl frequency. Review latency alongside status and crawl counts instead of interpreting fewer requests as a content-quality judgment.

    Add push paths where freshness changes the answer

    Publishing and waiting remains reasonable for stable content, but it is incomplete when discovery speed or data freshness affects whether an answer is useful. Add proactive delivery in layers, after the public URL and its canonical content are sound.

    1. Preserve the pull foundation. Give every durable page a crawlable canonical URL, sensible internal links and an accurate sitemap entry. Push mechanisms should supplement this foundation.
    2. Notify systems about meaningful URL changes. Bing’s IndexNow can accelerate discovery by telling participating systems that content is new or updated. Treat the notification as an entry signal, not a substitute for a fetchable and interpretable page.
    3. Provide machine-readable data when a receiver supports it. Use a structured feed or direct data connection for facts that should not depend on extracting prose. Define one authoritative source so the feed and public page do not contradict each other.
    4. Use MCP for genuinely current interactions. An MCP connection is justified when an agent needs information that could become stale between crawls. Specify what each tool exposes, which fields are authoritative, how errors are represented and who may call it. Do not create an MCP layer merely to duplicate static editorial pages.
    5. Strengthen the inputs to ambient discovery. Keep names, descriptions and relationships consistent across your first-party content and machine-readable outputs. Ambient recommendations are not a submission box you can force; they depend on whether systems can confidently recognize and contextualize the entity.

    Use a freshness test when choosing the route: if an older value would make the answer materially wrong, evaluate direct data or MCP access. If the information remains accurate until the next normal crawl, keep the architecture simple and focus on extraction quality.

    Centralize the underlying data before adding several delivery methods. Otherwise a page, feed and agent tool can expose three different versions of the same fact. Faster delivery only makes that inconsistency spread sooner.

    Measure access, citations and outcomes separately

    Three parallel visual channels depict content access, citation connections, and human outcomes using abstract gateways, fragments, and symbols.

    A click-only dashboard cannot explain generative visibility. An answer may cite you without sending a visit, retrieve your page without using it or mention your brand while linking elsewhere. A practical GEO technical audit combines citation share, log analysis and zero-click behavior rather than collapsing them into one traffic number.

    • Access: Group server requests by user agent. Record which important URLs were requested, whether they were allowed, how the server responded and whether latency changed.
    • Extraction: Compare the raw response with the rendered page. Confirm that the answer, entity name, qualifications, canonical and structured data are present and mutually consistent.
    • Interpretation: Check whether headings, visible copy, schema and linked canonical resources describe the same entity and claim. Flag conflicting names, dates, ownership or status.
    • Visibility: Maintain a fixed set of representative questions. Citation share is the portion of checked answers that cite your domain or a tracked URL. Record the engine, model, query, cited page and claim so later checks remain interpretable.
    • Outcome: Track identifiable AI referrals and their business actions, but keep citations as a separate measure. No referral does not prove that the system ignored you; the generated answer may have satisfied the user without a click.
    • SEO context: Compare changes in AI visibility with domain metrics, backlink profiles, keyword research and organic-search data. This helps distinguish an agent-access problem from a broader authority, demand or search-performance problem.

    The combination of signals points to the next action. No crawler requests usually directs you toward discovery or access controls. Successful fetching with no usable passage points toward rendering or extraction. Clear extraction with weak citation presence points toward annotation, relevance or authority. More citations without more referrals may reflect zero-click use rather than failure.

    Keep the prompt set and measurement method stable while evaluating a change. If you replace the questions, engines and success definition at the same time, the before-and-after comparison cannot tell you which intervention mattered.

    Start with one content cluster tied to a real business or reputation goal. Verify crawler policy, raw HTML, semantic sections and structured data; then add IndexNow, a structured feed or MCP only where the content’s freshness requires it. Record access and citations before and after the change. Once that evidence chain works, make it part of the publishing workflow for every similar page.

    References


  • How to Measure AI Agent Traffic and Attribute Conversions

    How to Measure AI Agent Traffic and Attribute Conversions

    Your analytics dashboard may show a human arriving at checkout while missing the machine that found the product, compared the options, and initiated the journey. It may also show nothing at all when an agent completes an action without running your client-side analytics code.

    You can close that gap, but not with a new referral channel alone. Reliable AI agent attribution starts in server and CDN logs, continues through first-party action events, and ends with an attribution model that distinguishes direct execution from assistance and unlinked automation.

    Key takeaways

    • Measure AI agents at the HTTP request layer. A request that does not execute your analytics script cannot create a normal browser event.
    • Separate training crawlers, real-time retrieval systems, and task-performing agents. They represent different intent and should not share one conversion rate.
    • Do not trust a user-agent string by itself. Combine it with published network information, request behavior, authentication state, and your own event data.
    • Use distinct attribution states for agent-executed, agent-assisted, discovery-only, and unresolved activity. Do not force uncertain traffic into a conversion channel.
    • Instrument forms, account actions, carts, and orders on the server. Page requests show access; confirmed business events show outcomes.

    Classify traffic by the job the machine is doing

    An automated request is not automatically a prospective customer. A model-training crawler collecting material, an answer engine retrieving a current page, and an agent submitting a form can all request the same URL. Their commercial meaning is entirely different.

    This distinction matters because machine activity is growing faster than human activity. HUMAN Security measured more than a quadrillion interactions from 2022 through 2025. In that dataset, automated traffic increased 23.5% in 2025 while human traffic increased 3.1%. AI-driven traffic rose 187%, and activity associated with AI agents and agentic browsers rose by nearly 8,000%. Those figures come from aggregated, anonymized customer data, so treat them as a market signal rather than a forecast for your site.

    Traffic classLikely jobWhat to measureAttribution treatment
    Training crawlerCollect content for later model developmentPages fetched, bytes served, crawl frequency, response statusContent access, not a visit or conversion
    Real-time retriever or scraperFetch current information for an answer or comparisonLanding routes, freshness-sensitive pages, response success, repeat retrievalDiscovery activity unless a handoff can be observed
    Task-performing agentNavigate or take an action for a userWorkflow steps, authenticated state, form or cart events, confirmed outcomeDirect or assisted attribution when the evidence supports it
    Unverified automationUnknown, mislabeled, or potentially hostile activityBehavior pattern, network identity, rate, errors, security challengesKeep unattributed until verified

    Training crawlers still represented 67.5% of measured AI traffic, while real-time scrapers grew by nearly 600% in 2025. That mix explains why a large increase in AI-labelled requests does not necessarily produce leads or revenue. Start by assigning each request to a functional class; calculate commercial performance only for traffic capable of participating in a user journey.

    Task-performing agents deserve special attention because their behavior is moving deeper into sites. In 2025, 77% of observed agentic activity occurred on product and search pages, nearly 9% involved account-level interactions, and more than 2% reached checkout. If you monitor only editorial URLs, you will miss the requests closest to a business outcome.

    Create at least two classification fields in your data: agent_type for the machine’s apparent job and verification_status for the strength of the identification. Keep the values independent. A request can look transactional while its claimed identity remains unverified.

    Build an evidence chain from request to outcome

    A continuous glowing trail links an incoming machine request to a gateway, server records, an action event, and a completed purchase.

    Attribution becomes credible when you can follow an agent from an incoming request to a server-confirmed action. A dashboard label such as “AI traffic” is not enough. You need a chain of evidence that survives redirects, browser changes, authentication, and the absence of JavaScript events.

    Capture the request before classifying it

    Preserve the raw evidence in your CDN, load balancer, or application logs before a bot filter removes it. For each relevant request, capture:

    • A UTC timestamp and a unique request ID.
    • The HTTP method, normalized route, response status, and response size.
    • The full user-agent value as received, plus the parser’s normalized result.
    • The source network information needed for verification.
    • Referrer and origin headers when present, without treating their absence as proof of anything.
    • Whether a first-party session was present or created.
    • A pseudonymous account or customer identifier when the request was legitimately authenticated.
    • The resulting application event, such as search performed, form accepted, cart updated, or order confirmed.

    Do not log authorization headers, passwords, payment details, complete form bodies, or sensitive query-string values for the sake of attribution. Strip or tokenize sensitive fields before they reach the analytics store. The useful connection is between a request identifier and a confirmed event, not between a marketing report and a copy of the user’s private data.

    Instrument the business action on the server

    A page view tells you that an agent requested a page. It does not tell you that a form was accepted, an account changed, or a payment completed. Emit a first-party server-side event only after the application confirms the action.

    Give that event its own ID and record the initiating request ID, event time, action type, outcome, and any internal transaction or lead identifier. If the event represents money, use the same finalized value your order system recognizes. Failed submissions and abandoned workflows belong in diagnostic reporting, not completed-conversion totals.

    Make an agent-to-human handoff observable

    Many useful agent journeys will not end inside the agent. The machine may find a product or prepare a configuration, then send the user into a browser to review, authenticate, or pay. Standard last-click attribution can give the browser all the credit because the earlier agent request had no ordinary campaign parameter or client-side session.

    When you control the handoff, attach an opaque, first-party handoff token to the destination URL. The token should identify a journey record, not expose an email address, prompt, account number, or other personal data. Expire it, prevent it from granting access, and associate it with the eventual conversion only after your server validates it. If the user is already authenticated, an internal pseudonymous account key can provide the connection without placing identity in the URL.

    If you cannot observe a deterministic handoff, do not manufacture one from matching timestamps or similar page paths. You may analyze those patterns in aggregate, but label the result as discovery influence rather than an assisted conversion.

    Recognize Google-Agent without weakening security

    An abstract automated agent passes through layered identity checks at a secure gateway while unverified requests are blocked.

    Google-Agent creates a useful distinction between continuous crawling and a request made while an AI system performs a user-initiated task. Google introduced it for agents hosted on its infrastructure, including experimental systems such as Project Mariner, and provided network ranges for desktop and mobile agent activity.

    That identity gives you a better starting signal, not a substitute for authentication. User-agent strings are supplied by the requester and can be copied. Never allow an account action, bypass a challenge, or relax a security rule solely because a request calls itself Google-Agent.

    Use confidence-based verification

    Apply the same verification pattern to Google-Agent and any other named agent:

    1. Match and preserve the claimed user-agent identity.
    2. Compare the source with the provider’s published network information and keep that information current.
    3. Check whether the request pattern is consistent with the claimed function, including the routes, methods, timing, and workflow sequence.
    4. Record the result as verified, probable, or unverified rather than reducing all three states to a boolean bot flag.
    5. Apply normal authorization, rate limiting, abuse detection, and transaction controls regardless of the identity label.

    This approach is more defensible than a single allowlist. It also reflects how large-scale AI traffic was classified: user-agent strings were combined with infrastructure signals and activity characteristics because self-reported bot identities do not capture every AI-driven request reliably.

    Test the paths that matter

    Review your CDN and web application firewall logs for named agents before changing any rule. Then test product search, detail pages, forms, sign-in, account functions, cart operations, and checkout with non-production accounts and non-chargeable test transactions where your systems support them.

    Look for redirects that loop, challenges that cannot be completed, required state that disappears between requests, and successful browser screens backed by failed server actions. Keep intentional security denials in place. The goal is to remove accidental incompatibility, not to give automated clients a privileged route into sensitive workflows.

    Report agent contribution without false precision

    Your reporting should tell operators what happened and tell decision-makers how certain the attribution is. One blended “AI conversions” number cannot do both.

    Use four mutually exclusive outcome states:

    • Agent-executed: A verified or explicitly qualified agent request is linked to a server-confirmed conversion that the agent performed.
    • Agent-assisted: An observable first-party handoff or authenticated journey connects agent activity to a later human conversion.
    • Discovery-only: An agent retrieved relevant content, but no deterministic connection to an individual outcome exists.
    • Unresolved automation: Automation was detected, but its identity, purpose, or relationship to an outcome remains uncertain.

    Do not add agent-executed and agent-assisted credit if they describe two stages of the same conversion. Keep a deduplicated conversion ID, choose a primary status, and retain the touch sequence separately for analysis.

    Your operational dashboard should cover three layers. The access layer needs request volume by agent type, verification state, route group, response status, and security disposition. The workflow layer needs starts, successful steps, failures, and confirmed completions for each key action. The business layer needs deduplicated leads, orders, revenue where applicable, and the four attribution states above.

    Choose an assistance window that reflects your actual buying cycle and publish that rule beside the metric. There is no defensible universal window in the available evidence. A short handoff into checkout and a long enterprise evaluation should not inherit the same arbitrary assumption.

    Establish the baseline even if named-agent volume is initially small. A rise in training access may affect infrastructure cost and content-control decisions without changing revenue. A rise in verified product-search and account activity deserves workflow testing. Repeated checkout attempts with no confirmed outcomes point to a technical or security investigation, not automatically to weak demand.

    Start with one path that matters commercially: discovery, a product or service page, and its next meaningful action. Join the request logs to one server-confirmed outcome, preserve uncertainty as an explicit field, and make that narrow chain trustworthy before expanding it across the site. That gives you a measurement system you can extend as agents become more capable, without rewriting history around traffic you never truly identified.

    References


  • Google Ads Developer AI Updates: A Practical Playbook

    Google Ads Developer AI Updates: A Practical Playbook

    You do not need another AI announcement in your backlog. You need to know whether Google’s direction changes what your advertising team should build, who should control it, and how much authority an AI agent should receive.

    The immediate answer is not to rebuild your Google Ads integration around agents. Treat the update as an architectural signal: prepare for AI systems to propose and invoke advertising actions, but keep permissions, validation, approvals, execution, and audit controls outside the model.

    The update is a learning channel, not an API release

    An engineer studies abstract signals from a studio beacon while a separate sealed production system remains unchanged on the workbench.

    Google has introduced Ads DevCast as a bi-weekly pilot hosted by Cory Liseno from its Advertising and Measurement Developer Relations team. Its technical scope includes Google Ads, Google Analytics, and Display & Video 360. Google is also inviting feedback while the pilot develops.

    That positioning matters. Ads Decoded, hosted by Ginny Marvin, addresses campaign strategy. Ads DevCast is intended for the people building, configuring, debugging, and governing the systems beneath that strategy. Subscribe the technical owner of your advertising stack, not only the person who manages campaigns.

    A new developer show does not, by itself, change an endpoint, schema, authentication flow, or deprecation date. Do not turn an episode into a production migration ticket merely because an idea sounds important. Use three separate lanes:

    • Discovery: Use Ads DevCast to notice technical themes, emerging capabilities, and the problems Google expects developers to encounter.
    • Verification: Confirm implementation details in the relevant official API documentation, release notes, schemas, and account controls before changing code.
    • Delivery: Create an engineering task only after you can name the affected platform, resource, operation, permission, test case, and rollback path.

    This distinction prevents two common errors. One is ignoring a directional signal until it becomes an urgent implementation problem. The other is treating a discussion of future architecture as though it were a released feature with stable production behavior.

    The agentic shift changes your control plane

    The first episode, titled “MCPs, Agents, and Ads. Oh My!”, presents an “agentic shift” in which AI agents become important users of advertising APIs. Treat that as Google’s direction of travel, not as evidence that every advertiser should give an agent unrestricted control of live campaigns.

    Model Context Protocol, or MCP, is relevant because it gives AI systems a common way to discover and invoke tools. A consistent tool interface can make an API easier for an agent to reach. It does not make the requested action correct, authorized, affordable, or reversible.

    The safest mental model is simple: the agent is a planner and operator working inside a control system. It is not the control system. A production workflow should separate intent from execution:

    1. Observe: Retrieve only the account and campaign data needed for the task.
    2. Propose: Produce a structured change showing the target resource, current value, proposed value, rationale, and expected scope.
    3. Validate: Check the proposal against the API schema, account state, internal policy, and allowed operations.
    4. Approve: Require the appropriate human or policy-based approval before any consequential write.
    5. Execute: Pass the approved action to deterministic code that calls the advertising API.
    6. Verify: Read the affected resource again, record the result, and surface any difference between the approved proposal and the final state.

    Put hard limits outside the prompt

    A prompt can tell an agent not to make risky changes. It should not be the only thing preventing them. The enforceable rules belong in the gateway between the agent and the ad platform.

    • Allowlist the accounts, resource types, fields, and operations the agent may access.
    • Use read-only access by default and grant write access per workflow rather than per agent.
    • Reject requests that omit the target account, current state, proposed state, or approval record.
    • Place budget, bid, scheduling, targeting, and deletion constraints in code or platform policy.
    • Use idempotency or equivalent duplicate protection where the operation supports it.
    • Log the request, tool call, actor, approval, API response, and resulting resource state.
    • Maintain a tested way to reverse mutable changes and a separate recovery procedure for actions that cannot be cleanly undone.

    This is a money-sensitive system. An agent with broad write access can alter live delivery before a person notices the mistake. For any action that can increase spend, narrow reach, pause revenue-producing activity, remove data, or change measurement, use a preview-and-approval flow until you have evidence that a more automated policy is safe for that exact operation.

    Turn each episode into an engineering decision

    A bi-weekly technical program can quickly become background noise unless someone owns the intake process. Give one person responsibility for converting each relevant item into a decision, including a deliberate decision to take no action.

    1. Capture the claim precisely. Write down the named product, capability, resource, or workflow. Avoid tickets such as “investigate AI for ads” because they have no testable boundary.
    2. Classify its status. Mark it as a concept, directional signal, pilot, documented capability, released change, or deprecation. Do not let enthusiasm silently upgrade its maturity.
    3. Map the affected surface. Identify whether it touches Google Ads, Google Analytics, Display & Video 360, or more than one system. Then name the relevant integration, credential, data flow, and owner.
    4. Verify implementation facts. Check the authoritative documentation for availability, supported operations, permissions, quotas, version requirements, and known limitations.
    5. Record the decision. Choose watch, prototype, adopt, migrate, or reject. Include the evidence needed to revisit that choice.

    Your decision record does not need to be elaborate. It should include the topic, status, affected system, documentation link, owner, next review trigger, test environment, approval requirement, and rollback method. That is enough to distinguish a useful technical signal from an unverified idea circulating in team chat.

    Use a prototype when the value is plausible but the operational risk is unclear. Start with a read-only workflow that answers one bounded question, then let the agent draft a change without executing it. Compare its proposal with the decision a qualified operator would make. Only after that should you test an approved write in a controlled account or environment.

    Because Ads DevCast is a pilot seeking community input, document where explanations leave an implementation gap. Useful feedback is specific: name the platform, operation, missing detail, and decision you could not safely make. That gives Google a clearer request than a general demand for more examples.

    Your ownership model must evolve with the integration

    An isometric AI advertising workflow routes action tokens through access controls, validation, human review, staging, and an audit vault while separate teams supervise their areas.

    Google is broadening the frame from a specialist Ads Developer Community toward a wider Ads Technical Community. That makes room for marketers to perform more technical work without waiting for a full development cycle. It does not erase the need for engineering ownership; it changes where the handoffs occur.

    Before connecting an agent to advertising tools, assign these responsibilities by name:

    • Business owner: Defines the campaign objective and decides which tradeoffs are acceptable.
    • Platform owner: Controls credentials, permissions, API configuration, and production access.
    • Workflow owner: Defines the agent’s tools, inputs, outputs, validation rules, and failure behavior.
    • Approver: Reviews consequential changes and has enough context to reject a technically valid but commercially poor action.
    • Incident owner: Can stop execution, assess affected resources, restore safe state, and preserve the audit trail.

    Do not collapse all five roles into “the AI team.” The business owner knows what should happen. The platform owner knows what can happen. The workflow owner controls how a request becomes an API call. The approver evaluates the actual change. The incident owner handles the moment when the system behaves differently from the plan.

    This division also makes low-code and agent-assisted work more practical. A marketer can describe or initiate a task without receiving unrestricted platform access. Engineering can provide constrained tools and reusable policies instead of implementing every request from scratch. The speed comes from a safer interface between roles, not from removing the roles.

    Key takeaways for your next working session

    • Use Ads DevCast as a technical discovery channel; verify every implementation detail in authoritative product documentation.
    • Treat Google’s agentic direction as a reason to prepare your architecture, not as permission to automate every campaign action.
    • Keep the agent focused on observation and structured proposals before granting narrowly scoped write capability.
    • Enforce permissions, spend constraints, approvals, logging, and recovery outside the model and its prompt.
    • Assign business, platform, workflow, approval, and incident ownership before connecting an agent to a live advertising account.
    • Convert each relevant update into a recorded decision: watch, prototype, adopt, migrate, or reject.

    Start with one existing Google Ads workflow that consumes too much operator time but has a clear input and output. Draw the six stages from observation through verification. Mark every place where a bad decision could affect spend, delivery, measurement, or data. Those marks define the controls your agent needs before it gets write access.

    Then build the smallest read-only version and require a structured proposal. That gives you a concrete way to evaluate Google’s agentic direction without betting a live account on an immature design.

    References


  • SEO After the Click: Winning AI Search and Agent Traffic

    SEO After the Click: Winning AI Search and Agent Traffic

    You can rank first and still lose the recommendation. A buyer asks an AI assistant for a shortlist, gets a synthesized answer, and never reaches the search result where you lead. Your competitor appears because its name, category, capabilities, and reputation are easier to retrieve and corroborate across the web.

    That does not make SEO obsolete. It changes the job. You still need pages that rank, but you also need a brand that AI systems can identify, trust, describe accurately, and use when helping someone make a decision.

    Key takeaways for AI search and agent traffic

    • Keep investing in technical SEO, content quality, and organic rankings. They support retrieval even when the final answer appears somewhere other than a conventional results page.
    • Give every important product, service, person, and claim one clear source of truth on your site. Make your schema markup and JSON-LD agree with the visible page.
    • Build independent corroboration. Repeated claims on your own domain are messaging; consistent mentions across credible publishers and communities create consensus.
    • Audit ChatGPT, Perplexity, Gemini, and Google AI Overviews with the questions customers actually ask. Record accuracy, citations, competitors, and whether your brand appears at all.
    • Separate AI referrals, brand mentions, and agent requests in your reporting. A crawler request is infrastructure activity, not proof of attention or revenue.

    The optimization target has split into three outcomes

    Three paths from one digital foundation lead toward a human visitor, an abstract search result, and an autonomous agent retrieving information.

    Traditional search optimization concentrated on discoverability, ranking, and the click. AI-mediated discovery adds two more requirements: corroboration and actionability. A useful strategy addresses all three instead of renaming ordinary SEO as GEO and leaving the workflow unchanged.

    AI can make structured technical work faster, but automation still depends on clean data, precise instructions, expert review, and strategic judgment. Your advantage will not come from producing more machine-written pages than everyone else. It will come from making better decisions about which facts deserve to be published, how they should be represented, and where they need independent support.

    Retrieval: can the system find and understand the right page?

    Create one authoritative page for each decision-critical subject. A service page should state what the service is, who it is for, what problem it addresses, where it is available, and what its important limitations are. An expert profile should use the same name, role, and area of expertise that appear on the content attributed to that person.

    Use stable language for your category. If the homepage calls you an AI visibility platform, a product page calls you an answer marketing suite, and an external profile calls you an SEO automation tool, a machine has to decide whether those descriptions refer to the same thing. Choose a primary category, explain adjacent terms, and use that relationship consistently.

    Treat schema markup and JSON-LD as a map of facts that a visitor can verify on the page. Markup should reinforce identity, relationships, authorship, and the subject of the page. It should not contain a more flattering or more complete version of the business than the visible content does. Structured data can reduce ambiguity, but it cannot manufacture third-party trust or guarantee inclusion in an AI answer.

    Do not confuse a carefully written title with control over the final interface. Google has tested AI-driven headline rewrites in search, so your title and headings must communicate the subject clearly even when the displayed wording changes. Optimize the underlying meaning, not only the snippet you hope to see.

    Corroboration: can the system verify the claim elsewhere?

    Your website can establish what you say about yourself. It cannot independently prove that customers, specialists, publishers, and communities recognize you in the same category. AI systems that synthesize answers can compare multiple sources, so a claim supported across independent domains is more defensible than a claim repeated across several pages you control.

    This is why rankings and AI visibility can diverge. A page may perform well in a conventional result while the brand behind it remains absent from synthesized recommendations. The missing ingredient is often not another keyword variation. It is distributed evidence.

    Actionability: can an assistant help the user decide what to do?

    An agent may need more than a persuasive description. It may be comparing price, quality, suitability, availability, prerequisites, or efficiency. Those decision facts should be explicit, current, and easy to distinguish from promotional claims.

    • State what the offering does and what it does not do.
    • Name the customer, use case, geography, or prerequisite that determines fit.
    • Publish current pricing when it is genuinely public. If pricing requires a quote, explain the pricing model and the information needed to obtain one.
    • Use consistent labels and units when presenting plans, features, limits, or performance evidence.
    • Give the user a clear next step on the same page: buy, book, apply, request a quote, check availability, or read the relevant documentation.

    These details help humans as much as machines. The difference is that an agent may discard a vague brand claim before a person ever sees it. As automated comparison grows, brand familiarity alone may be a weaker shortcut than a clear match on price, quality, and suitability.

    Build consensus beyond your own domain

    Retrieval-augmented systems assemble context from material they can find and then generate an answer from that context. When multiple credible sources associate the same entity with the same category or capability, the repeated relationship becomes easier to use. When your site is the only place making the connection, your brand looks like an unsupported outlier.

    The gap between rankings and citations can be substantial. One reported estimate places approximately nine out of ten pages cited by ChatGPT outside the top 20 organic results. Treat that figure as a directional warning rather than a universal rule: a first-page position does not automatically confer visibility in every AI system, and an AI citation does not require a top-20 ranking in every case.

    Start with a claim inventory. For every claim that could affect selection, write down the exact proposition you need the market to understand:

    • Identity: the brand, product, person, or organization being discussed.
    • Category: the primary market or problem to which the entity belongs.
    • Fit: the customer, situation, or constraint for which it is appropriate.
    • Capability: the outcome it can produce, with material limits attached.
    • Evidence: the data, method, example, credential, or customer experience that supports the capability.
    • Currency: the date, edition, plan, location, or version to which a changeable fact applies.

    For each proposition, mark where it appears on your site and where an independent source supports it. A capability mentioned on six owned pages still has only owned support. A trade publication, podcast, customer discussion, expert quotation, industry directory, or community recommendation adds a different kind of evidence.

    Links remain useful, but they are not the only signal worth pursuing. Unlinked brand mentions and diverse publisher coverage can also strengthen entity recognition. The practical implication is that digital PR, expert participation, and reputation work now belong inside the search strategy rather than beside it.

    The strongest consensus assets give other people a reason to refer to you. Original data, a proprietary survey, a transparent methodology, a useful public tool, or a genuinely qualified expert can earn citations without requiring every mention to repeat a marketing line. Make the underlying evidence easy to inspect and the responsible person easy to identify.

    Communities require a different approach. Answer the actual question, disclose your relationship to the brand, and accept that the product may not be the right recommendation. Planted praise and repetitive link drops can create reputation problems rather than consensus. A natural recommendation from an established participant is valuable precisely because you cannot manufacture it on demand.

    Consistency does not mean forcing every publisher to copy your wording. It means that independently written descriptions resolve to the same underlying facts. If credible sources disagree about your category, current features, leadership, or availability, repair the source-of-truth page first and then correct the most consequential external records.

    Audit AI visibility by failure mode

    Do not begin with another content calendar. Begin with the answers your prospects already receive. An AI visibility audit should tell you whether the problem is retrieval, entity clarity, corroboration, positioning, factual accuracy, or attribution.

    1. Build prompts from real decisions. Include category discovery, problem-to-solution questions, comparisons, use-case constraints, reputation questions, and branded fact checks. Examples include: What are the leading providers in this category? Which option fits this constraint? What do people say about this brand? Is this product suitable for this use case?
    2. Use the same prompt set across relevant surfaces. Check ChatGPT, Perplexity, Gemini, and Google AI Overviews where an overview appears. Keep the wording stable so you are comparing the answer, not your own prompt variations.
    3. Capture evidence, not impressions. Record the date, surface, prompt, whether the brand appeared, the exact category and attributes assigned to it, competing brands, cited domains, factual errors, and the action offered to the user.
    4. Classify the failure. Map each weak answer to a specific cause before creating or editing content.
    5. Fix the smallest responsible layer. Correct dangerous or commercially significant errors first. Then repair the owned source of truth, clarify entity relationships, and pursue external corroboration for claims that remain unsupported.
    Observed patternLikely gapFirst move
    Your brand is absent and the relevant owned page is unclear or incompleteRetrieval or entity clarityCreate or revise the authoritative page; align visible facts, headings, internal references, schema markup, and JSON-LD
    Competitors appear through several independent domains while your claims exist only on your siteConsensusDevelop evidence worth citing and earn coverage, expert mentions, customer discussion, or community recognition
    Your brand appears with an outdated feature, category, person, or locationConflicting or stale factsCorrect the owned source of truth and then prioritize the external pages that repeat the error
    Your brand appears for branded prompts but not for category or use-case promptsWeak category associationClarify the primary category and publish decision-focused content that connects your entity to the relevant problem
    Your brand is described accurately but sessions do not riseZero-click behavior or attributionMeasure mentions, branded demand, direct visits, and self-reported discovery before declaring the work ineffective

    A single favorable response is not a durable ranking. Generated answers can vary by system, context, and timing. Preserve your prompt set and evidence so the next audit can show whether a correction persisted, whether citations diversified, and whether competitors displaced you.

    Do not reduce the audit to a brand mention count. A recommendation in the wrong category can be worse than an omission, and an accurate mention supported by an irrelevant page may be fragile. Read the claim, the context, and the cited evidence together.

    Measure human demand and machine activity separately

    People and abstract software agents move through separate warm- and cool-colored channels toward an unlabeled measurement console.

    Clicks remain commercially important, but they no longer describe the entire discovery path. Organic click-through rates have declined in reported data for queries displaying AI Overviews since mid-2024, with declines also reported for some queries without AI answers. That is not a reason to abandon search performance reporting. It is a reason to stop using sessions as the sole measure of visibility.

    Agent traffic creates a separate measurement problem. Cloudflare CEO Matthew Prince has said bots represented roughly 20% of web traffic for a long period and projected that bot activity could exceed human activity by 2027. The date is a forecast, not a settled timetable. The operational point is more durable: an agent can retrieve far more pages than a person considering the same decision, so request volume may grow without an equivalent rise in human sessions.

    Use four reporting layers and resist combining them into one traffic number:

    • Search performance: rankings, impressions, click-through rate, organic sessions, and conversions. Keep these metrics because search engines remain a retrieval and demand channel.
    • Answer visibility: the share of your tracked prompts that mention the brand, the share that cite a useful owned or earned page, descriptor accuracy, competitor share of voice, and the diversity of domains supporting decision-critical claims.
    • Agent access: identifiable automated requests, requested URLs, response status, response volume, and infrastructure cost. Separate useful retrieval from errors, loops, and repeated fetching.
    • Business outcomes: qualified leads, sales, branded search, direct visits, AI referral sessions when a referrer is exposed, and self-reported discovery from forms or sales conversations.

    Give each visibility metric a stable denominator. Mention coverage can be calculated as tracked prompts in which the brand appears divided by all prompts checked. Descriptor accuracy can be calculated as correct brand appearances divided by all brand appearances reviewed. Citation coverage can track how often a relevant owned or earned page supports the answer. Keep the prompt set stable between reporting periods, and document additions instead of quietly changing the test.

    Agent requests should never be reported as visits, engagement, or purchase intent. If automated requests rise while answer visibility, branded demand, and qualified outcomes remain flat, you may have a cost increase rather than a marketing gain. If mentions improve while referral sessions decline, inspect branded search, direct demand, and lead-source responses before concluding that AI visibility has no value.

    The economic response also depends on your business model. Publishers supported by advertising face a direct problem because bots do not consume ads like people do. Unique reporting, original data, access controls, and possible licensing arrangements may become more important, although licensing is not a guaranteed substitute for audience revenue. Lead-generation and commerce sites have a different priority: publish accurate selection facts and make the next human action unmistakable.

    Before changing crawler permissions or rate limits, identify which automated systems request which pages, what those requests cost, and whether they contribute to discovery. Blocking broadly can reduce infrastructure load but may also reduce retrieval. Allowing unrestricted access may raise server costs or content-rights concerns. Treat access as a joint technical, commercial, and legal policy rather than a reflexive SEO setting.

    Your next move should happen before you approve another batch of content. Choose one revenue-critical topic, run the same decision prompts across the major AI surfaces, and classify the first failure you find. Fix the source-of-truth page if the facts are unclear; build independent evidence if the facts are clear but unsupported; improve the decision path if the recommendation is accurate but unusable.

    The durable SEO plan is not a choice between rankings and AI visibility. Rankings support retrieval, distributed evidence supports inclusion, and clear decision facts support action. Build those layers deliberately, and you will be prepared whether the next visitor arrives as a person, through an AI answer, or behind an agent.

    References

  • Harness Google Search Console Data with Profound Agents

    Harness Google Search Console Data with Profound Agents

    I’m excited to share that I can now effortlessly integrate Google Search Console data directly into any of my Profound Agents. This powerful combination, uniting Search Console insights with Profound’s answer engine data, is transforming how I handle reporting, content creation, monitoring, and optimization.

    Staying on the Profound platform makes the entire process seamless, allowing me to focus on what truly matters—building and optimizing my digital strategies without the hassle of platform switching.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • Google’s Universal Commerce Protocol: A Retailer Playbook

    Google’s Universal Commerce Protocol: A Retailer Playbook

    If you run ecommerce SEO, product feeds, or shopping infrastructure, your next visibility problem may not begin on a search results page. It may begin when an AI shopping agent tries to identify the right variant, confirm that it is available, calculate the correct price, and place it in a working basket.

    Google’s Universal Commerce Protocol, or UCP, is intended to connect those steps. Your practical task is to make product and customer data usable across discovery, selection, and checkout without assuming that protocol adoption will automatically produce rankings, recommendations, or sales.

    UCP moves product visibility closer to the transaction

    Traditional search optimization prepares a page for a person to discover and visit. Agentic commerce adds another route: software may evaluate products, assemble a purchase, and act for the shopper. UCP is an open, modular standard for connecting retailers with AI-driven shopping experiences.

    That does not make product pages irrelevant. It changes where accuracy has to survive. A persuasive description cannot compensate for an unavailable variant. Valid page markup cannot repair a cart that calculates the wrong price. A feed can expose a product, but the transaction can still fail if customer benefits disappear after identity linking.

    This gives you four connected layers to manage:

    • Page content and structured data explain the product in a crawlable, understandable form.
    • Catalog data supplies current commercial facts such as price, inventory, and available variants.
    • Cart logic turns selected items into a valid basket.
    • Identity and account logic determine whether the shopper receives eligible benefits.

    Keep these layers aligned, but do not treat them as interchangeable. UCP is not merely another name for JSON-LD, a product feed, or an ad format. It reaches into live commerce functions that page-level optimization alone cannot perform.

    Google has said it plans to use UCP capabilities in AI-enhanced experiences across Search and the Gemini app. That establishes a direction, not a promise that every retailer, market, capability, or product will receive the same access or exposure. Build readiness around documented availability and your own eligibility rather than an assumed rollout.

    Map each UCP capability to a real retail responsibility

    The useful way to evaluate UCP is capability by capability. Each one touches a different system, failure mode, and internal owner.

    CapabilityWhat it enablesWhat you should verifyLikely owner
    CatalogAccess to current product information, including pricing, inventory, and variantsStable identifiers, variant mapping, update freshness, and agreement between catalog, product page, and checkoutMerchandising, feed operations, or commerce platform team
    CartMultiple products from one retailer can be assembled into one basketAdd, update, remove, reprice, and out-of-stock behavior across a multi-item orderEcommerce engineering
    Identity linkingEligible benefits such as member pricing and free shipping can continue across connected experiencesAuthentication, consent, entitlement rules, session handling, and safe failure behaviorIdentity, security, loyalty, and legal or privacy teams
    Modular adoptionA retailer or platform can adopt selected capabilities instead of implementing everything at onceA rollout sequence tied to system readiness and a clear dependency mapCommerce product owner or program lead

    The capability names do not answer every implementation question. For example, knowing that an agent can create a cart does not by itself define how your taxes, promotions, substitutions, shipping restrictions, or returns work. Treat those as test cases that need authoritative documentation and validation in your own stack. Do not invent behavior from the protocol’s high-level description.

    Modularity is especially important for planning. You do not need to frame UCP as an all-or-nothing rebuild. If your identity system is not ready, that does not erase the value of repairing catalog inconsistencies. If your catalog cannot reliably distinguish variants, however, adding an agent-facing cart simply moves bad data closer to checkout.

    Audit product data as if it were the storefront

    An unbranded jacket, variant swatches, packaging, inventory objects, and a magnifying lens are arranged for a detailed product data audit.

    An agent cannot walk a virtual aisle and infer that a stale price is probably wrong. It receives representations of your inventory and has to make decisions from them. Because the catalog capability is designed to expose real-time pricing, inventory, and variant information, conflicting product facts become a commercial problem, not merely a feed-cleanup task.

    Start with one product family that has meaningful variation. A product with size, color, configuration, or member pricing will reveal more than a simple item with one price and one stock state. Trace it through every system an agent-assisted purchase could touch.

    1. Resolve the identity chain. Confirm that the parent product, each purchasable variant, the catalog record, the product page, and the cart line resolve to the intended item. A parent identifier should not silently stand in for a specific variant at purchase time.
    2. Name the source of truth for each commercial fact. Decide which system owns price, sale price, inventory, variant attributes, and account benefits. If two systems can overwrite the same fact, document precedence and failure handling.
    3. Compare anonymous and authenticated states. Check whether public pricing, member pricing, shipping benefits, and eligibility rules remain distinguishable. The agent should not present a conditional benefit as universal.
    4. Test change propagation. Change a price or inventory state in the owning system and observe every downstream representation. Record your actual delay and failure points rather than relying on the intended architecture.
    5. Inspect contradictions. Compare the catalog, rendered product page, structured data, basket, and logged-in experience. Any disagreement can lead to a poor recommendation, a rejected add-to-cart action, or an unpleasant price change at checkout.
    6. Log failed and stale updates. A synchronization process that usually works is not enough. Your team needs a way to identify which products failed, when the last successful update occurred, and which downstream surfaces may still carry old information.

    This is also where SEO, GEO, and feed teams should coordinate. Keep descriptive content and structured data consistent with commercial systems, but do not add unsupported claims to markup merely to make the product look more complete to an AI system. The safest machine-readable answer is the same answer the shopper will receive in the cart.

    Do not call the audit complete because a sample record validates syntactically. A valid record can still identify the wrong variant, carry an old price, or point to inventory that cannot be purchased. Validation checks form; transaction tests check truth.

    Roll out the smallest capability you can verify end to end

    A coffee maker follows one illuminated path through catalog, inventory, basket, payment, and delivery modules while unused modules remain dark.

    Catalog readiness is usually the sensible first workstream because cart and identity experiences depend on accurate merchandise data. That is a sequencing recommendation, not a protocol requirement. Your architecture may justify a different order, but every pilot should have one defined capability, one accountable owner, and an observable pass or fail condition.

    1. Choose a bounded product set. Select products that expose the problems you need to solve, including variants or conditional benefits, while keeping the pilot small enough to inspect manually.
    2. Capture a baseline. Record current catalog mismatches, failed add-to-cart actions, unavailable variants presented as purchasable, and benefit-entitlement failures. Without a baseline, protocol activity can look like progress while customer-facing accuracy remains unchanged.
    3. Define acceptance tests before integration. Write expected results for price changes, inventory changes, variant selection, multi-item baskets, account linking, and entitlement loss. Include negative cases, not just a successful purchase.
    4. Test the cart as a changing object. The new cart capability is intended to let agents place multiple products from one retailer into a single basket. Verify what happens when quantity changes, one line becomes unavailable, a promotion expires, or the shopper switches variants.
    5. Isolate identity testing. Identity linking can preserve member pricing and free shipping, but it also touches account access and personal data. Use controlled test accounts and obtain security, privacy, and legal approval before exposing real customer identities. The specific downside of rushing this step is not just a broken discount; it can be unauthorized account access or inappropriate data sharing.
    6. Monitor outcomes by failure stage. Separate catalog retrieval, variant resolution, cart creation, cart mutation, authentication, entitlement, and checkout failures. A single conversion total will not tell you which capability needs repair.

    Your ownership model matters as much as the integration. Feed operations can correct a variant mapping but should not define authentication policy. SEO can identify contradictions visible to search systems but should not own checkout integrity. Ecommerce engineering can make a cart function without knowing whether member benefits are represented correctly. Put these teams behind one shared test plan rather than handing UCP to whichever team first notices it.

    Google has also indicated that it plans to simplify UCP onboarding through Merchant Center. Use that as a reason to prepare your data and test cases, not as a reason to assume that implementation is already automatic. When onboarding becomes available to you, confirm supported capabilities, required fields, market coverage, permissions, and reporting from the documentation presented in your account.

    Most importantly, do not report UCP adoption as an SEO win by itself. There is no basis here for calling it a guaranteed ranking factor or recommendation boost. Measure what you can actually observe: eligibility, accurate product representation, successful basket creation, preserved benefits, completed purchases, and the failure rate at each handoff.

    Key takeaways

    • UCP connects product discovery with live commerce functions; it is broader than page markup, feeds, or advertising alone.
    • Catalog accuracy is foundational because price, inventory, and variant errors can follow an agent directly into the cart.
    • Cart, catalog, and identity linking should be treated as separate capabilities with separate owners and tests.
    • Modular adoption lets you start with a bounded capability instead of waiting for a complete commerce-stack rebuild.
    • Identity linking requires controlled testing and security, privacy, and legal review before real customer accounts are involved.
    • Protocol adoption does not establish a ranking or recommendation benefit. Evaluate transactional accuracy and measurable outcomes.

    Your best next step is concrete: take one high-value product family with variants, compare its catalog record, product page, structured data, cart, and logged-in benefits, then document every contradiction. That exercise will tell you whether your first UCP project is an integration project or, more likely, a product-data repair project that needs to happen before integration can deliver anything useful.

    References