Tag: AI Agents

  • How to Adapt Search Visibility and Customer Journeys for AI

    How to Adapt Search Visibility and Customer Journeys for AI

    Your rankings can look stable while part of your customer journey quietly moves elsewhere. A prospect can ask an AI assistant to define the problem, build a shortlist and challenge each option before visiting a website. They may then use Google to verify a detail, arrive through a branded search and convert on a page that receives all the credit.

    If your pages are inconsistent, duplicated or vague, the assistant may omit you, describe you incorrectly or send the prospect to an outdated URL. The answer is not a separate factory for AI content. You need one dependable set of business facts that search engines, AI systems, people and agents acting on their behalf can retrieve, evaluate and carry into a clear next step.

    Plan around the customer’s task, not the search platform

    Do not treat Google and AI assistants as interchangeable traffic sources. They often serve different parts of the same decision.

    One modeled estimate for Q4 2025 placed Google at 77.9% of global digital queries and ChatGPT at 17.1%. The intent split was more revealing: Google held an estimated 90% share of transactional queries, compared with 5% for ChatGPT, while ChatGPT had a much stronger position in generative and creative work. These are directional figures from a model combining client analytics, third-party data and anonymized logs, not a universal census of every query.

    The practical implication is straightforward. Do not dismantle the Google pages that capture high-intent demand. Strengthen the earlier stages where a person is framing a problem, learning terminology, comparing approaches or testing a recommendation. AI can influence the shortlist even when Google, direct traffic or a branded query produces the final visit.

    Start by sorting the questions around one commercially important journey into four jobs:

    • Discover: What kind of solution exists for this problem?
    • Compare: Which options fit my budget, use case, location or constraints?
    • Verify: Is this claim current, supported and applicable to me?
    • Act: What do I need to do next, and what will happen when I do it?

    For every job, name the page you want an AI system or search engine to select. If your team cannot agree on that URL, a retrieval system is unlikely to infer the right one consistently. That gap is more urgent than producing another loosely related blog post.

    Device behavior also affects the handoff. The same 2025 model put 62% of ChatGPT usage on desktop and 63% of Google usage on mobile. That does not establish a conversion pattern, but it is a useful warning: someone may research with AI at a desk and resume through search on a phone. Use stable names, URLs and claims across devices so that the second session confirms what the first one established.

    Map the human and AI journeys to the same pages
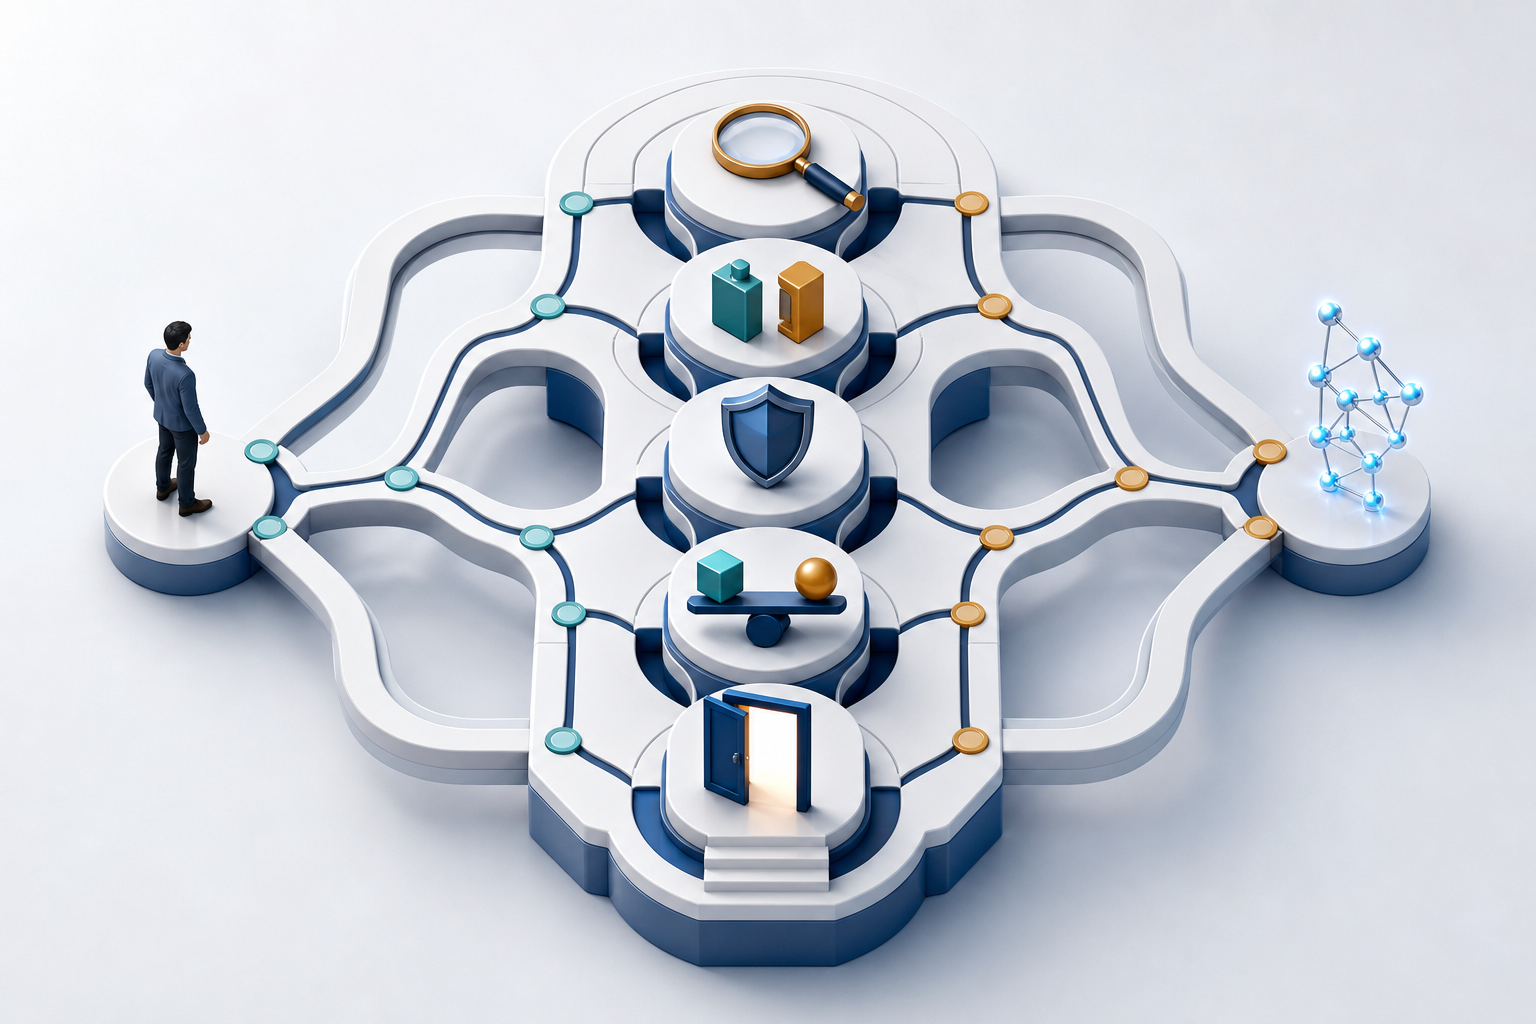
    A human and an abstract AI system follow connected paths through the same modular information hub.

    A conventional funnel describes what a person does. An AI-ready journey must also describe what a machine needs to retrieve and explain at each stage. Those are not separate funnels. They are two views of the same handoffs.

    Journey stageWhat the person needsWhat the AI system must resolveWhat the page should provide
    Problem framingLanguage for the problem and its possible causesWhether your entity and content are relevant to the questionA direct explanation, clear scope and links to the next decision
    Option discoveryA credible set of approaches or providersWhat you offer, who it is for and how it differsConsistent product or service names, use cases and qualification criteria
    EvaluationComparable facts, limitations and proofWhich claims apply under which conditionsExplicit criteria, evidence, exclusions, dates and current commercial details
    ActionA low-ambiguity next stepWhere to send the person or how to relay the taskA stable destination, visible prerequisites, a specific call to action and a confirmation path

    This map exposes two common failures. The first is an orphaned educational page that answers the question but never leads to a decision. The second is a conversion page that asks for a booking, trial or purchase without publishing enough information for the prospect to evaluate it. AI can compress several stages into one conversation, so both failures can remove you before a visit occurs.

    Key takeaways

    • Keep strong transactional SEO pages, but connect them to the informational and comparison questions AI assistants handle upstream.
    • Assign one preferred URL to every material intent. If several URLs appear equally valid, consolidate or differentiate them.
    • Put decision-critical facts in visible page content. Do not hide them only in images, downloads, scripts or structured data.
    • Use JSON-LD to mirror the page’s visible facts, not to introduce a second version of those facts.
    • Measure whether AI selects the correct page and represents it accurately, not just whether an identifiable referral arrives.

    Consolidate duplicate pages before expanding your coverage

    AI visibility becomes harder when several URLs compete to answer the same question. Repeated or near-identical pages weaken intent signals, and large language models may cluster the variants and select an outdated one. Publishing more versions can therefore reduce your control over the answer rather than expand your reach.

    Audit duplicates by intent, not just by matching text. Two pages can use different wording and still compete for the same customer task. Conversely, pages built from the same template may deserve to remain separate when they contain genuinely different local rules, prices, eligibility conditions or offers.

    Create a working sheet with one row per indexable URL and these columns: primary question, audience, product or service, location or language, preferred URL, canonical target, last meaningful update and intended next action. Then classify each overlapping page:

    1. Keep: It is the strongest, current page for a distinct intent. Make it the preferred destination and link to it consistently.
    2. Differentiate: It serves a real audience or intent that the primary page does not. Add meaningful differences in examples, terminology, regulations, eligibility, availability or pricing. A swapped place name is not a local strategy.
    3. Consolidate: It no longer deserves a separate destination. Move useful information into the preferred page and use a permanent redirect when the old URL is being retired.
    4. Canonicalize: The variant must remain accessible, but search systems should select another version. Point the canonical tag to the preferred page and keep internal linking consistent with that choice.
    5. Exclude: The page should not participate in discovery. This can apply to staging, archives and republished copies that exist for another operational purpose.

    Campaign pages need the same discipline. Keep a separate landing page when the campaign changes the offer, audience, season, location or other decision context. If only the tracking code and headline change, use one primary interaction page rather than creating a cluster of weak alternatives.

    Localization also requires more than duplicate translation or regional labels. Publish separate regional pages when the content answers a materially different need, use accurate language and regional targeting, and include the local facts a buyer must know. Otherwise, prefer a single strong page over multiple same-language pages serving an identical purpose.

    Syndication can create the same ambiguity across domains. Ask republishing partners to canonicalize to the original, publish a meaningfully reworked version or exclude the copy from indexing. A byline or backlink alone does not tell every retrieval system which full-text version should represent the claim.

    Do not apply redirects or canonical changes to a large group of valuable pages without checking what each URL currently serves. A page that looks repetitive in a crawl may still satisfy a distinct query, campaign or local need. Test the classification on a small group, verify indexing and landing behavior, and then expand the cleanup.

    Make the decision and action layers legible
    An AI guide organizes evidence for a customer beside a clear illuminated path from evaluation to action.

    Give every important page a decision block

    An AI system should not have to assemble your position from a slogan, an old comparison page and a footnote in a downloadable file. Put the minimum complete decision near the top of the preferred page. This is not a demand for simplistic writing. It is a demand for explicit relationships between the question, answer, conditions and evidence.

    A useful decision block contains:

    • Direct answer: State what the product, service or recommendation does in the language of the customer’s question.
    • Best-fit conditions: Name the use cases, audience or constraints under which the answer applies.
    • Exclusions: State when the offer is unavailable or when another approach would be more appropriate.
    • Decision facts: Show the specifications, coverage, requirements, pricing basis or process details needed to compare options.
    • Evidence: Connect important claims to visible support rather than relying on adjectives such as leading, advanced or seamless.
    • Freshness: Display a meaningful update date and revise dependent pages when the underlying fact changes.
    • Next action: Link to the exact place where the visitor can check, calculate, contact, book, buy or continue.

    Write headings that identify the decision being resolved. A heading such as “Eligibility and exclusions” gives both a hurried reader and a retrieval system more information than “What you need to know.” Use tables only for real comparisons, and keep each row based on the same criterion. A table that mixes pricing, brand claims and feature descriptions looks structured while remaining difficult to evaluate.

    JSON-LD belongs behind this visible decision layer. Use it to identify the entities and properties already stated on the page, with the same names, URLs and current values. Do not put an offer, rating, date or availability status in structured data if the visitor sees something different. Machine-readable markup can reduce ambiguity, but it cannot repair contradictory content or guarantee selection in an AI answer.

    Let agents relay or complete a task without guessing

    The machine visitor is usually an intermediary, not the person whose money, data or consent is at stake. Design the action path so an assistant can explain it clearly and an authorized agent can proceed only within the user’s intent.

    • Use stable action destinations. Send booking, checkout, application and contact traffic to durable URLs rather than temporary campaign variants.
    • Expose prerequisites before the action. State location limits, required documents, eligibility, fees, account requirements and expected next steps before asking for information.
    • Label controls by outcome. “Check availability” or “Request an assessment” is clearer than “Continue” because it describes what will happen.
    • Separate explanation from authorization. Public pages can make an offer understandable, while authenticated or consequential actions still require appropriate identity, consent and confirmation.
    • Return useful errors. If an option is unavailable, explain the failed condition and provide a valid alternative instead of sending the visitor back to a generic page.
    • Preserve a human route. Provide a clear support or contact path when the request is ambiguous, exceptional or too consequential to automate safely.

    This work also improves the human journey. Clear prerequisites reduce abandoned forms. Specific controls reduce misclicks. Visible constraints prevent a sales conversation from beginning with a misunderstanding. Agent readiness is largely the discipline of removing guesswork without removing safeguards.

    Measure selection, accuracy, handoff and outcome

    Referral traffic is useful but incomplete. Analytics can identify a source only when a visit arrives with recognizable referral information. It cannot see a recommendation that was copied, remembered or followed later through a branded search. Last-click reporting can therefore reward the final route while hiding the system that shaped the shortlist.

    Build a scorecard around four questions:

    LayerQuestionWhat to recordWhat a failure means
    SelectionDoes the brand appear for an eligible question?Prompt, platform, locale, date, brand inclusion and cited competitorsThe topic, entity or evidence may not be sufficiently clear or available
    AccuracyIs the answer current and supported?Correct claims, outdated claims, unsupported claims and missing conditionsImportant facts may be ambiguous, duplicated or stale
    HandoffDoes the answer lead to the preferred page?Cited URL, canonical status, landing experience and next actionThe system may be selecting a duplicate, weak or outdated destination
    OutcomeDoes the journey produce useful business activity?Identifiable AI referrals, qualified actions, conversions and self-reported discoveryVisibility may not align with intent, or the page may fail after retrieval

    Use a fixed, representative question set rather than collecting only flattering examples. Include discovery, comparison, verification and action questions. For each observation, preserve the exact wording and testing conditions so that later changes are interpretable. Separate questions for which your brand is genuinely eligible from questions where inclusion would be irrelevant.

    When an answer is wrong, diagnose the failure at the right layer:

    • If the correct page is absent, inspect crawlability, indexing, internal links, duplication and canonical signals.
    • If the page is selected but the claim is wrong, make the fact and its conditions explicit in visible content, then align structured data and dependent pages.
    • If the answer is accurate but cites an old URL, consolidate the old version and update internal destinations.
    • If the handoff is correct but nobody acts, inspect whether the page answers the comparison and qualification questions that precede the call to action.
    • If conversions appear without identifiable AI referrals, add a concise discovery question to sales or checkout research and treat the result as supporting evidence, not perfect attribution.

    Start with one high-value journey rather than rewriting the entire site. Choose a decision that already matters to the business, assign its preferred pages, consolidate competing versions, add the decision and action layers, and baseline the four-part scorecard. Expand only after an assistant can find the current page, describe its limits accurately and hand the person to a next step that requires no guesswork.
    References

  • AI Agent Analytics on Google Cloud: A Practical Setup Guide

    AI Agent Analytics on Google Cloud: A Practical Setup Guide

    If your content sits behind Google Cloud CDN, a rising bot count is not the answer you need. You need to know whether your measurement covers the pages that matter, which agents are reaching them, and what your team should do when the pattern changes.

    The practical goal is a trustworthy measurement chain from an agent request to a content decision. Build that chain carefully, and agent analytics can reveal coverage gaps, unusual behavior, and pages that deserve investigation. Build it loosely, and an incomplete log stream can send your SEO team in the wrong direction.

    Know what Google Cloud agent analytics can actually show

    Profound’s Agent Analytics connects with Google Cloud Platform through Cloud CDN to monitor how AI crawlers and agents interact with GCP-hosted content. That creates visibility at the content-delivery layer: an agent requests a resource, the measured delivery path observes the interaction, and the analytics system classifies and aggregates it.

    This is valuable evidence, but it has a strict boundary. An observed request does not prove that an AI system indexed the page, used its claims in an answer, cited your brand, or sent a visitor. Those are separate stages of the discovery journey.

    • Agent activity means a request associated with an AI crawler or agent reached the part of your delivery stack that you measure.
    • AI visibility means your content or brand appears in an AI-generated response for a relevant prompt.
    • Business impact means that visibility contributes to useful behavior such as a qualified visit, signup, inquiry, or sale.

    Keep those layers separate in your reporting. Agent analytics is strongest at the first layer. It can help you investigate the later layers, but it cannot establish them by itself.

    Coverage matters just as much as classification. Cloud CDN analytics can only describe requests that pass through the connected and measured path. A subdomain, application route, origin, regional setup, or content repository outside that path may be invisible. Before interpreting silence as a discovery problem, confirm that the page was observable in the first place.

    Design the measurement around decisions, not bot counts

    Start by writing down the decisions the data must support. This prevents an attractive activity chart from becoming a substitute for analysis.

    DecisionQuestion to answerAction the answer should trigger
    CoverageWhich priority content groups have observable agent activity?Investigate important groups with no activity, beginning with measurement and access checks.
    DistributionWhich agents, hostnames, and page groups account for the observed requests?Separate broad discovery from activity concentrated on a narrow or low-value part of the site.
    Change validationDid request patterns shift around a content, routing, or CDN change?Inspect the affected paths while treating timing as association, not automatic proof of cause.
    ReliabilityIs an apparent drop a content signal or a telemetry problem?Verify delivery coverage and ingestion before changing SEO strategy.

    You also need a page inventory outside the agent analytics platform. The inventory provides the denominator that request logs lack. Without it, you can count observed URLs but cannot tell whether the agents reached a meaningful share of the content you care about.

    • Group URLs by hostname and content type, such as product pages, documentation, editorial resources, comparison pages, and support content.
    • Assign each group a business role so that a request to an important decision page is not treated as equivalent to a request for a utility asset.
    • Record whether each group is expected to pass through the connected Cloud CDN path.
    • Mark recently published or materially revised groups so you can examine discovery patterns around real changes.
    • Preserve an unknown or unclassified automation category instead of forcing every suspicious request into a named AI-agent bucket.

    Do not begin with a universal target for how much agent traffic is good. A documentation library, ecommerce catalog, and corporate site have different content shapes and discovery patterns. Your useful reference point is your own verified baseline, segmented by agent and content group.

    Implement the Cloud CDN measurement path and validate it

    An isometric cloud CDN measurement path connects AI agent requests, edge servers, log events, and a validation checkpoint.

    The connector is only one part of the setup. The operational work is proving that the resulting data represents the delivery paths and URLs you think it represents.

    1. Map the request path. List the hostnames and content groups served through Cloud CDN, then identify routes that bypass it. Include alternate domains, localized sections, application routes, and other delivery paths that could make coverage partial.
    2. Connect the analytics integration with narrow access. Grant only the access needed for the relevant telemetry. Document the cloud identity, connected properties, responsible owner, and purpose so the setup can be audited later.
    3. Validate a matched sample. For requests classified as agents, compare the time, hostname, path, and available request details with the corresponding delivery evidence. Check time zones, query-string handling, path rewriting, and redirect behavior before comparing totals.
    4. Normalize URLs deliberately. Decide how to handle trailing slashes, query parameters, duplicate hostnames, localized variants, and canonical page groups. Do not merge parameters or routes when they produce meaningfully different content.
    5. Establish a clean baseline. Observe normal patterns before treating every movement as an SEO event. Keep agent identities and content groups separate so a change in one segment does not disappear inside a sitewide total.
    6. Assign an operating owner. Someone must maintain the URL taxonomy, review classification changes, investigate gaps, and record deployments that may explain shifts in the data.

    Run data-quality checks before every strategic interpretation

    • Coverage check: Confirm that the affected hostname and route still pass through the connected CDN configuration.
    • Ingestion check: Look for a broader loss or delay in incoming events before declaring that an agent stopped crawling.
    • Cache-awareness check: Do not use origin-only telemetry as your sole comparison. A request satisfied at the CDN edge may not reach the origin.
    • Classification check: Determine whether an agent label or identification rule changed. If classification relies partly on self-declared identity, spoofing and identity changes can distort the result.
    • URL check: Make sure redirects, rewrites, parameters, and canonical grouping have not split one page across several analytics rows or collapsed different resources into one.
    • Scope check: Separate a single-agent change from a sitewide change. They imply different investigations.

    Treat access telemetry as operational data. Use least-privilege permissions, keep access limited to people who need it, and align retention with your organization’s security and privacy requirements. Agent analysis does not require exposing more request data than the work actually uses.

    Turn agent activity into a disciplined investigation

    Two analysts examine clustered request signals and isolate an unusual path in a cloud operations workspace.

    Read the data as a diagnostic funnel. First ask whether the interaction could be measured. Then ask whether the agent could reach the content. Only after those checks should you investigate the content itself or connect the pattern to external visibility and business outcomes.

    • A priority page group has no observed activity: verify that the URLs are in your inventory, pass through the measured CDN path, and are accessible under your intended bot policy. If those checks pass, inspect discoverability, internal linking, content duplication, and whether the pages answer a distinct need.
    • Activity falls for a single agent: check that agent’s classification, identity behavior, and access path before making sitewide changes. Stable activity from other agents makes a universal delivery failure less likely, though it does not identify the cause by itself.
    • Activity falls across agents and content groups: investigate CDN routing, telemetry ingestion, access controls, and recent deployments before rewriting content. A broad drop is often a measurement or delivery question first.
    • Requests cluster on low-value pages: inspect why those pages are easier to discover than your primary resources. Compare navigation, internal links, URL consistency, duplication, and the clarity of each page’s purpose.
    • Activity rises after an update: record the association, then look for repetition across the affected content group. Do not call it an optimization win until independent outcome evidence also moves.
    • One page is requested repeatedly: do not assume it has greater authority. Repetition can reflect recrawling, volatility, a frequently changing resource, or inefficient access as well as genuine interest.

    A compact operating scorecard can include observed requests by classified agent, distinct requested URLs, the share of your priority inventory with any observed activity, distribution by content group, and the last observed interaction for important pages. Add delivery outcomes only when the connected telemetry actually exposes and defines them. Label every metric precisely so readers know whether they are seeing requests, URLs, pages, or external outcomes.

    Pair the scorecard with a change log for content releases, routing changes, access-policy updates, and analytics configuration changes. The log will not prove causation, but it gives your team specific hypotheses to test instead of encouraging a vague explanation for every spike or drop.

    Finally, connect agent activity to separate outcome evidence. Check whether the same content groups appear in relevant AI answers, earn citations or brand mentions, attract identifiable referrals, and support useful on-site actions. A crawler request is an upstream signal. It becomes strategically meaningful when you can trace it through the rest of the discovery and conversion path.

    Key takeaways

    • Google Cloud agent analytics is request-layer observability, not proof that an AI model used, cited, or recommended your content.
    • Map every hostname and content group to its Cloud CDN delivery path before interpreting missing activity.
    • Use a page inventory as the denominator; request logs alone cannot tell you how much priority content remains unseen.
    • Validate ingestion, classification, URL normalization, and cache behavior before making an SEO change.
    • Segment by agent and content group because a sitewide total can hide the pattern that explains the problem.
    • Connect crawler activity to independent visibility and business evidence before calling a movement a win or loss.

    Start with a domain whose content path you can map confidently. Define its priority page groups, verify that the Cloud CDN integration observes them, and document the first baseline. Once that measurement is trustworthy, expand the scope and let each new dashboard element answer a named decision rather than merely adding another count.

    References

  • How to Make Your Content and Site Ready for AI Search

    How to Make Your Content and Site Ready for AI Search

    If your pages perform in conventional search but rarely surface in AI-generated answers, publishing more copy is unlikely to solve the underlying problem. A machine may reach the page yet still struggle to identify its main subject, separate the answer from supporting detail, verify important claims, or determine what it is allowed to do next.

    An AI-ready site makes that chain explicit. Because AI systems can draw on inputs ranging from web crawls to licensed datasets, no single optimization can guarantee inclusion or citation. What you can control is whether your site is accessible, understandable, internally consistent, and useful. That means coordinating content, structured data, machine-readable context, controlled actions, and APIs instead of treating each as an isolated project.

    Key takeaways for an AI-ready website

    • Give every important page one clearly stated job, such as answering a question, explaining an entity, supporting a decision, or enabling an action.
    • Put the direct answer and its important qualifications in visible page content. Structured data should describe those facts, not introduce a second version of them.
    • Reduce ambiguity with stable names, explicit relationships, descriptive headings, canonical URLs, and links to supporting evidence.
    • Separate content readiness from action readiness. A page can be understandable without being safe for an AI agent to transact through.
    • Prioritize blocked access, incorrect claims, content-schema conflicts, and unsafe actions before cosmetic metadata or additional copy.

    Design each page around one answerable job

    AI optimization starts before schema. It starts with deciding what the page is supposed to help someone understand or accomplish.

    A page titled around a broad topic often tries to define a term, promote a service, answer several unrelated questions, compare alternatives, and capture a lead at the same time. A human can sometimes infer the intended path from the design. Automated systems have to resolve competing signals in the title, headings, navigation, body copy, metadata, and structured data.

    Write a plain-language page job before editing anything: “This page helps a qualified buyer determine whether this service supports their use case.” That sentence does not need to appear on the page, but the published content should fulfill it without making the reader assemble the answer from several sections.

    For an answer-oriented page, use this sequence:

    1. Name the subject. Use the full, consistent name of the product, organization, person, service, location, or concept being described.
    2. Answer the central question. Put the useful answer near the beginning rather than delaying it behind a promotional introduction.
    3. State the scope. Identify the audience, use case, region, plan, prerequisites, or other conditions that determine when the answer applies.
    4. Support the answer. Add definitions, evidence, examples, limitations, and links that let a reader verify or interpret the claim.
    5. Resolve the next decision. Tell the reader what to compare, check, read, or do next.

    Sentence construction matters as well. “It supports integrations” forces the reader and the machine to recover both the subject and the meaning of “integrations” from nearby text. “The service accepts customer records through its documented API” identifies the subject, capability, object, and mechanism. If authentication, account level, geography, or supported data format changes that claim, put the qualification in the same passage.

    This does not mean every sentence must sound mechanical. It means consequential claims should survive extraction from the surrounding design. A useful editing test is to copy the sentence into an empty document. If its subject, meaning, or scope disappears, rewrite it or keep the necessary qualifier attached.

    Do not turn this advice into a collection of thin question-and-answer pages. Create a separate URL when the question represents a distinct intent that deserves its own complete answer. Keep closely related questions on one page when they share the same subject, evidence, and next step.

    Use JSON-LD to clarify identity and relationships

    A central geometric entity is linked to several distinct objects through an orderly network of glowing connections and nested frames.

    Structured data is a translation layer between the visible page and a machine-readable representation of it. It is not a substitute for the page, a place to hide extra keywords, or a ranking coupon.

    Start by identifying the main entity. An organization page should primarily describe the organization. A service page should describe the service and connect it to its provider. A profile should distinguish the person from the organization that employs or publishes them. An informational page should make its subject, author or publisher, and relationship to the rest of the site clear.

    Then build the smallest accurate JSON-LD graph that represents what a visitor can verify. More properties do not automatically create more meaning. Every additional property creates another fact that can become stale, conflict with visible copy, or imply a relationship the page does not establish.

    Use these rules when reviewing the graph:

    • Keep identity stable. Use the same name and persistent identifier for the same entity across templates. Do not create what appear to be several unrelated entities merely because different pages generate their markup independently.
    • Connect related entities explicitly. Represent the relationship between a service and its provider, a person and an organization, or a page and its publisher when that relationship is real and relevant.
    • Match visible facts. Names, descriptions, eligibility conditions, important values, dates, and other material details should agree with the content a visitor sees.
    • Choose types by meaning. Select the type that describes the real object on the page, not the type that appears to offer the most fields or the most attractive search treatment.
    • Omit unsupported claims. If a fact cannot be confirmed from the page or a connected authoritative page, do not add it only to make the markup look complete.
    • Validate meaning as well as syntax. Markup can be syntactically valid while identifying the wrong main entity, reversing a relationship, or carrying obsolete information.

    The most important review is a parity check between what people read and what machines receive. Ask who or what the page is about, what it claims, who is responsible for it, which conditions limit those claims, and where the supporting detail lives. The answers should be the same whether you inspect the rendered content or the JSON-LD.

    Template ownership is essential here. If an editorial team updates a page while a developer, plugin, or feed controls its schema, the two versions can drift. Assign one owner for each underlying fact and generate both representations from that maintained value where your publishing system permits it.

    Make important evidence easy to crawl and verify

    A clear answer is useful only if an automated visitor can reach it in a dependable form. Review the published page as an anonymous visitor, not only through the content-management preview.

    Put the essential answer, qualifications, and entity names in accessible page text. If a critical fact appears only after a click, inside a stateful widget, behind an account prompt, or after a personalization step, treat it as less dependable for automated extraction. Interactive features can still improve the experience, but they should not be the only location of information needed to understand the page.

    Check the technical path as well:

    • Confirm that the preferred URL returns the intended page to an unauthenticated request and does not resolve to a soft error, challenge screen, or unrelated fallback.
    • Use one canonical destination for materially identical versions instead of making systems choose among conflicting URLs.
    • Make titles and headings describe the page content. A clever label that omits the subject creates avoidable ambiguity.
    • Link important pages from relevant navigation or body content. Do not rely on an internal search box as their only route of discovery.
    • Review robots controls, page-level indexing directives, authentication rules, and content-delivery protections together. A page can be public in the browser yet unavailable to a particular automated request.
    • Keep essential assets available when they are required to render or interpret the content, while preserving appropriate security controls.

    Do not respond to an access problem by allowing every bot through every layer of the site. Administrative areas, personal information, unpublished material, expensive dynamic endpoints, and account-specific pages need protection. The goal is deliberate access to publishable information, not indiscriminate exposure.

    Verification is the next layer. Give substantive claims enough context that another system can distinguish a fact from promotional language. Name the responsible organization or person where it matters. Explain the basis of a claim. Link to the page that defines a policy, method, limitation, or data point. If an important statement is conditional, attach the condition to the statement rather than burying it elsewhere.

    Dates deserve particular care. Updating a displayed date without materially reviewing the content creates a freshness signal that the page cannot support. When something changes, revise the affected claim, its visible date where appropriate, its structured representation, and any dependent pages. When nothing changed, leave cosmetic freshness alone.

    Discovery, live retrieval, and inclusion in model data should not be treated as the same event. Making a page crawlable does not guarantee that an AI service will select, quote, cite, or learn from it. Build for dependable access and interpretation because those are necessary qualities you can inspect, not because they promise a placement you cannot control.

    Treat agent actions as a controlled product surface

    An abstract AI agent passes through layered permission and confirmation gates while blocked routes end at protective barriers.

    Answer engines mainly need to understand information. Agents may also attempt to complete a task. That changes the optimization problem from “Can the system interpret this?” to “Can the system perform the intended operation without creating unacceptable risk?”

    Separate read operations from write operations. Looking up availability, retrieving documentation, or checking status generally has a different risk profile from placing an order, sending a message, changing an account, booking an appointment, or deleting a record. Do not expose a broad administrative function when a narrowly scoped operation would satisfy the user’s intent.

    For every supported action, define:

    • The intent: what the action does, and what it explicitly does not do.
    • The required inputs: which fields are mandatory, which formats are accepted, and which values are rejected.
    • The authorization boundary: who may invoke the action and which records or capabilities that identity may access.
    • The preview: what will change, what it will cost, and which destination or account is affected before a consequential operation is committed.
    • The confirmation rule: which paid, destructive, externally visible, or difficult-to-reverse actions require explicit approval.
    • The response contract: how success, partial completion, validation failure, denial, and temporary failure are represented.
    • The recovery path: whether a request can be retried safely, cancelled, reversed, or handed to a person.
    • The audit trail: what was requested, which identity authorized it, what changed, and how access can be revoked.

    Validate all inputs on the server side even when the interface already constrains them. Apply rate controls and abuse protections according to the operation’s cost and sensitivity. Use request identifiers or another duplicate-handling mechanism for actions that could be repeated after a timeout. Otherwise, a harmless retry can become a second purchase, message, or booking.

    A public API is not automatically an agent-ready API. The interface still needs a clear contract, appropriately scoped authentication, predictable errors, and a supported integration path. Conversely, you do not need to expose an action API merely to claim that your site is AI-ready. If safe execution is not part of the user journey, accurate machine-readable information is the correct boundary.

    Audit AI readiness in the order that reduces risk

    Do not begin with an unrestricted site-wide rewrite. Start with the page templates tied to your most important questions, decisions, and transactions. A focused audit makes it easier to find the recurring defect and correct it at the template or data-model level.

    For each selected page, mark every checkpoint as pass, partial, or fail:

    1. Page job: Can you state in one sentence what the page helps a visitor understand or do?
    2. Direct answer: Does the visible content answer that job early, with its important scope and limitations attached?
    3. Entity clarity: Are the main subject, responsible organization, related entities, and their relationships unambiguous?
    4. Structured-data parity: Does the JSON-LD represent the same facts as the visible page without hidden, stale, or conflicting claims?
    5. Access: Can an anonymous request reach the preferred URL and the information needed to interpret it?
    6. Evidence: Can a reader follow the definitions, supporting pages, policies, or other context behind consequential claims?
    7. Action safety: If the page supports an operation, are permission, validation, confirmation, failure, retry, and recovery behavior defined?
    8. Ownership: Is someone responsible for updating the visible content, structured representation, and connected interfaces when a fact changes?

    Fix failures in consequence order. Blocked public content, factually wrong pages, schema-content conflicts, leaked private information, and unsafe write operations come first. Ambiguous subjects, hidden qualifications, and inaccessible evidence come next. Redundant wording and optional markup fields can wait.

    When the same problem appears across several pages, stop editing URLs individually. Trace the defect to the template, shared content field, entity record, plugin configuration, or API contract that generated it. A durable fix should make the correct state easier to maintain than the incorrect one.

    Begin with one high-value template this week. Define its job, rewrite the direct answer, align its JSON-LD, inspect anonymous access, and document who owns each important fact. Once that template passes, apply the same model to the next page family and turn the checks into part of publishing rather than an occasional cleanup.

    References

  • OpenAI Agent Automation Tools: A Practical Build Guide

    OpenAI Agent Automation Tools: A Practical Build Guide

    You have a recurring marketing workflow that is too judgment-heavy for a simple rule and too repetitive to justify doing by hand. That is a sensible place to consider an OpenAI agent. The mistake is handing it a broad objective such as “manage PPC” or “run content operations” before you have defined what it may read, decide, change, and escalate.

    OpenAI’s AgentKit brings visual workflow building together with familiar tools such as Gmail and Dropbox, reducing how much glue code may be needed around an agent. That makes construction easier. It does not remove the harder work: designing a workflow that produces useful results without creating expensive surprises.

    Give the first agent a narrow outcome, not a department

    An agent is most useful in the gap between rigid automation and unrestricted human judgment. It can interpret messy inputs, choose among permitted actions, and use connected tools. It should not be treated as an autonomous employee with an implied understanding of your business.

    Start with a workflow that has a recognizable trigger, a bounded decision, a small set of tools, and an output you can inspect. A strong candidate can usually be described in one sentence: “When this event occurs, use these approved inputs to prepare this defined result for this person or system.”

    • Turn campaign data into an exception brief that identifies what needs a human decision.
    • Collect approved reporting inputs, prepare a dashboard entry, and draft the accompanying client summary.
    • Check draft ad copy against explicit brand rules and flag the exact rule behind each problem.
    • Prepare a meeting agenda from an approved account summary and unresolved action items.
    • Review an existing content brief for missing entities, unanswered questions, or unsupported claims before publication.

    Each example ends in an inspectable artifact. None asks the agent to “improve performance” without defining what improvement means or what authority the agent has.

    Use a simple eligibility test

    Before building, answer the following questions. If several answers are unclear, the process is not ready for an agent yet.

    • What exact event starts the workflow?
    • Which systems contain the facts the agent is allowed to use?
    • Which part requires interpretation rather than a fixed rule?
    • What does a complete output contain?
    • How can a reviewer verify the result without recreating all the work?
    • What is the worst plausible result of a wrong decision?
    • Can that result be prevented with permissions, validation, or approval?

    A poor starting workflow has an ambiguous goal, no authoritative data source, broad credentials, and no obvious stopping point. It may still be worth redesigning, but adding an agent will not repair those weaknesses.

    Know when ordinary automation is enough

    If the same input should always produce the same action, use a deterministic rule. Scheduling a recurring run, checking whether a required field is empty, applying a known naming convention, and moving an approved file do not require model judgment.

    Use an agent for the step that genuinely needs interpretation: classifying an unusual campaign change, reconciling context from a client email with a performance report, or explaining why draft copy conflicts with a brand rule. The strongest design is often a hybrid. Conventional automation handles triggers and validation; the agent handles a bounded judgment; conventional automation checks the output and routes it to the next stage.

    Separate facts, reasoning, actions, and controls

    A four-part automation model separates source records, a reasoning chamber, an action mechanism, and an independent control frame with locks and an approval gate.

    A visual canvas can make a complicated workflow look like one continuous chain. Operationally, you should still treat it as distinct layers. That separation tells you where an error started and which safeguard should catch it.

    LayerIts jobMarketing exampleMain failure to prevent
    FactsRetrieve authoritative input without changing itCampaign data, an approved brief, or brand rulesUsing stale, incomplete, or unapproved material
    ReasoningClassify, compare, prioritize, or draftExplain which exception deserves reviewProducing a plausible conclusion that the evidence does not support
    ActionWrite or send an approved result through a toolCreate a report draft or update a workflow statusChanging the wrong record or acting before approval
    ControlValidate, log, stop, or request authorizationRequire evidence fields and approval before publicationAllowing an error to pass silently into a consequential action

    Your language model should not become the system of record. Let tools retrieve facts from the authoritative system, and require the agent to preserve the identifiers that connect every conclusion to those facts. If it says a campaign needs attention, the output should identify the campaign, the relevant observation, the input used, and the proposed next step.

    Policies deserve the same separation. Brand requirements, approval rules, prohibited claims, and escalation conditions should be maintained as explicit instructions or structured data. Do not hide critical policy in an example and expect the agent to infer that the example is binding.

    A useful division of labor is straightforward: tools fetch facts, the agent interprets them, deterministic checks validate required conditions, and a person approves consequential changes. You can relax an approval later if the workflow earns that authority. Recovering from an unreviewed budget change or public claim is much harder.

    Write an executable contract before you build

    The workflow specification is the real product. The canvas, model, prompts, and connectors implement it. Write the specification in operational language that a reviewer can challenge before the agent touches live data.

    1. Define the outcome. Name the artifact or state the workflow must produce, not the general business goal it supports.
    2. Define the trigger. Identify the approved event, schedule, or human request that starts a run.
    3. Define the inputs. List the allowed systems, records, fields, and policy documents. State which one wins if two inputs conflict.
    4. Define the decision. Explain what the agent may infer and the criteria it must apply.
    5. Define the output. Require a stable structure with evidence, unresolved questions, and approval status.
    6. Define the tools. Grant only the operations needed for this workflow.
    7. Define the boundaries. State forbidden actions, stop conditions, and matters that always require escalation.
    8. Define completion. Say what must be true before a run can be marked successful.
    9. Define the evidence trail. Preserve the input references, tool results, output, approval, and final action.

    A practical specification for a PPC reporting agent

    Suppose you want an agent to prepare a campaign exception brief. The specification could read like this:

    • Outcome: prepare a review brief describing campaign exceptions; do not optimize the account.
    • Trigger: an approved reporting request with an account identifier and reporting context.
    • Inputs: current campaign data, the agreed comparison context, active brand rules, and unresolved items from the previous review.
    • Allowed decisions: group related observations, rank them by the supplied business criteria, and propose questions or next actions.
    • Required output: campaign identifier, observation, supporting evidence, applicable rule or objective, proposed action, uncertainty, and approval status.
    • Allowed actions: read approved inputs and create a draft in the designated location.
    • Forbidden actions: change bids or budgets, alter targeting, send client communications, publish copy, or invent a missing value.
    • Stop conditions: required data is missing, identifiers do not match, instructions conflict, or a tool returns an uncertain result.
    • Approval: the account owner reviews the brief before any recommendation enters a live campaign workflow.
    • Completion: every recommendation has evidence, every unresolved issue is labeled, and no prohibited action was attempted.

    This contract turns a vague assistant into a bounded operator. It also makes evaluation possible. A reviewer can test whether the agent followed each condition instead of debating whether the response merely looked intelligent.

    Express authority with precise verbs

    Words such as read, classify, draft, propose, update, send, publish, and delete represent very different levels of authority. Use them deliberately. “Handle the client report” conceals several decisions. “Read approved campaign data, draft the report summary, and request approval” exposes them.

    Do the same with uncertainty. If a required value is absent, tell the agent to stop or label the gap. Never ask it to complete a record using “the most likely” value unless inference is explicitly acceptable and clearly marked. A polished guess is still a data-quality failure.

    Place controls at the action boundary

    Permissions should follow a ladder. Reading is less consequential than drafting; drafting is less consequential than committing a database change; an internal change is usually less consequential than sending a message, publishing content, or changing advertising spend.

    • Begin with read-only access wherever the workflow allows it.
    • Write drafts to a staging location rather than replacing an approved asset.
    • Require a human decision immediately before an external, public, financial, destructive, or difficult-to-reverse action.
    • Use separate credentials or scoped permissions so one workflow cannot inherit unrelated authority.
    • Require the tool to return a stable record identifier and confirmation before the agent treats a write as successful.
    • Make repeated runs safe. A duplicate trigger should find the existing draft or action record rather than create another one.
    • Log the request, retrieved input references, tool calls, result, approval, and final action in a form that can be reviewed later.

    Connected email and document stores introduce another boundary: retrieved content is data, not authority. An email, attachment, or cloud document may contain text that tells the agent to ignore its rules or use another tool. The workflow should treat those instructions as untrusted unless they arrive through the approved control path. Keep system instructions, business policy, and retrieved content distinct.

    Test the agent’s failures before trusting its successes

    An engineer observes an automated agent being tested against missing inputs, conflicting records, unavailable tools, and a blocked unsafe action in a simulation lab.

    A smooth demonstration proves that the happy path can work. It does not show what happens when data is absent, tools fail, instructions conflict, or the same event arrives twice. Those cases determine whether the automation is fit for routine use.

    Build a test set from the ways the real workflow can break. It should include:

    • An ordinary case with complete, consistent inputs.
    • A case with a required input missing.
    • A stale, malformed, or mismatched record.
    • Two approved inputs that disagree.
    • An ambiguous request that permits more than one interpretation.
    • Retrieved content containing instructions the workflow must not obey.
    • A tool timeout, rejection, or incomplete response.
    • A duplicate trigger for a run that already produced an output.
    • A proposed action that violates a brand, permission, or approval rule.
    • A case where the correct behavior is to stop and ask for help.

    Score behavior against the contract, not writing quality. Check whether the conclusion is supported, required fields are present, prohibited actions are avoided, tool results match the intended record, and uncertainty is visible. Also record how much human correction the result needs. An agent that saves preparation time but creates a difficult verification job has moved the work rather than removed it.

    Roll out in stages

    Start in shadow mode: let the agent process real workflow inputs without writing to production systems or contacting anyone. Compare its proposed output with the existing process, classify the differences, and revise the contract or controls when the same error pattern returns.

    Next, allow draft creation while keeping approval mandatory. Expand authority only after the defined test set and real shadow runs show that failures are visible and contained. Increase one dimension at a time, such as the range of accepted inputs or the ability to update an internal status. If you broaden the workflow and its permissions simultaneously, you will not know which change caused a new failure.

    Monitor the operating result after launch. Useful measures include successful completions, stops and escalations, human edits, attempted policy violations, tool failures, duplicate prevention, and time saved after review and recovery work are included. Review the failure categories themselves. A rising cluster of missing-data errors may point to an upstream process problem rather than a prompt problem.

    Keep rollback practical. Preserve the previous state for reversible updates, retain the identifiers returned by action tools, and document how a reviewer disables the workflow without disabling unrelated automations. If a safe rollback is impossible, keep a person at the commit boundary.

    Key takeaways

    • Choose a narrow workflow with a clear trigger, bounded judgment, limited tools, and a verifiable output.
    • Keep deterministic triggers and validation outside the model; use agent reasoning only where interpretation adds value.
    • Treat the workflow specification as an executable contract covering inputs, decisions, outputs, permissions, stops, and evidence.
    • Start with read or draft access and require approval before public, financial, destructive, or difficult-to-reverse actions.
    • Treat email, attachments, and retrieved documents as untrusted data rather than instructions.
    • Test missing data, conflicting instructions, tool failures, duplicate events, and safe escalation before expanding authority.
    • Measure correction and recovery work as well as successful task completion.

    Pick one recurring workflow and write its contract before opening the visual builder. If you cannot identify the authoritative inputs, forbidden actions, approval point, and proof of completion on one page, narrow the job again. Once those boundaries are clear, OpenAI’s agent tools can automate the judgment bottleneck without quietly taking control of the whole operation.

    References

  • AI-Driven Commerce: Build for Search, Answers and Agents

    AI-Driven Commerce: Build for Search, Answers and Agents

    If a shopper needs six tabs and a set of notes to understand the differences between your products, your catalog has a data problem disguised as a user-experience problem. AI can now perform much of that comparison before the shopper reaches your site, so a polished product page is no longer your whole sales surface.

    Your job is not to choose between Google and ChatGPT. It is to give search engines, answer engines, and emerging shopping agents the same accurate, decision-ready facts, then measure how each channel moves the buyer toward a transaction.

    The commerce journey has expanded, not moved

    AI search is adding another discovery and evaluation layer. It is not yet a reason to abandon conventional search. Search engines still account for about 88% of search traffic, while AI usage is growing alongside it. For ecommerce specifically, Google organic search reportedly supplies 43% of traffic and supports 23.6% of sales. Those figures are directional rather than a forecast for your store, but they make the strategic choice clear: protect traditional search visibility while building AI visibility.

    A buyer may ask an AI assistant to shortlist products, use Google to verify a feature, open your product page to check availability, return to the assistant with a compatibility question, and later make a branded search before purchasing. If you measure only the final click, you can mistake a multi-channel decision for a single-channel conversion.

    SurfaceWhat the buyer needs thereWhat you should provide
    Traditional searchDiscovery, navigation, and verificationIndexable product, category, comparison, and supporting pages
    AI answerA concise explanation or recommendationDirect answers, complete context, explicit differences, and verifiable claims
    Shopping agentFacts it can retrieve and evaluate consistentlyStructured product, offer, variant, compatibility, and policy data
    Your websiteConfidence and a path to purchaseClear evidence, current commercial details, usable navigation, and checkout

    Do not run these as four disconnected strategies. They are four presentations of the same catalog. A processor name, supported device, price, included accessory, or return condition should not change depending on whether it appears in page copy, JSON-LD, a merchant feed, or an internal API.

    This changes the meaning of search optimization. You are no longer optimizing only for a ranking and a click. You are optimizing the information chain that lets a machine discover a product, distinguish it from alternatives, explain the distinction, and hand the buyer an accurate next step.

    Build product content around decisions, not descriptions

    Most product pages describe one item at a time because that is how a seller organizes a catalog. Buyers usually think in differences: what changes between the base and premium versions, which missing feature matters, whether two names describe the same capability, and whether the extra cost solves their actual problem. That gap is why even a built-in comparison tool can leave a shopper with more questions than answers.

    Start with the product families that generate repeated comparison questions, not necessarily the products with the most visits. A product with modest traffic but high consideration can benefit more from better decision content than a familiar commodity with substantially more visits.

    1. Define the real choice set. Group models, plans, sizes, generations, or substitutes that a reasonable buyer would compare. Your internal category structure may not reflect that choice set.
    2. Normalize the attributes. Use the same name, unit, and value format for the same characteristic. Do not call a field “battery duration” on one page and “typical runtime” on another unless they measure different things.
    3. State absence explicitly. A blank cell is ambiguous. Use language such as “not included,” “not supported,” “optional,” or “information not provided,” whichever is accurate.
    4. Translate specifications into consequences. Give the factual specification first, then explain why it could matter. If you cannot verify a practical consequence, do not manufacture one from a marketing adjective.
    5. Separate fact from recommendation. “Includes 256 GB” is a product fact. “Better for frequent offline video” is guidance that needs a visible rationale.
    6. Surface checks before the purchase. Put compatibility, required accessories, regional limitations, account requirements, and other decision-changing conditions beside the relevant claim instead of burying them in a general FAQ.
    7. Assign maintenance ownership. Every comparison needs an owner and a review trigger when a model, offer, specification, or policy changes.

    The opening of a comparison page should answer the decision before expanding on it. A practical template is: “Choose [product] when [need] because [verified differences]. Choose [alternative] when [different need]. Before buying, verify [important condition].” This gives a person a usable answer and gives an answer engine a compact passage it can interpret without reconstructing your position from scattered sections.

    Then support that answer with a complete comparison. Cover the questions that change the purchase:

    • Which capabilities are shared, and which are genuinely different?
    • What does the higher-priced option add?
    • What does each option leave out?
    • Which differences affect a defined use case?
    • Which accessories, subscriptions, or compatible devices are required?
    • What should the buyer verify before ordering?
    • When were the facts last checked?

    Do not turn this into keyword stuffing. AI systems interpret topics through connected concepts, so useful coverage means answering the related questions needed to understand the decision. Content about an eco-friendly product, for example, may need to explain its materials, relevant trade-offs, maintenance, and disposal. It does not need twenty variations of the phrase “sustainable product.” Clear topical relationships support both conventional and AI search performance.

    Keep each claim close to its proof. If you say a model works with a particular device family, identify the supported versions or link to the maintained compatibility information. If you say an option is better for a use case, show the differences that lead to that recommendation. A machine can repeat an unsupported conclusion as easily as a supported one; the structure of your page should make the distinction visible.

    Turn the catalog into a machine-readable product record

    A product floats above connected tiles representing its materials, dimensions, compatibility, availability, and shipping details.

    A webpage can make a price, specification, or model relationship obvious to a person without expressing its meaning explicitly to a machine. HTML is excellent for presentation, but visual proximity alone does not guarantee semantic clarity. Structured data exists to reduce that ambiguity, yet its implementation remains uneven.

    JSON-LD is not a replacement for a useful product page. Treat it as a translation layer between your governed catalog record and systems that need an explicit description of the entity. For a commerce implementation, inspect six groups of information:

    • Identity: the canonical product name, brand, internal SKU, and legitimate global identifier where one exists.
    • Variant relationships: the attributes that create distinct variants, such as size, color, capacity, model, or configuration, plus the relationship between each variant and its product family.
    • Commercial state: price, currency, availability, condition, seller, and the offer or variant to which each value applies.
    • Decision attributes: the measurable specifications, compatibility statements, included items, requirements, and exclusions that buyers use to compare options.
    • Policies and evidence: the maintained pages or records behind shipping, returns, warranties, ratings, and other claims you choose to expose.
    • Freshness controls: the system responsible for each field, its update trigger, and a way to detect disagreement between surfaces.

    Use the Schema.org Product vocabulary for an individual product representation and connect its Offer data where appropriate. The exact markup should follow the product and offer you actually display. Do not add a field because it looks advantageous in a validator. Do not mark up a family-level price as if it applied to every variant. Do not publish review or rating data in JSON-LD if a user cannot find the corresponding information on the page.

    Five implementation rules prevent most damaging inconsistencies:

    1. Match visible content. The machine-readable value and the customer-facing value should describe the same product, offer, and condition.
    2. Preserve identifiers. Do not reuse an SKU or global identifier across unrelated products. Stable identifiers help systems reconcile records from multiple surfaces.
    3. Include units and qualifiers. A number without its unit, measurement condition, region, or variant can create a confidently wrong comparison.
    4. Update dynamic fields from the catalog system. Manually copied price and availability values become stale. Generate them from the same maintained record used by the page whenever your stack permits it.
    5. Validate meaning as well as syntax. Passing a structured-data test proves that the markup parses. It does not prove that the claims are current, complete, assigned to the right variant, or useful for a purchasing decision.

    The proposed idea of an AI data interface, or AIDI, imagines a future in which personal agents retrieve structured information more directly instead of interpreting every business through a traditional page. The label and adoption path are uncertain. The durable requirement underneath it is not: reusable, well-defined product data will be easier to publish into pages, JSON-LD, feeds, and future interfaces than facts trapped in layout-specific copy.

    That is the sensible way to prepare for agents. Do not rebuild your commerce stack around a prediction that HTML will disappear. Move decision-critical facts into a governed catalog record, make each output consistent, and keep the human page strong. This improves the current experience while preserving options for whatever interface gains adoption.

    Measure discovery, influence, and revenue separately

    Three connected visual zones show signals being discovered, product options influencing a shopper, and a final path ending in a purchase.

    A dashboard that reports only organic clicks cannot tell you whether an AI assistant introduced the product and Google completed the journey. A dashboard that reports only AI referrals has the opposite problem: a shopper can read an answer, remember the brand, and return through branded search or direct navigation.

    Build measurement in three layers. The layers answer different questions and should not be collapsed into one visibility score.

    • Answer visibility: Is your brand or product named for the questions that matter? Is your site cited? Is the description accurate? Which competing products appear?
    • On-site behavior: Which AI referrals reach the site? What landing pages do they use? Do they view products, use comparisons, start checkout, or leave after encountering a mismatch?
    • Commercial outcome: Which journeys produce orders, revenue, qualified leads, or assisted conversions? How does that performance differ by landing page and intent?

    Keep a fixed prompt set for monitoring. Include category discovery, named product comparisons, use-case recommendations, compatibility questions, and pre-purchase checks. Record the exact prompt, platform, model or mode when visible, date, products mentioned, citations returned, and factual errors. A single answer is an observation, not a stable ranking. Repeating the same controlled set gives you a more useful view of change.

    In analytics, create a distinct channel group for identifiable AI referrals instead of silently mixing them with ordinary organic search. Preserve the landing URL and conversion path. Add a post-purchase or lead-form question about where the customer first researched the purchase; referral data alone cannot reveal every AI-influenced journey. Compare revenue and assisted outcomes, not just visits.

    Use the combination of metrics to diagnose the next change:

    • If your products are mentioned but described incorrectly, fix catalog consistency and claim clarity before creating more content.
    • If relevant pages rank in conventional search but rarely appear in AI answers, strengthen the direct answer, comparison structure, supporting context, and entity relationships.
    • If AI citations increase but qualified visits or conversions do not, inspect whether the cited passage promises something the landing page does not make easy to verify.
    • If visits convert but visibility remains narrow, expand the proven content and data pattern to adjacent product families.
    • If price or availability differs across surfaces, stop scaling and repair the update path. More visibility would only distribute the error further.

    You can put this into operation with a four-week pilot:

    1. Week 1: Establish the baseline. Select up to ten high-value product families with meaningful comparison friction. Inventory their visible facts, JSON-LD, feed values, AI answers, organic landing pages, and conversion paths. Record every contradiction.
    2. Week 2: Publish the decision layer. Create or revise one comparison experience per family. Lead with the choice, normalize attributes, state missing features, explain practical consequences, and add the checks that could change the purchase.
    3. Week 3: Align the data layer. Map identity, variants, offers, and decision attributes back to the maintained catalog. Correct structured data and feed discrepancies. Add validation to the publishing workflow.
    4. Week 4: Retest and connect outcomes. Run the same prompt set, review search visibility, verify cited claims, inspect landing behavior, and connect conversions to identifiable search and AI touchpoints. Use the defects you find to define the next product group.

    The pilot is successful when it creates a repeatable publishing and measurement loop, not merely when one prompt mentions your brand. The operational asset is a product record that stays accurate across channels and a content pattern that helps buyers make a decision.

    Key takeaways

    • Do not replace SEO with AI optimization. Buyers can use both channels during one purchase, and organic search still carries substantial ecommerce demand.
    • Organize product content around the differences buyers need to evaluate, not the order in which your catalog happens to store products.
    • Give direct recommendations a visible factual basis, including exclusions, compatibility conditions, and pre-purchase checks.
    • Keep page content, JSON-LD, feeds, and interfaces aligned to one governed catalog record.
    • Measure answer visibility, factual accuracy, on-site behavior, and commercial outcomes as separate layers.
    • Prepare for agents by improving reusable product data now, without betting your business on a specific interface or a predicted end of HTML.

    Start with one product family your customers routinely struggle to compare. Build its fact matrix, publish the decision clearly, map the same facts into structured data, and track the path through Google and AI answers. Once that loop stays accurate, scale it across the catalog. You will gain a better shopping experience now and a cleaner route into agent-driven commerce later.

    References

  • How to Build an AI-Era Search Marketing Team and Career

    How to Build an AI-Era Search Marketing Team and Career

    If your search marketing role is described mainly as keyword lists, briefs, audits, drafts and reports, AI makes the job look easy to compress. That description leaves out the work a company still needs: choosing the right problem, setting an evidence standard, connecting search activity to customer outcomes and taking responsibility when automation is wrong.

    You do not need to predict what every model will do next. You need an operating model that can absorb changing capabilities without surrendering judgment. The framework below will help you redesign roles, decide which workflows deserve automation, protect the entry-level career ladder and show that your own value extends beyond producing deliverables.

    Move your value from production volume to controlled decisions

    AI can reduce routine production and create more room for strategy, creativity, testing and optimization. That does not automatically make a team more strategic. A team can use the time it saves to produce more low-value pages, reports and variants. The career advantage belongs to the marketer who can decide what should be produced, what should be rejected and what evidence would justify the next action.

    Start by auditing recurring work according to risk and judgment, not according to how impressive the tool demonstration looks. For each workflow, answer these questions:

    • Consequence: What happens if the output is wrong? A weak title suggestion and an incorrect crawl directive do not belong in the same risk class.
    • Detectability: Will a person or automated check catch the error before customers, search systems or advertising platforms encounter it?
    • Reversibility: Can the team undo the action cleanly, or could it affect indexing, tracking, customer trust or media spend?
    • Context dependence: Does success depend on unstated brand, product, legal or customer knowledge?
    • Accountability: Which named person owns the outcome after AI has contributed to it?

    Those answers lead to four useful classifications. Keep high-consequence decisions human-owned. Use AI to assist work that needs context but benefits from faster analysis or drafting. Delegate repetitive, reversible actions that have reliable checks. Stop work that exists only because an old process required it.

    The last category matters. Automating a report nobody uses does not create leverage; it preserves waste at a lower unit cost. Before automating anything, identify the decision the output is supposed to change. If no one can name that decision, remove or redesign the output.

    Your durable career assets are therefore problem framing, evidence evaluation, experimentation, technical judgment and cross-functional influence. Tool fluency still matters, but it should support those abilities. Knowing how to generate a draft is less valuable than knowing why the draft should exist, which claims it may make, how it will be checked and what result would cause you to revise the strategy.

    Give humans and AI explicit responsibilities at every handoff

    Five connected workstations show people defining, checking, and approving work while translucent machines sort and assemble abstract components between them.

    Calling AI a teammate is only useful when the team defines its authority. AI can contribute to activities such as quality assurance, translation and performance alerts, but those capabilities do not answer who approves a claim, resolves conflicting signals or accepts business risk.

    Map the search workflow as a sequence of accountable handoffs. A practical division of work looks like this:

    Workflow stageHuman accountabilityUseful AI contributionRelease condition
    Opportunity selectionChoose the customer problem, business objective and acceptable trade-offsGroup inputs, identify patterns and surface gaps for reviewA named owner approves the objective and priority
    Brief developmentDefine intent, audience, required evidence, exclusions and success criteriaOrganize approved inputs and propose structures or variantsThe brief states what must be true, not merely what must be written
    ProductionOwn claims, brand meaning and final editorial judgmentDraft, transform, classify or adapt material within the briefEvery substantive claim can be checked against an approved input
    Search and schema validationDecide whether the page and markup accurately represent the visible subjectFlag omissions, inconsistencies, broken links or mismatched fieldsTechnical checks pass and a person reviews consequential changes
    PublicationAuthorize changes that affect users, indexing, tracking or spendExecute approved, logged and reversible stepsThe team has an owner, a record of the change and a rollback path
    MonitoringInterpret performance in business and market contextWatch defined signals, detect anomalies and prepare alertsAn alert identifies the expected response and the person responsible

    Then assign an autonomy level to each workflow. At the lowest level, AI proposes and a person executes. At the next level, AI can execute a pre-approved, reversible action after human review. At a higher level, an agent can complete a sequence of permitted actions inside defined boundaries, while logging its work and escalating exceptions.

    Do not promote a workflow to greater autonomy merely because it worked once. Require representative test cases, known failure categories, an approval boundary, an observable activity log and a tested recovery procedure. The accountable person must also be able to explain the system without relying on the person who originally configured it.

    This is where standard operating procedures become more important, not less. Record the trigger, required inputs, permitted actions, prohibited actions, expected output, evaluation method, escalation condition and rollback procedure. Also record which model, tool configuration and knowledge inputs were used. Without that context, the team cannot distinguish a genuine strategy change from a system change.

    Rebuild the junior career ladder around supervised judgment

    A junior professional progresses through three supervised work platforms, reviewing generated cards, checking evidence pieces, and presenting a completed model to colleagues.

    Entry-level search marketers have traditionally learned through repetitive work: collecting queries, checking pages, preparing reports, writing first drafts and applying routine changes. Automating that work can free capacity, but removing it without a replacement also removes the practice through which people learn to notice errors.

    The answer is not to preserve repetitive work for its own sake. Redesign it as supervised judgment. A junior marketer should learn to inspect AI output, identify why it fails, correct it, improve the workflow and eventually own the result. That prepares them for a role in which early-career marketers may increasingly coordinate AI systems as part of their daily work.

    A useful development sequence is:

    • Observe: Compare an output with the brief and label defects rather than merely accepting or rejecting it.
    • Correct: Repair factual, editorial, technical and intent-related problems while documenting why the correction matters.
    • Control: Write the instructions, checks and escalation rules that prevent the same defect from recurring.
    • Own: Run the workflow, interpret its results and recommend whether it should be expanded, revised or retired.

    Managers need a common review rubric so feedback does not collapse into personal preference. Evaluate user-intent fit, factual support, entity clarity, technical validity, consistency with visible content and connection to the intended business decision. For structured data, for example, syntactically valid markup is not enough; the markup must describe what the page actually presents. For an AI-assisted content brief, fluent prose is not enough; the brief must preserve approved claims, constraints and audience needs.

    Give junior employees access to the reasoning behind senior decisions. A completed audit shows the answer, but an annotated audit shows why one issue was prioritized and another was deferred. A final content page shows the outcome, but a decision log exposes the trade-offs. This creates institutional memory that remains useful when team members, tools or models change.

    Promotion criteria should follow the same shift. Do not reward someone solely for producing more artifacts with AI. Reward the ability to reduce preventable defects, improve a repeatable process, explain uncertainty, escalate appropriately and connect work to a meaningful outcome. That is how you avoid creating a team of fast operators who cannot function when the system encounters an exception.

    Make remote AI operations legible instead of meeting-heavy

    Distributed search teams already depend on written context. AI increases that dependency because people now need to understand not only what colleagues decided, but also what an automated system saw, produced and changed.

    Begin with an honest distinction between remote-first and remote-friendly work. A remote-first team expects decisions and collaboration to work virtually. A remote-friendly employer permits remote work but may still place important conversations, access or advancement around an office. State which one you operate, along with location limits, expected overlap hours, response expectations and genuine offline boundaries.

    If you are hiring, test the behaviors the job requires. Give the candidate an imperfect AI-assisted deliverable and ask them to identify defects, missing context and risky assumptions. Ask which questions they would raise before acting. A candidate who can explain a cautious decision is showing more relevant ability than one who produces a polished answer without exposing its basis.

    If you are considering a role, ask where decisions are recorded, which working hours require overlap, who approves automated changes and how remote employees receive feedback. These questions reveal whether the company has an operating system or merely a collection of tools and meetings.

    Onboarding should cover the first week through 90 days, with access, training, supervised delivery and eventual workflow ownership made explicit. A new employee should know where to find:

    • Team responsibilities, escalation contacts and approval boundaries.
    • Workflow instructions, examples of acceptable output and known failure modes.
    • Approved tools, model configurations, data-handling rules and security practices.
    • Decision logs, experiment records and explanations of previous changes.
    • Definitions for business, search, content and quality metrics.
    • Feedback channels and the expected response when an automation fails.

    Keep credentials, private customer information and other sensitive data out of prompts and shared workflow documents unless an approved system and access policy explicitly permit their use. Convenience is not a substitute for data governance.

    Use meetings for disagreement, prioritization, coaching and decisions that need synchronous discussion. Put status, routine approvals and reusable explanations into shared systems. Every consequential meeting should leave behind a decision, an owner and the context needed by someone who was not present. That makes the team easier for both people and controlled automation to support.

    Use a 90-day transition to prove one workflow before scaling

    A team-wide AI transformation is too vague to manage. Use a 90-day horizon and choose a single recurring workflow with a limited blast radius, clear review criteria and a reversible outcome. Good candidates assist research organization, brief preparation, quality checks or anomaly detection. Poor first candidates automatically publish pages, alter crawl controls, change redirects or spend advertising budget; an error in those workflows can reach users or affect revenue before the team understands the failure.

    Run the transition in four parts:

    1. Inventory during the first week. Record the current trigger, inputs, handoffs, completion time, defect categories and decision the workflow supports. Separate necessary human judgment from repetitive handling.
    2. Pilot under supervision. Define approved inputs, prohibited actions, evaluation examples, review gates and stop conditions. Name the person who owns the business outcome, not merely the person configuring the tool.
    3. Harden the workflow. Add activity logging, exception handling, permission limits, version records, documentation and a recovery procedure. Train another team member to operate and challenge the workflow.
    4. Decide by day 90. Compare the result with the original process. Scale it only if quality is acceptable, failures are detectable, the saved effort is being redirected to higher-value work and the accountable owner can explain its operation. Otherwise revise or retire it.

    Update roles and performance reviews as part of that decision. The owner of the workflow should be evaluated on its outcome, quality and controls, not on the volume it generates. Managers should also track whether the system creates new capability across the team or concentrates knowledge in one operator.

    If you are building your own career, turn the pilot into a portfolio artifact without exposing proprietary information. Show the original problem, risk classification, human and AI responsibilities, evaluation rubric, failure discovered, control added and decision to scale or stop. On a resume, describe the business or workflow outcome and your accountable decision. Naming an AI tool without explaining what you governed proves very little.

    Key takeaways

    • Build your career around judgment, evidence, experimentation and accountability rather than the volume of assets you can produce.
    • Assign every AI-assisted workflow a human owner, an authority boundary, a release condition and a recovery path.
    • Replace repetitive junior work with structured practice in detecting, correcting and preventing defects.
    • Make remote operations explicit through written decisions, shared documentation, clear overlap expectations and visible feedback.
    • Prove a low-consequence, reversible workflow before granting AI greater autonomy or expanding it across the team.

    Your next move can be small. Map one recurring workflow, name the decision it supports and mark the point where human accountability must remain. That single map will tell you which work to automate, which skill to develop and which part of the team’s operating model needs attention first.

    References