Tag: AI Agents

  • How Google’s New Ad Tools Connect Measurement and Action

    How Google’s New Ad Tools Connect Measurement and Action

    Google is developing two different ways to reduce friction in advertising operations: stronger conversion inputs for advertisers and conversational analysis for publishers. One beta supplements website conversion actions with backend records; the other brings a Gemini-powered assistant into Google Ad Manager.

    The tools do not form a single workflow, and the supplied reports do not describe an integration between them. Together, however, they illustrate a broader operating model: improve the evidence used to judge performance, then make that evidence easier to investigate and act on.

    Two tools address different parts of the advertising cycle

    The distinction between the products matters. CrushPress.AI reported that Google’s supplemental conversion data beta is intended for advertisers using eligible website conversion actions in Google Ads. Ask Ad Manager, meanwhile, was reported as a conversational assistant for publishers working in Google Ad Manager.

    AreaSupplemental conversion dataAsk Ad Manager
    Primary userAdvertisers measuring website conversionsPublishers managing advertising inventory and delivery
    Core problemConversions that website tags may not captureTime spent building reports, investigating delivery and navigating the platform
    Main inputBackend transaction records from systems such as CRMs, order databases and ecommerce platformsNatural-language questions evaluated against the publisher’s Ad Manager data
    Reported outcomeA more complete conversion action for measurement and optimizationTailored answers, reports, recommendations and platform guidance
    Important boundaryEnhances rather than replaces website taggingAssists analysis and operations rather than repairing conversion collection

    This comparison prevents a common category error. Better conversion capture cannot diagnose every publisher delivery issue, while a conversational reporting interface cannot recover a transaction that never reached an eligible conversion action. Each tool works on a different constraint.

    Supplemental data strengthens the measurement foundation
    Two layers of website activity and backend transaction signals form a unified measurement foundation beneath an attribution lens.

    According to CrushPress.AI’s report, the Google Ads beta lets an advertiser attach an additional data source to an existing website conversion action through Google Ads Data Manager or the Data Manager API. Backend conversion records are combined with signals collected by Google tags, allowing the same conversion action to support campaign measurement and optimization.

    The reported purpose is recovery, not replacement. Browser restrictions, privacy settings or ad blockers can prevent some tag-based signals from being captured. Transactional systems may retain evidence of those completed outcomes, so supplying that evidence can make measurement more resilient and give automated bidding a more complete input set.

    That benefit depends on record quality. The report states that every upload must include a transaction ID and the conversion date and time, plus at least one attribution identifier such as hashed customer data or a Google click identifier. Google reportedly uses transaction IDs to deduplicate tag and backend records within the same conversion action.

    The reported eligibility limits are equally significant. The beta applies to website conversion actions implemented with Google tags or Google Tag Manager; Google Analytics imports and URL-based conversion actions are excluded. Google also advises adding the supplemental source to the existing action instead of creating another action, which could introduce double-counting across campaign goals. Prompt uploads and conversion values formatted consistently with the tag’s currency were also reported as recommended practices.

    Ask Ad Manager compresses the path from question to diagnosis
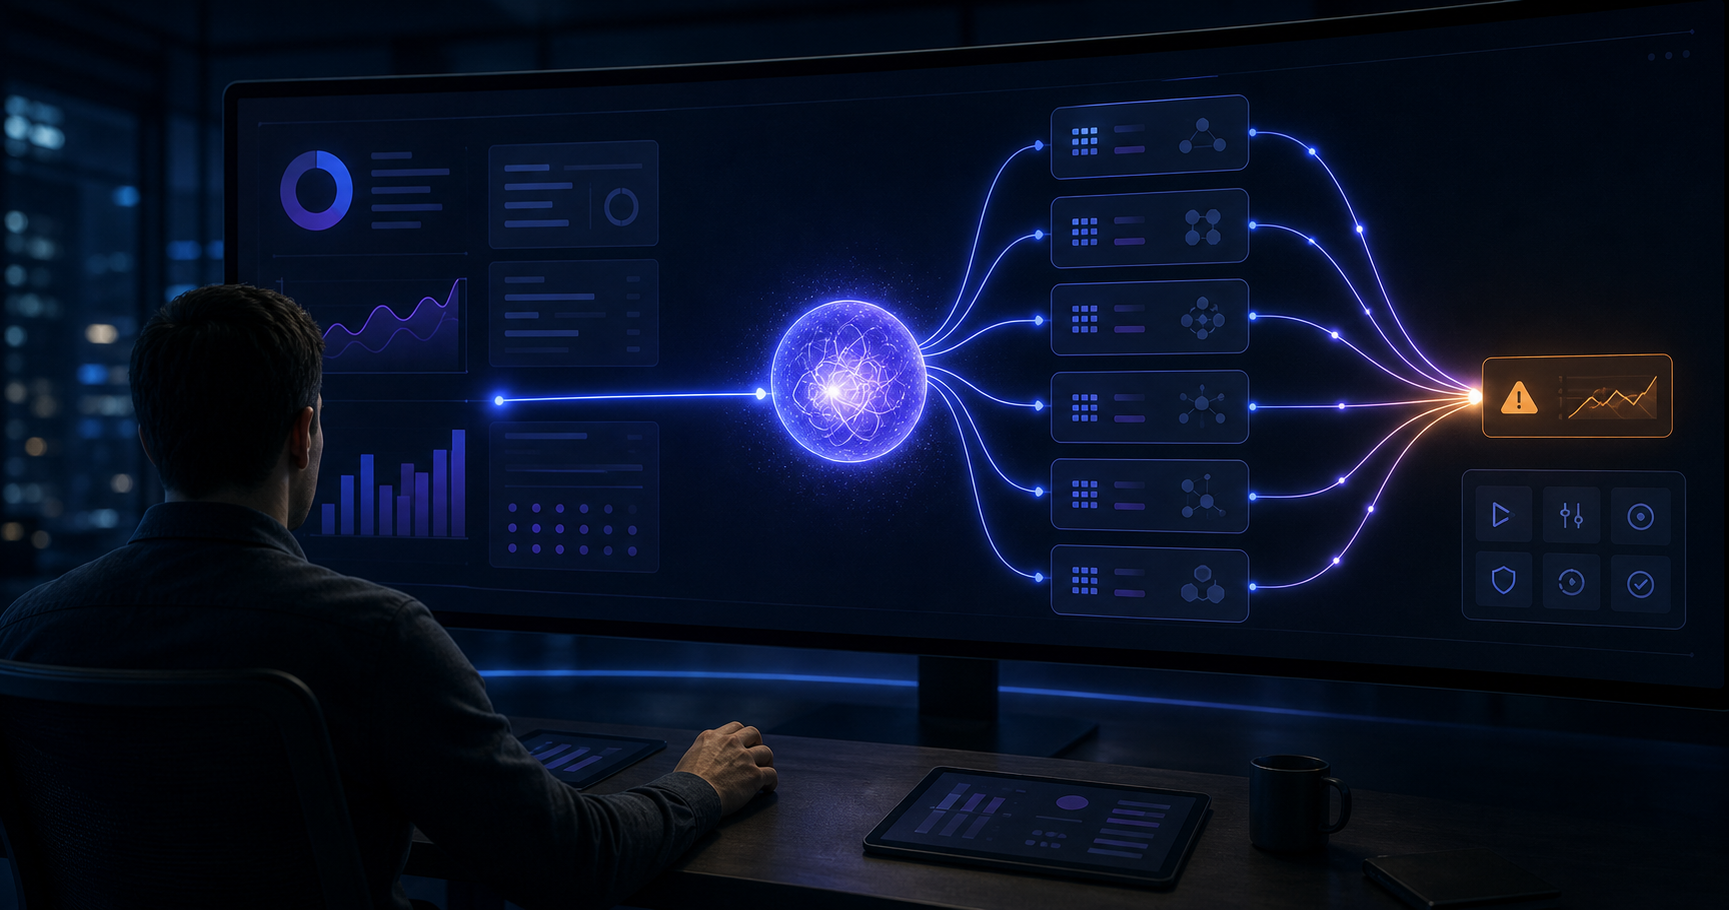
    A publisher revenue analyst uses a glowing conversational assistant to trace system signals to a highlighted anomaly and operational controls.

    Ask Ad Manager tackles a different bottleneck: extracting usable answers from a complex publisher platform. CrushPress.AI described it as a Gemini-powered beta that lets Google Ad Manager users ask questions in ordinary language and receive responses grounded in their own Ad Manager data.

    The reported capabilities span three recurring tasks. The assistant can investigate why line items are underdelivering and suggest possible causes or next steps. It can produce requested metrics, benchmarks and customized reports without requiring the user to construct each report manually. It can also direct a user to relevant Ad Manager pages while applying filters and settings derived from the conversation.

    The practical shift is from interface-led work to question-led work. Instead of beginning with menus, report fields and filters, a publisher can begin with the business or delivery question. The assistant then helps translate that question into platform activity. This may reduce operational effort, but the source does not establish that every answer or recommendation will be correct. As a general operating discipline, consequential findings should still be checked against the underlying report and campaign configuration.

    The report also attributes a wider roadmap to Google. Planned additions include developer tools such as REST APIs and an MCP server, along with specialized agents that could help publishers and agencies explore inventory, negotiate deals and execute campaigns. Those items are forward-looking plans, not capabilities established by the reported beta.

    Key takeaways

    • The conversion beta improves the data entering an eligible Google Ads conversion action; Ask Ad Manager improves how publishers interrogate and use their Ad Manager data.
    • Supplemental conversion data depends on reliable transaction IDs, timestamps, attribution identifiers and consistent values, as well as correct conversion-action configuration.
    • Deduplication is central to the measurement design because tag and backend systems may describe the same transaction.
    • Conversational analysis can shorten reporting and troubleshooting work, but important recommendations still warrant validation against source data and settings.
    • Both features were reported as betas, while the APIs, MCP server and specialized Ad Manager agents remain part of Google’s stated roadmap.

    A practical evaluation framework for advertising teams

    Teams evaluating the conversion beta should first determine whether their conversion actions use an eligible implementation. They can then assess whether backend systems retain the required identifiers, timestamps and values, and whether transaction IDs remain consistent across the tag and transactional record. This is not merely an integration exercise: weak identity matching, inconsistent currency formatting or duplicate campaign goals can undermine the additional data.

    Publishers assessing Ask Ad Manager should judge it against concrete operational questions. Useful tests include whether it can reproduce a trusted report, identify a known delivery issue and navigate to the correct filtered view. The relevant measure is not how fluent the conversation sounds, but whether it reduces investigation time without obscuring the evidence behind an answer.

    Across both products, data discipline remains the connecting requirement. More complete records can improve the basis for optimization, while a conversational layer can make platform data more accessible. Neither advantage removes the need for clear conversion definitions, dependable identifiers, reviewable reports and accountable decisions.

    If Google’s reported direction continues, advertising work will increasingly combine first-party data connections with agent-assisted operations. The teams best positioned to benefit will be those that treat reliable data and human verification as prerequisites for automation, not as cleanup work after deployment.
    References

  • Microsoft Web IQ: How to Optimize for AI-Agent Search

    Microsoft Web IQ: How to Optimize for AI-Agent Search

    If you’re wondering whether Microsoft Web IQ requires a new SEO playbook, the short answer is no. You don’t need a Web IQ schema or a separate version of your site. You do need content that an AI agent can discover, interpret, verify, and reuse across a chain of searches.

    That shifts the work from chasing one visible ranking to making every useful fact easy to retrieve. Here’s how to adapt without abandoning the technical SEO and content standards that already matter.

    Key takeaways

    • Web IQ connects AI systems with current web pages, news, images, and videos through AI-native grounding APIs built on Bing’s index.
    • AI agents may run several searches, refine their questions, and collect evidence before producing an answer.
    • A conventional rank position is a limited way to judge visibility when an agent is assembling an answer from multiple retrieval steps.
    • Clear answer sections, crawlable HTML, consistent entities, supported claims, and accurate structured data make your content easier to use.
    • There is no confirmed Web IQ-specific markup shortcut. Optimize the underlying information, not an imagined scoring system.

    What Web IQ changes about search

    Web IQ is a suite of AI-native grounding APIs that connects AI systems to fresh online information. It can retrieve web, news, image, and video material from Bing’s index. The underlying infrastructure also serves Microsoft Copilot, ChatGPT, and other large language model experiences.

    The important distinction is the customer. A traditional search results page is arranged for a person who scans titles, compares choices, and clicks. Web IQ is designed for software that needs to extract information quickly and continue working.

    An agent may begin with a broad request, identify missing details, issue narrower searches, and repeat that process until it can complete its task. Microsoft therefore reworked more than the presentation of results. The system extends from indexing into orchestration, with an emphasis on relevance, speed, and economical token use.

    This is why a single rank number becomes less informative. Microsoft has said that human-style ranking isn’t the priority for this service. That doesn’t mean relevance has disappeared. It means an agent’s repeated retrieval and extraction process may matter more than whether your page occupies one fixed blue-link position.

    Optimize for a search chain, not one keyword

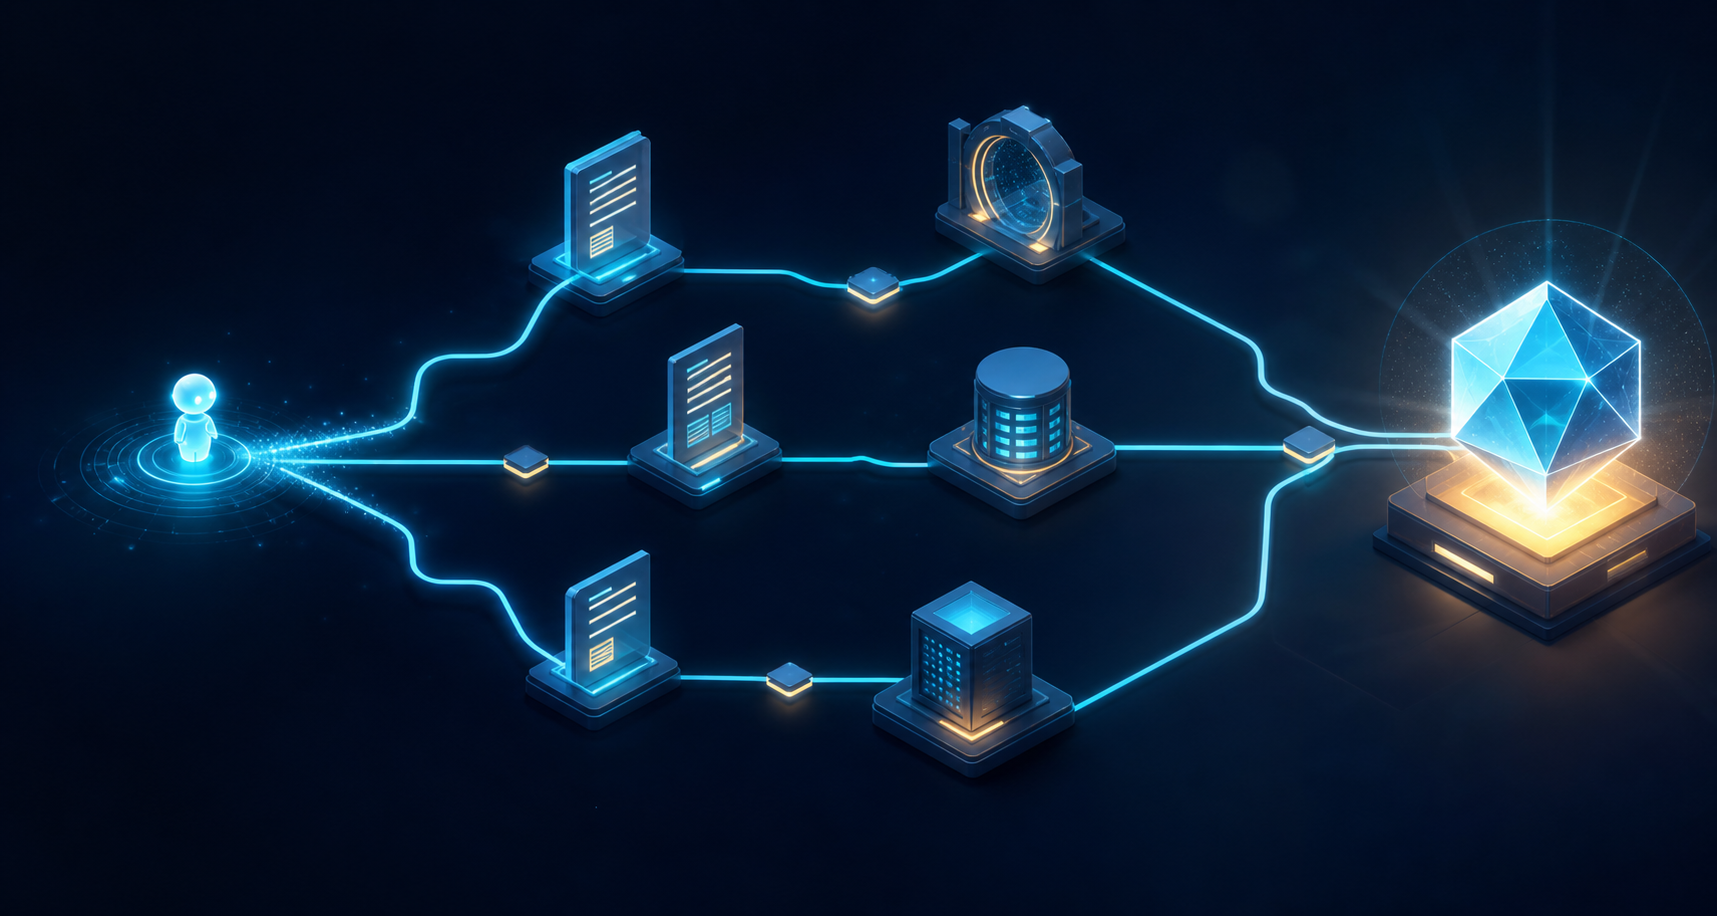
    A luminous agent follows multiple branching paths through document nodes before reaching a verified result.

    Start with the task behind the query. A person asking how to choose accounting software may cause an agent to investigate pricing, integrations, security, migration, support, and suitability for a particular business. A page that repeats the broad keyword but leaves those questions unanswered offers little material for the later steps.

    Map one primary question and the follow-up questions a careful buyer would ask before acting. Give each substantial follow-up its own descriptive heading. If a follow-up requires a full explanation, publish a dedicated page and link it from the main page with anchor text that names the question it answers.

    Build self-contained answer sections

    Each important section should make sense when retrieved without the paragraphs above it. State the subject explicitly, answer the question early, and then add conditions or evidence. Replace vague openings such as “it depends on several factors” with language that identifies what depends on what.

    For example, don’t hide a product’s eligibility rule inside a long narrative. Put the rule under a heading that names the product and decision. Explain who qualifies, who doesn’t, and what the reader should check next. That structure helps people scan the page and gives an agent a coherent passage to extract.

    Cover adjacent questions without bloating the page

    Agent-search readiness isn’t permission to add every remotely related keyword. Include a subtopic when it changes a decision, resolves a likely ambiguity, or supplies evidence for the main answer. Move tangents to their own pages. Thin expansions make the central answer harder to identify.

    Use internal links to form a deliberate evidence path: overview to requirements, requirements to implementation, and implementation to troubleshooting. The destination should answer the promise made by the link. This gives an agent a useful route for deeper retrieval while keeping each page focused.

    Make each page economical for an agent to process

    Web IQ was engineered for frequent searches and low token use. You can’t control how an external agent budgets its context, but you can remove avoidable interpretation work from your pages.

    Lead with the usable answer

    Place the direct answer near the start of the relevant section. Follow it with the reasoning, limitations, and examples. Don’t make a reader or agent work through a brand story before reaching the fact promised by the heading.

    Keep entities and claims consistent

    Use one clear name for each company, product, service, or concept, then explain aliases where necessary. Keep prices, availability, policies, and specifications consistent across landing pages, documentation, feeds, and structured data. Conflicting facts force an agent to resolve ambiguity and weaken the page’s usefulness as grounding material.

    Attach qualifications to the claim they modify. If an offer applies only in one region or a feature requires a certain plan, say so in the same section. A technically correct statement can still mislead when its condition sits several screens away.

    Use structured data as corroboration

    JSON-LD can clarify entities and relationships, but it isn’t a Web IQ access pass. Choose schema types that match the page, populate properties from visible information, and keep the markup synchronized with the content. Don’t mark up answers, reviews, prices, authors, or dates that visitors can’t verify on the page.

    Treat structured data as a machine-readable confirmation of the page, not a substitute for an explicit answer. The visible copy still needs to explain what the entity is, what the claim means, and when it applies.

    Give media enough context to stand alone

    Because Web IQ can source images and videos as well as pages, don’t publish important media with a generic filename and a one-word caption. Use accurate alternative text, descriptive captions, transcripts where appropriate, and nearby copy explaining what the media demonstrates. Keep the media attached to a canonical page with enough context to identify its subject.

    Run an AI-agent readiness audit

    Scanning beams inspect a modular website structure, with accessible content blocks and connections glowing green.

    You can audit a high-value page without access to Web IQ itself. Use the primary question the page should answer, then work through this sequence:

    1. Check discovery. Confirm that the canonical URL is crawlable, returns the intended content successfully, and isn’t blocked by an accidental robots directive or login requirement.
    2. Inspect the delivered page. Verify that the main answer, headings, links, and essential facts exist in the rendered output available to a crawler. Don’t leave the core answer dependent on an interaction that may never occur.
    3. Extract sections out of context. Read each important section by itself. Add the subject or qualification when the passage becomes ambiguous without its surrounding copy.
    4. Trace every consequential claim. Link to supporting documentation where readers need verification. Remove stale claims and unsupported precision.
    5. Compare visible content with JSON-LD. Resolve differences in names, dates, offers, authorship, and entity relationships.
    6. Follow the likely next questions. Make sure internal links lead to complete answers rather than thin category pages or unrelated sales copy.
    7. Test the task in AI assistants. Ask the same realistic question in experiences relevant to your audience. Record whether your brand appears, which page is used, whether the claim is represented correctly, and which competing evidence fills the gaps.
    8. Watch your own evidence. Review referral traffic and server logs where available, but don’t treat either as a complete count of agent visibility. Use them alongside repeated answer checks and conversion data.

    Prioritize corrections that affect the answer itself: inaccessible pages, conflicting facts, missing qualifications, unclear entity names, and unsupported claims. Cosmetic rewrites can wait. An agent can’t use a polished passage it can’t retrieve or trust.

    Web IQ access may broaden as Microsoft scales the service, but you don’t need to wait for a new dashboard. Choose one commercially important topic this week, map the likely follow-up searches, and repair the weakest answer path. That work improves your site for human visitors now while making its information more usable in agent-driven search.

    References

  • How to Prepare Your SEO Strategy for Google’s Agentic Search

    How to Prepare Your SEO Strategy for Google’s Agentic Search

    If your organic traffic depends on Google sending a click for every useful answer, you have a planning problem. Search is becoming more capable of explaining options, narrowing choices and helping people act without following the familiar results-page journey.

    You don’t need to abandon SEO or guess at an entirely new playbook. You need to make your content easier for people and machines to understand, verify and use, then measure the business outcomes that remain after clicks become less predictable.

    Plan for a task layer, not just a results page

    The important change isn’t simply that Google can generate longer answers. Google’s stated direction brings Search, Gemini and agentic tools toward a more unified product capable of assisting with end-to-end tasks. An agent might help someone investigate a problem, compare possible solutions and take the next step within one continuous interaction.

    Treat that as a direction of travel, not a finished product or a release schedule. Your practical response is to examine the jobs your pages help visitors complete. A page that merely attracts a broad query is vulnerable when an AI interface can satisfy that query directly. A page that supplies distinctive evidence, decision criteria, current business information or a useful action remains relevant to a deeper journey.

    Start with your highest-value landing pages. Write down the decision each one supports and the action a qualified visitor should take next. If you can’t name either, the page probably has an unclear role. Tighten it before producing more content around the same keyword.

    Google continues to describe the open web as part of its search experience, even while acknowledging that some clicks may disappear. That combination should shape your strategy: stay accessible to discovery systems, but stop treating a click as the only proof that your information created value.

    Build pages around decisions an agent can support

    An abstract AI assistant compares several unlabeled options using visual symbols for evidence, timing, location and trust while a person observes.

    Traditional keyword planning often stops after identifying what someone types. Agentic search requires a fuller model: what is the person trying to decide, what facts would change that decision, and what could prevent the next action?

    Answer the immediate question without ending the journey

    Put a direct answer near the point where the question appears. Then add the conditions that make the answer vary. If you sell a service, that may include who it fits, who it doesn’t fit, what inputs affect price, what preparation is required and what happens after an inquiry. If you publish educational content, show how readers can apply the answer and recognize when another option is better.

    This gives an answer system a clear passage to interpret while giving a serious buyer reasons to continue. It also prevents a common failure: producing a concise answer that is technically extractable but too generic to establish why your brand deserves consideration.

    Expose the comparison criteria

    People rarely need more adjectives. They need dimensions they can compare. Replace claims such as “flexible,” “advanced” or “best for growing teams” with the facts behind them: compatible use cases, constraints, required inputs, available service areas, purchasing conditions and the tradeoffs between options.

    Use consistent labels across related pages. If one page calls an offering a plan, another calls it a package and a third treats it as a product, you create unnecessary ambiguity. A stable vocabulary helps readers compare choices and gives automated systems a clearer entity model.

    Make the next action explicit

    Inspect every conversion path from the perspective of someone who has already received a competent summary elsewhere. That person may arrive ready to verify one detail and act. Put eligibility, availability, price structure, required information and the next step where they can be found without restarting the entire education journey.

    Use descriptive action labels. “Check availability,” “request an assessment” or “compare plans” communicates more than “learn more.” Keep the destination aligned with the promise. An AI-assisted journey will not rescue a vague form, missing terms or a landing page that changes the subject.

    Make your meaning verifiable with content and schema

    A cutaway model shows visible webpage content aligned with an organized network of structured data and supporting evidence beneath it.

    Schema is useful when it expresses facts that are already clear on the page. It isn’t a substitute for missing information, and it doesn’t guarantee inclusion in an AI response. Think of JSON-LD as a machine-readable agreement with your visible content.

    Choose schema types that match the actual entity and page purpose, such as Organization, Person, Product, Service or Article. Connect entities consistently. Names, URLs, authorship, offers and other properties should agree with what a visitor sees. If the business changes a price, service name or availability condition, update both the page and its markup as one publishing task.

    Don’t add FAQ markup simply because question-shaped text looks attractive for search. Use it only when the page contains a genuine visible FAQ, and make every marked answer match the displayed answer. The same rule applies to reviews, offers and organizational details: describe what exists rather than decorating the page with attributes you hope a system will infer.

    Verification also happens in the prose. Show who created or reviewed consequential content. State the basis for recommendations. Identify where a claim applies and where it doesn’t. Keep time-sensitive facts maintained. Link related pages through meaningful relationships instead of publishing disconnected variations of the same target phrase.

    Finally, test the rendered page and the generated markup. A valid JSON-LD block can still describe the wrong entity, preserve an old value or conflict with visible copy. Your quality check should ask two separate questions: does the syntax work, and is the meaning accurate?

    Measure qualified outcomes when raw clicks decline

    Google has framed some disappearing traffic as low-quality or bounce-prone traffic. Treat that as a hypothesis to test in your own data, not permission to ignore falling visits.

    Segment performance by landing-page purpose and query intent. Separate broad informational discovery from product evaluation, branded navigation and action-oriented visits. Then compare impressions, visits, meaningful engagement, leads, sales, subscriptions and retained customer value where those measures apply. A smaller audience can be healthy if the lost visitors never progressed. It is a warning if qualified demand, revenue or brand discovery falls with it.

    Watch for mismatched signals. Stable visibility with fewer visits may indicate that answers are being consumed before the click. Stable traffic with weaker conversion may point to a page or offer problem. Falling non-branded discovery alongside stable branded demand may mean your existing audience still finds you while new prospects do not. Each pattern calls for a different response.

    Publishers should also decide which relationships they want to own. Google has highlighted support for subscription-oriented experiences as publishers adapt to changing traffic patterns. A subscription can be part of that response, but only when you offer recurring value worth returning for. Email, saved tools, accounts, communities and customer data can serve the same strategic purpose: turning rented discovery into a direct relationship.

    Annotate major content, template, schema and conversion changes so you can connect movement to a plausible cause. Don’t combine every AI-related metric into one visibility score. Keep enough detail to see whether you are being discovered, selected, visited and trusted to complete a business action.

    Key takeaways

    • Audit important pages by the decision and next action they support, not only by the keyword they rank for.
    • Give direct answers, then add constraints, comparisons and evidence that make your contribution distinctive.
    • Keep visible facts and JSON-LD aligned; valid syntax cannot repair inaccurate meaning.
    • Make conversion paths usable for visitors who arrive late in the journey and are ready to verify or act.
    • Measure qualified demand and owned relationships alongside traffic so fewer clicks don’t automatically produce the wrong conclusion.

    Your next move is small but consequential: choose one commercially important page, define the decision it helps a visitor make, correct its facts and schema, and remove friction from the next action. That work remains useful whether Google sends a traditional result, generates an answer or introduces an agent into the journey.

    References

  • Discover Google Chrome Lighthouse’s New AI Scan Feature

    Discover Google Chrome Lighthouse’s New AI Scan Feature

    I’ve recently discovered that Google has introduced a new feature in Chrome Lighthouse to check for llms.txt files. Though Google mentions that llms.txt isn’t necessary for AI search visibility, Lighthouse has started flagging sites based on their presence.

    Google’s latest Lighthouse audits, under the “Agentic Browsing” category, now focus on a site’s usability for machine interaction. I find this interesting as it aligns with Google’s push towards better machine readability.

    The new audits are part of Chrome’s evolving “Agentic Browsing” features, which analyze if sites are prepared for automated interaction. This concept came soon after Google issued guidance on AI search optimization, debunking the necessity of llms.txt files in their new guide on generative AI features.

    What Lighthouse Evaluates Now. Lighthouse’s Agentic Browsing tests focus on how well my site is built for machine interactions, incorporating various deterministic audits as per Google’s documentation. These checks include:

    – WebMCP integration.

    – Accessibility tree integrity.

    – Layout stability through CLS.

    – Presence of an llms.txt file.

    These audits help ensure that there’s a machine-readable summary at the site’s domain root. Google explains that without llms.txt, agents might take longer to understand a site’s main structure.

    The impact of these audits doesn’t translate into a traditional Lighthouse score but into a fractional pass ratio related to agentic readiness signals.

    The Tension. Interestingly, while these audits don’t directly affect SEO rankings, their mention in Google’s readiness checks could make SEOs reconsider their stance on llms.txt files.

    Agentic Engine Optimization. Google’s approach aligns with insights shared by Addy Osmani from Google Cloud AI about Agentic Engine Optimization. Osmani emphasizes creating web content that is semantically structured, token-efficient, and easy for AI to process.

    SEO vs. llms.txt. According to Google, creating llms.txt or similar files isn’t necessary for AI search success, as outlined in the guide on Mythbusting generative AI search. The AI systems can discover, crawl, and index a variety of file types encountered on the internet.

    John Mueller from Google responded to concerns about the role of llms.txt in a discussion with Lily Ray on Bluesky, stating that the use of these files is more for functionality and not directly linked to search engine optimization.

    Google’s Take on AI Agents. Besides llms.txt, Google’s Lighthouse guidelines place strong emphasis on accessibility and interface stability. The insight I gained is that AI agents heavily rely on the accessibility tree as their core data model, focusing on integrity and proper layout.

    Ultimately, while Google indicates llms.txt isn’t needed for search, including such files might be beneficial for adapting to Google’s evolving tools that prioritize machine readability.

    Further Exploration.

    – Meet llms.txt, a proposed standard for AI website content crawling

    – llms.txt isn’t robots.txt: It’s a treasure map for AI

    – Does llms.txt matter? We tracked 10 sites to find out


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Unveiling Google’s Ask Advisor: Revolutionizing Ad Management

    Unveiling Google’s Ask Advisor: Revolutionizing Ad Management

    I’m thrilled to share that Google has just unveiled Ask Advisor, a new AI-driven tool designed to transform the way we approach campaign management, analytics, and optimization. Announced at Google Marketing Live 2026, this Gemini-powered AI is here to integrate seamlessly across Google Ads, Google Analytics, Merchant Center, and the Google Marketing Platform.

    Making Waves. Ask Advisor is set to be a game-changer, acting as a unifying force that weaves together insights, workflows, and recommendations across Google’s vast marketing ecosystem.

    For those of us in marketing, this means we can launch campaigns, analyze performance, and uncover optimization recommendations all without having to juggle between different tools.

    Imagine asking Ask Advisor to “find new customers for my hair care products.” It would seamlessly pull details from the Merchant Center and assist in crafting a campaign right in Google Ads.

    Understanding the Process. Ask Advisor connects the dots between Google Ads, Analytics, the Merchant Center, and the Marketing Platform via a Gemini-powered interface. This connectivity allows it to access a range of data to create recommendations, automate tasks, and offer insights that align with marketing goals.

    It doesn’t stop there. The integration of insights from Google Ads and Google Analytics helps explain campaign performance and suggests subsequent steps.

    The aim, Google states, is to democratize advanced campaign management, enabling even those without extensive technical expertise to make the most out of their advertising strategies.

    ```json
{
  "alt": "Dashboard displaying performance overview with graphs and metrics, showing impressions, cost, and conversions.",
  "caption": "Explore insights with this performance overview dashboard, offering a detailed look at impressions, costs, and conversion metrics with dynamic graphs.",
  "description": "This image showcases a performance overview dashboard, highlighting key metrics such as impressions, cost, and conversion values. The interface features a line graph depicting trends over time, supported by a sidebar with options to manage campaigns, goals, and admin tools. A chat interface appears on the right, indicating available support. This visualization is ideal for users seeking in-depth campaign analysis."
}
```

    This launch supports Google’s expanding lineup of AI-driven in-product agents, positioning Gemini as a fundamental layer in advertising and measurement tools.

    Why This Matters to Us. Ask Advisor symbolizes one of Google’s most direct steps into agent-based advertising workflows.

    Instead of interacting manually with separate reporting dashboards, campaign tools, and optimization settings, AI agents are being poised to handle operational tasks and present strategic insights.

    The more substantial evolution is structural: Google is anchoring Gemini as the core across its advertising platform, potentially redefining how campaigns are developed, optimized, and evaluated.

    Keep an Eye On. The biggest discussion point will be how much control advertisers are willing to cede to AI agents. Transparency over recommendations, automation choices, and reporting accuracy will be under scrutiny as Ask Advisor rolls out.

    When You Can Get It. Currently in beta, Ask Advisor is available for English-language accounts, with more features anticipated later this year.

    Want to Learn More? Here’s additional news from Google Marketing Live 2026:


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI Search Optimization Without Spam: A WebMCP Readiness Plan

    You need visibility in AI-generated search results, but you cannot afford to turn optimization into a collection of tricks that puts your existing rankings at risk. At the same time, AI agents are moving beyond finding information toward completing tasks on websites.

    The practical response is one connected strategy: publish material worth retrieving, keep every machine-readable claim tied to visible facts, and prepare a small set of site actions that an agent could eventually perform safely. That work improves your site now without requiring you to gamble on speculative markup or an unfinished implementation.

    Draw the policy line at genuine user value

    Google’s definition of search spam now explicitly includes attempts to manipulate generative AI responses in Google Search. A tactic does not become acceptable merely because its target is an AI Overview or AI Mode instead of a conventional ranking.

    That does not make AI search optimization illegitimate. It gives you a useful boundary: legitimate optimization makes a page, entity, or user journey more useful and easier to understand. Manipulation tries to influence the generated output without making the underlying experience more accurate, distinctive, or helpful.

    Run every proposed AI visibility tactic through these checks before it reaches production:

    • The user test: Would this change still improve the page if no AI system ever cited it?
    • The truth test: Can a reader verify every claim from visible content, supporting evidence, or the real product or service being described?
    • The surface test: Is the same meaning available to people and machines, or are you presenting an AI-only version designed to produce a preferred answer?
    • The reputation test: Are mentions, endorsements, and reviews authentic, or is the plan manufacturing apparent consensus?
    • The maintenance test: Can your team keep the claim accurate when prices, availability, policies, locations, or product details change?

    If a tactic fails any of these checks, stop. Instructions addressed to a model, unsupported superlatives in JSON-LD, manufactured third-party mentions, and batches of near-duplicate pages are not durable visibility strategies. They create a version of your brand that is difficult to defend and even harder to maintain.

    Keep a short decision record for material optimization changes. Record the user problem, the page being changed, the factual support for the change, and the outcome you intend to observe. This forces the team to describe value in user terms before debating whether an AI system might reward it.

    Build pages that are easy to retrieve, interpret, and trust

    For Google’s generative search features, ordinary SEO remains the foundation. Crawlability, semantic HTML, sensible JavaScript, useful content, page experience, and duplicate control still matter. You do not need a separate editorial system for humans and AI.

    Start with the pages that influence an important decision: choosing a service, comparing a product, checking eligibility, understanding a process, or finding a location. Inspect each page in this order:

    • State the page’s job clearly. The title, opening, and primary heading structure should describe the same question or task. If the page tries to satisfy several unrelated intentions, separate them or choose a clear primary purpose.
    • Answer before expanding. Put the direct answer, recommendation, definition, or decision criterion near the relevant heading. Follow it with evidence, conditions, exceptions, and next steps.
    • Use semantic structure. Headings should describe actual sections. Lists should represent real sequences or sets. Tables should be reserved for information readers genuinely need to compare by row and column.
    • Add information competitors cannot reproduce by paraphrasing. That can include a clear point of view, a documented process, product constraints, original examples, decision rules, or a candid explanation of where an option does not fit.
    • Keep important content available in the rendered page. If essential facts appear only after a fragile script, interaction, or client-side request, provide a stable and accessible presentation where appropriate.
    • Consolidate duplication. Merge pages that answer the same question without adding a meaningful distinction. Where separate URLs are necessary, make their individual purposes unmistakable.
    • Use media to resolve uncertainty. A diagram, product image, demonstration, or video should help the reader see something that the prose alone cannot establish. Decorative assets do not make a page more authoritative.

    Do not confuse good structure with artificial content chunking. Short sections are useful when the subject naturally divides into discrete decisions. They are not useful when a complete explanation has been chopped into repetitive fragments solely because someone believes an AI prefers a particular paragraph length. Google’s position is that sites do not need AI-specific rewrites or forced chunking.

    A strong page should let a reader identify what is being offered, who it suits, what conditions apply, why the claims are credible, and what to do next. If those answers are buried or inconsistent, no metadata layer can repair the underlying problem.

    Use JSON-LD as a consistency contract, not a persuasion layer

    Structured data helps a machine map the entities and relationships already present on a page. It does not create authority, prove a claim, or turn thin content into a useful answer. Google does not require special markup for its generative AI features, so an AI-only schema vocabulary should not be the center of your plan.

    Treat JSON-LD as a contract between your visible page, your business data, and the systems that consume both:

    1. Identify the real primary entity on the page before selecting a type. A local business page and a product detail page describe different things and should not be marked up as interchangeable templates.
    2. Include only properties your site can support and maintain. A value should not appear in JSON-LD merely because the vocabulary permits it.
    3. Match visible names, descriptions, prices, availability, ratings, locations, and other material details wherever they appear. Do not let markup become a more flattering version of the page.
    4. Trace frequently changing values back to an authoritative internal system instead of editing the same fact independently in several templates.
    5. Retest the rendered markup after content, theme, commerce, or template changes. Valid code can still describe the wrong entity or expose stale values.
    6. Remove unsupported properties rather than filling them with defaults. Missing data is better than a confident but inaccurate assertion.

    This is especially important for local and ecommerce pages, where precise business and product details deserve focused attention. A customer should see the same core fact in the page copy, structured data, catalog, and transaction flow. When those surfaces disagree, a search system or agent has to guess which version is current.

    Audit facts horizontally rather than reviewing JSON-LD in isolation. Choose a material fact, such as a location, product variant, price, or availability state, and follow it through every surface that publishes or acts on it. Fix the source of disagreement. Patching only the markup leaves the user journey inconsistent and guarantees the error will return.

    Prepare for WebMCP by defining safe, bounded actions

    Search visibility helps an AI system discover and assess your site. Agent readiness asks a different question: can that system complete a useful task without guessing how your interface works? WebMCP’s premise is to let websites communicate their capabilities more explicitly, making it easier for AI to interact with them. The browser-native work is associated with Google and Microsoft and points toward discovery systems that can act as well as recommend.

    You do not need to expose every button to prepare for that future. Your near-term job is to remove architectural ambiguity and identify which actions are safe enough to support. Use four readiness layers:

    Readiness layerQuestion to answerWork you can do now
    InformationCan an agent find and interpret the facts needed for the task?Improve semantic HTML, stable URLs, crawlable content, entity consistency, and duplicate control.
    CapabilityIs the task defined with clear inputs, outputs, and boundaries?Create a capability inventory for recurring user jobs rather than mapping isolated interface clicks.
    ControlWho may perform the action, and when is confirmation required?Document authentication, authorization, validation, consent, side effects, and recovery paths.
    ResultCan the system distinguish success, failure, and an incomplete action?Provide clear outcome states, useful errors, duplicate protection, and operational logging.

    Create a capability inventory around user goals

    Do not begin by listing every form, link, and button. Begin with bounded jobs a visitor already comes to complete. Checking availability, retrieving an order status, requesting a quote, scheduling an appointment, or adding a known item to a cart are capabilities. Clicking the blue button is only an interface instruction.

    For each candidate capability, record:

    • The user’s intended outcome.
    • The required and optional inputs.
    • The source of each fact used to make the decision.
    • Whether the task is read-only or changes data.
    • The authentication and permission required.
    • Any financial, contractual, privacy, inventory, or scheduling side effect.
    • The point where the user must review and confirm the action.
    • The success response and the errors the caller must be able to distinguish.
    • How the operation is cancelled, reversed, or corrected when reversal is possible.

    This inventory is useful even if you never deploy WebMCP. It exposes vague workflows, duplicated business rules, hidden dependencies, and actions that rely on a person interpreting an ambiguous interface.

    Keep state-changing operations behind explicit controls

    An agent action can spend money, disclose personal data, create a reservation, submit a request, or cancel something the user intended to keep. Do not expose those operations merely because they are technically callable. Keep them behind the same authentication, authorization, validation, and confirmation boundaries that protect the human workflow.

    Before a consequential action runs, show the user the material details they are approving: the item or service, current price where applicable, quantity, date or time, recipient, and cancellation conditions. If any material value changed after the task was planned, require a fresh confirmation instead of silently continuing.

    Design for retries as well. Networks fail, responses time out, and an agent may repeat a request when it cannot determine whether the first one succeeded. Use idempotent handling, or an equivalent duplicate-detection mechanism, so a retry does not create another order, appointment, payment, or submission.

    Separate business capabilities from fragile interface paths

    A workflow that depends on screen coordinates, changing button text, or a long sequence of DOM assumptions will be difficult for any automated system to use reliably. Keep the business operation and its validation separate from its visual presentation where your architecture permits it. The website remains the human interface, while the underlying capability has a clear contract and consistent result.

    Semantic controls and descriptive labels remain important. They improve accessibility, testing, human comprehension, and automated interpretation at the same time. WebMCP readiness should build on that interface rather than become an excuse to neglect it.

    Test failure paths before exposing a capability

    A workflow is not agent-ready merely because its happy path works. Exercise missing inputs, invalid values, expired sessions, insufficient permissions, stale prices, unavailable inventory, scheduling conflicts, duplicate submissions, downstream failures, and ambiguous responses. The caller should receive a result it can explain without pretending the task succeeded.

    Use a staging environment for state-changing tests and keep real customer data out of test prompts and logs. When you add operational logging, record enough to diagnose the action and its outcome while continuing to apply your existing access and retention controls.

    Follow a low-regret implementation sequence

    1. Select the important pages and bounded user tasks that already support a real business or customer need.
    2. Fix crawlability, semantic structure, duplication, JavaScript dependencies, and weak content on those pages.
    3. Reconcile visible facts, JSON-LD, catalogs, and transactional data so the same claim has one maintained source of truth.
    4. Apply the user, truth, surface, reputation, and maintenance tests to every AI visibility change.
    5. Document capability inputs, outputs, permissions, side effects, confirmation points, and recovery paths.
    6. Separate reusable business logic from fragile presentation-specific steps where practical.
    7. Test successful and unsuccessful outcomes in staging before enabling any agent-facing integration.
    8. Expose capabilities only through an implementation your team can secure, monitor, maintain, and disable if behavior changes.

    This sequence gives you value before WebMCP adoption becomes a deciding factor. The same work produces clearer content, cleaner data, safer transactions, and a site that is easier for both people and software to use.

    Practical questions before you approve the work

    Do you need an llms.txt file or special AI schema for Google?

    No. For Google’s generative AI features, neither llms.txt nor special AI markup is required. Use established technical SEO and structured data practices, and keep the machine-readable representation aligned with the visible page.

    How can you tell whether optimization has become manipulation?

    Remove the AI result from the business case. If the change no longer helps a reader, clarifies a fact, improves retrieval, or makes a legitimate task safer, its purpose is probably influence rather than usefulness. Treat that as a stop signal, especially when the tactic depends on hidden instructions, unsupported claims, or manufactured mentions.

    What should you optimize first?

    Choose the page attached to an important user decision where the facts are currently incomplete, duplicated, difficult to retrieve, or inconsistent with structured data. Fixing a known information gap is more defensible than creating a new AI-targeted page whose only purpose is to occupy another search surface.

    What can you do before deploying WebMCP?

    Build the capability inventory, classify read and write actions, document permission and confirmation boundaries, stabilize the underlying business operations, and test failure states. These preparations support the shift from AI-assisted discovery toward agent-completed actions without requiring you to expose a speculative production interface.

    Start with your highest-value page and safest bounded workflow. Make the facts consistent, map the control points, and test what happens when the request fails or repeats. You will have improved search visibility and operational quality even before an agent uses the result.

    References

  • How to Build the Data Foundation for AI-Powered Ads

    How to Build the Data Foundation for AI-Powered Ads

    You’ve connected your ad accounts to an AI system, and it can see every impression, click, conversion and campaign change. That may look like a strong data foundation. It isn’t. The system still can’t tell whether a lead became a customer, whether an order was profitable or whether operations can fulfill the demand it creates.

    Before you let AI move budget or restructure campaigns, you need a business outcome layer between the advertising platforms and the agent. Build that layer well, and automation can pursue results your company actually values. Skip it, and the agent will optimize the numbers it can see – even when those numbers point away from profit.

    Give the AI an optimization contract before giving it data

    An ad platform knows what happened inside its own boundary. It can report delivery, interactions and the conversions attributed to its ads. It usually doesn’t know the quality of a sales lead, the margin on a product, the value of a renewed account or the amount of work your team can fulfill. An agent using only those platform signals operates inside a closed optimization loop.

    More integrations won’t fix that problem until you define what the agent is supposed to optimize. Write an optimization contract that answers six questions:

    1. What is the business outcome? Name the final result, such as closed-won revenue, a completed order or contribution margin. Don’t use a platform conversion label as the definition.
    2. Which outcomes are eligible? State whether cancellations, invalid leads, duplicate orders, returning customers or other disqualified records should count.
    3. How is an outcome valued? Identify the field that carries realized revenue, margin or an approved stage value. Document its currency and whether the value is gross, net or estimated.
    4. When is the result mature enough to use? A form submission arrives quickly; a qualified opportunity or completed sale may arrive later. Define the lifecycle point at which the business accepts the result.
    5. What constraints outrank performance? Inventory, sales capacity, service availability, geographic coverage and fulfillment limits can all make additional conversions undesirable.
    6. What may the AI change? Separate analysis, recommendations and account changes. Specify allowed actions, approval requirements, financial limits and rollback conditions.

    This contract prevents a proxy from quietly becoming the objective. In lead generation, a form submission is an early signal, not proof of revenue. Map the progression from submission to qualification, opportunity and closed business. If only the submission reaches the ad platform, call it a proxy in reporting and keep the later CRM result on the business scorecard.

    For ecommerce, order revenue is still incomplete when products have different margins or fulfillment constraints. A campaign can improve reported return on ad spend by selling more of a low-margin product or promoting something the business cannot readily fulfill. That is why CRM outcomes, product economics and operational signals belong in the decision model.

    Do not ask the model to invent missing business values. If sales has not agreed on what a qualified opportunity is, or finance cannot identify the value field to use, the agent should expose the gap rather than manufacture a score. In that state, it can still draft creative, summarize performance and recommend investigations. It is not ready to control spend autonomously.

    Build a business outcome layer across five data domains

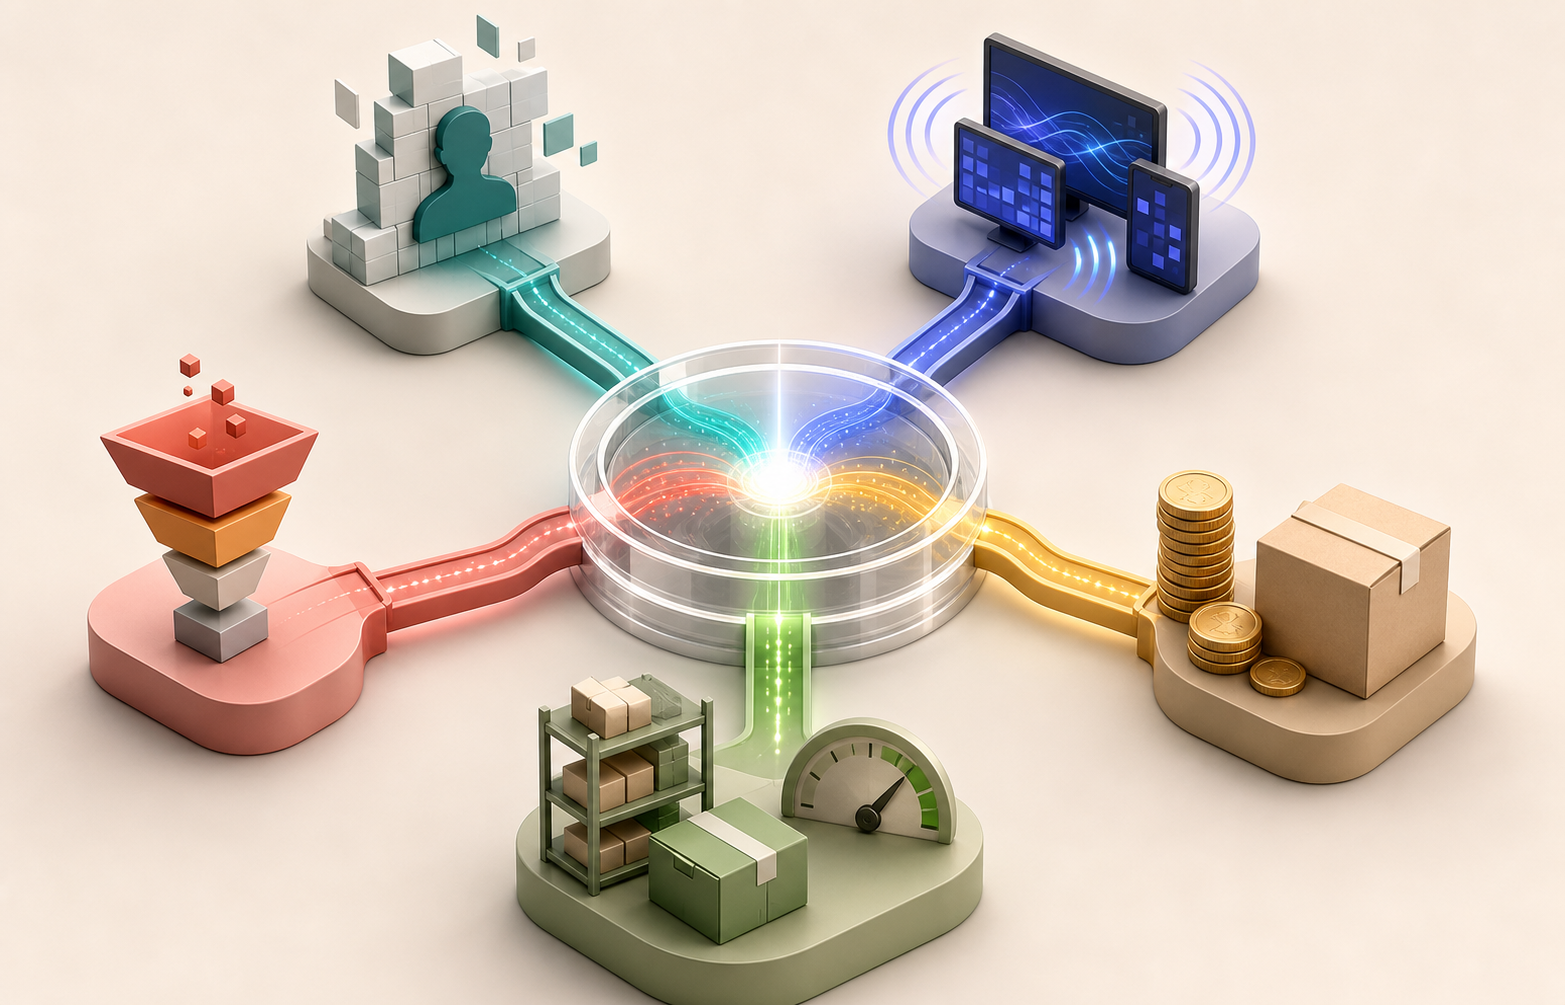
    Five symbolic data domains for customers, advertising, sales, transactions, and operations connect to one central business outcome hub.

    A useful advertising data model keeps different kinds of evidence separate. Platform delivery data, customer outcomes and operational constraints answer different questions. Flattening them into a single conversion column destroys the distinctions the agent needs.

    Data domainWhat it tells the AIRecords and fields to connectHow it should affect decisions
    Advertising platformsWhat was delivered and what the platform attributedCampaign, ad, creative, audience, click, conversion, timestamp and platform-reported valueDiagnose delivery and compare tactics inside the platform
    Web or app analyticsWhat happened during observable visitsSession, landing page, traffic source, on-site events and consent stateExplain journeys and identify experience or measurement problems
    CRM or order systemWhat became a valid lead, customer, order or realized revenueLead, customer or order ID; lifecycle status; outcome value; new or returning status; cancellation or invalidation stateAnchor business reporting and train toward genuine downstream outcomes
    Product economicsWhich sales create business valueProduct or SKU, margin measure and the date for which that value appliesPrefer valuable demand rather than revenue alone
    OperationsWhat the business can sell and fulfillAvailability, capacity, service area and fulfillment constraintSuppress or limit spend when additional demand would create an operational problem

    Competitive intelligence can sit beside these five domains, but it should not become the outcome label. Adthena says its ChatGPT advertising product monitors more than 300,000 daily prompts to surface brands, placements, messages and share of voice. That kind of market visibility can help you form targeting and creative hypotheses. It cannot tell you whether your own acquired customer was profitable or incremental.

    The next job is making the records joinable. Your data contract should specify:

    • A stable lead, customer or order identifier in the business system.
    • Platform click, campaign, ad and creative identifiers where collection and use are permitted.
    • Separate timestamps for the interaction, conversion, lifecycle update and data ingestion.
    • A controlled vocabulary for statuses such as qualified, won, cancelled and invalid.
    • The owner, currency, unit and calculation method for every monetary field.
    • The system that originated each field and the last time it was refreshed.
    • Identity-matching rules, including what the pipeline does when it cannot safely match a person or order.
    • Retention, access and consent rules appropriate to the data you are permitted to use.

    Those details are not housekeeping. They determine whether the same customer becomes one outcome or several apparent outcomes, whether last month’s campaign receives credit for this month’s sale and whether a stale margin value drives a current budget decision.

    Time deserves special treatment because the systems do not necessarily place the same conversion in the same period. Ad platforms may credit a conversion to the day of the ad interaction, while analytics and CRM reporting commonly place it on the day the conversion occurred. This difference in attribution dates can make two accurate reports disagree at a daily or monthly boundary. Preserve both the event date and the platform credit date instead of overwriting one with the other.

    Build the pipeline from the business result backward. First identify the accepted outcome in the CRM or order system. Then attach identity and campaign metadata, enrich the outcome with product and operational values, and only then send an approved signal back to the ad platform through offline conversion tracking or a direct connection. Keep the unmodified business record as well. You will need it when you reconcile totals or change the value logic later.

    Reconcile the systems without forcing their numbers to match

    Google Ads, Meta Ads, analytics and a CRM can all be working as designed while showing different conversion totals. They observe different parts of the journey, use different attribution rules and handle identity, privacy gaps and modeled conversions differently. Treating disagreement as proof that one tool is broken sends teams into endless tracking rebuilds.

    Consider a buyer who clicks a Meta ad, encounters YouTube retargeting, searches for the brand and then buys within a week. Meta and Google may each report a conversion because neither platform has the complete cross-platform path. Analytics and the CRM may record one sale and credit the final paid-search visit. The platform conversions are not two additional customers; they are different claims on the same customer journey.

    Your reporting model should therefore preserve three views:

    • Business outcomes: valid customers, orders, deals and revenue recorded by the CRM, commerce platform or finance system.
    • Attributed outcomes: conversions and value claimed by each advertising platform under its own rules.
    • Journey evidence: observable sessions, touchpoints and on-site behavior captured by analytics.

    Never add attributed outcomes across platforms and present the sum as company revenue. Use the business system to answer how much happened. Use platform and analytics data to explain which interactions were observed and where performance changed.

    A practical reconciliation process looks like this:

    1. Choose the CRM, order system or finance record that defines the total business outcome. Document why it is authoritative and which statuses it includes.
    2. Align time zones, currencies, conversion definitions and reporting dates before comparing systems.
    3. Break the comparison down by outcome type, campaign group, new versus returning customer and lifecycle stage where those fields are available.
    4. Compare platform-attributed results with business outcomes, but do not demand equality. Record the ratio between them for each stable reporting segment.
    5. Investigate abrupt ratio changes. A jump can indicate a tagging failure, a changed attribution setting, a new sales lag, missing offline imports or a real shift in the customer journey.
    6. Annotate known changes to schemas, consent behavior, campaigns and operational availability so the AI does not interpret a measurement change as a performance change.

    Ratios are especially useful because the normal gap between systems can be more informative than an impossible attempt at perfect agreement. If a platform usually reports more attributed orders than the order system and that relationship remains stable, you have a usable baseline. If the relationship suddenly changes, investigate before the agent moves budget.

    Attribution still cannot answer the causal question: would the customer have converted without the ad? Attribution allocates credit after a conversion exists. Incrementality estimates the conversions that would not have happened without the campaign. Keep those jobs separate in your data model.

    When the budget and data volume can support a meaningful control group, you can test incrementality through geographic holdouts, audience holdouts or carefully designed pauses. Time-based pauses are vulnerable to seasonality and other concurrent changes, while any test with an indistinct control group can produce an inconclusive result. These methods are different from attribution reporting; do not let an agent treat an attributed conversion as proof of incremental impact.

    The decision hierarchy is simple: business records tell you how much happened, attribution tools describe the credit assigned to observed interactions, and controlled experiments provide evidence about what caused additional outcomes. Your AI should preserve that hierarchy rather than collapse it into one synthetic score.

    Expand the agent’s permissions only after the data proves reliable

    A glowing AI core passes through sequential security gates as validated data signals unlock access to advertising controls.

    Generating headlines or summarizing a dashboard is not the same as running an advertising account. A true agent can adjust budgets, bids, targeting or campaign structure. That power also accelerates mistakes when business data is missing or misaligned. Because those actions spend real money, enforce limits in the surrounding system rather than relying on a prompt to remember them.

    Stage 1: Observe in read-only mode

    Let the agent read platform, CRM, product and operational data without changing an account. Run this stage through a period long enough to include the normal delay between an ad interaction and the business outcome you care about.

    Review whether it joins the correct records, respects lifecycle updates and explains discrepancies without summing incompatible numbers. Every conclusion should identify the metric definition, originating system and data timestamp it used. If the agent cannot show that lineage, you cannot reliably audit its reasoning.

    Stage 2: Produce structured recommendations

    Require each recommendation to contain the proposed action, business objective, evidence, applicable constraint, estimated exposure and rollback condition. A person should approve the action while you compare recommendations with actual downstream outcomes.

    This stage exposes a common failure early: the model may recommend scaling a campaign because platform return improved even though CRM quality, product margin or capacity deteriorated. Rejecting that proposal is not a prompt-tuning exercise. It means the optimization contract, data mapping or decision rule still needs work.

    Stage 3: Allow bounded execution

    Once recommendations are consistently traceable to accepted business outcomes, allow only a narrow set of reversible actions. Put the following controls outside the model:

    • An allowlist of accounts, campaigns and action types the agent may touch.
    • Per-action and cumulative financial limits over a defined period.
    • A freshness gate that blocks changes when CRM, margin or operational data is late.
    • A completeness gate that blocks optimization when essential outcome fields are missing.
    • A cooldown that prevents repeated changes before delayed results can arrive.
    • A before-and-after audit record containing the input data version, decision, approver and resulting account state.
    • A rollback procedure and kill switch that do not depend on the agent remaining available.

    Fail closed when the business context disappears. If the inventory feed stops updating, the CRM import fails or a margin table changes schema, the safe response is to pause autonomous changes and alert an operator. Continuing with platform-only data recreates the closed loop you built the foundation to avoid.

    Keep experimentation separate from routine optimization as well. Mark campaigns, regions or audiences participating in a holdout so the agent cannot erase the control group in pursuit of short-term attributed performance. An autonomous optimizer should execute the experiment design, not silently rewrite it.

    Key takeaways: your AI advertising readiness check

    Your foundation is ready for controlled automation when you can answer yes to every item below:

    • The optimization objective maps to an accepted CRM, order or finance outcome rather than a platform conversion label alone.
    • Early proxies such as clicks, form submissions and attributed conversions are clearly distinguished from realized business results.
    • Outcome values have documented owners, currencies, units, calculation methods and validity dates.
    • Campaign, customer and order records can be joined without counting one business outcome as several customers.
    • Interaction, conversion, attribution and ingestion timestamps remain separate.
    • Product margin and operational constraints reach the decision layer before the agent allocates budget.
    • CRM totals, analytics journeys and platform attribution remain separate views, with normal discrepancies monitored rather than erased.
    • Incrementality evidence is labeled separately from attribution evidence.
    • Missing or stale business data automatically blocks account changes.
    • Every permitted action has an enforced limit, audit trail, rollback path and independent kill switch.

    If any essential item fails, keep the system in read-only or recommendation mode. That is still useful automation. It becomes unsafe automation only when the authority to spend grows faster than the quality of the data underneath it.

    Start with one campaign group and one downstream outcome that sales, finance or commerce operations already recognizes. Connect that result, reconcile it against platform reporting and let the AI recommend changes before it executes them. Expand to more campaigns and wider permissions only after the outcome remains traceable from ad interaction to business record.

    References

  • Google Web Bot Auth: A Practical Adoption Plan for Websites

    Google Web Bot Auth: A Practical Adoption Plan for Websites

    If you manage bot access at a CDN, firewall, reverse proxy, or application layer, Google Web Bot Auth presents an awkward decision: prepare for stronger bot identity without blocking legitimate traffic that does not yet use it.

    The safe approach is to add Web Bot Auth as a new verification signal, not replace your existing controls. You can then learn from signed requests, distinguish authentication from permission, and tighten access only when coverage is reliable enough for the agents and routes you care about.

    What Web Bot Auth actually changes

    A user-agent string tells you what a requester claims to be. IP and reverse-DNS checks can associate a request with known infrastructure. Neither gives you the same kind of identity evidence as a cryptographically signed request.

    Web Bot Auth is an experimental cryptographic protocol that lets participating bots sign requests. A compatible verifier can use that proof to determine whether the request came from the claimed agent rather than trusting a label that another client could copy.

    SignalWhat it tells youHow to use it now
    User-agent stringThe identity a requester claimsKeep it as classification context, not proof by itself
    IP and reverse DNSWhether the request is associated with expected network infrastructureKeep using these checks during the limited rollout
    Web Bot AuthWhether a participating agent supplied valid cryptographic identity proofAdd it as a stronger signal where verification is supported

    This is an authentication improvement, not a complete bot-management policy. A valid signature can help establish who sent a request. It does not decide whether that agent may crawl a page, use an expensive endpoint, access licensed material, or bypass rate limits. Those are authorization decisions that remain yours.

    That distinction prevents the most dangerous implementation mistake: treating “authentic” as a synonym for “allowed.” A verified agent can still request a route your policy excludes. An unsigned agent may still be legitimate while adoption remains partial.

    Why Web Bot Auth must remain an additional signal

    Web Bot Auth is in a limited test involving some AI agents hosted on Google infrastructure. Not every Google user agent uses it, and Google is not signing every bot request. Requiring a valid Web Bot Auth result across your site would therefore turn incomplete deployment into an access-control failure.

    In practice, the absence of a signature has three possible meanings: the requester is not participating, a participating agent did not sign that request, or the requester is not what it claims to be. The rollout does not yet let you collapse those cases into “fraudulent.” Keep IP, reverse-DNS, and user-agent checks operating alongside the new protocol, as Google advises during gradual adoption.

    Your internal classification should represent that uncertainty. A binary “Google bot” field is no longer enough. Use separate states such as:

    • Cryptographically verified: Web Bot Auth verification succeeded and resolved to an identity you recognize.
    • Legacy verified: the request passed your established network and identity checks but did not carry usable Web Bot Auth proof.
    • Unverified: the request supplied no acceptable proof and did not pass your legacy verification path.
    • Contradictory or failed: the claimed identity conflicts with your verification results, or supplied authentication material fails verification.

    Do not silently translate “legacy verified” into “untrusted.” That would make a protocol coverage gap look like a security finding. Conversely, do not let a familiar user-agent string upgrade an unverified request into a trusted one.

    Failed proof deserves more scrutiny than absent proof. An unsigned request may simply sit outside the test. A request that presents authentication material but cannot be validated has actively failed the verification path. Your system should preserve that distinction for policy decisions and incident review.

    A safe adoption plan for your edge and application stack

    A layered website stack shows signed and unsigned automated requests moving through observation, verification, and limited enforcement paths with monitoring and rollback routes.

    You do not need to redesign every bot rule at once. Start by separating verification from enforcement, then introduce the new result in stages.

    1. Map the current decision path. Identify where user-agent checks, IP rules, reverse-DNS verification, rate limits, robots directives, and application permissions affect a request. Note whether the decisive action happens at the CDN, firewall, reverse proxy, application, or more than one layer.
    2. Define the verdicts before integrating them. Decide how your system will represent valid, absent, failed, unsupported, and indeterminate Web Bot Auth outcomes. Do not force these states into one Boolean field.
    3. Add verification without changing access. In the first phase, calculate and log the Web Bot Auth result while preserving existing allow, limit, challenge, and deny behavior. This gives you evidence about real coverage without risking accidental exclusions.
    4. Compare signals. Review requests that claim the same agent identity but produce different network and cryptographic results. Investigate disagreements before using the new signal to make blocking decisions.
    5. Introduce graded enforcement. Prefer lower-risk actions, such as applying ordinary rate limits to unverified automation, before making a signature mandatory. Reserve strict requirements for routes where you have confirmed support and where the cost of unauthorized access justifies the tighter rule.
    6. Keep a rollback path. Authentication failures should be visible, attributable to a specific policy, and reversible without redeploying unrelated application code.

    Place verification where request data can be inspected before an irreversible allow-or-deny decision. That may be at the edge in one architecture and inside a trusted gateway in another. Do not assume your CDN, security plugin, or bot-management service supports the protocol merely because it can read headers. Cryptographic verification requires a compatible implementation and a defined trust process.

    Before enabling enforcement, make the implementer answer the operational questions that matter for any signed-request system: What parts of the request are covered? How is the signing identity trusted? How are invalid, stale, or unverifiable proofs handled? How does verification behave during key or service changes? Which failure mode applies if the verifier is unavailable? If your stack cannot answer those questions, keep the integration in observation mode.

    Your logs should store conclusions that operators can use, not just a dump of unfamiliar authentication data. Useful fields include the claimed user agent, legacy-verification result, Web Bot Auth result, resolved identity, requested route, policy action, response status, and the component that made the decision. Apply your normal security, privacy, and retention rules to those records.

    Build AI-agent access rules around identity and purpose

    Verified automated agents follow different permission paths to public and restricted website resources, while policy barriers block access to sensitive areas.

    Once you can verify an agent, resist the urge to create a single global allowlist. Public articles, resource-intensive APIs, account pages, and licensed datasets do not have the same risk or purpose. The identity result should feed a route-specific policy.

    • Verified identity plus permitted route: allow the request under the limits assigned to that agent and content class.
    • Verified identity plus prohibited route: deny it. Authentication does not override the route policy.
    • No Web Bot Auth proof plus successful legacy verification: continue the established bot policy while coverage remains incomplete.
    • Claimed known identity plus failed verification: treat the request as untrusted and preserve the failed result for investigation.
    • Unknown automation: apply your general unknown-bot controls rather than granting access based on a recognizable name.

    Private or account-bound routes still need their ordinary application authentication and authorization. Bot identity proof is not a substitute for a user session, API credential, subscription entitlement, or content license.

    The same separation applies to robots instructions and other content-use rules. Web Bot Auth can help determine which agent is asking. Your published directives and internal access policy determine what that identity may receive. Keep those systems aligned, but do not merge them conceptually.

    For SEO, AEO, and GEO teams, the immediate benefit is cleaner observability rather than a promised visibility gain. Nothing in the limited rollout establishes Web Bot Auth as a ranking, citation, or inclusion mechanism. Do not change canonical tags, structured data, content architecture, or indexation rules merely because signed bot requests appear in your logs.

    Use the stronger identity signal to answer narrower operational questions: Which verified agents request your content? Which sections do they reach? What status codes do they receive? Where do rate limits or access rules interrupt them? How often does a claimed identity match a verified identity?

    Do not label a verified crawl as an AI citation, recommendation, or referral. A request proves an interaction with a URL, not what an agent later generated for a user. Keep server-side agent activity separate from user referral traffic and from any evidence that your brand appeared in an AI answer.

    Key takeaways and your next move

    • Web Bot Auth adds cryptographic identity evidence to participating bot requests.
    • The protocol remains experimental and is being tested with only some AI agents on Google infrastructure.
    • Not every Google user agent or request is signed, so missing proof is not proof of impersonation.
    • Keep user-agent, IP, and reverse-DNS verification running alongside Web Bot Auth during the rollout.
    • Authentication establishes identity; your route, content, and rate-limit policies still decide permission.
    • Use verified requests to improve bot observability, but do not treat a crawl as evidence of an AI citation or ranking benefit.

    Your next move is concrete: map the component that currently decides whether a bot request is allowed, add a multi-state Web Bot Auth verdict to that path, and run it without enforcement first. Preserve your existing controls until signed-request coverage is confirmed for the exact agents and routes you intend to govern.

    That design lets you benefit as adoption expands without making today’s legitimate unsigned traffic pay for tomorrow’s authentication model.

    References

  • How to Build Reliable SEO Agents That Verify Their Work

    How to Build Reliable SEO Agents That Verify Their Work

    You ask an SEO agent to audit a site, and minutes later it returns a polished list of problems. The real question is not whether the report sounds expert. It is whether every claim came from a page the agent retrieved, evidence it preserved, and a rule it can explain.

    If you cannot trace a finding from recommendation back to observation, you do not have a reliable SEO agent yet. You have a text generator with access to SEO vocabulary. The way forward is to build a small inspection system around the model: tools to collect facts, rules to classify them, tests to expose failure, memory to preserve lessons, and a deployment gate that blocks unsupported conclusions.

    Reliability begins with an evidence contract, not a longer prompt

    A role prompt can tell a model to act like an SEO expert. It cannot prove that the model fetched a URL, received the expected response, inspected the relevant HTML, or distinguished a real defect from an intentional configuration.

    This distinction matters because confident language can hide incomplete inspection. In one documented build, an agent returned 20 findings, eight of which described problems that did not exist. It had not actually visited many of the URLs behind those claims. Better wording would not have corrected that failure. The agent needed tools, evidence requirements, and a way to reject its own unverified findings.

    Before choosing a model or writing detailed instructions, define an evidence contract. It should answer five questions:

    • What may the agent inspect? Name the permitted inputs, such as XML sitemaps, robots.txt, HTTP responses, raw HTML, rendered page output, and crawl data.
    • What counts as proof? Require the requested URL, final URL, retrieval result, inspected representation, observed value, and applicable rule for every finding.
    • What can the agent conclude? Limit conclusions to issue types supported by its tools and reference criteria.
    • What happens when evidence is unavailable? Require an explicit unknown or unverified state instead of allowing the agent to guess.
    • What must appear in the deliverable? Define the fields, evidence excerpts, coverage totals, confidence state, and recommendation format before the run begins.

    Suppose the agent wants to report a missing canonical element. It must first show that the page was fetched successfully and that it inspected the intended representation. A redirect, authentication screen, bot challenge, blocked request, empty response, or tool failure does not prove that the canonical is missing. It proves that the check was not completed.

    The same discipline applies to indexability. Finding a noindex directive is an observation. Declaring it an SEO problem is a classification that depends on the page’s intended role. If the agent does not have that context, it should report the directive and request confirmation rather than inventing intent.

    Make the agent separate each result into three layers:

    • Observation: what the tool found, including the URL, response, element, value, and retrieval method.
    • Classification: the rule that turns the observation into confirmed issue, acceptable state, rejected candidate, or unknown.
    • Recommendation: the action justified by that classification, with any required human decision stated plainly.

    This separation makes review faster. A human can challenge the rule without disputing the collected fact, or rerun the collection step without rewriting the recommendation. It also prevents a plausible recommendation from disguising a weak observation.

    Give every SEO agent a workspace it can operate from

    An isometric workspace connects a central robotic agent to abstract page snapshots, structured records, rules, tests, an archive, and an error tray.

    A standalone prompt has nowhere to put operating procedures, executable tools, false-positive rules, previous failures, and output contracts. A dedicated workspace gives each of those concerns a stable home.

    Workspace componentWhat belongs thereReliability job
    AGENTS.mdOrdered methodology, allowed tools, stop conditions, escalation rules, and required outputKeeps the agent on the same operating procedure across runs
    SOUL.mdJudgment principles, skepticism rules, quality bar, and communication standardsDefines how the agent behaves when instructions do not cover an edge case
    scripts/Reusable crawlers, sitemap parsers, extractors, validators, and renderersCollects facts through repeatable operations instead of improvised commands
    references/Issue criteria, severity definitions, exceptions, and known false positivesSeparates real problems from noise
    memory/Run manifests, failure logs, rule changes, and regression historyPreserves lessons and exposes changes between executions
    templates/Finding records, summaries, evidence fields, and final report structurePrevents important fields from disappearing when prose varies

    The filenames are less important than the boundaries. Instructions should explain the workflow. Scripts should perform deterministic collection and validation where possible. References should define judgment. Memory should record what happened. Templates should constrain what can be published.

    Write AGENTS.md as an operating procedure, not a persona paragraph. An instruction such as “check the sitemap” leaves too much unspecified. A useful procedure tells the agent to look for sitemap declarations in robots.txt, try expected locations such as /sitemap.xml and /sitemap_index.xml, parse discovered sitemap indexes, record failed retrievals, and switch to an approved discovery method when no sitemap can be found.

    Give scripts equally clear contracts. A crawler should return structured records rather than a narrative. At minimum, each record should distinguish the requested URL from the final URL, record whether retrieval succeeded, preserve the response status, identify the collection method, and expose tool errors as data. The agent can explain those records later, but it should not have to reconstruct them from terminal prose.

    References need operational definitions. Do not write “flag bad canonicals.” Define the observable condition, the exceptions that suppress it, the evidence required for confirmation, and the severity rule. Put recurring traps in a separate gotchas file so they remain visible: intentional noindex pages, redirected URLs, blocked resources, duplicate URLs that resolve to one destination, and pages whose useful output requires rendering are examples of cases your test environment may need to cover.

    The output template should make unsupported findings difficult to express. Give every finding mandatory fields for evidence, rule ID, verification state, and affected URL. Reserve a visible section for unknowns and crawl failures. If the template offers only “issue” and “no issue,” the agent will be pushed toward false certainty whenever collection fails.

    Turn the audit into a collection and verification pipeline

    A reliable SEO audit is not one model call. It is a pipeline in which each stage produces an inspectable artifact for the next stage. The following sequence gives you a practical starting point.

    1. Create a run manifest. Record the target host, allowed scope, enabled checks, agent version, rule version, script versions, and any crawl constraints. This lets you explain why two runs differ.
    2. Discover the URL set. Start with declared sitemaps. Check robots.txt for references, then expected routes such as /sitemap.xml and /sitemap_index.xml. If none are available, use the approved crawl or supplied URL inventory and record that fallback.
    3. Collect responses without interpreting them. Apply configured rate limits, follow the approved redirect policy, and store requested URL, final URL, response result, and retrieval failure. A collection error belongs in the data, not in a discarded console message.
    4. Capture the representation required by each check. Preserve raw HTML for server responses. Use rendering when the initial response does not contain the elements a supported check needs. Label the representation so reviewers know what was inspected.
    5. Generate candidate observations. Extract canonical elements, robots directives, status behavior, titles, descriptions, links, or other in-scope signals without calling them defects yet.
    6. Verify every candidate. Recheck the relevant page and element through the appropriate tool. Reject stale, contradictory, duplicated, or unsupported candidates. If verification cannot finish, change the state to unknown.
    7. Classify against explicit criteria. Apply the relevant rule and its exceptions. Preserve the rule identifier and reason so a reviewer can reproduce the decision.
    8. Build the report from verified records. Let the model prioritize and explain confirmed findings, but do not let it introduce new URLs, counts, or diagnoses that are absent from the records.

    The pipeline should retain rejected candidates as internal run data. They tell you where the agent almost produced a false positive. If a rule repeatedly rejects the same pattern, you may be able to move that exception earlier in the workflow and save verification work.

    Coverage also needs to be explicit. Report separate totals for URLs discovered, retrievals attempted, pages fetched, pages inspected for each enabled check, and pages left unknown. “Crawled 500 URLs” is not useful if only part of that set reached the check that produced the recommendation. The denominator for a claim must be the set actually inspected for that claim.

    Do not collapse access failure into site failure. A CDN response, rate limit, robots restriction, timeout, or rendering error can stop the agent from observing the page. None of those outcomes proves that the suspected on-page issue exists. After the configured retry and fallback paths are exhausted, publish the limitation as a limitation.

    A compact finding record can carry the chain of evidence:

    • Run ID and rule version
    • Requested URL and final URL
    • Retrieval state and inspection method
    • Observed element or response value
    • Rule ID and applied exception
    • Verification state: confirmed, rejected, or unknown
    • Recommended action and any decision that still needs a person

    Once those fields exist, the model’s job becomes narrower and safer. It can group related findings, explain likely consequences, and make the report readable. It no longer needs to invent the factual substrate underneath the prose.

    Make every failure a regression test and a permanent lesson

    A transparent audit machine collects abstract web pages, preserves evidence, checks rules, and routes a failed item through a test bench into a new checkpoint.

    You cannot establish reliability by running the agent once on a cooperative site. Build a small fixture set in which the expected observations and classifications are already known. It should include clean pages as well as failures, because an agent that finds seeded defects may still produce unacceptable noise on valid configurations.

    Your fixture set should exercise the conditions your agent claims to handle:

    • A static page with all required elements present
    • A page with a deliberately missing in-scope element
    • A page with a canonical element that should not be flagged
    • An intentionally noindexed page whose intent is supplied to the test
    • A redirect and its final destination
    • A nonexistent URL
    • A blocked, challenged, or rate-limited response
    • A route whose supported checks require rendered output
    • A standard sitemap, a sitemap index, a robots.txt sitemap declaration, and a site with no discoverable sitemap

    For each fixture, store the expected collection result, extracted observation, classification, and output state. Run the suite whenever you change instructions, scripts, issue criteria, templates, or model configuration. Review both misses and false positives. A report that catches every seeded problem but invents several more is not ready.

    When a live run fails, convert the failure into four artifacts:

    1. A minimal fixture that reproduces the condition
    2. A test that fails before the correction
    3. A change to the appropriate script, instruction, or reference rule
    4. A run-log entry that explains the symptom, cause, correction, and affected version

    This is how iteration creates an accumulating reliability advantage. Problems involving modern CDNs, rate limiting, JavaScript rendering, sitemap discovery, and noisy classifications stop being isolated surprises once their fixes are preserved in the workspace and exercised on every later change. The architecture becomes measurably better as failures become reusable lessons.

    Memory must not become a substitute for current evidence. A previous run may tell the agent that a URL once lacked a meta description, but it cannot prove the page still lacks one. Use memory to retain operating knowledge, compare changes, and select regression checks. Require a fresh observation before making a current-site claim.

    A useful run log records the run ID, workspace version, scope, discovery method, coverage totals, confirmed findings, rejected candidates, unknown checks, tool failures, and rule changes. Keep links to retained evidence where your data-handling rules allow it. This gives you a basis for comparing runs without asking the model to remember what happened.

    Repeatability does not mean every sentence must be identical. It means the same collected facts and rule versions should produce the same classifications. Keep factual extraction and rule evaluation structured; allow the model more freedom only when it turns those stable records into reader-friendly explanations.

    Key takeaways before you deploy

    Use this as the release gate for an SEO agent that will influence audits, tickets, or client recommendations:

    • Require evidence for every finding. A published issue must identify the inspected URL, observed value, retrieval method, verification state, and rule that supports it.
    • Keep observation separate from judgment. The tool collects the fact, the criteria classify it, and the final layer recommends an action.
    • Treat inaccessible as unknown. A failed request, blocked page, rendering problem, or exhausted retry path must never be translated into a missing element.
    • Expose coverage. Show how many URLs were discovered, fetched, inspected for each check, and left unresolved so readers can interpret the scope correctly.
    • Test valid and invalid configurations. Your regression set must prove that the agent can stay quiet on acceptable pages as well as detect seeded problems.
    • Preserve every correction. A false positive should result in a fixture, regression test, rule or tool change, and versioned run-log entry.
    • Keep memory subordinate to fresh inspection. Previous runs can guide comparisons and testing, but current claims require current evidence.
    • Block unsupported prose. The report generator may explain and prioritize verified records; it may not add facts, URLs, counts, or issue types that the pipeline did not produce.

    Your next move should be deliberately narrow. Build a URL inventory agent that records discovery, redirects, response results, indexability signals, and canonical observations. Give it known fixtures, force it to show unknowns, and manually inspect a sample of its evidence on a site you control. Add another issue class only after the first one survives the same gate across repeated runs.

    That pace may feel slower than asking for a comprehensive audit in one prompt. It is also how you end up with an agent whose conclusions deserve to be acted on.

    References

  • How to Give AI Agents Live Marketing Data Without Losing Control

    How to Give AI Agents Live Marketing Data Without Losing Control

    If your AI workflow begins with exporting campaign data, pasting it into a chat, and explaining the same business context again, you do not have an agent. You have a capable analyst waiting for a manual data delivery.

    The fix is not a longer prompt. You need a controlled path from your marketing systems to the agent, with enough current context to support a decision and enough guardrails to stop a bad decision from becoming an expensive action.

    Live means decision-ready, not merely connected

    Live marketing data does not have to mean that every event reaches the agent within milliseconds. It means the information is refreshed before the decision it supports becomes stale. A pacing decision may need current spend and budget data. A lead-quality decision may need the latest CRM disposition. A promotion may need inventory availability before the agent recommends sending more traffic to it.

    That distinction matters because access alone is not enough. An agent can be connected to Google Ads and still make a poor decision if it cannot see what happened after a conversion. It can be connected to a CRM and still misread performance if campaign identifiers do not match. It can see inventory data and still act on an item whose availability record is old.

    A familiar failure starts with a keyword that appears healthy inside the ad platform. It has useful volume and an acceptable cost per acquisition. The CRM, however, shows that the resulting leads are being disqualified. Without that downstream outcome, the agent will keep treating the keyword as successful and may continue spending until a person reconciles the systems. Repeated exports and delayed cross-checks preserve this blind spot; they do not create automation.

    SystemWhat the agent can learnDecision it can improve
    Ad platformSpend, conversions, volume, and campaign performanceWhere traffic appears efficient
    CRMQualification, sales progression, and lead dispositionWhether reported conversions have business value
    Inventory systemAvailability and stock constraintsWhether demand should be increased for a product

    Before integrating anything, write down the decision the agent will support and how fresh each input must be for that decision. If you cannot define when the data becomes too old to trust, the word live is doing no useful work.

    Build a decision context, not a giant data dump

    Raw marketing inputs pass through filtering and verification stages before a compact bundle of relevant context reaches an AI reasoning system.

    An agent rarely needs unrestricted access to every field in every marketing system. It needs a compact, reliable view of the variables that determine one decision. Sending more data without defining its meaning can make the workflow harder to inspect and easier to misconfigure.

    Build that view from the decision backward:

    1. Name the decision. Be precise: recommend a bid change, flag a lead-quality problem, pause promotion of unavailable inventory, or produce a daily exception list.
    2. List the evidence required. Separate platform metrics from business outcomes. A conversion count is not the same thing as a qualified lead, a sale, or an item that can still be fulfilled.
    3. Choose the join keys. Decide how campaign, ad group, keyword, click, lead, customer, product, and order records connect. If systems use different identifiers, define the mapping before the agent sees the data.
    4. Normalize time and meaning. Record the reporting window, timezone, attribution context, currency, and status definitions relevant to the decision. The agent should not have to infer whether two similarly named fields measure the same event.
    5. Attach provenance and freshness. Return the originating system and update time with the value. The agent needs to distinguish a current zero from a missing or stale record.
    6. Define conflict behavior. Decide which system controls when records disagree. If the CRM says a lead is disqualified while the ad platform counts a conversion, the workflow should preserve both facts and use the business outcome for the decision you defined.

    This turns integration into a data contract. Each input has a source, definition, identity, update time, and permitted use. That contract also gives your team something concrete to test when the agent behaves unexpectedly.

    Use MCP as the connection layer, not the policy

    The Model Context Protocol, or MCP, provides a standardized way for an AI client to connect to external tools and data sources. In a marketing workflow, an MCP implementation can expose ad performance, CRM outcomes, and inventory information through a consistent interface instead of forcing you to create a separate conversational integration for every system. This can remove much of the manual handoff that keeps an agent from working with current data.

    MCP does not decide what a qualified lead means, repair broken campaign identifiers, choose a safe budget policy, or determine whether the agent should be allowed to change a bid. It is the connection layer. Your data contract and control layer still carry the business logic.

    Expose narrow tools that correspond to real tasks. A useful initial tool set might let the agent read campaign performance, retrieve CRM dispositions, check product availability, and generate a recommendation. A later tool could execute a preapproved campaign rule. A generic tool with unrestricted account access is harder to audit and creates a much larger failure surface.

    The tool description should also tell the agent what the result does not prove. For example, ad-platform conversions describe recorded conversion events; they do not by themselves establish lead quality. Inventory availability can constrain promotion; it does not establish campaign profitability. Clear boundaries reduce the chance that the model treats one system’s partial view as the complete business outcome.

    Put enforceable guardrails between reasoning and action

    Proposed AI actions pass through layered permission, validation, spending-limit, audit, and human-approval controls before reaching marketing systems.

    Read access and write access are different risk decisions. A mistaken read may produce a bad recommendation. A mistaken write can change bids, pause campaigns, redirect spend, or promote stock that is not available. Do not grant unrestricted write access merely because the agent has produced sensible analysis in a chat window.

    A prompt is not a permission system. Instructions such as be careful or do not overspend can influence behavior, but they do not enforce account boundaries. Operational constraints need to sit around the agent, where the integration can reject an action that falls outside policy.

    Define every write-capable action with these controls:

    • Permission: Specify whether the agent can read, recommend, or execute. Default new workflows to read-only.
    • Scope: Restrict access to the relevant accounts, campaigns, markets, products, and action types.
    • Preconditions: Require the necessary data sources to be available and fresh before an action can run.
    • Policy limits: Encode the budget, bid, status, and inventory rules the action must satisfy. The surrounding system, not the model’s prose, should enforce them.
    • Approval: Route high-impact or ambiguous changes to a person. The agent should return the proposed action, supporting evidence, and reason for escalation.
    • Auditability: Record the inputs, tool calls, decision, approver when applicable, and resulting change.
    • Recovery: Preserve enough prior state to reverse a change when the platform and action type allow it.

    Roll out those permissions in stages. Begin with read-only analysis and verify that the agent retrieves the right records. Next, let it recommend actions while a person compares those recommendations with actual decisions. Then allow only bounded, reversible writes with enforced preconditions. Expand the scope after the data and control layers have proved reliable, not merely after the model has written persuasive explanations.

    Test the data path before judging the agent

    When an agent produces a questionable answer, teams often adjust the prompt first. That is useful only if the required evidence reached the model correctly. A polished prompt cannot recover a missing CRM record, an incorrect join, or inventory data that failed to refresh.

    Test the pipeline with cases that reveal those failures:

    • Freshness: Can you see when each source last updated, and does the workflow stop when a required input is stale?
    • Coverage: Are all in-scope campaigns, leads, products, and accounts represented, or does the connector silently omit some records?
    • Identity: Can a conversion be connected to the correct lead or order and then traced back to the responsible campaign entity?
    • Semantics: Do conversion, qualified lead, sale, availability, and revenue have explicit definitions in the systems that provide them?
    • Missing data: Does the agent distinguish no activity from unavailable data? Treating both as zero can trigger the wrong action.
    • Conflicts: What happens when two systems disagree? The workflow should surface the disagreement rather than silently choosing whichever value arrived first.
    • Failure mode: If the CRM or inventory service is unavailable, does the agent stop, fall back to recommendation-only mode, or request review? Continuing with partial context should be an explicit policy choice.

    Evaluate the system against the decision it was built to improve. For a lead-quality workflow, inspect whether it identifies campaigns producing disqualified leads. For an inventory-aware workflow, inspect whether it avoids recommending more demand for unavailable products. Fluent explanations are useful for review, but they are not evidence that the underlying joins and controls work.

    Key takeaways

    • Live data is data that arrives before the supported decision becomes stale; it is not simply data behind an API.
    • An agent needs business outcomes from systems such as the CRM and inventory platform, not only the conversion view inside an ad platform.
    • Start with one decision and build a defined data contract for its evidence, identifiers, timing, provenance, and conflict rules.
    • MCP can standardize how AI clients reach tools and data, but it does not replace data modeling, permissions, or business policy.
    • Keep new agents read-only until you have validated retrieval, joins, freshness, and failure behavior.
    • Enforce write limits outside the prompt, and log the evidence and action so a person can inspect what happened.

    Choose one recurring marketing decision that still depends on an export or spreadsheet reconciliation. Map the platform metric, downstream business outcome, join key, freshness requirement, and permitted action. That small, inspectable workflow is the right place to prove live data access before you give an agent broader reach.

    References