Category: PPC

  • AI-Driven PPC Strategy: Measure What the Algorithm Learns

    AI-Driven PPC Strategy: Measure What the Algorithm Learns

    Your ad platform says automation found more conversions. Your CRM says qualified pipeline barely moved. Or the reverse: reported conversions fell while orders or accepted leads held steady. If you treat either dashboard as unquestioned truth, your AI-driven PPC system can learn from a distorted version of the business.

    The answer is not to wait for perfect tracking. It is to connect two systems deliberately: the decision engine that allocates ad spend and the evidence system that checks whether those decisions created valuable outcomes. You need a clear optimization signal, an independent business record, redundant collection paths, and rules for making decisions when the numbers disagree.

    Key takeaways

    • Automation optimizes the event you send it, not the business intent you meant to express.
    • Use a browser event for fast feedback and a backend outcome for business validation. Neither view is sufficient by itself.
    • Server-side delivery can improve data collection, but it cannot repair a vague conversion definition or override consent.
    • Expect the ad platform, analytics system, and CRM to disagree. Reconcile their definitions and trends instead of forcing their totals to match.
    • Treat AI Max and other automated features as governed experiments with business-level success metrics, spending guardrails, and a rollback rule.

    Give the algorithm a signal worth optimizing

    An AI-driven campaign does not understand your growth strategy in the abstract. It sees inputs: conversions, values, costs, audience and query patterns, and whatever feedback returns to the platform. If the easiest event to collect is a form submission, the system can become very good at finding form submissions. That does not mean it will find accepted opportunities, profitable orders, or customers who remain valuable.

    Before changing a bidding strategy or enabling another automated feature, write an optimization contract for the campaign. It should answer these questions:

    1. What business outcome matters? Name the outcome in operational terms, such as a completed purchase, an accepted lead, or a booked engagement.
    2. What event will the platform optimize? Choose an event that occurs often and soon enough to provide usable feedback, but remains close enough to the business outcome to represent real value.
    3. Which system owns the truth? Decide whether the CRM, order database, billing system, or another backend record settles the final business result.
    4. How long does validation take? Measure the actual time between the ad interaction, the optimization event, and the final outcome. Do not evaluate results before the relevant outcomes have had time to mature.
    5. What must never count? Define exclusions for duplicates, test records, spam, cancelled orders, rejected leads, internal activity, and any other event that would teach the system the wrong lesson.

    Use a signal ladder, not one overloaded conversion

    A practical account separates three jobs that are often collapsed into one conversion column:

    • Optimization signal: the event the campaign is allowed to learn from and bid toward.
    • Validation outcome: the later business result used to determine whether the optimization signal remains trustworthy.
    • Guardrail metrics: indicators that expose harmful trade-offs, such as rising spend, weaker lead acceptance, lower order value, or a change in the mix of outcomes.

    For lead generation, a raw form submission may be useful as an early diagnostic event while an accepted or qualified lead provides a stronger optimization signal. For ecommerce, an add-to-cart can help diagnose the journey, but a completed order and its value are closer to the business result. The correct hierarchy depends on your volume and conversion lag. The important decision is which event is diagnostic, which is trainable, and which validates commercial value.

    Offline conversion imports move later outcomes from backend systems into the measurement loop, reducing dependence on a browser surviving the entire journey. They are especially useful when the meaningful outcome occurs after the website event or inside a CRM. Keep the browser event as an early signal where it remains useful; do not assume it represents the whole customer journey.

    Create an event dictionary before sending data

    For every event sent to an ad platform, record:

    • the exact trigger and the system where it occurs;
    • the business meaning of the event;
    • whether it is used for optimization, observation, or validation;
    • the timestamp and value rules;
    • the identifier used to prevent duplicate processing;
    • the events or records that must be excluded;
    • the person or team responsible for approving definition changes.

    This dictionary prevents a quiet but expensive failure: changing the meaning of a conversion without changing its name. If a campaign learns from one definition this month and a broader definition later, the performance graph may improve even though customer quality did not. Version the definition, annotate the change, and avoid judging campaign performance across incompatible versions.

    Build a redundant measurement stack for partial data
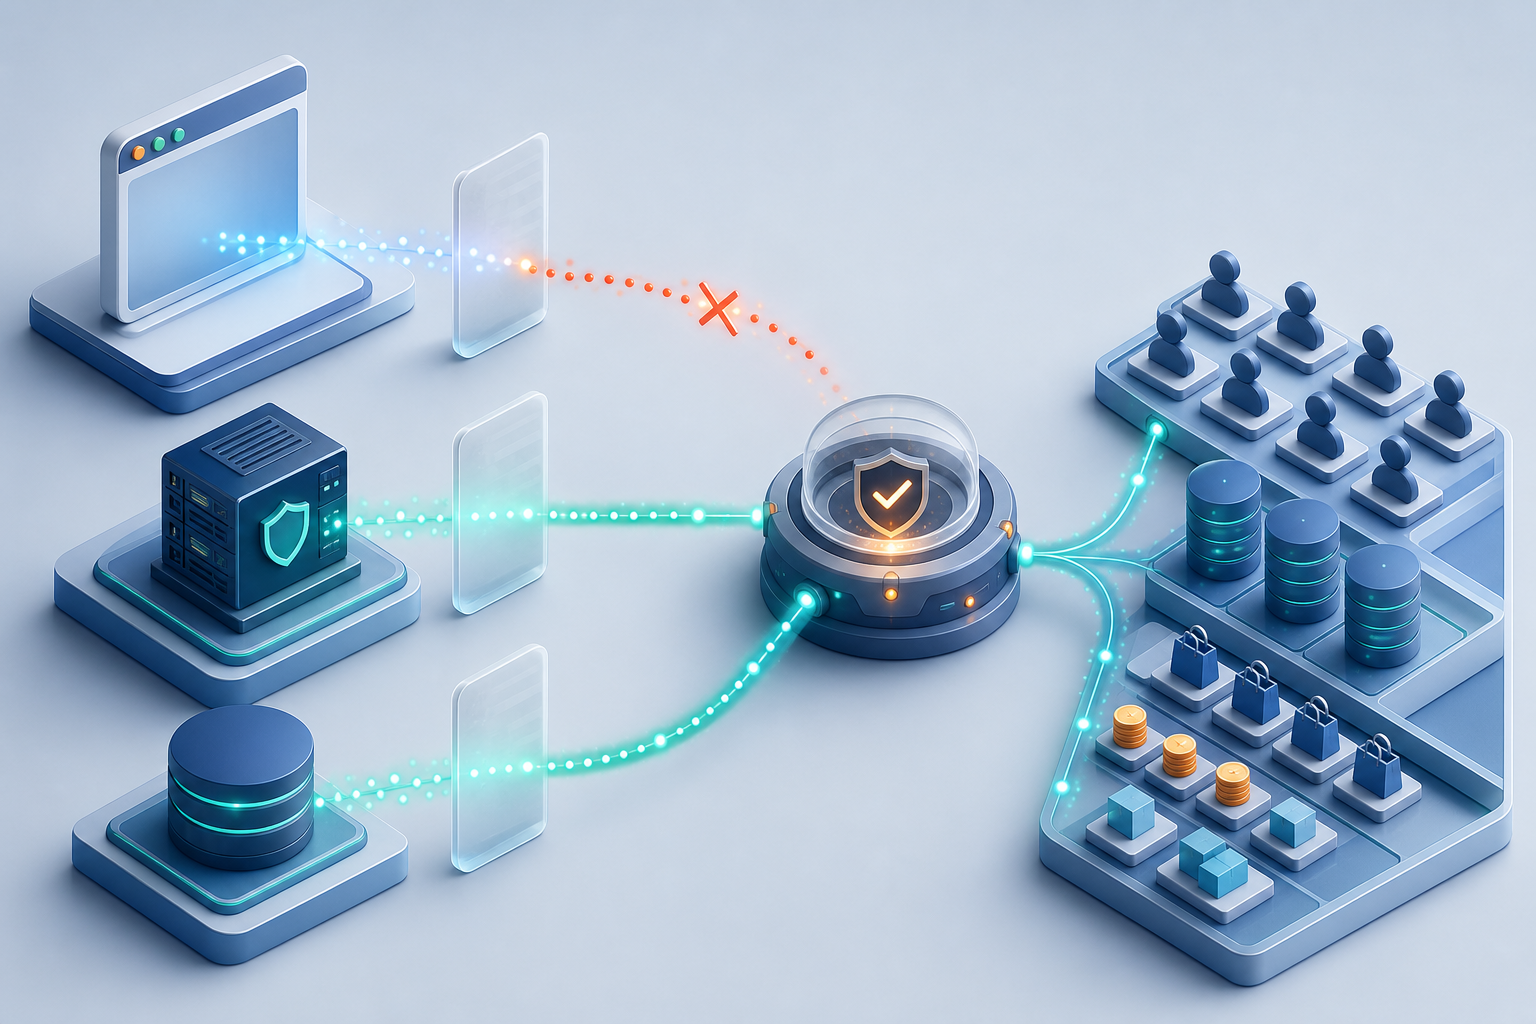
    Three independent data paths connect an advertising source, a server node, and a business database despite gaps and privacy barriers.

    A browser pixel is still useful, but it no longer provides complete observability. Click identifiers can disappear, cookies may not persist, consent can limit collection, and conversions may arrive after a delay. Restrictions such as Apple’s Intelligent Tracking Prevention are part of the environment in which missing GCLIDs and incomplete browser-side records have become routine measurement conditions.

    Build the stack around distinct views rather than asking one tool to perform every job:

    Measurement viewQuestion it answersBest useWhat it cannot prove alone
    Ad platformWhat feedback did the delivery system receive?Optimization, pacing, and campaign diagnosticsThat attributed conversions equal incremental business growth
    Analytics and browser eventsWhat observable actions occurred on the site?Journey and implementation diagnosticsA complete record when identifiers, cookies, or consent are unavailable
    CRM, order, or backend systemWhich outcomes did the business accept and value?Commercial validation and outcome qualityPerfect ad matching for every record

    These totals can disagree without any system being wholly useless. They answer different questions, use different definitions, and observe different parts of the journey. Your task is to understand the disagreement well enough to make a decision.

    Use several collection paths without counting outcomes twice

    • Client-side events provide fast feedback about observable website actions. Keep them lean, documented, and tested across consent states.
    • Improved tag delivery can reduce preventable collection failures. A same-origin approach such as Google Tag Gateway changes how tags are delivered, but it does not determine which events deserve to count.
    • Offline imports return accepted leads, completed sales, or other backend outcomes to the platform after the browser session has ended.
    • An internal reconciliation record preserves every business outcome, including records the ad platform cannot match. Unmatched outcomes must not disappear merely because they cannot support platform attribution.
    • Modeled reporting may fill gaps when consent or identifiers are missing. Treat modeled conversions as inference, not as individually observed customer records.

    Redundancy means preserving independent evidence, not sending the same outcome repeatedly under several names. When an event can arrive through both browser and backend paths, establish a stable deduplication rule and test replay behavior before using the event for optimization. A duplicated high-value conversion is not just a reporting error; it can redirect spend toward the conditions that produced the duplicate.

    Server-side collection is also not a consent bypass. It changes the route data takes, not whether you are permitted to collect and use it. Configure consent behavior explicitly, document the data flow, and involve the people responsible for privacy and legal review before sending new customer data to an advertising platform.

    Run a failure drill before relying on the stack. Check what happens when a browser event is blocked, an identifier is absent, an offline import is delayed, and the same event is submitted again. For each case, decide which record remains available, what alert should appear, and whether the campaign may continue optimizing safely. That gives you a recovery plan before a dashboard gap becomes a spending problem.

    Test AI features as controlled business changes
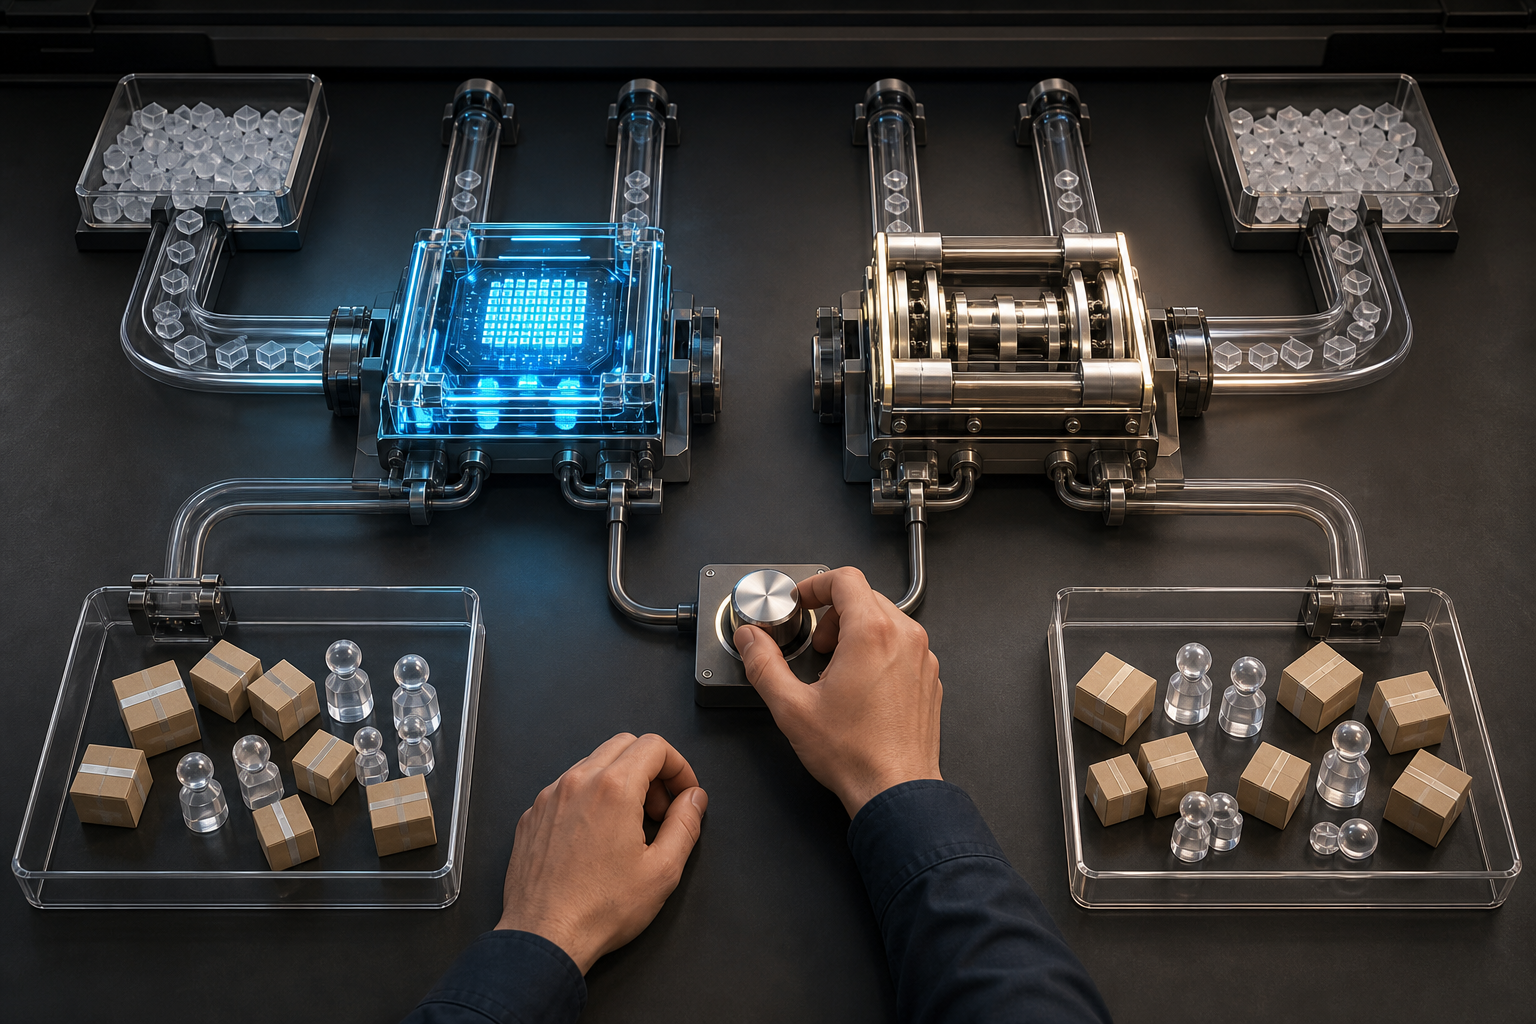
    Two parallel advertising experiment channels compare an AI-controlled route with a stable control route using purchase and customer outcome objects.

    Google is promoting AI Max directly inside Search campaign settings. That placement makes adoption easy, but it does not establish that the feature fits your account, measurement maturity, or risk tolerance. A prompt inside the buying platform is a product recommendation from a party that benefits when advertisers use more of the platform. Your own success criteria still have to govern the decision.

    Treat AI Max, automated bidding changes, and other AI-led controls as experiments that can affect real spend. Do not enable one merely because it appears during an account audit. Write the test brief first:

    • Hypothesis: state the mechanism you expect to improve, not just the metric you hope will rise.
    • Scope: identify the campaigns, markets, products, and conversion actions included. Keep unrelated areas out of the test.
    • Training signal: name the exact event and event-definition version the automation will receive.
    • Business success metric: use the accepted outcome or value held in your backend system.
    • Guardrails: define the spending, outcome-quality, customer-mix, and relevance conditions that would make the result unacceptable.
    • Comparison: use a platform experiment where an appropriate one is available. If you rely on a before-and-after comparison, label it as observational and account for changes in demand, budgets, offers, and conversion maturity.
    • Rollback rule: decide in advance what will cause you to stop, what settings must be restored, and which measurement data must be preserved for diagnosis.

    Separate measurement changes from campaign changes

    If you redefine a conversion, launch an offline import, change bidding, and enable a new AI feature together, an improved graph will not tell you which change caused it. Sequence the work:

    1. Validate the browser and backend events against real business records.
    2. Freeze the event definitions and record their versions.
    3. Confirm that delayed imports, exclusions, consent behavior, and deduplication work as intended.
    4. Establish the pre-test business outcome and measurement-discrepancy patterns.
    5. Run the automation change in the defined scope.
    6. Wait for the relevant business outcomes to mature before making the final judgment.
    7. Compare platform performance, backend outcomes, guardrails, and measurement coverage in the same decision record.

    Early platform indicators can help you catch a delivery or tracking failure, but they should not overrule an immature business result. If your accepted outcome normally appears well after the initial conversion, a fast improvement in reported cost per conversion is an early observation, not yet proof of better economics.

    When a controlled experiment is not possible, be precise about the strength of the conclusion. A before-and-after change can show that two things moved together. It cannot isolate the effect of automation from seasonality, changing demand, a new offer, or a measurement change. You may still make a practical decision, but record the uncertainty instead of presenting estimated lift as settled fact.

    Treat dashboard disagreements as diagnostic evidence

    Partial observability changes the question you ask. Instead of asking which dashboard is correct, ask what each system observed, what it inferred, and what it could not see. The pattern of disagreement often tells you where to investigate first.

    • Platform conversions rise while accepted outcomes stay flat: inspect the optimization-event definition, duplicate processing, low-quality lead sources, outcome mix, and any change in the distance between the early event and the business result.
    • Business outcomes rise while platform conversions stay flat: inspect lost identifiers, consent effects, blocked browser events, delayed offline imports, matching coverage, and import errors before reducing spend solely because platform reporting looks weak.
    • Browser events fall while backend outcomes remain stable: investigate collection and consent behavior first. Compare the event implementation with independent order or CRM records before assuming demand collapsed.
    • Every view falls: check measurement health, but also examine demand, offer, landing experience, eligibility, budgets, and campaign delivery. A tracking explanation should not become a reflex that hides a real performance problem.
    • Platform performance improves immediately after a definition change: compare the old and new event rules. The account may be counting more events rather than creating more value.

    These patterns are starting hypotheses, not automatic diagnoses. Confirm them with event-level samples, import logs, backend records, and a timeline of account changes.

    Reconcile without manufacturing agreement

    A useful reconciliation process explains differences while protecting the original records:

    1. Choose the cohort basis: interaction date, early-event date, or business-outcome date. Do not mix them silently.
    2. Align the conversion definition, timestamp logic, inclusion rules, and value calculation across reports.
    3. Separate observed website events, imported outcomes, and modeled gaps wherever the available reporting allows it.
    4. Measure which backend outcomes were matched to the ad platform and retain the unmatched population as a visible category.
    5. Review duplicate, rejected, cancelled, spam, test, and missing-value records separately rather than deleting them from the investigation.
    6. Record the remaining discrepancy and its likely causes. Do not rewrite CRM outcomes merely to make the advertising report balance.

    Your decision log should then capture the campaign change, hypothesis, event-definition version, expected conversion lag, available early evidence, final backend result, guardrail outcome, and decision. This creates institutional memory when a platform recommendation reappears or a later team member asks why an automated setting was accepted or rejected.

    The most useful next step is small and concrete: choose one important campaign and write its optimization contract. Trace the event from browser to backend, identify the record that validates business value, and rehearse the failure cases. Only then test an additional AI control. If you cannot name what the algorithm is learning from and what independent evidence will judge it, the account is not ready for more automation.

    References

  • Uncover the Top Blocker to PPC Growth and Fix It

    Uncover the Top Blocker to PPC Growth and Fix It

    I’ve been there myself. A client approaches me, eager to upscale their Google Ads spend from €10,000 to €100,000 monthly. Like any dedicated PPC manager, I dive into the usual strategies:

    • Refine bidding strategies.
    • Test new ad copy.
    • Expand keyword lists.
    • Optimize landing pages.
    • Boost Quality Scores.
    • Launch Performance Max campaigns.

    Several months in, the ad spend only grows by 15%. The client is content, but I know we can do better.

    Here’s a harsh truth I’ve learned: much of what we consider PPC optimization is really just sophisticated procrastination.

    The theory of constraints, introduced by Eliyahu Goldratt, offers insights for PPC much like it does for manufacturing. It shows that every system has a single constraint that limits its potential.

    It doesn’t matter if the marketing team is super-efficient if the production capacity is what’s limited. Likewise, a 20% improvement in ad copy CTR isn’t useful if the real constraint lies in budget or conversion tactics.

    This theory calls for radical focus: pinpoint the weakest link, make it your priority, and tune out the rest.

    Applying this to PPC means stopping the widespread optimization efforts. Detect the primary barrier, resolve it, and press on.

    Over time, managing PPC accounts has shown me that scaling challenges usually fit within one of seven categories:

    Budget: Profitability could be higher, but client approval caps spending.

    For instance, a campaign might run successfully at €10,000 monthly, with scope to go to €50,000, yet the client hesitates due to risk aversion or cash flow concerns.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    Developing a compelling business case that showcases past ROI and projected returns is vital here.

    I ignore ad copy tests or keyword expansions because, if I can’t increase budget, they won’t help.

    Impression Share: Already capturing over 90% share, limiting traffic growth.

    Entering new markets or ad platforms can often be the solution for these scenarios.

    The Creative aspect needs tightening when high impressions yield low CTRs, and so on for conversion rate, fulfillment, profitability, and tracking or attribution challenges.

    With my diagnostic steps, I start by running an audit to benchmark the key metrics—impression share, CTRs, CPCs, and conversion rates— to pinpoint what’s genuinely holding the account back.

    The moment I finish an audit and single out the top challenge, the focus becomes precise. For instance, if it turns out conversion rate optimization can unlock growth, that’s where all my efforts channel into until I see a breakthrough.

    Every time the constraint is overcome, a new bottleneck emerges, signifying growth and the movement to new phases. It is both a marker of success and a roadmap to what needs attention next.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Performance Max Testing and Diagnostics: A Practical System

    Performance Max Testing and Diagnostics: A Practical System

    Your Performance Max results have moved in the wrong direction, and the campaign offers enough levers to make almost any explanation sound plausible. You could replace assets, add negatives, split campaigns, exclude placements, or change the budget before lunch. If you do all of them, you may change performance, but you will lose the ability to explain why.

    The better question is not “What can I optimize?” It is “Which layer failed?” Start with conversion data, establish a stable baseline, test one hypothesis, and only then intervene at the search, channel, placement, or device layer.

    Verify the conversion signal before diagnosing the campaign

    A technician inspects a glowing signal passing from a parcel through translucent verification gates, with one gate visibly misaligned.

    Performance Max depends on conversion data for both reporting and automated bidding. When a CRM import, offline conversion feed, or tag connection breaks, the campaign can appear to deteriorate even when the first failure occurred in the measurement pipeline. Optimizing against that false decline can waste budget and teach the bidding system from incomplete outcomes.

    Google Ads’ Data Manager includes a central diagnostics view for data connections. It assigns statuses such as Excellent, Good, Needs Attention, and Urgent, and it can surface refused credentials, formatting problems, failed imports, and tagging mismatches. Its run history also shows recent synchronization attempts and error counts.

    Use that information as an incident log, not as decoration. A Needs Attention or Urgent connection should stop a creative or targeting diagnosis until you understand whether conversions are missing. An Excellent or Good status is useful, but it is not proof that you selected the right conversion action or assigned the right business value. It tells you about connection health, not the quality of your measurement design.

    1. Record when the unexplained performance shift began. Do not rely on memory; you will need to compare that point with import and synchronization history.
    2. Check every data connection that supplies conversions used by the campaign, including CRM and offline conversion imports.
    3. Read the status and actionable alerts. Separate an authentication failure from a formatting error, a failed import, or a tag mismatch because each requires a different fix.
    4. Open the run history and identify the first unsuccessful or error-heavy synchronization. A failure that starts near the apparent campaign decline is a measurement lead worth resolving first.
    5. Compare completed outcomes in the originating business system with successfully imported outcomes for the same period. This helps distinguish a reporting gap from a real demand or traffic problem.
    6. After restoring the connection, mark the affected dates as an incident window. Do not use that contaminated period to declare a creative winner or justify a structural campaign change.

    This order matters most when you optimize toward offline revenue, qualified leads, or later-stage CRM events. A small import failure can make high-quality traffic look unproductive, while a delayed correction can make the recovery look like sudden campaign growth. Neither interpretation describes the media accurately.

    Build a baseline that separates the diagnostic layers

    Once the conversion pipeline is credible, take a campaign snapshot before editing anything. Record the campaign and asset group, the conversion objective being evaluated, the date of the last material change, conversion volume or value, spend, and the efficiency metric tied to your business goal. Add notes for promotions, feed changes, landing-page changes, and other events that could alter demand or conversion rate.

    The snapshot gives every later comparison an anchor. It also forces you to distinguish a campaign-wide decline from a concentrated problem. That distinction determines whether you need an experiment, an exclusion, or no change at all.

    Diagnostic questionWhere to inspect itWhat the view can establishImportant limitation
    Did the conversion pipeline fail?Data Manager diagnostics and run historyConnection status, synchronization failures, error types, and error countsA healthy connection does not validate the business definition of a conversion
    Did query intent change?Campaign-level search term viewSearch terms with campaign metrics that can support exclusions and intent analysisThe visibility applies to search-network traffic, not every Performance Max channel
    Are search themes contributing?Search theme reportingWhether a theme is receiving traffic and producing conversionsLow use is different from poor performance
    Did delivery move between networks?Channel performance reportPerformance across channels such as Search, Discover, and DisplayA channel difference identifies where to investigate; it does not by itself prove the cause
    Is inventory irrelevant or unsafe?Placement data in the API or Report EditorSpecific placements that warrant relevance or brand-safety reviewPlacement analysis does not explain search-query performance
    Is the issue concentrated by device?Device reportingDifferences in product and campaign outcomes across devicesSplitting campaigns can fragment the data used by machine learning

    Do not confuse grouped search term insights with the campaign-level search term view. Grouped insights can help you recognize query categories, but they have lacked the cost depth needed for many optimization decisions. The campaign-level view exposes more detailed search metrics, although it still describes only the search-network portion of Performance Max.

    That limitation changes how you interpret silence. If the search view does not explain the decline, you have not proved that search is healthy or that another channel is guilty. You have only eliminated the visible search terms as the complete explanation. Move to the channel report rather than stretching search-only data across the whole campaign.

    Run a creative experiment only when creative is the question

    A built-in Performance Max beta makes structured creative testing possible inside one campaign and asset group. You can define a control from existing assets, create a treatment with alternatives, retain shared assets across both variants, and assign a traffic split such as 50/50. This within-asset-group experiment reduces interference from separate campaign structures.

    Use the beta when your hypothesis is genuinely about creative. It cannot cleanly answer whether a budget change, product feed edit, landing-page release, search-term exclusion, or conversion import repair caused the result. If those variables move during the experiment, the split may still produce numbers, but the business conclusion will be weak.

    1. Write one falsifiable hypothesis. Name the asset change, the business metric expected to improve, and the reason the audience should respond differently.
    2. Select one campaign and one asset group where the beta is available. Confirm that both variants will be evaluated against the same conversion setup.
    3. Use the current creative set as the control. Change only the intended creative variable in the treatment, and share assets that are not part of the hypothesis across both sides.
    4. Choose the traffic allocation deliberately. A 50/50 split gives the two variants equal traffic opportunity, but it also assigns half of experiment traffic to an unproven treatment.
    5. Define the decision rule before launch. Choose a primary business outcome and note any guardrails, such as conversion volume or spend, that would make an apparent efficiency gain commercially unacceptable.
    6. Freeze unrelated campaign changes. Keep a change log so that an emergency edit, promotion, feed update, or measurement incident is visible during interpretation.
    7. Give the experiment enough time. Early experience indicates that tests shorter than three weeks can be unstable, particularly in lower-volume accounts. Three weeks is a warning boundary, not a universal guarantee of certainty; low volume may require a longer run.
    8. Apply the treatment only when the result answers the original hypothesis. If the evidence is inconclusive, preserve that conclusion instead of promoting whichever side happens to be ahead at the stopping point.

    The last step is easy to mishandle. A tie or inconclusive result is useful: it tells you that the proposed creative change has not demonstrated enough value to justify rollout under the observed conditions. It does not authorize a second round of post-hoc metric hunting until something looks favorable.

    Randomized traffic improves causal confidence, but it cannot rescue a damaged conversion feed or a test that overlaps several campaign edits. Test quality still begins with signal quality and operational discipline.

    Diagnose search, channel, placement, and device problems separately

    Four isolated diagnostic stations represent search, media channels, placements, and devices on an organized dark workbench.

    If creative is not the only credible cause, work down through the remaining delivery layers. Make the smallest change supported by the evidence. A query problem calls for a query control; a risky placement calls for a placement review. Neither automatically justifies rebuilding the campaign.

    Search terms, search themes, and brand traffic

    Start with the campaign-level search term view and compare terms by both traffic and outcomes. Terms with higher-than-average click volume and zero conversions are sensible exclusion candidates. They are not automatic exclusions. Check whether tracking is complete, whether the term is relevant, and whether the evaluation period contains enough activity to support the decision.

    Review brand traffic separately. Performance Max can lean toward high-intent branded searches, which may make aggregate efficiency look stronger without answering how much non-brand demand the campaign is creating. When preventing brand leakage is the actual requirement, explicit negative keywords provide more direct control than simply admiring the blended result. Brand exclusions also exist, but the key is to choose a control that matches the question you are trying to answer.

    Treat search themes as positive targeting input, not as a substitute for term-level diagnosis. Use search theme reporting to see whether a theme receives traffic, where that traffic originates, and whether it converts. An underused theme has not necessarily failed; it may simply have received too little delivery to evaluate. A used theme with meaningful traffic and no business outcome presents a different problem.

    Channels and placements

    The channel performance report helps you locate delivery and performance across networks such as Discover and Display. Use it to identify where the deviation is concentrated. If total campaign efficiency falls while one channel’s delivery or outcomes change sharply, inspect that channel’s inventory and creative fit before changing every asset group.

    For placement-level work, use the API or Report Editor data to identify inventory that is irrelevant or creates brand-safety concerns. Political content and children’s videos on YouTube are examples of placements that may require closer scrutiny for some advertisers. When placement names or video titles are in an unfamiliar language, Google Sheets’ translation function can speed up the relevance review.

    Keep Search Partner Network limitations in view. Performance Max does not provide a simple opt-out for that network. Compare its performance with Google Search where the reporting permits, document the constraint, and focus on exclusions and controls that are actually available. Do not promise an optimization that the campaign settings cannot enforce.

    Devices

    Device reporting can reveal that certain products perform differently across phones, computers, or other devices. Treat that as a prompt to inspect the experience as well as the media. Product presentation, landing-page usability, checkout behavior, and competitive conditions may all sit between the click and the conversion.

    Do not split campaigns by device merely because the report shows a difference. Campaign splits reduce the data available to each campaign and can weaken machine-learning inputs. Consider a split only when the difference is sustained and commercially material, both sides will retain enough volume to evaluate, and the new structure gives you a control you can use. If the split only produces cleaner-looking reports, the cost in fragmented learning may be higher than the benefit.

    Key takeaways: use this Performance Max diagnostic order

    • If a conversion connection needs attention, shows urgent errors, or has failed imports, repair measurement before judging campaign performance.
    • If measurement is healthy, capture a stable baseline and identify whether the deviation belongs to search, a broader channel, placements, devices, or creative.
    • If the question is specifically about creative and the beta is available, use the native asset experiment inside one campaign and asset group.
    • If a creative test has run for less than three weeks, especially with low volume, treat an apparent lead as unstable rather than rushing to declare a winner.
    • If a search term has unusually high click volume and no conversions, review it as an exclusion candidate instead of applying an arbitrary account-wide threshold.
    • If a problem is confined to one delivery layer, change that layer. Avoid campaign-wide restructuring until the evidence shows that the structure itself is the constraint.
    • If a device or campaign split would starve each side of useful data, keep the structure intact and use reporting for diagnosis rather than control for its own sake.

    On your next review, begin with the data connection history and a dated baseline. Then write down one question that the available report or experiment can actually answer. One clean diagnosis gives you a reusable decision; five simultaneous optimizations give you a new mystery.

    References

  • How to Build an Intent-Driven Google Ads Strategy

    How to Build an Intent-Driven Google Ads Strategy

    Your Google Ads account can be neatly organized by match type and still be built around the wrong thing. A searcher does not arrive as an exact-match phrase or a broad-match variant. They arrive with a problem, a level of awareness, and a decision they are trying to make.

    An intent-driven strategy connects that decision to your campaign structure, ad promise, landing page, and measurement. You still use keywords, but you stop asking them to carry the entire strategy.

    Stop treating the keyword as the whole decision

    The practical change is not that keywords have disappeared. It is that Google can increasingly interpret the goal behind a search instead of relying only on a literal query-to-keyword correspondence. Complex questions can be decomposed into related subtopics through query fan-out and intent inference, allowing an apparently informational search to reveal a plausible commercial next step.

    Consider the query Why is my pool green? The wording does not name a product. The underlying job is troubleshooting, however, and products may be part of the solution. A campaign limited to explicit product language can miss that relationship. A campaign that chases every pool-related question without understanding the product’s role can waste money just as easily.

    Intent is the bridge between those two extremes. It explains why the person is searching and where your offer fits. The keyword remains useful as a targeting input, an observation point, and a control. It should not automatically determine the account architecture.

    The reverse problem matters too. Identical words do not guarantee identical intent. Someone searching for best CRM may be learning which features matter, creating a shortlist, replacing an existing system, or preparing to contact a vendor. Google can make contextual distinctions between searches that look alike. Your messaging and destinations need to account for them as well.

    Before assigning a query to a campaign, answer four questions:

    • What problem is the person trying to resolve? Name the situation in the customer’s language, not your internal product category.
    • What decision are they making now? Diagnosing, exploring, comparing, selecting, and returning to buy are different jobs.
    • What role can the offer legitimately play? It might explain the problem, provide a tool, supply a remedy, replace an existing solution, or complete a purchase.
    • What is the smallest appropriate next step? Reading an explanation, comparing options, checking fit, viewing an offer, requesting contact, and purchasing are not interchangeable.

    That four-part description is your intent hypothesis. It is a hypothesis because a query rarely proves intent by itself. You validate it through the search terms that appear, the pages people use, and the business outcomes that follow.

    Build an intent map before changing campaign structure

    A strategist arranges icon clusters for learning, comparison, local action, and purchase around a central searcher symbol on a tabletop.

    Do the first pass outside the Google Ads interface. A worksheet forces you to describe the customer decision before the existing campaign names and match types pull you back into the old structure.

    1. Inventory the language already reaching the account. Collect meaningful search-term themes, current keywords, ads, landing pages, and conversion actions. You are looking for recurring situations, not merely recurring word roots.
    2. Group expressions by the problem they represent. Phrases with different vocabulary can belong together when the user needs the same answer. Similar-looking phrases may need to be separated when they lead to different decisions.
    3. Assign a decision stage. Use a small working vocabulary such as diagnosing, exploring, comparing, selecting, or purchasing. These are planning labels, not official Google categories.
    4. Define the product’s role. State exactly how the offer helps at that stage. If you cannot write this in one sentence, the group is probably too broad or the relationship is too weak.
    5. Choose the promise and destination. Decide what the ad can truthfully promise and which page can fulfill that promise without making the visitor translate it.
    6. Mark ambiguity explicitly. Do not force every query into one supposedly correct intent. Record the plausible alternatives and decide whether they require different messages, pages, or success criteria.

    A useful intent map looks like this:

    Search signal and contextUser’s immediate jobDecision stageOffer’s roleMessage directionBest destination type
    Why is my pool green?Identify the cause and a path to fix itDiagnosingProvide a relevant remedy after the problem is understoodExplain the likely path from diagnosis to treatmentTroubleshooting page with clear routes to relevant products
    Best CRM, with broad research behaviorLearn how to evaluate possible systemsComparingBecome a credible candidate in the shortlistHelp the user compare fit, workflows, and constraintsEvaluation or comparison page
    Best CRM, with clear vendor-selection behaviorChoose a provider and determine the next stepSelectingPresent the solution directlyShow product fit and the available next actionProduct, offer, pricing, or contact page, depending on what actually exists

    The two CRM rows are deliberately similar at the query level. The distinction comes from the decision being made. If both people receive the same generic ad and the same generic page, the account asks one experience to do incompatible jobs.

    For each row in your own map, write a one-sentence intent brief:

    • The user is trying to complete this immediate job.
    • They are currently at this decision stage.
    • Our offer helps by playing this specific role.
    • The appropriate next step is this action.

    If two keyword clusters produce the same brief, they may not need separate structures. If one cluster produces two materially different briefs, a single ad group may be hiding an important distinction.

    Turn the map into campaigns, ads, and landing pages

    An intent map becomes useful only when it changes what the searcher sees. Structure, creative, and destination should tell the same story. If one layer points to a different intent, performance data becomes difficult to interpret because you no longer know which promise the system is learning from.

    Split structures when the customer experience must change

    Do not create a campaign for every subtle variation. Split an intent when the distinction requires a different business decision or customer experience. A separate structure is more defensible when one or more of these elements changes:

    • The problem being solved.
    • The person’s decision stage.
    • The role of the product or service.
    • The promise the ad needs to make.
    • The landing page needed to fulfill that promise.
    • The conversion action or business value used to judge success.
    • The amount of budget exposure you are willing to accept while testing the hypothesis.

    Keep variations together when they are merely different ways of expressing the same job and can honestly use the same ad, page, and success definition. This prevents intent strategy from turning into a new form of over-segmentation.

    Match types can still help you manage boundaries. Use them in service of the intent plan: to protect a proven pattern, explore adjacent language, or limit an uncertain theme. Do not let a match-type label become a substitute for explaining why the traffic deserves the same treatment.

    Write the ad around the goal, not an echoed phrase

    Keyword repetition can make an ad look relevant while leaving the user’s actual question unanswered. Build the message from three layers:

    • Goal: Acknowledge what the person is trying to accomplish.
    • Role: Explain how the offer fits that job, using only claims the destination can support.
    • Next step: Offer an action appropriate to the decision stage.

    For a troubleshooting search, the ad might lead with understanding the cause and finding the relevant treatment path. For an early CRM comparison, it might help the user evaluate fit. For a selection-stage CRM search, it can move directly to product details and the available contact or purchase step.

    The distinction is small in wording but large in function. One message helps the searcher frame a decision. Another helps them complete it. Do not promise a comparison, diagnosis, price, demonstration, or outcome that the landing page does not actually provide.

    Make the landing page finish the same job

    A good ad-to-page transition should not require the visitor to reinterpret your offer. The first meaningful portion of the page should make four things clear:

    • They have reached a page for the problem or decision they had in mind.
    • The page provides the type of help promised in the ad.
    • The connection between that help and the offer is understandable.
    • The next action matches their current level of readiness.

    This is why every informational query should not be sent straight to a product page. When the user is still diagnosing the problem, a focused explanation with a clear route to the relevant solution may create a more coherent journey. Conversely, a person ready to evaluate a specific offer should not be forced through a broad educational page before they can find product details.

    Intent-based organization can affect eligibility, landing-page effectiveness, and system learning. Treat the landing page as part of targeting, not as a destination chosen after the campaign has already been designed.

    Measure whether you captured the right intent

    Colored pathways connect searcher intent symbols to campaign containers, ad cards, landing pages, and evaluation instruments, while one mismatched pathway is diverted.

    A search term that resembles your keyword is not proof that the campaign worked. The real test is whether the account reached a useful customer situation, made an appropriate promise, and produced an outcome worth paying for.

    Create an intent-level scorecard alongside your normal campaign reporting. For each intent, review:

    • Coverage: Which expressions and customer situations are being reached, and which intended situations remain absent?
    • Traffic response: Do the ad and offer earn attention from the people in that intent group?
    • Destination behavior: Do visitors take the next step that the page was designed to support?
    • Business outcome: Do leads, sales, qualified opportunities, or conversion value justify the spend?
    • Query drift: Are new search terms still versions of the intended job, or has the group expanded into unrelated needs?
    • Stage fit: Are you judging a diagnosing visitor by a purchasing action that the experience never prepared them to take?

    Do not turn every early-stage action into an equally valuable optimization goal. A page view, content interaction, qualified lead, and sale may each tell you something, but they do not represent the same business result. Keep the distinction visible so cheap activity does not masquerade as successful intent matching.

    Common performance patterns point to different fixes:

    • Relevant-looking traffic but weak business outcomes: Recheck the intent definition, conversion action, and search-term drift before changing bids. The campaign may be attracting a real audience for the wrong job.
    • Strong ad response but weak landing-page action: Compare the ad promise with the page’s first answer and next step. A stage mismatch often appears at this handoff.
    • Conversions from many different phrasings: Preserve the shared intent before fragmenting the group by vocabulary. The language varies, but the customer job may be stable.
    • Mixed quality from the same apparent query theme: Stop treating the words as a complete label. Revisit the possible decision states and test distinct messages or destinations where the difference is meaningful.
    • Traffic concentrated around only explicit product terms: Look for adjacent problem and comparison intents where the offer has a clear, defensible role. Expansion without that role is merely broader targeting.

    Because Google Ads spend has direct financial consequences, do not dismantle a profitable structure solely to make the account taxonomy look more modern. That can remove your baseline and expose more budget before the new intent hypothesis is proven.

    Use a bounded migration instead:

    1. Select one campaign or problem cluster with a clear customer job and interpretable conversion data.
    2. Record its current structure, search-term themes, spend, outcomes, and landing pages as your baseline.
    3. Write the new intent brief and identify exactly what is changing: grouping, message, destination, or some combination of them.
    4. Keep the underlying definition of business success stable while testing the new structure. If you change both the campaign logic and the conversion definition, you will not know which change produced the result.
    5. Protect proven coverage while the new approach is evaluated. Do not assume broader eligibility is automatically better.
    6. Judge the test on business quality and intent fit, not only on added traffic.
    7. Expand the model to adjacent clusters only after the original intent remains coherent from query through outcome.

    This approach gives you a way to learn without turning an account-wide rebuild into a single irreversible bet.

    Key takeaways

    • Treat keywords as evidence and controls, not as complete descriptions of the customer.
    • Define each important intent through the user’s problem, decision stage, product role, and appropriate next step.
    • Group different phrasings when they require the same message, page, and success measure.
    • Separate similar-looking searches when they represent materially different decisions.
    • Write ads around the goal behind the query, then send the visitor to a page that completes the same job.
    • Evaluate intent groups by downstream business quality, not by query resemblance or traffic volume alone.
    • Migrate a bounded part of the account first, preserve your baseline, and expand only when the new structure proves useful.

    For your next account review, choose one campaign and try to describe its audience without mentioning a keyword or match type. If you cannot state the problem, decision stage, product role, and next step clearly, that is where the intent-driven rebuild should begin.

    References

  • Harnessing First-Party Data for AI-Enhanced Ad Success

    Harnessing First-Party Data for AI-Enhanced Ad Success

    I recently discovered how crucial first-party data has become in the evolving landscape of AI-powered advertising. It’s fascinating to see how it shapes the optimization and measurement of automated ad campaigns.

    During a chat with Search Engine Land, I learned from Julie Warneke, CEO of Found Search Marketing, about the profound impact first-party data has on profitable advertising, regardless of potential changes to Google’s third-party cookie policies.

    Embracing first-party data means tapping into customer information that I own, typically stored in a CRM, like lead details, purchase history, revenue, and customer value collected from various touchpoints.

    This type of data is distinct from platform-owned or browser-based data, over which I have limited control.

    Digital advertising has evolved over the years. The shift from focusing on impressions and clicks to outcomes emphasizes profitable conversions, according to Warneke. Advertisers who provide AI systems with quality customer data gain a significant edge.

    Although rising cost-per-clicks (CPCs) are inevitable in paid media, first-party data enhances conversion quality, revenue, and return on ad spend, making higher costs justifiable with better results.

    By leveraging first-party data tied to revenue and customer value, AI bidding systems can target users resembling high-value customers, even beyond usual demographic or geographic signals, leading to better conversions.

    Among campaign types, Performance Max (PMax) thrives with first-party data activation. It performs best when I shift from manual optimizations to feeding it accurate data, allowing the system to learn, as Warneke highlighted.

    Even small and mid-sized businesses can leverage first-party data, as seen in Warneke’s examples of success with small customer lists. The challenge lies in setting up proper infrastructure for tracking, consent management, and data flow.

    Common mistakes include weak data capture, where brands rely on browser-side tracking that falters on platforms like iOS, and broken feedback loops from sporadic CRM data uploads. Continuous data streams are crucial.

    Warneke advises taking a step back to audit how data is captured, stored, and relayed to platforms. Incremental improvements can pave the way for significant long-term gains, even starting with a small portion of a budget as a test.

    Ultimately, AI optimization reflects the quality of signals received. By refining first-party data, I can influence outcomes favorably, avoiding inefficiency risks.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google Ads Automation: Build Signals That Improve Performance

    If Google Ads is meeting its reported target while revenue quality gets worse, the bid strategy may be doing exactly what you asked. The account is simply teaching automation that the wrong event is success.

    Your real control now sits upstream of the auction. It is in the conversions, values, audience data, creative, landing pages, budgets and campaign boundaries you define. Align those inputs and automation can find valuable demand. Let them conflict and it will scale the conflict.

    Start by separating goals, context, constraints and diagnostics

    Automation cannot infer your commercial intent from a campaign name or a note in your media plan. Each eligible search can produce a different auction-time decision based on many available signals, but those signals still need a clear definition of success.

    The word signal is often used too loosely. Some account elements teach the system which outcomes are valuable. Others supply context, impose constraints or diagnose a problem. They all influence performance, but they do not carry equal weight.

    PriorityInputWhat it communicatesCommon failure
    CriticalPurchases, qualified opportunities, offline sales and conversion valuesWhat the business considers a successful outcomeA page view, form start or unqualified lead receives the same status as revenue
    HighCustomer Match lists, first-party customer data and custom audience segmentsWhat a valuable customer tends to look likeLists are stale, mixed across customer types or dominated by low-value records
    ContextualKeywords, search intent, products and audience patternsWhat demand the campaign should interpret and exploreBrand and non-brand demand, or high- and low-intent traffic, are blended together
    SupportingCreative and landing pagesWhich promise is likely to fit a person and satisfy the clickThe ad attracts one expectation and the page delivers another
    ConstrainingBid strategy, budget and campaign structureHow aggressively to pursue the objective and where trade-offs are allowedOne target is applied to products or leads with incompatible economics
    DiagnosticQuality Score, ad strength and optimization scoreWhere setup or experience may need attentionA platform score is treated as the business objective

    This hierarchy gives you a practical order of operations. If cost per lead looks healthy but the sales team rejects most leads, changing the target CPA is not the first fix. The outcome signal is broken. If revenue tracking is sound but one ad group is paying too much for relevant traffic, then message quality deserves attention.

    Key takeaways

    • Optimize toward the deepest business outcome you can track reliably, not the easiest event to collect.
    • Keep useful funnel events available for reporting, but do not make them primary bidding goals when they have little commercial value.
    • Use Quality Score to find message and landing-page problems; do not use it as a substitute for profit, revenue or qualified pipeline.
    • Earn broad automation such as Performance Max with verified tracking, known acquisition economics and proven demand.
    • Detect drift by comparing the outcomes Google Ads credits with the orders, opportunities or sales your business accepts.

    Build the conversion signal before adjusting the bid strategy

    Conversion data has the strongest influence because it answers the system’s most important question: what should I find more of? A bidding algorithm cannot distinguish a profitable customer from a worthless submission unless your measurement setup makes that distinction visible.

    Run a conversion-action inventory before changing targets, budgets or campaign types:

    1. List every action included in bidding. Do not stop at the conversions shown in a campaign summary. Identify which account-level and campaign-specific goals are marked as primary.
    2. Classify each action by business depth. Separate revenue outcomes, qualified milestones and behavioral diagnostics. A purchase or imported offline sale belongs in a different class from a product-page view, download or form start.
    3. Verify how each action fires. Check that one real outcome does not produce duplicate conversions, that test or spam submissions are excluded where possible, and that ecommerce transactions carry the intended value.
    4. Reconcile the advertising record with business records. Match purchases to the order system. For lead generation, compare credited leads with the qualified opportunities and sales recorded in the CRM.
    5. Assign roles deliberately. Use the deepest reliably measured commercial outcome as the primary optimization goal. Retain helpful early-stage events as secondary observations when you still need them for funnel analysis.
    6. Document the replacement before removing a goal. Changing a primary conversion can redirect real spend. Confirm that the replacement is recording correctly, preserve the old configuration for comparison and monitor the campaigns affected by the edit.

    For ecommerce, purchase value helps the system distinguish a small order from a large one. If products have materially different economics, value-based bidding and campaign separation can communicate that difference more clearly than a single conversion count.

    For B2B campaigns, a raw lead is often only an intermediate event. Offline conversions and value-based signals can move optimization closer to qualified pipeline and profit. If closed sales cannot yet be imported consistently, use the deepest stable qualification milestone you can verify. Do not label a sporadically reported outcome as the sole source of truth.

    Enhanced conversions and first-party data matter for the same reason. They strengthen the connection between an ad interaction and a business outcome when other identifiers are incomplete. Customer Match lists can also give automation a better model audience, provided the records represent customers you actually want more of rather than everyone who ever entered the database.

    Structure campaigns so strong signals do not cancel each other

    A clean conversion setup can still be weakened by a campaign that asks automation to solve incompatible problems at once. Separate traffic when the business objective or economics genuinely differ:

    • Brand and non-brand demand: branded searches often reflect existing awareness, while non-brand searches ask the campaign to create or capture new demand. Blending them can hide where incremental growth is coming from.
    • High- and low-intent traffic: a specific product or service query should not necessarily compete under the same assumptions as broad exploratory demand.
    • Products with different return requirements: a high-margin product and a low-margin product may require different value targets, budgets or campaign boundaries.
    • New and proven inventory: exploratory products need room to gather evidence without consuming the budget assigned to established performers.

    Do not split campaigns merely to make the account look orderly. Fragmentation is useful only when it clarifies a goal, an economic constraint or an intent pattern. If two segments have the same objective and treatment, another campaign boundary may create administration without creating information.

    Creative and landing pages should then reinforce the same interpretation. A useful test is to read the search intent, ad promise and landing-page headline as one continuous sentence. If the sentence changes meaning halfway through, the system is receiving mixed context and the visitor is receiving a broken promise.

    Use Quality Score to diagnose mismatch, not define success

    Quality Score, ad strength and optimization score answer different questions. Quality Score is a keyword-level diagnostic built from expected click-through rate, ad relevance and landing-page experience. Ad strength checks whether a responsive ad follows creative best practices. Optimization score reflects platform recommendations. None of them tells you whether a customer was profitable.

    Add these four columns to the Keywords report: Quality Score, Expected CTR, Ad Relevance and Landing Page Experience. Then review patterns at the ad-group level. One weak keyword may be noise. A cluster of weak component ratings usually points to a shared message or page problem.

    As a practical triage rule, ad groups where most keywords score 7 or higher generally do not need an urgent Quality Score project. When the cluster is around 5 or below, inspect the three components rather than trying to force the headline number upward.

    • Below-average ad relevance: tighten the relationship between the query theme and the ad. Use the customer’s language in the copy and make the offer explicit. Dynamic Keyword Insertion can help when every eligible keyword produces an accurate, grammatical promise; it cannot repair an incoherent ad group.
    • Below-average landing-page experience: confirm that the page fulfils the ad’s promise, works on mobile and has understandable navigation. PageSpeed Insights can help identify performance problems, but speed alone will not fix a page that answers the wrong intent.
    • Below-average expected CTR: inspect Auction Insights and the Google Ads Transparency Center to understand the competitive message around the query. Improve the relevance and specificity of your claim rather than manufacturing curiosity that attracts the wrong click.

    Do not chase a 10 out of 10 across the account. A highly relevant ad can still bring unprofitable customers, and a higher click-through rate can increase waste if the conversion goal rewards low-quality activity. Fix Quality Score when it reveals friction between intent, ad and page. Fix conversion signals when the account is finding the wrong kind of success.

    This distinction also prevents expensive reactions. Raising a budget does not cure a relevance problem. Rewriting an ad does not cure duplicate purchases. Lowering a target CPA does not teach the system which leads the sales team accepts. Choose the control that acts on the layer where the failure began.

    Earn Performance Max with verified data and known economics

    Performance Max can expand reach and allocate budget across Google’s inventory, but that breadth reduces the clarity available to an advertiser who is still discovering the basics. Starting with broad automation before conversion tracking is trustworthy can spread a bad assumption across more channels.

    Use a launch gate. Performance Max is a more defensible choice when you can answer yes to these questions:

    • Does the primary conversion represent a purchase, qualified opportunity or another outcome the business accepts?
    • Can you reconcile credited conversions and values with the order system or CRM?
    • Do you know which products, offers or lead types have produced commercially acceptable results?
    • Have you decided how brand demand should be handled, rather than allowing it to obscure incremental performance?
    • Do the product feed, creative and landing page describe the same offer accurately?
    • Can you compare the automated campaign with a controlled baseline or protected group of proven activity?

    If several answers are no, do not use Performance Max to discover whether measurement works. In one documented retail example, a chocolatier spent $3,000 for one purchase while incorrect conversion tracking distorted the setup. Moving back to a more controlled Shopping structure made it possible to learn from actual product behavior instead of an unreliable automated signal.

    For a new retail account, Standard Shopping can provide a clearer baseline for product demand and acquisition cost. Once products and outcomes are validated, a hybrid structure can preserve that controlled activity while Performance Max tests broader reach. This is not an argument against automation. It is a sequence: establish truth, prove economics and then grant the system more freedom.

    Treat platform recommendations as proposals, not instructions. Before accepting one, write down which signal or constraint it changes, what business outcome should improve and what would justify reversing it. Optimization score may rise when you adopt a recommendation, but your margin, cash flow and lead quality remain the deciding evidence.

    Budget deserves the same discipline. A higher budget gives the system permission to enter or explore more auctions. It does not make conversion tracking more accurate, repair a mismatched landing page or turn an unqualified lead into revenue.

    Catch signal drift before reported efficiency hides the damage

    Signal drift occurs when campaign behavior gradually moves away from the business outcome you intended. The dashboard may still look efficient because the system has found an easier path to the measured goal. Your job is to notice when easier stops meaning better.

    Watch for mismatches that a top-line CPA or ROAS can conceal:

    • Reported leads rise while qualified opportunities or sales remain flat.
    • Conversion volume improves because a soft action started receiving primary credit.
    • Spend shifts toward branded demand even though the campaign is expected to acquire new customers.
    • Revenue rises while the product mix moves toward lower-margin inventory.
    • An expanded creative message increases clicks but weakens the connection between the query and landing page.
    • Audience lists or product feeds change without anyone checking how the new records alter the model.

    Use a decision-based audit rather than scrolling through every available metric:

    1. Reconcile outcomes. Compare the conversions receiving bidding credit with orders, qualified opportunities and offline sales. Find out whether the advertising metric and business result moved together.
    2. Locate the distribution shift. Break performance apart by brand versus non-brand intent, product or offer, campaign and conversion action. Look for the segment that absorbed spend or conversion credit.
    3. Find the changed input. Review edits to primary goals, conversion values, customer lists, feeds, creative, landing pages, budgets, bid targets and campaign structure.
    4. Correct the highest-priority failure first. Repair the outcome definition before the audience pattern, the audience pattern before message details, and message details before using budget as the answer.
    5. Change one major signal family at a time. If you replace the conversion goal, restructure campaigns and rewrite every ad simultaneously, you will not know which correction restored performance.
    6. Record the decision and reversal condition. State what you expect to change in the business result, not merely which platform metric should move.

    Do not preserve polluted learning simply because a campaign has been running for a long time. Stability is useful only when the system is learning from the right outcome. At the same time, avoid rebuilding healthy campaigns when a single conversion action or landing page explains the drift. Make the smallest correction that restores a coherent signal.

    Open your account and inventory the conversion actions before touching another bid target. For every primary goal, finish this sentence: the business benefits when this event happens because it produces or predicts ____. If the answer is vague, that is where your automation work starts.

    References

  • How to Target Google Ads and See Where PMax Performs

    How to Target Google Ads and See Where PMax Performs

    Your Search campaigns can be well built and still leave growth on the table. Keywords meet people after they express intent; they do not automatically reach every suitable buyer who has not started searching. If you answer that gap by handing more work to Performance Max, you inherit a second problem: knowing which Google channel produced the result.

    You can solve both problems without pretending automation is transparent. Define targeting as a two-part decision – where relevant intent appears and who qualifies – then use Google Ads API v23 channel reporting to inspect how Performance Max distributed and converted traffic. That gives you a practical operating loop: targeting hypothesis, channel evidence, focused correction, and cost-per-acquisition review.

    Separate where an ad can appear from who should see it

    A targeting plan becomes much easier to audit when you stop treating every setting as interchangeable. Google Ads targeting falls into two functional groups: content targeting and audience targeting.

    DecisionContent targetingAudience targeting
    Question it answersIn what query or content environment can the ad appear?What kind of person should be eligible to see the ad?
    Main optionsKeywords, topics and placementsGoogle data, your data, custom segments and automated targeting
    Best useCapturing a relevant moment or contextImproving the fit between the person, message and offer
    Common mistakeAssuming a relevant query always identifies the right buyerAssuming a plausible audience is ready for the same offer at the same time

    Keyword targeting reaches people through searches and also extends into dynamic ad groups and Performance Max. Topic targeting places ads alongside content about a selected subject in display and video campaigns. Placement targeting lets you choose particular websites, apps, YouTube channels or videos.

    Audience targeting works on a different axis. Google’s prebuilt options include detailed demographics, affinity segments, in-market segments and life events. Your own data can include website visitors, app users, people who engaged with your Google content and eligible Customer Match data. Custom segments can be based on relevant searches, interests, websites or apps. Automated options can expand from the signals and data you provide, although their names and exact behavior vary by campaign type.

    The distinction matters because a keyword can reveal intent without identifying the buyer. Someone searching for vacation packages could be planning a family trip, honeymoon or retirement holiday. The query is the same, but the useful message, proof and offer can be completely different. Treat the keyword as evidence of a moment, not as a complete persona.

    Build the targeting stack before automation expands it

    An isometric targeting system shows layers for intent, context, audience qualification, and controlled automated expansion.

    Before changing campaign settings, write down the answers to two separate questions: How can Google Ads promote this offer, and how can Google Ads reach this particular audience? If you can answer only the first, you have a distribution plan without an audience strategy. If you can answer only the second, you have a persona without a reliable way to reach it.

    1. Define the action that creates business value. Name the conversion you actually want, the offer attached to it and the page where it happens. This prevents cheap but irrelevant traffic from becoming the campaign’s de facto objective.
    2. Describe audience fit independently of search behavior. State who has the problem, what makes the offer relevant and what language that person would immediately recognize. Do this before selecting a Google segment.
    3. Choose the content signals that reveal a useful moment. Use keywords for expressed search intent, topics for subject context and placements when you know the specific sites, apps, channels or videos where the audience spends attention.
    4. Add the audience data you can legitimately use. Consider Google’s segments, eligible first-party data and custom segments. Treat automated expansion as another layer of reach, not as a substitute for defining the audience yourself.
    5. Make the creative perform a targeting job. Use the buyer’s vocabulary, problem, context and expected outcome. A broad audience paired with precise creative can filter attention more effectively than generic creative placed in a narrowly named segment.
    6. Set the success hierarchy before launch. Put conversions and cost per acquisition ahead of click volume and cost per click. Otherwise, an apparent traffic improvement can move the campaign away from qualified demand.

    For example, lead-generation software intended for Google Ads professionals could use custom segments informed by searches for terms such as Performance Max, visits to relevant industry sites or use of the Google Ads app. Content targeting could add placements on industry education channels and topics around search marketing. The creative should then speak in the terminology of campaign management rather than generic business-software language.

    This is a coordinated stack, not necessarily an instruction to combine every setting as a restrictive intersection. Campaign types interpret signals differently. Your planning document should show what each input contributes: context, identity, prior relationship, expansion or creative qualification.

    When remarketing or custom segments are restricted

    Some sensitive-interest campaigns, including certain legal or healthcare advertising, may not be eligible for custom segments or remarketing. When those options are unavailable, do not treat the restriction as a technical obstacle to work around. Start with an eligible Google data audience that has plausible overlap, then let the creative filter for relevance.

    Industry terminology, recognizable acronyms and specialist visuals can make the intended audience pay attention while other people move on. That approach is especially useful when you can target a broad eligible group but cannot encode the sensitive trait directly. Confirm which options are available in the account and campaign you are actually running before finalizing the plan.

    Use API v23 to turn PMax delivery into channel evidence

    An analyst observes one automated advertising stream separated into visible paths for search, video, shopping, web, and map channels.

    Older Google Ads API versions returned MIXED for the Performance Max ad_network_type segment. API v23 can instead break results out across Search, YouTube, Display, Discover, Gmail, Maps and Search Partners. That changes Performance Max reporting from a single blended row into a view of where delivery occurred.

    The visibility is available at three useful levels:

    • Campaign level: See the overall channel mix and identify which channels deserve a closer look.
    • Asset group level: Determine whether a channel pattern belongs to the whole campaign or is concentrated in one audience-and-creative grouping. This channel breakdown is available through the API, not the Google Ads interface.
    • Individual asset level: Connect channel delivery to particular creative assets instead of judging every asset against one blended campaign result.

    There are three implementation constraints you should record in the reporting specification. Channel-specific data is available only for dates beginning June 1, 2025. A blank result before that date means the breakdown is unavailable, not that the channel delivered nothing. Asset-group channel reporting must come from the API, so a UI-only review will not reproduce the same analysis. Any pipeline that expects the old MIXED value must also be updated to accept and store the distinct channel enums.

    Your export should retain the campaign, asset group and asset identifiers alongside the date, channel, cost, clicks, conversions and whichever business-value metric governs the account. Keep the v22 segments ad_using_video and ad_using_product_data in the analysis where relevant. They let you distinguish video-supported delivery from product-data-supported delivery rather than assuming that every result inside a channel used the same ad format.

    This is reporting visibility, not proof that each channel should receive a manual budget or that the channel caused the conversion by itself. Use the channel enum to locate a pattern. Then use the asset group, asset type, audience hypothesis and conversion outcome to explain what may be producing it.

    Turn channel visibility into a focused optimization decision

    A channel report is useful only when it changes the next decision. Start at campaign level, narrow the pattern to an asset group or asset, and then change the smallest controllable input that could explain it.

    1. Validate the conversion basis. Make sure the report is evaluating the action the campaign is meant to produce. A channel comparison built on the wrong conversion cannot guide useful optimization.
    2. Read conversion rate and cost per acquisition before CPC. High click costs can be acceptable when those clicks convert efficiently. Low click costs are not a win when they buy unqualified visits.
    3. Compare channels at campaign level. Look for meaningful differences in delivery, conversion rate and acquisition cost. Do not label the largest channel good or bad solely because it received the most traffic.
    4. Drill into asset groups. If the pattern appears across every asset group, investigate campaign-wide assumptions such as the offer, audience definition or landing experience. If it appears in one asset group, keep the correction confined to that group.
    5. Inspect the relevant assets and format flags. For YouTube delivery, use the video segment and asset results to inspect whether the video communicates the offer clearly. For Search delivery involving product data, separate that traffic from other Search behavior before deciding what needs to change.
    6. Correct the closest mismatch. If clicks arrive but conversions do not, examine the continuity between targeting, creative promise, offer and landing page. If one asset performs poorly only within one channel, revise that asset before rebuilding the entire campaign.
    7. Recheck a comparable reporting window. Keep the conversion definition and analysis scope consistent so the next result answers whether the focused change improved acquisition quality.

    The metric order has a large financial consequence. In an illustrative comparison, a $10 click with a 10% conversion rate implies a $100 cost per acquisition. A $1 click with a 0.02% conversion rate implies a $5,000 cost per acquisition. The cheaper click is fifty times more expensive at the outcome that matters. This is why low-quality traffic is a more serious problem than a high CPC.

    Channel visibility also limits the blast radius of your changes. If weak YouTube results are concentrated in one asset group and one video, you have a creative diagnosis, not yet a reason to rewrite the entire campaign. If inefficient traffic appears across channels and asset groups, the shared offer, conversion setup or audience premise deserves attention first.

    Key takeaways

    • Ask two targeting questions: where relevant intent appears and which people fit the offer.
    • Use keywords, topics and placements for context; use Google data, your data, custom segments and automation for audience reach.
    • Make creative specific enough to qualify attention, especially when sensitive-interest restrictions limit audience options.
    • Google Ads API v23 reports Performance Max delivery across Search, YouTube, Display, Discover, Gmail, Maps and Search Partners for dates beginning June 1, 2025.
    • Use the API for asset-group channel reporting; that breakdown is not available in the Google Ads interface.
    • Treat channel data as a diagnostic dimension and judge outcomes by conversion quality and cost per acquisition, not cheap clicks alone.

    Start with the Performance Max campaign carrying the most financial consequence. Write its targeting hypothesis in one sentence, then export v23 channel data at campaign, asset-group and asset level. If your reporting cannot preserve those levels, fix the reporting path before changing the campaign. Once the pattern is visible, correct the narrowest mismatch you can support with conversion evidence.

    References

  • How to Build a Paid Media Operating Structure That Scales

    How to Build a Paid Media Operating Structure That Scales

    You can have capable campaign managers, active ads and polished dashboards while paid media quietly loses its ability to drive growth. The warning sign is not always a dramatic drop. It is often a long stretch in which spend and activity continue, but pipeline stops moving.

    Adding another specialist or changing agencies will not resolve that plateau if ownership, measurement and experimentation remain unclear. You need an operating structure that turns business outcomes into campaign decisions, gives execution teams useful feedback and exposes the strategy to regular challenge.

    Replace the org-chart question with an ownership model

    The familiar choice between an internal team and an agency hides the more consequential question: who owns performance direction, and how often is that direction challenged?

    Campaign execution is only one part of the job. A durable paid media operation separates four accountabilities, even when a small team combines several of them in the same role:

    • Business outcome ownership: Someone with authority defines what paid media must contribute to pipeline or revenue, which customer segments matter and what economics the business can accept.
    • Performance direction: A named leader translates those goals into channel roles, budget priorities, measurement requirements and a testing roadmap.
    • Campaign execution: Channel operators build, monitor and adjust campaigns while documenting what changed and why.
    • Independent challenge: A qualified person outside the daily workflow questions assumptions, identifies structural weaknesses and brings perspective from other accounts, markets or growth stages.

    These are accountabilities, not a headcount plan. One person may cover more than one role. The important constraint is that performance direction cannot belong vaguely to the marketing department, an agency or a committee. A single owner must be able to make or escalate the decision.

    Test your current structure by asking the performance owner to answer the following questions without assembling an emergency meeting:

    1. What business result is paid media expected to change?
    2. What is preventing the account from producing more of that result now?
    3. Which decision is currently being tested?
    4. What evidence would cause us to maintain, change or stop the current approach?
    5. Who has authority to act when that evidence arrives?

    If the answers come back as platform metrics, disconnected tasks or conflicting opinions, the problem is not simply campaign optimization. The operating model has no clear path from business intent to action.

    Make measurement a feedback loop, not a reporting layer

    Three marketing specialists observe and adjust a circular workstation linked by an illuminated feedback path.

    A dashboard can describe activity without helping anyone improve it. Paid media needs a feedback loop that carries business outcomes back to the people and systems making campaign decisions.

    Build that loop in layers. Leadership needs pipeline and revenue evidence. The performance leader needs measures that show whether the channel is creating qualified demand at acceptable economics. Campaign platforms need conversion signals that are frequent, accurate and meaningfully related to the business outcome.

    Those layers should connect, but they should not be treated as interchangeable. A form submission can help a bidding system react quickly, for example, while still being too early to prove pipeline quality. Conversely, a closed sale may be commercially decisive but arrive too late or too infrequently to guide every campaign adjustment. Your structure must state which signal serves which decision.

    Create a measurement map for every conversion event used in reporting or optimization. Record:

    • The customer action being captured.
    • The business stage that action is meant to represent.
    • The system in which the event originates.
    • The campaign, click or audience data that travels with it.
    • The CRM status or downstream result that confirms quality.
    • The destination receiving the signal, including any advertising platform using it for optimization.
    • The person responsible for detecting and repairing a broken data path.
    • The budget or campaign decision the metric is allowed to influence.

    This exercise exposes a common structural failure: the marketing platform records a conversion, but the CRM cannot reliably connect that action to a qualified opportunity or revenue outcome. The campaign team then receives a weak signal, leadership receives a partial story and both groups optimize different versions of performance.

    Do not hide that gap by adding more charts. Mark the affected metric as incomplete, identify the missing connection and limit the decisions it can support until the data path is repaired. Otherwise, greater automation can amplify the wrong behavior because the system is being rewarded for the easiest visible action rather than the outcome the business values.

    Your leadership view should therefore show more than spend and lead volume. At minimum, it should make the following visible together:

    • Spend against the authorized budget.
    • Qualified pipeline and revenue under the organization’s agreed attribution approach.
    • Movement between the lead, qualification, opportunity and customer stages the business actually uses.
    • Known tracking gaps, data delays and attribution limitations.
    • Material campaign or measurement changes that affect interpretation.
    • The next decision, its owner and the evidence still required.

    The goal is not to claim perfect attribution. It is to make uncertainty explicit enough that the team can still decide responsibly.

    Protect testing capacity and turn reviews into decisions

    Campaign prototypes sit in separate testing lanes while a team selects an option at a nearby decision table.

    Maintenance work expands to fill the team’s available capacity. Search terms need review, creative needs refreshing, budgets need pacing and stakeholders need answers. If experimentation is treated as whatever happens after those tasks, the account may remain orderly while its growth logic goes untested.

    Separate routine optimization from experimentation. Routine optimization applies established operating rules, corrects defects or restores an expected standard. An experiment addresses a meaningful uncertainty and produces evidence for a future decision. Renaming ordinary account changes as tests does not create a learning program.

    Every proposed experiment should have a short brief containing:

    • Constraint: The business or funnel problem limiting performance.
    • Hypothesis: The reason a specific change may relieve that constraint.
    • Change: The variable being altered, with unrelated variables kept as stable as practical.
    • Decision metric: The result that determines whether the idea should influence future investment.
    • Guardrails: The outcomes that must not deteriorate while the primary metric improves.
    • Evidence requirement: The conditions needed before the team interprets the result.
    • Decision: The actions available when the evidence is favorable, unfavorable or inconclusive.
    • Owner: The person responsible for execution, interpretation and documentation.

    Start the backlog with the current business constraint, not with a platform feature the team wants to try. If qualified pipeline is weak, determine whether the likely constraint is audience fit, message, offer, conversion path, sales follow-up, measurement or something else. That diagnosis tells you what deserves testing. It also prevents the team from changing targeting, creative, bidding and landing pages at once, then being unable to explain the result.

    Many well-designed experiments will not produce an improvement worth scaling. That is not a reason to avoid testing. It is a reason to demand a useful decision from each test. An unfavorable result can still eliminate a bad assumption, narrow the next question or prevent a larger budget mistake.

    Performance reviews should use the same discipline. Replace the dashboard tour with a decision sequence:

    1. State which business outcome changed or failed to change.
    2. Identify the funnel and campaign signals that help explain it.
    3. Separate confirmed evidence from plausible interpretation.
    4. Name the current constraint and the decision it creates.
    5. Assign the action, evidence requirement and next review point.

    Match the review cadence to the feedback available. Execution signals may support frequent checks, while qualified pipeline or revenue may require a longer observation window. Do not demand final proof faster than the buying process can produce it. But do not use a long sales cycle as an excuse to ignore leading indicators, tracking health or obvious execution problems.

    End each review with a decision log. The outcome might be to continue, stop, scale, narrow, repair measurement or gather more evidence. If the meeting produces only observations and follow-up analysis, performance ownership is still unresolved.

    Use external expertise without splitting strategy from execution

    An external partner can provide pattern recognition, technical scrutiny and a challenge to assumptions that have become normal inside the business. That advantage disappears when the partner is asked to improve campaigns in isolation or when internal and external teams operate from different definitions of success.

    A hybrid structure works when each side retains the decisions it is equipped to make.

    The internal team should retain ownership of:

    • Business goals, commercial constraints and budget authority.
    • Customer, product, market and sales-process context.
    • The organization’s definitions of a qualified lead, opportunity and acceptable customer.
    • Access to CRM outcomes and the teams responsible for acting on demand.
    • Final decisions about risk, investment and strategic priorities.

    An external performance leader or specialist can be accountable for:

    • An independent assessment of account, measurement and integration structure.
    • Challenging whether platform recommendations serve the business objective.
    • Bringing relevant patterns from other accounts and growth stages without assuming those patterns automatically apply.
    • Turning observed constraints into a disciplined testing roadmap.
    • Explaining tradeoffs and structural risks in language leadership can use.
    • Reviewing whether campaign execution still reflects the agreed strategy.

    The performance owner sits across that boundary. This person does not forward agency reports to leadership or pass leadership requests to channel operators. They reconcile business context, external challenge and campaign evidence into a decision.

    Watch for signs that the hybrid model has become a handoff chain:

    • The partner reports platform conversions while the internal team separately reports pipeline.
    • Campaign operators receive tasks but cannot explain the commercial priority behind them.
    • The internal team withholds CRM or sales context, then judges the partner on revenue.
    • Strategy appears in presentations but does not change budgets, account structure or the testing backlog.
    • No one has authority to resolve conflicting interpretations of performance.
    • The partner’s work is never subjected to an informed internal or independent review.

    External support is most useful before confidence collapses. Bring it in when measurement is being designed, a new channel is being prepared, a plateau is emerging or a larger budget decision requires independent scrutiny. Waiting until leadership has already decided the channel does not work leaves less room to repair the structure and gather credible evidence.

    Key takeaways

    • Paid media needs a named performance owner with authority to connect business goals, measurement, budget and campaign decisions.
    • Business outcomes, decision metrics and platform optimization signals serve different purposes; map how they connect before relying on them.
    • Protect experimentation from routine campaign maintenance, and require every test to answer a consequential question.
    • Run performance reviews around constraints and decisions rather than collections of metrics.
    • Use external expertise to challenge strategy and structure while keeping business context and commercial authority inside the organization.

    At your next paid media review, make one structural change before asking for another campaign tactic. Name the performance owner, choose the most important measurement gap or growth constraint, and record the decision the team must make next. That creates a working feedback loop. Once it exists, better execution has somewhere useful to go.

    References

  • Third-Party Endorsements in Google Search Ads: What to Do

    Third-Party Endorsements in Google Search Ads: What to Do

    If you buy Google Search ads, the immediate question is whether you can get a publisher quote into your own ad. For now, there is no disclosed setup path, eligibility rule, or request process. Rebuilding a campaign around this feature would be premature.

    You can still prepare intelligently. The useful work is to organize the independent evidence behind your brand, decide how you would measure an endorsement if one appeared, and avoid confusing an experimental ad treatment with an advertiser-controlled asset.

    What the endorsement test actually changes

    The experimental format places a short statement from an external publisher directly beneath the advertiser’s description. The treatment can include the publisher’s name, logo, and favicon, visually separating the statement from the copy supplied by the advertiser.

    One observed ad displayed the line “Best for Frequent Travelers” and attributed it to PCMag. That example matters because it shows the kind of claim involved: a concise editorial judgment about whom a product suits, rather than a generic customer rating or another promotional sentence written by the advertiser.

    This distinction changes how you should evaluate the feature. Your headline and description present your own proposition. A recognizable external endorsement could add a different kind of evidence at the moment someone is deciding which result deserves a click. It may make the ad resemble an editorial recommendation more closely, but that possible effect has not yet been established through disclosed performance data.

    Google has confirmed only that it is running a “small experiment” involving third-party endorsement content. Several operational questions remain unanswered:

    • Which advertisers, products, queries, or publishers are eligible.
    • Whether an advertiser can opt in or opt out.
    • Whether an advertiser can request, select, approve, or reject an endorsement.
    • How Google finds the content and decides which statement to display.
    • How old, changed, disputed, or removed publisher content would be handled.
    • Whether the experiment is connected to review-extension concepts, publisher partnerships, or broader trust-and-safety systems.

    Until those questions are answered, treat the endorsement as a possible search-result treatment, not as a new asset type you can add to a campaign. There is no documented basis for changing bids, budgets, campaign structure, or creative solely to obtain it.

    Prepare your brand without trying to game the experiment

    Hands organize blank press materials, a neutral medallion, and research documents beside a separate tray of generic ad cards.

    You cannot configure an undisclosed feature, but you can make your external reputation easier to understand and manage. Start with an endorsement inventory. A simple worksheet should contain the publisher, URL, covered brand or product, exact wording, publication date, current status, and the person responsible for checking it.

    1. Record exact claims, not flattering paraphrases. “Best for frequent travelers” is materially different from “best travel product.” Preserve the original wording and context internally so your team does not turn a narrow judgment into a broader claim.
    2. Classify the evidence correctly. Keep editorial endorsements separate from customer reviews, testimonials, awards, certifications, affiliate roundups, and paid placements. They may all support trust, but they are not interchangeable.
    3. Check the product and audience match. An endorsement for one plan, model, or use case should not be treated as validation for an entire company. Map each statement to the exact landing page and offer it describes.
    4. Make brand and product names consistent. If a product has several informal names across your site, campaign, and public coverage, document which names refer to the same thing. Clear naming helps your own team avoid attaching the wrong evidence to an ad or landing page.
    5. Create a correction route. Assign an owner who can contact a publisher when a factual detail is outdated or inaccurate. You may not be able to control what Google displays, but you can keep the underlying public information accurate.

    Do not copy publisher quotations or logos into your creative merely because Google displayed them in an experiment. A platform-generated treatment does not automatically give an advertiser permission to reuse editorial language or branding elsewhere. Keep the inventory as an evidence and monitoring tool unless your organization has the appropriate permission for direct reuse.

    It is also too early to commission coverage for the purpose of triggering this format. You do not know whether Google considers a particular publisher, whether paid or affiliate relationships affect selection, or whether advertisers will ever receive controls. Earn credible coverage because the coverage itself helps buyers evaluate you, not because you expect it to become an ad decoration.

    Measure an appearance without inventing causality

    A magnifying lens examines a blank search-ad card surrounded by separate contextual layers, while a broken link separates the observation from an outcome token.

    If an endorsement appears beneath one of your ads, a screenshot proves that the treatment rendered. It does not prove that the treatment improved performance. Queries, competitors, auction conditions, audience mix, devices, and campaign changes can all affect the same metrics.

    1. Capture the context. Save the screenshot along with the query, date, time, country, device type, displayed endorsement, publisher, ad copy, and destination URL.
    2. Annotate your reporting. Record when the first appearance was observed and note any simultaneous changes to bids, budgets, targeting, creative, landing pages, offers, or conversion tracking.
    3. Look for repeated exposure. Do not make a budget decision after one observation. Establish whether the treatment appears repeatedly and whether its wording stays consistent.
    4. Use business metrics in sequence. Examine click-through rate first, then conversion rate and the cost or return metric your campaign actually uses. A higher click-through rate with lower post-click quality is not automatically an improvement.
    5. Use the closest valid comparison. Compare similar queries, ads, audiences, and periods where possible. If Google does not provide an exposure field or experiment control, label any apparent difference as directional rather than causal.

    Avoid rewriting your description to imitate the endorsement. Repetition can waste limited ad space, and a line that looks independent loses its meaning when the advertiser makes the same claim about itself. Your copy should explain the offer; the external statement, if shown, should remain clearly external.

    Keep paid search, SEO, AEO, GEO, and schema in their proper lanes

    Third-party validation can support a broader visibility strategy, but this experiment does not establish a technical connection between Search ads and organic or AI-generated results. The selection process and its relationship to other Google systems remain undisclosed.

    • For paid search: the observed endorsement is an experimental element displayed with an ad. It is not currently a documented advertiser asset.
    • For SEO: there is no disclosed evidence that appearing in this treatment changes organic rankings.
    • For AEO and GEO: independent coverage can give people and answer systems public material with which to understand a brand, but this ad experiment does not prove that the same selection mechanism powers AI answers or citations.
    • For structured data: there is no disclosed evidence that JSON-LD or another schema type triggers the endorsement.

    Your safest cross-channel strategy is therefore straightforward: keep product facts precise, use consistent entity names, maintain the pages that substantiate your claims, and organize legitimate independent coverage. Those actions make your brand easier to verify even if this particular ad format never expands.

    Use a simple decision rule. If an activity makes your public evidence clearer, more accurate, or more useful to a prospective buyer, it is worth considering on its own merits. If its only purpose is to trigger an undocumented ad feature, defer it until Google publishes eligibility rules and advertiser controls.

    Key takeaways

    • Google is testing publisher quotations, names, logos, and favicons beneath some Search ad descriptions.
    • The confirmed example is part of a small experiment, not a generally available ad feature.
    • No public setup path, eligibility rule, opt-in mechanism, selection method, or performance reporting has been disclosed.
    • An endorsement inventory can help you manage external claims without assuming that you can submit them to Google.
    • If the treatment appears, document the exposure and assess the entire path from click to conversion before changing spend.
    • Do not treat SEO, AEO, GEO, or schema work as a shortcut into the experiment without evidence of a connection.

    Build the inventory now, add a place for endorsement observations to your campaign log, and leave campaign economics unchanged until repeated data or official controls give you something reliable to act on.

    References