Author: shivamcrushpressai

  • How to Build Trust With Data in AI and SEO Decisions

    How to Build Trust With Data in AI and SEO Decisions

    Your dashboard can be technically correct and still fail the meeting. If nobody can explain who is represented, how the number was produced, or whether automated and fraudulent activity was removed, the chart asks people to take your conclusions on faith.

    Trust comes from making the evidence inspectable. You should be able to move from a recommendation to its claim, from the claim to its metric, from the metric to the underlying records, and from those records back to their origin. Assumptions, exclusions, and uncertainty need to remain visible throughout that chain.

    Trust starts with a claim your data can support

    A precise-looking number is not automatically a trustworthy number. Decimal places, clean schemas, polished charts, and large record counts can make data appear authoritative without proving that it represents the right people, activities, or period.

    This distinction matters when AI enters the workflow. An AI system can process weak data efficiently, but it cannot independently establish that an identity is genuine or an event is meaningful. In practice, AI can amplify fragmented, outdated, or manipulated inputs and return the result with more confidence than the evidence deserves.

    Before you analyze a dataset, make its intended claim explicit. Then test the claim against six questions:

    • Entity: Who or what does each record represent? Determine whether identifiers refer to the same person, account, page, organization, query, or session across the systems involved.
    • Activity: What actually happened? Separate a recorded event from an authentic action with business or user value.
    • Time: When was the record true, collected, and refreshed? A valid historical snapshot should not be treated as a current state.
    • Origin: Which system created the record, and which system merely copied or transformed it? Name the accountable owner.
    • Exclusions: Which records were filtered out, suppressed, deduplicated, or classified as suspicious? Record the rule and its reason.
    • Decision fit: Does the dataset measure the decision in front of you, or only a convenient proxy for it?

    If you cannot answer one of those questions, narrow the claim. For example, do not report that AI visibility improved everywhere when you measured only a defined set of prompts and answer environments. State that limited scope in the claim itself. A smaller claim that can be verified is more useful than a sweeping conclusion that cannot survive inspection.

    Clean structure is still valuable, but it solves a different problem. A record can have the expected fields, valid syntax, and consistent formatting while referring to the wrong identity or a fabricated activity. Structural validity tells you that the data can be processed. It does not prove that the data is accurate.

    Create an evidence card for every decision-bearing claim
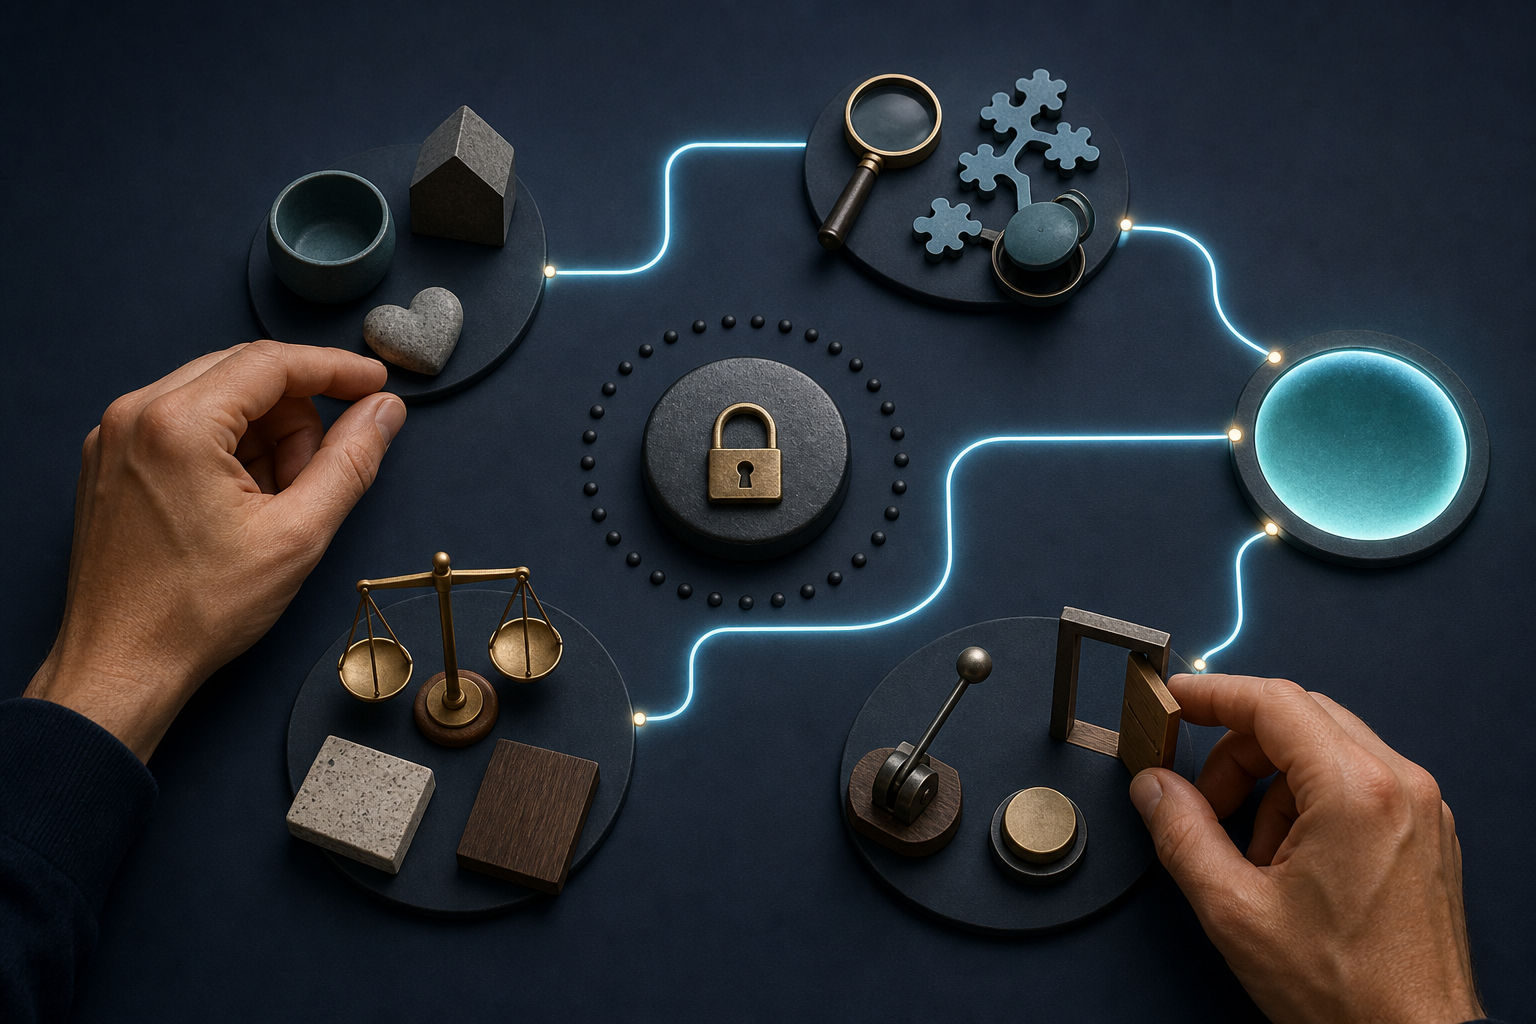
    Hands arrange transparent evidence tiles linked to a central token, with one tile lifted to reveal the granular pieces beneath it.

    A dashboard rarely carries enough context on its own. Filters live in one tool, transformations in another, and caveats in somebody’s memory. When the result is challenged, the team has to reconstruct the reasoning after the fact.

    Use a compact evidence card for each claim that could change a budget, campaign, content plan, model, or workflow. Store it beside the analysis rather than in private notes.

    1. Decision: Write the choice this evidence is meant to inform. If no decision changes, question whether the metric belongs in the report.
    2. Claim: State one sentence that the data directly supports. Avoid combining an observation, an explanation, and a recommendation in the same sentence.
    3. Scope: Name the entity, population, channel, property, prompt set, and time window included. Record the denominator where the metric has one.
    4. Definition: Define the metric in operational terms. Specify what creates an event, what qualifies it, and how duplicates are handled.
    5. Lineage: List the originating system, collection method, joins, transformations, filters, and derived fields used to produce the result.
    6. Quality gates: Document the checks applied to identity, authenticity, freshness, completeness, and consistency.
    7. Limitations: Separate known gaps from suspected gaps. Explain how each one could change the conclusion rather than hiding them under a generic disclaimer.
    8. Action and owner: Name the proposed action, the person responsible, the signal that will be monitored, and the condition that would trigger reconsideration.

    The evidence card also protects metric definitions from drifting. If one reporting period counts all detected visits and another excludes suspected automation, the results are not directly comparable. The definition and filter change must travel with the number.

    Keep rejected records and reason codes available for review when your systems permit it. Silently removing questionable data makes a clean result harder to audit. A visible exclusion such as duplicate identity, stale record, suspected automated activity, or missing attribution shows exactly where judgment entered the pipeline.

    Audit AI and SEO inputs before you automate decisions

    AI readiness is often assessed through volume, match rates, or the apparent precision of model output. None of those signals proves that the underlying identities are stable or that the recorded behavior is authentic. Consumers move between devices and profiles, while systems often treat a temporary identity snapshot as permanent. Fraud and low-value activity can then distort both model output and the performance data used to retrain or evaluate it.

    Run an input audit at each layer of an AI SEO or analytics workflow. The purpose is not to certify data as perfect. It is to prevent the claim from becoming broader than the evidence.

    LayerQuestion to verifyMisleading conclusion to prevent
    Observed AI visibilityWhich prompts, answer environments, properties, locations, settings, and collection windows were monitored?A sampled result presented as universal visibility.
    On-site activityAre sessions and events authentic, consistently defined, and separated from suspected automated or fraudulent activity?Machine activity presented as audience demand.
    Identity and attributionCan records be matched to the intended person, account, organization, or journey without treating uncertain matches as confirmed?Inflated reach, duplicated users, or credit assigned to the wrong interaction.
    Business outcomeDoes the conversion represent a reachable, meaningful outcome rather than a form event or low-value identity?Nominal conversions presented as genuine pipeline or customer value.
    Model inputAre the records current, relevant, authentic, and appropriate for the task the model will perform?Confident automation built on an unreliable foundation.

    Treat identity validity and activity authenticity as gates, not decorative quality scores. If either one cannot be established, the affected data may still support exploration, but it should not silently drive targeting, outreach, optimization, or other automated actions.

    Use sensitivity checks when uncertainty is concentrated in a recognizable subset. Compare the conclusion with and without low-confidence identities, suspected automation, stale records, or unmatched events. If removing that subset reverses the recommendation, the recommendation is fragile. Report that dependence before anyone acts on it.

    Watch for feedback loops as well. If fraudulent or low-value behavior improves a reported metric, an optimization system may learn to seek more of it. The apparent performance improvement then reinforces the very contamination that produced it. Suppress or quarantine questionable inputs before they become training signals, targeting criteria, or success labels.

    Separate observation, interpretation, and recommendation
    Three connected workbench stations show raw data pieces, a lens revealing patterns, and several possible paths around a decision marker.

    Many data presentations lose trust because they slide from measurement to causation without marking the transition. A result occurred after a change, so the change is credited with causing it. A visibility metric rose, so business impact is implied. A model found a pattern, so the pattern is treated as a stable rule.

    Use four explicit labels in reports, dashboards, and decision memos:

    • Observed: What the collection method directly recorded within its stated scope.
    • Calculated: What was produced through a documented formula, join, classification, or transformation.
    • Inferred: What the evidence may explain or predict, including plausible alternatives.
    • Unknown: What the current design cannot establish.

    A careful AI visibility statement might say that a page appeared more frequently in the monitored answer set during the review window. That is the observation. Content or structural changes may be plausible contributors, but prompt sampling, model behavior, competitor changes, and measurement differences remain alternative explanations unless the evaluation design rules them out. The recommendation can still be to retain or extend the change, provided the team continues testing the explanation.

    This language is not weakness. It tells the decision-maker which parts are facts, which parts are judgment, and which parts require another measurement cycle. Use causal words such as caused, produced, or drove only when the evaluation was designed to support causality. Otherwise, use language such as coincided with, is consistent with, or may have contributed.

    Do not turn uncertainty into an arbitrary confidence percentage. If confidence has not been calibrated, a precise score creates another unsupported claim. Name the evidence that raises confidence, the gap that lowers it, and the observation that would change your position.

    Use a three-act narrative without turning evidence into theater

    People need more than a pile of verified metrics. They need to understand why the evidence matters and what should happen next. A setup, confrontation, and resolution structure can organize that reasoning while keeping the decision-maker at the center of it.

    1. Setup – establish the baseline and objective. State the decision, the prior strategy, the relevant success criteria, and the conditions in which the data was collected. Show what was working as well as what was not.
    2. Confrontation – expose the obstacle and competing explanations. Present the gap between the objective and the observed state. Include identity problems, suspicious activity, measurement changes, missing coverage, and other facts that could challenge the easy interpretation.
    3. Resolution – connect action to evidence. Recommend the next move, explain which claim supports it, and define the guardrails. State what will be measured next and what result would cause the team to revise the plan.

    The narrative should organize evidence, not rescue it. Do not remove an inconvenient metric because it interrupts the story. Do not portray a forecast as the ending. The resolution is a justified next action with a way to learn, not a guaranteed outcome.

    At the presentation level, use one decision-bearing claim per chart or report block. Put the scope in the title or immediately below it. Display the comparison window, unit, denominator, filters, and relevant definition change close to the result. Place a material limitation beside the claim it limits, where it can affect the decision, rather than collecting caveats at the end.

    Finish each claim with an action, an owner, and a revisit condition. That turns the presentation from a performance into a shared operating record. It also gives future analysis a clean baseline: the team can see what it believed, why it believed it, what it decided, and which evidence later confirmed or challenged that decision.

    Key takeaways

    • Make every claim no broader than the identities, activities, channels, and time window you can verify.
    • Do not confuse structured or complete-looking records with accurate identities and authentic behavior.
    • Give each decision-bearing claim an evidence card containing its scope, definition, lineage, quality checks, limitations, action, and owner.
    • Audit data before it enters an AI workflow because automation can scale unreliable inputs and reinforce contaminated feedback loops.
    • Label observations, calculations, inferences, and unknowns so readers can see where evidence ends and judgment begins.
    • Present the decision as a setup, a confrontation with the real constraints, and a resolution tied to a measurable next action.

    Before your next dashboard review or model run, choose the one claim most likely to change a decision and complete its evidence card. If you cannot identify the entity, activity, window, origin, exclusions, and limitation, narrow the claim before you polish the presentation. Then give the decision-maker a clear next action and a defined reason to revisit it.

    References


  • Google Ads Security and Conversion Infrastructure Runbook

    Google Ads Security and Conversion Infrastructure Runbook

    Your Google Ads stack can fail in two opposite ways: access becomes too loose to trust, or security controls become so brittle that the people and automations responsible for measurement are locked out. Meanwhile, a conversion tag can deploy cleanly and still measure the wrong action.

    The practical goal is not merely to enable multi-factor authentication or create a Google Tag Manager tag. You need a traceable path from an authorized identity to a tested conversion event, with an owner and a recovery route at every handoff. This runbook shows you how to build that path without turning an access change or tagging shortcut into a campaign outage.

    Key takeaways

    • MFA enforcement matters most when someone creates a new OAuth 2.0 refresh token. An integration that works now can still fail during reconnection, onboarding, or credential replacement.
    • Service accounts remain the better fit for supported automated or offline workflows, but they still need explicit ownership, limited access, and a tested handoff process.
    • A pre-filled Google Tag Manager configuration can remove transcription work. It cannot decide whether you selected the right container, conversion action, trigger, or counting logic.
    • Never revoke a working credential or remove a working conversion tag until its replacement has passed a controlled test. Otherwise, your rollback path disappears at the moment you need it.
    • Security and measurement should share one release record: identity owner, authentication method, Ads account, conversion action, GTM container, test evidence, publisher, and rollback decision.

    Map authentication before MFA exposes a hidden dependency

    A cutaway security system shows human, automated, and recovery access routes converging on one gateway, with one route blocked and a backup route remaining open.

    Google’s announced rollout made MFA mandatory for new user-based Google Ads API authentication from April 21, with enforcement expanding over the following weeks. The important boundary is token creation: OAuth 2.0 refresh tokens that were already in use were not invalidated by the change, but fresh authentication requires the additional identity check.

    That boundary explains why an account can look healthy until a routine maintenance task causes a failure. A scheduled process may continue using its existing refresh token, while a new employee, replacement integration, revoked credential, or reconnection attempt reaches the MFA gate. Passing today’s automated run is therefore not proof that your recovery workflow is ready.

    Start with an authentication inventory. Do not begin by changing credentials. For every connection that can read from or act on a Google Ads account, record:

    • Workflow: the API job, reporting transfer, desktop tool, script, dashboard, or application that depends on access.
    • Authentication pattern: user-based OAuth or a service account.
    • Named owner: the person responsible for approving access, completing MFA, and handling recovery.
    • Operational owner: the person who can prove the workflow still runs correctly after an authentication change.
    • Credential event: what would force a new authorization flow, such as onboarding a user, replacing a connection, or rebuilding an integration.
    • Recovery route: who can restore access if the primary owner is unavailable, without sharing a personal password or MFA prompt.
    • Evidence: the last successful controlled authentication and the workflow result it enabled.

    For user authentication, make the MFA rehearsal realistic. Use the same consent and token-generation path that the production workflow expects. Confirm that the designated person can complete the second factor, which may be a phone prompt or an authenticator app. Then verify that the resulting credential reaches the intended account and supports the intended workflow. A successful Google sign-in alone is not enough.

    Choose user authentication or a service account deliberately

    Keep user-based OAuth when the workflow is genuinely tied to a person’s authorization and an interactive sign-in is acceptable. Use a service account for a supported automated or offline workload when the connection should survive staff changes and should not depend on a person responding to an MFA prompt. Google left service-account workflows outside the new MFA requirement and recommends them for automated or offline scenarios.

    Do not migrate to a service account merely to avoid MFA. A service account is a machine identity, not an exemption from governance. Confirm that the application supports it, grant only the access the workflow needs, document who owns that identity, and test what happens when its permissions or connection must be replaced.

    Expand the inventory beyond custom API code. The same security change reaches authentication used by Google Ads Editor, Scripts, BigQuery Data Transfer, and Data Studio. If those tools are owned by different teams, give one person responsibility for the complete dependency map. Otherwise, each team may believe another team owns the failing sign-in.

    Most importantly, do not revoke the working refresh token while you are only testing its replacement. Prove the new path first, record the result, and then retire the old credential through a reviewed change. Revoking first can stop reporting or automation without leaving you a quick way back.

    Use direct GTM setup to remove copying, not judgment

    Google Ads has tested a Set up in Google Tag Manager option inside the conversion setup flow. Where the option is available, you can select a GTM container and open a suggested, pre-filled tag configuration instead of manually carrying the conversion ID and label between products.

    Treat this as a safer handoff, not an automatic implementation. It reduces opportunities for transcription errors, but it does not know whether your chosen website action represents a qualified lead, a completed sale, an internal test, or an accidental page view. It also cannot resolve a poor container naming convention or decide whether an existing tag will overlap with the new one.

    The integration is described as a test, so do not make a launch deadline depend on the button appearing in your account. If it is absent, continue with the established manual setup and apply the same review process. Availability and implementation correctness are separate questions.

    1. Confirm the conversion definition. Write down the user action that should count, where it occurs, and what must not count. Do this before opening GTM.
    2. Match the account and container. Verify the Google Ads account, conversion action, website, GTM account, and container as one set. Similar client or environment names are not proof of a match.
    3. Inspect the pre-filled values. Check the conversion ID and label against the intended conversion action even when Google populated them. Automation should reduce copying, not eliminate review.
    4. Review the trigger separately. The tag configuration identifies where data should go; the trigger determines when it goes there. Confirm that the trigger represents the business event you defined in the first step.
    5. Check for an existing implementation. Search the container for tags and triggers that already send the same action. Publishing a second path may produce duplicate events or conflicting behavior.
    6. Test before publishing. Use GTM’s preview process and complete a controlled conversion path. Confirm that the tag fires on the intended action and remains silent on nearby actions that should not count.
    7. Publish a traceable version. Record the conversion action, reason for the change, reviewer, test performed, and rollback instruction in the version description or release record.
    8. Verify both ends. Confirm the expected firing behavior in GTM and then confirm that Google Ads recognizes the intended conversion setup. A passing browser-side test proves the trigger ran; it does not by itself prove that the account mapping is correct.

    Avoid deleting the old tag before the new configuration has been verified. At the same time, do not publish two equivalent live paths and hope to compare them later. Modify the existing implementation when that is the cleanest route, or make the old and new triggers mutually controlled during the release. Your rollback should restore a known configuration, not create a second unknown one.

    Operate access and tagging as one controlled release

    Two specialists approve access and inspect a digital event as it passes through secure testing, monitored release, and rollback stages.

    Authentication and conversion tracking are often assigned to different specialists, but they meet at the same operational boundary. The person publishing a tag needs reliable account access. The automation consuming conversion data needs a stable identity. The campaign owner needs confidence that the event still means what its name claims.

    Use one release record for both sides. In a larger team, assign an access owner, GTM implementer, independent reviewer, and business owner for the conversion definition. In a smaller team, one person may hold several roles, but the checkpoints should remain separate. Pause between configuring, reviewing, publishing, and validating so that familiarity does not replace evidence.

    1. Freeze unrelated changes. Keep other credential, container, and conversion-action edits out of the same release so a failure has a narrow set of possible causes.
    2. Capture the known-good state. Record which automation currently succeeds, which tag and trigger currently fire, and which conversion action they serve.
    3. Prove recovery access. Confirm that the named owner can complete a fresh user-authentication flow with MFA, or that the supported service-account workflow can be restored by its documented owner.
    4. Stage the measurement change. Build or review the pre-filled GTM configuration without publishing it. Confirm the account, action, ID, label, trigger, and duplication check.
    5. Run the controlled path. Exercise the actual conversion behavior and preserve enough evidence for another person to understand what was tested.
    6. Publish and validate. Confirm the container version, the live firing conditions, the Google Ads destination, and the next successful dependent automation run.
    7. Retire only what has been replaced. Revoke an old credential or remove an old tag only after the new path is proven and the rollback decision is documented.

    Use the failure layer to choose your first check

    When something breaks, identify whether the failure occurs at identity, authorization, container configuration, trigger logic, publishing, or destination mapping. Rolling back everything at once can hide the actual defect.

    SymptomLikely layerFirst check
    An existing API job runs, but a new connection cannot generate a refresh tokenUser authentication and MFARepeat the fresh consent flow with the named owner and confirm that the second factor can be completed.
    A connection succeeds for one person but cannot be recovered by the teamOwnership and recoveryCheck whether the workflow depends on one personal identity and whether a supported service-account pattern is more appropriate.
    Editor, Scripts, a transfer, or a dashboard fails during sign-inShared authentication policyIdentify the actual Google identity behind the tool instead of treating it as an isolated application error.
    The direct GTM option does not appearFeature availabilityUse the manual tag setup rather than delaying the release; the integration is being tested and may not be available in every flow.
    The tag does not fire during previewContainer or trigger logicConfirm the selected container, preview environment, trigger conditions, and exact user action.
    The tag fires, but it points to the wrong conversion actionDestination mappingCompare the conversion ID and label with the intended Google Ads action and account.
    More than one tag fires for a single intended actionDuplicate implementationSearch for older tags, overlapping triggers, and parallel containers before changing the conversion definition.
    The browser-side test passes, but the dependent automation failsAPI authorization or workflow logicTest the automation separately with its own identity and permissions; the GTM test does not validate API access.

    At your next planned change window, exercise one fresh authentication flow and trace one controlled conversion from the user action through GTM to the intended Google Ads action. If either path lacks a named owner, test evidence, or a safe rollback, fix that gap before you scale the campaign or add another integration. Your infrastructure is ready when another authorized person can understand it, test it, and recover it without guessing.

    References


  • How to Turn AI Referral Traffic Into Bottom-Funnel Growth

    How to Turn AI Referral Traffic Into Bottom-Funnel Growth

    You may already see the awkward pattern: informational clicks are falling, AI assistants send a thin stream of referrals, and some conversions appear later under direct or branded search. If you judge that pattern with an organic traffic dashboard alone, the strategy can look weaker precisely when it is starting to influence revenue.

    Your job is not to replace every lost pageview. It is to publish the decision-stage answers that buyers and AI systems need, connect those answers to the rest of your site, and measure the journey beyond the first visible click.

    AI referrals are decision-assistance traffic, not replacement pageviews

    An informational search traditionally sent a person to several pages to assemble an answer. An AI interface can now do much of that assembly before the person visits a website. The resulting click is therefore more likely to represent validation, comparison, or purchase research than initial discovery.

    That changes the value of a session. A page that attracts thousands of definition-seeking visitors can produce less commercial movement than a comparison page attracting a much smaller group of people who are choosing between viable options.

    There is evidence that this difference can show up in conversion behavior, but it should not be turned into a universal benchmark. In an Adobe analysis covering more than one trillion visits to U.S. retail websites, AI-referred visits in March converted 42% better than non-AI visits. They also spent 48% more time on site and viewed 13% more pages per visit. A year earlier, AI visits in the same analysis had been 38% less likely to convert.

    Those figures describe U.S. retail traffic, not every market, business model, or AI platform. A retail purchase is not a B2B demo request, and a known brand is not in the same position as an unfamiliar one. Use the finding to form a hypothesis: AI referrals may be lower in volume but further along in the decision process. Then test that hypothesis against your own landing pages, conversions, lead quality, and sales outcomes.

    Key takeaways

    • Judge AI referrals by buying intent and conversion quality, not by whether they replace lost informational traffic.
    • For a pipeline-focused program, consider assigning 60% to 80% of new content effort to mid- and bottom-funnel needs, then adjust from your results.
    • Build comparison content with a disclosed method, consistent criteria, specific limitations, and recommendations for distinct buyer situations.
    • Keep top-funnel content, but give each useful page a clear route into a relevant evaluation or product decision.
    • Measure visible AI referrals alongside citations, branded search, direct visits, qualified leads, and total conversions.

    Rebalance content around the questions that delay a purchase

    A buyer stands among several symbolic decision stations as their branching research paths merge into one clear route toward a product pedestal.

    The strategic shift is not simply from educational articles to product pages. A product page explains what you sell. Bottom-funnel content helps a buyer decide whether it is the right choice, how it compares, where it fits, and what tradeoffs they would accept.

    Start with the questions that appear after a buyer understands the category:

    • Which options are suitable for my industry, company size, use case, or operating constraint?
    • How do two shortlisted products differ on the criteria that matter to me?
    • What are the strengths and limitations of each option?
    • Which product is the better fit for a specific situation?
    • What evidence would let me remove this option from my shortlist?
    • What should I verify before requesting a demo, starting a trial, or making a purchase?

    These are decision tasks, not just keywords. That distinction matters because buyers can express the same task through conventional search, a conversational AI prompt, a follow-up question, or a branded query after seeing a recommendation elsewhere.

    Audit your coverage by task. List your priority products, use cases, buyer groups, and serious alternatives. Then mark whether you have a useful answer for each relevant combination. Typical gaps include:

    • A broad category list with no version for a high-value industry or use case.
    • A product comparison that names features but never explains who should choose which option.
    • An alternatives page that treats every alternative as interchangeable.
    • A use-case page that makes claims without screenshots, expert explanation, or product evidence.
    • An educational page that attracts the right audience but offers no logical next step.

    Prioritize gaps where three conditions overlap: the question occurs close to a purchase, your product has a legitimate reason to be considered, and you can support the answer with specific evidence. A high-intent phrase is not useful if the resulting page would be evasive, generic, or unsupported.

    For teams measured on leads or revenue, a practical starting point is to put 60% to 80% of content effort into mid- and bottom-funnel work. Treat that as a portfolio choice to test, not a law. The right allocation depends on how complete your educational foundation is, how many decision-stage gaps remain, and whether your business has credible evidence for the pages it wants to publish.

    Build comparison pages that remain useful after the click

    A weak comparison page is an advertisement wearing an editorial title. It places the publisher’s product first, assigns vague praise to every option, hides meaningful drawbacks, and ends with an unrelated sales button. Buyers notice the bias. An AI system also has little precise material to reuse because the page never makes a bounded, supportable recommendation.

    A stronger page defines its scope, applies one review method to every option, and makes the tradeoffs visible. A construction-specific time-tracking comparison built this way became a frequently referenced page in LLM responses within weeks and outperformed a dozen earlier informational pages in pipeline impact. That is one documented outcome, not a promise that every listicle will perform the same way. The transferable lesson is the structure: answer a real purchasing question with enough specificity to guide a decision.

    A practical comparison-page blueprint

    1. Define the buyer and decision. State the industry, use case, operating constraint, and type of purchase covered. “Best time-tracking software” is broad; “best time-tracking software for construction” establishes a meaningful evaluation context.
    2. Publish the selection method. Explain how options qualified for inclusion and which criteria were applied. If you cannot explain why a product appears, the list will feel arbitrary.
    3. Give the short answer early. Identify which option fits which situation. Do not force a ready-to-buy reader through a long category lesson before providing the decision map.
    4. Use one comparison framework. Evaluate every option against the same relevant fields. Suitable columns might include best-fit use case, important strengths, material limitations, and the factor a buyer should verify.
    5. Separate fact from judgement. Product capabilities should be factual and current. Recommendations should show the reasoning that connects those facts to a buyer’s situation.
    6. Cover limitations directly. A useful limitation tells the reader who may be poorly served and why. Empty phrases such as “may not suit everyone” add no decision value.
    7. Recommend by situation. End with conditional guidance rather than a single universal winner. Different constraints can produce different correct choices.
    8. Place the next step in context. Put a demo, trial, pricing, or product link beside the point where it becomes useful. Do not rely on one generic call to action at the bottom.

    Credibility rules for including your own product

    You can include your own product when it genuinely meets the selection method. Disclose the relationship plainly, subject it to the same criteria, and resist the urge to make it the winner for every buyer. If an alternative is better for a particular situation, say so.

    Use screenshots, named features, and expert explanations where they help a buyer verify a claim. Keep each product section structurally consistent. A reader should not receive detailed drawbacks for competitors and only promotional language for your product.

    Write recommendations as complete, bounded statements. “Option A is the better fit for teams that need [capability], while Option B is more suitable when [different constraint] matters” is more useful than “Option A is best overall.” The bounded version exposes the reasoning, gives the buyer a usable distinction, and is less likely to be quoted outside its intended context.

    Update the page when the underlying facts change. A polished comparison built on stale capabilities is still unreliable. Record the last substantive review date, recheck each option using the published method, and remove claims you can no longer support.

    Give top-funnel content a direct route to the decision

    Top-funnel content still has an important job. It can establish the concepts a buyer needs, complete a topic cluster, attract relevant links, and pass internal link equity toward decision-stage pages. What has changed is the economics of publishing generic explanations that an AI result can answer without a click.

    Do not delete useful educational pages merely because their traffic has softened. Start with the pages that still reach the right audience and give each one a deliberate handoff:

    1. Identify the next decision. After reading the page, what question would a qualified buyer naturally ask? That question should determine the destination link.
    2. Add evidence where the subject touches your product. A relevant screenshot, implementation detail, or expert observation can turn an abstract explanation into practical understanding.
    3. Link to the closest evaluation page. Send the reader to a use-case comparison, alternatives page, product capability, or selection checklist rather than an unrelated homepage.
    4. Write a contextual call to action. Explain why the destination is useful at that moment. “Compare the options for construction teams” carries more meaning than “Learn more.”
    5. Place the handoff where the need appears. A relevant next step can sit beside the section that creates it. It does not have to wait until the final paragraph.
    6. Preserve the informational answer. The page should still solve the question that earned the visit. Turning every paragraph into a pitch will weaken trust and usefulness.

    This creates a simple content path: education establishes the problem, mid-funnel material frames the available approaches, and bottom-funnel material supports the choice. Internal links should reflect that progression in both directions. The comparison page can link back to definitions or methods a reader needs, while educational pages can point forward when the reader is ready.

    Specificity is the filter. If a top-funnel page merely repeats a general answer already available everywhere, adding a product button will not rescue it. Give the page a distinct expert perspective, a concrete example, a useful framework, or original product evidence before asking it to support a commercial journey.

    Measure the influence that last-click analytics misses

    A glowing thread connects an AI referral to several visits and a final purchase, while a narrow lens highlights only the last step and a wider lens reveals the full journey.

    An AI-assisted journey can cross several channels. A buyer sees your brand or page in an AI answer, does not click, returns through a branded search, and converts. Another buyer clicks an AI citation, leaves, and later returns directly. Standard acquisition reports may credit those outcomes to organic brand traffic or direct traffic even though AI visibility helped create the demand.

    Start by isolating the AI referrals you can see. In GA4, create a segment or channel definition that matches the AI referral domains actually present in your data. A regular-expression rule is useful because it can group multiple sources, but maintain the domain list instead of treating it as permanent. Validate the rule against raw source values so an overly broad match does not pull unrelated referrals into the channel.

    Break that segment down by landing page and intent. Mixing an educational visit with a product-comparison visit hides the question you need answered. Compare like with like: AI-referred visits to bottom-funnel pages against other visits to those same pages, using the same conversion definition.

    Your scorecard should combine directly observed traffic with directional indicators of influence:

    SignalWhat it can tell youHow to act on it
    AI referral sessions by landing pageWhich pages receive visible visits from AI platformsProtect, update, and expand pages attracting relevant evaluators
    Conversion rate by landing-page intentWhether decision-stage visits produce more commercial action than informational visitsAllocate effort according to qualified outcomes, not aggregate sessions
    Engagement and product-page progressionWhether visitors continue evaluating after arrivalImprove the page’s decision support or contextual handoff where progression stalls
    LLM citation frequency for a stable prompt setWhether your brand or page appears in relevant answers, even without a clickReview the cited passages and close factual or use-case gaps
    Branded search and direct-traffic trendsWhether discovery may be resurfacing through channels that obscure the first touchTreat the movement as directional evidence and examine it beside publication activity
    Qualified leads, purchases, and pipelineWhether the program contributes to business outcomesFavor pages and topics that produce valuable customers rather than raw volume

    None of the directional signals proves causation on its own. Direct traffic can move for many reasons, and a branded search increase can reflect activity outside content. Use publication and update dates as annotations, compare several signals together, and avoid assigning all subsequent growth to one page.

    Lead capture can close part of the gap. Preserve the original landing page and referral source where available, then pair them with a simple self-reported discovery field. A buyer who says an AI assistant introduced the brand gives you information that a last-click field may have lost. Keep self-reported and system-attributed sources separate so one does not overwrite the other.

    Report the channel in business language. Instead of stopping at “AI referrals increased,” show which decision-stage pages received those visits, how the visitors behaved, how many qualified conversions followed, and whether brand discovery moved in the same period. Stable or lower total traffic can still support a healthier strategy if conversion quality and pipeline improve.

    Your next move is small and concrete: choose one purchase-stage question that repeatedly blocks a decision. Build the most complete, candid answer you can support. Connect your strongest relevant educational pages to it, establish the measurement baseline, and watch referrals, citations, branded discovery, and qualified conversions together. Once that loop produces a useful signal, repeat it for the next decision your buyers need help making.

    References


  • AI-Era Advertising: How to Prove and Scale Real Growth

    AI-Era Advertising: How to Prove and Scale Real Growth

    Your dashboard says advertising is working. ROAS is up, automated campaigns are claiming conversions, and conversational AI is opening new inventory. But the decision in front of you is harder: which spending actually created revenue that would not have happened otherwise?

    You can answer that question without waiting for perfect attribution. Separate platform-reported performance from incremental lift, measure the return on the next dollar rather than the average dollar, and treat new AI placements as controlled learning investments. That gives you a practical basis for scaling, holding, or cutting spend.

    A high ROAS can still describe demand capture

    Platform ROAS answers a narrow question: how much revenue did the platform attribute to ads relative to their cost? It does not tell you how many of those purchases required the ads.

    That distinction becomes important when automated systems can concentrate spending around branded searches, repeat visitors, existing customers, and people already close to buying. The platform may be accurately recording its involvement while claiming revenue that would have arrived through direct, organic, or another channel. The number is useful for optimizing activity inside the platform, but it is not causal proof of growth.

    Before you increase a campaign budget, ask three separate questions:

    • Did the platform influence conversions? Platform attribution, CPA, and ROAS can help answer this.
    • Did advertising cause additional conversions? A controlled incrementality test is needed to estimate this.
    • Will the next block of spending remain profitable? Marginal return and contribution economics answer this better than average ROAS.

    Use the right calculation for each decision

    • Attributed ROAS equals platform-attributed revenue divided by ad spend. Use it to compare campaigns under the same attribution rules and improve execution within a platform.
    • Incremental revenue is the difference between the outcome for an exposed group and the estimated outcome for a comparable unexposed group, after accounting for relevant baseline differences.
    • Incremental ROAS equals incremental revenue divided by the advertising cost required to produce that lift. Use it to decide whether the campaign adds enough business value to keep funding.
    • Marginal ROAS equals the change in incremental revenue divided by the change in spend. Use it to decide whether an additional budget block is worth buying.

    The average and marginal numbers can point in opposite directions. A campaign that produces $50,000 from its first $10,000 has a 500% average ROAS. If another $5,000 produces only $5,000 more revenue, the combined average still looks respectable at roughly 366%, but the marginal ROAS on the added spend is only 100%.

    Do not call that final dollar break-even merely because one dollar of spend returned one dollar of revenue. Product costs, fulfillment, payment fees, returns, sales commissions, and other variable costs can make a 100% revenue ROAS unprofitable. Convert incremental revenue into incremental contribution before approving more budget. If margins differ by product or customer segment, calculate contribution at that level instead of applying one blended percentage to everything.

    Build a measurement ladder instead of one master metric

    Two analysts inspect a five-level staircase containing signal lights, matched customer groups, test vessels, and a prism illuminating a new group.

    No single metric can optimize campaigns, prove causality, and allocate the next dollar. A measurement ladder gives each metric a specific job and prevents a familiar dashboard number from being stretched beyond what it can establish.

    DecisionPrimary evidenceWhat that evidence cannot prove alone
    Which bid, audience, or creative should run?Platform conversions, CPA, and attributed ROASWhether the advertising caused the conversion
    Should the campaign keep receiving money?Incremental lift, incremental ROAS, and contributionWhether a larger budget will perform at the same rate
    Where should the next budget block go?Marginal incremental revenue or contributionHow performance will change after a major market or product shift
    Is the brand gaining visibility in AI answers?Paid exposure and unpaid AI mentions measured separatelyThat either form of visibility caused profitable demand

    Run an incrementality test that matches the business question

    You do not need a perfect measurement laboratory. You do need a credible counterfactual: an estimate of what would have happened without the advertising.

    1. Choose one business outcome before launch. Use completed revenue, gross contribution, qualified pipeline, new customers, or another outcome tied to the decision. Do not replace it mid-test with whichever platform metric looks strongest.
    2. Choose a control design. Comparable geographic markets, randomized audience holdouts, platform lift tests, audience exclusions, and controlled spend reductions can all create evidence beyond ordinary attribution. Geo splits and audience holdouts are especially useful when user-level journeys cannot be observed cleanly.
    3. Protect the contrast. Record which campaigns, markets, audiences, promotions, and prices differ between treatment and control. A large promotion in only one group can look like advertising lift even when the ad had little effect.
    4. Record the exposure rules. Preserve campaign settings, eligibility, placement types, creative versions, market coverage, and any platform product changes. This matters more in AI inventory, where formats and reporting can change while the channel is still maturing.
    5. Let the test cover the decision cycle. A test that ends before delayed purchases or qualified leads can mature will favor channels with short feedback loops. Set the observation window from the actual buying process, not from a convenient reporting date.
    6. Report uncertainty with the result. A positive point estimate from a small or volatile control group is not automatically a scalable win. If the result is too noisy to distinguish lift from normal variation, enlarge the test unit, repeat it, or classify the conclusion as unresolved.

    Maintain a test ledger with the hypothesis, primary outcome, treatment and control definitions, launch and end conditions, known confounders, result range, and budget decision. That record stops teams from remembering only successful tests and makes later retesting much faster.

    Treat conversational AI ads as a learning budget

    A researcher directs a measured stream of budget tokens into three transparent chambers testing abstract conversational ad experiences with anonymous audiences.

    Conversational advertising should not inherit the assumptions of search, social, or display. OpenAI began rolling out ads to Free and Go users in Australia, New Zealand, and Canada while keeping Pro, Business, Enterprise, and Education plans ad-free. Results from that inventory therefore should not be generalized to every ChatGPT user, market, or subscription tier.

    The early buying environment also carries unusually high measurement risk. Initial advertiser accounts described impression-led campaigns, limited reporting, high CPMs, and starting commitments in the six-figure range. Those accounts are preliminary, not a dependable benchmark for what every advertiser will pay or achieve. They are still enough reason to demand a sharper test plan before committing a material budget.

    Write the pilot brief before negotiating inventory

    • State the user moment. Name the conversational situation you expect to influence, such as category comparison, product research, retailer selection, or troubleshooting. A generic awareness objective is too broad to diagnose.
    • Define an exposure. Establish whether the platform reports a served impression, visible placement, interaction, click, conversation, or another unit. Do not compare CPMs until you know what the impression represents.
    • Name one primary outcome. Choose incremental qualified visits, incremental orders, incremental contribution, or qualified pipeline. Treat impressions and clicks as diagnostic signals rather than proof of growth.
    • Set the economic boundary in advance. Calculate the maximum acceptable acquisition cost or minimum contribution return from your own unit economics. If the required commitment would displace a proven campaign or consume the budget needed for a valid control, wait.
    • Specify the control. Use an unexposed geography, audience, eligible period, or other comparable unit where the placement will not run. If the seller cannot support or tolerate a credible comparison, classify the investment as exploratory rather than performance-proven.
    • Preserve evidence. Export the available delivery, market, tier, placement, creative, billing, and outcome data. Note reporting-definition changes so a product update is not mistaken for a performance change.
    • Set a stop rule. Decide what level of economic loss, reporting failure, brand-safety concern, or control contamination ends the test. The novelty of the format is not a reason to ignore an invalid experiment.

    Keep paid presence separate from earned AI visibility

    A sponsored brand appearing near a recommendation is not the same as a model selecting, citing, or mentioning that brand without payment. Early placements may influence the journey indirectly by making a sponsored retailer more prominent among recommendations, even when the underlying answer is presented as independent from the ad.

    Measure three lanes separately:

    • Paid AI delivery: eligible exposure, served placements, interactions, clicks, cost, and available conversion signals.
    • Earned AI visibility: unaided brand mentions, citations, recommendation presence, and factual accuracy across a fixed set of representative prompts.
    • Business effect: incremental visits, qualified leads, new customers, revenue, and contribution against a control or credible baseline.

    This separation protects your AEO and GEO work from a false success signal. Paid exposure can increase while unpaid recommendation visibility falls, or an AI system can mention the brand more often without creating profitable demand. Neither outcome should be credited to the other without a test.

    Move budget according to marginal contribution

    The AI shift does not make established channels irrelevant. IAB/PwC figures put U.S. search advertising revenue at $114.2 billion in 2025 within a $294.6 billion digital advertising market. Digital video reached $78 billion after 25.4% growth, while social reached $117.7 billion after 32.6% growth. The ten largest companies controlled 84.1% of the market.

    Those market totals describe where money went, not where your next dollar belongs. A rapidly growing channel can be unprofitable for your offer, while a slower-growing channel can still produce strong incremental contribution. Concentration also means the same large platforms often control inventory, optimization, and attribution. Use their reporting to manage campaigns, but require independent business outcomes or controlled lift before treating claimed conversions as proof.

    Use a repeatable capital-allocation cycle

    1. Rank current channels by marginal contribution. Use the most recent credible spend change or controlled test, not lifetime average ROAS.
    2. Choose the next observable budget block. It should be large enough to create a measurable change but small enough that a weak result does not materially damage the plan.
    3. Estimate the expected range. Record a low, central, and high outcome using evidence from your tests and unit economics. Do not convert an uncertain pilot into a single precise forecast.
    4. Move one block from the weakest expected marginal use to the strongest. Keep major promotions, pricing changes, and other confounders visible so they do not receive advertising credit.
    5. Remeasure after the change. Marginal returns usually change with spend. A channel that deserved the previous increase does not automatically deserve the next one.

    It also helps to classify spending by purpose. Core campaigns have repeatable causal and economic evidence. Experimental campaigns buy information about new inventory, audiences, or creative. Verification spending retests old assumptions after platform, product, or market changes. A brand-defense campaign may remain strategically valuable despite low measured incrementality, but label it as protection rather than presenting it as growth. That makes the trade-off explicit.

    Key takeaways

    • Platform ROAS measures attributed performance; it does not establish how much revenue advertising caused.
    • Incrementality tells you whether a campaign created an outcome that would not otherwise have occurred.
    • Marginal contribution, not blended ROAS, should determine whether the next budget increase is economically sound.
    • Conversational AI ads need a defined exposure unit, control, business outcome, economic limit, and stop rule before a substantial commitment.
    • Paid AI placements, earned AI visibility, and business impact belong in separate measurement lanes.
    • Market growth identifies where advertisers are moving, but your own causal evidence and unit economics should determine where you move.

    For your next budget review, replace the single ROAS column with six fields: attributed return, incremental lift, incremental contribution, marginal return, confidence level, and next test. Mark an untested channel as unproven rather than successful or failed. Then fund the next measurable budget block where the expected marginal contribution is strongest. AI formats will keep changing; that decision discipline will remain useful even when the placements do not.

    References


  • SEO Under Constraints: Rendering and Restricted Keywords

    SEO Under Constraints: Rendering and Restricted Keywords

    Your page can fail search visibility in two places at once. The content a crawler needs may not exist until JavaScript runs, while the phrase customers actually search may be prohibited by legal, trademark or brand rules.

    Treat those as separate failure modes. First, make the page understandable without waiting for client-side rendering. Then build relevance around the intent you are allowed to express. That order matters: stronger copy cannot rescue content a crawler never receives.

    Separate retrieval problems from relevance problems

    A rendering constraint affects retrieval. The server returns a thin document, and JavaScript later inserts the main copy, navigation, product details or internal links. A wording constraint affects relevance. The page is available, but the language that connects it to a valuable query is weak, indirect or deliberately absent.

    When both occur on the same page, teams often misread the symptoms. An editor adds more synonyms when the copy is missing from the initial response. A developer improves rendering while the approved vocabulary still fails to describe the searcher’s need. Neither change closes both gaps.

    QuestionWhat to inspectWhat the result means
    Can a crawler understand the page before JavaScript runs?The raw HTML response, including the title, main heading, essential copy and linksIf the page’s purpose is missing, you have a retrieval problem.
    Can a visitor understand the offer without the restricted phrase?Headings, body copy, definitions, attributes, use cases and related terminologyIf the offer remains vague, you have a relevance problem.
    Is the phrase legally prohibited or merely discouraged?The written rule for body copy, metadata, links, comparisons, questions and definitionsThe permitted tactics depend on the actual boundary, not an informal preference.
    Does the approved vocabulary match how people express the need?Query data grouped by intent rather than one isolated keywordA large demand gap may justify revisiting the policy or creating a stronger semantic route.

    Run these checks before changing templates or copy. They tell you whether the next ticket belongs with engineering, content, legal or all three. They also give each team a testable acceptance criterion instead of the vague instruction to improve SEO.

    Put the essential answer in the initial HTML

    Solid core page panels emerge first from a server while translucent secondary modules assemble behind them.

    Google can execute JavaScript, but execution is not the same as immediate, complete discovery. Pages can be queued until rendering resources are available, after which a headless browser processes the client-side code. That extra stage creates another opportunity for delayed or incomplete discovery.

    The dependency is even riskier outside Google. Many AI crawlers and other non-Google bots do not consistently execute JavaScript. If the useful answer exists only inside a client-rendered component, those systems may receive a shell rather than a document they can quote, classify or follow.

    You do not need to rebuild every interaction as a no-JavaScript application. You do need an HTML-first discovery path for anything that establishes what the page is, what it offers and where its important links lead.

    • Return a unique, meaningful page title and a clear main heading in the server response.
    • Include the primary explanation, answer, product description or service description before client-side code runs.
    • Expose essential facts that determine whether the result satisfies the visitor’s need. Do not hide the only useful details behind tabs, filters or event handlers.
    • Render primary navigation, breadcrumbs and contextual internal links as ordinary anchors with real destinations.
    • Deliver structured information needed to identify the page and its subject in the initial document where practical.
    • Add JavaScript for filtering, personalization, live calculations and other interactions after the discoverable foundation is present.

    Server-side rendering, static generation and pre-rendering can all provide that foundation. The right choice depends on how often the content changes and how much of the interface is truly dynamic. A stable service page may suit static generation. A frequently updated catalogue may need server-side rendering. A client-rendered application can selectively pre-render its public discovery pages while keeping authenticated workflows dynamic.

    A <noscript> block can be a safety net, but it should not become a second, neglected version of the page. If you use one, keep it concise and aligned with the visible experience. The safer architectural target is meaningful server-delivered HTML that JavaScript enhances rather than replaces.

    Test the response, not just the finished screen

    A browser screenshot with JavaScript enabled proves that a visitor can see the interface. It does not prove that a crawler received the content or that the links are discoverable. Use this sequence on every important template:

    1. Open the raw server response or page source. Find the title, main heading, first useful answer and primary links.
    2. Load the page with JavaScript disabled. Confirm that its subject and next step remain understandable.
    3. Inspect critical links. They should have crawlable destinations rather than relying only on click handlers.
    4. Compare the initial and enhanced versions. They can differ in presentation, but they should not contradict each other or describe different offers.
    5. Repeat the check while logged out and without stored browser state. Public discovery must not depend on a previous session.
    6. Test a sample from every shared template. Passing one editorial page says little about a product, location or category template built through a different rendering path.

    Prioritize pages by consequence. Start with the homepage, high-demand landing pages, major categories, locations and pages that supply internal links to deeper content. A missing decorative widget is inconvenient. A missing product description or category link changes what the crawler can understand and reach.

    Map the search intent before working around a restricted term

    Hands arrange groups of pictorial tokens along illuminated paths around a locked central tile.

    Do not treat every keyword restriction as the same instruction. A trademark concern, an absolute legal prohibition, a brand preference and a rule against making one phrase the primary focus create different boundaries. Get the rule in writing before anyone places the term in a heading, title, image description or link.

    The first question is not, “How can we hide this keyword?” It is, “What is the searcher trying to identify, compare or accomplish?” That change of frame gives you legitimate language to work with even when the familiar label is unavailable.

    Demand data can also reveal whether an internal naming preference carries a substantial visibility cost. In one senior-living comparison, “skilled nursing near me” showed 4,400 monthly searches while “nursing home near me” showed 27,100. Those figures do not create permission to use a prohibited phrase. They do show why legal, brand and search teams should make the decision with the same evidence in front of them.

    Build an intent map around the restricted query. Include:

    • The approved category: the clearest accurate name you are allowed to use.
    • The underlying job: what the person wants to buy, arrange, learn, compare or solve.
    • Defining attributes: materials, features, level of support, location, compatibility or other characteristics that make the offering identifiable.
    • Use contexts: the occasions, environments and situations in which the need appears.
    • Audience language: natural questions, synonyms, spelling variants and adjacent terms that people use for the same intent.
    • Necessary distinctions: what the offering is, what it is not and how nearby categories differ.

    For a beverage-insulation product, for example, the semantic field might include can cooler, insulated drink sleeve, beer, cold drinks, party favors and occasions such as a bachelorette party. No single substitute has to impersonate the restricted name. Together, accurate category, attribute and context language can make the page’s subject clear.

    Use the exact term only where permission is explicit

    Some policies allow a term in a factual definition, comparison, question or combined product label but prohibit presenting it as the brand’s preferred category. If legal or brand reviewers approve that boundary, a limited contextual mention can clarify the relationship between the common query and the approved offering.

    If the phrase is prohibited everywhere, do not smuggle it into metadata, alternative text or anchor text. Those fields are still published content. Search engines can process them, users may encounter them, and moving a term out of the visible body does not remove a trademark or compliance concern.

    Apply the same rule to each element:

    • Title and main heading: lead with the approved category and the page’s actual promise.
    • Introduction: answer the underlying need immediately. Do not force awkward synonyms into a sentence that becomes harder to understand.
    • Definitions: explain unfamiliar approved terminology and its boundaries. Use the restricted label only if that explanatory use has been cleared.
    • Internal links: choose descriptive anchor text that truthfully identifies the destination. An approved common term can be useful; an unapproved one remains unapproved.
    • Alternative text: describe the image and its purpose. It is not a storage area for keywords that copy reviewers rejected.
    • External links: do not build an artificial exact-match pattern. Use language that is accurate, natural and permitted in that context.

    You may still earn visibility without the exact phrase because relevance can be established through related concepts and intent. It is not a guarantee, especially when competitors can use the dominant wording directly. Set expectations accordingly: the goal is the strongest truthful signal set available under the constraint, not a loophole that makes the constraint disappear.

    Use one launch gate for code, copy and compliance

    A constrained page should not move through engineering, editorial and legal as three disconnected deliverables. Give it one acceptance checklist. That prevents a technically crawlable page from shipping with vague language, or approved copy from disappearing behind client-side rendering.

    1. Define the page’s job. Write one sentence stating who the page helps, what they need and what action the page should enable.
    2. Name the query family. Group the restricted term, approved synonyms, questions, category language, attributes and use cases by shared intent.
    3. Record the wording boundary. Specify whether the term is banned everywhere, allowed only in named contexts or merely excluded as the primary label. Cover headings, body copy, metadata, links and image descriptions separately.
    4. Draft the minimum complete answer. Before designing interactive elements, write the heading, concise explanation, essential facts and next-step links that must exist in the initial HTML.
    5. Place approved relevance signals. Use the approved category prominently, then add useful attributes, applications, distinctions and definitions. Each addition should improve understanding, not just keyword coverage.
    6. Render the foundation on the server. Choose static generation, server-side rendering or pre-rendering for the public content. Hydrate interactive features on top of it.
    7. Run two reviews. Technical QA verifies the raw response and crawlable links. Editorial and legal review verify that every published field follows the wording policy.
    8. Measure by query group and template. Watch whether the intended family of searches reaches the page and whether affected templates are discoverable. Do not judge the work from one exact keyword or one successfully rendered URL.

    Write the acceptance criteria so failure is obvious. “Improve crawlability” is not testable. “The service description and links to all primary locations appear in the initial HTML” is. “Use related keywords” is equally weak. “The title names the approved category, and the body explains its use, defining attributes and difference from adjacent categories” gives an editor something concrete to deliver.

    When a page still underperforms, return to the two failure modes. If the content is absent from the response, fix retrieval. If it is present but does not clearly resolve the intent, fix relevance. If the exact phrase would materially change the opportunity but remains prohibited, take the demand evidence back to the decision-maker rather than quietly violating the rule.

    Key takeaways

    • Rendering and keyword restrictions are independent constraints: one limits retrieval, while the other limits relevance signals.
    • Put the page’s heading, essential answer, core facts and important links in server-delivered HTML.
    • Use JavaScript to enhance the experience, not as the only delivery mechanism for content that must be discovered.
    • Clarify whether a restricted term is legally banned, contextually permitted or simply discouraged before placing it anywhere.
    • Build relevance through approved category language, intent, attributes, use cases, definitions and natural internal links.
    • Make raw-HTML validation and wording compliance part of the same launch gate.

    Start with one high-value template this week. Capture its raw HTML, mark the essential content that is missing, document the exact wording boundary and rebuild the smallest complete answer that satisfies both. Once that page passes, turn the checks into requirements for every template that follows.

    References


  • Effortless Google PMax Campaign Import with Microsoft Updates

    Effortless Google PMax Campaign Import with Microsoft Updates

    I’m thrilled to share that Microsoft is simplifying the process of expanding Google PMax campaigns into Microsoft, allowing us to enjoy greater visibility and control over our campaign performance.

    Microsoft Advertising is launching several updates to make managing, measuring, and migrating Performance Max campaigns more straightforward, especially for those of us already familiar with Google Ads.

    Driving the news. Microsoft now allows us to import Google PMax campaigns with new customer acquisition (NCA) goals, a feature that’s been part of Microsoft since earlier this year.

    The update is live for all advertisers now, enabling us to transfer campaigns focused on first-time buyers more seamlessly, without having to start from scratch.

    What’s new. Microsoft ensures that when we import Google PMax campaigns with NCA goals, they will be retained if they don’t already exist in our account. Our existing settings won’t be overwritten.

    Regarding audience lists:

    • Google website visitor segments transform into Microsoft remarketing lists.
    • Google’s “all visitors” and “all converters” lists map to similar lists on Microsoft.
    • For unsupported lists like Customer Match, we may need to use alternate options.

    I’ve also noticed that Microsoft takes a cautious approach with “unknown” customers, categorizing them as existing customers to avoid inflating new customer conversion counts.

    Why we care. This initiative could streamline cross-platform campaign expansion and reduce the hassle of rebuilding, making it simpler to test Microsoft’s PMax inventory. Plus, enhanced landing page reporting and search term insights offer a clearer picture of campaign performance, aiding our optimization and budget decisions.

    More visibility for PMax. Microsoft is integrating landing page (Final URL) reporting for PMax campaigns, allowing us to review spend, clicks, impressions, conversion value, and ROAS by landing page.

    We can also break this information down by campaign, asset group, and other dimensions.

    Additionally, Microsoft stated that search term reporting will become more apparent by default, with more transparency updates such as auction insights and publisher URL metrics rolling out soon.

    Other key updates:

    • Seasonality adjustments now support portfolio bid strategies, aiding short-term promotions.
    • Campaign name limits have increased, enabling up to 400 characters for easier management.
    • Autogenerated assets are improving ad relevance and performance by filling in underused Responsive Search Ads.
    • Merchant Center users can directly update store names and domains without needing support.

    The bottom line. These updates simplify scaling across platforms, save time on campaign setups, and enhance our visibility into campaign performance, giving us greater control over efficiency and outcomes.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google Chrome AI Mode: What Changes for Search and SEO

    Google Chrome AI Mode: What Changes for Search and SEO

    If you work in SEO, a new Google AI interface can look like an urgent ranking update. That is not the right conclusion to draw from Chrome AI Mode. The immediate change is to the searcher’s workspace: an AI response, webpages, open tabs, images, and files can now become parts of the same research session.

    Your practical task is to separate two questions. First, can AI Mode discover your page without help? Second, when someone opens or supplies your page as context, does it make the answer easier to verify? Chrome’s new interface makes both questions important, but they measure different kinds of success.

    Chrome AI Mode turns a search into a working context

    Traditional web research creates friction as the searcher moves among a results page, multiple tabs, downloaded documents, and notes. Chrome AI Mode reduces that switching by keeping more of the research context attached to the query.

    Side-by-side search keeps the answer and webpage visible

    On desktop, clicking a result in AI Mode can open the linked webpage beside the AI experience. The searcher can inspect the page, compare details, visit other relevant sites, and ask follow-up questions without abandoning the original context.

    That layout changes the moment at which your page is evaluated. A visitor does not necessarily arrive after leaving the AI answer behind. Your title, answer, qualifications, and supporting evidence may be judged while the generated response remains visible next to them. If the two conflict, the mismatch is easier to notice. If your page supplies a missing condition or clearer explanation, that is easier to notice too.

    Recent tabs can become query context

    On desktop and mobile, the plus menu on the New Tab page or inside AI Mode can bring recent tabs into a search. AI Mode can use that selected context to customize its response and recommend additional sites.

    This creates an important measurement boundary. If you add your own website as a tab and AI Mode then discusses it accurately, you have tested contextual understanding. You have not shown that the website would have been discovered from a cold query. Run those tests separately or you will mistake supplied context for organic AI visibility.

    Images and files can join the same task

    The plus menu can also combine tabs, images, and files such as PDFs in the prompt context. Canvas and image-creation tools are available through that menu as well.

    For a content team, this means a webpage may be compared with material that never appeared in the written query: a specification PDF, a screenshot, a chart, or another open page. Make each important asset understandable on its own. Give PDFs descriptive titles, label charts plainly, explain what an image proves in the surrounding copy, and keep terminology consistent across formats. Those practices help a person verify the material even when the surrounding AI behavior is uncertain.

    Availability also needs a qualifier. These Chrome-specific capabilities initially launched for U.S. English users. Do not assume every teammate, market, device, or customer can reproduce the same workflow. Record language, market, device type, and feature availability with every test.

    The SEO impact is behavioral, not a confirmed ranking change

    Chrome AI Mode changes how people can gather and examine information. The announced capabilities do not establish a new ranking factor, crawler requirement, or structured-data type. There is no sound basis here for a Chrome-specific schema, a new metadata field, or an emergency rewrite of every page.

    The useful SEO interpretation is narrower. Chrome is making contextual search and page-level verification easier. That creates three distinct outcomes you should track:

    • Cold discovery: your brand or page appears when the query begins without your site, tabs, or files being supplied.
    • Contextual synthesis: AI Mode uses your page correctly after the searcher deliberately adds it as a tab or file.
    • Verification: the searcher opens your page beside the answer and can quickly confirm, qualify, or reject the generated claim.

    Only the first outcome directly tests whether your content was discovered from the query. The other two still matter: they show whether the content is usable and trustworthy once it enters the session. But reporting all three as “AI rankings” would conceal what actually happened.

    This distinction also explains why a single screenshot is weak evidence. A response may depend on the recent tabs, images, or files that were added before the prompt. Preserve the prompt and the supplied context when you document a result. If you cannot reconstruct the session, you cannot tell whether the page was retrieved, supplied, or merely opened for confirmation.

    Audit pages for side-by-side verification

    A split-screen monitor shows an abstract AI answer beside a structured webpage, with a magnifying glass positioned between them for comparison.

    A page opened next to an AI response has a demanding job. It must orient the visitor quickly, answer the relevant question, and expose enough support for the visitor to decide whether the answer is reliable. A long page can still do this well; the requirement is clarity, not brevity.

    1. Start with a decision query. Use the question a customer asks when choosing, comparing, troubleshooting, or validating something, not just a short keyword.
    2. Open the most relevant page beside AI Mode on desktop. Check whether its visible title and opening copy make the subject and scope unmistakable.
    3. Locate the direct answer. The reader should not have to infer it from a broad introduction. State the answer before expanding into background, exceptions, or examples.
    4. Trace the important claims. Make sure a person can find the definition, limitation, comparison basis, or supporting detail that justifies each conclusion.
    5. Check context independence. A visitor may land on a subsection from an AI-assisted journey, so headings such as “Benefits” or “Options” are often too vague. Name the product, task, or decision in the heading when ambiguity is possible.
    6. Compare formats. If the webpage, PDF, image labels, and structured data describe the same entity, use the same names, attributes, and qualifications across them.
    7. Repeat the query without adding your site as a tab. Record whether the page is discovered cold, used only after being supplied, or opened only as supporting evidence.

    The structured-data check deserves restraint. Keep existing markup aligned with what a visitor can see on the page, and correct contradictions between markup and copy. Do not add invented properties or relabel established schema because an AI interface changed. Nothing in this Chrome feature set demonstrates a special markup shortcut into AI Mode.

    Pay particular attention to scope language. A direct answer can still mislead if the applicable market, product version, audience, prerequisite, or exception appears much later. Put a necessary qualification beside the claim it limits. That makes the page more useful when someone is comparing it with an abbreviated AI response.

    Use AI Mode for content QA without fooling yourself

    A content specialist compares an abstract AI panel with a webpage and source documents while using a magnifying glass and check tokens.

    Chrome AI Mode can support a disciplined content review, provided you control the context. The purpose is not to manufacture a favorable response. It is to find where your content becomes ambiguous, incomplete, or hard to verify.

    1. Begin with a clean query and no company-owned tabs or files included. Save the exact wording and note whether your page appears.
    2. Open a relevant result beside AI Mode. Compare the generated answer with the page’s actual wording, scope, and qualifications.
    3. Add only the tabs or files needed for the decision. A smaller context makes it easier to identify which material influenced the response.
    4. Ask follow-up questions about conflicts, missing conditions, and comparison criteria. Use the answers to locate weaknesses in the underlying pages, not as proof that the model is always correct.
    5. Remove the supplied context and run the clean query again. Differences between the two sessions reveal what depended on your added material.
    6. Log the test environment: desktop or mobile, language and market, query, included tabs, included files, pages opened, and observed result.

    Use the findings to repair the content itself. If AI Mode overlooks a qualification that is buried near the bottom, move that qualification next to the claim. If two pages use different names for the same feature, choose a canonical term and explain any necessary synonym. If a PDF contains the decisive evidence but the webpage barely identifies it, add a descriptive link and explain why the file matters.

    Do not optimize merely for the generated wording you happened to receive. Because selected tabs and files can change the context, a context-bound answer is not a stable template for future responses. Optimize the underlying facts, relationships, labels, and evidence that should remain correct across many possible prompts.

    Key takeaways

    • Chrome AI Mode can keep a webpage beside the generated response on desktop, making comparison and verification part of the same view.
    • Recent tabs can be added on desktop and mobile, while images and files such as PDFs can supply further context.
    • A favorable response after adding your own page tests contextual usefulness, not cold discovery or ranking.
    • The feature set does not establish a new ranking signal or Chrome-specific schema requirement.
    • Audit content for direct answers, visible qualifications, consistent terminology, and evidence that is easy to locate beside an AI response.
    • Initial availability was limited to U.S. English users, so document the market, language, device, and context behind every test.

    Start with the decision query that matters most to your audience. Test it once without supplied context and once with the relevant page or document added. The gap between those sessions will tell you whether your next priority is discovery, clearer content, or better supporting evidence.

    References


  • How to Build Website Authority for AI Search Visibility

    How to Build Website Authority for AI Search Visibility

    If an AI answer gets your business wrong, leaves you out, or cites a competitor, publishing another broad article is rarely the cleanest fix. You need to make the right facts easy to crawl, easy to retrieve, difficult to misinterpret, and consistent everywhere they appear.

    That turns website authority from a vague reputation goal into a practical system. You can inspect each part, find the break, and fix the page or fact that is actually limiting your visibility.

    Treat authority as a chain from crawl to customer

    AI search visibility can fail at several different stages. A page may be accurate but inaccessible to a crawler. It may be crawlable but poorly matched to the question. It may be retrieved but not selected as supporting evidence. Your brand may even appear in an answer without earning the customer’s trust afterward.

    Separate the chain into these diagnostic layers:

    • Crawl access: Can relevant crawlers request the public URL and receive the page successfully?
    • Interpretation: Does the page identify the business, service, location, product, or person without ambiguity?
    • Retrieval: Does one section closely answer the user’s actual question?
    • Selection: Is the answer precise and well-supported enough to be used or cited?
    • Validation: Do your other pages and external profiles confirm the same facts?
    • Conversion: Can a person who follows the recommendation verify the offer and take the next step?

    This distinction matters because a citation is not the same as a recommendation, and a recommendation is not the same as a sale. A citation means your URL supported an answer. A mention means your name appeared. A recommendation places you among the options. Authority has to carry the user through all three and then survive their visit to your site.

    Retrieval is especially important. Across an AirOps analysis of 16,851 unique queries, the first retrieval result was cited 58.4% of the time, while the result in tenth position was cited 14.2% of the time. Pages with headings that strongly matched the query were cited 41% of the time. Those figures do not establish a universal ChatGPT ranking formula, but they show why a generally authoritative domain can still lose a particular answer: the wrong page or passage wins retrieval.

    When you diagnose a visibility problem, do not begin with, “How do we make the whole domain more authoritative?” Begin with a narrower question: “For this customer question, which URL should be retrieved, which passage should be selected, and which facts must another source be able to confirm?”

    Design pages to win retrieval, not merely cover topics

    An organized modular website feeds distinct fact objects into a central retrieval beam while cluttered pages sit outside it.

    A page earns retrieval by making its purpose obvious. The title, primary heading, opening answer, supporting details, and internal links should all point to the same intent. A page called “Our Solutions” forces a system to infer what it contains. A heading such as “Does the service include installation?” identifies both the question and the expected answer.

    Build each important answer in this order:

    1. Choose one real customer question. Pull it from sales emails, support conversations, reviews, search queries, and questions on business profiles.
    2. Decide what kind of answer the user needs: a fact, qualification, process, comparison, availability check, or next action.
    3. Place a query-shaped heading above the answer. Use the customer’s language where it remains accurate.
    4. Answer immediately in plain sentences. Do not make the reader cross an origin story, promotional introduction, or table of contents to reach the useful fact.
    5. Add the conditions that prevent a misleading extraction. State relevant locations, exclusions, eligibility rules, dependencies, or situations in which the answer changes.
    6. Support the answer with concrete business information, then point the reader to the appropriate verification or action page.

    A narrow page is not necessarily a short or shallow page. It is a page with one dominant job. A service page can explain scope, suitability, process, limitations, and next steps without becoming a general guide to the entire industry.

    Conversely, long content is not automatically authoritative. In the same query analysis, pages between 500 and 2,000 words performed best for citations, while pages over 5,000 words were cited less often than even the shortest pages. Content with 4 to 10 subheadings also performed notably well. Treat those as observations from that dataset, not mandatory publishing limits. The useful principle is precision: stop when the question has been answered, qualified, and supported.

    A practical site architecture usually needs both hubs and focused pages. Use a broad hub to organize a subject and help users navigate it. Use a focused page when a distinct question requires its own evidence, conditions, or conversion path. Do not create separate URLs for trivial wording changes; consolidate near-duplicate questions under the clearest heading so your own pages do not compete to be the answer.

    Before publishing, apply a simple extraction test. Read only the heading and the paragraph beneath it. If that fragment would be accurate when shown without the rest of the page, the answer is well-formed. If it would overpromise, omit a location, or confuse one service with another, add the missing qualifier beside the answer rather than burying it later.

    Make your website the canonical truth layer

    Your site cannot function as an authority if its own facts drift. A homepage may use one business name, a location page another, and a profile an old address or schedule. An AI system then has to resolve the conflict, and the version it chooses may not be yours.

    This is particularly important in local search, where services, locations, hours, reviews, and business profiles help establish whether a recommendation fits the query. AI recommendations can be checked against multiple online profiles, while customers commonly validate the choice by visiting the website and reading reviews. Your site therefore has two jobs: provide precise information for the recommendation and provide enough proof for the person evaluating it.

    Create a fact inventory with one row for every claim that can change or cause a customer to choose incorrectly. Useful fields include:

    • The fact itself, written in its approved form.
    • The canonical page where that fact is explained.
    • Every important internal page and external profile that repeats it.
    • The person responsible for verifying it.
    • The event that should trigger an update.
    • The date on which someone last confirmed it.

    Start with identity and decision facts: business name, locations, service areas, hours, contact details, offerings, eligibility, availability, policies, and important limitations. For a local business, compare those facts with its Google Business Profile and major directories. For a product or service company, compare landing pages with pricing, support, policy, and documentation pages. Resolve contradictions at the canonical page first, then update every surface that repeats the fact.

    Authority also depends on evidence placement. Put identity information on the homepage and about page. Put service scope and limitations on the service page. Put location-specific availability on the relevant location page. Put policy details on the policy page. Repeating a short fact for context is reasonable, but one page should remain the full, maintained explanation.

    Use JSON-LD to identify facts, not manufacture authority

    Structured data helps a machine identify entities and relationships, but it cannot make vague copy precise or reconcile conflicting claims. In the citation dataset, pages with JSON-LD had a 38.5% citation rate, compared with 32.0% for pages without it. That is a useful but modest association, not evidence that schema alone causes citations.

    Use JSON-LD as a faithful machine-readable version of the visible page:

    • Select the most specific schema type that truthfully describes the entity or content.
    • Mark up only facts that users can verify on the page or through an appropriate canonical page.
    • Use stable URLs and identifiers for the same entity across connected markup.
    • Keep names, addresses, service descriptions, dates, and other properties aligned with visible content.
    • Validate syntax after changes and include structured-data checks in the same workflow that updates the page.

    If you have to choose between adding more properties and correcting a contradiction, correct the contradiction. Clear content establishes the claim; structured data labels it.

    Run an audit that separates visibility from accuracy

    A digital workbench uses separate illuminated lanes to inspect website fact modules for discoverability and consistency.

    An occasional vanity prompt will not tell you whether authority is improving. Generative answers can vary, and one broad question mixes discovery, retrieval, recommendation, and citation into a single result. Use a fixed audit that preserves the wording, platform, run date, and evidence.

    1. Build a prompt set around real decisions. Include questions about fit, availability, location, process, limitations, alternatives, and the next step. Use neutral language rather than inserting your brand into every prompt.
    2. Run the same prompts on the AI systems your customers are likely to use. Repeat important prompts so a single variable response does not become your conclusion.
    3. Record whether your brand appears, how it is described, whether the description is correct, whether your site is cited, which URL is used, and which competing or third-party sources support the answer.
    4. Inspect the cited or likely landing page. Check whether its title and headings match the question, whether the answer appears near the relevant heading, and whether all necessary qualifiers sit beside it.
    5. Check crawler access. Confirm that important URLs can be requested, do not return error responses, and are not unintentionally restricted by access rules.
    6. Fix the earliest broken link in the chain. There is little value in rewriting an answer passage if the page cannot be crawled, or adding schema while external profiles still carry the wrong location.

    Server-log analysis can expose crawler activity that ordinary traffic reports do not make obvious. Logs can show the requested URL, time, declared user agent, and response status. They cannot prove that a model stored, trusted, retrieved, cited, or used the content. Treat them as crawl evidence, then use prompt audits and citation tracking to evaluate the later stages.

    Prioritize corrections by consequence. Fix inaccurate high-intent facts first, followed by access failures, conflicting profiles, missing direct answers, and stale supporting content. This order protects the customer decision while also improving the material available for retrieval.

    Freshness deserves a targeted approach. Pages published 30 to 89 days before collection had the strongest citation performance in the AirOps dataset, while content less than 30 days old performed slightly worse and content older than two years struggled. That pattern may reflect the time needed to accumulate retrieval signals, and it does not justify rewriting every page on a fixed schedule. Use it as a reason to review older pages that already serve valuable queries, especially when their facts, examples, policies, or answer structure have drifted.

    Measure the outcome at each stage

    Your reporting should make failures distinguishable. Track prompt coverage, accurate-answer rate, brand mention rate, citation rate, owned-site citation share, cited URLs, crawler access, corrected fact conflicts, and the customer actions that follow AI-assisted discovery. Keep the prompt set stable long enough to detect a direction, and log material page changes so you can connect movement to an intervention.

    Do not use organic clicks as the sole verdict. An Ahrefs analysis found that 99% of keywords triggering an AI Overview were informational, while navigational keywords accounted for 0.13%. In that dataset, AI Overviews were concentrated overwhelmingly in informational searches. A decline in clicks from quick-answer queries can therefore coexist with useful visibility, but only if your brand is represented accurately and decision-stage users can still reach a convincing destination.

    Report exposure and business impact separately. Exposure tells you whether the brand and site enter the answer. Accuracy tells you whether the answer helps or harms. Decision actions tell you whether the website completes the job. Combining them into one visibility score hides the part you need to fix.

    Frequently asked questions

    What does website authority mean in AI search?

    Website authority in AI search is the site’s ability to provide crawlable, unambiguous, retrievable, consistent, and verifiable information for a particular question. It is not just a domain-level reputation score. A strong domain can lose a citation when its relevant page is vague, stale, inaccessible, or poorly matched to the query.

    Should every customer question have its own URL?

    No. Give a question its own page when it has distinct evidence, conditions, search intent, or a separate next action. Put closely related questions on one focused page under descriptive headings. Creating near-duplicate URLs for every phrasing makes maintenance harder and leaves several pages competing to represent the same answer.

    Can an uncited AI mention still be valuable?

    Yes, but count it separately from a citation. First check whether the mention is accurate, relevant to the question, and likely to lead a user toward verification. Then inspect whether your website supports the description and offers a clear next step. An inaccurate mention is not positive visibility merely because the brand appeared.

    What should you fix first?

    Fix the error with the greatest decision consequence. An incorrect location, service condition, eligibility rule, or availability claim comes before a missing optional schema property. After factual accuracy, address crawl failures and retrieval structure, then improve supporting depth and presentation.

    Start with the questions closest to a real customer choice. Assign each one a canonical page, verify every changeable fact, correct conflicts across your profiles, and make the answer extractable beneath a precise heading. Then rerun the same prompt set and inspect the logs. That cycle gives you something more useful than a vague authority campaign: a clear record of what AI systems can access, what they say, and what you need to improve next.

    References