Microsoft has just rolled out a suite of updates across Microsoft Advertising, and I couldn
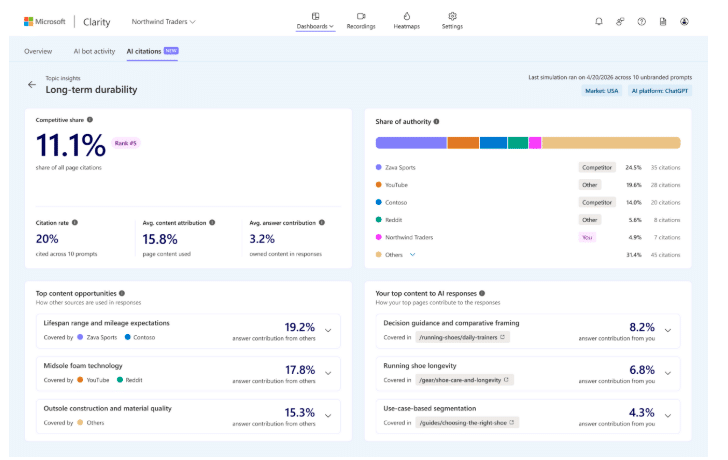
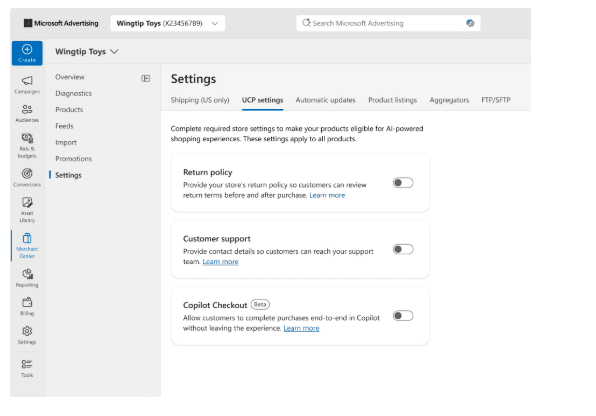
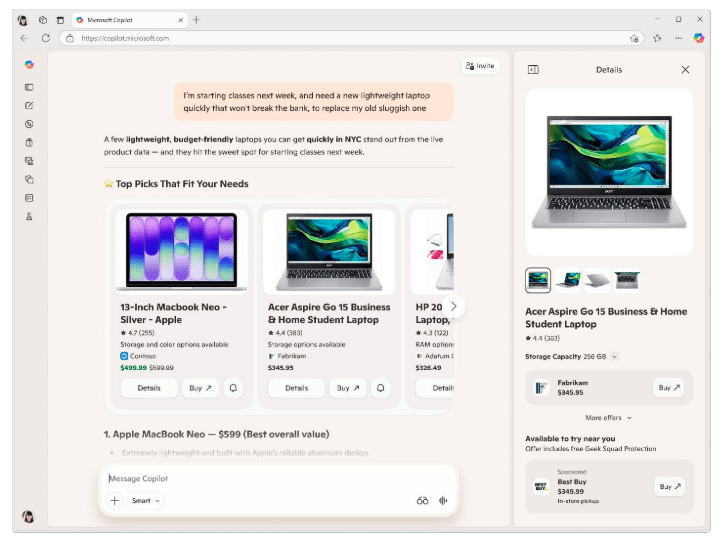
Inspired by this post on Search Engine Land.

Microsoft has just rolled out a suite of updates across Microsoft Advertising, and I couldn
Inspired by this post on Search Engine Land.
Your dashboard is green, the meeting starts soon, and you still cannot answer the question that matters: what changed, why did it change, and what should the team do next?
That is a reporting-system problem, not a chart problem. Modern marketing analytics should connect business outcomes to channel activity, preserve the definitions behind every metric, expose uncertainty, and deliver the next decision without forcing someone to reconstruct the analysis during the meeting.
Most bloated reports begin with a harmless question: what data can we pull? Every available metric gets added, the dashboard becomes comprehensive, and the decision it was meant to support disappears.
Reverse the sequence. Before choosing a connector, chart, or reporting platform, write a one-sentence measurement brief:
This report helps [owner] decide [action] at [cadence] by comparing [outcome] with [baseline], using [drivers] to explain the result and [guardrails] to prevent a bad trade-off.
A paid media lead might need to reallocate campaign budget each week. A content lead might need to decide which topics deserve an update, expansion, or new format. An SEO lead might need to distinguish a visibility problem from a conversion problem. These decisions require different evidence even when they draw from the same underlying data.
Assign every metric a role. If a metric has no role, remove it from the primary report.
| Metric role | Question it answers | Marketing example | How it should affect action |
|---|---|---|---|
| Outcome | Did the work produce the intended business result? | Qualified conversions, pipeline, revenue, retained customers | Determines whether the strategy is working |
| Driver | What directly influenced the outcome? | Qualified traffic, landing-page conversion rate, lead acceptance | Identifies where to intervene |
| Diagnostic | Where did performance change? | Campaign, query group, page type, audience, device, video | Narrows the investigation |
| Guardrail | What must not deteriorate while the team optimizes? | Acquisition cost, lead quality, unsubscribe rate, brand demand | Prevents a local gain from becoming a business loss |
This hierarchy corrects a common reporting mistake. Impressions, views, clicks, and engagement can be useful drivers or diagnostics, but they do not automatically become business outcomes because they are easy to retrieve. Likewise, a channel-level return figure is not trustworthy unless the report states what counts as a conversion, which costs are included, and how credit is assigned.
Record five items beside every primary outcome: its definition, owner, data system, update cadence, and attribution rule. If attribution is involved, also state the model, lookback window, reporting timezone, currency treatment, and whether the metric uses event time or processing time. There is no universally correct attribution model. There is only a model that is explicit enough to interpret and consistent enough to compare.
Set action rules before looking at the latest result. The rule does not need an invented universal threshold. It can be operational: investigate when an outcome moves outside its expected range, when a guardrail worsens, when the data is stale, or when two systems no longer reconcile. Precommitting to the rule reduces the temptation to invent a convenient explanation after seeing the chart.
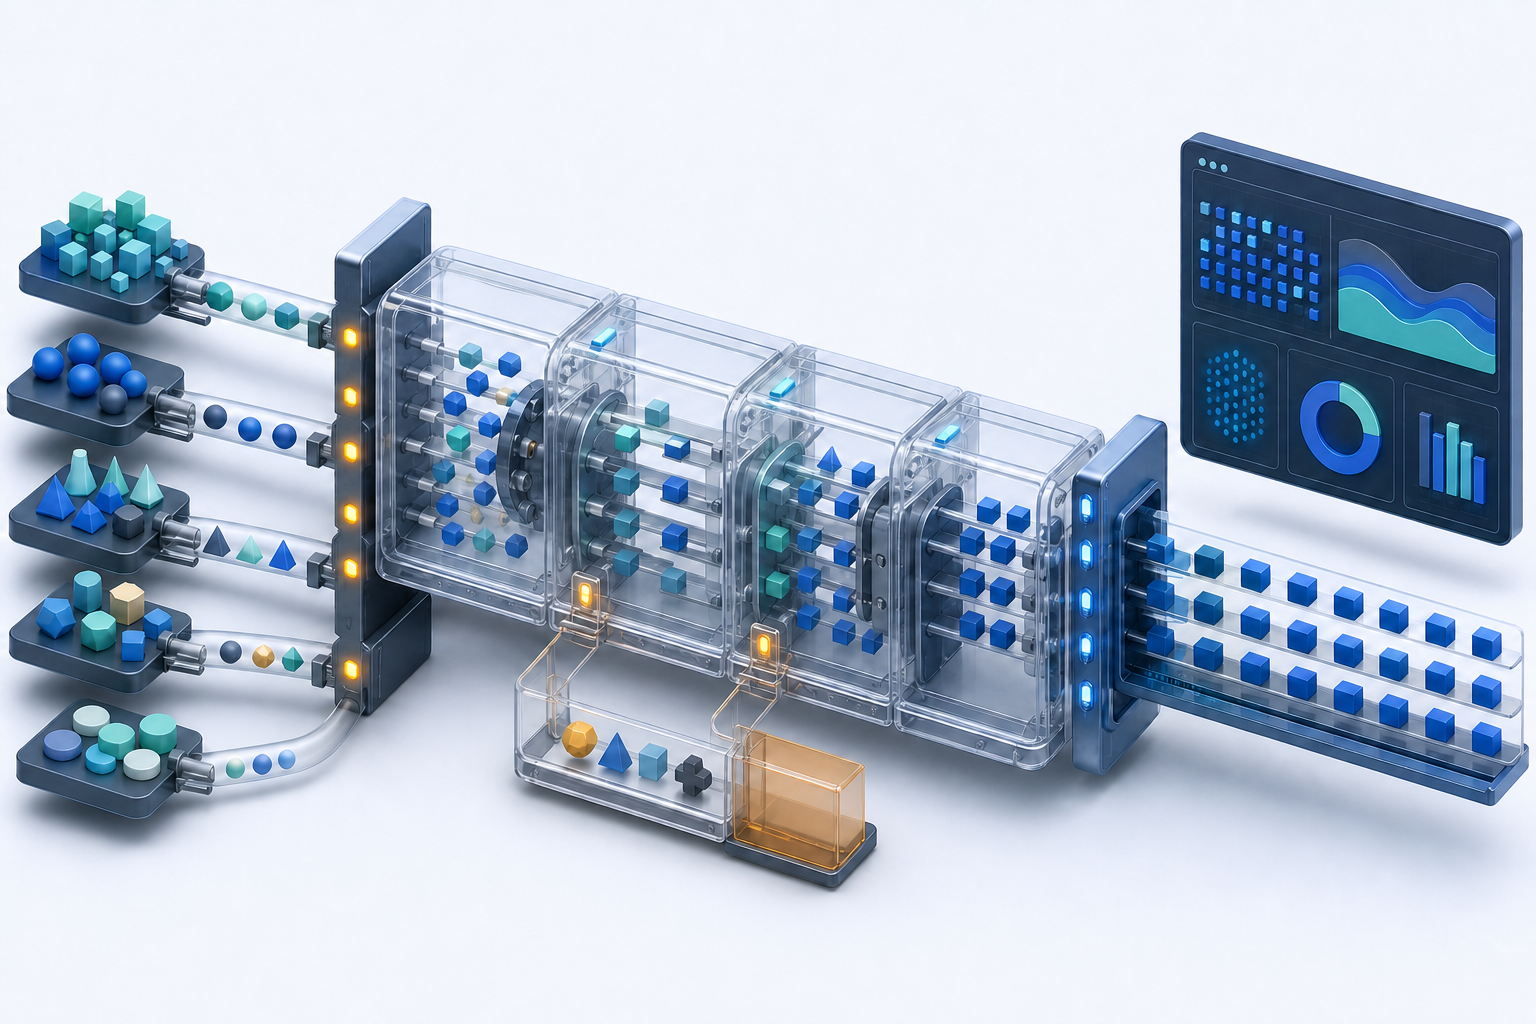
A polished dashboard cannot repair inconsistent definitions underneath it. If paid media uses platform-reported conversions, analytics uses attributed sessions, sales uses accepted opportunities, and finance uses recognized revenue, placing the figures on one page does not make them comparable.
Create a small data contract for each reporting dataset. It should specify:
Grain is the detail most likely to prevent a silent reporting error. Joining campaign-day costs to lead-level conversions can multiply spend when several leads share the same campaign and date. Aggregate both datasets to a compatible grain before joining them, or model the relationship so the cost appears only once. After every join, compare row counts and totals with the inputs.
Separate period reporting from cohort reporting. A period view answers what happened during a selected date range. A cohort view follows people, accounts, campaigns, or content acquired in a particular period through later outcomes. A recent acquisition cohort may look weak simply because its conversions have not had time to mature. Label incomplete cohorts instead of presenting them as final.
Run a compact quality checklist before publishing any result:
Do not hide a reconciliation gap with a calculated adjustment. If two systems answer different questions, label the difference. If they should match and do not, hold the affected conclusion until you know why. A visible limitation is manageable; an invisible one becomes a decision error.
A modern reporting stack does not require one tool to extract, clean, model, visualize, explain, and distribute everything. It works better when each layer has a narrow responsibility:
Dashboards are effective presentation surfaces when stakeholders need filters, recurring monitoring, and a shared view without access to every backend system. A Looker Studio report can, for example, connect YouTube Analytics data, support customized views, and distribute scheduled PDF snapshots. That makes it useful for a channel owner who needs repeatable visibility rather than a custom analysis every morning.
Keep the dashboard when its data volume is manageable, the transformations are simple, refreshes complete reliably, and an analyst can trace a wrong number back to its origin. Move complex logic upstream when the same calculated field is copied across pages, manual updates recur, refreshes become fragile, or debugging requires a long sequence of interface clicks. Broad datasets and accumulated business logic can make a dashboard slow to change, difficult to debug, and vulnerable to dataset limits.
Code is a better home for repeatable extraction, normalization, backfills, joins, tests, and calculations that need review. It gives you files that can be compared, versioned, and rerun. That does not mean every marketing team needs to replace every dashboard. A practical architecture keeps a familiar dashboard at the front while moving fragile transformations into a controlled pipeline behind it.
APIs are retrieval mechanisms, not guarantees of completeness. For every API connection, record the account or property queried, requested fields, filters, pagination behavior, expected refresh schedule, and the response received when data is unavailable. Keep credentials outside report code, grant only the access required, and plan for permission revocation. A successful request proves that data arrived; reconciliation proves that the right data arrived.
AI coding assistants can reduce the effort required to scaffold connectors, transformations, tests, and report components. Natural-language specifications can help tools such as Claude Code and OpenAI Codex assemble multistep reporting workflows. Treat the generated work as a draft implementation. Review the query grain, inspect joins, run tests, protect secrets, and compare outputs with authoritative systems before a generated number reaches a stakeholder.
Use AI differently in the analysis layer. Ask it to identify anomalies worth investigating, draft plain-language explanations from approved metrics, or translate a validated analysis for different audiences. Do not let it infer causation from a correlated chart or invent a reason for a movement that the data cannot explain. The final narrative should distinguish among a measured fact, an analyst interpretation, and a proposed test.
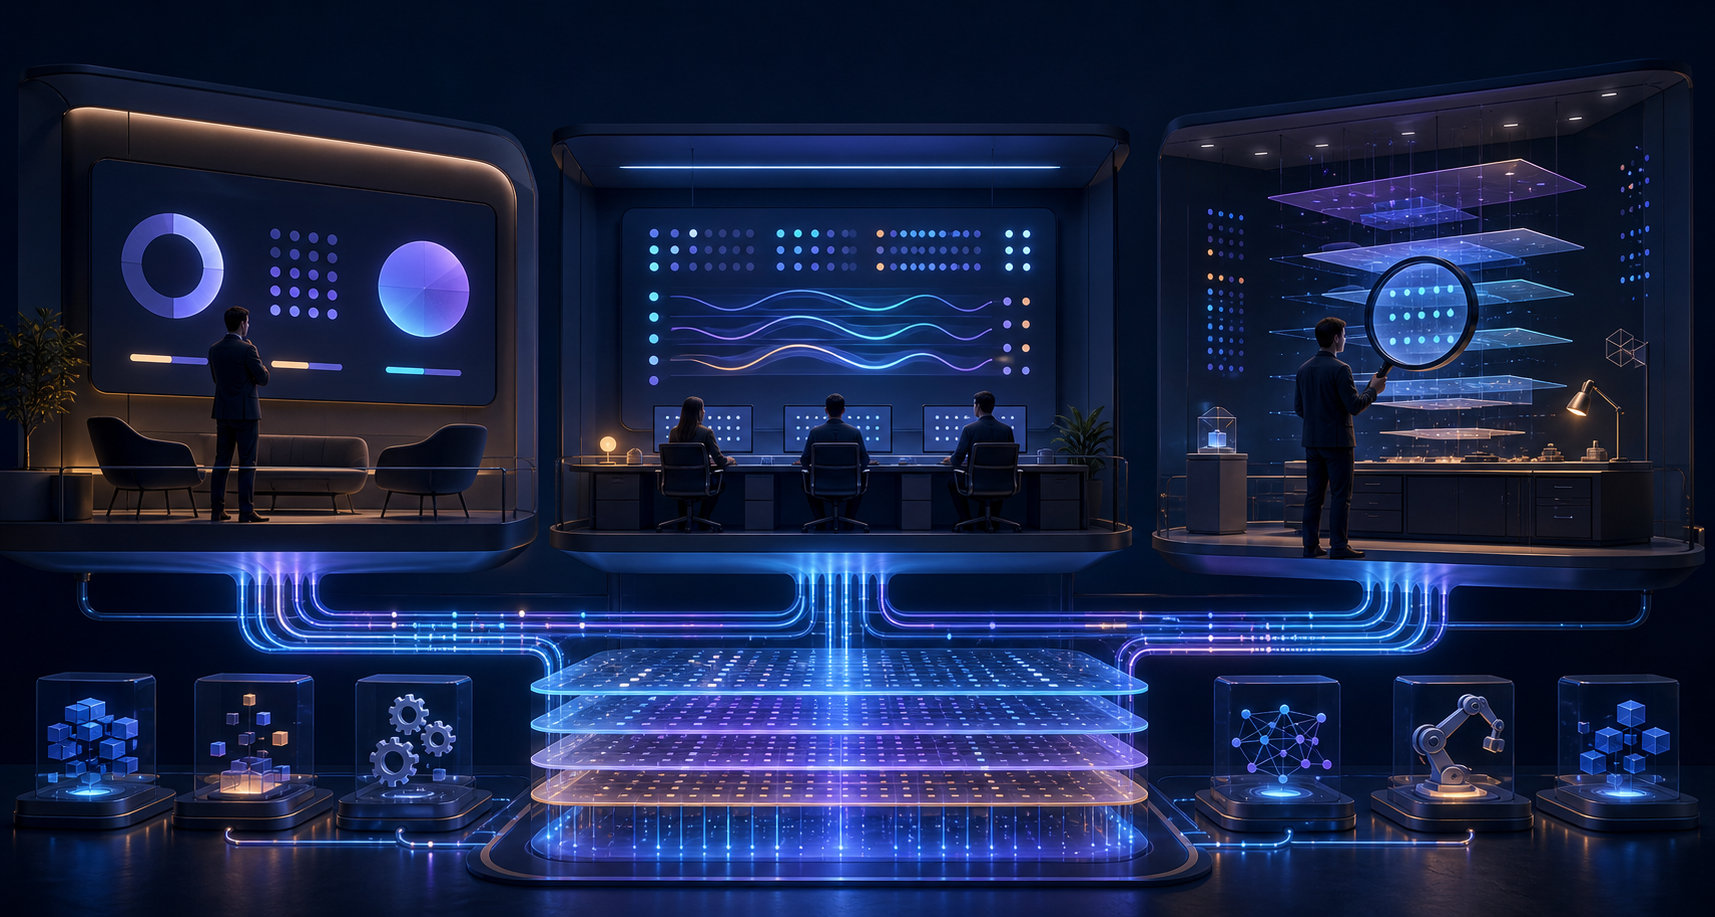
One dashboard should not try to answer every question for every person. An executive wants to know whether the business outcome changed and whether intervention is needed. A channel operator needs enough detail to choose the intervention. An analyst needs access to definitions, segments, and reconciliation evidence.
Build three layers, even if they live in the same reporting product:
Put context next to the metric it qualifies. A global note at the bottom of a long report will not protect a chart at the top from misinterpretation. Each primary view should show its date range, comparison basis, filters, timezone, attribution label, refresh timestamp, and any material gap in coverage.
Add a short narrative block to every decision view:
Be strict about causal language. If a campaign change and a conversion change occurred together, say they coincided unless the measurement design supports a stronger claim. If an experiment or another credible identification method isolates the effect, explain that method. Precision in the wording is part of analytics quality.
Annotations should capture business events that a chart cannot know: a campaign launch, budget change, tracking migration, site release, promotion, pricing change, consent update, or outage. Store the event date, owner, affected scope, and a brief description. An annotation is a lead for investigation, not automatic proof that the event caused the movement.
Distribution needs the same discipline as analysis. A scheduled PDF is a fixed snapshot, so include its reporting window and data cutoff. Link it to the interactive view when recipients may need filters or diagnostics. Archive material snapshots used for recurring business decisions; otherwise a later refresh can leave the team debating a number that no longer appears on screen.
Access is part of report design. Stakeholders should not need administrative access to every marketing platform simply to read an approved result. The reporting team, however, must document which account and permission power each connection. With YouTube Analytics, a report builder who does not own the channel may need Manager permission and the Channel ID entered through the connector’s advanced settings. Test delegated access with the actual reporting identity instead of assuming that a visible channel in YouTube Studio will automatically appear in the reporting connector.
A wholesale reporting rebuild creates too many simultaneous unknowns. Start with one recurring workflow that consumes meaningful time, has a known audience, and regularly produces a decision. A pre-meeting channel report, weekly SEO performance brief, or campaign pacing view is a better migration candidate than an enterprise-wide measurement platform.
The parallel run matters because two reports can display plausible but different numbers. A discrepancy may come from timezone boundaries, attribution logic, late-arriving conversions, deduplication, renamed dimensions, incomplete pagination, or a genuine bug. Matching the old number is not always the goal if the old logic was wrong, but every difference should have an explanation.
Give the finished workflow a runbook. It should tell another qualified person how to trigger a refresh, locate logs, rerun a failed period, backfill data, rotate credentials, verify source totals, publish the output, and roll back a breaking change. Include the last known successful run and the owner of each upstream dependency.
Measure the reporting system itself. Track whether scheduled runs complete, whether data meets its freshness expectation, whether reconciliation tests pass, whether recipients receive the right artifact, and whether decisions and owners are captured. The point is not to create a dashboard about dashboards. It is to notice reliability problems before they become meeting problems.
Choose the recurring report that causes the most avoidable pre-meeting work. Write its decision contract, mark every metric as an outcome, driver, diagnostic, or guardrail, and remove anything that serves no decision. That small redesign will show you exactly where the next improvement belongs: the definition, the data pipeline, the analysis, or the delivery.
Your next prospect may not begin with your homepage, an ad, or even a conventional search result. They may ask an AI assistant to define the problem, compare possible approaches, narrow the field, and recommend a provider. Because AI tools can answer, compare, and recommend without sending the user to a website, your brand can lose consideration before a measurable visit ever occurs.
The practical response is not to abandon awareness marketing. It is to change the order in which you prepare for organic discovery. First make the brand understandable. Then make its claims credible and its expertise easy to retrieve. Only then should you expect AI systems to introduce it confidently. This bottom-up sequence gives your acquisition work a foundation instead of leaving an assistant to infer what your brand is from scattered pages and inconsistent mentions.
People still move through a familiar progression: awareness, consideration, and decision. AI does not remove that progression. It changes who can influence the early stages and what that intermediary needs to know before it will mention you.
That creates two connected sequences:
The second sequence has to be built before it can support the first. An assistant cannot reliably recommend a company when it cannot determine what the company does, who it serves, how its products relate to the category, or whether anyone beyond the company supports its claims. That is why AI-oriented acquisition starts with understanding and credibility, even though the buyer still starts with awareness.
This distinction also prevents a costly overreaction. Paid media, direct outreach, events, and other controlled channels can still create reach. Keep using them when they produce qualified demand. Just do not assume that awareness spend also teaches organic answer engines how to represent you. A memorable campaign can increase human recognition while leaving the underlying entity confused.
Before expanding an awareness campaign, ask three readiness questions:
If any answer is no, the immediate acquisition problem is not reach. It is missing or unreliable information at the layer that produces reach.
Brand understanding begins with facts, not slogans. A buyer may appreciate an expressive positioning line, but a retrieval system still needs unambiguous answers to basic questions: What is this entity? What does it provide? Who is it for? Which problems does it address? Where does it operate? How are its products, services, founders, and parent organization related?
Create a canonical brand fact sheet before editing individual pages. It should record the approved form of your name, a plain-language category description, core offerings, primary audiences, supported locations or markets, important entity relationships, and the claims you are prepared to substantiate. Add the URLs where each fact should appear. Give every field an owner so that a positioning change does not produce five competing versions across the site.
Then reconcile the public surfaces in a deliberate order:
Prioritize incorrect information over missing information. An omitted detail limits what a system can say. A contradiction gives it competing versions to choose from, which can contaminate descriptions, comparisons, and recommendations. Resolve naming, category, audience, and product-relationship conflicts before producing another broad batch of content.
Structured data helps machines identify the type and relationships of information, but it is not a substitute for evidence. JSON-LD can label an organization, service, product, person, or relationship. It cannot make a vague claim credible or repair a visible page that says something different. Treat schema as a precise representation layer over clear, supported content.
You can turn this into a repeatable brand-understanding audit. Ask representative questions using several natural phrasings, inspect the answers, and classify each important fact as correct, absent, ambiguous, outdated, or unsupported. Each classification points to a different fix. Correct errors at the canonical location, add absent facts where they belong, clarify ambiguous relationships, retire outdated descriptions, and remove or substantiate unsupported claims.
This work may feel less visible than a campaign launch, but it is not administrative cleanup. Machines have been forming entity-level interpretations of brands since developments such as Google’s Knowledge Graph in 2012. Generative discovery makes the commercial effect more obvious because those interpretations can now appear directly inside an answer.
Once the entity is clear, examine whether your content can supply a useful answer. Conventional SEO often encourages teams to think in pages: choose a query, publish a comprehensive URL, and earn a ranking. Generative systems may instead retrieve a passage that answers one part of a larger conversation. A page can be thorough and still be difficult to use if the answer is buried under scene-setting, dispersed across tabs, or dependent on context elsewhere.
A retrieval-ready passage usually needs five elements:
The goal is not to turn every heading into an awkward search query or reduce expert material to fragments. The goal is local clarity. If a passage is extracted from the page, it should retain enough nouns, qualifiers, and context to remain accurate. Replace unexplained pronouns such as “it” or “this solution” with the relevant entity or offering where confusion is possible.
Build this content around decisions rather than keyword variations. Cover the questions a buyer needs to resolve: how the category works, when an approach is suitable, when it is not, what requirements apply, which tradeoffs matter, how alternatives differ, and what evidence supports a claim. Comparison content should disclose the criteria and constraints behind the comparison instead of declaring a universal winner.
The technical layer must preserve that clarity. Clean HTML, structured data, directly available content, extraction-friendly sections, and capable on-site search all make it easier for systems to locate and interpret the answer. Important information should not exist only after an interaction that a crawler may never perform. Structured data should agree with the visible text, and headings should describe the section beneath them rather than act as decorative labels.
Use a practical extraction test on every high-value decision page:
If your own search cannot find the answer, the page requires several interactions to reveal it, or the extracted text loses its meaning, fix retrieval before adding more schema. Machine readability begins with information architecture and writing; markup reinforces it.
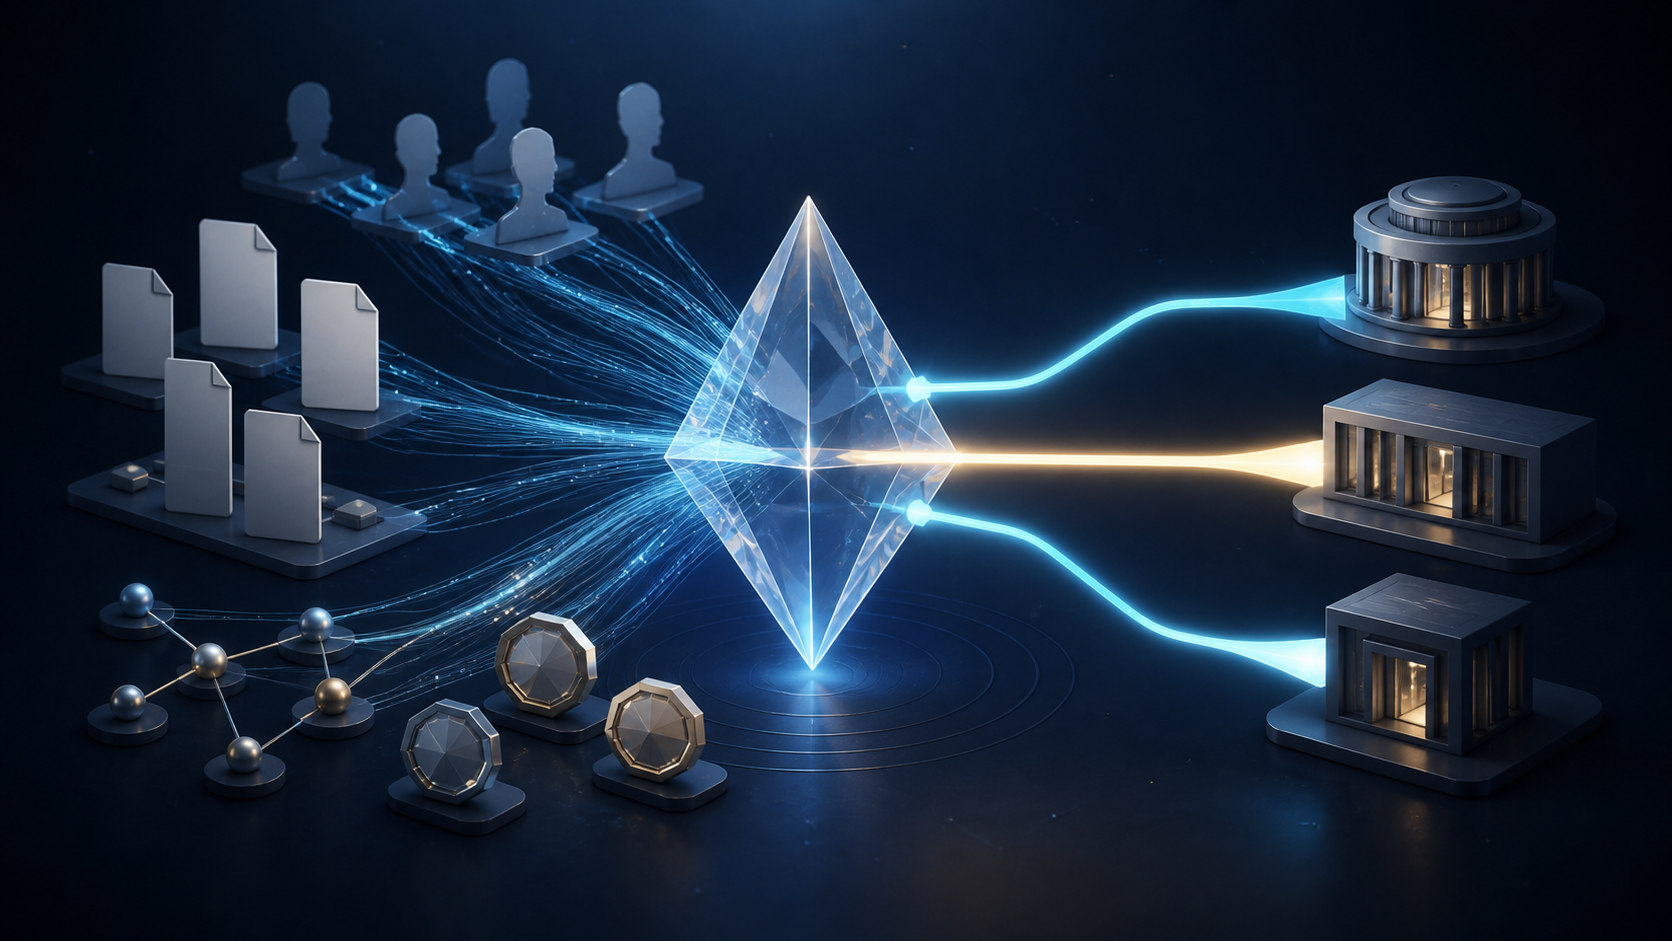
Your website establishes what you say about the brand. External coverage, profiles, discussions, reviews, and partner materials help a system judge whether that description is recognized elsewhere. This is why third-party mentions across publications, communities, Reddit, and social channels belong inside an AI-discovery strategy rather than being treated as unrelated PR activity.
Start with accuracy, not volume. Give PR, partnerships, social, community, and reputation teams the same canonical facts used on the website. Correct important external profiles that use an old name or category. Make current product details easy for partners to reference. Contribute useful, attributable expertise where relevant conversations already happen. Do not manufacture community discussions or seed disguised endorsements; unreliable promotion creates reputational risk and weak evidence.
Do not reduce this work to link building. A brand mention can contribute context even when it is not a conventional backlink, and a linked mention can still be unhelpful when it repeats the wrong positioning. Inspect the wording around the name, the relevance of the domain and discussion, the accuracy of the claim, and whether the mention helps distinguish the brand from similarly named entities.
Traffic alone cannot reveal a decision that ended inside an AI answer. Add a prompt-based observation layer to your existing SEO and acquisition reporting. Build the prompt set from real buyer decisions, not from vanity questions designed to force a brand mention.
For each observation, record the prompt, date, model or interface, whether the brand appeared, how it was described, whether it was recommended, which competitors appeared, and which URLs or domains were cited. Preserve the answer or relevant excerpt so that a later review can distinguish a real change from a reporting mistake.
A simple internal rubric can make the findings actionable:
Do not average a serious error into a visibility score. A wrong product relationship, unsupported capability, or obsolete brand description should become a correction task even when mention frequency is rising. Visibility without accuracy can amplify the problem you need to solve.
The work crosses too many systems to live in an isolated SEO backlog. Brand owners define canonical identity and positioning. Product and subject experts verify claims. Content teams create retrieval-ready answers. Web teams manage rendering, structured data, and on-site search. PR and community teams develop legitimate external corroboration. Analytics teams preserve observations and report changes.
Write a short publishing and maintenance SOP that specifies the canonical fact sheet, required reviewers, passage structure, structured-data checks, third-party update responsibilities, and the events that trigger revalidation. A rebrand, renamed product, changed audience, new market, retired capability, or revised claim should update the website, markup, profiles, partner materials, and prompt observations as one coordinated change.
Assign a decision owner who can resolve conflicts between teams. AI discovery becomes a leadership concern when inconsistent positioning, publishing incentives, or ownership boundaries prevent the organization from supplying one reliable version of itself. Governance, versioning, shared procedures, and new visibility metrics keep the system current after the initial cleanup.
Start with the offering closest to revenue and the buyer questions closest to a decision. Correct its identity gaps, make its answers retrievable, document credible external support, and establish a baseline across the recommendation layer. Expand only after that path is coherent. The result is a brand that can be introduced accurately before the prospect ever knows to search for it by name.
If your Yelp profile gets seen but still produces too few bookings, the problem may no longer be simple visibility. A customer can now ask a detailed question, compare the suggested businesses, and act without following the familiar path from search result to website.
Your job is to make that compressed journey work. Yelp needs clear business facts, customers need credible evidence of fit, and the booking or ordering connection needs to survive the handoff. A weakness in any one of those layers can turn a recommendation into an abandoned transaction.
Traditional local SEO often treats discovery and conversion as separate stages. You rank or appear in a marketplace, earn a click, and then persuade the visitor on your own site. Yelp Assistant narrows that distance because it can answer complex questions, recommend businesses, explain why a business fits, refine the results conversationally, and continue into supported booking, ordering, or quote flows.
That changes the optimization target. A conversational local request usually contains several constraints at once: the service, location, occasion, timing, preferences, and desired next step. A profile can be relevant to the broad category while failing to resolve one of those constraints. The customer may never reach your website to investigate further.
Audit your Yelp presence against four questions:
Build the audit from real customer language. Collect the questions that appear in calls, messages, quote requests, appointment notes, and reviews. Group them by intent, then check whether a person could answer each one from the information visible in Yelp. If the answer depends on an assumption or an old photo, you have found a content gap.
Correct the underlying field wherever possible. Put hours in the hours field, services in the relevant service area, menu information in the menu, and the primary transaction in the appropriate action. Descriptive copy can clarify the offer, but it should not become a container for disconnected phrases. Treat this as an answerability audit, not as a claim that repeating keywords will influence Yelp’s selection logic.
Your website still matters, including its LocalBusiness structured data. Keep the name, address, telephone number, URL, hours, and applicable business subtype aligned with the facts you publish elsewhere. Use a sameAs link when it accurately identifies your Yelp profile. That consistency helps search systems understand the same entity, but JSON-LD on your website cannot repair stale Yelp information or reconnect a broken booking calendar.
A recommendation is not the conversion. The final action may depend on Yelp, your profile configuration, a scheduling or delivery partner, inventory or calendar data, and the confirmation experience. Every connection can look present while still sending the customer to the wrong service, location, or availability view.
Yelp has expanded integrations involving Vagaro, Zocdoc, and Calendly across areas such as beauty, healthcare, and home services, alongside delivery support involving DoorDash. The practical implication is not that every business automatically receives every transaction type. It is that a connected marketplace profile and the external system behind it must be managed as one customer journey.
Test the journey in the environment where customers encounter it:
Test more than the happy path. Try a service that has limited availability, a different location if you operate more than one, and a request that should become a quote rather than an instant booking. The purpose is to find mismatches between what the profile promises and what the connected system can actually accept.
Assign ownership for each layer. The person updating the Yelp profile may not control the scheduling platform, menu, delivery availability, or service calendar. Record who owns each one and where changes originate. Otherwise, a corrected profile can be overwritten by old partner data, or the profile can continue advertising an option that operations no longer fulfils.
The initial feature availability was described as mobile-first on iOS and Android, with broader category and desktop expansion planned. Rollout scope can differ by experience, so verify what customers can actually see instead of assuming that an announcement describes every account, category, or device.
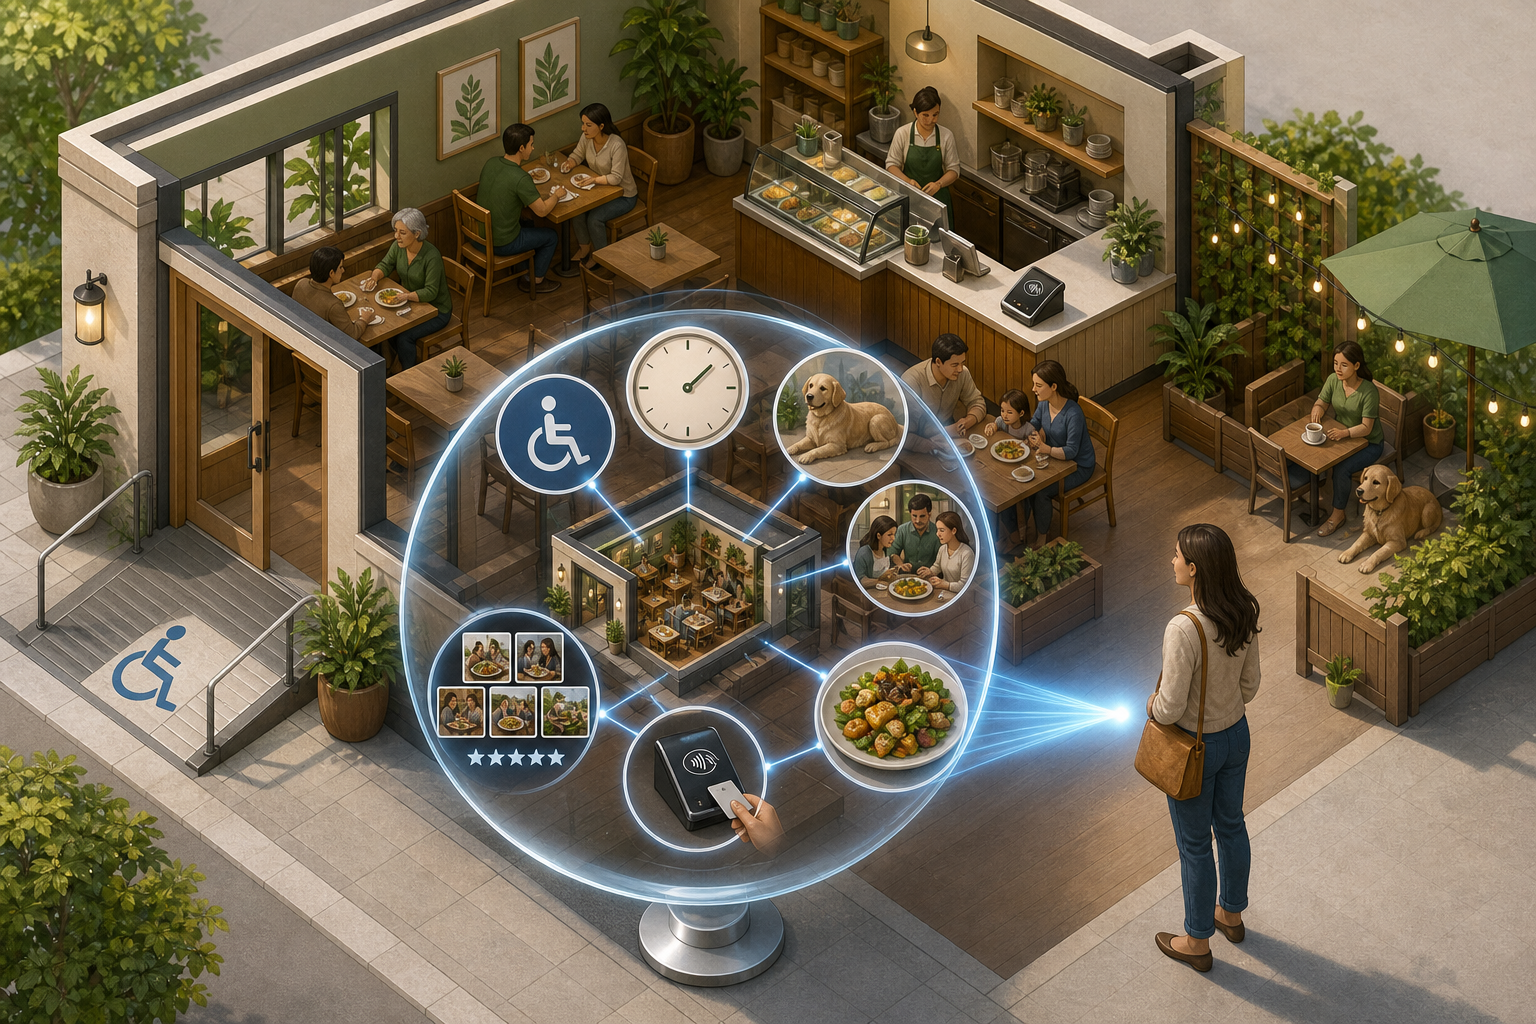
Yelp Assistant draws on Yelp’s reviews and photos to tailor recommendations and explain why a business may be a good match. That makes customer-generated evidence part of the conversion surface. Your description can state that you provide a service; reviews and photos can show what receiving it is like.
Do not translate that into a campaign for generic praise. Broad comments such as great service reveal little about the specific situations in which the business succeeds. Honest reviews are more useful when customers naturally mention the service received, the type of need, the location, and the experience. Any request for feedback should remain neutral and comply with the platform’s current policies.
Use reviews as an operating dataset, not as copy you control:
Photos need a similar job-based audit. Cover the decision points a new customer cannot infer: what the exterior looks like on arrival, what the relevant space or service looks like, what is actually delivered, and how distinct options differ. Accuracy matters more than decorative volume. An attractive image that no longer represents the current offer can create a stronger expectation mismatch than having no image at all.
Restaurants have an additional surface to watch. Yelp’s revised Menu Vision can place dish information, reviews, and photos into visual overlays while a customer browses a menu. Menu item names, current availability, and corresponding images therefore need to describe the same dish. Remove or update obsolete material wherever your listing or connected system gives you control; do not let a retired item become the evidence for a current order.
The same principle applies outside restaurants. A salon service name, healthcare appointment type, contractor quote category, and the evidence surrounding each one should remain consistent from recommendation through confirmation. The assistant can shorten the journey, but it cannot reconcile a profile, photograph, review pattern, and booking system that tell different stories.
If a customer can complete more of the journey inside Yelp or a connected partner flow, website traffic alone becomes an incomplete scorecard. Flat website sessions do not prove that local visibility is stagnant, and more profile activity does not prove that qualified business increased.
Choose the completed outcome that matches the action:
Use the reporting fields available in Yelp and the connected platform, and keep definitions stable. If a partner exposes an origin label or channel field, preserve it through your export or customer-management workflow. If it does not, do not manufacture precise attribution from incomplete data. Record the limitation and compare only metrics that are defined consistently.
Read funnel patterns as diagnostic clues, not proof of a single cause. If profile visibility rises while actions stay flat, start by checking whether the listing resolves fit and presents a clear next step. If actions rise while completed transactions do not, inspect the partner handoff, availability, eligibility rules, and confirmation flow. If transactions rise but cancellations, no-shows, or poor-fit requests also rise, compare the promise in Yelp with what the customer can actually book.
Keep a change log alongside those measures. Record which profile fact, image set, menu item, service name, or transaction connection changed and when. Without that record, several simultaneous edits can make an improvement impossible to interpret and a regression hard to reverse.
A full profile overhaul can hide the problem you need to solve. Start with one commercially meaningful intent: the reservation type, appointment, service request, or order you most need Yelp to support.
The businesses best prepared for AI-assisted local bookings will not necessarily be those with the longest descriptions. They will be the ones whose facts answer the question, whose evidence supports the choice, and whose transaction path does exactly what the recommendation promised. Pick the path tied most closely to revenue or qualified demand, and make that one dependable first.
You want Google Ads automation to remove repetitive work, not remove your control over spend. The problem is that an automated campaign can look efficient inside the platform while attracting weak leads, claiming conversions that would have happened anyway, or scaling a creative idea that has never proved incremental value.
The answer is not to choose between manual management and full autonomy. Build a control system in which machines execute within explicit boundaries, experiments establish causality, and a person remains accountable for the objective, economics and exceptions.
Automation is not one switch. Bidding, budgets, keyword or query expansion, audiences, creative, campaign construction and landing-page testing are separate control layers. Give each layer its own permission, boundary and owner.
Some commercial platforms are marketed as handling campaign builds, bids, ad copy, keyword expansion, landing-page experiments and reporting. That feature scope is a vendor claim, not independent evidence that full autonomy will improve profit or generate incremental demand in your account. Evaluate the decision rights behind the feature list.
| Control layer | What automation may do | What you must define | When to pause it |
|---|---|---|---|
| Conversion measurement | Receive events and values used for optimization | Which event represents a real business outcome and how its value is calculated | Tracking breaks, duplicates appear or the mix of conversion events changes unexpectedly |
| Bidding and budget | Adjust bids and allocate spend within approved campaigns | Maximum acceptable acquisition cost, minimum acceptable return and hard spending limits | Spend or unit economics moves outside the approved boundary |
| Queries and audiences | Explore demand patterns and expand reach | Markets, exclusions, customer fit and intent boundaries | Traffic drifts toward irrelevant intent, excluded regions or low-value prospects |
| Creative | Assemble, rotate or test approved assets | Claims, tone, brand rules and the hypothesis being tested | A policy or brand risk appears, or simultaneous changes make the test uninterpretable |
| Landing pages | Route traffic or test approved variations | Permitted page elements, data handling and the required user journey | Forms, tracking, consent mechanisms or essential page functions fail |
Write these boundaries before connecting a tool that can make changes. At minimum, your operating brief should contain:
<!– wp:list {
You can have AI finding topics, another tool drafting copy, and a CMS waiting at the end, yet still spend most of your time repairing handoffs. The idea loses its original purpose, evidence disappears during drafting, and the CMS entry arrives without the context an editor needs to approve it.
The fix is a controlled workflow in which every stage produces a clear artifact for the next one. Discovery should become an evidence-backed brief. The brief should constrain drafting. The approved draft should map cleanly into CMS fields. Publishing should happen only after editorial, technical, and discovery checks pass.
Treat AI-mediated discovery as a reasoning layer in which original insights and citations shape visibility. That changes the unit of work. A keyword is not enough. You need to identify a question, the situation behind it, the missing answer, and the contribution your page can make.
A useful discovery record should answer the following before anyone opens a drafting tool:
This record prevents a common failure: a discovery system finds a promising theme, but the production team receives only a phrase such as “AI content workflow.” That phrase does not explain who needs the content, what problem is unresolved, or why another page deserves to exist.
A production-ready opportunity is much sharper: a content lead wants to move AI-discovered questions into a CMS without allowing unreviewed copy to publish, and needs a field map, approval states, and quality gates. That statement gives the writer a job to complete. It also gives the editor a basis for rejecting a draft that drifts into a generic discussion of AI writing.
Group related questions by reader decision rather than by shared wording. Questions about choosing a workflow, configuring it, approving output, and diagnosing failures may contain overlapping terms, but they belong on the same page only when they help the same reader complete the same job. If they represent different decisions, give them separate discovery records.
Reject an opportunity when nobody can name its distinctive contribution. “We should cover this because competitors do” is not a contribution. Neither is “AI can write it quickly.” Speed lowers the cost of producing a redundant page; it does not give that page a reason to be discovered or cited.
The brief is the contract between discovery, drafting, review, and publishing. It should preserve the reasoning that made the opportunity worth pursuing. If the brief contains only a title, keywords, and a word-count target, the drafting stage has to reconstruct that reasoning and will often invent the missing parts.
Build the brief around decisions and claims:
The claim map deserves particular care. Classify each important statement as an established fact, an interpretation, an original finding supplied by your organization, a recommendation, or an unsupported hypothesis. These labels can remain internal, but they force the team to apply the right standard of proof.
For each claim, store the exact wording, claim type, evidence URL or internal evidence location, permitted interpretation, uncertainty, and destination section. This makes citation review mechanical. An editor can see whether the evidence supports the actual sentence instead of merely discussing the same general subject.
Original insight does not mean unsupported novelty. It can be a useful synthesis, a clearly explained method, a distinction that resolves confusion, or an analysis grounded in material you are permitted to publish. The workflow should preserve the connection between original insight, citation, credibility, and discovery, not ask a model to manufacture something that merely sounds new.
Give the drafting model the approved brief, claim map, evidence, house rules, and explicit boundaries. A practical instruction is: Use only the supplied evidence for factual claims. Mark missing support as [EVIDENCE NEEDED]. Do not create quotations, figures, examples presented as real, product behavior, or conclusions that the evidence does not establish.
Draft in controlled passes. Generate the answer structure first, then develop sections, then review claim-to-evidence alignment, and only then polish the prose. This makes drift visible. If a section cannot fulfill its assigned reader purpose with the approved evidence, send it back to the brief instead of hiding the weakness beneath smoother language.
Use AI as a challenger after it has been a drafter. Ask it to identify unsupported claims, vague nouns, missing steps, repeated ideas, and recommendations that lack a stated mechanism. Treat those findings as review leads, not automatic corrections. A model can flag a possible gap, but the responsible editor still decides whether the content is accurate and sufficiently supported.
Direct integrations can remove copy-and-paste work. Profound Agents, for example, can read from and write to Framer CMS while moving content from insight into staged CMS items. That is valuable when the integration carries editorial context with the copy. It is risky when “write to CMS” silently becomes “publish whatever the model produced.”
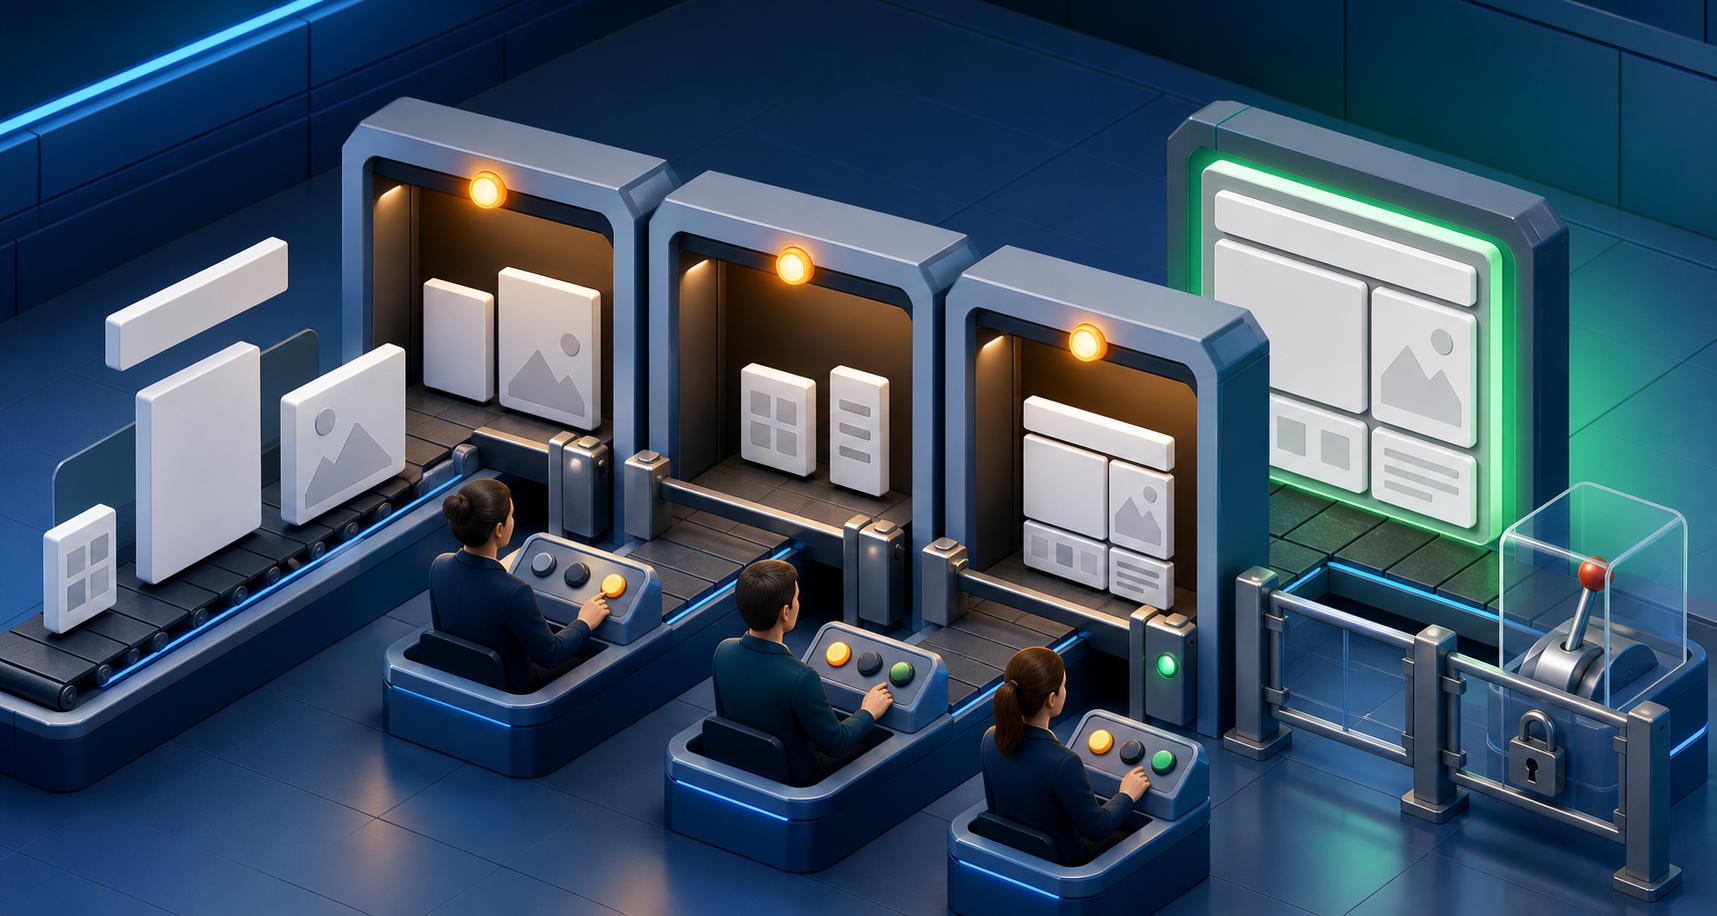
Give every item an explicit workflow state. Each state should define what the automation may do and what a person must approve before the item can advance.
| Workflow state | Required input | Permitted automation | Human gate |
|---|---|---|---|
| Discovered | Question, reader situation, gap, and available evidence | Cluster related questions and populate the discovery record | Confirm that the opportunity represents a real reader decision and has a defensible contribution |
| Briefed | Accepted discovery record | Assemble the production brief, structure, and initial claim map | Approve scope, evidence, uncertainty, and stop conditions |
| Drafted | Approved brief and evidence | Generate and revise copy within the stated constraints | Verify accuracy, usefulness, originality, and claim-to-evidence alignment |
| Staged | Reviewed copy and CMS field map | Create or update the CMS item and fill mapped fields | Inspect the rendered preview, links, taxonomy, metadata, and structured data |
| Approved | CMS item that passed review | Prepare the approved item for its authorized release | Confirm the final URL, publication status, ownership, and timing |
| Published | Live URL | Collect workflow and discovery observations | Decide whether to update, expand, consolidate, or retire the content |
Use a stable content ID from discovery through publication. The connector should update the CMS item associated with that ID rather than creating a new item whenever a job is retried. This is an idempotent write: running the same approved action again reaches the same intended state instead of producing duplicates.
Your field map should distinguish editorial content from workflow control data. At minimum, map the stable content ID, workflow state, owner, working title, public title, slug, excerpt, body, taxonomy, internal links, evidence record, approval status, and structured-data inputs. Keep nonpublic notes and evidence metadata out of public body fields.
Generate JSON-LD from the approved, visible page rather than from an earlier draft. Structured data must not introduce claims, entities, authorship, dates, or relationships that the reader cannot verify on the page. If the body changes after schema generation, send both through the same review state again.
Keep live publication behind a separate permission. Discovery, brief assembly, drafting, linting, and CMS staging are suitable candidates for automation because their output can still be inspected. Acceptance of the original contribution, resolution of contested claims, and release to the public need an accountable owner.
When a connector fails, preserve the last approved state and return a clear error. Do not let a partial write produce a live item with a title but no body, a body with stale schema, or a revised page without its approved citations. Recovery should resume from the failed state, not restart the entire workflow without context.
A polished draft can still fail after publishing. The copy may not answer the target question clearly, the CMS may render it incorrectly, or the most important claim may be too vague to cite. Separate these checks so a general “looks good” approval cannot conceal a technical or evidence problem.
After publication, measure the workflow and the outcome separately. Workflow records can show where work stalls: discovery awaiting evidence, briefs waiting for approval, drafts accumulating revisions, or CMS items failing at preview. Outcome records can capture whether the target question produces a relevant AI answer, whether your brand or URL is mentioned or cited, whether the landing page receives useful visits, and whether those visits support the intended next action.
Do not collapse those observations into a single visibility score. A page can be cited without receiving meaningful traffic. It can receive traffic while attracting the wrong reader. It can also be a useful page that has not yet been surfaced for the question you tracked. Keep the observations distinct so the next action addresses the actual problem.
Feed each diagnosis back into the appropriate stage. Do not respond to every disappointing outcome by generating more content. Sometimes the right action is a clearer answer, better evidence, corrected CMS data, a merged page, or a decision to stop pursuing an opportunity that never had a defensible contribution.
Start with one repeatable content type. Create its discovery record, claim map, CMS field map, and approval states, then run a real item through the entire path. Keep the connector in staging mode until the team can recover from failed writes, explain every status change, and show who approved the live version. Once that path is dependable, you can expand automation without giving up editorial control.
Ever since learning about Google’s latest update to its YouTube and Discover Feed ad requirements, I’ve been intrigued by the clarification on election-related ads. This change, effective April 2026, doesn’t alter enforcement but provides much-needed transparency.
Why it matters. As someone navigating the complex landscape of YouTube and Discover ad placements, I understand how tightly regulated these spaces are. Historically, election ads have been surrounded by ambiguity. Now, the update helps clear up that confusion without imposing additional restrictions.
What’s new (and what’s not). It’s interesting to note that election ads are now clearly exempt from specific YouTube and Discover Feed ad requirements. However, no changes in enforcement mean that if compliance was achieved before, there’s no need for advertisers to shift gears.
Why we care. With this update, I’ve noticed how Google aims to eliminate the haze surrounding election ads on YouTube and Discover. Although these ads don’t need to meet placement-specific requirements, adherence to Google Ads policies remains essential, offering clearer guidance and more predictable campaign launches.
Zoom in. For election ad campaigns, this exemption is beneficial since these ads aren’t required to comply with the targeted YouTube and Discover Feed ad guidelines. However, advertisers must pass the Election Ads verification within the ad’s targeted region.
Between the lines. It’s vital to recognize this as a documentation clarification rather than a policy change. Google is distinguishing between the unique requirements for YouTube and Discover ads and its overarching ads policy framework.
What advertisers should do. If you’re running political campaigns, it’s crucial to maintain your verification status and continue adhering to Google Ads policies. Despite the exemption, keeping up with regulations is necessary for a smooth advertising process.
Dig deeper. For more details, check out the full YouTube and Discover Feed ad requirements (April 2026).
Inspired by this post on Search Engine Land.
Your last successful pitch should not disappear into a sent folder after the coverage lands. It contains a useful asset: a sequence of editorial decisions that persuaded a particular journalist to keep reading, understand the news value, and respond.
The mistake is to copy that email and swap a few nouns. That preserves the most disposable part of the pitch while carrying stale claims, irrelevant personalization, and familiar phrasing into a new campaign. Effective pitch reuse works at a deeper level. You preserve the reasoning structure, replace every campaign-specific input, and make the new email earn its relevance on its own.
A reusable pitch is a framework for making decisions. It tells you what the subject line must accomplish, how the opening establishes relevance, where the strongest evidence appears, how the facts build an angle, and what the call to action offers the journalist’s audience.
That distinction matters because almost half of journalists receive six or more pitches a day. When attention is already scarce, faster production isn’t much of an advantage. A pitch still has to be relevant, credible, and easy to evaluate.
Reuse the parts that govern clarity. Rebuild the parts that determine whether this campaign belongs in this journalist’s inbox.
| Pitch layer | What you can preserve | What you must rebuild |
|---|---|---|
| Subject line | The type of promise, level of specificity, and relationship to the reader | The claim, consequence, wording, and any reference to the recipient |
| Opening | The function it performs, such as establishing editorial relevance before presenting the campaign | The observation, context, and reason this journalist is a fit |
| Angle | The logical progression from finding to consequence | The actual news, audience implication, and timing |
| Evidence | The order in which proof becomes useful | Every fact, figure, comparison, method note, and supporting asset |
| Call to action | A low-friction decision focused on editorial value | The deliverable, access, expert, visual, dataset, or next step being offered |
Personalization deserves particular care. You can reuse the principle that the opening should feel written for one recipient. You cannot reuse the personal detail itself. A reference to someone’s interests, work, or public comments should be accurate, current, proportionate, and connected to the pitch. If the detail has no editorial purpose, it can feel ornamental or intrusive rather than thoughtful.
The same rule applies to tone. Preserve your recognizable voice, but don’t preserve sentences simply because they once worked. Voice is a set of choices about directness, rhythm, detail, and restraint. Copy is the temporary expression of those choices.
A reply or placement tells you that the whole combination worked in one situation. It doesn’t prove that the subject line, personal opening, evidence order, or call to action caused the result by itself. The story’s strength, the journalist’s schedule, an existing relationship, and timing may also have mattered.
Treat the first extraction as a hypothesis, not a universal template. Your job is to identify the likely functions inside the pitch and then see whether those functions remain useful in another campaign.
The resulting blueprint might look like this:
This is more useful than a fill-in-the-blank email. It preserves editorial logic without encouraging the sender to treat a journalist’s name as the only variable.
AI is well suited to mapping sentence functions, proposing alternative phrasing, and adapting a proven sequence to a new brief. It is poorly suited to deciding what is true, whether a personal reference is appropriate, or whether the angle genuinely fits a journalist. Those decisions need verified inputs and human judgment.
Give the model a controlled packet rather than asking it to write a pitch from the campaign name alone. That packet should contain the approved campaign brief, verified fact sheet, methodology notes where relevant, available assets, audience definition, house-voice constraints, and a short recipient profile based on public professional information. Clearly distinguish confirmed facts from working ideas.
Reusable prompt: Analyze the successful pitch below by sentence function, not by wording. Create a structural map that explains the purpose of each part. Then adapt that structure to the new campaign brief and recipient profile. Use only facts supplied in the verified fact sheet. Do not carry over names, claims, figures, personal details, examples, or distinctive phrases from the successful pitch. If the new material cannot support a structural element, mark it as [NEEDS INPUT] instead of inventing content. Return the structural map, a concise draft, alternative subject lines, a substitution ledger showing which supplied input supports each factual statement, and a list of relevance or accuracy risks for human review.
The substitution ledger is the important part. It turns review from a vague question about whether the email sounds good into a traceable check: where did this claim come from, is it approved, and does it mean what the draft says it means?
Keep generation and personalization separate. First ask AI to build the cleanest version of the campaign argument. Then add recipient-specific context after checking the journalist’s current beat and work. This makes it easier to remove generic flattery and prevents an attractive personal hook from concealing a weak editorial match.
Before keeping a personalized opening, apply a simple relevance gate:
AI can also help challenge the blueprint. Ask it to identify sections that depend on the old campaign, places where the logic no longer holds, and phrases likely to sound mass-produced. The goal isn’t to force every new pitch through the old shape. It is to notice when the proven structure helps and when the new story needs a different route.
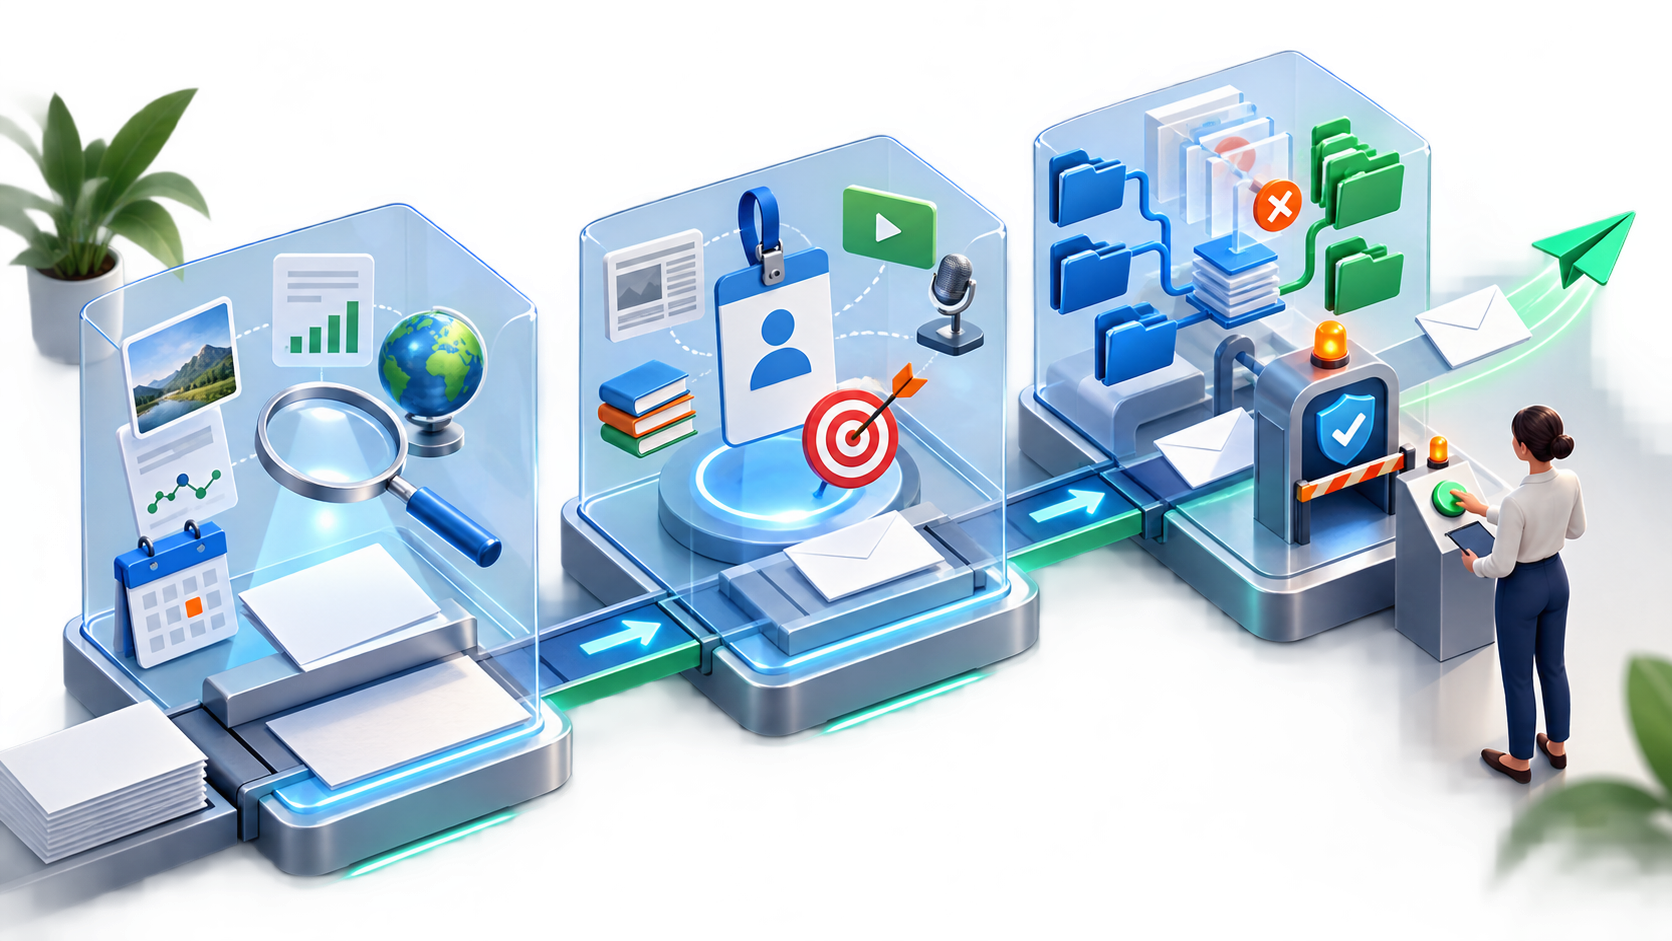
A polished draft can still fail in three different ways: it can misstate the campaign, mismatch the recipient, or reveal that your template is spreading stale language across the outreach program. Review each level separately.
A good pitch library therefore contains more than examples labeled successful. It contains versioned patterns, the situations in which they were used, the evidence available at the time, and notes about what remains uncertain. That context is what allows a team to learn instead of merely imitate.
It also protects your voice. If different team members can see the reasoning behind a pitch, they don’t need to mimic one person’s sentences. They can make the same kind of editorial choices in language that suits the new campaign.
Before your next campaign, open the last pitch that earned a meaningful response and replace its sentences with labels describing what each one did. Save that map beside the original, then build the new outreach from verified inputs. You will start with something your team has learned from without making the recipient feel that they have seen it before.
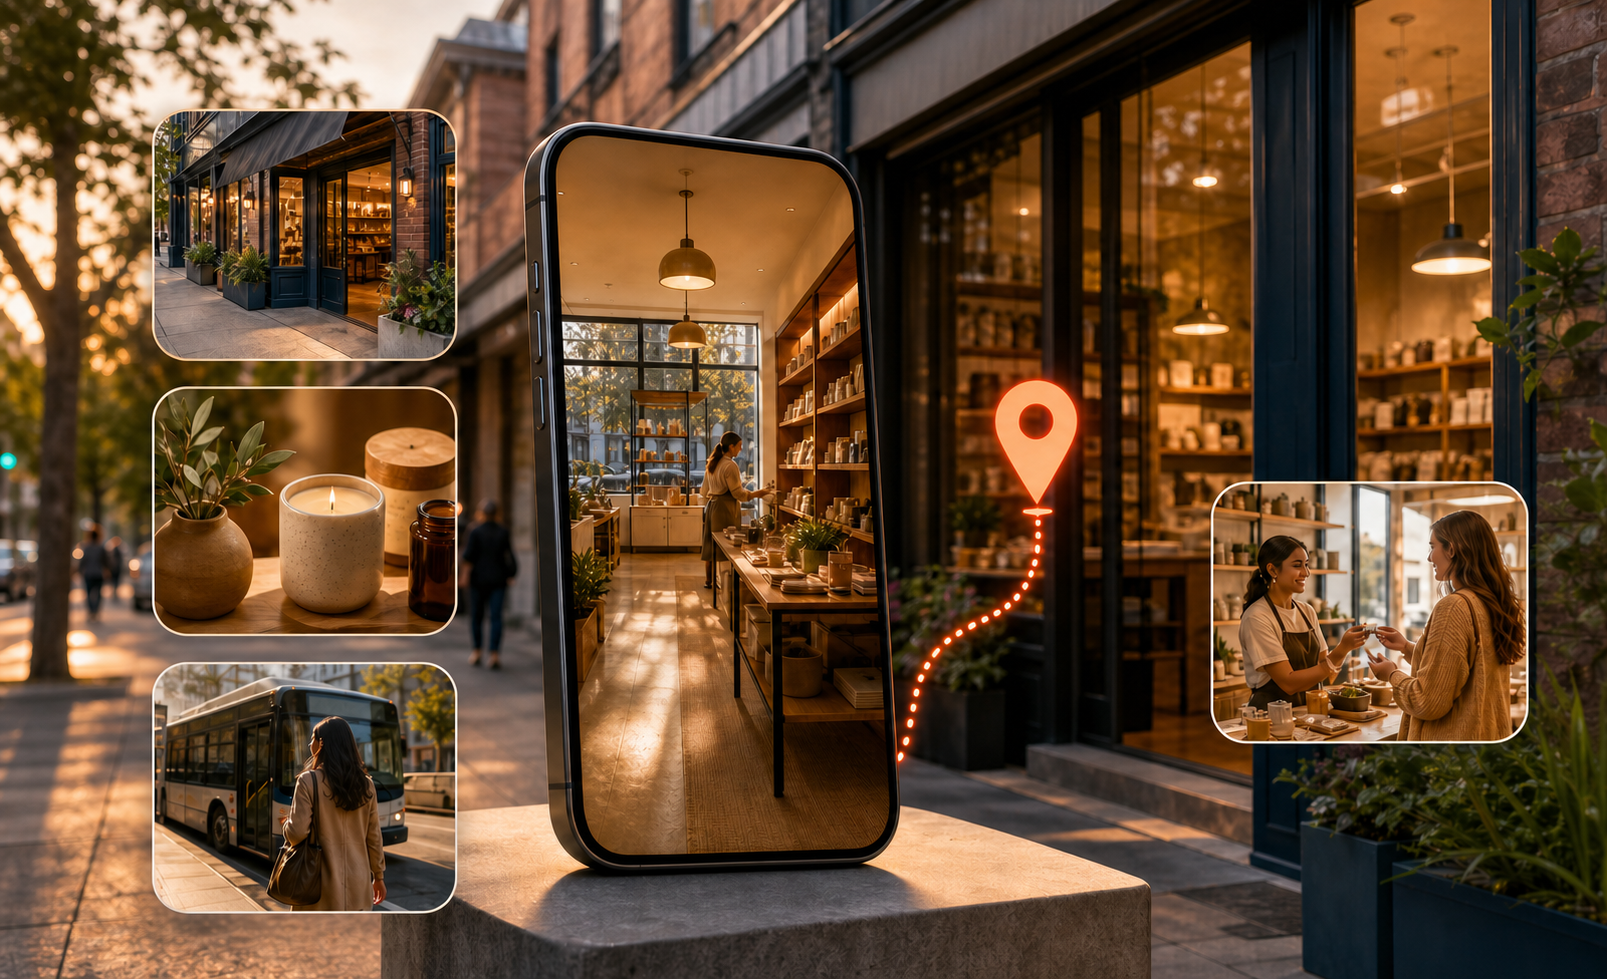
If you advertise physical locations, Google’s local video experiment puts a practical decision in front of you: prepare visual assets now, or wait until the format is more established and rush production later. You don’t need to gamble your local budget or commission a polished brand film to get ready.
The useful move is to build a small, reusable creative system around proof of place. Show what a nearby customer needs to see, connect each asset to the correct location, and test it against business outcomes. That approach remains valuable even while access to the emerging placement is uncertain.
Google has been testing video ads inside the local pack through an immersive, map-style experience. This puts paid visual creative in a context where the user is already comparing nearby businesses. The format is still preliminary, and its performance against conventional local ads hasn’t been established.
That context changes the creative brief. A general brand montage may look polished but still leave the local decision unanswered. Your video should help the viewer confirm that this is the right place, understand what is available there, or feel confident about the next step.
Give each asset a clear local job:
Don’t force every job into the same edit. A short asset focused on finding the entrance can be more useful than a compressed tour of the brand, building, staff, services, offers, and history. If the customer uncertainty is specific, the creative answer should be specific too.
Use a brief that can fit on a small card. Complete these fields before opening a production tool:
A useful brief might be as simple as showing a first-time visitor where to enter and then sending them to that location’s booking page. It doesn’t need a cinematic concept. It needs continuity from search, to image, to arrival or conversion.
Keep that promise location-specific. If footage shows the flagship branch’s amenities while the ad is attached to a smaller branch, the creative may win attention by creating an expectation the business can’t meet. Treat location accuracy as part of ad accuracy, not as a final production check.
The reported implementation appears connected to Google Ads Location Manager and may involve a pre-opted control in the Shared Library. Because the placement is experimental, you shouldn’t assume that uploading a video makes an account eligible, that every account exposes the same controls, or that an asset will appear in the local pack.
Before changing a setting or adding assets, create a record of the current configuration. That gives you a clean way to distinguish a creative change from an account or location change.
An unfamiliar pre-enabled setting isn’t a reason to switch the entire account on or off. Use the smallest reversible scope the interface allows, and confirm which locations are included. The downside of a mismatched local ad isn’t merely a weaker click-through rate. It can send a customer toward the wrong branch, offer, entrance, or service.
Also separate inventory from eligibility. Having an approved video in the account means you have an asset available; it doesn’t prove that the experimental local format served it. If delivery doesn’t occur, investigate placement access, campaign configuration, location linkage, and asset status before declaring the creative ineffective.
Google Ads Asset Studio, available through Google Ads > Tools > Asset Studio, can manage visual assets and turn supplied images into video variations. AI-assisted features such as Veo and Nano Banana can make simple animation and versioning more accessible when you don’t have a full production workflow.
Speed is not the same as direction, though. Asset Studio has shown limited scene-level control, errors involving face-like content, and constrained audio choices without custom-track uploads. Those constraints matter most when your concept depends on exact motion, a human performance, precise pacing, or a distinctive soundtrack.
Use the tool as a production lane, not as the owner of your creative strategy. Decide what must be shown before generating anything, and choose the production route according to how much control the idea requires.
| Creative requirement | Recommended starting route | What to verify |
|---|---|---|
| Simple motion from accurate location or product images | Asset Studio template or AI-assisted generation | Signs, architecture, product details, sequence, and location identity |
| Exact scene order, movement, or pacing | A manually edited master | Every required shot survives the final placement treatment |
| Human-led demonstration or testimonial | Approved original footage, with Asset Studio used only where the input is accepted | Identity, consent, facial integrity, gestures, and spoken claims |
| Custom music or a tightly timed audio concept | External production or editing | Audio rights and whether the visual story remains understandable without relying on the score |
| Fast variations of a stable concept | Asset Studio trimming, templates, or image-to-video tools | Each version still represents the same location and offer accurately |
Start with a library of accurate source material rather than a single finished video. Capture or collect the exterior, entrance, arrival path, interior, product or service detail, staff activity where appropriate, and a clean ending image. Label every file by location and keep its usage approval with it.
Then storyboard the sequence outside the generator. This can be plain language: establish the place, show the relevant proof, and support the next action. The storyboard becomes your acceptance test. If a generated version changes the order, invents a feature, deforms a sign, alters a product, or obscures the local proof, reject it rather than trying to justify the output after production.
Keep original images and edited masters outside Asset Studio as well. A modular library lets you rebuild the ad when placement requirements change, a location is renovated, an offer expires, or the generator can’t reproduce an acceptable version. It also prevents the generated file from becoming the only surviving copy of your creative.
If the available audio choices don’t fit, simplify the concept instead of attaching unsuitable music. The visual sequence should communicate the local point on its own. If sound is central to the idea, move that concept into a workflow that gives you the necessary audio control.
Performance for the emerging local format remains unclear, while easier production can create more assets than a team can evaluate responsibly. The right question isn’t whether Asset Studio produced a video quickly. It is whether the creative improved conversions, sales, or another meaningful campaign outcome without compromising accuracy.
Set up the test so you can make a decision when the data arrives:
Use the pattern in the data to decide what to inspect next:
Production efficiency is still useful. Templates, trimming, and image-to-video generation can lower the effort required to reach a testable asset. But the time saved in production should be reinvested in location verification, experiment design, and outcome review. Otherwise, automation simply helps you publish weak creative faster.
Start with the location where you can verify the visual promise, destination, and business outcome most cleanly. Build one focused brief, prepare accurate source assets, and document the account state before launch. That gives you a controlled pilot without betting the wider local program on an unproven placement.
Your ranking report looks healthy, but organic visits are slipping. That gap does not automatically mean your SEO has failed. It can mean that more of the search journey is happening inside an AI answer, featured result, or search-results page before a visitor reaches your site.
Zero-click behavior also predates generative search. Rand Fishkin traces its emergence to around 2011, estimates that nearly half of searches ended without a click by 2016-2017, and puts the current share above two-thirds. Those estimates should not become a universal benchmark for your reporting, but the direction is clear: you need to measure whether your brand influenced the answer, not only whether your page received the visit.
Traditional SEO reporting often jumps from ranking to session to conversion. AI search introduces several observable outcomes between ranking and session. If you skip them, every answer that satisfies a user without a click looks like failure, while every low-quality visit looks more valuable than it really is.
Use a visibility ladder instead:
A mention is not a conversion, and a citation is not revenue. They are upstream signals. Keeping the stages separate prevents you from assigning invented financial value to an AI appearance while still acknowledging that search visibility can exist without a session.
| Visibility layer | What to record | What it helps you decide |
|---|---|---|
| Answer exposure | Presence in AI answers, AI Overviews, featured snippets, and other answer surfaces | Whether your content is entering the visible answer set |
| Attribution | Brand mentions, citations, links, cited URLs, and the context surrounding the mention | Whether the platform connects the information to you |
| Site engagement | Search impressions, click-through rate, AI referral visits, deep-link landings, and useful on-site actions | Whether the visible answer creates a reason to continue |
| Brand demand | Branded searches, direct visits, returning visitors, subscriptions, and preferred-source selection where available | Whether repeated exposure is becoming intentional demand |
| Business outcome | Qualified leads, purchases, subscriptions, renewals, or another agreed conversion | Whether the search program contributes to the organization |
Do not collapse these measures into a single visibility score unless every weight has a defensible business meaning. A composite score can rise because mentions increased while qualified visits disappeared. A stage-by-stage dashboard makes that tradeoff visible.
The wrong response to zero-click search is to conceal the answer and force the user to hunt for it. That weakens the page for the person who does visit and makes its central purpose harder to identify. The stronger model has two layers: an answer layer that can stand on its own and a continuation layer that helps the reader make a decision or complete a task.
Start the relevant section with the conclusion, definition, instruction, or status the query requires. Name the subject explicitly. State important scope conditions beside the claim instead of hiding them in a distant caveat. A reader and an answer system should not need to combine several vague paragraphs to work out what you mean.
This is the practical value of utility content: service-oriented explanations, checklists, FAQs, and comprehensive guides answer immediate audience questions in a simple form. Simple does not mean thin. A short answer can be clear while the rest of the page handles exceptions, evidence, consequences, and application.
An answer surface can usually absorb a definition, a short explanation, or a basic checklist. It is less able to replace the work that comes after the answer. That is where your page should become more useful.
Do not add length merely to manufacture a click. A long generic page gives an AI system more interchangeable language without giving the reader more value. The continuation layer should resolve uncertainty that remains after the top-line answer.
This also changes how you manage evergreen content. Keep a working inventory of the questions each page owns. Watch the events that could invalidate an answer. Refresh the relevant explainer when the facts change, create content only where a genuine question remains uncovered, and consolidate overlapping pages into a maintained topic library. Recirculate the useful resource when demand returns. Evergreen should describe the question, not an assumption that the answer never needs attention.
Passage-level visibility matters when a search result sends the reader to a specific section rather than the top of the page. Google’s read-more snippet links make that path possible, but the destination has to survive the load process. The first test is not whether the section exists in your content management system. It is whether a visitor following the deep link can see the intended passage immediately.
Google’s published implementation advice is concrete: keep the destination content visible, avoid JavaScript that takes control of the user’s scroll position during page load, and preserve the hash fragment when using the History API or changing window.location.hash.
Treat structured data the same way. JSON-LD should clarify the entities and relationships already supported by the visible page. It should not introduce answers, authorship, reviews, dates, or other claims that a visitor cannot verify in the content. Valid markup can improve machine readability, but validation alone does not guarantee an AI citation, a rich result, or a ranking.
Your final quality check should follow the user’s route: search result, deep link, visible passage, supporting detail, and next action. A technically valid page can still fail if that route breaks after the click.
Generative answers are not fixed search listings. The same or similar request can produce different wording, citations, and omissions across attempts. That variability makes a single screenshot useful as evidence of an occurrence, but weak as evidence of reliable visibility. A more defensible process repeats prompts and looks for consistent patterns across the outputs.
The pattern matters more than any isolated metric. If search impressions remain strong, clicks decline, and attributed AI appearances become more consistent, zero-click consumption is a plausible explanation. Protect the accurate answer while improving the reason to continue. If rankings hold but your brand rarely appears in answer surfaces, inspect the directness, scope, freshness, entity consistency, and passage accessibility of the page before producing more content on the same question.
If citations increase but qualified actions do not, inspect the query and landing experience. The content may be visible for an informational question that has little relationship to the business, or the cited passage may answer the question without leading naturally to a useful next step. That is not an argument for making the answer worse. It is a reason to stop treating every impression as equally valuable.
Brand framing deserves its own review. An unlinked but accurate mention can still support recognition. A prominent but inaccurate mention can damage it. Record the surrounding claim, not merely the presence of your name. Where a platform lets users choose preferred sources, inviting an existing audience to select your publication can support future visibility and loyalty, but it should remain a separate measure from organic inclusion.
For your next publishing cycle, choose a commercially meaningful topic cluster and map its visibility ladder before adding more pages. Rewrite the primary answer for clarity, strengthen the continuation value, test every deep link, and add repeated AI observations to the same dashboard as traffic and conversions. You will then be able to distinguish lost demand from changed behavior and make the right fix.