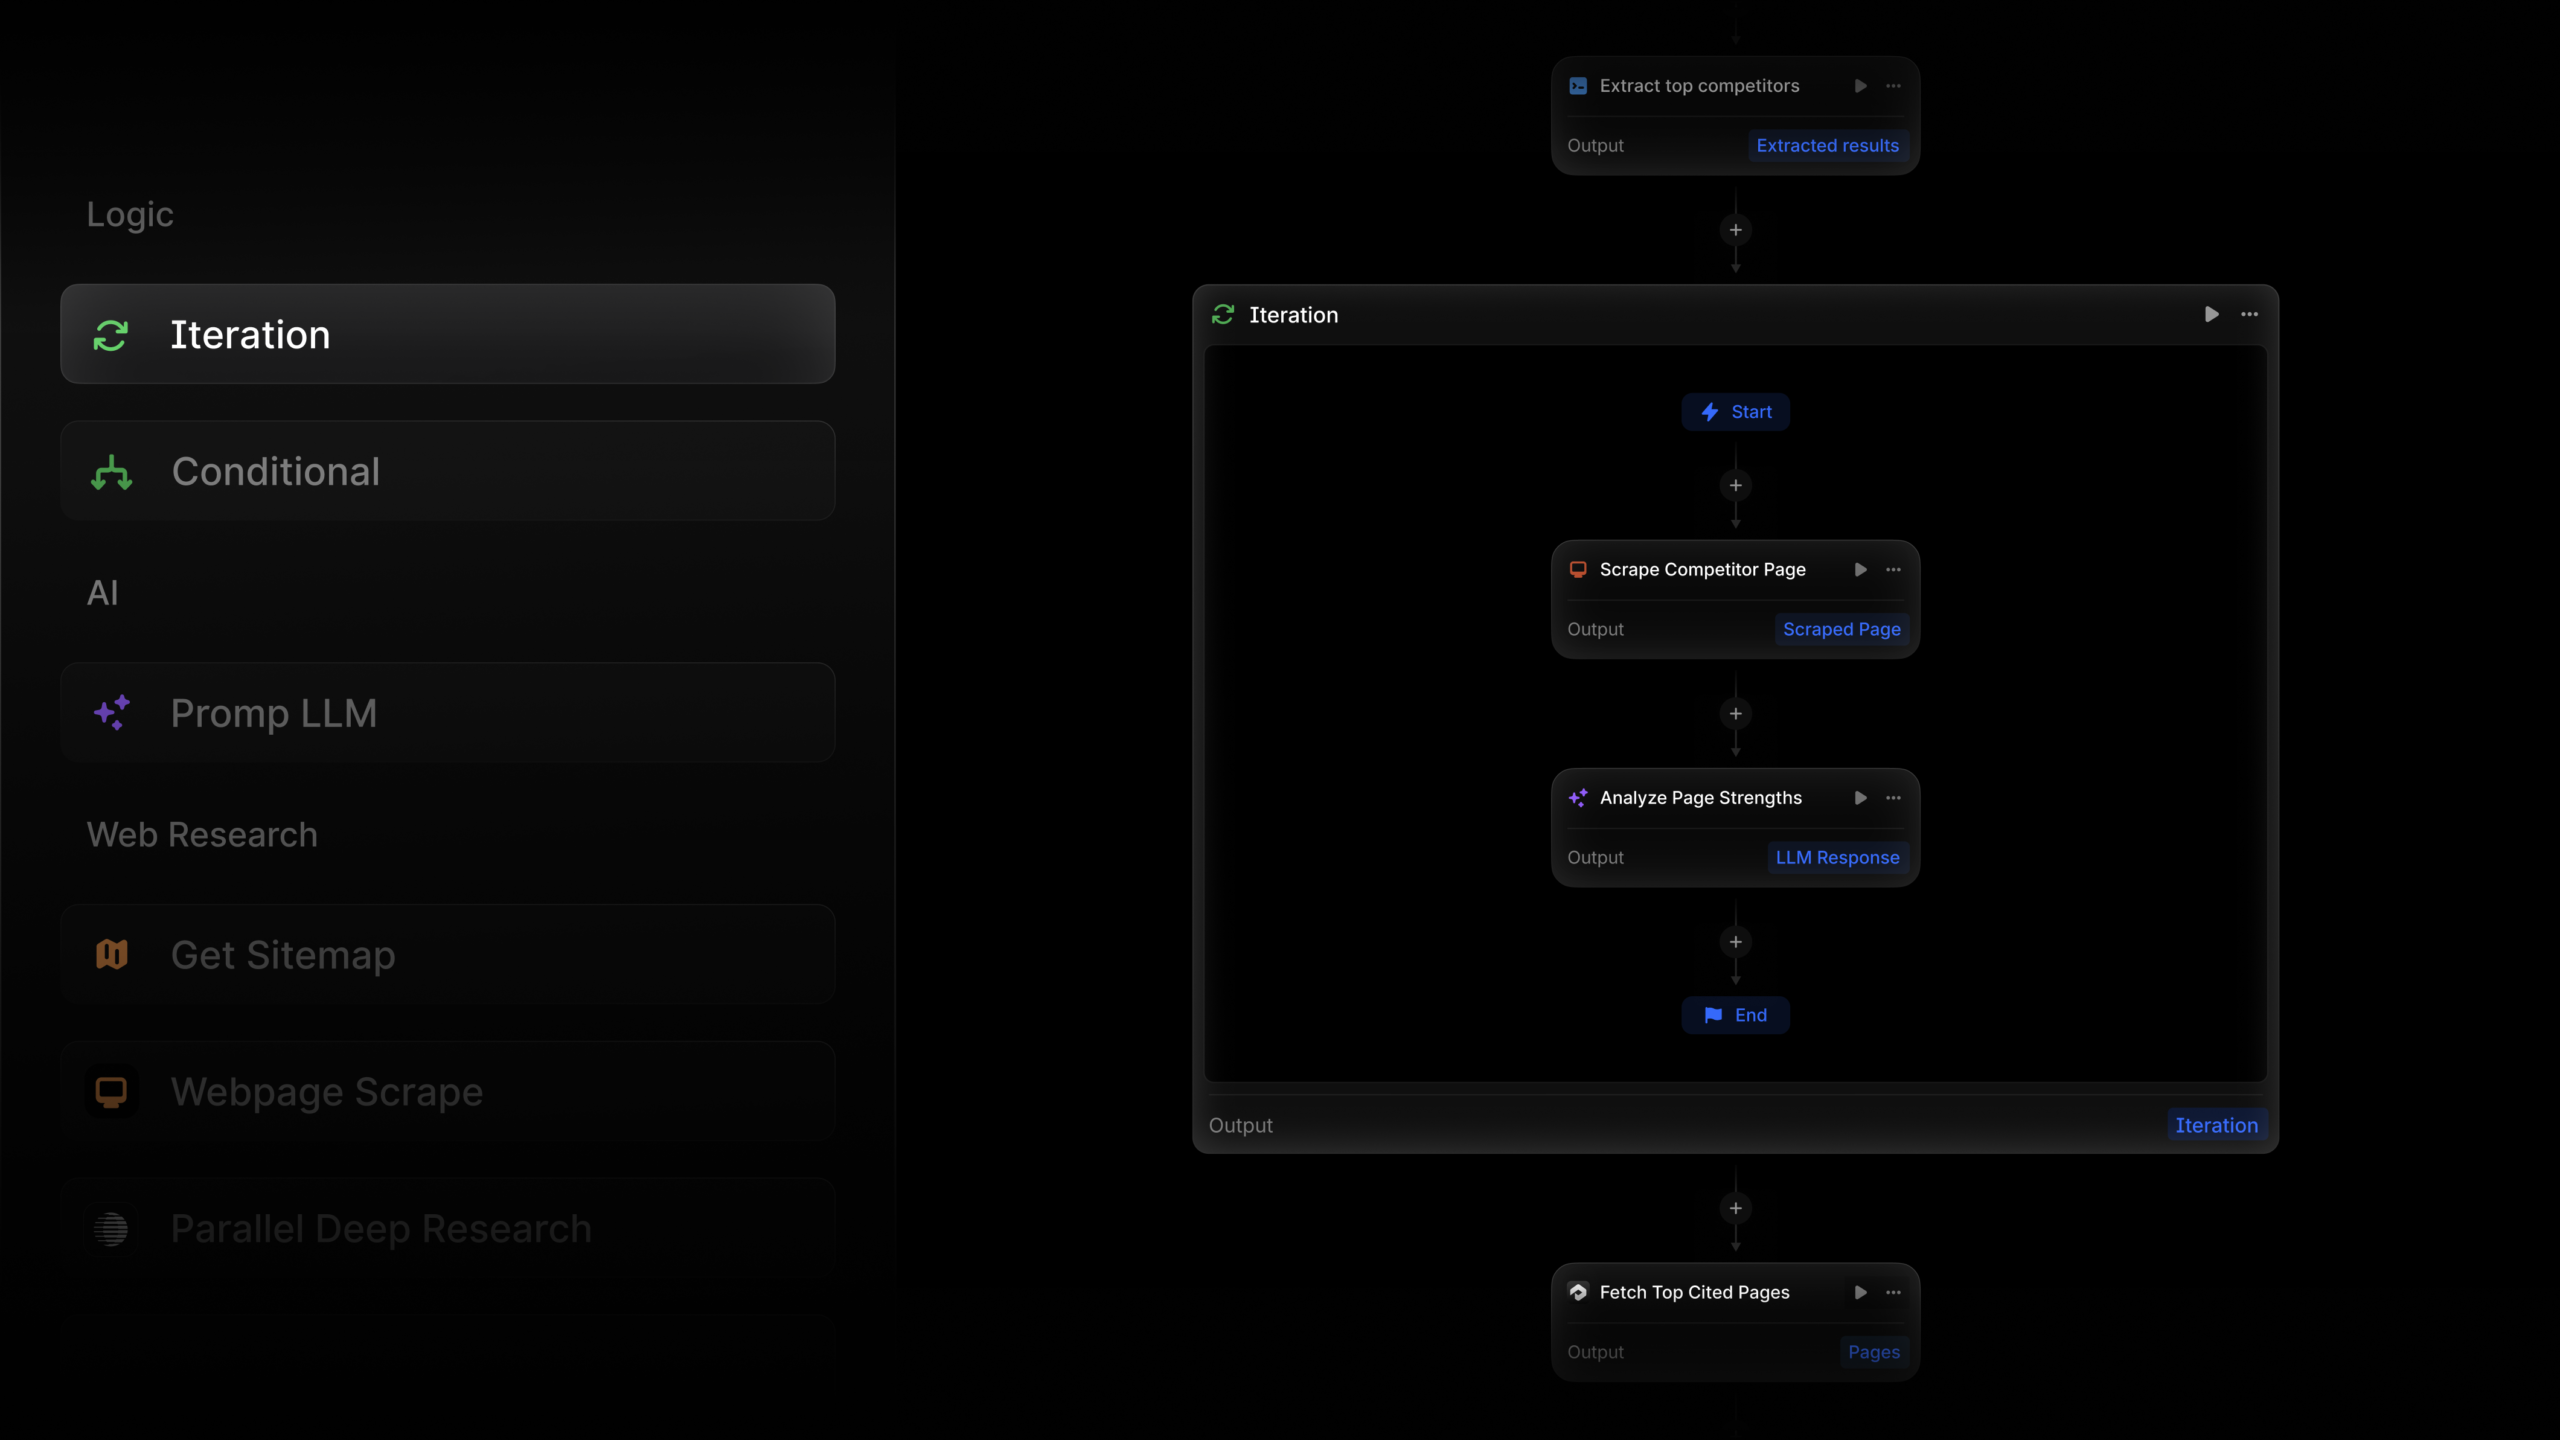
I’m excited to introduce you to the innovative iteration nodes in Profound Agents, designed to revolutionize the way we manage complex workflows.
The beauty of the iteration node lies in its ability to encapsulate a series of steps within your Agent. By setting up these steps just once, I can easily pass in a list of items, and watch as each item seamlessly progresses through the specified sequence, simultaneously.
I’ve recently experienced frustrations with Google Ads as there’s a known issue causing Demand Gen ads to face review delays of over a week. Google acknowledges this problem and assures us that they’re working on a solution.
Some of us advertising on Google have noticed our ads are lingering in review, taking more than seven days—something that deviates from normal review timelines.
What’s happening. Matthew Skelton, a senior PPC specialist I follow, has pointed out a trending issue: Demand Gen campaigns stuck in review for an unexpectedly long time. This delay is noticeable across various accounts and industries, seemingly without any policy breaches causing it.
Interestingly, other campaign types, like Search and Performance Max, aren’t affected and continue processing as usual, which suggests the problem is isolated to Demand Gen ads.
Why we care. For those of us using Demand Gen to test creatives and drive top-of-funnel results, speed is crucial. Long review times hinder our ability to iterate swiftly, delay launches, and make it challenging to respond to seasonal trends or time-sensitive opportunities.
A delay lasting a week can disrupt our pacing and diminish the effectiveness of campaigns relying on rapid optimization.
The response. Ginny Marvin, a Google Ads Liaison, acknowledged this issue specifically impacting Demand Gen image ads, admitting reviews are taking longer than anticipated. She assured us that Google’s team is actively seeking a solution, but no clear timeline has been provided yet.
Bottom line. If you’re experiencing delays with your Demand Gen ads, know that it’s a widespread issue acknowledged by Google rather than something you can directly address.
First seen. This situation was first reported by Matthew Skelton, who shared his insights on LinkedIn.
I recently sat down with Anuj Srivastava to explore the synergy between engineering and marketing when launching a new franchise.
At First Page Sage, I’ve witnessed countless companies pour millions into fleeting algorithm tricks, only to see them crumble overnight. Genuine authority— the type that withstands every Google update and earns citations from ChatGPT—requires true engineering, not quick hacks.
This belief led me to Scott Hietpas, CEO of Computype, a leader in creating the most resilient labels that adhere to any surface and thrive in any environment. While my team focuses on digital permanence, Scott’s team excels in physical identification systems. We’re both tackling the same challenge: ensuring vital information endures when other solutions fall short.
Scott and his company label blood products across North America’s blood supply chain, and odds are, your car tires are marked with their labels too. Their products can withstand temperatures ranging from -196°C to 204°C. If you’re curious why ‘built to last’ isn’t just a slogan but a powerful competitive advantage, read on.
First Page Sage: Many firms promise durability. Why do cheap labels fail, and what are the hidden costs?
Scott Hietpas: Cheap labels fail because they’re not crafted to endure harsh conditions. Adhesives might not suit cold storage, substrates may crack under high heat, and barcodes can fade and become unreadable. A lab might save a cent per label and feel smart, but then spend $200,000 re-labeling specimens after cold storage failures. Similarly, a pharmaceutical company might lose FDA compliance when commodity labels render codes unreadable, halting production. We engineer labels that adhere to any surface—be it glass, silicone, or textured metals—and perform in diverse environments. The price for failing is always catastrophic. Paying a little more for durability is a small price compared to the colossal cost of failure. We assist our clients in assessing their total expenses and minimizing risks.
First Page Sage: What does it take to engineer for extreme temperatures from -196°C to 204°C?
Hietpas: It involves material science that most labeling companies find too intricate. Cryogenic tasks like biobanking need adhesives that don’t crystallize and substrates that don’t shatter when frozen. High-heat needs in tire manufacturing demand polyimide films that retain integrity under thermal stress. Blood services choose our labels for freeze-thaw cycles and international cold-chain transport. Tire producers rely on us for labels that survive vulcanization at 400°F and stay readable throughout the tire’s lifetime. Standard labels fail under these conditions, and our capability to withstand them is why we confidently say our labels perform universally.
First Page Sage: You dominate the global tire bead and healthcare label market. How did Computype become the go-to for critical industries?
Hietpas: It’s our zero tolerance for failure. If a tire maker’s ID system collapses, defect rates spike and costs soar. If blood labels fail, blood shortages and steep replacement expenses follow. These sectors can’t accept ‘just okay’ solutions. Our labels are engineered for permanence, earning trust through undeniable, long-term performance. Millions of our tire and blood bag labels are scanned during production to ensure functionality before leaving our facility. While competitors sell labels, we offer solutions that outlive the products they identify, solving critical problems.
First Page Sage: How does “stick to any surface” work when dealing with challenging surfaces?
Hietpas: Our labels are tailored for specific uses. Medical silicone needs different bonding agents compared to powder-coated steel. Curved glass requires different flow traits than textured surfaces. Instead of universal adhesives, we create custom solutions for demanding surfaces that don’t respond to generic labels. Our engineering understands adhesive-substrate interactions, optimizing for permanent bonding even under stress. When we claim our labels stick to any surface, it’s because we’ve addressed adhesion issues for difficult materials. Our expertise means we offer ready-to-use or customizable solutions that quickly meet our clients’ challenges.
First Page Sage: How do durable labeling and lasting digital authority align?
Hietpas: Both demand thorough knowledge and application understanding. Inexpensive labels may save costs now but lead to eventual disasters. Similarly, black-hat SEO might provide short-lived success but ultimately ruins your rankings. True durability, both physical and digital, entails designing systems for worst-case scenarios—environmental extremes for us, algorithmic turmoil for you. Companies eyeing short savings or growth hacks often lose to those engineering for durability. For over 50 years, our labels have outlasted the competition. Likewise, First Page Sage excels because your authority strategies outlast algorithm changes. Build lasting solutions, or continually rebuild.
Labels that triumph when all else fails. Explore Computype.com for systems designed for extremes—since in critical applications, there’s no second place.
You probably do not need another AI SEO tool. You need to know which recurring job to automate, what evidence its output must meet, and who steps in when the system gets something wrong.
That is the difference between scattered AI experiments and an AI-enabled SEO operation. The goal is not to generate more material. It is to move reliable work through content, analytics, technical SEO, brand and publishing with less friction, while keeping consequential decisions in human hands.
Key takeaways for AI-enabled SEO operations
Start with a business outcome and an existing workflow, not a tool or prompt.
Automate stable, repeatable work only after you understand how it is completed manually.
Use reach, intent, scale and execution to reject AI ideas that will not produce a measurable result.
Give every automation an owner, acceptance criteria, a human escalation path and a manual fallback.
Measure quality and business impact alongside time saved. Faster output is not a win if it creates rework or publishes weak information.
Start with an operating map, not another AI tool
AI adoption often looks like a tooling problem because tools are the most visible part. The harder problem is that SEO work crosses several functions. A content lead may be generating briefs while an analyst builds a reporting assistant and a developer creates a schema workflow. Each project can be useful on its own, yet the combined system may duplicate effort, produce incompatible outputs or leave nobody accountable for the final result.
The practical barrier is usually coordination and integration, not willingness to experiment with AI. Legal needs to understand exposure. Developers need defined requirements. Editors need to know what they must verify. Leadership needs to see how the work affects a business objective. A prompt library cannot resolve those dependencies.
Begin by mapping one complete SEO workflow. Do not start with every task your team performs. Choose a recurring process with a visible beginning and end, such as refreshing declining pages, producing content briefs, reviewing internal links or explaining monthly performance.
Name the outcome. State what should improve: faster refresh decisions, more consistent briefs, fewer unsupported brand claims, better internal-link coverage or less time spent preparing reports.
Define the trigger. Specify what starts the workflow. It might be a scheduled audit, a page crossing a performance condition, an approved keyword cluster or a completed reporting period.
Trace the inputs and handoffs. List the data, documents and approvals required at each stage. Mark where work waits, returns for correction or gets copied between systems.
Assign one accountable owner. Several people may contribute, but one role must own the workflow’s health, approve changes and decide when automation should stop.
Mark the decision points. Separate transformations a machine can perform from judgements a person must make. Summarizing rows is a transformation. Deciding whether a recommendation fits the brand and search intent is a judgement.
Record the baseline. Capture how the workflow currently performs before changing it. Use the measures that already matter: completion time, revision volume, error rate, publishing delay or an associated SEO outcome.
A small workflow register makes this map usable. It should show where AI assists and where responsibility remains human.
Workflow
Trigger and input
AI role
Human decision
Outcome
Content refresh
Performance review and current page
Summarize changes, gaps and candidate updates
Choose whether to refresh, consolidate or leave the page alone
Better update decisions with less audit preparation
Internal linking
New or updated URL plus site inventory
Suggest relevant source pages and destinations
Confirm contextual relevance and approve placement
More consistent link coverage
Monthly reporting
Validated analytics and search data
Surface anomalies and draft observations
Verify causes, add business context and select actions
Less reporting busywork and clearer decisions
Metadata or schema
Approved page facts and a defined template
Generate a structured draft
Verify factual support, syntax and suitability for publication
Faster production without surrendering control
This register also exposes misplaced automation. If an AI step produces an outline before keyword selection is approved, for example, it may accelerate work that will later be discarded. Moving one task faster does not help when the actual delay sits at a different handoff.
Build the automation backlog from work you already understand
The strongest automation candidates are usually hiding inside work your team already performs repeatedly. They have known inputs, recognizable outputs and a reviewer who can explain what good looks like. That makes them easier to test than a new process invented around an AI feature.
Use two tests to identify a candidate. First, ask whether you would confidently delegate the task to a new team member after giving them instructions and examples. Second, ask whether an experienced reviewer could detect a bad output without repeating the whole task. If both answers are yes, AI may be useful for the first pass.
A 70% machine draft and 30% human refinement can be a useful starting heuristic for research and drafting work. It is not a staffing formula or a promise that every task divides neatly. It means the machine handles collection, classification, formatting or an initial draft, while a person supplies judgement, context and approval.
Before putting a candidate in the backlog, pass it through an automation-readiness check:
The manual process is stable. Different team members follow substantially the same steps.
The input is available and trustworthy. The automation will not need to guess around missing page facts, incomplete analytics or inconsistent naming.
The output has a defined shape. A template, field structure or explicit deliverable makes validation possible.
Quality can be evaluated. Reviewers can distinguish an acceptable result from a plausible-looking failure.
Failures will be visible. A malformed output, missing input or unsupported statement will be flagged rather than silently published.
A person owns escalation. Someone knows what to do when the result falls outside the normal path.
The manual path still exists. The team can continue critical work if the model, integration or maintainer becomes unavailable.
Be especially cautious when the required asset does not exist. AI cannot reliably enforce brand rules that have never been documented, fill a content template whose fields are disputed or repair an analytics pipeline with incomplete data. Those are ownership and process problems. Treating them as prompt problems delays the real fix.
Use RISE to reject weak automation ideas early
An automation backlog will grow faster than your ability to implement it. The useful management skill is therefore rejection. A small number of well-integrated workflows will usually create more value than a large collection of clever demonstrations.
Reach is not a vague claim that a workflow affects SEO. Name the inventory, frequency and result. For a recurring task, you can model operational reach as eligible items multiplied by handling time and run frequency. For an SEO initiative, include the pages, query groups or customer questions it can materially affect.
Write down the baseline and the expected movement before implementation. If you cannot identify a numerical business or operational upside, keep the idea in exploration rather than placing it on the production roadmap. This prevents novelty from being mistaken for impact.
Intent: prove that the output serves a real decision
Intent means more than classifying a keyword as informational or transactional. Ask who will use the output, what question it answers and what action follows. An automated content-gap report has little value if nobody has the authority or capacity to commission the missing work. A metadata generator is misplaced if weak positioning, not drafting time, is the constraint.
For content operations, connect the workflow to a defined audience question and page purpose. AI can expand an outline, but a strategist still needs to decide whether the page deserves to exist and what distinct value it should provide.
Scale: look for structural reuse
A scalable workflow does not require someone to reconstruct the prompt, clean the inputs and explain the output every time it runs. It uses repeatable triggers, standardized fields, documented rules and a destination inside the team’s normal systems.
Do not confuse a large batch with scale. Generating thousands of outputs once is volume. Scale exists when the operation can run again, under ownership, without rebuilding the process or accumulating hidden manual cleanup.
Execution: define how the work reaches production
Execution is where promising demonstrations tend to stall. Name the owner, required access, review stage, acceptance criteria and publishing destination. Identify the team that will maintain the workflow when prompts, templates, data fields or business rules change.
A one-page initiative brief is enough to force clarity. It should contain the problem, baseline, eligible inventory, intended user, workflow owner, AI role, human decision, quality checks, expected outcome and stop condition. If those fields cannot be completed, the initiative is not ready for production.
After an idea passes RISE, test it against previously completed work. Historical cases give you an expected result and let reviewers compare the automated output with decisions that have already been made. Only then move to a live pilot, with every output reviewed until the failure patterns are understood.
Make control and measurement part of the workflow
Human review is necessary, but it is not a complete control system. A vague instruction to check the output leaves each reviewer to invent a different standard. Effective QA combines machine-readable checks, explicit editorial criteria and a named person who can approve exceptions.
Design each production workflow as a controlled sequence:
Validate the input. Confirm required fields, data freshness and allowed formats before sending anything to the model.
Run the bounded AI task. Give the system a specific transformation, required output structure and the information it is allowed to use.
Apply deterministic checks. Test syntax, missing fields, duplicates, prohibited terms, unsupported values or other conditions that do not require subjective judgement.
Route the result for human review. Show the generated output with its input and any warnings. A reviewer should not have to hunt for the evidence needed to approve it.
Publish through the normal system. Keep existing permissions and approval controls instead of creating a parallel route around the CMS or engineering workflow.
Log the result and any correction. Record failures, overrides and substantive edits so the team can improve the process rather than correcting the same pattern indefinitely.
The acceptance criteria should match the output. An internal-link recommendation needs a relevant context, a valid destination and an editorially sensible placement. A reporting narrative must reconcile with validated data and separate observation from explanation. Generated schema must be syntactically valid and contain only claims supported by the visible page. A content brief needs a defined intent, usable structure and enough evidence for a writer to proceed without guessing.
Keep the final check personal where the output affects a public page, brand claim or strategic decision. Automating the first pass is useful precisely because it leaves more attention for quality assurance and consequential decision-making. Removing that review to maximize throughput defeats the purpose.
Document the workflow well enough that it can survive a change of maintainer. Include its purpose, owner, trigger, input location, prompt or instruction version, output format, validation rules, reviewer, publishing path and failure response. This reduces the risk of losing both operational knowledge and a critical process when the person who built the automation is no longer available.
Run governance at three different cadences. A weekly cross-functional checkpoint should handle exceptions, blocked handoffs and decisions that cannot wait. A monthly review should compare efficiency, quality and SEO or business outcomes with the baseline. A quarterly roadmap session should decide which workflows to expand, repair, retire or leave manual. Weekly coordination, monthly performance reviews and quarterly roadmap alignment keep ownership active after launch.
Measure the operation in three layers:
Efficiency: completion time, queue age, manual touches and work returned for correction.
Quality: acceptance rate, substantive edit rate, validation failures, false positives and published corrections.
Outcome: the business or SEO measure named when the initiative was approved, such as refresh completion, useful internal-link coverage, reporting decisions or performance of the affected page group.
Do not report time saved without showing what happened to quality and outcomes. An automation that halves drafting effort but doubles review work has shifted the cost, not removed it. Likewise, a workflow can be accurate and still be unnecessary if nobody acts on its output.
Recovered capacity should have an explicit destination. Use it for work AI cannot own: coordinating priorities across teams, investigating why performance changed, improving the customer search journey and deciding which emerging search behaviors deserve attention. Otherwise, the saved time tends to be absorbed by a larger volume of low-value production.
Your next move can be small. Select one recurring workflow, write its one-page operating brief, record the current baseline and test the proposed automation on completed work. If you cannot name the owner, acceptance criteria and failure path, do not automate it yet. Fix those three gaps first, then let AI accelerate a process you can actually control.
Your rankings can look stable while your brand quietly loses ground in AI answers. If you count every citation as a win, you may miss the more important problem: an AI system can cite your page, recommend a competitor, and send you no qualified traffic.
A useful GEO strategy connects four things: the buyer decisions you want to influence, the brand narrative AI systems encounter, the evidence that supports that narrative, and your ability to publish accurate facts quickly. Here is how to build that operating system without getting trapped in formatting tricks or vanity metrics.
Key takeaways
Measure recommendations, not citations alone. Track whether your brand is retrieved, cited, described accurately, recommended, clicked, and chosen.
Prioritize prompts by commercial value. Comparison and question-based searches frequently trigger AI Overviews, while transactional searches are less likely to do so.
Make your category position consistent. Your website, partner profiles, customer evidence, public relations, reviews, and independent coverage should tell a compatible story about what you are and who you serve.
Treat technical GEO as infrastructure. Crawlability, internal links, structured data, and clean templates help machines retrieve facts, but they cannot manufacture authority or third-party validation.
Reduce the time between fact and publication. Pre-approved data fields and schema-locked templates can move factual resources through compliance faster than open-ended marketing copy.
Start with buyer prompts and business outcomes
Do not begin your GEO plan with, “How many times did ChatGPT cite us?” Begin with, “Which buyer decisions should include us, and what does a useful appearance look like at each stage?” That change prevents a citation dashboard from becoming a substitute for commercial visibility.
AI visibility is a sequence, not a single metric. A page can be retrievable without being cited. It can be cited without the brand being mentioned. A brand can be mentioned without being recommended. A recommendation can generate awareness without producing a trackable referral. You need to observe the whole chain.
Visibility layer
Question to answer
Evidence to record
Discoverability
Can the system find a relevant page or fact?
Your domain or page appears among the retrieved or cited material.
Citation
Does the answer use your content as support?
A linked URL, named page, or clearly attributable fact appears in the response.
Representation
Does the answer describe the brand correctly?
The category, audience, capabilities, limits, and differentiators match your verified position.
Recommendation
Does the system present the brand as a suitable choice?
Your brand appears in a shortlist or recommendation with a relevant reason.
Traffic
Does the appearance create a visit?
Referral sessions, landing-page activity, or another defined discovery signal increases.
Business value
Does the visibility influence a useful outcome?
Qualified inquiries, signups, purchases, pipeline, or self-reported AI discovery connects to the prompt family.
Build your measurement set from real decisions instead of broad keywords. Sales calls, support questions, customer interviews, site search, and conventional search-query data can reveal the language buyers use when they are evaluating a category. Convert that language into prompt families such as:
Best products or providers for a named use case.
Alternatives to a known product or approach.
Comparisons between categories, methods, or vendors.
Options that satisfy a constraint such as compatibility, geography, company size, regulation, or budget structure.
Questions about fees, limits, implementation, integrations, eligibility, risks, or switching.
Branded questions that test whether your basic facts are represented accurately.
Test the commercial prompts without putting your brand name in them. A branded prompt mainly measures whether the system can repeat what it already associates with you. An unbranded prompt reveals whether you enter the consideration set when the buyer has not chosen a vendor.
For each run, record the platform or model, date, exact prompt, answer, brands mentioned, brands recommended, recommendation rationale, cited domains, cited URLs, and factual errors. AI answers can vary between runs, so keep the prompt wording and test conditions stable enough to compare like with like.
A simple scoring rubric keeps the review honest. Give citation a binary score: absent or present. Score recommendation separately: absent, mentioned without endorsement, or recommended with a relevant reason. Score representation as inaccurate, incomplete, or aligned. Then report recommendation rate by prompt family alongside citation rate. Do not merge them into a single visibility score that hides why you are winning or losing.
Also separate platforms in your reporting. A result in Google AI Overviews is not interchangeable with a response from ChatGPT or Claude. Track the same prompt family across systems, but evaluate progress within each system before trying to produce one blended number.
Prioritize the searches where AI changes the click path
AI search does not affect every query in the same way. In data covering January 2025 through February 2026, AI Overviews appeared for approximately 95% of comparison queries, 86% of questions, 36% of informational queries, and 5% of transactional queries. Those percentages came from a Seer Interactive analysis of 53 brands, 5.47 million queries, and 2.43 billion impressions. They are a cross-brand observation, not a forecast for every site, but the intent pattern is useful for prioritization.
Comparison and question prompts deserve close attention because the AI response often sits directly inside the evaluation process. Transactional queries still matter, but conventional organic rankings, paid visibility, landing-page relevance, and conversion performance are more likely to remain central when an AI Overview is absent.
Citation improves your position inside an AI result, but it does not restore the click behavior of a search without one. The analyzed pages received approximately 2.1% organic CTR when cited in an AI Overview, 0.9% when not cited, and 3.3% when no AI Overview appeared. A citation was therefore substantially better than exclusion within an AI Overview, while searches without an AI Overview still produced the higher CTR.
The overall CTR for searches containing AI Overviews also rose from 1.3% in December 2025 to 2.4% in February 2026, an 85% relative increase. That rebound is encouraging, but it is not evidence that click loss has ended. A percentage can recover while the AI interface continues to answer many simple questions before the user visits a website.
Use those distinctions to give each query cluster a job:
Recommendation targets: Unbranded comparison, shortlist, alternative, and suitability prompts. Measure whether your brand enters the recommended set and whether the reason matches your intended position.
Citation targets: Questions where a specific fact, table, definition, process, or constraint could support the answer. Measure whether the correct page is cited and whether the fact survives paraphrasing.
Click targets: Queries where the buyer still needs a calculator, configuration tool, full specification, current data, detailed methodology, or transaction. Give the AI answer a reason to send the user to a destination that does more than repeat the summary.
Accuracy targets: Branded questions about pricing, availability, capabilities, policies, integrations, or limitations. Correcting a harmful error may matter even when the prompt produces little traffic.
Conventional search targets: High-value transactional queries that rarely trigger AI Overviews. Do not weaken proven SEO and conversion work merely because the organization has adopted a GEO program.
Review impressions, clicks, citations, recommendations, and conversions together. Falling CTR with rising impressions can mean that your brand is appearing in more AI-generated results, not necessarily that demand has collapsed. Conversely, stable ranking reports can conceal a loss of recommendation share. The right diagnosis depends on the entire query cluster, not one percentage.
Build a brand story the wider web can corroborate
Technical access helps an AI system read your claims. It does not require the system to believe those claims or recommend the brand behind them. Recommendations are shaped by how clearly the brand fits a category and whether multiple credible surfaces support a compatible interpretation.
This is why citation count and recommendation rate can move in different directions. Your resource may be useful enough to support a factual sentence while another brand is presented as the better option. A first-party listicle that ranks your own product first does not create the independent recognition needed to make that recommendation persuasive.
Create a short brand-consensus brief before commissioning more GEO content. It should answer six questions in language that can be checked against evidence:
Recently, I noticed a significant change in Google’s approach to handling spam reports. They’ve updated their stance on whether they’ll process reports containing personally identifying information, and it feels like a big shift from what was communicated just a week prior.
On their updated spam report page, Google now clearly states that any spam report containing personally identifying information will not be processed. This revision comes after their previous announcement that such information could be passed on to the site in question.
Here’s What’s Changed: Google has added a highlighted note on their official spam report page, emphasizing two points:
(1) Avoid including personally identifying information in your spam reports.
(2) If you do include such information, your submission won’t be processed.
Google’s explanation reads:
“Don’t include any personally identifying information in your submission. To comply with regulations, we must send the submission text to the site owner to help them understand the context of a manual action, if one is issued. Because of this, we won’t process your submission if we determine it contains personally identifying information to protect privacy. Not including such information fully ensures your information is safe and prevents your submission from being discarded.”
Previously: Just a week ago, as we documented, Google allowed:
“If we issue a manual action, we send whatever you write in the submission report verbatim to the site owner to help them understand the context of the manual action.”
This policy raised many eyebrows across the industry. Concerns were not just about being flagged for identifying competitors or spammers, but there were also legal implications. It seems Google is now aligning with regulations to avoid sharing personally identifying data.
Why You Should Care: If you’re aiming to submit a spam report to Google, make sure it doesn’t contain any personally identifying information. Should you inadvertently include such information, rest assured that it won’t reach the reported site and the report simply won’t be processed. You can always resubmit your report without these details.
If you’re deciding whether ChatGPT belongs in your paid media plan, don’t treat its advertising expansion as a cue to move budget immediately. Treat it as a cue to become test-ready. The opportunity may be meaningful, but availability, targeting, reporting, and campaign economics still need to be proved.
Your advantage won’t come from being first at any cost. It will come from knowing exactly what you want to learn, what evidence would justify more investment, and how paid placement fits beside your existing SEO, AEO, and generative engine optimization work.
The expansion addresses inventory, not the whole advertising case
Early observations indicate that ads are appearing within conversations for some logged-out users, although OpenAI had not formally announced the expansion. That uncertainty matters. A visible rollout can establish that inventory is growing without establishing who can buy it, which users are eligible, how delivery is priced, or whether the experience is stable enough for forecasting.
The immediate pressure appears to be supply. Pilot advertisers have reportedly struggled to spend their intended budgets because inventory was limited, even after the financial hurdle fell from $200,000 to $50,000. Opening more conversations to ads is a logical way to create additional opportunities for delivery.
That doesn’t automatically make ChatGPT a scalable performance channel. More inventory can help campaigns spend, but it doesn’t prove that the added impressions will produce qualified traffic, incremental customers, or acceptable acquisition costs. Logged-out reach could also differ from logged-in reach in ways that affect relevance and measurement. Until the buying interface or your agreement provides the details, don’t assume the platform can recognize, target, exclude, or report on these two audiences in the same way.
Keep ChatGPT out of your dependable base forecast for now. Put it in an experimental budget with its own success criteria and loss limit. That protects the budget you already rely on while giving you room to learn if access becomes available.
Key takeaways
Wider logged-out reach may relieve an inventory constraint, but it doesn’t yet establish stable campaign economics.
Conversational placement deserves its own creative and landing-page strategy; repurposing a display banner is unlikely to answer the user’s immediate need.
Require definitions for delivery, targeting, attribution, and logged-in versus logged-out reporting before committing meaningful budget.
Measure paid placement separately from organic AI visibility. Buying an ad doesn’t demonstrate that ChatGPT knows, cites, or recommends your brand.
Prepare a controlled pilot now, but release money only after the platform can support the decisions you need to make.
Build the pilot around one commercial decision
Novelty is not a campaign objective. A useful pilot answers a decision such as: Should we add this channel to our acquisition mix? Can it reach buyers earlier than search ads? Does it create qualified demand we wouldn’t otherwise capture? Choose one question. A pilot designed to prove awareness, traffic quality, lead generation, and revenue at once usually produces an ambiguous answer to all four.
Choose one demand state. Define the situation in which your offer helps, such as comparing approaches, narrowing a shortlist, solving an urgent problem, or selecting a provider. Don’t assume the platform lets you bid on exact prompts. Ask what targeting controls actually exist, then translate your demand state into the controls available.
Name one primary business outcome. Use a completed purchase, qualified lead, activated account, booked consultation, or another event connected to value. A click can diagnose delivery, but it shouldn’t become the business case merely because it is easy to count.
Set a quality guardrail. For lead generation, that could be lead acceptance or sales qualification. For commerce, it could be cancellation, return, or contribution margin. A campaign can report an attractive acquisition cost while sending customers who never become profitable.
Create a landing page for the conversational handoff. Restate the promise plainly, answer the next likely question, provide evidence for important claims, and make the next step obvious. If the advertisement answers one question but the page opens with a generic corporate message, you lose the contextual advantage of the placement.
Prepare multiple message angles. Ads have been observed fitting into the conversation rather than behaving like conventional banners. Write concise copy around the user’s task: a direct answer or benefit, a relevant qualification, and a proportionate next step. Keep every claim defensible when read outside the surrounding conversation.
Write the expansion rule before launch. Define the acquisition cost, conversion quality, and measurement confidence needed for more investment. Also define the conditions that stop the test. Historical economics from your own business are more useful here than an arbitrary industry benchmark.
Your test charter should also identify the comparison that matters. If ChatGPT merely receives budget that would have converted through paid search, platform-reported conversions may look encouraging without adding much business value. Compare the pilot with your normal channel mix, not with doing nothing in an imaginary market.
Demand measurement answers before you demand scale
Conversational advertising can create a less familiar path than keyword, feed, or social advertising. A person may ask several questions, see a commercial placement, leave, research the brand elsewhere, and convert later. That makes a clean platform dashboard especially tempting. It also makes unexamined platform attribution especially risky.
Before launch, get written answers to the questions that can change your interpretation of performance:
What event counts as an impression, and can one conversation generate more than one?
What counts as a click or other engagement?
Which click-through or view-through attribution windows are used?
Can you change those windows or compare them with your analytics standard?
Can results be segmented by logged-in status, placement type, geography, device, creative, and audience method?
What contextual, behavioral, demographic, or account-level signals can influence delivery?
Which exclusion, frequency, suitability, and sensitive-topic controls are available?
How are duplicate conversions, invalid interactions, refunds, cancellations, and offline outcomes handled?
Can you export event-level or sufficiently granular campaign data for independent reconciliation?
A missing answer is information. If you can’t distinguish the new logged-out inventory from the rest of delivery, you won’t know whether the expansion improved reach, reduced quality, or simply changed the mix. If you can’t align attribution windows, you won’t be able to compare ChatGPT with another channel fairly.
Build reporting in four layers. Delivery tells you whether the campaign can spend. Response tells you whether people engage. Business quality tells you whether those interactions become valuable outcomes. Incrementality asks whether the outcomes would have happened without the campaign. Keep these layers separate so a strong click rate cannot disguise weak economics.
Use a controlled comparison if one is available and proportionate. A randomized holdout is the clearest option when the platform supports it. Otherwise, use a carefully chosen geographic or time-based comparison and document its limitations. Seasonality, promotions, sales activity, and changes in other media can all create false lift. Don’t call a before-and-after difference incremental merely because the dates line up.
Preserve campaign and creative identifiers in your analytics, connect conversions to revenue or lead quality where consent and applicable rules allow, and deduplicate outcomes across platforms. Compare the platform’s totals with your own analytics before increasing spend. A disagreement doesn’t automatically mean one system is wrong; attribution systems can assign the same conversion differently. It does mean you need to understand the difference.
Keep paid ChatGPT reach separate from organic AI visibility
ChatGPT advertising and generative engine optimization address different problems. An ad buys an opportunity to appear under specified campaign conditions. Organic visibility depends on whether a system can discover, interpret, trust, and use information about your brand or subject. Paid delivery is not evidence of organic inclusion, and an organic mention is not evidence that advertising caused it.
This distinction should shape both your dashboard and your content plan. Report paid impressions, engagements, conversions, acquisition cost, and incrementality as campaign metrics. Track organic citations, brand mentions, referred visits, answer accuracy, and visibility across relevant prompts as a separate program. You can examine relationships between them, but don’t combine them into one score that hides which mechanism changed.
The landing pages used for conversational ads should still meet the same evidence standard as your organic content:
Answer the visitor’s central question before forcing them through a broad brand narrative.
Use descriptive headings that make each section understandable on its own.
Identify products, services, organizations, and authors consistently across the page and site.
Support material claims with evidence a reader can inspect.
Keep prices, availability, policies, and other changeable facts current wherever you publish them.
Use schema types and properties that accurately represent visible content. JSON-LD can clarify entities and relationships, but it cannot guarantee inclusion in an AI answer or eligibility for an advertisement.
Make ownership, contact details, and the path to a real next step easy to verify.
Use paid learning to improve content only when the data supports the connection. If a message angle attracts qualified visitors, examine the underlying need and build a fuller answer around it. Don’t manufacture near-duplicate pages for every phrasing variation, and don’t turn an advertising result into an unsupported claim about what all ChatGPT users want.
The reverse is useful too. Organic visibility analysis can reveal questions where your brand is absent, misunderstood, or poorly supported. Those gaps can inform a paid hypothesis while you improve the underlying content. The advertisement may create immediate reach; the content fixes the durable information problem.
Use a readiness gate before committing budget
You don’t need to choose between rushing in and ignoring the channel. Use three readiness states.
Prepare now if ChatGPT is relevant to how your buyers research or compare solutions. Create the test charter, conversion definitions, landing page, creative hypotheses, suitability rules, and reporting requirements without assuming access.
Test when available if you can isolate a meaningful business outcome, cap the downside, reconcile conversion data, and learn something that affects a real channel decision. Learning value matters, but it should be named rather than used as an excuse for unlimited spending.
Delay investment if access requires a commitment your experiment cannot justify, essential targeting or safety controls are missing, results cannot be independently reconciled, or your landing experience is not ready. Scarcity of access is not proof of value.
The reported reduction from $200,000 to $50,000 still represents material exposure for many organizations. Don’t commit merely to reserve a place in a pilot. Confirm the contract terms, cancellation rights, measurement access, inventory expectations, and responsibility for unsuitable placement before funds become difficult to recover.
Start with a one-page test charter. Write down the user need, primary outcome, quality guardrail, maximum acceptable downside, required platform answers, and expansion rule. When broader access arrives, that page will let you evaluate the opportunity on business evidence instead of launch momentum.
You have more ways than ever to tell Google Ads what kind of customer to pursue. The difficult part is knowing whether a performance lift came from acquiring better customers, adding extra value to those customers, counting conversions after ad views, or testing an unfinished feature.
If those signals are mixed together, an improving ROAS can hide unchanged revenue. The safer approach is to separate customer economics, attribution, and experimentation before you let automated bidding act on them.
Start with the acquisition decision, not the campaign type
A campaign cannot repair an undefined customer strategy. Before choosing Demand Gen, Performance Max, a customer acquisition goal, or an experimental app feature, write down the business decision the campaign is supposed to make.
High-value acquisition: Find new customers who resemble the people your business considers valuable.
Retention: Re-engage customers who meet your definition of lapsed, with a separate distinction for high-value lapsed customers when the data supports it.
Demand creation: Reach people in discovery-oriented environments where an ad view may influence a later conversion even when no click occurs.
Product experimentation: Test an early Google Ads capability without making the business dependent on a feature that may disappear.
Do not use “new customer” as shorthand for “good customer.” A first-time buyer with a small, one-off order may be less valuable than an existing customer ready for a premium service. Define value using evidence your business already understands, such as order value, repeat purchasing, margin, or interest in a premium offering. Then decide which of those attributes can be represented reliably in a customer list.
A clean campaign map usually has one lane for high-value new-customer acquisition, another for lapsed-customer retention, and a separate learning lane for experimental features. Demand Gen can support acquisition, but it should still inherit one clearly defined customer objective. The campaign type is the delivery mechanism; the customer decision comes first.
Make customer states usable before Smart Bidding sees them
Define high value and lapsed in your own data
Google’s predictive bidding can look for likely high-value customers, but your Customer Match list supplies the examples. If the list contains a mixture of loyal buyers, discount-only buyers, recent customers, and stale records, the label “high value” carries little usable meaning.
Create a short data definition before creating the audience. It should answer four questions:
What observable behavior makes a customer high value?
How does that definition differ from merely having a large first order?
What period without an eligible purchase or action makes a customer lapsed?
Which condition takes precedence when someone qualifies for more than one list?
There is no universal lapse window. A sensible definition follows your buying cycle, not an arbitrary calendar interval. Document the rule so that a future list refresh classifies customers the same way.
List scale matters as well. High-value Customer Match audiences need at least 1,000 active members on YouTube or Search networks to serve effectively. Treat that as an operational floor, not proof that the audience is representative. If only a narrow or unusual slice of high-value customers matches, bidding can still learn from a distorted picture.
Include eligible identifiers such as phone numbers and addresses alongside the other customer data you upload; richer records can improve match rates. Direct audience integrations, including Klaviyo, can reduce the manual work of keeping lists current. Automation only solves the transfer, however. It will reproduce a bad definition just as efficiently as a good one.
Treat additional customer value as a bidding instruction
Lifecycle settings are managed in the customer lifecycle optimization area under Goals > Summary, followed by Edit Goal. For a high-value acquisition campaign, you can assign an additional new-customer value so bidding is more aggressive when Google predicts that a conversion will come from the desired customer type.
That additional value is not money collected at checkout. It is a bidding adjustment layered onto the sale or lead value. If a conversion has an actual value and the lifecycle setting adds another amount, the value used in reporting and optimization can include both.
Google may suggest an adjustment based on higher lifetime value, but the suggestion still needs to be reconciled with your own economics. A value that is too small will barely change bidding. A value that is too large can cause the campaign to overpay for customers who merely look like the uploaded audience.
The reporting consequence is especially important under a ROAS strategy. Additional customer value increases the conversion-value numerator even though it does not increase booked revenue at the moment of conversion. The discrepancy is less influential when decisions are based on cost per conversion, but it can materially change the interpretation of ROAS. Use the reporting column that separates true conversion value from additional lifecycle value, and keep all three figures visible in your working report:
Actual sale or lead value.
Additional value assigned for the customer state.
Total value presented to the bidding and reporting system.
If stakeholders see only the total, label it as optimization value rather than revenue. Otherwise, a campaign can appear to produce more economic value when the account has simply changed how much value it assigns to the same type of conversion.
Choose click, view, and lifecycle signals for different jobs
Customer lifecycle and attribution answer different questions. Lifecycle data asks who converted: new, existing, lapsed, or high value. Attribution asks how the advertising interaction receives credit: through a click, a view, or another eligible touchpoint. Combining those dimensions is useful, but only if you continue to report them separately.
View-through conversion optimization gives the system another signal. It can focus on conversions that occur after someone views an ad, even when that person does not click at the time. That fits discovery environments such as YouTube, where exposure may precede a later visit or purchase.
A view-through conversion is still an attributed conversion, not automatic proof of incremental demand. It tells you that an eligible view occurred before the conversion under the account’s attribution rules. It does not establish that the conversion would have been lost without the ad.
That distinction should change how you evaluate a Demand Gen test. Keep click-associated and view-through outcomes visible as separate paths. Then compare actual customer and revenue outcomes, not just the total number of attributed conversions. If view-through volume grows while qualified new customers and true conversion value remain flat, the campaign has changed how credit is assigned more clearly than it has demonstrated business growth.
Creative must follow the same separation. High-value acquisition messaging should make sense to someone who has not bought from you. Retention messaging should acknowledge the reason a lapsed customer might return. In Performance Max, lapsed customers may encounter several ads across the campaign, so a generic asset mix can undermine an otherwise well-configured retention goal.
Before launch, inspect each eligible asset from the perspective of the customer state attached to the campaign. If the ad would be confusing to that person, targeting precision will not rescue it.
Run App Labs as a reversible test, not a permanent dependency
Early access can produce useful learning before a capability becomes widely available. It also carries product risk: an App Labs feature is not guaranteed to become permanent. Build the test so that losing access would remove an option, not break your acquisition program.
Use this protocol for an App Labs test or any other early acquisition feature:
Write one hypothesis. State which customer behavior or business outcome the feature is expected to change and why.
Freeze the customer definitions. Do not change high-value or lapsed-list rules while evaluating a campaign feature.
Select one primary business measure. Prefer true conversion value, qualified new customers, or another observed outcome over adjusted ROAS alone.
Record the feature state. Note the settings, audience lists, attribution configuration, creative, and eligibility present when the test begins.
Keep a stable comparison. Where the interface supports a control, use it. If it does not, document the limitations of the nearest comparable stable campaign rather than presenting the comparison as causal proof.
Cap the learning spend. Put only an amount you are prepared to spend on uncertain learning at risk, and define the condition that will stop the test.
Wait for the normal conversion lag. Reading the result before delayed conversions arrive will favor whichever path reports fastest, not necessarily the one that creates more value.
Avoid changing the lifecycle value, attribution treatment, audience definition, and experimental feature at the same time. If the result moves, you will not know whether customers changed, credit changed, or bidding changed. Sequence the changes so each test resolves one decision.
An experimental feature can still teach you something even if Google later removes it. Preserve the customer insight, creative finding, or measurement lesson in your test log. Do not build an essential workflow around the beta’s exact interface or availability.
Key takeaways for your next campaign cycle
Define high value and lapsed status from your business data before uploading Customer Match lists.
Keep customer acquisition and retention goals in separate campaigns because both bidding goals cannot run on the same campaign.
Separate actual conversion value from the additional lifecycle value used to influence bidding, especially when evaluating ROAS.
Use view-through optimization for discovery journeys, but do not treat attributed views as proof of incremental conversions.
Match creative to the customer state; acquisition and reactivation messages have different jobs.
Test App Labs features in a bounded learning lane because limited-time experiments may never become permanent products.
Your first move does not need to be a new campaign. Open Goals > Summary and identify every lifecycle adjustment currently affecting reported value. Then verify the attached customer lists, their definitions, and whether your report separates real conversion value from added bidding value.
Once those numbers reconcile, choose one next experiment: a high-value acquisition goal, a retention goal, view-through optimization, or an App Labs feature. One clear change will teach you more than four simultaneous upgrades and a better-looking ROAS you cannot explain.
Your SEO roadmap is approved, yet engineering work keeps slipping, content reviews stall, and the next executive meeting is drifting toward another debate about traffic. That is not a roadmap problem. Leadership never reached a usable agreement about the business outcome, the trade-offs, the evidence, or who must act.
You can fix that by treating alignment as an operating system for decisions. The aim is not to make every executive enthusiastic about SEO. It is to give the right leaders enough shared context to fund a bet, commit their teams, interpret the result, and decide what happens next.
Alignment starts with the decision leadership must make
Enterprise SEO teams often ask leadership to approve a roadmap containing audits, templates, internal linking, content briefs, structured data, and reporting. Leadership sees a collection of activities. It still has to work out what business problem those activities solve, why they should take precedence, and what accepting the roadmap commits the company to do.
Replace the roadmap discussion with a decision statement:
We recommend investing in [SEO bet] for [audience or business area] because [diagnosed opportunity or constraint]. We expect it to influence [business outcome], will judge it using [agreed evidence], and need [named commitments] from [owners]. Leadership must decide [specific choice].
This forces several useful distinctions. A diagnosis is not a task list. A hypothesis is not a forecast. A metric is not automatically a business outcome. Verbal support is not a resource commitment. If you cannot complete each part in plain language, the initiative is not ready for executive approval.
The decision also needs boundaries. State which products, markets, page groups, or query classes are in scope. Name what will not be addressed. Enterprise leaders hesitate when an SEO proposal appears capable of expanding indefinitely, because an open-ended initiative competes with every other open-ended initiative.
Do not make organic sessions the only reason to act. One Seer Interactive analysis found a 61% decline in click-through rate for queries with AI Overviews. That finding does not prove every traffic decline has the same cause, but it does show why traffic alone can be an unstable verdict on execution. Connect the SEO bet to the business mechanism it is meant to influence: qualified discovery, product consideration, lead creation, ecommerce revenue, support avoidance, brand presence, or another outcome the company already manages.
Translate the SEO plan into a one-page investment case
An executive-ready SEO strategy should be compressible without becoming vague. Keep the technical plan behind it, but lead with one page that answers the questions required for a decision.
Business objective: Name the existing company priority this work supports. Do not create an SEO-only objective and expect leadership to translate it.
Diagnosed constraint or opportunity: Explain what is preventing the outcome now. Distinguish evidence from assumptions and mark any uncertainty that remains.
Strategic bet: State the change you believe will affect that constraint. A bet is a causal claim, not a bundle of deliverables.
Scope and exclusions: Identify the affected markets, products, templates, page groups, or audiences, along with anything deliberately left out.
Evidence plan: Define the leading indicators, business outcomes, comparison method, and conditions that would support or weaken the hypothesis.
Dependencies: Name the teams, systems, approvals, and capacity the work requires. Assign an owner to each dependency.
Risks and guardrails: Surface the material downside, including customer-experience, platform, brand, compliance, or opportunity-cost concerns where relevant.
Decision requested: Ask for a choice, an owner, committed capacity, or an accepted trade-off. Avoid ending with a generic request for feedback.
The strategic bet is the center of the page. Compare these two formulations:
Investment framing: Make priority category pages easier for search systems to discover and interpret, and more useful to high-intent visitors, so those pages can contribute more qualified product discovery.
The second formulation can be challenged, measured, and resourced. The first can only be completed.
Next, translate the same bet for each leader whose team, budget, or risk tolerance affects delivery. You are not changing the strategy for different rooms. You are showing each person the part of the same decision they own.
Leader or function
Question to answer
Evidence to bring
Commitment to request
Marketing leadership
Which audience or growth priority does this advance?
Demand pattern, journey role, content gap, and relationship to the marketing plan
Priority, accountable sponsor, and agreement on the outcome
Finance
Why should capacity or budget move here?
Investment required, plausible value mechanism, uncertainty, and opportunity cost
Funding boundary and rules for continuing or stopping
Technology leadership
What must change, and what operational risk does it introduce?
Affected systems, implementation scope, dependencies, reversibility, and validation plan
Technical owner and committed delivery capacity
Product or ecommerce
How will this affect the customer journey or commercial experience?
Affected templates, user intent, conversion path, and guardrails
Product priority, acceptance criteria, and release coordination
Brand, legal, or compliance
What claims, controls, or reputation risks require review?
Proposed language, publishing rules, data use, and escalation conditions
Named reviewer and a defined approval path
Titles and ownership differ by company, so adapt the rows rather than copying them mechanically. The important rule is that every critical dependency becomes a named commitment. A stakeholder who says the initiative sounds sensible has not necessarily agreed to allocate people, accept a trade-off, or own a deadline.
Pre-wire consequential decisions before the formal meeting. Speak with the leaders who control the largest dependencies and ask what evidence they need, which risk they expect peers to raise, and what would prevent them from committing. Use those conversations to improve the case, not to collect ceremonial endorsements. The executive meeting should resolve visible choices rather than reveal hidden objections for the first time.
Create the measurement contract before results arrive
Alignment usually looks strongest when a project is approved. The real test comes later, when rankings rise without conversions, traffic falls while revenue holds, an external event distorts the baseline, or implementation lands differently from the approved plan. Without prior rules for interpreting those outcomes, every review becomes a negotiation over what success was supposed to mean.
A measurement contract prevents that drift. It is not a guarantee of results. It is an agreement about what you are testing, which evidence matters, how uncertainty will be handled, and what decisions different outcomes will trigger.
Unit of analysis: Define the page group, query class, market, product line, or audience affected by the work. Sitewide totals can conceal what the initiative itself did.
Baseline: Record the comparison period and any known distortion, such as a campaign-driven spike, a major site change, seasonality, or incomplete tracking.
Intervention record: Preserve what actually shipped, where it shipped, and when. Do not evaluate an approved plan if only part of it was implemented.
Leading indicators: Choose signals that show whether the mechanism is beginning to work, such as crawl access, indexation, relevant visibility, or qualified landing-page engagement.
Business outcomes: Identify the downstream result leadership cares about and explain the expected path from the leading indicators to that result.
Comparison method: Where possible, use unaffected or matched groups to test whether the changed pages behaved differently. If a credible comparison is unavailable, say so and avoid causal certainty.
Confounders: Log releases, migrations, tracking changes, campaigns, market events, and other factors that could alter the result.
Decision rules: Agree in advance what evidence would justify scaling, revising, continuing to learn, or stopping the bet.
Keep forecasts subordinate to the measurement contract. A forecast can help compare investment choices, but it cannot remove search volatility, implementation risk, competitor action, or uncertainty about user behavior. Record the assumptions that would have to hold for the forecast to remain informative. When an assumption breaks, update the decision rather than defending the old number.
This is also where you separate a failed experiment from unmanaged work. An experiment begins with a hypothesis, defined scope, expected evidence, and a next decision. If the result disappoints, leadership still learns something useful. A surprise has no agreed frame, so the room must debate the result, its cause, and its meaning at the same time. Structuring SEO work as explicit bets makes an unfavorable outcome easier to diagnose and act on.
Run executive reviews around decisions and exception handling
A leadership review is not the place to narrate every completed task. Send implementation detail as pre-read material. Use the meeting to answer four questions: What changed? Why does it matter? What do we recommend? What decision or commitment is needed?
Maintain a decision log beside the performance report. For each material choice, record the decision, owner, dependencies, assumptions, and condition that would reopen it. This stops old debates from returning without new evidence and makes slippage visible as an ownership issue rather than an unexplained SEO delay.
When performance is off plan, use a consistent bad-news sequence:
State the variance plainly. Name the affected outcome, scope, and comparison without burying it beneath favorable metrics.
Establish the blast radius. Clarify whether the issue is sitewide or isolated to a market, template, page cohort, query class, tracking layer, or unshipped dependency.
Present the diagnosis and confidence level. Separate what is known, what is likely, and what remains untested. A campaign spike can distort a comparison, while crawl waste can create a genuine technical constraint; similar dashboard shapes do not establish the same cause.
Show what has already been checked. This gives leadership a reason to trust the diagnosis without forcing the room through every technical detail.
Recommend a path. Offer realistic alternatives when a genuine trade-off exists, but identify the option you support and why.
Ask for the decision. Specify the owner, capacity, approval, scope change, or risk acceptance needed to proceed.
Do not diagnose live from a single top-line chart if you can investigate first. A strong recommendation depends on a credible diagnosis, not on confident delivery. Check the comparison period, segmentation, implementation history, tracking changes, technical conditions, and external influences before assigning a cause.
Bad news without a recommendation transfers the unresolved problem to leadership. Bad news with false certainty creates a different problem. The useful middle is a bounded conclusion: what the evidence supports, what it does not yet support, which action is reversible, and what you will learn from taking it.
Own execution errors directly. Explain the consequence, correction, prevention step, and any decision required from leadership. Do not dilute accountability by mixing the error with unrelated wins. Executives can work with an unfavorable result; they cannot make a sound decision from a curated version of reality.
Close every review by reading back the decisions and commitments. Afterward, distribute the updated decision log. Alignment is not what people appeared to agree with in the room. It is the set of recorded choices that named owners now act on.
Key takeaways
Ask leadership to approve a defined business bet, not a list of SEO activities.
Connect the bet to an existing business objective and name the mechanism by which SEO can influence it.
Convert every essential cross-functional dependency into a named owner and an explicit capacity, approval, or risk commitment.
Agree on scope, baseline, leading indicators, business outcomes, confounders, and decision rules before the result is known.
Report company-level organic performance and the initiative’s in-scope performance separately so neither view hides the other.
Treat a disappointing experiment as evidence for the next decision; treat an unexplained surprise as a signal that the operating model is incomplete.
Bring bad news with a diagnosis, confidence level, recommended response, and precise decision request.
Your next move is to take the highest-priority item on your current SEO roadmap and rewrite it as the decision statement above. If you cannot name the business outcome, evidence plan, dependencies, and executive choice on one page, pause the pitch. Resolve those gaps first, then ask leadership for a commitment everyone can recognize later.
I’ve noticed that Google is currently investigating an issue with the Google Search Console. Specifically, this concerns the data logging and reporting of “Job listing” and “Job details” search appearance filters.
On April 16th, a bug began affecting how this data is logged, causing Google to report zero clicks and impressions for job-related reports. Although traffic is still being received, it’s not being recorded correctly.
What Google said. According to an update from Google, “A logging error is preventing Search Console from reporting impressions and clicks for ‘Job listing’ and ‘Job details’ Search appearance types from April 16, 2026 onward. We’re working to resolve this issue. This issue affects data logging only.”
Complaints. I’ve also seen numerous SEOs voicing their concerns on social media, as shared in a tweet by Max Peters. The bug seems to impact impressions and clicks, but the traffic still comes through other measurement methods like google_jobs_apply UTM.
Why we care. If you’ve noticed a decrease in search data for job listings, rest assured, it’s due to this bug on Google’s side. Your listings are likely still active and receiving traffic, although this isn’t reflected in Search Console at the moment.