Author: shivamcrushpressai

  • A Practical Mathematical Model of Brand Perception in AI Search

    A Practical Mathematical Model of Brand Perception in AI Search

    Your homepage may describe a sharply positioned brand while an AI answer treats you as a generic provider, associates you with the wrong problem, or leaves you out entirely. Rewriting the homepage alone may not fix that mismatch. The stronger signal can be hiding across hundreds of headings, product descriptions, comparisons, help pages, and outdated paragraphs.

    You can make this problem measurable. Model your published content as a cloud of semantic points, examine its center and spread, and then ask whether the right points sit close to the queries you want to win. You won’t reproduce a proprietary AI system, but you will get a disciplined way to decide what to create, rewrite, consolidate, or leave alone.

    Your brand is a cloud of meanings, not a single message

    Start by treating each meaningful section of your content as a separate unit. That reflects the practical reality that AI retrieval can work with small passages rather than whole pages. A carefully worded positioning statement is therefore only one point among all the other passages an AI system may encounter.

    For an audit, split your indexable content into n chunks. Each chunk becomes an embedding vector, v_i, representing its meaning in a multidimensional space. Chunks about similar subjects should sit closer together than chunks about unrelated subjects.

    The simplest brand centroid is the mean of those vectors:

    mu = (1/n) x sum(v_i)

    Scott Stouffer’s framework treats that centroid as a practical representation of how AI may locate a brand in meaning space. It captures an important editorial truth: the accumulated content portfolio can define the computed brand more strongly than the intended brand.

    Do not mistake the centroid for a universal specification or a reputation score. There is no reason to assume every search or answer system stores one permanent master vector for your company. Models, indexes, chunk boundaries, queries, and retrieval methods can differ. The centroid is useful because it turns a vague positioning concern into quantities you can inspect consistently.

    The mean is only the beginning. A mathematically serious audit also looks at dispersion, subclusters, query distance, and overlap with competing content.

    Audit quantityWhat it representsWhat you should notice
    CentroidThe average semantic position of the audited chunksWhether the portfolio’s dominant meaning matches the position you intend
    DispersionThe average distance between chunks and the centroidWhether your message is concentrated or scattered across unrelated themes
    Nearest-chunk distanceThe distance from a target query to its closest relevant chunkWhether you have a passage that directly answers the query
    SubclustersDense groups inside the larger content cloudWhether different products, audiences, or legacy strategies are competing for meaning
    Cluster overlapThe degree to which your semantic territory resembles other brands’ contentWhether your supposed differentiation exists in published evidence or only in brand language

    Dispersion can be expressed as D = (1/n) x sum(distance(v_i, mu)). A low value means your chunks remain relatively concentrated. A high value means they are spread out. Neither result is automatically good or bad. A focused product company may want a tight cloud. A multi-product enterprise may legitimately need several clusters, provided the relationship among the brand, products, audiences, and use cases is explicit.

    This distinction prevents a common mistake: trying to force every page toward one generic corporate phrase. The goal is not identical language. It is a coherent semantic structure in which each important cluster has a clear purpose and an unambiguous connection to the correct entity.

    Retrieval is the gate your positioning must pass

    Traditional rank tracking encourages you to ask where a page appears. AI visibility starts with an earlier question: was a relevant passage considered at all? In the retrieval-first model, content must enter the eligible set before later ranking factors can help it.

    Represent a query as vector q. A retrieval process compares q with candidate chunk vectors and selects close matches. For your own analysis, you might use cosine similarity:

    similarity(q, v) = (q dot v) / (norm(q) x norm(v))

    A higher value in this audit means the query and chunk point in a more similar semantic direction. The exact metric, candidate pool, and eligibility cutoff used by a production system may be different, so do not turn your audit score into a supposed universal threshold. Its value comes from comparing your own pages and measuring change with a consistent method.

    The most useful quantity is often not the distance from q to your overall brand centroid. It is the distance to the nearest genuinely relevant chunk:

    d_min(q) = min distance(q, v_i)

    This changes the content question. You are no longer asking whether the site discusses a broad topic somewhere. You are asking whether one passage expresses the user’s exact problem, your relevant capability, the conditions under which it applies, and the entity responsible for it.

    A retrievable passage should usually survive this five-part test:

    • It gives a direct answer or proposition before expanding into background.
    • It names the brand, product, service, or other entity that owns the claim when the identity would otherwise be ambiguous.
    • It uses the language of the real problem, not only an internal campaign slogan.
    • It states an important boundary, qualification, audience, or use case instead of implying universal applicability.
    • It remains understandable when read without the page title, preceding paragraph, navigation, or hero image.

    Compare two content patterns. A vague passage says: A better way for modern teams to move forward with confidence. A retrievable passage follows a more concrete structure: This product category helps this audience complete this job through this method, and it is not intended for this excluded case. The second pattern creates several semantic anchors without resorting to keyword repetition.

    Page-level strength cannot compensate for every passage-level gap. A page may have strong links, sound technical SEO, and substantial topical coverage while still lacking the chunk that matches a decisive query. That is why your content audit must go below the URL level.

    Three mathematical failure modes explain most positioning gaps
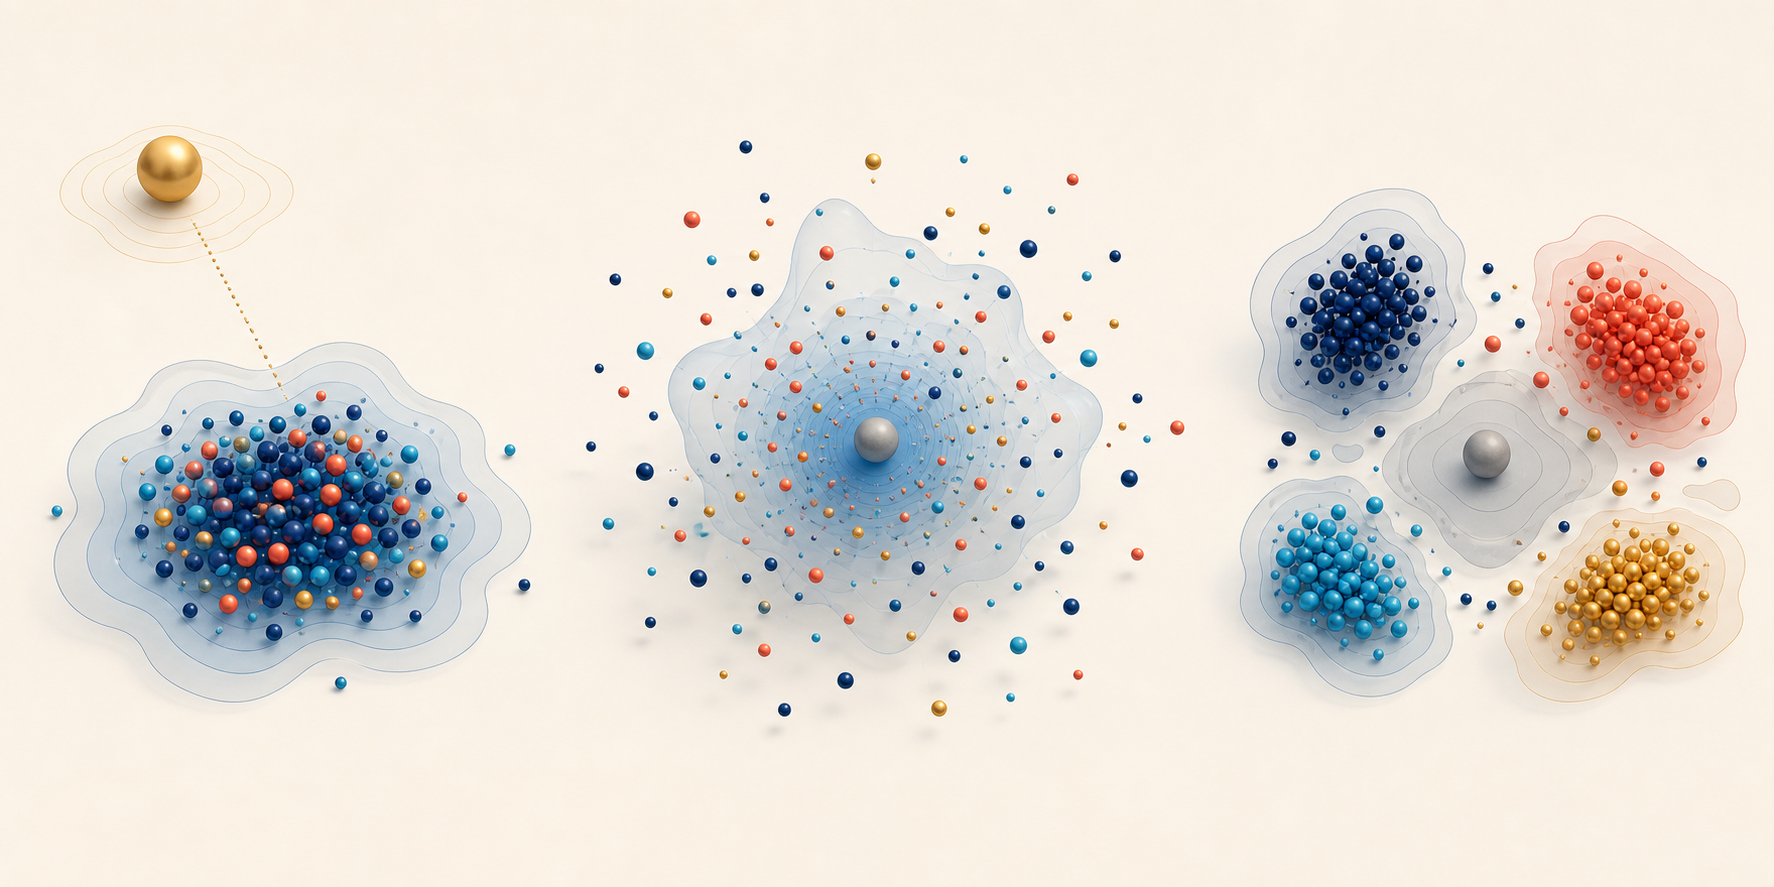
    Three abstract point-cloud scenes show an off-center cluster, a widely dispersed cloud, and several isolated clusters.

    Centroid drift: publishing changes what the portfolio means

    Suppose your existing portfolio has n chunks and centroid mu. You add m chunks whose mean vector is b. The updated centroid is:

    mu_new = (n x mu + m x b) / (n + m)

    The equation exposes two practical levers. The new material pulls harder when there is more of it, and it pulls harder when its meaning is farther from the existing center. One off-topic paragraph may barely move a large corpus. A sustained publishing campaign in an adjacent category can move the portfolio substantially.

    Drift is therefore a portfolio-management problem, not merely an editing problem. Review the semantic direction of a planned content batch before publication. Ask which association the batch strengthens, which existing cluster it joins, and whether the brand genuinely wants to become more closely associated with that subject. Traffic potential alone is not enough.

    This does not mean adjacent content is harmful. Adjacent content becomes dangerous when it is prolific, weakly connected to the core offer, or written without clear entity boundaries. If an adjacent topic serves a legitimate audience journey, connect it explicitly to the relevant problem, product, and next decision.

    Hidden subclusters: the average can conceal a split identity

    An average can land where none of the underlying points actually sit. Imagine that half a company’s content concerns enterprise analytics and the other half concerns consumer productivity. The centroid may fall between the two even though no page clearly owns that middle territory.

    That is why a centroid without a cluster map can mislead you. Inspect the dense groups beneath the mean. For each group, identify its entity, audience, problem, method, and intended query family. If you cannot label a cluster cleanly, the content may be mixing purposes that should be separated.

    When multiple clusters are intentional, give them an explicit architecture. Create a clear hub for each product or solution. State how each one relates to the parent brand. Keep comparisons, use cases, documentation, and proof connected to the correct entity. Consistent structured data can reinforce valid entity relationships, but it cannot rescue page copy that makes those relationships unclear or contradictory.

    Cluster collision: your differentiation disappears in generic content

    If competitors publish the same definitions, broad benefits, listicles, and category language, their semantic clouds can overlap. This cluster-collision problem helps explain why brands with different visual identities can still look interchangeable in meaning space.

    More content is not the direct cure. Publishing another generic overview can make your cluster denser without making it more distinct. Differentiation requires passages that encode substantive differences: the audience you serve best, the problem boundary you recognize, the method you actually use, the tradeoffs you accept, the alternatives you compare, and the evidence that supports your claims.

    Adjectives such as seamless, innovative, robust, and leading do little semantic work when every company uses them. A documented constraint can be more differentiating than a superlative. A clear statement about who should not choose an approach can be more useful than a page of unqualified benefits.

    Run a centroid audit, then repair the shape you find
    A disorganized cloud of colored points is measured and reorganized into a compact cluster around a glowing center.

    You do not need access to an AI platform’s internal index to perform a useful audit. You need a stable representation of your own corpus, a defined set of target queries, and the discipline to treat the results as a diagnostic proxy rather than a replica of any one engine.

    Build the audit in seven steps

    1. Write the intended position as one testable sentence. Use four slots: the entity, the audience, the problem, and the distinctive method or qualification. If the sentence contains only an aspiration such as trusted leader, it is not precise enough to audit.
    2. Create a chunk-level inventory. Record the URL, page title, section heading, chunk text, named entity, target query, main claim, supporting evidence, content type, and publication status. Do not assume every section on a relevant URL serves the same semantic purpose.
    3. Define the axes you care about. Typical axes include audience, problem, category, method, use case, proof, and exclusions. Add adjacent topics that could pull the brand away from its intended position. These axes become the labels against which you inspect clusters and outliers.
    4. Choose a measurement path. For a manual audit, score each chunk on each intended association using -1 for conflicting language, 0 for no signal, 1 for an implied association, and 2 for an explicit, supported association. These are internal review scores, not AI retrieval thresholds. For an embedding-assisted audit, use one embedding model and one chunking rule throughout the comparison. Changing either midway makes before-and-after movement difficult to interpret.
    5. Map query families, not isolated prompts. Group queries by the decisions they represent: discovery, definition, problem diagnosis, implementation, comparison, suitability, proof, and exclusion. Calculate or review the nearest relevant chunks for each family. A strong match for an informational definition does not prove you are close to a buying or evaluation query.
    6. Measure both center and shape. Record the portfolio centroid, dispersion, important subclusters, query-to-nearest-chunk distance, and obvious overlap with competitor language. A two-dimensional plot can help you inspect patterns, but the picture is only a projection. Confirm apparent findings by reading the underlying chunks.
    7. Save a baseline and repeat the same procedure after a substantial publishing batch, a repositioning effort, a product launch, or a major consolidation. Keep the original query set as a stable cohort. Add newly important queries as a separate cohort so changes in the test itself do not masquerade as performance changes.

    If you have several products or audiences, calculate more than one centroid. A brand-wide mean can answer a governance question, while a product centroid or query-conditioned centroid answers a retrieval question. For a query-conditioned view, examine the nearest relevant chunks rather than averaging every page the company has ever published.

    Match the repair to the diagnosed problem

    • If a valuable query has no nearby chunk, create or rewrite a passage that answers it directly. Place that answer on the page whose purpose and entity already match the query.
    • If the centroid looks correct but dispersion is high, inspect the farthest chunks. Update unclear legacy language, reconnect legitimate adjacent content to the core proposition, and consolidate duplicative material where doing so improves clarity.
    • If two legitimate subclusters are being averaged into a confusing middle, separate their hubs and identify the correct product, audience, and use case in each. Preserve a parent-brand page that explains the relationship between them.
    • If your cloud collides with competitors, stop commissioning interchangeable category summaries. Prioritize decision criteria, limitations, comparisons, methods, and verifiable proof that competitors cannot truthfully reproduce word for word.
    • If a strong topical cluster has a weak brand association, name the responsible entity inside the relevant passages. Use consistent entity names in visible copy and valid structured data. Do not mark up claims or relationships that the page does not actually support.
    • If a publishing campaign caused drift, correct the editorial brief before adding more pages. Define the association each proposed piece should strengthen and the core entity to which it must connect.

    Do not respond to an ugly cluster map with a mass deletion. Removing pages can also discard rankings, links, useful history, and coverage for legitimate journeys. Read the outliers first. An update, a clearer entity boundary, a consolidation, or a better internal path may solve the semantic problem while preserving existing value.

    Monitor outcomes without confusing them with internal retrieval data

    Pair the corpus audit with a stable prompt set. For each prompt, record whether the brand appears, which product or capability is attributed to it, whether that representation matches the intended position, which owned page is cited or linked, and whether the answer introduces an unsupported association.

    These observations are outcome proxies. They do not prove which chunks were retrieved internally, and an answer can vary across systems or runs. Their purpose is to show whether your content changes are producing a more accurate and useful external representation.

    Watch for a particularly important failure pattern: inclusion improving while representation accuracy declines. More mentions are not a win if the brand is increasingly associated with the wrong audience, category, or promise. Track visibility and message fit as separate measures.

    Key takeaways

    • Your AI-facing brand is better modeled as a distribution of published meanings than as a single positioning statement.
    • Retrieval comes before ranking, so the first operational question is whether a relevant chunk is close enough to the query to be considered.
    • A centroid shows the average direction, but dispersion and subclusters reveal whether that average is coherent or misleading.
    • Content volume can move the centroid. Review the semantic direction of an entire campaign, not only the quality of each page in isolation.
    • Distinctive brand perception comes from distinctive, supportable information: audience fit, methods, boundaries, tradeoffs, comparisons, and evidence.
    • Your measurements are diagnostic proxies. Use a consistent method to compare changes, not to claim access to an AI engine’s private retrieval logic.

    Start with one commercially important query family and the pages meant to support it. Write the position you want the system to recover, inventory the relevant sections, find the closest missing or ambiguous answer, and repair the smallest set of chunks that will make the intended meaning explicit. Then rerun the same audit after the next content batch. That is how brand perception becomes a managed system rather than a slogan you hope AI notices.
    References

  • How to Give AI Agents Live Marketing Data Without Losing Control

    How to Give AI Agents Live Marketing Data Without Losing Control

    If your AI workflow begins with exporting campaign data, pasting it into a chat, and explaining the same business context again, you do not have an agent. You have a capable analyst waiting for a manual data delivery.

    The fix is not a longer prompt. You need a controlled path from your marketing systems to the agent, with enough current context to support a decision and enough guardrails to stop a bad decision from becoming an expensive action.

    Live means decision-ready, not merely connected

    Live marketing data does not have to mean that every event reaches the agent within milliseconds. It means the information is refreshed before the decision it supports becomes stale. A pacing decision may need current spend and budget data. A lead-quality decision may need the latest CRM disposition. A promotion may need inventory availability before the agent recommends sending more traffic to it.

    That distinction matters because access alone is not enough. An agent can be connected to Google Ads and still make a poor decision if it cannot see what happened after a conversion. It can be connected to a CRM and still misread performance if campaign identifiers do not match. It can see inventory data and still act on an item whose availability record is old.

    A familiar failure starts with a keyword that appears healthy inside the ad platform. It has useful volume and an acceptable cost per acquisition. The CRM, however, shows that the resulting leads are being disqualified. Without that downstream outcome, the agent will keep treating the keyword as successful and may continue spending until a person reconciles the systems. Repeated exports and delayed cross-checks preserve this blind spot; they do not create automation.

    SystemWhat the agent can learnDecision it can improve
    Ad platformSpend, conversions, volume, and campaign performanceWhere traffic appears efficient
    CRMQualification, sales progression, and lead dispositionWhether reported conversions have business value
    Inventory systemAvailability and stock constraintsWhether demand should be increased for a product

    Before integrating anything, write down the decision the agent will support and how fresh each input must be for that decision. If you cannot define when the data becomes too old to trust, the word live is doing no useful work.

    Build a decision context, not a giant data dump

    Raw marketing inputs pass through filtering and verification stages before a compact bundle of relevant context reaches an AI reasoning system.

    An agent rarely needs unrestricted access to every field in every marketing system. It needs a compact, reliable view of the variables that determine one decision. Sending more data without defining its meaning can make the workflow harder to inspect and easier to misconfigure.

    Build that view from the decision backward:

    1. Name the decision. Be precise: recommend a bid change, flag a lead-quality problem, pause promotion of unavailable inventory, or produce a daily exception list.
    2. List the evidence required. Separate platform metrics from business outcomes. A conversion count is not the same thing as a qualified lead, a sale, or an item that can still be fulfilled.
    3. Choose the join keys. Decide how campaign, ad group, keyword, click, lead, customer, product, and order records connect. If systems use different identifiers, define the mapping before the agent sees the data.
    4. Normalize time and meaning. Record the reporting window, timezone, attribution context, currency, and status definitions relevant to the decision. The agent should not have to infer whether two similarly named fields measure the same event.
    5. Attach provenance and freshness. Return the originating system and update time with the value. The agent needs to distinguish a current zero from a missing or stale record.
    6. Define conflict behavior. Decide which system controls when records disagree. If the CRM says a lead is disqualified while the ad platform counts a conversion, the workflow should preserve both facts and use the business outcome for the decision you defined.

    This turns integration into a data contract. Each input has a source, definition, identity, update time, and permitted use. That contract also gives your team something concrete to test when the agent behaves unexpectedly.

    Use MCP as the connection layer, not the policy

    The Model Context Protocol, or MCP, provides a standardized way for an AI client to connect to external tools and data sources. In a marketing workflow, an MCP implementation can expose ad performance, CRM outcomes, and inventory information through a consistent interface instead of forcing you to create a separate conversational integration for every system. This can remove much of the manual handoff that keeps an agent from working with current data.

    MCP does not decide what a qualified lead means, repair broken campaign identifiers, choose a safe budget policy, or determine whether the agent should be allowed to change a bid. It is the connection layer. Your data contract and control layer still carry the business logic.

    Expose narrow tools that correspond to real tasks. A useful initial tool set might let the agent read campaign performance, retrieve CRM dispositions, check product availability, and generate a recommendation. A later tool could execute a preapproved campaign rule. A generic tool with unrestricted account access is harder to audit and creates a much larger failure surface.

    The tool description should also tell the agent what the result does not prove. For example, ad-platform conversions describe recorded conversion events; they do not by themselves establish lead quality. Inventory availability can constrain promotion; it does not establish campaign profitability. Clear boundaries reduce the chance that the model treats one system’s partial view as the complete business outcome.

    Put enforceable guardrails between reasoning and action

    Proposed AI actions pass through layered permission, validation, spending-limit, audit, and human-approval controls before reaching marketing systems.

    Read access and write access are different risk decisions. A mistaken read may produce a bad recommendation. A mistaken write can change bids, pause campaigns, redirect spend, or promote stock that is not available. Do not grant unrestricted write access merely because the agent has produced sensible analysis in a chat window.

    A prompt is not a permission system. Instructions such as be careful or do not overspend can influence behavior, but they do not enforce account boundaries. Operational constraints need to sit around the agent, where the integration can reject an action that falls outside policy.

    Define every write-capable action with these controls:

    • Permission: Specify whether the agent can read, recommend, or execute. Default new workflows to read-only.
    • Scope: Restrict access to the relevant accounts, campaigns, markets, products, and action types.
    • Preconditions: Require the necessary data sources to be available and fresh before an action can run.
    • Policy limits: Encode the budget, bid, status, and inventory rules the action must satisfy. The surrounding system, not the model’s prose, should enforce them.
    • Approval: Route high-impact or ambiguous changes to a person. The agent should return the proposed action, supporting evidence, and reason for escalation.
    • Auditability: Record the inputs, tool calls, decision, approver when applicable, and resulting change.
    • Recovery: Preserve enough prior state to reverse a change when the platform and action type allow it.

    Roll out those permissions in stages. Begin with read-only analysis and verify that the agent retrieves the right records. Next, let it recommend actions while a person compares those recommendations with actual decisions. Then allow only bounded, reversible writes with enforced preconditions. Expand the scope after the data and control layers have proved reliable, not merely after the model has written persuasive explanations.

    Test the data path before judging the agent

    When an agent produces a questionable answer, teams often adjust the prompt first. That is useful only if the required evidence reached the model correctly. A polished prompt cannot recover a missing CRM record, an incorrect join, or inventory data that failed to refresh.

    Test the pipeline with cases that reveal those failures:

    • Freshness: Can you see when each source last updated, and does the workflow stop when a required input is stale?
    • Coverage: Are all in-scope campaigns, leads, products, and accounts represented, or does the connector silently omit some records?
    • Identity: Can a conversion be connected to the correct lead or order and then traced back to the responsible campaign entity?
    • Semantics: Do conversion, qualified lead, sale, availability, and revenue have explicit definitions in the systems that provide them?
    • Missing data: Does the agent distinguish no activity from unavailable data? Treating both as zero can trigger the wrong action.
    • Conflicts: What happens when two systems disagree? The workflow should surface the disagreement rather than silently choosing whichever value arrived first.
    • Failure mode: If the CRM or inventory service is unavailable, does the agent stop, fall back to recommendation-only mode, or request review? Continuing with partial context should be an explicit policy choice.

    Evaluate the system against the decision it was built to improve. For a lead-quality workflow, inspect whether it identifies campaigns producing disqualified leads. For an inventory-aware workflow, inspect whether it avoids recommending more demand for unavailable products. Fluent explanations are useful for review, but they are not evidence that the underlying joins and controls work.

    Key takeaways

    • Live data is data that arrives before the supported decision becomes stale; it is not simply data behind an API.
    • An agent needs business outcomes from systems such as the CRM and inventory platform, not only the conversion view inside an ad platform.
    • Start with one decision and build a defined data contract for its evidence, identifiers, timing, provenance, and conflict rules.
    • MCP can standardize how AI clients reach tools and data, but it does not replace data modeling, permissions, or business policy.
    • Keep new agents read-only until you have validated retrieval, joins, freshness, and failure behavior.
    • Enforce write limits outside the prompt, and log the evidence and action so a person can inspect what happened.

    Choose one recurring marketing decision that still depends on an export or spreadsheet reconciliation. Map the platform metric, downstream business outcome, join key, freshness requirement, and permitted action. That small, inspectable workflow is the right place to prove live data access before you give an agent broader reach.

    References

  • How AI Is Revolutionizing Retail: The End of Shopping Carts?

    How AI Is Revolutionizing Retail: The End of Shopping Carts?

    I’ve recently delved into the fascinating world of conversational commerce AI, and I can’t help but feel excited about how it’s changing the shopping landscape. From how we discover products to the actual purchasing process, this technology is redefining our retail experiences.

    What really intrigues me is what these changes mean for brands operating in an AI-dominated retail space. The implications are huge, and it could very well spell the end for traditional shopping carts as we know them.


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot
  • Top SEO Experts to Watch in 2026: Who

    Top SEO Experts to Watch in 2026: Who

    n

    Last updated: April 27, 2026

    n nnn

    I

    ```json
{
  "alt": "Person speaking on stage, gesturing, in a gray suit with a blue backdrop.",
  "caption": "Engaged in thought-provoking discourse, the speaker captivates the audience under a striking blue backdrop.",
  "description": "A person stands on a stage, speaking and gesturing confidently. They are dressed in a gray suit and light checkered shirt, with a blue background that adds depth to the scene. The image captures the essence of a dynamic presentation, showcasing public speaking in a professional setting. Keywords: public speaking, presentation, keynote, professional speaker, stage presentation."
}
```

    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • Technical SEO Foundations for Search in the AI Era

    Technical SEO Foundations for Search in the AI Era

    You can publish excellent answers, add structured data, and track dozens of AI prompts, yet still remain invisible because the underlying site sends mixed signals about which pages exist, which URLs matter, and what each page is actually about.

    The remedy is less exotic than the problem sounds. Build a site that can be discovered, fetched, interpreted, and trusted without guesswork. That foundation serves conventional search engines, retrieval systems, and the people who eventually land on your pages.

    Key takeaways

    • AI search optimization starts with ordinary technical access: clean URLs, crawlable links, indexable pages, and content that exposes its main answer clearly.
    • Give each important intent one preferred URL, then make internal links, redirects, canonical signals, navigation, and structured data agree with that choice.
    • Remove campaign tracking parameters from internal destinations. Measure the click without creating another version of the destination URL.
    • Write pages as extractable answer systems: state the answer, define the subject, support the claim, preserve its qualifiers, and cover the natural follow-up questions.
    • Structured data can confirm visible meaning, but it cannot repair inaccessible content, contradictory facts, weak architecture, or an unclear page purpose.
    • Measure discovery, URL selection, extraction, corroboration, and AI answer visibility separately. A missing citation does not identify which layer failed.

    Audit the complete retrieval chain before rewriting content

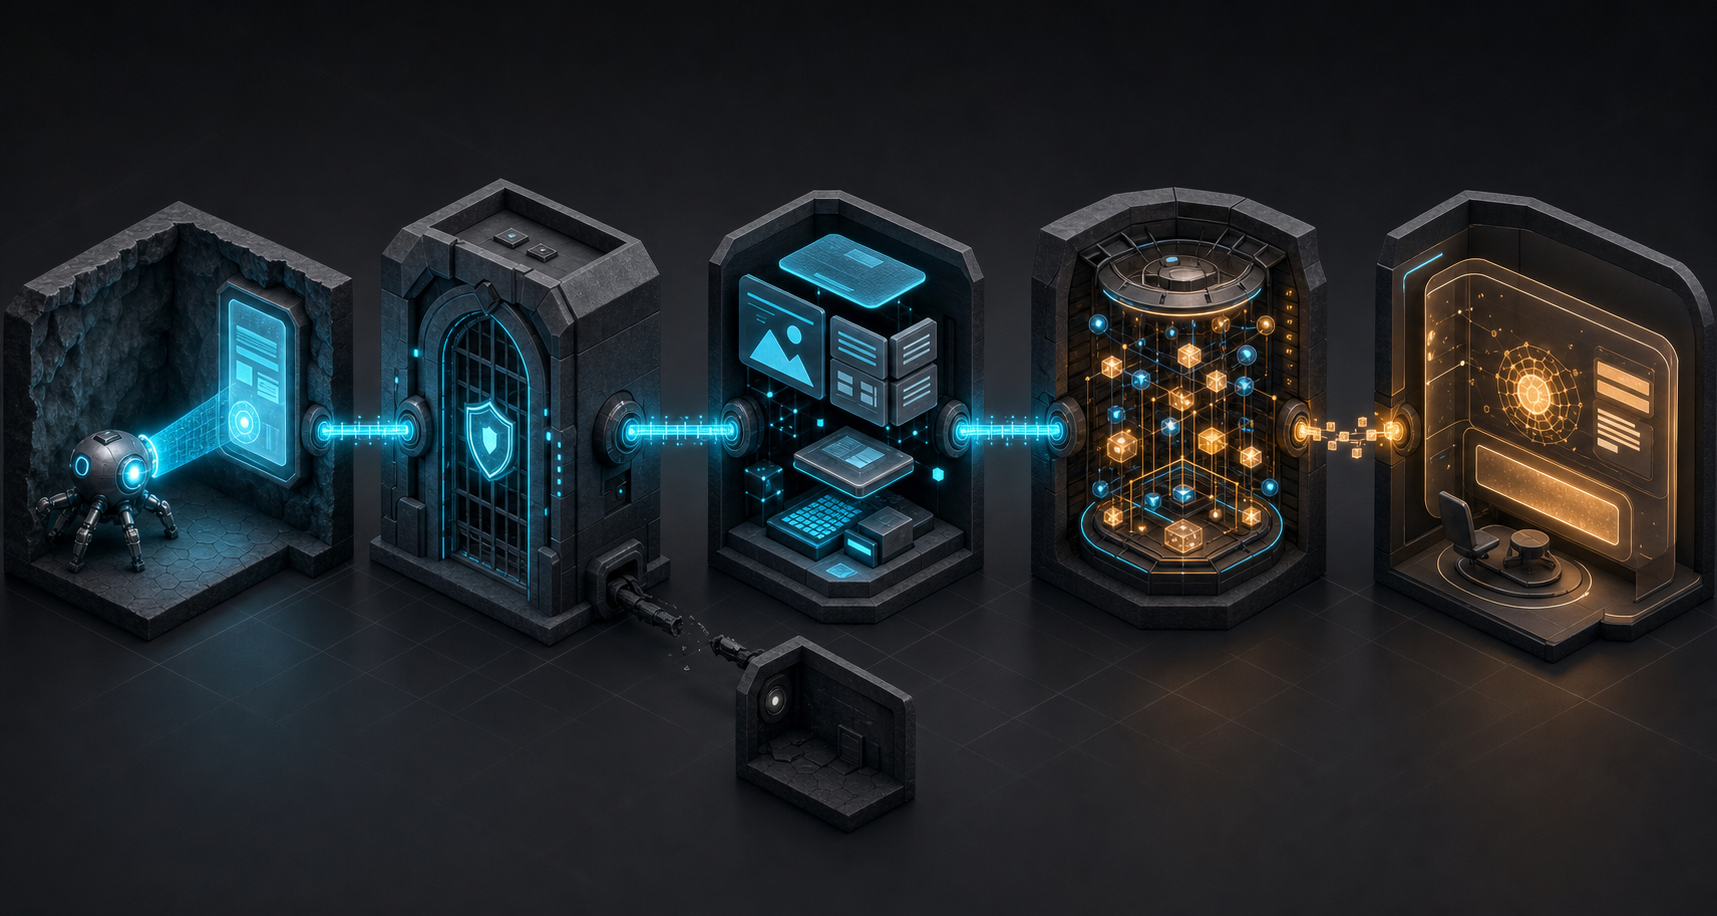
    A cutaway sequence shows a page moving through discovery, server access, rendering, indexing, and retrieval, with one connection visibly inactive.

    An AI-generated answer may look different from a page of blue links, but much of the upstream work is familiar. Retrieval, page quality, speed, and intent matching remain durable foundations. If a system cannot reliably reach or interpret a page, polishing its answer format will not solve the real problem.

    Retrieval-augmented generation, usually shortened to RAG, gives you a useful model for thinking about this process. Instead of relying only on information learned during model training, a RAG system can retrieve external material to help construct an answer. Your technical job is to make the right page a strong retrieval candidate.

    Work through the chain in order. Each step depends on the one before it:

    1. Discovery: Can a crawler reach the page through ordinary internal links from an indexable part of the site? A sitemap can support discovery, but it should not be the page’s only connection to the site.
    2. Access: Does the preferred URL return a successful response and expose the primary content without a login, consent dead end, redirect loop, or permanent loading failure?
    3. Eligibility: Do robots controls, page-level indexing directives, canonical tags, and other technical signals permit the page to be considered?
    4. URL selection: Do all signals identify the same preferred URL, or do internal links point to parameters and redirects while the canonical tag names something else?
    5. Extraction: Can a machine identify the subject, main answer, supporting details, and important qualifiers from the page itself?
    6. Corroboration: Is the claim consistent with the rest of your site, and does the page offer evidence or references appropriate to the question?

    Do not collapse these checks into a single question such as, “Is the page indexed?” Indexing does not prove that the preferred URL was selected, that the decisive passage was extracted, or that the page was judged useful for a particular prompt.

    Start the audit with pages tied to real decisions: a service page, a product category, an important comparison, a technical explanation, or a support page that resolves a costly problem. For each one, begin at the home page or its nearest topic hub and follow the path a crawler would take. Record every redirect, parameterized destination, blocked step, and conflicting canonical signal. You are testing the route, not merely inspecting the destination.

    Run the same check in your templates. A clean link added manually to one page does not compensate for a navigation component, related-content module, or call-to-action block that generates messy URLs across the site. Template defects multiply; template fixes do too.

    Use one stable URL per intent, then make every link agree

    A canonical tag is not a substitute for coherent architecture. It is one signal describing your preferred version. If navigation, breadcrumbs, content links, redirects, sitemaps, and structured data repeatedly point elsewhere, you force retrieval systems to reconcile a disagreement you created.

    Choose the preferred page before changing tags

    For every important topic or task, decide which page should own the intent. That decision should be based on the page’s purpose, not on which URL happens to rank at the moment.

    • Write one sentence describing the question or decision the page owns.
    • Identify overlapping pages that answer substantially the same need.
    • Decide whether each overlapping page has a distinct job, should be consolidated, or should point readers toward the preferred page.
    • Update internal links so their destination is the final preferred URL, not a redirecting or parameterized variation.
    • Align canonical tags, sitemap entries, structured-data URLs, navigation, and alternate versions with that same choice.

    Do not merge pages merely because they share a keyword. A setup tutorial, pricing explanation, troubleshooting page, and buyer comparison can mention the same product while serving different decisions. Consolidate only when the pages compete for essentially the same purpose and neither needs to exist independently.

    Remove tracking parameters from internal destinations

    Campaign parameters are useful when a link crosses from a campaign into your site. They become a liability when your own pages keep appending them to internal destinations. Tracking parameters in internal links can undermine otherwise useful internal linking by creating discoverable URL variants and making the site’s preferred paths less consistent.

    The clean pattern is simple: link internally to the canonical destination and record the interaction separately. Use an analytics event, the referring page, or another measurement method that does not alter the destination URL. The user reaches the same content, while crawlers receive one stable address.

    Audit parameter use as a controlled cleanup:

    1. Export or crawl all internal links, including links produced by headers, footers, cards, related-content blocks, banners, and reusable calls to action.
    2. Group destinations that resolve to the same underlying page but contain different query strings, fragments, protocols, hostnames, or path formats.
    3. Classify each query parameter as tracking, decorative, or functional before changing anything.
    4. Replace tracking variants in templates and page content with the preferred clean URL.
    5. Keep redirects for legacy or externally linked variants when they are still needed, but stop producing those variants internally.
    6. Recrawl the affected paths and confirm that new internal links now point directly to the final destination.

    Do not delete query parameters indiscriminately. Search filters, pagination, account flows, carts, localization, and other features may rely on them. Removing a functional parameter can break the experience or change the content being requested. Classify first; clean second.

    Make internal links explain the site’s knowledge structure

    Internal links do more than move authority around. They describe relationships. A broad topic hub should lead to its detailed explanations; a comparison should link to the products or methods it evaluates; a troubleshooting page should link to the relevant setup instructions; and a supporting definition should point back to the page where the larger decision is made.

    Use anchor text that names what the reader will find. Repeated “learn more” links make the relationship less explicit. You do not need to force the same exact phrase everywhere, but the wording should make sense without relying on the surrounding design.

    Watch for orphaned expertise. A strong technical explanation buried in an old resource directory may be technically indexable yet disconnected from the pages that establish its relevance. Link it from the appropriate hub and from related pages where it resolves a genuine follow-up question.

    Design pages for fan-out, extraction, and corroboration

    A bright central web page receives converging internal links and branches into retrievable fragments that connect with several corroborating source nodes.

    A conversational prompt often contains more than one information need. A person asking which platform fits a regulated team may implicitly need definitions, feature differences, limitations, implementation requirements, and evidence of reliability. AI systems can respond through query fan-out and related prompt intents, retrieving material for those component questions.

    You do not need a separate page for every wording of every prompt. You need a page with one clear primary job and enough well-organized support to answer the natural questions surrounding that job.

    Put the answer where it can be extracted intact

    Open the main content with a direct response to the page’s primary question. Follow it with the mechanism, conditions, evidence, and exceptions. If the answer depends on a product version, user type, location, or implementation state, keep that qualifier beside the claim. A technically correct caveat buried far away can be lost when a passage is retrieved on its own.

    • Use a descriptive page title and heading that identify the subject and task.
    • Give each major follow-up question a descriptive subheading.
    • State important nouns explicitly instead of making long sections depend on vague pronouns such as “it” or “this solution.”
    • Keep definitions near the terms they define.
    • Place evidence, limitations, and applicability conditions near the claim they qualify.
    • Use lists for procedures or criteria, prose for reasoning, and tables only when readers need to compare the same fields across several options.
    • Remove introductions that delay the answer without adding context the reader needs.

    This structure is not an invitation to write in disconnected fragments. A page still needs a coherent argument. The goal is for each important section to remain accurate and useful when encountered independently.

    Keep entity facts consistent across the site

    Machines have a harder job when your own pages disagree about basic identity. Product names, organization names, service areas, feature labels, relationships, and current availability should not change casually between a landing page, documentation, an author profile, and structured data.

    Create a small factual inventory for the entities that matter most. Record the preferred name, concise description, relationship to the organization, and the canonical page that represents each entity. Use that inventory when updating templates and content. This is especially valuable after rebranding, product consolidation, acquisitions, URL migrations, or changes in terminology.

    Consistency does not mean copying the same marketing paragraph everywhere. It means that factual identity remains stable while each page explains the entity in the context of its own task.

    Use structured data to confirm visible meaning

    Structured data should describe what the page visibly communicates. It can make entities, page roles, and relationships more explicit, but it cannot make a blocked page retrievable or turn contradictory copy into a reliable fact.

    • Use the preferred canonical URL wherever the markup identifies the page or its main entity.
    • Keep names, descriptions, relationships, and other properties consistent with visible content.
    • Remove markup left behind by deleted templates, expired offers, or repurposed pages.
    • Validate syntax after template changes, then inspect the rendered page to confirm that the intended markup is actually present.
    • Treat eligibility for a search feature as separate from guaranteed visibility. Valid markup is an input, not an outcome.

    Support claims with appropriate corroboration

    AI optimization is not confined to your own domain. Quality backlinks and third-party visibility remain relevant because retrieval systems need reasons to treat one candidate as more dependable than another.

    On the page, cite primary material when a claim depends on a standard, regulation, official specification, dataset, or named research result. Outside the page, make sure reputable profiles, directories, partners, and industry references use the same core identity. Do not manufacture mentions or fill the web with duplicated descriptions. The useful signal is independent, contextually relevant corroboration.

    Measure the failed layer, not just the missing mention

    AI visibility is tempting to reduce to a yes-or-no brand check. That hides the diagnosis. Your site may be absent because the page was not discovered, the wrong URL was selected, the relevant passage was difficult to extract, another page answered the intent better, or the system produced an answer without showing its external inputs.

    That last case matters: AI tools may provide an answer without displaying external sources. A visible citation is useful evidence, but the lack of one does not prove that no retrieval occurred. Treat AI answer monitoring as directional evidence, not as a conventional rank report with a fixed position.

    Build a prompt set around real user decisions

    Group prompts by intent instead of generating superficial keyword variations. Include the questions people ask when defining a problem, comparing approaches, checking suitability, planning implementation, and resolving failure. Preserve the exact wording so you can rerun the same prompt after a change.

    For every observation, record the system used, the exact prompt, the date, the answer’s main claims, any cited domains, the cited page URL, and whether the answer represented your entity accurately. Reviewing responses in systems such as Google AI Mode and ChatGPT can reveal which external pages are being selected and which prompt intents your coverage misses.

    Do not interpret one generated response as permanent. Retrieval inputs and generated wording can vary. Look for repeated patterns across your stable prompt set, then connect those patterns to technical evidence from crawling, indexing inspection, analytics, and server data where available.

    Use the symptom to choose the next check

    • The preferred page is not discoverable through the site: repair navigation, hub links, orphaning, and template-generated destinations before rewriting the copy.
    • A parameterized or redirected URL appears instead of the preferred page: align internal links, canonical signals, redirects, sitemaps, and structured-data URLs.
    • The page is accessible, but the extracted answer is incomplete: move the direct answer and its qualifiers into a coherent section under a descriptive heading.
    • The wrong page answers the prompt: clarify the purpose of overlapping pages, consolidate true duplicates, and strengthen links to the intended owner.
    • The entity appears with incorrect facts: locate contradictions across landing pages, documentation, profiles, structured data, and relevant third-party references.
    • Competitors are repeatedly cited for a subtopic you barely cover: decide whether that subtopic belongs on the existing page or deserves a distinct page with its own purpose and evidence.
    • Your answer appears without a visible citation: record the mention, but do not claim attribution you cannot observe. Continue checking retrievability, accuracy, and independent corroboration.

    Ship improvements in dependency order

    1. Restore discovery and access for the preferred page.
    2. Resolve conflicting URL and indexability signals.
    3. Clean internal destinations and repair the path from relevant hubs.
    4. Clarify the page’s primary intent and reorganize its answer.
    5. Align entity facts and structured data with visible content.
    6. Strengthen evidence and relevant third-party corroboration.
    7. Rerun the same prompt set and document what changed.

    Your next move is not another isolated AI tactic. Pick one important path through your site, audit it from discovery to extraction, fix the first broken layer, and verify the same prompts again. Once that path is coherent, repeat the process on the next decision that matters to your audience.

    References

  • How to Test and Measure AI Search Visibility Signals

    How to Test and Measure AI Search Visibility Signals

    Your page can rank well in Google and still be absent from the answer your buyer sees. Ahrefs found that only 38% of pages appearing in Google AI Overviews also ranked in the traditional top 10, down from 76% eight months earlier. Organic rank is still useful, but it can no longer stand in for AI visibility.

    You need a test that shows where visibility breaks: whether an AI system retrieves your brand, mentions it, cites it, explains it correctly, places it on a shortlist, or recommends it. The framework below turns those separate outcomes into a prompt panel, a repeatable scorecard, and an experiment you can act on.

    Start with the decision, not a visibility score

    AI visibility is not a single event. Your brand can be cited without being recommended, mentioned without receiving a citation, or described accurately but placed behind competitors. Treating all three situations as visible conceals the problem you need to fix.

    Separate each answer into five measurement states:

    • Retrieval: the AI answer appears and has an opportunity to include your brand.
    • Inclusion: your brand, product, or page is mentioned.
    • Attribution: an owned URL or a third-party page about your brand is cited.
    • Positioning: the answer gives your brand a particular order, category, use case, or authority level.
    • Recommendation: the answer actively includes your brand in the decision set for the intended user.

    This separation reflects how mention order, explanation depth, authority framing, and comparative positioning can each change the value of an appearance. Decide which state matters before collecting answers.

    Your objectivePrompt family to testPrimary measurementGuardrail
    Correct the brand narrativeBranded identity and validation promptsFactual accuracy and explanation depthOwned citation rate
    Expand category discoveryUnbranded category and problem promptsBrand mention rateCompetitive share of mentions
    Enter the buyer’s shortlistAlternative, comparison, and decision promptsRecommendation rate and mention orderAccuracy of the stated use case
    Become a cited evidence sourceInformational and how-to promptsOwned-domain citation rateRelevance of the cited page

    Denominators matter, especially on search surfaces that do not generate an AI answer for every query. A missing AI Overview is not the same result as an AI Overview that appears but omits your brand. Track both:

    • AI answer trigger rate = attempts that produced an AI answer divided by all attempts.
    • Among-answer mention rate = rendered AI answers mentioning the brand divided by all rendered AI answers.
    • End-to-end mention rate = attempts mentioning the brand divided by all attempts, including attempts without an AI answer.

    Do not compress these outcomes into one proprietary visibility score. A composite can rise because branded prompts improved while the unbranded prompts that create new demand deteriorated. Show the component rates and their numerators so a change remains interpretable.

    Build a prompt panel that can be rerun

    Rows of color-coded prompt capsules travel through parallel AI testing chambers and return through a circular rerun mechanism.

    A useful prompt panel is a measurement instrument, not a loose keyword list. Every prompt needs a defined intent, an eligible engine or surface, and a reason for being in the panel.

    1. Branded identity prompts test whether the system knows what the brand is, who it serves, and how it differs.
    2. Category prompts remove the brand name and test discovery for the problem or product class.
    3. Comparison prompts test alternatives, versus questions, and the attributes used to separate competitors.
    4. Decision prompts add a buyer constraint, such as audience, use case, risk, or required capability, and test whether the brand is recommended.
    5. Validation prompts test reputation, limitations, suitability, or factual claims that a buyer may check before acting.

    Keep a stable core panel for trend reporting and a separate exploratory panel for new questions. If you rewrite, remove, or add core prompts, create a new panel version. Do not splice the results into the previous trend line as though the test stayed constant.

    Run each target engine as its own surface. A first-month fictional-brand test covering 825 prompts and 15,835 answers found materially different behavior across ChatGPT, Google AI Overviews, Google AI Mode, Perplexity, and Gemini. Google AI Mode was comparatively stable for branded questions, Perplexity surfaced new material quickly, ChatGPT recognition strengthened during the month, and Gemini produced substantial citation gaps. Because the brand was artificial and the observation window was short, those results are evidence that engines differ, not a permanent ranking of the engines.

    Repeat the exact prompt rather than trusting one screenshot. SE Ranking observed that Google AI Mode overlapped with itself only 9.2% when the same query was run three times. Three runs will not eliminate uncertainty, but they provide a practical first check on whether an appearance is repeatable or incidental.

    For every run, store:

    • A permanent prompt ID, prompt family, and panel version.
    • The exact prompt text without silent edits.
    • The engine and specific surface, such as Google AI Mode or Google AI Overviews.
    • The date, run number, locale, and any account or session conditions you can keep consistent.
    • The complete answer, ordered brand mentions, cited URLs, and first cited URL.
    • Whether your brand was recommended, how it was framed, and whether the description was accurate.

    Use a fresh conversation for each conversational-engine run so earlier messages do not become an uncontrolled input. Run repetitions in the same measurement window, then rerun the complete batch on a fixed cadence. Weekly measurement can suit an active intervention; a monthly cadence may be enough for an established baseline. Consistency matters more than choosing an arbitrary universal interval.

    Evaluate tracking tools against this test design. Familiar SEO integration can still leave you with narrow LLM coverage and no optimization workflow. Before committing to a platform, confirm that it covers your target surfaces, retains raw answers and cited URLs, distinguishes mentions from citations, preserves prompt versions, records repeated runs, and exports answer-level rows. A polished summary dashboard cannot compensate for missing evidence.

    Score each answer without losing its context

    Create one row per answer, not one row per prompt. Aggregating three runs before storing them destroys the variation you are trying to measure.

    1. Inclusion: record brand absent or present. Calculate mention rate separately for branded, category, comparison, decision, and validation prompts.
    2. Attribution: distinguish an owned-domain citation from a citation to an independent page about the brand. Then record whether the owned page was the first or main cited source. A third-party citation can improve brand exposure without giving your site attribution.
    3. Order and recommendation: record the brand’s position among listed options and whether the language explicitly recommends it. Do not treat a neutral appearance in a list as a recommendation.
    4. Explanation depth: apply a small internal rubric consistently. Score 0 for absent, 1 for a name-only list appearance, 2 for a short explanation containing one defined claim, and 3 for a substantive explanation covering the audience, use case, or reason to choose. This is an operational rubric, not an industry benchmark.
    5. Framing and accuracy: label the tone as positive, neutral, cautionary, or negative. Record authority labels such as leader, challenger, or niche option only when the answer actually uses that framing. Mark factual descriptions as correct, incomplete, or incorrect in a separate field.
    6. Stability: with three runs, report whether the brand appeared in none, one, two, or all three. Keep that distribution visible beside the average rate.

    Mention order deserves its own field because people often accept the shortlist they receive. A Growth Memo and Citation Labs test found that 74% of users selected the AI system’s first suggestion, while 26% changed the order when they recognized a brand they trusted. First position can provide an advantage, but it does not erase brand recognition, explanation quality, or trust.

    Accuracy is the non-negotiable guardrail. A confidently worded but false recommendation is not a visibility win. Keep inaccurate claims in the visibility totals so you do not hide the problem, but flag them separately and prioritize correction over reach.

    Report each metric with its numerator and denominator. A percentage without the number of eligible answers conceals small samples, missing AI-answer triggers, and changes to the prompt mix. Break results down by engine, prompt family, branded versus unbranded intent, and run consistency before looking at an overall total.

    Turn signal patterns into controlled content changes

    Two nearly identical content stacks feed AI answer prisms, with one highlighted module changed on the experimental stack for a controlled comparison.

    Diagnose the gap before editing

    The scorecard should point to a failure mode. It should not merely tell you that visibility is low.

    Observed patternLikely readingNext test
    Strong branded mentions, weak category mentionsThe entity is recognized, but its association with the wider problem or category is weak.Test a page that connects the brand clearly to the category, audience, and use cases.
    Frequent mentions, few owned citationsThe brand is known, but the main site is not being selected as evidence.Consolidate definitive facts on an owned page and inspect which independent URLs are being cited instead.
    Citations without recommendationsYour material is useful as evidence, but the brand’s decision position is unclear.Test explicit audience fit, differentiators, selection criteria, and honest limitations.
    Name-only appearancesThe system has too little usable information for a deeper explanation.Test one comprehensive page that answers what the brand is, who uses it, and how to choose it.
    Top placement in only one runThe apparent lead may be output volatility rather than a stable gain.Repeat the batch and report the run distribution instead of publishing the best screenshot.
    Visibility on one engine onlyThe gain is surface-specific.Inspect that engine’s citations and distribution path; do not describe the result as universal AI visibility.
    Positive but inaccurate descriptionsRepeated claims are shaping the narrative without adequate verification.Correct the canonical brand information and monitor the exact false claim across owned and independent pages.

    Identity pages can matter earlier than broad authority. In the fictional-brand experiment, an About page and a consolidated brand guide became frequent citations, while detailed guides, reviews, and comparison pages performed better than generic formats. For a legitimate brand, that makes an accurate entity page and decision-oriented content sensible hypotheses to test. It does not guarantee the same outcome in every category or engine.

    Do not assume a topical cluster is itself an AI visibility signal. During the first month of the same artificial setup, a hub with 10 supporting pages earned no citations, while 30 shorter, repetitive pages collectively generated more than 1,800 citations. That result does not establish repetition as a durable content strategy. It shows that site architecture alone is not a treatment, volume can create exposure, and visibility is not proof that a claim has been rigorously verified.

    For your site, give each supporting page a distinct job tied to a real prompt or decision. Measure which URL is cited. Remove or correct pages that merely repeat claims, especially when repetition could amplify an error.

    Test one explanation at a time

    Most AI visibility work is a structured before-and-after test, not a true randomized A/B test. Retrieval systems change, answers vary, and you do not control when every engine discovers a revision. You can still make the evidence more useful:

    1. Write a falsifiable hypothesis. For example, clarifying audience and category on the canonical brand page should increase explanation depth on branded identity prompts.
    2. Capture a triplicate baseline batch. If the three runs conflict sharply, repeat the baseline before changing the site.
    3. Make the smallest coherent intervention. Update the entity page, publish a comparison resource, or improve a specific claim set, but do not combine a redesign, a large publishing sprint, and a distribution campaign if you want to know what helped.
    4. Record the changed URLs, publication date, affected claims, internal links, and prompt families expected to move.
    5. Use discovery as the gate instead of assuming every engine follows the same calendar. Begin interpreting the post-change period only after the new or revised material appears in citations or is otherwise demonstrably available to the surface being tested.
    6. Rerun the same panel, engine mix, session setup, and scoring rules. Keep newly discovered prompts in the exploratory panel until the current test ends.
    7. Compare the target prompts with unaffected prompt families and competitor patterns. If every brand moves in the same direction, engine drift is a stronger explanation than your page change.
    8. Repeat the result in another scheduled window. Call a one-engine or one-run gain directional, not conclusive.

    Describe a before-and-after movement as associated with the intervention unless you have stronger controls. That language is not timidity; it is an accurate reflection of a system whose retrieval, citations, and generated wording can all change outside your test.

    Keep AI response metrics beside traditional SEO and business outcomes. Citations do not guarantee visits, and visits do not prove that the answer influenced a decision. Some ChatGPT journeys continue on Google as users verify what they were told, so direct AI referrals may miss part of the path. Compare AI visibility with organic landing-page activity, branded demand, qualified visits, and conversions, but do not assign causation merely because two lines moved together.

    Key takeaways

    • Choose the decision you need to make before choosing a visibility metric.
    • Separate AI-answer triggers, mentions, owned citations, independent citations, mention order, recommendations, explanation depth, framing, accuracy, and stability.
    • Keep branded, category, comparison, decision, and validation prompts in separate cohorts.
    • Measure each engine and surface independently, and run the exact prompt three times as a practical volatility check.
    • Store one row per answer with the raw response and cited URLs. Do not rely on a composite score or a selected screenshot.
    • Diagnose the missing stage, change one coherent content element, wait for discovery, and rerun the versioned panel.
    • Track AI visibility beside rankings, traffic, and conversions without treating any one of them as a substitute for the others.

    Your first useful measurement system can be a spreadsheet: a stable core prompt panel, three runs per prompt, one row per answer, and one intervention tied to one failure mode. Automate it after the process can explain why a number moved. That is the point at which AI visibility becomes an operating metric instead of a collection of interesting screenshots.

    References

  • Human Factors That Make Agentic AI Deployments Work

    Human Factors That Make Agentic AI Deployments Work

    Your agent can draft pages, change metadata, select audiences, trigger campaigns, and coordinate customer journeys. The hard question isn’t whether it can perform those actions. It’s whether it should be allowed to perform each one without stopping for a person.

    If you’re deciding how much autonomy to grant, treat the deployment as an operating-model decision rather than a software installation. Define who owns the outcome, which actions require approval, how people will detect a bad decision, and how they can stop or reverse it. Those human controls determine whether the agent produces useful leverage or merely executes mistakes faster.

    Start with a decision, not an AI agent

    Agentic AI projects often begin with a capability demonstration: the system can plan a campaign, create content, update a workflow, or act across several tools. A convincing demonstration doesn’t establish that the workflow is worth automating or safe to delegate.

    The warning is concrete. Gartner expects more than 40% of agentic AI projects to be canceled by the end of 2027. The projection, based on more than 3,400 organizations investing in the technology, points to unclear value, weak governance, and hype-led experimentation rather than a simple lack of technical capability. Treat that percentage as a forecast, not a settled outcome, but don’t miss the operational problem behind it.

    Before you select a product or build an agent, write a decision brief for one workflow. It should answer these questions:

    • What outcome changes? Name the business result, not the AI activity. “Reduce the time required to prepare a technically reviewed content brief” is an outcome. “Use an agent for briefs” is not.
    • What does the workflow look like now? Record its inputs, decisions, handoffs, failure points, review work, and final action. Otherwise, you won’t know whether the agent improved the process or merely moved effort into supervision and repair.
    • Which judgment is scarce? Separate repetitive coordination from decisions that depend on audience knowledge, brand context, ethics, or commercial priorities. Automating the former may create capacity. Hiding the latter inside a prompt creates unmanaged risk.
    • What evidence would justify continuation? Choose outcome, quality, intervention, and recovery measures before launch. A pilot without an exit rule tends to survive because it exists, not because it works.
    • Who can stop it? Assign a named operational owner with authority to pause actions, narrow scope, and require remediation.

    This brief also protects you from “agent washing.” A conventional chatbot or fixed automation shouldn’t be purchased as an autonomous agent simply because the label changed. Ask the vendor or internal team to demonstrate the operating loop: what the system observes, which choices it makes, what it can change, how it checks the result, when it stops, and when it escalates. If every meaningful path was predetermined, you may still have useful automation, but you don’t have the adaptive autonomy the name implies.

    For an SEO or GEO workflow, make the distinction visible. An agent that recommends schema corrections is materially different from one that edits production markup. An agent that identifies possible internal links is different from one that publishes them. An agent that proposes a redirect is different from one that changes routing. Evaluate the authority being granted, not just the sophistication of the output.

    Design human control before you grant autonomy

    Two operators oversee a modular automated workflow equipped with an approval gate, a pause lever, and a track that can reverse direction.

    “Human in the loop” is too vague to serve as a control. A person can technically appear in a workflow while lacking the context, time, authority, or evidence needed to catch a problem. Effective oversight specifies the decision rights on both sides of the human-agent boundary.

    Classify every action the agent may take using four practical questions:

    • Can it be reversed? Saving a draft is easy to undo. Sending a customer message, changing access, publishing an unsupported claim, or allowing a damaging URL change to propagate may not be.
    • How wide is the impact? A suggestion affecting one draft has a smaller blast radius than a template change affecting thousands of pages or an audience rule applied across campaigns.
    • How much context does the decision require? Stable rules are easier to delegate than choices involving brand nuance, conflicting evidence, unusual customer circumstances, or several acceptable outcomes.
    • Will failure be visible quickly? A malformed output may be obvious. A plausible but strategically wrong recommendation can remain unnoticed while it influences content, spend, or customer treatment.

    Use the answers to assign authority. Reversible, narrow, observable actions with clear rules are reasonable candidates for bounded autonomy. Irreversible, broad, ambiguous, or slow-to-detect actions should require approval or remain human-owned. Don’t use one autonomy setting for the entire workflow.

    ControlQuestion it must answerEvidence to retain
    Named ownerWho is accountable for the business outcome and failure response?Owner, backup, authority, and escalation route
    Scope boundaryWhich systems, records, audiences, and actions may the agent touch?Allowlist, denied actions, and permission configuration
    Approval gateWhich conditions force a person to decide?Trigger, reviewer, required context, and decision record
    Stop controlHow can a person halt new actions without waiting for the agent?Pause procedure, access owner, and confirmation that execution stopped
    Recovery pathHow will the team contain and reverse a bad action?Rollback method, affected-system inventory, and notification route
    Audit trailCan reviewers reconstruct what the agent knew, chose, and changed?Inputs, retrieved context, proposed action, approval, execution result, and exceptions

    The audit trail needs to capture more than generated text. Store the context used for the decision, the action requested, the tools called, the result returned, any human intervention, and the final system state. A polished explanation generated after the event isn’t a substitute for an execution record.

    Approval interfaces deserve the same care. Don’t ask a reviewer to click “approve” after showing only the agent’s preferred answer. Show the original input, relevant constraints, proposed change, affected assets, uncertainty or missing information, and available alternatives. Make rejection and escalation as easy as approval. Otherwise, the interface quietly trains people to accept.

    For content and search operations, require explicit review before actions such as publishing factual claims, changing canonical directives, modifying crawl controls, issuing broad redirects, altering product or business data, sending outreach, or communicating with customers. Your exact gates should reflect your systems and risk, but the rule is stable: the person must intervene before the consequential action, not after the impact appears in analytics.

    Increase autonomy only after the workflow becomes observable

    Analysts monitor tasks moving through a transparent automated system while an unusual task is diverted into a separate human review bay.

    A pilot should test the complete operating system around the agent. Testing only whether the model can produce a good answer leaves permissions, handoffs, monitoring, escalation, and recovery unexamined.

    Move through these modes in order:

    1. Shadow mode: Let the agent observe real inputs and record what it would do, but prevent external actions. Compare its proposed decisions with actual outcomes and inspect where its context is incomplete.
    2. Advisory mode: Let it recommend actions to a responsible operator. Record approvals, edits, rejections, escalation reasons, and the time required to review. Heavy correction is evidence that the workflow or context is not ready for autonomy.
    3. Bounded action mode: Allow a defined set of reversible actions within an allowlisted scope. Keep consequential actions behind approval gates and enforce a direct stop mechanism.
    4. Expanded autonomy: Broaden authority only when the existing scope produces acceptable outcomes, exceptions are understood, logs support investigation, and the team can demonstrate recovery.

    Promotion between modes should be an evidence decision. Don’t advance because the pilot deadline arrived or because a successful demonstration created executive enthusiasm. Review routine cases, edge cases, ambiguous requests, missing-data situations, conflicting instructions, permission failures, and attempts to push the agent beyond its assigned scope.

    Measure the deployment across four layers:

    • Outcome: Did the workflow improve the business result named in the decision brief?
    • Quality: Were outputs accurate, complete, on-brand, appropriately sourced, and suitable for the intended audience?
    • Control: How often did people edit, reject, stop, or escalate an action, and why?
    • Recovery: Could the team identify affected assets, contain the problem, restore the correct state, and learn from the failure?

    Don’t optimize the intervention rate toward zero. A falling rate can mean the system improved, but it can also mean reviewers stopped looking carefully. Read intervention data alongside sampled quality checks, downstream outcomes, and exception reports. The useful question is whether human attention is landing on the decisions where it changes the outcome.

    FOMO creates pressure to skip this progression and move directly from demo to production. That pressure is especially dangerous when an agent can act at campaign or site scale. Speed comes from making the safe path repeatable: clear permissions, reusable evaluation cases, reliable logs, tested rollback, and known escalation owners.

    Protect human judgment and customer trust as operating assets

    An agent’s output can look coherent even when its recommendation is unsuitable. That makes reviewer competence part of the control environment. If the person approving an action can’t recognize a strategic, factual, or ethical error, the approval step is ceremonial.

    One projection expects half of organizations to reassess their competencies as reliance on AI threatens critical thinking. You don’t need to reject automation to respond. You need to keep the relevant judgment active.

    • Require a reason for consequential approvals. The reviewer should identify why the action fits the goal and constraints, not merely confirm that the output reads well.
    • Keep people capable of performing the underlying task. Rotate qualified operators through manual cases and exception handling so the team retains a working model of what good looks like.
    • Separate creation from high-impact approval. The person who configured or champions the agent shouldn’t be the only person judging its production readiness.
    • Review disagreements, not just errors. Repeated edits and rejected recommendations reveal missing context, unclear policy, or a task that requires more human judgment than expected.
    • Run post-incident reviews around the system. Examine instructions, data, permissions, interface design, workload, escalation, and incentives. Telling reviewers to “be more careful” leaves the mechanism intact.

    Customer trust needs its own controls. A related forecast warns that poorly applied agentic AI could damage customer relationships by 2026. The risk isn’t limited to obviously nonsensical responses. An agent can send a polished message to the wrong person, apply a reasonable rule at the wrong moment, or take an authorized action that conflicts with the customer’s circumstances.

    Map each customer-facing action to an identity, authority, and escalation rule. The customer should be able to tell what happened, correct wrong information, reach a person when the automated path is unsuitable, and receive a clear resolution when an action causes harm. Internally, the team should be able to identify which agent acted, under whose authority, using what information.

    Brand alignment can’t live only in a long prompt. Translate it into reviewable policies: prohibited claims, evidence requirements, tone boundaries, audience exclusions, escalation topics, and actions the agent may never take. Give each policy an owner and a process for change. That turns “use good judgment” into controls a team can inspect.

    Key takeaways

    • Begin with one defined business decision and its current workflow, not a general mandate to deploy an agent.
    • Evaluate actual autonomy by inspecting what the system observes, decides, changes, verifies, and escalates.
    • Grant authority action by action. Reversibility, impact, ambiguity, and observability should determine where people intervene.
    • Test in shadow, advisory, bounded-action, and expanded-autonomy modes, with evidence required before each increase in authority.
    • Retain execution logs, explicit stop controls, and tested recovery paths before the agent touches consequential systems.
    • Treat reviewer competence and customer escalation as core infrastructure, not training tasks to add after launch.

    Before your next agent demo, produce a one-page deployment contract for the workflow: outcome, owner, allowed actions, prohibited actions, approval triggers, stop mechanism, recovery path, and evidence required for more autonomy. If the team can’t agree on that page, the agent isn’t ready for broader access. Resolving those human decisions first is the shortest route to a deployment you can trust.

    References

  • How to Create Helpful Content That Earns SEO Visibility

    How to Create Helpful Content That Earns SEO Visibility

    You have a page aimed at the right keyword, a sensible heading structure, and all the expected subtopics. Yet the draft still feels interchangeable with ten competing results. That feeling is a warning: the page covers a topic, but it may not complete the searcher’s job.

    Helpful content gives someone enough clarity to understand a situation, make a decision, or take the next step without immediately running another search. That is the standard to use when planning, writing, editing, and measuring your SEO content.

    Helpful content completes a searcher’s job

    Start by replacing the vague goal of “covering the topic” with a specific outcome. Before you outline the page, finish this sentence:

    After reading this page, [specific audience] can [specific action or decision] without [avoidable uncertainty].

    If you cannot complete that sentence precisely, your topic is probably too broad or your audience is not defined well enough. “Understand technical SEO” is not a workable outcome. “Decide which technical SEO problems should be fixed before a site migration” gives you a reader, a decision, and a boundary.

    Most search-driven pages serve one of three jobs:

    • Learn: The reader needs a direct answer, an explanation of the mechanism, and enough context to interpret it correctly.
    • Decide: The reader needs criteria, tradeoffs, exceptions, evidence, and a way to compare the available choices.
    • Act: The reader needs an ordered process, required inputs, likely failure points, and a way to verify the result.

    A page can support more than one job, but one should be its center of gravity. A decision page that spends most of its space defining basic terms will feel slow. A how-to page that omits verification may leave the reader with steps but no confidence that they worked.

    This is also the right way to think about depth. Depth is not a word count. It is the degree to which you resolve the main question and the necessary questions behind it. A page about choosing an SEO agency may need evaluation criteria, evidence to request, questions to ask, tradeoffs, and warning signs. A long history of SEO adds words without helping that decision.

    Google’s March 2026 core update focused on surfacing relevant and satisfying content across sites. The practical response is not to chase a new writing formula. Make the reader’s intended outcome the organizing principle of the page.

    Map the question chain before you draft

    A writer's hands arrange connected research objects, including a magnifying glass, measuring tool, wooden blocks, key, and doorway model, around a blank sheet.

    A search query is often only the first visible part of a larger problem. Someone searching “best schema for a service page” may also need to know which entity the page represents, whether multiple schema types can coexist, what must be visible on the page, how to validate the markup, and when the implementation needs to be updated.

    Modern search architecture makes those follow-up questions more important. Retrieval-augmented generation can gather relevant information from multiple locations, while query fan-out can split a broad request into related searches. The editorial consequence is simple: a missing subquestion is a real gap, even when the page uses the primary keyword in all the expected places.

    Build a question map before building the outline:

    1. Name the reader and the moment. Identify who is searching and what has prompted the search. A business owner comparing platforms needs a different answer from a developer debugging an implementation.
    2. Write the immediate question in the reader’s language. Use a complete question, not a two-word keyword label. This forces you to confront the actual decision or task.
    3. List the questions that appear after the first answer. Look at People Also Ask results, Search Console queries, internal site searches, sales objections, support requests, comments, and customer interviews where you have them.
    4. Classify each question. Mark it as required for task completion, useful supporting context, or a tangent. Required questions belong on the page. Useful context can be concise. Tangents usually deserve a separate, linked page.
    5. Put the questions in decision order. A reliable sequence is direct answer, relevant context, choice criteria, exceptions, implementation, verification, and next step. Change that order when the reader’s task demands it.
    6. Assign evidence before writing prose. Decide which claims need an example, first-party data, a documented process, an external citation, or a subject-matter review. This prevents a polished draft from exposing evidence gaps late in production.

    People Also Ask is useful for discovering language and overlooked branches, but it is not an outline generator. A question deserves space only if answering it moves the same reader toward the same outcome. Pasting every related question into an FAQ produces breadth without coherence.

    Give the finished page one center of gravity. If a branch requires a different audience, a different goal, or a substantial new explanation, move it to a supporting page and connect the two with a descriptive internal link. The result is a tighter primary page and a more useful topic structure.

    Turn expertise into visible, verifiable evidence

    An expert measures a generic component with a caliper while documenting the test with a camera, surrounded by samples, tools, a notebook, and process photographs.

    Expertise is not created by calling a page “complete,” adding an author biography, or repeating familiar advice in a confident tone. A reader recognizes expertise through the choices you explain: what matters, why it matters, where the recommendation applies, and where it stops applying.

    Generic content names concepts. Expert content exposes the decision-making behind them. Look for opportunities to include:

    • A precise process: Put the work in its real order and explain dependencies between steps.
    • Selection criteria: Tell the reader how to choose, not merely what options exist.
    • Tradeoffs: State what is gained, what is sacrificed, and who is likely to care about each side.
    • Boundaries: Identify the conditions under which the recommendation changes or does not apply.
    • Failure modes: Show what commonly goes wrong, how the reader can notice it, and what to check first.
    • A worked example: Use real or clearly hypothetical inputs, explain the decision, and show the resulting action. Never turn a plausible scenario into a claimed client result.
    • Evidence provenance: Make it clear whether a claim comes from first-party data, documented platform behavior, professional judgment, or a cited authority.

    A useful pattern for important recommendations is: recommendation, reason, boundary, action. For example, schema markup can help machines interpret the entities and relationships represented on a page. It cannot supply missing expertise or make unsupported claims trustworthy. Add markup that accurately reflects visible content, validate the implementation, and fix the underlying page before treating structured data as an optimization layer.

    Apply the same test to AI-assisted drafts. The problem is not that a tool helped produce the words. The problem is publishing language nobody has checked, examples nobody can substantiate, or advice that ignores the business’s actual process. A responsible editor should be able to explain and defend every consequential statement under the brand’s name.

    Remove credibility theater during editing. Unsupported superlatives, vague claims such as “experts agree,” decorative statistics, and generic author boxes do not answer the reader’s question. Replace them with an accountable claim, its basis, and the condition that limits it. If you do not have the evidence, narrow or remove the claim.

    Edit for fast answers and passage-level clarity

    Readers skim because they are trying to locate the part that resolves their problem. Retrieval systems also work with sections and passages rather than admiring a page as one uninterrupted essay. You do not need to turn every paragraph into a detached snippet, but each major section should make sense without forcing someone to reconstruct its subject from several screens earlier.

    Use this editing pass after the factual draft is complete:

    • Make every heading describe the question, decision, or action addressed below it. Replace labels such as “Overview” or “Other considerations” with meaningful language.
    • Answer the heading in the opening sentence or paragraph. Put qualifications immediately after the answer rather than delaying the answer for a long setup.
    • Keep one main idea per paragraph. Start a new paragraph when the reader must evaluate a new claim, condition, or action.
    • Name the subject explicitly. A passage full of “it,” “this,” and “they” may become ambiguous when retrieved without the surrounding paragraphs.
    • Define specialist terms where the intended reader may not know them. Do not interrupt an expert audience with definitions it does not need.
    • Place an example directly after the principle it demonstrates. A distant example forces the reader to perform the connection.
    • Use lists for steps and criteria. Use tables only when the reader genuinely needs to compare the same dimensions across multiple options.
    • End sections with the decision, check, or next action the reader can take. Do not close with a vague statement about importance.

    Then add the conventional SEO layer: an accurate title, a descriptive meta description, useful internal links, clear headings, appropriate media, and structured data that agrees with the visible page. These elements help discovery and interpretation. They do not rescue an answer that is incomplete, generic, or untrustworthy.

    Measure the job, not only the click

    AI-generated search results make click-only reporting less complete. Semrush tracking found AI Overviews on 6.49% of queries in January 2025 and 15.69% by November 2025. Those percentages describe the tracked query set, not a universal rate for every industry, but the direction is enough to justify measuring more than website sessions.

    Choose success signals that match the page’s declared job:

    • Learning pages: Track qualified search visibility, engagement with the answer, and movement to the next relevant resource.
    • Decision pages: Track meaningful next-step actions, conversions, and lead quality rather than rewarding any visit equally.
    • How-to pages: Use the best available completion proxy, such as interaction with a verification step or a reduction in repeated support questions.
    • Local and service pages: Include branded searches, direct inquiries, and presence in relevant recommendation results. AI platforms can mention or recommend a business without producing a direct website visit.

    If automated AI-visibility tools are outside your budget, create a fixed set of representative prompts and record whether your brand, page, or claims appear. Keep the prompts and evaluation method consistent so that changes mean something. A single favorable response is an observation, not a trend.

    Use performance data diagnostically. Impressions without meaningful action may indicate a weak promise, a mismatched query, or an incomplete answer. Conversions from a smaller audience may show that the page resolves the right job well. Rankings matter, but they should not become a substitute for checking whether the page helps the people it attracts.

    Helpful content FAQ

    What makes content helpful for SEO?

    Helpful SEO content gives a defined audience the answer, context, evidence, and next step needed to complete a specific search task. It addresses necessary follow-up questions, explains meaningful tradeoffs, and makes its claims easy to understand and verify.

    Does helpful content need to be long?

    No. It needs to be complete for the intended job. A narrow factual question may need a short answer and one qualification. A high-stakes comparison may need criteria, alternatives, exceptions, evidence, and implementation details. Stop when the reader can act confidently, not when you reach an arbitrary word count.

    Should every related question appear on one page?

    No. Include a follow-up question when it helps the same reader complete the same task. Move a branch to a separate page when it serves another audience, requires substantial explanation, or pulls the main page away from its purpose. Link the pages where the relationship is genuinely useful.

    Can JSON-LD or schema make thin content helpful?

    No. Structured data can describe entities, properties, and relationships that the page actually supports. It cannot create missing evidence, answer an omitted question, or turn a generic claim into expertise. Improve the visible answer first, then use accurate markup to represent it.

    Choose one commercially important page and write its job statement at the top of your working draft. Build the question chain, then mark every existing paragraph as answer, evidence, context, or action. Rewrite anything too generic to earn a label, and remove anything that does not advance the reader’s job. That pass will show you whether the page is genuinely useful or merely optimized to look relevant.

    References

  • How to Build a Human-Led B2B Brand and Content Strategy

    How to Build a Human-Led B2B Brand and Content Strategy

    You can have a full content calendar, capable writers, strong subject-matter experts, and an AI workflow that produces drafts in minutes, yet still sound interchangeable with every competitor. The problem usually sits upstream: nobody has made a firm decision about what the market should believe about the brand.

    A human-led strategy fixes that without discarding AI. People retain the decisions with commercial consequences: what the brand should mean, which evidence deserves emphasis, what not to claim, and which trade-offs are acceptable. AI handles bounded work around those decisions, including organization, drafting, transformation, consistency checks, and distribution.

    Brand strategy begins with a decision, not a prompt

    AI can generate dozens of plausible positioning statements. That abundance is useful for exploration, but it is not a strategy. A position becomes strategic when you choose one interpretation of the business, support it, and reject adjacent messages that would weaken it.

    The distinction matters because your preferred position may not be the most obvious conclusion available from the facts. AI can connect known information and propose possible narratives, but it does not carry responsibility for choosing the narrative that serves your company, customers, and long-term direction. A named human must make that choice.

    A practical way to structure the decision is the claim-frame-prove discipline. It separates three elements that teams often collapse into one vague brand statement.

    ElementQuestion it must answerHuman decisionRequired output
    ClaimWhat do we want the market to believe?Choose a specific, defensible proposition instead of a collection of benefits.A sentence that can be tested against evidence.
    FrameWhy does this claim matter, and how should the evidence be interpreted?Select the commercially useful conclusion and the alternative view you are challenging.An explicit logical bridge from accepted facts to the desired association.
    ProofWhy should a buyer or an answer engine believe us?Set the evidence threshold, boundaries, and caveats.Named, accessible support for every material assertion.

    Write the claim so it can succeed or fail

    Statements such as trusted partner, innovative platform, and customer-first company are difficult to disprove, which also makes them difficult to value. Replace them with a proposition that has an identifiable audience, problem, outcome, and reason to believe.

    Use this working structure: For a specific buyer facing a specific decision, the brand represents a defined approach or advantage because named evidence supports it. This matters because the evidence leads to a useful conclusion the buyer may not have considered.

    Do not publish the template itself. Use it to force the internal decision. If the team cannot complete it without broad adjectives, multiple audiences, or unsupported outcomes, the positioning is not ready for production.

    Treat the frame as strategy, not decoration

    A frame is not a clever slogan placed above the same old product copy. It tells the reader what the evidence means. Two companies may have similar capabilities, but the company that explains the consequence of those capabilities can own a more useful association in the buyer’s mind.

    Pressure-test a proposed frame with five questions:

    • Would a relevant competitor be equally comfortable making this claim?
    • Does the proof establish the promised outcome, or merely show that a feature exists?
    • Does the frame add a meaningful conclusion rather than restating the claim?
    • Can a skeptical reader follow the path from evidence to conclusion without filling in a missing step?
    • Have you stated the conditions or use cases in which the claim does not apply?

    If the competitor can copy the entire argument without changing the evidence, you have a category description, not a position. If the conclusion requires a leap that the proof cannot support, you have promotion, not a position. Human judgment is the work of finding the narrow territory between those failures.

    Turn positioning into a content operating system

    A human hand places a central colored block into a connected tabletop system of blank content modules and evidence tokens.

    A positioning document has little value if every writer interprets it differently. Your content system must carry the same claim, frame, and proof into landing pages, executive viewpoints, product education, case material, sales enablement, and answer-focused content without forcing every asset to repeat identical wording.

    Start with a claim ledger rather than a topic calendar. The calendar tells you when something will be published. The ledger tells you what the business is prepared to assert, why it is true, where the evidence lives, and who is accountable for approving it.

    Each ledger entry should contain:

    • Approved claim: the exact proposition content may communicate.
    • Intended audience and decision: who needs the information and what they are trying to decide.
    • Strategic frame: the conclusion the evidence should help the audience reach.
    • Proof: the product fact, operational evidence, customer evidence, expert knowledge, or other support available for the claim.
    • Evidence location: the page, record, or internal owner that can substantiate the assertion.
    • Scope limits: markets, use cases, products, or circumstances the claim does not cover.
    • Approval owner: the person authorized to accept, narrow, or reject the claim.

    A claim without an evidence location or owner is not ready to enter an AI prompt. Marking it as unverified is safer than allowing a drafting system to fill the gap with language that merely sounds credible.

    Brief content around a buyer decision

    Topic-only briefs produce topic-shaped content: broad, informative, and hard to distinguish. A decision brief tells the writer what must change for the reader. It should identify the question that brought the reader to the page, the misconception or uncertainty blocking progress, the approved claim, the frame, the evidence, and the next sensible action.

    Before drafting, require the content owner to finish this sentence: After reading, the intended buyer should be able to decide whether or how to do something specific. If the answer is merely understand the topic, the brief is probably too broad.

    Then assign the page one primary job. It might define a problem, establish a fact, compare approaches, resolve an objection, substantiate a brand claim, or help the buyer act. A page may support secondary jobs, but letting every asset do everything usually produces a long page with no clear purpose.

    Give AI bounded responsibilities

    AI is most useful after the decision architecture exists. Give it approved material and a defined transformation, then require it to expose gaps instead of inventing bridges.

    Suitable AI responsibilities include:

    • Grouping buyer questions by intent or stage.
    • Turning approved interviews and notes into candidate outlines.
    • Producing channel-specific versions of an approved argument.
    • Checking drafts for contradictions against the claim ledger.
    • Finding assertions that lack attached evidence.
    • Suggesting alternative explanations while preserving the approved position.
    • Identifying where the relationship between a claim and its proof remains implicit.

    Keep these responsibilities human:

    • Choosing the market association the brand will pursue.
    • Deciding which audience or use case takes priority.
    • Judging whether the available evidence is strong enough.
    • Resolving disagreements between subject-matter experts.
    • Approving external claims, comparisons, and conclusions.
    • Deciding what the brand will deliberately decline to say.

    The boundary is simple: AI may generate options and transformations, but it does not receive decision rights. Record the human decision before generation begins so the team can distinguish deliberate strategy from wording that appeared during drafting.

    Make the brand legible to buyers and answer engines

    Business buyers and an abstract scanning device examine the same illuminated geometric object and its visible proof components.

    Having evidence somewhere on the website is not the same as communicating an evidence-backed position. A person may infer the connection after visiting several pages. A search or answer system may not make the same connection, and it has no obligation to choose the interpretation most favorable to your brand.

    Brand evidence typically becomes more usable through three levels:

    <!– wp:list {
  • Quality-First SEO: Build Trust Before You Publish More

    Quality-First SEO: Build Trust Before You Publish More

    Your editorial calendar is full, the site keeps growing, and organic visibility is barely moving. The problem may not be a lack of content. Publishing more URLs can split authority, create internal competition, and consume attention that stronger pages need.

    You need a strategy that concentrates value. That means assigning every page a clear job, consolidating pages that compete for the same intent, strengthening the reasons a reader should believe you, and measuring whether visibility leads to a real choice.

    Key takeaways

    • More pages do not automatically create more search demand. Several URLs aimed at the same intent can divide signals without expanding your reach.
    • Content quality is not a word count. A useful page completes a specific user task, makes a distinct contribution, supports its claims, and stays accurate.
    • Trust begins after discovery. A ranking or AI mention has limited value when the reader cannot verify the answer or reconcile it with what other people say about the brand.
    • Classify existing pages as keep, improve, merge, or retire. Do not use traffic alone to make the decision.
    • Approve a new URL only when you can name its distinct intent, contribution, evidence, maintenance owner, distribution path, and business purpose.
    • Measure three stages separately: whether you were seen, whether you were believed, and whether you were chosen.

    Audit the content library as a connected system

    A strategist organizes linked page cards into topic clusters and identifies overlapping, isolated, and central pages.

    A content audit should not be a spreadsheet of traffic totals followed by a mass deletion. It should show how the URLs work together. A small set of pages can produce most of a library’s useful visibility while many others add maintenance work without strengthening the site.

    Every URL is a commitment. Someone must keep its facts accurate, preserve its internal links, reconcile it with newer advice, and make sure it still represents the brand. At scale, low-value URLs also compete for finite crawl attention. Even when crawling is not your main constraint, unnecessary pages make the site’s hierarchy and editorial priorities harder to understand.

    Build an inventory with decision-making fields, not just SEO metrics. For every indexable page, record:

    1. Primary user job: Write the exact question, problem, or decision the page helps with. If you need several unrelated sentences, the page may be unfocused.
    2. Audience and stage: Identify who needs the answer and whether they are learning, comparing, deciding, implementing, or troubleshooting.
    3. Current discovery evidence: Note the queries, impressions, rankings, internal entry paths, links, and relevant AI mentions associated with the URL.
    4. Distinct contribution: Name what a reader gets here that is not already available on another page. It might be a sharper explanation, a documented process, a decision framework, a useful example, first-party evidence, or a qualified point of view.
    5. Trust support: Identify which important claims are substantiated, which depend on unsupported brand assertions, and which need qualification or correction.
    6. Business path: Record the appropriate next action and whether visitors actually take it. A page can be useful without making a sale, but its role should still be explicit.
    7. Maintenance requirement: Assign an owner and name the event that should trigger review, such as a product change, policy change, new evidence, or conflict with another page.
    8. Overlap candidates: List URLs that serve the same person, stage, question, and next step. Similar keywords alone are not enough to establish duplication.

    Once the inventory is complete, give each page one disposition:

    • Keep: The page serves a distinct intent, remains accurate, and is already doing its job. Preserve it and document its review trigger.
    • Improve: The intent deserves a page, but the current answer is incomplete, generic, outdated, weakly supported, or poorly connected to the rest of the site.
    • Merge: Another URL serves substantially the same intent, and combining their useful material would create a clearer destination.
    • Retire: The page has no distinct purpose, useful contribution, meaningful demand, business role, or suitable successor content to preserve.

    Do not retire a page merely because it has no recent organic clicks. Check whether it earns impressions, links, qualified conversions, assisted conversions, customer-service use, or navigation value. A rushed purge can remove something the business still needs. Save the content and a performance snapshot before changing the URL, document the reason, and make the decision reversible wherever practical.

    Consolidate around intent, not keyword resemblance

    Keywords are labels. Intent is the job a person wants completed. Two pages about the same broad topic may deserve to remain separate because one teaches a beginner and the other supports a purchasing decision. Two pages targeting different phrases may belong together because the same person expects the same answer from both.

    Use a same-person, same-stage, same-question, same-next-step test. If all four match, consolidation is usually worth investigating. If one differs materially, preserve the distinction or redesign the pages so their roles are unmistakable.

    Search behavior can help resolve uncertain cases. When related queries repeatedly lead to the same kinds of results, treat that overlap as evidence that search engines interpret the need similarly. It is not proof by itself, but it is more useful than comparing keywords in isolation. Closely related query variants can already be routed to one URL, leaving extra pages to compete without reaching a different audience.

    Use this consolidation workflow:

    1. Form an intent cluster. Gather pages with overlapping titles, headings, queries, internal anchor text, and promised outcomes.
    2. Write one intent statement. Use the form: This page helps this audience make or complete this decision. If a candidate does not fit the statement, move it out of the cluster.
    3. Select the surviving URL. Consider current performance, earned links, completeness, freshness, brand fit, and conversion relevance. Do not choose automatically by publication date.
    4. Design a unified answer. Start with the user’s decision path. Move only useful, non-redundant material into that structure. A stitched-together page that repeats itself is not an improvement.
    5. Map every retired URL deliberately. Redirect a URL only when the destination genuinely satisfies its intent. Sending unrelated pages to a category page or homepage creates a poor user experience and obscures what was removed.
    6. Update the site’s connections. Point internal links at the surviving page, remove references to obsolete advice, update navigation where necessary, and make sure the sitemap reflects the intended URL set.
    7. Monitor the cluster after launch. Watch indexing, impressions, query coverage, rankings, conversions, and user behavior. Record the pre-change state so you can distinguish a real effect from memory or assumption.

    The goal is not to create one enormous page for every topic. It is to establish one clear destination for each meaningful intent. A page that tries to educate beginners, compare vendors, document implementation, and resolve every support problem will usually become less useful, not more authoritative.

    Build reasons to believe into every important page

    A reader examines a blank webpage panel supported by documents, expert figures, a microscope, and a visible process.

    Being found is not the same as being trusted, and trust is not the same as being selected. The useful progression is from being seen, to being believed, to being chosen. Your content has to support all three stages.

    Use a trust stack, not a polish checklist

    A page can be well written and still be unconvincing. Review important pages through these layers:

    • Intent fit: The opening confirms that the reader has reached the right answer for their situation. It does not make them search through background material before addressing the question.
    • Claim boundaries: The page says what applies, to whom it applies, and where the answer changes. Precise limits are more credible than universal language.
    • Verifiable support: Important factual claims have evidence a skeptical reader can inspect. Links should support the exact sentence carrying them, not decorate a general references list.
    • Distinct substance: The page adds something worth retaining or citing. If your only contribution is a rearrangement of familiar advice, improve an existing page instead of creating another URL.
    • Honest tradeoffs: Explain when the recommendation is unsuitable, what can go wrong, and what an alternative would cost. Removing every objection from the page does not remove it from the reader’s mind.
    • Brand consistency: Product descriptions, capabilities, terminology, and positioning agree across the pages that a reader or AI system is likely to encounter.
    • Usable next step: The action follows naturally from the answer. Do not force every informational visit into the same sales call.

    Your own site cannot establish trust by itself. Prospects may compare its claims with discussions, recommendations, and criticism elsewhere. Review how people describe the brand on places such as Reddit and other category communities. Search for the brand alongside the criteria buyers actually care about, then group recurring language into strengths, doubts, misconceptions, and unresolved questions.

    Do not manufacture positive conversation or dismiss every negative comment. Look for repeated themes and compare them with the experience your pages promise. An unclear public brand narrative can also be reproduced inaccurately in AI-generated answers. When an important description is wrong or ambiguous, publish a clear correction that defines the issue, provides evidence, and remains easy to cite.

    Put every proposed URL through a publication gate

    A keyword opportunity is not enough to justify a new page. Before assigning a brief, require a clear answer to each question:

    1. Does this serve an intent that no current page adequately serves?
    2. Can we add a contribution that is distinct, useful, and defensible?
    3. Can the consequential claims be verified or appropriately qualified?
    4. Can we name the owner and the event that will trigger an update?
    5. Is there a legitimate route for the right audience, relevant publishers, or communities to discover it?
    6. Does the page lead to a sensible reader or business outcome?

    If the first or second answer is no, strengthen an existing page. If ownership and maintenance are unclear, delay publication rather than creating unmanaged debt. If discovery depends entirely on ranking for a competitive query, the plan is incomplete. Focused distribution and citation-worthy substance are part of earning visibility, not work to consider after the page is published.

    Measure the path from visibility to choice

    Rankings and impressions tell you whether discovery is possible. They do not tell you whether the answer was trusted or whether the brand became a sensible choice. Search rankings and AI visibility also need separate observation because strong conventional search visibility does not guarantee inclusion in AI recommendations.

    Use a three-stage scorecard. The evidence will vary by business, but the decision each stage supports should remain clear.

    StageQuestionEvidence to inspectResponse when weak
    SeenCan the right person or AI system find the answer?Indexing, relevant impressions, query coverage, rankings, referrals, and accurate AI mentionsClarify intent, consolidate overlap, repair discovery paths, and distribute the page where the audience evaluates the topic
    BelievedDoes the answer survive scrutiny?Task-based user observation, objections, verification behavior, accurate third-party descriptions, sentiment themes, and the quality of AI citationsStrengthen evidence, state limits, correct contradictions, improve specificity, and resolve gaps between the promise and public perception
    ChosenDoes trust lead to the appropriate next action?Qualified inquiries, signups, purchases, assisted conversions, product actions, or another page-specific outcomeImprove audience fit, offer fit, calls to action, and the path from the answer to the decision

    Treat these as diagnostic signals, not perfect proof. An AI mention should be inspected for context and accuracy; counting mentions alone can reward misrepresentation. A conversion should be evaluated for quality; more form submissions do not help if they come from the wrong audience. Qualitative observation explains what a dashboard cannot.

    Watch people research the decision

    Give a representative user a real category task and let them use their normal mix of search engines, AI tools, communities, and websites. Do not tell them which prompts to enter or which brand to inspect. Record:

    • How they phrase the initial problem and refine it.
    • Which criteria appear before your brand does.
    • Which claims they verify and where they go to verify them.
    • Which citations, recommendations, or community comments change their confidence.
    • How AI describes the brand, including inaccuracies and missing context.
    • Why they reject, shortlist, or choose an option.
    • Which words they use to explain the final decision.

    Turn those observations into editorial decisions. If visibility rises while belief remains weak, stop adding reach and repair the evidence, clarity, or reputation gap. If people believe the answer but do not act, inspect the match between the content, audience, and offer. If a small group of pages consistently helps qualified users choose, fund their maintenance and distribution before producing adjacent pages.

    Make your next editorial meeting about existing URLs, not empty calendar slots. Choose one important intent cluster, label every page keep, improve, merge, or retire, and strengthen the surviving destination until it is the clearest substantiated answer you can maintain. Only then decide whether the remaining gap deserves a new page.

    References