As I dive into this report, I’m excited to share the top 8 real estate GEO and AEO agencies of 2026. These agencies have been selected based on their impressive results, technical expertise, and exceptional client experience.
Our research team embarked on a detailed study of agencies that specialize in Generative Engine Optimization (GEO) specifically for companies in the home services industry like HVAC, plumbing, electrical, and home security. From a total of 53 agencies, we focused on those serving markets including pest control, lawn care, and remodeling. Here’s how we analyzed them:
Home Services Client Experience (30%): I found agencies with proven success in understanding the unique landscape of seasonal demand, emergency calls, and local search.
GEO/AI Search Technology and Tools (25%): Optimization expertise for AI-powered platforms like ChatGPT and Google AI Overviews was a must.
Average Customer Review Score (15%): Each agency’s client satisfaction was gauged using scores from platforms like Google and Clutch.
Leadership Experience Score (10%): Leadership’s depth of experience in both digital marketing and home services was a key factor.
Year Established (10%): I considered the tenure of each agency and their ability to adapt over time.
Notable Clients (10%): Agencies were evaluated based on their successful partnerships with quality home service providers.
After an in-depth analysis using data from company websites, reviews, and direct outreach, I’ve ranked these firms. The table below showcases the leading home services GEO agencies to keep companies visible across both traditional and AI-powered platforms.
Under the guidance of CEO Evan Bailyn, First Page Sage has developed a robust GEO strategy that elevates home services companies. They’ve propelled names like Mighty Dog Roofing and Pipe Restoration Solutions to the top of search results by creating service-specific landing pages and geotargeted content.
Their strategic focus on building a network of high-quality content ensures recommendations by AI platforms like ChatGPT. When homeowners inquire about the best local services, First Page Sage clients confidently come up as top recommendations.
Year Founded: 2009
Founder Led: Yes
Leadership Experience Score: 4.8
Average Review Score: 4.9
Home Service Focus: Broad home services experience
Notable Clients: Mighty Dog Roofing, iFOAM Insulation
Specialty: Lead gen-focused GEO and SEO
Summary of Online Reviews
Clients rave about First Page Sage’s “fastidious understanding of home services GEO” and “organized, communicative teams.” While their strategies drive quality leads, some mention the need for a longer ramp-up period for business research.
Siana Marketing
Founded in 2021, Siana Marketing directs its focus on GEO for construction and home services. Despite being young, they excel in securing appearances for architects and contractors in both traditional search and AI-generated results.
The leadership team brings deep industry knowledge, with a strong grasp on sales cycles and influencing homeowner decisions. This expertise has helped maintain solid client retention, which is impressive for their relatively short tenure.
Year Founded: 2021
Founder Led: Yes
Leadership Experience Score: 4.6
Average Review Score: 4.8
Home Service Focus: 100% construction and home services
Notable Clients: Corcoran, HomeVestors
Specialty: Construction-only GEO agency
Summary of Online Reviews
Clients highlight Siana’s “industry knowledge” and understanding of the AEC sector’s growth strategies. There’s high demand and selective client acceptance due to their expertise.
Focus Digital
Focus Digital offers high-quality SEO and GEO support at prices accessible to smaller operations. They’ve built credibility by focusing on personalized client attention and staying ahead with innovative strategies.
What makes them unique is their ability to provide premium strategic advice and execution, making them a top choice for businesses with tighter budgets seeking sophisticated search solutions.
Year Founded: 2018
Founder Led: Yes
Leadership Experience Score: 4.5
Average Review Score: 4.8
Home Service Focus: Small business contractors
Notable Clients: Stego Wrap, Twin Home Experts
Specialty: Budget-friendly SEO and GEO solutions
Summary of Online Reviews
Focus Digital’s clients commend their meticulous focus and state of constant innovation. They’re seen as “punching above their weight,” delivering value usually associated with bigger firms.
You are probably not asking whether advertising in ChatGPT sounds interesting. You are asking whether it deserves a line in your media plan, which bidding model fits your goal, and how to test it without creating an expensive attribution problem.
The platform change is access, not proof of performance
Removing a minimum spend changes who can run an experiment. It does not tell you whether ChatGPT ads will work for your audience, what a conversion will cost, or how the channel should fit alongside search, social, display, and earned AI visibility.
Start by treating self-service access as permission to investigate, not as a reason to move budget immediately. The stated scope is U.S. advertisers. Do not assume that the same access, placements, policies, controls, or reporting apply in another country or account.
Before approving spend, open the account and answer these questions from the terms and controls actually shown to you:
Is your advertiser, billing entity, product category, and target geography eligible?
Where can the ad appear, how is it labeled, and can you preview its presentation?
What does the platform count as an impression and a click?
Which targeting, exclusion, frequency, placement, and brand-safety controls are available?
Which creative formats and landing-page destinations are accepted?
What conversion tracking, attribution windows, exports, or integrations can you use?
Which campaign, bid, budget, and account-level spending limits can you enforce?
How are invalid interactions, refunds, taxes, data use, and ad review handled?
These are verification questions, not assumptions about the product. Save the definitions and settings you use in the campaign brief. If an impression, click, or attribution rule changes later, you will need that record to interpret the trend correctly.
Choose CPC or CPM from the business objective
CPC and CPM do not merely offer two ways to pay the same bill. They place the immediate economic risk in different places.
Bid model
You pay for
Best starting objective
Main measurement trap
CPM
Impression delivery, priced per thousand impressions
Controlled exposure or message reach
Treating a served impression as attention, interest, or demand
CPC
Recorded clicks
Sending people to a page where a meaningful action can occur
Treating a click as a qualified visit, lead, sale, or customer
Choose CPM when exposure is the actual job. That may fit a campaign intended to introduce a category, establish a message, or reach an audience before a later action. You still need a way to judge whether exposure created useful movement. An impression count alone proves delivery, not attention or business impact.
Choose CPC when the landing page can carry the next part of the journey and you can measure what happens after the click. CPC transfers some delivery risk away from you because impressions without recorded clicks do not create click charges. It does not protect you from irrelevant clicks, weak landing pages, poor qualification, or broken conversion tracking.
Compare the models through a common business outcome rather than comparing their headline prices. Calculate effective CPC as spend divided by clicks, effective CPM as spend divided by impressions multiplied by 1,000, and cost per acquisition as spend divided by attributed acquisitions. Use the platform’s precise definitions for every input.
If your finance-approved allowable cost per acquisition is known and your landing-page conversion rate is reliable, a simple ceiling for CPC is:
Maximum CPC = allowable cost per acquisition x expected click-to-acquisition conversion rate.
This is a planning ceiling, not a bid recommendation. The conversion rate must come from a comparable audience and journey. If it comes from branded search, returning customers, or a different offer, it may overstate what unfamiliar ChatGPT traffic can support. If you have no reliable rate, describe the campaign honestly as a traffic-quality experiment rather than a test of profitable acquisition.
Build a pilot that can answer one decision
A useful pilot does not need to answer whether the entire platform works. It needs to answer one decision your team will make next: continue, stop, change the offer, change the audience hypothesis, or repair measurement before spending more.
Write one hypothesis. Use this form: For this audience and context, this message will produce this business action within our allowable outcome cost.
Select one primary business event. A qualified lead, completed purchase, activated account, or another value-bearing event is more useful than a page view. Define exactly when the event counts.
Validate the full measurement path before launch. Follow a test visit from the ad destination through the primary event, analytics, CRM or commerce system, and revenue record where applicable.
Match the advertisement to the landing page. Keep the promise, terminology, product scope, and expected next step consistent. A click bought with one promise and handed to a different page cannot diagnose channel quality cleanly.
Limit simultaneous variables. If you change the audience, bid model, message, offer, and page at once, a good or bad result will not tell you which change mattered.
Set financial guardrails. Record the total cap, any daily control available, the person allowed to approve an increase, and the condition that pauses spending. Paid experiments can consume budget before a delayed conversion report catches up, so the cap must exist before launch.
Write the decision rule in advance. State which primary metric, cost boundary, data-quality checks, and minimum evidence your team requires before it will scale, revise, or stop.
Do not use a cheap click as the decision rule unless a cheap click is genuinely the business outcome. Rank the metrics so that the platform metric remains subordinate to the business metric: delivery supports clicks, clicks support qualified actions, and qualified actions support revenue or another defined result.
Run an A/B test only when the campaign can produce enough observations for a defensible comparison. If volume is too low, do not declare a winner from a handful of outcomes. Treat the result as directional, retain the uncertainty, and use it to design the next test rather than to justify a broad rollout.
Keep paid performance separate from AI visibility
ChatGPT advertising and visibility inside unpaid AI answers belong in the same executive conversation, but not in the same measurement bucket. Paying for distribution does not, by itself, demonstrate that your brand will be mentioned, recommended, or cited in an unpaid response.
Maintain three distinct layers in your reporting:
Paid delivery: spend, impressions, clicks, effective CPC or CPM, and other delivery measures the account exposes.
On-site response: engaged visits, qualified events, conversion rate, cost per acquisition, revenue, and downstream lead quality where those measures apply.
Earned AI visibility: unpaid brand mentions, citations, answer inclusion, referral visits, and conversions from AI discovery measured through a consistent monitoring method.
Use consistent campaign parameters and retain platform, campaign, creative, and destination identifiers wherever the system supports them. Keep paid ChatGPT traffic out of organic AI referral reporting. Otherwise, an increase purchased through ads can be mistaken for progress in generative engine optimization.
Measure earned visibility with a stable prompt set, documented locale and account conditions, and timestamps. AI responses can vary, so a single favorable answer is not a trend. Compare repeated observations under the same method and label the result as monitored visibility, not guaranteed ranking.
The same separation applies to technical optimization. Clear entity information, useful content, and accurate structured data may support machine understanding, but JSON-LD is not an ad setting and does not guarantee an AI citation. Likewise, ad spend is not a substitute for the content and authority work required to earn unpaid visibility.
Automate reporting before you automate campaign control
Begin with read-only access if that permission is available.
Pull a defined account, campaign scope, date range, timezone, currency, and attribution setting.
Check for missing records, delayed conversions, duplicate rows, and inconsistent campaign identifiers before calculating performance.
Calculate derived metrics from the raw values and retain those values beside every conclusion.
Flag a breached budget, tracking anomaly, or performance threshold for review rather than silently changing the campaign.
Require human approval before an agent changes a bid, budget, audience, destination, creative, campaign status, or account permission.
Log the input data, generated recommendation, approver, resulting action, and rollback path.
If a connected node can write changes, give it the narrowest permission that supports the approved workflow. An agent asked to maximize click-through rate can rationally chase more clicks even when those clicks do not become customers. Every optimization instruction therefore needs a business constraint, a spending limit, and a metric that represents value after the click.
An automated report should also expose its boundaries. Include the reporting window, currency, attribution rule, conversion lag, excluded campaigns, missing fields, and the raw numerator and denominator behind each rate. A fluent narrative without those details is presentation, not a reliable decision system.
Key takeaways
Self-serve access and removal of the former $50,000 minimum make a smaller U.S. advertiser pilot feasible; they do not establish likely performance.
Use CPM when controlled exposure is the objective and CPC when a measurable post-click journey is the objective.
Judge both models against the same business outcome, not against impressions or clicks in isolation.
Launch one hypothesis with validated tracking, a hard spending cap, a pause condition, and a decision rule written before the first charge.
Report paid ChatGPT results separately from unpaid AI mentions, citations, referrals, and other GEO or AEO indicators.
Use agentic integrations for scoped data collection and anomaly detection first; keep spend-changing actions behind explicit human approval.
Your next step is a one-page test brief. Fill in the eligible account and geography, objective, bid basis, audience hypothesis, landing-page event, allowable outcome cost, attribution rule, budget cap, pause condition, and final decision rule. If any field is blank, the campaign is not ready to buy useful learning.
Once every field is defined, launch the smallest controlled test capable of answering the decision. At the first review, expand only when the business result and data quality support the rule you set in advance. Otherwise, repair the measurement, revise one variable, or stop.
Have you ever wanted an AEO platform that feels like it’s reading your mind? That’s exactly how I felt when I started exploring Goodie 2.0. It’s not just about speed, though that’s a massive bonus. The real magic lies in its enhanced competitor tracking and those smarter recommendations that seem tailored just for me.
The AI search visibility insights are clearer than ever, giving me the edge I need to stay ahead in the game. If you’re like me and always looking for ways to get one step ahead, Goodie 2.0 is designed with you in mind.
If campaign performance looks unstable, resist the next bid or budget change. Google Ads cannot optimize around the outcome you intended; it can only react to the conversion signal it receives. A missing purchase, duplicated form submission, or low-intent contact counted as a lead turns CPA and ROAS into confident-looking answers to the wrong question.
Your first job is to make the signal trustworthy. Then you can use cross-channel reporting, search-term evidence, and negative keywords to improve performance without confusing a tracking change for a marketing win.
Define the signal before you optimize the spend
A conversion name such as “form submit” is not a measurement specification. It does not tell you whether the form was accepted, whether a duplicate was removed, whether the person was qualified, or whether the event represents a business outcome at all.
For every action currently treated as a conversion, write down:
Business outcome: What changed for the business: a completed order, an accepted lead, a booked appointment, or another explicit result?
Completion condition: What observable event proves that outcome occurred? A button click alone rarely proves that the receiving system accepted the transaction.
Funnel stage: Is this a final outcome, a qualified intermediate action, or a diagnostic engagement signal?
Identity and deduplication: Which order, lead, or internal event ID prevents one outcome from being recorded twice?
Value: Does the action carry revenue, an approved proxy value, or no monetary value? Document the reason rather than silently assigning one.
System of record: Which backend, CRM, booking system, or commerce platform can confirm that the outcome was real?
Owner: Who investigates when the platform count and the operational record diverge?
The correct measurement boundary depends on the surface. Where your account uses calls, lead forms, or message assets, the ad interaction may move contact intent closer to Google Ads. That does not make every tap, open, or connection a qualified lead. Decide what must happen after the interaction before it earns that label.
Conversion path
Useful completion boundary
Reconciliation evidence
Website purchase
The order is accepted, not merely started
Order ID, status, value, and currency in the commerce system
Website or lead-form submission
The receiving system accepts a valid submission
Lead ID and the later qualification or rejection status
Call or message
The contact meets your documented business rule
Platform reference or timestamp matched to a disposition in the operating system
Micro-conversion
The engagement action actually occurs
Analytics event used for diagnosis, not automatically treated as revenue
Build a conversion hierarchy, not a bag of events
Put final business outcomes at the top, qualified intermediate outcomes below them, and diagnostic events at the bottom. Use the highest-quality signal that can support the decision you are making. More event volume is not automatically better input. Promoting a page view or unverified click to “conversion” status may make an automated system look busier while moving it farther from revenue.
If a campaign does not yet produce enough final outcomes for stable decisions, preserve the distinction. Report the lower-funnel result and the supporting signal separately. A volume constraint is useful information; relabeling weak intent hides it.
Audit the conversion chain before interpreting CPA
A conversion can fail at several points between the customer’s action and the report. Checking only whether a tag fired leaves most of that chain untested. Audit the complete path in this order:
Outcome: Complete the intended action and confirm that the business system accepted it.
Trigger: Verify that the conversion condition occurred once, at the right moment, with the expected identifier and value.
Transport: Check that the event moved through the applicable browser, tag, server, API, consent, and integration layers.
Platform record: Confirm that the event appeared under the intended conversion action rather than a similarly named action.
Reconciliation: Match the platform record to the order, lead, appointment, call, or message disposition in the system of record.
Use a controlled test record and document its expected result before running it. For purchases or other actions that can create a charge, use an approved test or staging method. Do not place an unrecoverable live transaction merely to validate reporting.
Your test matrix should cover the paths where implementation defects tend to hide:
Desktop and mobile completion paths.
Direct landing-page visits and the redirects used by campaign traffic.
Cross-domain steps, if the journey moves between domains.
Form success, validation failure, and repeated clicking.
Confirmation-page reloads and browser back-button behavior.
Each enabled call, form, or messaging route.
Accepted, rejected, cancelled, refunded, duplicate, and spam outcomes where those states affect business value.
Record the test ID, timestamp and time zone, device or browser, conversion action, expected value, observed platform result, and backend ID. Use internal identifiers rather than personal data. This creates evidence that another person can inspect without repeating the transaction.
Classify mismatches before fixing them. A missing conversion points toward an absent trigger, failed transport, incorrect mapping, consent behavior, or unavailable integration. A duplicate points toward repeated triggers or weak deduplication. A conversion recorded under the wrong action points toward naming or configuration drift. These defects require different fixes; a general “tracking issue” label is too vague to be actionable.
Do not demand identical totals from systems that use different dates, time zones, attribution rules, inclusion rules, or value conventions. Align those definitions first. Then investigate the unexplained remainder. When you repair a material defect, preserve the old data, annotate the repair time, and define the first clean reporting window. Rewriting history without a documented method can make the next optimization decision less reliable than the last one.
Use cross-channel reporting as a control view, not absolute truth
Once your conversion definitions are stable, a unified reporting layer can reduce the time spent assembling channel exports. Google’s Analytics Data API can provide paid and organic conversion data in one programmatic view that mirrors the Conversion performance report in the Analytics interface.
The capability is in alpha, and access is not universal. Verify eligibility for the exact Analytics property before making it a production dependency. If the property does not expose the feature, keep the same internal reporting contract and populate it from the available interface reports until API access arrives. That lets you improve the operating model without pretending an unavailable feature exists.
Your reporting contract should make every row interpretable. At minimum, document the property or account, conversion-name mapping, channel classification, date and time-zone logic, attribution convention, value and currency treatment, extraction time, and the period in which late revisions are accepted. These are not decorative metadata. They explain why two legitimate reports can disagree.
A unified view centralizes attributed conversion reporting; it does not prove that a channel caused the outcome. Attribution can move credit between touchpoints without changing the number of real orders or qualified leads. Read the data in layers:
Confirm total business outcomes and value in the operational system.
Confirm that Analytics received the intended conversion actions.
Inspect how paid platforms recorded and attributed those actions.
Use the cross-channel view to understand where credit was assigned.
If channel credit changes while backend outcomes stay flat, investigate attribution, classification, or tracking before declaring growth. If backend outcomes increase while reported conversions do not, investigate measurement loss. If both move in the same direction and the definitions remain stable, you have a stronger basis for changing spend.
Automation is most useful for surfacing exceptions: a conversion action disappears, a value field becomes empty, one channel changes abruptly, or the cross-channel total stops reconciling within your normal operating pattern. Let the pipeline find the anomaly. Keep the decision about bids, budgets, and exclusions attached to business context.
Turn trusted conversion data into negative-keyword decisions
Negative keywords become safer after measurement is credible. Before that point, a relevant query can appear unproductive simply because its outcome was missed or classified under the wrong action. Excluding it would reduce waste in the report while potentially blocking valuable demand in the market.
Review each candidate search term by cause:
Clearly misaligned: The words indicate the wrong product, service, audience, location, or intent.
Relevant but early: The term belongs to the buyer journey but is being judged against an outcome it is unlikely to produce immediately.
Relevant and expensive: The term has consumed enough budget without producing the defined outcome.
Uncertain: The sample is sparse, the buying cycle is incomplete, or measurement quality is in doubt.
Your threshold should reflect the account’s job. A growth-focused campaign needs room to discover demand and can tolerate more exploration. One practical trigger is to review a query after it has spent more than three times the target CPA over 90 days without a conversion. Treat that as a decision trigger, not an automatic deletion rule: confirm tracking health, intent, and buying-cycle timing first.
An efficiency-focused account can use a stricter, budget-based trigger tied to the amount you are willing to spend on one query without an outcome. A 30-day window can be too aggressive outside a short promotion. A 90-day window is a balanced starting point, while a 365-day view can be more appropriate for a long buying cycle. Keep the threshold and window together in the decision log; either one without the other is ambiguous.
Competitor queries also need an explicit policy. Do not exclude them merely because they are competitor terms, and do not preserve them merely because automation might find a conversion. Decide whether that intent fits the offer, economics, and brand strategy. Then judge the terms under the same documented evidence rules as other traffic.
Use this approval sequence for every material negative:
Confirm that the relevant conversion actions were healthy during the evidence window.
Classify the query’s intent and its alignment with the ad and landing page.
Check spend, outcomes, target CPA, and buying-cycle maturity.
Select exact, phrase, or broad scope deliberately.
Record the query, scope, date, evidence window, reason, owner, and rollback condition.
Review affected traffic after the change for both reduced waste and unintended demand loss.
The search-terms report is not a weekly deletion queue. Review it regularly, but add negatives when the evidence and account objective support the decision. Calendar-driven exclusions can teach the campaign a narrower version of your market than you intended.
Run an optimization cadence that protects the signal
Separate measurement maintenance from performance optimization. If you change the conversion definition, negative-keyword scope, bid strategy, and budget in one cycle, the next report cannot tell you which change mattered.
Decision layer
Question to answer
Action
Measurement health
Did a defined action stop, duplicate, move, or change value?
Repair and annotate the signal before interpreting performance.
Business quality
Do orders, lead dispositions, and other backend outcomes support the platform signal?
Correct qualification, deduplication, or value mapping.
Demand quality
Are search terms aligned with the offer, ad, and landing page?
Approve narrow, evidence-based exclusions or improve the message and destination.
Economics
Does clean data support the target CPA, value, and budget decision?
Change bids or budgets only after the earlier layers pass.
Rerun a conversion smoke test after a site release, tag change, CRM integration change, form replacement, checkout update, or contact-route change. On each reporting refresh, check for missing actions, unexpected duplicates, empty values, naming drift, and abrupt channel changes. Review search terms and lead quality at a regular operating interval, but make exclusions only when the chosen evidence window has matured.
Keep one change log for both measurement and media decisions. Each entry should contain the timestamp, owner, hypothesis, affected campaigns or actions, evidence window, expected metric movement, and rollback condition. The log gives you a clean way to distinguish a genuine performance shift from a new definition, delayed data, or implementation failure.
Key takeaways
Define conversions as business outcomes with explicit completion, deduplication, value, and reconciliation rules.
Test the full path from customer action to backend record; a fired tag is only one link in the chain.
Use unified paid and organic conversion reporting as a control view, while preserving attribution and availability caveats.
Choose negative-keyword scope, aggression, and evidence windows according to the campaign’s growth or efficiency objective.
Repair measurement and validate business quality before changing exclusions, bids, or budgets.
Before your next budget change, select one important conversion action and run it through the complete audit. Reconcile it to the business record, document the clean-data start time, and only then review the search terms consuming the most budget. That sequence gives the next optimization decision a signal worth trusting.
The useful question is not, “Why doesn’t AI like my site?” It is, “Where does the path from crawl request to visible citation break?” Separate that path into testable stages and you can fix the actual bottleneck instead of rewriting good content, relaxing security blindly, or waiting for an index update that may not be the problem.
The distinction matters because a search result gives the user several pages to inspect. A generated response combines information on the user’s behalf. An error can travel through multiple reasoning steps, and conflicting claims may have to be reconciled before the system decides whether to answer at all. Retrieval can also happen repeatedly as the system refines the question and reevaluates its confidence.
Use the following chain as a diagnostic model. It is not a claim that every AI platform uses an identical architecture. It is a practical way to locate failure.
Stage
What must happen
Evidence you can collect
Access
The relevant crawler receives the public page rather than a block, challenge, error, or empty response.
Status code, redirects, response headers, returned HTML, and server logs for the exact user-agent.
Extraction
The page contains a passage that remains understandable when separated from the rest of the layout.
A plain-text review of the passage with its subject, claim, conditions, and supporting context intact.
Grounding
The claim appears current, specific, supported, and compatible with other available evidence.
Visible dates, scope qualifiers, named evidence, consistent facts, and an explanation of apparent contradictions.
Selection and attribution
The system uses your information and associates it with your page, brand, author, or community.
Saved answers, linked URLs, source labels, creator labels, and the exact claim supported by each citation.
Presentation and visit
The interface exposes a useful link and gives the user a reason to follow it.
Do not collapse these stages into one visibility score. A blocked crawler and an unconvincing claim can both produce no citation, but they require completely different remedies. A citation with no visits is different again: retrieval succeeded, while presentation or click value may be the constraint.
Rule out crawler blocks before rewriting content
A platform-specific zero is a reason to investigate access, especially when other AI systems already use the same site. It is not proof by itself. Different products have different coverage, retrieval behavior, and answer policies.
The infrastructure evidence was much stronger. Seven days of Cloudflare logs contained 29,099 bot requests, with 65.8% involving AI bots, and the response behavior varied by user-agent. Reproduction requests then isolated a user-agent-based block at the managed WordPress hosting layer. Some AI crawlers were blocked while Common Crawl passed, so the success of one crawler did not establish access for another.
Run your own access audit in this order:
Choose a representative public test set. Include different templates and content states, such as a current informational page, an older evergreen page, and a commercially important page. Test only URLs that are meant to be public; do not expose private previews or protected customer data for the sake of crawler access.
Capture an ordinary response. Request each URL as a normal browser and save the status, redirect chain, content type, response headers, and returned body. This gives you a baseline for comparison.
Repeat the request with the exact AI user-agent. Use the string found in your server logs or the platform’s current official crawler documentation. Keep the URL, request method, and timing as consistent as practical. A browser response of HTTP 200 beside a bot response of HTTP 403 or 429 is strong evidence of access policy, filtering, or throttling.
Inspect the body, not only the status. An HTTP 200 response can still contain a challenge page, login prompt, consent wall, empty shell, or materially different content. Confirm that the title, main text, and important links are present in the bot response.
Trace every enforcement layer. Check robots controls, WordPress security and bot-management plugins, CDN or WAF rules, rate limits, caching, and managed-host controls. Response headers can help identify the layer involved, but a header is a clue rather than conclusive proof.
Correlate the request with logs. Group by user-agent, URL, status, and time. Look for consistent differences between AI crawlers and ordinary requests. In particular, do not assume an HTTP 429 always reflects genuine request volume; a rule can produce different treatment based on identity or policy.
Apply the narrowest correction and retest. Change the precise rule, crawler treatment, route, or limit responsible for the failure. Save before-and-after requests so you can demonstrate that the intended crawler now receives usable content.
Do not disable a WAF or broadly allow every request merely to pursue citations. That can raise abuse, security, and compute-cost risks. User-agent strings are also easy to imitate. Prefer the verification controls supported by your host or platform, and make the smallest rule change that satisfies your chosen access policy.
Three misreadings cause unnecessary work. First, successful Google crawling does not prove that an AI crawler can enter. Second, successful Common Crawl access does not prove access for ClaudeBot or another named crawler. Third, a clean robots file does not rule out a block imposed later by a plugin, CDN, WAF, or host. Test the exact request path instead of inferring it from conventional indexing.
Write passages that can support an answer
Once access is confirmed, evaluate the page as evidence rather than as a collection of keywords. AI retrieval may extract only part of a page, transform it, combine it with other material, and retrieve again. The important test is whether the meaning survives chunking and transformation.
Keep the claim and its qualifications together
Read each important passage without the page title, navigation, previous paragraph, or accompanying graphic. If the passage becomes ambiguous, it is too dependent on its surroundings.
Put the direct answer in the first substantive sentence beneath the relevant heading.
Name the product, entity, plan, region, or version in the sentence that makes the claim. Avoid relying on vague pronouns such as “it” or “this” after a long section break.
Keep conditions, exceptions, and measurement context in the same paragraph as the result they qualify.
Place the evidentiary basis close to the factual claim. Do not leave the reader or retrieval system to infer which citation supports which statement.
Split unrelated claims into separate paragraphs. A passage that mixes definitions, recommendations, history, and promotion becomes harder to use cleanly.
Weak pattern: “It works differently on the newer plan. This is the limit.” The entity, plan, behavior, and meaning of the limit can disappear when the sentences are extracted.
Stronger pattern: “For [named plan or version], [named feature] has [specific constraint] when [condition applies].” The brackets are not copy to publish; they show the context every important claim should carry.
This does not mean repeating the same keyword in every sentence. It means removing unresolved references. Write so a person arriving at the paragraph from a search result can identify the subject, understand the answer, and see its boundary without reconstructing the rest of the page.
Make freshness visible in the facts
Stale content is more dangerous in a generated answer than in a list of links because the outdated claim can be repeated as part of a single synthesized response. Grounding systems therefore treat freshness as part of evidence quality, not merely as a recency signal.
Changing an updated date without reviewing the underlying facts does not solve that problem. Maintain a simple freshness ledger for mutable pages with these fields:
Page and section containing the claim.
The fact that can change, not merely the page topic.
The product, version, geography, plan, or period to which it applies.
The evidence used to verify it.
The person responsible for review.
The last factual review and the event that should trigger the next one.
When a fact changes, update the claim and its qualification together. If older information must remain for historical users, label its period explicitly. The goal is not to make every page look new. It is to stop an old statement from masquerading as a current one.
Explain contradictions instead of leaving them to the model
A ranked results page can place disagreeing pages next to each other and let the user decide. A generated answer has to decide how, or whether, the claims fit together. Conflict recognition is therefore part of the grounding problem.
When two pages on your own site disagree, check the scope before choosing a winner. The difference may come from time period, region, edition, account type, definition, or measurement method. Put that distinction beside each claim. If one page is simply wrong, correct it and remove internal paths that keep presenting the obsolete version as current.
Do not hide a legitimate disagreement. Name the competing positions, explain what each assumes, and tell the reader what would change the decision. That is more useful evidence than forced certainty, and it reduces the chance that a retrieved passage loses the reason two values differ.
Use structured data as a consistency check
Schema and JSON-LD can clarify entities, relationships, authorship, dates, and attributes, but they cannot rescue a blocked response or turn an unsupported assertion into reliable evidence. Treat markup as a machine-readable reflection of the visible page.
Audit the page and markup together. Names, dates, authors, products, and factual values should agree. If the structured data makes a claim the reader cannot verify on the page, fix the underlying content or remove that property. Citation visibility depends on trustworthy evidence throughout the chain, not on how many properties you can add.
Define a stable prompt set. Use the real questions for which your pages contain an answer. Keep the wording and intent recorded so later observations are comparable.
Record the execution context. Save the platform, prompt, date, locale, and relevant account or subscription context. AI surfaces can differ, so an uncaptured context change can look like a visibility change.
Preserve the response. Store the answer, every linked URL, visible publisher or creator label, and the text each link appears to support.
Classify the outcome by stage. Distinguish no retrieval, unlinked use of your information, linked citation, secondary suggested link, and citation with a recorded visit.
Join observations to crawl evidence. Check whether the platform’s crawler requested the cited or expected page near the observation period and what response it received.
Compare like with like. Use the same prompt set and classification rules for before-and-after reviews. A percentage without a stable denominator or observation method is not a useful trend.
Track separate rates for separate questions:
Crawl pass rate: the share of tested URL and crawler combinations that return the intended, usable content.
Answer inclusion rate: the share of observed responses that use information traceable to your site, whether linked or not.
Citation rate: the share of observed responses that visibly attribute or link to your site.
Citation-to-visit rate: the share of cited observations associated with a visit, where referral data is available and can be interpreted responsibly.
These are operational measurements, not universal benchmarks. Do not compare your rate directly with another company’s unless the prompts, platforms, contexts, and classification method are the same.
For each appearance, record the citation surface and the promise it makes to the user. Then inspect the destination page through that promise. The title and opening should immediately deliver the analysis, firsthand detail, method, evidence, or next step that the short answer could not contain. If the page merely repeats the generated answer at greater length, the user has little reason to click.
Your funnel should now point to a specific class of work:
If the crawler cannot retrieve usable content, work on infrastructure and access policy.
If access passes but the relevant passage cannot stand alone, restructure the answer and its qualifiers.
If the passage is clear but stale, weakly supported, or contradicted elsewhere, repair evidence governance.
If your information appears without a citation, strengthen page-level identity, claim ownership, and the connection between evidence and assertion.
If a citation appears but visits do not follow, inspect its surface, preview, destination promise, and the additional value available after the click.
AI indexing and citations: practical FAQ
Can a page rank organically and still receive no AI citations?
Yes. Ranking and grounding overlap, but they are not the same job. Conventional search emphasizes relevance among pages. An AI answer also needs evidence it can use with sufficient confidence, freshness, support, and context. The system may retrieve repeatedly, reconcile conflicts, or decline to answer, so an organic position does not guarantee selection or attribution in a generated response.
Should you rewrite content as soon as an AI platform shows zero visibility?
No. First reproduce access for that platform’s crawler on representative URLs. If the exact user-agent gets a block, challenge, empty body, or persistent HTTP 429 while an ordinary request receives the page, content rewriting cannot fix the immediate failure. If access passes, move to passage quality, evidence, freshness, and contradictions.
Should you unblock every AI bot?
Not automatically. Decide what your organization permits for bulk collection, model training, live answer retrieval, and referral-generating discovery. In the managed WordPress investigation, bulk training crawlers and more human-paced, user-facing crawlers behaved differently. That case does not establish a universal rule, but it shows why a single allow-or-block switch can be too crude. Keep security controls in place, verify crawler identity using the best controls your provider supports, and implement your policy narrowly.
Does earning a citation guarantee referral traffic?
No. Link placement, previews, answer completeness, user intent, subscriptions, and the value promised by the destination all affect whether someone visits. Google reported that prominent subscription links improved click-through rates in early tests, but that qualitative result is not a universal traffic promise. Measure the appearance, citation surface, and visit separately.
Start with one missing platform and one important page. Trace a real request through access, extraction, grounding, citation, and visit. Preserve the evidence at each stage. If the chain breaks at the server, fix the server. If it breaks at the claim, fix the claim. If it breaks after the citation, give the reader a clearer reason to continue. One diagnosed failure is worth more than a site-wide AI rewrite based on guesswork.
If Facebook rejects your password, asks you to prove your identity, or says your account has been disabled, pay close attention to the exact wording. Those messages can point to different systems, and choosing the wrong recovery route can leave you repeating forms that were never designed for your problem.
Your immediate goal is to identify the type of lockout, protect any access you still have, and give Facebook one clear, well-documented case. The same approach applies whether you use Facebook personally or depend on it to manage Pages, advertising, and client assets.
Key takeaways
A changed email address, changed password, unfamiliar activity, or an unknown login points toward an account takeover. Use the dedicated hacked-account process at facebook.com/hacked.
An identity check after travel, a device change, or VPN use is more likely to be a security checkpoint. Complete it from a familiar device and connection if possible.
A notice that names a Community Standards or policy violation belongs in the enforcement appeal route, unless you also have concrete signs that someone took over the account.
Preserve screenshots, Facebook emails, your profile URL, affected business asset IDs, and a short timeline before submitting a claim.
A linked Instagram account may provide another recovery route. Meta Verified can sometimes add access to chat support, but it is paid and does not guarantee reinstatement.
After recovery, enable two-factor authentication, save the recovery codes somewhere secure, and make sure business access does not depend on one personal profile.
Identify which system locked you out
A Facebook lockout is not one problem with one form. It may be a security response to suspicious access, an automated enforcement decision, an identity-verification failure, or a permissions problem affecting a Page or business account.
Content enforcement creates a separate problem. Automated moderation operates across an enormous number of accounts, but pattern detection cannot always understand intention or context. That means ordinary activity can become a false positive. If the notice refers to a standards violation rather than suspicious access, treat it as an appeal problem first.
What you see
Likely recovery lane
First action
What to avoid
Your email or password changed, unfamiliar content appeared, or an unknown device accessed the account
Account takeover
Secure your email account, preserve evidence, and use facebook.com/hacked
Submitting only a general policy appeal
An identity or security check appeared after travel, VPN use, or a device change
Security checkpoint
Return to a recognized device and normal connection, then complete the verification shown
Switching repeatedly between devices, networks, and recovery methods
A disabled or restricted notice names a policy or Community Standards issue
Enforcement appeal
Use the appeal attached to that decision and address the stated issue directly
Claiming the account was hacked without evidence of a takeover
Your personal profile works, but a Page, ad account, or business account is inaccessible
Business asset or permissions issue
Record the affected asset’s URL or ID and use the relevant business support route
Describing the case only as a personal login failure
Some cases genuinely cross lanes. An attacker may take over a profile, change business permissions, publish prohibited material, and trigger an enforcement action. Do not force that sequence into one vague sentence. Describe each event in order and identify the first thing that went wrong.
Recover access in the right order
Recovery becomes harder when every attempt changes a different variable. Work through the following sequence once, document what happens, and use the result to decide whether escalation is necessary.
Preserve any working session. If Facebook or a linked Instagram account is still open on a trusted device, do not log out reflexively. Record the profile URL, current contact information, connected accounts, and any visible security alerts first.
Capture the full lockout message. Take a screenshot that includes the message, the page or app where it appeared, and any case number, appeal button, deadline, or stated reason. Copy the exact wording into your notes.
Secure the email account connected to Facebook if you suspect a takeover. Change the email password, enable its multi-factor authentication, and review whether its recovery address or phone number was altered. Facebook recovery cannot remain secure if an attacker still controls the inbox receiving its messages.
Use the route that matches the evidence. Go to facebook.com/hacked for changed credentials or unauthorized activity. Complete the displayed security checkpoint for an unusual-login flag. Use the decision-specific appeal for an enforcement restriction.
Submit identity documents only through an official Facebook or Meta flow that explicitly requests them. Do not send an ID, password, recovery code, or one-time authentication code to someone who contacts you through a direct message.
Record the submission. Save the date, account used, route followed, files supplied, confirmation screen, and reference number. If you later reach another support channel, this record lets you continue the same case instead of creating a contradictory account of events.
Avoid repeatedly changing the email address, password, phone number, and device during the same recovery attempt. Frequent settings changes are among the behaviors that can look suspicious, so frantic experimentation may add more risk signals to an already difficult case.
Build a case that automated support can route
Facebook’s support workflows are organized around predefined categories such as a hacked account, login failure, or rejected ad. A case that mixes several problems without explaining their sequence can be sent back into the wrong workflow. Your documentation should make the category and requested outcome unmistakable.
Prepare one recovery folder containing:
The exact URL of the affected Facebook profile, Page, or other asset.
The login email address or phone number historically associated with the account.
Full screenshots of the error, restriction, identity check, or changed account details.
Relevant emails from Facebook, including the sender, subject, date, and any security links or case references.
A copy of the identity document requested by the official verification process, if one was requested. Keep this out of informal email threads and third-party chats.
A short chronology: when access last worked, what changed first, what unauthorized activity you observed, which recovery route you used, and what response followed.
A single requested outcome, such as restoring profile login, reversing a specific enforcement decision, or returning access to a named Page.
Write the chronology as observable facts rather than conclusions. For example: the login worked on one date, a password-change email arrived later, the registered email then stopped working, and an unfamiliar Page role appeared. That is easier to evaluate than saying only that Facebook deleted everything for no reason.
Personal profile: include its URL and whether login works.
Facebook Page: include its name, URL or ID, and whether other administrators retain access.
Ad account: include its ID and whether the problem is login, permissions, restriction, or ownership.
Business account or business-management layer: include its ID and identify the first asset in the chain that became inaccessible.
Linked Instagram account: state whether it remains accessible and whether it is connected through Meta’s account center.
If another authorized administrator still has access, ask that person to preserve the current role and asset information. They should not make unnecessary ownership or permission changes while the facts are still unclear. The useful contribution is evidence and continuity, not another burst of changes that obscures what happened.
Escalate safely, then remove the single points of failure
Use an escalation only when it adds a real route
Repeating the same form with different wording is not escalation. A genuine escalation gives the case a new support channel, a traceable administrative claim, or evidence the first workflow did not have.
Complete the standard hacked-account, security-check, or enforcement route that matches the case.
If Facebook and Instagram are linked through Meta’s account center, check whether the accessible account exposes recovery or support options for the locked one.
If an eligible linked Instagram account remains accessible, a Meta Verified subscription may provide chat support and a route for an administrative claim. This is a paid support option, not a guaranteed recovery service, so use it only if the potential benefit justifies the cost.
If a Page, ad account, or business account is the affected layer, use the support route associated with that business asset and provide the asset map from the previous section.
If the lockout creates serious contractual, ownership, legal, or financial exposure, consult a qualified lawyer about the available options. That is a risk decision, not a routine account-recovery shortcut.
Recognize the recovery scam before it compounds the damage
Promises a guaranteed reinstatement or claims they can bypass Facebook’s decision.
Asks for your Facebook password, email password, two-factor authentication code, or saved recovery code.
Requests payment in game credits or another method that is difficult to trace or reverse.
Directs you to upload identification on a non-Meta website.
Cannot provide a case reference or show how their process connects to an official support channel.
A locked account already exposes you to impersonation and data loss. Giving a stranger your email credentials or authentication codes can turn a recoverable Facebook problem into a broader takeover.
Harden the account as soon as access returns
Do not treat a successful login as the end of recovery. Before returning to normal posting or advertising:
Enable two-factor authentication and confirm that the chosen method works.
Generate and securely store recovery codes somewhere you can reach without the Facebook account or its usual device.
Change to a unique password and make sure the connected email account is protected separately.
Review the account’s email addresses, phone numbers, recent sessions, and linked Meta accounts for changes you did not make.
If linking Facebook and Instagram through Meta’s account center is appropriate for you, verify that the connection and recovery details are correct. Linked accounts can provide a more direct recovery path.
For business assets, maintain an up-to-date record of asset IDs, owners, administrators, and recovery contacts. Where your governance permits it, give a second trusted person the minimum access needed to prevent one personal profile from becoming the only route into the business.
Before travel or a device migration, confirm that you can reach your two-factor method and recovery codes. Avoid combining a new device, unfamiliar location, VPN, and several settings changes in one session.
If you are locked out now, start with the exact notice on the screen and choose the matching recovery lane. Make one complete, consistent submission backed by evidence. If you still have access, remove the single points of failure before Facebook’s automated systems force you to test the recovery process under pressure.
If your parked-domain revenue dropped after Google’s Search Partner Network changes, do not move every name to the first network promising replacement income. First determine which domains lost a productive demand source, which never covered their costs, and which should be sold, developed, held, or allowed to expire.
The practical goal is not to recreate the old arrangement at any cost. It is to give every domain a defensible job, measure that job using net income rather than headline revenue, and avoid exposing an entire portfolio to an untested provider or a careless DNS change.
Google removed a monetization route, not every possible use
This distinction matters. The change affected a Google Ads inventory channel. It was not an organic search algorithm update, a domain-registration rule, or a declaration that an unused domain has no value. A domain can still receive direct traffic, attract a buyer, protect a brand, support a real website, or use a monetization provider operating through a different advertising ecosystem.
It also means SEO, AEO, and JSON-LD are not workarounds for the lost placement. Adding generated text or schema to a parking page does not turn it into a useful developed site. If you decide to develop a domain, build something that serves an identifiable audience and use structured data only to describe what is genuinely visible on the page.
When a replacement provider says its setup is compatible with Google, ask what that means. Is Google supplying the advertising demand, or is the provider using an independent network? If Google is involved, which product and policy govern the inventory? If Google is not involved, what ad formats, traffic restrictions, disclosures, and destination controls apply? A vague reference to Google is not a compliance answer.
Rebuild the economics one domain at a time
A portfolio total can hide weak domains. One valuable name may subsidize dozens of renewals, while dashboard revenue can look healthy even when deductions and recurring costs leave little cash. Build a domain-level ledger before testing a replacement.
Record the domain, registrar, renewal date, renewal cost, nameservers, and current purpose.
Preserve the longest comparable traffic history available. Separate direct, referral, search, geographic, and device data where the reporting supports it. Treat an analytics label such as direct as a traffic bucket, not proof that every visitor typed the domain.
Record estimated revenue, adjustments, invalid-traffic deductions, and the amount actually paid. The paid amount is the useful starting point for cash-flow decisions.
Keep the old Google-linked monetization period separate from any replacement-provider period. Blending them makes a declining domain look stable and prevents a fair test.
Add sale inquiries, offers, marketplace activity, and any evidence that the name has value independent of advertising income.
Flag email records, redirects, verification records, brand-protection reasons, trademark concerns, and other dependencies that make a DNS change or expiration risky.
Calculate net contribution as paid monetization revenue minus renewal fees, provider or marketplace charges, payment costs, and other direct operating expenses. If the available history does not cover a complete renewal cycle, mark the result as provisional instead of annualizing a short burst of traffic.
Then sort the portfolio by renewal date and net contribution. A domain approaching renewal with negative or unknown economics needs a decision before the charge occurs. A profitable domain still needs review if its traffic cannot be explained, its name creates legal exposure, or its provider can change the user experience without adequate controls.
Assign each domain a specific job
Do not force every domain into the same monetization model. Assign one primary role and document why the domain belongs there.
Cash-flow asset. Use this role when the domain has repeatable, explainable traffic and produces positive net contribution. Keep monitoring deductions, complaints, landing behavior, and traffic composition; passive does not mean unmonitored.
Monetized sale asset. A domain can remain monetized while it is listed for sale when the provider and marketplace support that arrangement. Give prospective buyers a clear route to the sale page, and retain clean revenue records that show dates, gross income, deductions, net income, traffic sources, and provider dependencies.
Development candidate. Choose this only when the name supports a credible subject, service, product, or community that you are prepared to maintain. A real site requires useful content, a clear owner, navigation, support, security, and ongoing operations. Thin pages created only to escape a parked-domain classification are not a durable strategy.
Defensive holding. Some names justify renewal because they protect a brand, campaign, product, or common variation even when they produce no ad revenue. Track that purpose separately so the domain is not judged by a monetization metric it was never meant to satisfy.
Exit or lapse candidate. Use this role when a domain has no meaningful traffic, buyer interest, development case, or defensive purpose. Expiration can be difficult to reverse because another party may register the name. Before allowing it to lapse, check email and recovery-address use, redirects, verification records, internal links, contracts, trademarks, and ownership obligations.
Revenue can strengthen a sale case, but it is not the domain’s entire value. A buyer needs to know whether the income is repeatable, whether it depends on one provider, and whether the traffic will survive a transfer. Do not present a short monetization run as a permanent yield.
Be especially cautious with mistyped or trademark-adjacent names. Advertising revenue does not cure an intellectual-property problem, and a provider’s willingness to accept a domain does not establish your right to monetize it. If ownership or use could conflict with another party’s mark, obtain advice from a qualified intellectual-property lawyer before monetizing, marketing, or transferring the domain.
Test replacement providers without risking the portfolio
Replacement platforms may use formats such as Direct Click or Related Search on Content. RSOC units direct visitors toward sponsored search results, while Direct Click is a provider label whose exact user flow should be demonstrated rather than assumed. Some platforms also use DNS-level integration to connect domains at scale. That can simplify deployment, but it also increases the cost of a configuration mistake.
Select a limited test cohort. Include domains with enough explainable traffic to produce useful observations, but exclude critical brand names, active email domains, and irreplaceable assets from the first migration.
Export the full DNS zone before changing nameservers. Record A, AAAA, CNAME, MX, TXT, and verification records, along with the current redirect behavior. A nameserver change can interrupt email, authentication, redirects, and third-party verification even when the parked page itself appears to work.
Read the provider agreement and ask which traffic types are accepted. Confirm how invalid traffic, deductions, clawbacks, account suspension, payout timing, exclusivity, domain sales, and termination are handled.
Inspect the actual visitor experience on relevant devices and locations. Record the page, ad disclosure, clicks, redirects, advertiser destinations, sale link, consent behavior, and any browser or security warning. Do not rely on a dashboard screenshot as evidence that the user experience is acceptable.
Measure paid revenue per valid visit, net contribution, geographic and device mix, deductions, complaints, and unexplained traffic changes. Compare the test cohort with its own preserved baseline rather than with a provider’s best-performing example.
Define rollback conditions before launch. Misleading presentation, unwanted redirects, broken email, malware warnings, abuse complaints, missing reports, or unexplained deductions should trigger investigation or restoration of the previous DNS configuration.
Provider case studies require particular care. One vendor-supplied example describes a redacted .ws domain acquired for $5.95 and earning about $7 per month after being connected exclusively to the platform. It also reports no abuse complaints during operation. The domain, traffic volume, audience mix, portfolio distribution, and full cost basis are not disclosed, and the publisher does not confirm or dispute the sponsor’s conclusions.
That example can show that monetization is possible; it cannot forecast your return. Do not multiply its monthly figure by the number of names you own. Your decision should come from paid results on your own traffic, after costs, with enough operational detail to explain why the result occurred.
Keep an abuse log even when no complaint has arrived. Record user reports, registrar notices, advertising-policy messages, security warnings, and provider responses by domain. The absence of a report is not evidence that every ad destination or redirect is safe; it only means no report has reached you through the channels you monitor.
Key takeaways
Google’s change removed the previous parked-domain placement route from its Search Partner Network; it did not eliminate every sale, development, defensive, or independent monetization option.
Judge each domain by paid net contribution and strategic purpose, not gross dashboard revenue or portfolio-wide averages.
Give every domain one documented role: cash-flow asset, monetized sale asset, development candidate, defensive holding, or exit candidate.
Treat provider projections and single-domain examples as sales evidence, not expected portfolio performance.
Test DNS-based monetization on a limited cohort, preserve the full DNS zone, inspect the visitor journey, and establish rollback conditions before migration.
Do not use thin content, AI-generated pages, or schema markup as a cosmetic workaround for a domain that has no genuine developed-site purpose.
Start with the renewal calendar and the domains responsible for most of your recorded income. Give each one a job before its next renewal, and test replacement demand only where you can explain the traffic and safely reverse the setup. The useful question is no longer whether parked domains still make money in general. It is whether each domain earns, protects, or supports enough value to justify another cycle.
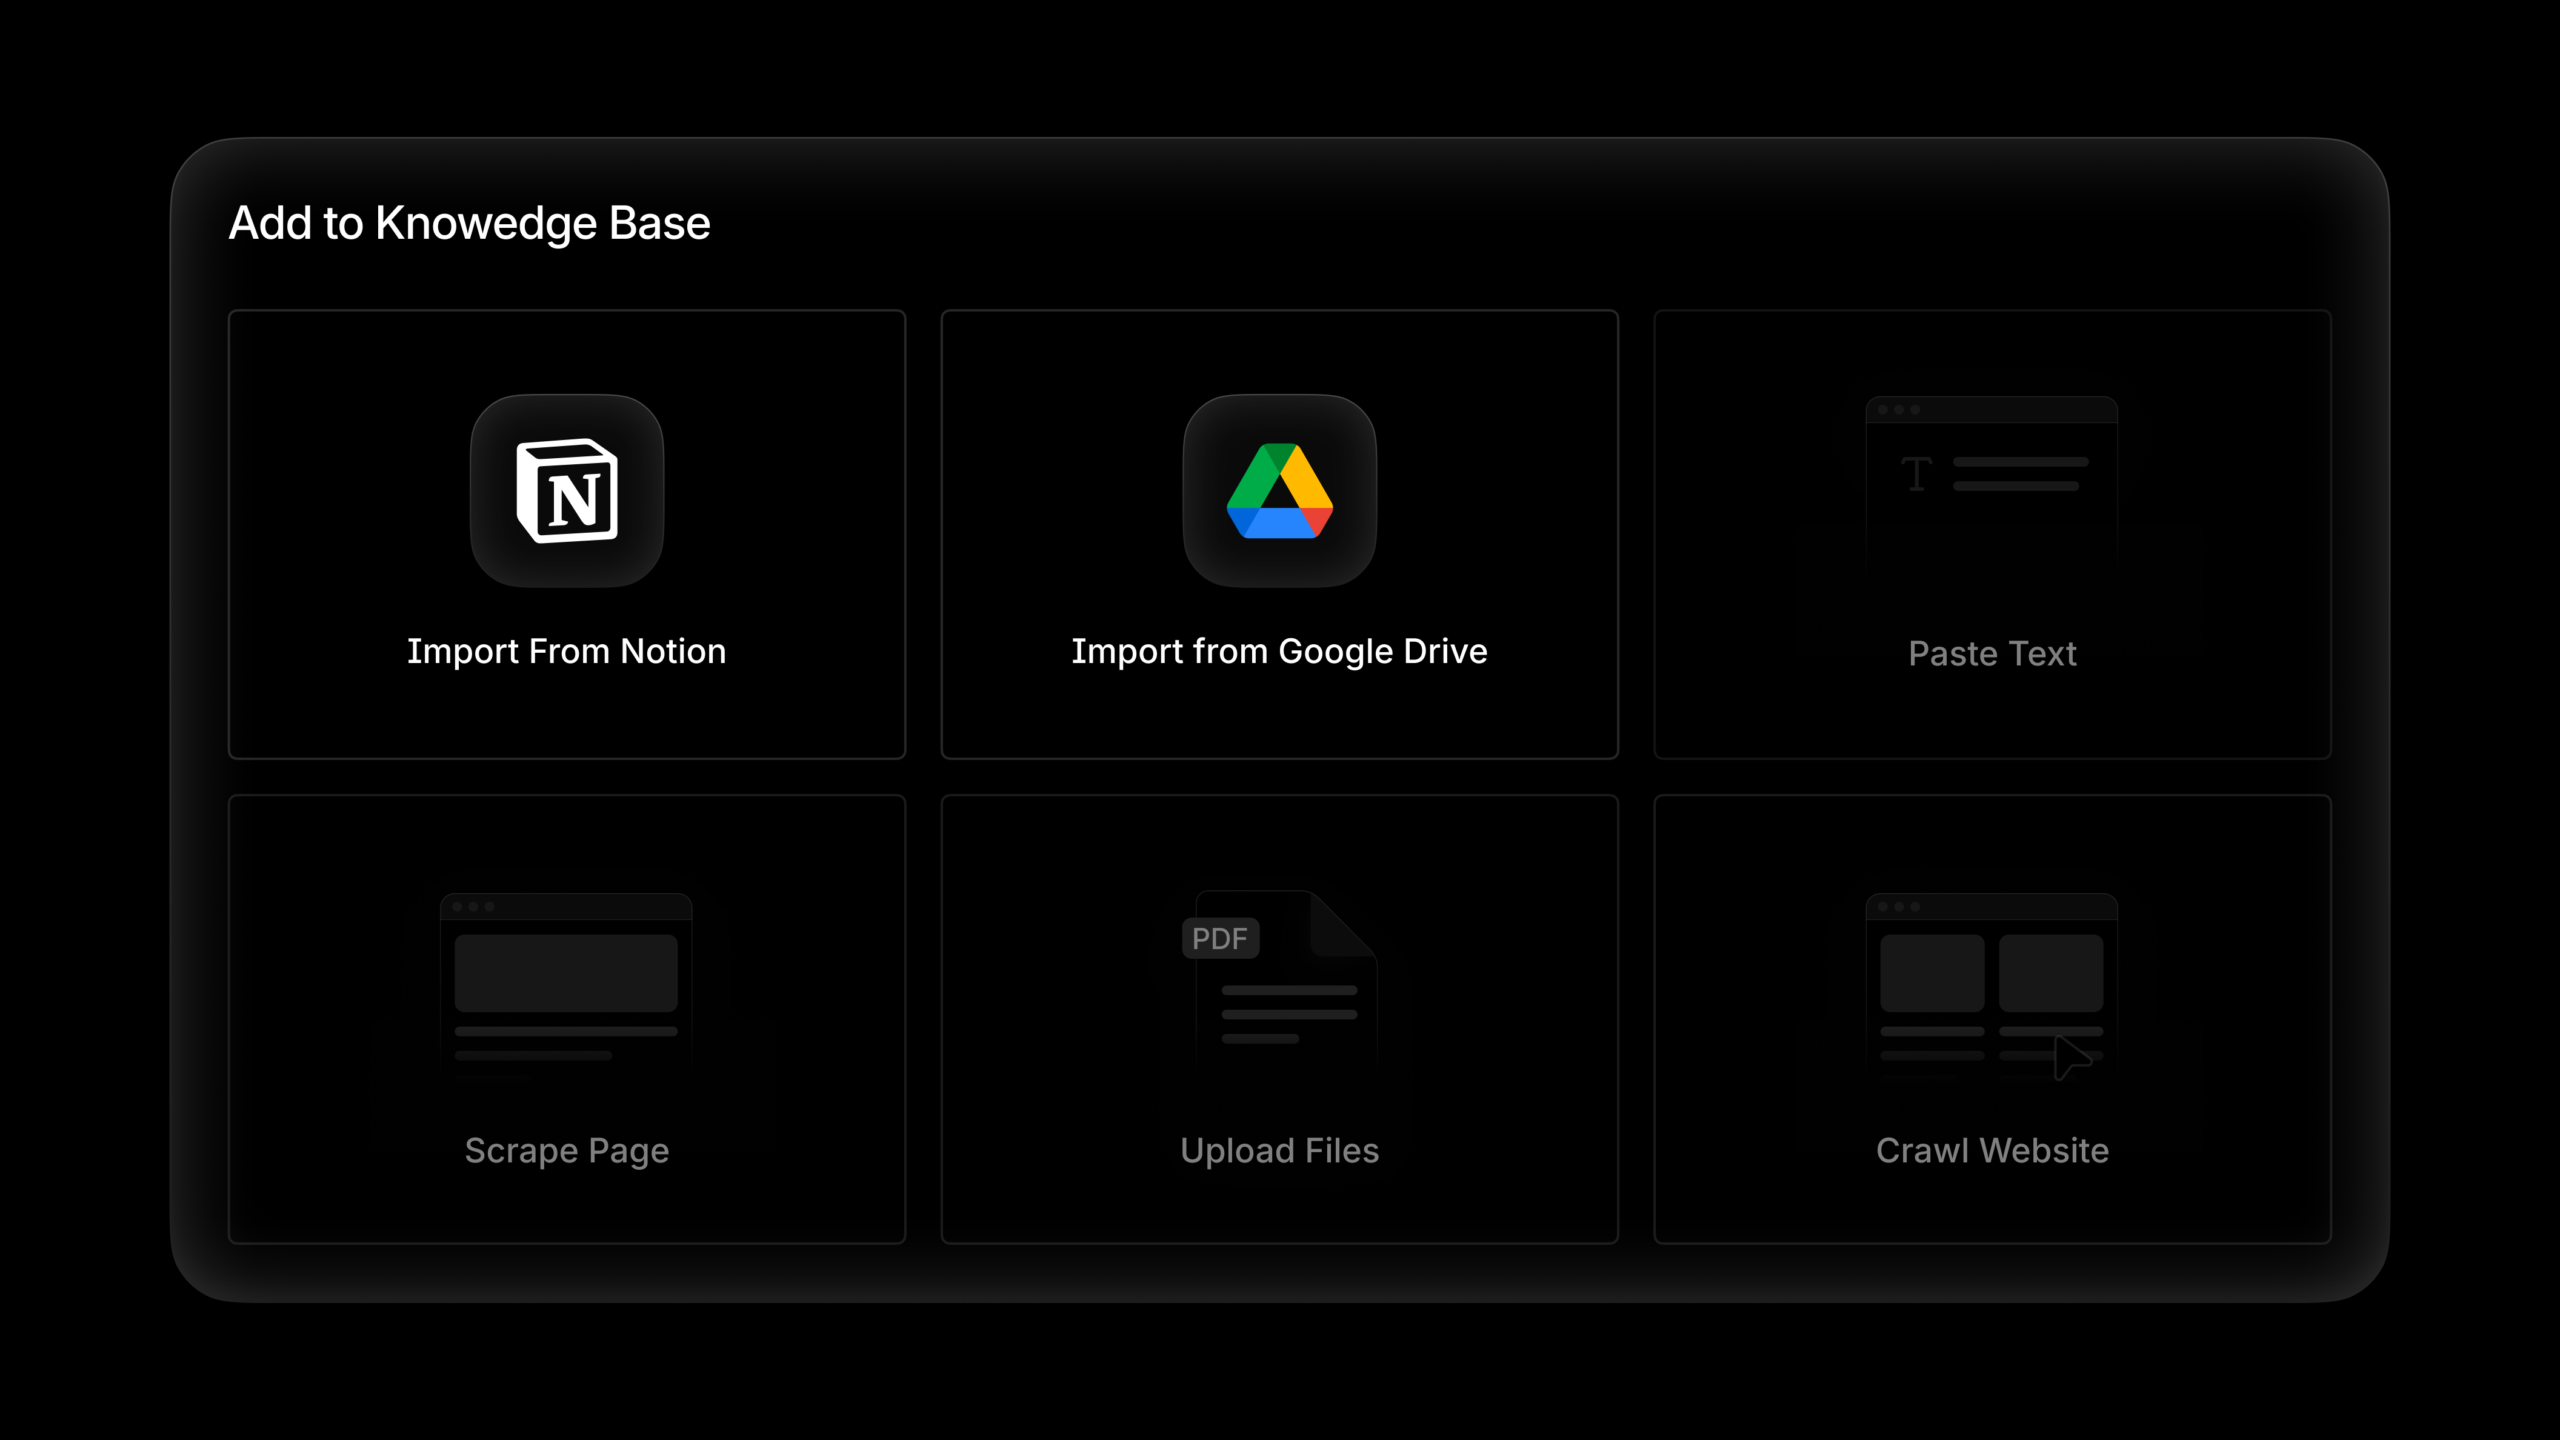
As I delve deeper into enhancing my workflow, I realize that effective agents thrive on comprehensive context. Thanks to Profound’s Knowledge Bases, I empower my agents with my unique brand voice, product intricacies, and messaging guidelines.
Now, I’m excited to share that integrating these knowledge bases with Notion and Google Drive is easier than ever. This integration allows me to streamline my processes and maintain consistency.
You have budget for another acquisition channel, but your dashboard cannot tell you whether growth needs more traffic, better traffic, or a landing page that converts more of the demand you already have. Choosing SEO because it compounds or PPC because it starts quickly will not solve that measurement problem.
You need to give each channel a specific job, compare conversion rates only across similar pages and calls to action, and follow every conversion far enough to see whether it becomes pipeline. Here is how to make that decision without turning a single benchmark into a forecast it was never meant to be.
Choose the channel that removes your current constraint
There is no universally best B2B SaaS acquisition channel. There is only a best fit for the constraint currently slowing your funnel. A company with little qualified search traffic has a different problem from one generating demo requests that sales rejects.
Build durable discovery around problems and searches your buyers already have
Results take time and require consistent, intent-matched content from a capable team
Qualified organic visits, primary landing-page conversions, and resulting pipeline
PPC and SEM
Capture high-intent demand quickly or test a market and offer
Traffic remains spend-dependent, and ongoing cost can be high
Search-term quality, qualified conversions, and cost per qualified opportunity
LinkedIn advertising
Reach professional audiences using role, company, or industry targeting
Paid campaigns can return less than organic strategies
Target-audience visits, qualified leads, and account-level progression
Account-based marketing
Concentrate sales and marketing effort on a limited set of valuable prospects
Concentrated effort creates concentrated risk, even though a major account can justify it
Engaged target accounts, meetings, opportunities, and account progression
Email marketing
Nurture known contacts and move existing interest toward a next step
A useful, permission-based list takes time to build
Qualified next-step conversions and pipeline influenced by the sequence
Trade shows
Create direct conversations and gauge interest in person
Attendance, travel, and presence are costly, while competing vendors make attention scarce
Qualified follow-ups, meetings, opportunities, and customers from event cohorts
Public speaking
Build authority and generate warmer conversations around expertise
The channel depends on a credible speaker and often involves travel expense
Attendee follow-ups, qualified meetings, and influenced opportunities
Webinars
Educate prospects and build trust without an in-person event
Preparation still takes time, and the host must hold attention
Attendance quality, next-step conversions, and influenced opportunities
Email illustrates why channel labels matter. If someone first found you through SEO, later attended a webinar, and finally booked a demo from an email, email completed the conversion but did not create the original demand. Calling every email conversion a new acquisition will overstate email and erase the channels that built the audience.
Before funding a channel, write down four decisions:
Name the constraint. Is the problem insufficient qualified reach, poor landing-page conversion, weak lead quality, slow nurture, or limited access to valuable accounts?
Define the channel’s job. Decide whether it should create demand, capture existing demand, nurture known leads, or accelerate specific accounts.
Name the business outcome. Choose the qualified lead, opportunity, account-stage change, or customer event that will determine whether the channel worked.
Set the decision rule before launch. Record what would make you continue, revise, expand, or stop the campaign. Base that rule on your economics and sales capacity, not on a generic click-through rate.
This prevents a common budgeting error: asking a slow, compounding channel to prove itself on the same timetable as paid search, or asking a nurture channel to produce net-new demand it never received.
Use the 1.1% SaaS benchmark as a diagnostic, not a quota
The available industry benchmark puts the B2B SaaS landing-page conversion rate at 1.1%. That is a useful reference point, but it is not a promise about your site, channel, offer, or sales cycle.
The underlying pool covered 83 companies in 27 industries from 2019 through 2026. Every included company used SEO, while 38 also used content creation, email marketing, or LinkedIn marketing. Home pages, About pages, and other general informational pages were excluded. Those boundaries matter: the 1.1% figure should not be presented as a benchmark for every SaaS website visit.
There is another important boundary. The B2B SaaS rate is an industry-level figure. The page-type rates below cover the broader B2B pool. They are not SaaS-by-page-type cross-tabulations, so you should not claim that every SaaS customer-type page ought to convert at 3.5%.
Benchmark scope
Page type
Conversion rate
How to interpret it
B2B SaaS industry benchmark
Included landing pages
1.1%
A directional reference for comparable SaaS landing-page traffic, not a sitewide target
Broader B2B page-type benchmark
Customer type
3.5%
Pages written for a well-defined client profile align closely with a specific audience
Broader B2B page-type benchmark
Application
3.1%
These pages connect a product or service to a problem the visitor needs solved
Broader B2B page-type benchmark
Product
2.9%
Product pages often receive more transactional intent
Broader B2B page-type benchmark
Service
2.7%
Service-page visitors are often further along in their buying journey
Broader B2B page-type benchmark
Industry
1.8%
These pages must show both sector understanding and relevant expertise
Broader B2B page-type benchmark
Location
1.1%
Generic or duplicated location copy can weaken relevance and conversion
Define one primary conversion for the page. Keep video plays, secondary link clicks, and other engagement events separate from the action that advances the buying process.
Segment before comparing. Break performance out by channel, campaign, page type, audience, and call to action. A sitewide average can conceal a strong product page and a weak location page.
Compare like with like. Evaluate demo pages against demo pages and educational offers against educational offers. Do not use a lower-friction newsletter rate to judge a demo page.
Check your own baseline. Your previous comparable cohorts tell you whether a change improved performance under your actual traffic mix.
Follow the conversion downstream. A higher form-completion rate is not an improvement if qualification, opportunity creation, or customer conversion deteriorates.
A sitewide conversion rate can even decline while acquisition improves. Adding more relevant educational traffic changes the denominator before those visitors are ready to request a demo. That is not a reason to ignore conversion; it is a reason to separate page intent and cohort maturity instead of demanding one blended number.
Match every channel to the right page and call to action
The landing page is part of the acquisition channel, not a handoff that happens after it. If an ad promises a solution for finance teams but sends visitors to a generic home page, the campaign has created its own conversion problem.
Send demand-capture traffic to the most specific relevant page
High-intent SEO and PPC traffic should land on the product, service, application, customer-type, industry, or location page that best matches the query and promise. Preserve that message from the search result or ad through the headline, supporting copy, proof, and primary call to action.
Product or service intent: lead with the problem solved, the relevant capability, and a suitable evaluation step.
Application intent: show how the product handles the named use case rather than repeating a generic feature list.
Customer-type intent: address the role or company profile directly, including the outcomes, objections, and proof that matter to that audience.
Industry intent: demonstrate sector knowledge with relevant language and evidence; changing only the industry name is not enough.
Location intent: explain why location changes delivery, coverage, compliance, availability, or service. If geography makes no meaningful difference, multiplying near-duplicate pages is unlikely to improve the visitor’s decision.
Not every organic visitor is ready for a demo. Educational SEO pages can offer a lower-friction next step, while transactional pages ask for a product conversation. Record those actions separately so the easier conversion does not make the channel look more commercially productive than it is.
Give targeted and relationship channels a continuous next step
LinkedIn advertising and ABM should carry audience specificity onto the destination page. If the targeting is built around a particular customer type or industry, the page should speak to that same group. Sending a narrow audience to broad copy discards the main advantage of the channel.
Trade shows, speaking engagements, webinars, and email need continuity of topic rather than a generic follow-up. The destination should remind the visitor what they engaged with, add the promised evidence or resource, and offer a next step consistent with their level of intent. A webinar attendee who requested education should not be treated as if they submitted a demo request.
Remove friction after you confirm message match
Form optimization cannot rescue irrelevant traffic or a mismatched offer. First confirm that the audience, promise, page, and call to action align. Then remove avoidable friction:
Do not remove fields merely to produce more submissions. If sales needs a field to identify fit or route the lead, deleting it can move work downstream and inflate an unqualified conversion rate. Test the field against qualified pipeline, not form completions alone.
Build a scorecard that connects acquisition to revenue
A landing-page conversion rate tells you where a visitor acted. It does not tell you whether the action was qualified, whether sales accepted it, or whether the channel created a customer. Your scorecard needs to preserve that chain.
Funnel measure
Definition
What a weak result usually tells you to inspect
Eligible landing-page visits
Relevant visits that had a genuine opportunity to complete the page’s primary action
Reach, targeting, search demand, tracking exclusions, and traffic quality
Visit-to-primary-conversion rate
Primary conversions divided by eligible landing-page visits
Message match, offer, proof, form friction, page type, and call-to-action clarity
Conversion-to-qualified-lead rate
Qualified leads divided by primary conversions
Targeting, qualification criteria, form design, and whether the conversion is too easy or too broad
Qualified-lead-to-opportunity rate
Created opportunities divided by qualified leads
Handoff speed, buyer readiness, sales follow-up, and offer-to-market fit
Opportunity-to-customer rate
New customers divided by opportunities
Commercial fit, evaluation process, competition, pricing, and sales execution
Cost per qualified opportunity
Full channel cost divided by qualified opportunities
Whether reach and conversion translate into economically useful pipeline
Customer acquisition cost
Applicable acquisition cost divided by new customers
Whether the complete channel economics support continued investment
Time to result
Elapsed time from cohort entry or channel investment to the chosen business outcome
Whether you are comparing channels over an appropriate decision window
For every primary conversion, retain the channel, campaign, landing page, page type, call to action, and form version. Connect that record to lead status, opportunity status, customer status, and the relevant dates. Without those dimensions, a redesign, new offer, or change in traffic mix can alter the blended rate without showing you why.
Keep first-touch acquisition and converting touch separate. First touch helps you understand where demand entered the measurable journey. Converting touch shows what prompted the recorded action. Assisted interactions explain how channels such as email, webinars, and retargeting helped between those points. None of those views is a complete truth by itself.
Use the scorecard as a diagnostic sequence:
Qualified visits are scarce, but comparable pages convert acceptably: work on acquisition reach and targeting.
Qualified visits are present, but the primary conversion rate is weak: inspect message continuity, page type, proof, form friction, and the call to action.
Primary conversions are healthy, but qualification is weak: tighten the audience, promise, conversion definition, or qualification step.
Qualified leads are healthy, but opportunities are weak: inspect readiness, routing, follow-up, and the sales handoff before buying more traffic.
Opportunities are healthy, but customers are scarce: the main constraint is now downstream of acquisition.
This sequence protects you from paying to amplify the wrong stage. More traffic into a weak page produces more leakage. More form fills with poor qualification create more sales work. A better headline metric is only valuable when the improvement survives the rest of the funnel.
Key takeaways
Choose a channel for a defined job: demand creation, demand capture, nurture, or account acceleration.
The 1.1% B2B SaaS landing-page benchmark is a directional reference with a specific sample and scope, not a forecast for every SaaS page.
Customer-type, application, product, service, industry, and location benchmarks describe the broader B2B pool; they are not SaaS-specific page targets.
Compare conversion rates only when page intent, traffic source, audience, and call to action are genuinely comparable.
Optimize forms and page elements against qualified pipeline, not raw submissions.
Connect channel, page, conversion, qualification, opportunity, customer, cost, and elapsed time before reallocating budget.
Start with your most recent complete acquisition cohort. Put each channel beside its intended job, destination page, primary conversion, qualified opportunities, customers, cost, and time to result. If you cannot trace that path yet, fix the measurement before changing the budget. Once the path is visible, fund the channel that removes the actual constraint and repair the stage where qualified demand is being lost.
If you have been waiting for a practical way to test ChatGPT advertising without entering a large, managed pilot, self-serve buying changes the conversation. The important question is no longer whether the channel sounds interesting. It is whether you can run a controlled test without mistaking novelty, clicks, or platform-reported conversions for profitable growth.
You need a defined conversion, a defensible cost ceiling, a landing page that matches the ad, and tracking that reaches your order system or CRM. Put those pieces in place before you request access or allocate budget, and ChatGPT ads can be evaluated like a performance channel rather than treated as an open-ended experiment.
What self-serve buying changes, and what it does not
The announced rollout moves ChatGPT advertising beyond a tightly controlled pilot. Advertisers can pursue inventory through agency and technology partners or use a beta Ads Manager rolling out in the United States. The direct interface provides control over budgets, bids, creative uploads, and performance tracking.
That lowers the operational barrier for smaller businesses and teams that could not justify a high-touch engagement. It does not mean access is universal. The product remains in beta, so confirm that your account and market are eligible before you build a launch plan around it.
The addition of cost-per-click bidding is the most consequential change for performance marketers. The initiative began with CPM-based buying, where cost is tied to impressions. CPC lets you bid around visits instead. That is useful because ChatGPT interactions can occur while people are exploring a problem, comparing approaches, or moving toward a decision.
A click is still an intermediate event. CPC is not CPA: paying for a click does not mean you are paying only when a sale, signup, or qualified lead occurs. You still own everything between the click and the business outcome, including page relevance, offer strength, conversion friction, follow-up, and measurement.
Use exploratory, comparative, and decision-ready intent as a creative planning lens:
Exploratory intent: Explain the problem and the practical outcome your offer supports. Avoid demanding a large commitment before the visitor understands the value.
Comparative intent: State the relevant difference, qualification, or tradeoff plainly. Give the visitor enough evidence to judge fit.
Decision-ready intent: Make the offer, next step, price condition, or eligibility requirement easy to find.
This is a messaging framework, not a claim that Ads Manager exposes individual prompts, conversation targeting, or query-level reports. OpenAI’s measurement model is aggregated, and advertisers do not receive access to individual conversations. Do not design targeting, attribution, or sales workflows that depend on identifying what a particular person told ChatGPT.
Direct access is not the only route. Agency and technology relationships include WPP, Publicis Groupe, Criteo, and Adobe. If you buy through a partner, ask who owns the account, which bidding controls you receive, how conversion data is implemented, what reporting can be exported, how frequently it is delivered, and which fees sit outside media spend. A familiar partner workflow is useful only if you can still audit the campaign’s economics.
Keep paid ChatGPT campaigns separate from organic AI visibility work. Ads buy exposure and traffic; AEO and GEO aim to improve how machines understand, retrieve, cite, and represent your content. Do not use paid click-through or conversion data as proof that organic ChatGPT visibility improved. Label the channels separately in analytics so paid traffic does not distort your AI-search reporting.
Decide whether your business is ready to test
Self-serve access makes launching easier, but it cannot supply the business logic that determines whether a campaign should run. Use the following readiness gate before committing spend:
You can name the primary conversion. Choose the event that represents value: a purchase, signup, or lead. If you optimize for a shallow action, such as a form start, keep the true business outcome visible in your reporting.
You know what that conversion is worth. Establish an acceptable acquisition cost from contribution margin, lead quality, close rate, retention assumptions, and fulfillment cost. Do not copy a target from another advertising channel without checking whether the traffic and sales process are comparable.
The destination can fulfill the ad’s promise. The landing page should repeat the core offer, explain who it is for, show relevant evidence, and provide the next step without forcing the visitor to reconstruct the argument.
You can connect ad activity to business records. Ads Manager reporting should be reconciled with web analytics and the system that records revenue or lead quality. Platform conversions alone cannot tell you whether a lead was qualified, duplicated, refunded, or closed.
You can afford an inconclusive test. A beta channel may not produce enough evidence to support a scaling decision. Treat the approved test budget as money at risk, not as revenue you expect the campaign to return on a fixed schedule.
For a performance campaign, calculate a planning ceiling before choosing a bid:
Maximum break-even CPC = acceptable cost per conversion multiplied by the expected landing-page conversion rate.
Use the conversion rate from genuinely comparable traffic when you have it. If you do not, model a conservative range rather than borrowing the best rate from branded search, email, or returning visitors. The result is a break-even boundary, not an automatic bid recommendation. Your actual bid still has to reflect available controls, delivery, competition, and the evidence generated by the campaign.
Lead-generation teams need an additional check. A campaign can appear efficient when it produces inexpensive forms but fail when sales rejects the leads. Define what makes a lead qualified, ensure the CRM records that status, and decide whether the beta’s Conversions API can receive the deeper outcome you want to optimize toward. If it cannot, use the deeper event for business evaluation even if campaign optimization must rely on an earlier event.
Wait to launch if nobody owns the landing page, conversion implementation, or lead follow-up. Buying traffic before those responsibilities are assigned creates a predictable dispute: the ad platform shows activity, analytics shows something different, and the sales team sees outcomes that neither report explains.
Build the first campaign around a falsifiable hypothesis
Your first campaign should answer a narrow business question. Write the hypothesis before opening Ads Manager:
For people in a defined decision state, this offer and message will produce this conversion at or below this acquisition-cost ceiling.
That sentence prevents several common mistakes. It keeps brand awareness from being judged by last-click sales, stops a lead campaign from optimizing toward unqualified form fills, and gives you a reason to pause when the economics do not work.
Choose a single primary outcome. Purchases, signups, and leads require different pages, event definitions, and follow-up. Pick the event that matches the offer instead of mixing several goals into one test.
Define the decision state. Decide whether the message is helping someone understand a problem, compare alternatives, or act. Use that decision in your creative brief and landing-page structure. Apply only targeting options that are actually available in your beta account.
Write a specific promise. State the result, the relevant qualifier, and the next step. Avoid copy that merely announces your brand or repeats broad AI terminology. The visitor should know why the click is worth making.
Prepare controlled creative variants. Vary the claim, proof, or call to action separately so you can interpret the result. If every element changes at once, a winning variation does not tell you what to retain.
Build message continuity after the click. The landing page headline should resolve the promise made in the ad. Put the decision-critical facts, constraints, evidence, and action on the page rather than hiding them behind generic navigation.
Set stop and scale rules. Pause immediately if conversion tracking fails. Stop and diagnose when the approved test budget is exhausted without evidence that supports the hypothesis. Scale only when verified outcomes remain within the acquisition-cost ceiling.
Do not invent a universal testing threshold. The amount of evidence you need depends on conversion frequency, normal sales-cycle length, the cost of a false positive, and how much variation exists in lead or order value. Record the threshold you will use before seeing the result so a promising-looking dashboard does not move the goalposts.
Use a stable campaign naming and URL-tagging convention from the start. A workable UTM pattern is utm_source=chatgpt, utm_medium=paid_ai, a campaign value tied to the offer, and a content value tied to the creative variant. Record the exact values in the campaign brief. Consistency matters more than the label itself because it lets analytics, CRM, and finance records join the same test.
Your SEO and GEO work should support clarity on the destination page without being confused with ad configuration. Use visible, accurate facts and structured data that matches the page. JSON-LD can help machines interpret supported entities and attributes, but it is not a ChatGPT ad-targeting control, conversion tag, or substitute for persuasive page content.
Make measurement trustworthy before optimizing bids
ChatGPT advertising is adding pixel-based tracking and a Conversions API for actions such as purchases, signups, and leads. The pixel can capture supported browser-side events. A Conversions API can pass supported events from a server, commerce system, or CRM. Check the beta documentation available in your account before implementation because event fields and diagnostics may evolve.
If you use both methods, verify how duplicate events are handled before sending the same conversion through each path. Two tracking methods should improve resilience, not turn one order into multiple conversions. Test event names, identifiers, values, currency fields, timestamps, and final status against the platform’s current specification.
Build the measurement chain from the business outcome backward:
Business system: The order platform or CRM records revenue, qualification, cancellation, refund, or closed status.
Analytics: The session retains the expected campaign parameters and records the relevant onsite actions.
Conversion integration: The pixel or Conversions API sends the supported event with the correct value and status.
Ads Manager: The campaign reports clicks, spend, and attributed conversions using the attribution settings shown in the account.
Run a validation pass before meaningful spend begins. Confirm that the landing URL works through every redirect, UTM parameters survive navigation, consent behavior is understood, the intended event fires only when its real condition is met, and the backend stores the campaign identifiers you need. Save evidence of the test so later discrepancies can be compared with a known-good implementation.
Expect the systems to disagree at times. Attribution windows, consent choices, browser restrictions, server timing, duplicate handling, and later changes to an order or lead can all create differences. Reconcile the direction and magnitude of the data rather than forcing a false impression of perfect identity. The privacy model also means you should not expect a conversation-level customer trail: reporting is aggregated, and individual ChatGPT conversations are not exposed to advertisers.
Read early results in a fixed order: tracking integrity, visitor behavior, conversion quality, and only then media efficiency. The pattern in the data tells you where to look first:
Observed pattern
First interpretation to test
Action
Ads Manager records clicks, but analytics sees few matching sessions
The click path, redirects, campaign parameters, consent handling, or analytics filters may be breaking attribution
Validate the final URL and session tracking before changing bids or creative
Analytics and the backend record completions, but Ads Manager records few conversions
The pixel or Conversions API event may be missing, malformed, delayed, or duplicated incorrectly
Repair and retest the conversion integration before judging campaign performance
Clicks arrive, but visitors do not reach meaningful onsite actions
The creative may be attracting curiosity, or the page may not continue the ad’s promise
Tighten the qualification in the message and remove landing-page mismatch
Platform conversions look efficient, but sales rejects the leads
The optimized event is too shallow to represent business value
Report qualified outcomes from the CRM and use a deeper supported event when possible
Verified conversions remain within the cost ceiling
The campaign is a candidate for controlled expansion
Increase exposure gradually and keep the offer, page, and measurement stable while evaluating the change
Delivery remains limited
Campaign settings, bid or budget constraints, access, or available inventory may be limiting the test
Check account diagnostics and settings before concluding that demand is absent
Do not respond to weak conversion economics by raising the bid first. Confirm that measurement works, inspect the promise-to-page transition, and check whether the recorded conversion represents real value. Increase bids or budgets only when account data indicates delivery is constrained and the verified acquisition economics can absorb more traffic.
Document every material change with its effective time, including bid, budget, creative, destination, event definition, and attribution setting. If several variables change together, the next reporting period may look different without telling you why.
Key takeaways
ChatGPT’s self-serve Ads Manager is a U.S. beta, so verify access and current account controls before planning a launch.
CPC bidding makes traffic easier to buy and evaluate, but a paid click is not a sale, qualified lead, or profitable customer.
Write the campaign hypothesis, conversion definition, cost ceiling, test budget, and stop rule before spend begins.
Use a matching landing page and consistent campaign parameters so Ads Manager, analytics, and backend outcomes can be reconciled.
Pixel and Conversions API tracking improve measurement, but data is aggregated and does not expose individual conversations.
Keep paid ChatGPT performance separate from organic AEO and GEO visibility. Neither should be used as proof that the other improved.
Your next move is to write the hypothesis and acquisition-cost ceiling, then trace the conversion from the landing page to the final business record. If either remains undefined, keep the budget closed. If both survive that check, you have the basis for a controlled beta test and a clear decision when the results arrive.