Author: shivamcrushpressai

  • How to Report Fake Google Reviews and Preserve Evidence

    How to Report Fake Google Reviews and Preserve Evidence

    When a Google review looks fabricated, your first impulse may be to challenge it in public. Pause. The useful work happens before the reply: preserve the review, identify exactly what makes it suspect, and send the evidence through the reporting route that matches the problem.

    If someone is demanding money, goods, services, or another concession in exchange for removing a bad review or stopping more reviews, treat the incident differently from an ordinary rating dispute. Google provides a dedicated reporting form for negative review extortion scams. The workflow below will help you build a clearer case without escalating the situation or making claims you cannot prove.

    First decide what kind of review problem you have

    Fake is often used as shorthand for any review a business disputes. That is too broad for an effective report. A real customer can be wrong, unfair, confused, or posting under a name you do not recognize. None of those facts automatically proves fabrication.

    Classify the incident by its observable features. That determines what evidence to collect and which reporting path to use.

    SituationWhat you can verifyBest next step
    Genuine but negative experienceThe event, order, booking, or service interaction can be identified, even if you disagree with the accountRespond to the substance and try to resolve the complaint; do not label it fake merely because it is unfavorable
    Reviewer cannot be matchedThe displayed name does not appear in the records you checkedInvestigate other names, purchasers, guests, dates, and channels before reporting; treat the mismatch as an indicator, not proof
    Wrong business or locationThe review describes a different company, branch, product, address, or servicePreserve the mismatch and report the review using the closest available reason
    Fabricated or coordinated activitySeveral observable signals align, such as repeated wording, connected demands, implausible details, or a cluster of related profilesSave every review separately, document the connections, and report the specific reviews
    Negative review extortionA message makes a concession conditional on removing a review, changing a rating, or preventing additional reviewsPreserve the complete demand and use the dedicated extortion-reporting route

    The distinction matters most when you cannot find the reviewer in your customer records. A customer may use a nickname, post through a family member’s account, buy through a third party, or complain about an interaction that did not create a normal transaction record. Write down what you searched and what you found. Do not turn an incomplete match into a categorical accusation.

    For an extortion report, focus on the conditional exchange rather than trying to prove a legal label. The important fact is that the person connected a demand to the review: provide something, or the review stays, changes, or multiplies.

    Build an evidence packet before you report anything
    A person photographs a suspicious review on a laptop while organizing screenshots, records, and other digital evidence.

    A review can be edited, removed, or separated from the message that explains it. Capture the original context before replying, negotiating, blocking the sender, or asking staff members to report it.

    1. Preserve the complete review. Save a screenshot showing the review text, rating, displayed reviewer name, review date, and the business profile. Copy the review text and its direct URL when one is available. Avoid a tight crop that removes identifying context.
    2. Preserve the reviewer profile context. Record the profile URL and the public information visible when you collected it. If other reviews appear relevant, save their URLs and screenshots separately rather than relying on a single composite image.
    3. Keep demands in their original channel. Retain the original email, text message, direct message, voicemail, or letter. Include sender information and timestamps. If an email service allows you to download the original message, keep that file in addition to a screenshot.
    4. Create a chronology. List the first contact, the review publication, each demand, any promised consequence, later reviews, and your responses. Record the date, time, and time zone. A simple timeline is easier to evaluate than a folder of unsorted screenshots.
    5. Document your internal check. Note which booking system, order history, CRM, support inbox, or staff schedule you searched. Record the names, phone numbers, email addresses, reference numbers, locations, and date ranges used. State that no match was found only if that is what the search established.
    6. Separate observations from conclusions. Repeated wording and close timing are observations. A claim that several profiles are controlled by one person is a conclusion unless you have evidence connecting them. Keep that distinction clear in your submission.

    Keep untouched originals in one folder and working copies in another. A practical case folder can contain four subfolders: originals, timeline, submitted evidence, and Google correspondence. Name files with the date, review identifier, and evidence type so another employee can understand the record without reconstructing the incident from memory.

    Include only information relevant to the report. Do not publish customer records, private contact details, payment information, or employee data in a public response. If a demand includes credible threats of violence, stalking, disclosure of private information, or continuing fraud, preserve the material and seek appropriate local legal or law-enforcement guidance. A platform review report is not a substitute for responding to an immediate safety risk.

    Use the Google reporting path that matches the conduct
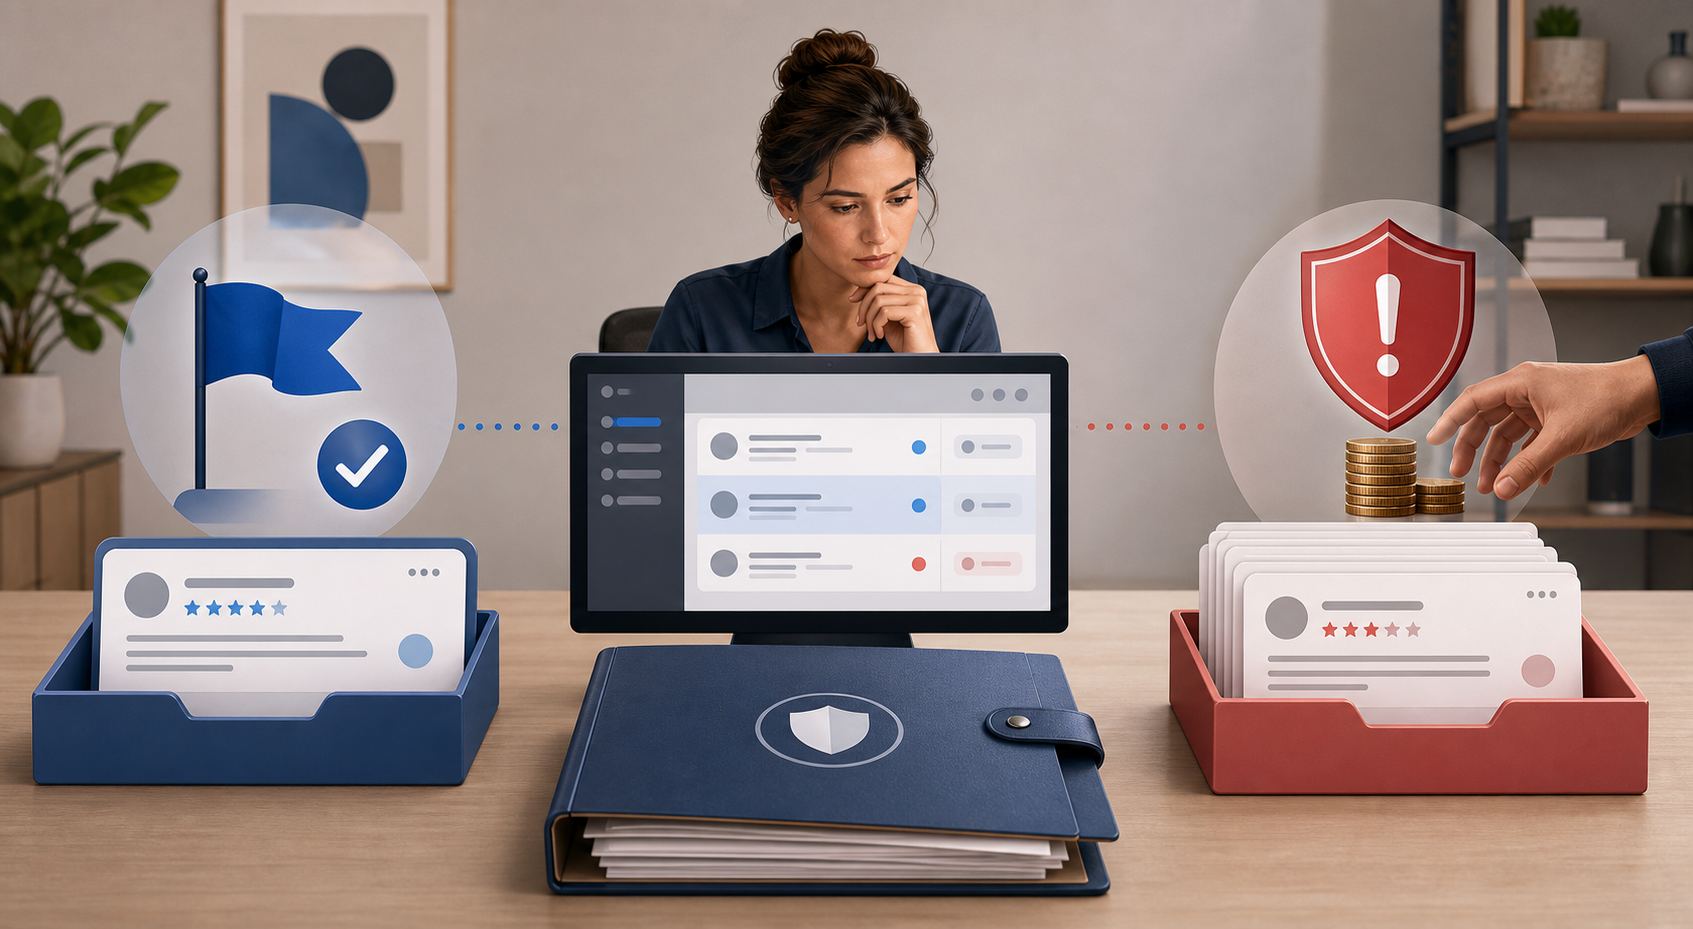
    A business owner compares a standard suspicious-review report with a separate extortion-related reporting route.

    For an ordinary suspected fake or misplaced review

    Open the review through the Google Business Profile management surface available to your business and use the review’s report or flag control. Interface wording can change, so choose the available reason that most closely describes the observable problem rather than the outcome you want.

    1. Confirm that you are reporting the correct review on the correct location profile.
    2. Select the reason that matches the evidence, such as irrelevant, misplaced, deceptive, or otherwise prohibited content, when that option is available.
    3. If you receive a field for additional information, explain the specific mismatch in a few factual sentences.
    4. Save the submission date, confirmation, case number, or other reference Google provides.
    5. Record the result in your case log and retain the evidence even if the review later disappears.

    A useful explanation identifies the contradiction. For example, say that the review describes a service your business does not offer or names an employee who has never worked at that location. A bare statement that the reviewer is not a customer gives the reviewer no context and gives the evaluator little to assess.

    For a review tied to an extortion demand

    Use the dedicated extortion form and make the conditional demand the center of the submission. Identify the linked review or reviews, then attach the chronology and original communications that connect the demand to them.

    Submission template: On [date, time, and time zone], [verifiable account or contact] demanded [specific payment, product, service, refund, or other concession] in exchange for [removing or changing a review, or not posting further reviews]. The linked review or reviews appeared on [dates]. The attached material includes the original messages, review URLs, screenshots, and a chronological timeline. We have retained unedited copies of the originals.

    Replace every bracketed field with a fact you can support. If you suspect that a message sender controls a reviewer profile but cannot prove it, describe the connection as suspected and explain why. Do not fill the gap with certainty.

    Keep one tracking row for each review, even when several belong to the same incident. Record the review URL, displayed profile, reporting path, submission date, selected reason, case reference, evidence included, current status, and next follow-up date. This prevents a multi-review incident from turning into a series of undocumented reports.

    Protect your reputation while the report is pending

    Use this sequence whenever possible: preserve the evidence first, submit the report second, and decide on a public reply third. Replying first can alert the sender before you have captured material that may later change or disappear.

    If you respond publicly, write for the prospective customer reading the exchange, not for the reviewer you suspect. Keep the reply short, avoid personal information, and offer a verifiable channel through which a genuine customer could identify the transaction.

    Public response template: We take complaints seriously, but we cannot match the details in this review to an interaction in our records. Please contact [verified support channel] with the service date, location, and reference number so we can investigate.

    Do not publicly call the reviewer a criminal, disclose an alleged payment demand, threaten legal action, or post screenshots containing private information. Those moves can intensify the dispute and create avoidable legal or privacy exposure. When legal counsel is already involved, have counsel review any public statement before it goes live.

    Do not organize a counterattack. Employees, friends, and customers should not be directed to argue with the reviewer or flood the profile with defensive ratings. Continue your normal review-request process with real customers, ask for honest feedback without prescribing a rating, and keep the incident response separate from ordinary reputation management.

    Assign one case owner. Route new demands, staff questions, Google correspondence, and public replies through that person. During an active incident, set a review-monitoring cadence you can maintain, such as one check each business day. Save new evidence before reporting it, add it to the existing chronology, and tell customer-facing employees not to engage independently.

    FAQ about fake Google review reporting

    Is a missing customer record enough to prove a review is fake?

    No. It is a reason to investigate, not proof by itself. Search alternate names, purchasers, guests, phone numbers, email addresses, locations, booking channels, and the date range implied by the review. Report the facts you can verify and avoid claiming more.

    Should you reply before reporting the review?

    Usually, preserve the review and connected evidence first, submit the appropriate report, and then consider a neutral public reply. If the incident includes credible threats, private information, or an active legal matter, get appropriate advice before responding publicly.

    Can you use the extortion form for every suspected fake review?

    No. The distinguishing feature is a demand tied to the review or the threat of further reviews. Use the normal review-reporting control for suspected spam, fabricated experiences, irrelevant content, or reviews posted to the wrong business when no conditional demand exists.

    What should you do if Google does not remove the review?

    Do not promise your team or client a removal date. Keep the case log, retain the original evidence, and use any follow-up or appeal option presented in your review-management interface. Add genuinely new evidence instead of repeatedly submitting the same assertion. Maintain a measured public response and continue collecting legitimate customer feedback. If threats, impersonation, fraud, or harassment continue outside the review platform, seek help through the channel appropriate to that conduct.

    Start with the evidence you can preserve now: the complete review, its URL, the reviewer profile, and any connected demand. Build the chronology before the incident grows. Once the facts are organized, the choice becomes straightforward: use the ordinary review-reporting control for a suspected fake or misplaced review, and the dedicated form when a conditional demand turns the incident into negative review extortion.
    References

  • How to Build Brand Visibility Across AI Search Systems

    How to Build Brand Visibility Across AI Search Systems

    Your site ranks, your schema validates, and your content answers the right questions. Yet when a buyer asks ChatGPT, Perplexity, or an AI search feature for a recommendation, competitors appear and your brand does not.

    That gap is rarely caused by one missing keyword or schema property. AI visibility depends on whether a system can find your brand, connect it to the buyer’s situation, verify its claims, and confidently include it in a generated answer. You need to manage that entire path.

    Stop looking for a single AI ranking

    Traditional rank tracking gives you a familiar object: a query, a search results page, and a position. AI search does not reliably preserve that object. The system may reinterpret the prompt, generate related searches, retrieve a small candidate set, combine several result lists, rerank passages, and then compose an answer that mentions only part of what it found.

    StageWhat can go wrongWhat you can improveWhat to measure
    DiscoveryThe system cannot access or identify the relevant page.Crawlability, indexability, internal links, sitemaps, canonicalization, and stable entity information.Crawler requests, indexed pages, and cited URLs.
    RetrievalYour page is accessible but not considered relevant to the prompt or its related searches.Coverage of buyer needs, category entry points, terminology, and clear page purpose.Appearance across prompt families and recurring citation themes.
    RerankingYour page enters the candidate set but stronger or more specific evidence outranks it.Passage-level answers, distinctive claims, supporting evidence, freshness where relevant, and external corroboration.Citation frequency, competitor overlap, and the pages repeatedly selected.
    SynthesisYour page is used, but your brand is omitted, misrepresented, or reduced to a generic fact.Explicit entity naming, claim ownership, concise descriptions, and consistent facts.Brand mentions, attribution, factual accuracy, and recommendation context.
    ActionThe answer mentions your brand but produces no meaningful business response.A clear value proposition, navigable landing pages, and a reason to visit beyond the generated summary.Referral visits, assisted conversions, branded demand, leads, and sales.

    The size of the candidate set matters. In one documented ChatGPT implementation, retrieval returned only 38 to 65 results before later selection stages. That is an implementation-specific observation, not a permanent limit for every model. It still illustrates the practical problem: a page can be relevant somewhere in a search index and never enter the much smaller pool available to the answer generator.

    Some retrieval systems also combine multiple ranked lists with Reciprocal Rank Fusion. When that method is used, appearing consistently across several related searches can contribute more than one isolated win. This makes broad relevance across a buyer’s decision journey more useful than forcing one page toward one exact prompt. It does not mean every AI platform uses the same fusion method, constant, or reranking model.

    Diagnose the stage before changing the content:

    • If your pages are never retrieved or cited, check access, indexability, entity clarity, and topic coverage.
    • If the pages are cited but the brand is absent, make the relationship between the claim and the named entity explicit.
    • If the brand appears for informational prompts but not recommendations, strengthen evidence about who the product serves, when it fits, and why it deserves consideration.
    • If the brand is recommended inaccurately, repair conflicting facts across your site, structured data, directories, profiles, and third-party coverage.
    • If mentions rise but business outcomes do not, improve the reason to click and the destination users reach after the answer.

    This is why SEO and generative engine optimization should remain connected. Search visibility can help a page become discoverable, but discovery is only the beginning of AI visibility.

    Map the situations in which your brand should be chosen

    A brand does not need to appear whenever someone mentions its broad category. It needs to appear when it is a credible answer to a specific need. That is the practical meaning of AI availability: a system can recognize the brand, associate it with the right purchasing situation, and present it as a suitable option.

    Start with category entry points rather than a pile of high-volume keywords. A category entry point is the need, trigger, constraint, or occasion that brings a buyer into the market. It sounds like software for a distributed team that needs client approvals, not simply project management software. The narrower statement tells you what the answer must prove.

    1. List the decisions you legitimately want to influence. Include use cases, audiences, constraints, locations, integrations, risks, and switching situations. Exclude situations where the offer is not a defensible fit.
    2. Write the evidence threshold for each decision. A recommendation may require documented capabilities, product specifications, availability, professional credentials, reviews, independent recognition, or a clear service area.
    3. Turn each decision into natural prompts. Cover exploratory questions, comparisons, objections, compatibility questions, and requests for a shortlist. Do not create dozens of cosmetic rewrites that preserve the same intent.
    4. Assign an owned destination. Each important need should lead to a page that answers it directly. If several pages compete to explain the same thing, consolidate or clarify their roles.
    5. Assign outside corroboration. Record which directory, review platform, partner, publication, association, or other credible third party can confirm the claim. If nothing can confirm it, label the claim as unsupported rather than disguising the gap with more copy.

    This map protects you from a common GEO failure: publishing many generic pages while leaving the brand’s actual reasons to be chosen implicit. AI systems can infer relationships, but you should not make a recommendation depend on a generous inference.

    Turn brand language into observable attributes

    Words such as leading, innovative, and trusted do not tell a retrieval system what the company does or when it fits. Replace them with attributes a buyer could examine.

    • Name the audience precisely enough to distinguish it from the entire market.
    • Describe the use case and constraint the product handles.
    • State capabilities in concrete language and link them to supporting documentation.
    • Put limitations, prerequisites, locations, and availability beside the claim they qualify.
    • Keep important facts consistent across product pages, help content, profiles, directories, and structured data.

    A useful internal template is: Brand serves audience in situation through capability, supported by evidence. The final page should read naturally, but every important recommendation claim should be complete enough to fill that structure.

    Do not create a landing page for every prompt variation. AI search can fan one request out into several related searches, so build one authoritative resource around a coherent need and support it with tightly related pages. Thin variations are more likely to compete with one another than to create meaningful coverage.

    Make every important claim retrievable and hard to misread

    A beam of light selects one organized evidence module from a grid of transparent drawers connected to matching source records.

    A useful page has two jobs. It must satisfy the person who visits, and it must contain passages that remain clear when retrieved away from the rest of the page. You do not need to write robotic fragments. You do need to stop burying essential facts under clever introductions, unexplained pronouns, or unsupported superlatives.

    Write passages that can survive retrieval

    • Answer the section’s question near the start of the section.
    • Name the product, organization, service, or location instead of relying on it, we, or this solution for several paragraphs.
    • Keep the evidence beside the claim. Do not make a system follow an unrelated link to discover what a number or credential means.
    • Qualify claims where they are made. State the relevant plan, market, product version, audience, or condition instead of hiding it in a distant note.
    • Use headings that describe the decision being answered, not vague labels such as Overview or More information.
    • Place critical facts in HTML text. Do not leave a specification, service area, or comparison trapped only inside an image.
    • Show when time-sensitive information was reviewed or changed. Do not add a new date to unchanged content merely to simulate freshness.

    Short paragraphs can improve scanability, but paragraph length is not an AI ranking factor you can treat as settled. The real goal is semantic completeness: a selected passage should identify the entity, answer the question, carry its qualifications, and expose its evidence.

    Give the brand a stable entity record

    Create a canonical home for durable facts such as the official name, what the organization does, the products or services it offers, the markets it serves, and the profiles it controls. Link relevant pages back to that entity rather than redefining it inconsistently on every page.

    Entity consistency does not require identical marketing copy everywhere. It requires agreement on factual identity. A shortened brand name can coexist with a legal name, for example, as long as the relationship is clear. Conflicting categories, locations, product names, or descriptions create a harder reconciliation problem.

    Use JSON-LD as confirmation, not decoration

    Schema.org vocabulary helps turn page information into machine-readable data. It can reduce ambiguity about entities and relationships, but valid markup does not guarantee retrieval, citation, or recommendation.

    • Choose the most specific accurate type for the visible entity, such as Organization, LocalBusiness, Product, Service, or Article.
    • Represent the same entity with a stable @id so separate page graphs refer back to one identifiable thing.
    • Connect related entities instead of producing isolated markup blocks with no shared identity.
    • Keep names, URLs, offers, authorship, dates, and other properties aligned with visible page content.
    • Include only facts you can maintain. Stale structured data makes the machine-readable version less trustworthy, not more useful.
    • Validate syntax and eligibility, then inspect the rendered page. A clean validator result cannot compensate for inaccessible or contradictory content.

    Adding every possible schema type is not an optimization strategy. Model the facts that matter to the decision and maintain them as the underlying business changes.

    Treat crawler access as a deliberate business decision

    Check robots directives, authentication, JavaScript rendering, canonical tags, and response behavior on the pages you expect systems to use. Then inspect server or edge logs by user agent. A crawler request proves that an automated client reached a URL; it does not prove that the content was indexed, retrieved for a prompt, or cited.

    Separate training crawlers, search crawlers, and user-initiated page fetchers when your infrastructure allows it. They do not necessarily serve the same purpose. A blanket block may protect content from one form of collection while also reducing some forms of discovery. If valuable content requires payment, registration, or a licensing arrangement, decide which public summary can remain accessible without exposing the protected asset.

    That choice also affects publishing economics. Sir Tim Berners-Lee has warned that AI answers can weaken the visit-and-advertising loop that supports the open web. If your business depends on page views, measure qualified visits and revenue alongside mentions. Visibility without a visit may still build demand, but it is not a substitute for the outcome that funds the content.

    Build corroboration beyond your own domain

    Your website can explain what the brand wants to be known for. It cannot independently establish every reason the brand should be trusted or recommended. AI visibility therefore has an off-site component: credible places need to describe the brand in the categories and situations that matter.

    This is not a request to scatter the same promotional paragraph across low-quality directories. The objective is useful corroboration from places a buyer would reasonably consult.

    1. Audit the existing footprint. Search for the brand, its products, important executives where relevant, and each priority use case. Record outdated facts, missing profiles, unexplained name variations, and category mismatches.
    2. Fix foundational listings. Correct names, categories, locations, contact details, product descriptions, and destination URLs on authoritative profiles and directories relevant to the business.
    3. Earn category inclusion. Seek legitimate buyer guides, specialist directories, partner ecosystems, association listings, event programs, and editorial resources that cover the actual category entry point.
    4. Make evidence publishable. Maintain accessible product documentation, methodology, policies, specifications, original data, or other artifacts that allow a claim to be checked. An evidence artifact should be useful even if no AI system ever cites it.
    5. Improve review quality ethically. Ask real customers for honest reviews at an appropriate point in their experience. Do not script attributes, manufacture sentiment, or offer incentives that compromise the review platform’s rules.
    6. Correct material inaccuracies. Prioritize errors that could change a recommendation, such as the wrong market, discontinued feature, unsupported integration, or outdated location. Cosmetic wording differences matter less.

    A local business can make this concrete by publishing accurate service details and distinctive attributes, then keeping those facts aligned with mapping profiles, directories, and genuine reviews. A B2B company may need product documentation, partner pages, specialist coverage, and clear customer evidence. The channel changes; the need for consistent, verifiable context does not.

    PR, content, reputation management, and SEO all contribute here, but they should work from the same claim map. If PR promotes one positioning, product pages use another, and review profiles assign the business to a third category, the brand accumulates mentions without accumulating a stable identity.

    Measure AI visibility as a distribution, not a screenshot

    Glowing orbs move through branching channels into multiple answer chambers where a blue token appears with different levels of prominence.

    A single answer is evidence that one system produced one response under one set of conditions. It is not a durable rank. Generated answers can change with prompt wording, retrieval availability, session context, reranking, model updates, and other implementation details. Repeated observation is therefore part of measurement, not an optional layer of polish.

    1. Freeze a prompt portfolio. Organize prompts by category entry point, funnel stage, audience, constraint, and market. Preserve the exact wording so later runs remain comparable.
    2. Record the environment. Save the platform, available model label, date, location or language context where relevant, account state, and whether the session was clean or carried prior conversation.
    3. Repeat comparable runs. Variation between answers is itself information. Keep the conditions consistent enough to separate normal response variance from a meaningful visibility change.
    4. Capture the full answer. Store mentions, recommendation order where an order exists, linked and unlinked citations, cited URLs, surrounding claims, competitors, and factual errors.
    5. Connect answers to technical evidence. Compare cited pages with search visibility, crawl logs, indexation, page changes, structured data changes, and external coverage. Avoid treating temporal coincidence as proof of causation.
    6. Change one strategic variable at a time. Test a clearer passage, stronger evidence, corrected entity data, better internal linking, or new corroboration against a defined visibility problem.
    7. Watch for drift. Annotate model or platform changes when known. A broad movement across many unchanged prompts may reflect system behavior rather than a sudden improvement or failure on your site.

    Use metrics that reveal where the pipeline breaks

    • Mention rate: the share of comparable runs in which the brand appears.
    • Citation rate: the share of comparable runs that link to or identify an owned page.
    • Category coverage: the priority need states for which the brand appears at all.
    • Recommendation coverage: the situations in which the brand is presented as an option, not merely named as a factual reference.
    • Representation accuracy: the share of captured claims that match current, supportable facts.
    • Citation concentration: whether visibility depends on one page, one outside mention, or a healthier set of relevant resources.
    • Competitive presence: which brands recur for the same need and which evidence appears to support them.
    • Business response: referral traffic, assisted conversions, branded demand, qualified leads, or sales associated with AI discovery where attribution is available.

    Do not force these into one opaque visibility score. A rising mention rate can conceal falling accuracy. More citations can point to an irrelevant page. Strong recommendation coverage can still produce no visits. Keep the component measures visible so the next action is obvious.

    Key takeaways

    • AI visibility is a pipeline spanning discovery, retrieval, reranking, synthesis, and business action. Diagnose the failing stage before editing pages.
    • Organize your strategy around buyer situations and category entry points, not isolated prompt wording.
    • Make recommendation claims explicit, passage-level, qualified, and supported by evidence close to the claim.
    • Use JSON-LD to reinforce accurate visible facts and stable entity relationships, not as a substitute for useful content or authority.
    • Build consistent corroboration through relevant profiles, directories, reviews, documentation, partnerships, and editorial coverage.
    • Measure repeated outcomes across a fixed prompt portfolio. One favorable screenshot is not a rank, and one omission is not proof of failure.

    Choose the category entry point most closely tied to revenue and trace it through the pipeline. Identify the best owned page, the exact claim a recommendation requires, the evidence supporting it, and the credible places that corroborate it. Then establish a baseline before changing anything.

    That gives you a manageable first move: improve one decision path end to end. Once the brand becomes easier to find, understand, verify, and represent accurately there, extend the same method to the next purchasing situation.

    References

  • Google Ads Image Carousels and Phone Number Fraud Controls

    Google Ads Image Carousels and Phone Number Fraud Controls

    Google Ads now puts two very different jobs on the same campaign manager’s desk. The mobile Images tab can carry horizontally scrollable ads built from images, headlines and links, creating another route into visual discovery. But a phone number associated with fraud or earlier policy violations can cause an ad to be disapproved under Destination requirements. One change expands your reach; the other can shut it down.

    If you manage paid search, do not leave compliance until after the creative is ready. Treat the query, image, headline, destination and phone number as one chain. Your practical goal is not merely to activate a new format. You need to know that the ad is relevant, the contact identity is defensible and a delivery problem will not be mistaken for a performance problem.

    Key takeaways

    • Use an image carousel when the visual answers a real customer question. A decorative image may fill the format without helping someone choose.
    • AI-driven matching can connect visuals with searches beyond traditional shopping categories, but it cannot make an unclear offer useful.
    • Manage every advertised phone number as an identity asset. Its history can matter even when your current ad and landing page look compliant.
    • Confirm approval and delivery before judging performance. A disapproved ad tells you nothing about whether its creative would have worked.
    • When possible, do not change the phone number and the main creative idea in the same test. Staging those changes makes the cause of a failure much easier to identify.

    Design the carousel around a visual decision

    A designer arranges five coordinated image cards in a horizontal sequence beside a smartphone on a dark worktable.

    The Images tab serves people who are already exploring through visuals. The carousel format can put your brand in front of someone while they compare and investigate options, before their behavior narrows to a conventional text-ad click. That makes the placement useful for discovery, but only when the image carries information.

    Google’s matching technology can align an ad’s visuals with a search and can surface the format outside retail shopping, including categories such as law and insurance. That expanded availability is not proof that every advertiser needs an image campaign. A generic courthouse, handshake or office photo may signal a category, but it rarely explains why the searcher should choose one result over another.

    Write a four-part creative brief

    Before anyone selects an image, require the brief to answer four questions:

    1. What is the searcher trying to see? Name the visual question, not merely the keyword. The person may need to recognize a product, compare alternatives, understand a process or verify a visible attribute.
    2. What does the image resolve? State what someone should understand before reading the headline. If the answer is only that your company exists, the asset is probably too generic.
    3. What context must the headline add? Use the headline for the qualification, distinction or next step that the visual cannot communicate reliably. Repeating the image wastes limited attention.
    4. Does the destination continue the same thought? The linked page should immediately confirm the subject and promise shown in the carousel. A visually relevant ad that opens an unrelated or overly broad page creates a broken handoff.

    Keep those answers together in the campaign record. If AI matching places the visual beside a relevant search, you can then inspect the whole path rather than debating the image in isolation.

    Test a decision, not a decoration

    Organize creative variants around different reasons a person might choose. One version might demonstrate the offering itself; another might make a comparison easier; a third might explain a process visually. Changing only the crop, background color or ornamental treatment may produce a different-looking ad without testing a meaningful customer question.

    • Give each variant a one-sentence hypothesis: what the image should help the searcher understand or decide.
    • Keep the destination aligned with that hypothesis. Do not send every visual idea to the same generic page merely because the URL is convenient.
    • Change one major idea at a time when learning matters. If the subject, headline, destination and contact method all change together, the result will be difficult to interpret.
    • Define the intended action before launch, such as a qualified visit, call or lead. Increased visual exposure is not automatically business value.

    AI matching is distribution logic, not your creative strategy. Google can decide that a visual corresponds to a search; you still have to decide whether the match expresses the right promise and attracts the right person.

    Audit the phone number as a campaign identity

    A magnifying lens examines a telephone handset token in a connected campaign chain with clean green and tangled red pathways.

    Google set December 10, 2025 as the effective date for rejecting phone numbers tied to fraud or previous policy violations, with enforcement scheduled to increase over roughly the following eight weeks. That ramp described how enforcement would be introduced; it was not a guaranteed grace period for every account. Your campaign controls should already treat the rule as a baseline.

    Do not misclassify this as click-fraud prevention. The change sits under Google’s Destination requirements and concerns the reputation and policy history associated with a phone number. It is not a measurement of invalid traffic. A clean-looking ad or landing page therefore does not neutralize a flagged contact number.

    A phone number is more than a line of copy. It connects the ad to the identity, routing and history of the business presented to the user. Treat it like a governed asset by maintaining a simple registry for every number placed in an ad or ad asset. If the same number appears on the destination, record that placement as well so the complete contact path remains traceable.

    Registry fieldWhat to recordDecision it supports
    Exact phone numberThe complete number as it appears in the campaignPrevents formatting variants or duplicates from escaping review
    Campaign placementEvery ad, asset or destination where your team uses itShows the likely scope if the number is rejected
    Owner and providerThe business owner, vendor or partner responsible for the numberIdentifies who can investigate its use and history
    Provenance checkWhether the number is dedicated, shared or reassigned, plus what the provider can confirm about prior useExposes uncertainty before the number reaches a campaign
    Routing checkThe business, team or call flow that answers the numberConfirms that the contact experience matches the advertiser represented
    Review stateVerified, pending investigation or rejected, with the review dateStops an old assumption from being treated as a current check

    Pay particular attention to numbers supplied by agencies, tracking vendors, franchises, call centers or other partners. The fact that your team did not create a number’s history does not remove the operational risk when Google evaluates its association with fraud or past policy breaches. Ask who controls it, whether it has been shared or reassigned, and who can investigate a flag. Those answers do not guarantee Google’s approval, but they give you a responsible escalation path.

    Do not respond to uncertainty by cycling through unverified numbers until one is accepted. That destroys traceability and preserves the same control gap. A replacement should have a known owner, correct routing and documented provenance before it enters another campaign.

    Separate policy eligibility from creative performance

    A campaign can fail before the audience ever evaluates it. If you treat that failure as weak demand, you may discard a sound visual idea. The safer release sequence has two stages: establish eligibility first, then measure performance.

    Stage one: prove that the campaign can serve

    1. Freeze the proposed package: image, headline, destination and any advertised phone number. Give each item a clear owner.
    2. Confirm that the visual answers the intended search task and that the linked page continues the same promise.
    3. Check every included phone number against your registry. Resolve unknown ownership, routing or provider history before launch.
    4. After submission, verify approval and delivery status before increasing exposure or interpreting performance.
    5. If a phone-related disapproval appears, record the exact notice, number and affected placements. Stop adding that number to new ads while it is being investigated.
    6. Verify the number with its owner or provider, then follow the remediation route supplied in the disapproval notice and Google’s Help Center. Replace the number only with another contact that has passed your ownership, routing and provenance checks.
    7. Once the issue is resolved, review other campaigns that use the same number. Fixing a single rejected ad does not remove the shared dependency elsewhere.

    Avoid rewriting unrelated headlines or swapping landing pages while investigating a phone-specific rejection unless the notice identifies those elements too. Unrelated changes create more possible causes and make the final resolution harder to document.

    Stage two: prove that the creative earns its place

    Once the campaign is eligible to serve, evaluate the visual hypothesis against the action you defined. Keep the approved phone number and destination stable while comparing major image ideas whenever possible. This separates three conditions that are often blurred together:

    • Low or interrupted delivery: first check eligibility and policy status. There may not be enough audience exposure to judge the creative.
    • Exposure without useful engagement: inspect whether the image answers a meaningful question or only signals the category.
    • Engagement without the intended action: inspect the handoff among the image, headline, destination and contact path. The ad may attract attention while promising something the next step does not confirm.

    An approved ad can still be irrelevant, and an AI-matched visual can still be weak. A disapproved ad, however, cannot prove or disprove the creative idea. Keeping those judgments separate prevents you from abandoning useful visual direction because a contact asset blocked delivery, or scaling an attractive ad while its phone-number governance remains unresolved.

    Before your next image-carousel test, require two approvals. The creative owner should confirm the image, headline and destination in one sentence. The operational owner should identify the exact phone number, its controller and its review state just as quickly. If either owner cannot answer, the campaign is not ready to scale.

    References

  • Google Display Asset Reporting: A Practical Optimization Guide

    Google Display Asset Reporting: A Practical Optimization Guide

    You know a Display ad is working, but you cannot tell whether the image, headline, or description earned its place. That gap often leads to blunt creative changes: an entire ad gets rebuilt, including elements that may have been helping.

    Asset-level reporting gives you a better starting point. Its value is not that it names an automatic winner. It lets you make smaller, more deliberate changes while preserving the creative signals you still need.

    What the Assets tab changes for Display campaigns

    Where it is available, Google Display asset reporting shifts the question from “Did this ad perform?” to “Which creative input appears to be helping?” The reporting is designed to show performance for individual images, headlines, and descriptions in an Assets tab. It also shows when an asset was last updated.

    That is a meaningful improvement over an overall ad-level view. You can inspect the components inside an ad before deciding what to retain, revise, or remove. The last-updated information also gives you an anchor for reconstructing when a creative iteration entered the campaign.

    The report does not turn an asset into an isolated experiment. Images, headlines, and descriptions still operate as parts of an ad, within a campaign, for a particular audience and delivery context. Treat the asset signal as evidence for your next test, not as proof that one component caused the complete campaign result.

    Availability was initially identified before a broad release had been confirmed. Begin by opening the relevant Display campaign and checking for the Assets tab. If it is absent, do not assume that your campaign is misconfigured; confirm feature availability in your own account before building a workflow around it.

    Four checks before you call an asset a winner

    A performance label or comparative signal can look decisive when it is not. Before acting, check whether the comparison is fair enough to support a creative decision.

    • Check delivery first. A recently added or lightly served asset has had less opportunity to produce a useful signal. Do not impose one universal waiting period; campaigns accumulate evidence at different rates. Look for meaningful delivery within the account before making a permanent decision.
    • Compare assets with the same job. An image and a headline are different inputs. Even two headlines may serve different purposes, such as introducing the offer or explaining the benefit. Compare like with like before declaring one creative idea stronger.
    • Read the last-updated date against your reporting window. If the date range covers periods before and after an asset changed, the result may represent more than one creative state. Narrow the window or annotate the change before drawing a conclusion.
    • Keep the campaign objective in view. The asset report is a creative diagnostic. Campaign reporting still tells you whether the advertising is producing the outcome you need. A component that attracts attention is not automatically valuable if the campaign result moves in the wrong direction.

    Context matters most when results conflict. If a message works in one campaign but not another, the difference may reflect the audience, offer, or surrounding creative rather than a universally good or bad asset. Keep the asset where it has support and test the underlying idea separately where it does not.

    Turn the report into a controlled creative workflow

    Hands move one colored creative tile through a sequence of ad asset groups while the other components remain unchanged.

    The fastest way to waste asset reporting is to open the tab, remove everything that looks weak, and wait for a better result. That changes several inputs at once and destroys the comparison you need for the next review. Use a repeatable sequence instead.

    1. Select one campaign and one useful date range. Avoid mixing a creative review with major audience, budget, or campaign-structure changes when possible. If those changes are unavoidable, record them so you do not attribute their effects to the assets.
    2. Create a baseline inventory. Record each asset, its type, the performance information shown, and its last-updated date. This can be a simple campaign change log. The important part is preserving what you knew before editing.
    3. Label the idea behind each asset. Group headlines by message, such as product feature, customer benefit, offer, or call to action. Group images by the visual idea they express. This lets you learn about creative themes rather than collecting disconnected asset verdicts.
    4. Choose one uncertainty to resolve. Write a short hypothesis before making the change. For example: “The benefit-led headline is clearer than the feature-led headline for this audience.” A test without a written hypothesis usually becomes a collection of unrelated replacements.
    5. Keep a stable reference asset. Retain a credible existing asset while introducing a deliberate variant. If you replace every component together, you may improve the ad, but you will not know which decision to repeat.
    6. Change the smallest practical set. Replace or update only the assets needed to test the hypothesis. Keep the offer, landing-page destination, and unrelated creative elements stable when the campaign allows it.
    7. Wait for usable delivery, then review in context. Do not make a decision merely because a new signal appears. Confirm that the assets had a reasonable chance to serve and that no major campaign change makes the comparison misleading.
    8. Document the decision. Record what you kept, updated, removed, or left in place, along with the reason. The next reviewer should be able to distinguish an evidence-based choice from a routine creative refresh.

    This workflow also protects you from creative drift. Without labels and a change log, teams often produce several versions of the same message while assuming they are testing different strategies. Naming the idea behind each asset reveals whether you are exploring a new angle or merely rewriting the same one.

    Use guardrails for keep, update, remove, and wait decisions

    A hand considers four color-coded trays holding creative assets for keeping, updating, removing, or waiting.

    The report becomes actionable when each observed pattern leads to a defined response. You do not need a complicated scoring model, but you do need a rule that prevents recent or underexposed assets from being judged like established ones.

    Observed patternWhat it may meanBest next action
    Useful performance signal in a stable campaign contextThe asset is a credible reference, though not necessarily the sole cause of the resultKeep it and create one purposeful variant based on the same idea
    Weak signal after meaningful, comparable deliveryThe execution or message may be less useful than the alternativesUpdate or replace it with a variant tied to a written hypothesis
    Recent update or limited deliveryThe current evidence may be prematureWait, preserve the asset, and review after it has had a fair opportunity to serve
    One execution is weak while the same theme works elsewhereThe concept may be sound, but this wording or visual treatment may not beTest a new execution without abandoning the theme
    The same theme is weak across several asset typesThe underlying message may be the problemTest a genuinely different angle rather than another cosmetic rewrite
    Asset and campaign signals point in different directionsAttention at the asset level may not be translating into the intended outcomePrioritize the campaign objective and investigate the mismatch before scaling the asset

    Removal deserves the most caution because it eliminates a reference point and changes the available creative mix. Have a replacement ready, record why the old asset is leaving, and avoid removing several unrelated assets in one pass. When the evidence is unclear, “wait” is a valid decision rather than a failure to optimize.

    The last-updated field helps, but it is not a complete experiment history. Pair it with your own note describing the hypothesis, the changed component, and any campaign-level changes made at the same time. That turns a timestamp into an audit trail another person can understand.

    Key takeaways for your next asset review

    • Use asset reporting to choose the next creative test, not to claim that one component caused the whole result.
    • Compare assets by type, message, campaign context, and opportunity to serve.
    • Check the last-updated date before interpreting a reporting window.
    • Preserve a stable reference asset and change one creative hypothesis at a time.
    • Keep a separate change log so each keep, update, remove, or wait decision remains explainable.
    • Let the campaign objective settle conflicts between an attractive asset signal and an unhelpful business result.

    Your first review can be simple. Inventory the current assets, label the idea behind each one, and identify the single decision with the weakest evidence. Build one deliberate variant for that uncertainty and leave the unrelated assets alone.

    Repeat that process and the Assets tab becomes more than another reporting screen. It becomes a creative memory: which messages deserve another iteration, which executions need work, and which decisions your next campaign should not have to relearn.

    References

  • Google Opal for Scalable AI Content Without Scaled Spam

    Google Opal for Scalable AI Content Without Scaled Spam

    Your bottleneck is not generating another draft. It is knowing whether the next draft deserves to exist. Google Opal can widen production quickly, but the same speed that helps a campaign can also multiply weak claims, overlapping pages, and editorial work.

    If you are deciding whether to use Opal at scale, build the controls before the volume. The safest operating model has three parts: one governed fact base, one clear job for every asset, and a human release decision for every publishable URL.

    Scale the production system, not the number of URLs

    Opal can turn a single product concept into blog posts, social captions, and video advertising scripts. That one-to-many pattern can be useful because each channel asks the content to do a different job.

    A blog post might answer a buyer’s question in detail. A social caption might introduce the idea to someone who was not looking for it. A video script might demonstrate the product or frame the problem visually. The underlying facts can remain consistent while the format, depth, and immediate purpose change.

    The trouble starts when a team treats every generated variation as a new search page. Changing a keyword, location, audience label, or product name does not automatically create a new reason to publish. If the reader receives substantially the same answer, the outputs are variants of one asset rather than independent URLs.

    Google’s scaled content abuse policy is concerned with producing many pages mainly to influence rankings, especially when those pages are unoriginal and add little value. Generative AI used to manufacture large amounts of low-value content is one example of that risk. The presence of AI is not the decisive issue. The purpose and usefulness of the resulting pages are.

    Scale itself is not a verdict either. Google’s apparent acceptance of Reddit using AI to translate pages at scale illustrates the distinction: a transformation can expand access to existing information instead of manufacturing search inventory. That does not create blanket permission for automated publishing, but it shows why volume alone is the wrong test.

    Before opening Opal, make an output map. Give every proposed asset the following fields:

    • Audience: Who specifically needs this asset?
    • User task: What are they trying to understand, compare, decide, or complete?
    • Distinct value: What will they get here that is not already available on your existing page?
    • Format: Why is a blog post, landing page, caption, or video script the right container?
    • Destination: Will it become an indexable URL, update an existing URL, or live only in a distribution channel?
    • Owner: Who can approve, merge, revise, or reject it?

    If two rows have the same audience, task, evidence, answer, and destination, consolidate them before generation. That single check prevents a campaign plan from quietly becoming a doorway-page plan.

    Ground Opal in a reusable source packet

    An organized central source packet connects to several distinct content formats on a clean creative workspace.

    A product concept is enough to inspire copy, but it is not enough to govern factual content. When the input is vague, a fluent output can hide assumptions, omit necessary qualifiers, or turn a positioning idea into an unsupported claim.

    Build a source packet before you generate anything. This becomes the controlled factual layer shared by the article, social copy, scripts, and future updates. Include:

    • Approved facts: Product capabilities, limitations, compatibility details, terminology, and other statements the content may treat as true.
    • Claim provenance: The internal record, public evidence, subject-matter owner, or approved page supporting each important claim.
    • Entity names: The exact names of the company, product, feature, category, people, places, standards, and versions involved.
    • Prohibited claims: Comparisons, guarantees, performance statements, or implications the available evidence does not support.
    • Audience context: What the intended reader already knows, what decision they face, and what would make the answer useful.
    • Unique contribution: The explanation, example, method, data, opinion, or decision support that gives the asset a reason to exist.
    • Canonical relationship: Which page owns the main answer and how each derivative should refer back to it.
    • Next action: What the reader should be able to do after consuming the asset.

    The packet should also define how Opal handles missing information. A practical generation contract is: use supplied facts for specific claims, preserve every qualification, flag unsupported gaps, and never convert a creative suggestion into a factual assertion. Asking for a visible marker such as [NEEDS EVIDENCE] is more useful than letting a plausible sentence pass unnoticed.

    Have the workflow return a claim ledger with the draft. The ledger does not need to be elaborate. It should identify each verifiable assertion, the packet item supporting it, and any statement that still requires review. This turns fact-checking from a hunt through polished prose into a finite approval task.

    The source packet also gives you an update path. When a product fact changes, revise the controlled record first, identify the affected assets, and update them from the same approved information. Without that shared layer, every derivative becomes an independent copy that can drift away from the truth.

    Put human decisions at the points automation cannot judge

    A human editor operates decision gates along an automated content pipeline, approving one page and diverting uncertain items for review.

    Human review should not mean correcting punctuation after generation. A polished unsupported claim is still unsupported, and an elegant duplicate page is still a duplicate page. Reviewers need authority to decide whether an asset should exist at all.

    1. Intent gate: Before generation, confirm the asset serves a named user task. Reject briefs whose only purpose is covering another keyword variation.
    2. Claim gate: Compare the draft and claim ledger with the source packet. Remove or qualify anything that cannot be traced to approved information.
    3. Value gate: Identify the passage that makes this asset more useful than the canonical page or an existing competitor-independent answer. If that passage does not exist, merge or rework the draft.
    4. Editorial gate: Remove generic setup, repeated conclusions, false certainty, and transitions that merely restate headings. Make the answer direct enough that a reader does not have to excavate it.
    5. Release gate: Decide whether the output becomes an indexable page, an update to an existing page, a non-indexed campaign asset, or discarded material.

    Apply the full set of gates to every indexable URL. A social caption or advertising script may need a lighter structural review, but it still needs factual and brand approval because it draws from the same claims. A publishing template cannot absorb that responsibility; generated outputs can fail in different ways even when they share a prompt.

    Where possible, separate generation from final approval. The person accountable for throughput will naturally see usable material in an almost-finished draft. An approver accountable for accuracy, usefulness, and site quality has a different incentive and can stop unnecessary pages before they enter the index.

    Measure the workflow by accepted assets and resolved user tasks, not raw drafts. Draft count rewards regeneration. Published URL count rewards fragmentation. A useful operating record instead tracks why an asset was accepted, merged, revised, or rejected. Those decisions reveal whether Opal is removing production friction or simply moving the bottleneck into review.

    Make useful content legible to search and AI systems

    SEO, AEO, and GEO work cannot manufacture value after generation. They can make existing value easier for search engines and language models to identify, extract, and connect to the right entity or question. Treat optimization as a clarity layer.

    • Answer the primary question near the start instead of delaying it behind a generic introduction.
    • Use headings that describe real decisions, distinctions, risks, or steps rather than repeating broad keywords.
    • Name products, organizations, features, standards, and versions consistently so the subject does not shift across assets.
    • Keep qualifications next to the claims they limit. Do not hide them in a note at the bottom.
    • Link derivative assets to the page that owns the complete explanation, and update that canonical page when the core answer changes.
    • Use examples only when they illuminate the reader’s task. A generated example that adds no information is decoration, not evidence.
    • Add structured data only for information that is present and visible on the page. JSON-LD describes content; it cannot compensate for a thin or unsupported answer.
    • Use FAQ content only when distinct questions require distinct answers. Do not turn heading variations into artificial question-and-answer padding.

    Then run a release audit from the reader’s side. Ask:

    • Can we state the user’s task in one clear sentence?
    • Does the page deliver information, reasoning, or utility that its closest existing page does not?
    • Can every consequential claim be traced to the source packet?
    • Would the page still help someone who received the link if search rankings disappeared?
    • Does the title promise exactly what the body delivers?
    • Are product names, qualifiers, and conclusions consistent with the related captions and scripts?
    • Does any structured data match the visible page rather than an intended or generated version of it?
    • Are we publishing this URL because a person needs it, or because the workflow happened to produce it?

    The answers should lead to an explicit disposition. Publish an asset with a distinct job, grounded claims, and a complete answer. Merge an asset whose useful material belongs on an existing page. Rework one with a valid user task but inadequate evidence or differentiation. Keep a campaign variation out of the index when it serves distribution rather than search. Discard an output whose only remaining purpose is expanding keyword coverage.

    This is how one product concept can support a coherent content system: the canonical page owns the durable answer, channel assets adapt it for their environments, and the source packet keeps every expression aligned. Opal can accelerate the transformations without being allowed to decide that every transformation deserves a URL.

    Key takeaways

    • Use Google Opal to scale governed transformations across channels, not near-duplicate indexable pages.
    • Require a unique audience task and a distinct contribution before generating a new search asset.
    • Ground every output in a reusable source packet containing approved facts, prohibited claims, entity names, and provenance.
    • Make human review a publish, merge, rework, or reject decision rather than a copy-editing step.
    • Use SEO, AEO, GEO, internal links, and structured data to clarify genuine value, never to substitute for it.
    • Judge the system by accepted, useful assets and consistent claims rather than drafts produced or URLs published.

    Before your next Opal run, choose one product concept, build its source packet, and map each proposed output to a real user task. Generate the channel set only after that map survives review. Scale further when the workflow repeatedly produces assets your editors would choose to publish even without the pressure to produce more.

    References

  • How to Build a Forum That Earns Visibility in AI Search

    How to Build a Forum That Earns Visibility in AI Search

    Your content team can answer the obvious questions. The harder problem is everything too specific, contextual, or fast-changing to justify its own editorial brief. Those questions still get asked. If your site does not host the conversation, users and AI assistants will look elsewhere for it.

    A well-run forum gives those questions a durable home while letting customers, practitioners, and subject-matter experts add the details a conventional content calendar misses. But the software is the easy part. To earn visibility, the community must produce public, well-structured, trustworthy answers rather than empty categories, unresolved threads, and searchable spam.

    Forums capture the demand your editorial calendar misses

    Traditional SEO programs tend to prioritize head terms: topics with recognizable search volume, clear commercial value, and enough demand to support a standalone page. That leaves a wide gap around questions involving unusual configurations, narrow use cases, product combinations, exceptions, and real-world tradeoffs.

    Users do not experience that gap as a keyword problem. They experience it as a question nobody has answered. When an AI assistant lacks enough internal knowledge to respond, it may search the web through engines such as Google or Bing. A detailed discussion can then become more useful than another broad page repeating the standard explanation.

    The scale of that appetite is already visible: Reddit appeared in more than 40% of LLM responses in a June 2025 analysis of 150,000 AI citations. That percentage is not a promise that launching a forum will produce citations. It shows how often AI answer systems rely on conversational material when they need specific, experience-shaped information.

    A useful thread can contain several forms of evidence at once: the language of the original problem, the constraints that made it difficult, several proposed solutions, objections from other practitioners, and a final resolution. That creates semantic depth naturally. It also exposes where an answer works, where it fails, and which conditions change the outcome.

    User-generated content is not automatically accurate, current, or trustworthy. Those qualities come from expert participation and active curation. An unanswered question is merely a thin page. A confident but incorrect reply is worse because it can mislead a customer and give search or AI systems a poor representation of your brand’s knowledge.

    Start by building a question inventory from places where long-tail demand is already visible:

    • Support conversations that require more context than the help center provides.
    • Pre-sale questions that repeatedly need a specialist to answer.
    • Internal site searches that return no useful result.
    • Comments and replies that reveal exceptions to your published guidance.
    • Implementation questions that have several valid answers rather than one universal procedure.
    • Product feedback that begins as a how-to question but exposes a missing feature, unclear workflow, or documentation gap.

    For each candidate, record the audience, product or process involved, constraint, desired outcome, and evidence needed for a credible answer. This becomes both your launch backlog and your first taxonomy. It is far more useful than creating empty categories based on the structure of your company.

    Choose the community format before choosing the software

    A forum should not absorb every type of content. The right format depends on the job the user is trying to complete and how much disagreement belongs in the answer.

    User needBest primary formatWhy it fits
    Compare approaches, share examples, or discuss tradeoffsDiscussion forumSeveral perspectives may remain useful even after the original problem is resolved.
    Solve one defined problem and identify the clearest resolutionQ&A communityAnswers can be evaluated, corrected, and marked as accepted or resolved.
    Confirm an official rule, specification, policy, or supported procedureDocumentationThe brand needs to maintain one canonical answer without ambiguity.
    Explain a broad strategy or synthesize several related issuesEditorial contentA controlled narrative is better than asking readers to reconstruct the answer from replies.

    Many brands need a combination. The community surfaces the question and gathers experience. Documentation records the official procedure. Editorial content explains the larger pattern. Links between those formats help a user move from conversation to an authoritative answer without forcing one page to do every job.

    For discussion-led communities, Flarum and Discourse are open-source options. For a more resolution-oriented Q&A model, Apache Answer and Question2Answer fit that structure. Open-source software can provide customization and control over community data, but it does not remove the operating work. Hosting, security updates, spam controls, moderation, backups, and contributor support still need owners.

    Evaluate each platform against the workflow you intend to run, not the length of its feature list:

    • Public access: Can valuable threads be read without signing in, and can their text be crawled at stable URLs?
    • Data control: Can you export users, threads, replies, moderation history, and attachments in a usable form?
    • Answer states: Can moderators mark a question as resolved, identify an accepted answer, and reopen it when circumstances change?
    • Identity and authority: Can you distinguish employees, verified experts, moderators, experienced members, and ordinary participants without implying that every badge guarantees accuracy?
    • Curation: Can you merge duplicates, redirect obsolete URLs, feature a useful summary, and connect related discussions?
    • Moderation controls: Can permissions expand gradually as a member earns trust, with a clear escalation path for sensitive cases?
    • Search hygiene: Can you prevent thin tag, filter, profile, and empty category pages from overwhelming the useful discussions?

    Do not launch merely because the installation works. Your minimum launch gate should include a named community owner, published participation rules, a prepared backlog of real questions, committed experts who will answer them, and a process for escalating incorrect or sensitive replies. Without those pieces, early visitors learn that asking is not worth the effort.

    Turn each thread into a page an answer engine can understand

    A branching group of discussion tiles is organized into a structured page with separate areas for a question, a primary answer, supporting replies, and related topics.

    A forum thread is both a conversation and a content page. If you optimize only for conversation, the useful answer may be buried under vague titles, missing context, jokes, and outdated replies. If you optimize only for search, the community begins to feel like an unpaid content factory. The page template has to serve both.

    1. Require a descriptive question title. A title such as Need help with discounts carries almost no meaning. How can I limit a discount to subscriptions without changing one-time purchases names the action, object, and constraint.
    2. Prompt for decision-changing context. Ask for the product or process, relevant version, intended outcome, constraints, steps already tried, and any visible error. Do not ask users to publish account credentials, personal information, confidential data, or anything else that should remain private.
    3. Put the usable answer near the top. Once a thread is resolved, add or feature a short summary that states the solution before the longer discussion. Keep the reasoning and alternatives below it for readers whose situation differs.
    4. Label the role behind each reply. An official policy, a verified specialist’s recommendation, and a customer’s workaround are different kinds of evidence. Make that distinction visible instead of flattening every reply into the same level of authority.
    5. Show the resolution and freshness state. Mark threads as open, resolved, or superseded. Display when the accepted information was last reviewed, and reopen the question when a product or policy change makes the old resolution uncertain.
    6. Curate duplicates into a stronger destination. Merge substantially identical questions or point them to the canonical discussion. Preserve distinct threads when a different constraint genuinely changes the answer.

    The technical baseline matters as much as the editorial template. Give every valuable thread one durable URL. Expose the question and replies as crawlable HTML. Use a descriptive page title, keep internal links reachable, redirect merged discussions, and keep empty or low-value system pages out of the index. Include only eligible public pages in discovery feeds such as XML sitemaps.

    Structured data may help machines interpret the page, but it must describe what visitors can actually see. Do not mark an unresolved reply as accepted, manufacture an answer that is absent from the thread, or treat decorative voting as evidence of expertise. Markup can clarify a sound page; it cannot turn a weak discussion into an authoritative answer.

    Being crawlable is not the same as being citable. A passage becomes easier to reuse when it answers the question in self-contained language. Replace replies such as That worked for me with language that names what worked, under which conditions, and what the reader should check before applying it. The simple editorial test is whether two sentences could be quoted outside the thread without losing the subject, constraint, or conclusion.

    Preserve useful disagreement. A minority answer may cover a version, market, or implementation the accepted answer does not. Moderators should remove abuse, spam, impersonation, and dangerous misinformation, but they should not erase a good-faith alternative merely to make the thread look unanimous. Expert consensus is valuable only when the community can see how it was reached.

    Operate the forum as a knowledge system, then measure it

    Community stewards review, connect, and maintain glowing discussion nodes inside a digital archive-like workspace.

    Build moderation into the publishing workflow

    Moderation is not a cleanup queue that begins after growth. It is the process that turns raw participation into reliable knowledge. Define the boundaries before inviting users: what belongs in the community, what evidence is expected, what promotion is allowed, how conflicts are handled, and which questions must move to private support.

    1. Triage new questions. Correct unclear titles, request missing context, merge true duplicates, and move private account issues out of public view.
    2. Route the question. Assign unanswered topics to the employee, partner, or community expert most able to resolve them. Publish an internal response target that reflects actual staffing so questions do not disappear between teams.
    3. Separate contribution from endorsement. Let members share workarounds, but mark which answers represent official guidance. Correct false claims without presenting all disagreement as misconduct.
    4. Close the knowledge loop. When the question is resolved, feature the clearest answer, add a concise summary, connect relevant documentation, and record whether the resolution depends on a particular version or condition.
    5. Distribute responsibility carefully. Give consistent contributors limited moderation privileges, then expand those permissions as judgment and reliability become clear. Keep policy decisions and serious escalations under accountable brand ownership.

    Community-led moderation can scale better than routing every task through one central team because knowledgeable members can improve titles, flag duplicates, welcome newcomers, and surface strong answers. It still needs oversight. Passion for the topic is not the same as authority to set company policy or adjudicate every dispute.

    Measure answer quality before celebrating traffic

    Pageviews can rise while the community deteriorates. Define what counts as a useful reply and a resolved question before building the dashboard, then keep those definitions consistent. Track a small set of measures tied to decisions:

    OutcomeWhat to trackWhat you can do with it
    Question coverageIn-scope questions, unanswered share by topic, time to first useful reply, and resolved shareFind topics with real demand but insufficient expert capacity.
    Contributor healthRepeat contributors, active subject-matter experts, answer corrections, and reliance on a single responderSee whether knowledge is becoming distributed or remains a bottleneck.
    DiscoveryIndexed resolved threads, non-branded search landings, verified AI citations, and identifiable AI referral sessionsDetermine which answer formats and topic clusters earn external visibility.
    Customer valueRepeated support questions, forum-assisted journeys, documentation gaps, and product issues surfaced by discussionsConnect the community to support, content, sales, and product decisions.

    Do not collapse these signals into one vanity score. Response health is an operating signal; search and AI visibility are downstream outcomes. A bot crawl is not a citation, and a citation is not automatically a conversion. Verify important AI mentions against the actual answer, inspect the landing behavior where analytics allows it, and check whether the cited thread represents your position accurately.

    The best measurement loop changes the community. If one topic attracts questions but few answers, recruit or assign an expert. If several threads resolve the same issue, promote the resolution into documentation. If a discussion exposes several legitimate strategies, turn it into a deeper editorial resource and link back to the original examples. If obsolete threads keep earning visits, update or supersede them before they continue spreading stale advice.

    Key takeaways

    • A forum is most valuable when it captures narrow, contextual questions that conventional keyword and editorial planning leave unanswered.
    • Choose discussion software for multiple valid perspectives and a Q&A model when users need a clearly resolved outcome.
    • Require descriptive titles, decision-changing context, visible authority labels, concise answer summaries, and clear resolution states.
    • Public crawlability, stable URLs, duplicate control, and accurate page markup are prerequisites, not substitutes for trustworthy answers.
    • Measure response quality, expert participation, discovery, and customer value separately so you know which part of the system needs attention.

    Your first move is not to install a platform. Collect the questions already escaping into support queues, sales calls, comments, and third-party communities. Choose one coherent topic area, assign the people who can answer it, and design the resolution workflow before opening the doors. A focused forum that reliably solves difficult questions is a stronger AI-search asset than a large community full of unanswered ones.

    References

  • Mastering SEO Strategy Documentation: Your Guide to Success

    Mastering SEO Strategy Documentation: Your Guide to Success

    I’ve learned that documenting an SEO strategy is vital for success. It


    Inspired by this post on Search Engine Land.

  • How to generate OpenAI API Key?

    How to generate OpenAI API Key?

    An OpenAI API key lets you programmatically use OpenAI’s models — so you can build apps, automate tasks, experiment, or integrate AI features into software.

    Why someone would generate one

    • Build applications — chatbots, writing assistants, code tools, content generators, recommendation engines.
    • Automate workflows — summarize emails, generate reports, extract data from documents, classify text at scale.
    • Prototype ideas quickly without hosting models yourself.
    • Integrate AI into products — add natural language features to websites, mobile apps, CRM systems, etc.
    • Research and experiments — testing prompts, comparing models, doing fine-tuning (if available).
    • Batch processing / analytics — run large text/audio/image jobs programmatically.

    How to generate one?

    Step 1 – Go to OpenAI Platform

    Go to https://platform.openai.com/ and use the Login or Sign Up options on the top right

    Step 2 (Optional) – Complete Onboarding if you just signed up

    Step 3 – Generate & Copy your API key

    Step 4 – Add it to crushpress Suite wordpress plugin

    Go to wp-admin -> CrushPress Suite -> Settings and paste the API Key (Secret Key) you just copied and hit save.

    Important security & usage best practices

    • Never embed keys in client-side code (JavaScript on webpages, mobile apps).
    • Store keys in environment variables or a secrets manager.
    • Rotate keys periodically and revoke compromised keys immediately.
    • Apply least privilege (use separate keys for dev/staging/prod).
    • Monitor usage and set billing/quotas to avoid surprises.
    • Restrict keys where possible (IP restrictions, allowed referrers).
    • Don’t share keys publicly (no GitHub commits with keys).

    Risks & costs

    • Keys grant access to billable API usage — a leaked key can generate charges.
    • Misuse could cause unwanted outputs; always validate/guard outputs before using them in critical flows.

  • November 2025

    November 2025

    Last Updated: November 7, 2025

    I

    ```json
{
  "alt": "Line graph showing Gemini's market share trend from July 2024 to September 2025, ranging between 13.30% and 13.70%.",
  "caption": "Gemini's market share remains steady from July 2024 to September 2025, fluctuating slightly around 13.50%.",
  "description": "This line graph illustrates Gemini's market share from July 2024 to September 2025. The market share ranges between 13.30% and 13.70%, showing minor fluctuations. The graph presents data points at each two-month interval, highlighting a stable trend around 13.50%. This visual representation provides insight into the consistency of Gemini's market presence during this period. Keywords: Gemini, market share, trend, graph, 2025, stability."
}
```

    Inspired by this post on First Page Sage Blog.

  • How to Expand Performance Max Without Losing Budget Control

    How to Expand Performance Max Without Losing Budget Control

    Your Google Ads account is asking you to make two bets at once: let Performance Max reach more places, and consider spending more when a campaign is budget limited. The dangerous move is to treat both prompts as proof that profitable scale is available.

    Expansion can be rational, but only when you separate reach, budget, and campaign architecture. The framework below helps you test each decision, read the additional visibility correctly, and keep automation accountable to revenue, qualified demand, or store outcomes rather than raw platform activity.

    Key takeaways

    • Deciding to use Performance Max, approving more budget, and accepting broader inventory are three separate decisions. Review them separately.
    • Google Ads investment strategies are forecasts, not guarantees. Evaluate the marginal return from the proposed increase rather than the campaign’s blended average.
    • Channel reporting can tell you where Performance Max delivered ads. It cannot, by itself, prove that a channel caused incremental business.
    • Waze inventory matters primarily to eligible store-goal campaigns. It is not a general reason for an online-only advertiser to adopt Performance Max.
    • Search and Performance Max can coexist. Move budget service by service or product group by product group, then judge the portfolio on business outcomes.

    Split expansion into three decisions

    A hand adjusts one of three separate control modules for network reach, budget flow, and campaign structure.

    Google is automating several layers of advertising at the same time. A budget-constrained campaign can surface an investment strategy that models higher spend. Eligible store-goal Performance Max campaigns can gain additional reach through Waze. Google has also announced AI-assisted ad review, reporting, and support across its publisher products.

    The practical consequence is that one apparent recommendation may contain several choices. Untangle them before you approve anything.

    DecisionQuestion to answerMinimum evidence
    Campaign architectureShould Performance Max complement or replace part of Search?Business results for a defined service, product group, market, or goal
    BudgetIs the next unit of spend likely to meet your economics?Marginal cost per acquisition or marginal return on ad spend, adjusted for lead quality, margin, and capacity
    InventoryDoes broader delivery reach people who can complete the intended action?Channel delivery data checked against CRM, commerce, or store outcomes

    Do not evaluate all three with a single headline metric. If you increase the budget while Performance Max gains new inventory and you also change creative assets, a rise in conversions will not tell you which change helped. Record the effective date of each material change and keep the other variables stable long enough to interpret the result.

    Run a readiness gate before you scale

    Automation magnifies the instructions and evidence you give it. Before adding budget, require a clear answer to each item below.

    • Primary outcome: Name the result the campaign should optimize. A purchase, accepted lead, booked appointment, store visit, and click are not interchangeable.
    • Signal integrity: Confirm that conversion definitions, values, and attribution settings have not changed during the comparison period. Reconcile platform records with the system where the business outcome is actually recorded.
    • Asset coverage: Check whether the campaign has images, video, copy, and landing pages that represent the specific offer. Strong visual assets are especially important as AI-led campaigns distribute beyond conventional text placements.
    • Unit economics: Write down the maximum acquisition cost or minimum return the business can accept. Platform conversion value is not automatically revenue, margin, or profit.
    • Traffic fit: Confirm that the products, services, locations, and audiences included in the campaign match what the business can fulfill.
    • Review ownership: Assign one person to compare channel delivery, campaign results, and downstream business quality on a fixed review date.

    If you cannot pass this gate, you can still run a bounded learning test. You cannot responsibly call it a scale test, because the conditions for judging success are missing.

    Use investment strategies without outsourcing the budget decision

    When Google identifies a budget-limited campaign, it can invite you to create an investment strategy. The tool lets you model budget increases and preview projected changes in conversions, conversion value, or clicks.

    That is useful scenario planning. It is not approval evidence on its own. A forecast answers what the advertising system predicts under its assumptions. It does not decide whether your margin, lead acceptance rate, sales capacity, cash position, or inventory can support the proposed spend.

    Use the forecast in this sequence:

    1. Freeze the baseline. Record current spend, conversions, conversion value, and the downstream business result. Note any recent changes to assets, targeting, conversion definitions, or landing pages.
    2. Select the output that matters. For ecommerce, that may be validated order value or contribution margin. For lead generation, it may be accepted opportunities or closed revenue. Do not justify more budget with projected clicks unless a click is genuinely the business objective.
    3. Measure the delta. Subtract the current forecast from the higher-budget scenario. Marginal cost per acquisition equals extra spend divided by extra conversions. Marginal return on ad spend equals extra conversion value divided by extra spend.
    4. Translate platform value into business value. Adjust for cancellations, returns, lead rejection, sales close rate, fulfillment cost, and any other difference between a recorded conversion and an economic result.
    5. Set a downside boundary before spending. Define the amount you can test, the review date, and the condition that pauses further increases. If the business cannot absorb the test when the forecast misses, the proposed increase is too large.
    6. Stage the increase. Approve one increment, compare actual marginal performance with the projection, and use that variance when considering the next increment.

    The marginal calculation is the part most teams miss. A campaign can retain an attractive blended average while its newest spend is substantially less efficient. Budget decisions belong at the margin because that is where the next dollar will operate.

    Keep the forecast with your decision record. At the next review, compare projected and actual changes rather than merely asking whether total conversions increased. Repeated forecast misses are a reason to reduce confidence in the next scenario, even when the campaign remains profitable overall.

    Govern broader inventory with business-level reporting

    Treat Waze as a store-goal expansion

    The announced Waze integration applies to Performance Max campaigns using store goals. It was introduced for U.S. advertisers through Promoted Places in Navigation pins, using existing campaign assets without additional setup and optimizing toward store visits or sales. Worldwide availability was anticipated in 2026, so confirm availability in your account instead of assuming the planned rollout is universal.

    This distinction prevents a common category error. If your objective is online lead generation with no location outcome, Waze inventory is not a reason to launch Performance Max. If you operate physical locations, it may be relevant, but only after the location and store outcomes are ready to support optimization.

    • Confirm that the store goal is a real business priority, not merely an enabled conversion action.
    • Validate the locations and destinations represented by the campaign before relying on navigation-based exposure.
    • Choose the business record that will validate the result, such as completed store sales or another approved location outcome.
    • Record when Waze delivery becomes available so changes in the channel mix are not mistaken for a creative or budget effect.
    • Do not include anticipated Waze reach in a forecast until the inventory is actually available to the campaign.

    Read channel reports in three layers

    Performance Max channel reporting adds visibility into where ads appear across Google’s network. The reporting expansion also included bulk workflows, segmentation, and downloadable data, which makes multi-account analysis more practical. Search partner detail was described as a forthcoming addition, so verify its presence before building a process that depends on it.

    1. Delivery: Where did Performance Max serve, and did the channel mix change after the expansion?
    2. Platform performance: What conversions or value did Google Ads associate with that delivery?
    3. Business validation: Did qualified leads, completed orders, store sales, or another accepted outcome improve outside the ad interface?

    The third layer authorizes scale. Channel reporting can make allocation more inspectable, but it does not establish incrementality by itself. A channel may receive credit for a conversion that would have occurred through another touchpoint, and a higher platform conversion count can coexist with weaker lead quality.

    Use channel data to form a question, then test that question against the business record. If Waze delivery rises, for example, inspect location outcomes and the rest of the channel mix before attributing an overall lift to Waze. If Search partner detail becomes available, evaluate it with the same standard rather than treating added transparency as automatic evidence of value.

    Migrate from keyword campaigns in controlled slices

    A segmented bridge is moved in controlled stages from a narrow campaign route to a broader network, with budget gates at each checkpoint.

    Performance Max versus Search is a false binary for most accounts. Some B2B teams have produced enough months-long evidence to move selected services from keyword campaigns toward Performance Max. In that approach, high-priority services initially retained keyword coverage while Performance Max tested other services that were costly to promote through keywords. Stronger results then justified additional budget and broader use.

    That shows that Performance Max can earn a larger B2B role. It does not establish that every account should abandon keywords. Use a staged migration:

    1. Choose a bounded slice. Select one service, product group, or market with distinct economics. Avoid beginning with the entire account.
    2. Protect the baseline. Keep high-intent Search coverage stable for the priority offer while Performance Max tests a secondary area. This preserves a reference point and limits business exposure.
    3. Align the inputs. Give the Performance Max slice a clear conversion goal, complete assets, relevant landing pages, and the same downstream quality review used for Search.
    4. Allow a meaningful assessment window. A two-month initial evaluation is a practical starting point when budget and risk allow, but it is a test-design choice rather than a universal learning-period guarantee. Stop earlier if tracking breaks or spend leaves the approved scope.
    5. Compare business quality. Review accepted leads, pipeline, sales, or another outcome that both campaign types can influence. Conversion volume alone is insufficient when one campaign attracts materially weaker demand.
    6. Expand only after the bounded test passes. Add Performance Max to a priority service if it contributes acceptable business value. Reduce keyword coverage only after the total portfolio remains healthy through that change.

    For B2B advertisers, this also prevents one campaign from carrying incompatible jobs. Demand Gen, YouTube, or another brand-trust effort can build familiarity; Search can retain explicit intent; and Performance Max can test broader automated reach. Give each role its own success measure, then judge how the combination affects the buyer journey and final commercial result.

    At your next planning review, approve one bounded change: a campaign test, a budget increment, or an inventory expansion. Write down the business outcome and stop condition first. Automation becomes easier to trust when every increase must earn the next one.

    References