Author: shivamcrushpressai

  • Branded-Search PPC Defense: A Practical Campaign Playbook

    Branded-Search PPC Defense: A Practical Campaign Playbook

    Your brand ad can be winning clicks while losing the decision. If every branded query triggers the same message and lands on your homepage, a prospect searching Is [Brand] good? or Alternatives to [Brand] still has to find the answer alone. A competitor, affiliate, or review site can make that answer easier to reach.

    A useful branded-search defense does more than bid on your name. It separates navigation from validation, feature research, comparison, and objection handling. That gives you control over the bid, message, proof, and landing page at the point where each decision is being made.

    Treat branded search as four different decisions
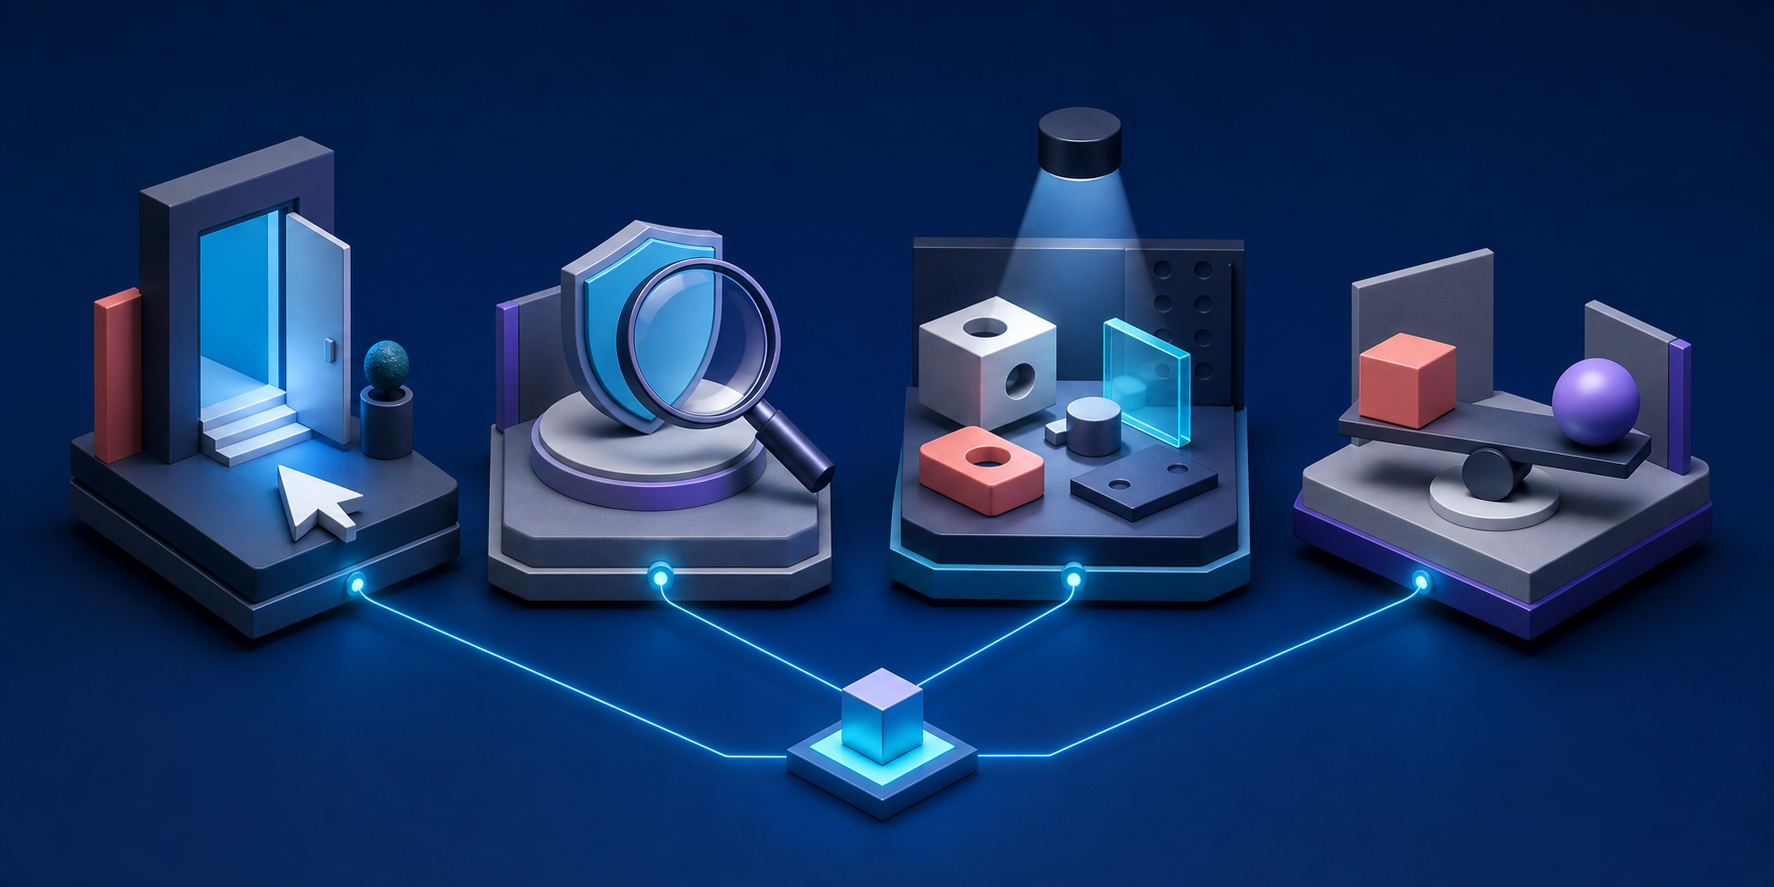
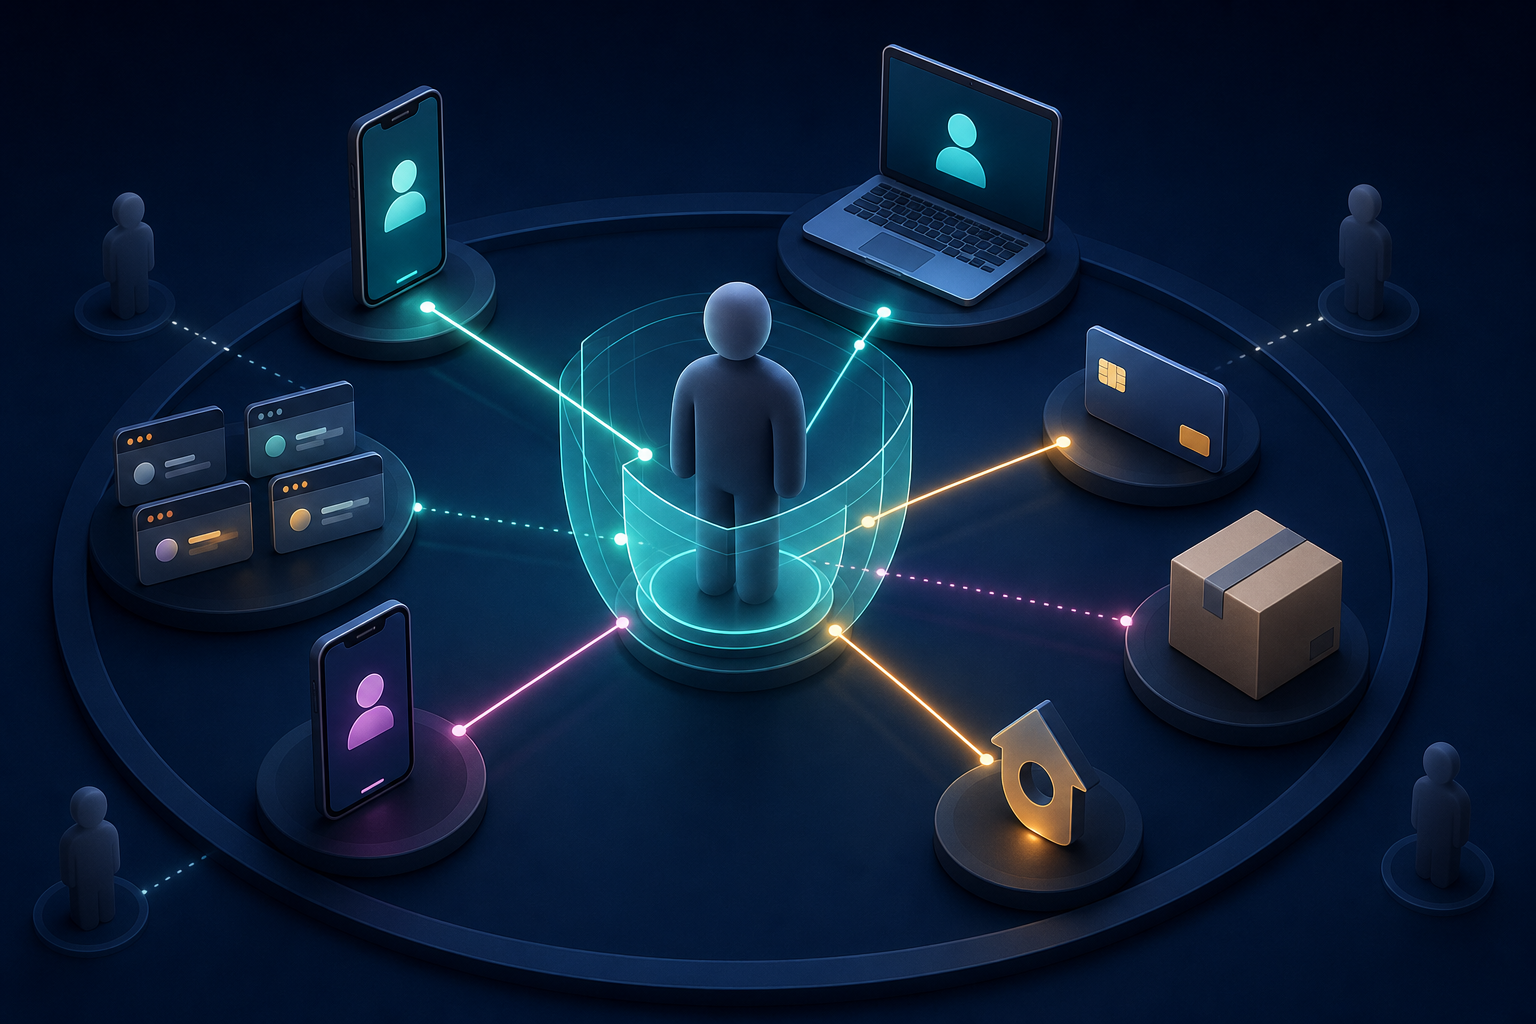
    Four connected isometric scenes depict direct navigation, proof checking, feature research, and comparison as separate decision paths.

    The exact brand name is your baseline, not your complete keyword strategy. People add modifiers when they need reassurance, confirmation, alternatives, or an answer to a specific concern. Those searches carry different risks and should not be forced through one generic ad group.

    Query familyWhat the prospect needsCompetitive openingBest response
    Trust and reputationEvidence that your brand is credible and safe to chooseReview sites can redirect the prospect toward competing offersProof-led ads and a testimonial or reputation page
    Product and featureConfirmation that a required capability existsA rival can introduce its own feature claim before you answerFeature-specific copy, sitelinks, and a relevant product page
    ComparisonHelp choosing between your brand and another optionCompetitors and affiliates can frame the comparison for youTransparent comparison content, clear positioning, and sufficient bids for visibility
    Niche question or objectionA direct answer about cost, suitability, or another concernAn unanswered concern can become a reason to leaveFAQ-style copy and a page that resolves the exact issue

    This division matters because branded searches extend across validation, feature research, comparisons, and narrow questions. Combining them hides which searches face competitive pressure and which landing pages fail to answer the prospect’s real question.

    Keep navigational searches such as the brand name by itself in their own group. Someone trying to reach your website is not in the same decision state as someone asking whether your product is expensive. The first may need a quick route to the correct page. The second needs context before a price can make sense.

    Build the campaign around intent, not one brand keyword

    You do not need a complicated account structure for its own sake. You need enough separation to change the bid, ad, and destination when the query’s purpose changes. In a smaller account, distinct ad groups may provide enough control. Use separate campaigns when an intent family needs its own budget or other campaign-level settings.

    1. Inspect the search terms that actually triggered your branded ads. Do not limit the review to the keywords you originally added.
    2. Label each useful term as navigation, trust and reputation, product and feature, comparison, or niche question. Put unclear modifiers in a review queue rather than forcing them into a convenient category.
    3. Separate the intent families that require different bids, messages, or landing pages. If two terms would receive the same treatment, they do not need artificial separation.
    4. Create a destination map before rewriting ads. Assign each group to the page that answers its question most directly.
    5. Use negative keywords to prevent obvious routing conflicts, but check the effect before expanding them. An aggressive negative list can remove the very modifier coverage the defense is meant to create.
    6. Maintain a controlled way to discover new brand modifiers. Exact-match coverage alone cannot reveal every reputation concern, comparison phrase, or feature question appearing in real searches.

    The destination map is the most important check in this process. If every row still points to the homepage, the structure has changed but the customer experience has not. Either build a page that answers the intent or acknowledge that you are not yet ready to buy that traffic aggressively.

    Query classification also prevents an easy reporting mistake. A high-converting navigational group can make the overall brand campaign look healthy while reputation or comparison traffic quietly underperforms. Review performance by intent family, not only at campaign level.

    Match the ad and landing page to the modifier
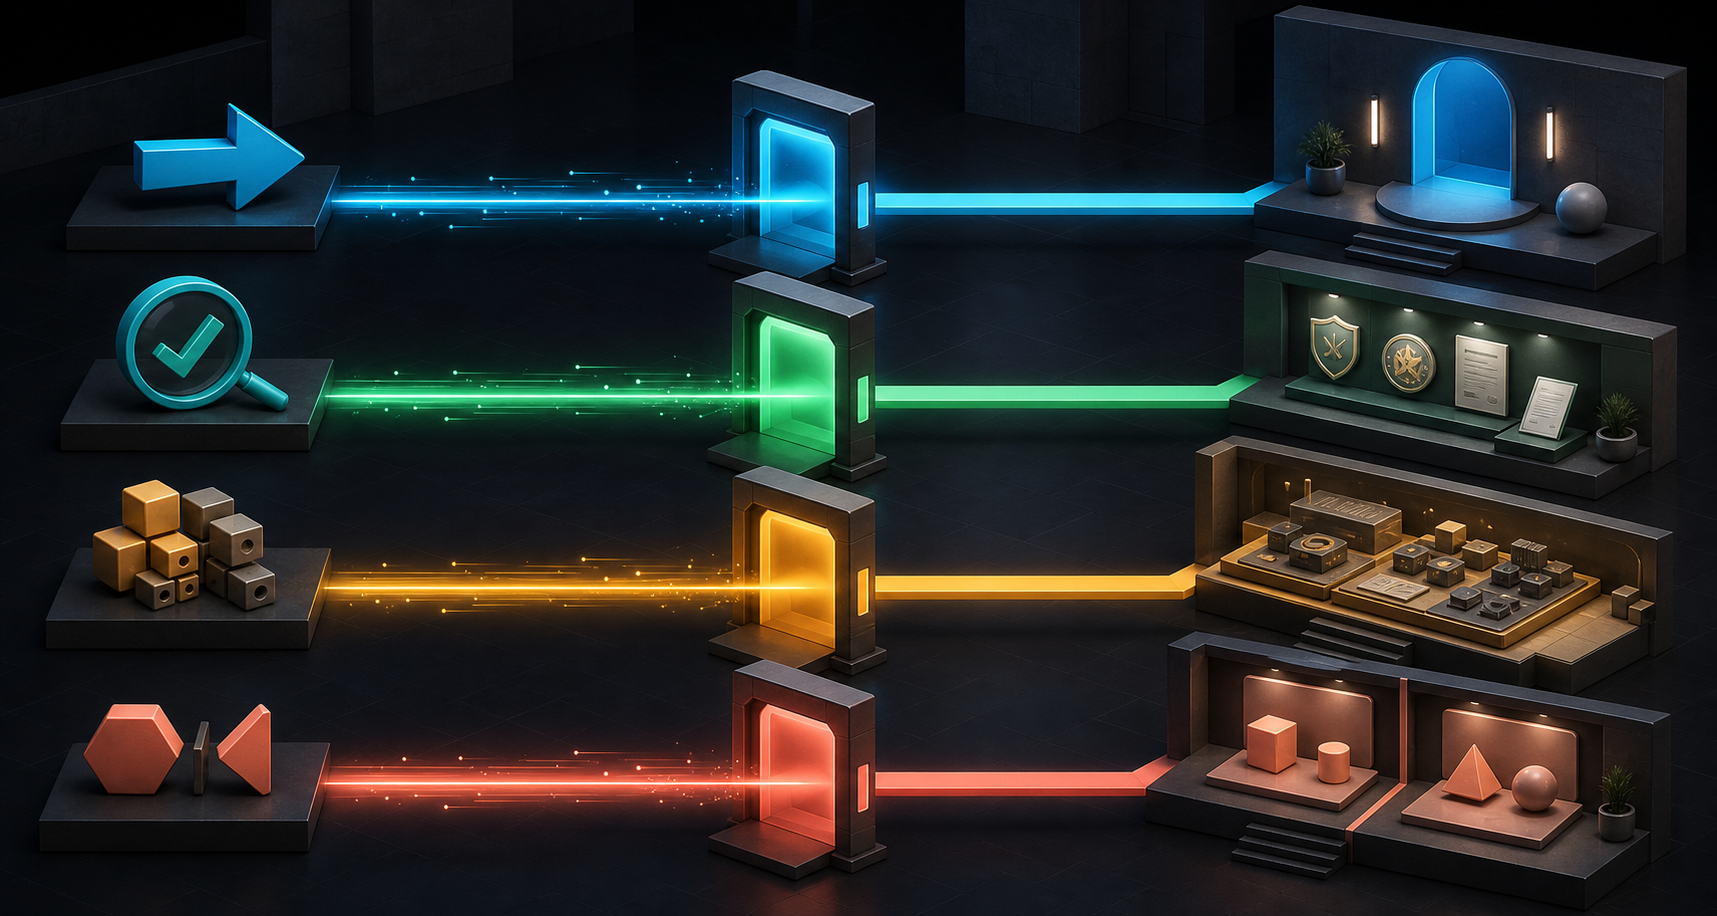
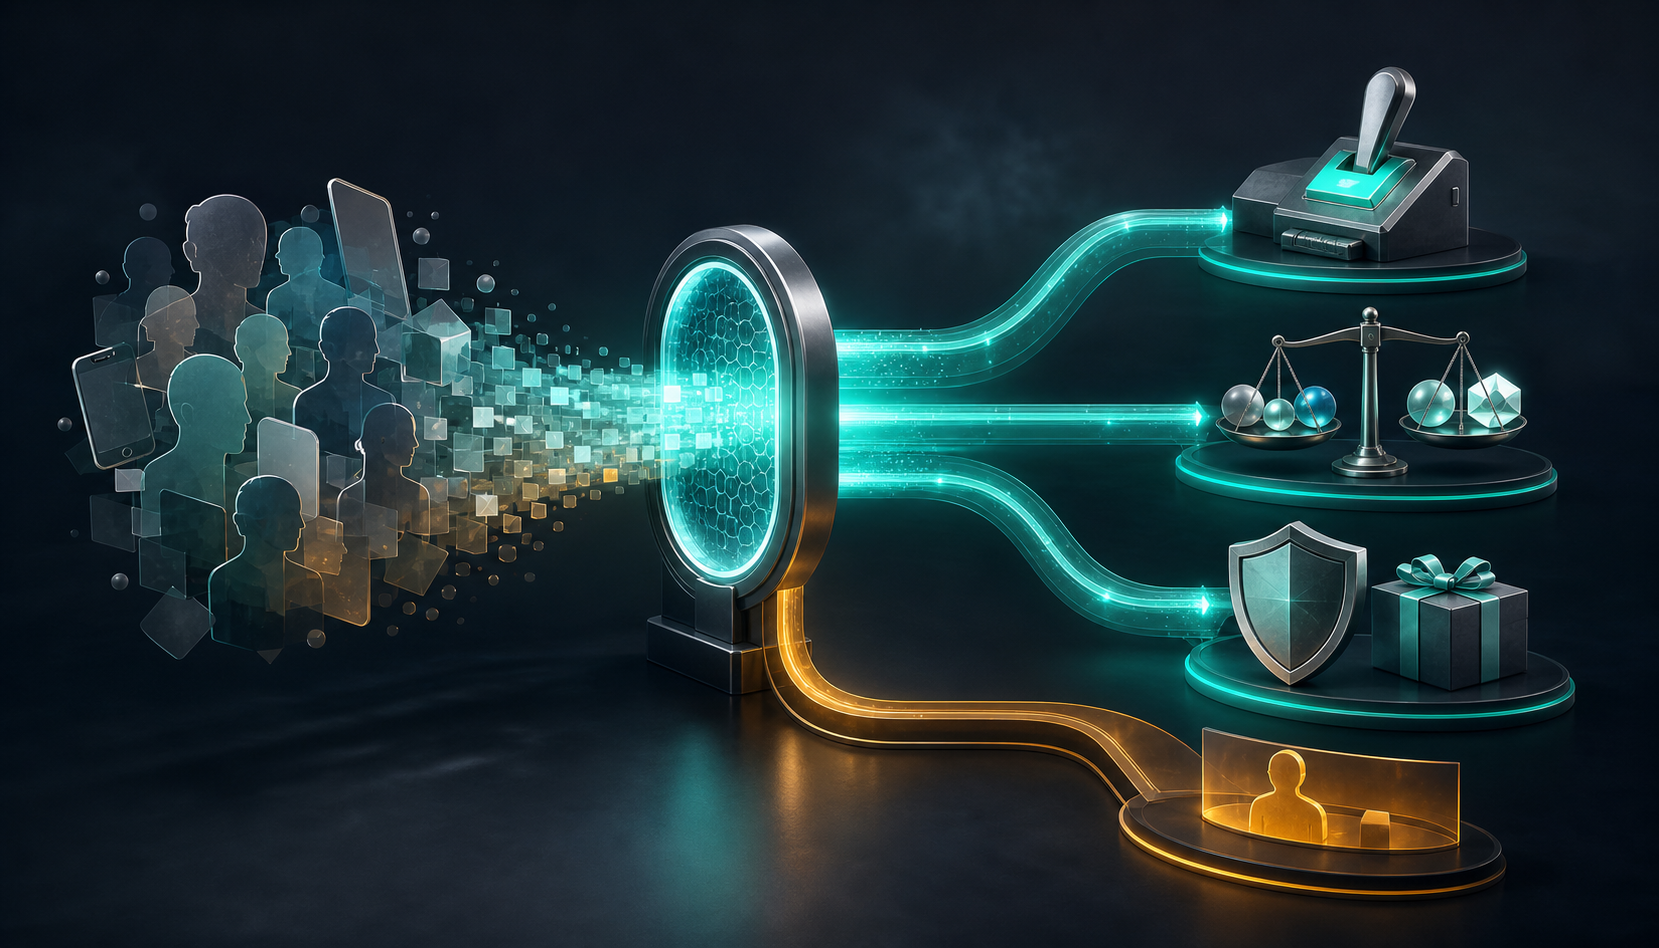
    Four icon-based search signals pass through separate colored gateways and lead to four different landing-page environments.

    Your ad should answer the extra words in the search. Repeating the brand name is rarely enough because the prospect already knows it. Use the headline and supporting copy to address what changed when the modifier was added.

    Trust and reputation searches need verifiable proof

    A query such as Is [Brand] good? is a request for reassurance, not a request for your standard value proposition. Lead with evidence the prospect can verify. That might include eligible ratings, genuine awards, a meaningful history in the market, or a concrete customer outcome, but only when the claim is accurate and supported on the destination page.

    Send the click to a page organized around trust. Put testimonials, rating context, credentials, and answers to common doubts where the visitor can find them without navigating through the rest of the site. Available rating or review assets can reinforce the message, but they cannot compensate for a landing page with no proof.

    Feature searches need a direct confirmation

    For a query containing a specific feature, lead with that capability. The brand is already present in the query, so repeating it in every headline may use space that could resolve the question. Use sitelinks to expose closely related feature pages, documentation, demonstrations, or videos when they help the prospect verify the claim.

    The landing page should make the feature easy to confirm and understand. Name what it does, show how it works, and explain any material limits. A vague product overview forces the visitor back to the search results, where a competitor may offer a clearer answer.

    Comparison searches need an honest decision page

    Alternatives to [Brand] signals active comparison. Avoid answering it with copy that pretends no alternatives exist. Explain the criteria that should drive the decision, where your offer fits, and who may not be a good fit. If your pricing is an advantage, make it easy to understand rather than burying it behind a generic call to action.

    A comparison page should not rely on a straw-man competitor. Use criteria a buyer would genuinely consider, keep claims supportable, and make the basis of each comparison visible. Monitor auction insights for this query family because a new advertiser can change the value of maintaining top-page presence even when the core brand term looks quiet.

    Niche questions need a concise answer before a pitch

    A question such as Is [Brand] expensive? exposes a specific hesitation. Route it to an FAQ-style page or a tightly relevant section that answers the concern in plain language. Explain the factors that affect the answer, then give the visitor an appropriate next step.

    Competition may be lighter on narrow questions, so test lower bids instead of copying the bidding posture used for comparison terms. Check the auction rather than assuming the query is uncontested. More importantly, treat newly appearing questions as feedback: repeated concerns may warrant changes to product pages, sales material, organic content, and customer-facing FAQs.

    Set bids by the cost of losing the decision

    Branded campaigns are often managed as if every click has the same defensive value. It does not. A clean navigational query with no visible advertiser pressure is different from a reputation query surrounded by review sites or a comparison query targeted by competitors.

    • Bid assertively on trust and reputation searches when the prospect is close to choosing and competing pages can intercept that choice.
    • Protect comparison visibility when competitors are actively appearing, but make sure the landing page can support the bid with a credible comparison.
    • Evaluate feature terms separately. A high-value feature query may justify more coverage than the unmodified brand name.
    • Start niche questions with controlled bids when competition is limited, then adjust according to conversion quality and auction pressure.
    • Set navigational brand bids from observed competition and incremental value, not from the assumption that the top paid position must be owned at any cost.

    There is real budget risk in bidding aggressively before you segment performance. Easy navigational conversions can subsidize expensive comparison clicks and conceal the difference in your aggregate return. Separate reporting before raising bids, then decide which searches are worth defending and which need a better page first.

    Judge the campaign with a small set of diagnostic questions:

    • Did the important query trigger the intended ad group and message?
    • Did it land on a page that answered the modifier directly?
    • Which competitors, affiliates, or review properties appeared in auction insights for that intent family?
    • Did the click produce the intended conversion or a qualified lead, rather than merely a high click-through rate?
    • Which new modifiers reveal objections, comparisons, or feature needs that your current structure misses?

    Do not use aggregate branded return as the only success measure. Break out conversion rate, conversion value or lead quality, search-term coverage, and auction pressure by intent. The goal is not to maximize paid brand traffic. It is to preserve access to valuable prospects when paid visibility and a better answer can influence the outcome.

    If you need to test whether paid ads are merely capturing clicks your organic result would have received, avoid pausing the entire defense in the middle of visible competition. Start with the least contested navigational segment and preserve coverage for reputation and comparison queries. A broad pause can expose the brand to competitors while producing a result that does not explain which intent family caused the change.

    Key takeaways

    • A bid on the exact brand name covers navigation, not the full branded customer journey.
    • Separate trust, feature, comparison, and niche-question searches when they need different bids, messages, or destinations.
    • Fix the landing-page route before paying more for a query. A stronger bid cannot repair an unanswered question.
    • Use proof for reputation searches, direct confirmation for feature searches, transparent criteria for comparisons, and concise answers for narrow objections.
    • Review auction insights and search terms by intent so easy brand conversions do not hide competitive gaps.
    • Feed recurring modifiers back into your organic pages and FAQs; they reveal the language prospects use when deciding whether to trust or choose you.

    Start with your existing search-term data. Label the terms by intent, identify the valuable queries currently routed to a generic page, and fix those destinations first. Then change the ads and bids. That order keeps branded-search defense tied to the decision you need to protect, rather than the position you want to occupy.
    References

  • AI Search Content Optimization: A Practical Rewrite Method

    AI Search Content Optimization: A Practical Rewrite Method

    You have a page with real expertise, a useful answer, and a clear business purpose, yet AI-generated search results keep passing it over. The problem may not be the quality of the information. The answer may be buried in a long introduction, hidden behind a vague heading, or scattered across passages that make sense only when someone reads the whole page.

    The practical fix is to make that expertise easier to retrieve and combine. You do not need to flatten every page into robotic question-and-answer copy. You need to expose the answer, keep each important section understandable on its own, and connect the page to the rest of your topic coverage.

    Key takeaways

    • Prioritize pages that already contain valuable expertise but communicate their answers indirectly.
    • Build each important section around one question, claim, or decision so the passage still makes sense outside the page.
    • Use hub pages for topic orientation and spoke pages for focused, in-depth answers.
    • State the direct answer before adding reasoning, evidence, limitations, and exceptions.
    • Use titles, headings, descriptions, and internal links to reinforce the page’s purpose rather than compensate for unclear body copy.
    • Test whether an AI system can summarize the page accurately without losing the qualification that makes the answer trustworthy.

    Start with pages that already have answer value

    Traditional content refreshes often begin with declining traffic, outdated keywords, or slipping rankings. Those signals can still matter, but they do not tell you whether a page is a good candidate for AI search optimization. A page can receive modest traffic and still contain the clearest answer your organization has to an important customer question.

    For AI search, prioritize answer value. Look for pages that contain clear expertise, recurring customer questions, proprietary insight, durable reports, or evergreen explanations. Internal training material and pages that your sales, support, or subject-matter teams repeatedly share can also be strong candidates. Repeated internal use is a practical sign that the page already helps people understand something consequential.

    Create a revision queue with these fields:

    • Primary question: What exact question should this page answer?
    • Business purpose: What should a qualified reader understand, decide, or do after reading it?
    • Distinct value: What does this page contribute beyond a generic explanation of the topic?
    • Current answer: Where does the page actually state its main conclusion?
    • Extraction weakness: What would become confusing if a passage appeared without the introduction or surrounding sections?
    • Content relationship: Which broader hub and narrower related pages should connect to it?

    Then apply a simple screen. Can a reader identify the page’s question from the title and opening? Is the answer visible before the background material? Can a key passage be understood without reading the paragraphs above it? Are important qualifications attached to the claim they limit? Are the takeaways stated rather than left for the reader to infer?

    If the page is commercially or strategically important and those checks fail, move it up the queue. If it has no distinctive answer, rewriting the headings will not solve the deeper problem. Formatting can reveal expertise, but it cannot manufacture expertise that is not there.

    Rewrite the page as a set of standalone answer units

    A long layered document is separated into an orderly grid of distinct blank content cards.

    AI search systems do not always use a page as one indivisible document. They may retrieve a passage that appears relevant to a question and use it while constructing an answer. That makes chunk-level clarity a core editing requirement.

    An answer unit is a section centered on one idea. It should remain useful when separated from the page around it. A strong unit usually contains:

    1. A specific heading: Name the question, assertion, problem, or decision the section addresses.
    2. A direct opening answer: Give the conclusion before the history or explanation.
    3. The necessary qualification: State who, when, or under what conditions the answer applies.
    4. Support: Explain the reasoning, evidence, example, or mechanism behind the answer.
    5. A useful connection: Link to the next page a reader needs if the topic extends beyond this section.

    Consider a section headed Why it matters that begins, “This can also make the process easier.” Both the heading and sentence depend on missing context. A clearer version would use the heading Why does answer-first formatting help AI search? and open with, “Answer-first formatting exposes the section’s main claim before the supporting explanation and exceptions.” The revised passage names the subject and gives the reader an answer immediately.

    Run an isolation test on every important section. Copy the heading and its paragraphs into a blank document, then inspect the passage without the page title, introduction, sidebar, or preceding section. Look for words such as “it,” “this,” “that method,” “the issue,” and “these benefits.” If the missing context could change the meaning, replace the vague reference with the actual subject.

    This may require slightly more noun repetition than polished magazine prose. That is acceptable when the repetition removes ambiguity. You are not trying to make every sentence repetitive. You are making sure the passage does not become misleading when retrieved on its own.

    Do not confuse chunking with aggressive fragmentation. Create a new section when the reader’s question or decision changes, not whenever the page reaches a convenient visual break. If adjacent sections require the same setup before either one makes sense, they may belong in a single answer unit. If one section tries to define a term, compare options, describe implementation, and handle exceptions, it probably needs to be divided.

    Clarity also does not require oversimplification. Put the plain answer first, then preserve the conditions that make it accurate. A statement such as “Use this approach” is easy to extract but not useful if the real recommendation applies only to a particular audience or situation. Keep the recommendation and its boundary together.

    Build breadth with hubs and depth with spokes

    A single page should not carry every possible question about a broad topic. Trying to make one URL comprehensive often produces a long page with shallow sections, overlapping intent, and no obvious main answer. A hub-and-spoke structure gives each page a clearer job.

    The hub introduces the subject, establishes its major branches, and directs the reader to focused resources. Each spoke resolves one narrower question in greater depth. Linking the spokes back to the hub, and linking related spokes when the reader genuinely needs both, creates explicit signals about how the topics relate.

    Map the topic before rewriting individual paragraphs:

    1. Define the hub’s promise. Write one sentence describing what the reader should understand after using the hub.
    2. List the major question types. Separate definitions, reasons, processes, use cases, constraints, mistakes, and decision points where they require materially different answers.
    3. Assign an owner to each question. Choose one page that will provide the primary answer instead of allowing several URLs to compete with near-identical explanations.
    4. Find missing depth. Mark important questions that receive only a sentence on the hub but deserve a focused spoke.
    5. Find unnecessary overlap. Merge or reposition pages that answer the same question without contributing a distinct audience, condition, or level of detail.
    6. Add purposeful links. Connect pages where the relationship helps the reader continue the task, not merely because the pages share a keyword.

    Use descriptive internal-link text. “See our content audit process” gives the destination a clearer role than “learn more.” The surrounding sentence should explain why the linked page matters: it may supply the implementation steps, define a prerequisite, document an exception, or address the next decision.

    Keep the distinction between breadth and depth visible during editing. Breadth means your site covers the important branches of the subject. Depth means the responsible page answers its assigned question with enough explanation, support, and qualification to be useful. Adding more headings to the hub does not create depth if every section remains superficial.

    This structure also gives you a practical publishing decision. If a missing answer can be handled clearly within the existing page’s purpose, add it there. If it changes the audience, intent, or decision being addressed, create a separate spoke and connect it to the hub. That keeps the original page focused while expanding the site’s topical coverage.

    Make the answer easy to synthesize

    Retrieval is only part of the job. An AI system may need to combine definitions, conditions, examples, and limitations from different passages. Your copy should make those relationships explicit enough that the system does not have to rewrite the argument merely to understand it.

    For each important question, use an answer-first sequence:

    • Answer: State the conclusion in plain language.
    • Explain: Describe why the answer holds or how the process works.
    • Support: Add the evidence, example, or expertise that makes the answer worth using.
    • Bound: Identify limitations, exceptions, prerequisites, or cases where a different answer applies.
    • Direct: Tell the reader what to do next or where to find the connected detail.

    This order is not a ban on nuance. It is a decision about timing. Give the answer before the complexity, then add the complexity where it can refine the answer instead of delaying it.

    Use explicit labels when they help. “Summary,” “What this means,” and “When this does not apply” tell both the scanning reader and the retrieval system what a passage is doing. Avoid decorative labels such as “The road ahead” when the section is actually explaining implementation requirements. A heading should describe its information, not merely set a mood.

    Write title tags around purpose, not just topic

    A title tag that names only a broad keyword leaves the page’s contribution unclear. Add the question, decision, or scope that distinguishes the answer. For example, “Session replay software” identifies a topic, while “Session replay: what it shows, when to use it, and its limits” describes the page’s purpose.

    Use this working template: [Topic]: [main question, decision, or outcome]. Do not force every title into the same formula, and do not promise coverage the page does not provide. The title should be a faithful description of the answer below it.

    Turn headings into questions or useful assertions

    Readers should be able to scan the heading structure and understand the page’s argument. Replace labels such as “Overview,” “Benefits,” “Considerations,” and “More information” with the actual idea:

    • What is AI search content optimization?
    • Which pages should you optimize first?
    • Why does a self-contained passage improve retrievability?
    • When should a question become a separate spoke page?
    • What should you test before publishing the revision?

    You do not need to phrase every heading as a question. A clear assertion such as “A hub maps the topic while a spoke resolves one task” can be equally effective. What matters is that the heading exposes the section’s intent.

    Use the meta description as a compact intent statement

    The meta description should identify the audience, problem, and framing of the page. A practical drafting template is: For [audience], this page explains [problem or decision] in the context of [scope or condition].

    For example: “For content teams updating established pages, this workflow explains how to expose direct answers, improve passage clarity, and connect topic coverage for AI search.” That description does more than repeat the title. It clarifies who the page serves and how the subject is handled.

    Treat titles, headings, and descriptions as context anchors. They reinforce a clear page; they do not rescue an opaque one. If the body never states the promised answer, metadata will only make the mismatch more obvious.

    Preserve the expertise that makes the answer worth citing

    A clean structure can still produce forgettable content if the editing removes every specific judgement. Generic copy often defines a topic, lists familiar benefits, and ends before making a meaningful decision. Keep the material that demonstrates why your answer deserves attention.

    • Name the recommendation instead of implying that several options may be useful.
    • Explain the mechanism behind the recommendation, not just the expected benefit.
    • Retain accurate proprietary examples, original analysis, and subject-matter insight already present on the page.
    • Separate the default case from exceptions rather than blending them into vague language.
    • State what the method cannot solve, especially when a reader might otherwise apply it too broadly.
    • Delete introductions and transitions that delay the answer without adding context, evidence, or qualification.

    The goal is not to sound like a machine. It is to make your judgement legible. Human readers also benefit when a page names its conclusion, explains the reasoning, and makes exceptions easy to find.

    Test extraction before you publish the revision

    A transparent scanning frame lifts selected blank answer cards from a modular web page into a separate tray.

    Do not finish the refresh when the copy looks cleaner in the editor. Finish when the important answers survive extraction. Run the following editorial checks on the rendered page:

    1. Intent check: Read only the title, opening paragraphs, and headings. Confirm that they describe one coherent purpose and show where the reader’s main questions are answered.
    2. Isolation check: Move each critical section into a blank document. Restore any subject, condition, or definition that disappeared with the surrounding context.
    3. Answer check: Inspect the first sentence beneath each important heading. Rewrite openings that merely announce what the section will discuss.
    4. Qualification check: Confirm that limitations appear in the same answer unit as the claims they restrict. A caveat hidden several sections later is easy to lose.
    5. Overlap check: Compare sections and related URLs. Give each question one primary answer and remove duplicative passages that do not add a distinct condition or perspective.
    6. Relationship check: Follow every important internal link. Verify that the destination resolves the next question and that the anchor text names that relationship.
    7. Synthesis check: Ask an AI model to summarize the page and identify its main takeaways. Compare the output with what the page actually says, paying particular attention to missing conditions and overstated conclusions.
    8. Human-usefulness check: Read the page as someone making the decision it addresses. Make sure the answer is fast to locate, the reasoning is sufficient, and the next action is explicit.

    The synthesis check is diagnostic, not proof of visibility. AI output can vary with the question and context, so do not treat one response as a ranking report. Use a stable set of representative questions before and after the revision. Record whether the model identifies the correct main answer, preserves the important qualifications, and connects related concepts accurately.

    A useful final test is whether the model can quote or summarize the page accurately and find its answer quickly. If the summary is wrong, locate the passage that permitted the error. The cause is often an implicit subject, a conclusion delayed until the end, a missing boundary, or competing answers spread across the site.

    If the page passes the structural checks but still produces an empty or generic answer, stop reformatting. The next revision needs better substance: a clearer judgement, stronger support, a useful example, or a more precise explanation of when the recommendation applies. More headings will not fix an undifferentiated answer.

    Start with one page your team already relies on to answer a recurring question. Put its conclusion near the top, rebuild its important sections as standalone answer units, connect it to the right hub and spokes, and run the extraction checks. Once that page works, turn its structure and QA gate into the repeatable standard for your next revision.

    References

  • Google Commerce and Checkout Updates: A Merchant Playbook

    Google Commerce and Checkout Updates: A Merchant Playbook

    If your commerce strategy ends when a shopper clicks through to a product page, Google’s transaction layer creates a new gap. Products may now be discovered, evaluated and purchased within a Google experience, but only when your catalog data, payment processing and offer terms can support the same transaction.

    Your immediate decision isn’t simply whether to adopt AI shopping. You need to determine which offers are eligible, whether Merchant Center can express them accurately, whether your processor can complete the payment and whether the customer sees consistent terms from discovery through purchase.

    Google is turning some discovery journeys into checkout journeys

    Google’s Universal Commerce Protocol, or UCP, supports a native Buy button that can keep checkout on Google while the merchant remains the seller of record. The transaction can use credentials stored in Google Wallet, and the payment processor must support Google Pay tokens. Merchants implement the associated Merchant Center signal through the native_commerce attribute.

    This changes what commerce readiness means. In a conventional search journey, Google primarily needs enough reliable information to match a product with a query and send the shopper to the merchant. In a native checkout journey, the offer must also be executable. A discoverable product with an unsupported payment path, incomplete transaction data or conflicting terms isn’t transaction-ready.

    That distinction matters for SEO, AEO and GEO teams. Product schema and clear page content can help systems understand an offer, but they don’t replace a required Merchant Center attribute or payment integration. Treat page markup, catalog feeds and transaction infrastructure as connected layers with different jobs.

    A shorter path to payment may reduce friction in experiences such as Gemini and AI Mode, but conversion improvement is a possibility, not a guaranteed result. Merchant eligibility, offer quality, payment reliability and customer confidence still determine whether the shorter journey performs better.

    Separate transaction readiness from policy eligibility

    Generic products pass through separate compliance and transaction checkpoints before converging on a completed order package.

    Google’s broader checkout capability and its recurring prescription billing expansion affect different parts of the commerce stack. UCP is a transaction mechanism. The pharmacy change is a category-specific policy expansion for certified online pharmacies in the United States. Combining them into one implementation project can hide the gate that is actually blocking an offer.

    Commerce changeWhen it mattersRequired elementsWhat it changes
    UCP-powered checkoutWhen a merchant is preparing an on-Google purchase flownative_commerce in Merchant Center and a processor that supports Google Pay tokensThe shopper can use stored Google Wallet credentials while the merchant remains the seller of record
    Recurring prescription billingWhen a certified U.S. online pharmacy promotes an eligible subscription, bundle or consultationMerchant certification, an accurate subscription_cost value, transparent landing-page terms and fees, and continued Healthcare & Medicine policy complianceEligible prescription offers can use recurring billing, subject to Google’s category requirements

    For certified U.S. online pharmacies, the expanded policy covers recurring prescription purchases, qualifying bundles and recurring prescription-eligibility consultations. A bundle may combine medication with services such as coaching or a treatment program, but the medication must remain the primary product. A consultation may be offered on its own or alongside medication when its purpose is to assess prescription eligibility.

    The expansion doesn’t remove the existing certification or Healthcare & Medicine requirements. It also doesn’t turn an eligibility assessment into guaranteed access to a prescription. Describe the consultation as an assessment, make the recurring arrangement explicit and ensure the promoted offer matches what the customer can actually purchase.

    This gives you two independent questions to answer. First, is the offer allowed? Second, can your systems execute it through the intended Google experience? A policy-approved offer can still fail the technical test, while a technically complete transaction can still be ineligible for promotion.

    Build the commerce stack in the right order

    A layered digital commerce stack links catalog objects, account controls, payment processing, order management, and customer offers.

    Don’t begin by adding an attribute across the catalog. Start with one clearly defined offer and trace it from Merchant Center to the confirmed order. That limits the number of variables when something doesn’t match.

    1. Define the offer as a customer would understand it. Record the product being purchased, whether billing recurs, what the subscription costs, what a bundle contains, which item is primary, and which terms or fees apply. If the team cannot describe the offer consistently in one internal record, the feed and landing page are unlikely to agree.
    2. Create an offer-level eligibility matrix. Use one row per offer, not one row per business. Track the applicable market, certification status, policy eligibility, required Merchant Center attribute, processor status, landing-page match and review status. This prevents approval for one product from being treated as approval for an entire catalog.
    3. Confirm the payment path before activating native commerce. Ask the payment team or processor to verify support for Google Pay tokens in the intended flow. General support for a familiar wallet experience isn’t specific enough; the requirement concerns the tokens used to execute the UCP-powered transaction.
    4. Submit only the attributes that apply. Use native_commerce for the UCP checkout implementation. For an eligible recurring prescription offer, submit the subscription cost accurately through subscription_cost. Don’t copy a recurring-billing value to one-time products or enable a transaction signal before its corresponding payment path is ready.
    5. Make the landing page agree with the feed. A shopper should see the same product, recurring cost, bundle composition, fees and material terms represented in Merchant Center. For pharmacy bundles, the page must also make it clear that medication is the primary product rather than presenting the service as the main purchase.
    6. Test the seller-of-record handoff. Google may host the checkout interface, but the merchant retains the seller-of-record role. Confirm that your order system receives what it needs to identify, fulfill and support the purchase. A successful payment that produces an incomplete or unusable order isn’t a successful implementation.
    7. Reconcile measurement across systems. Establish a baseline for checkout starts, completed payments, failed payments and confirmed orders before rollout. Because an on-Google checkout can remove parts of the usual website journey, pageview-only reporting may not describe the full funnel. Reconcile Merchant Center activity, processor outcomes and order records instead of relying on a single web session.
    8. Request a review only after correcting the underlying issue. A previously disapproved pharmacy account can seek another review once it meets the expanded requirements. Preserve the corrected feed values, visible landing-page terms, certification status and payment confirmation so the team can verify that the reviewed configuration is the one actually in production.

    This sequence also clarifies ownership. SEO and content teams can define the offer and maintain page clarity. Feed specialists can implement Merchant Center attributes. Payments teams can validate token support. Compliance teams can determine whether a regulated offer is eligible. Analytics and commerce operations can verify that a paid transaction becomes a usable order. No single discipline can safely infer that the other layers are ready.

    Offer consistency is now part of transaction architecture

    Merchants often treat feed discrepancies as catalog housekeeping. Native checkout raises the consequence. Google isn’t only using the offer to decide whether and where it should appear; the offer data can help shape a transaction. A mismatch can therefore affect customer understanding, policy eligibility or the ability to complete the purchase.

    • The page describes recurring billing, but the subscription cost is missing or inaccurate. Correct the Merchant Center value and verify it against the live offer before requesting review.
    • The feed contains a native-commerce signal, but processor support hasn’t been confirmed. Hold activation until the payment path can accept the required Google Pay tokens.
    • A prescription bundle visually leads with coaching or a treatment program. Rework the offer so the medication is unmistakably the primary product, as the category policy requires.
    • A consultation is presented as if it guarantees medication. State its actual role: assessing prescription eligibility. Keep the assessment distinct from the outcome.
    • Terms or fees are technically present but difficult to find. Put them where the customer can understand the recurring commitment before proceeding. Mere presence isn’t the same as transparency.
    • A prior disapproval is treated as permanent. If a certified U.S. pharmacy now meets the expanded requirements, correct the offer and account configuration, then use the available review process.

    For regulated health offers, this isn’t only a conversion concern. Ambiguous billing, unclear eligibility language or a service-led bundle can misrepresent what a patient is buying. Keep medical and policy review in the launch path, and don’t use optimization work to soften or obscure a condition that determines access, cost or recurring payment.

    The same consistency principle applies outside healthcare. Use one governed offer record as the reference for feed data, landing-page copy, checkout configuration and internal review. When a price, fee, bundle or term changes, update each layer as one release rather than as separate content and engineering tasks.

    Key takeaways

    • UCP can place a native Buy action on Google, but the merchant remains the seller of record.
    • Merchant Center’s native_commerce attribute and processor support for Google Pay tokens solve different parts of the same checkout flow.
    • Certified U.S. online pharmacies can promote qualifying recurring prescriptions, bundles and consultations when they meet the expanded requirements.
    • Eligible pharmacy offers need accurate subscription_cost data, transparent terms and fees, continued certification, and compliance with existing Healthcare & Medicine policies.
    • Schema and page optimization support offer understanding; they don’t substitute for Merchant Center configuration, payment readiness or policy approval.
    • Measure confirmed orders and payment outcomes across systems because an on-Google transaction may not follow the website funnel your current reports expect.

    Choose one eligible offer and run it through the matrix before expanding the rollout. If its policy status, Merchant Center data, landing page, processor response and confirmed order all agree, you have a repeatable commerce path. If they don’t, the failed checkpoint tells you exactly which team should fix the next problem.

    References

  • Google Search and Discover Optimization: A Practical Playbook

    Google Search and Discover Optimization: A Practical Playbook

    You did the hard part: the page is useful, current, and ready to earn attention. Then Google surfaces a generic thumbnail, crops out the subject, or gives the URL Search visibility without any meaningful Discover exposure. Those outcomes can have different causes, so adding one more tag isn’t a complete diagnosis.

    Your job is to make the page suitable for the surface, give Google consistent image signals, and make the people and publisher behind the content easy to verify. This workflow shows you where to start, what to implement, and what not to blame when Discover traffic moves.

    Treat Search and Discover as different outcomes

    Google Search responds to an expressed need. A person types a query, and your page competes to answer it. Discover works ahead of the query. It tries to predict what a person will want to see from their interests and recent context.

    That difference changes the publishing decision. A durable tutorial may deserve a Search-first brief even if it never becomes a meaningful Discover story. A timely development with a compelling visual and a clear connection to your audience may be suitable for both. Timeliness, relevance, and publisher authority tend to matter heavily in Discover, while evergreen content appears less often.

    Classify the page before you optimize it:

    • Search-first: The page answers a durable question or helps someone complete a task. Build it for sustained usefulness and treat Discover exposure as an upside, not the forecast.
    • Discover candidate: The subject is timely, closely connected to your audience’s interests, and supported by an image that can carry the story in a visual feed.
    • Dual-purpose: The topic has immediate relevance but also resolves a query people will continue to search. Preserve the useful answer instead of forcing the entire page into a short-lived news angle.

    This classification prevents a common strategic error: treating every lack of Discover traffic as a technical failure. Discover isn’t a dependable fit for every brand or every page. Technical readiness can make a suitable page eligible for stronger presentation, but it cannot create audience interest that the subject does not have.

    Align the thumbnail signals in the rendered page

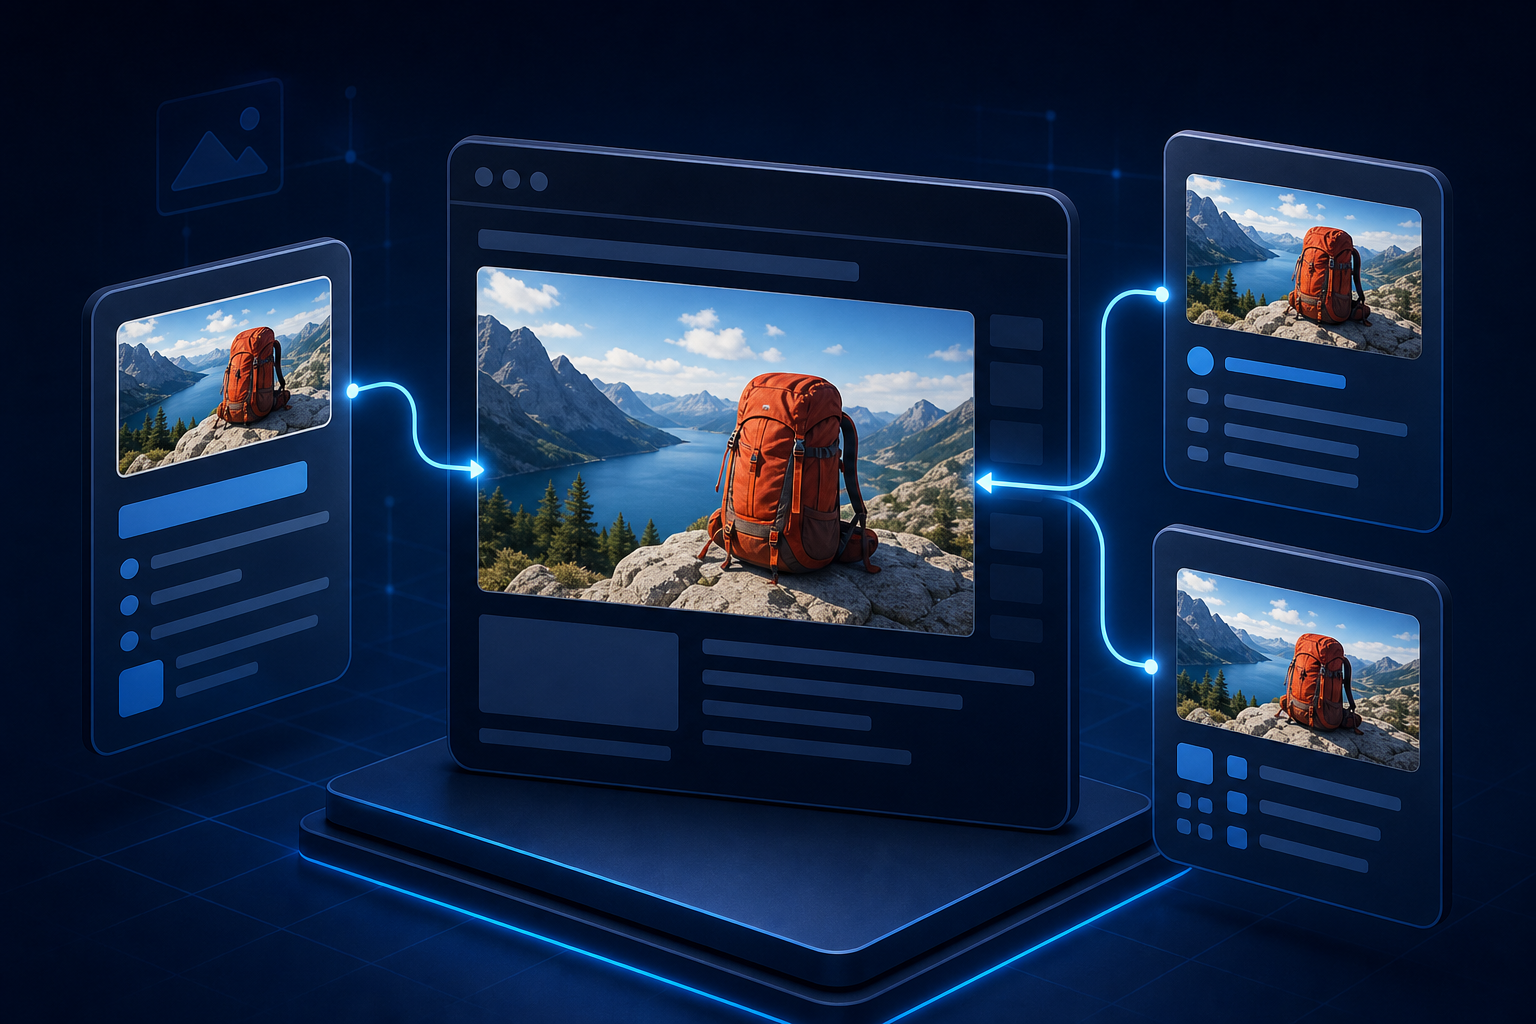
    Matching backpack images in three floating page-signal layers connect to the same thumbnail in a central browser frame.

    Google does not promise to use the image you nominate. Image-preview selection is automated and can draw on several sources, including page content, structured data, and Open Graph metadata. The practical goal is therefore not to force a thumbnail. It is to remove contradictory signals.

    Use this implementation sequence on every content template that can appear in Search or Discover:

    1. Choose one preferred image. It should represent the specific page, not merely the publisher, section, or general subject area.
    2. Declare it in Schema.org markup. Use primaryImageOfPage with either the image URL or an ImageObject. Where your schema model describes a main entity, the image can also be connected through the relevant mainEntity or mainEntityOfPage relationship.
    3. Set the same asset as og:image. Do not let an SEO plugin, social plugin, and theme independently emit different preferred images.
    4. Permit large previews. For a non-AMP implementation, the rendered robots directive should include max-image-preview:large. A typical output is <meta name="robots" content="max-image-preview:large">.
    5. Inspect the final rendered page. Verify the HTML and JSON-LD that Google can receive, not just the image selected in the CMS editor.

    The rendered-page check catches the failures that configuration screens hide. A template may retain an old og:image, fall back to a logo when a field is empty, omit structured data on one content type, or output a restrictive image-preview directive. The image URL must also resolve to the intended file in production. A perfectly configured CMS field has no value if the resulting URL is broken or points to a placeholder.

    Pay particular attention to disagreement. If primaryImageOfPage identifies the hero image while og:image identifies a logo, you have given an automated system two different answers. Using both forms of metadata is useful when they reinforce the same decision; duplicating fields without aligning them only multiplies ambiguity.

    The max-image-preview:large directive deserves equally careful language. It allows Google to consider a large preview; it does not guarantee that a large image will appear, that your nominated asset will be selected, or that the page will enter Discover. Think of it as permission, not a ranking command.

    Build the image for the crop, not only the page

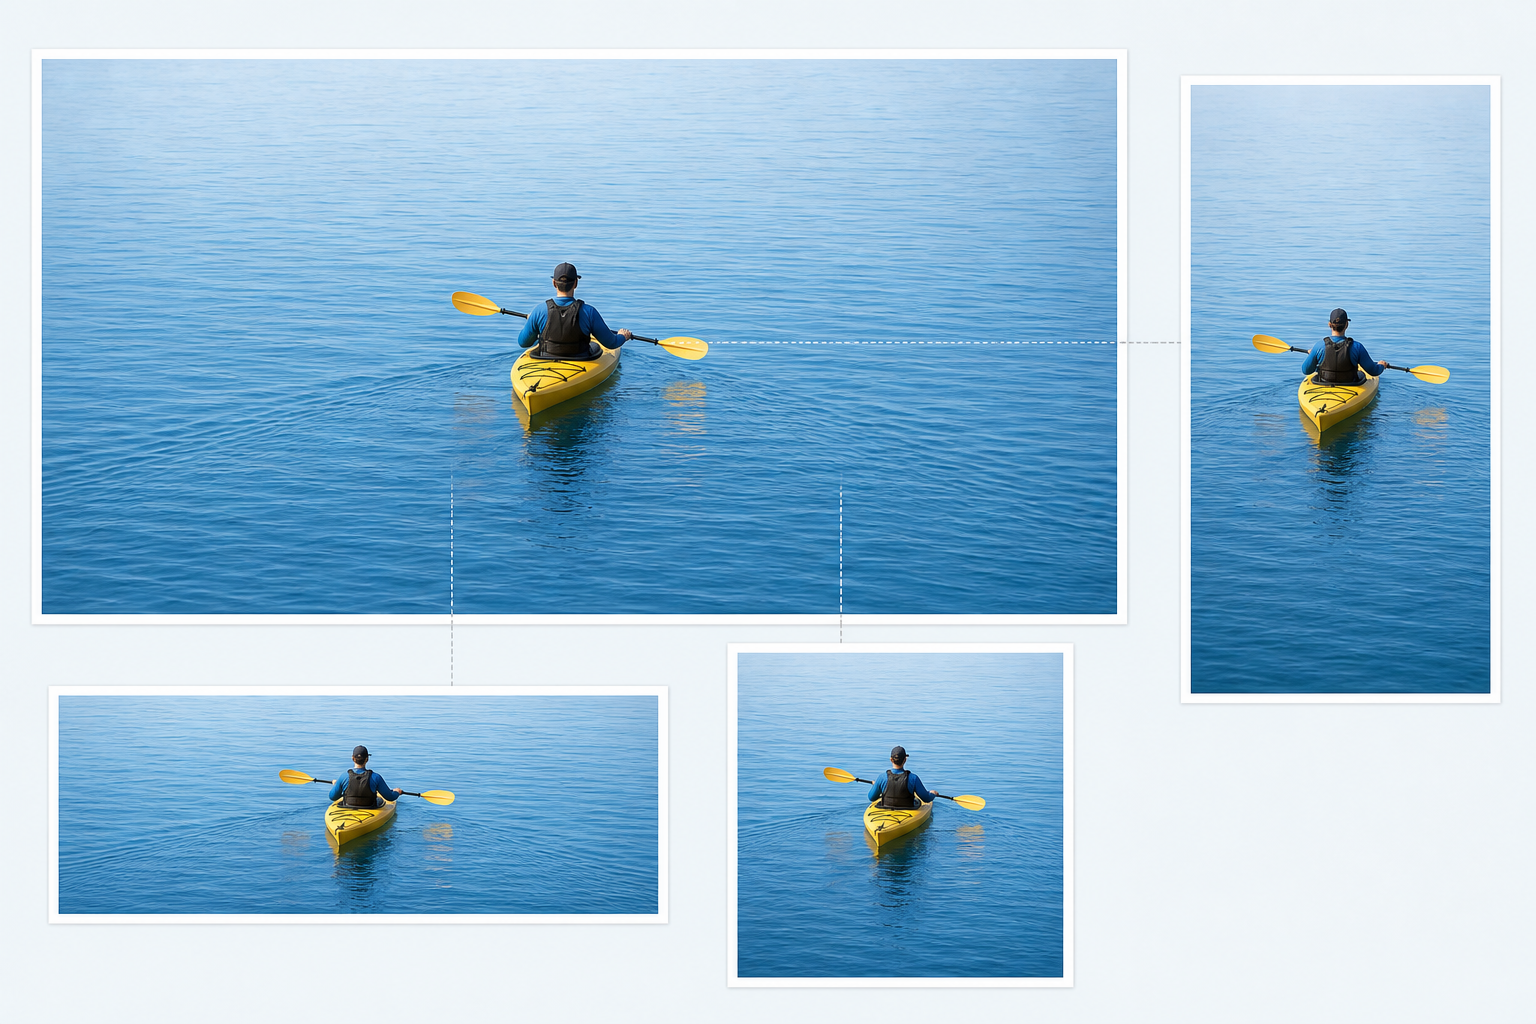
    Wide, square, and vertical crops of the same kayaking scene all keep the yellow kayak and paddler fully visible near the center.

    An image can look excellent at the top of an article and still fail inside a feed card. Discover may crop the asset for its layout, so the page-level composition is only half the job. A strong Discover candidate is at least 1,200 pixels wide, high resolution, and suited to a 16:9 landscape presentation.

    Use an asset-level publishing checklist:

    • Make the image specific. A real product, person, place, event, or visual result is more informative than a generic thematic image.
    • Avoid logos as the editorial thumbnail. The image should explain what this page is about, not simply identify who published it.
    • Keep essential detail away from fragile edges. Place the focal subject so it remains understandable after a landscape crop.
    • Avoid embedding the headline in the image. Text can become illegible or disappear when the asset is cropped and reduced.
    • Avoid extreme aspect ratios. A very tall or unusually wide source makes useful automatic cropping harder.
    • Keep the file visually sharp. Compression should not leave faces, products, screenshots, or other critical details soft at card size.

    Check the crop before publishing

    Start with the actual image URL emitted in og:image, not the larger file you happen to have in the media library. Preview it in a 16:9 landscape frame. Then reduce the preview until it resembles a feed card and ask a blunt question: can someone still tell what happened or what the page covers without reading embedded text?

    If the answer is no, change the composition or supply a deliberately cropped landscape asset. Google attempts to crop images automatically, but automatic cropping cannot recover a subject that occupies a narrow edge or make a generic image more relevant. When you provide your own crop, use it consistently in the page’s preferred-image metadata.

    This is also where editorial and technical teams need a shared definition of done. The image is not finished when it has been uploaded. It is finished when the correct file is visible, large-preview permission is present, the metadata fields agree, and the landscape crop still communicates the subject.

    Make the publisher and author easy to verify

    Discover optimization extends beyond the individual URL. Google can represent a publisher through a profile associated with the entity’s Knowledge Graph identity. That publisher profile can connect the website with its social profiles, so inconsistent names, outdated handles, and incomplete identity information deserve attention.

    Audit the publisher as a person encountering the brand for the first time:

    • Use a consistent publisher name, identity, and website across the site and official social profiles.
    • Check whether the Discover publisher profile accurately represents the organization and includes the intended social handles.
    • Keep the About page easy to find and specific about ownership, editorial purpose, and the people responsible for the site.
    • Link relevant editorial, correction, privacy, and other policy pages from predictable locations.
    • Ensure structured data agrees with the information a reader can see. Markup should clarify a real identity, not introduce a separate version of it.

    Profile corrections may require manual updates and patience. That makes prevention more valuable than repeatedly repairing mismatches. Decide on the canonical publisher name and official profiles, then use them consistently whenever you launch a new template, section, or social account.

    Apply the same transparency standard to authors. Visible author photos, biographies, and relevant social links support clearer authorship. A strong implementation gives each article a real byline, links that byline to a useful author page, and explains why that person is qualified to cover the subject.

    Do not turn this into decorative credential stuffing. The author page should help a reader answer practical questions: Who wrote this? What area do they cover? Is their work on this site accessible? Can their public identity be verified? If those answers are missing from the visible site, adding more structured data will not repair the underlying transparency problem.

    Diagnose weak Discover performance in the right order

    Technical fixes are attractive because they are concrete. They are also easy to over-credit. Content relevance and quality remain more important than technical polish. A technically perfect page can still be a poor Discover candidate, while an appropriate page can underperform because its template suppresses large images or emits the wrong thumbnail.

    The feed itself is not static. Social posts and AI-generated summaries can occupy space that previously went to conventional publisher pages. That means a broad decline does not, by itself, prove that a developer broke the site. Use this order of investigation:

    1. Recheck content fit. Was the page genuinely timely and relevant to an established audience, or was Discover traffic assumed simply because the page was new?
    2. Determine the scope. Separate a page-level issue from a content-type, template, section, or sitewide pattern.
    3. Inspect the rendered metadata. Compare primaryImageOfPage, entity relationships, og:image, and the robots image-preview directive.
    4. Inspect the emitted asset. Confirm its width, quality, subject, aspect ratio, and crop resilience.
    5. Review publisher and author transparency. Check profiles, bylines, biographies, About information, policy pages, and consistency between visible information and structured data.
    6. Revisit the expectation. If the implementation is clean, the remaining issue may be content suitability, audience interest, authority, or changing competition within the feed.

    The following symptoms are useful starting points, not proof of a single cause:

    What you noticeCheck firstWhat not to assume
    Large previews are absent across one content templateThe rendered max-image-preview:large directive and template-level image fieldsThat every affected page has weak content
    Search and Discover surface an unintended imageAgreement between primaryImageOfPage, entity relationships, og:image, and the visible hero imageThat adding another duplicate image field will force the selection
    The metadata is clean, but a durable evergreen page receives no Discover exposureWhether the subject is timely and aligned with audience interestsThat valid markup creates Discover demand
    Traffic declines broadly without a relevant site releaseRecent content mix, audience relevance, publisher authority, and changing feed competitionThat a technical regression is the only possible explanation
    Only some authors or sections perform inconsistentlyTemplate output, byline links, author pages, preferred images, and section-specific defaultsThat the entire domain needs to be rebuilt

    Key takeaways

    • Decide whether each page is Search-first, Discover-suitable, or useful for both before setting traffic expectations.
    • Point Schema.org image properties and og:image to the same relevant, high-quality asset.
    • Use an image at least 1,200 pixels wide and prepare it for a 16:9 landscape crop.
    • Enable max-image-preview:large when you want a non-AMP page to be eligible for a large preview.
    • Make publisher and author identities visible, consistent, and supported by useful profile and policy pages.
    • Investigate content fit before treating every Discover decline as a technical defect.

    Choose one recent URL that you genuinely expect Discover to carry. Inspect its rendered head, follow every preferred-image reference to the live asset, test the landscape crop, and then follow the publisher and author paths as a reader would. Fix any template-level inconsistency before producing more candidates. Once those signals agree, you can make the next publishing decision around the subject and audience instead of gambling on metadata.

    References

  • Google AI Commerce: How Ecommerce Brands Stay Visible

    Google AI Commerce: How Ecommerce Brands Stay Visible

    Your product can hold a respectable search position and still lose the sale before a shopper reaches your site. When an AI system interprets the need, compares the options, chooses an offer and potentially handles checkout, the decisive visibility event happens upstream of the click.

    You now need to make each product easy for an agent to find, understand, select and transact. That means treating product truth, recommendation fit and operational readiness as parts of SEO rather than leaving them to separate catalog, merchandising and checkout teams.

    The sale can now be won before a site visit happens

    The familiar ecommerce journey starts with a query, moves through a search result and ends on a merchant-controlled product page or checkout. Google’s AI commerce direction compresses that journey. Its Universal Commerce Protocol enables AI agents to discover, evaluate, recommend and purchase products across the web within Google’s AI experiences.

    UCP matters because it is not an isolated shopping widget. Its launch collaboration included Shopify, Etsy, Wayfair, Target and Walmart, with existing payment networks incorporated. Google also introduced three related commerce surfaces: Business Agent for brand-specific conversations in Search and Gemini, Direct Offers for promotions inside AI Mode, and Checkout in AI Mode for purchases completed within Google’s interface.

    For you, the important shift is from ranking alone to selection. A conventional ranking report asks whether a URL appeared and received a click. AI commerce requires four different questions:

    Visibility stageQuestion to answerTypical failure to investigate
    EligibilityCan the system find and use the product record?The item, variant or offer is absent, inaccessible or unsupported.
    InterpretationCan it identify exactly what the product is?Names, identifiers, attributes, prices or availability conflict.
    SelectionCan it explain why this product fits the shopper’s need?The catalog describes the item but not its use, constraints or differences.
    TransactionCan the selected offer be purchased successfully?The offer is stale, the variant is unavailable or the handoff fails.

    Your website remains important. It may still be the clearest public expression of your product facts, policies and brand expertise. But a polished page cannot compensate for exclusion at the eligibility stage, contradictory data at the interpretation stage or weak product fit at the selection stage. Diagnose the stage that failed before rewriting copy or increasing media spend.

    Build a product truth layer before optimizing recommendations

    A running shoe is connected to organized product details, inventory, shipping and verification symbols above a foundation of data blocks.

    The first job is agreement, not persuasion. Your page, structured data, catalog feed, commerce platform, inventory system and checkout should describe the same purchasable item. If they disagree, an agent has to decide which representation to trust while the shopper sees only the result.

    Create a field-level catalog audit. For each commercially important product and variant, record the canonical system, the surfaces that publish the field, the event that refreshes it and the person responsible when synchronization fails. Inspect at least these groups of information:

    • Identity: product name, brand, internal identifier, SKU and any supported external identifier.
    • Variant definition: the attributes that distinguish one purchasable option from another, such as size, color, configuration or quantity.
    • Offer state: current price, currency, discount terms, availability and the exact variant to which each value applies.
    • Product facts: materials, dimensions, included components, compatibility, care requirements and other attributes the shopper may use to rule an option in or out.
    • Fulfillment facts: the shipping, pickup or delivery conditions your operation can actually honor.
    • Policy facts: the conditions that affect the decision or the completed order, including relevant return, cancellation and warranty terms.

    This is not a claim that every field is a UCP requirement. It is a practical inventory of the commercial truths that discovery, comparison and checkout systems must keep straight. Match the audit to the fields, integrations and eligibility rules that apply to your own platform setup.

    Keep identifiers and variants stable

    Variant ambiguity is particularly costly. A parent product may be available while the size or configuration the shopper wants is not. If the parent page, structured data and feed collapse those states into one generic record, the system can recommend an option that cannot be purchased.

    Use stable identifiers for the same item everywhere. Do not casually recycle an identifier after replacing a product, merge materially different variants into a single offer or use different names for the same attribute across systems. When a product changes enough that compatibility or customer expectations change, treat identity as a catalog decision rather than a copy edit.

    Make freshness an operating rule

    Price and availability are state, not static content. Document what event updates each downstream representation: an inventory change, a promotion activation, a price revision or a product withdrawal. Then define what happens when the update does not arrive. A safe failure may mean suppressing an uncertain offer until it is reconciled instead of continuing to advertise a price or item you cannot honor.

    Test a real purchasable variant from end to end. Compare its visible page, Product and Offer structured data where used, feed record, API response, cart and checkout. Search for disagreement in identifiers, price, currency, availability and variant labels. A valid schema block does not make a stale price true; structured data is a machine-readable representation of your commerce record, not a substitute for one.

    Give the recommendation system reasons to choose you

    Traditional product copy often assumes that the shopper already knows the category and is comparing familiar options. Conversational shopping starts earlier. Gemini can turn requests such as planning a camping trip or removing wine from a couch into product discovery based on inventory, price and availability. The initial language may describe a problem or outcome without naming a product category.

    A catalog full of short, near-duplicate descriptions gives an agent little basis for matching those needs. Add decision information that helps it distinguish fit. For each priority product, make the following explicit in visible, accurate language:

    • What the product is, without relying on a clever product name to carry the definition.
    • Which use cases it is designed for and which product attributes support those uses.
    • Which shopper, environment or constraint it suits.
    • What it requires to work, including compatibility, installation or complementary components where relevant.
    • How it differs from nearby options in your own range.
    • When another option is a better fit.
    • Which claims are factual and where the supporting evidence appears.

    The last two points deserve attention. If every item is described as the best choice for every buyer, none of the descriptions provides a useful selection boundary. A clear exclusion such as an incompatible device, unsuitable environment or missing feature can improve recommendation fit by preventing the wrong product from being chosen.

    Do not turn this into an exercise in manufacturing question-and-answer text or repeating likely prompts. Write complete product facts and decision criteria in the language customers use. The goal is not to imitate a chatbot. It is to remove the inference a chatbot would otherwise have to make.

    Make category pages do comparison work

    A product page can explain one item well while the category still fails to explain choice. Build category content around meaningful differences: intended use, decisive attributes, compatibility, level of capability and tradeoffs. If two products differ only in internal merchandising language, rewrite the distinction so a customer can tell why both exist.

    Use comparison tables only when the attributes are genuinely comparable. Keep values normalized, name units and avoid leaving a blank cell when the real meaning is unknown, not applicable or not included. Those states lead to different decisions and should not be collapsed into the same empty space.

    Prepare each AI commerce surface as a separate operation

    A travel bottle on a central operations hub connects to conversational, comparison, visual discovery and checkout surfaces through separate readiness gates.

    Business Agent, Direct Offers and Checkout in AI Mode affect different parts of the buying journey. Do not assume that connecting one surface makes the others accurate or operational. Give each capability an owner, a source of truth, an approval boundary and a failure procedure.

    Business Agent needs governed brand knowledge

    Business Agent acts as an AI-powered brand representative in Search and Gemini, where shoppers can ask about products, compare choices and receive brand-specific guidance without opening a separate site. That makes answer quality part of merchandising and reputation management, not merely customer support.

    Start by identifying the questions that materially change a purchase: suitability, compatibility, differences between models, included components, availability and relevant policies. Map each answer to an approved source. Decide which claims can be stated directly, which require conditions and which should not be made. When an answer depends on information the agent cannot reliably access, provide a safe path to verification rather than filling the gap with promotional language.

    Audit the agent as a buyer would use it. Ask underspecified questions, add a constraint, change a variant and challenge a recommendation. Check whether the answer preserves the constraint, cites the correct product facts and avoids promising unavailable stock or unsupported capabilities.

    Direct Offers need commercial controls

    Direct Offers allow merchants to put exclusive discounts into AI Mode, placing the promotion inside the recommendation environment. That can make offer quality part of selection, but it also introduces margin and customer-expectation risk.

    Every offer should have an unambiguous product or variant scope, eligibility rule, valid period, discount definition and fallback state. Confirm that the same terms reach the agent, cart and order system. If the promotion cannot be honored at checkout, suppress or correct it rather than relying on fine print after selection. An expired or mis-scoped offer can turn added visibility into support costs, cancellations and lost trust.

    Checkout in AI Mode needs order-level testing

    Checkout in AI Mode moves purchase completion into Google’s interface. Your storefront may no longer control every step or observe a conventional browsing session before the order. Test the transaction as an operational flow: selected variant, current price, inventory reservation, payment status, tax and delivery handling, order creation, confirmation, cancellation and returns.

    Do not begin with your entire catalog merely because the integration permits broad coverage. A bounded set of products with clean data, dependable inventory and understood margins gives you a safer place to verify order routing and exception handling. Commerce automation can create real financial exposure when a discount, stock state or fulfillment promise is wrong, so expand only after the failure path works as well as the happy path.

    Measure AI visibility as a decision journey

    Rankings, clicks and onsite conversion rate still describe part of ecommerce performance. They do not tell you whether an agent found the product, interpreted it correctly, recommended it for the right need or completed the purchase without a traditional visit. Keep the established metrics, but add observations for the stages you can now lose before the click.

    • Catalog coverage: which priority products and variants are eligible for the commerce surfaces you use.
    • Data consistency: whether identity, price, availability and offer terms agree across exposed systems.
    • Recommendation presence: whether your product appears for a controlled set of relevant buyer needs.
    • Recommendation accuracy: whether the explanation, constraints and selected variant match the underlying product facts.
    • Offer integrity: whether the displayed promotion remains valid through checkout.
    • Transaction quality: whether the order is created correctly and can be fulfilled without avoidable correction, cancellation or support intervention.
    • Commercial quality: whether the resulting order remains worthwhile after discounts, fulfillment costs, returns and service demands.

    Use the telemetry your platforms actually expose, and do not manufacture precision where reporting is incomplete. A repeatable observation log can still reveal problems. Record the shopper need, constraints, region or language, date, products surfaced, recommendation wording, displayed offer and any incorrect claim. Run the same scenario after a meaningful catalog or content change. A single conversation is an example, not proof of sustained visibility.

    Prioritize changes by stage. If the product is absent, investigate eligibility and data delivery. If it appears with wrong facts, fix the truth layer. If the facts are right but the fit is unclear, improve decision content. If selection succeeds but the order fails, stop rewriting pages and repair the transaction path.

    Key takeaways

    • Google AI commerce visibility spans eligibility, interpretation, selection and transaction, not only rankings and clicks.
    • Product pages, structured data, feeds, inventory systems and checkout must agree on the identity and current state of each variant.
    • Useful product content states use cases, constraints, compatibility, differences and exclusions so an agent has a defensible reason to recommend the item.
    • Business Agent, Direct Offers and Checkout in AI Mode need separate ownership, controls and failure procedures.
    • Measurement should connect recommendation presence and accuracy to valid offers, successful orders and commercial outcomes.

    Choose a commercially important category and trace a real variant from product record to recommendation and completed order. Log every contradiction, missing decision fact and broken handoff. Fix that path before expanding coverage. The brands that become easier for AI to choose will be the ones that make product truth operational, not merely publish more content.

    References

  • SAP Customer Engagement Strategy: Build One Customer Memory

    SAP Customer Engagement Strategy: Build One Customer Memory

    Your SAP landscape can execute every message as designed and still produce a disjointed customer experience. When service, sales, commerce, stores, and marketing each act on a different version of the customer’s history, you aren’t managing a relationship. You’re scheduling collisions.

    A workable SAP customer engagement strategy gives those teams a shared customer state, consistent decision rules, and a feedback loop. The goal isn’t to make every channel sound identical. It’s to make the next action appropriate to what the customer has already done, requested, purchased, or declined.

    Key takeaways

    • Start with customer decisions and handoffs, not a list of channels or SAP modules.
    • Create a usable customer memory that includes identity, permissions, recent events, active issues, eligibility, and suppressions.
    • Model each journey as a set of states, entry conditions, decisions, exits, and conflict rules.
    • Use AI for bounded tasks inside an approved decision system. Do not ask it to compensate for disconnected data or unclear ownership.
    • Measure contradictory contacts, failed handoffs, repeat questions, and suppression errors alongside conventional campaign results.

    Replace channel plans with a relationship operating model

    A channel plan asks, “What should email send?” or “What should sales do next?” A relationship plan asks, “Given what we know about this customer now, what should the business do next, who should do it, and which actions must be suppressed?”

    That distinction exposes the real problem. Email, social, ecommerce, sales, and service can all meet their own targets while the customer receives incompatible treatment. SAP calls the gap between customer expectations and an organization’s ability to deliver coherent engagement the Engagement Divide. Closing it requires an operating model, not merely another campaign layer.

    Use four connected layers to define that model:

    • Memory: What does the organization know about the customer’s identity, permissions, activity, purchases, conversations, and unresolved needs?
    • Decision: Which actions are eligible, which should take priority, and which must be blocked?
    • Execution: Which channel or employee should carry out the decision?
    • Learning: What happened, and how will that outcome change the next customer state?

    Write each important interaction as a complete operating statement: When this customer state occurs, make this decision, execute it through this owner or channel, suppress these conflicting actions, and record this outcome. If you cannot fill in every part, the journey isn’t operational yet.

    Start your audit with collisions rather than architecture. Select a journey in which customers can encounter more than one department. Map every system that reads or changes the relationship during that journey. For each system, record what it knows, what it can trigger, what it writes back, and how quickly another team can see the change.

    If this happensThe meaningful customer stateThe response to coordinateThe rule to encode
    A service case remains unresolvedThe relationship is in recoveryLet service lead while promotional contacts are reviewed or suppressedCurrent case status overrides ordinary marketing eligibility
    A prospect has completed a demoThe prospect is evaluating, not awaiting an introductionContinue from the known demo outcomeThe completion event suppresses another introductory demo invitation
    A store purchase has been recordedThe person is a recent purchaserUpdate ecommerce treatment before the next follow-upThe purchase event becomes available to every relevant activation channel

    This exercise gives you a prioritized backlog. A missing event, an ambiguous owner, and an absent suppression rule are different defects. Label them separately so the team fixes the mechanism instead of redesigning the message around it.

    Build the customer memory your decisions actually need

    Purchase, delivery, service, store, consent, and return signals converge into a single translucent customer-memory hub while duplicate fragments are filtered out.

    “Single customer view” sounds like a complete answer, but a large consolidated profile can still be useless at the moment of engagement. Your decision layer needs a current, explainable relationship record, not every field the organization has ever collected.

    Define a minimum viable relationship record for the first journey. It should usually cover:

    • Identity keys: the identifiers used to connect activity without merging people on weak evidence.
    • Permission state: what the customer permitted, where the permission came from, when it changed, and which uses or channels it covers.
    • Lifecycle state: the customer’s current relationship with the business, such as prospect, active customer, recent purchaser, or former customer.
    • Recent events: purchases, demo completion, service contacts, responses, and other actions that materially affect the next decision.
    • Open business context: unresolved cases, active opportunities, pending orders, returns, or other processes that should change treatment.
    • Eligibility and suppressions: actions the customer can receive, actions currently blocked, the reason for each block, and when the status should be reconsidered.
    • Decision history: what the system or employee decided, which rule was applied, and what action followed.
    • Outcome history: whether the customer responded, ignored the action, opted out, reopened an issue, progressed, or left the journey.

    Keep observations, interpretations, and decisions separate. “Case opened” is an observed event. “Relationship in recovery” is an interpreted state. “Suppress promotional message” is a decision. If those are collapsed into one field, you will struggle to explain why an action occurred or safely change the rule later.

    Attach a source and timestamp to every state-changing signal. Where identity or classification is uncertain, preserve that uncertainty instead of silently converting it into fact. An incorrect merge can expose one person’s activity to another person’s journey, while an overconfident classification can trigger an inappropriate action. Ambiguous records should follow an explicit review or fallback path.

    Freshness should be defined by decision, not by a blanket demand for “real time.” A service status must be current before marketing checks a suppression rule. A slower analytical attribute may remain useful for planning. Document the maximum acceptable age of each input at the point of decision, then verify that the integration path can meet it.

    Finally, name the authoritative system for every required field. If service, commerce, and marketing can all overwrite the same status without precedence rules, integration will distribute the conflict faster. A shared memory needs clear write ownership as much as it needs connectivity.

    Turn customer journeys into governed decision systems

    A customer journey passes through connected purchase, delivery, support, and shopping moments while shared decision gates and a feedback loop coordinate several teams.

    A journey diagram shows the experience you hope to create. An executable journey defines what the organization will do when reality departs from that diagram.

    For each journey, specify:

    • Entry condition: the event and qualifying state that place a customer in the journey.
    • Current states: the meaningful stages the customer can occupy, expressed in business language that channel teams understand.
    • Decision inputs: the precise fields and events needed to select an action.
    • Eligible actions: what the business may do in each state.
    • Priority rules: which need takes precedence when service, sales, and marketing all have a possible action.
    • Suppression rules: which actions must pause, stop, or yield to another journey.
    • Exit conditions: the events that complete, cancel, or transfer the journey.
    • Fallback behavior: the safe action when data is late, missing, conflicting, or uncertain.
    • Outcome event: what must be written back so the next decision reflects what happened.
    • Owner: the person accountable for the cross-channel decision, not merely the team operating a channel.

    Cross-journey priority is where many otherwise polished designs fail. A customer can be part of a retention program, a sales opportunity, a service recovery process, and a product campaign at the same time. Define which state wins before the systems encounter that conflict. The rule should be visible to every affected team and testable with a sample customer history.

    AI belongs inside this system, not above it. It can help classify an inbound request, summarize a long interaction history, identify relevant approved content, or recommend an action from an eligible set. Those are bounded jobs with observable inputs and reviewable outputs.

    Do not delegate permissions, identity resolution, mandatory suppressions, or other hard constraints to a probabilistic recommendation. Keep those decisions deterministic. AI should never invent missing customer context, infer consent, or bypass an unresolved service state simply because a promotional action appears likely to perform.

    Every AI-assisted decision needs the same operational record as a rules-based decision: the inputs available at the time, the eligible options, the selected option, any human override, the action taken, and the outcome. Without that record, you cannot distinguish a model problem from stale data, a bad rule, or a channel execution failure.

    Govern the handoffs and launch one coherent journey

    Channel ownership is necessary, but it is not enough. Someone must own the relationship decision across channels. That owner resolves priority conflicts, approves state definitions, coordinates rule changes, and accepts the outcome when a handoff fails.

    Assign the supporting responsibilities explicitly:

    • A relationship owner defines the journey outcome and cross-channel priorities.
    • Business data owners define authoritative fields and approve changes to their meaning.
    • Integration owners deliver the required events with the agreed freshness and failure handling.
    • Channel owners execute eligible actions and return outcomes in a consistent form.
    • Service, sales, commerce, and marketing leaders approve rules that affect their teams.
    • Privacy and compliance owners review identity, permission, retention, and activation controls.
    • Analytics owners monitor customer-level coherence as well as channel performance.

    Your scorecard should make fragmented engagement visible. Keep delivery, response, conversion, and revenue measures where they are useful, but add operational measures such as contradictory-contact rate, contacts made during an active suppression, handoff completion, repeated information requests, unresolved-case contact, identity corrections, and decisions that fell back because required data was unavailable.

    These measures tell you where the relationship breaks. A campaign can produce a strong response while still creating avoidable service contacts or contradicting another interaction. Looking only at the campaign result hides that cost.

    Use this rollout sequence to move from architecture discussion to a live, controlled journey:

    1. Choose a visible fracture. Start with a journey where channel conflict is recognizable, the business outcome matters, and an accountable owner is available.
    2. Reconstruct the current path. Follow the customer state across systems and mark missing events, stale fields, manual handoffs, conflicting owners, and absent suppressions.
    3. Define the required memory. Name only the identity, permission, event, state, and outcome data needed for this journey, along with the authoritative source for each item.
    4. Write the decisions before configuring tools. Document eligibility, priority, suppression, exit, and fallback rules in language business and technical teams can test together.
    5. Test complete event sequences. Include normal progression, unresolved service issues, duplicate identities, missing data, late events, permission changes, and simultaneous journey eligibility.
    6. Observe decisions before broad activation. Replay representative histories or run the logic without sending customer-facing actions. Review what would have happened and why.
    7. Launch within a controlled scope. Limit the initial journey so owners can inspect exceptions, correct state definitions, and verify that outcomes return to the shared memory.
    8. Expand by decision pattern. Reuse proven identity, permission, priority, and outcome patterns in the next journey instead of copying an entire campaign workflow.

    Before launch, ask one final question: if the customer contacts a different department immediately after this action, will that team know what happened and respond appropriately? If the answer is no, the feedback loop is still open.

    Your next move is small but consequential. Pick one broken handoff, name the customer state both teams must share, and write the priority and suppression rules that should govern it. Once that decision works across SAP-connected systems, you have the foundation for a relationship strategy that can scale.

    References

  • How to Build an AI Search Visibility and AEO Strategy

    How to Build an AI Search Visibility and AEO Strategy

    Your search rankings can look stable while your brand disappears from the decision. A buyer can ask an AI assistant to define the problem, assemble a shortlist, compare options, and identify objections before visiting a conventional search result.

    OpenAI has reported that ChatGPT surpassed 900 million weekly active users. That scale makes answer engines a discovery environment, not merely a different interface for search. Your job is no longer limited to earning a blue-link click. You need to make your brand understandable, retrievable, citable, and appropriate to recommend.

    Key takeaways

    • Choose the questions and decisions for which your brand has a credible right to appear. Broad visibility without decision relevance is mostly noise.
    • Treat brand mentions and URL citations as separate outcomes. Mentions build consideration; citations show that your material supplied part of the answer.
    • Build self-contained answer units with a clear scope, direct answer, evidence, limitations, and a useful next step.
    • Use taxonomy, internal links, and accurate schema to reinforce the same entities and relationships expressed in the visible content.
    • Measure AI visibility with a fixed prompt set, then connect the observations to branded search, qualified landing-page visits, and conversions.

    Define the answer you want your brand to own

    Do not start by asking, “How do we rank in ChatGPT?” That question is too broad to guide a page, an editorial calendar, or a measurement plan. Start with the decision your customer is trying to make and the conditions that change the right answer.

    An AI response can produce several materially different outcomes for your business. It can name your brand without linking to you, cite your page without recommending the brand, do both, or omit you entirely. Brand mentions and LLM citations are distinct forms of visibility, so each needs its own strategy and metric.

    • A mention is useful when your goal is to enter a shortlist or become associated with a product category, use case, or audience.
    • A citation is useful when you publish facts, definitions, methods, comparisons, or original information that an answer can reuse.
    • A mention plus a citation is strongest when the cited evidence directly supports the reason the brand was included.
    • An appearance in an irrelevant answer is not a win. It can create the wrong expectation and send poorly qualified visitors to the site.

    Build a query-to-answer map before you change any content. For every important customer decision, record the following:

    1. Audience: Who is asking? Include the role, level of knowledge, or use case that materially changes the answer.
    2. Decision: What are they choosing, rejecting, verifying, or trying to accomplish?
    3. Constraints: Note compatibility, location, budget class, risk, scale, physical requirements, or other conditions that narrow the valid choices.
    4. Evidence needed: Identify the facts a careful buyer would need before trusting the answer.
    5. Desired visibility: Decide whether you want a brand mention, a citation, or both.
    6. Best destination: Select the page that can satisfy the next step without forcing the visitor to restart the search.

    Consider the query “waterproof hiking boots for wide feet.” A generic hiking-boots category page matches some keywords, but it does not resolve the decision. A useful answer needs to define what “wide” means for the available products, distinguish waterproof construction from water resistance, explain relevant fit limitations, and lead to products that actually meet those conditions. That is the difference between topical proximity and answer eligibility.

    Prioritize questions where you can substantiate the answer. If your only support is a marketing adjective such as “leading,” “easy,” or “best,” you do not yet have an answer-engine asset. You have a claim that a retrieval system has little reason to trust or repeat.

    A published Google patent outlines a possible system that could generate organization-specific landing pages tailored to a user’s query. A patent is not a product announcement and may never become a search feature. The useful strategic signal is narrower: generic destination pages are vulnerable when they make a machine or a person perform too much work to connect the query, the entity, and the relevant offer. Make those relationships explicit on your own site now.

    Build pages from retrievable answer units

    A blank page-like slab separates into modular information blocks while selected blocks rise toward a translucent lens.

    Give every answer unit enough context to stand alone

    AI retrieval does not always treat a page as one indivisible object. Content can be segmented into chunks and evaluated against the user’s intent. That makes the section beneath a heading an important unit of work. Semantic depth and retrievable structure matter alongside keywords.

    A strong answer unit contains these elements:

    • Scope: Name the exact question, audience, product, process, or condition being addressed.
    • Direct answer: Resolve the main question early instead of delaying the answer behind a long introduction.
    • Reasoning or evidence: Explain why the answer holds and identify the facts that support it.
    • Boundaries: State the conditions under which the answer changes, does not apply, or needs qualification.
    • Next step: Link to the comparison, product, calculator, documentation, or action that logically follows.

    Use a simple extraction test during editing. Read the heading and its section without the page title or preceding paragraphs. If you encounter vague phrases such as “this solution,” “these benefits,” or “it depends” without enough local context to identify the subject and conditions, revise the section. The goal is not to repeat the entire page. It is to remove dependencies that make the passage ambiguous when retrieved on its own.

    Do the same test on tables, captions, comparison criteria, and FAQ answers. A technically correct fragment can still be unusable if its unit, timeframe, product version, geography, or comparison basis is missing.

    Increase context density without inflating word count

    Context density is not a request to make every page longer. It means that each section contributes a distinct piece of meaning around the primary topic. A useful contextual field includes the main entity, supporting concepts, user intent, relevant constraints, natural language variants, and relationships to other entities.

    • Use the primary topic as the page’s axis, not as a phrase that must be repeated mechanically.
    • Add secondary concepts only when they define a criterion, answer a real question, introduce evidence, or establish a necessary relationship.
    • Use the terms your audience uses, including legitimate variants, but do not create near-duplicate paragraphs to accommodate every phrasing.
    • Name entities precisely. Distinguish a company from its product, a product family from a model, and a feature from the outcome it may support.
    • Place qualifications beside the claim they constrain. Do not hide a critical exception in an unrelated section near the bottom of the page.

    A decision-oriented page will often need a direct answer, definitions, evaluation criteria, evidence, limitations, comparisons, and a next action. It does not need a ceremonial history lesson unless that history changes the decision. Precision is more useful than reaching an arbitrary word count.

    Make architecture and schema confirm the same meaning

    A good paragraph can be weakened by a site that sends contradictory signals. Taxonomy, internal links, canonical destinations, visible labels, and structured data should agree about what the page represents and how it relates to the rest of the site. Internal linking, taxonomy, and schema provide structural and entity context; they are not merely housekeeping.

    • Taxonomy: Group content by meaningful subjects and entities, not by every keyword variation. A category should help a visitor predict what belongs inside it.
    • Internal links: Link from explanatory content to the most relevant decision or product page. Use anchor text that describes the relationship rather than generic instructions such as “click here.”
    • Canonical destinations: Choose a clear primary page when several URLs compete to explain the same entity or intent.
    • JSON-LD: Use the most specific applicable schema type and describe the same organization, article, product, offer, or other entity that appears in the visible page.
    • Entity consistency: Keep names, URLs, product identifiers, authorship, and organizational relationships consistent wherever they are declared.
    • Validation: Check the deployed markup for syntax errors, missing required values, and discrepancies between structured data and visible content.

    Schema does not force an answer engine to mention or cite you. Its role is clarification. It reduces ambiguity about entity type, ownership, attributes, and relationships. Marking up a claim that the page cannot support does not create authority; it only expresses the unsupported claim more formally.

    Create evidence worth reusing and corroborating

    Answer engines need material they can use, not just language that says your company is good. Your content becomes more citable when it contributes information gain: original data, precise specifications, a transparent method, a clear definition, a useful comparison, or a well-supported explanation. Unique information creates a stronger opportunity for URL citations.

    Create a claim ledger for every commercially important page. For each claim, record the exact wording, the evidence that supports it, the page where that evidence is visible, the conditions or limitations, and the person responsible for keeping it current. This exposes a common content problem: a claim may appear throughout the site while its proof exists nowhere a reader can inspect.

    • Product and service facts: Publish exact attributes, compatibility, requirements, inclusions, exclusions, and operating conditions where they affect suitability.
    • Decision evidence: Explain the criteria a buyer should use and why those criteria matter.
    • Methods: When you publish an evaluation, test, survey, or benchmark, state how it was produced and what its limitations are.
    • Definitions: Define specialized terms before using them to support a commercial conclusion.
    • Limitations: Say who should not choose the option, where it does not fit, or which assumptions would change the recommendation.
    • Maintenance signals: Show when time-sensitive facts were reviewed and update or remove claims that can no longer be verified.

    For an ecommerce business, this work connects discovery to revenue. A useful product answer does more than repeat a product name. It connects the shopper’s constraint to verifiable attributes, explains the tradeoff, and leads to a suitable product or category. That is how answer-engine visibility can support trust and purchase consideration rather than producing an empty impression.

    Your website is only part of the entity environment. Relevant review platforms, professional communities, trade coverage, and other independent contexts can reinforce what your brand is known for. Consistent presence in the places your audience actually uses can support brand recognition and recommendation visibility. It also gives you an external consistency check: if independent descriptions of the brand differ sharply from your preferred positioning, the market may not understand the category or use case you are trying to own.

    Do not manufacture reviews, seed disguised endorsements, or flood communities with repetitive promotional copy. Besides the reputational risk, artificial repetition is weak evidence. Contribute useful explanations, accurate product information, expert participation, and material that other people have a legitimate reason to reference.

    Measure the dark funnel and improve the next cycle

    A buyer silhouette travels through a dark branching information tunnel toward a brightly lit group of product objects, with glowing observation points along the route.

    AI discovery can happen before any observable visit to your site. A person may encounter the brand in an answer, search for the brand later, and convert through a channel that receives all the credit. This ingestion-to-recommendation-to-verification path is difficult to reconstruct with conventional analytics. Traffic remains useful, but it cannot fully describe AI visibility.

    Create a repeatable prompt-monitoring set

    1. Select prompts from the query-to-answer map, including discovery, comparison, suitability, objection, and verification questions that matter to the business.
    2. Preserve the exact prompt wording. A rewritten prompt is a new observation, not a clean continuation of the old one.
    3. Run the set on a consistent schedule and record the answer engine, model or mode when visible, date, account state, and location when those variables may affect the result.
    4. Capture the complete answer. Record whether the brand appeared, how it was described, which URLs were cited, where the brand appeared in the response, and which competitors or alternatives were included.
    5. Annotate meaningful changes to content, schema, internal links, product information, digital PR, and third-party coverage.
    6. Compare repeated observations without treating a single changed response as proof that your intervention caused the change.

    Keep the reporting layers separate. Combining everything into a single AI visibility score can conceal the exact failure you need to fix.

    • Prompt coverage: The share of tracked, relevant prompts in which the brand appears.
    • Citation coverage: The share of tracked prompts that cite an owned URL.
    • Answer fit: Whether the brand appears for the intended audience, constraint, and use case rather than in a generic or inaccurate context.
    • Evidence reuse: Which claims, definitions, data points, or pages recur across answers.
    • Competitor context: Which entities appear beside your brand and which stated criteria seem to drive their inclusion.
    • Verification behavior: Changes in branded search, direct visits, visits to named product or service pages, and other signals that people may be checking an AI-assisted decision.
    • Business outcomes: Qualified leads, purchases, conversion rate, and revenue from the destinations most closely connected to the tracked decisions.

    Use the following combinations as working diagnoses, not as proof of how a model reached its answer:

    Observed resultWorking interpretationNext check
    Brand mentioned, owned URL not citedThe entity may be recognized, but your site is not supplying the reusable evidence.Inspect whether the relevant claim has a precise, indexable evidence page and a clear relationship to the brand.
    Owned URL cited, brand not recommendedThe content may be useful while the commercial entity remains weakly associated with the use case.Strengthen entity relationships, brand attribution, relevant internal links, and independent corroboration.
    Brand mentioned and URL citedThe answer connects the entity with evidence, but commercial value is not guaranteed.Check answer accuracy, destination relevance, qualified visits, and conversion behavior.
    Neither mention nor citationThe gap may involve relevance, retrieval, indexing, insufficient evidence, or a query the brand cannot credibly satisfy.Verify technical accessibility, intent alignment, answer-unit clarity, and the strength of the underlying claim.

    Turn the findings into a publishing cycle

    1. Establish the prompt and analytics baseline before making changes.
    2. Choose a commercially meaningful decision where the brand has credible evidence but weak mention or citation visibility.
    3. Audit the relevant page for answer completeness, extractable context, claim support, internal links, and accurate schema.
    4. Fill the evidence gap. Add facts, methodology, qualifications, comparisons, or product attributes that a careful answer would need.
    5. Align related pages and entity declarations so they reinforce rather than compete with the primary destination.
    6. Earn legitimate independent visibility in the communities, review environments, and publications relevant to that decision.
    7. Repeat the prompt set, inspect the resulting patterns, and compare them with branded demand, qualified visits, and business outcomes.

    Start with the customer decision closest to qualified demand. Make its answer explicit, make its evidence inspectable, and make the underlying entities consistent across content, links, and schema. Then measure whether answer engines begin to retrieve the page, cite the evidence, and place the brand in the right consideration set. That is a strategy you can improve, even when the full journey remains hidden.

    References

  • Marketing Data Doppelgangers: An Identity Confidence Playbook

    Marketing Data Doppelgangers: An Identity Confidence Playbook

    Your CRM has identified an apparent ideal customer. This person opens almost every email, checks products repeatedly, moves between devices, and redeems offers with remarkable timing. The activity is real enough to enter your dashboards, but it may not belong to one person or represent the intent your models assign to it.

    Before you increase bids, trigger a high-value nurture sequence, or extend another promotion, you need to know whether you are acting on a coherent customer or a marketing data doppelganger. The practical fix is not another round of duplicate removal. It is an identity-confidence system that separates observed activity from actor, intent, and customer identity.

    What your apparently complete customer profile may be hiding

    A marketing data doppelganger is a customer profile that looks internally valid but does not map cleanly to one actor. Its email may be deliverable. Its clicks may have occurred. Its purchases may be legitimate. The error appears when your systems treat all those events as evidence about the same individual.

    This problem has two main identity patterns:

    • Convergence: Multiple people or systems are folded into one profile. A shared login, forwarded corporate alias, recycled email address, AI assistant, and human account holder can all contribute activity that appears to come from one customer.
    • Fragmentation: One customer is distributed across multiple profiles. Alternate email addresses, several devices, subscription accounts, loyalty records, and repeated new-customer registrations can make one person look like several unrelated prospects.

    Delegated activity complicates both patterns. AI assistants can summarize emails, compare products, monitor prices, complete forms, and sometimes make purchases. That activity is not automatically fraudulent or irrelevant. It is evidence that software acted, possibly with a customer’s authorization. It is not automatically evidence that a person read a message, evaluated an offer, or developed stronger purchase intent.

    Use three separate questions whenever a profile drives a decision:

    • Identity: Which customer, account, household, or organization do we believe this activity belongs to?
    • Actor: Was the event produced by a person, an authorized assistant, an email client, an automated workflow, a shared user, or an unknown process?
    • Intent: What does the event actually establish: message delivery, monitoring, consideration, authorization, or a completed commercial outcome?

    Those answers are not interchangeable. A deliverable email establishes that a destination can receive mail; it does not establish that one enduring person controls it. A completed order establishes a commercial outcome; it does not prove that the payer, shopper, recipient, and account user were the same person.

    Observed patternPossible doppelganger mechanismDecision at risk
    Frequent opens with little subsequent activityEmail prefetching or AI summarizationLead scores, send frequency, and engagement segments
    Repeated product checks at unusually precise intervalsPrice-monitoring or shopping automationRetargeting intensity and inferred purchase urgency
    Contrasting preferences under one addressShared credentials, a forwarding alias, or a recycled addressPersonalization and customer lifetime analysis
    Several apparently new profiles with related account behaviorOne customer using alternate identifiersAcquisition reporting and promotion eligibility
    A customer journey spread across disconnected devices or accountsIdentity fragmentationAttribution, suppression, retention, and forecasting

    The important correction is simple: valid events do not guarantee a valid person-level interpretation. Your job is to preserve what was observed while reducing confidence in conclusions the evidence cannot support.

    Audit the marketing decision before cleaning the database

    A database-wide identity project can become expensive and abstract before it changes a single campaign. Start with one consequential decision: a lead score, promotion rule, churn prediction, retargeting audience, acquisition report, or budget forecast. Then work backward to the identity assumptions that make the decision possible.

    1. Write the claim behind the decision. A high-engagement segment may depend on the claim that repeated opens and product views represent increasing interest from one person. A new-customer discount may depend on the claim that one profile represents one previously unseen customer. State that claim plainly.
    2. List the events that support the claim. Separate email opens, clicks, page views, form submissions, account activity, promotion redemptions, and transactions. Do not collapse them into a single engagement total during the audit.
    3. Recover event provenance. For each event, retain the event time, collection source, profile and account identifiers, campaign, session or device identifier where permitted, related transaction or promotion, automation marker, and downstream outcome. A missing provenance field is an audit finding, not permission to assume a human acted.
    4. Classify the likely actor. Use practical states such as human-confirmed, delegated or agent-assisted, platform-generated, shared or ambiguous, and unknown. Preserve unknown as a real category. Treating unknown as human simply hides the uncertainty.
    5. Look for convergence and fragmentation. Search for abrupt cross-device activity, mutually inconsistent preferences, shared or reassigned contact points, automated monitoring patterns, and apparently new profiles connected to established activity. Each pattern is a reason to investigate, not proof of abuse.
    6. Run a counterfactual version of the decision. Recalculate the segment, score, attribution result, or forecast after excluding events with uncertain actor provenance. Then consolidate likely fragments where you have defensible evidence. If the decision changes materially, it depends on identity assumptions that need to be exposed.
    7. Record the operational consequence. Note whether the uncertainty can waste media, increase message frequency, distort attribution, issue duplicate benefits, suppress a legitimate customer, or create unnecessary checkout friction. This converts identity quality from a data-cleaning concern into a prioritized business risk.

    Email engagement deserves early attention because prefetching and automated summarization can create activity that resembles high engagement. An open can remain useful as a delivery or processing event, but it should not carry the same intent weight as an explicit response or a coherent downstream journey.

    Do not delete ambiguous events. Preserve the raw observation and change its interpretation. Deletion destroys evidence you may need for attribution, troubleshooting, or future validation. Classification lets you ask better questions without pretending uncertain data never existed.

    Replace the golden record with an evidence-backed confidence record

    An anonymous customer figure surrounded by devices and transaction objects, with solid and faint connection lines indicating different levels of identity confidence.

    The traditional golden record promises one definitive profile assembled from every available identifier. That model becomes brittle when one person can produce several identities and several actors can produce events under one identity. A larger merged profile can look more complete while becoming less coherent.

    Use a confidence record instead. It should not merely declare that two records match. It should explain why your organization currently considers a profile stable enough for a particular use.

    Evaluate identity confidence across these dimensions:

    • Identifier continuity: Are the account and contact identifiers stable over time, or do they show signs of reassignment, sharing, or frequent substitution?
    • Behavioral coherence: Can the activity plausibly belong to the same customer context, or does it contain conflicting needs, abrupt channel changes, and overlapping journeys?
    • Actor provenance: Can you distinguish explicit customer actions from platform processing, delegated agent activity, autofill, and unknown automation?
    • Commercial continuity: Do account history, offer use, and completed outcomes support the same customer relationship, or do they reveal fragmentation or convergence?
    • Ambiguity burden: How much of the profile’s apparent value depends on events whose actor or meaning cannot be established?

    A practical profile record can store an identity state, actor state, confidence band, supporting evidence, contradictory evidence, last validation trigger, and permitted uses. For example, the identity state might be stable, fragmented, composite, or unknown. The actor state might be human, delegated, platform-generated, shared, mixed, or unknown.

    Use confidence bands with reason codes before reaching for a precise score. A numerical score can create false certainty if nobody can explain what moved it. A band such as high, conditional, or low is useful when it is attached to evidence and an allowed decision:

    • High confidence: The available evidence is coherent and sufficiently attributable for the named use. This does not mean every event came directly from a human.
    • Conditional confidence: The profile contains stable evidence, but shared, delegated, or fragmented activity limits some uses. It may be suitable for service communication while remaining unsuitable as clean training data for an intent model.
    • Low confidence: The profile depends heavily on weak identifiers, unknown event provenance, or contradictory activity. Use it cautiously and avoid expensive personalization or irreversible risk decisions based on it alone.

    Confidence must be use-specific. The evidence required to send a general newsletter is not the same as the evidence required to grant a one-time benefit, block an order, label a person as a high-value customer, or train a predictive model. A universal identity score hides those differences.

    Revalidate when meaningful evidence changes, not only during a periodic cleanup. Useful triggers include a new account relationship, a sudden shift in device or channel behavior, evidence of a shared or recycled contact point, new agent-assisted activity, conflicting transactions, and a promotion or risk event. Continuous validation is necessary because identity now behaves like an evolving relationship rather than a static match.

    Identity confidence is not a reason to collect every possible identifier. Use permitted data with a clear purpose, retain provenance, and avoid treating invasive surveillance as a substitute for coherent evidence. Better validation should make your interpretation more disciplined, not make your collection indiscriminate.

    Change campaign, attribution, and risk decisions at the same time

    Overlapping customer and device signals pass through a confidence gate before branching toward campaign, attribution, and risk decision symbols.

    An identity audit has little value if every downstream system continues treating all events as equal. Carry the confidence state into activation, reporting, modeling, and revenue protection.

    Separate activity, human intent, and identity confidence

    Replace a single engagement score with distinct measures. Observed activity records what happened. Intent classification describes what the event can reasonably imply. Identity confidence describes how safely the behavior can be attached to the profile.

    • Treat prefetches and automated message processing as delivery or machine-processing evidence, not direct proof of interest.
    • Classify agent-based comparison and price monitoring as delegated activity. It may represent customer interest, but it should remain distinguishable from a human browsing session.
    • Give coherent downstream actions more decision weight than isolated high-volume signals, while retaining uncertainty about who performed them.
    • Prevent low-confidence profiles from automatically entering expensive personalization, aggressive retargeting, or high-priority sales queues.

    This structure lets a campaign acknowledge useful agent activity without pretending that every machine event is a human signal.

    Publish attribution with an uncertainty view

    Do not hide identity ambiguity inside a probabilistic attribution model. Browser privacy changes and cross-device behavior already make attribution more dependent on inferred relationships. Adding composite profiles can make a precise report less trustworthy, even when the arithmetic is correct.

    Show the reported result beside an identity-quality view. Track the share of events with unknown actors, conversions attached to composite or fragmented profiles, and the sensitivity of channel credit when automated events are removed. You do not need to invent a confidence-adjusted revenue figure if your evidence cannot support one. Showing the uncertainty is more useful than concealing it behind a new calculation.

    Keep unstable identities from becoming model ground truth

    A model trained to equate automated opens with customer interest will seek more people who produce the same distorted pattern. Campaigns then generate additional machine activity, which returns as apparent proof that the model was right. This is how an identity problem becomes a performance feedback loop.

    Attach identity and actor labels before training. Depending on the model and decision, filter unstable profiles, reduce their training weight, or retain them as a separately labeled population. Evaluate performance by confidence band as well as in aggregate. If a model performs well only where identity is ambiguous, inspect what it has actually learned before expanding its use.

    Distinguish delegated assistance from promotional abuse

    An AI assistant acting for a customer is not, by itself, evidence of fraud. Shared accounts are not automatically abusive either. Blocking every ambiguous profile adds friction for legitimate customers, while permissive rules can allow one person to appear repeatedly as a new customer.

    Escalate controls when low identity confidence coincides with an economic action and contradictory account history. Do not make an agent marker the sole reason for a block. Use proportionate checks, preserve the reason for the decision, and provide a review path when a legitimate customer may have been caught by the control.

    Give each team an explicit responsibility

    Identity confidence fails when it belongs only to the data team. Assign ownership at the point where interpretation becomes action:

    • Marketing operations preserves event provenance and exposes confidence fields to campaign tools.
    • Analytics reports identity uncertainty and tests how sensitive conclusions are to ambiguous events.
    • Lifecycle and sales teams define which confidence bands may enter each journey or priority queue.
    • Model owners document which identity states are accepted as labels and evaluate performance across those states.
    • Risk and commerce teams define when an ambiguous identity warrants additional validation rather than automatic denial.

    Begin with the decision that has the clearest cost when identity is wrong. Rewrite its event rules, add actor and confidence fields, rerun the decision under alternative inclusion rules, and document what changes. Once that loop works, extend the same method to the next campaign, model, or control. You will improve trust faster by validating consequential decisions one at a time than by declaring the entire customer database clean.

    Key takeaways

    • A marketing data doppelganger is a coherent-looking profile whose events do not reliably represent one actor or one customer’s intent.
    • The problem includes both convergence, where several actors appear as one profile, and fragmentation, where one customer appears as several profiles.
    • Preserve the distinction between identity, actor, and intent. A valid event does not make every person-level inference valid.
    • Audit one costly decision first, recover event provenance, classify uncertain actors, and rerun the decision without ambiguous signals.
    • Replace binary identity matches with explainable, use-specific confidence bands supported by evidence and contradiction records.
    • Carry identity confidence into segmentation, attribution, model training, promotion controls, and reporting so the same uncertainty is not lost downstream.

    Your next step is to choose one segment, score, or promotion rule that would hurt if the customer identity were wrong. Find the weakest event it relies on and make that uncertainty visible. That small change gives you a defensible starting point for rebuilding trust in the rest of your marketing data.

    References