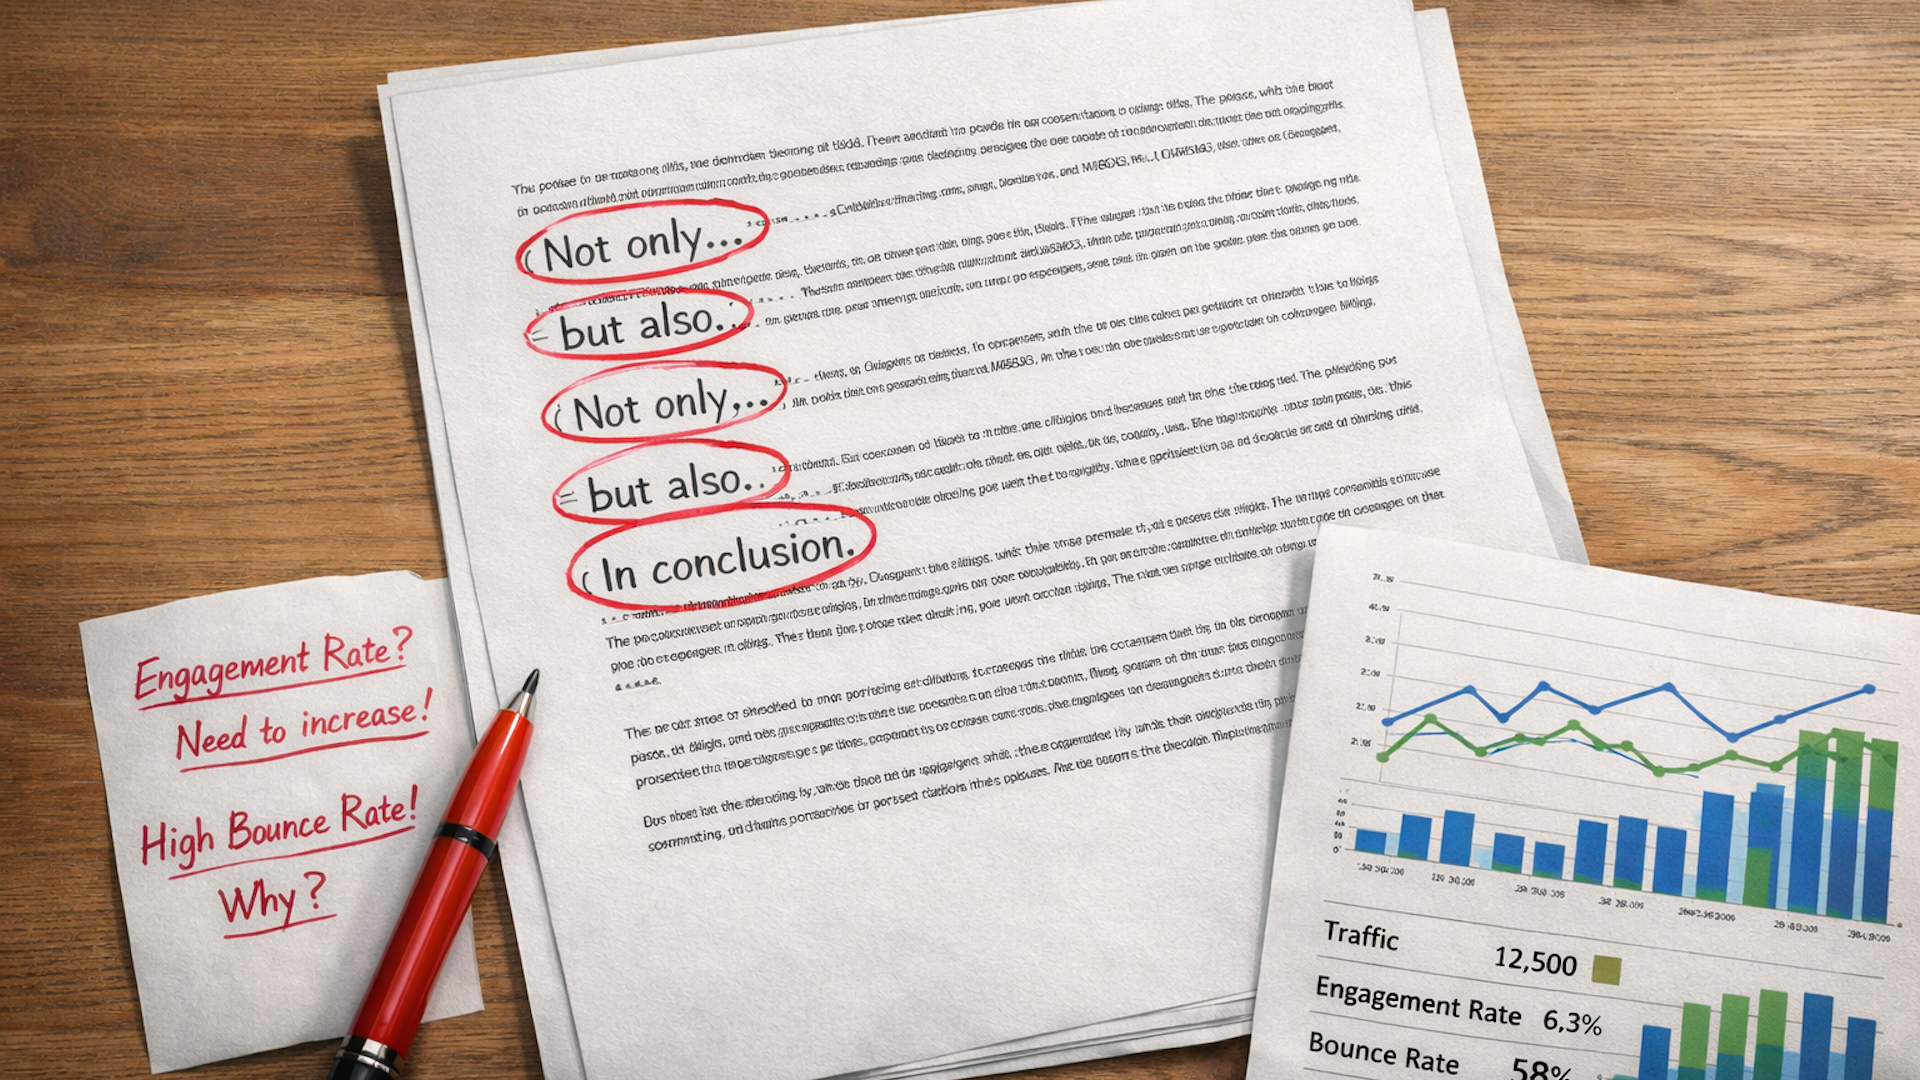
I recently dove into a fascinating study that explored the impact of specific AI writing quirks on reader engagement. We analyzed data from over 1,000 URLs to distinguish which common writing patterns actually affect how readers interact with content.
n
nnn
Scrolling through LinkedIn as a content marketer, I
Your page can be crawlable, polished and successful in search yet receive little or no Google Discover exposure. The common mistake is treating Discover as another blue-link ranking system. It is a personalized, visual feed with gates that can remove a page or publisher before ranking begins.
That changes how you should diagnose a weak result. First verify eligibility and card integrity. Then examine interest fit, predicted click appeal, freshness and user feedback. This order helps you fix the layer that is actually limiting visibility instead of rewriting content that never reached the ranking stage.
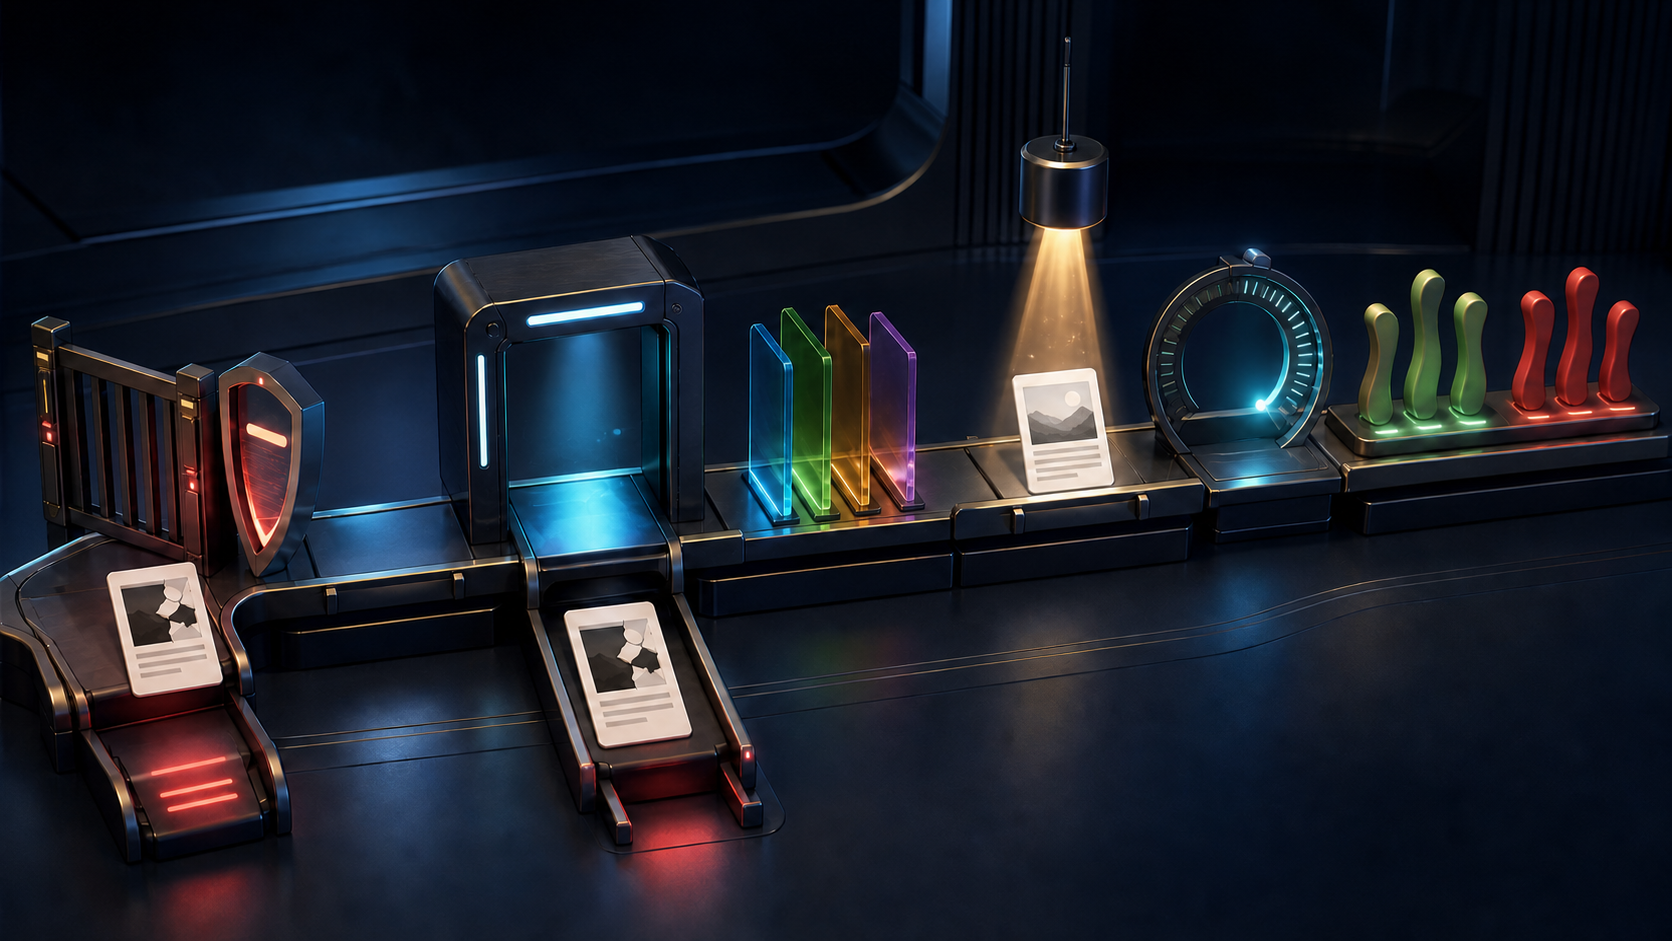
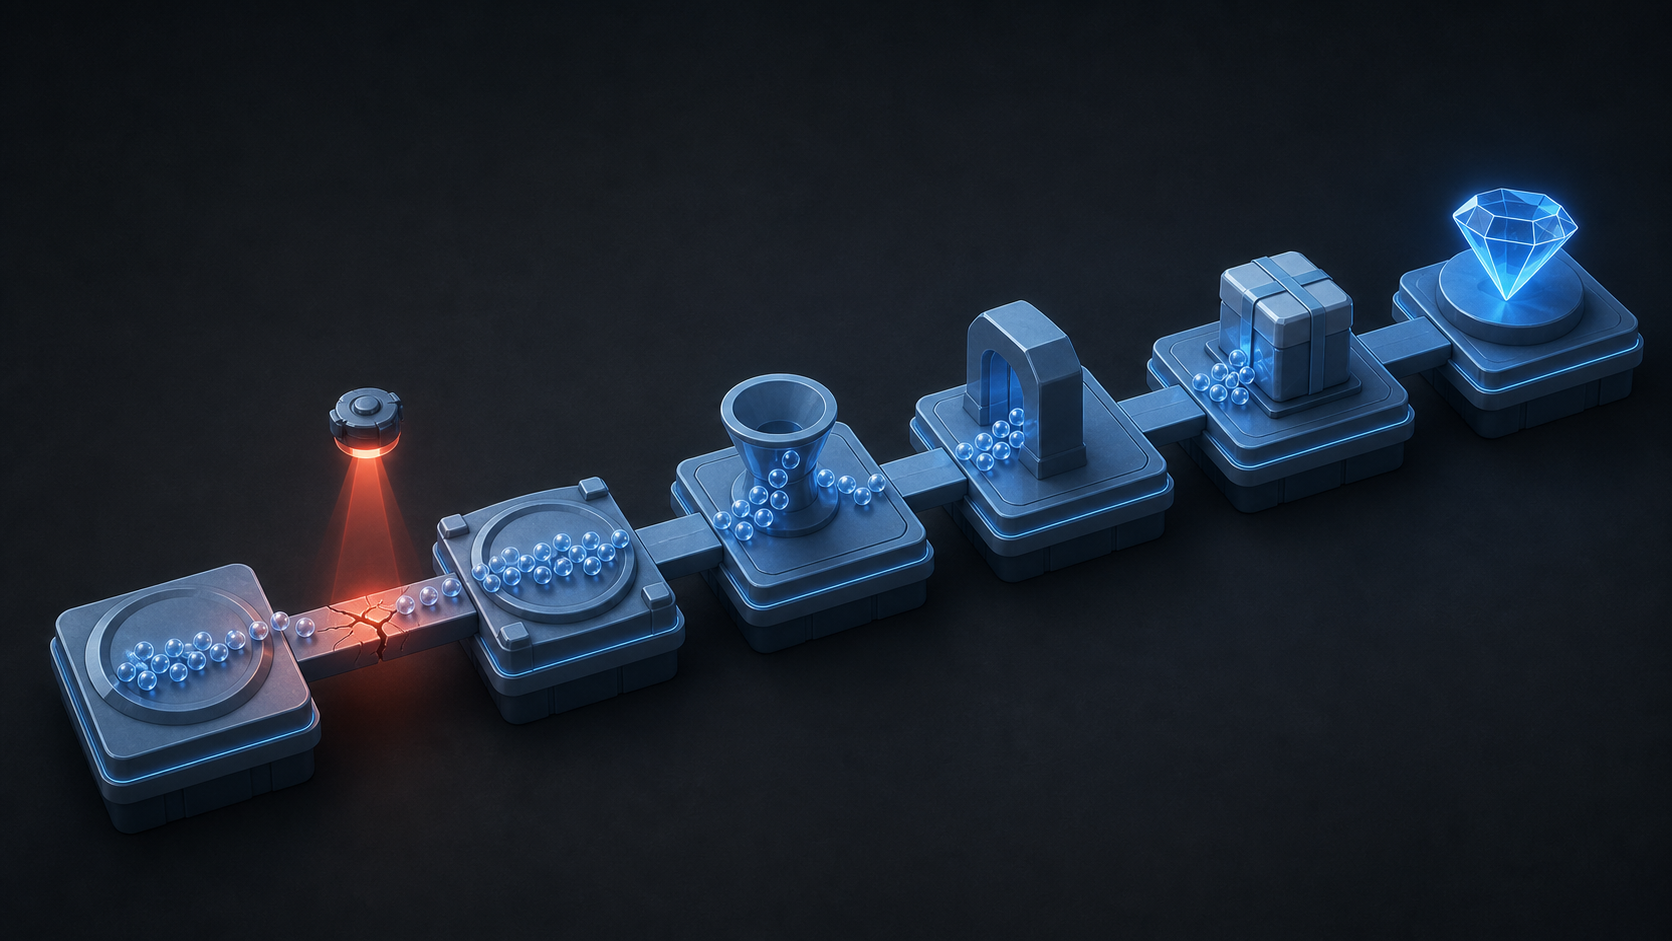
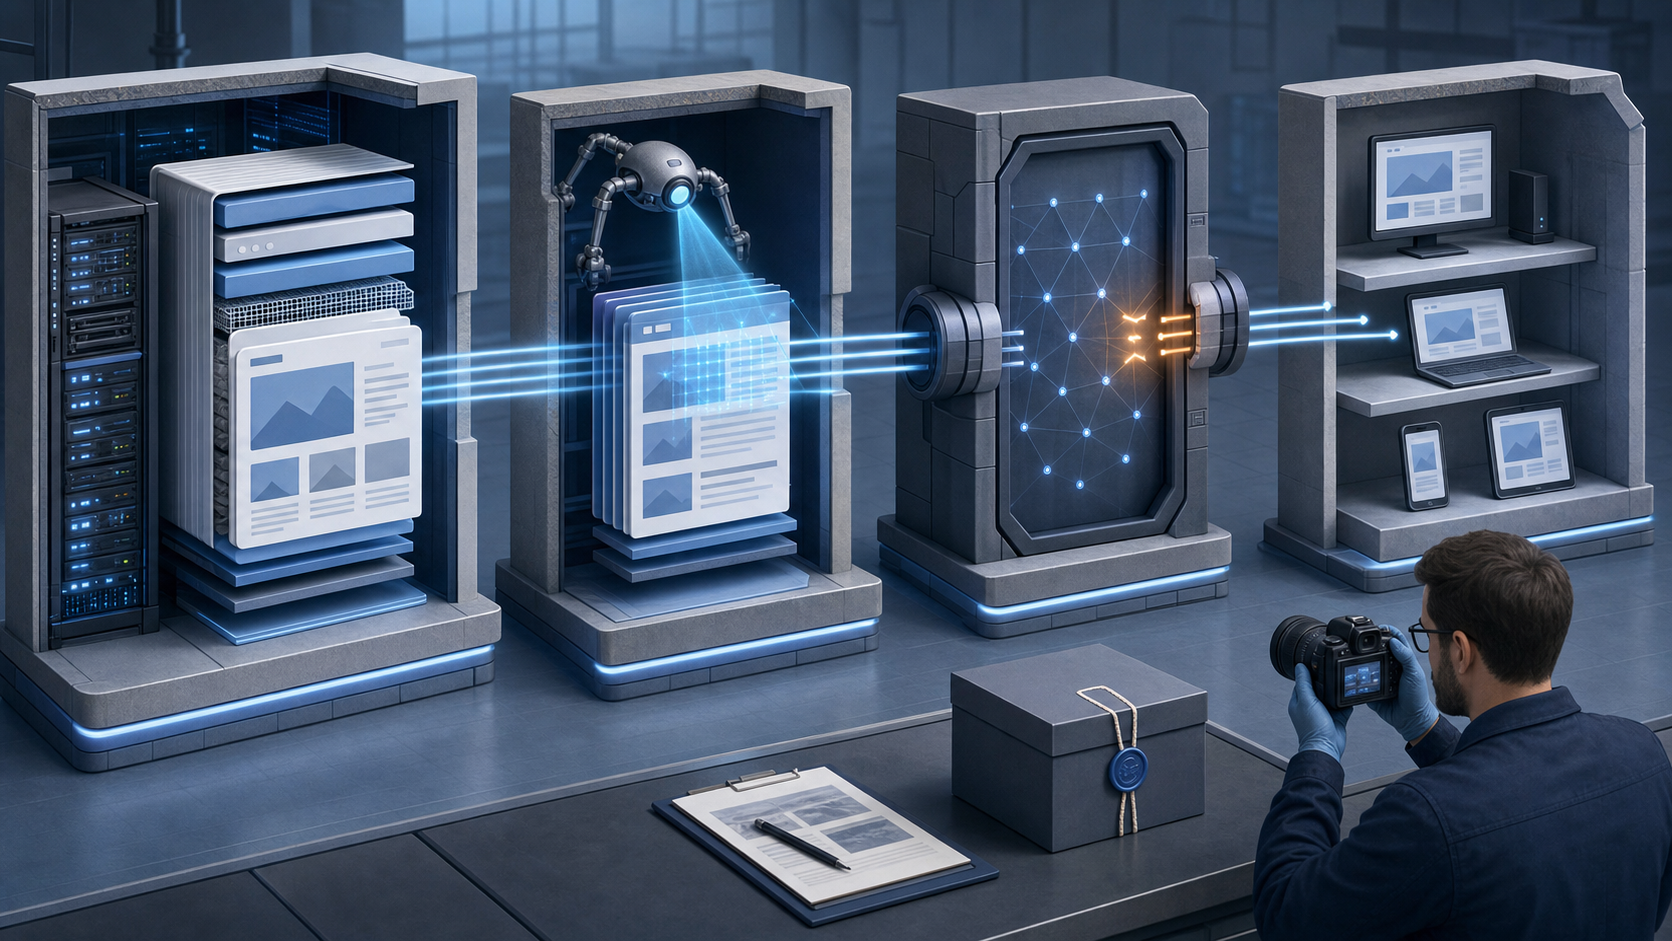
Discover ranking starts after several ways to disappear
It extracts card information such as the title and image.
It classifies the content, including whether it is breaking, recent or evergreen.
Eligibility rules and blocks can remove it.
Remaining candidates are matched with a person’s interests.
A server-side model predicts the likelihood of a click.
The feed layout is assembled.
The selected card is served.
Interactions and feedback are recorded.
This sequence explains why a ranking-focused edit may accomplish nothing. A missing image, an exclusionary meta tag or a publisher block can stop the page before its title, historical engagement and predicted click-through rate have a chance to compete.
Publisher blocks are especially consequential. When a person chooses not to see content from a publisher, the domain can be removed from that person’s candidate set before interest matching. That is broader than dismissing one URL, although it does not mean the domain is suppressed for every user. No mirror-image domain-wide boost was exposed in the same pipeline.
Start every investigation by distinguishing absence from underperformance. If the page is not producing meaningful exposure, inspect qualification, card construction, age and audience fit first. If it is being shown but attracts few clicks, the title-image combination and its relevance to the matched audience become more plausible constraints. Neither symptom proves a single cause, but the distinction keeps your audit pointed at the right stage.
The ranking signals you can actually work on
Once a page survives the earlier filters, a server-side predicted click-through rate model estimates whether someone is likely to open it. The model and its weights have not been disclosed. Client-side telemetry does, however, expose several of the inputs and conditions surrounding that decision.
Signal or condition
How it enters the feed
What to check
Title
The card title is taken from og:title. If it is missing, Google may fall back to a Twitter title or the HTML title.
Inspect the emitted HTML and make sure all title fields describe the same page. Do not let an old template value become the unintended fallback.
Image
Image dimensions, quality and successful loading affect card treatment. A missing image can leave the page without a card.
Open the exact og:image URL, verify that it loads and confirm that the asset is at least 1200 pixels wide if you want eligibility for the larger card presentation.
Freshness
Content age is grouped into decay windows, with the strongest advantage during the first seven days.
Record the real publication age before diagnosing a later decline as a title or technical problem.
URL history
Previous clicks and impressions for the URL can inform predicted engagement.
Evaluate a page in the context of its own exposure history. A result from another URL or topic is not a clean substitute.
Personal relevance
Broader interest data and individual actions such as follows, saves, dismissals and reading engagement help shape the feed.
Define the specific interest the page serves. A generally interesting subject is not the same as a strong match for a particular person.
Publisher context
Publisher-level signals can include Publisher Center registration, while a person’s publisher block can exclude the domain from that person’s feed.
Keep publisher identity consistent and treat every card as part of a domain-level relationship, not only as an isolated URL.
The image threshold deserves literal treatment. An asset that is 1199 pixels wide does not meet a 1200-pixel requirement. Smaller images may still appear as thumbnails, but thumbnail cards generally provide less visual space and tend to attract fewer clicks. The practical target is therefore not merely having an image. You need a suitable, accessible image attached to the metadata Google reads.
The title fallback chain is another frequent source of confusion. Your editorial interface may show the intended headline while the page emits a stale og:title. In that case, the social card field can govern Discover’s title. Check the final HTML delivered by the page rather than assuming the visible on-page heading and metadata match.
Two less obvious meta directives also belong in the qualification audit. The exposed behavior indicates that nopagereadaloud and notranslate can prevent Discover appearance. If either directive is generated by a sitewide template, localization plugin or publishing workflow, confirm that its presence is intentional before changing copy or images.
Do not turn this signal list into a formula. Predicted click-through rate is a model output, not a field you can set, and the available evidence does not reveal a reliable weight for each input. Your job is to remove preventable defects and create a truthful, immediately understandable card. A title-image combination that wins a click but disappoints the reader can still lead to a dismissal or publisher block.
Freshness creates a clock, not an automatic expiration date
Content age is not treated as a smooth, uniform curve from the moment of publication. The exposed freshness model uses four practical age bands:
Age of content
Expected freshness treatment
Operational implication
1-7 days
Strongest freshness boost
Complete metadata, image and loading checks before publication so the best window is not spent repairing the card.
8-14 days
Moderate visibility remains possible
Separate a normal reduction in freshness from a technical failure. Review exposure and click behavior before making large changes.
15-30 days
Visibility tends to fall
Expect age to become a stronger competing explanation when performance declines.
More than 30 days
Gradual decay continues
Do not assume exclusion. Determine whether the page has durable evergreen value and whether a substantive update is editorially warranted.
These bands describe relative treatment, not guaranteed traffic. A one-day-old page can still fail eligibility or interest matching, while older content may receive an evergreen classification. Freshness is an advantage after the page qualifies; it cannot repair a missing card, an accidental block or a weak audience match.
The first seven days should change your publishing workflow. Finish the large image, metadata and page-loading checks before the URL goes live. If those tasks wait until the next morning, part of the strongest freshness window has already passed. Coordinate the initial distribution during that same period rather than treating publication and promotion as unrelated jobs.
Do not read the decay model as permission to change a date without changing the content. Nothing in the exposed mechanics establishes that a timestamp edit alone reliably resets classification or restores distribution. If a mature page deserves renewed attention, make the update useful on its own merits, confirm the card again and then judge the result without assuming a reset.
User feedback can narrow future opportunity
Discover is not just personalized when the feed is first assembled. It learns from direct actions and reading behavior. Follows, saves, story dismissals and time spent with content can influence what a person sees next. The feed can also add, remove or reorder cards while someone scrolls, without requiring a manual refresh.
The scope of each negative action matters. A dismissal is stored for the specific URL and prevents that story from reappearing for that person. A publisher block is broader: it can remove the domain from that person’s feed before future pages are matched with interests. That asymmetry makes a misleading card a publisher-level risk, even when it succeeds at generating the first click.
Use that distinction when reviewing content. For an individual URL, ask whether the title and image promise the same experience the page delivers. At the publisher level, look for repeated patterns that could make someone reject the whole domain: unclear topic fit, cards that routinely overstate the content or inconsistent value between pages. You may not be able to attribute every block to a specific card, but you can remove the recurring reasons a reader would choose one.
A single device check is useful for spotting a broken image or malformed title, but it is not a ranking test. Do not treat one person’s feed position, card shape or absence as a stable benchmark. Look for repeated patterns across comparable URLs and time windows, while remembering that a page moving down after its first week may reflect freshness decay rather than an editorial mistake.
Run your Discover audit in pipeline order
When visibility disappoints, use the same sequence the feed uses. Stop at the first failed check, correct it and verify the result before redesigning everything downstream.
Confirm basic qualification. Make sure Google can crawl and interpret the page, then check for nopagereadaloud, notranslate or another intentional publishing restriction.
Inspect the delivered metadata. Read the final og:title and og:image values from the page. Check the Twitter and HTML titles as possible fallbacks rather than relying only on the CMS preview.
Validate the image as a card asset. Open the exact image URL, verify that it loads and confirm a width of at least 1200 pixels for the larger presentation. A visually attractive file that fails to load is still a failed signal.
Place the URL in its freshness band. Record whether it is 1-7, 8-14, 15-30 or more than 30 days old. Use that context before interpreting a rise or decline.
Name the intended interest match. Complete the sentence: this page is for a person who follows or engages with this specific subject. If the answer is only a broad demographic, the content proposition is probably not precise enough for a personalized feed.
Review the predicted-click inputs. Put the title and image together as a card. Check whether they communicate a specific, accurate reason to open the page without depending on context that appears only inside the body.
Assess feedback risk. Compare the card’s promise with the first screen and the substance of the page. Remove gaps that might win an initial click but invite a URL dismissal or publisher block.
Interpret results as a pattern. Compare similar pages and equivalent age windows. Treat a single feed view as a rendering check, not proof of ranking success or failure.
Key takeaways
Google Discover can filter a page or publisher before interest matching and ranking begin.
The ranking stage uses a server-side predicted click-through rate model, but its formula and signal weights are not public.
Card titles primarily come from og:title, with Twitter and HTML title fields available as fallbacks.
Images should load correctly and be at least 1200 pixels wide for eligibility for a prominent card treatment.
Freshness is strongest at 1-7 days, moderates at 8-14 days, falls at 15-30 days and gradually decays beyond 30 days.
A story dismissal applies to one URL for one person, while a publisher block can remove the entire domain from that person’s feed.
Experiments and live feed reordering make individual screenshots unreliable as performance benchmarks.
Choose one recently published URL and run only the first three audit steps before changing its writing. If qualification, metadata or image delivery fails, fix that layer first. If all three pass, move to interest fit, predicted click appeal, freshness and feedback in that order. This gives you a defensible diagnosis even when Discover itself remains variable.
Your brand can appear in an AI answer and still send almost no visible traffic to your analytics. It can also send only a handful of visits that produce valuable leads or purchases. If you judge both outcomes by sessions alone, you will either dismiss AI search too early or overstate what it contributes.
The practical answer is to manage AI visibility as a pipeline: access, source selection, click and business outcome. Each stage needs its own metric and its own fix. Once you separate them, you can tell whether you have a visibility problem, a traffic problem or a conversion problem.
Key takeaways
An AI citation is exposure, an LLM referral session is a click, and a conversion is a business outcome. Do not combine them into one visibility number.
Track both LLM share of referral traffic and LLM share of total site traffic. They answer different questions and must use different denominators.
Keep raw sessions and conversions beside percentage metrics. Low traffic volumes can make conversion rates look more stable than they are.
Ordinary SEO still matters. Crawl access, clear page structure, descriptive metadata, internal links and authoritative mentions help make content discoverable.
ClaudeBot, Claude-User and Claude-SearchBot perform different jobs. Set crawler policy for each instead of treating all Claude access as one decision.
Measure the four-stage path, not one visibility score
A conventional analytics report begins after someone clicks. AI discovery often begins much earlier, and an answer can mention your brand without generating a visit. Your scorecard therefore needs four layers.
Access: Can the relevant crawler or user-initiated fetcher retrieve the page? Check robots.txt, page availability, indexing controls and server responses.
Selection: Does the brand, domain or page appear in answers for a fixed set of relevant prompts? Record mentions and citations separately because an answer can name a brand without linking to it.
Visit: How many detectable referral sessions arrive from ChatGPT, Perplexity, Gemini, Claude and other identified LLM sources? Break them down by source and landing page.
Outcome: How many of those visits produce the event that matters to the business, such as a purchase or qualified lead? Keep that event definition consistent across channels.
Those figures are useful orientation, not a forecast for your site. Industry, audience, analytics configuration and the definition of a conversion can all change the result. A small channel can also produce a high rate from very few conversions, so report the numerator and denominator: sessions, conversions and conversion rate.
Be exact about traffic share. LLM referral sessions divided by all referral sessions measures the channel’s share of referral traffic. LLM referral sessions divided by all site sessions measures its share of total acquisition. A result below 2% of referral traffic cannot automatically be restated as below 2% of all site visits.
Your working report should include the following fields:
LLM source
Landing page
Referral sessions
Defined conversion event
Number of conversions
Conversion rate using a documented denominator
Visibility or citation status for the relevant prompt group
Notes on page updates, crawler changes, PR activity and distribution
Keep the LLM source group editable. The mix of platforms and the pages cited in answers can change, so a report hard-coded around one provider will become incomplete. Referral analytics also measures detectable clicks, not every citation or unlinked mention. A zero in the referral column does not prove zero AI visibility.
Make each important page easy to retrieve and cite
AI search optimization does not replace SEO. The companies operating generative AI products also invest in technical SEO, content, conversion paths and organic acquisition. For your site, the same foundation determines whether a useful answer is available in a form that machines and people can understand.
Use a citation-ready page pattern
Give the page one clear job. Target a specific question, task or decision instead of combining several loosely related intents.
Answer before expanding. Put the direct answer near the start, then explain conditions, exceptions and evidence. Do not make a reader hunt through a long preamble.
Label the useful units. Descriptive headings, lists and genuine comparison tables make definitions, steps and distinctions easier to locate.
Separate fact from recommendation. State what is documented, what depends on context and what you recommend. This prevents a conditional claim from looking universal.
Offer value beyond the extracted answer. Original examples, methods, tools, templates or deeper supporting detail give an interested user a reason to visit the page.
Match the next action to the query. A visitor who arrived for a technical answer should see a relevant technical next step, not a generic request to contact sales.
Do not neglect basic on-page signals. Clear meta titles, useful descriptions, readable URLs, accurate tags and descriptive image names are among the technical and content elements associated with stronger search discovery. They will not force an AI system to cite you, but missing or vague signals create avoidable ambiguity.
Distribute one consistent evidence set
A strong page can still remain isolated. Align SEO, social distribution, PR and supporting content around the same canonical evidence rather than publishing disconnected versions of the claim. A unified SEO, social, PR and content strategy gives the brand more consistent language, mentions and paths back to the page you want treated as the primary resource.
Start with the canonical page. Give it the complete answer and supporting detail. Supporting articles can address narrower questions and link back to it. Social posts can surface individual findings without changing their meaning. PR outreach can point to the same evidence when it is genuinely relevant. Keep the brand name, product names, category language and core claims consistent across these surfaces.
Consistency does not mean copying the same paragraph everywhere. It means that the entity, claim and destination remain stable while the format changes for each channel. If five pages compete to be the definitive version, you have made source selection harder for search systems and readers alike.
Choose Claude crawler rules by purpose
AI training access and AI search visibility are separate decisions. Anthropic identifies three Claude user agents with different functions, so blocking one does not automatically block the others.
User agent
Purpose
What blocking changes
ClaudeBot
Collects public web content for model training.
Excludes the disallowed pages from this training crawl. It does not by itself block user-requested retrieval or search indexing.
Claude-User
Fetches a page when a user asks Claude to access information that requires it.
Prevents those user-initiated fetches from retrieving disallowed pages, which can remove your content from relevant response workflows.
Claude-SearchBot
Indexes material used to improve Claude search results.
May reduce the visibility or accuracy of your content in Claude-enhanced search responses.
If you want to block only the training crawler across the site, the directive is:
User-agent: ClaudeBot
Disallow: /
Create a separate group for every bot you intend to control. If your subdomains have different policies, publish the appropriate robots.txt file on each one. Anthropic’s bots support standard directives including Disallow and Crawl-delay.
Do not use broad public-cloud IP blocking as a substitute for a precise crawler policy. These bots can operate through public cloud infrastructure, so an IP-level rule can affect unrelated traffic and may interfere with access to robots.txt. Save the previous file, verify the exact user agent and path you are changing, fetch the live robots.txt after deployment, and inspect server logs for the expected behavior. A misplaced site-wide rule can materially reduce discovery.
Run a monthly cycle around the weakest stage
Do not begin each month by asking how to get more AI traffic. Begin by locating the bottleneck. The answer determines whether you need analytics work, a crawler change, a better page or stronger distribution.
Save the baseline. Record LLM sessions, landing pages, conversions, conversion rates and results from a stable set of commercially relevant prompts. Preserve raw counts.
Check access. Review robots.txt, page availability, indexing controls, canonical destinations and the Claude user agents that match your policy.
Improve the highest-intent weak page. Clarify its answer, heading structure, metadata, evidence and next action. Log the publication date so a later change can be connected to the work.
Coordinate distribution. Point relevant supporting content, social activity and PR toward the canonical page while keeping the core entity and claim consistent.
Review by source and landing page. Compare the new period with the saved baseline, but do not call a percentage change meaningful without looking at the underlying session and conversion counts.
Use the pattern of results to choose the next action:
No appearances and no visits: investigate access, page relevance, answer clarity, internal discovery and external authority. Conversion work is not yet the bottleneck.
Appearances but no detectable visits: treat the citation as visibility, not traffic. Check whether the page offers a compelling reason to continue beyond the generated answer. Some informational prompts will naturally produce few clicks.
Visits but no conversions: inspect the landing page’s intent match, offer and next step. More citations will amplify the same conversion problem.
Conversions from low volume: protect the working page and expand into closely related high-intent questions. Do not assume the observed conversion rate will remain unchanged as volume grows.
Traffic without known visibility: confirm the referral classification and add the source and landing page to your monitored prompt set. Your visibility measurement may be missing a real route into the site.
Start with one report, one explicit crawler decision and one high-intent page. Annotate each change. The next monthly review will then tell you which stage moved and where the next unit of effort belongs, even while total LLM traffic remains small.
Your ROAS has dropped, and the obvious move is to pause the ad. That may stop the loss, but it doesn’t tell you what failed. ROAS is the last result in a chain that begins with delivery, passes through attention and the click, and ends with a purchase and its value.
You can make a better decision by finding the first broken handoff in that chain. Once you know whether the friction sits in the auction, creative, page load, offer or checkout experience, you can test the part that actually needs work.
Build one KPI chain from impression to revenue
Ads Manager presents metrics as neighboring columns. Your customer does not experience them that way. Each stage depends on the one before it, so a weak result downstream may have been created several steps earlier.
Read the account from left to right. Start with delivery and volume, then follow the user through attention, click, arrival, conversion and order value. Your job is to find the earliest stage where performance diverged from its normal relationship with the next stage.
Stage
Question to answer
KPIs to read together
Delivery
Is Meta finding and serving enough impressions at a workable cost?
Spend, impressions, reach, CPM and frequency
Attention
Does the creative earn attention and keep it?
Hook rate and hold rate
Response
Does that attention create a useful click?
Link CTR, link clicks and CPC
Arrival
Does the click become a loaded landing page?
Link clicks, landing page views and cost per landing page view
Conversion
Does the page turn qualified visits into the intended action?
CVR and CPA
Value
Does each conversion generate enough revenue?
AOV and ROAS
This sequence prevents a common diagnostic error: blaming the most visible metric rather than the first broken relationship. Low ROAS does not automatically make the ad creative the problem. High CPM does not automatically make the audience the problem. High CTR does not automatically mean the traffic is valuable.
Be precise about metric definitions before comparing them. Link CTR and CTR for all clicks do not describe the same behavior. CVR based on landing page views is not interchangeable with CVR based on link clicks or sessions. Select one definition for each stage and use it consistently across the campaigns, ads and periods you compare.
Treat “high” and “low” as comparisons with a relevant baseline, not universal judgments. Use the same campaign objective, conversion event, attribution setting and reporting level. A campaign can look different because its measurement context changed even when the customer journey did not.
Use KPI math to locate the pressure on CPA and ROAS
The relationships become clearer when you decompose the outcome. The following equations are useful diagnostic identities when every input uses the same spend, reporting period, attribution scope and event definitions.
Relationship
What it isolates
What a deterioration means
CPC = CPM / (1,000 x link CTR as a decimal)
The combined effect of auction cost and click efficiency
CPC can rise because impressions became more expensive, link CTR fell, or both happened
Arrival rate = landing page views / link clicks
The handoff between the ad and the website
More clicks are failing to become recorded page loads
Cost per landing page view = CPC / arrival rate
The real cost of delivering a visitor to the page
Even inexpensive clicks can become expensive visits when arrival rate falls
CPA = cost per landing page view / CVR
The combined effect of visit cost and conversion efficiency
CPA can rise because visits cost more, fewer visits convert, or both
ROAS = AOV / CPA
The relationship between acquisition cost and order value
ROAS can fall because CPA rose, AOV fell, or both
The last identity assumes that CPA represents an attributed purchase and AOV uses the same attributed purchases and revenue. If your account mixes lead events, modeled values, different attribution settings or different denominators, use the relationship directionally rather than expecting the columns to reconcile exactly.
This decomposition gives you four useful reads:
If CPM rises while link CTR stays flat, CPC should rise. The pressure began before the website.
If CPC stays stable while CPA worsens, inspect arrival rate and CVR. The auction is unlikely to be the first bottleneck.
If CPA stays stable while ROAS declines, inspect AOV and recorded purchase value before replacing a productive ad.
If link CTR improves while CVR falls, the creative may be generating more interest without generating more qualified demand.
The equations are not a substitute for judgment. They narrow the investigation. They tell you which relationship must have changed, then the surrounding metrics help you decide why.
Find the first broken handoff before choosing a fix
CPM and reach: separate auction pressure from a delivery problem
CPM is not simply the price of an audience. It is feedback from an auction in which bid, estimated action rates and user value contribute to total value. A CPM increase can therefore support several hypotheses: stronger competition, weaker expected response, reduced creative resonance or some combination of them.
Pair CPM with spend, impressions, reach and link CTR. If CPM rises while delivery and response weaken, investigate the creative and auction environment before assuming that a higher budget will solve the problem. If CPM rises but CTR, CVR and order value remain healthy, you may be seeing cost pressure rather than a broken journey. The unit economics decide whether that pressure is tolerable.
A fall in impressions or spend also deserves attention before you inspect rates. When volume changes sharply, rate metrics can distract you from the more basic issue that the system is no longer delivering the ad at the same level. Check the delivery pattern and creative response together; lower volume identifies an area to investigate, not a cause by itself.
Hook rate and hold rate: distinguish stopping power from sustained interest
Hook rate and hold rate answer different questions. The hook earns the first moment of attention. The rest of the creative has to retain that attention, develop the proposition and create a reason to act. Use the definitions configured in your reporting setup consistently, because the exact event or viewing threshold behind each metric may differ.
High hook rate with low hold rate: the opening stops the scroll, but the body loses people. Keep the opening as the control and test the middle, pacing, proposition or closing call to action.
Low hook rate with high hold rate: the content works for the smaller group that gets past the opening. Test a new hook that accurately sets up the existing message; rebuilding the whole ad would discard the part already holding attention.
Healthy hook and hold rates with weak link CTR: the ad may be watchable without making the next step compelling. Clarify the value of clicking, the offer and the call to action.
Do not optimize the hook in isolation. A sensational opening can improve an attention metric while attracting people who do not want the product. The relevant question is whether the hook hands the right viewer to the body of the ad, and whether the body hands that viewer to the landing page.
Link clicks and landing page views: verify that traffic actually arrives
A link click records intent to leave the placement. A landing page view indicates that the destination loaded far enough to produce the relevant event. The gap between the two is a separate performance stage, not a minor reporting detail.
A result such as 1,000 link clicks but only 450 landing page views should trigger a technical investigation. It does not prove one cause, but it is too large a handoff loss to treat as a creative problem without checking the destination.
Work through the handoff in this order:
Confirm that link clicks and landing page views use the same date range, reporting level and destination.
Calculate arrival rate by dividing landing page views by link clicks. Track that ratio beside CTR and CPC.
Open the exact destination used by the ad and check whether redirects, server response or page load delay obstruct the visit.
Verify that the landing page view event is present and firing as intended. A measurement failure and a loading failure can create a similar dashboard pattern.
Judge CVR only after you understand which denominator it uses. Purchases divided by clicks and purchases divided by landing page views answer different questions when arrival rate is weak.
This relationship explains why cheap clicks can still produce an expensive campaign. If many clicks never become page views, the effective cost of an actual visitor rises even when CPC looks attractive.
CTR, CVR and AOV: test message match before blaming traffic
High CTR and low CPC show that an ad can generate clicks efficiently. They do not show that the page can convert those clicks or that the resulting purchases carry enough value. When CTR looks healthy but ROAS does not, split the post-click result into CVR and AOV.
CVR fell: inspect landing-page relevance, the offer and the path to conversion. The traffic may have encountered friction, or the ad may have promised something the page does not deliver clearly.
CVR held but CPA rose: look upstream at the cost of delivering a real visitor. CPM, CTR or arrival rate may have changed.
CPA held but ROAS fell: inspect AOV and attributed revenue. Replacing the ad will not repair a decline in value per purchase.
Message match is often the practical issue. If one creative promotes several products but sends every click to a detailed page for only one of them, some interested users will land in the wrong context. A relevant collection page can preserve the range of choices presented in the ad. The destination should continue the decision the creative started.
This is also why a CTR increase can be misleading. More clicks are useful only when the next-stage metrics show that they are arriving and converting. If CTR rises while CVR collapses, test whether the new creative broadened curiosity beyond the people who are likely to buy.
CPA and frequency: look for fatigue as a paired movement
Frequency matters because it gives context to a changing CPA. When frequency and CPA rise together, creative fatigue becomes a reasonable working hypothesis. Refresh the creative input or expand targeting when the audience is too narrow before relying on higher bids or budgets.
Frequency alone is not a verdict. If it rises while CTR, CVR and CPA remain stable, the account is not showing the same evidence of fatigue. Monitor the relationship instead of applying an arbitrary frequency cutoff. The damaging condition is repeated exposure accompanied by weaker response or more expensive acquisition.
Turn the diagnosis into one controlled Meta Ads test
A diagnosis is useful only when it changes what you test. Use the following process whenever a campaign or ad appears to be underperforming.
Lock the comparison context. Use the same reporting level, objective, conversion event, attribution setting and metric definitions. Do not compare one ad with a campaign-wide blended result and treat the difference as causal.
Check volume first. Record spend, impressions and reach. A delivery change can alter the meaning of every rate that follows.
Trace the chain in order. Read CPM and frequency, hook and hold, link CTR and CPC, clicks and landing page views, CVR and AOV, then CPA and ROAS.
Name the first broken relationship. “ROAS is down” is an outcome, not a diagnosis. “CPC is stable, but fewer clicks become landing page views” identifies a handoff you can investigate.
Assign the problem to an owner. Creative owns attention and click motivation. The media and auction context shape delivery. The website and measurement setup own the click-to-page-view handoff. The page, offer and purchase path shape CVR. Product mix and order value shape AOV.
Change one meaningful variable. If CVR is the first break, test the landing experience or offer while holding the ad steady. If hold rate is the first break, edit the body or ending while retaining the hook as the control.
Choose an expected KPI and a guardrail. A page-load fix should improve arrival rate without requiring CTR to change. A new hook should improve initial attention without damaging hold rate, CTR or downstream conversion quality.
Read the whole chain again. A local improvement counts only if it preserves or improves the handoff to the next stage.
Write the test as a short diagnostic note before making the change: observed pattern, working hypothesis, variable being changed, metric expected to respond and downstream guardrail. For example: “Link CTR is stable, arrival rate has fallen and CVR among recorded landing page views is stable. Check page delivery and tracking; do not replace the ad. Arrival rate is the response metric, while link CTR is the guardrail.”
This discipline matters because simultaneous changes erase the explanation. If you replace the creative, broaden targeting, rewrite the page and alter the offer at once, a better result will not tell you which bottleneck was real. A worse result will be equally difficult to interpret.
Key takeaways
ROAS and CPA are outputs. Diagnose them by tracing delivery, attention, click, arrival, conversion and value in order.
Use compatible denominators. Link CTR, landing page arrival rate and landing-page-based CVR reveal different handoffs that blended metrics can hide.
Read paired movements. CPM with CTR, hook with hold, clicks with landing page views, CPA with frequency, and CPA with AOV are more informative than isolated scores.
Find the first broken relationship. Downstream damage does not prove that the downstream stage created it.
Change one variable at the identified bottleneck, then watch the next-stage KPI as a guardrail.
The next time ROAS falls, do not begin with the pause button. Put the KPIs in journey order and mark the first handoff that changed. That relationship gives you the next investigation, the next controlled test and a reason for acting that is stronger than a red number on a dashboard.
Your Google organic traffic suddenly drops, and the chart looks bad enough to demand an immediate response. The fastest reaction, however, is often the wrong one: changing titles, canonicals, redirects, or indexation settings before you know whether your site caused the decline.
A Google search results outage can interrupt traffic without changing your rankings or indexation. Your job is to establish the timing, isolate the affected layer, preserve the evidence, and avoid introducing a second problem while the first one clears.
It is not automatic proof. Google’s acknowledgement establishes that a serving problem existed. It does not establish that every query, country, device, or website was affected. It also does not tell you the incident’s exact duration. Closely spaced status updates show when Google communicated, not necessarily the precise beginning and end of the underlying failure.
Create an incident entry before exploring possible SEO causes. Record the Google timestamp in ET, convert it to the reporting timezone used by your analytics platform, and retain both. A timezone mismatch can make a related traffic drop look as if it started before or after the search incident.
Then answer four narrow questions:
When did the decline begin in the timezone used by the report?
Did traffic begin recovering after Google reported the serving issue fixed?
Was the decline concentrated in Google organic traffic, or did other acquisition channels fall too?
Did the website remain available and continue receiving requests from other sources?
A close match across those checks makes the outage explanation more plausible. A mismatch gives you a reason to keep investigating rather than forcing the external incident to fit your chart.
Read the shape of the drop before naming the cause
A serving failure, a ranking loss, a website failure, and an analytics fault can all produce a downward line. They happen at different layers, so the surrounding evidence should look different.
Search results serving problem: Google has trouble delivering search results normally. Your site can remain healthy, indexed, and technically unchanged while fewer searchers reach it.
Ranking or visibility loss: pages appear less often or in weaker positions for relevant queries. The decline can persist after a serving incident ends and may be concentrated around particular queries, landing pages, or sections.
Website availability problem: searchers can see a result but encounter an error, timeout, redirect failure, or unavailable page after clicking. Server, CDN, application, and deployment records become central evidence.
Measurement problem: visits or conversions occur but fail to appear correctly in reporting. Consent changes, tag failures, filters, attribution rules, and broken data pipelines can create an apparent traffic loss without an equivalent loss in real activity.
Use independent signals to separate these layers. Compare organic traffic with direct, referral, paid, and other search-engine traffic. Check whether transactions, leads, or authenticated activity changed with sessions. Review uptime and HTTP errors. Look for deployments, DNS changes, CDN changes, analytics releases, or consent configuration changes in the same window.
Also inspect the distribution of the decline. A broad, short-lived reduction in Google organic traffic that overlaps the acknowledged incident is compatible with a serving problem. A sustained loss limited to one template, directory, country, device class, or set of queries points toward a more specific issue. Neither pattern proves the cause by itself, but each tells you where to look next.
Rank-tracking data needs similar care. A tracker that tried to retrieve results during a serving disruption may report missing or unstable positions because it could not obtain a normal result page. Preserve that run, label the affected window, and compare it with a fresh run after service has recovered. Do not rewrite pages in response to one anomalous collection window.
Run a clean outage triage before changing SEO
The aim of triage is not to prove your preferred explanation. It is to eliminate layers until one explanation fits the available evidence better than the others.
Capture the original alert. Save the metric, time range, timezone, filters, comparison period, and dashboard view that triggered concern. Do this before changing filters or waiting for reports to refresh.
Mark the acknowledged incident window. Add Google’s reported time and resolution status to your analytics or incident log. Keep the external confirmation link with the entry so the explanation remains auditable later.
Separate Google organic traffic from everything else. Compare channels over the same intervals. If every channel declined, start with your site, analytics, or a broader business event rather than assuming Google search serving was solely responsible.
Check the delivery path. Review uptime monitoring, server responses, application errors, CDN events, DNS changes, security controls, and deployment history. A search incident does not rule out a simultaneous problem on your own infrastructure.
Segment the organic loss. Inspect landing pages, site sections, devices, countries, branded demand, and important query groups where your available tools support those views. Concentration is diagnostic; an account-wide total hides it.
Reconcile traffic with outcomes. Compare sessions or clicks with leads, purchases, calls, sign-ins, and other business events you can verify. If reported traffic collapses while independently recorded outcomes remain normal, investigate measurement before rankings.
Reassess with complete periods. Compare equivalent reporting intervals once the relevant data pipelines have finished processing. Do not compare a partial recovery period with a complete baseline day and call the difference an ongoing loss.
Classify the incident. Close it as an external serving event only when the timing, affected channel, recovery, and site-health evidence support that conclusion. Otherwise, open a separate technical, analytics, or visibility investigation.
Your internal update can stay concise: state what changed, when it changed, which channel and segments were affected, what remained healthy, whether Google acknowledged a related incident, and when you will assess complete data. Label the cause as suspected until the evidence supports a firmer conclusion.
Protect the recovery window from unnecessary changes
Do not respond to a short serving incident by editing robots.txt, adding or removing noindex directives, changing canonicals, replacing redirects, rewriting titles, or mass-submitting URLs. Those controls affect crawling, indexation, and page selection. They do not repair Google’s search-results delivery layer, and changing them can turn a temporary external disruption into a persistent site problem.
During active diagnosis, keep a record of scheduled releases and defer non-essential SEO changes that would make the recovery harder to interpret. If you already have direct evidence that your own release caused an error, follow your normal rollback process. The existence of a Google incident should never override stronger evidence from your infrastructure.
Once traffic normalizes, annotate the event instead of deleting or smoothing the abnormal data. Future comparisons, forecasts, reports, and anomaly-detection systems may encounter the same interval. An annotation prevents another analyst from rediscovering the incident and incorrectly treating it as seasonality, a campaign effect, or an algorithm update.
If traffic does not recover after the acknowledged serving problem ends, stop using the outage as the default explanation. Recheck technical availability, measurement, query visibility, landing-page distribution, recent site changes, and affected markets. An external event can explain an overlapping dip; it cannot explain an indefinite decline without supporting evidence.
A useful incident record includes the first alert, all relevant timestamps and timezones, affected metrics, unaffected control metrics, segment breakdowns, internal changes, external confirmation, recovery evidence, final classification, and the person responsible for follow-up. That record is more valuable than a confident but undocumented explanation.
Key takeaways
A sudden Google organic decline is an alert, not a diagnosis.
Match the traffic window to Google’s reported incident in the same timezone before drawing conclusions.
A search-results serving problem is different from a ranking, indexation, website, or analytics problem.
Use other channels, site-health records, business outcomes, and segment data as independent checks.
Do not change crawl or indexation controls to address an external serving failure.
Preserve and annotate the affected data so later reporting does not misclassify the anomaly.
If the loss continues beyond the event window, investigate it as a separate problem.
Your next move is simple: add the incident to your timeline, preserve the affected reports, and compare the recovery against unaffected channels and site-health evidence. Make an SEO change only when that evidence points back to your site.
The landscape of AI is rapidly shifting in 2026. I’ve noticed that AI models are losing their once shared data access, resulting in fragmented and less cohesive answers.
This change is primarily due to the surge in platform-controlled data, which is significantly altering how visibility and search functions within AI systems. It’s intriguing to see how these developments are reshaping the way we interact with and trust AI-driven responses.
If you manage a retail or nonprofit account, your next move should not be to accept every imported asset or enable every available goal. First determine what Google can now use, whether it represents the organization accurately, and what campaign behavior you are authorizing.
Two updates, two different control points
The Merchant Center change affects campaign inputs. The Ad Grants change affects campaign objectives. That distinction determines who should review each update and what can go wrong if nobody does.
Should automated optimization prioritize physical attendance alongside, or instead of, existing online outcomes?
The connecting theme is delegation. Google is doing more to discover usable creative and letting advertisers optimize toward an outcome closer to real-world activity. Your work moves upstream: govern the inputs, define the outcome hierarchy, and verify what the system actually did.
Audit auto-populated videos as potential ad inventory
Google previewed the Merchant Center Video Assets area at Google Marketing Live 2025. The rollout began in September, but the section remained blank for many users before populated libraries started appearing. That progression matters because the interface is no longer just a placeholder. It is now an operational surface that retail teams need to review.
Automatic discovery reduces upload work, but it also changes the failure mode. An old demonstration, expired promotion, superseded product, or video created for a different audience can enter the creative workflow without anyone deliberately adding it to that screen. Treat the library as a review queue, not a quality endorsement.
Record what appeared. Create a review sheet with the visible video title, apparent origin, relevant product or category, owner, and review status. If the interface does not expose a field you need, mark it unknown instead of guessing.
Confirm the authoritative version. Identify whether the asset comes from an official YouTube presence or another approved business source. Duplicate edits and abandoned channel uploads are easy to mistake for current creative.
Check every commercial claim. Compare product names, availability, model references, prices, promotions, and calls to action with the current product feed and destination page. A polished video is still unsafe to use if its facts have expired.
Watch it as an ad, not as archived content. The product and brand should be identifiable without relying on surrounding page copy. The main point should remain understandable when audio is unavailable, and the clip should not depend on an earlier episode or presentation for context.
Classify it internally. Use clear statuses such as commerce-ready, correction required, and not intended for advertising. Assign an owner and a reason for every non-ready classification.
Review changes at the source carefully. A YouTube video may serve customer support, education, or organic discovery even when it is unsuitable for an ad. Do not remove or rewrite a useful source asset merely to tidy Merchant Center until you understand the effect on its other uses.
Keep three states separate in your reporting: discovered in the library, permitted or selected through the controls available to your account, and confirmed as served in campaign reporting. Without that distinction, teams can mistakenly call an imported video an active ad or attribute a performance change to an asset that never received delivery.
This is also why your first audit should be reversible. Document and classify before making broad changes to channels, source videos, or campaign assets. The interface is live, but the available controls and reporting may not yet answer every governance question.
Make shop visits primary only when attendance is the priority
A primary conversion goal is not a decorative reporting preference. It tells the account which outcomes should matter to bidding and optimization. Changing that priority can change the traffic an automated campaign pursues and how it values one user action against another.
The option is especially relevant when attendance is the mission outcome: a museum needs visitors, a community center needs participation, and a place of worship may value physical attendance more than a page view. Those are among the organizations that can connect local search activity with real-world visits.
Availability does not make the goal appropriate for every account. Before making it primary, ask whether a visit is genuinely more important than an online donation, registration, appointment request, membership application, or other existing conversion. If the answer differs by campaign, do not let an account-level default silently settle that strategic question.
Write the outcome hierarchy in plain language. For example: physical visits are the primary outcome, event registrations are the next priority, and general page views are diagnostic only. Get agreement before changing the platform.
Inspect the current goal configuration. Record the existing primary goals, the campaigns relying on account-level goals, and the bidding approach in use. This gives you a defensible before-state.
Confirm that the option exists in the account. The capability applies to eligible accounts. If shop visits are unavailable, do not describe the rollout as universal or treat the missing control as proof that somebody configured the account incorrectly.
Verify the local journey. Make sure the ad destination and public location information identify the correct organization and place. Optimizing for visits cannot compensate for inaccurate location details or a landing page that leaves visitors unsure where to go.
Document the change. Record the date, owner, reason, affected goals, and expected behavior. Without a change log, a later shift in campaign results can look mysterious.
Evaluate mission outcomes, not just clicks. Review spend, reported visits, online conversions, and the downstream result the organization actually values. A campaign that produces more visits is not automatically better if those visits do not support the intended program or location.
The financial risk is straightforward: automated bidding may pursue visit-rich traffic while online donations or registrations receive less emphasis. That trade may be correct, but it should be deliberate. If the organization has not agreed on the relative value of those outcomes, leave the current primary configuration unchanged until it has.
Keep paid activation separate from SEO, AEO, and GEO
Neither update is evidence of an organic ranking change. A video appearing in Merchant Center does not prove that it will rank in Google Search or be cited by an AI system. Making shop visits primary in Ad Grants does not, by itself, improve local organic visibility. These are advertising workflow and optimization changes.
The paid and organic teams should still coordinate because both depend on the same underlying facts. The useful connection is operational consistency, not a promise of cross-channel ranking benefits.
Use one factual source of truth. Product names, models, availability, offers, organization names, locations, and destination URLs should not contradict one another across videos, feeds, landing pages, and local content.
Keep activation controls channel-specific. Merchant Center asset discovery, Performance Max asset use, Ad Grants conversion goals, organic pages, and AI visibility each have their own mechanisms. Approval in one system should not be treated as approval in every other system.
Measure each channel on its own evidence. Paid delivery and conversions belong in advertising reporting. Search visibility, organic traffic, and AI citations require their own observations. A simultaneous change is not enough to claim that one caused the other.
Treat structured data as a separate implementation. Product, video, organization, or local-business markup may make appropriate page facts machine-readable, but neither rollout gives you a basis to expect JSON-LD alone to populate Merchant Center’s video library or enable an Ad Grants goal.
Share governance, not conclusions. SEO, content, ecommerce, local, and paid-media owners should use the same approved facts and change log while retaining separate success criteria.
This separation prevents a common reporting error: turning an advertising-platform observation into a claim about search or AI visibility. It also makes coordination more useful. When a product changes, one approved update can trigger reviews of the feed, landing page, video library, structured data, and campaign creative without pretending those surfaces perform the same job.
Key takeaways
Merchant Center’s populated Video Assets area should be treated as an asset-discovery queue, not proof that every video is approved or serving.
Review imported videos against current product data and landing pages before allowing them to influence commerce campaigns.
Shop visits can now be a primary goal in eligible Ad Grants accounts, but the setting should reflect an agreed hierarchy of real organizational outcomes.
Record account settings before changing primary goals because automated optimization may shift emphasis away from existing online conversions.
Keep Google Ads activation, organic search performance, structured data, and AI visibility separate in measurement, even when the teams share the same factual source of truth.
Start with one controlled audit. Retail teams should open the Video Assets library, record what Google discovered, and assign every asset a review status. Ad Grants teams should write down their current primary goals and decide where physical visits belong before changing the account. Automation becomes useful when somebody still owns the facts, the priorities, and the evidence.
If you lead AI search, SEO, content, or marketing technology, Profound’s funding can create immediate pressure. Is the company now the category winner? Is your team late? Should you add another platform to your stack? The financing matters, but none of those conclusions follows automatically.
Read the round correctly before changing your strategy
A funding round is evidence that investors were willing to finance a company on negotiated terms. It is not a product certification, an independent performance test, or proof that customers are receiving a positive return.
The distinction matters because the headline contains several figures that are easy to misread. The $96 million is financing, not revenue. The $1 billion valuation is the value assigned to the company in the context of the transaction, not cash deposited into its accounts. Neither figure tells you how much customers spend, whether the business is profitable, how well its software performs, or how the new capital will be allocated.
Series C also describes a financing stage, not a universal level of product maturity. It can support expansion after earlier growth, but the label does not guarantee stable data, complete model coverage, enterprise-ready controls, or a roadmap that matches your needs.
What the round establishes: Profound has attracted substantial private backing for an AI marketing platform.
What it reasonably signals: the participating investors see enough potential to finance further growth at the announced valuation.
What it does not establish: that Profound is the right platform for your use case, that AI visibility software has settled on a standard methodology, or that a large valuation predicts your results.
That last point should shape your response. Do not rewrite your AI strategy around a financing headline. Use the event as a reason to update your assumptions, inspect the category, and ask vendors harder questions.
Where fresh capital could change the AI marketing market
Capital gives Profound more options. It could fund product development, infrastructure, model and market coverage, integrations, hiring, customer support, or go-to-market expansion. Those are possibilities, not disclosed commitments. Treat them as items to verify through shipped capabilities, release records, service levels, and written commercial terms.
The broader signal is that investors are willing to place significant capital behind the problem of marketing through AI-generated answers. That is relevant if you have been treating AI visibility as a temporary reporting experiment. It suggests that the category may attract more product development, sales activity, and competition. One transaction, however, does not establish the size of customer demand or prove that AI search has replaced conventional search.
Your operating model should therefore connect AI visibility to the rest of search and content work instead of building an isolated dashboard. A useful workflow has four linked jobs:
Observe: identify where your brand, products, experts, and pages appear or disappear in relevant AI answers.
Diagnose: determine whether the issue involves ambiguous entities, missing evidence, inaccessible content, inconsistent facts, weak third-party corroboration, or an irrelevant prompt sample.
Intervene: improve the assets you control, including factual copy, source pages, technical accessibility, appropriate structured data, and evidence that other publishers can verify.
Validate: repeat the measurement, inspect the underlying answers and citations, and connect any change to a business decision rather than celebrating a score in isolation.
A platform that performs only the observation step may still be useful, but it has not completed the marketing job. The value appears when your team can trace a detected issue to a defensible action and then check whether that action changed anything meaningful.
Use a buyer’s scorecard, not the valuation
If you are evaluating Profound or another AI visibility platform, apply the same scorecard to every vendor. This prevents brand momentum, investor names, and polished aggregate scores from substituting for evidence.
Start with measurement integrity. Ask which AI models and user experiences are covered, which markets and languages are supported, and whether the results represent live answers, an external data provider, or another collection method. Model output can vary with prompt wording, model version, user context, and repeated runs. You need to know how the platform handles that variability before treating movement as a trend.
How are prompts selected, grouped, weighted, and updated?
Can you inspect the exact prompt, answer, cited pages, collection time, and relevant execution context behind every score?
Does the system distinguish a brand mention from a recommendation, a citation, a comparison, or a factual statement?
How does it prevent changes in prompt coverage from looking like changes in brand performance?
Can you preserve a stable benchmark while separately exploring new prompts and models?
How are failed collections, unavailable models, duplicate answers, and ambiguous brand names handled?
A visibility score that cannot be decomposed is difficult to act on. If the score rises, you should be able to see which answers changed and why. If it falls, you should be able to distinguish a real deterioration from a collection or coverage change.
Then test actionability. Ask the vendor to walk from a detected problem to a recommended intervention using your own data. A useful recommendation identifies the affected audience, the evidence behind the diagnosis, the asset or relationship that needs work, the owner who can act, and the signal that would count as improvement.
Does the platform separate issues on your website from gaps in third-party authority?
Can recommendations point to the exact pages, claims, citations, or entity conflicts involved?
Does it explain where structured data is relevant without presenting schema as a guarantee of inclusion in an AI answer?
Can findings flow into the content, SEO, analytics, public relations, and product workflows your team already uses?
Can analysts annotate changes so later reporting does not confuse an intentional intervention with unexplained movement?
Finish with commercial and operational resilience. Funding may improve a vendor’s capacity to invest, but it does not remove switching costs or contractual risk. Get data ownership, export access, retention, usage limits, overage rules, support scope, renewal terms, and the total expected cost in writing. Confirm what happens to your historical data if you leave. Treat roadmap slides as possibilities until a capability is included in the agreement or available in the product.
Run a controlled evaluation around a real decision
The cleanest way to evaluate an AI marketing platform is to make it answer a decision your team already faces. Do not begin with, “Can this produce an interesting dashboard?” Begin with a question such as, “Can this show us why qualified buyers encounter competitors instead of us, and can it help us choose what to change?”
Define the decision. Name the audience, product or service, market, and business question. Decide who will act if the platform finds a credible problem.
Create a representative prompt set. Include branded and unbranded questions from different stages of the buying journey. Write down why each prompt matters. Keep the core set stable so a changing sample does not masquerade as performance movement.
Capture a manual baseline. Save the exact prompts, visible answers, citations, model or surface, and relevant context. Note entity ambiguity and obvious collection errors before introducing a vendor score.
Run the platform against the same scope. Compare its output with the baseline. Investigate disagreements rather than assuming the platform or the manual sample is automatically correct.
Act on findings you can verify. Correct inconsistent facts, strengthen useful first-party pages, improve crawlability, add appropriate structured data, and pursue credible third-party coverage where the diagnosis supports those actions.
Judge decision value. Ask whether the platform found important issues accurately, explained them clearly, helped the right owner act, preserved evidence, and made follow-up measurement more reliable.
Keep AI visibility metrics in their proper place. Mentions, citations, answer share, and sentiment can be useful intermediate signals, but they are not automatically revenue or causation. If a dashboard improves after you change content, inspect the underlying answers. If business outcomes also change, examine other campaigns, seasonality, brand activity, and measurement gaps before assigning credit.
Be equally cautious with promises of fixed placement. Generative answers are not conventional ranking tables, and their behavior can change. A credible evaluation should show variability, preserve raw evidence, and describe uncertainty instead of hiding it inside a single precise-looking number.
Key takeaways
Profound announced a $96 million Series C and a $1 billion valuation, with Lightspeed Venture Partners leading the round.
The financing signals investor conviction and gives the company more strategic options; it does not prove product performance, revenue, profitability, or customer return.
For AI marketers, the round is a reason to take the category seriously, not a reason to replace a working stack without evaluation.
A useful AI visibility platform must expose prompts, answers, citations, collection context, and methodology behind its scores.
Your evaluation should connect observation to diagnosis, intervention, and validation using a stable prompt set and a manually checked baseline.
Commercial diligence still matters: verify exports, data ownership, limits, support, renewal terms, switching costs, and delivered capabilities before making a long-term commitment.
Treat Profound’s funding as a prompt to sharpen your vendor questions, not to change strategy overnight. Preserve your baseline, test the platform against a decision that matters, and commit only when its data survives manual inspection and fits the way your team acts. That lets you benefit from a better-funded category without outsourcing your judgment to its valuation.
You can publish accurate, polished, keyword-relevant content and still struggle for visibility. As AI makes publishing easier, the competitive problem is increasingly sameness across otherwise competent pages. A page that merely restates the standard advice gives a searcher, answer engine, or agent little reason to prefer it.
You do not need to abandon SEO or start separate programs for every new acronym. You need one operating model that makes each important page discoverable, easy to extract, connected to a clearly defined entity, credible enough to recommend, and complete enough to support a decision.
Key takeaways
Keep the SEO foundation. Clear titles, headings, descriptive language, crawlable content, and intent alignment still determine whether a page gets found and understood.
Optimize for four nested outcomes: be found, become the answer, earn the recommendation, and supply enough verified information to be chosen.
Design for three kinds of processing: traditional search retrieval, language-model extraction, and entity or knowledge-graph understanding.
Refresh useful pages before creating more of the same. Fix the promise, answer order, specificity, entity facts, and technical accessibility.
Use structured data to reinforce visible, consistent facts. It cannot repair vague positioning or contradictory information.
Let AI accelerate inventory, variation, and formatting work. Keep intent, factual verification, differentiation, and final editorial judgment with a person.
Optimize for four outcomes, not four disconnected channels
The language around AI search is unsettled. SEO, AEO, AIEO, GEO, entity SEO, LLM optimization, and assistive agent optimization describe overlapping parts of the same environment. Building a separate workflow around every label creates duplicated briefs, conflicting measurements, and pages that optimize one layer while neglecting the others.
A more useful approach is to treat optimization as a sequence of outcomes. Each later outcome depends on the earlier ones, so the work compounds instead of restarting whenever the terminology changes.
Layer
Required outcome
The question your page must answer
SEO
Be found
Can a system discover, interpret, and match this page to the searcher’s actual need?
AEO
Be the answer
Can an answer engine extract a direct, accurate response without reconstructing it from several vague sections?
AIEO
Be recommended
Are the offering, audience, constraints, and evidence clear enough to support a comparison?
AAO
Be chosen
Can an assistive agent verify the decisive facts and identify the correct next action?
This does not mean every informational page must close a transaction. It means the page should completely perform its assigned job. A definition page may need to resolve a concept and point to the next relevant question. A service page may need to establish fit, exclusions, evidence, and a contact path. A product page may need to expose the attributes on which selection depends.
Use one brief with four acceptance criteria:
Discovery: State the problem in the language a person would recognize, then reflect it in the title, primary heading, description, and opening.
Extraction: Put the core answer in a self-contained passage. Do not make a system combine an introduction, a definition, and a conclusion to infer your position.
Recommendation: Name who the advice or offering is for, when it applies, what constraints matter, and what makes it preferable in that situation.
Selection: Supply the facts, corroboration, and next step required to move from consideration to action.
If a page cannot pass the first layer, work on crawlability and intent before debating agent optimization. If it is discoverable but never mentioned, improve answer clarity and entity definition. If it is mentioned but not recommended, the missing layer is usually decision-grade detail rather than another block of general background.
Design pages for search, language models, and knowledge graphs
A practical model for AI-era retrieval has three components: traditional search, large language models, and knowledge graphs. Their relative influence can vary by platform and task, but the model prevents you from optimizing only the visible prose or only the technical markup. Think of it as three different readings of the same page.
Traditional search needs a clear promise and accessible content
The title, primary heading, description, internal organization, and crawlable copy tell a search system what the page is about. They also tell a person whether the result is worth opening. That second role matters: titles and descriptions are not administrative metadata. They are decision copy.
Write the title after you can complete this sentence: “This page helps [specific audience] do or decide [specific thing] under [relevant condition].” You do not have to use that entire sentence as the title. Its purpose is to expose a vague brief before the vagueness reaches the page.
Compare these title shapes:
Broad: AI Content Optimization
Intent-aligned: How to Optimize Service Pages for AI Recommendations
Constraint-aware: How to Optimize Service Pages for AI Recommendations Without Rebuilding the Site
The sharper version identifies the object, desired outcome, and practical constraint. It helps the right reader recognize the page and gives the page a more precise assignment. A single-site title experiment found a substantial increase in click-through rate after titles were aligned more closely with intent, even though the underlying content was unchanged. That result does not establish a universal lift, but it is a good reason to test packaging before commissioning a replacement page.
Language models need extractable passages
A language model can summarize long prose, but making it perform avoidable interpretation introduces ambiguity. Give each important question a direct answer, then support it with reasoning, conditions, and examples.
Use a descriptive heading that states the question, decision, or problem covered by the section.
Answer that heading in the opening sentence or paragraph of the section.
Name the subject instead of relying on a chain of pronouns whose meaning depends on earlier paragraphs.
Keep qualifications beside the claim they qualify. Do not hide the limitation several screens later.
Separate definitions, procedures, tradeoffs, and examples so each passage can stand on its own.
Use lists when the reader needs steps or criteria, not merely to break prose into fragments.
Extractability is not the same as writing robotic copy. It is the discipline of making the relationship between the question, answer, evidence, and limitation unmistakable.
Knowledge graphs need stable entity facts
An agent evaluating organizations, products, or experts needs to understand what each entity is, what it offers, whom it serves, and whether the relevant facts are dependable. Create an entity home: a page you control that states the canonical facts about the entity in clear language.
For a business, that page should make the following information unambiguous:
The canonical name and any commonly used alternate form.
A plain description of what the business provides.
The audiences, use cases, or markets it serves.
The relevant operating area, eligibility conditions, or service constraints.
The products, services, people, and locations connected to the business.
The evidence a reader can use to assess reliability.
The authoritative destination for contact, purchase, booking, or another next action.
Structured data should reinforce those visible facts, not introduce a second version of them. If the page describes one audience while the markup, profiles, and feeds imply another, more markup increases the contradiction. Resolve the entity definition first, then make the structured representation match it.
Rendering also matters. Critical copy that appears only after client-side execution is vulnerable because many AI-agent crawlers do not process JavaScript. Inspect the raw HTML of an important page. If its main answer, entity name, decisive attributes, or action path is absent, make that information available in the initial HTML through an appropriate server-rendered or pre-rendered implementation. Treat anything injected only after interaction as potentially unavailable to a crawler that does not execute the page like a full browser.
Refresh intent, packaging, and specificity before adding pages
Freshness is not a newer publication date attached to an unchanged answer. In an AI-saturated market, useful freshness comes from restoring alignment between the reader’s current problem, the page’s promise, and the information required to act. That is why refreshing an established page can be more valuable than publishing another broad treatment of the same subject.
Use this sequence when a page has relevant subject matter but underperforms:
Write the intent in one sentence. State what the reader should be able to do or decide after reading, including the constraint that makes the question difficult.
Compare the promise with the answer. Check whether the title and description promise the same outcome the body actually delivers. If not, change the packaging, the body, or both.
Move the useful answer forward. Remove the generic setup that delays the response. Put the direct answer where the reader can encounter it before the supporting detail.
Replace interchangeable passages. Add boundaries, decision rules, tradeoffs, relevant evidence, and corrections to common misreadings.
Reconcile entity facts. Confirm that names, descriptions, relationships, service details, and next steps agree across the page and the other representations you control.
Validate machine access. Check the initial HTML, heading structure, links, and structured data. The content a person sees and the facts a machine receives should describe the same reality.
Measure the changed behavior. Watch click-through rate to assess the search promise, then use time on page and scroll depth to see whether visitors engage with the answer. Change a limited set of elements when you need to understand what affected the result.
The pattern of behavior helps you choose the next edit. Visibility without clicks often points to weak or mismatched packaging. Clicks followed by shallow reading often point to a promise-answer mismatch, excessive setup, or the wrong audience. Sustained reading without the intended next action can indicate that the page explains the subject but omits the criteria needed to decide.
Replace generic competence with decision-grade specificity
The competitive weakness of AI-assisted copy is often sameness, even when the draft is readable and factually acceptable. A useful editorial test is simple: could an unrelated organization publish this passage unchanged? If so, it probably does not contain enough judgment or context to influence a decision.
Strengthen the passage by adding at least one of these elements:
A boundary: who the advice is not for or when it stops applying.
A constraint: the platform, workflow, audience, resources, or operating condition that changes the answer.
A tradeoff: what improves, what becomes harder, and which priority should decide between them.
A decision rule: the condition under which the reader should choose one path rather than another.
A correction: a common interpretation that sounds plausible but leads to the wrong action.
Relevant evidence: a fact that substantiates the claim being made, placed beside that claim.
Specificity does not mean adding decorative detail. A longer page full of definitions can remain generic. The right detail reduces uncertainty at the exact point where the reader or agent must distinguish between options.
Give AI the work that does not require final judgment
AI can accelerate content operations without becoming the editor. Use it to inventory recurring topics, group similar pages for review, produce alternative title shapes, identify repeated passages, restructure already verified material, or turn an approved process into a draft checklist.
Keep the consequential decisions with a person:
Choosing the reader and the intent worth serving.
Deciding which facts are true, current, relevant, and sufficiently supported.
Setting the boundaries and tradeoffs that make the answer useful.
Resolving contradictions between page copy, structured data, profiles, and operational systems.
Approving the final claims, recommendations, and next action.
This division of labor preserves the speed advantage while preventing a plausible draft from becoming another indistinguishable page.
Turn brand facts into a verifiable decision path
Traditional search often sent a person through separate awareness, comparison, and decision visits. An assistive interface can perform much of that evaluation internally and present a narrow recommendation. Your page is therefore competing to become an input to the decision, not merely a blue link near the beginning of the journey.
That changes the role of brand information. A clever positioning line may attract attention, but an agent still needs explicit facts about the entity, offering, audience, suitability, and reliability. If those facts are unclear or inconsistent, a better-understood alternative is easier to choose.
Build a corroboration chain around the entity home
Start with the entity home, then trace every decisive fact outward. The goal is not to repeat promotional copy everywhere. It is to prevent the systems involved in research from encountering incompatible identities.
Define the canonical fact. Decide the exact name, description, relationship, service condition, or destination that should be treated as authoritative.
State it visibly. Put the fact in clear, crawlable language on the relevant owned page.
Represent it structurally. Make the structured data describe the same fact and relationship that the visitor can see.
Align controlled profiles and feeds. Correct outdated names, descriptions, destinations, and eligibility details wherever you can manage them.
Check operational data. When availability or selection depends on an API, booking system, inventory system, or internal database, make sure the decision-critical values agree with the public representation.
Preserve a valid action path. The recommended entity must lead to the right contact, booking, purchase, or information destination.
This broader check matters because the public web index is no longer the only information layer available to assistive systems. Proprietary datasets, APIs, booking platforms, and internal databases can contribute information that is not obtained from an ordinary crawl. Optimizing the page while neglecting the operational record can leave the decision system with conflicting answers.
Treat push mechanisms as delivery, not authority
Proactive mechanisms such as IndexNow, structured data feeds, and emerging agent connections can reduce reliance on waiting for a crawler. They do not make a claim trustworthy merely because it arrived faster. Use a supported push method when it fits the platform, but send information that is already accurate, consistent, and attached to a well-defined entity.
Before releasing or refreshing an important page, run this five-question check:
Can it be found? The title matches a real intent, and the essential content is available to the crawler.
Can it be answered from? A self-contained passage resolves the main question with its necessary qualification.
Can it be understood? The people, organization, offering, and relationships are explicitly named.
Can it be verified? Visible facts, structured data, controlled profiles, and relevant operational records do not contradict one another.
Can it be chosen? The page supplies the fit criteria, constraints, evidence, and correct next action required for its role.
Start with one commercially or strategically important page rather than rewriting the entire site. Clarify its title, place the answer earlier, add the missing decision criteria, establish the entity facts, inspect the raw HTML, and reconcile the structured and operational representations. Measure how people respond, then carry the successful pattern into the next group of pages.
The durable advantage in AI-era search is not publishing faster than every competitor. It is reducing uncertainty more completely – for the person asking the question and for every system deciding whether your answer or brand deserves to move forward.
If your contact page contains only a phone number and a form, your customer still has work to do. They must find out when you are open, whether they can text you, where to park, which payment methods you accept, and what will happen after they submit an inquiry.
A useful contact page answers three questions without making the visitor search the rest of your site:
Have I found the right business? The page confirms your name, brand, location, and what you do.
Can this business meet my practical needs? The visitor can check hours, service options, amenities, directions, parking, and payment methods.
What should I do next? The page presents a visible action and explains what happens after the customer takes it.
That makes the contact page closer to a focused local landing page than an administrative endpoint. It still needs to be concise, but concise does not mean incomplete. The goal is to put every fact needed for a call, visit, message, pickup, delivery, or appointment in one dependable place.
Key takeaways
Publish a complete business identity, not just a name, address, and phone number.
Make shared details agree with your Google Business Profile.
Answer practical questions about contacting, visiting, buying, and arriving.
Support your claims with verifiable reviews, credentials, awards, and local involvement.
Use a prominent call to action, explain the follow-up process, and track completed actions.
Publish one complete and consistent business record
Start with facts before rewriting headlines or changing the design. Open the contact page beside your Google Business Profile and compare every field they share. A customer should not see one phone number on the page, another on the profile, and unexplained hours somewhere else.
Make the business identity unmistakable
Use the same recognizable logo that appears on your signage and other marketing materials. State the full customer-facing business name prominently. If you use a slogan, keep it accurate and useful; forcing location phrases or service keywords into it will make the page sound less credible.
Follow the identity block with a short introduction that says what you do, where you operate, and why someone would choose you. A practical pattern is: business type, location, main area of expertise, and a genuine differentiator. This gives a first-time visitor enough context to confirm that they reached the intended company.
Include the details customers otherwise have to hunt for
Full business name: Use the name customers encounter on your storefront, Google Business Profile, invoices, and other public materials.
Complete address: Include every part needed to reach the correct entrance or unit.
Phone number: Make it easy to select on a mobile device and label its purpose if you publish more than one number.
Text number: If texting is supported, say so explicitly. Do not leave visitors guessing whether the main number accepts messages.
Contact form and email address: Provide an alternative when the form fails, the request needs an attachment, or the visitor prefers email.
Operating hours: Publish normal hours and keep special or holiday variations current.
Social profiles: Link only to profiles you actively associate with the business.
Ways to buy: State whether you offer in-store shopping, curbside pickup, delivery, appointments, or another relevant arrangement.
Map and directions: Embed the Google Map connected to the business and include a direct link to its Google Maps listing. A generic pin for the street address can be less useful than the actual business listing.
Accepted payment methods: Tell customers what they can use before they arrive or place an order.
Parking information: Explain where customers can park and identify any instructions they need before reaching the entrance.
The shared facts on this page and your Google Business Profile should agree. That does not mean every channel must contain identical prose. It means the business name, location, contact routes, hours, service options, and applicable attributes should not contradict one another.
When something changes, update both records as part of the same task. Assign an owner for the page and include it in the workflow for holiday hours, phone changes, relocations, new payment methods, and revised pickup or appointment policies. A technically polished page with stale operational information still fails the customer.
Remove friction from calling, visiting, and buying
Visitors do not all arrive with the same intention. One wants to call immediately. Another needs directions. A third is checking whether curbside pickup is available. The page should support those paths without forcing everyone through the contact form.
For callers: Place the phone number near the primary call to action and show the hours during which a response is available.
For people who want to text: Label the text option and set an expectation for how the conversation continues.
For visitors traveling to you: Pair the address with the business map, a Google Maps link, parking instructions, and any arrival detail that prevents confusion.
For shoppers: State whether the relevant option is in-store service, pickup, curbside collection, delivery, an appointment, or some combination.
For people comparing fit: Publish relevant amenities and business attributes in plain language rather than assuming they will infer them from photos.
For written inquiries: Offer both the form and an email address, then explain what information will help your team respond.
Put the most common action early on the page, but do not hide the supporting details below a long promotional introduction. Someone standing outside your building needs the address, hours, map, and parking information more than another paragraph about brand values.
Amenities deserve particular attention because they often decide whether a customer can use a business at all. Review the attributes shown on your Google Business Profile, confirm which ones are still accurate, and reproduce the applicable facts on the page. Add other genuinely useful amenities that are specific to your location. Do not claim an attribute merely because it sounds desirable.
If you operate multiple locations, do not mix several addresses, phone numbers, and sets of hours into an unlabeled block. Make the selected location obvious, separate its facts from every other branch, and ensure each call to action reaches the right team or destination.
Put trust and local relevance beside the decision
Reaching the contact page does not mean the visitor has decided to contact you. They may be looking for one final reason to proceed or one warning sign that tells them to leave. Place evidence close to the action instead of expecting them to visit a separate company-history page.
Explain what happens after contact
Uncertainty is a conversion barrier. State the expected response time, whether the visitor will receive a confirmation, and what the next step normally involves. If different channels have different processes, explain them separately. A form submission might lead to a callback, while an appointment request might require confirmation before the time is reserved.
Make those expectations operationally honest. A vague promise such as “we respond quickly” gives the customer no usable information. A clearly stated response window is better, but only if your team can maintain it. If you cannot commit to a window, describe the sequence instead: confirmation, review, and follow-up.
Use proof that a visitor can verify
Associations and memberships: Name relevant industry groups, chambers of commerce, professional organizations, neighborhood associations, and community groups. Link to your business entry on the organization’s site when one exists.
Ratings and credentials: Display current credentials and any applicable Better Business Bureau information without overstating what the rating or membership means.
Awards and press: Identify the award or coverage and link to the organization or publication that issued it.
Reviews and testimonials: Use external reviews or testimonials that include enough context to feel authentic, such as the reviewer’s name, photo, city, or public profile when you have permission to publish those details.
Verification matters more than the number of badges. An unfamiliar logo with no explanation can become visual clutter. A named organization, a clear relationship, and a link to an independent listing give the visitor something they can evaluate.
The page can also serve existing customers. Include a clear link for leaving a Google review where appropriate, especially for repeat customers who arrived looking for your contact details. Keep that request separate from the main inquiry action so a new customer does not mistake it for the contact route.
Replace generic local copy with specific local evidence
Calling yourself a trusted local business does not establish local relevance. Show it through details: team names and photographs, areas of expertise, the customer needs you handle, neighborhoods you serve, current guarantees, local events, volunteer work, and partnerships.
Only include details that help someone decide or verify. A list of neighborhood names added solely for keyword coverage is not useful local content. A short explanation of where you work, which services are available there, and what a customer should expect is useful.
Make the next action obvious, reliable, and measurable
Choose a primary call to action that matches the way the business actually converts inquiries. “Request an appointment,” “Call the store,” “Get directions,” and “Ask about pickup” each describe an outcome. “Submit” describes only what the button does.
Repeat the primary action at sensible decision points: after the identity and contact details, after the trust evidence, and near the end. Keep its wording consistent. Secondary actions can support visitors with a different intent, but they should not make every option look equally important.
Treat the form as a working contact channel
Pair the form with an email address so customers have a fallback.
Tell the visitor what happens after submission and how your team will respond.
Use an appropriate spam control, such as reCAPTCHA, a form plugin’s protection, a double opt-in process, or an obfuscated public email address.
Test the spam protection on a phone and with keyboard navigation so it does not block legitimate inquiries.
Send submissions to a monitored destination and verify that confirmation messages and internal notifications arrive.
Track a successful form completion as a conversion. Measuring a button click alone can count attempts that failed validation or never reached your team.
Tracking should reflect the actions that matter to the business. At minimum, verify the form completion event. If calls, text messages, map visits, appointment requests, or pickup inquiries are important contact paths, decide which of those interactions should also be measured. Analytics cannot repair a broken contact experience, but it can reveal which routes customers use and whether a redesign disrupted them.
Run this publishing audit from a customer’s point of view
Confirm identity. Check the full name, logo, location, business description, and differentiator.
Reconcile business data. Compare the address, phone and text numbers, hours, service options, and applicable attributes with the Google Business Profile.
Test every contact route. Call the number, open the text option, send the form, use the email link, and confirm that each route reaches the intended destination.
Test the visit. Open the embedded map and Google Maps link, then verify that they lead to the actual business listing. Read the parking and arrival instructions as though you have never visited.
Check practical fit. Confirm that payment methods, shopping options, amenities, and appointment requirements are accurate.
Verify the proof. Open association, award, press, review, and credential links. Remove expired claims and unexplained badges.
Complete the primary action. Use both a mobile and a larger screen. Confirm that the call to action is visible, the form is usable, the confirmation appears, the inquiry reaches the team, and the conversion is recorded.
Assign maintenance. Identify who will update the page when hours, staff, contact details, service methods, parking, amenities, or credentials change.
Start your first pass with the facts, not the design. Reconcile the page with your Google Business Profile, fix every broken contact route, and then add the missing visit details and proof. Once a customer can identify you, assess fit, trust the business, and complete the next step without guessing, the contact page is doing its real job.