Author: shivamcrushpressai

  • Modern PPC Operations: Formats, Feeds, and Reporting

    Modern PPC Operations: Formats, Feeds, and Reporting

    Your ads can look healthy while the business result quietly deteriorates. A visual asset may be winning clicks but sending the wrong audience. A feed delay may suppress eligible products while the campaign settings remain untouched. A polished dashboard may hide either problem because its blended totals still look plausible.

    Modern PPC needs an operating system, not a longer optimization checklist. You have to manage three connected layers: the experience people see, the inputs advertising systems use, and the reporting that tells you what to change. This framework will help you find the failing layer before you spend money fixing the wrong one.

    Key takeaways

    • Treat each image, headline, description, product record, and landing page as an independent campaign input. Automated systems cannot rescue an asset that lacks a clear message or role.
    • Monitor feed health as a delivery dependency. A feed problem can resemble weak demand, an auction change, or poor campaign management unless you inspect product eligibility separately.
    • Give each data system a defined responsibility. Ad platforms explain delivery, Merchant Center explains product eligibility, GA4 explains post-click behavior, and business systems explain realized value.
    • Build reports around decisions and exceptions, including budget variance, zero-conversion spend, feed degradation, weak post-click behavior, and creative fatigue.
    • Investigate performance in causal order: platform availability, item eligibility, ad delivery, on-site behavior, and business value. That order prevents downstream symptoms from being mistaken for upstream causes.

    Build campaigns around assets, not just ads

    The old keyword-to-text-ad model is no longer a sufficient mental model for PPC. Conversational discovery, interactive showroom ads, visual experiences, and emerging gaming placements create journeys in which a person may inspect, compare, and refine an idea before producing anything that resembles a conventional search click.

    That changes your unit of optimization. You are no longer managing only ads or campaigns. You are managing a library of components that an automated system can select, combine, and distribute across different contexts.

    Give every asset a specific job

    Start by assigning each asset a funnel role. A visual can orient someone to the category, demonstrate a product, make a comparison easier, establish trust, or support an action. If you label everything as generic creative, you will know which file received impressions but not why it worked.

    • Orientation: Show what the product or service is without requiring supporting copy to make it intelligible.
    • Context: Show the offer in the situation where someone would use, choose, or evaluate it.
    • Detail: Make an important feature, difference, or constraint visible.
    • Validation: Reinforce the brand, proof, or reason a buyer should trust the offer.
    • Action: Make the next step and the value of taking it unambiguous.

    Visuals belong across the funnel, not only in awareness or remarketing. At the same time, every asset should remain recognizably yours. Brand-forward visuals and curated creative libraries matter because automated distribution can place one component in contexts you did not manually assemble.

    Maintain an asset register beside the media plan. Record the asset identifier, concept, offer, format, funnel role, intended audience, landing page, launch point, and current status. Use stable identifiers in both the ad platform and the reporting layer. A filename such as image-final-new is useless when you need to connect a result to a creative decision.

    Use AI as a selection system, not a substitute for judgment

    Automation needs good inputs: first-party data, creative assets, copy, website content, goals, and budgets. It can evaluate combinations and expose niche winners, but it cannot decide what your brand should mean or whether an isolated claim is persuasive. Individual asset performance can reveal which components deserve replacement and which niche performers deserve closer attention.

    Do not respond by replacing the whole library at once. Preserve strong components, remove clearly weak ones, and introduce distinct alternatives. A bulk replacement destroys your ability to tell whether the concept, format, offer, or audience match caused the change.

    Before uploading an asset, ask:

    • Can someone understand the central promise if this component appears without its preferred companion asset?
    • Does it add a genuinely different concept, or is it a cosmetic variation of material already in the library?
    • Is the brand identifiable without overwhelming the useful part of the message?
    • Can the asset be mapped to one business objective and one landing-page experience?
    • Will its identifier survive exports, blended reports, and future creative revisions?

    This discipline reduces asset overlap. It also makes automated performance easier to interpret: the system may choose the components, but you retain control over what each component is capable of communicating.

    Treat product feeds as production infrastructure
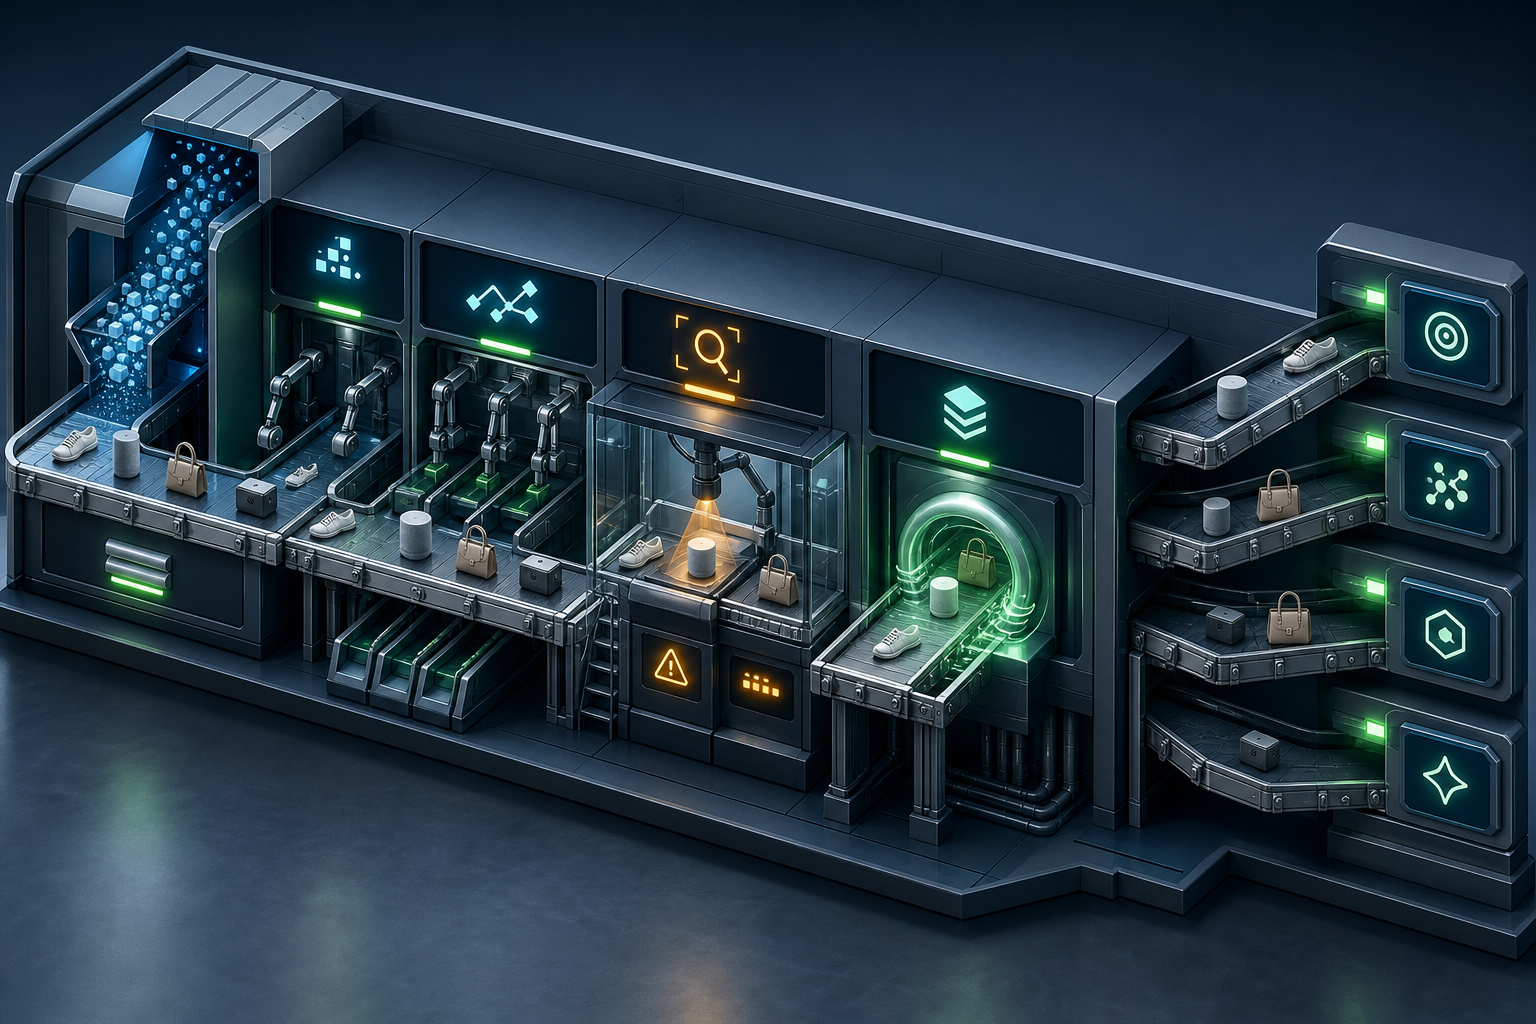
    Retail products move through an automated feed pipeline with sorting, quality checks, synchronization, and a gate that catches one delayed item.

    A retail campaign cannot advertise a product reliably if the advertising system cannot ingest, approve, or refresh its record. That makes the feed part of campaign delivery, not a back-office file owned exclusively by merchandising or development.

    The operational risk is real even when campaign settings have not changed. In one Merchant Center service disruption, the feed incident began on February 4, 2026, and was still under investigation in the February 20 status update. The available notice did not establish the cause, affected scope, or resolution time. That uncertainty is exactly why your monitoring has to distinguish platform availability from a defect in your own data.

    Map the feed pipeline as four separate states:

    1. Source state: The catalog, inventory, price, availability, destination URL, and other product data are correct in the system that owns them.
    2. Export state: The scheduled file, API process, or connector emits the expected records and completes successfully.
    3. Ingestion state: Merchant Center receives and processes the feed without an abnormal delay or unexpected drop in item count.
    4. Eligibility and delivery state: Products remain approved, current, and able to participate in the campaigns and free listings that depend on them.

    A green export job proves only the second state. It does not prove that Merchant Center processed the file, that products remained eligible, or that campaigns continued serving them.

    Use a feed incident protocol that preserves evidence

    When product delivery falls unexpectedly, capture the current state before making repairs. Save the feed completion time, processed item count, approval and disapproval pattern, affected product segments, campaign delivery change, and any platform status notice. Without that snapshot, a later recovery can erase the evidence you need to identify the cause.

    1. Check scope. Determine whether the problem affects the entire catalog, one market, one destination, one product type, or a recently edited segment.
    2. Check timing. Compare the first visible delivery change with the last successful source update, export, ingestion event, and platform notice.
    3. Check the status dashboard. A broad service notice does not prove your account has the same problem, but it changes the order of investigation.
    4. Inspect diagnostics. Separate delayed processing from new disapprovals, missing products, and stale price or availability data.
    5. Limit intervention. If the evidence points to a platform disruption, avoid rewriting a previously valid feed merely to force a refresh. That can introduce a second failure and make recovery harder to interpret.
    6. Validate recovery by layer. Confirm processing, item counts, approval status, campaign delivery, and business outcomes before releasing a backlog of unrelated feed changes.

    A platform incident usually has broad timing and multiple affected records. A local transformation problem is more likely to follow a catalog or connector change and affect a coherent subset. Normal feed diagnostics combined with falling spend point you back toward campaign eligibility, auction conditions, budgets, or demand. Do not pause an entire account simply because revenue fell; first establish whether the feed is actually the failing layer.

    Build reporting that can identify the failing layer
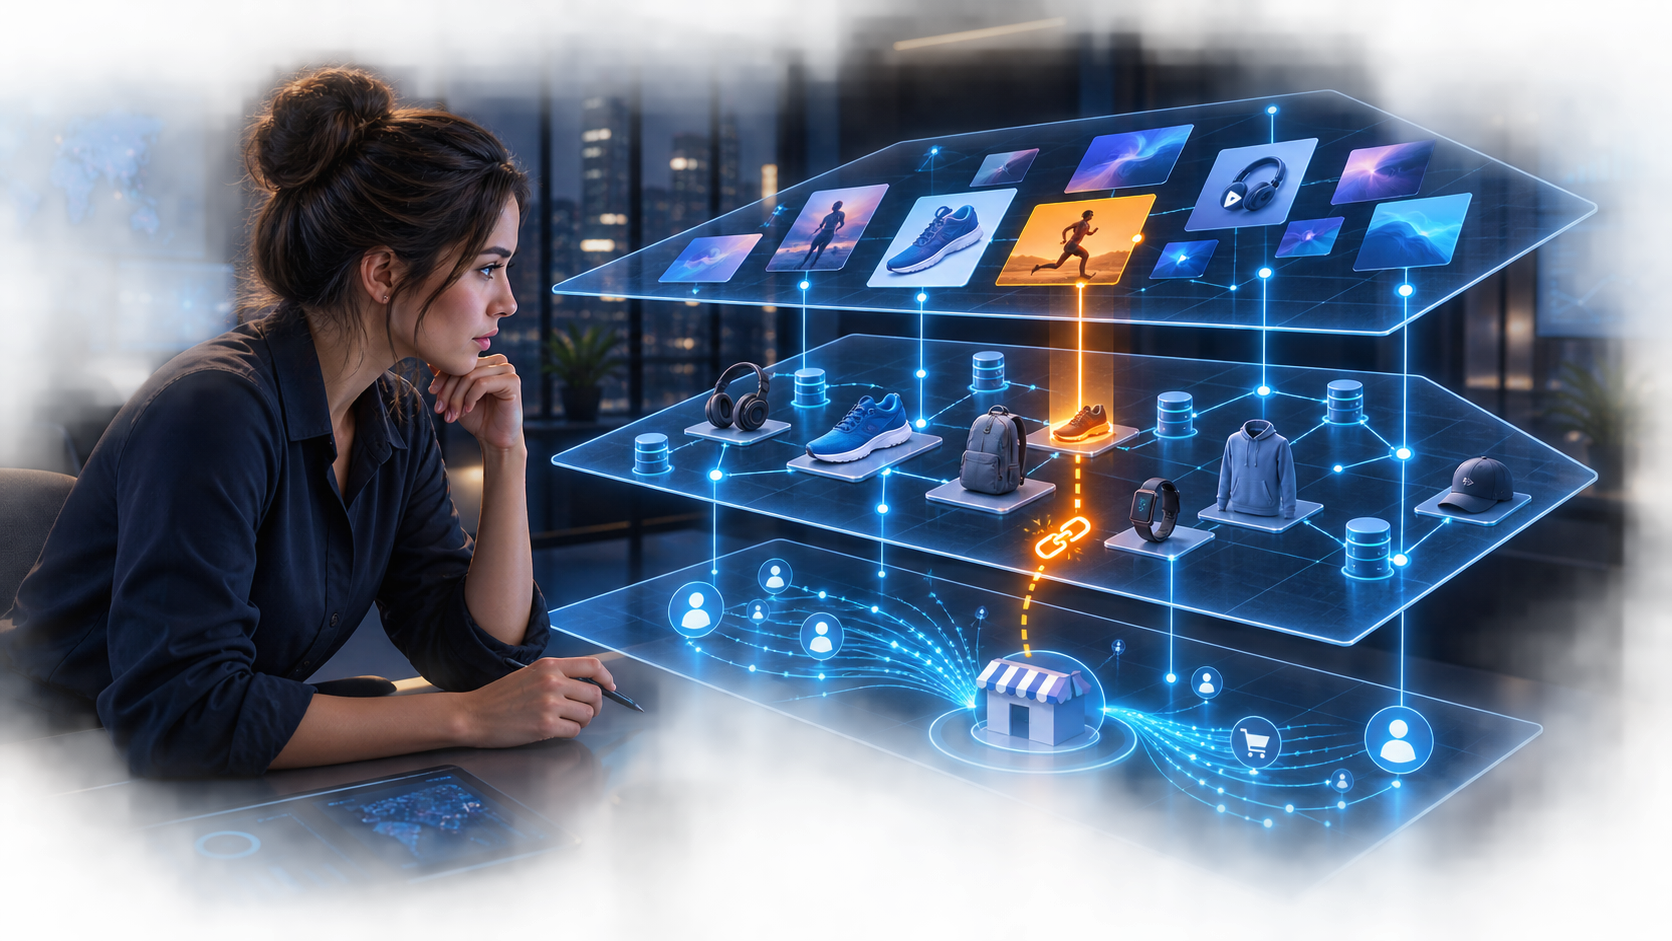
    An analyst traces an amber fault through stacked creative, product-feed, and conversion layers in a three-dimensional reporting system.

    A useful PPC dashboard does more than reproduce platform totals. It connects delivery to post-click behavior and business outcomes while making missing or delayed inputs visible.

    GA4 and Looker Studio solve different parts of that problem. GA4 uses an event-based model for website and app interactions. Looker Studio is designed to combine and present data, with connections to more than 800 data sources, calculated fields, blending, interactive controls, and scheduled report delivery. Neither should be treated as the sole owner of PPC truth.

    Assign ownership before you blend anything

    • Advertising platforms: Own impressions, clicks, spend, placement, bidding, and platform-attributed actions.
    • Merchant Center diagnostics: Own feed processing, product approval, and product-level eligibility evidence.
    • GA4: Own the configured view of sessions, engagement, events, and other website or app behavior after the click.
    • CRM or commerce systems: Own qualified leads, orders, realized revenue, and other downstream business states.
    • Looker Studio: Presents and calculates across those systems. It does not repair inconsistent definitions in the underlying data.

    GA4 can natively import cost, click, and impression data from additional advertising platforms, including Meta and TikTok, but strict UTM matching and limited campaign-name cleanup can constrain the result. Native ingestion reduces manual work; it does not remove the need for a campaign naming standard.

    Write the join plan before building charts. Specify the date grain, channel definition, account identifier, campaign identifier, creative identifier, currency, time zone, and conversion definition. Normalize labels in a controlled field rather than editing historical campaign names to make a chart look tidy. If two datasets have multiple rows for the same join key, aggregate them to the intended grain before blending; otherwise cost or conversions can be duplicated.

    Organize the dashboard around decisions

    A decision-grade PPC report needs four views:

    1. Outcome and pacing: Show spend against plan, primary outcomes, efficiency, and downstream value. If the monthly plan is intentionally linear, the expected spend point halfway through the month is 50% of the budget. If demand or promotions are not linear, replace that line with the actual spending plan rather than pretending uniform pacing is desirable.
    2. Delivery and feed health: Show changes in eligible products, product diagnostics, impressions, clicks, and spend together. This view tells you whether falling revenue began before or after the click.
    3. Creative performance: Display the actual visual beside its stable asset identifier, spend, click response, conversion result, and post-click quality. Looker Studio’s IMAGE function can place creative previews inside a report table, making the discussion about the asset rather than an opaque ad-group name.
    4. Waste and post-click quality: Surface spend with no recorded conversion above a threshold chosen for the account. Pair click response with engagement and lead quality so a high click-through rate cannot disguise a poor landing-page or audience match.

    Calculated fields should translate platform activity into business language. Profit can be calculated by subtracting cost from revenue, while ROAS can connect CRM revenue with advertising cost. Document which revenue state you use. Booked revenue, collected revenue, predicted value, and platform-attributed conversion value answer different questions and should not share an unlabeled metric name.

    Add a trust panel to every report. Include the last successful refresh, source coverage, reporting time zone, currency treatment, primary conversion definition, attribution scope, exclusions, and known incidents. A viewer should be able to tell whether a flat line means no activity or failed data retrieval.

    Keep performance observations separate from explanations. An annotation such as “cost per lead increased after the promotion ended” records a sequence. “Competitor aggression caused the increase” is a hypothesis unless you have supporting evidence. Labeling the difference protects the dashboard from turning a plausible story into an accepted fact.

    Complex dashboards also create a reliability problem of their own. Heavy use of GA4 widgets and concurrent views can run into API quotas. For demanding reporting environments, extracting GA4 data to BigQuery before connecting Looker Studio can reduce quota pressure and improve report performance. Before adding another chart, ask what decision it changes; fewer meaningful queries are easier to trust than a wall of fragile widgets.

    Use one operating sequence for every performance anomaly

    The same symptom can come from several layers. A revenue decline might begin with product eligibility, creative-message mismatch, landing-page behavior, tracking, lead quality, or actual demand. Use the earliest reliable evidence to decide where to investigate.

    What you noticeCheck firstWhat to do next
    Product impressions and spend fall suddenlyFeed processing, item counts, diagnostics, eligibility, and platform statusIsolate the affected product set and preserve the last known valid feed configuration while you identify the failing state.
    Delivery is stable but click response weakensAsset, format, placement, audience, and offer breakdownsReplace a weak component with a meaningfully different alternative while retaining stable winners.
    Clicks remain stable but engagement or leads deteriorateLanding-page behavior, conversion collection, page-message continuity, and audience qualityInvestigate the post-click path before changing bids or product data.
    Spend is ahead of planPlanned pacing, current demand, outcome quality, and budget configurationDecide whether the variance is productive before reducing delivery solely to match a straight line.
    Platform ROAS falls while recorded business revenue is stableAttribution scope, conversion definitions, join logic, and data refresh timingReconcile measurement before reallocating budget on the assumption that demand collapsed.
    Several dashboard charts flatten or fail togetherConnector refreshes, source credentials, API quotas, and source coverageRestore reporting reliability and mark the affected period instead of interpreting missing data as zero performance.

    Work from cause to consequence

    1. Availability: Can each required platform and connector process or return data?
    2. Eligibility: Are the intended ads, products, assets, destinations, and audiences allowed to participate?
    3. Delivery: Did impressions, clicks, spend, format mix, or product coverage change?
    4. Behavior: Did people engage with the landing experience and complete the configured events?
    5. Value: Did those actions become qualified leads, orders, revenue, profit, or another business outcome?

    Keep a decision log beside the dashboard. Record the observed condition, affected scope, evidence, working hypothesis, action, owner, and validation signal. Where practical, change only one causal layer at a time. If you rewrite the feed, replace the creative library, alter bids, and edit conversion definitions together, even a recovery will teach you very little.

    Start with the report you already use. Add its last refresh, feed status, spend against plan, primary business outcome, and known incident state. Then make your next optimization only after you can name the layer that failed. That small change turns PPC reporting from a record of what happened into a control system for what you do next.

    References


  • A Press Release Outreach Strategy That Earns Media Coverage

    A Press Release Outreach Strategy That Earns Media Coverage

    You published a legitimate announcement, the wire carried it, and the reporters you hoped would notice it stayed silent. The problem may not be the release itself. Distribution made your news available, but it did not give a particular journalist a compelling reason to cover it.

    Earned coverage requires a second system around the release: find the journalists already working on the relevant issue, connect your announcement to that work, and approach them with a usable follow-up angle. The release supplies the evidence. Your outreach supplies the editorial reason to act.

    Key takeaways

    • Research recent coverage before drafting the release, not after publication.
    • Build your media list around topic relevance and prior coverage rather than outlet prestige alone.
    • Use three to five genuinely useful citations in the release, then prioritize the journalists whose work you cited.
    • Personalize the editorial connection: what the journalist covered, what has changed, and what your announcement adds.
    • Treat each earned feature as a new outreach asset, not the end of the campaign.

    Build a coverage map before you build a media list

    An overhead coverage map groups anonymous reporter cards, story clippings, subject images, and colored connection threads around a central evidence folder.

    A conventional media list tells you who works at an outlet. A coverage map tells you why a specific person might care about your announcement. That distinction determines whether your pitch feels timely or merely targeted.

    Begin by reducing the announcement to a neutral sentence. Strip out promotional adjectives and ask what changed, who it affects, and why the change matters outside your organization. Then identify the adjacent topics that a newsroom could reasonably use to frame it. Depending on the announcement, those may include economic impact, enabling technology, legislation, market behavior, or the activity of major industry participants.

    Now work backward from the outlets where you want coverage. Review their coverage from the past quarter for your core topic and its adjacent themes. Recent work matters because it reveals the journalist’s active beat, preferred framing, and unanswered questions. A job title or an old staff biography cannot give you the same signal.

    Create a working tracker with a row for every relevant item you find. Record:

    • The outlet and journalist.
    • A link to the coverage and its publication date.
    • The central point, tension, or question it addressed.
    • The exact connection to your announcement.
    • The journalist’s current contact route.
    • Relevant social posts in which the journalist or their audience continued the discussion.
    • Your proposed follow-up angle.
    • The outreach status and eventual result.

    Do not add someone merely because they cover your industry. A broad industry match can still produce an irrelevant pitch. A journalist who covers financing is not automatically interested in a product integration; a policy reporter is not necessarily the right person for a leadership appointment. Prioritize the people whose recent work gives your announcement a natural place to go next.

    The strongest candidates usually satisfy several conditions at once: the topic is a direct match, the coverage is recent, your announcement adds something verifiable, and you can describe the continuation angle without stretching either piece of information. Put those candidates at the top. Save looser connections for later outreach rather than forcing them into the first wave.

    Make the press release useful inside the pitch

    A laptop with a blank message layout sits beside an announcement document, source materials, and a selected evidence photograph.

    A press release has two jobs in this workflow. It must explain the announcement accurately to anyone who reaches it, and it must support the specific claims you make in outreach. It is not a substitute for the pitch, and the pitch should not be required to make the release intelligible.

    Use the coverage map while drafting. Include three to five relevant citations where outside context helps the reader understand the issue. The links should clarify the market, establish the surrounding debate, or connect the announcement to an ongoing development. They should not exist merely to attract a journalist’s attention.

    That boundary matters. A citation acknowledges relevant work; it does not imply that the journalist endorses your organization, product, or claim. Never describe it that way. If the cited coverage does not materially improve the release, remove it. Empty recognition is easy to detect and gives the journalist no editorial reason to respond.

    A practical release structure is:

    <!– wp:list {
  • Google Ads Attribution and PMax Creative Automation Guide

    Google Ads Attribution and PMax Creative Automation Guide

    You have handed Google Ads two important jobs: decide which opportunities deserve your budget and assemble creative that can run across its inventory. The first job depends on when conversions reach the bidding system. The second depends on which images the system is allowed to reuse.

    Those controls are easy to manage separately and dangerous to ignore together. If app installs appear on a reporting date that does not match your Mobile Measurement Partner, you may make decisions from a distorted timeline. If an unsuitable landing-page image enters Performance Max, the campaign can distribute a message you never intended. You need one operating model for both the conversion signal and the creative supply.

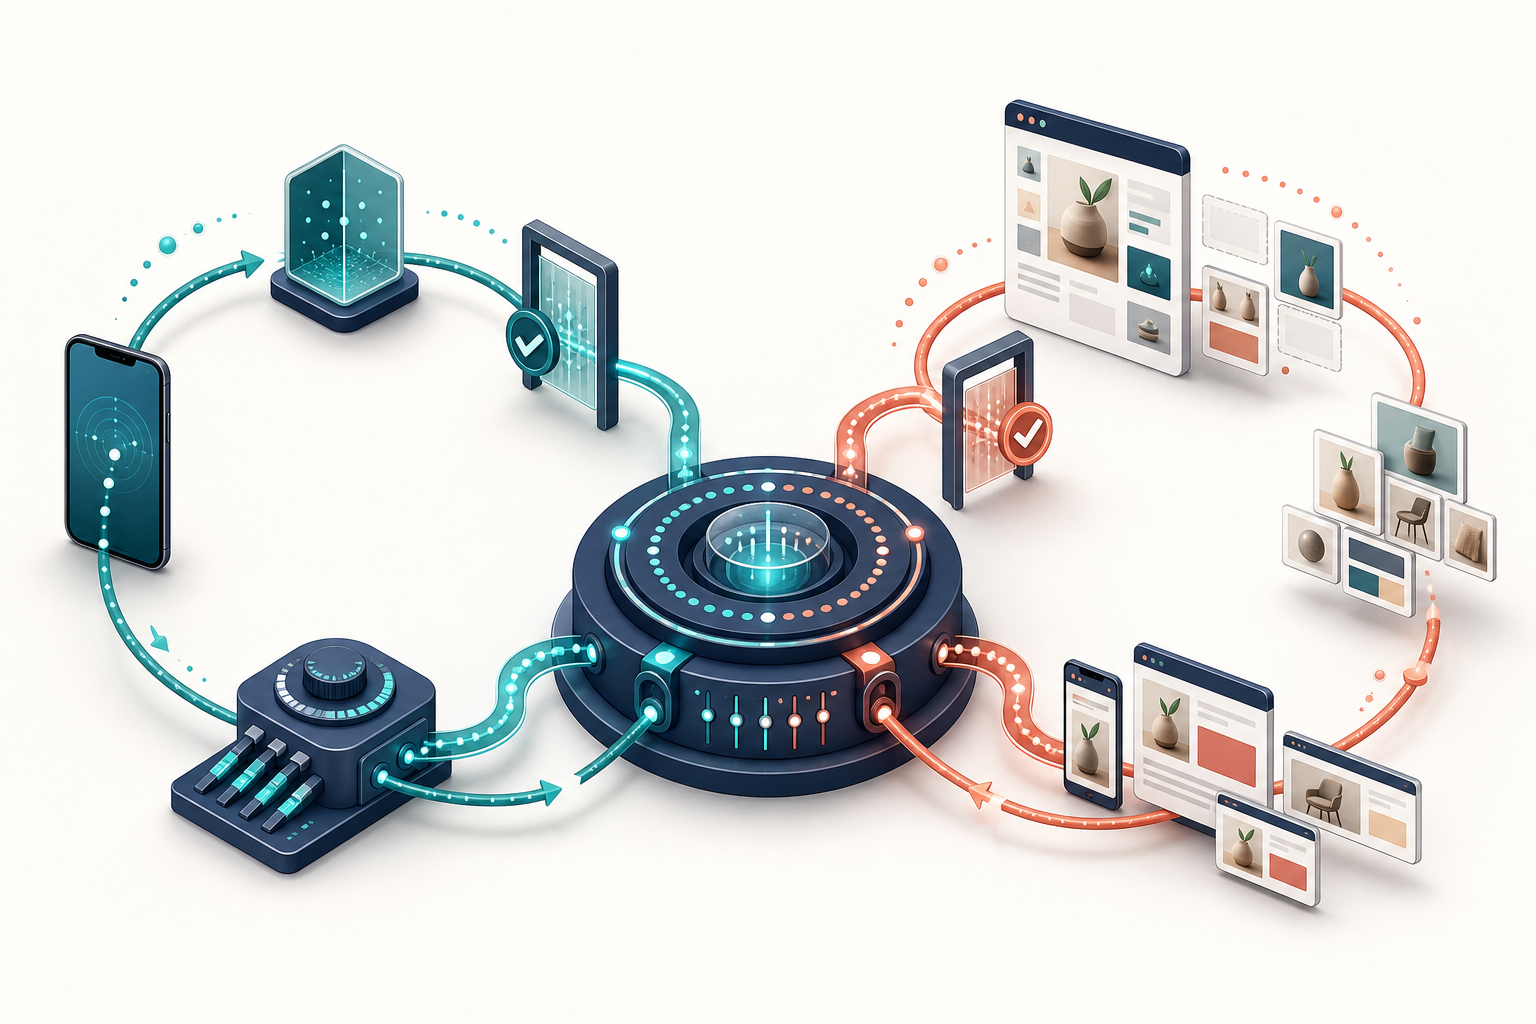
    Google Ads automation runs on two feedback loops

    The measurement loop starts with an ad interaction, continues through an app install, and ends when the conversion enters campaign reporting and informs bidding. Google now places app conversion credit on the install date rather than the date of the ad interaction. That brings the reporting timeline closer to the install-date view used by Mobile Measurement Partners such as AppsFlyer and Adjust.

    The creative loop starts on your website. When you opt into the relevant automation, Google can extract images from landing pages, turn them into PMax creative, and show you a preview before launch. Those visuals can then appear in ads across Search, Display, YouTube, and Discover.

    Each loop can fail independently. Accurate conversion timing will not rescue a misleading image. Strong creative will not fix delayed or inconsistently interpreted conversion data. A well-governed account therefore asks two different questions:

    Control areaQuestion to answerCommon misreading
    Conversion signalWhich date receives credit, and are Google Ads and the MMP being compared on the same basis?A reporting-date shift is treated as a sudden change in customer demand.
    Creative supplyWhich landing-page images may become standalone ads, and would you approve each one?A page image is assumed to be safe because it was originally designed for the website.

    The practical principle is simple: automation magnifies the quality of the inputs you give it. Your job is not to approve every automated decision manually. It is to make sure the system learns from the right event timeline and draws from a deliberate asset pool.

    Control the move to install-date attribution

    Abstract mobile conversion signals being reconciled between a later reporting timeline and earlier smartphone install points.

    Install-date attribution changes where a conversion appears on the reporting timeline. It does not, by itself, prove that more or fewer people installed your app. This distinction matters whenever you compare periods that use different attribution logic.

    Under the earlier approach, conversion credit was associated with the ad-interaction date. The default 30-day attribution window could leave important feedback separated from the day of the eventual install. Moving the credit to the install date gives Smart Bidding a fresher signal and may help its optimization cycle move faster. That is a potential operational benefit, not a guarantee that campaign performance will immediately improve.

    Do not confuse the conversion window with the credited date. The window determines which delayed outcomes can qualify after an interaction. The credited date determines where a qualifying outcome appears in reporting. Changing the second does not mean the customer journey itself became shorter.

    Audit the reporting boundary before changing bids

    1. Record the attribution boundary. Note when the account begins presenting app conversions by install date. Treat that point as a break in the reporting series rather than silently combining unlike periods.
    2. Confirm the event being compared. Match the same app, conversion event, date range, time zone, and inclusion rules in Google Ads and your MMP. Similar dashboard labels do not guarantee identical filters.
    3. Compare install cohorts, not just headline totals. If one system groups an install by interaction date and another groups it by install date, their daily charts can disagree even when they describe many of the same outcomes.
    4. Inspect timing before diagnosing demand. If a day looks unusually strong or weak around the change, check whether credit moved between dates before concluding that traffic quality changed.
    5. Keep other major changes separate when practical. Simultaneous changes to budgets, bidding goals, conversion definitions, and attribution logic make it difficult to identify what caused the next movement.
    6. Document any remaining discrepancy. Install-date alignment should reduce one important source of disagreement with AppsFlyer or Adjust, but it does not establish that every dashboard total must match. Keep investigating differences in event definitions and filters rather than forcing a false reconciliation.

    Most advertisers should resist reacting to the first daily swing. Review the timing of credit first. Once you know that both systems are looking at the same install cohort, you can judge whether the campaign itself changed.

    This is also the right moment to inspect the account’s attribution-window setting instead of assuming the default is appropriate. Many advertisers leave the 30-day setting untouched. That may be acceptable, but it should be a documented choice connected to the way people actually move from an ad interaction to an install.

    Treat every PMax landing page as a creative library

    An unbranded landing page supplying image cards to ad placements through a gate that filters unsuitable creative assets.

    A landing page used to have one obvious job: persuade the visitor who arrived there. In an automated PMax workflow, it can also supply images for ads. That turns website publishing into part of campaign production.

    The distinction matters because an image can work well inside a page and fail when separated from it. A banner may rely on a nearby heading for context. A product photo may need a caption to distinguish the model. A promotional image may remain online after its offer has expired. A decorative visual may be harmless on the page but confusing as the main element of an ad.

    Before allowing Google to use landing-page images, audit each campaign destination as if it were an asset folder:

    • List every meaningful image. Include hero images, product shots, promotional banners, lifestyle photography, diagrams, badges, and supporting graphics. Do not review only the image you expect Google to choose.
    • Apply the standalone test. Look at the image without its heading, caption, navigation, or surrounding copy. If its meaning changes or disappears, revise it before treating it as ad inventory.
    • Check commercial accuracy. Remove or replace visuals with expired offers, outdated packaging, old product interfaces, unavailable variants, or unsupported claims.
    • Check placement resilience. Search, Display, YouTube, and Discover provide different surrounding contexts. Keep the central subject and intended message understandable without depending on the original page layout.
    • Protect the brand boundary. Decide whether the image is current, recognizable, and appropriate for paid distribution. Website publication should not automatically equal advertising approval.
    • Preview the automated output. Use the available preview before the creative goes live. Review what Google assembled, not merely the original image in your media library.
    • Resolve weak assets at the source. If a preview reveals an unsuitable image, update or remove it from the page, or keep the automation disabled until the page is ready. Do not knowingly feed an unsafe asset into the system and hope it receives little delivery.

    A page can be an effective destination and still be a poor creative library. It may contain useful navigation graphics, dense explanatory diagrams, or temporary banners that help an on-page visitor but should never represent the campaign. Judge page performance and asset eligibility as separate questions.

    Set an approval rule your team can repeat

    A simple three-state decision prevents subjective reviews from dragging on:

    • Approve: the image is current, accurate, on-brand, and understandable without nearby page copy.
    • Revise: the concept is usable, but the image depends on context, contains dated information, or does not represent the destination clearly enough.
    • Hold: the image could misstate an offer, show an unavailable product, create a compliance problem, or damage brand recognition if distributed as an ad.

    Assign an owner to that decision. The person who publishes a web page may not own paid-media approval, and the media buyer may not know when a product image becomes outdated. Without an explicit handoff, landing-page automation creates an invisible gap between the web and advertising teams.

    Use one workflow for measurement and creative control

    The cleanest operating routine reviews the conversion signal and the asset supply before asking PMax or Smart Bidding to do more. You can use the following sequence for a new campaign, an attribution change, or a landing-page refresh:

    1. Name the outcome. Identify the app conversion that represents success and should inform bidding. Avoid letting a convenient but secondary event stand in for the outcome you actually value.
    2. Define its timeline. Record whether Google Ads displays that conversion on the interaction date or install date, and write down the comparison basis used in your MMP.
    3. Mark measurement changes. Keep an account note or change log whenever attribution treatment, conversion definitions, or inclusion rules change. Future reviewers need to know why two periods may not be directly comparable.
    4. Map the destinations. List the landing pages connected to the PMax campaign. Include pages added through later campaign or site changes, not only the original destination.
    5. Classify the visual inventory. Give every relevant landing-page image an approve, revise, or hold status. Record who made the decision and what would require another review.
    6. Inspect the preview. Review the creative Google proposes before launch. Make sure the result still represents the product, offer, and destination accurately when removed from the page.
    7. Change one major layer at a time when possible. If attribution, bidding, budgets, landing pages, and asset automation all change together, the next performance movement will be hard to interpret.
    8. Review in two lanes. In the measurement lane, check counts, credited dates, and MMP alignment. In the creative lane, check which imagery was assembled and whether it remains suitable. Do not let a strong result in one lane conceal a control failure in the other.

    This workflow also gives you a faster diagnostic path. If Google Ads and the MMP disagree by day, inspect attribution timing before changing the campaign. If an unexpected image appears in a preview, inspect the destination page before rebuilding the whole asset group. If bidding behavior changes after the attribution update, determine whether the algorithm received a fresher event timeline before attributing the movement to new audience demand.

    Keep a compact control record for each campaign: the primary conversion, its credited date, the MMP comparison basis, the eligible landing pages, the status of their images, the latest preview review, and any unresolved exceptions. That record is more useful than a generic statement that automation is enabled because it tells the next person exactly what the system can learn and what it can show.

    Key takeaways

    • Install-date attribution changes the reporting timeline; it does not automatically mean install demand changed.
    • Compare Google Ads with AppsFlyer or Adjust using the same install cohort, event definition, date range, time zone, and filters.
    • Fresher conversion signals may help Smart Bidding learn more quickly, but cleaner attribution is not a performance guarantee.
    • An opted-in PMax landing page is also a potential creative library, so every meaningful image needs an advertising review.
    • Preview extracted images before launch and fix unsuitable assets at the landing-page level rather than accepting avoidable surprises.
    • Manage conversion timing and creative eligibility in one change log so you can separate measurement shifts from campaign shifts.

    Start with one app campaign and one PMax campaign. For the app campaign, document the credited conversion date and compare the same install cohort in your MMP. For PMax, open every active destination, classify its images, and inspect the automated preview. Resolve those inputs before you use a reporting swing to justify new budgets or bidding targets.

    As Google takes on more bidding and creative decisions, your durable advantage is a cleaner contract with the automation: this is the event that matters, this is when it receives credit, and these are the assets we are prepared to distribute.

    References

  • Reddit Unveils AI-Powered Shopping Boost in Search Results

    Reddit Unveils AI-Powered Shopping Boost in Search Results

    I find Reddit’s new pilot program fascinating. They’re using AI to transform our beloved community recommendations into interactive, shoppable product carousels within search results.

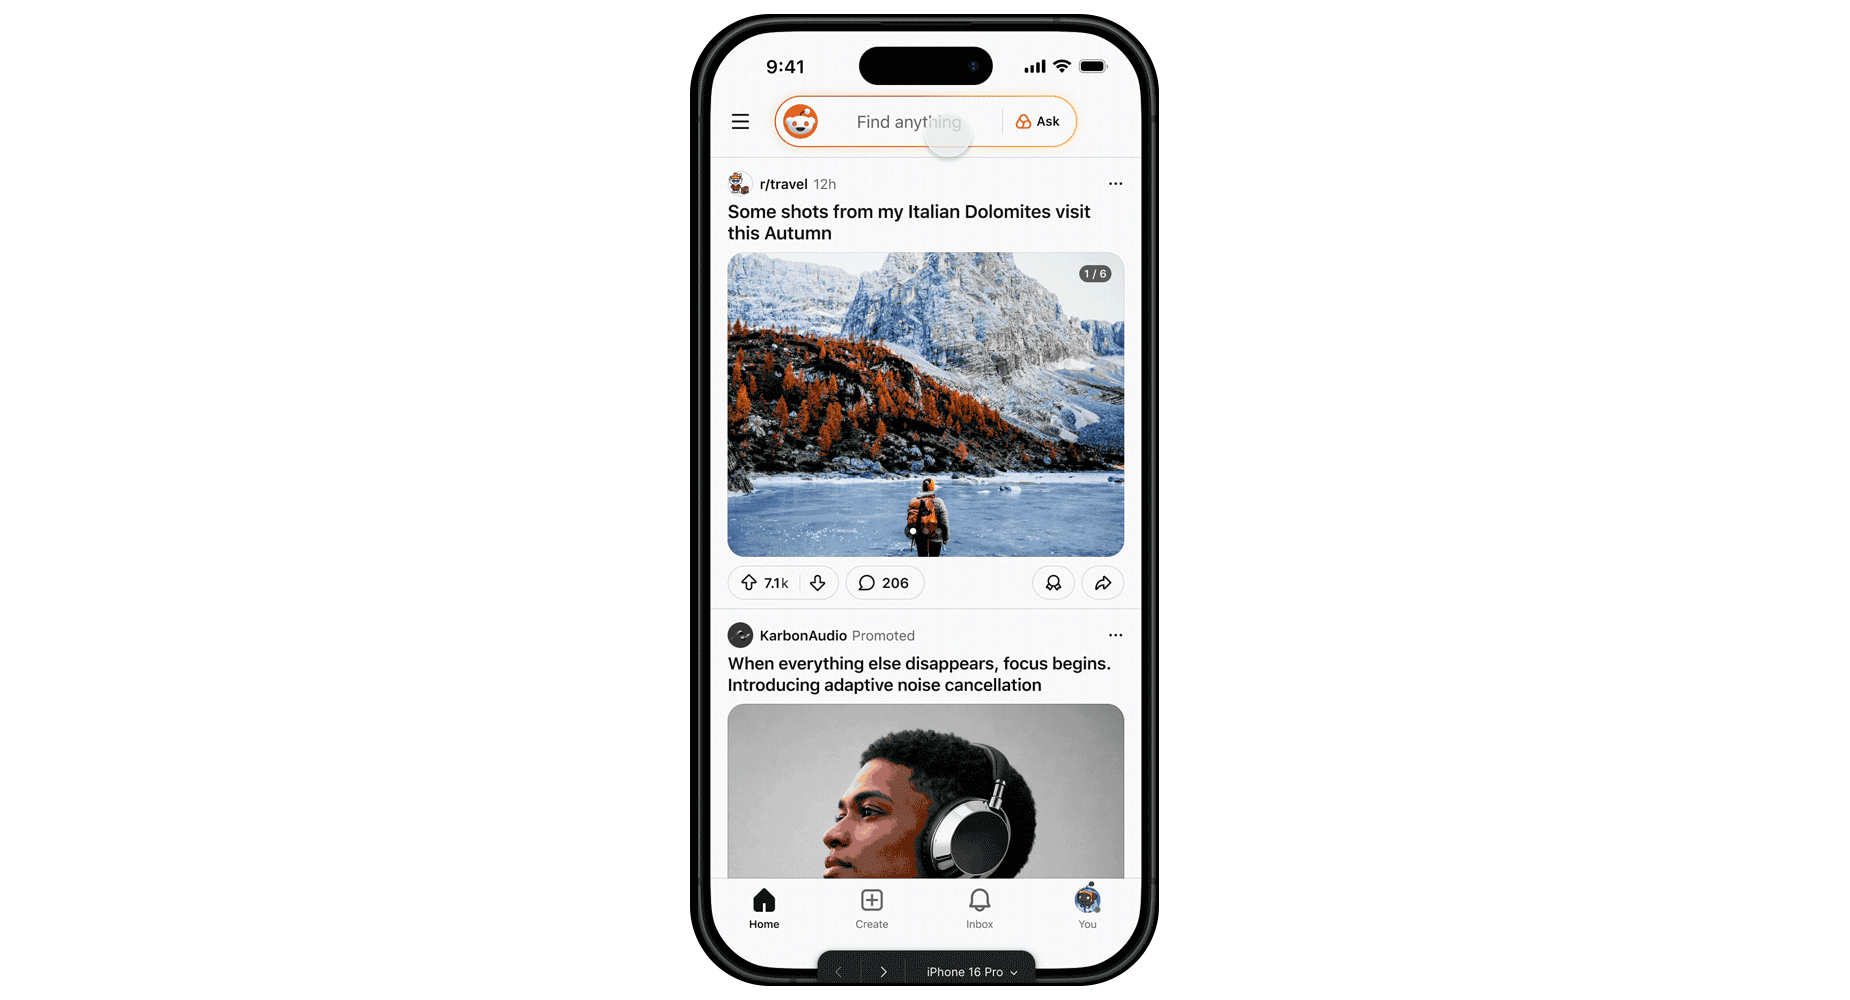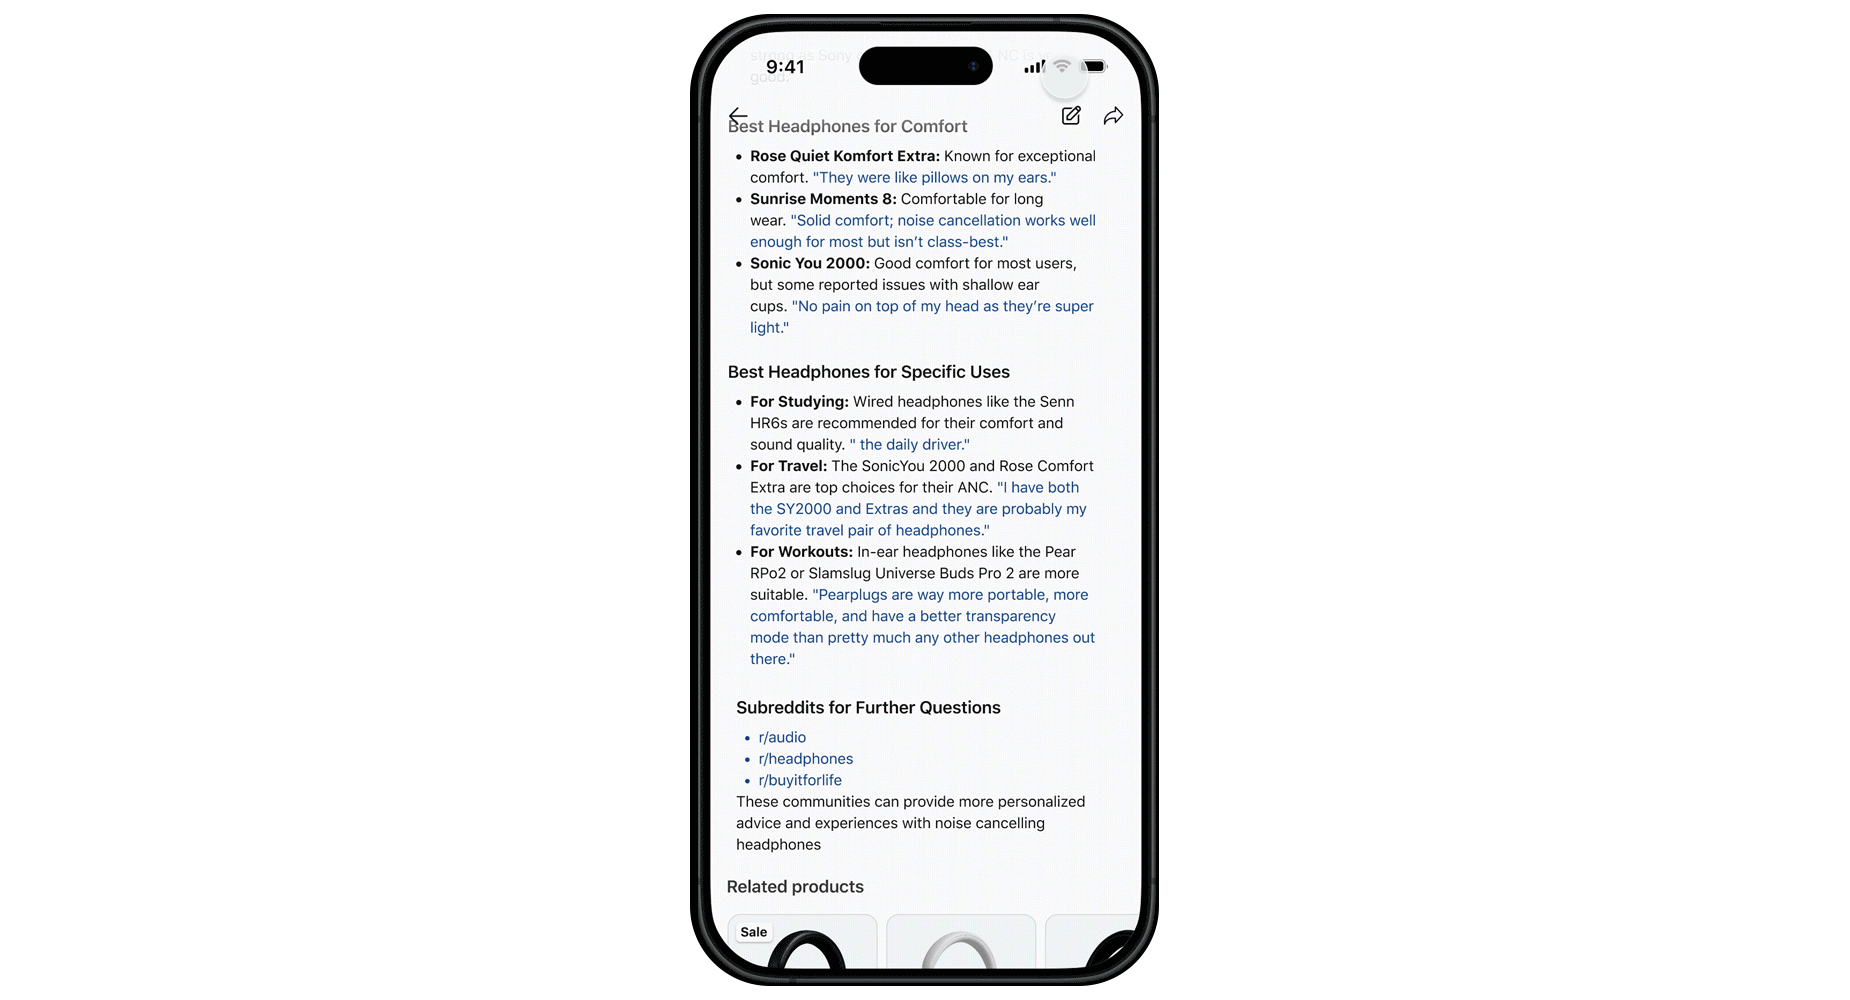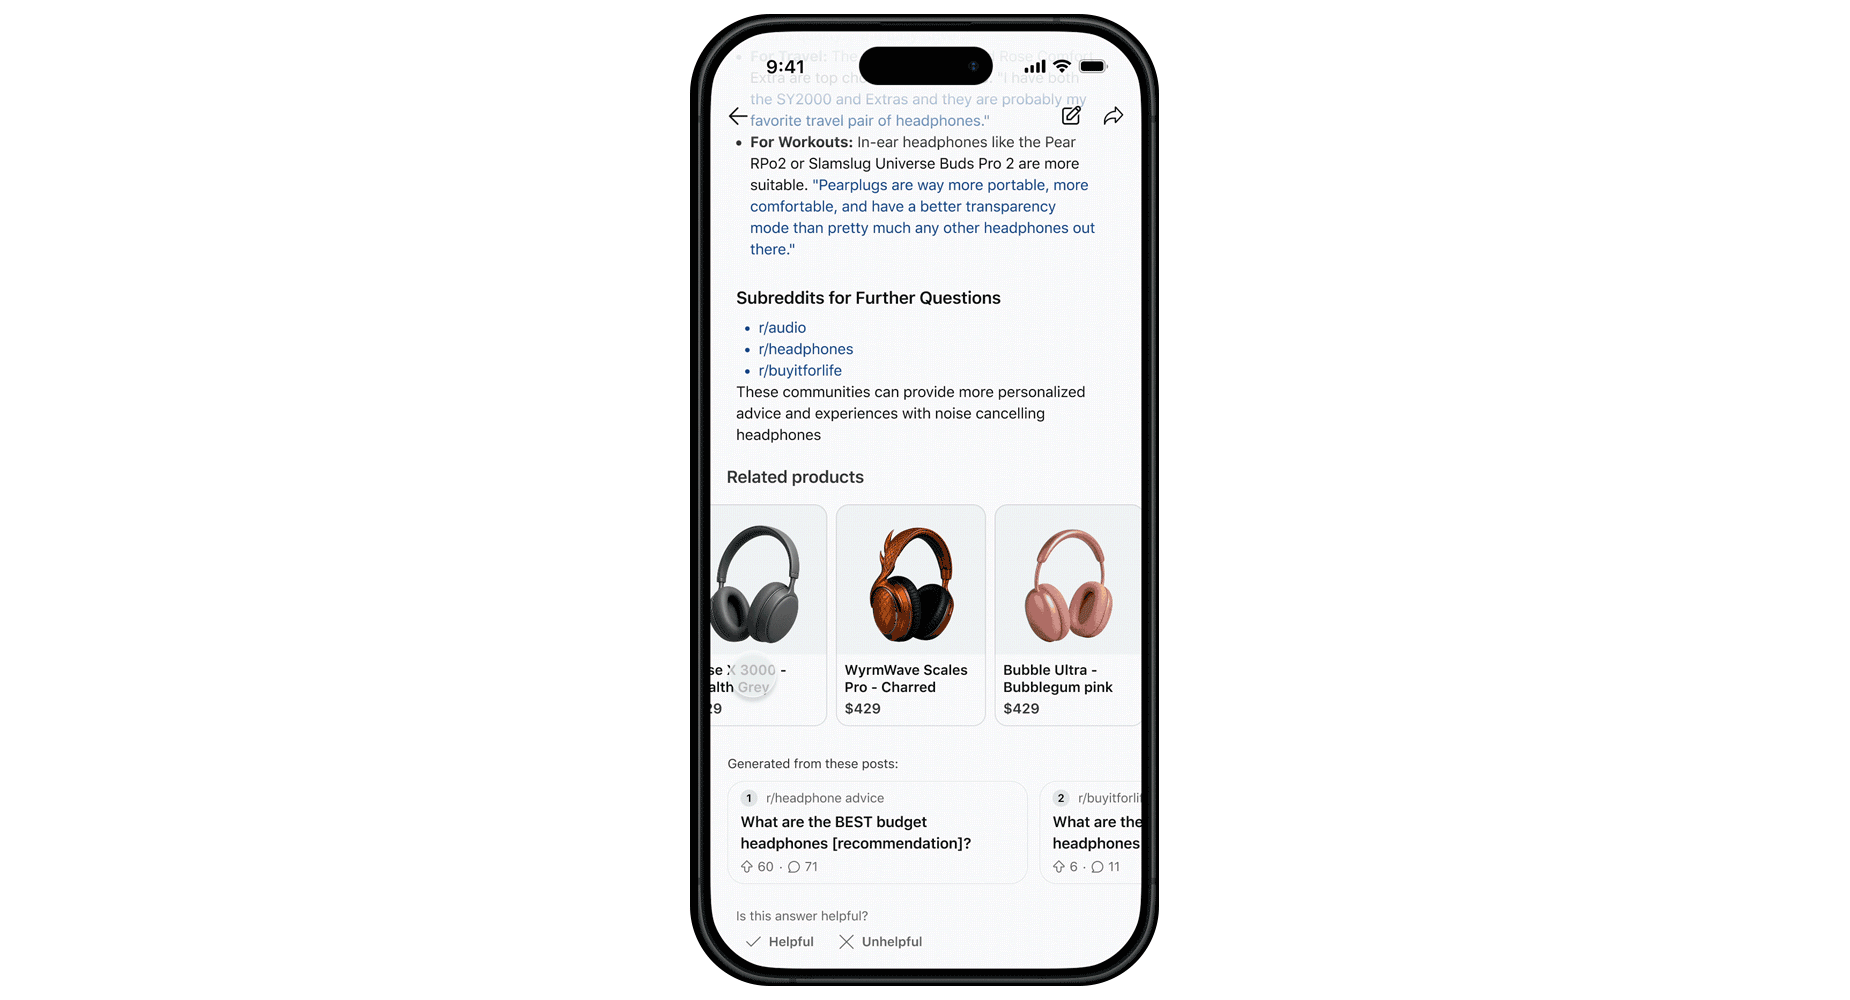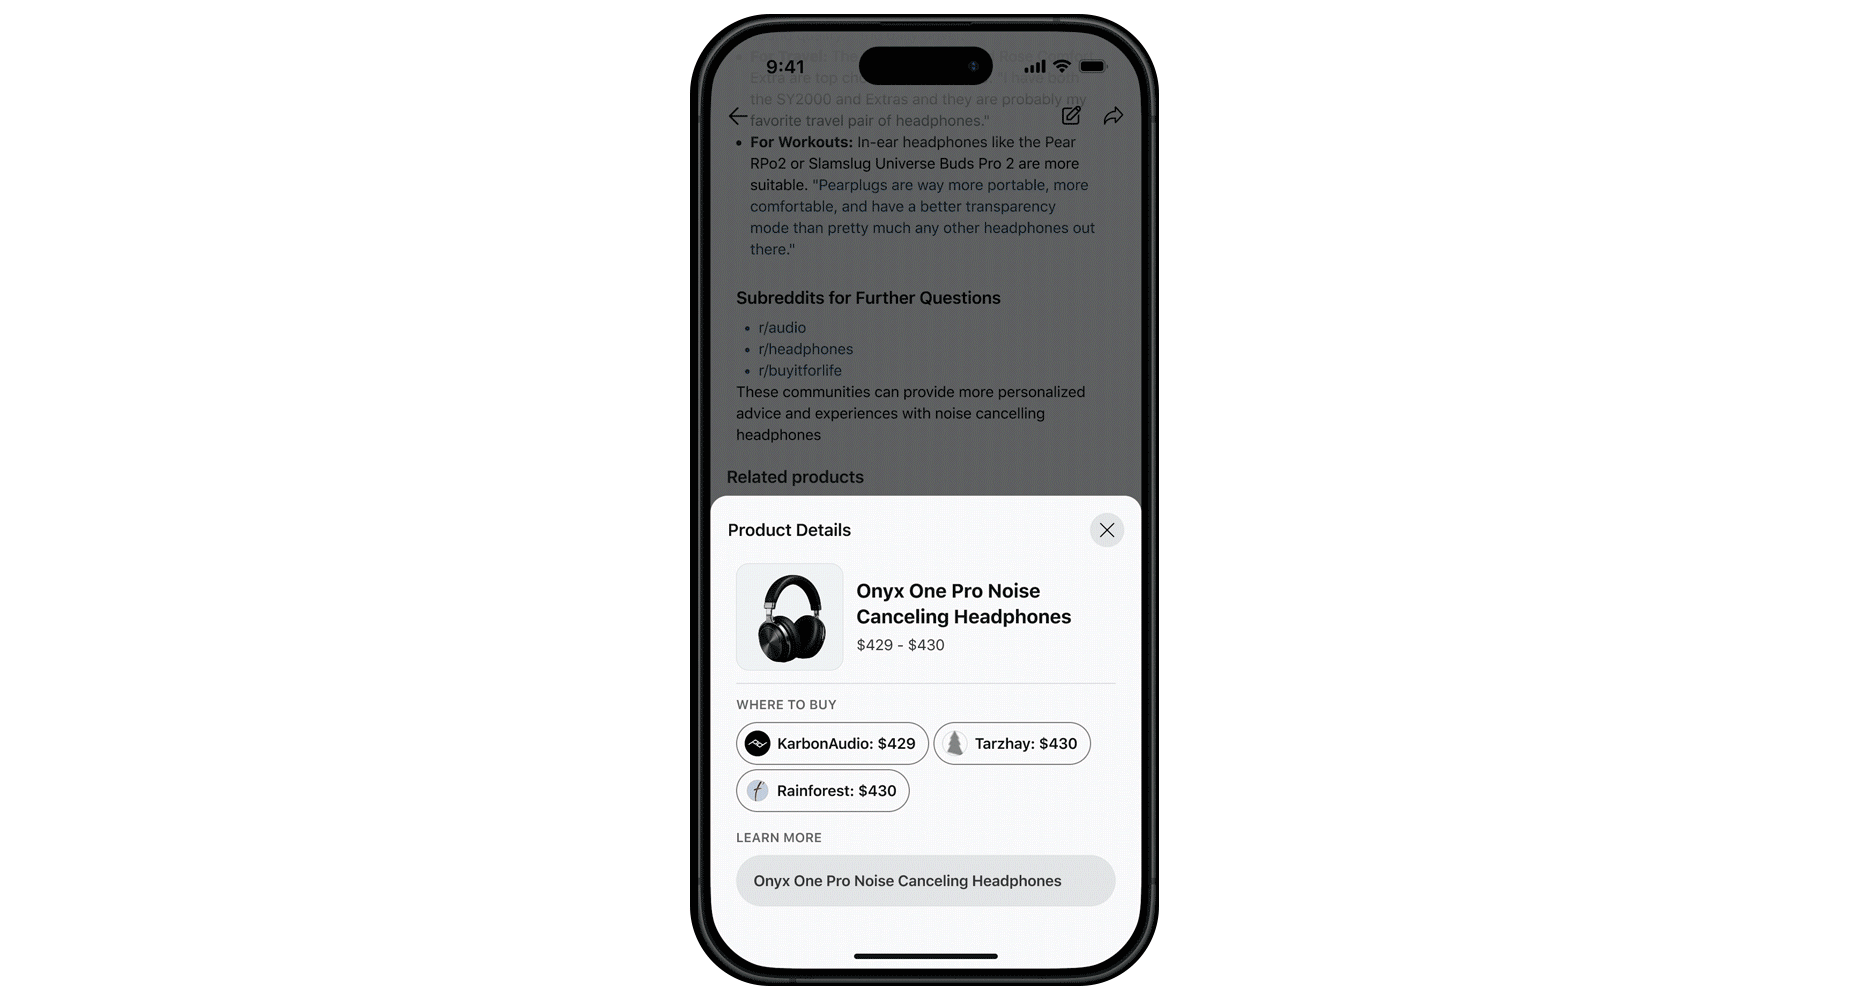
    What’s happening: Right now, a select group of U.S.-based folks, including myself, might notice these exciting product carousels popping up in search results whenever our queries suggest a buying intent, like when searching for “best noise-canceling headphones” or “top budget laptops.”

    These carousels conveniently appear right at the bottom of the search results, showcasing pricing, images, and direct links to retailers. The coolest part? These products are derived from actual Reddit posts and comments rather than existing ad inventories.

    For those of us interested in consumer electronics, Reddit also collects data from specific Dynamic Product Ads (DPA) partner catalogs.

    How it works: The AI cleverly identifies queries with purchase intent, scans through relevant Reddit discussions for any product mentions, and arranges them into tidy, shoppable cards. When a card catches my attention, I can simply tap it to gain more information or be redirected to a retailer.

    Why we care: These shopping carousels are a real game-changer for advertisers. They bring products to the spotlight right when consumers, like me, are contemplating a purchase and seeking peer approval. Unlike typical ads, here these products merge with Reddit’s trusted community vibe, making them seem more like genuine recommendations than mere advertisements.

    For brands already involved in Dynamic Product Ads on Reddit, this development offers a seamless pipeline from community buzz directly to action.

    ```json
{
  "alt": "Smartphone display showing a Reddit app post of a person in front of snowy mountains.",
  "caption": "Explore stunning vistas through the lens of a traveler! Dive into breathtaking shots of the Italian Dolomites as shared on Reddit.",
  "description": "The image shows a smartphone screen displaying a Reddit app interface. A highlighted post from the travel subreddit features a photograph of a person standing in front of a landscape with vibrant autumn foliage and majestic snowy mountains, identified as the Italian Dolomites. The post has 7.1k upvotes and 206 comments, showcasing significant engagement. Below, a promoted ad for noise-cancelling headphones is visible. The interface also displays elements like search bar and navigation icons, illustrating typical usage of a social media app."
}
```

    Between the lines: Reddit is really onto something big here, doing what many competitors have struggled to achieve—using organic, community-driven content as the foundation for a shopping experience, rather than depending solely on targeted advertising.

    This approach is ingenious because consumers, myself included, are becoming warier of sponsored content. Reddit’s value relies on authentic community engagement, and by integrating that into a shopping feature, it elevates their credibility beyond traditional retail media networks.

    The big picture: Retail media is booming, and platforms catering to audiences with high purchase intent are in a race to claim their portion of the pie. With Reddit’s increasing search traffic, especially after partnering with Google, this development seems like the perfect next step.

    The bottom line: Reddit is testing how it can turn search intent directly into transactions, making it smoother for users like me to transition from recommendations to purchase, all while staying within the community context that fosters trust.

    Dig deeper: Check out the official statement on Reddit’s innovative shopping experience: In Case You Saw It: We are Testing a New Shopping Product Experience in Search


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • ChatGPT Ads: How to Unify SEO and PPC Around Prompts

    ChatGPT Ads: How to Unify SEO and PPC Around Prompts

    If your SEO team plans around rankings while your paid team plans around keyword auctions, ChatGPT ads create an immediate coordination problem. The same user can now encounter an AI-generated recommendation and a sponsored placement inside one conversational experience.

    You do not need to merge two departments or move an entire budget to respond. You need one shared map of prompt-level demand, a clear view of organic and paid coverage, and landing pages that continue the specific decision the user was making.

    Treat the prompt as the shared unit of demand

    Do not build your plan on the assumption that ads appear only after a long conversation. Early observations found sponsored placements appearing after a single intent-driven prompt. Those observations were limited to signed-in desktop users in the United States, so they show an emerging format rather than a universal rollout or permanent specification.

    That limited evidence is still enough to change how you organize demand. A user does not have to type a compact search term such as best CRM. A prompt can include the category, company type, size, required integration, budget sensitivity, and intended use in one request. Each qualifier can affect whether your offer is relevant.

    Start by separating a valuable prompt into its working parts. For a request such as What is the best CRM for a B2B SaaS company under 50 employees that integrates with HubSpot, the root topic is CRM. The fanout keywords are the contextual qualifiers embedded in the request: B2B SaaS, under 50 employees, and HubSpot integration. These details are not decorative long-tail language. They describe the conditions under which the recommendation must be useful.

    Build your prompt inventory with this sequence:

    1. Collect prompts associated with actual buying questions. Use customer language from search queries, sales calls, support tickets, on-site search, and any LLM visibility monitoring you already run.
    2. Group paraphrases by decision, not by exact wording. Best CRM for a small SaaS team and CRM for a SaaS startup with fewer than 50 people may belong to the same cluster if they require the same answer and destination page.
    3. Extract the root need and every meaningful qualifier. Typical qualifier types include audience, organization size, use case, compatibility requirement, constraint, and decision stage.
    4. Remove variants your business cannot serve. Prompt volume is irrelevant when the requested integration, geography, price level, or use case makes your offer a poor fit.
    5. Assign one plain-language intent label to the surviving cluster. That label becomes the shared reference for SEO analysis, paid targeting, creative, landing pages, and reporting.

    This prevents a common mistake: expanding a familiar keyword list with more words and calling it prompt intelligence. A real prompt map preserves the conditions that determine whether the answer is relevant.

    Create one coverage map for organic and sponsored visibility

    Two pairs of hands arrange teal and amber tokens together on a grid of blank translucent planning tiles.

    Once you have prompt clusters, audit both surfaces against the same list. Organic visibility means that the generated answer includes your brand, product, page, or supporting evidence in a relevant way. Sponsored coverage means that your campaign can address that context and, where observable, that a sponsored placement appears.

    Keep unknown separate from absent. If your organization does not have access to ChatGPT ad controls, or if delivery is limited by account, device, or location, you cannot conclude that a prompt has no commercial inventory. Record the scope of every observation instead.

    Organic answer visibilitySponsored coverageWorking interpretationNext move
    PresentMissing or unavailableYour brand has contextual relevance, but there is no observed paid reinforcement.Protect the content and evidence supporting that visibility. Test paid coverage only when access and economics justify it.
    AbsentPresentAn ad can capture attention, but the generated answer does not independently validate the brand.Keep the paid test accountable while improving the page content and evidence needed to address the prompt.
    PresentPresentOrganic and sponsored surfaces may participate in the same decision.Test incremental value. Do not assume that two appearances automatically produce a better business result.
    AbsentAbsent or unknownThe cluster is unserved, inaccessible, or not yet prioritized.Validate customer fit and the conversion path before creating content or assigning budget.

    The map should be owned jointly, even if execution remains specialized. SEO can diagnose answer visibility, citation patterns, entity clarity, and content gaps. Paid media can manage eligibility, targeting, creative, bids, spend, and campaign controls. Neither team should privately redefine the prompt cluster or send users to a different interpretation of the need.

    A practical shared workflow looks like this:

    1. Agree on the prompt cluster and the commercial question it represents.
    2. Run representative prompts and log whether the brand appears, why it is relevant, and which page or evidence supports the appearance.
    3. Audit paid coverage for the root need and its important qualifiers when campaign access permits it.
    4. Prioritize intersections: valuable prompts with an organic gap, a paid gap, or a poor destination-page match.
    5. Assign one owner for the cluster-level result, while keeping channel specialists responsible for their controls.

    Repeat representative prompt checks rather than treating one response as a permanent ranking. Log the exact prompt, date, account state, device, location, generated answer, cited pages, sponsored placement, and destination URL. This gives you an auditable observation instead of a screenshot detached from its conditions.

    Build landing pages for the complete decision context

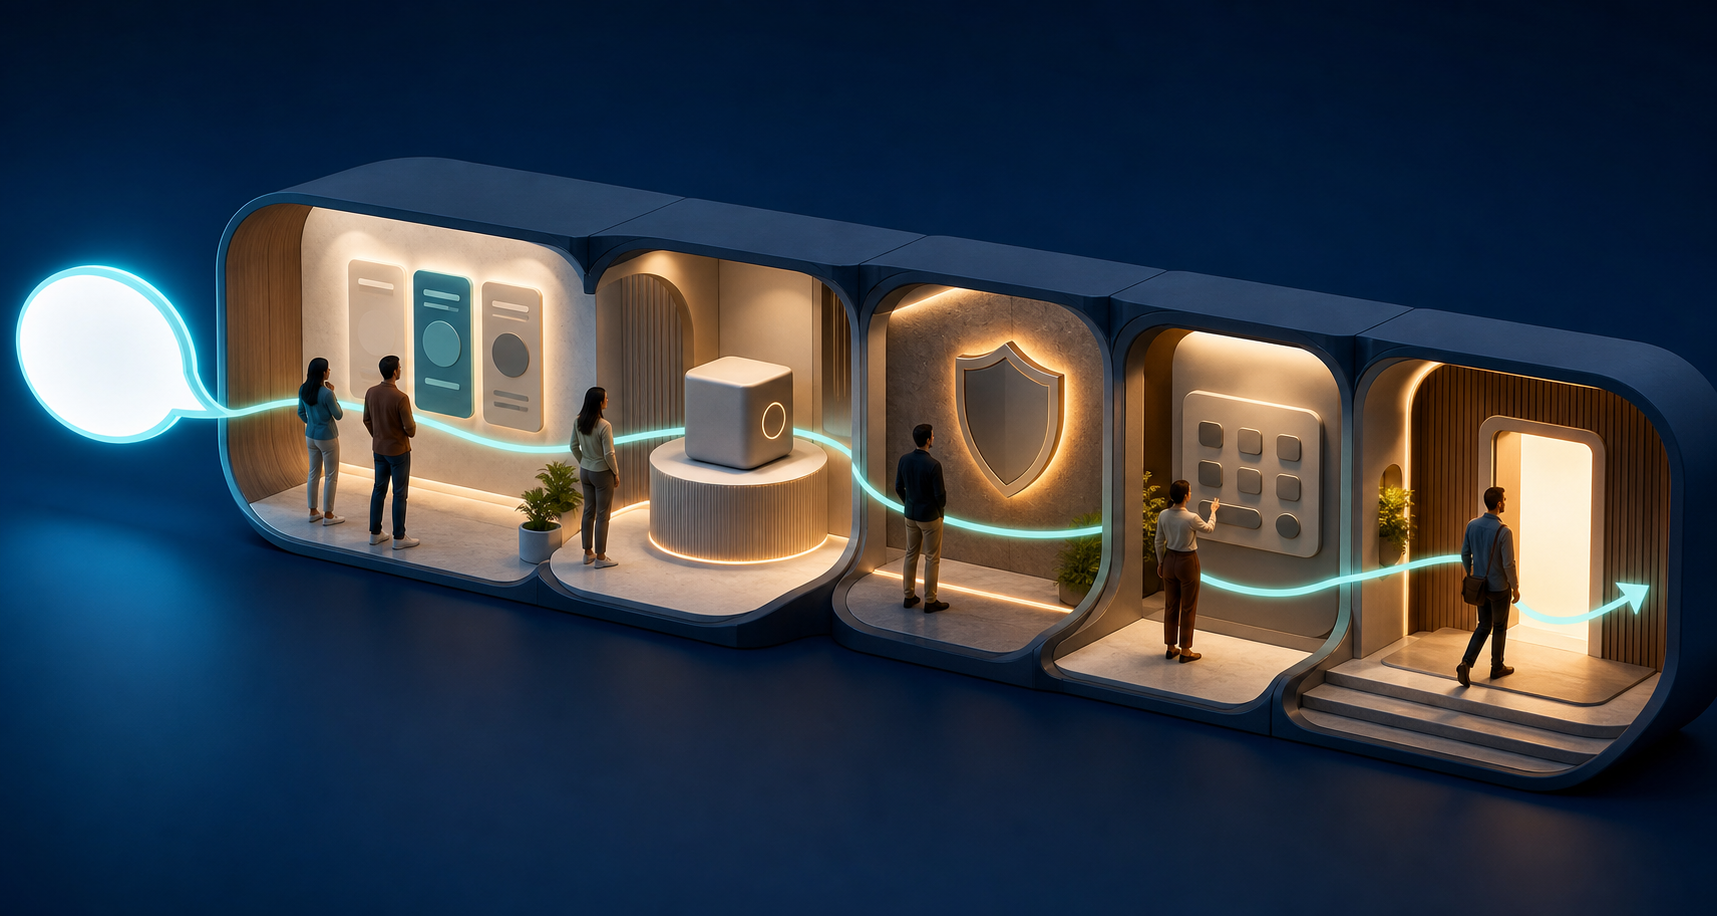
    Visitors move from a glowing conversation bubble through connected landing-page spaces for comparison, demonstration, trust, calculation, and action.

    A context-rich ad followed by a generic landing page breaks the conversation. If the prompt asks about a CRM for a small B2B SaaS company with a specific integration, a destination that merely announces CRM software forces the visitor to reconstruct the answer alone.

    The landing page should resolve the questions that remain after the AI response. Use a brief with five required elements:

    • A heading that names the relevant use case and audience without pretending to support conditions the product cannot meet.
    • A qualification block that states who the offer is for, who it is not for, and which constraints matter.
    • Specific compatibility or integration details, including limitations that could change the buying decision.
    • Visible evidence for important claims, such as product documentation, concrete capabilities, policies, or appropriate customer proof.
    • A next action that fits the decision stage. A user comparing options may need detailed evaluation material before being asked to buy or book a call.

    Create one strong page for a meaningful decision context, not a thin page for every prompt paraphrase. The test is whether two prompts require materially different claims, evidence, or next steps. If the answer is no, they belong on the same page.

    SEO and paid teams should review that page together. Paid media can identify where the message loses continuity between prompt, ad, and destination. SEO can make sure the page explains the subject with enough clarity and substance to be understood outside the campaign. Clearer, context-matched pages support both conversion and accurate recognition by language models, which is why the destination is shared infrastructure rather than a channel-specific asset.

    If you use structured data, apply it only to facts that are visible and supported on the page. Markup can clarify existing information; it cannot repair vague copy, supply missing proof, buy an ad placement, or guarantee inclusion in a generated answer.

    Measure the journey without collapsing distinct signals

    Converged planning does not mean organic and paid performance become the same metric. Keep four layers separate, then connect them through the prompt-cluster identifier:

    • Answer visibility: whether the brand appears in a relevant generated response, what role it is given, and which evidence or pages are cited.
    • Sponsored delivery: whether a clearly labeled placement appears, which message is used, and where the click leads.
    • Landing-page behavior: whether visitors continue the task represented by the prompt, reach key information, and complete the intended action.
    • Business outcome: whether the cluster produces qualified leads, purchases, retained customers, or another result your organization already treats as valuable.

    Where campaign and URL controls allow it, carry the shared cluster label into campaign naming, destination parameters, analytics, and reporting. The label should describe the decision context rather than the channel. This lets you compare CRM for small SaaS teams across answer visibility, ad delivery, landing behavior, and outcomes without pretending that every prompt wording is a separate market.

    Do not use sponsored presence as a proxy for organic authority. In the documented format, ads appear beneath the response with a Sponsored label, and the paid placement remains separate from the generated answer. Buying exposure therefore does not fix an inaccurate answer, earn a citation, or make the underlying page more persuasive.

    Likewise, do not call every organic mention incremental value. If the brand already appears in the answer and an ad also appears, only a controlled comparison can tell you whether the sponsored placement added a worthwhile result. Use the strongest control the available platform and your traffic permit. If a controlled split is unavailable, label a time-bounded pilot as directional and avoid presenting a before-and-after change as proof of causation.

    Use the evidence to make a cluster-level decision:

    • If the ad attracts relevant visitors but the brand is absent from the answer, keep paid performance accountable while repairing the organic content and evidence gap.
    • If both surfaces are present but the ad adds no measurable value in a valid test, do not keep paying merely to maximize visual coverage.
    • If visitors arrive but cannot confirm the qualifier that triggered their interest, fix the destination before increasing spend.
    • If neither surface is present and the prompt does not represent a customer you can serve well, deprioritize it instead of manufacturing content for theoretical visibility.

    Key takeaways

    • Plan for commercial intent from the first prompt; do not assume a long conversation must happen before an ad can appear.
    • Use prompt clusters, not isolated keywords, as the common planning unit for SEO, PPC, content, landing pages, and measurement.
    • Extract fanout qualifiers such as audience, company size, use case, constraint, and integration because they determine whether an offer actually fits.
    • Track organic visibility, sponsored delivery, landing behavior, and business outcomes separately before evaluating their combined effect.
    • Treat the landing page as shared search infrastructure and make it answer the complete decision context carried by the prompt.

    Your next move is small and concrete: choose one commercially important prompt cluster, document its qualifiers, check both visibility surfaces, and inspect the destination through that user’s question. That single end-to-end audit will expose more useful work than another disconnected SEO keyword list or PPC expansion.

    References

  • How to Turn Google Analytics Insights Into a Smarter Budget

    How to Turn Google Analytics Insights Into a Smarter Budget

    If you are opening Google Analytics to decide where the next part of your paid-media budget should go, a performance alert is not the answer you need. It is only the start of the decision. The dangerous shortcut is to see a channel move, assume the channel caused it, and transfer money before checking whether the movement came from measurement, timing, demand, or campaign execution.

    Google is shortening the distance between monitoring and planning through generated Home insights, cross-channel budgeting, and a no-code scenario interface for Meridian. You can use that shorter path without surrendering judgment. The workflow below turns a signal into a documented, constrained, and reversible budget decision.

    Key takeaways

    • Use generated insights as a triage queue. They can tell you what deserves attention, but they do not prove why a metric changed.
    • Make paid channels comparable before moving money. Align the outcome definition, cost coverage, reporting window, attribution policy, and conversion maturity.
    • Separate historical efficiency from expected marginal return. The best destination for additional budget is not automatically the channel with the best average result.
    • Use scenarios to expose assumptions and constraints, not to manufacture certainty. A forecast is an estimate that still needs business judgment.
    • Document the hypothesis, approved change, guardrails, and evaluation conditions before changing spend. This prevents a plausible explanation from quietly becoming an untestable decision.

    Give each Google planning feature one clear job

    Google Analytics can place the top three changes since your last visit on the Home page, including notable performance shifts, anomalies, and seasonality patterns. That is a detection layer. Its useful output is not a budget instruction. It is a shorter list of changes worth investigating.

    The cross-channel budgeting capability has a different job. It is intended to connect performance across paid channels with investment decisions, but it remains a beta feature with limited access. Build a process that can use the interface when it is available without making your decision discipline dependent on it.

    Google’s no-code Scenario Planner turns Meridian marketing mix model outputs into budget and ROI forecasts. It lets a marketer test alternative allocations without writing code or relying on a data scientist to operate the interface. It does not remove the need to choose the right outcome, understand the model’s limits, or account for constraints the model may not contain.

    CapabilityDecision jobQuestion it can supportWhat it cannot establish by itself
    Generated Home insightsDetection and prioritizationWhat changed enough to investigate?What caused the change or whether budget should move
    Cross-channel budgetingPaid-channel comparison and allocationHow is paid investment performing across channels?Whether the channel inputs are truly comparable
    Scenario PlannerForward-looking simulationHow might budget and ROI change under another allocation?Whether the forecast will occur or whether omitted business constraints make it impractical

    This separation matters because detection, explanation, and allocation require different evidence. An unusual movement may deserve immediate attention while still being a poor reason for an immediate budget change. A scenario may look attractive while depending on immature conversion data or a channel definition that differs from the rest of the plan.

    Turn a surfaced change into an auditable budget decision

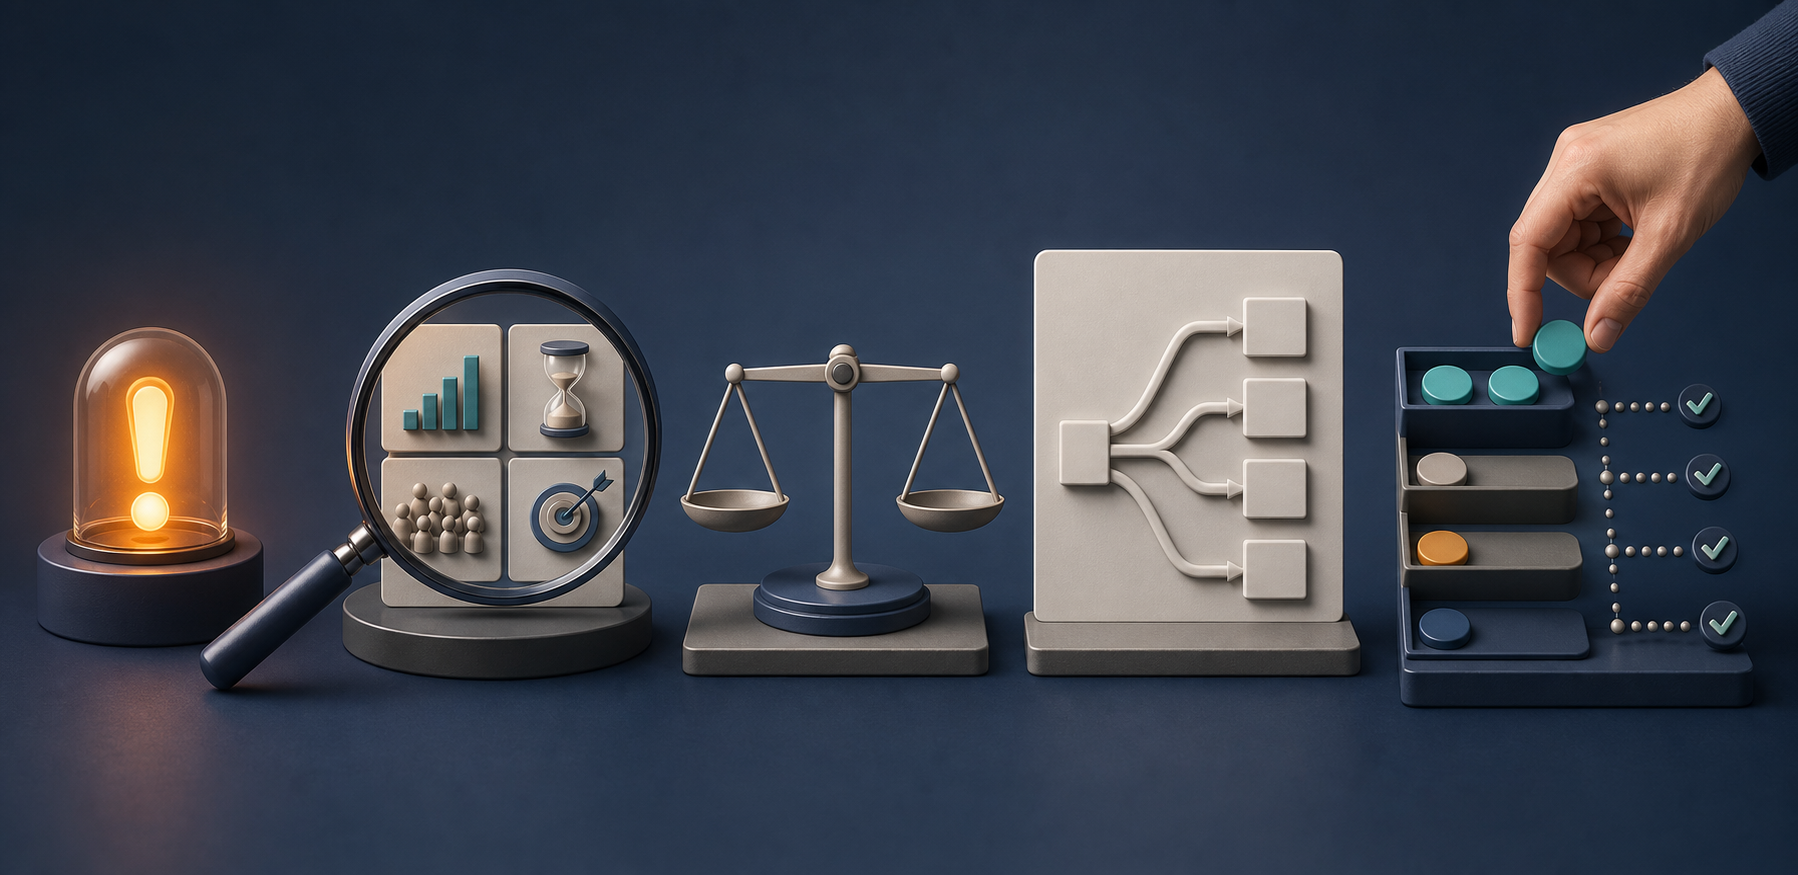
    An unlabeled visual workflow moves from a performance signal through evidence checks and scenario comparison to a documented budget allocation.

    Every budget change should have a visible chain from signal to decision. If someone cannot reconstruct that chain later, you will struggle to tell whether the allocation worked, whether the original explanation was wrong, or whether the market simply changed after approval.

    1. Define the decision before examining allocations. Write down the business outcome, planning horizon, channels in scope, total budget boundary, and any commitments that cannot move. If the business cares about qualified demand, a rise in raw conversion volume is supporting evidence rather than the decision metric.
    2. Capture the signal precisely. Record the metric that moved, its date range, the property and filters in use, the affected channel or campaign, and the comparison that made it notable. Avoid summaries such as paid social is down. They are too vague to validate.
    3. Check measurement before interpreting performance. Look for changes to event definitions, tags, consent behavior, attribution settings, campaign naming, imported costs, and reporting filters. A measurement discontinuity can resemble a sudden gain or loss in channel efficiency.
    4. Classify the most plausible explanation. Useful classes include measurement, seasonality, underlying demand, campaign execution, channel mix, and normal variation. The classification tells you what evidence to inspect next; it is not yet a causal conclusion.
    5. Write a testable hypothesis. State what you think changed, the mechanism connecting it to the outcome, and what observation would weaken the explanation. If nothing could disprove the hypothesis, it is a story rather than a basis for allocating money.
    6. Create a comparable baseline. Align the reporting window, outcome definition, included costs, attribution treatment, and conversion maturity across the channels being considered. Preserve any important differences instead of hiding them inside a blended total.
    7. Model alternatives within real constraints. Keep the current allocation as the baseline, then create a reallocation that respects budget limits, channel commitments, operational capacity, and risk tolerance. Add a more conservative version when the input data or model fit leaves substantial uncertainty.
    8. Approve the smallest change that can answer the decision question. A reversible adjustment limits the cost of a wrong assumption and gives you a cleaner read than changing many channels, audiences, bids, and creative variables at once.
    9. Predefine the readout. Name the primary outcome, diagnostic metrics, guardrails, required conversion maturity, and the conditions for continuing, pausing, or reversing the move. Do this before the result is visible so the success rule cannot drift toward whatever happened.

    The planning interface belongs in the modeling stage, not at the beginning of the chain. Starting with a recommended allocation invites you to reverse-engineer a justification. Starting with a defined decision and validated baseline lets you judge whether the recommendation is relevant at all.

    If Scenario Planner or cross-channel budgeting is not available in your account, keep the same structure in a controlled worksheet or planning document. Tool access changes the speed of the work. It should not change the evidence required to approve spend.

    Make every paid channel earn comparison on the same basis

    A cross-channel screen can place metrics beside each other without making them economically equivalent. Before you rank channels, normalize what can be normalized and label what cannot. Otherwise, the cleanest-looking comparison may reward the channel with the most favorable measurement rules rather than the strongest business contribution.

    Use one decision outcome and consistent cost coverage

    Choose the outcome that the budget decision is meant to improve. Revenue, qualified leads, new customers, and platform conversions are not interchangeable. A channel can generate inexpensive form submissions while producing little qualified demand, so optimizing against the cheapest visible conversion may move money away from the business result you actually need.

    Use supporting metrics to diagnose the result, not replace it. Clicks, sessions, reach, and intermediate actions can help explain why the primary outcome changed. They should not outrank that outcome simply because they arrive sooner or look more favorable.

    Apply the same cost policy across the comparison. Decide whether the analysis includes media spend only or a broader set of in-scope costs, then use that definition consistently. Align currencies and the treatment of credits, taxes, and fees where they affect the data. An incomplete cost import can make a channel appear more efficient without any real improvement.

    Respect conversion timing

    Channels often influence outcomes on different timelines. A channel whose conversions mature slowly can look weak beside one whose outcomes are recorded quickly, especially near the end of the reporting window. Do not make the slower channel defend an incomplete result against the faster channel’s mature result.

    Set the evaluation window from the buying cycle and conversion delay relevant to your business. Mark immature periods as incomplete. If leadership needs an earlier read, present leading indicators as provisional evidence and say what remains unknown rather than treating them as final ROI.

    Plan around marginal return, not the historical average

    Average efficiency answers what the channel produced across the spend it already received. Budget planning asks a different question: what is the next portion of spend expected to produce? That distinction is where many reallocations go wrong.

    A historically efficient channel may have limited room to absorb additional budget at the same return. A channel with a weaker average may still have useful incremental capacity. Neither conclusion should be assumed from the averages alone. Use the scenario output, current delivery constraints, and recent evidence to judge the expected effect of the proposed change.

    A practical budget structure separates committed investment, protected learning investment, and reallocatable investment. Committed spend covers obligations or strategic coverage you have decided not to disturb. Protected learning spend preserves experiments that would otherwise be cut before producing useful evidence. Reallocatable spend is the portion the scenario can genuinely move. This prevents a mathematically neat plan from recommending a transfer that the business cannot or should not execute.

    Let attribution and marketing mix modeling answer different questions

    Attribution assigns credit among observed touchpoints under a defined rule or model. Marketing mix modeling estimates relationships between investment and aggregate outcomes across time. Their outputs can differ because the methods, data, and questions differ.

    Do not force the two views to agree before you can make a decision. Use disagreement as an investigation trigger. Check channel definitions, missing costs, promotional periods, conversion lag, offline effects, and the outcome each method is measuring. Then document which view is carrying more weight for this decision and why.

    Put guardrails around AI-assisted budget recommendations

    A human hand reviews glowing budget recommendations that pass through locks, balances, and other safeguards before reaching paid-channel containers.

    Generated explanations and accessible forecasts can make a budget recommendation feel more complete than its evidence warrants. The remedy is not to ignore the tools. It is to require a few checks before the recommendation becomes an instruction.

    • Alert is not explanation. Confirm that the movement is real, material to the decision, and not created by a reporting change.
    • Correlation is not a causal mechanism. Write the proposed explanation and identify evidence that could contradict it.
    • Forecast is not commitment. Treat predicted ROI as conditional on the model, inputs, assumptions, and scenario design.
    • No-code is not assumption-free. Someone still has to define the outcome, constraints, planning period, and acceptable risk.
    • Cross-channel visibility is not complete business visibility. Add margin, capacity, inventory, contractual, brand, or geographic constraints when they matter and are not represented in the analytics view.
    • Optimization is not permission to remove learning. Preserve strategically useful experiments when their evidence has not had time to mature.
    • Beta access is not an operational control. Keep the decision record outside the feature so your process survives access, interface, or availability changes.

    Use a decision record that survives the meeting

    Keep each allocation decision in a short, consistent record. Include the decision question, surfaced signal, validated evidence, rejected explanations, remaining uncertainty, baseline allocation, proposed change, scenario assumptions, business constraints, expected outcome, guardrails, effective period, evaluation conditions, owner, and next review point.

    The record should make the status explicit: hold the allocation, investigate the signal, model alternatives, or implement a change. A review that ends with general agreement but no named status leaves the team vulnerable to accidental changes and conflicting interpretations.

    At the next review, compare the observed result with the expectation and examine the mechanism, not just the final total. A favorable outcome does not automatically validate the original explanation, and an unfavorable outcome does not automatically prove the channel is ineffective. Demand, measurement, and execution may have changed while the budget test was running.

    On your next visit to Google Analytics, take the most decision-relevant surfaced change and run it through the chain before touching spend: validate the measurement, define the hypothesis, create a comparable baseline, model a constrained alternative, and set the reversal conditions. That turns faster analytics into a better decision rather than merely a faster reaction.

    References

  • How to Measure SEO Performance in AI-Driven Discovery

    How to Measure SEO Performance in AI-Driven Discovery

    Your organic sessions are down, AI-generated answers are absorbing more of the discovery journey, and your dashboard still expects traffic to explain whether SEO is working. If you answer with average position or a sitewide traffic total, you can make a healthy program look weak—or celebrate visibility that never becomes demand.

    The answer isn’t to replace one vanity metric with a count of AI mentions. You need a measurement chain that connects search visibility, AI citations, brand recommendations and commercial outcomes. That chain reveals influence that can occur without a click while keeping pipeline and revenue at the center of the scorecard.

    Key takeaways

    • Keep traffic, impressions and rankings, but segment them by topic, intent and business value before using them to judge performance.
    • Measure AI visibility across prompt variations, platforms and collection windows. A favorable answer from one prompt is an observation, not a trend.
    • Track citations, mentions and recommendations separately. They represent different levels of influence.
    • Pair recommendation rate with recommendation share: one measures how often you are recommended, while the other measures how much competitive recommendation space you occupy.
    • Connect the same topic taxonomy to landing pages, conversions and CRM outcomes so the AI visibility report can support an actual decision.

    Measure five links between retrieval and revenue

    Five connected visual stages show web visibility, retrieval, AI citations, brand consideration, and a commercial outcome.

    Traditional SEO reporting often jumps from ranking to traffic and then to conversion. AI-driven discovery adds several decisions between those stages. A system may have access to your page, use it as evidence, mention your brand, or actively recommend you. Those events are not interchangeable: being available, being cited and being recommended are distinct levels of visibility.

    Measurement stageQuestion it answersUseful measuresCommon misreading
    AvailabilityCan search and AI systems find a relevant page?Indexation, topic-level organic visibility, impressions and SERP coverageAssuming an indexed or highly ranked page must appear in an AI answer
    CitationIs your domain selected as evidence?Domain citation rate and citation consistency by topicTreating every citation as a brand endorsement
    MentionDoes the response include your brand?Brand mention rate, context and accuracyCounting neutral or negative mentions as recommendations
    RecommendationIs your brand presented as a suitable choice?Recommendation rate, recommendation share and consistencyCelebrating one favorable response as durable visibility
    OutcomeDoes discovery contribute to valuable demand?Qualified conversions, customers, pipeline and revenue by topic or landing pageUsing last-click attribution as the complete customer journey

    This framework prevents a particularly costly reporting error. If an answer cites your page but recommends a competitor, your content won the evidence-selection step while your brand lost the choice step. More citations alone won’t tell you why.

    Use a response cell as the basic unit of measurement: one prompt variant, on one platform, in one recorded run. Store failed or incomplete runs separately rather than coding them as brand absences. From those cells, calculate:

    • Mention rate: response cells that mention your brand divided by all valid response cells.
    • Citation rate: response cells that cite your domain divided by all valid response cells.
    • Recommendation rate: response cells that recommend your brand divided by all valid response cells.
    • Recommendation share: your brand’s recommendation instances divided by all named-brand recommendation instances in the tracked category. Count a brand no more than once per response so repetition within the prose doesn’t inflate its share.
    • Consistency: the recurrence of your mentions or recommendations across prompt variants, platforms and collection windows. Report each dimension separately so strength on one interface cannot conceal absence elsewhere.

    Recommendation rate and recommendation share answer different questions. A category may produce few brand recommendations overall, giving one brand a large share of a small space. Conversely, your brand may appear frequently while losing relative share because competitors appear even more often. Put both measures beside each other.

    LLM consistency and recommendation share, often grouped as LCRS, provide a repeatable way to examine presence across prompts, platforms and time. Keep the components visible instead of manufacturing a blended score with arbitrary weights. A composite is useful only when its weighting rules are documented and tied to a real business decision.

    Build a repeatable AI discovery sample

    A prompt tracker should represent buyer decisions, not a bag of interesting questions. Isolated keyword tracking already struggles to represent semantic search and intent; copying that model into an AI visibility tool preserves the same flaw. Organize prompts into topic-and-intent families that correspond to the decisions your audience makes.

    Construct prompt families around decisions

    Start with commercially meaningful topic clusters, then cover the different ways a person could approach each one:

    • Category discovery: solutions for a defined problem or goal.
    • Comparison: alternatives, trade-offs or differences between approaches.
    • Shortlisting: suitable providers or products for a particular use case.
    • Constraint: choices shaped by industry, organization size, compatibility, location or another relevant requirement.
    • Validation: questions about trust, fit, limitations or reasons to choose one option over another.

    Create wording variants within each family, but preserve the underlying intent. If you change the audience, constraint and requested output at the same time, you have created a different decision rather than a controlled variation. Keep a permanent identifier for the family and a separate identifier for each variant.

    Track the category, not only your brand name. Brand-prompt performance can show whether a system knows you, but category prompts reveal whether it chooses you before the user has supplied your name. That is the competitive question recommendation share is meant to answer.

    Freeze the protocol before collecting answers

    1. Define the scope. Record the topic clusters, intent classes, markets and AI interfaces the scorecard is supposed to represent. Keep an initial competitor set for reporting, but capture unlisted brands so the tracker can detect new entrants.
    2. Lock a prompt version. Preserve the exact text and variant identifier. Add new prompts as a new version instead of silently editing the historical set.
    3. Record the conditions. Save the platform, interface, collection time, exposed model label, relevant account or location context, and any settings that could affect the response.
    4. Repeat collection. Run the same portfolio on a fixed cadence and retain every raw response. Because LLM output is non-deterministic, directional trends are more useful than one-shot results.
    5. Code observable events. Use separate fields for domain citation, brand mention, explicit recommendation, competitor recommendation, negative context and factual inaccuracy. A response can satisfy several fields at once.
    6. Review ambiguous cases. Automated parsing can handle volume, but human review should resolve implied recommendations, misspelled brands, parent-subsidiary relationships and passages where a brand is mentioned only as a warning.

    The coding rule for a recommendation should be written before anyone sees the results. A practical definition is an explicit suggestion, shortlist placement or statement that the brand is suitable for the requested use case. Incidental examples, citations, navigation instructions and negative comparisons do not qualify.

    Keep the raw answer beside the coded fields. If recommendation share moves, you need to know whether the market changed, the model phrased the same judgment differently, or the parser made a classification error. A dashboard without retrievable evidence is difficult to audit and easy to overinterpret.

    Give executives and practitioners different dashboard views

    An executive scorecard should explain commercial performance. A working SEO view should explain what caused it. Combining both into one page usually leaves leaders staring at diagnostic noise while practitioners lose the detail needed to act.

    The executive view

    • Qualified organic outcomes: leads that become sales-qualified opportunities or customers, not unfiltered form fills.
    • Pipeline and revenue contribution: shown by product category, service line or another useful business unit.
    • Conversion-weighted search visibility: visibility across topic clusters adjusted by documented business value.
    • AI recommendation performance: recommendation rate, recommendation share and consistency for the same high-value clusters.
    • Supporting demand indicators: branded search, direct visits and returning visitors, interpreted alongside campaigns and other factors that can move them.

    To calculate conversion-weighted visibility, assign each topic cluster a business-value weight grounded in qualified conversion or customer data. Multiply the cluster’s visibility by that weight, add the weighted values, and divide by the total weight. Retain the unweighted result beside it. This makes the judgment transparent and prevents a large set of low-intent impressions from overpowering a smaller commercial opportunity.

    Do not let search volume alone determine those weights. A high-volume informational cluster may be useful for awareness, but it should not receive the same commercial importance as a lower-volume cluster that repeatedly produces customers. Traffic and impressions without intent or revenue context can point a strategy in the wrong direction.

    The working SEO view

    • Search impressions, clicks and landing-page conversions segmented by topic cluster and intent.
    • SERP coverage across organic results, snippets, local results and other relevant search features.
    • AI citations, mentions and recommendations by prompt family, platform and collection window.
    • Competitor recommendation share and the prompts where competitors displace your brand.
    • Response accuracy, negative context and unsupported claims that require reputation or content work.
    • Indexation, page eligibility and conversion-path issues that can explain a break in the measurement chain.

    Traffic, impressions and rankings remain useful diagnostics. They become misleading when reported as context-free outcomes. Average position treats queries of unequal value as though they matter equally, and a share-of-top-10 metric can be dominated by low-intent terms. Segment both before using them to allocate work.

    Move proprietary authority scores, total backlink counts and unqualified bounce rate out of the executive scorecard. They may support audits, but they don’t establish business performance. A visitor who gets a complete answer and leaves can produce a high bounce rate despite a successful visit; extra page views from a pricing page can reflect confusion rather than engagement. Engagement measures need page purpose and conversion context.

    Join AI visibility to customer outcomes

    Use the same topic-cluster names in the prompt tracker, content inventory, analytics reporting and CRM. That shared key lets you compare recommendation changes with the landing pages, qualified conversions and opportunities associated with the same need. Without it, AI visibility and revenue remain two charts that happen to sit beside each other.

    Show first-touch, assisted and last-touch views rather than forcing one attribution model to tell the entire story. Where appropriate, add AI assistants as an option in buyer-discovery fields and preserve a free-text answer. Treat self-reported discovery, branded search and direct traffic as supporting evidence, not proof that one AI response caused a sale. Their value is corroboration across signals.

    Interpret combinations of signals, then make a decision

    An analyst watches search, citation, brand, engagement, and purchase signals converge into a glowing path toward one selected action.

    No single movement establishes success or failure. The useful diagnosis comes from the relationship among visibility, recommendation and outcome measures.

    Observed patternLikely measurement implicationWhat to do next
    Citations rise while recommendation rate stays flatYour pages are useful evidence, but the brand is not being selected as a solution.Review whether the content clearly connects the named entity, offer, use case, differentiators and supporting proof. Do not diagnose this as an indexation problem.
    Recommendation share rises while site traffic stays flatZero-click influence is plausible, but the commercial effect is still unconfirmed.Check branded demand, direct and returning visits, qualified conversions and pipeline for the same topic clusters.
    Organic traffic falls while qualified conversions or revenue riseThe lost visits may be concentrated in low-intent queries.Segment the decline by intent, landing page and topic before attempting to restore the old total.
    Traditional rankings are strong while AI citations and mentions are weakRanking availability is not translating into selection within generated answers.Audit whether the relevant pages answer the prompt directly and express entities, claims and supporting evidence clearly.
    Visibility improves on one platform but not across prompt variants or timeThe gain is platform-specific or unstable rather than consistent.Keep collecting under the fixed protocol before changing strategy or claiming category-wide growth.
    AI visibility rises while qualified outcomes remain flatThe tracked prompts may not represent valuable demand, or the break may occur after discovery.Revalidate prompt intent, then inspect the offer, landing-page journey and lead qualification before pursuing more mentions.
    Results swing sharply between runsSampling volatility may be larger than the underlying change.Inspect raw responses and wait for the direction to recur across variants, platforms or collection windows.

    Predefine the decision attached to each pattern. If citation consistency is high but recommendation rate is low, work on brand-to-solution clarity and comparative evidence. If both AI visibility and commercial outcomes are weak for a high-value cluster, revisit the intent, content and conversion path. If recommendation performance and qualified outcomes improve together across a stable sample, expand the approach to the next closely related cluster.

    When you make a substantial change, annotate it in the measurement record. Where feasible, update one topic cluster while leaving a comparable cluster unchanged. Continue using the same prompt version and coding rules. This won’t turn observational data into perfect causal proof, but it gives you a much stronger comparison than a before-and-after screenshot taken from changing prompts.

    Begin with one commercially important topic cluster. Build its prompt families, collect the raw responses, code citations and recommendations, and connect the cluster to qualified conversions. Once that baseline is stable, the next report can answer the question that matters: whether your brand is merely available, repeatedly chosen, or contributing to demand.

    References

  • Unlocking SEO Success: AI’s Role in Authority Building

    Unlocking SEO Success: AI’s Role in Authority Building

    In an AI-driven search world, authority outweighs optimization

    As someone deeply immersed in the world of SEO, I’ve witnessed a fascinating evolution. In the early 2000s, if you were like me, you probably focused on gaming PageRank with enough links and keywords to achieve visibility. It was a mechanical process, and frankly, relatively simple to exploit.

    Fast forward two decades, and the search landscape has radically transformed. Algorithms have become sophisticated, mirroring Google’s deeper understanding of brands, individuals, and reputations. This transformation, driven by AI-powered discovery, means authority is now the cornerstone of search rankings. The journey culminates in an era where brand legitimacy is sustained through genuine visibility.

    ```json
{
  "alt": "Google Hotel Finder review snippet on Hallam Internet by Susan Hallam.",
  "caption": "Discover Susan Hallam's insights on Google Hotel Finder's UK launch. Her verdict? A thumbs up! Dive into the detailed review.",
  "description": "This image displays a snippet from Hallam Internet featuring a review of Google Hotel Finder by Susan Hallam. The service has recently launched in the UK, and the review is positive, with a recommendation to try it. The snippet includes the website link, author photo, and mentions Google+ circles."
}
```

    I witnessed Google’s first significant stand against manipulation with the Penguin update, prompting many of us to rethink our link-building strategies. “Digital PR” began to replace traditional notions, while Google’s experiments with entity-based understanding introduced innovations like author photos in search results and knowledge panels.

    Although Google eventually phased out some features like authorship, the message was clear: authority assessment was being redefined. Instead of asking, “Who links to this page?” Google’s algorithms started considering “Who authored this content, and how is this author recognized?” This shift, propelled by AI-driven search enhancements over the past year, is now impossible to ignore.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    Helpful content and the end of synthetic authority

    When Google integrated the helpful content system into its core algorithm, it marked a turning point for us in SEO. Sites that once thrived on over-optimization saw their performance crumble. In contrast, brands demonstrating authentic expertise and brand authority began to rise.

    It’s now vital that search systems accurately evaluate whether content reflects true expertise. As someone who’s navigated the core updates, I’ve seen larger brands with robust reputations consistently outperform technically proficient but less well-known sites. Authority has evolved from being a differentiator to a necessity.

    ```json
{
  "alt": "Line graph showing top cited domains in ChatGPT with Wikipedia and Reddit as leading sources.",
  "caption": "A visual dive into ChatGPT's source preferences reveals Wikipedia and Reddit as predominant domains before a notable mid-September drop.",
  "description": "This line graph illustrates the percentage of times specific domains were cited as sources in ChatGPT responses from July to September 2025. Wikipedia.org and Reddit.com show initial dominance with citation rates over 40%, followed by a significant decline around mid-September. Other domains like Medium, Forbes, and LinkedIn remain low. Based on a Semrush study of 230K prompts in October 2025, sourced from semrush.com."
}
```

    Authority in an AI‑mediated search world

    In diving into resources about large language models (LLMs), I’ve learned that they source their information from diverse platforms—journalism, forums, reviews, and video transcripts. It’s through these platforms that reputation is built, highlighting the power of consistent, positive mention of your brand.

    This revelation has profound implications for our SEO strategies. Platforms like Reddit, Quora, LinkedIn, YouTube, and trusted review platforms such as G2 are regularly cited in AI search responses. These platforms organically reflect what people genuinely think about brands, rather than what we aim to claim.

    ```json
{
  "alt": "Bar chart comparing factors correlating with AI mentions among ChatGPT, AI Mode, and AI Overviews.",
  "caption": "Explore how ChatGPT, AI Mode, and AI Overviews differ in correlation factors related to AI mentions, based on a study of 75,000 brands by Ahrefs.",
  "description": "This image features a bar chart that compares correlation factors with AI mentions among ChatGPT, AI Mode, and AI Overviews. The data includes metrics such as YouTube mentions, branded web mentions, and URL rating, derived from a study of approximately 75,000 brands by Ahrefs Brand Radar and Site Explorer. The chart reveals varying correlation levels, providing insights into digital presence and AI-related discussions."
}
```

    This doesn’t mean the end of Google

    Despite AI’s growing integration, Google continues to dominate with over 90% of global search usage. Even among frequent AI platform users, reliance on Google persists. Google’s interfaces now absorb AI-style answers, meaning users experience AI directly within Google platforms. This hybrid presence offers an exciting opportunity for building cross-platform authority.

    Brand building is the new SEO multiplier

    As someone who bridges the gap between paid and organic strategy, I’ve seen that effective authority signals often emerge from outside traditional search channels. Digital PR, brand advertising, events, and offline activities increasingly shape organic performance. This sphere where paid and organic strategies converge enhances your brand’s legitimacy.

    ```json
{
  "alt": "Graphic showing three types of authority: Category, Canonical, and Distributed, with descriptions and examples.",
  "caption": "Exploring the pillars of authority: Learn how Category, Canonical, and Distributed Authority help shape perceptions and build credibility across various platforms.",
  "description": "This graphic illustrates three essential types of authority: Category Authority, Canonical Authority, and Distributed Authority. Each type offers unique methods to build credibility. Category Authority involves defining the narrative with POV, thought leadership, and research. Canonical Authority focuses on creating trusted, reusable content like pillar pages and guides. Distributed Authority emphasizes credibility through external channels like PR, social media, and partnerships. © 2026 Hallam."
}
```

    Brand awareness significantly boosts click-through rates, with familiar names drawing references across various media. I’ve noticed mentions in YouTube videos or long-form journalism reinforcing topical authority that simple links cannot. The digital ecosystem now validates authority externally, and this multiplication effect is constantly evident in the results I oversee.

    A practical framework: The three pillars of authority

    Building enduring authority requires an integrated approach. Drawing from my experience, I’ve devised a framework focusing on three core areas: Category, Canonical, and Distributed authority. Each pillar strengthens your position as an industry leader, beyond mere SEO tactics.

    1. Category authority: Owning the truth, not just the traffic

    It begins with shaping how the category is defined. Instead of chasing keywords, the focus is on establishing your brand as the reference point others turn to for clarity. This strategy cultivates an authentic authority that search engines and AI increasingly reward.

    2. Canonical authority: Creating the definitive explanations

    This involves crafting explanation-focused content that thoroughly answers queries, becoming the go-to resource cited across various platforms. The content serves as the backbone across the digital landscape, ensuring enduring visibility through AI and future technologies.

    3. Distributed authority: Proving legitimacy beyond your website

    Genuine authority thrives through widespread credibility on platforms outside your control, including PR coverage, social media mentions, and product experiences. These elements amplify your brand’s presence and solidify trustworthiness.

    Ultimately, focusing on brand authority ensures durability amidst evolving algorithms. It’s about becoming the undisputed leader in your niche, where authority extends beyond traditional SEO into the realm of comprehensive digital engagement.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Grow Paid Search Without Losing Campaign Visibility

    How to Grow Paid Search Without Losing Campaign Visibility

    If organic clicks are slipping while search demand appears intact, raising every paid budget is the fastest way to hide the real problem. You have two visibility questions to answer: whether your brand still appears where searchers click, and whether you can see where your campaigns are actually delivering.

    The right response is not to replace SEO with paid search. It is to identify where valuable clicks have moved, assign each campaign a specific recovery job, and make budget decisions using both customer visibility and account-level evidence.

    Confirm that demand moved before you buy it back

    An organic decline does not automatically mean lower rankings, weaker demand, or an AI Overview taking every click. The search results page can redistribute the same pool of attention among classic organic listings, text ads, Product Listing Ads, AI features, and zero-click activity.

    That redistribution has become large enough to affect channel planning. Between January 2025 and January 2026, classic organic click share fell by 11 to 23 percentage points across four U.S. product and entertainment categories, while text ads gained 7 to 13 points.

    Within the same data, text-ad click share moved as follows:

    Query categoryJanuary 2025January 2026Change
    Headphones3%16%+13 percentage points
    Online games3%13%+10 percentage points
    Jeans7%16%+9 percentage points
    Greeting cards9%16%+7 percentage points

    Those figures are directional rather than universal. They cover the top 5,000 U.S. queries in headphones, jeans, and online games, plus 956 greeting-card queries. You should not apply their percentages to your account as a forecast. You should use them as a reason to test whether your own lost organic traffic has been captured by paid inventory.

    Do not diagnose that movement from AI Overview presence alone. For headphones, AI Overview presence rose from 2.28% to 32.76%, yet the zero-click rate remained at 63%. For jeans, AI Overview presence increased from 2.28% to 12.06% while the zero-click rate fell from 65% to 61%. AI features expanded, but zero-click behavior did not move in one consistent direction. Paid-result expansion therefore deserves its own place in your diagnosis.

    Build the diagnosis at the query-cluster level, not from an account-wide traffic total:

    1. Group queries by intent. Separate branded navigation, product or service searches, problem-aware searches, comparisons, and informational questions. A lost click on a purchase-ready query is not equivalent to a lost visit to a definition page.
    2. Align the periods. Compare organic impressions and clicks, paid impressions and clicks, conversions, and business value for the same query cluster and date range.
    3. Classify the pattern. Falling visibility across both organic and paid channels points toward weaker demand or broader coverage loss. Stable demand with falling organic clicks and rising paid capture is more consistent with SERP redistribution. Stable traffic with weaker conversion points you toward the offer, landing page, audience quality, or measurement.
    4. Prioritize recoverable value. Move a cluster into paid testing only when it has meaningful commercial intent, a credible landing page, and unit economics that can support the acquisition cost.

    These patterns are diagnostic clues, not proof of causation. If the budget decision is material, validate it with a controlled campaign change rather than assuming that two simultaneous trends are connected.

    Give each paid campaign one recovery job

    Three separate campaign modules connect to different gaps in an abstract search visibility landscape.

    Paid search cannot recover an aggregate SEO shortfall. It can buy coverage for particular intents and placements. A campaign becomes easier to manage when its name, targeting, budget, landing pages, and success metric all describe the same job.

    • Nonbrand text search: capture explicit commercial intent where classic organic listings have lost click share. Keep this separate from branded demand so an efficient brand campaign cannot conceal expensive acquisition traffic.
    • Shopping or Product Listing Ads: cover product-led discovery with a feed-based format. PLA click share rose from 16% to 36% for headphones, 18% to 34% for jeans, and 10% to 19% for greeting cards, making this a distinct visibility layer for ecommerce rather than an optional extension of text search.
    • Brand search: protect navigational demand where paid competition or a crowded results page creates a genuine coverage risk. Report it separately and test incrementality where practical, because a branded paid click is not automatically a newly acquired customer.
    • Performance Max: extend delivery across Google’s inventory when the broader reach fits your objective. Use its placement reporting to audit where that reach came from instead of treating PMax as an unexplained block of traffic.

    Competitor expansion can make the auction pressure self-reinforcing. As organic clicks fell in the tracked categories, Amazon increased paid headphone clicks by 35%, Walmart increased them nearly sixfold, Gap increased paid jeans clicks by 137%, and CrazyGames quadrupled paid clicks. Those shifts show brands buying more coverage as organic share contracts. They do not prove that every additional click was profitable.

    That distinction matters when you set a budget. Do not copy a competitor’s apparent response or multiply spend by the percentage of organic traffic you lost. Set the ceiling from your own gross profit, lead value, conversion quality, and acceptable acquisition cost. If those economics are uncertain, use an amount you can afford to lose while learning and write the stop condition before launch.

    A simple recovery brief should name the query cluster, the suspected click displacement, the campaign responsible for recovering it, the landing page, the primary business outcome, the budget ceiling, and the condition that would cause you to hold, scale, or reverse the change. If one brief needs several campaign types, split it. That keeps the eventual result interpretable.

    Turn PMax placement visibility into decisions

    A transparent prism reveals varied digital ad placements while a lens routes selected placements toward a business outcome.

    The Google Ads Where ads showed report gives you a clearer delivery view for Performance Max. It can surface placements, placement types, networks, and impression data across areas that include Google Search Partners and display inventory.

    This closes part of the visibility gap, but it does not turn every reported impression into placement-level profit evidence. An impression tells you where delivery occurred. It does not, by itself, tell you whether that placement created an incremental sale, a qualified lead, or wasted spend.

    1. Use matching date ranges. Pull the placement view for the same period as your cost, conversion, revenue, or qualified-lead results.
    2. Group delivery before judging it. Summarize reported impressions by network and placement type. Calculate each group’s proportion of reported impressions, but call it the reported impression mix rather than Google’s technical impression-share metric.
    3. Mark changes and surprises. Look for a sudden shift in network mix, a concentration of impressions in an unexpected placement type, or delivery that conflicts with the campaign’s intended market and brand-suitability rules.
    4. Compare the shift with business outcomes. If the mix changed while cost per qualified result, conversion value, or lead quality remained stable, the placement change alone does not justify intervention. If reach moved at the same time that business performance weakened, you have a candidate for investigation, not a final verdict.
    5. Change one controllable element. Verify targeting, campaign settings, assets, feeds, suitability controls, and any available exclusions. Make one supported change where the platform allows it, then record the reason so the next review can distinguish cause from coincidence.

    The most common mistake is to rank placements by impressions and label the largest one wasteful. High impression volume can mean broad delivery, low-cost inventory, or simply the way PMax assembled reach. Without matching outcome evidence, removing or constraining it can reduce useful coverage along with the unwanted inventory.

    What you seeWhat you can concludeWhat to do next
    Network mix changed; business outcomes stayed stableDelivery changed, but harm is not establishedRecord the shift and continue monitoring comparable periods
    Unexpected placement concentration; outcomes weakenedThe placement mix may be involved, but correlation is not causationCheck settings and suitability, then isolate one controlled change
    Unexpected placement; only impression data is availableYou know where delivery occurred, not what that placement returnedValidate suitability and seek matching performance evidence before changing spend
    Search Partner delivery increased; lead quality remained acceptableThe network label alone is not evidence of wasteKeep the decision tied to business quality and marginal cost

    Connect SERP loss, campaign reach, and business value

    A paid-search dashboard should make the chain from demand to value visible. If it shows only spend and conversions, you cannot tell whether growth came from recovering displaced clicks, harvesting brand demand, or expanding into new inventory. If it shows only placement impressions, you cannot tell whether the added visibility helped the business.

    Use one review sheet with a row for each intent cluster and these fields:

    • Demand signal: the direction of relevant search impressions or another consistent demand measure.
    • Organic capture: organic impressions, clicks, click-through rate, and classic organic share where reliable third-party data is available.
    • Paid capture: text-ad clicks, Shopping or PLA clicks, cost, and the campaign responsible for the cluster.
    • PMax delivery: reported impressions by network and placement type, plus any meaningful change in the mix.
    • Business result: purchases, qualified leads, revenue or conversion value, acquisition cost, and the quality measure that matters after the form fill or transaction.
    • Decision record: what changed, why it changed, the expected result, and whether the next action is to hold, expand, investigate, or reverse it.

    Review the sheet in that order. First ask whether demand changed. Then identify where clicks were lost or gained. Only after that should you judge whether paid coverage produced additional business at an acceptable marginal cost.

    Keep five analytical traps out of the review:

    • Do not blame AI Overviews from presence alone. Check paid-result growth and zero-click behavior before assigning the loss to an AI feature.
    • Do not blend brand and nonbrand performance. A strong branded return can make weak acquisition activity look efficient.
    • Do not treat the PMax placement report as a conversion report. Use it to understand delivery, then connect delivery changes to campaign outcomes.
    • Do not copy a competitor’s budget response. Their organic exposure, margins, customer value, and measurement may be different from yours.
    • Do not change bids, budget, targeting, assets, feeds, and landing pages together. You may increase volume, but you will not know which intervention caused it or which one should be repeated.

    Trend lines can establish that events happened together; they cannot establish incrementality by themselves. When the financial consequence is meaningful, use a controlled test that holds other material variables stable. Otherwise, a paid campaign may receive credit for demand that would have converted through organic, direct, or branded traffic anyway.

    Key takeaways

    • An organic click decline can reflect demand loss, ranking loss, paid-result expansion, AI features, zero-click behavior, or a combination. Diagnose the query cluster before adding budget.
    • Text ads and Product Listing Ads gained substantial click share in the tracked U.S. categories, so paid coverage belongs in a modern search-visibility plan without becoming a substitute for SEO.
    • Assign separate jobs and reporting to nonbrand text search, Shopping, brand campaigns, and Performance Max.
    • Use PMax placement data to see where impressions were delivered, but do not infer placement-level profitability from impressions alone.
    • Scale only when added coverage produces acceptable marginal business value, not merely more clicks or a larger reported reach.

    Start with one commercially important query cluster where organic clicks fell but demand still appears healthy. Map its current paid coverage, set a ceiling from your unit economics, inspect where PMax is delivering, and change one lever. That gives you an answer you can use: whether you recovered valuable demand or simply paid for more visibility.

    References

  • How to Build a Paid Search Optimization System That Learns

    How to Build a Paid Search Optimization System That Learns

    Your paid search account is probably not short of prompts to act. The harder problem is deciding which recommendation deserves budget, whether an automated result represents added business value, and how to preserve what your team learned after the interface changes.

    You need more than a collection of campaign tools. You need an operating system that connects operator skill, controlled execution, and credible measurement. That system lets you move quickly without treating every platform suggestion as an instruction.

    Key takeaways

    • Give every tool one clear job: build capability, execute a change, or verify its effect.
    • Record the hypothesis, baseline, spending limit, success metric, and rollback condition before applying a recommendation.
    • Treat platform-reported incremental lift as decision support. Compare it with the marginal cost and the business value of the added outcomes.
    • Turn Performance Max training into reusable launch and troubleshooting checklists instead of leaving the knowledge inside a course.
    • Manage additional Shopping images as structured feed data and test them against a defined commercial outcome.

    Build your optimization stack around decisions, not features

    A paid search tool earns its place when it helps you make a specific decision. A new dashboard, recommendation, feed field, or course is not automatically useful just because the platform makes it available.

    Separate your stack into capability, execution, and evidence. The separation matters because no single platform surface should be expected to train the operator, make the change, and deliver the final commercial verdict.

    LayerTools and resourcesDecision it should support
    CapabilityApplied Performance Max courses, scenarios, checklists, and reference materialCan the operator configure, review, and troubleshoot the campaign reliably?
    ExecutionCampaign controls, recommendation workflows, and product-feed image fieldsWhat exactly will change in the account, and which campaigns or products will be exposed?
    EvidenceRecommendation impact reporting, change records, and business performance dataDid the change create enough additional value to justify its cost?

    This model exposes gaps that a tool inventory can hide. A credential can support operator development, but it cannot establish campaign profitability. A recommendation can identify an opportunity, but it cannot decide how much financial exposure your business will accept. A results view can estimate added conversions, but it cannot repair an incorrect conversion action or an inflated conversion value.

    For each tool, write down its owner, required inputs, output, and resulting decision. If nobody can name the decision, the tool is adding interface activity rather than optimization capacity. If the same platform proposes a change, applies it, and scores it, add an independent business guardrail such as allowable acquisition cost, margin, qualified-lead rate, or incremental return on ad spend.

    Put every automated recommendation through an evidence gate

    An analyst operates a transparent inspection gate that tests glowing recommendation tiles before a few are allowed to reach a regulated budget reservoir.

    Automated recommendations are hypotheses generated from the platform’s view of the account. They may be useful hypotheses, but accepting one still changes real bids, targets, or budget. A projected improvement is not the same thing as measured incremental value.

    Google Ads is testing a Results area that adds a useful verification layer. For an applied bid or budget recommendation, the system analyzes performance one week later and compares the outcome with a baseline estimate. Its reporting uses a seven-day rolling average measured over the 28 days after the recommendation, organizes results around Budget and Target changes, and focuses on the campaign’s primary bidding objective: clicks, conversions, or conversion value.

    Availability should not be assumed because the Results area is an early pilot. The operating principle still applies in accounts without it: define the expected effect before the change, preserve the starting state, and return after a declared observation window.

    Before you apply a recommendation, add this record to your campaign log:

    • Recommendation: The exact budget, bid, or target change and every campaign it affects.
    • Hypothesis: The outcome expected to increase and the mechanism that should produce it.
    • Baseline: Current spend, the primary bidding objective, and the business metric used to judge quality.
    • Exposure limit: The maximum additional spend or efficiency deterioration you have approved.
    • Observation window: When you will evaluate the change and why that period is suitable for the available reporting.
    • Rollback condition: The result that will cause you to reverse or revise the change.
    • Confounders: Promotions, tracking changes, feed edits, landing-page releases, or other campaign changes that could affect the comparison.

    The exposure limit is not paperwork. Raising a budget can spend more money without producing proportionate business value. Set the limit before approval so a promising platform forecast cannot become open-ended authority to spend.

    When results arrive, separate volume from efficiency. Additional conversions can be valuable even if average campaign efficiency changes, but only when their marginal economics work. Calculate incremental cost per acquisition as additional cost divided by additional conversions. Calculate incremental return on ad spend as additional conversion value divided by additional cost. If clicks are the bidding objective, do not treat extra clicks as revenue; follow them through to the business outcome that justified buying the traffic.

    The baseline in the Results area is an estimate, not direct observation of what the same campaign would have done without the change. Seasonality, promotions, competitor activity, measurement changes, and delayed conversions can still complicate interpretation. Use the reported lift as evidence, then ask whether the direction appears in your business data and whether any concurrent change offers a better explanation.

    Turn Performance Max training into campaign infrastructure

    Performance Max optimization often becomes account folklore: one person knows how the setup was built, another remembers why a target changed, and nobody has a stable troubleshooting sequence. Training is most valuable when it removes that dependence on memory.

    Microsoft Advertising’s applied learning path provides a useful progression: foundations, guided hands-on setup, and advanced scenario-based implementation and optimization. The advanced course includes checklists, videos, reusable reference material, and contextual support through Help me understand during an assessment. Completion can also lead to a shareable Performance Max badge through Credly.

    Use that progression to create internal operating assets:

    • From foundations, create a shared glossary. Define each objective, target, status, input, and output in the language your team uses when approving spend.
    • From setup training, create a launch checklist. Require the campaign objective, conversion action, budget authority, target, product or asset inputs, owner, and first review point to be documented before launch.
    • From advanced scenarios, create a troubleshooting tree. Start with the observed symptom, list the measurement and input checks that could explain it, and identify the smallest reversible action for each branch.
    • From reference material, create account notes. Link each live setting to the reason it was chosen so the next operator does not have to infer strategy from configuration alone.

    Do not measure training only by course completion. Ask the operator to review a live configuration, identify one defensible change, explain the evidence required to keep it, and state the rollback condition. That exercise connects knowledge to account control without pretending that a credential proves commercial performance.

    Reusable artifacts also make optimization safer when ownership changes. The campaign retains its operating history, and a new manager can distinguish a deliberate constraint from an overlooked default.

    Treat multi-image Shopping ads as a feed experiment

    Shopping creative is partly a feed-management problem. If you treat additional images as an informal upload task, you lose control over image purpose, product coverage, and measurement.

    Microsoft Advertising’s multi-image Shopping format uses the optional additional_image_link attribute for as many as 10 comma-separated images. Those images can appear with the product’s price and retailer information, giving shoppers more visual context before the click.

    The existence of 10 available image slots does not mean every product needs 10 images. Each image should resolve a meaningful pre-click uncertainty. An alternate angle can clarify shape. A detail view can reveal construction or a feature. A variation image can help a shopper understand an option that the primary image cannot show clearly. Repetitive images consume feed space without adding equivalent information.

    Use this rollout sequence:

    1. Select a coherent product group. Start with items for which extra views communicate material information, not an arbitrary mix of the catalog.
    2. Assign every image a role. Record whether it shows an alternate angle, close detail, style, color, or another useful distinction.
    3. Validate the feed. Check that image links resolve, remain attached to the correct product, follow the intended order, and agree with the corresponding landing page.
    4. Declare the commercial outcome. Choose the metric that would justify expansion, such as qualified click-through, purchase rate, conversion value, or revenue per click.
    5. Protect the comparison. Avoid changing the same products’ bids, titles, prices, landing pages, and image sets at once. If your account structure permits it, compare a defined rollout group with a similar unchanged group.
    6. Expand only after the whole path improves. A higher click-through rate is not sufficient when the added visits convert poorly or produce weak value.

    This turns a creative feature into a testable merchandising decision. It also gives your feed team a clear rule for future images: add visual information that helps a shopper decide, then keep it only when the downstream result supports the added complexity.

    Use one repeatable loop for every campaign change

    A campaign specialist moves a glowing token around a circular workbench with stations for observation, testing, controlled change, comparison, and archiving.

    Your review process should remain stable even when platforms introduce new controls. A durable optimization loop looks like this:

    1. Start with the business decision. State whether you are trying to acquire more acceptable customers, recover efficiency, improve lead quality, or increase valuable product sales.
    2. Verify the measurement input. Confirm that the campaign’s primary objective represents the outcome you intend to optimize and that the business can interpret it consistently.
    3. Select one intervention class. Choose a budget change, target change, campaign setup correction, or creative-feed change. Separating change types makes the result easier to interpret.
    4. Write the hypothesis and guardrails. Define the expected movement, allowable spending exposure, observation window, and rollback condition.
    5. Apply the change and preserve context. Save the previous setting, implementation date, affected scope, owner, and any concurrent activity. Where Google’s pilot reporting is available, account for its 28-day measurement design rather than forcing an earlier conclusion from incomplete reporting.
    6. Evaluate platform lift and business economics separately. First determine whether the platform’s primary outcome moved. Then determine whether the additional cost produced acceptable downstream value.
    7. Turn the result into a reusable rule. Keep, revise, or reverse the change, and record what future operators should do when the same conditions appear again.

    A compact decision record needs only the campaign, owner, date, starting state, changed setting, hypothesis, spending limit, primary platform objective, business metric, observation window, result, and next action. Keep that record outside any temporary recommendation card so it remains available after the interface or account ownership changes.

    At your next account review, open the decision log before the recommendations queue. Pick one constrained problem, choose the tool that fits its layer, and define the evidence required to close the decision. That is how optimization becomes cumulative learning instead of a sequence of disconnected clicks.

    References