Author: shivamcrushpressai

  • How to Build an AI Search Visibility Content Strategy

    How to Build an AI Search Visibility Content Strategy

    You can rank well in conventional search and still disappear when a buyer asks ChatGPT or Google’s AI Mode to recommend an option. You can also appear in the answer and lose the opportunity because the system describes your business vaguely, assigns it to the wrong category, or repeats an outdated limitation.

    A useful AI search content strategy therefore has three jobs: place your brand in the buyer’s consideration set, make the right description easy to retrieve, and support that description with evidence an AI system can cite. Here is how to build that strategy around real buyer decisions rather than an unstable idea of “ranking first” in a generated answer.

    Optimize for consideration and representation, not one position

    A generated recommendation is not a fixed search results page. The order can change when the wording, context, platform, or response changes. Treating the first brand mentioned as the AI equivalent of Google’s first organic result gives you a fragile target and hides a more consequential question: does the answer present your brand as a credible fit?

    Observed sessions in ChatGPT and Google’s AI Mode found that users considered an average of 3.7 businesses. In the same dataset, 75% examined businesses shown in positions 2 through 8, and approximately 60% completed their decisions from the AI response without visiting a business website or returning to Google. Those figures come from one body of observational work, so they are not universal benchmarks. They do show why inclusion and message quality deserve more attention than mention order alone.

    Before you plan more content, write the description you want a qualified buyer to receive. A practical template is: [Brand] is a [specific category] for [specific audience] that needs [job or outcome]. It is strongest when [fit condition] and is not the right choice when [meaningful limitation]. If your team cannot agree on that statement, an AI system will have to reconcile inconsistent language scattered across your website and third-party pages.

    Key takeaways

    • Seek eligible inclusion: measure whether your brand appears when it genuinely fits the buyer’s request, not whether it always appears first.
    • Control the description: publish explicit category, audience, use-case, price, fit, and limitation information instead of expecting the system to infer your positioning.
    • Support the claim: combine a clear first-party fact base with accurate, legitimate third-party corroboration.
    • Measure the decision: track inclusion, message accuracy, citations, and commercial outcomes by buyer intent.

    This changes the content brief. “Rank for AI SEO agency” is a keyword objective. “Help a multi-location marketing team determine whether this service fits its reporting and governance needs” is an answer objective. The second version tells the writer which audience, decision, conditions, and tradeoffs must be explicit.

    Build your content map from the questions buyers use to decide
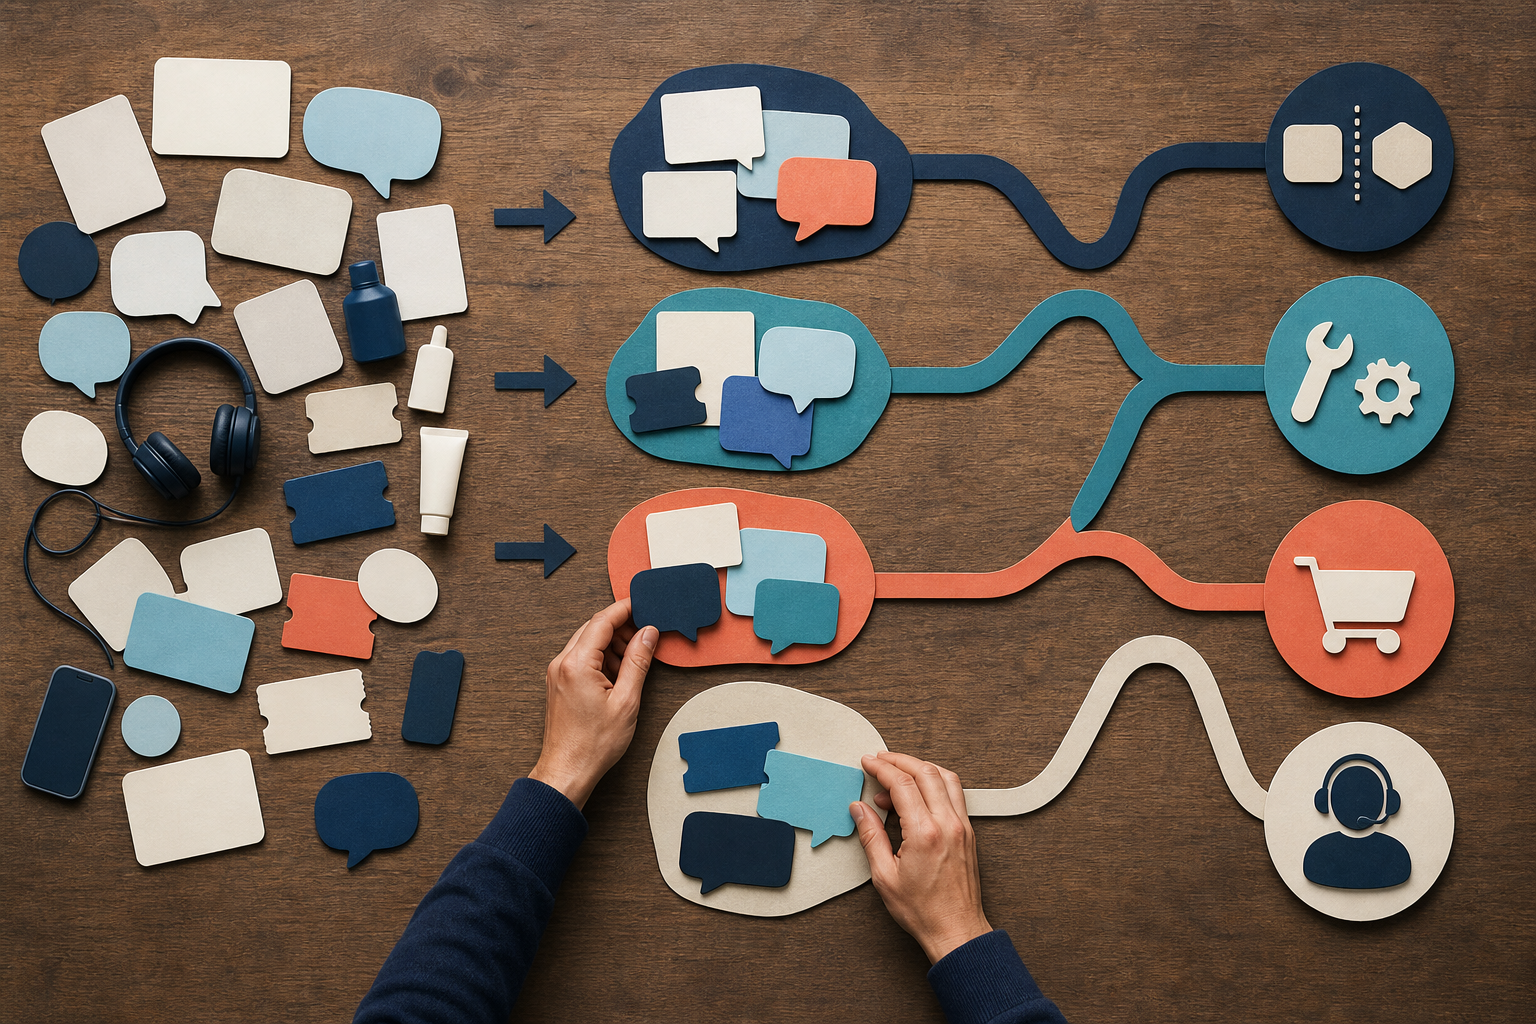
    A hand arranges blank cards, geometric icons, and colored connections into a branching map from a problem to a shortlist of options.

    Broad educational traffic can introduce a category, but recommendation prompts are often built from decision questions: What will this cost? What can go wrong? Which option suits my situation? How does one provider differ from another? Which choices are credible? If those answers are absent, vague, or hidden behind a sales form, the model must rely on whatever else it can find.

    Start with evidence of the language your buyers already use. Search Google Search Console queries, Google Business Profile activity, semantic question maps from tools such as AnswerThePublic, and competitive gaps found with Semrush or Ahrefs. Then add the higher-value material that keyword tools often miss: sales-call notes, live-chat transcripts, prospect emails, objections, support questions, customer feedback, and reasons a buyer rejected an option.

    Sort the questions into five decision categories. This answer-first framework is useful because each category resolves a different kind of buyer uncertainty:

    • Pricing and cost: Give a price, range, or pricing model when you can. Explain what changes the cost, what is included, what is excluded, and which buyer conditions produce a materially different quote. “Contact us” is not an answer.
    • Problems and limitations: Name the situations in which the product, service, or approach becomes difficult, expensive, slow, or unsuitable. Explain the cause, the consequence, and any available workaround. Acknowledging a real limitation makes the surrounding claims easier to trust.
    • Versus and comparisons: Compare options on criteria that affect the decision. State which option is better for which use case, where each creates a tradeoff, and what information the buyer should verify. Avoid declaring a universal winner when fit depends on context.
    • Reviews and evaluation: Help the buyer judge evidence rather than publishing unsupported praise. Describe the evaluation method, the relevant use case, what was observed, and what remains uncertain. Distinguish first-hand evidence from information collected elsewhere.
    • Best-in-class choices: Define the criteria before naming candidates. Include other businesses when they genuinely meet those criteria, explain the scenarios each suits, and disclose where your own offering does not win. The goal is to become a useful evaluator, not to turn every list into an advertisement.

    Prioritize a question when it is close to a purchase decision, repeatedly causes confusion, or exposes a material gap between your intended positioning and what AI answers currently say. Defer a question when you cannot support an answer with facts or when your business is not reasonably eligible for the recommendation. Publishing a confident page does not make an unsupported claim true.

    Give every planned page an answer brief with these fields: the exact buyer question, intended audience, direct answer, decision criteria, named entities, evidence, limitations, desired brand description, related questions, and external information that may confirm or contradict the answer. This keeps a content calendar from becoming a list of loosely related keywords.

    Write each page as a briefing that can stand on its own

    Do not make the reader or retrieval system cross an autobiographical introduction before reaching the answer. Open with the conclusion, identify the entity and context, and then supply the evidence and qualifications needed to use it correctly.

    A large citation analysis covering 1.2 million AI responses and 18,012 verified citations found that 44.2% of citations came from the opening 30% of the content. The middle portion supplied 31.1%, while the final portion supplied 24.7%. This does not mean the rest of a page is disposable. It means a conclusion saved for the final section has a weaker chance of framing how the page is interpreted and used.

    Use this sequence for an answer page:

    1. Answer the question immediately. Name the product, service, method, or category and state the conclusion in plain language.
    2. Qualify the answer. Identify the audience, conditions, version, location, plan, or use case that changes the conclusion.
    3. Expose the decision factors. Explain cost drivers, capabilities, limitations, dependencies, and meaningful alternatives.
    4. Support the important claims. Use first-party facts, transparent criteria, documented examples, and legitimate external corroboration. Remove claims you cannot substantiate.
    5. Resolve the next question. Link to the comparison, pricing, problem, review, or implementation answer the buyer will need next.

    A reusable opening can follow this pattern: [Offering] is best suited to [audience] when [condition]. It is a poor fit when [limitation]. The decision usually turns on [named criteria], so compare options using [evidence the buyer can verify]. Replace every bracket with a concrete fact. If the result still works for almost any competitor, the positioning is not specific enough.

    At paragraph level, the same citation analysis attributed 53% of matched citations to middle sentences, compared with 24.5% to opening sentences and 22.5% to closing sentences. Do not game that distribution by hiding every useful fact in sentence two. Page location and sentence location are different signals. The practical lesson is that the whole paragraph must carry meaning: lead with the claim, develop it with the condition or mechanism, and finish with the consequence instead of adding filler around one quotable sentence.

    Content that earned citations tended to use definitive language, question-and-answer organization, dense entity information, balanced sentiment, and business-grade clarity. Definitive does not mean absolute. “This platform is the best” is unsupported certainty. “This platform fits distributed teams that require these named controls, but it is unsuitable when these constraints apply” is a clear, bounded claim.

    Entity-rich writing is also different from keyword repetition. Name the company, product, category, audience, location, compatible systems, pricing model, and relevant alternatives where they affect the answer. Then keep those facts consistent across service pages, comparison pages, author information, policies, and structured data. If you use schema, align it with visible page content; do not ask markup to carry positioning or review claims that the reader cannot verify on the page.

    Connect your first-party facts to third-party trust
    A transparent bridge of evidence blocks connects a blue information hub with independent publication, laboratory, community, and library structures.

    Your website is the canonical place to explain what you sell, who it serves, how it is priced, and where it does not fit. It is not the only place an AI system may use to evaluate those facts. In wearable-technology queries, trusted third-party domains appeared more often than brand websites. That is a vertical-specific pattern, not proof that every market behaves identically, but it exposes a risk: a strong first-party explanation may still be outweighed by a better-established external account.

    Information layerIts jobWhat to inspect
    First-party websiteEstablish canonical facts and answer buyer questionsCategory, audience, capabilities, pricing, limitations, policies, authorship, and visible evidence
    Third-party ecosystemCorroborate, compare, review, or contextualize the brandAccuracy, recency, editorial independence, criteria, and conflicting descriptions
    AI responseSynthesize a recommendation for the buyerInclusion, message, omissions, errors, alternatives, and cited domains

    Audit these layers as one information system. Ask representative buyer questions, record the domains cited, and inspect what those pages say about your category and fit. Correct inaccurate pages you control. When a legitimate third-party page contains a material error, use its normal correction process and provide verifiable information. Do not manufacture reviews, disguised placements, or repetitive mentions; they do not create the independent trust you are trying to earn.

    Then look for honest gaps in external coverage. A reputable comparison may lack your category. A directory may use an obsolete description. An industry explainer may need a qualified expert contribution. A customer may be willing to document a real use case. Pursue only opportunities where your information improves the resource for its audience. The useful question is not “Where can we place our brand name?” but “Which independent pages help a buyer verify this claim?”

    Keep the facts synchronized. If your homepage calls the business an AI SEO platform, a service page calls it a content agency, and third-party profiles call it a WordPress plugin, the system has several plausible categories to choose from. Decide whether those are distinct offerings or inconsistent labels, then state the relationship explicitly on the relevant pages.

    Measure inclusion, message quality, citations, and outcomes

    A single screenshot showing your brand first for a favorable prompt is not a visibility report. Build the measurement set from the same buyer-question inventory that drives your content. Include prompts for cost, problems, comparisons, reviews, best-fit recommendations, and disqualifying conditions. Mark whether your brand is genuinely eligible for each prompt before judging the answer.

    For every check, record the platform, exact prompt, buyer intent, eligibility, whether the brand appeared, how it was described, any material error or omission, the alternatives mentioned, and the cited domains. Preserve the prompt wording because a response to a broad category request should not be compared casually with a response constrained by industry, budget, geography, or technical requirements.

    Use the resulting record to calculate and interpret these working KPIs:

    • Eligible inclusion rate: the share of prompts where the brand appeared among prompts for which it was a defensible recommendation.
    • Message accuracy rate: the share of appearances that contained no material category, audience, capability, price, or limitation error.
    • Positioning alignment: whether the response expressed the differentiators and fit conditions in your approved brand description.
    • Citation coverage: whether important claims were connected to accurate first-party or independent evidence rather than left unsupported.
    • Commercial contribution: qualified inquiries, assisted conversions, or customer-reported discovery connected to AI interactions. Add AI assistants as a selectable discovery path where you collect attribution, while allowing the buyer to describe the path in their own words.

    Keep mention position as a diagnostic field, not the primary success metric. If the brand is absent from eligible prompts, investigate answer coverage, entity clarity, discoverability, and external corroboration. If it appears with the wrong description, reconcile positioning and factual inconsistencies. If it appears accurately but buyers do not progress, inspect the offer, fit, proof, and next step rather than producing more visibility content by default.

    Review results by decision category. A healthy inclusion rate for broad educational prompts can conceal an absence from high-intent comparisons. Likewise, a citation win can conceal damaging language about price or suitability. The unit of analysis is the buyer decision, not the total number of mentions.

    Start with the high-intent question that has the weakest current answer. Rewrite its opening, add the missing fit and limitation facts, connect it to credible evidence, and check how the exact buyer question is answered. Record the first discrepancy and fix it at the layer where it originates. Expanding that disciplined pattern across your question map will do more for durable AI visibility than producing another collection of interchangeable keyword pages.

    References

  • What Perplexity’s Ad Retreat Means for AI Search Strategy

    What Perplexity’s Ad Retreat Means for AI Search Strategy

    If Perplexity appears in your paid AI media plan, change the plan, not the audience strategy. The company has phased out its sponsored-placement experiment and has no current intention of bringing it back. Brands can still pursue visibility across Perplexity’s answers, but they cannot currently treat that visibility as inventory they can buy.

    The practical shift is from placement control to evidence quality. You need content that an answer engine can understand, claims it can support, a brand it can identify consistently, and measurement that distinguishes citations from mentions, referrals, and actual business results.

    Perplexity is treating trust as part of the product

    Perplexity began testing sponsored placements in 2024. Sponsored answers appeared beneath chatbot responses, were labeled as advertising, and were presented as separate from the system’s answer selection. The experiment still created a deeper problem: disclosure can identify a commercial relationship, but it cannot force a user to believe that the surrounding answer is free from commercial influence.

    That distinction matters in an answer engine. A conventional results page visibly separates advertisements from organic links and leaves the user to choose among them. An AI interface synthesizes information into a direct response. If an advertisement sits close to that response, the user may wonder whether payment affected the conclusion, even when the company says it did not. Perplexity decided that protecting the belief that users receive the best available answer was more valuable than continuing the test.

    This is not simply an anti-advertising position. It is a choice about which revenue model creates the least damaging perceived conflict. Perplexity is relying primarily on subscriptions, with paid plans reported between $20 and $200 per month, more than 100 million users, and approximately $200 million in annual revenue. Those are reported company-scale figures, not proof that subscriptions will fund every future ambition, but they explain why Perplexity can give trust more weight in the trade-off.

    The same boundary appears in commerce. Perplexity has introduced shopping features but does not take a cut of the transaction. That keeps the platform from earning more merely because it recommends one purchasable result over another. Subscriptions still create business incentives, but the revenue connection is more direct: users pay for access rather than brands paying for proximity to an answer.

    Do not turn the current decision into a permanent promise. A platform strategy can change as costs, competition, and user behavior change. Treat Perplexity as ad-free for planning purposes while maintaining a watchlist for any documented relaunch, rather than building a forecast around an assumed future product.

    Remove paid Perplexity inventory from forecasts, not Perplexity from the plan

    Perplexity reportedly handles 780 million queries per month. That signals substantial usage, but it is not an advertising forecast. Query volume does not tell you how many impressions a brand could buy, which audiences would be reachable, what targeting would exist, or whether exposure would produce qualified visits. Without an active ad product, it cannot be converted into CPMs, clicks, or revenue projections.

    If you own a media plan, make four operational changes:

    1. Move Perplexity advertising out of committed spend. Do not promise inventory, delivery, or launch dates based on the discontinued test. That creates a budget gap and a client commitment you cannot fulfill.

    2. Keep Perplexity in the discovery strategy. Assign ownership to the SEO, AEO, GEO, content, or digital PR workstream responsible for earned visibility.

    3. Preserve relevant creative and audience hypotheses. If ads return, the messaging lessons may remain useful even if the eventual format, targeting, and reporting differ.

    4. Define relaunch evidence in advance. Require an official product announcement, access terms, placement rules, pricing, labeling, targeting, measurement, and brand-safety controls before moving money back into the forecast.

    Do not create one universal policy for all AI products. At the time Perplexity ended its experiment, OpenAI was testing ads for free ChatGPT users, Google was placing ads in AI Mode but not Gemini, and Anthropic was keeping Claude ad-free. Monetization can differ between companies and between products owned by the same company.

    Your channel sheet should therefore use the product surface as the unit of planning. For each surface, record the current ad status, who can access it, where sponsorship appears, how it is labeled, what can be targeted, which reports are available, and when the status was last verified. A row labeled only “AI advertising” is too broad to support a real budget decision.

    Build the visibility that sponsored answers can no longer provide

    A bridge assembled from documents, evidence blocks, and verification seals leads toward a glowing abstract answer engine.

    You cannot choose where Perplexity mentions or cites you in the way you choose an ad placement. You can improve the inputs that make your organization useful as an answer source. The goal is eligibility and clarity, not a guaranteed citation.

    1. Map the questions that precede a decision. Include problem-identification queries, category questions, comparisons, brand-verification questions, objections, risks, and action-oriented queries. Use the language customers use, not only the terms in your navigation.

    2. Give each important page a clear answer job. State the useful answer near the top, then support it with definitions, evidence, limitations, examples, and next steps. A page that hides its conclusion behind a long preamble makes the core claim harder for both people and machines to isolate.

    3. Make claims attributable. Identify who produced the information, when it was updated, what the claim covers, and where its limits begin. If you publish original data, explain the method and scope. If you make a comparison, name the criteria instead of declaring a vague winner.

    4. Keep entity facts consistent. Your company name, product names, author names, service descriptions, locations, and ownership relationships should agree across the site. Conflicting facts create an identification problem before they create a ranking problem.

    5. Use structured data to clarify, not decorate. Organization and Person markup can express publisher and author identity; Article can describe editorial content; Product belongs on genuine product pages; and FAQPage should represent questions and answers visitors can actually see. JSON-LD can make relationships explicit, but it cannot rescue unsupported claims or guarantee inclusion in Perplexity.

    6. Close evidence gaps outside your site. If competing brands are repeatedly supported by independent explanations, reviews, or industry references and yours is not, publishing more self-description may not solve the gap. Give credible third parties something verifiable to reference: transparent data, a useful tool, clear documentation, expert commentary, or a defensible point of view.

    7. Maintain the pages that carry important facts. Correct obsolete details, preserve useful URLs, show meaningful update information, and avoid leaving contradictory versions live. An answer engine cannot reliably resolve a disagreement your own site has not resolved.

    This work should not imitate an advertisement. Promotional adjectives, unsupported superlatives, and repeated brand mentions add little evidence. A strong answer asset lets the underlying facts do the selling: it answers the question, shows why the answer is credible, states who the answer is for, and acknowledges conditions where a different choice may be better.

    Trust is also part of your own publishing system. Label sponsorships, disclose affiliate relationships, separate editorial conclusions from commercial arrangements, and make corrections visible. Perplexity’s decision shows why technical disclosure alone is not enough. Readers also judge whether the surrounding incentives could have shaped the answer.

    Measure answer visibility without pretending it is a fixed ranking

    Multiple translucent lenses show different arrangements of source cards and pathways around a spherical answer engine.

    A generative answer is an observation made under particular conditions, not a permanent search position. Record enough context to reproduce the check: the exact prompt, date and time, account state, answer text, brand mentions, cited URLs, linked pages, competitor mentions, and whether each statement about your brand is accurate.

    Repeat the same query set on a fixed cadence and preserve the results. If you change prompts continually, you cannot tell whether the platform changed or the question changed. If you check only once, you cannot distinguish a durable pattern from normal answer variation.

    Observed stateWhat it meansWhat to do next
    Cited and described accuratelyYour page is functioning as supporting evidence for that query.Preserve the useful URL, keep its facts current, and examine which passage appears to support the answer.
    Mentioned without a citationThe brand is present, but the answer does not visibly attribute the claim to your page.Identify the claim being made and strengthen the page that can support it with explicit, attributable evidence.
    Cited but described inaccuratelyVisibility is creating a reputation or conversion risk.Publish the correct fact prominently, remove contradictions, verify canonical pages, and monitor whether the answer changes.
    Absent while relevant competitors appearThe gap may involve content coverage, entity clarity, evidence quality, or independent corroboration.Compare the cited pages by question answered, evidence supplied, freshness, specificity, and source authority. Fix the missing component instead of copying their wording.
    Results vary across repeated checksThe evidence is not stable enough for a strategic conclusion.Expand the observation history and avoid reporting a gain or loss until a pattern emerges.

    Separate visibility metrics from outcome metrics. Useful visibility measures include brand inclusion rate, citation coverage, citation accuracy, and share of observed answers relative to named competitors. Outcome measures include referral sessions, engaged visits, assisted conversions, leads, and revenue from identifiable Perplexity traffic. A citation can be strategically valuable without generating a click, but that does not justify presenting it as traffic or sales.

    When a result changes, diagnose it at the query-and-page level. Ask which claim disappeared, which URL replaced yours, whether your linked page changed, and whether the competing evidence is more direct. A single sitewide “AI visibility score” can be useful for reporting direction, but it cannot tell an editor which paragraph, fact, entity relationship, or evidence gap needs attention.

    Key takeaways

    • Perplexity’s discontinued ad test removes a direct paid route to its audience; it does not remove the audience from your search strategy.

    • Labeled advertising can satisfy disclosure requirements while still weakening perceived answer independence. Trust depends on incentives as well as interface labels.

    • Do not convert monthly query volume into an advertising forecast when no active inventory, targeting, pricing, or reporting product exists.

    • Treat Perplexity visibility as earned. Improve answer coverage, attributable evidence, entity consistency, structured data, independent corroboration, and factual maintenance.

    • Measure citations, uncited mentions, accuracy, competitor inclusion, referrals, and conversions separately. They answer different business questions.

    • Track advertising status by product surface. ChatGPT, Google AI Mode, Gemini, Claude, and Perplexity do not share one monetization policy.

    Start by moving Perplexity from the paid-inventory line of your plan into an owned-and-earned AI visibility workstream. Establish a repeatable query set, capture the current baseline, and assign each meaningful gap to a specific page, fact, schema relationship, or authority-building task. If advertising returns, evaluate the actual product then. Until it does, the durable advantage is being useful enough to earn a place in the answer.

    References

  • Boost Your SEO Team’s AI Confidence: A Step-by-Step Guide

    Boost Your SEO Team’s AI Confidence: A Step-by-Step Guide

    With over twenty years in SEO, I’ve experienced every major industry disruption—from the days of keyword stuffing on AltaVista to the era of Google’s search algorithms, mobile-first indexing, and now the rise of AI.

    What’s striking today is the rapid pace of change and the emotional challenges it brings. I notice mounting pressure among teams, even those who have navigated previous shifts successfully.

    The common apprehension is valid: If AI improves speed, where does that leave me? This isn’t just a technical question—it’s deeply personal.

    This uncertainty can lower morale and slow adoption. Productivity can wane, and experimentation might stall, leading teams to either over-rely on AI or completely avoid it.

    The real leadership challenge is building confidence, capability, and trust in AI-assisted teams.

    4 Ways to Boost AI Confidence in SEO Teams

    Instilling genuine AI confidence within an SEO team goes beyond just adopting the latest tools—it’s a cultural shift.

    The most effective SEO teams don’t just accumulate tools; they use AI purposefully and with discipline—automating data pulls, summarizing research, and clustering keywords—to devote more time to strategy, storytelling, and aligning with stakeholders.

    As noted by Harvard Business School, technology adoption is largely cultural. Tools themselves don’t drive change—trust does. This insight is crucial for SEO teams navigating AI today.

    Below are four strategies for enhancing AI confidence in your teams through clarity, participation, and shared ownership, instead of pressure or hype.

    1. Earn Trust by Involving the Team in AI Tool Selection and Workflow Design

    Strengthening trust can effectively be achieved by transitioning from a top-down approach to shared ownership. People generally trust what they help create.

    When AI tools are imposed, resistance can increase. Inviting team members to participate in evaluation and workflow design makes AI seem less daunting and more empowering. Involving teams early provides real-world insights into where AI can reduce friction or introduce new challenges.

    Effective leaders:

    • Invite teams to test tools and share feedback.
    • Run small experiments before scaling adoption.
    • Communicate clearly about what you’re adopting, what you’re rejecting, and why.

    When teams feel included, they are more willing to experiment, and growth and innovation are fueled.

    Dig deeper: Why SEO teams need to ask ‘should we use AI?’ not just ‘can we?’

    2. Meet People Where They Are—Not Where You Want Them to Be

    AI capability varies widely across SEO teams. Some members might experiment daily, while others feel inundated or skeptical, influenced by past automation trends that have come and gone.

    Leaders who boost confidence know that capability develops at different speeds. They cultivate environments where curiosity is encouraged, uncertainty is acceptable, and learning is continuous rather than mandated.

    This means:

    • Normalizing different comfort levels.
    • Creating psychological safety around “I don’t know yet.”
    • Avoiding the shaming or over-celebration of early adopters.
    • Offering multiple learning paths.

    Acknowledging different starting points makes growth seem attainable rather than intimidating.

    @media (max-width: 768px) {.headline-responsive {font-size: 30px !important; line-height: 1.3 !important;}}

    3. Celebrate Wins and Highlight Champions

    Confidence builds with visible success.

    When a team member uses AI to reduce a task from hours to minutes, it’s a moment worth recognizing. It demonstrates AI’s potential to support meaningful work without sidelining human insight.

    Successful teams:

    • Share clear examples of AI improving quality and efficiency.
    • Highlight internal champions who can mentor others.
    • Create opportunities for demos and knowledge sharing.
    • Foster a culture of exploration, not criticism.

    My agency created AI focus groups with members from various departments. One group worked on integrating AI into project management, including representatives from SEO, operations, and leadership.

    This collaborative ownership resulted in more successful implementation. Teams were not just introducing AI; they were defining how it fit within real-world workflows. This approach led to enhanced buy-in, improved collaboration, and increased confidence.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    Each group shared its achievements and lessons learned, building awareness of what succeeded and the reasons behind that success. When teams observe their peers embracing AI effectively, momentum flourishes.

    Dig deeper: The future of SEO teams is human-led and agent-powered

    4. Frame AI as a Collaborative Partner, Not a Replacement

    The fear of being replaced by AI is genuine. Ignoring this concern won’t make it disappear. It’s vital for teams to understand where human expertise remains indispensable.

    Reframing AI as a partner involves highlighting:

    • AI handles volume. Humans handle nuance.
    • AI accelerates analysis. Humans interpret meaning.
    • AI drafts. Humans validate, refine, and contextualize.
    • AI scales output. Humans build trust and influence.

    While AI aids execution, it cannot replace strategic instincts, contextual judgment, or cross-functional leadership—skills that ultimately drive performance.

    Why Experience Still Matters in AI-Driven SEO

    AI has lowered the entry barrier for many SEO tasks. With effective prompts, nearly anyone can produce keyword lists, outlines, or summaries. However, this accessibility often results in fleeting tactics and recycled quick fixes. 

    Anyone with a lengthy tenure in SEO recognizes this cycle. Tactics evolve. Fundamentals remain. Experience is the key differentiator here.

    AI Can Generate Outputs, Not Accountability

    AI can create content and analyze data, but it doesn’t bear responsibility for outcomes. It doesn’t uphold brand reputation, compliance, or long-term performance.

    SEO professionals remain responsible for:

    • Deciding what to exclude from publication.
    • Assessing technical, reputational, and compliance risks.
    • Weighing long-term consequences against short-term gains.

    AI executes. Humans decide. That distinction matters more than ever.

    Pattern Recognition Is Learned, Not Automated

    AI excels at identifying patterns but struggles to explain their significance or relevance in specific contexts.

    Experienced SEOs bring a depth of understanding AI can’t replicate. Their historical insights help them identify true shifts instead of simply reacting to industry noise. 

    Few industries witness as many tactic fluctuations as SEO. Experience fosters strategic thinking beyond previously successful approaches and avoids repeating tactics that later failed.

    AI suggests possibilities. Experience evaluates relevance.

    Professional Integrity Remains a Differentiator

    In high-visibility search environments, mistakes scale quickly. AI may produce inaccuracies, risking brand trust and compliance dangers.

    Teams with strong professional SEO foundations:

    • Validate AI output instead of assuming correctness.
    • Prioritize accuracy over speed.
    • Maintain ethical SEO standards.
    • Protect brand voice and credibility.

    Integrity isn’t automated. It’s a practiced discipline. In a fast-paced AI environment, it holds increasing importance.

    Dig deeper: How to build and lead a successful remote SEO team

    Growing the SEO Profession in an AI Era

    AI is accelerating SEO execution.

    As routine tasks become automated, the role of an SEO professional shifts to strategic oversight. Time previously spent on manual analysis can now focus on interpreting user intent, shaping search strategy, guiding stakeholders, and assessing risks.

    This evolution makes fundamentals even more critical. Teams still need sound judgment, technical expertise, and accountability. While AI supports execution, professionals remain responsible for decisions, quality, and long-term performance.

    Developing future SEOs necessitates more than tool proficiency; it requires teaching:

    • When to rely on AI.
    • When to question AI outputs.
    • How to apply experience and context to its output.

    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google AI Overview Interactive Links: An SEO Action Plan

    Google AI Overview Interactive Links: An SEO Action Plan

    If your page appears in Google’s generated answers, earning the citation is only the first part of the job. A searcher still has to notice your link, understand what it offers and choose it from the other available sources.

    Google’s interactive link treatment gives that choice more visual weight. It may create a better route from an AI answer to your site, but it does not guarantee more traffic. Your practical response is to improve the pages behind likely citations and establish a measurement process that does not confuse correlation with proof.

    The click path now has a visible choice layer

    Google has made groups of links in AI Overviews and AI Mode open in a pop-up when a desktop user hovers over them. These cards provide more context about the linked websites, giving the user a clearer opportunity to leave the generated response and investigate a source.

    The behavior is different on mobile because there is no hover action. Google is instead using more descriptive and prominent link icons across desktop and mobile. That distinction matters when you audit visibility: a desktop screenshot of an open link group and a mobile screenshot of a link icon are observations of two related but different interfaces.

    This creates an additional choice point in the search journey:

    • Your page first has to be selected as a supporting source.
    • The searcher then has to notice and choose it within the link interface.
    • The landing page has to confirm quickly that the click was worthwhile.

    That middle step is the important change. A citation can now be exposed through a richer, more noticeable interaction, but greater visibility is not the same as a visit. The other links in the group remain alternatives, and the user may decide that the generated answer is already sufficient.

    Google says its testing found the interface more engaging and made web content easier to reach. Treat that as a directional product finding, not a traffic forecast for your site. The result depends on whether you are cited, how your option is presented, what else appears beside it and whether the searcher still needs more information.

    Optimize for citation, choice and landing-page confirmation

    A structured webpage connects to a highlighted source card and then to a visually matching landing page.

    Do not infer a new markup requirement from the interface. A new visual treatment is not evidence of a special interactive-link schema or a new ranking signal. Keep valid structured data where it accurately describes the page, but do not invent properties or rename schema solely to chase the pop-up.

    Instead, audit the whole path from the question to the page. Start with URLs that directly answer the questions your audience asks and that already receive impressions for relevant queries. Then review each candidate against the following criteria:

    • Question alignment: The page should address the searcher’s actual problem, not merely mention the same entity or keyword. If the relevant answer is a minor aside, give it a focused section or use a better page.
    • Immediate answer: State the useful answer near the beginning of the relevant section. A reader arriving from an AI response should not have to reconstruct it from a long introduction.
    • Descriptive headings: Use section headings that identify the decision, process or distinction being explained. Generic headings make both scanning and passage-level understanding harder.
    • Clear page promise: Make the title specific enough to distinguish your page from adjacent sources. The wording should describe what the visitor will learn without promising evidence, scope or freshness the page does not provide.
    • Visible substantiation: Put definitions, qualifications and supporting evidence close to the claims they support. Add authorship and update information when those details genuinely help a reader judge the material.
    • Landing-page continuity: The heading and opening visible after the click should confirm that the visitor reached the expected answer. If the title promises a procedure but the page begins with a broad industry essay, the click has created friction.
    • Useful next step: Once the immediate question is answered, provide a relevant route to a deeper explanation, tool, product category or decision page. Do not force that continuation before delivering the answer that earned the visit.
    • Mobile usability: Check the page on a narrow screen. A prominent mobile link is of little value if overlays, slow media, crowded navigation or an unclear opening block the answer.

    Keep these improvements honest. Rewriting every heading as a question, repeating the same answer in several sections or adding unsupported claims may make a page look optimized while making it less useful. The goal is not to imitate an AI response. It is to make the underlying page the clearest place to verify, understand and act on the answer.

    You should also separate interface optimization from eligibility. Better titles, openings and page structure can improve the experience when your page is shown, but they do not guarantee inclusion in an AI Overview or AI Mode response. Record inclusion and post-click performance as separate outcomes so a content change is not credited for something it did not cause.

    Measure impact without inventing attribution

    Glowing visitor paths pass through a transparent observation frame between an abstract search panel and a website panel.

    The rollout does not provide a dedicated way to isolate the impact of interactive links in Google Search Console. Existing search metrics can show that a page’s performance changed, but they cannot by themselves prove that a hover card or a more prominent icon caused the change.

    Use two connected records: a manual visibility log for the interface and your normal performance data for outcomes.

    1. Create a fixed watchlist of commercially or editorially important questions. Avoid changing the query set whenever you see an interesting result, because that makes comparisons inconsistent.
    2. For every observation, record the query, date, device type and whether you checked AI Overviews or AI Mode. Note whether your URL appeared, what context was visible and which other sites shared the link group.
    3. Save a screenshot when the interface or citation changes. The screenshot preserves evidence that aggregate analytics cannot supply later.
    4. Before editing a candidate page, export its Search Console impressions, clicks and click-through rate by page, query and device. Preserve that baseline rather than relying on memory.
    5. Annotate the date and substance of every material content change. Changing the title, answer, structure and conversion path simultaneously will make the result difficult to interpret.
    6. Review on-site sessions and meaningful outcomes for the same landing pages. Choose outcomes that fit the page, such as a completed signup, a qualified inquiry, a product-view continuation or another defined conversion.
    7. Compare the edited pages with relevant pages you did not change. This does not create perfect causal proof, but it can help you notice whether a movement is page-specific or widespread.

    Interpret the patterns carefully. More observed citations with flat clicks can mean that visibility improved without winning the user’s choice. Higher visits with weak engagement can reveal a mismatch between the visible promise and the landing page. Stronger engagement or conversions without a clear Search Console shift can still justify improving the post-click journey, but it does not prove the interactive links supplied the visitors.

    Seasonality, ranking changes, query demand, competing results and your own edits can move the same metrics. Use language such as associated with or observed after when reporting the result internally. Reserve caused by for evidence that can actually isolate the interface.

    Key takeaways

    • Desktop users can reveal grouped links in AI Overviews and AI Mode by hovering, while both desktop and mobile receive more prominent, descriptive link icons.
    • The interface increases the visibility of source choices; it does not guarantee that a citation will produce a click.
    • There is no basis here for adding a special interactive-link schema. Concentrate on accurate structured data and a page that clearly fulfills the cited question.
    • Audit three separate stages: citation inclusion, selection from the link group and post-click performance.
    • Search Console cannot isolate the feature’s impact, so combine a manual query log with page-, query- and device-level performance data.
    • Report changes as directional unless you can separate the interface from rankings, demand, competing results and content edits.

    Start with a small, stable watchlist and capture the baseline before changing anything. Improve the pages where a clearer answer and a better landing experience would help regardless of how Google’s interface evolves. That gives you useful content now and credible evidence when the link treatment changes again.

    References

  • ChatGPT Conversion Rates by Industry: 2026 Benchmarks

    ChatGPT Conversion Rates by Industry: 2026 Benchmarks

    If ChatGPT has started appearing in your referral report, the hard question isn’t whether the traffic exists. It’s whether your conversion rate is healthy enough to justify more investment or weak enough to expose a broken landing path.

    Industry context helps, but only when you use it as a diagnostic. Reported 2026 rates run from 1.4% to 7.0%. That spread reflects more than differences in demand: participating companies defined their own conversion actions, and most had already invested in generative engine optimization and ChatGPT-focused funnels. Match the definitions before you match the percentages.

    Key takeaways for evaluating ChatGPT conversions

    • The 2026 industry range is 1.4% to 7.0%, with hotels and resorts at the high end and engineering at the low end.
    • A conversion was whatever action each participating company had designated, so the rates do not represent one uniform outcome.
    • Most participating companies had invested in GEO and dedicated ChatGPT funnels. Treat the figures as an optimized-cohort reference, not a universal market average.
    • Absolute conversion rate and improvement over traditional SEO are different measurements. You need your own matched SEO baseline to calculate channel lift.
    • Keep direct ChatGPT referrals separate from broader AI influence so that attribution assumptions do not distort your benchmark.

    2026 ChatGPT conversion benchmarks by industry

    Six differently shaped visitor pathways lead to geometric goals beside objects representing retail, software, finance, travel, healthcare, and business services.

    Between May 2025 and February 2026, anonymous client data from more than 150 companies measured the proportion of ChatGPT referral traffic that completed a conversion action defined by each company. Most companies in the cohort had higher-than-average ChatGPT referral traffic, prior GEO investment, and a dedicated conversion path for that traffic.

    That context matters. These are useful reference points for a company actively optimizing AI discovery and its post-click experience. They are not reliable predictions for an unoptimized site, and they should not be inserted directly into a revenue forecast.

    IndustryReported average conversion rate
    Addiction Treatment2.9%
    Apparel & Fashion2.8%
    B2B SaaS2.4%
    Biotech2.1%
    Commercial Insurance3.1%
    Construction3.4%
    eCommerce3.0%
    Engineering1.4%
    Entertainment4.7%
    Environmental Services2.0%
    Financial Services1.9%
    Food & Beverage3.4%
    Healthcare4.5%
    Heavy Equipment1.8%
    Higher Education & College4.9%
    Hotels & Resorts7.0%
    HVAC Services3.9%
    Industrial IoT3.9%
    IT & Managed Services2.4%
    Legal Services5.6%
    Luxury Goods1.9%
    Manufacturing3.8%
    Medical Device2.3%
    Oil & Gas3.2%
    PCB Design & Manufacturing2.9%
    Pest Control3.8%
    Pharmaceutical3.2%
    Real Estate2.8%
    Software Development1.8%
    Solar3.5%
    Staffing & Recruiting3.7%
    Transportation & Logistics1.9%

    The useful comparison is your rate against the row for your industry and a matched conversion event, not against the highest rate in the table. A hotel booking and an engineering inquiry represent different commitments. Even two companies in the same industry may assign conversion status to different actions.

    What the industry spread does and does not prove

    The leading rates identify a pattern, not its cause

    Hotels and resorts led at 7.0%, followed by legal services at 5.6%, higher education and college at 4.9%, entertainment at 4.7%, and healthcare at 4.5%. Engineering recorded 1.4%; heavy equipment and software development each recorded 1.8%; financial services, luxury goods, and transportation and logistics each recorded 1.9%.

    Those rates show where conversions landed, not why. Buying urgency, brand strength, traffic mix, conversion definition, landing-page quality, and the amount of friction in the next step are all plausible contributors. None can be isolated from an industry-level rate alone.

    A useful working hypothesis is that conversational search can pre-qualify some visitors. A user can describe a detailed problem, refine the request, and narrow the options before clicking. That can produce a visitor who is closer to a decision than someone arriving through a broad search query. Test that hypothesis against lead quality and downstream outcomes rather than treating it as a settled explanation.

    Complexity can improve channel lift without producing the highest rate

    Commercial insurance converted at 3.1%, while pharmaceuticals converted at 3.2%. Neither sits near the top of the absolute rankings. Their significance lies in the reported advantage over traditional search for complex buying decisions, not in having the largest raw percentages.

    No industry-by-industry traditional SEO baseline rates accompany these ChatGPT figures, so you cannot calculate a defensible uplift from the benchmark alone. Likewise, B2B sectors showed larger improvements over traditional SEO than B2C sectors, but no specific lift values are provided. Treat that distinction as directional until your own analytics can compare the same conversion event over the same measurement period.

    Referral conversion is narrower than total AI influence

    The benchmark measures referral traffic from ChatGPT. It does not represent every buyer who encountered a company in an AI answer and later arrived through direct traffic, branded search, email, or another channel. Mixing those journeys into the referral denominator would make your result incomparable with the industry figures.

    Maintain two views. Use direct ChatGPT referral conversion rate for the industry comparison. Use a separate assisted or influenced view for broader journey analysis, with its attribution assumptions documented. The first tells you how referred visits perform; the second helps you investigate whether AI visibility contributes elsewhere in the buying journey.

    Build an internal benchmark you can defend

    Two hands align visitor tokens, transparent funnels, landing-page tiles, a magnifying lens, and goal markers on an analyst's worktable.

    A percentage becomes useful only when everyone knows what entered its numerator and denominator. Build the internal benchmark in this order:

    1. Choose one primary conversion for each buying motion. For lead generation, distinguish an initial inquiry from a qualified lead, booked meeting, or sales opportunity. For commerce, keep completed purchases separate from add-to-cart and checkout events. Micro-conversions can remain diagnostic metrics, but blending them into the primary rate makes the result easier to inflate and harder to interpret.
    2. State the attribution scope. Label the series as direct ChatGPT referral traffic. If you also model assisted AI influence, store it as a separate series rather than silently adding it to the direct result.
    3. Keep the denominator with the rate. Calculate the percentage from completed primary conversions attributed to ChatGPT referrals divided by all ChatGPT-referred visits, multiplied by 100. Report the visit count, conversion count, conversion rate, event definition, and measurement period together. A rate without its underlying counts can look stable when it is not.
    4. Create a like-for-like comparison. Compare ChatGPT with traditional SEO using the same primary event, date range, geography, device rules, and treatment of new and returning visitors. Annotate any mismatch instead of presenting the resulting difference as channel lift.
    5. Segment by observable landing paths. Break performance down by landing page, content cluster, offer, and call to action. Do not claim to know the user’s original prompt if you did not capture it. The page visited and the actions taken on your site are evidence; an inferred prompt is a hypothesis.
    6. Connect the event to business quality. For lead generation, carry the referral source into qualification and opportunity reporting. For commerce, connect it to completed orders rather than stopping at a checkout signal. A high top-of-funnel conversion rate can still be commercially weak if the resulting leads or orders do not meet the business definition of value.
    7. Choose the decision rule before changing the funnel. When traffic volume supports a controlled test, define the success event and comparison method in advance. When referral volume is sparse, report the uncertainty, group genuinely similar landing paths where appropriate, and avoid declaring a winner from a volatile percentage.

    This process also prevents a common benchmarking mistake: celebrating a rate above the industry figure when your conversion event is easier to complete. A newsletter signup should not be compared with a booked consultation, completed application, or purchase simply because every event has been labeled a conversion.

    Turn the performance pattern into the right next move

    Judge high and low performance relative to a matched industry rate and your own stable history. Then use the combination of referral volume, primary conversion rate, and downstream quality to decide what to investigate.

    Observed patternWhat it may indicateWhat to do next
    Low ChatGPT referral volume with a healthy matched conversion rateThe post-click path may work, while AI discovery or citation coverage is limited.Audit the questions and decision criteria covered by your content. Strengthen pages that contain evidence, clear entity information, and a natural path to the existing conversion action.
    Healthy referral volume with a low matched conversion rateChatGPT visibility is producing clicks, but the landing experience may not continue the user’s intent.Rank landing pages by referred visits, then examine message continuity, proof, call-to-action relevance, and form or checkout friction on the highest-volume cluster.
    Healthy conversion rate with weak qualified-lead or revenue performanceThe primary event may be too shallow, or the offer may attract the wrong kind of demand.Move the primary benchmark deeper into the funnel, preserve the shallow event as a diagnostic metric, and evaluate results by qualified outcome.
    An apparently high rate supported by a small denominatorNormal variation may be creating a persuasive but unstable percentage.Show the counts, gather more observations, and avoid projecting the rate into a budget or revenue model until it becomes decision-worthy.
    ChatGPT and SEO rates calculated from different events or attribution rulesThe apparent channel lift may be a measurement artifact.Rebuild both series around the same event and scope before changing channel investment.

    Do not respond to an underperforming benchmark by rewriting every page that receives a ChatGPT referral. Start with the content cluster responsible for the most referred visits and select one failure point: intent mismatch, missing proof, an irrelevant next step, or conversion friction. Preserve the baseline and record the change so the next measurement has a clear before-and-after boundary.

    Your immediate task is to name the primary conversion, export ChatGPT-referred visits and completed events for the same period, and compare the result with the matched industry row. The benchmark has done its job when it points you to one tracking correction or one funnel test. It has not done its job when it becomes a percentage copied into a forecast without the definitions that produced it.

    References

  • How to Use AI-Powered Advertising Without Losing Control

    How to Use AI-Powered Advertising Without Losing Control

    Your ad platform can now reach beyond the audience you selected, produce analysis inside the campaign interface, and decide which entertainment title is most likely to interest a viewer. Those capabilities may all carry the AI label, but they do not create the same risk or require the same supervision.

    Your job is not to recover every manual lever. It is to decide what the system may optimize, which boundaries it must respect, and what evidence it must produce before you give it more budget. That requires a control system built for automation rather than a longer list of settings.

    The control surface has moved from audience settings to campaign inputs

    Manual advertising made control easy to see. You selected an audience, chose a similarity range, and expected delivery to remain within it. AI-led delivery weakens that visual connection. A setting can influence the model without defining the final audience.

    Google’s announced March 2026 change to Demand Gen Lookalike segments illustrates the shift. Narrow, balanced, and broad similarity tiers become optimization signals instead of rigid targeting limits. Google can reach beyond the selected segment when its system predicts that other users are likely to convert.

    That distinction changes how you should read the campaign setup. A Lookalike tier still communicates useful direction, but it no longer answers the eligibility question by itself. Optimized Targeting remains a separate feature, and layering it with Lookalike signals can give the system additional room to expand.

    Before you launch or diagnose an AI-powered campaign, classify every important input as one of four things:

    • Objective: the result the platform is being asked to maximize, such as a purchase, subscription, ticket sale, or another conversion.
    • Signal: information that helps the model search, such as a seed audience, similarity tier, genre preference, or observed price sensitivity. A signal provides direction; it does not necessarily restrict delivery.
    • Constraint: a boundary the campaign must not cross, such as a spend ceiling, eligible territory, product restriction, or contractual audience requirement.
    • Observation: a metric you use to understand behavior but have not asked the model to optimize, such as reach, conversion rate, or downstream customer quality.

    Do not call a signal a constraint unless the platform’s current behavior explicitly guarantees it. If a territory, age rule, customer exclusion, or other eligibility condition is commercially or legally important, confirm the setting that enforces it. An audience seed is not a safe substitute for a hard boundary.

    Keep a campaign change log with the date, campaign, previous setting, new setting, whether the change was automatic or manual, the expected effect, and the person responsible for reviewing it. This small record becomes essential when the platform changes its interpretation of a familiar control. Without it, a sudden increase in reach can look like creative success when it was actually caused by audience expansion.

    Write an optimization contract before you spend

    A human hand adjusts safety stops around a tabletop model containing audience figures, creative tiles, budget tokens, and an objective marker.

    An AI system can optimize only what you make legible to it. If the selected conversion event is a weak proxy for the business result, the platform can improve its own score while sending the campaign in the wrong direction. A system asked to find inexpensive page visits should not be expected to discover profitable customers by implication.

    Write a short optimization contract for each campaign. It does not need legal language or a new software tool. It needs six explicit decisions:

    1. Name the business outcome. State what has to happen outside the advertising interface: a paid subscription, completed ticket purchase, qualified opportunity, retained customer, or another result that matters to the business.
    2. Name the platform event. Record the event the platform can observe and optimize. If that event occurs earlier than the business outcome, describe the gap instead of pretending the two are equivalent.
    3. Choose one primary score. CPA, conversion rate, conversion volume, and reach answer different questions. Select the metric that decides whether the test passes, then use the others for diagnosis.
    4. Set economic and eligibility boundaries. Use your actual unit economics to define an acceptable acquisition cost and a campaign spend limit. Record territories, offers, audiences, and products that are not eligible for expansion.
    5. Define the quality check. Decide how you will notice low-value conversions. Depending on the campaign, that may be completed purchases, valid subscriptions, qualified leads, attendance, retention, or another downstream signal.
    6. Assign decision rights. State which changes AI may make automatically, which recommendations require human approval, and who can pause, expand, or revert the campaign.

    For an entertainment release, the contract might connect the ad platform’s purchase event to paid tickets, use CPA as the primary score, monitor conversion rate and reach for diagnosis, restrict delivery to eligible markets, and require a human review before a material budget increase. The exact thresholds should come from the release’s economics, not from a generic platform benchmark.

    Do not broaden the audience and increase the budget in the same test step. If performance changes, you will not know whether the cause was additional delivery freedom, additional spend, or an interaction between them. Change one source of freedom, observe the result through the normal conversion lag, and then decide whether the next increment is justified.

    Supervise each kind of advertising AI differently

    AI-powered advertising is not one operating mode. Some features help you analyze a campaign. Some change who receives an ad. Others personalize the content or format presented to a user. The amount and location of human review should follow the type of decision being automated.

    AI roleWhat it changesMain control questionHuman checkpoint
    Decision supportReports, summaries, and audience researchIs the analysis based on the right data and definitions?Verify filters, calculations, and causal claims before acting
    Audience expansionWho may receive the ad beyond the original seedWhich inputs are signals, and which are enforceable boundaries?Audit expansion settings, eligibility, and conversion quality
    Content and format selectionWhich title, card, or presentation a user seesDoes the selected format match the buying decision?Measure the business outcome by title, offer, and market

    Google Demand Gen: audit expansion before interpreting performance

    Start by finding out which targeting behavior actually applies to the campaign. Under Google’s announced transition, campaigns move to the signal-based Lookalike model unless the advertiser uses the dedicated opt-out route for traditional behavior. If restricted audience eligibility is important, verify the account’s current setting rather than relying on the familiar name of the segment.

    Record the selected Lookalike tier even though it is now a signal. It remains part of the model’s direction and therefore part of the test. Record the Optimized Targeting status separately because the two mechanisms are not interchangeable and can operate together.

    Then read the result as a sequence rather than a single KPI:

    • Did reach expand beyond the pattern you expected?
    • Did conversion volume rise with that expansion?
    • Did conversion rate and CPA remain commercially acceptable?
    • Did the additional conversions produce the same downstream quality as the original audience?

    More reach is evidence that the delivery system found more people. It is not evidence that it found better customers. A lower CPA is more promising, but it still needs a quality check if the platform conversion can include low-value or incomplete outcomes.

    Use the traditional targeting option when strict audience control is a real requirement or when you need a clean baseline. Do not opt out merely because expansion feels less familiar. Conversely, do not accept expansion merely because it is the default. The right choice depends on whether scale or controlled eligibility is the binding constraint for that campaign.

    Meta Ads Manager: treat Manus as an analyst, not an authority

    Meta has embedded Manus AI in Ads Manager, where it can assist with report creation and audience research. This is decision-support automation. It may shorten the route from raw campaign data to a usable analysis, but a faster report is not the same as better ad delivery.

    Give the assistant bounded analytical tasks. A useful request names the account or campaign, date range, metrics, comparison, segments, and desired output. Asking for a performance report without those details invites the system to choose definitions that may not match the decision in front of you.

    Review every AI-built report at three levels:

    • Data scope: confirm the campaigns, dates, markets, and filters included.
    • Metric meaning: confirm that conversions, CPA, reach, and other measures use the definitions required by your optimization contract.
    • Inference: separate what changed from why it changed. A report can identify a correlation without proving that an audience, creative, or platform action caused it.

    Audience research generated inside the workflow should become a testable hypothesis, not an immediate budget instruction. Translate the output into a specific question: which audience, which offer, which expected behavior, and which metric would disprove the idea? That keeps the assistant useful without allowing polished language to substitute for evidence.

    Measure Manus first by workflow outcomes: whether it reduced repetitive report building, made useful segments easier to inspect, or surfaced a hypothesis worth testing. Claim an advertising performance gain only when a controlled campaign decision produces one. The presence of AI inside Ads Manager does not establish that causal link by itself.

    TikTok entertainment ads: match the AI format to the buying decision

    TikTok’s European rollout separates two useful entertainment jobs. Streaming Ads can personalize a four-title video carousel or multi-title media card using user interaction, while New Title Launch is designed to find high-intent audiences using signals such as genre preference and price sensitivity.

    Choose between them by starting with the decision you need the viewer to make:

    • Use the streaming format for catalog discovery. Multiple titles make sense when the viewer can enter through more than one piece of content and the business outcome is a subscription, viewership action, or another catalog-level result.
    • Use the launch format for a concentrated release. High-intent signals are more relevant when one title, event, or cultural moment needs to produce tickets, subscriptions, or attendance.

    Do not let personalization blur the measurement unit. Tag and review results by title, offer, and eligible market. If a multi-title unit generates strong interaction but only one title produces the intended business outcome, the useful finding is not that the carousel worked equally well. It is that the AI found an effective entry point that deserves a title-level follow-up.

    TikTok says 80% of its users report that the platform influences their streaming decisions. Treat that vendor-supplied figure as context for why TikTok built the formats, not as a forecast for your campaign. It does not mean 80% of the people you reach will subscribe, buy, or attend. Your optimization contract and campaign evidence still determine whether the format earns more spend.

    Test automation without creating an uninterpretable result

    An analyst observes two isolated campaign-testing lanes, one stable and one containing a glowing automation module.

    The hardest failure to detect is not a campaign that performs badly. It is a campaign that changes in several ways, appears to improve, and leaves you unable to explain which change mattered. AI makes this easier to do because an apparently small setting can alter the system’s decision space.

    Use this sequence whenever a platform introduces a new AI feature or changes the meaning of an existing control:

    1. Write one test question. For example: does signal-based audience expansion increase valid conversion volume while keeping CPA and downstream quality within our limits?
    2. Capture the starting state. Save the objective, conversion event, audience inputs, similarity tier, expansion settings, budget, creative, geography, and any other condition that could affect delivery.
    3. Change one category of decision. Test audience freedom, analytical workflow, format selection, creative, or budget separately whenever the platform and campaign volume make that possible.
    4. Choose the evaluation window from the conversion process. Allow the normal conversion lag to pass before judging results. Do not declare a winner from an incomplete cohort simply because the interface is already showing activity.
    5. Use the strongest comparison available. Prefer a platform experiment when a valid one is available. Otherwise, keep surrounding inputs stable and label a before-and-after comparison as observational rather than causal proof.
    6. Inspect business quality as well as platform efficiency. Compare valid purchases, qualified leads, paid subscriptions, ticket completions, attendance, or the downstream outcome specified in the contract.
    7. Make an explicit decision. Scale, hold, narrow, opt out, or revert. Record the evidence and the unresolved uncertainty so the next review does not restart the argument from memory.

    Set a spend ceiling before the test begins. If the experiment can consume a meaningful amount of budget without producing interpretable evidence, reduce its exposure or improve the measurement design first. Automation does not suspend the campaign’s economics.

    Watch for four false wins. More reach without better outcomes is distribution, not success. A lower platform CPA with weaker downstream quality is metric substitution. A faster AI-generated report is a workflow gain, not a campaign lift. An improvement that appears after simultaneous audience, creative, budget, and format changes is a lead for another test, not a reliable conclusion.

    Key takeaways

    • AI advertising control now depends more on objectives, data, constraints, and review rules than on the number of manual audience settings.
    • A seed audience, similarity tier, or behavioral input may guide a model without restricting delivery. Verify hard eligibility boundaries separately.
    • Write an optimization contract that connects the platform event to a business outcome, an economic limit, a quality check, and a named decision owner.
    • Supervise decision-support AI, audience expansion, and content-selection AI differently. They automate different decisions and create different failure modes.
    • Do not award more budget for reach, reporting speed, or a vendor benchmark. Scale only when the campaign improves the predefined business result within its constraints.

    Before your next campaign review, take one active campaign and write down its objective, signal, hard constraints, primary score, quality check, and stop decision. If you cannot fill in all six, do not give the system more freedom yet. Once those answers are clear, you do not need every old manual lever. You have something more useful: accountable control.

    References

  • Google AI Search Infrastructure: A Reporting Playbook

    Google AI Search Infrastructure: A Reporting Playbook

    When an AI answer appears and your page does not, it is tempting to blame the final generation step. That diagnosis starts too late. Your page first has to be fresh enough to trust, relevant enough to retrieve, and competitive enough to survive several ranking passes.

    The practical question is not simply, “How do we rank in AI Search?” It is, “At which gate are we losing visibility, and what can our reporting actually prove?” Once you separate those questions, Google Search Console becomes more useful and your optimization backlog becomes much less speculative.

    Key takeaways

    • Google’s AI output sits on top of retrieval and ranking. Crawling, indexing, freshness, relevance, and ranking remain prerequisites for consideration.
    • Search can match a query to the meaning of a page or passage without requiring identical wording, so complete topic coverage matters more than repeated exact-match phrases.
    • Search Console’s AI-powered configuration builds reports from existing metrics, filters, and comparisons. It does not create an AI citation metric or reveal Google’s internal candidate set.
    • Clicks, impressions, CTR, and average position can narrow your diagnosis, but none of them alone proves why an AI answer did or did not use your content.
    • Use the AI configuration as a report builder, then inspect every generated setting before acting on the result.

    AI visibility is a pipeline, not a single ranking

    Google does not send an unrestricted model across the entire web every time someone enters a query. It reduces the problem in stages. Google’s Jeff Dean has described examples that begin with roughly 30,000 candidate documents and narrow the working material dramatically before the most capable model performs the final task. One LLM-oriented example ended with about 117 documents.

    Those figures are explanatory examples, not fixed quotas you can optimize against. Their value is architectural: the expensive reasoning step operates on a selected subset. If your content is absent from that subset, improving the polish of an answer paragraph will not solve the earlier failure by itself.

    1. Crawl and refresh: Google needs an accessible, current version of the page in its systems.
    2. Retrieve: lightweight methods identify a broad set of documents that could satisfy the query.
    3. Rerank: more sophisticated signals reduce that set and determine which candidates deserve deeper processing.
    4. Synthesize: an LLM reasons over a much smaller collection and constructs the response or result experience.

    This model changes how you prioritize SEO work. A page with weak crawl eligibility has a stage-one problem. A page that appears for irrelevant queries has a matching problem. A page with relevant impressions but poor competitive positions has a reranking problem. Only after those gates are reasonably healthy does synthesis readiness become the main editorial question.

    Matching is also broader than literal keyword overlap. LLM-based representations can assess the topical relationship between a query and an entire page or an individual paragraph. That gives Google room to connect different phrasings of the same intent. It does not make terminology irrelevant; it makes mechanical repetition a poor substitute for answering the full question.

    Semantic expansion is not an AI-era invention. When Google moved its index into memory across machines in 2001, it became practical to expand short searches into far richer query representations, including examples with around 50 terms. Modern models make the representations more capable, but meaning-based retrieval has deep roots in the search infrastructure. A reporting plan that tracks only one exact phrase therefore sees too little of the query space.

    Freshness belongs in the same pipeline. Google can refresh some material in under a minute, while crawl scheduling weighs how likely a page is to change and how valuable a newer version would be. Even an important page that changes infrequently may merit frequent checking. The actionable lesson is not to alter timestamps on a schedule. It is to identify pages where changed facts would alter the answer and maintain those pages when the underlying information actually changes.

    Read Search Console as evidence, not an AI visibility score

    Search Console gives you evidence about observed search performance. Its familiar metrics answer four different questions: did a result receive impressions, where did it tend to appear, how often did users click it, and what share of impressions became clicks? They do not expose the broad retrieval pool, the intermediate reranking passes, or the documents an LLM considered during synthesis.

    The AI-powered configuration does not change that boundary. It translates a plain-language request into a report by selecting clicks, impressions, average CTR, and average position; applying query, page, country, device, or date filters; and setting comparisons. That is valuable automation, but it is automation of report setup rather than a new source of AI-specific measurements.

    Use metric combinations to form a hypothesis, then segment until competing explanations become less plausible. The patterns below are diagnostic starting points, not causal conclusions.

    Pattern in a filtered viewWhat it can supportWhat it does not proveNext report to run
    Impressions fall and average position worsensThe selected cohort has lost search exposure or appears lower within its current query mix.It does not prove that an LLM rejected the pages.Split the cohort by page group and query theme, then compare countries and devices.
    Impressions remain stable while clicks and CTR fallThe pages are still appearing, but user response or the result environment may have changed.It does not prove that AI answers took the clicks.Hold the page and query filters constant, then separate device and country views.
    Impressions rise while average position worsensThe pages may be entering a broader or lower-ranking query mix.It does not automatically mean that established rankings declined.Find the query themes responsible for the new impressions and review their positions separately.
    Clicks and impressions rise with little movement in average positionDemand, eligibility, or the mix of queries may have expanded.It does not demonstrate increased inclusion in generated answers.Identify which pages and queries contributed the growth before assigning credit to a change.

    Average position needs particular care because it summarizes a changing mix. A page can gain many new impressions at lower positions while retaining its strongest rankings. The aggregate average then falls even though no established query deteriorated. Conversely, a stable sitewide average can hide a severe decline in one commercial directory if another directory improves at the same time.

    Scope matters too. At rollout, AI-powered configuration was limited to the Performance report for Search results, rather than serving as a configuration layer for Discover and News. Where that remains the interface presented in your property, keep conclusions within the Search results dataset. Do not label a Search performance chart as total AI visibility.

    Configure reports that isolate one failure mode

    Isometric diagnostic console filtering several document signal paths and highlighting one broken stage.

    A useful report begins with a decision, not a metric. “Show our AI performance” is too vague because neither the desired cohort nor the possible action is defined. “Did our migration guides lose search exposure on mobile after the update?” tells you which pages, device, period, and metrics matter.

    1. State the decision. Decide whether the result will trigger a technical check, a content review, a freshness update, or no action.
    2. Define one cohort. Use a page directory, query theme, country, or device that represents a coherent set rather than the whole property.
    3. Select all four metrics for the first pass. Clicks and impressions show scale, CTR shows response, and average position adds ranking context.
    4. Use comparable periods. Equal-length ranges reduce one obvious source of distortion. If demand is seasonal, compare periods that represent the same part of the demand cycle.
    5. Change one dimension at a time. After establishing the cohort baseline, split it by query, page, device, or country rather than changing several filters together.
    6. Record the generated settings. Your analysis should be reproducible without relying on the wording of the original prompt.

    The following requests are specific enough to produce an inspectable configuration:

    • Directory baseline: Show clicks, impressions, average CTR, and average position for pages containing /guides/, comparing the last 28 days with the previous 28 days.
    • Query-theme check: For mobile searches in Canada, show all four metrics for queries containing migration and compare the two specified date ranges.
    • Page-level drill-down: Show the four metrics for pages containing /pricing/ within the selected country and date comparison.
    • Device comparison: Compare mobile and desktop performance for queries containing the target topic within the same period.

    The prompts are starting configurations, not completed analyses. Replace the sample directories, topic, market, and dates with groups that map to your site. Keep one unfiltered baseline beside every filtered report so you can see whether a change is local or property-wide.

    Always inspect what Search Console generated. The configuration system may not interpret every request perfectly, so confirm that the intended metrics, filters, and comparison ranges are actually active. Check that a page filter was not substituted for a query filter, that the correct country and device remain selected, and that both periods use the same cohort. A fluent prompt response is not proof of a correct configuration.

    For recurring reporting, keep a small measurement ledger with six fields: question, cohort, filters, comparison periods, observed pattern, and decision. Add the action and the date you plan to reassess it. This prevents a common reporting failure in which a team remembers the chart but cannot reconstruct the population behind it.

    Turn the diagnosis into the right work queue

    Abstract page cards routed from a central diagnostic hub into four separate optimization work queues.

    The pipeline is useful only if it changes what you do next. Route each finding to the earliest plausible failure point. Fixing a later stage while an earlier gate is broken creates activity without restoring eligibility.

    Eligibility and freshness work

    Start here when a coherent page group loses impressions broadly across its relevant queries, especially if the decline spans devices and countries. Confirm that important pages remain available for crawling and suitable for indexing. Then check whether the information on them still reflects the facts a searcher needs.

    Prioritize freshness by consequence. A changed fact on a time-sensitive page can alter the answer, while a cosmetic rewrite on an evergreen definition may add no retrieval value. Google’s crawl systems consider both expected change and the value of obtaining a current version, and some pages can be refreshed extremely quickly when the system assigns sufficient value. Your publishing process should therefore flag meaningful changes early rather than rely on blanket update schedules.

    • Maintain a list of pages whose answers depend on changing facts.
    • Assign an owner to verify those facts when the underlying event, product, policy, or dataset changes.
    • Update the affected answer, supporting context, and visible date together.
    • Measure the page cohort separately from evergreen content so different update needs do not disappear inside one average.

    Semantic retrieval work

    Use this queue when a page appears for only a narrow slice of the intent it should satisfy, or when its impressions come from the wrong query themes. Audit the page around the reader’s task rather than a keyword count.

    • Write down the primary question the page resolves and the decisions a reader must make after receiving the answer.
    • Give each important subquestion a self-contained passage with enough local context to make sense on its own.
    • Use the vocabulary readers, practitioners, and product interfaces naturally use, including genuine variations, without repeating a single phrase mechanically.
    • Remove sections that broaden the page without helping the target task. More words do not automatically create stronger topical relevance.
    • Separate materially different intents into different pages when combining them would force one page to give several competing answers.

    Paragraph-level matching makes local clarity important. A passage headed “Requirements” should identify what is required, for whom, and under which conditions. A heading followed by several paragraphs of scene-setting makes the relevant passage harder to distinguish from surrounding material. This is an editorial implication of semantic retrieval, not a guaranteed citation formula.

    Ranking and synthesis-readiness work

    Move here when relevant pages receive impressions but consistently occupy weak positions within the intended query cohort. The page has cleared at least part of the retrieval problem; now it must compete within a smaller, stronger set.

    Make the central answer easy to identify. State the conclusion, define its scope, and place qualifications beside the claim they limit. Where the reader must choose, name the deciding criterion rather than listing options without guidance. Where the answer depends on a version, market, date, or audience, carry that condition into the relevant paragraph.

    This structure helps a human reader and gives downstream systems less ambiguity to resolve, but it cannot guarantee selection in an AI response. The synthesis stage still operates after retrieval and reranking, and Search Console does not disclose its document-level choices. Report improvements as stronger search eligibility or engagement when that is what the data shows. Do not convert them into unsupported claims about citations.

    Measurement work

    Sometimes the right action is a better test. If a decline disappears when you hold the query theme constant, the original problem was probably mix rather than a universal ranking loss. If it exists only on one device, investigate that segment before rewriting every page. If one directory falls while the sitewide totals remain flat, keep the work scoped to that directory until another report supports a wider response.

    At your next review, choose one business-critical directory and run four views: an unfiltered baseline, the directory cohort, its main query theme, and its device split. Validate every AI-generated setting, write down the earliest plausible pipeline failure, and assign only the work queue supported by the evidence. That is how you turn an opaque AI Search concern into a diagnosis you can test and improve.

    References

  • How to Measure AI Discovery, Attribution, and Conversion

    How to Measure AI Discovery, Attribution, and Conversion

    You can be named in AI answers, receive almost no identifiable referral traffic, and still influence a sale. You can also collect a burst of chatbot visits that never becomes revenue. If your dashboard treats those outcomes as the same thing, you will optimize the wrong part of the customer journey.

    The practical fix is to separate AI discovery visibility, attribution, and conversion, then reconnect them with an evidence chain. That gives you a defensible answer to three different questions: Are AI systems recommending you? Can you identify their influence? Does that influence create valuable outcomes?

    Key takeaways

    • Measure AI discovery, attribution, and conversion as separate stages. A strong result at one stage does not prove success at the next.
    • Treat AI visibility as sampled visibility, not a permanent ranking position. Track a fixed set of prompts, repeated outputs, mentions, recommendations, citations, and cited pages.
    • Build consistency around an entity home: one authoritative place where your identity, offers, audience, availability, and supporting facts agree with your visible content and JSON-LD.
    • Separate observed referrals, customer-reported AI influence, assisted journeys, and broader trend signals. Combining them into one conversion count creates false certainty.
    • Compare conversion rates only after checking traffic volume, intent, landing-page purpose, outcome quality, and measurement coverage.
    • Use one scorecard across content, analytics, CRM, and revenue systems so each team is working from the same channel definitions.

    Measure discovery, attribution, and conversion separately

    Three connected scenes show an AI highlighting an option, evidence trails converging through a lens, and a verified path reaching a purchase package.

    AI discovery visibility is your presence inside an assistant’s answer. It includes being mentioned, recommended, described accurately, cited, or used as the basis for an answer. The user does not have to visit your site for that visibility to matter.

    Attribution is the evidence connecting that exposure to a later action. A detectable referral is one form of evidence, but AI-assisted decisions can occur without producing the traditional click. That makes attribution a confidence problem rather than a simple channel lookup.

    Conversion is the valuable outcome: a purchase, booking, qualified lead, application, subscription, or another action your business has defined in advance. It belongs at the end of the chain. A brand mention is not a conversion, and a chatbot session is not proof of revenue.

    StageQuestion to answerUseful evidenceCommon mistake
    DiscoveryDoes the assistant include and represent us for relevant needs?Mentions, recommendations, citations, cited pages, answer accuracy, and repeatability across tracked promptsTreating one favorable answer as a stable ranking
    AttributionWhat evidence connects AI exposure with a visit or decision?Detectable referrals, customer reports, identifiable journey sequences, and directional demand signalsCalling every direct visit or branded search an AI visit
    ConversionDid identifiable or reported AI influence create a valuable outcome?Conversions, qualified outcomes, revenue, conversion rate, and time to conversionComparing rates without checking volume, intent, or measurement coverage

    Define the measurement contract before collecting results. Fix the audience, market, use case, conversion event, reporting window, and set of assistants you intend to evaluate. Otherwise, a change in prompt mix or business definition can look like a performance change.

    Your prompt set should cover distinct stages of intent. Category prompts reveal whether you are discovered at all. Comparison prompts reveal whether you enter a shortlist. Validation prompts reveal whether the assistant can explain your fit, limitations, and evidence. Decision prompts reveal whether it can direct a user toward the right next step. Keep these groups separate because an improvement in broad discovery can hide a decline among high-intent questions.

    Make your brand easy to identify and corroborate

    AI recommendations can vary considerably between outputs. There is no single position to check and declare permanent. Your first visibility metric should therefore be repeatability: does the same brand appear, for the same relevant need, often enough to indicate more than a one-off answer?

    Record the exact prompt, assistant, date, account state, answer, brand position within the answer, cited URLs, and any material factual errors. Repeat the same prompts under comparable conditions. This does not remove model variability, but it stops your own testing process from introducing avoidable noise.

    Establish an entity home

    An entity home is the authoritative page, or tightly connected group of pages, where a machine can resolve what your brand is. It should make the following facts explicit rather than forcing an assistant to infer them:

    • Your canonical brand name and website.
    • What you provide, using the terms customers use to describe the need.
    • Who the offer is for and when it is not a fit.
    • Where the offer is available and which limitations matter.
    • The relationship between the brand, its products, and any parent or operating organization.
    • The evidence supporting important claims.
    • The correct next step for someone who wants to evaluate, contact, buy, or book.

    Visible copy, navigation labels, page metadata, and JSON-LD should express the same facts. Structured data is a clarification layer, not a way to publish a second version of the business. If the page calls an offer a platform, the markup describes a service, and external profiles use a third label, you have created an identity-resolution problem.

    Keep a claim ledger

    Create a working list of the claims you want an assistant to repeat. For each claim, record the approved wording, the controlled page that supports it, the evidence behind it, the machine-readable representation, the external locations that mention it, and the person responsible for keeping it current.

    This catches a common failure mode: marketing changes a promise, product changes an availability condition, and structured data or external profiles retain the old version. An assistant may then omit the claim, hedge it, or reproduce the wrong version. Fix the disagreement before producing more pages about the same subject.

    Build corroboration, not repetition

    Repeating a claim across your own site can improve clarity, but it does not create independent support. More consistent AI visibility tends to emerge when your controlled identity and authoritative third-party information align. The practical goal is not to manufacture mentions. It is to make legitimate profiles, listings, coverage, documentation, and references accurate enough to confirm the same core facts.

    Audit contradictions before chasing additional coverage. Start with the facts most likely to affect a recommendation: category, audience, capabilities, availability, pricing model if publicly stated, location, ownership, and material limitations. A smaller set of consistent claims is more useful than a larger footprint full of stale descriptions.

    Write pages that can support an answer

    A page should answer one identifiable decision question well. Put the direct answer near the start, define who it applies to, show the supporting facts, state meaningful limits, and link to the canonical pages behind those facts. Give comparison and use-case pages enough context to stand alone; an isolated slogan is difficult to verify and easy to misrepresent.

    Do not judge these pages only by search visits. In an AI journey, a page can help establish the facts used in an answer even when the user never opens it. Track whether the page is cited, whether its language appears accurately in answers, and whether improvements make recommendations more consistent across your prompt set.

    Build attribution that survives a missing click

    A person researches on a tablet and later buys on a laptop, with indirect signal trails bridging the missing digital connection.

    No single attribution method will reveal every AI-influenced journey. The defensible approach is to keep evidence classes separate and assign each one an appropriate level of confidence.

    1. Observed AI referral: A visit arrives with a detectable referring platform or a campaign link you deliberately placed. This is the strongest channel evidence, but it covers only journeys that produce a visible handoff.
    2. Customer-reported AI influence: A lead or buyer identifies an AI assistant when asked how they discovered you or what helped them decide. Preserve the original response and map it to a reporting category without discarding the raw wording.
    3. Identifiable assisted journey: An AI referral occurs earlier in a known journey and a later session converts. Report it as assisted rather than relabeling the final touch.
    4. Directional influence signal: AI visibility changes alongside branded demand, direct visits, sales questions, or conversions. This can support an investigation, but correlation alone does not prove that AI caused the result.
    5. Unknown: No reliable connection can be established. Keep this category. Forcing unknown journeys into AI reporting makes the dashboard look complete while weakening every decision based on it.

    Use separate reporting fields for observed, reported, assisted, directional, and unknown influence. Your deduplicated AI-influenced conversion total may include the first three when their identities are clear. Directional signals should remain outside that total because they describe context, not attributable conversions.

    Preserve the evidence at collection time

    At the first identifiable visit, preserve the raw referrer, landing page, timestamp, campaign value when present, and assistant name when it can be observed. Do not overwrite those fields when your channel-classification rules change. Retaining the raw values lets you repair historical classification without inventing history.

    At a lead or purchase step, ask an optional discovery question such as, “Where did you first hear about us?” A second question such as, “What helped you decide?” distinguishes discovery from decision support. Offer an AI-assistant option, but retain an open field because customers may name a platform, describe a generated answer, or use terminology your choices did not anticipate.

    Do not quietly infer and store a person’s private prompt. Record only the information the platform legitimately passes or the customer voluntarily provides. Attribution does not become more accurate merely because more sensitive data is collected.

    Use the same definitions in every system

    A common channel taxonomy should flow through web analytics, lead records, customer systems, the data warehouse, and revenue reporting. If marketing defines an AI-assisted lead differently from sales operations, the reconciliation meeting will become an argument over labels rather than a decision about performance.

    Enterprise teams also need a repeatable way to move search intelligence into the systems where decisions are made. Conductor’s Data API is designed to extend search data across enterprise platforms and AI infrastructure. Whether you use that product or another integration route, the architectural requirement is the same: prompt-level visibility, visit evidence, customer-reported influence, and commercial outcomes need shared identifiers and shared definitions.

    Run a reconciliation check before presenting an AI revenue figure. Confirm that a conversion has not been counted once as an observed referral, again as a reported discovery, and a third time as an assisted journey. Preserve the separate flags, but deduplicate the commercial outcome.

    Read AI conversion rates without fooling yourself

    During Airbnb’s Q4 2025 earnings call, CEO Brian Chesky said chatbot traffic converted at a higher rate than Google traffic. The disclosure did not include the underlying conversion rates, referral volume, or the chatbots responsible for those visits. It is a useful signal that chatbot referrals can carry strong intent, but it is not a benchmark you can transfer to another business.

    A plausible interpretation is that some users arrive from assistants after narrowing their choices, which places them further along in the journey. Other explanations remain possible: different landing pages, audience composition, attribution coverage, device mix, or a small group of unusually motivated visitors. Your own data must distinguish those possibilities.

    Check six things before calling AI traffic a better channel:

    • Denominator: Decide whether the rate uses sessions, users, leads, or another unit. Do not compare rates built from different denominators.
    • Volume: Show the conversion count beside the rate. A small stream can produce a high rate while contributing little total revenue.
    • Intent: Compare visitors who were trying to complete a similar task. A decision-ready referral should not be compared casually with broad informational traffic.
    • Landing experience: Check whether channels enter through pages with different purposes. A booking or product page naturally has a different job from an educational page.
    • Outcome quality: Measure the outcome the business values, not merely the easiest event to count. For a complex sale, that may be a qualified opportunity rather than a form submission.
    • Coverage and lag: State how much traffic could be classified and how long conversions typically remain connected to an earlier touch in your reporting model.

    Keep rate, volume, and value in adjacent columns. If AI referrals convert strongly but remain small, expand visibility around the prompts and pages already producing qualified visitors. Do not treat the rate alone as a reason to reallocate a large budget. If referral volume rises while conversion weakens, inspect query intent and landing-page continuity before trying to increase visibility further.

    When visibility rises but detectable traffic does not, check which pages assistants cite and whether users have a clear reason to continue to your site. Some answers may satisfy the question without a click. Others may mention the brand but omit a usable next step. That is a discovery-to-handoff problem, not yet a conversion-rate problem.

    When referrals and customer-reported influence rise but qualified outcomes do not, the break is later. Compare the promise made in AI answers with the landing page, offer, eligibility conditions, and sales follow-up. A mismatch at that handoff can produce plenty of apparently relevant traffic without commercial value.

    Run one AI discovery-to-revenue review

    A useful review follows the journey in order. It does not open with a single visibility score or end with a single attribution number. Use the same prompt set and definitions for each reporting cycle, then organize the scorecard into four layers.

    Visibility layer

    • Mention rate: tracked runs in which the brand appears divided by total tracked runs.
    • Recommendation rate: tracked runs in which the brand is presented as a suitable option, kept separate from incidental mentions.
    • Citation rate: tracked answers that link to a controlled page, with the actual cited URLs listed.
    • Accuracy rate: appearances that represent the monitored brand facts correctly.
    • Repeatability: prompts for which the brand remains present across repeated comparable runs.

    Do not merge all prompts into one opaque score. Break these measures out by category discovery, comparison, validation, and decision intent. A stable overall percentage can otherwise hide movement at the stage closest to conversion.

    Attribution layer

    • Detectable AI referrals and the landing pages receiving them.
    • Customers who report discovering the brand through an assistant.
    • Customers who report that an assistant helped with the decision.
    • Identifiable journeys in which an AI referral assisted a later conversion.
    • Directional signals, displayed as context and clearly labeled as non-causal.
    • The share of outcomes that remains unknown or unclassified.

    Conversion layer

    • Sessions or users, conversion count, and conversion rate for observed referrals.
    • Qualified outcomes and value from customer-reported or identifiable assisted journeys.
    • Time from first known AI interaction to conversion.
    • Performance against a comparable non-AI cohort with similar intent.
    • Results by landing page, prompt-intent group, audience, and market where the data supports that split.

    Evidence-quality layer

    • Changes to the prompt set, assistant mix, account conditions, or collection process.
    • Changes to channel-classification rules or customer-survey wording.
    • Missing data, small groups, duplicate records, and known tracking gaps.
    • Entity-home, JSON-LD, content, or third-party corrections made during the period.

    End the review with one test tied to the weakest link. If visibility is inconsistent, reconcile the entity home and external descriptions around one important claim. If mentions are stable but citations are poor, improve the page that should substantiate the answer. If referrals are visible but influence disappears in customer records, repair the data handoff. If qualified conversions are weak, examine intent and promise continuity before publishing more content.

    You can start with a fixed prompt set, a canonical-fact audit, two optional attribution questions, and separate fields for observed, reported, assisted, and directional evidence. After one complete review cycle, invest in the stage where the chain actually breaks. That is how AI visibility becomes a measurable acquisition system instead of another disconnected dashboard.

    References

  • How to Build an AI-Era SEO and Content Strategy That Holds Up

    How to Build an AI-Era SEO and Content Strategy That Holds Up

    If your traffic plan still starts with a keyword list and ends when a page is published, AI search exposes the missing middle. You need content that answers a real decision clearly enough for search engines and language models to retrieve, while giving a person enough evidence to trust the answer and take the next step.

    You don’t need a separate content library for every search or AI interface. You need one evidence-led system: learn how your audience describes the problem, organize that demand into distinct decisions, publish answerable pages, keep them technically accessible, and measure what happens after a machine fetches them.

    Key takeaways

    • Start with customer evidence, not an AI-generated keyword universe. Reviews, calls, audience data and search behavior reveal the language and stakes behind a query.
    • Use a persona GPT as a critic grounded in your approved evidence. It can expose omissions quickly, but it cannot replace customers or validate its own assumptions.
    • Build long-tail clusters around distinct decisions, constraints and stages. Don’t create a new URL for every wording variation.
    • Make each important section an answer module: a descriptive heading, a direct answer, its conditions, supporting evidence and a useful next step.
    • Keep canonical HTML as your default. Treat Markdown delivery as a controlled experiment, not as a presumed AI-ranking advantage.
    • Measure demand, crawling, retrieval, visits and business outcomes separately. More bot requests alone do not prove more AI visibility or value.

    Start with audience evidence, not AI guesses

    AI can organize what you know about an audience. It cannot know that audience merely because you assigned it a name, job title and personality. A fictional persona built from a prompt usually reflects your assumptions with more polished wording.

    Begin with observable inputs. Useful audience research can combine SparkToro exploration, review mining and sales-call listening. Each channel reveals something different: where people spend attention, how they describe satisfactory and disappointing outcomes, and which question finally moves them to contact a company.

    Put those inputs into an evidence bank before asking AI to interpret them. Each record should preserve:

    • The trigger: what changed or happened before the person started looking.
    • The job: what progress the person is trying to make, expressed as an action rather than a broad topic.
    • The original wording: the customer’s own phrase, kept separate from your preferred terminology.
    • The constraint: budget, compatibility, risk, experience, time, approval or another condition shaping the answer.
    • The objection: what could stop the decision or make the person distrust a claim.
    • The decision criteria: what the person compares and which proof they need.
    • The journey moment: whether they are identifying the problem, evaluating approaches, choosing an option or trying to implement it.
    • The evidence location: the call note, review, survey response, analytics view or other record from which the observation came.

    This structure prevents a common content mistake. Two people can type similar words while facing different decisions, and one person can use several different queries while making the same decision. The decision should determine your content architecture; the wording should help you shape headings, examples and internal links.

    Now turn the evidence into an operational persona. Skip invented hobbies and decorative biographies unless they affect the purchase or task. Capture the person’s context, trigger, desired progress, current alternative, objections, proof threshold and appropriate next action. Attach the supporting records so an editor can inspect where each conclusion came from.

    A custom GPT becomes useful at this point because it acts as an interface to the evidence. Give it only approved persona material, explain which fields are facts and which are interpretations, and require it to expose uncertainty. Persona GPTs can provide fast feedback on alignment and omissions, but their claims still need to be checked against the supplied data.

    Use this persona test prompt: Review this page only against the supplied persona evidence. For every criticism, identify the supporting evidence field. Mark any unsupported inference as unknown. Separate missing information, unclear wording and genuine objections. Do not rewrite the page until you have explained why each proposed change matters to this persona.

    That last instruction matters. If you ask for a rewrite first, fluent copy can conceal weak reasoning. Ask for the evidence trail first, decide which criticism is valid, and then request a constrained revision. Update the persona when new calls, reviews or campaign findings change what you know; remove stale assumptions rather than allowing the profile to grow indefinitely.

    Map long-tail demand to decisions, not keyword variations

    Hands sort blank audience research cards into clusters that branch toward several different decision outcomes.

    A useful long-tail query is not simply a longer phrase. It usually narrows the decision by adding a situation, goal, constraint, comparison or stage. That specificity is valuable because it tells you what must be present for an answer to feel complete.

    Use customer language as the seed, then let AI expand the dimensions around it. AI-assisted long-tail work is most useful when the model is asked to expose meaningful variations rather than generate a large list of loosely related phrases.

    For each observed problem, explore these dimensions:

    • Situation: what is already true when the search begins.
    • Goal: the result the person is trying to achieve.
    • Constraint: the condition that rules out a generic answer.
    • Alternative: the option, workaround or competitor category being considered.
    • Risk: what the person fears losing, breaking or choosing incorrectly.
    • Stage: whether the person needs orientation, evaluation, selection or implementation help.

    Require every generated query or question to carry one of two labels: supported by an evidence-bank record or an unvalidated hypothesis. Hypotheses can become research prompts. They should not quietly become editorial facts just because the wording sounds plausible.

    Use this expansion prompt: From the supplied customer evidence, generate question variants by situation, goal, constraint, alternative, risk and journey stage. Preserve the customer’s terminology. Cite the evidence record behind each question. Put anything not directly supported into a separate hypothesis list, and do not invent demand, product capabilities or customer concerns.

    Next, group the questions by the decision they serve. You are looking for answer overlap, not merely shared words. If several queries lead to the same recommendation, evidence and next step, they probably belong on the same canonical page. Give the page a clear primary decision and use subsections for the meaningful variants.

    Create a separate URL only when the reader has a materially different job, needs a different answer, requires different proof, or should take a different next action. Otherwise, more pages create maintenance work and compete to explain the same thing. A larger content inventory is not broader coverage when the underlying answers are interchangeable.

    For every planned page, write a short content contract before drafting:

    • The decision this page helps the reader make.
    • The audience situation and constraints it covers.
    • The direct answer the page must deliver.
    • The evidence available to support that answer.
    • The adjacent questions that belong as subsections.
    • The questions that belong on other pages.
    • The next useful action after the reader understands the answer.

    This contract gives editors, subject-matter experts and AI tools the same boundary. It also makes content consolidation easier: when two pages claim the same decision, you can compare their evidence and choose which one should own it. Check existing traffic, links and business dependencies before merging or redirecting a live URL.

    Publish answer modules, then test the delivery format

    Editors rearrange the same visual answer modules into desktop, mobile, and conversational interface layouts.

    Build sections that can stand on their own

    Search results and AI answers often retrieve a passage, not the argument as you pictured it on the editorial calendar. Important sections therefore need enough local context to remain accurate when encountered on their own. That does not mean repeating the entire page under every heading. It means resolving ambiguous subjects and carrying necessary conditions into the answer.

    A durable answer module has a simple shape:

    • A descriptive heading: name the exact question, task or distinction addressed by the section.
    • A direct opening answer: give the conclusion before background, including any condition that changes it.
    • An explanation: show the mechanism, reasoning or distinction that makes the conclusion credible.
    • Supporting evidence: provide the relevant data, specification, example, expert input or first-party observation you actually possess.
    • An action boundary: tell the reader what to do, what not to infer and when a different answer applies.
    • A next step: point to the next decision, tool, page or workflow rather than ending with a vague invitation.

    Answer-first writing is not the same as oversimplification. A direct answer can be conditional. In fact, stating the condition early is more useful than offering a universal claim and burying the exceptions later. The reader should be able to tell quickly whether the answer applies to their situation.

    Keep entity references explicit at section boundaries. Name the product, organization, method or concept instead of opening a retrieved passage with an unclear it, they or this. Define an acronym before relying on it. Use the same name consistently unless a real distinction requires different terminology.

    Separate three kinds of statement during editing: observed fact, interpretation and recommendation. Facts need a traceable basis. Interpretations need reasoning. Recommendations need a condition and intended outcome. If you lack proof, do not ask AI to manufacture an example, quotation, benchmark or customer story to make the section feel authoritative.

    Use semantic HTML to preserve the hierarchy: headings for sections, lists for criteria or steps, and tables only for real comparisons. If you add JSON-LD, it should describe the visible page accurately. Structured data can clarify entities and content properties, but it cannot repair a vague answer, unsupported claim or page that search systems cannot fetch.

    Treat Markdown as a testable delivery hypothesis

    Markdown can represent clean, easy-to-parse text. That does not establish that AI crawlers prefer it, that additional crawling produces citations, or that citations produce customers. Formatting, access, retrieval and business value are separate questions.

    Your canonical public page should usually remain HTML because it serves browsers and ordinary search discovery directly. Do not replace working canonical pages or publish uncontrolled duplicate URLs merely to attract AI bots. If you want to offer a Markdown representation, decide how canonicalization, internal linking, metadata and updates will remain consistent before exposing it.

    Run a controlled test if format preference matters to your site:

    1. Select a representative cohort and a comparable control group.
    2. Change only the delivery format. Keep the underlying content, page purpose, internal discovery, canonical signals and server availability stable.
    3. Record which crawler labels request each version, whether the full response is delivered, and whether requests repeat.
    4. Measure crawl behavior separately from appearance in relevant AI answers.
    5. Measure AI visibility separately from human visits and qualified actions.
    6. Document the hypothesis and stopping condition before inspecting the result, so an interesting traffic spike does not become the success definition after the fact.

    One controlled setup observed 381 pages over three weeks. That scale is useful as a reminder that a formatting claim needs a cohort and an observation window, not a single-page before-and-after anecdote. It does not establish the correct sample or duration for your site, which depends on how often your pages are normally fetched.

    Request logs are diagnostic evidence, not the final KPI. A bot label does not tell you whether a model retrieved the page for an important question, represented the answer accurately, sent a visitor or influenced a business result. Keep those outcomes separate in your reporting.

    Measure the full chain from demand to business outcome

    AI-era SEO becomes manageable when you stop treating visibility as one metric. A page can answer a valuable question but remain inaccessible. It can be fetched without being retrieved. It can appear in an answer without earning a visit. It can earn visits that never reach the right next step.

    StageQuestion to answerSignals to inspectLikely response
    DemandDoes this question reflect a real audience decision?Customer calls, reviews, audience findings, search behavior and on-site questionsRevise the query cluster or collect more evidence before producing more content
    AccessCan the relevant systems discover and fetch the intended content?Server requests, successful delivery, canonical handling, internal links and rendered page contentFix discovery, blocking, rendering or delivery issues before rewriting the answer
    RetrievalDoes the page appear for the relevant question and context?A documented query set, answer citations, brand mentions and passage selectionImprove answer fit, entity clarity, supporting evidence and alignment with the decision
    VisitDo exposed users reach the site and continue?Landing sessions, available referral data and engagement with the intended next stepStrengthen the transition from the answer to a useful on-site action
    OutcomeDoes the interaction produce a qualified result?Relevant signups, inquiries, purchases or other business actionsCorrect the audience, offer, page intent or conversion path

    The stage where performance breaks tells you what to change. If crawlers do not fetch the page, investigate access and discovery. If the page is fetched but absent from relevant answers, inspect intent fit, extractability, evidence and entity consistency. If the answer mentions you but few people visit, the interface may already satisfy the query; give the reader a concrete reason to continue rather than withholding the basic answer. If qualified visitors arrive but do not act, the problem is more likely the offer, proof or next step than crawl format.

    Use a stable set of audience questions for retrieval checks. Record the wording, audience context, system tested and observed answer so later comparisons mean something. AI output can vary, so do not treat a single response as a durable ranking. Look for repeated patterns under documented conditions.

    Connect each content change to a hypothesis. A useful change log states which audience evidence triggered the edit, which answer module changed, what technical behavior should improve, and which downstream outcome will determine whether the change stays. Avoid changing the persona, page structure, delivery format and call to action at the same time; you will not know which layer caused the movement.

    A practical first implementation

    1. Choose a commercially meaningful query cluster already supported by customer evidence.
    2. Build the evidence bank and operational persona for that decision.
    3. Give the canonical page a content contract, then remove sections that do not help the decision.
    4. Rewrite the core sections as answer modules with explicit conditions, evidence and next steps.
    5. Check semantic structure, visible content, JSON-LD accuracy, internal discovery and server delivery.
    6. Use the persona GPT to identify unsupported assumptions and missing objections, requiring an evidence reference for every criticism.
    7. Establish the demand, access, retrieval, visit and outcome baselines before testing a delivery or content change.
    8. Expand the system to another cluster only after you can explain what worked, where it worked and which evidence supports that conclusion.

    Start with the page closest to a real customer decision, not the topic with the easiest AI-generated outline. By your next editorial review, you should be able to show which audience evidence shaped that page, which decision it owns, how machines can access and interpret it, and which outcome will decide its next revision.

    References

  • Unlock Ad Success: Connect External Data with Google Ads

    Unlock Ad Success: Connect External Data with Google Ads

    I’ve recently discovered an exciting development in Google Ads that’s set to revolutionize how we track and measure our advertising success. The platform is now testing a beta feature that allows us to link external data sources directly into the conversion action settings. This move aims to strengthen the bridge between our first-party data and campaign measurement.

    How does this work, you might ask? In the conversion action details, a new section titled “Get deeper insights about your customers’ behavior to improve measurement” encourages us to connect our external databases to our Google tag, offering a seamless integration experience.

    This integration supports platforms like BigQuery and MySQL, with the primary goal of enriching our conversion metrics and enhancing performance signals. Notably, this feature is highlighted within the data attribution settings and is gradually being rolled out in its Beta phase.

    Why do we care? The ability to directly integrate these data sources reduces the hassle of syncing offline or backend data with ad measurements. This beta feature from Google Ads simplifies connecting first-party data to conversion tracking, improving our measurement accuracy and campaign optimization.

    ```json
{
  "alt": "Screenshot of a Google Ads interface showing data-driven attribution and enhanced conversions.",
  "caption": "Unlock deeper customer insights with enhanced Google Ads metrics. Connect data sources like BigQuery for improved measurement.",
  "description": "This image displays a screenshot of the Google Ads interface, highlighting data-driven attribution recommendations and information on enhanced conversions managed through Google Tag. It features a prompt to connect data sources such as BigQuery or MySQL to improve conversion metrics, campaign performance, and measurement signals, with an interactive button to 'Connect a data source'. Relevant keywords include Google Ads, data-driven attribution, enhanced conversions, and BigQuery."
}
```

    By harnessing the power of platforms like BigQuery or MySQL, we’re able to incorporate richer customer data into our signals, crucially offsetting any data loss resulting from recent privacy changes. In practical terms, this means smarter bidding, clearer attribution, and the potential for a stronger ROI.

    Beneath the surface, embedding these data connections directly within conversion settings—rather than relying on separate pipelines—democratizes advanced measurement tactics, making them accessible not only to large enterprises but to advertisers like you and me.

    As ad platforms compete for superior measurement accuracy, these native data integrations are emerging as a pivotal advantage, particularly for brands heavily investing in proprietary customer data.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot