Local search continues to be a significant driver of consistent lead flow for service businesses like mine. However, outdated SEO tactics are losing their effectiveness as Google

Inspired by this post on Search Engine Land.

Local search continues to be a significant driver of consistent lead flow for service businesses like mine. However, outdated SEO tactics are losing their effectiveness as Google
Inspired by this post on Search Engine Land.
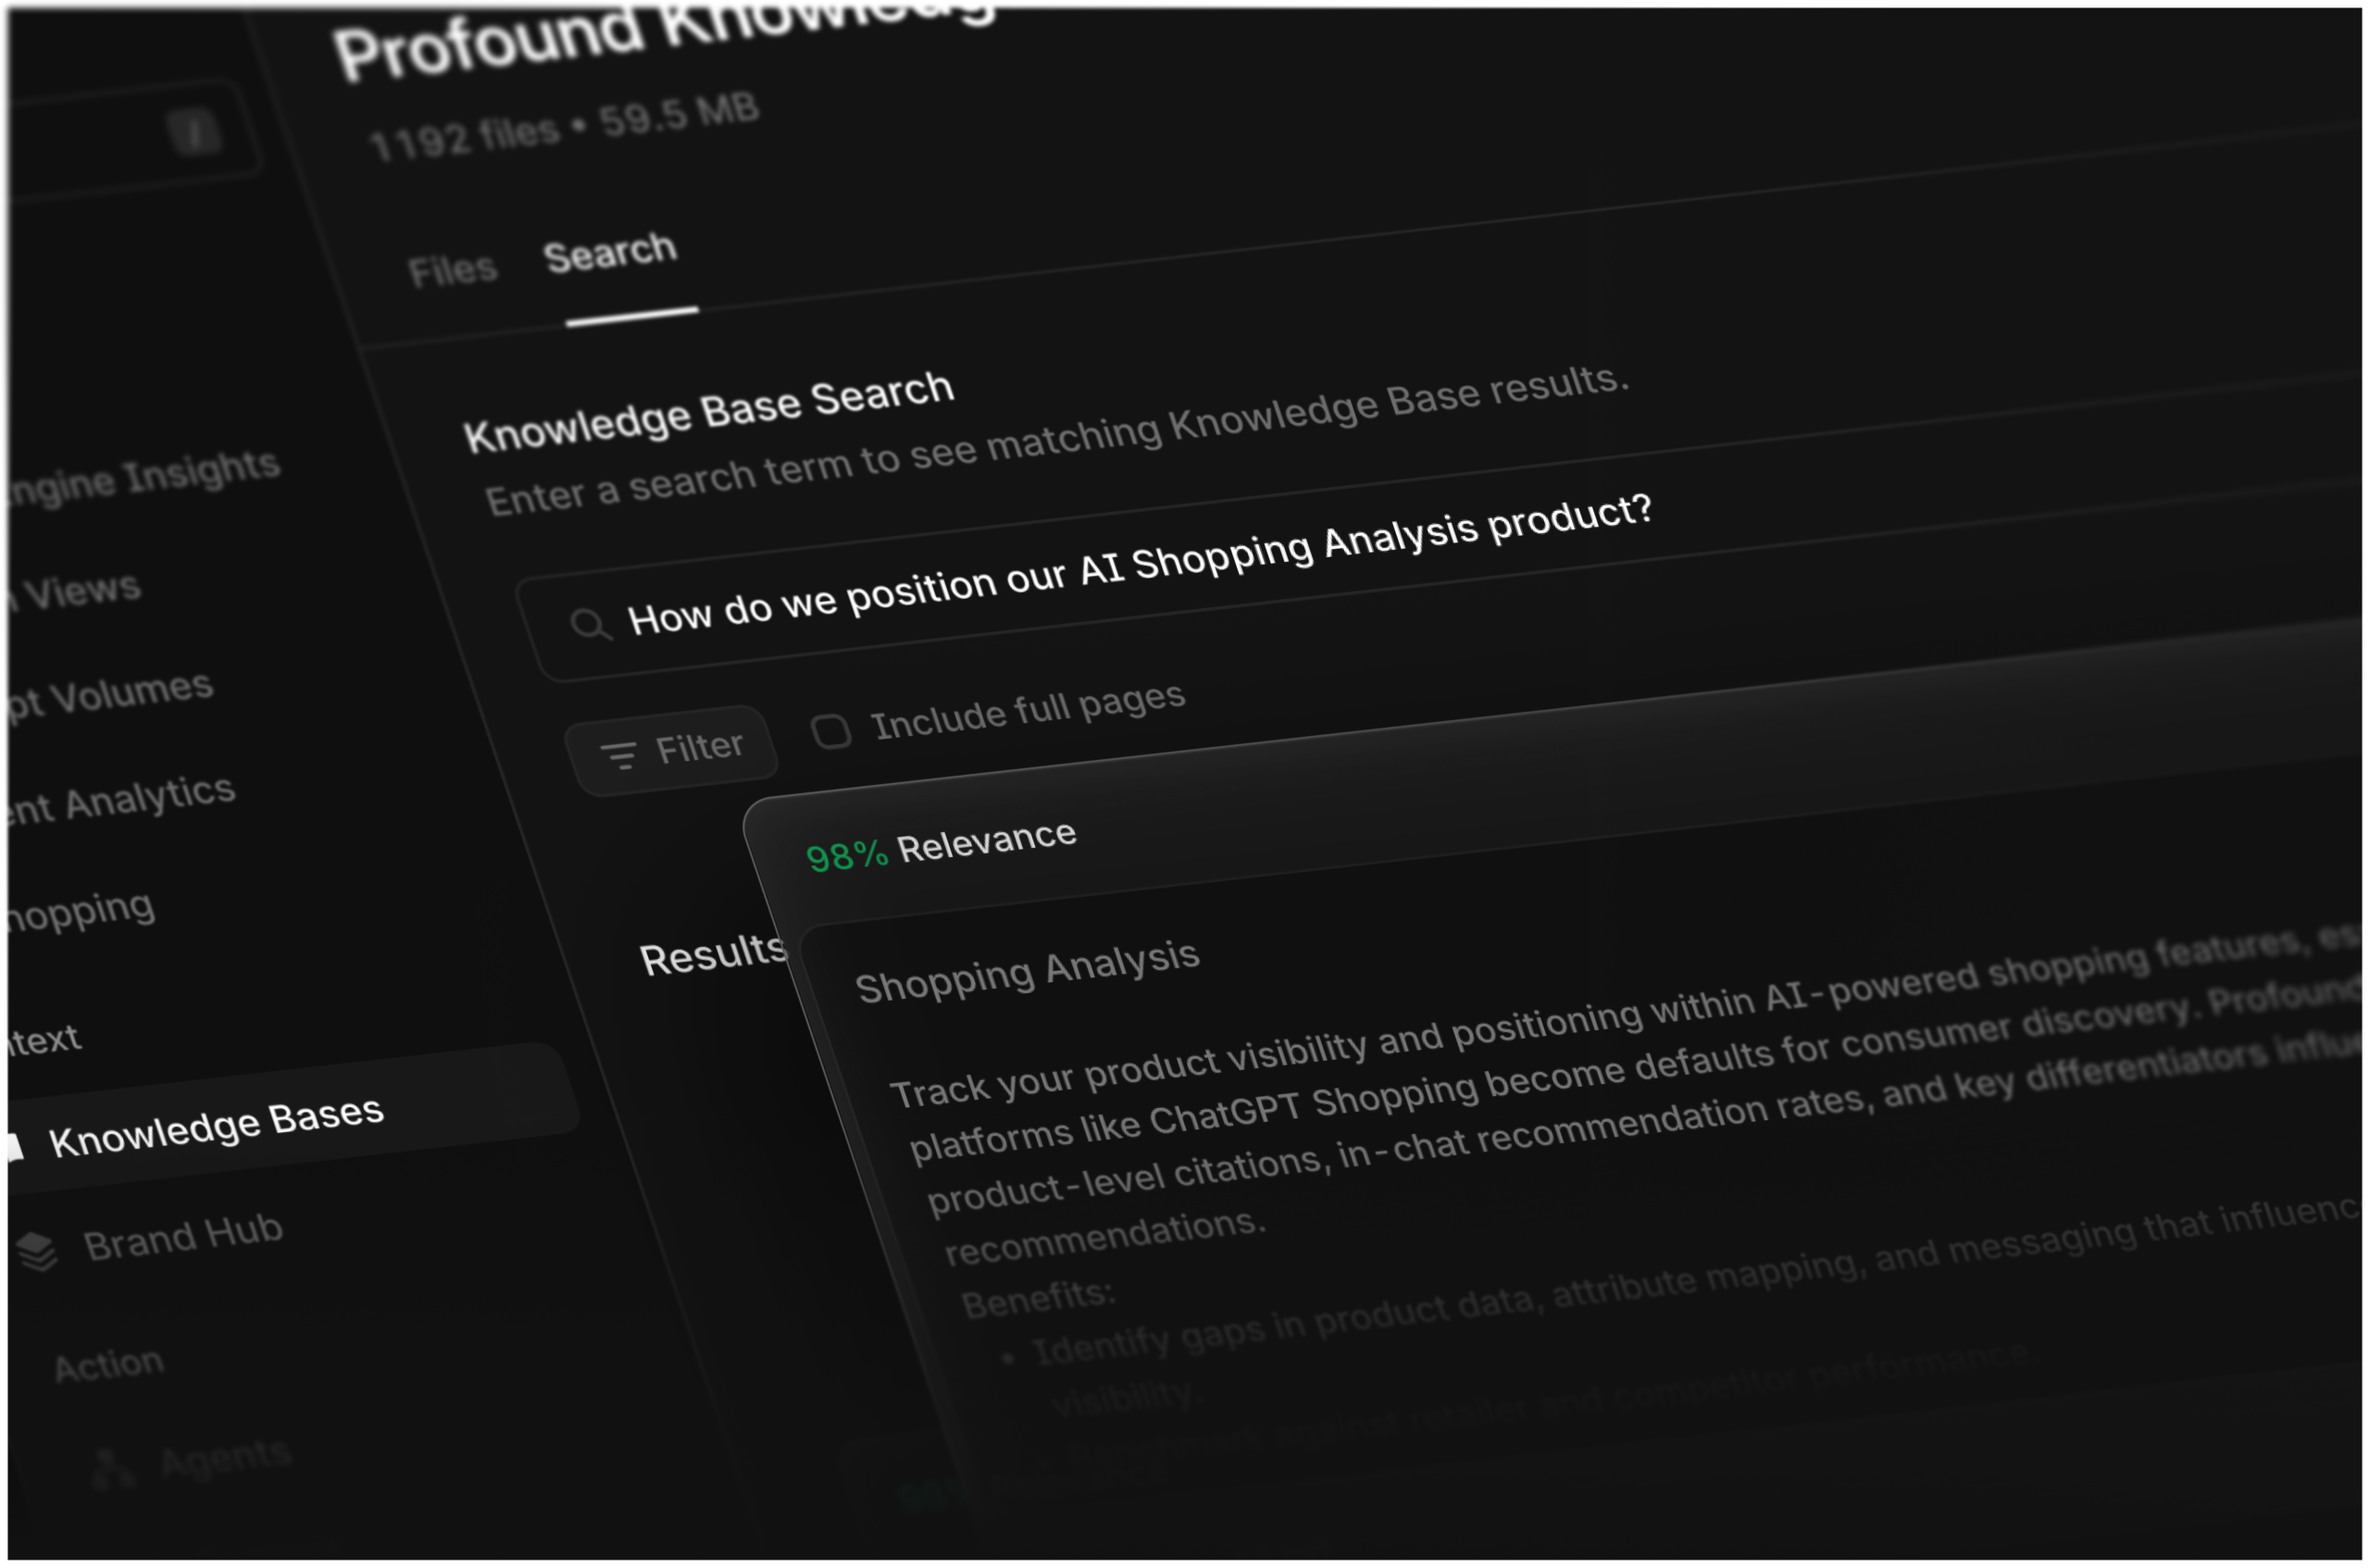
As someone deeply involved in marketing, I know how crucial it is to have access to accurate and comprehensive company information. That’s why when our marketing team uses Profound to upload Knowledge Bases, it gives us a single source of truth for company-specific data.
This capability empowers us, as agents, to provide the right context about your brand every time we execute a marketing action on your behalf. This streamlined approach ensures consistency and accuracy in representing your brand.
Inspired by this post on Try Profound Blog.
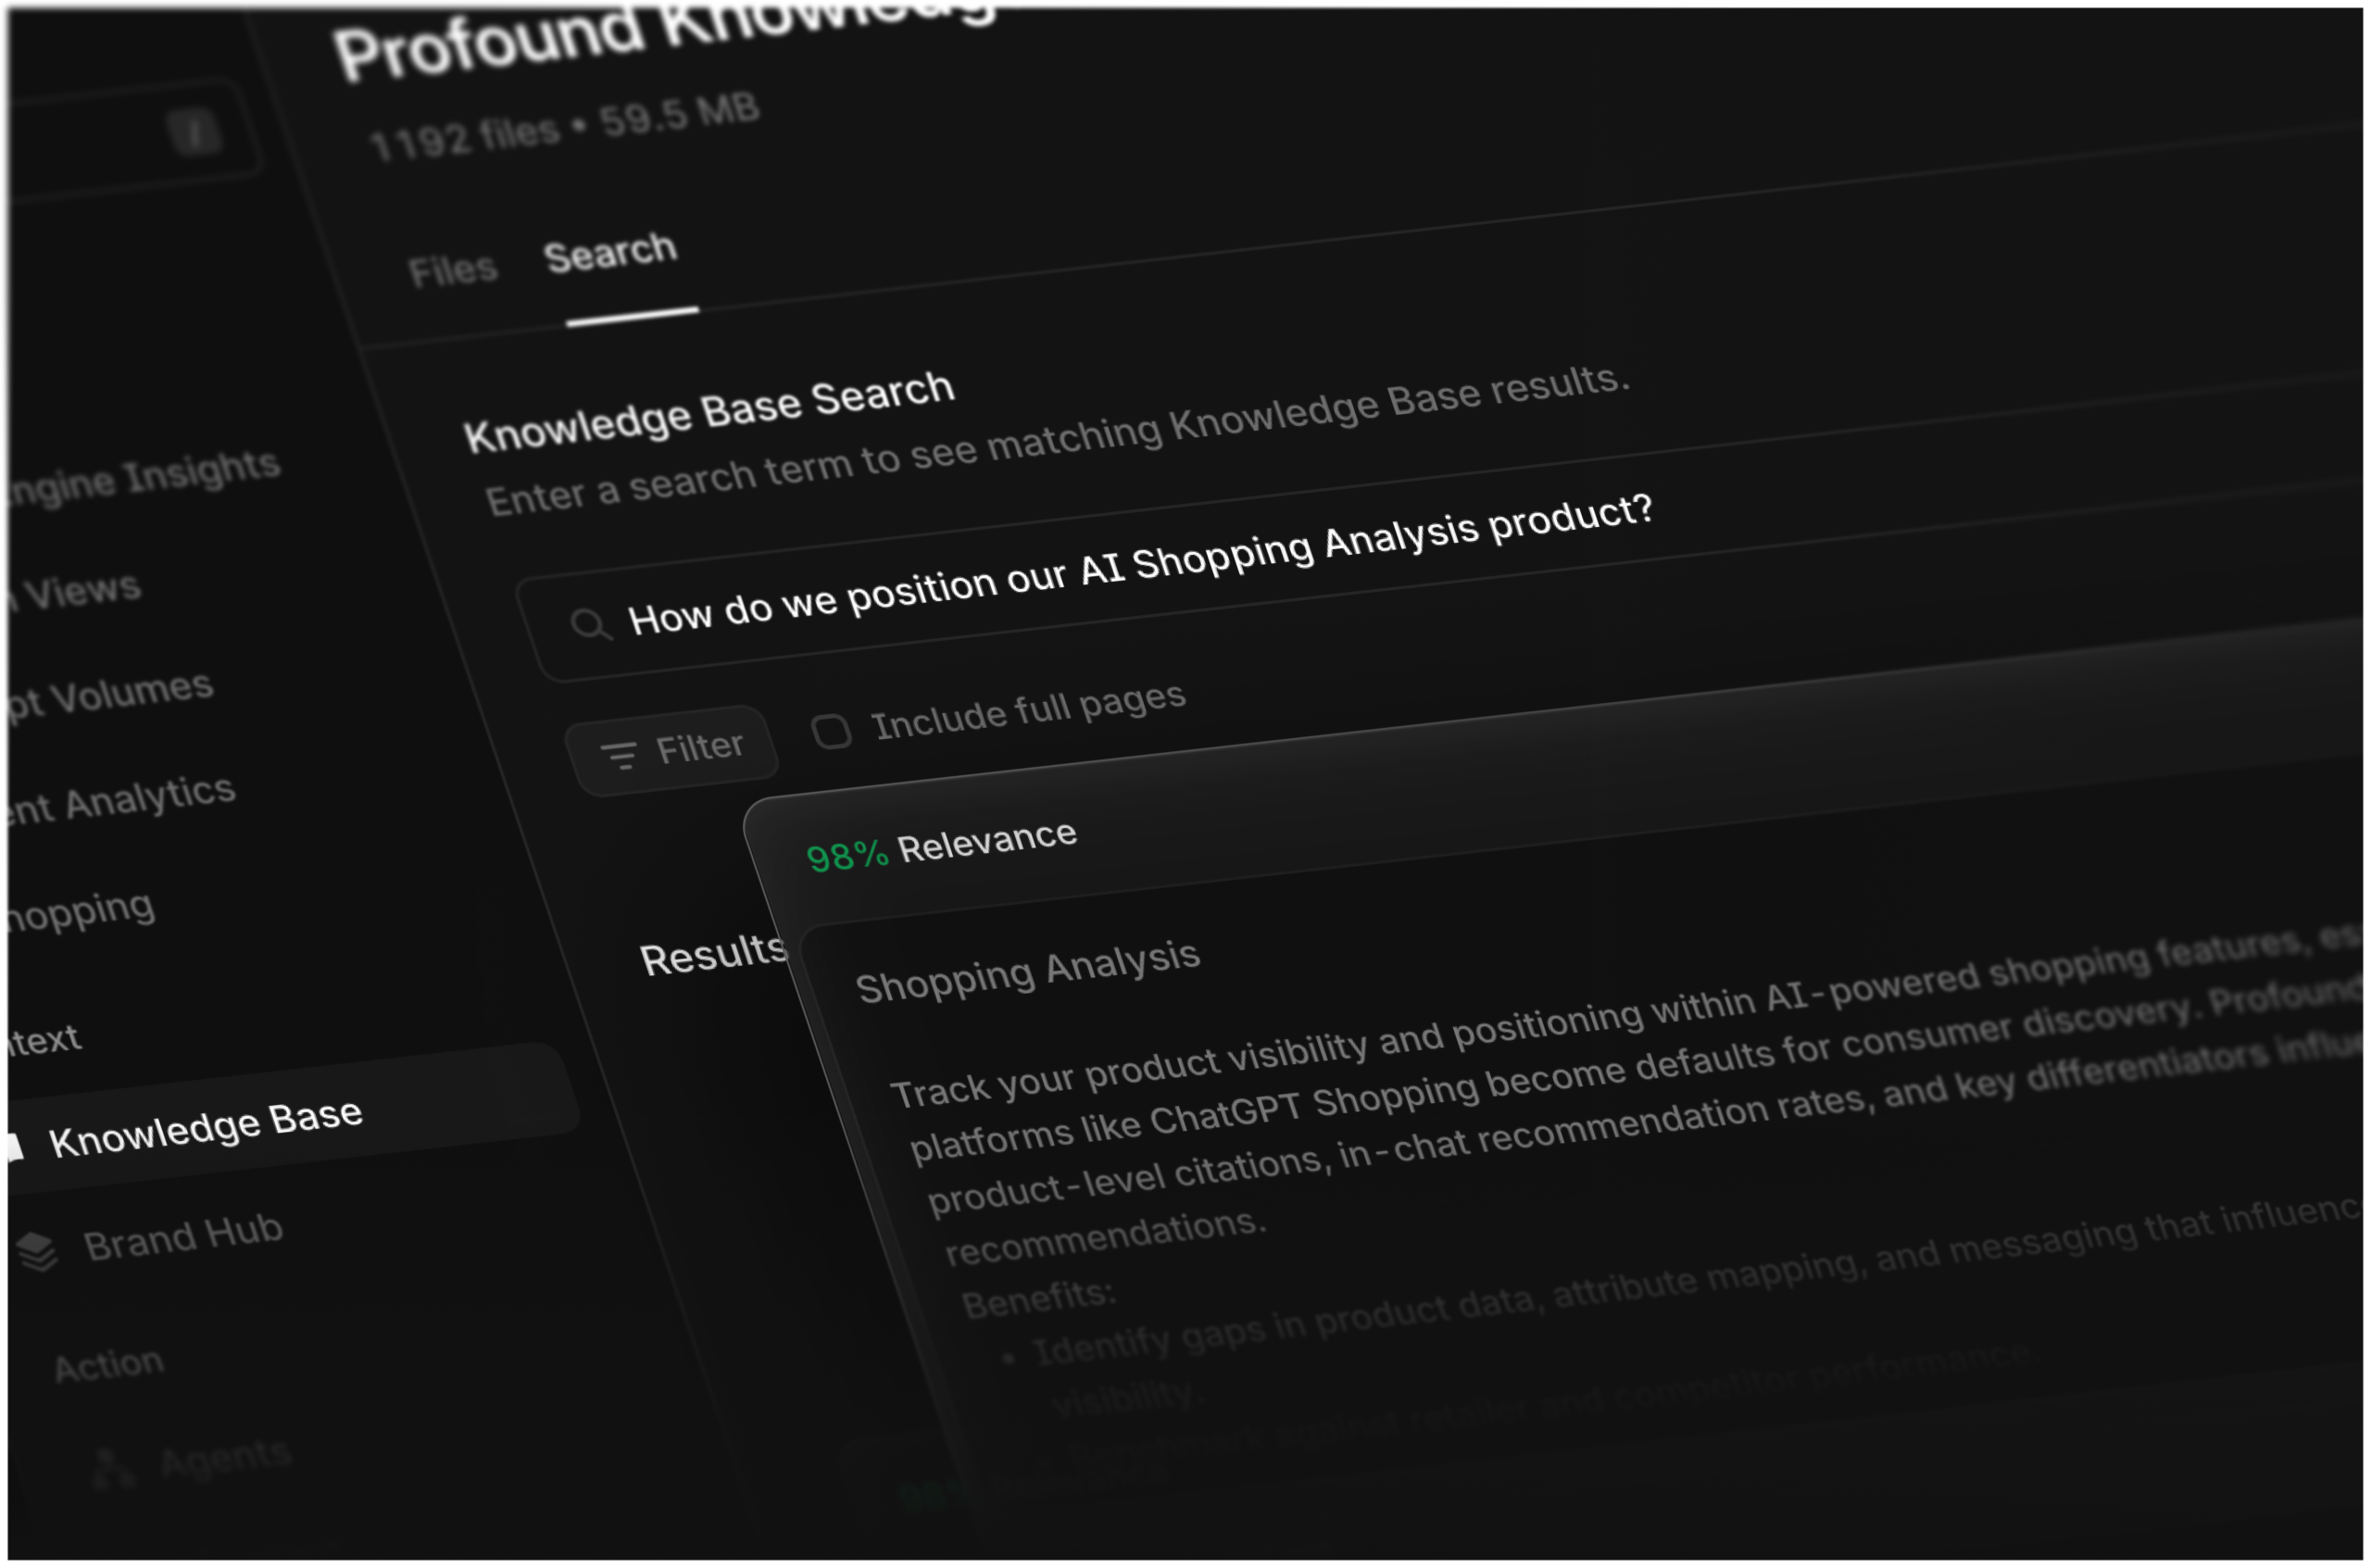
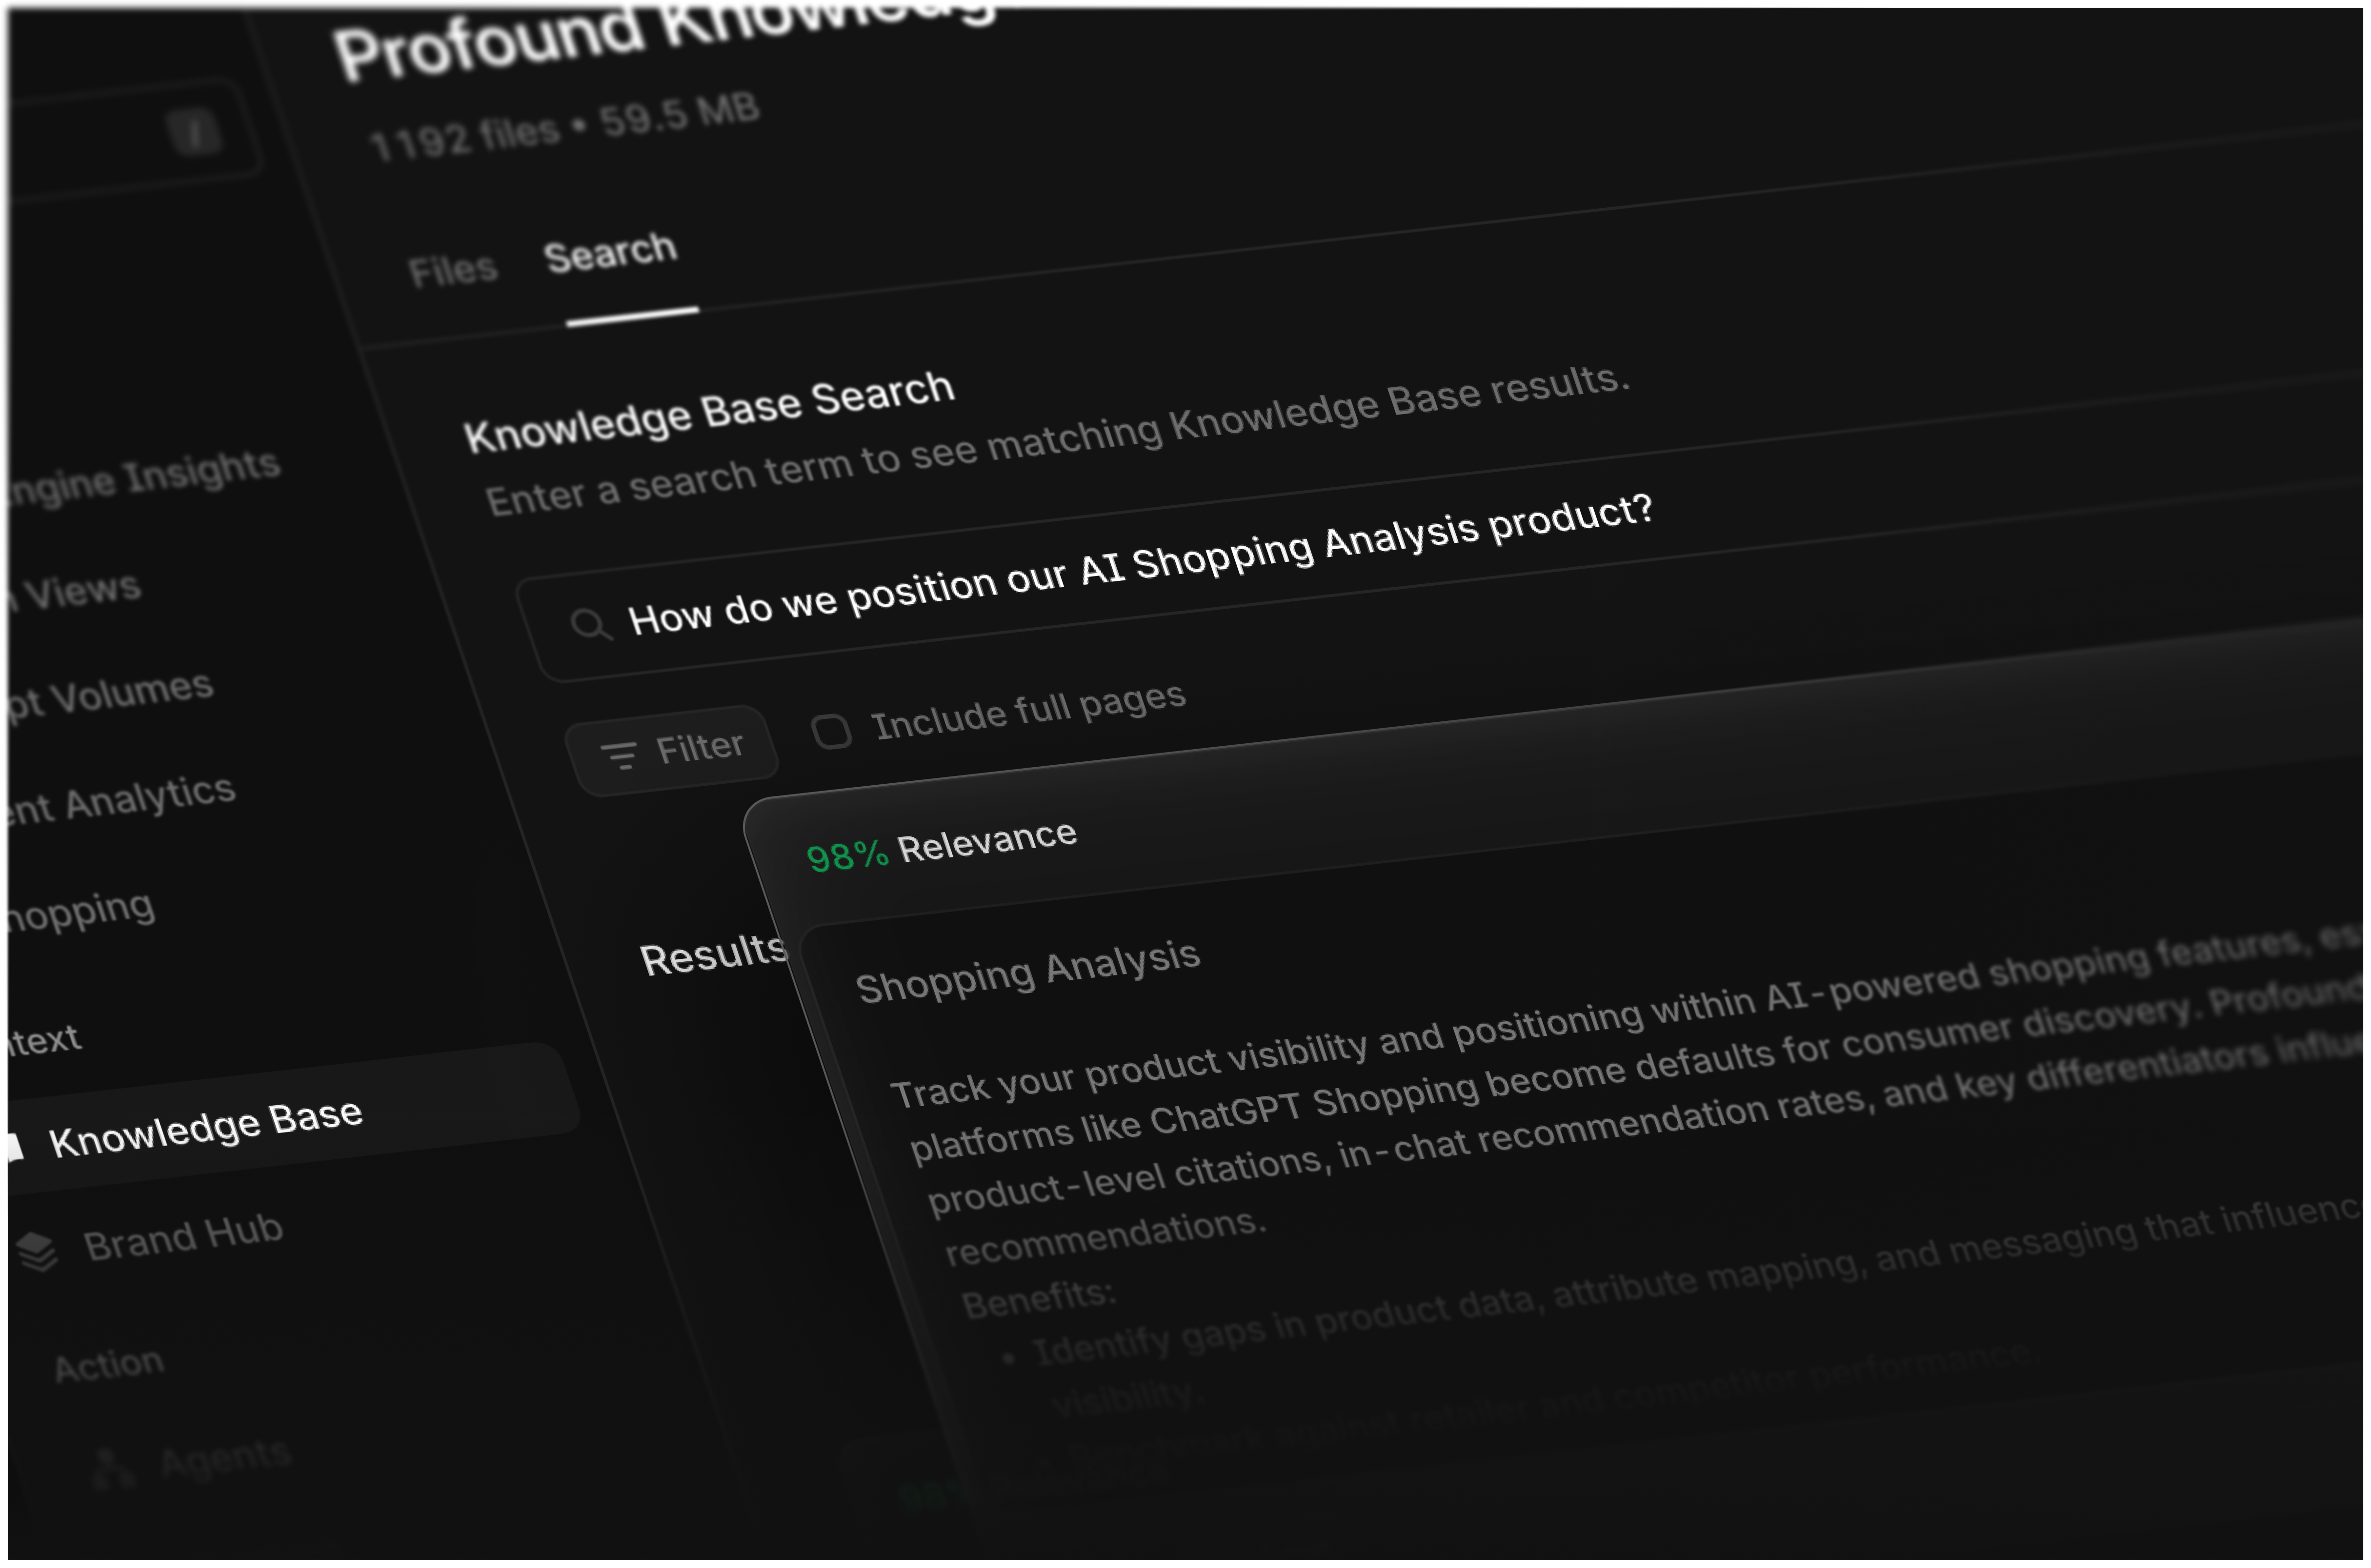
When I upload documents to the Knowledge Base, I provide Profound Agents with a comprehensive, single source of truth about my company’s unique information. This ensures that every marketing action performed on my behalf is informed with the right context about my brand.
Inspired by this post on Try Profound Blog.
Your product page can be perfectly usable by a person and still be unreliable for an AI shopping agent. A shopper can interpret layout, infer which option is selected, notice a warning, and back out of a mistake. An agent needs explicit facts, unambiguous choices, and a safe path from finding an item to taking an action.
If you run an ecommerce or transactional site, the question is no longer just whether an AI system can mention your brand. You also need to know whether an agent can identify the right product, resolve its options, understand the commercial constraints, and complete the next permitted step without guessing. You can prepare for that shift now without treating an experimental protocol as a finished standard.
AI-driven shopping discovery changes the job of a product page. It still has to persuade a person, but it increasingly has to help a machine determine whether a particular product satisfies a particular set of constraints.
That journey has four layers: discovery, decision, action, and confirmation. Traditional search optimization concentrates heavily on the first. An agent-driven experience can fail at any of the other three even when the page ranks, gets cited, or receives a visit.
| Journey stage | What the agent must establish | Typical site-level failure | What to fix |
|---|---|---|---|
| Discover | Whether the page and product match the user’s need | Important facts exist only in images, interface states, or vague promotional copy | Put essential product facts in clear HTML and consistent structured data |
| Decide | Which exact product and variant satisfy the constraints | Sizes, units, compatibility, availability, or variant relationships are ambiguous | Tie every choice to a stable product or variant identifier and its current commercial facts |
| Act | Which operation is allowed and which inputs it requires | The agent must guess what buttons do or manipulate a changing document structure | Expose narrow, named actions with explicit inputs, outputs, and errors |
| Confirm | What changed, what it will cost, and whether further approval is required | A side effect occurs without a review step or a clear result | Return the resolved item, quantity, price, status, and next required decision |
Use those four stages as separate audit columns. If an agent finds the page but selects the wrong size, you have a decision-layer problem. If it selects the correct variant but cannot add it to a cart reliably, you have an action-layer problem. If it can place the same order twice, you have a confirmation and transaction-safety problem. Calling all three problems “AI visibility” hides the work that actually needs to be done.
An action contract cannot repair an unclear catalog. Before you expose callable tools, make sure an agent can resolve one user request to one exact purchasable item. That requires more than a polished product name and a paragraph of sales copy.
The same facts may appear in rendered HTML, Product and Offer structured data, a catalog feed, an internal API, a form, and an agent tool response. They should resolve to the same item and current state. If JSON-LD presents one price, visible copy presents another, and the cart calculates a third, an agent has no unambiguous value on which to act.
Schema markup and an agent tool contract solve related but different problems. Product structured data can describe an item, its offer, and its availability. It does not, by itself, grant an agent a reliable function for configuring the item or changing a cart. A tool contract describes an operation the site is prepared to accept.
A useful shorthand is: schema explains what something is; a tool contract explains what can be done with it. You need both layers to agree, but you should not treat one as a substitute for the other. Keep the human-readable page as the visible source of context, terms, and control as well.
If you can only fix one layer first, fix product truth. A fast agent action that operates on an ambiguous variant is worse than a slower path that asks the user to choose.
Google’s early WebMCP preview proposes a structured way for websites to expose tools to browser agents. A site can publish a Tool Contract through the navigator.modelContext browser API so an agent receives named functions instead of having to infer the meaning of links and buttons from the document structure.
That distinction matters. Raw interface operation is fragile because labels, layouts, overlays, and component states change. A named action can state its purpose, required inputs, expected result, and failure conditions directly. The agent still has to reason about the user’s request, but it should not have to reverse-engineer your checkout interface.
WebMCP describes two approaches. The declarative API is intended for standard actions that can be defined through HTML forms. The imperative API supports more complex or dynamic interactions that require JavaScript execution.
WebMCP is an early preview, so its details may change. Do not rebuild your checkout around it or assume that implementing it creates a search-ranking advantage. Treat the protocol as an experimental delivery mechanism for an interaction model you should design carefully regardless of which standard eventually carries it.
An illustrative shopping sequence might expose searchProducts, getProduct, selectVariant, addToCart, and beginCheckout as separate operations. A submitOrder action would sit behind an explicit review and approval step. Those names illustrate separation of responsibility; they are not prescribed WebMCP syntax.
Resist the urge to publish one general-purpose function that accepts a natural-language instruction and performs an entire purchase. It may look flexible, but it conceals intermediate decisions, makes permissions harder to enforce, and leaves fewer points where the user can inspect or correct the result.
An agent acting on behalf of a shopper can create financial consequences. The site therefore needs a permission model based on what an action changes, not merely on whether the agent knows how to call it.
Do not let an agent infer a missing variant, quantity, shipping destination, or commitment period when the choice affects the transaction. Return the missing field as a required decision. A short clarification is safer than a confidently completed wrong order.
Agents, browsers, and networks can retry an operation after an interrupted response. Your transaction design should ensure that repeating the same confirmed request does not silently create duplicate orders or charges. In engineering terms, the consequential operation should be idempotent or protected by an equivalent duplicate-prevention mechanism.
Keep payment credentials, authentication secrets, and unnecessary prompt content out of general agent analytics. Operational visibility is useful, but it does not justify collecting sensitive data that the team does not need for diagnosis.
The shopper should be able to inspect what the agent selected, edit it in the ordinary interface, and continue without starting over. Before a commitment, show the exact line items and variants, quantities, current charges, applicable fulfilment details, and the action that confirmation will trigger.
A handoff is not necessarily an agent failure. It is the correct result when authentication, policy, missing information, or financial approval requires the person. Design it as an intentional state with preserved context, not as an error page.
Testing whether an agent can call a function is not enough. The real unit of quality is a complete user task: the right item is found, the right option is selected, the allowed action succeeds, and the shopper receives an accurate result. A safe stop also counts as correct behavior when required information or permission is missing.
Track outcomes by journey stage. Useful measures include product-resolution accuracy, completed-task rate, clarification rate, invalid-action rate, duplicate-attempt handling, safe-stop rate, recovery after a structured error, and successful human handoff. Keep discovery events separate from tool invocations and completed actions. Otherwise, an increase in AI-originated visits can conceal a broken decision or checkout path.
Review failures by cause, not only by agent or channel. If several agents choose the wrong variant, inspect the catalog relationships and labels before tuning prompts. If they choose correctly but fail at cart mutation, inspect the action contract and transaction state. That diagnosis tells you whether the next fix belongs in content, schema, product data, interface logic, or the agent tool layer.
Choose one high-value journey this week: product search, variant selection, and add to cart is a sensible starting boundary. Resolve every ambiguity in that path, document its allowed actions and failures, and leave order submission behind an explicit user confirmation. Once that narrow journey works reliably, expand one consequential step at a time.
If ChatGPT recommends your brand but analytics reports no AI conversions, you do not necessarily have a performance problem. You have a measurement gap. A buyer can use AI throughout their research and still enter your site through Instagram, branded search, a bookmark, or a direct visit.
Your job is to separate three questions that dashboards tend to collapse: Can AI find and describe your brand correctly? Does that information help a buyer shortlist you? Does the influence produce a commercial result? Once you measure those separately, you can improve visibility without mistaking every mention for revenue.
Generative engine optimization, or GEO, aligns your brand and content with the way answer engines retrieve, summarize, cite, and recommend information. That makes visibility a useful leading indicator. It does not make visibility the final business outcome.
This distinction matters because appearing in an answer can be surprisingly easy. Self-promotional pages placing their publisher first on a best-provider list have surfaced quickly in AI recommendations. That demonstrates retrievability, not independent authority or buyer confidence. A screenshot of the result is therefore evidence that an answer engine found the page. It is not evidence that a prospect believed it, clicked it, or bought anything.
Prompt-tracking totals also require restraint. API responses and answers shown to real users can differ sharply; one comparison found overlap as low as 24% in some cases. Interfaces can vary by model, account state, location, available retrieval, and the wording or history of a conversation. Use automated tracking to find patterns, but verify commercially important prompts in the live products your buyers actually use.
A practical AI-search scorecard should consequently report accuracy and influence beside visibility. If the brand appears often but is described incorrectly, you have exposure without control. If qualified prospects repeatedly name AI as a decision aid despite few referral clicks, you have influence that last-click analytics cannot see.
No single tool can measure AI-search attribution end to end. The answer may be generated before a visit, the visit may occur through another channel, and the commercial effect may appear as a shorter evaluation rather than an extra conversion. Build one evidence chain from three layers instead.
Start with prompt families tied to real decisions, not a long list of ways to ask for your brand by name. Branded prompts test whether AI knows you; unbranded and comparative prompts test whether it would introduce you when a buyer has not chosen a vendor.
Test the same core prompts in the live interfaces relevant to your market, such as ChatGPT, Perplexity, Gemini, and Google AI Overviews. Record the exact prompt, interface, model when visible, account state, date, answer, cited URLs, and follow-up context. Do not quietly rewrite a prompt until your brand appears; that measures your ability to steer a test, not ordinary buyer discovery.
For each answer, capture whether the brand was mentioned, recommended, cited, or omitted. Then score factual claims individually. Mark a claim as accurate, incomplete, outdated, unsupported, or wrong. Preserve the answer itself so that a later correction can be compared with a real baseline.
A single form field asking how someone heard about you cannot represent a multi-channel decision. The place where a buyer first encountered the brand may differ from the place that validated it. Ask two separate questions:
Allow more than one response to the second question and include an AI assistant option. Keep a free-text field because buyers may name ChatGPT, Perplexity, Gemini, Grok, Google AI Overviews, or simply say they asked AI. If they remember it, ask what they wanted to learn. The prompt topic is often more useful than the platform name because it reveals the decision or objection your content helped resolve.
Do not force the buyer to choose between AI, search, social, email, and word of mouth when several played different roles. Store discovery source and decision influence as separate CRM properties. Preserve the buyer’s own wording in a note rather than translating every answer into a generic AI lead label.
AI can summarize alternatives, reduce uncertainty, and help form a shortlist before the buyer visits a vendor. Its commercial contribution may therefore appear in the sales process rather than the acquisition report. Compare AI-influenced opportunities with other qualified opportunities on:
Business observations have found that some AI-influenced leads needed less education and closed faster. Treat that as a hypothesis to test in your own pipeline, not a universal benchmark. A shorter sales cycle might reflect AI-assisted preparation, but it could also reflect deal type, buyer seniority, budget, or an existing relationship.
| Measurement layer | Evidence to capture | Question it can answer | What it cannot prove alone |
|---|---|---|---|
| Answer | Live outputs, citations, factual accuracy, recommendation language, competitor context | Can the system find and represent the brand? | Whether a buyer saw or trusted the answer |
| Buyer | Discovery response, decision-influence response, named assistant, remembered question | Did AI contribute to consideration? | The exact share of influence attributable to AI |
| Business | Stage timestamps, objections, education needs, conversion, value, outcome | Did AI-influenced opportunities behave differently? | That AI caused the difference without controlling for other factors |
Apply confidence labels instead of pretending every signal is deterministic. Mark attribution as confirmed when the buyer explicitly names AI’s role, supported when self-report and sales evidence agree, and possible when you only see an indirect pattern such as rising branded demand. Keep possible influence out of confirmed revenue totals.
Measurement tells you where the brand is missing or distorted. Correction requires a dependable record that retrieval systems can access and reconcile. Without specific evidence, an AI system may fill gaps from generic category patterns, scattered third-party descriptions, or outdated pages. That failure is often called brand drift.
Do not treat a canonical record as one oversized About page. Build a controlled set of public pages and media in which every important claim has a clear home, a responsible owner, and a visible update path.
Text is appropriate for definitions, specifications, and policies. Video becomes especially useful when a buyer needs to see a real product, process, location, result, or subject-matter expert. It combines spoken explanation, visual context, and a transcript, creating a dense record that can be republished without changing the underlying claim.
Plan the recording around likely misrepresentation. If AI repeatedly invents a feature, have the responsible expert show what the product actually does, state the boundary plainly, and explain the correct workflow. Publish the video on a relevant canonical page with a descriptive title, an edited transcript, speaker identity, supporting links, and VideoObject markup. A transcript should preserve qualifications rather than turning a careful explanation into an absolute promise.
Where your production workflow supports it, retain C2PA-compatible Content Credentials and editing history. Cryptographic provenance can help establish where media came from and whether its recorded chain has been altered. It does not prove that every statement in the media is true, so pair provenance with named expertise, visible evidence, and claims a buyer can verify.
Repurpose the same evidence into an article, short clips, images, audio, FAQs, and social posts. Keep the central facts and qualifiers consistent across formats. The purpose is not to manufacture a larger content count; it is to give retrieval systems several accessible paths back to the same coherent brand record.
Accuracy can make your brand eligible for consideration. Evidence makes it defensible to recommend. This is where self-authored best-provider pages reach their limit: they can state a position, but the publisher and beneficiary are the same entity.
Build content around the questions a cautious buyer asks after discovery. The strongest page is not always the one that praises the brand most. It is often the one that makes the decision criteria, tradeoffs, and evidence easiest to inspect.
Clarity is part of authority. If your homepage describes the offer with a creative slogan while product pages, profiles, and interviews use different category language, both buyers and machines must infer what you actually sell. Keep the positioning distinctive, but repeat the plain category, audience, and use case consistently wherever identification matters.
Maintain an AI-error register alongside your content inventory. For every observed error, save the prompt and answer, identify the false or missing claim, note the cited page if one appears, assign a canonical correction URL, and track the content change. Prioritize errors about core capabilities, compatibility, availability, pricing, or suitability before cosmetic wording differences. Those errors can change a purchase decision.
Retest after correction, but expect variation. A changed answer does not prove permanent removal, and one unchanged answer does not prove the correction failed. Look for a repeated pattern across live sessions and interfaces while continuing to strengthen the public evidence.
AI visibility, brand accuracy, content operations, and revenue measurement should not live in separate projects. Run them as one loop attached to a real buyer decision.
Start with one question that can put your brand on or off a buyer’s shortlist. Capture what the major live interfaces say, correct the public evidence, and add the two attribution questions to your CRM. That gives you a defensible first line from AI answer to buyer decision – and a system you can expand without pretending every mention is a sale.
If you’re being asked for an “AI ads strategy,” don’t start by moving a search campaign into a new interface. An AI experience may be answering a question, narrowing a comparison, selecting an offer, or helping complete a purchase. Your ad has to help with that task without pretending to be the answer.
The practical job is to make four things line up: the user’s decision, the claim the system can verify, the offer you can honor, and the next action you can measure. When one breaks, more targeting or more generated creative won’t rescue the experience.
A conventional search ad usually occupies a known slot between a query and a landing page. An ad inside an AI experience enters a more fluid sequence. The user may have already described constraints, rejected alternatives, requested a comparison, or asked the system to help complete a task.
That does not mean advertisers automatically receive the conversation or control the answer. In the initial ChatGPT design, ads are limited to the Free and Go tiers, kept separate visually and technically from model answers, and hidden from Plus, Pro, and Enterprise users. The model is not informed that an ad is present and does not refer to it unless the user asks. Treat that separation as a real product boundary, not a temporary obstacle to work around.
Google is pursuing a different but related path. Conversational and visual discovery in AI Mode can include sponsored retail listings and Direct Offers intended to help a user continue a shopping journey. The useful planning unit is therefore not merely the keyword, placement, or audience. It is the decision the user is trying to make.
Rewrite each campaign brief as a decision task. “Reach operations leaders” is an audience description. “Help an operations leader compare tools that meet a stated integration requirement” is a task. The second version tells your team what facts, offer, destination, and measurement the experience needs.
The same principle applies outside chat. AI can help connect brands with YouTube creators and turn creator-led discovery into commerce. Define creator fit through the audience problem, acceptable claims, and commercial handoff – not reach alone. A highly visible creator cannot repair a mismatched offer or an unsupported product promise.
AI advertising readiness is not a media-only project. The system may need to understand your business, retrieve a current offer, and pass the user into a reliable transaction. Those are separate layers, and each can fail independently.
Your organic AI visibility and your paid eligibility are different, but they depend on a shared factual foundation. A discovery system should be able to identify what you sell, who it is for, where it is available, what conditions apply, and which page is authoritative.
No schema type guarantees inclusion in an AI answer or an ad placement. The point of structured data is to reduce ambiguity and connect entities, properties, and offers. It cannot compensate for missing content or contradictory records.
An AI-matched ad becomes unhelpful the moment its offer is stale. This matters more when a sponsored option is presented after the user has already supplied detailed constraints. The apparent relevance raises the cost of a mismatch.
For retail, reconcile the identifier, title, destination URL, price, currency, availability, variant, shipping terms, return terms, and promotion conditions across the feed, landing page, structured data, and checkout. For services, do the equivalent with the service area, qualification rules, deliverable, capacity, expected handoff, and any condition that can disqualify the lead.
Assign an owner to every field that can change. Then define which system is authoritative when two records disagree. “The feed team owns price” is incomplete if checkout can display something else. The useful rule is operational: when the source of record changes, every consumer of that field must receive the update, and the affected offer should stop serving if synchronization fails.
Agentic commerce shortens the distance between recommendation and purchase. Google’s Universal Commerce Protocol is intended to standardize AI-assisted browsing, purchasing, and transaction completion. That makes checkout reliability, inventory state, and exception handling part of advertising quality.
Do not enable an automated purchase path while duplicate-order protection, cancellation, or exception handling remains untested. The downside is not a weak engagement metric; it is an incorrect charge, unavailable order, or commitment the user did not understand. Keep a confirmation step and a conventional checkout alternative until the failure paths are reliable.
Relevance does not excuse hidden influence. An AI answer carries a different kind of perceived authority from a familiar ad slot, so sponsorship has to remain legible at the moment the user evaluates the recommendation.
ChatGPT’s initial guardrails include not sharing conversations with advertisers, excluding ads from health, politics, and other sensitive discussions, and giving users personalization controls. These are platform-specific commitments, not universal rules for every AI ad product. Verify the controls and exclusions of each channel before you approve a campaign.
Your own delivery specification should cover the following:
Do not report a sponsored appearance as proof that a model independently recommends your brand. Do not report an organic mention as paid campaign delivery. They answer different questions.
This separation protects your reporting and your optimization. A bid or budget cannot make weak facts more authoritative. Better organic answer coverage does not guarantee sponsored distribution. Both programs can improve the same landing pages and entity records without pretending to be the same channel.
Generative tools can make asset production much faster. Google’s advertising direction includes Gemini 3, Nano Banana, Veo 3, and AI Max for creative production, reach, and campaign optimization. Faster production increases the need for tighter review because one outdated input can be repeated across many polished variations.
Start creative generation from an approved claim set, not an open-ended prompt. Require each variation to retain the qualifying language, destination, and current offer. Store the asset with its source claim and offer identifier. When the underlying fact changes, you can then find and retire every affected version instead of searching campaigns by eye.
A broad launch makes diagnosis difficult. If performance disappoints, you will not know whether the problem was matching, creative, answer readiness, offer accuracy, the landing-page handoff, or transaction friction. A narrow pilot gives each failure somewhere specific to land.
Click-through rate can diagnose whether a sponsored option attracts attention, but it cannot tell you whether the AI-assisted decision was good. Define qualification and completion before launch, then measure the handoff with metrics that expose both performance and failure.
| Metric | How to calculate it | What it helps you decide |
|---|---|---|
| Qualified action rate | Qualified actions divided by attributed AI ad visits | Whether matching and creative are producing commercially relevant responses |
| Offer consistency rate | Audited offers whose ad, destination, structured data, and transaction terms agree divided by all audited offers | Whether the commercial data is dependable enough to scale |
| Decision completion rate | Confirmed target outcomes divided by eligible initiated paths | Whether the handoff helps the user finish the intended task |
| Outcome quality rate | Accepted, retained, or otherwise qualified outcomes divided by completed outcomes | Whether apparent conversions remain valuable after validation |
| Mismatch or complaint rate | Recorded relevance, sponsorship, offer, or transaction complaints divided by attributable interactions | Whether utility is being purchased at the cost of trust |
| Incremental outcome | Difference between exposed and valid comparison groups | Whether the channel created value beyond outcomes that would have happened anyway |
Set the definitions, data owner, and decision rule for each metric before anyone sees campaign results. Otherwise, teams tend to relax the meaning of “qualified” or emphasize whichever event improved.
Pause the affected offer or path when the ad claim is absent from the destination, displayed terms disagree with checkout, inventory cannot be confirmed, users mistake sponsorship for an independent answer, or additional conversions arrive with a corresponding rise in reversals, refunds, or disqualified leads. These are not creative-learning signals. They indicate that the experience is making a promise the operating system cannot reliably keep.
Your first move does not need to be a large media commitment. Choose a commercially important decision, make its facts and offer machine-readable, connect it to a dependable action, and define the conditions that will stop the campaign. That foundation will remain useful as AI ad formats, matching systems, and agentic purchase paths continue to change.
Your Google Ads account can look healthy while it produces less useful business. Conversion volume rises, cost per conversion falls, or a campaign spends its full budget, yet qualified leads, profitable orders, or product coverage move in the wrong direction.
Random setting changes make that problem harder to diagnose. Use a fixed order instead: verify the outcome Google Ads is pursuing, check whether the right products can enter the right campaigns, investigate where lead quality breaks down, and test one plausible correction at a time. That sequence separates a measurement problem from a coverage problem, a traffic problem, and a genuine campaign-performance problem.
Before inspecting bids, assets, audiences, or budgets, ask one question: if this campaign generated more of its selected conversion, would the business actually want more of it?
A form submission may be easy to count, but it isn’t necessarily a useful lead. A low cost per lead can hide bot submissions, disposable email addresses, people outside your service area, or prospects who never qualify. When those submissions are treated as successful conversions, automation has a reason to find more people who behave the same way.
That creates a common diagnostic trap. The campaign appears to be improving against the metric shown in Google Ads while deteriorating against the outcome recorded in the CRM. The platform and the sales team aren’t necessarily contradicting each other; they are measuring different stages of the same journey.
Performance Max is especially sensitive to the signal you supply. If the selected goal rewards an easy conversion, the campaign may pursue cheaper conversions without improving the pipeline. Optimizing toward sales-qualified or closed-won outcomes gives the system a closer representation of what the business values.
If you cannot send reliable downstream data back yet, don’t disguise the limitation. Keep platform conversions and CRM-qualified outcomes side by side in your reporting. You can still diagnose the gap, but you should not interpret a falling cost per form fill as conclusive business improvement.
When a Shopping or Performance Max product isn’t generating expected results, start with eligibility. A product that cannot enter the intended campaign will not be rescued by a larger budget. Conversely, a product included in several campaigns may create an ownership and budget-control problem that aggregate campaign reports obscure.
The Products section can now show which campaigns each product is eligible and not eligible for. Its product table includes status, issues, and priority flags; filters help isolate relevant groups; a line graph summarizes campaign-status trends; and the product-level panel exposes campaign eligibility without requiring you to reconstruct it from separate campaign views.
| What you see | What it indicates | What to do next |
|---|---|---|
| A product is absent from the expected campaign’s eligible list | A coverage or eligibility problem exists before bidding begins | Inspect its status, issues, and campaign setup |
| A product appears in several campaigns unexpectedly | Campaign ownership is unclear or overlapping | Decide which campaign should own the product and remove unintended coverage |
| A product is eligible in the intended campaign but produces no useful result | Eligibility is working; the cause lies later in delivery or conversion | Investigate demand, bids, assets, landing experience, and economics |
| Eligibility trends change across a larger product group | The problem may be systematic rather than product-specific | Identify the affected group and compare the shift with recent account or catalog changes |
Eligibility is a prerequisite, not a promise of impressions, clicks, or sales. That distinction matters. Once coverage is correct, a lack of results becomes a performance question. Until then, performance adjustments are aimed at the wrong layer of the account.
Performance Max can reach people across Search, Display, YouTube, Discovery, and Gmail. That reach gives automation more ways to find conversions, but it also creates more routes to low-intent or spam-driven submissions when the account rewards every captured lead equally.
Diagnose poor lead quality as a chain. The ad attracts a person, campaign settings decide where and when the opportunity can occur, the form determines who can submit, and the conversion setup tells Google which submissions count as success. A weakness at any one of those points can make the final campaign metric misleading.
A useful intervention changes the inputs that determine who can convert or what the system learns from a conversion. The strongest lead-quality controls for Performance Max fall into four groups:
Form friction needs judgment. Every extra rule can reject a bad submission, but it can also obstruct a legitimate prospect. Tie each validation rule or question to a rejection pattern you can actually see. A field that no one uses to qualify, route, or follow up on a lead is merely extra work for the visitor.
Switching bid strategies, adding assets, or increasing budget may change reach, conversion volume, or cost. None inherently teaches the campaign what a qualified lead is. Treating them as primary lead-quality fixes can scale the existing problem.
This doesn’t make those levers useless. It means their purpose must match the diagnosis. Add budget when a campaign is producing economically useful demand and is constrained from capturing more of it. Test assets when the message or creative is the suspected problem. Change bidding when the bid strategy itself conflicts with the campaign objective. If the underlying issue is that cheap junk leads are being counted as success, repair the success signal first.
Google Ads can surface ready-to-run experiments based on account setup and performance data. Suggested tests may cover bidding, creative variations, or campaign features, and their configurations can be adjusted before launch. Final URL expansion is one example of a feature Google may propose testing.
A preconfigured experiment removes setup work; it does not establish that the recommendation fits your objective. Treat every recommendation as a hypothesis. If you cannot state what problem it is meant to solve, don’t spend budget testing it yet.
Keep the test narrow enough that its result is interpretable. If you change bidding, creative, destinations, audience inputs, and conversion goals together, a better result will not tell you which change helped. A worse result will be equally difficult to reverse intelligently.
Some recommendations alter more than a visible setting. A final URL expansion test, for example, can change which pages receive traffic. Before launch, inspect the pages that could become destinations and ask whether their message, conversion path, and audience fit the campaign. Evaluate the experiment against qualified outcomes or useful orders, not merely the extra traffic or top-of-funnel conversions it may generate.
Recommended bidding and creative experiments deserve the same scrutiny. Confirm the campaign objective, conversion action, scope, and guardrail metrics. Edit a suggested configuration when it doesn’t match the business question. The convenience of a prepared setup is valuable only after the design is valid.
If the original problem was lead quality, a rise in platform conversions is not enough to declare a winner. Follow those conversions through qualification and, when the available data supports it, through closed outcomes. If the problem was product coverage, verify that the affected products became eligible in the intended campaign before interpreting later sales performance.
Open the account with one documented symptom, not a general intention to optimize. Trace that symptom to its first broken layer, make the smallest change that addresses the cause, and preserve the result as evidence for the next decision. That is how account maintenance becomes diagnosis instead of guesswork.
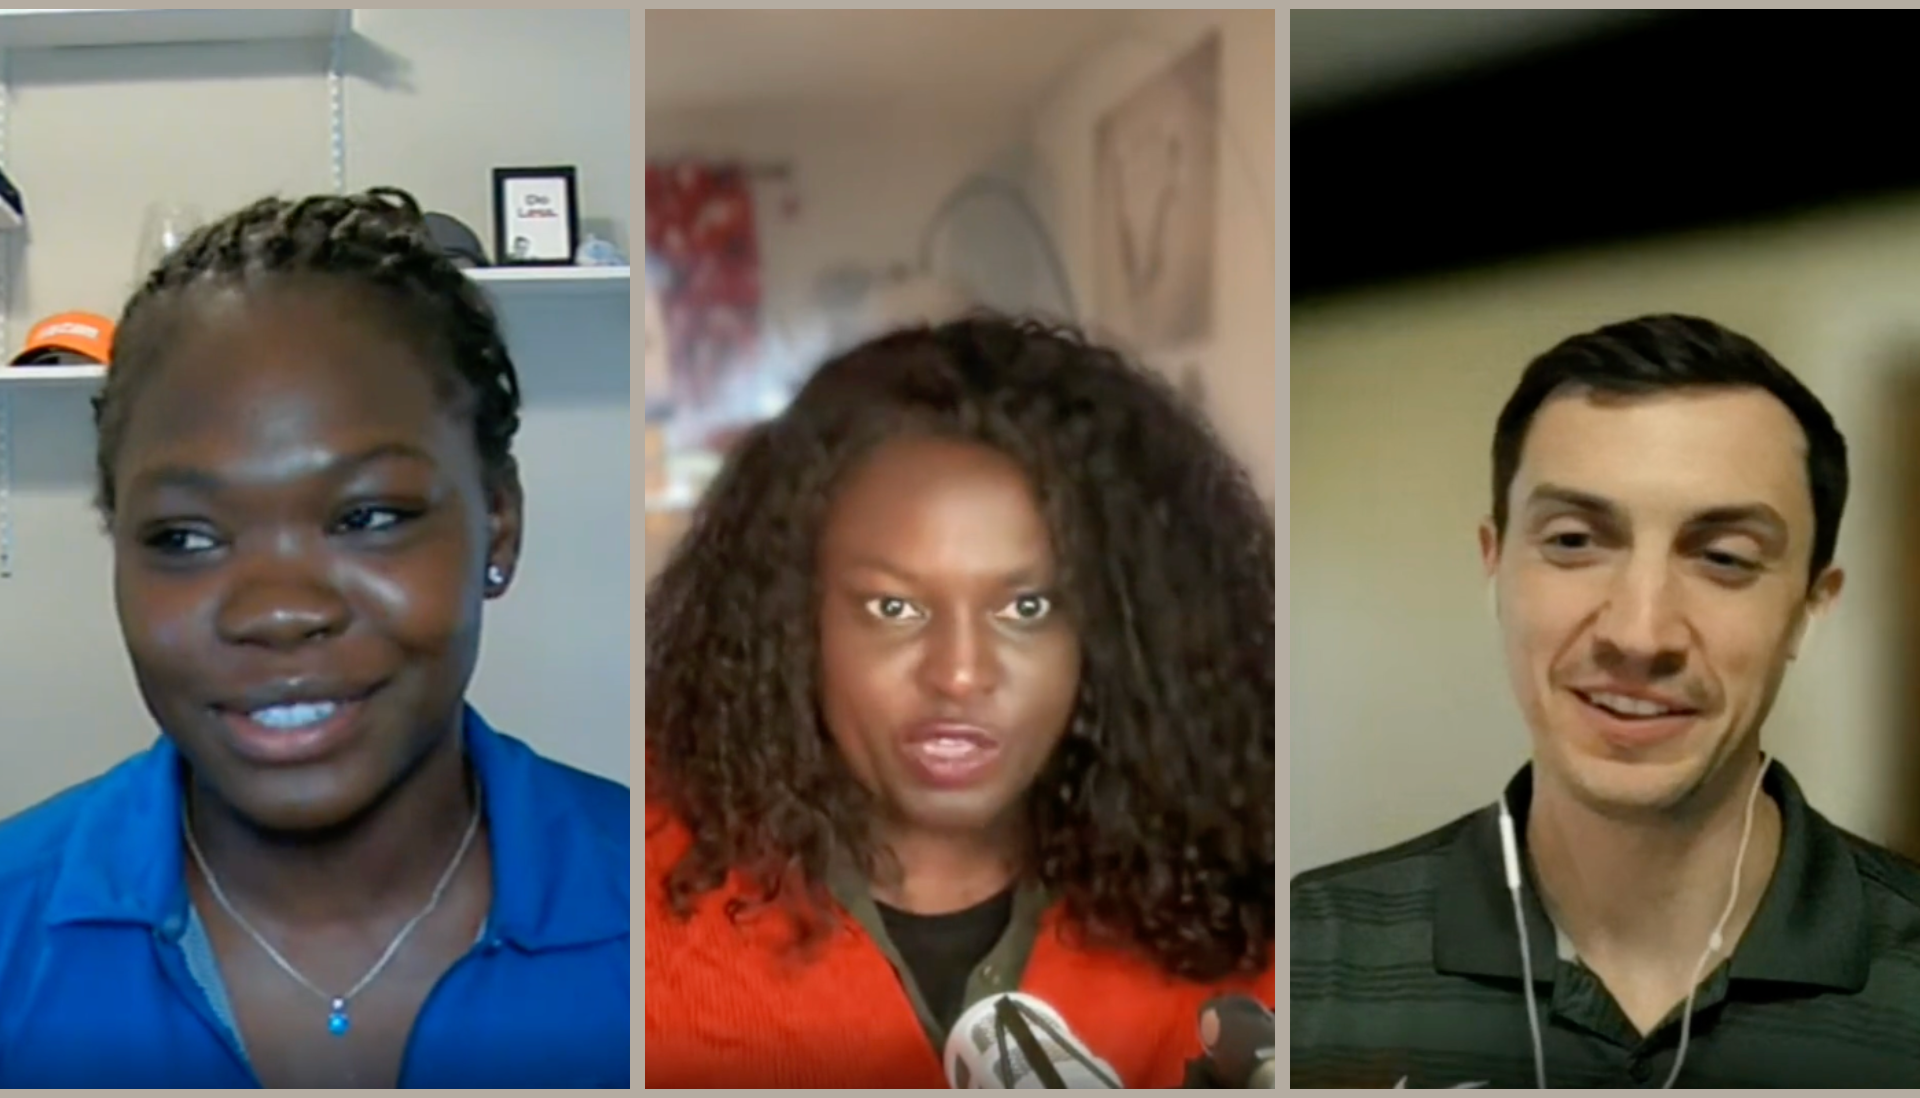
Let me share a few valuable lessons I’ve learned about PPC advertising from seasoned experts. Even the most experienced among us encounter pitfalls—like hastily launching campaigns or leaving automation unchecked. Recently, I joined Greg Kohler from ServiceMaster Brands and Susan Yen from SearchLab Digital at SMX Next, where we candidly discussed the mistakes that catch us off guard.
Read on to discover the blunders that even the most seasoned marketers must navigate.

This is a well-known pitfall, yet it continues to happen. Susan Yen mentioned that due to client demands, campaigns often go live on Fridays, leading to weekend chaos if things go awry. A minor error like an inflated budget setting can cause significant issues.
Greg Kohler emphasizes the importance of reviewing setups with fresh eyes. Wait until Monday to launch; doing so may avert unnecessary problems. Even experts can become overconfident, only to be reminded of these lessons by a Friday crisis.
Takeaway: Avoid launching before the weekend or holidays and stand firm if clients push. It protects both your peace of mind and campaign performance.
Greg shared an experience where an error in location targeting meant campaigns ran in the wrong timezone. By Saturday, ads intended for a U.S. audience accumulated thousands of views in Europe instead.
Takeaway: Configure location settings directly within the Google Ads interface to minimize risks and ensure precise targeting.
Susan stressed that search term reports are essential for every campaign. Ignoring them can lead to wasted clicks and difficult client conversations later on. She advises checking these reports monthly to avoid irrelevant traffic.
Takeaway: Routine reviews help refine what to target or exclude, enhance performance, and maintain efficient account strategy.
The gap between the Google Ads Editor and the interface often leaves teams in a bind. Susan’s team preps in Excel before using Editor for bulk edits but prefers the interface to ensure accuracy in settings.
Takeaway: Use the interface for tasks requiring precision, like responsive ads or location targeting.
Automatically created assets often default to ‘on,’ requiring tedious navigation to disable. New types of assets can inadvertently apply to all campaigns.
Takeaway: Regularly review these settings. Set reminders to maintain control as new features roll out.
Yen warned of the pitfalls of importing Google campaigns directly into Microsoft Ads due to discrepancies in budget assumptions and automation settings.
Takeaway: Treat Microsoft Ads independently with a tailored strategy post-import for optimal results.
A slip in excluding app audiences can direct spend to irrelevant categories. Yen advises vigilance, as settings to exclude these are often hidden.
Takeaway: Establish comprehensive exclusion lists to guard against inappropriate targeting.
Applying content exclusions from the start helps avoid placement in irrelevant or inappropriate contexts, though manual follow-up remains necessary.
Takeaway: Consistent reviews ensure Google honors your settings, preventing unwelcome surprises.
Susan highlighted the importance of client communication in effectively tracking call quality, advocating for monthly check-ins focused on conversion metrics.
Kohler suggested distinguishing first-time from repeat callers in analytics to optimize automated bidding systems.
Litner pointed out issues with scheduled assets appearing outside their promotional windows, urging manual checks to ensure proper timing.
Kohler echoed similar concerns with automated rules potentially misfiring.
Takeaway: Verify scheduled actions on their launch dates manually to prevent mishaps.
The issues of AI-driven campaign settings defaulting to active require diligence in monitoring and fine-tuning each setting.
Takeaway: Despite AI advancements, practice consistent oversight to manage budget spend effectively.
Susan flagged the risk of overlooking critical account-level settings that can derail campaigns silently, suggesting a standardized checklist approach.
Takeaway: Establish and follow a thorough account setup checklist to catch any hidden conflicts with campaign goals.
Here are several recurring themes from our discussion:
The takeaway is that everyone makes mistakes. The difference lies not in avoiding them but in swiftly addressing them, learning from experiences, and creating systems to prevent recurrence. As Kohler notes, stay vigilant, question automation, and avoid the temptation of a Friday launch.
Inspired by this post on Search Engine Land.
Every day, millions turn to ChatGPT for answers, but have you noticed your brand isn’t included in those results? I’ve been there, wondering why my brand isn’t gaining visibility and how to change that. If you’re like me and want to understand what’s happening, I’ve gathered the seven main reasons why ChatGPT might be ignoring your brand.
Understanding these reasons is the first step to making a change. You’ll learn specific steps to enhance your visibility in AI searches, and I can tell you from experience, it’s worth the effort.
Perhaps you’re wondering: what can I do to ensure my brand stands out? Don’t worry, I’m here to guide you through actionable strategies for gaining prominence in AI search results.
Inspired by this post on genmark.ai Blog.
You probably do not need another lead generation tool. If your automated campaigns produce cheap form fills that sales rejects, the system is working exactly as instructed: it has learned that submitting a form is the outcome that matters.
The fix is to give automation a visible path from early interest to qualified pipeline, then make each campaign optimize for one stage of that path. You can scale from there without mistaking activity for demand.
B2B automation has a signal problem. A purchase platform can often see an order, its value, and the ad that produced it within a short period. B2B campaigns may generate fewer conversions, lack an immediate transaction value, and feed a sales process that can continue for more than a year.
The bidding system cannot infer what happened in your CRM unless you send that information back. Left alone, it will favor the observable event it receives most frequently. That is usually the form submission, regardless of whether the person used a personal email address, fell outside your service area, represented the wrong company size, or never progressed beyond the first sales review.
Before changing bids, audiences, creative, or campaign types, answer four questions:
Your ideal optimization event is not automatically the final sale. A closed deal may be economically meaningful but too delayed or infrequent to guide every campaign. A marketing qualified lead may be available sooner, while an accepted opportunity may carry a stronger connection to revenue. Choose the deepest stage that is both trustworthy and repeatable, then continue importing later outcomes for measurement.
Do not judge this system on lead count alone. Review the number of leads, the share becoming qualified, the opportunities created, and the deals closed. One documented implementation reported a 150% increase in leads, a 350% increase in opportunities, and a 200% increase in closed deals. That is a single case result, not a benchmark, but the uneven movement across stages makes the important point: top-of-funnel volume and downstream value do not necessarily rise at the same rate.
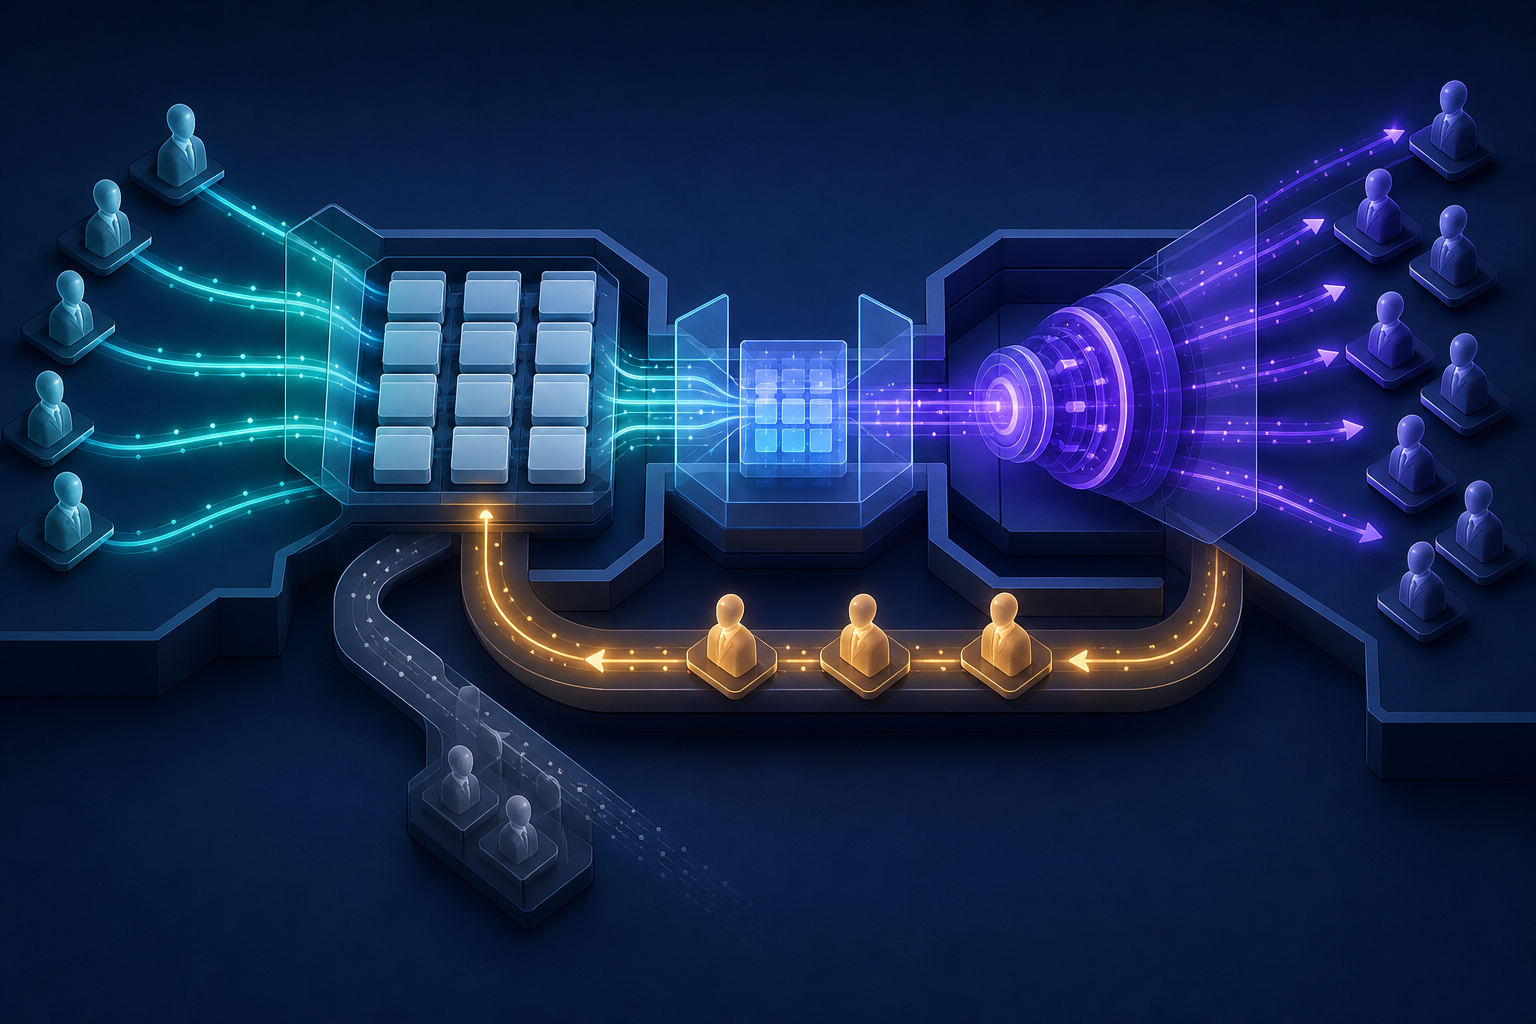
Offline conversion tracking is the foundation of automated B2B acquisition. Your ad platform needs to learn when an online inquiry becomes a qualified lead, an opportunity, or a customer. Google Ads Data Manager provides integration paths involving HubSpot and Salesforce, as well as custom workflows using systems such as Snowflake and Zapier.
The connector matters less than the integrity of the lifecycle data moving through it. A fast integration will only automate confusion if sales and marketing use the same CRM stage for different situations.
Micro conversions can help when qualified outcomes are sparse or delayed. The important move is to assign relative values that express the difference between curiosity and commercial intent. One workable example uses values of 1 for a video view, 10 for an asset download, 100 for a form fill, and 1,000 for a marketing qualified lead.
| Event | Example relative value | What it tells the system | How to treat it |
|---|---|---|---|
| Video view | 1 | The visitor showed initial interest | Use as a weak supporting signal, not proof of demand |
| Asset download | 10 | The visitor exchanged attention for useful material | Use as a stronger engagement signal, while checking whether the asset attracts your ideal buyer |
| Form submission | 100 | The visitor initiated direct contact | Count it as intent, but separate valid prospects from spam and poor-fit inquiries |
| Marketing qualified lead | 1,000 | The record passed an agreed qualification rule | Use as a primary quality signal when the CRM stage is reliable |
These are utility points, not universal prices. Do not label them as revenue or report a value-based bid result as financial return on ad spend unless the values actually represent money. Their purpose is to tell the optimizer that one qualified lead should matter far more than one video view.
Review how much total conversion value each event contributes. A low-value event can still dominate if it happens often enough. If video views or downloads create most of the recorded value, the campaign may learn to buy abundant engagement instead of scarce business intent. Reduce the shallow event’s value, remove it from the campaign’s optimization goal, or keep it for observation only.
Also control repeated actions. One person replaying a video, downloading several files, or submitting the same form twice should not automatically look more valuable than a newly qualified account. Your counting rules, deduplication, and CRM logic must reflect the business event you actually want to reproduce.
An account-wide list of conversion actions is not a strategy. If the same campaign is rewarded for video engagement, downloads, inquiries, and qualified leads without a clear hierarchy, the easiest event can overpower the event that matters.
Use campaign-specific goals to match optimization to the campaign’s role:
This separation also makes diagnosis easier. If an awareness campaign produces inexpensive views but no later demand, you can question the audience or message without contaminating the performance signal of a campaign designed to generate qualified inquiries.
Low volume does not always require collapsing every initiative into one campaign. When several campaigns serve similar buyers and pursue the same conversion goal, portfolio bidding can combine their data. It is particularly useful when separate campaigns struggle to reach the commonly cited 30-conversion-per-month threshold. Portfolio strategies can also provide a maximum cost-per-click cap, which helps limit runaway bids.
Only pool campaigns whose economics and objectives belong together. Combining a high-value enterprise offer with a low-value self-service offer may produce more data, but the shared strategy will be learning from two different businesses. More observations do not help when they describe incompatible outcomes.
Your first-party CRM data should also shape targeting. Customer lists can support exclusions when acquisition campaigns should not spend on current customers. Contact and prospect lists can be used for observation, direct targeting, or audience signals where the campaign type permits. These lists give broad, AI-driven campaigns a concrete description of the people and accounts you already recognize.
Performance Max is not automatically unsuitable for B2B lead generation. It becomes a defensible test after you have reliable offline outcomes, sensible conversion values, a campaign-specific goal, and useful first-party signals. A Target ROAS strategy can then optimize toward recorded customer value instead of treating every conversion as equivalent. If you use relative utility points rather than monetary values, remember that the resulting ROAS is an optimization ratio, not an accounting measure.
AI can shorten research, organization, and drafting work, but it cannot repair a missing feedback loop. Put it on bounded tasks whose outputs a marketer can inspect before they affect bids, budgets, exclusions, or customer communication.
Start with a reusable context brief. Include your offer, differentiators, target personas, ideal client profile, buying roles, disqualifiers, and approved claims. Explicitly state that the customer is another business; that B2B instruction changes the frame of the response and reduces the chance of receiving consumer-oriented ideas.
Prompt skeleton: You are supporting B2B demand generation for [company]. We sell [offer] to [ideal client profile]. The buying group includes [roles]. Our differentiators are [approved claims], and we do not serve [disqualifiers]. Complete [task]. Separate verified inputs from inferences, identify missing information, and do not invent competitor claims or customer evidence.
That context can support several practical workflows:
Keep consequential decisions outside a fully automatic chain until you trust the inputs and failure modes. A mistaken theme label is easy to correct. An automatically applied negative keyword can suppress qualified demand, while an unverified competitor claim can create reputational or legal exposure. Let AI propose; require an accountable person to approve.
Use controlled experiments for bid strategies, match types, and landing pages. Write the hypothesis and success measure before launch. If you change the audience, bid strategy, offer, creative, and page at once, even a positive result will not tell you which decision to repeat.
You do not need to rebuild the whole account at once. Start with one meaningful campaign and make its data path trustworthy before expanding the design.
Your next step is small: choose one campaign, one qualified CRM stage, and one imported offline event. Trace a real record through that loop. Once the campaign can tell the difference between a completed form and a viable prospect, additional automation has something worth scaling.