Author: shivamcrushpressai

  • How to Build an AI-Assisted SEO Workflow You Can Trust

    How to Build an AI-Assisted SEO Workflow You Can Trust

    You have the data. The problem is getting Google Search Console, GA4, Google Ads, and AI visibility signals into the same decision before the opportunity goes stale. Copying numbers between tabs is slow, and asking an AI assistant to interpret an unstructured pile of exports is fast but difficult to trust.

    A useful AI-assisted SEO workflow fixes both problems. Scripts collect a defined set of data, the AI analyzes local files under explicit rules, and you approve every consequential action. The goal is not automated SEO judgment. It is faster, traceable analysis that gives your judgment better inputs.

    Start with the decision, not the AI tool

    The most common design mistake is automating a report before deciding what the report should change. That produces a polished summary, not a workflow. Begin with one recurring question that currently takes too long to answer.

    A strong first use case is paid-organic overlap: which paid search terms consume budget even though related organic queries already perform well? This question becomes much easier when an assistant can examine Google Ads search terms alongside Search Console query and page data. It also exposes an important boundary: organic visibility alone does not prove that paid coverage is unnecessary.

    Define the decision before you build anything. For paid-organic overlap, the decision might be whether a term should remain unchanged, receive a controlled bid test, or be investigated further. The AI should identify candidates and show its evidence. It should not label spend as waste or change a campaign on its own.

    Write a small analysis contract for the question:

    • Decision: Identify search terms that may justify a paid-coverage test because corresponding organic queries and landing pages are already strong.
    • Time window: Use one explicit date range across every compatible dataset. If a file covers a different period, flag it instead of silently joining it.
    • Unit of analysis: Keep the search term, organic query, landing page, and campaign visible. Do not collapse everything into a keyword total.
    • Matching rule: Show exact normalized matches first. Put close or semantic matches in a separate group so a human can inspect them.
    • Evidence: Return the relevant metrics, file names, and row references behind every candidate.
    • Allowed outcomes: Use labels such as keep, test, and investigate. Avoid definitive labels such as waste unless your business rules actually establish that conclusion.
    • Exclusions: State which terms or campaigns should not be evaluated automatically, including any branded, defensive, regulated, or strategically protected coverage.

    This contract does more than improve the prompt. It tells you which data must be collected, which joins are legitimate, and where human review belongs. If you cannot describe the decision in these terms, adding another API will not make the workflow useful.

    Build a small, auditable SEO data project
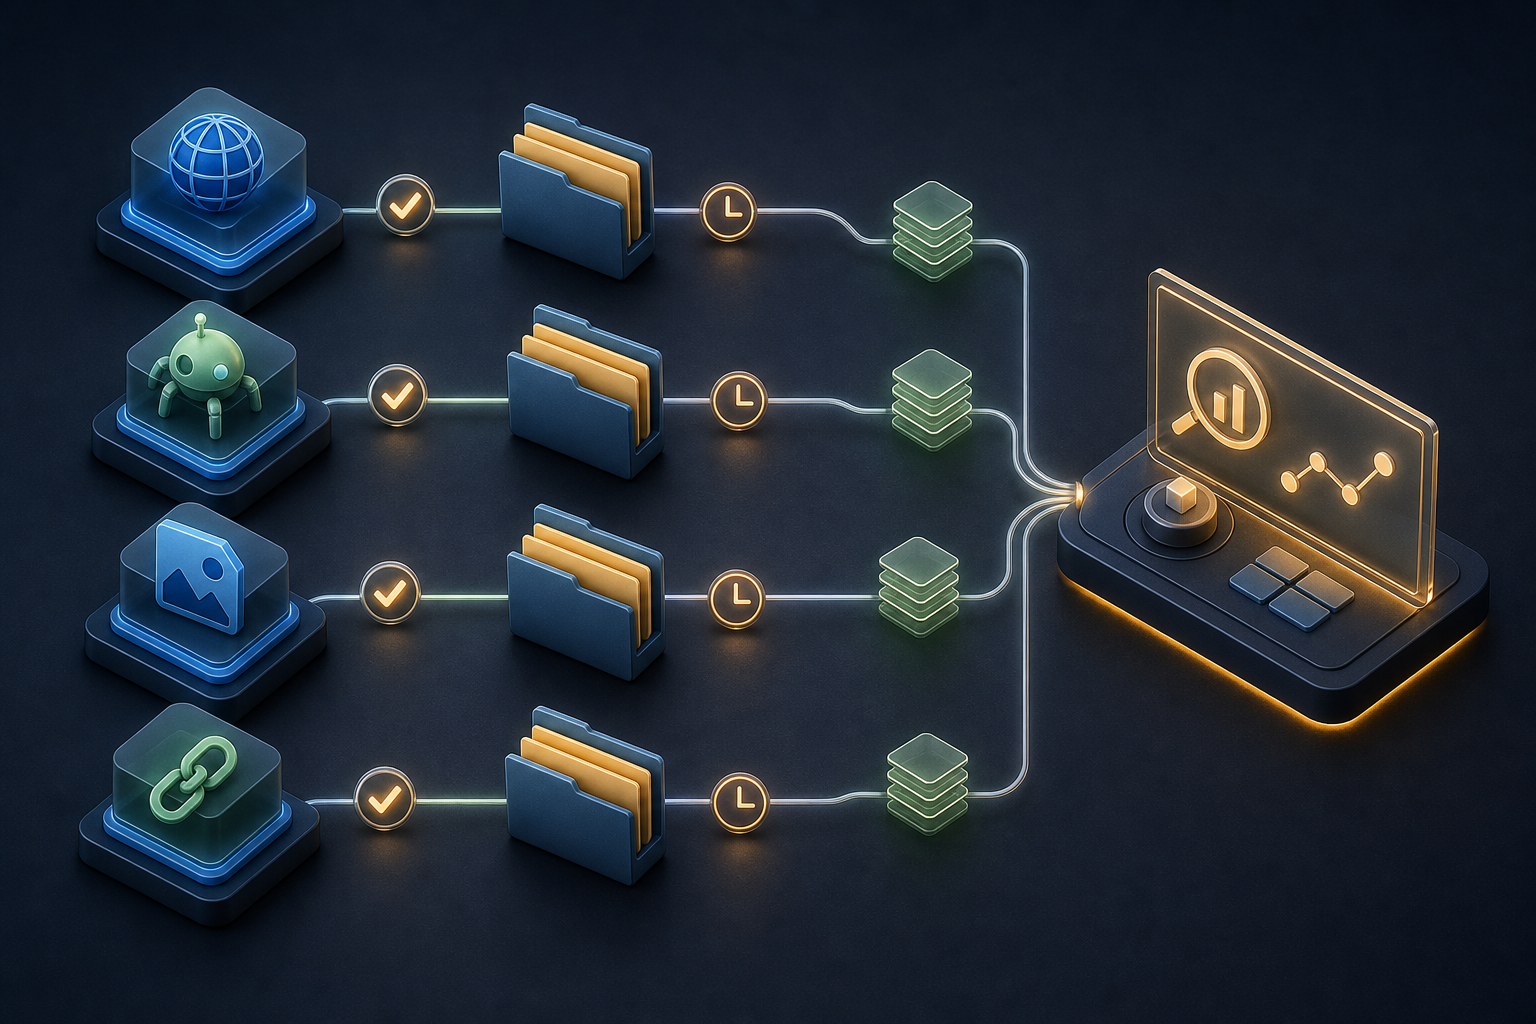
    Four abstract data sources connect to a compact set of organized file folders and a central analysis workspace.

    You do not need a data warehouse to begin. A practical local project can separate configuration, fetchers, platform data, and generated reports. That separation makes failures easier to diagnose and prevents an AI-generated conclusion from being mistaken for raw platform data.

    Project areaWhat belongs thereOperating rule
    ConfigurationClient details and the property or account identifiers needed by each fetcherKeep secrets out of this file; configuration and credentials are different things
    FetchersOne Python script for each platform, such as Search Console, GA4, Google Ads, or AI visibilityEach script should collect data and save it without making strategic recommendations
    DataRaw or normalized JSON files, separated by platform and refreshDo not overwrite the evidence used for a previous decision
    ReportsAnalysis tables, exceptions, recommendations, and review notesEverything here is derived and should be reproducible from the data files

    The collection layer should be deterministic. Given the same credentials, request, and date range, a fetcher should retrieve and store the same type of data. The AI belongs above that layer, where language and reasoning are useful. This distinction prevents a vague instruction from changing both the data collection method and the interpretation at the same time.

    Set up the project in this order:

    1. Create one project directory per client or site. Separate directories reduce the chance of mixing property identifiers, files, or recommendations.
    2. Configure authentication. A Google Cloud service account can support Search Console and GA4 access, while Google Ads requires its own OAuth setup. Grant only the access the workflow needs.
    3. Specify each fetcher in plain language. Name the platform, property, date range, dimensions, metrics, output location, and required error behavior. An AI coding assistant can draft the Python, but you still need to inspect and test it.
    4. Save platform data separately. Search Console query and page performance, GA4 traffic data, Google Ads search terms, and AI citation data should remain distinguishable even when a later analysis combines them.
    5. Add a refresh manifest. Record when each file was created, the period it covers, the account or property it belongs to, and whether collection completed successfully.
    6. Test with a narrow request. Pull a small, known date range first. Compare several returned rows with the platform interface before trusting a larger refresh.

    Keep credentials outside the project data and out of version control. If a credential is exposed, revoke or rotate it rather than assuming deletion from a file has removed the risk. Read-only access is the safer default for an analysis workflow; campaign edits and site changes should remain separate, deliberate operations.

    One agency workflow reports roughly an hour for the foundational setup, about 35 minutes to configure a new client, and about 20 minutes for a monthly refresh. Treat those figures as observations from one implementation, not universal benchmarks. Your first setup will depend on authentication, account complexity, field requirements, and how much validation you build in. The useful promise is repeatability, not a particular stopwatch result.

    Use prompts that produce evidence, not commentary

    Once the files exist, resist the easy prompt: analyze my SEO data. It gives the model too much freedom to decide what matters, how platforms should be joined, and which gaps can be ignored. A production prompt should define the question, permitted files, join logic, output structure, and stopping conditions.

    Separate validation from interpretation

    Run a validation prompt before asking for strategy. Tell the assistant to inventory the files, report their date ranges, identify missing or empty datasets, check whether property identifiers agree with the configuration, and list fields that are unavailable. It should stop if a required input is absent.

    Only then run the decision prompt. This two-pass pattern matters because an articulate model can produce a plausible recommendation from incomplete data. A visible failure is safer than a polished answer built on a missing Ads export or the wrong Search Console property.

    Give the assistant a reusable analysis template

    A practical prompt can follow this structure:

    • Role: Act as an analyst. Do not alter files, accounts, campaigns, or site content.
    • Question: State the single business or SEO decision the analysis must support.
    • Inputs: List the exact directories and files the assistant may use.
    • Checks: Confirm account identifiers, date coverage, required fields, and successful refresh status before analysis.
    • Method: Describe the allowed joins and calculations. Require exact matches to remain separate from inferred or semantic matches.
    • Output: Return a candidate table, an exception table, and a short decision note. Every row should identify its supporting files and metrics.
    • Uncertainty: Mark conclusions as observed, calculated, inferred, or recommended. If the files cannot answer something, say that directly.

    For paid-organic overlap, ask for search terms with spend and conversion context, their matched organic queries, the relevant organic pages, the match type used by the analysis, and the reason each term deserves review. Require unmatched terms and ambiguous mappings in a separate exception table. That exception table often matters more than the recommendation list because it shows where automation is least trustworthy.

    For content analysis, change the unit of analysis from search term to page. Ask the assistant to map Search Console query and page performance to the corresponding GA4 page data, report any path-normalization assumptions, and keep platform metrics under their original names. Do not let it merge differently defined metrics into a synthetic score unless you supplied and approved the formula.

    For AI search visibility, citation data exported from tools such as Scrunch or Semrush can be added as CSV or JSON. Keep that dataset in its own directory and label its collection method. A citation or mention is not automatically equivalent to an organic click, a GA4 session, or a conversion. Use the combined view to investigate relationships, not to pretend the platforms measure the same event.

    Install a review gate before any SEO action
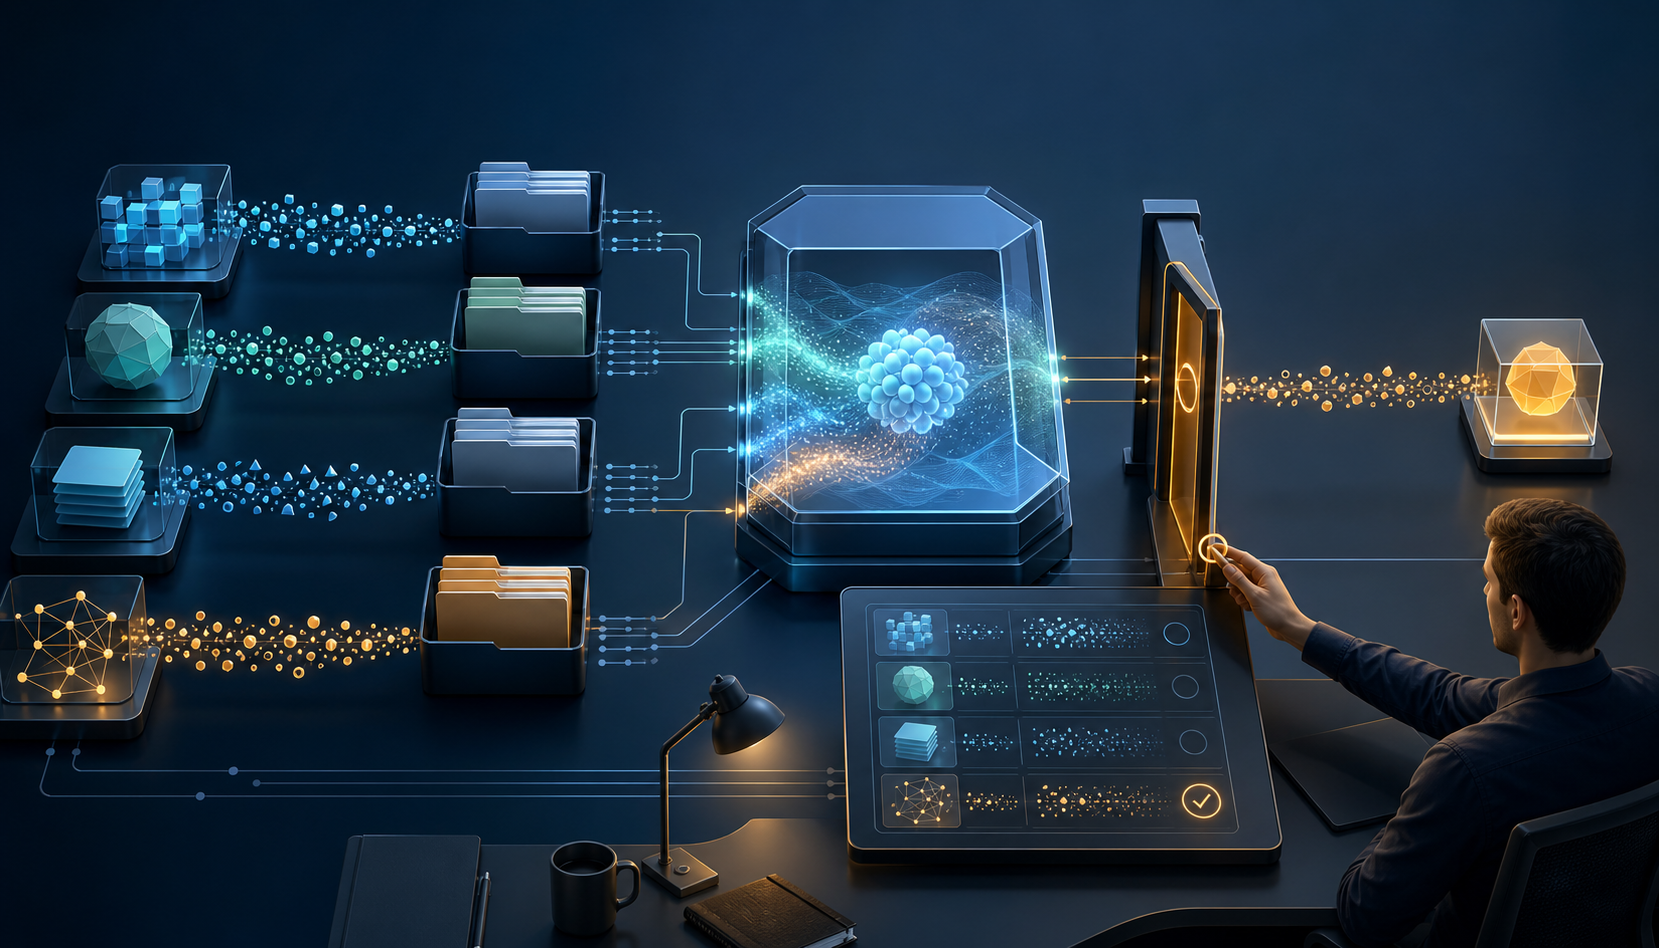
    An analyst inspects abstract evidence tiles at a closed gate before approving workflow actions.

    Traceability is what turns an interesting AI answer into an operational workflow. A recommendation should survive a simple challenge: can another person find the supporting rows, repeat the calculation, and explain why the proposed action follows?

    Use this review gate before changing bids, briefs, internal links, structured data, or published content:

    1. Verify identity and time. Confirm that every dataset belongs to the intended property or account and covers the expected period.
    2. Inspect collection exceptions. Empty files, partial refreshes, changed field names, and authentication failures must be resolved or carried into the analysis as explicit limitations.
    3. Recalculate a sample. Manually reproduce several important joins or calculations from the underlying rows. Include at least one recommendation and one excluded case.
    4. Challenge the matching logic. Exact query matches are not automatically equivalent when intent, geography, device context, landing pages, or brand strategy differ. Semantic matches require even more scrutiny.
    5. Separate fact from judgment. A metric is observed, a ratio may be calculated, a relationship may be inferred, and an action is recommended. The report should not blur those categories.
    6. Check the downside. Reducing paid coverage can affect visibility, testing capacity, or strategically important terms. Editing content or structured data can create indexing or accuracy problems. Use a reversible test when the consequence is uncertain.
    7. Record the decision. Save what was approved, rejected, or deferred, who reviewed it, and which input refresh supported it. The next cycle needs this context.

    Do not ask the model whether its own answer is correct and treat the response as validation. Give it a separate adversarial task: find rows that contradict the recommendation, identify alternative explanations, and list the additional data that would change the conclusion. Then inspect the evidence yourself.

    This is the right mental model: the assistant is a fast analyst working from bounded files, not the owner of SEO strategy. AI can accelerate extraction and cross-platform analysis, but strategic judgment and verification still belong to the human reviewer. Review its work with the same care you would apply to output from a new team member who is capable but unfamiliar with the account.

    Key takeaways for a repeatable operating loop

    • Automate collection before interpretation. Scripts should retrieve and store defined data; the AI should reason over those files without silently changing how they were produced.
    • Start with one decision. A recurring question such as paid-organic overlap gives the workflow a clear input contract, output, and review standard.
    • Preserve the evidence chain. Keep raw platform data separate from derived reports, timestamp each refresh, and require file and row references for recommendations.
    • Make uncertainty visible. Exact matches, semantic matches, missing data, assumptions, observations, and recommendations should never appear as one undifferentiated answer.
    • Keep consequential actions human-approved. Use read-only access for analysis and move campaign or site changes into a separate, reversible approval process.
    • Save decisions, not just reports. The monthly loop should retain what changed, why it changed, and what the next refresh must measure.

    Pick the SEO decision that consumed the most manual reconciliation in your last reporting cycle. Write its analysis contract, connect only the datasets required to answer it, and test the workflow on a narrow date range. Once the evidence survives review, schedule the refresh. Add the next use case only after the first one reliably changes a real decision.
    References

  • Google Crawl Frequency: What It Says About Site Health

    Google Crawl Frequency: What It Says About Site Health

    When Google starts crawling your site more often, it is tempting to treat the increase as an SEO win. When activity falls, it is just as tempting to assume that something is broken. Neither conclusion is safe on its own.

    Crawl frequency is most useful as a diagnostic clue. It can show you where Google sees freshness, relevance, or demand, but it cannot tell you by itself whether a page is indexed, ranks well, or deserves more search visibility. Your job is not to maximize crawling. It is to make sure Google can efficiently revisit the pages that need to stay current.

    Frequent crawling is a positive signal, not an SEO score

    Google tends to crawl pages frequently when its systems recognize fresh or highly relevant information that people want to find. Repeat visits let the search engine detect changes and keep its understanding of those pages current.

    Ecommerce makes the mechanism easy to see. Prices, promotions, and inventory can change quickly, so current search results depend on Google revisiting product and category pages. A crawl increase across an active commercial catalog can therefore be entirely healthy.

    The mistake is turning that positive signal into a universal performance metric. Four separate events matter:

    • Discovery: Google becomes aware that a URL exists.
    • Crawling: a crawler requests the URL and attempts to retrieve its content and required resources.
    • Indexing: Google processes the retrieved content and decides whether and how it may be stored in the search index.
    • Search selection: Google decides whether the indexed page is useful for a particular query and where it should appear.

    More crawling confirms activity at the second stage. It does not prove that indexing or ranking improved. A frequently fetched page can still be unhelpful, duplicative, outdated, or ineligible for indexing. Conversely, a stable page may remain valuable without needing constant repeat visits.

    Be especially careful with the reverse inference. If frequent crawling is a good sign, it does not follow that less frequent crawling is automatically a bad sign. Google optimizes crawling automatically, so there is no single healthy request rate that every site or page should reach. The useful question is whether the frequency fits the purpose and rate of change of the pages involved.

    Judge crawl patterns by page type and update need

    A sitewide crawl total hides the distinctions that matter. Separate your pages into functional groups before deciding that a change requires action.

    Page groupHow to interpret crawl activityWhat to check
    Prices, products, promotions, and inventoryFrequent repeat crawling can match the need for current commercial information.Confirm that the fetched page exposes the current public data and that access controls do not block required content.
    Recently revised editorial or reference pagesA repeat crawl is the step that lets Google encounter the revision, but it does not guarantee reindexing or better rankings.Sample important changed URLs and verify that Google can retrieve the new version.
    Stable company, policy, or evergreen pagesLower activity may simply reflect a lower need for freshness.Keep the information accurate, but do not make cosmetic edits merely to provoke crawler visits.
    Member-only, subscription, or paywalled pagesLimited access may be intentional rather than a technical failure.Confirm that the public and restricted portions match your publishing policy and the access you have chosen to permit.

    Segment the evidence again by directory, template, hostname, and crawler identity. Google uses multiple crawlers with different jobs. Combining every request into one total can make a change in one part of the site look like a sitewide health event.

    Compare your site with itself, not with an unrelated domain. A retailer with changing stock naturally creates a different freshness need from a small site whose core information rarely changes. Even within one domain, product availability and an evergreen company history page should not share the same crawl expectation.

    Diagnose a crawl decline in the right order

    An isometric website system shows a crawler route passing from a server through linked pages toward blocked, broken, looping, and duplicate paths.

    A meaningful decline is one that affects pages Google needs to revisit, especially after those pages have changed. Diagnose it from the narrowest evidence outward:

    1. Verify the comparison. Make sure you are looking at the same hostname, page group, crawler, and measurement window. A reporting change or a shift between crawlers can resemble a loss of activity.
    2. Find the boundary. Determine whether the decline affects the whole site, one directory, one template, or only a small group of URLs. A clean boundary often points toward the release, configuration, or publishing workflow that changed.
    3. Match the timing to site changes. Review deployments, migrations, authentication changes, robots.txt edits, page-level crawler instructions, paywall changes, and rendering changes. Modern pages are more complex to retrieve, so a template change can alter what a crawler can access even when the visible design looks correct.
    4. Inspect representative fetches. Check important URLs from each affected group. Confirm that the request succeeds, the intended content is present, and essential resources are available. Do not rely only on a sitewide graph.
    5. Review crawler instructions deliberately. Google normally respects robots.txt and other crawling instructions. An accidental restriction can therefore produce exactly the decline you asked the crawler to create, even if that was not the business intention.
    6. Trace how changed pages are rediscovered. Important URLs should remain reachable through ordinary internal navigation. If you maintain discovery files such as an XML sitemap, make sure they represent the public URLs you actually want Google to revisit.
    7. Separate access from demand. If Google can fetch the pages, the content has not materially changed, and the audience need is stable, lower activity may be rational. Record it as a baseline instead of manufacturing updates to chase a larger number.

    Do not respond to a decline by exposing private material or removing restrictions indiscriminately. Google does not access paywalled or subscription content without the site owner’s permission. Decide what should be public first, then configure access to express that decision. Crawl volume is not worth compromising a membership model or publishing rights.

    Build a site-health view that leads to action

    An analyst traces an amber warning from an abstract site-health monitoring wall to a highlighted page node.

    Crawl frequency becomes useful when you place it inside a small operational scorecard. Review these dimensions together whenever a technical release, content migration, or major publishing change affects important pages:

    • Access: Can Google retrieve priority URLs and the content required to understand them?
    • Purpose: Is repeat activity concentrated on useful, public pages rather than unwanted URL variations or redundant versions?
    • Freshness: When an important fact changes, can a later fetch retrieve the new value?
    • Control: Do robots.txt, page-level instructions, authentication, and paywall rules match the publishing decision behind each section?
    • Outcome: Are discovery, crawling, indexing, and search performance being measured separately instead of being collapsed into one health label?

    This framework also prevents a common mistake in structured-data and AI-search work. JSON-LD can clarify the meaning of information that a crawler retrieves, but markup cannot compensate for blocked or unavailable content. Verify access and content delivery before treating schema changes as the answer to a crawl problem.

    You also retain meaningful control over what Google is allowed to crawl and how it receives instructions. Treat each exclusion as a publishing rule with an owner and a reason. Broad rules left behind after a migration are much harder to diagnose than restrictions whose intent is documented.

    The healthiest goal is purposeful crawling: current, relevant pages are available when Google needs them; stable pages remain accurate without artificial churn; and restricted content stays restricted by design.

    Key takeaways

    • Frequent crawling generally indicates that Google recognizes freshness, relevance, or user demand, but it is not a ranking score.
    • A crawl is not the same as discovery, indexing, or ranking. Measure those stages separately.
    • There is no universal healthy crawl frequency. Compare activity with the page’s purpose and actual rate of change.
    • Investigate declines by page group, template, hostname, and crawler before treating them as a sitewide problem.
    • Check access controls and the fetched content before trying to stimulate more requests.
    • Do not manufacture superficial updates, expose private content, or remove deliberate restrictions merely to increase crawl volume.

    For your next crawl review, compare fast-changing pages, recently revised pages, stable pages, and intentionally restricted pages separately. Fix any gap between publishing intent and crawler access. If the remaining pattern matches how often the information changes, keep it as your baseline and monitor the outcomes that come after crawling.

    References

  • WebMCP for Browser-Based AI Agents: A Practical Readiness Guide

    WebMCP for Browser-Based AI Agents: A Practical Readiness Guide

    Your website can be perfectly clear to a person and still force an AI agent to guess. The agent has to locate the right control, infer what each field means, enter values in the expected format, and decide whether a changed screen means the task succeeded.

    If you manage an ecommerce store, booking flow, lead-generation site, or publishing platform, the practical question is not whether every page needs an agent interface. It is which valuable task should get a reliable, machine-readable contract first. WebMCP gives you a way to start answering that question.

    WebMCP changes the interface from controls to callable tools

    Web Model Context Protocol, or WebMCP, is an emerging approach for exposing website actions to browser-based AI agents. Instead of making an agent reconstruct a workflow from buttons and fields, a page can present discoverable tools through JavaScript APIs or annotated HTML forms. Those tools can define their inputs and outputs with JSON schemas and change their availability as the page state changes. That is the central idea behind the early WebMCP preview in Chrome 146.

    Think of the difference as intent versus appearance. A person can look at a blue button labeled Search Flights and understand what to do. An agent works more reliably when it can discover a searchFlights or bookFlight action, inspect the required date, origin, destination, and passenger parameters, call the tool, and receive a structured result.

    Interaction routeWhat the agent must doMain limitation
    UI automationInspect the rendered page, identify controls, enter values, and interpret visual changesText, layout, and component changes can break the agent’s assumptions
    Conventional APICall an endpoint using a separately documented contractAn API may not exist, may not be available to the agent, or may not reflect the current page context
    WebMCPDiscover tools exposed by the current page, supply schema-defined inputs, and consume a structured resultThe Chrome implementation described so far is an early preview, not a mature cross-browser deployment guarantee

    WebMCP does not make your human interface unnecessary. People still need an understandable, accessible flow, and agents may still fall back to that flow when no compatible tool is available. It also does not remove the need for an API when partners, mobile applications, or backend systems require one.

    For SEO, AEO, and GEO teams, the most important distinction is between discovery, understanding, and action. Search-friendly content helps a system find the page. Structured content and JSON-LD help clarify what the page, entity, product, or offer represents. WebMCP addresses what an agent can do once it reaches the relevant browser context. A tool declaration does not make a brand rank, earn a citation, or become the agent’s preferred choice. Treat it as actionability infrastructure, not as an assumed ranking factor.

    Choose one bounded task before exposing an entire journey

    A site-wide WebMCP project is usually the wrong starting unit. Begin with one task whose successful outcome is easy to recognize. Product search, inventory checking, quote requests, registration, and booking are stronger candidates than a vague action such as helpMe or handleMyAccount.

    Use this filter when selecting the first task:

    • The user outcome can be stated in one sentence. Check whether a particular item is available is clearer than assist with shopping.
    • The required inputs can be named and validated. A quote request might require a product, quantity, contact method, and organization identity rather than an unrestricted message.
    • The result can be returned as data. Availability status, a quote-request identifier, or a list of matching products is easier for an agent to use than a visual success banner.
    • The preconditions are knowable. You can state whether the action requires authentication, a non-empty cart, a selected product, or a particular page state.
    • The side effect is limited or confirmable. Read-only inventory lookup is a safer first implementation than charging a card, issuing a ticket, or publishing content.
    • A human fallback exists. If the tool cannot complete the task, the user should be able to continue in the normal interface without reconstructing the entire journey.

    Write a plain-language planning card before writing code. For a B2B quote flow, it could contain the tool name requestQuote, the exact business outcome, required and optional inputs, the returned request status, the conditions under which the tool is available, the permissions it needs, and the point at which the user must confirm submission. This exposes ambiguity while it is still cheap to correct.

    Map one existing human journey against that card. If the page asks for information that is absent from the proposed input schema, either add it to the contract or establish that the server can derive it safely. If the proposed tool requests data that the human journey does not need, challenge the requirement. An agent-facing path should not become an excuse to collect more information.

    Design a tool contract an agent can call without guessing

    An isometric tool module receives structured inputs, validates them, and produces one confirmed output while unrelated interface elements remain disconnected.

    A tool is only as reliable as the decisions its contract removes. Discovery tells the agent that an action exists. The schema tells it how to call the action. The structured result tells it what happened. State determines whether calling it now makes sense.

    Make discovery names describe outcomes

    Name the task after the result, not the page element. searchProducts, checkInventory, requestQuote, and bookFlight communicate intent. clickPrimaryButton, submitForm, and runAction merely expose implementation details. A redesign can replace a button or form while the user outcome stays the same.

    The description should also establish scope. If checkInventory covers one location and one product variant, say so. If searchProducts returns candidates but does not reserve stock, make that boundary explicit. Two tools with overlapping names and unclear scopes force the agent back into interpretation.

    Use schemas to eliminate format decisions

    The WebMCP model uses JSON schemas to define expected inputs and outputs. Use that structure to settle details that a visual form often leaves implicit:

    • Identify which fields are required and which are optional.
    • Use precise data types rather than asking the agent to encode everything as free text.
    • Define accepted formats for dates, locations, identifiers, quantities, and other constrained values.
    • Use enumerated choices when the system accepts a closed set of options.
    • Make defaults explicit. Do not rely on a checked box, placeholder, or hidden field that only exists in the rendered interface.
    • Describe outputs well enough for the agent to determine whether the goal was completed, partially completed, or rejected.

    A flight action illustrates the problem. Date, origin, destination, and passenger count are obvious inputs, but an agent should not have to infer whether an ambiguous numeric date uses month-first or day-first order. It should not have to guess whether the location field expects a city, airport, or internal identifier. The schema should make those choices visible before the call.

    Separate exploration from commitment when the consequences differ. Searching for flights and purchasing one are not the same action. Searching can return options. Booking can reference a selected option, display the final itinerary and price, obtain confirmation, and then commit. A single broad tool that silently crosses both stages is difficult to control and difficult to audit.

    Expose tools only when the current state supports them

    WebMCP’s state-aware model lets tool availability change with context. Use that capability deliberately. Checkout should not appear when the cart is empty. Publish should not appear when there is no valid draft or the current user lacks the required permission. A booking action should not appear before an option has been selected.

    This is more than interface tidiness. Every unavailable action shown to an agent creates another path it can choose incorrectly. Prefer a small set of valid actions for the current state over a large catalog that returns preventable errors. Keep server-side validation in place even when discovery is state-aware; page state can change between discovery and execution.

    Put permissions, confirmation, and failure handling in the design

    A geometric AI agent's task passes through a permission gate and human confirmation checkpoint before reaching success or recoverable failure paths.

    Agent-callable does not mean agent-authorized. WebMCP can describe an interaction, but the website still owns authentication, authorization, validation, and the consequences of the action. Do not treat tool metadata as a substitute for those controls.

    Classify each tool by effect before deciding how it can run:

    • Read-only actions retrieve information without changing user or business data. Product search and inventory checks are useful first candidates.
    • Reversible or draft actions prepare work without finalizing it. Filling a quote draft or assembling a checkout summary can reduce effort while keeping the user in control.
    • Consequential actions create cost, external communication, publication, reservations, or another durable change. Purchasing a ticket, submitting an order, or publishing content should require an explicit confirmation step that presents the material terms before execution.

    For a consequential action, confirmation should describe what will happen, not merely ask the user to continue. Show the item or service, selected options, final amount when money is involved, destination or recipient, and whether the action can be reversed. If any material value changes after confirmation, stop and obtain a new confirmation. The downside of getting this wrong is a real charge, booking, message, or publication that the user did not approve.

    Design structured failures as carefully as successful results. At minimum, the calling agent needs to know which field or precondition failed, whether retrying is safe, whether the current state has changed, and what valid next step is available. Invalid input, expired state, missing permission, unavailable inventory, and an internal failure should not collapse into one generic message.

    Repeated calls deserve special attention. A timeout can leave the agent unsure whether a write succeeded. If retrying could create a second order, booking, quote request, or publication, make duplicate prevention part of the underlying transaction design. Return enough structured status for the agent to reconcile the original attempt instead of blindly submitting again.

    Keep an audit trail that helps you investigate outcomes without recording unnecessary sensitive values. Useful events include the tool discovered, tool invoked, authorization result, validation result, confirmation state, completion status, and fallback route. Your analytics should distinguish an agent that could not find the right tool from one that found it but supplied invalid inputs.

    Test Chrome’s preview as a learning environment

    The Chrome 146 implementation was presented as an early testing preview behind a feature flag. For that preview, the documented setup required Chrome version 146.0.7672.0 or later and the WebMCP testing flag. That makes it useful for prototyping, but it does not justify assuming stable syntax, broad browser support, or production compatibility.

    To recreate that preview environment:

    1. Use the Chrome version specified for the preview: 146.0.7672.0 or later.
    2. Open chrome://flags/#enable-webmcp-testing.
    3. Set WebMCP for testing to Enabled.
    4. Relaunch Chrome.
    5. Use the optional Model Context Tool Inspector Extension to inspect which tools the page exposes and how their contracts appear.

    Do not stop when the inspector can see a tool. Run a small test matrix against the outcome:

    • Discovery: Can the agent identify the correct tool from its name, description, and current state?
    • Valid execution: Does a complete, schema-valid request produce the expected structured result?
    • Invalid input: Does each missing, malformed, or unsupported value produce a useful field-level response?
    • State transition: Do tools appear and disappear when the cart, selection, login state, or draft state changes?
    • Permission boundary: Can an unauthorized user discover or execute an action that should be restricted?
    • Confirmation: Does a consequential action stop before commitment and present the right details?
    • Replay: Can a retry accidentally create a duplicate side effect?
    • UI change: Does the tool continue to work when labels or layout change but the underlying business task remains the same?
    • Fallback: Can the user continue through the normal interface when the agent-facing action fails?

    Record pass or fail by stage rather than using one overall completion number. Separate discovery failures, schema-validation failures, permission denials, user-declined confirmations, server errors, duplicate-prevention events, successful completions, and human fallbacks. That breakdown tells you whether to rewrite the tool description, change the schema, fix state exposure, or repair the underlying transaction.

    Key takeaways

    • WebMCP gives a browser-based agent an explicit tool contract instead of requiring it to infer every action from the visible interface.
    • Start with one bounded, measurable task whose inputs, result, state, and side effects can be described clearly.
    • Use action-oriented names, strict schemas, structured results, and state-aware availability to remove guesswork.
    • Keep authentication and server-side validation in place, and require meaningful confirmation before payments, bookings, publication, or other consequential actions.
    • Treat the Chrome 146 implementation as a testing preview, not proof of stable or universal browser support.
    • Keep investing in content, technical SEO, and structured data. WebMCP adds actionability; it does not guarantee discovery, citation, selection, or ranking.

    Your next move is small: choose one read-only or low-risk task, write its tool contract on a single page, and test discovery, valid input, invalid input, state change, and fallback in the preview environment. Even if the emerging interface changes, the work of defining the task, permissions, schemas, side effects, and success criteria will remain useful.

    References

  • Boost AI Search Visibility with Effective Schema Markup

    Boost AI Search Visibility with Effective Schema Markup

    As someone keen on improving AI search visibility, I’ve delved into the world of schema markup. Let me share what I’ve learned about essential schema types, practical implementation tips, and how structured data enhances the understanding of content by Large Language Models (LLMs).

    By incorporating schema markup, I’ve noticed significant improvements in how AI and search engines interpret my content. This not only boosts my content’s visibility but also ensures it reaches the right audience effectively.

    The right schema types serve as a bridge, enabling AI systems to decipher and present content accurately. In my experience, selecting the appropriate schema type is crucial for optimizing how LLMs process information.

    Moreover, implementing schema markup isn’t as daunting as it seems. With some practice, I’ve found that the structured data seamlessly fits into my workflow, enhancing the overall search optimization process.


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot
  • AI Recommendation Pipeline Optimization, Gate by Gate

    AI Recommendation Pipeline Optimization, Gate by Gate

    Your page can rank, load correctly, and carry structured data yet still disappear when an AI system recommends a product, provider, or approach. Publishing more content will not fix that if the real failure happened earlier in the recommendation pipeline.

    You need to find the earliest gate your content cannot reliably pass. Fix that dependency first, then work forward until the system can retrieve, understand, trust, present, and ultimately prefer your answer.

    Think in gates, not one AI visibility score

    A practical AI recommendation pipeline contains 10 dependent gates: Discovered, Selected, Crawled, Rendered, Indexed, Annotated, Recruited, Grounded, Displayed, and Won. This is an operational model for diagnosis, not a claim that every AI engine exposes the same internal architecture.

    The distinction matters because a weak result does not identify its own cause. If your brand is absent from an answer, the underlying problem could be access, interpretation, credibility, relevance, or competitive fit. Treating every absence as a content-writing problem produces activity without revealing the bottleneck.

    The first five gates determine whether your material becomes technically eligible for use. The final five determine whether the system can understand and use it, verify it, show it, and choose it over alternatives. A hard failure upstream dominates everything downstream. A page that is not fetched cannot be rescued by better prose, and a page that is misunderstood cannot be rescued by stronger claims.

    Before you audit anything, define the recommendation you are trying to earn:

    • Decision: the question or task for which you want to be recommended.
    • Entity: the brand, product, service, location, person, or resource the system must recognize.
    • Canonical evidence page: the primary URL that explains why the entity fits the decision.
    • Qualifying facts: the attributes, limitations, audience, and use cases that make the recommendation accurate.
    • Desired outcome: an accurate citation, inclusion in a shortlist, a preferred recommendation, or another observable result.

    Do not audit an entire domain as one unit. A site can pass the pipeline for one entity and fail it for another. Your product page might be understood correctly while a location, plan, feature, or professional service remains invisible or ambiguously classified.

    Key takeaways

    • Find the earliest plausible failure instead of averaging every signal into one visibility score.
    • Separate technical eligibility from the later contest for recruitment, grounding, display, and preference.
    • Use observable evidence as a proxy. You usually cannot inspect an AI system’s internal gate state directly.
    • Treat visible copy, structured data, feeds, and supporting pages as representations of the same entity, not separate stories.
    • Keep post-decision reality aligned with the promise that earned the recommendation.

    Earn eligibility from discovery through indexing

    Exploration probes find a glowing content object that passes through a selective opening into an organized digital archive.

    Discovery, selection, crawling, rendering, and indexing form a dependency chain. Work through it in order. Checking only whether a URL loads in your own browser skips several different failure modes.

    Discovered: create legitimate paths to the entity

    Discovery asks whether a system can become aware that the entity and its supporting content exist. Start with the canonical page and trace every route that can expose it.

    • Link the page from a relevant navigation path, category page, hub, or related resource. Do not leave important evidence isolated behind a site search form.
    • Use descriptive internal links that identify the destination’s subject. Generic labels make the relationship less explicit.
    • Keep the canonical URL stable. If the same entity is scattered across temporary or duplicative URLs, choose a primary destination and make the hierarchy clear.
    • Inventory feeds, APIs, directories, and other structured distribution routes that legitimately carry the entity’s data.
    • Check whether site-level bot controls, security layers, or access policies unintentionally prevent discovery.

    Some platforms accept structured feeds or direct data pushes. Where those routes are available, they can bypass parts of the traditional discovery path. Use them as maintained representations of the same facts found on your site. A fast data route filled with stale names, prices, locations, or availability merely distributes the contradiction faster.

    Selected: make the page worth investigating

    Discovery creates awareness; selection determines whether the system has a reason to inspect the material. Open the page and look only at its title, opening paragraphs, headings, and internal-link context. Those elements should make the entity and its purpose unambiguous.

    • Name the entity and its category instead of relying on a slogan.
    • State the audience or situation the page serves.
    • Align the page with a specific decision rather than collecting loosely related keywords.
    • Separate genuinely different intents when combining them would make the primary answer unclear.
    • Resolve competing pages that make substantially different claims about the same entity.

    A page titled around broad thought leadership may be useful to a reader but still give a recommendation system no clear reason to retrieve it for a purchase, comparison, eligibility, or implementation question. Give each important page a recognizable job.

    Crawled, rendered, and indexed: verify access and interpretation separately

    A successful visit in your normal browser does not prove that an automated system received the same useful material. Test the page without a signed-in session, inspect available server or delivery logs, and separate these questions:

    • Crawled: Can an automated requester fetch the document without authentication, an unresolved challenge, or an interaction that never occurs?
    • Rendered: Does the resulting document contain the entity name, answer, qualifiers, and evidence as readable text?
    • Indexed: Is the page distinct, stable, and useful enough to be retained as a retrievable representation of the entity?

    Keep recommendation-critical facts out of image-only layouts, hover states, closed interface elements, and experiences that require a user action before any meaningful text appears. Interactive tools can remain valuable, but their core purpose, inputs, output meaning, and limitations should also be explained in text.

    Indexing is not something you can prove merely by finding a URL in one search interface. Use multiple proxies: a stable canonical destination, unique content, consistent internal references, successful fetch evidence where available, and downstream appearances that could not happen without retrieval. Record uncertainty instead of marking the gate as passed on weak evidence.

    Make the content usable for annotation, recruitment, and grounding

    Unlabeled modular content panels connect through semantic markers and evidence fragments to a transparent frame surrounding a glowing answer core.

    Passing the access gates only makes your content eligible. The next job is to remove ambiguity, package useful answers, and support the claims an AI system would have to repeat.

    Annotated: define the entity before decorating it with schema

    Annotation is where content is classified by meaning. Before editing JSON-LD, write an internal entity fact sheet that answers:

    • What is the entity’s exact name?
    • What type or category does it belong to?
    • What does it do, provide, or represent?
    • Who is it intended for, and who is it not intended for?
    • Which use cases does it support?
    • Which limitations, eligibility rules, locations, or availability conditions qualify the claims?
    • How does it relate to the parent brand, other offerings, locations, versions, or people?

    Then compare that sheet with visible copy, structured data, feeds, navigation labels, supporting pages, and external profiles you control. The facts do not need identical wording, but they should not describe different entities.

    Schema can clarify a page’s meaning. It cannot repair a missing explanation or safely substitute a stronger claim for the one a visitor can see. Treat JSON-LD as a structured representation of the visible entity. If a material attribute appears only in markup, either support it clearly on the page or remove it.

    Recruited: build answer units that remain clear when extracted

    Recruitment asks whether the system can use the content for the decision at hand. Long-form depth helps only when the relevant answer can be located and understood without reconstructing it from scattered sections.

    For every important question, create a self-contained answer unit with this sequence:

    <!– wp:list {
  • Meta Attribution Updates: A Practical Guide for Advertisers

    Meta Attribution Updates: A Practical Guide for Advertisers

    If Meta Ads Manager starts showing a different mix of attributed conversions, do not let the first reporting change trigger an automatic budget change. Your ads may not have become better or worse. Meta has changed how it classifies the interactions that happen before a conversion.

    You now need to separate conversions connected to an actual link click from conversions preceded by a like, share, save, or qualifying video engagement. That distinction can improve your analysis, but only if you reset your baseline and stop treating every attributed conversion as the same kind of evidence.

    Meta now draws a harder line between traffic and engagement

    For campaigns focused on website or in-store conversions, only link clicks will contribute to click-through attribution. Likes, shares, saves, and other non-link interactions will no longer be counted as click-through activity. Conversions associated with those interactions move into engage-through attribution.

    Reporting elementPrevious treatmentNew treatmentHow to interpret it
    Link click before conversionIncluded in click-through attributionRemains in click-through attributionThe person used the ad’s link before converting
    Like, share, save, or another non-link interactionCould contribute to the broader click-through classificationMoves to engage-through attributionThe person interacted with the ad but did not necessarily visit through its link
    Engagement-based namingEngaged-view attributionEngage-through attributionThe label now covers a broader range of social interactions
    Video engaged-view qualification10 seconds5 secondsShorter video engagement can qualify for the engagement-based category

    This is more than a terminology cleanup. A link click is evidence of navigation. A like or save is evidence of engagement. Both can matter, but they answer different questions. Keeping them in separate reporting categories prevents a social interaction from looking like a website visit.

    The shorter video qualification reflects how quickly people can respond to short-form creative. Meta reports that 46% of Reels purchase conversions happen within the first two seconds. Treat that as evidence that meaningful exposure can happen quickly, not as proof that every brief view caused the eventual purchase.

    The reporting definitions are changing, but Meta says billing methods remain unchanged. That matters when you investigate an apparent performance shift: first establish whether spend, sales, and cost actually changed, or whether the same outcomes were redistributed between attribution categories.

    Key takeaways

    • Click-through attribution now requires a link click for website and in-store conversion campaigns.
    • Likes, shares, saves, and other qualifying non-link interactions belong under engage-through attribution.
    • Engage-through replaces the older engaged-view label and gives social interactions a distinct reporting role.
    • The video engaged-view qualification moves from 10 seconds to 5 seconds.
    • Historical and current reports may not be directly comparable, so establish a new baseline before changing budgets.
    • Cleaner click-through reporting can reduce one source of disagreement with Google Analytics, but it will not make the two platforms identical.

    Reset your baseline before changing campaign spend

    An analyst aligns two measurement rails at a shared starting point while budget tokens remain set aside on the desk.

    An attribution definition change creates a break in your reporting history. If you compare a period using the old classification with one using the new classification, part of the apparent movement may come from relabeling rather than customer behavior.

    Build a clean handoff around the date the new definitions become visible in your account:

    1. Record the transition date. Note when click-through and engage-through first appear under the new definitions. Add that date to your reporting calendar, dashboard annotations, and client notes.
    2. Preserve a pre-change export. Save campaign, ad set, and ad-level results from a representative period before the transition. Include spend, impressions, link clicks, attributed conversions, conversion value, and the attribution settings used at the time.
    3. Write down your conversion definition. Specify the event that counts as success, where it occurs, and whether your report covers website conversions, in-store conversions, or both. A purchase, qualified lead, and store visit should not be blended into one unexplained total.
    4. Create separate reporting lines. Show link-click conversions, engage-through conversions, and the combined attributed total where those fields are available. Do not hide the split inside one return-on-ad-spend number.
    5. Compare matched periods. Use periods with the same length and comparable day mix. Keep the conversion event and attribution configuration consistent. Otherwise, you will be measuring several changes at once.
    6. Delay attribution-driven budget reactions. If sales, leads, or revenue changed, investigate immediately. If only the attribution mix changed, wait until you have a complete reporting cycle under the new definitions. Changing spend at the transition point makes it harder to distinguish a real performance effect from reclassification.

    Your old results are not useless. They simply need a boundary marker. Keep them for directional and seasonal context, but do not present an old click-through conversion and a newly defined click-through conversion as perfectly equivalent.

    Reconcile Meta and Google Analytics without forcing a match

    Two transparent measurement lenses observe different parts of the same path from an advertisement to a website visit and purchase.

    Restricting click-through attribution to link clicks should make that category conceptually closer to the traffic Google Analytics can observe. It removes likes, shares, and saves from a bucket that sounds like site navigation. That can reduce one source of reporting confusion, but it does not create measurement parity.

    Meta Ads Manager and Google Analytics observe different parts of the journey and apply different credit rules. Ads Manager can associate a conversion with an eligible ad interaction. Google Analytics primarily reports activity it can observe on the website or app. Engagement-based and view-based influence will therefore remain a legitimate reason for totals to differ.

    When the platforms disagree, reconcile them in this order:

    1. Match the business outcome. Confirm that both reports use the same event. Do not compare Meta purchases with a Google Analytics report that includes begin-checkout events or other conversions.
    2. Match the period and time zone. A conversion near midnight can land on different dates when account settings differ. Check this before interpreting a daily gap.
    3. Inspect link tracking. Verify that campaign parameters survive redirects and reach the final landing page. A genuine Meta link click cannot appear under the expected campaign in Google Analytics if the identifying parameters are removed.
    4. Separate click-through from engage-through. Compare Google Analytics traffic and conversions primarily with Meta’s link-click-derived results. Keep engage-through visible as a separate influence measure instead of treating its absence from Google Analytics as a tracking failure.
    5. Check the conversion handoff. For purchases or leads, compare the underlying business records with both platforms. Platform totals are interpretations of those outcomes; your order or lead system should remain the control total.
    6. Document unresolved differences. Record which touchpoints, attribution rules, and conversion windows each report includes. A known, consistently defined gap is more useful than a forced match built from incompatible metrics.

    If you use Northbeam or Triple Whale, inspect their definitions as well. Meta is working with both analytics providers to incorporate clicks and views into their attribution models. That collaboration does not remove the need to verify which fields are available in your account, when the integration takes effect, and whether historical data is reclassified. Do not assume two dashboards use the same definition merely because both display a Meta conversion total.

    Use the new split to make better creative and budget decisions

    The practical value of the update is not a tidier dashboard. It is the ability to ask what kind of response each ad produces before you decide what to scale.

    Use link-click results to judge the route to conversion

    Link-click attribution is the more relevant slice when an ad is expected to move someone directly to a product page, lead form, booking page, or store-information page. Evaluate it alongside link clicks, landing-page activity, completed conversions, conversion value, and cost.

    If Meta shows strong link-click conversion performance but your analytics platform records little corresponding traffic, investigate the path before increasing spend. Check the destination URL, campaign parameters, redirects, page loading, consent behavior, and conversion event. A platform-reported conversion does not prove that your traffic instrumentation is healthy.

    Use engage-through results as influence evidence

    An engage-through conversion tells you that an eligible social interaction preceded the conversion. It does not tell you that the person visited through the ad, and attribution alone does not prove that the interaction caused the sale.

    That makes engage-through useful for creative designed to earn saves, sharing, discussion, or later consideration. Read it with engagement quality, branded demand, direct traffic, and business outcomes. If engage-through conversions rise while link clicks and sales stay flat, do not scale a direct-response budget solely because the attributed total looks larger. Test whether the creative produces incremental conversions or improves the next step in the journey.

    Treat five-second video qualification as a measurement rule, not a creative target

    The shift from 10 seconds to 5 seconds makes shorter video engagement eligible sooner. It does not mean five seconds is the ideal ad length, that a five-second viewer has purchase intent, or that every conversion following a short view belongs entirely to the video.

    For Reels and other fast video placements, make the opening seconds understandable without a long setup. Show the product, problem, use case, or brand cue early enough that a brief exposure communicates something real. Then judge the ad on two tracks: whether it earns attention and whether the resulting business outcomes justify the spend.

    A simple decision matrix can keep the new categories in proportion:

    • Strong link-click conversions and strong business outcomes: the ad is supporting a measurable route to conversion. Consider scaling gradually while watching marginal cost.
    • Strong engage-through results but weak link traffic: the creative may be influencing consideration rather than driving immediate visits. Keep it separate from direct-response evaluation and test its incremental contribution.
    • Strong link clicks but weak completed conversions: examine the offer, landing page, checkout, lead form, and event implementation. The ad may be generating traffic while the post-click experience loses it.
    • High attributed totals with no movement in underlying sales or leads: treat the platform result cautiously. Attribution can redistribute credit; it cannot create business outcomes.
    • Weak click-through and engage-through performance: changing the attribution label will not rescue the campaign. Revisit the audience, offer, creative, and conversion path.

    At your next performance review, place link-click conversions, engage-through conversions, and verified business outcomes beside one another. Make a budget decision only after you can identify which line moved and what behavior it represents. That is how the attribution update becomes a better decision system instead of another reporting dispute.

    References

  • How to Optimize Content for Humans and AI Discovery

    How to Optimize Content for Humans and AI Discovery

    Your page has two jobs before it can earn a business result. A person must understand why it matters, and a search or AI system must be able to identify what it says without guessing. Treat those as separate writing assignments and you usually get a stiff “AI version” alongside a more expressive page whose meaning remains implicit.

    Use one clarity-first page instead. Make its meaning explicit, its value hard to substitute and its next action easy to complete. That approach matters because generic informational content now competes with direct AI answers while visibility becomes scarcer. Publishing more is not enough. Each page must be understandable, retrievable, memorable and useful.

    Optimize the shared information, not two separate audiences

    People and AI systems process a page differently, but they tend to struggle at the same points: an unclear subject, an unsupported claim, an unexplained term, a buried qualification or an ambiguous next step. That is why clear messaging, usable experiences and technical precision form a shared foundation for people and automated systems.

    A person can sometimes infer meaning from visual position, tone or previous experience. An automated system may depend more heavily on labels, surrounding text and explicit relationships. The answer is not to flatten your writing into robotic prose. Keep the voice, examples and visual hierarchy that help people, but state the essential facts in text that can stand on its own.

    Page elementWhat a person needsWhat an AI system needs to identifyShared treatment
    OpeningWhether the page is relevantThe primary subject, audience and outcomeGive a direct answer or promise before background
    HeadingsA fast route to the right detailClear boundaries between subtopicsUse descriptive headings that name the question or decision
    EvidenceA reason to believe the claimThe relationship between a claim, its support and its limitsPlace support and qualifications beside the claim
    Call to actionConfidence about what happens nextThe action available and its destinationUse a specific label and a working, direct path

    Key takeaways

    • Optimize one canonical page for shared clarity instead of creating separate human and AI versions.
    • Put the main answer, offer or decision near the beginning, then add the context needed to evaluate it.
    • Use descriptive headings and self-contained sections so readers and systems can locate the right passage.
    • Keep evidence, definitions and limitations close to the claims they support.
    • Make the primary next action explicit in both its wording and its destination.
    • Plan how the page will reach its audience before committing resources to its production.

    Build every page as a question-to-action path

    A person follows a connected path of blank content cards from an initial question to a final action control.

    Optimization starts before the draft. Write a three-line page contract that prevents the page from drifting into a broad topic summary:

    • Audience: Who is making a decision or trying to complete a task?
    • Promise: What will this page help that person understand, choose or do?
    • Action: What should become possible after the promise has been fulfilled?

    Be specific enough that an editor could reject material that does not belong. “People interested in AI SEO” is too broad. “A content lead deciding how to revise service pages for human visitors and AI discovery” establishes a reader, a page type and a decision.

    1. Choose one dominant job. Decide whether the page primarily helps someone learn, compare, evaluate, buy or complete an action. A page may support secondary needs, but it should not give all of them equal weight.
    2. Answer before explaining. State the conclusion, offer or recommended direction early. Background belongs after the reader knows why it matters.
    3. Develop a visible reasoning chain. Move from the answer to the mechanism, supporting evidence or criteria, important limitations and the appropriate next step.
    4. Name important entities consistently. If you alternate among a product name, category name and vague phrases such as “the solution,” neither the reader nor a downstream system should have to infer whether they refer to the same thing.
    5. Close the loop. The call to action should follow from the page’s promise. A comparison page might lead to a specification, consultation or purchase path. An instructional page should let the reader perform or verify the task it explained.

    Then perform a sentence-level clarity audit. Replace pronouns whose antecedents are uncertain. Define an acronym at first use. Remove adjectives such as “advanced,” “leading” or “seamless” unless the page supplies a basis for them. Put exceptions beside the rule instead of hiding them in a closing note. Replace generic links such as “click here” and “learn more” with labels that identify the destination or action.

    A useful stress test is whether a 10-year-old could roughly explain what you offer, why it matters and how someone engages with it. That clarity test is meant to expose unnecessary complexity, not to make a technical subject childish. Keep the precise terms your audience needs, but define them in the same section where they become relevant.

    Write modules that survive scanning, extraction and reuse

    Blank visual content modules move from a central page into a mobile screen, an AI extraction frame, and a reader's reference card.

    There is no universally correct amount of text for a page. The right length is the amount required to explain the offer or answer, establish why it is credible, distinguish it from alternatives and support the intended action. A long page can be easy to use when it is modular. A short page can still fail when it omits the facts needed to decide.

    Give each section a repeatable internal shape:

    1. Descriptive heading: Name the subquestion, criterion or decision addressed by the section.
    2. Direct opening: Answer that subquestion in the first sentence or paragraph.
    3. Support: Add the mechanism, evidence, definition, example or comparison needed to evaluate the answer.
    4. Boundary: State any condition under which the answer changes or does not apply.
    5. Implication: Tell the reader what to notice, decide or do with the information.

    This structure makes a section useful when someone scans directly to it. It also reduces the risk that a sentence will be extracted without the qualifier that changes its meaning. Do not repeat the same conclusion in every module. Each section should advance the decision.

    Match formatting to the relationship in the information. Use bullets for criteria of the same kind, numbered lists when sequence matters and tables only when readers need to compare the same attributes across multiple options. Use images when they explain something the text cannot show as efficiently. Relevant alt text should communicate the image’s purpose or information, while decorative imagery should not be forced to carry a claim. Readable typography, adequate contrast and meaningful image descriptions support accessibility as well as comprehension.

    Once the visible copy is stable, align the structured layer. Treat JSON-LD as a machine-readable restatement of facts on the page, not as a second marketing message. Entity names, descriptions, relationships and available actions should agree with what a visitor can see. Do not add a claim to structured data that the page does not substantiate, and do not expect schema to rescue copy whose subject or purpose is unclear.

    • Use the same preferred name for the organization, product, service or person in the copy and structured data.
    • Make each marked-up type match the thing the page actually describes.
    • Keep dates, status information and other changeable facts synchronized wherever they appear.
    • Ensure an action described in structured data resolves to a real, functioning destination.
    • Remove obsolete markup when the corresponding visible content or capability is removed.

    When an AI agent must interact with tools or shared information rather than merely read a page, connection standards such as Model Context Protocol can help systems reach those resources. But clean, well-structured and actionable information is still required downstream. Connectivity does not correct an ambiguous offer, an unsupported statement or a broken workflow.

    Add value that cannot be replaced by a generic summary

    A generic explanation can be accurate and still be strategically weak. If a capable system can reproduce the page’s entire value from common knowledge, the reader has little reason to remember your brand or visit for the next step. As content production becomes easier, originality, distinctiveness and deliberate distribution carry more of the visibility burden.

    Do not confuse originality with novelty for its own sake. A useful page becomes harder to substitute when it contributes at least one defensible unit of value:

    • A decision rule: A clear way to choose between options, including the condition that changes the choice.
    • A bounded position: A recommendation that states where it applies, where it does not and why.
    • Owned evidence: Substantiated data, examples, observations or methods that your organization is entitled to publish.
    • An operational method: A checklist, sequence, template or diagnostic that lets the reader perform the work.
    • A revealing limitation: A tradeoff or failure mode that generic descriptions tend to omit.
    • A distinctive asset: A useful visual, framework or recurring editorial device that people can recognize and share.

    Use only material you can support. Invented data, anonymous anecdotes and manufactured certainty may make a page look specific, but they weaken trust and make its claims unsafe to reuse. Precision includes saying when evidence is limited or a recommendation depends on context.

    Apply a substitution test before publication. Could a competitor replace the logo and publish the page unchanged? Does the page contain a rule someone can use, or only a summary of the topic? Is there a sentence that expresses a recognizable point of view? Would a partner have a concrete reason to share it? If every answer points to interchangeability, revise the value proposition before polishing metadata.

    Distinctive content still needs a route to attention. Reverse the volume-era workflow that publishes first and asks about promotion later. Media, partnerships and events can push useful work toward an audience instead of leaving discovery entirely to search. Complete a distribution brief before approving the draft:

    • Audience: Name the specific group that will use the page and the decision it helps them make.
    • Carrier: Identify the newsletter, partner, community, media relationship, event, paid placement or owned channel capable of reaching that group.
    • Reason to share: State the practical value the carrier can offer its audience by distributing the work.
    • Portable asset: Choose the checklist, chart, decision rule, example or excerpt that can travel without stripping away the meaning.
    • Destination: Decide where interested people should land and what they should be able to do there.

    If you cannot identify a credible carrier or reason to share, that is useful information. Narrow the audience, strengthen the original contribution or reconsider whether the page deserves production. Distribution should shape the content brief, not become a rescue operation after publication.

    Use a publish gate for clarity, action and delivery

    Technical optimization belongs after the message and user path are coherent. It can expose and remove friction, but it cannot manufacture relevance. A fast, marked-up page with a vague offer remains vague. The final review should test meaning, task completion, rendering, discovery and distribution as one system.

    Run the same comprehension test with a person and an AI assistant

    Give the page to a colleague who was not involved in writing it. Ask that person to identify the intended audience, main answer or offer, supporting evidence, important limitation and primary next action. Do not explain the page before the test.

    Then give an AI assistant only the visible page copy and use this prompt: “Identify the intended audience, main claim or offer, supporting evidence, limitations and primary next action. Quote the text that supports each answer. If an answer is unsupported, write ‘not stated.’” Compare both responses with the page contract.

    A correct AI response does not prove that the page will rank, appear in an answer or receive a citation. Treat the exercise as an ambiguity detector, not a visibility score. When the assistant invents a benefit, misses a limitation or chooses the wrong action, find the wording or structure that allowed the misreading. The same ambiguity may also be costing human comprehension.

    Complete the action yourself

    • Follow the primary call to action and confirm that its destination matches its label.
    • Test phone numbers, email links, forms, validation messages and confirmation states where they are part of the path.
    • Remove form fields and separate steps that are not required to complete or qualify the action.
    • Check that a user can recover from an error without re-entering unrelated information.
    • Confirm that transactional or lead-generation intent is stated in visible language instead of being implied only by a button or form.

    Clear calls to action and simple task paths matter because unclear checkout and lead-generation flows obstruct people and automated agents alike. A button labeled “Submit” identifies an interface event. A label such as “Request the estimate” identifies the user’s action and expected outcome.

    Inspect the experience that carries the content

    • Load the page at common desktop and mobile widths and check whether text, controls or media move after they first appear.
    • Remove intrusive overlays, excessive advertising and visual elements that compete with the page’s primary purpose.
    • Check contrast, text readability, keyboard access, control labels and meaningful alternative text.
    • Verify that the complete page renders, internal resources load and security warnings are absent.
    • Review the visible copy and structured data after deployment rather than assuming the content management system published both correctly.

    Large layout shifts, incomplete rendering, weak contrast, malware warnings and disruptive pop-ups undermine usability and trust. Fix those problems because they interfere with the experience, not because a technical score can replace a clear answer.

    Measure the page by the job it was built to do

    Traffic remains useful context, but it is not a complete outcome. Informational visits have always been a proxy for business progress, and direct answers make that proxy less dependable on its own. Keep a small scorecard tied to the page contract:

    • Comprehension: Record which parts people or AI extraction tests misinterpret, omit or overstate.
    • Action: Track starts, completions, abandonment and errors for the page’s intended task.
    • Discovery: Monitor the relevant queries, impressions, brand mentions and AI-answer appearances that matter to the defined audience.
    • Demand and memory: Watch branded search, direct or returning visits and voluntary brand engagement without treating any one measure as conclusive.
    • Distribution: Record placements, partner participation, qualified referral activity and reuse of the portable asset.

    Tools can make individual checks easier. IndexNow can notify participating search engines about a changed URL more quickly, though notification is not a promise of indexing or visibility. Microsoft Clarity can reveal behavioral friction, including problems in chatbot experiences. Both are diagnostic aids for updates and user behavior, not substitutes for editorial judgment.

    Start with the page closest to a meaningful customer decision. Make its promise and action unmistakable, align its structured data, run the paired comprehension test and give it a real distribution path. Once that page passes, turn the same publish gate into the default for every high-value page you create or revise.

    References

  • YouTube VRC Non-Skip Ads: A Practical Campaign Guide

    YouTube VRC Non-Skip Ads: A Practical Campaign Guide

    You need your YouTube message to survive past the skip button, especially when it appears on the largest screen in the home. But non-skippable delivery is easy to overvalue: it means the ad can run to completion, not that the viewer paid attention, understood the offer, or changed their mind.

    YouTube VRC Non-Skip ads are most useful when complete-message delivery and connected TV reach are central to the campaign. The practical challenge is to give the optimizer a coherent set of 6-, 15-, and 30-second ads, then judge the campaign by incremental audience and business effects rather than completion alone.

    Know what VRC Non-Skip buys before you budget for it

    VRC stands for Video Reach Campaign. The Non-Skip option is available globally through Google Ads and Display & Video 360 and is designed around non-skippable placements on connected TV screens.

    The format solves a specific media problem. If your idea needs more than a fleeting brand appearance, removing the skip decision gives the complete sequence an opportunity to play. That is particularly relevant in the living room: YouTube has held the position of the leading U.S. streaming platform for three consecutive years, making its TV inventory difficult for reach-focused advertisers to ignore.

    What you are buying is delivery, however, not guaranteed attention. A non-skippable impression cannot tell you whether someone looked away, started a conversation, remembered the brand, or later bought. Write that distinction into the brief. Otherwise, the campaign’s most predictable behavior – a high proportion of ads playing through – can be mistaken for proof that the advertising worked.

    VRC Non-Skip is a strong candidate when your primary objective is broad reach and the full message matters. It is a weaker fit when success depends mainly on an immediate click, when every second of budget must be assigned manually to a particular duration, or when you have only one piece of creative that cannot adapt to different placements.

    Build one creative system for three different jobs

    Three connected scenes show the same unbranded lantern in a close-up, during a power outage, and illuminating a family dinner.

    Google AI can dynamically optimize delivery across 6-second bumpers, 15-second standard ads, and 30-second connected-TV-exclusive ads. That does not mean the same edit should simply be cut shorter twice. Each duration needs to express the same proposition at a different level of depth.

    DurationRole in the creative systemWhat to protect
    6 secondsMake the brand and one idea recognizable immediatelyBrand cue, category context, and a single memorable point
    15 secondsConnect the problem, promise, and brand without detoursOne clear benefit and one simple next step
    30 secondsUse the CTV-exclusive time for a fuller argument or storyContext, proof or explanation, brand, and a legible closing action

    Start by writing one sentence that every version must communicate. If you cannot reduce the campaign to one proposition, the optimizer may distribute three different ideas rather than three expressions of the same idea. You will then be unable to tell whether a duration, a message, or the media placement caused the difference.

    1. Lock the invariant. Keep the audience problem, brand promise, and intended perception consistent across all three cuts.
    2. Write the six-second ad from scratch. Do not speed up a longer script. Show the brand early and remove every supporting point that competes with the central idea.
    3. Let the 15-second ad make one complete argument. Give the viewer enough context to understand why the promise matters, but resist adding a second benefit merely because time remains.
    4. Earn the 30 seconds. Use the longer CTV format for information that changes understanding: a demonstration, meaningful contrast, qualification, or narrative progression. A slower version of the 15-second cut wastes the additional exposure.
    5. Design for viewing distance. Use large, persistent visual cues and a closing instruction that can be understood from across a room. Tiny disclaimers, dense feature lists, and several competing calls to action make a completed ad difficult to process.

    Review the three versions side by side without sound and then audio-only. They do not need to communicate every detail in both modes, but the brand and main promise should not disappear when either the visual or audio channel loses the viewer’s attention.

    Give the AI a precise objective, not three unrelated ads

    The operational benefit of VRC Non-Skip is that Google AI allocates impressions across the available formats instead of requiring you to maintain a separate budget for each duration. The optimizer handles that allocation; you still own the strategic choices around audience, message, constraints, and evidence of success.

    A useful campaign brief should settle these points before launch:

    • The audience to be reached: define who must see the campaign and which geography and flight period matter. A broad label such as “prospects” is not enough to interpret the resulting reach.
    • The change you want: specify the perception, recall, consideration, or business behavior the campaign is intended to influence. “Run the whole ad” is delivery behavior, not the marketing outcome.
    • The invariant proposition: document the one promise that appears in every duration so format allocation does not become message allocation by accident.
    • The acceptable trade-off: decide how much control you are willing to exchange for automated reach efficiency. If a contract or internal plan requires an exact spending share by duration, verify that requirement can be enforced rather than assuming the optimizer will infer it.
    • The decision rule: state which result would justify scaling, maintaining, changing, or stopping the campaign. Set it before performance data can tempt the team to choose whichever metric looks best.

    Do not feed the system one awareness ad, one product tutorial, and one promotional spot and call them a format mix. Even if all three carry the same logo, they ask different questions of the audience. Keep the campaign thesis stable; vary the amount of time used to express it.

    The same discipline applies to calls to action. A CTV reach campaign can support later search, site visits, store activity, or other responses, but the viewer may not act on the television itself. Use a short, memorable destination or instruction. If the action requires several details, let the ad create the reason to act and let the destination handle the explanation.

    Test for incremental impact, not inevitable completion

    An isometric illustration shows two matched audience groups following parallel test paths, with one group exposed to a product film before both enter identical shopping spaces.

    A non-skippable campaign should complete more of its message by design. Completion therefore belongs in delivery quality checks, not at the top of the business scorecard. Scaling spend because the ads played through would reward the defining feature of the format without showing that it improved the result you care about.

    Measure the campaign in three layers:

    • Delivery: confirm where the ads ran, how impressions were distributed among durations, and whether the intended connected TV inventory and audience were reached.
    • Audience: examine unique reach and frequency, not just the impression total. Repeatedly reaching the same viewers is different from extending the campaign to new viewers.
    • Outcome: evaluate the predefined brand or business change. That might involve a controlled brand measure, qualified visits, conversions, or another result tied to the campaign’s actual objective.

    If you want to know whether Non-Skip adds value over your existing YouTube reach approach, create a real comparison rather than contrasting the new campaign with an unrelated historical period. Keep the audience definition, proposition, flight conditions, and outcome measure as consistent as your testing method allows. The main variable should be the delivery strategy you are trying to evaluate.

    Branded search, direct traffic, and channel activity can help you notice movement after a CTV push, but they do not establish causation on their own. Other campaigns, seasonality, news, and existing demand can move the same signals. Treat them as supporting evidence unless you have a controlled design capable of isolating the campaign’s effect.

    Set the scale decision in advance. For example, require evidence that Non-Skip reaches additional members of the intended audience and improves the chosen outcome at an acceptable cost. If it only increases completed delivery, revise the creative or media plan before committing more budget. That protects you from paying more for a result that is mechanically built into the unit.

    Key takeaways for your launch decision

    • Use VRC Non-Skip when connected TV reach and complete-message delivery are central to the objective, not simply because non-skippable inventory sounds more forceful.
    • Treat 6-, 15-, and 30-second ads as a coordinated creative system with one proposition, not as three independent campaigns.
    • Let Google AI allocate impressions across eligible formats, but define the audience, constraints, intended change, and scale rule yourself.
    • Separate playback from persuasion. A completed non-skippable ad is a delivery result, not proof of attention or business impact.
    • Compare Non-Skip with a credible alternative under similar conditions and scale only when it improves incremental audience or outcome value.

    Your next move is to write the invariant campaign sentence and the scale rule before opening the ad platform. If the team can agree on both, build the three duration-specific executions and run a bounded test. If it cannot, more automation will only distribute an unresolved strategy faster.

    References

  • Unlock In-Depth Insights with Asset Hierarchies

    Unlock In-Depth Insights with Asset Hierarchies

    I’ve discovered that Asset Hierarchies offer a powerful way to track each of my products, features, and other sub-assets individually. Despite this detailed tracking, everything seamlessly integrates back into the bigger picture of overall brand performance.

    This approach allows me to gain granular insights while still maintaining an understanding of my brand’s overall landscape.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot