Author: shivamcrushpressai

  • How to Measure AI Visibility and Social Signal Impact

    How to Measure AI Visibility and Social Signal Impact

    You see your brand appear in an AI answer after a burst of YouTube or Reddit activity. Now you need to know whether social content contributed to the gain, merely accompanied it, or had nothing to do with it. A screenshot cannot answer that.

    The useful approach is to measure a chain of distinct outcomes: whether an answer was produced, whether your brand was mentioned, what the answer cited, whether anyone visited, and whether that visit mattered. Once you separate those events, social activity becomes something you can test instead of a vague visibility score you have to trust.

    Measure the visibility chain, not a single score

    AI visibility is not one event. A model can name your brand without citing you, cite your page without sending a visit, or use a social discussion as evidence while ignoring your own site. Combining those outcomes into one number hides the exact problem you need to solve.

    Build your measurement around five stages:

    • Answer coverage: Did the AI surface return a valid answer for the prompt? Errors, refusals, and empty results should not quietly enter the denominator.
    • Brand presence: Did the answer name your brand, product, expert, or another tracked entity? A name without attribution is a mention, not a citation.
    • Evidence selection: Did the answer cite an owned page, a brand-controlled social asset, an independent social discussion, or a third-party website?
    • Referral: Did an identifiable visit arrive from the AI surface? Keep this separate from citation counts because a visible citation does not guarantee a click.
    • Business outcome: Did an identified visitor subscribe, enquire, start a trial, add a product, or complete the outcome your organization already values?

    The denominator matters. Brand presence rate should mean valid answers containing your brand divided by all valid answers in the same prompt panel. Owned citation rate should mean valid answers linking to your domain divided by those valid answers. Do not divide one metric by all scheduled prompts and another by successful responses, then place them on the same chart as if they were comparable.

    Keep results separate by model, answer mode, locale, and signed-in or personalized state when those conditions apply. You can add a roll-up later, but the underlying rows must remain available. Otherwise, a change in the mix of tests can look like a visibility improvement even when no individual segment improved.

    Key takeaways

    • A brand mention, a citation, a referral, and a conversion are different outcomes. Report each one separately.
    • Social engagement is an audience response. It is not, by itself, evidence that an AI system found or reused the content.
    • Classify social citations as brand-controlled or independently earned so you can see who is actually carrying your claims.
    • Use a stable prompt panel and captured answers to measure change. Screenshots of favorable answers are examples, not a trend line.
    • Treat staged publishing tests as contribution evidence, not absolute proof of causation.

    Separate social engagement from social reuse

    The phrase “social signal” is too broad for a serious dashboard. It can refer to audience behavior, the accessibility of a public post, a brand mention inside a discussion, or an AI answer citing that discussion. Those events belong in different columns.

    Use three measurement layers. The audience layer contains views, comments, shares, saves, and other platform engagement. The content layer records what you published, where it lives, which topic it answers, and whether it is publicly accessible. The AI layer records mentions, citations, source types, and the claims an answer appears to draw from each asset.

    YouTube, Reddit, and long-form formats appear prominently in AI citation patterns. That gives you a reason to test those surfaces and formats independently. It does not establish likes, comments, views, or shares as direct ranking factors. Engagement and AI reuse may move together, but movement alone does not reveal the mechanism.

    Classify every social citation by ownership:

    • Owned social: A video, profile, post, or channel your organization controls.
    • Earned social: A customer discussion, community answer, review, creator video, or other independently controlled asset.
    • Unresolved social: A social URL whose ownership or relationship to the brand is not yet clear.

    This distinction changes the decision you make. If AI answers repeatedly cite your own videos, you can inspect which topics and formats are being reused. If independent Reddit discussions carry the citations, the opportunity may be better product documentation, clearer public answers, or stronger community participation. It is not permission to manufacture conversations or disguise promotional posts as customer opinion.

    Also separate direct from indirect evidence. A visible source marker that resolves to a social URL is direct citation evidence. A new brand mention that appears after social distribution is contribution evidence, provided you used a consistent test. A rise in engagement alongside a rise in AI visibility is only correlation. Give those observations different labels instead of compressing them into one “social impact” score.

    Build a dashboard that preserves the evidence
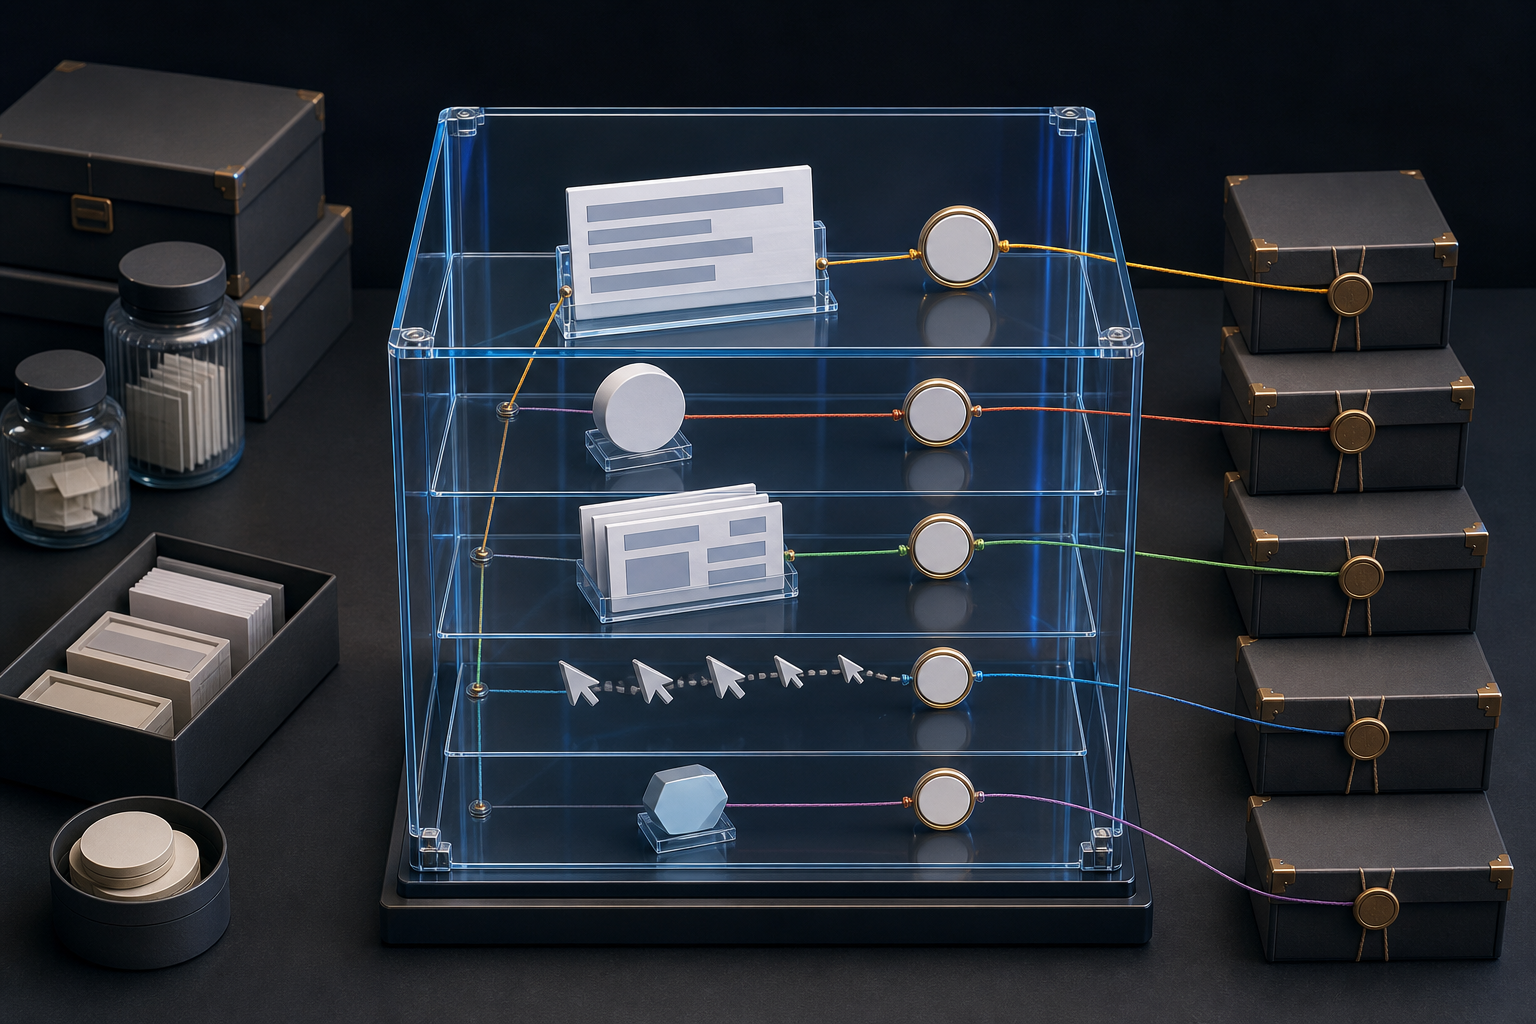
    Isometric evidence workspace with layered answer, source, visit, and outcome artifacts connected to clocks and archive boxes.

    Your dashboard should answer a decision question at each stage. It should also let someone open the underlying response and verify the classification. If a metric cannot be traced back to a prompt, captured answer, and URL, it is difficult to audit and easy to overstate.

    MeasurementCalculation or recordDecision it supports
    Valid-answer coverageValid answers / scheduled prompt runsWhether the rest of the sample is complete enough to compare
    Brand presence rateValid answers naming the brand / valid answersWhether the brand enters the answer at all
    Owned citation rateValid answers citing an owned URL / valid answersWhether your site is selected as evidence
    Owned-social citation rateValid answers citing a brand-controlled social URL / valid answersWhether your social assets are reused directly
    Earned-social citation rateValid answers citing an independent social URL about the brand / valid answersWhether communities and creators carry your visibility
    Social share of citationsSocial URL citations / all observed URL citationsHow much of the visible evidence comes from social platforms
    Identified AI referralsAnalytics sessions attributed to tracked AI surfacesWhether visible answers are producing measurable visits
    Business outcomesDefined events associated with identified AI-referred sessionsWhether measurable traffic contributes to a valuable action

    Store one row for every prompt run. At minimum, keep a stable prompt ID, the intent being tested, the exact prompt, model or surface, answer mode, relevant locale, capture time, complete answer, brand-present status, cited URLs, ownership class, and notes about errors or ambiguity. Save the response itself, not only the extracted score.

    Define “citation” before collecting data. A practical rule is a visible source marker or link that resolves to a specific URL. If an answer merely says “reviews indicate” without exposing a source, record it as unattributed language rather than guessing which page influenced it. If a source card points to a Reddit thread that mentions your brand, record the thread URL and classify it as earned social; do not credit your domain simply because the discussion is about you.

    Use both response-level and URL-level counts. Response-level citation rate tells you how often answers contain at least one qualifying citation. URL-level counts tell you which individual assets recur. Without both, one answer containing several links can distort your view of overall coverage, while a simple yes-or-no rate can conceal the page or social asset doing the work.

    Do not make engagement totals the headline AI metric. Keep views and comments nearby as diagnostic context, but place them in their own channel panel. That layout prevents a popular social campaign from being reported as an AI visibility win before any AI outcome has changed.

    Test social contribution with staged publishing
    Two parallel experimental pathways compare an immediate social release with a delayed release before identical AI processing stages.

    You cannot fully control model updates, retrieval behavior, or competing publications. You can still produce more useful evidence by changing your content in stages and keeping the measurement conditions as consistent as possible.

    1. Choose one intent gap. Start with a question for which your brand is absent, weakly represented, or cited through an unsuitable third party. Record why the intent matters before publishing anything.
    2. Freeze the prompt panel. Include unbranded category questions, problem-led questions, comparisons where appropriate, and branded verification questions. Assign stable IDs so wording changes do not disappear into the trend.
    3. Capture a baseline. Save the complete answers, mentions, cited URLs, and source classes under the model and mode you plan to retest.
    4. Publish the canonical owned answer first. Give the question a clear, complete page on your site. Record its URL, publication state, and the claim or explanation it is designed to support.
    5. Measure again before adding social distribution. This creates a checkpoint between the owned-page change and the social change. It will not eliminate every outside variable, but it prevents simultaneous publishing from making the two contributions impossible to separate.
    6. Add the appropriate social format. Adapt the answer to the platform instead of pasting a promotional link. Record the precise video, thread, or post URL and classify it as an owned social asset.
    7. Repeat the same capture process. Look for a new mention, a new citation, a change in source ownership, or repeated use of a particular asset. Keep referral and business outcomes in their own columns.
    8. Label the strength of the result. A cited social URL is direct reuse evidence. A repeated visibility change after the social stage is contribution evidence. Parallel movement in engagement and visibility remains correlation.

    Give each format a complete job

    A social asset should answer the intended question on its own. The platform version can point to a deeper owned page, but it should not be an empty teaser whose only useful content sits behind a click.

    • For YouTube: State the question clearly, answer it in the video, and make the title and description accurately identify the subject. Record the video URL separately from the channel URL so citations can be attributed to the asset that appeared.
    • For Reddit: Contribute a native answer suited to the community and disclose a brand relationship when one exists. Track independent threads separately from posts made through an official brand account.
    • For long-form owned pages: Put the direct answer near the relevant heading, explain the reasoning, define ambiguous terms, and make supporting details easy to locate. A social asset should extend that answer, not contradict it.

    Do not alter the prompt panel whenever a result disappoints you. Add genuinely new intents as new tracked rows, and preserve the original set. Otherwise, prompt selection becomes an invisible optimization lever that can manufacture an improving trend.

    Use the pattern to choose your next action

    The value of measurement is not the score. It is knowing what to change. These patterns lead to different decisions:

    • Engagement rises, but AI mentions and citations stay flat: The social asset reached people, but your capture shows no AI reuse. Keep the campaign result in the social report and test whether a more complete, publicly accessible answer changes the AI outcome.
    • Brand mentions rise, but citations stay flat: Your brand is entering responses without visible evidence from your content. Strengthen the owned answer around the exact intent and track whether a specific page begins to appear.
    • Earned-social citations rise, but owned citations remain weak: Communities are explaining your brand more successfully than your site. Inspect the questions, terminology, objections, and comparisons in those discussions, then close the corresponding information gaps on pages you control.
    • Owned-social citations rise, but owned-site citations do not: The platform asset is carrying the answer. Preserve what makes it useful, then improve the related site page so it can serve as the durable, canonical explanation.
    • Citations rise, but identified referrals do not: Do not erase the citation gain or call it a traffic win. Report evidence selection and identified visits as separate results, then decide whether brand inclusion itself matters for that intent.
    • One model improves while another does not: Keep the gain attached to the model and mode where it occurred. Do not generalize it into universal AI visibility.

    Agent analytics can reduce the manual work, but the product still needs to expose enough evidence for you to audit its metrics. For Shopify teams, Profound and Nostra position their integration as a way to see whether store pages are referenced by large language models. Treat that as a vendor capability to evaluate, not proof that every relevant model, prompt, locale, or answer mode is covered.

    Before adopting any AI visibility tool, verify which surfaces it observes, whether you can manage a stable prompt panel, whether it stores complete answers and exact cited URLs, how it handles failed responses, whether owned and earned social sources can be separated, and whether historical rows can be exported. A polished composite score is less useful than verifiable records if you cannot explain what changed underneath it.

    Start with one commercially relevant intent, one fixed prompt panel, and one staged owned-to-social publishing test. Preserve every response and URL. At the end of the cycle, you should be able to say not merely that visibility moved, but where it moved, which evidence appeared, how strong the social connection is, and what you will publish next.
    References

  • Google AI Max Economics: When Revenue Growth Costs More

    Google AI Max Economics: When Revenue Growth Costs More

    You enabled Google AI Max and revenue went up. Unfortunately, CPA went up too. That leaves you with the question that matters: did the campaign create profitable demand, or did automation simply buy more conversions at a price your business cannot sustain?

    You cannot answer that from Google’s conversion column alone. You need an economic threshold, evidence of incremental reach, and a breakdown of where AI Max spent the additional money. Here is how to make that decision without mistaking higher volume for better performance.

    Key takeaways

    • AI Max can increase revenue without improving efficiency. Across more than 250 campaigns, median revenue increased 13% while median CPA increased 16%.
    • Set your allowable CPA and minimum ROAS before activation. Otherwise, a larger conversion total can make an economically weak result look successful.
    • Separate new non-brand demand from existing keyword coverage, branded searches, competitor terms, Search Partners traffic, and URL expansion.
    • Accounts already using Broad Match, Dynamic Search Ads, and Performance Max may have less untouched demand for AI Max to discover.
    • Scale only when the incremental conversion value produces acceptable contribution after ad spend, not merely when Google Ads reports an uplift.

    Read the uplift as a trade-off, not a forecast

    Across an independently assessed set of more than 250 campaigns, median revenue increased by 13% and median CPA increased by 16%. Individual ROAS changes stretched from a 42% improvement to a 35% decline. That range is more useful than a single average because it shows that activation alone does not determine the economic outcome.

    Do not combine the two medians into a synthetic result for your account. The campaign at the middle of the revenue distribution is not necessarily the campaign at the middle of the CPA distribution. More importantly, neither metric tells you what happened to contribution margin after product costs, fulfilment, discounts, lead quality, and other variable expenses.

    Google presents a more favourable platform benchmark. It says advertisers activating AI Max often receive 14% more conversions or conversion value at nearly the same CPA or ROAS. Google puts the uplift at 27% for advertisers relying on exact and phrase match keywords. Treat those as vendor-reported benchmarks, not promises. Retail was omitted from the 14% figure, which makes that benchmark less informative for ecommerce teams.

    The right verdict depends on your unit economics. If AI Max produces $1 of additional revenue that carries less than $1 of combined product, fulfilment, servicing, and advertising cost, the uplift may be valuable. If the extra revenue does not cover its incremental costs and required contribution, scale magnifies the problem.

    For ecommerce, start with contribution margin before ad spend:

    • Contribution after ads = conversion value multiplied by the pre-ad contribution-margin rate, minus ad spend.
    • Break-even ROAS = 1 divided by the pre-ad contribution-margin rate.

    Use the margin left after discounts, product cost, payment fees, fulfilment, and other variable order costs. If your conversion values are already profit-weighted, do not apply the margin adjustment a second time.

    For lead generation, platform CPA is useful only when the recorded action has stable commercial value. A form submission is not interchangeable with a qualified opportunity or a sale. Estimate the expected contribution from an acquired customer, multiply it by the observed lead-to-customer rate, and set your allowable lead cost below that value by the contribution you need to retain. If lead quality varies by query or campaign, evaluate those segments separately instead of relying on a blended CPA.

    Write the decision rule before the test:

    1. Name the business outcome that counts: completed order, qualified opportunity, or acquired customer.
    2. Define the highest CPA or lowest ROAS that preserves your required contribution.
    3. Set a minimum acceptable volume or value uplift so a trivial change does not justify more complexity.
    4. Choose the point at which normal conversion lag has matured enough to evaluate the result.
    5. Record the conditions that trigger restriction or rollback, including network, query, and landing-page failures.

    This prevents a common analytical error: moving the target after an attractive revenue number appears.

    Find where the additional spend and revenue came from

    A central pool of glowing budget particles branches toward established shoppers, new audience groups, and sparsely converting areas in an isometric digital marketplace.

    AI Max brings three major automation layers into a Search campaign: Search Term Matching, Text Customization, and Final URL Expansion. Each one can add reach, but each one can also obscure the mechanism behind an uplift.

    Search Term Matching combines broad-match expansion with keywordless targeting. The economically important question is not simply whether it found more queries. You need to know whether those queries represented genuinely new, profitable demand.

    Broad-match cannibalization can recycle coverage that already existed. An AI Max conversion may therefore be new to the reporting path without being incremental to the account. Own-brand searches can create the same illusion because they often capture demand generated elsewhere. Competitor terms deserve their own category as well: AI Max has sometimes taken a large share of Search impressions from competitor-brand queries.

    Classify search terms into at least five buckets:

    • Queries already covered by exact or phrase keywords.
    • Queries already reachable through existing broad-match keywords.
    • New non-brand queries that express commercially relevant intent.
    • Your own branded queries.
    • Competitor-brand queries.

    Measure spend, conversion value, CPA, ROAS, and contribution for each bucket. If the uplift sits mainly in existing coverage or branded demand, the campaign has not yet demonstrated meaningful expansion. If it comes from new non-brand terms at acceptable contribution, the case is stronger.

    Text Customization dynamically changes ad copy. Review the generated combinations for factual accuracy, offer consistency, and alignment with the query and destination. A conversion increase is not worth preserving if the copy creates promises the landing page cannot support. The volume of search-term and ad-combination reporting can become difficult to inspect manually, so build a repeatable export or reporting view rather than sampling a few conspicuous examples.

    Final URL Expansion lets the system choose landing pages automatically. Track the actual destination alongside the query and economics. A page can convert and still be the wrong destination if it shifts demand toward a low-margin product, weak lead type, or unintended offer. Restrict unsuitable destinations with the controls available in your account, and judge the remaining traffic against the same economic floor as manually selected pages.

    Network performance needs a separate cut. Some AI Max campaigns have experienced disproportionate Search Partner Network impressions with lower conversion rates than standard Google Search. A blended campaign average can hide that leak. Compare Google Search and Search Partners independently before changing bids, budgets, or campaign-wide targets.

    Your working audit should therefore contain one row per useful reporting segment and include:

    • Search term and query classification.
    • Google Search or Search Partner Network.
    • Original or expanded landing-page URL.
    • Ad customization or combination, where reporting exposes it.
    • Spend, conversions, conversion value, CPA, and ROAS.
    • Your internal margin or lead-quality adjustment.

    That final internal adjustment is what turns an advertising report into an economic assessment.

    Run a rollout that measures incremental value

    Two matched groups of storefronts and customers are compared side by side, with only one group receiving additional automated advertising signals.

    An account already using Broad Match, Dynamic Search Ads, and Performance Max may have less unexplored demand available to AI Max. That does not mean AI Max cannot work. It means recorded conversions are less likely to prove incrementality on their own because several automated systems may already cover overlapping intent.

    Use an experiment or phased campaign cohort that preserves a credible comparison. Keep the rollout small enough that a poor result cannot consume an uncontrolled share of the account budget, but large enough to pass through the account’s normal conversion cycle.

    1. Snapshot the baseline. Export search terms, query classes, network distribution, destination URLs, spend, conversions, value, CPA, ROAS, and contribution before activation.
    2. Choose an economically legible campaign. Start where conversion values are trustworthy and the products or leads have sufficiently consistent margins. A campaign that mixes radically different economics will produce a blended answer you cannot use.
    3. Preserve a comparison. Use the experiment structure available to you or phase AI Max into a defined cohort while leaving a comparable cohort unchanged. Avoid unrelated bidding, budget, creative, landing-page, and tracking changes during the evaluation.
    4. Apply prewritten guardrails. Use the allowable CPA, minimum ROAS, required contribution, and rollback conditions established before activation.
    5. Wait for conversion lag. Do not declare success from early clicks and partial conversions. Evaluate both test and comparison periods only after the account’s normal lag has matured.
    6. Reconcile the uplift. Determine how much came from new non-brand demand, existing coverage, brand queries, competitor terms, Search Partners, text changes, and expanded URLs.

    A before-and-after comparison without a control is weak evidence. Seasonality, promotions, budget changes, changes in demand, and delayed conversions can all resemble an AI Max effect. When a clean holdout is impossible, document those confounders and lower your confidence in the result rather than presenting a precise uplift as causal.

    Dynamic Search Ads also affect the rollout decision. Google Ads Liaison Ginny Marvin has confirmed that AI Max is intended to replace Dynamic Search Ads eventually, but Google has not announced an official timeline. Treat that as a reason to learn how keywordless targeting behaves inside your Search campaigns, not as a deadline for an account-wide migration.

    Phase out a DSA campaign only after the AI Max replacement has demonstrated acceptable coverage and economics. The product direction does not require you to move the traffic into Performance Max, and it does not justify removing a profitable DSA setup before its replacement is validated.

    Use a decision matrix to scale, restrict, or stop

    AI Max does not deserve a single account-wide verdict. The result can be good in one query or network segment and poor in another. Make the next change at the narrowest level supported by the evidence.

    Observed resultLikely interpretationNext action
    Revenue and contribution rise, CPA remains below its ceiling, and new non-brand coverage accounts for meaningful liftAI Max is finding economically useful incremental demandIncrease exposure gradually and keep the same segment-level audit in place
    Revenue rises, but CPA exceeds its ceiling or ROAS falls below its floorThe campaign bought additional volume too expensivelyRestrict the query, network, or URL segments causing the loss; pause if the controls cannot restore acceptable economics
    Reported conversions rise mainly through existing keywords, own-brand searches, or overlapping automated campaignsThe apparent gain may be cannibalization rather than incrementalityPreserve or strengthen the holdout and require evidence of total account lift before scaling
    Competitor terms or Search Partners consume spend without adequate contributionExpansion is reaching a distinct but uneconomic traffic sourceSeparate and restrict that traffic where account controls permit instead of weakening the entire campaign
    Performance is materially unchanged while reporting and governance work increaseNo incremental value has been demonstratedLeave AI Max off unless a tightly scoped DSA-transition test provides a separate reason to continue

    Do not activate AI Max because automation feels inevitable or because AI Overviews create fear of being left behind. AI Overviews are not a campaign economics metric. Your decision belongs in the contribution calculation and the controlled comparison.

    Start with one campaign whose margins and conversion values you trust. Write the CPA and ROAS boundaries, preserve the current query and network baseline, and activate AI Max only within that controlled scope. Expand it when incremental margin clears your threshold. If it cannot, the higher revenue number is not a reason to keep paying more.

    References

  • Industry Barriers to AI Search Visibility and How to Fix Them

    Industry Barriers to AI Search Visibility and How to Fix Them

    You can make a page easy for conventional crawlers, add structured data, and still remain absent from AI-generated answers. That usually does not mean you need more content. It means your site is failing before, during, or after citation: AI systems cannot reliably reach the page, cannot justify using it, or can satisfy the user without sending them to you.

    Before you commission another AI SEO rewrite, identify which gate is failing. Access problems need engineering and security work. Trust problems need evidence. Utility problems need a stronger next step. Treating all three as copy problems wastes budget and can deepen the actual barrier.

    Your industry is usually failing at one of three gates

    Access is the first gate. Across 201 AI visibility audits covering ten industries, 38 audits returned errors, an error rate of 18.9%. Another eight scored zero because missing subscores pointed to extraction or rendering problems. Those sites did not merely have weak answers; they created doubt about whether the relevant content could be retrieved at all.

    Trust is the second gate. Among 163 successful audits, the average overall score was 61.6 and the median was 66. About 70.6% landed in the inconsistent-visibility range, only 4.9% had a strong foundation, and none reached the exceptional range. In practical terms, being readable was common. Being predictably usable as a citation was not.

    The ordering of the subscores explains the problem. Median structure was 92 and extractability was 74, while authority and evidence reached 48 and freshness reached 45. If your team responds by polishing headings, adding more schema, or rewriting introductions, it may be working on the two areas that are already strongest while leaving the proof deficit untouched.

    Utility is the third gate. A page can be accessible and defensible yet still produce no visit when the answer itself is the entire product. This is where an AI search problem becomes a business-model problem. Citation determines whether your brand participates in the answer; post-answer utility determines whether that participation can lead to a booking, application, purchase, enrollment, or other meaningful outcome.

    The figures are directional, not a universal benchmark. The sample leaned heavily toward homepages, which often contain more positioning language and less supporting evidence than articles, methodology pages, policies, and detailed listings. Use the pattern to choose what to inspect, not to assume that every site in a sector has the same score.

    Key takeaways

    • Test retrieval before optimizing prose or schema. A page cannot earn a citation when its useful content does not arrive reliably.
    • Separate readability from authority. Clear formatting helps extraction, but claims still need evidence, ownership, scope, and truthful freshness signals.
    • Design for what happens after the answer. If your entire value can be summarized, visibility may not create a visit or commercial outcome.
    • Audit representative page types and query journeys, not just your homepage or a single blended visibility score.

    Access barriers turn site architecture into exclusion

    An abstract website building has blocked corridors and sealed entrances, while one illuminated route reaches its central content chamber.

    Access failure is unevenly distributed. In the audited sample, job boards had a 40% error rate, legal directories 35%, travel booking sites 33.3%, online course marketplaces 30%, and coupon sites 20%. Local directories, by comparison, had a 5.3% error rate. These percentages do not diagnose your domain, but they show why access deserves its own workstream in sectors built around dynamic listings, defensive bot controls, or application-like interfaces.

    Three mechanisms deserve attention. A web application may place essential information behind client-side rendering. A web application firewall may treat an AI agent as hostile traffic. An interstitial, popup, or script may replace the useful response with a consent request, challenge, or empty shell. A human using a familiar browser can still see the page, so a normal visual check may miss all three.

    Run an access audit as a delivery test, not a design review:

    1. Choose representative URLs. Include the homepage, an editorial resource, a category or results page, a detailed listing, a methodology or policy page, and the page where the user completes an action. Do not let a working homepage stand in for the rest of the site.
    2. Inspect the raw response. Record whether the request succeeds, what content type returns, and whether the response body contains the page’s answer-bearing facts.
    3. Compare raw and rendered content. If titles, descriptions, prices, eligibility conditions, locations, dates, or supporting evidence appear only after scripts execute, document that dependency.
    4. Use a clean session. Confirm that the information appears without stored cookies, an existing login, dismissed popups, or a sequence of clicks that an automated retriever may never perform.
    5. Repeat the retrieval. A page that works once and fails on the next attempt is still unreliable. Check multiple URLs from each important template so you can distinguish an isolated page defect from a systemic one.
    6. Review delivery logs. Match failed requests to firewall challenges, blocked user agents, script dependencies, interstitials, or other delivery errors. Assign the fix to the system that actually caused the failure.

    Do not respond by broadly disabling bot protection or allowing every automated agent across the domain. That can create security, abuse, and infrastructure risks. Define the narrowest access rule that supports the agents you intend to serve, retain controls for sensitive and authenticated areas, and rerun the same retrieval tests after the change.

    For rendering problems, put the facts required to understand the page in the initial HTML or a reliably rendered response. Client-side code can still handle filtering, personalization, account functions, and transactions. It should not be the only place where an agent can find the identity and purpose of a listing.

    Structured data cannot rescue an empty document, a firewall challenge, or a blocked response. The access gate passes only when useful visible content and its supporting context can be retrieved consistently, not merely when the page looks correct in a logged-in employee’s browser.

    Trust barriers begin where polished marketing ends

    Once a page is reachable, the question changes from can it be read to can its claims be defended. Page type matters here. Articles had a median authority score of 76, compared with 45 for homepages. A homepage can establish what a company wants to be known for, but positioning statements rarely provide the methodology, citations, qualifications, and scope needed to support a factual answer.

    Freshness and evidence cues were also thin. A Last-Modified header was missing in 114 instances, while citations or outbound links were recorded only 13 times. A missing header does not prove that content is stale, and an outbound link does not automatically make a claim true. The practical problem is that a reviewer or retrieval system has fewer inspectable clues for determining when the information was checked and why it should be trusted.

    Turn important claims into citable units

    A citable unit is a compact passage that answers a specific question and carries enough context to survive extraction. Build each important unit from the following parts:

    • Direct answer: State the fact or conclusion clearly before expanding on it.
    • Scope: Explain where, when, and to whom the claim applies. Include relevant conditions such as location, eligibility, exclusions, or effective period.
    • Evidence: Show the calculation, comparison method, documented basis, or primary references that support the claim.
    • Stewardship: Identify the author, editor, reviewer, or organization responsible for maintaining the information.
    • Freshness: Display a truthful reviewed or updated date and align machine-readable dates or headers with the actual editorial change.
    • Continuation: Give the reader an exact next action when the answer alone does not complete the task.

    Apply this at the level where a decision is made. A coupon page needs more than a promise of savings; it needs the offer, conditions, applicable products, exclusions, and verification context. A legal directory needs more than claims about quality; it needs a transparent listing or ranking method, relevant jurisdictional information, profile ownership, and disclosures. A course marketplace needs more than aspirational outcomes; it needs a syllabus, prerequisites, instructor responsibility, and a clear explanation of what completion entails.

    Move proof out of generic brand language and into articles, detailed listings, methodology pages, editorial policies, and other resources where it can be inspected. Then link those resources at the claim they support. A distant policy in the footer is less useful than evidence attached to the decision in front of the user.

    Use JSON-LD as a map, not a substitute for evidence

    JSON-LD can identify entities, page types, authorship, dates, and relationships. It cannot manufacture authority that is absent from the visible page. Mark up facts that users can verify in the content, keep names and dates consistent, and use only types that accurately describe the page.

    A dateModified value should reflect a substantive review or change, not an automated date bump. Author and organization markup should resolve to real, maintained identities. Article, profile, offer, course, or other page-level markup should agree with the visible subject rather than describe the business more broadly than the page supports.

    Validation can tell you whether the markup is syntactically sound. It cannot tell you whether the claim is current, properly scoped, or supported. Treat structured data as an index to the evidence you have published, not as the evidence itself.

    Utility barriers decide whether visibility produces value

    Even a reachable, well-supported page can lose the click when its value ends with a short factual answer. If the page only answers the question, an AI system can summarize it; if the site completes the user’s task, the user may still need the business. That distinction is especially important for industries that historically monetized large volumes of informational visits.

    Use the following framework to separate the public answer from the value that requires an interaction:

    Industry patternCompressible answerProof that should remain publicUseful completion layer
    Coupons and dealsWhich code or offer provides a discountTerms, exclusions, applicable products, and verification contextA direct redemption path, relevant filtering, and a way to act on a valid offer
    Travel bookingWhere to go or how to plan a tripComparison assumptions, destination details, and planning constraintsCurrent availability, date-specific choices, and booking
    Job boardsRole descriptions and general career guidanceEmployer, location, requirements, posting status, and application conditionsApplication, saved searches, alerts, and employer interaction
    Legal directoriesBasic professional profiles or market comparisonsIdentity, jurisdiction, practice focus, listing method, and disclosuresFit screening and a clear contact or consultation path
    Online coursesA course overview or explanation of a skillSyllabus, prerequisites, outcomes, instructor responsibility, and policiesEnrollment, the learning environment, assessment, and completion process

    Do not try to manufacture utility by hiding the facts required to evaluate the offer. Gating a syllabus, job requirements, coupon conditions, or basic provider information may force an extra click, but it also weakens access and trust. Keep the answer layer public. Reserve the interaction layer for functionality that genuinely helps the user complete the task.

    Ask one blunt question for every important query: after the user knows the answer, what remains difficult or impossible without our site? If the honest answer is nothing, the page has an exposure problem that better formatting will not solve. You either need a real completion capability or a measurement model that values influence and brand inclusion without assuming a visit will follow.

    A citation without a downstream outcome is visibility, not yet business value. Conversely, a lower-volume page that moves someone from a complex answer into a useful tool, application, booking, or consultation may matter more than a highly summarized informational page. This is why AI search cannot be managed solely as a rankings project.

    Run the audit in dependency order

    Three connected diagnostic stations examine a reachable path, supporting evidence, and a useful destination in sequence.

    Industry averages can help you choose where to look first, but they cannot tell you why your own domain is absent. Build the diagnosis around query journeys and page templates:

    1. Define the query family. Group the questions that represent one user need, such as finding a job, comparing a course, validating an offer, or choosing a provider. Keep informational and transactional intentions separate.
    2. Map each question to a page. Identify the page that should supply the answer, the page where supporting evidence lives, and the next action you want the user to take.
    3. Grade the access gate. Mark it Pass, Mixed, or Fail based on repeated retrieval of the useful content. Do not average an unreachable page together with a strong content score.
    4. Grade the trust gate. For each consequential claim, check the answer, scope, evidence, stewardship, freshness, and consistency between visible content and structured data.
    5. Grade the utility gate. Decide whether the answer completes the need. If it does not, confirm that the next action is visible, relevant, and functional. If it does, reconsider what commercial role the page can realistically play.
    6. Fix in dependency order. Repair blocked delivery and rendering first, because no amount of editorial proof helps a page that cannot be reached. Then strengthen evidence and freshness. Finally, improve the answer-to-action path without hiding the answer.
    7. Measure the gates separately. Track retrieval success for representative URLs, mentions and citations for a stable set of queries, and the visits or completed actions that follow. A single visibility score cannot tell you which team owns the next fix.

    The pattern in the measurements tells you where to work. Strong retrieval with weak citation points toward trust. Strong citation with weak commercial outcomes points toward utility. Intermittent retrieval means the access problem is unresolved, even if the page occasionally appears in an answer.

    Start with one commercially important query family and one representative page template. If access fails, route the work to engineering and security. If trust fails, route it to editorial, subject-matter review, and structured-data owners. If utility fails, involve product and commercial strategy. Expand the program only after that first barrier has a named owner, a visible fix, and a repeatable test.

    References

  • How ChatGPT Shopping Triggers and Product Sourcing Work

    How ChatGPT Shopping Triggers and Product Sourcing Work

    If you’re trying to get a product into ChatGPT’s shopping carousel, start by identifying which part of the system is failing. A purchase-oriented prompt must first activate a shopping response. Only then does product sourcing determine which items appear.

    That gives you two separate jobs: test the prompts that open the shopping experience, then improve product visibility in the systems supplying the carousel. Treating both jobs as one leads to wasted content changes, misleading screenshots, and rankings that never translate into inclusion.

    Separate the shopping trigger from the product source

    Shopping is a relatively rare response mode. During nine months of prompt tracking, fewer than 10% of prompts produced shopping, while 79% never activated a shopping response. A query can sound commercial to you and still fail to open the shopping interface.

    Once shopping activates, a different process decides what fills the carousel. Across more than 40,000 observed carousel products, 83% could be tied to Google Shopping through shopping query fan-outs. Those figures describe different populations, so don’t multiply them or treat product sourcing share as the probability that an arbitrary prompt will show shopping.

    LayerQuestion to answerWhat to measure
    TriggerDoes this exact prompt activate shopping?Shopping response present or absent, followed by a next-day retest
    SourcingWhich product system appears to supply the carousel?Carousel overlap with Google Shopping results for related queries
    SelectionWhy does one eligible product appear instead of another?Google Shopping position, product-data consistency, and unexplained selection gaps

    This separation also explains why a conventional SEO win may not produce a carousel win. Shopping fan-outs appear to use a distinct retrieval path from standard search fan-outs. Your category page can perform well as an informational result while your products remain weak or absent in the shopping pipeline.

    Test shopping intent as a matrix, not a magic keyword

    Top-down illustration of blank prompt cards arranged in a testing grid, with several cards activating generic product symbols.

    There is no supported universal phrase that forces ChatGPT to shop. Build a prompt matrix around the purchase decisions your customers actually make. The templates below are experimental cells, not guaranteed triggers:

    • Category discovery: “best [category] for [use case]”
    • Budget constraint: “best [category] under [budget]”
    • Feature constraint: “[category] with [feature] for [audience or situation]”
    • Product comparison: “[product A] vs [product B] for [use case]”
    • Replacement search: “alternative to [product] with [constraint]”
    • Exact-product shopping: “where can I buy [brand, model, and variant]?”

    Build the first version from language in onsite searches, support questions, sales conversations, and product reviews. Preserve the customer’s wording instead of converting every query into polished SEO language. You are trying to model a real buying conversation.

    Run each prompt in a clean conversation and record the exact wording. Change one element at a time: the use case, constraint, category, product, or comparison. If you change several elements together, a new carousel won’t tell you which change mattered.

    Internal shopping fan-outs tend to be shorter and more item-specific than ordinary search fan-outs. Do not confuse those internal retrieval queries with the user’s full prompt. Copying a conversational prompt word for word into product titles is therefore a weak strategy. Make the product easy to identify for concise category, model, feature, and variant queries instead.

    When a prompt activates shopping, repeat it unchanged the following day. A previously successful trigger had an 83% chance of triggering again on the next day, which makes short-term retesting useful but does not make the behavior permanent. Prompt-level tracking is more informative than a broad label such as “laptops trigger shopping” because two superficially similar requests can behave differently.

    Use trigger testing to map demand, not to promise a user-interface outcome. You can create pages that answer a purchase question clearly, but no wording change on your site can guarantee that ChatGPT will activate its shopping experience for someone else’s prompt.

    Treat Google Shopping visibility as a distribution requirement

    Google Shopping is the practical starting point once you have confirmed that a target prompt can trigger a carousel. In the observed matches, almost 84% appeared within Google’s top 20 organic shopping positions. Only 0.16% of products were exclusive matches with Bing, making Bing-only optimization a poor first response to a missing ChatGPT product.

    The word “organic” matters. These observations do not establish that buying Google Shopping ads buys placement in ChatGPT. Paid campaign performance and organic product visibility should remain separate measurements unless you have evidence connecting them in your own results.

    Audit the distribution layer in this order:

    1. Confirm that the exact product and variant are visible in Google Shopping for the market you are testing. A neighboring model or a different retailer’s offer does not establish visibility for yours.
    2. Search with concise item and attribute combinations related to the target prompt. These are better proxies for item-specific fan-outs than the entire conversational question.
    3. Record the product’s position for each proxy query. Visibility within the top 20 is a useful diagnostic benchmark because most observed matches came from that range, but it is not a guarantee of ChatGPT inclusion.
    4. Check that the product feed and landing page agree on brand, model, variant, price, availability, and the attributes that distinguish the item. Conflicting facts make the offer harder to identify reliably.
    5. Make the product title specific enough to separate one offer from another. Include meaningful model and variant information, but do not turn the title into a list of every possible query.
    6. Recheck the live product page after feed changes. A corrected feed paired with stale or contradictory page content leaves the underlying identity problem unresolved.

    Product structured data belongs in this consistency work. Use Product schema to express the same facts that users and shopping systems see on the page. However, no direct role for JSON-LD as a ChatGPT shopping trigger was demonstrated here. Schema is machine-readable hygiene, not a switch that forces carousel inclusion.

    Rank also does not explain every selection. If a product is consistently visible for relevant Google Shopping queries but remains absent from triggered carousels, examine context around the item: whether the use case fits, whether the selected variant matches the constraint, and whether product sentiment may differ from competing choices. Sentiment is a hypothesis to test, not a proven ranking factor, so address genuine reputation or product issues rather than manufacturing reviews or mentions.

    Build monitoring that survives model changes

    Illustration of a monitoring console tracking product cards through a modular shopping pipeline while one module is replaced.

    A single carousel screenshot is evidence of one response, not durable visibility. Trigger behavior can persist from one day to the next, yet model updates have coincided with overnight resets. When the model or shopping experience changes, rebuild the baseline instead of comparing the new state with an old experiment as though nothing changed.

    Keep one row for every exact prompt and record:

    • The complete prompt, including constraints and product names.
    • The intent family, such as category discovery, comparison, replacement, or exact-product lookup.
    • Whether shopping activated.
    • Whether the same prompt activated shopping on the following day.
    • The products and retailers shown, in their displayed order.
    • Whether your product appeared and whether the correct variant was shown.
    • Your approximate Google Shopping position for the related short, item-specific queries.
    • Any conflicting price, availability, model, or variant information.
    • The model or interface state visible during the test, especially when a broad change appears across many prompts.

    Calculate each metric with the right denominator. Shopping activation rate is the share of tested prompts that produced shopping. Brand inclusion rate is the share of triggered carousels containing your product. Next-day persistence is the share of successful triggers that remained successful when retested. Keeping those rates separate tells you whether the problem is demand activation, sourcing, or selection.

    Classify the failure before changing anything

    • No shopping response: work on the trigger test. Try a more explicit buying task or a single meaningful constraint, while preserving the original prompt as your control.
    • Shopping appears, but your product is weak in Google Shopping: fix product distribution, data quality, and query-level visibility before changing editorial content.
    • Your product appears with the wrong facts or variant: reconcile the feed, retailer offer, landing page, and structured data.
    • Your product ranks strongly in relevant shopping results but remains absent: investigate selection context, product fit, and reputation as hypotheses. Do not assume rank alone guarantees inclusion.
    • Many previously stable prompts change together: mark a new baseline and rerun the full prompt set. The trigger system may have changed, so isolated page edits are unlikely to explain the pattern.

    This diagnostic order prevents the most common strategic error: editing content when the prompt never triggered shopping, or rewriting schema when the product simply lacked competitive Google Shopping visibility.

    Key takeaways

    • ChatGPT shopping visibility has at least two distinct gates: the prompt must trigger shopping, and the sourcing pipeline must select the product.
    • Shopping activated for fewer than 10% of tracked prompts, so measure exact purchase-intent prompts instead of assuming every commercial query opens a carousel.
    • A successful trigger is often repeatable the next day, but model changes can reset the pattern. Retest after any broad shift.
    • Google Shopping is the main sourcing priority supported by current observations: 83% of analyzed carousel products could be tied to it, and most matching products appeared in its top 20 organic shopping positions.
    • Neither paid Shopping ads nor Product schema has been established as a direct route into ChatGPT carousels. Keep product data consistent, but don’t treat either as a guaranteed trigger.
    • Measure trigger rate, brand inclusion, next-day persistence, and Google Shopping visibility separately. The first failing metric tells you where to work.

    Start with the purchase questions your customers already ask. Establish whether each one activates shopping, inspect the sourcing layer only after it does, and fix the first point of failure. That sequence turns ChatGPT shopping optimization from a screenshot hunt into a manageable distribution and measurement process.

    References

  • Content Structure and Technical SEO for Machine Retrieval

    Content Structure and Technical SEO for Machine Retrieval

    If a page contains the right answer but rarely becomes the answer that search engines or AI systems retrieve, topic coverage may not be the problem. The useful passage could be buried in a multi-purpose paragraph, separated from a vague heading, added only after a click, or obscured by an unnecessarily complex DOM.

    You need two conditions to hold at the same time: the answer must form a clear unit of meaning, and the rendered page must expose that unit in a structure a crawler can reach and interpret. Here is how to build and test both without turning useful prose into disconnected fragments.

    Diagnose the content layer and delivery layer separately

    Machine retrieval can fail at either of two layers. A content-layer failure makes the answer hard to isolate. A delivery-layer failure prevents the machine from reliably receiving the answer at all. Rewriting copy will not repair content that never enters the crawler’s DOM, while a rendering fix will not clarify a paragraph that tries to answer four questions at once.

    LayerTypical failureFirst check
    Content structureThe answer is scattered across sections, introduced by a generic heading, or dependent on distant context.Copy the relevant heading and passage into a blank document. Check whether they still answer the target question clearly.
    DOM structureThe heading and answer have an unclear relationship because of excessive nesting, misplaced elements, or JavaScript changes.Inspect the live DOM and confirm that the passage sits under the intended heading in a logical hierarchy.
    Content deliveryImportant text or links appear only after a click, selection, or other user action.Reload the page and check what exists before any interaction.
    Crawler accessGoogle may render the content, but another crawler that does not execute JavaScript receives an incomplete page.Compare the initial HTML, the browser DOM, and the crawler-rendered HTML.

    Start with the layer that fails. If the passage is missing after a fresh load, fix delivery first. If it is present but ambiguous outside the full page, restructure it. If both tests pass, investigate relevance, authority, and other ranking factors rather than repeatedly editing an already retrievable answer.

    Build answer-sized sections without writing fragments

    A useful content chunk is a self-contained unit centered on one idea. It is not a fixed word count, a paragraph chopped at an arbitrary length, or a collection of terse statements written to resemble search snippets. Its boundary follows a change in the reader’s question.

    Build those boundaries into the outline before drafting:

    1. Assign one job to each section. An H2 can cover a major decision or task. Use an H3 only when that task divides into a distinct question that deserves its own answer.
    2. Write the heading as a promise. Replace labels such as Overview, Details, or Implementation with language that identifies what the reader will learn. A heading such as How JavaScript-loaded content affects crawling establishes a much clearer retrieval target.
    3. Answer the heading promptly. Put the direct answer in the opening sentence or paragraph, then add the mechanism, conditions, exceptions, and next action.
    4. Keep each paragraph on one idea. Start a new paragraph when you move from definition to consequence, from consequence to procedure, or from a general rule to an exception.
    5. Use a list only when the items are genuinely parallel. Steps, criteria, checks, and alternatives belong in lists. A connected explanation still belongs in prose.

    Run the self-contained passage test

    Copy a heading and the passage immediately below it into a blank document. Do not include the title, introduction, sidebar, or preceding section. Then ask:

    • Does the heading identify the actual question or decision?
    • Does the first sentence give a direct answer rather than a transition?
    • Are important nouns named, or does the passage rely on vague references such as this, that, it, or they?
    • Does the passage contain the condition that limits the advice?
    • Can a reader act without searching the rest of the page for a missing step?

    For example, Implementation considerations followed by This can create problems is not independently useful. How interaction-dependent content affects crawling followed by Content added only after a user action may be absent from a crawler’s initial view establishes the subject, mechanism, and risk immediately.

    Preserve the reading path between chunks

    Self-contained does not mean isolated. A section should carry enough context to survive retrieval while still advancing the page’s larger argument. Keep necessary transitions, define a term before relying on it, and let supporting paragraphs deepen the answer instead of restating it.

    Do not split one coherent explanation merely to manufacture more headings. The practical case for chunking is that clear sections help people scan and give machines more precise passages to interpret. If the result feels repetitive or jerky to a reader, the boundaries are too aggressive.

    Make the content hierarchy explicit in the DOM

    An isometric document structure shows orderly nested content blocks beside a smaller cluster of tangled and disconnected elements.

    A person sees a rendered page. A crawler works with a document structure. The DOM is the browser’s in-memory tree of elements and their parent, child, and sibling relationships. Those relationships help establish which paragraph belongs to which heading and which sections belong to the main article.

    Use HTML that expresses those relationships directly:

    • Place the primary editorial content in an <article> element rather than mixing it with navigation and unrelated interface components.
    • Use heading levels to represent hierarchy, not visual size. An H3 should describe a subsection of the preceding H2.
    • Group a coherent topic in a <section> when that grouping adds meaning to the document structure.
    • Use <p> for paragraphs and real <ul> or <ol> elements for lists instead of constructing their appearance from generic containers.
    • Remove empty wrappers and repeated layout containers that make the tree deeper without adding structure.

    Semantic markup is not a substitute for relevant content, and changing a <div> to a <section> does not guarantee a ranking gain. Its value is more basic: it reduces ambiguity and makes the intended hierarchy easier to preserve across browsers, templates, crawlers, and assistive systems.

    The HTML response is only the starting point. As the browser parses that HTML into nodes, JavaScript can pause construction, add elements, replace text, or change links. The result can be a final DOM that differs materially from the original HTML.

    Keep three versions of the page distinct

    • Initial HTML: the response returned by the server before client-side scripts modify it.
    • Current browser DOM: the live tree shown in the Elements panel after scripts have run and possibly after a person has interacted with the page.
    • Crawler-rendered HTML: the version a particular crawler produced with its own rendering capabilities, timing, and interaction limits.

    These versions can match, but you should not assume they do. That distinction matters whenever a template relies on client-side rendering, delayed components, tabs, expandable panels, or JavaScript navigation.

    Test retrieval on the rendered page before publishing

    A scanning probe traces a clear path through a rendered web page and illuminates one visible, self-contained content block.

    The safest delivery rule is simple: important content should enter the DOM during the initial page load. Googlebot can parse HTML, execute JavaScript, and evaluate a rendered DOM, but it does not interact with a page as a person would. Other crawlers may not render JavaScript at all.

    This creates an important distinction for tabs and accordions. If the text is already in the DOM and the control merely changes its presentation, the content is present for inspection. If clicking the control fetches or creates the text, a non-interacting crawler may never receive it. Move essential answers into the initial render or provide an ordinary crawlable page that contains them.

    Run this release check on every important template and on any page where machine visibility matters:

    1. Choose the target answer. Write down the exact question the page should answer and identify the heading and passage intended to answer it.
    2. Reload without interacting. Confirm that the complete answer appears without a click, scroll-triggered action, selection, or form submission.
    3. Inspect the live DOM. Open browser DevTools, select Elements, and use Ctrl+F or Cmd+F to search for a distinctive phrase from the answer. Confirm that it appears once, in the intended section, under the correct heading.
    4. Inspect internal links. Important navigation should use real <a> elements with usable destinations. JavaScript event handlers that merely imitate links create avoidable crawlability risk.
    5. Check the crawler’s render. Use Google Search Console’s URL Inspection tool to examine the rendered HTML available to Google. Search that output for the same distinctive phrase, heading, and essential internal links.
    6. Use a public fallback when needed. If you do not have Search Console access, the Rich Results Test can provide a rendered-page view for investigation. Treat it as a diagnostic aid, not proof of what has already been indexed.
    7. Review DOM size. In the browser console, document.querySelectorAll('*').length provides a simple element count. Treat about 1,500 nodes as a reason to investigate unnecessary complexity, not as a universal ranking cutoff. Remove redundant wrappers and duplicated components only after confirming they are not required by the interface.

    Choose legacy pages by expected return

    You do not need to rechunk an entire archive at once. Start with high-value pages where structure is most likely to be limiting performance:

    • Pages with meaningful traffic but weak engagement, especially when readers must hunt for the promised answer.
    • Pages that already rank for relevant queries but are not being surfaced or cited for the specific answers they contain.
    • Complex explanations where headings are generic and paragraphs routinely change subject midway through.
    • JavaScript-heavy pages where important text is absent from the initial response or appears only after interaction.

    For each candidate, record whether the failure is structural, technical, or both. That prevents a content team from rewriting material that actually needs a template fix, and it keeps developers from rebuilding components when clearer headings would solve the immediate retrieval problem.

    Key takeaways for machine-retrievable content

    • A retrievable answer needs both a clear unit of meaning and reliable delivery in the rendered page.
    • Let each heading make a specific promise, then answer it promptly in a focused passage.
    • Split content when the reader’s question changes, not when a paragraph reaches an arbitrary length.
    • Use semantic HTML and a logical heading hierarchy to make relationships explicit in the DOM.
    • Put important text and links in the initial page state rather than behind required interaction.
    • Compare the initial HTML, live DOM, and crawler-rendered HTML instead of assuming that one represents all three.
    • Use DOM size as an investigation signal, not as a standalone SEO score.

    Pick one commercially important URL and test one intended answer from outline to rendered DOM. Repair the first broken handoff you find, validate the crawler-visible result, and only then scale the same audit across the rest of the template or content set.

    References

  • Boost SEO with AI Without Sacrificing Your Unique Brand Voice

    Boost SEO with AI Without Sacrificing Your Unique Brand Voice

    As someone navigating the world of SEO and content marketing, I’ve noticed a looming problem: everything is starting to sound eerily similar. It’s the same phrases, the same structure, and a robotic tone that seems to dominate.

    The web is overflowing with content that’s perfectly optimized yet fails to engage readers. That’s the real danger, not AI replacing SEOs or causing penalties. The biggest threat is losing our unique brand voice in the quest for efficiency.

    Rather than flattening our content, AI should enhance our SEO efforts. It should make us faster and more adaptable, without stripping away what makes our brand stand out. Here’s how I ensure AI doesn’t turn my brand into a faceless entity.

    To me, AI works best when it complements a clear strategy. It’s not a substitute for a marketing plan or brand direction. Just like tools such as Google Analytics or Semrush, AI is a support system, not a replacement.

    In my experience, without a deep understanding of our audience, AI merely churns out content that lacks distinction. That’s why defining who you are as a brand is crucial before turning to AI as an assistant.

    I’ve found AI shines when handling large data sets, spotting trends, or identifying content gaps. It accelerates my processes, allowing me to focus on the strategic aspects of SEO.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    However, AI falls short in areas that depend on creativity and emotional engagement. It doesn’t truly understand brand values or ethical nuances. It can mimic, but not truly connect or empathize.

    Therefore, I let AI handle data-driven tasks, while keeping the heart of my branding – its voice and soul – firmly within human hands.

    Before using AI, I clarify my brand’s tone, language, and boundaries. A well-defined brand voice ensures AI assists without diluting our identity.

    In practice, I use AI for research and framework creation, but ensure human inputs sculpt the final content. Editing and authenticity checks are critical steps I never skip.

    The key takeaway is that AI amplifies whatever brand essence you feed it—it can’t create it from scratch. Maintaining clarity and a distinct brand voice is what sets successful SEO apart.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI Marketing Governance: Scale Creative Without Losing Trust

    AI Marketing Governance: Scale Creative Without Losing Trust

    You have a campaign due, the platform wants more assets than your team can shoot, and an AI tool can produce the missing scenes in minutes. The production problem looks solved. The harder question arrives at approval: does the result still represent the product, the customer and the brand truthfully?

    You do not need to choose between using AI and being authentic. You need a governance system that distinguishes harmless assistance from consequential manipulation, preserves evidence for every claim and stops questionable work before speed turns it into scale.

    Key takeaways

    • Authenticity is not the absence of AI. It is the absence of a misleading gap between what your marketing depicts and what a reasonable customer would believe.
    • Govern the output and its likely interpretation, not the name of the tool that produced it.
    • Give every AI-assisted asset a source record, a named approver and a defined withdrawal path before publication.
    • Disclosure can explain how an asset was made, but it cannot make a false product claim, invented testimonial or nonexistent result acceptable.
    • Use the same approved facts across ads, landing pages, product feeds, public relations, structured data and answer-engine content. Contradictory claims weaken both customer trust and machine-readable credibility.

    Authenticity is a truth boundary, not a production method

    A manually produced campaign can be deceptive. An AI-assisted campaign can be accurate. The relevant distinction is not human versus machine; it is faithful representation versus manufactured belief.

    That distinction matters because AI can now support a wide range of creative operations, including background removal, lifestyle-scene generation, synthetic people and rapid asset variation. The resulting production capacity is useful, but technical permission is not the same as brand permission. Your policy has to decide what the audience may reasonably infer from the finished asset.

    Use four questions at the creative brief, review and approval stages:

    1. What will the audience think is real? Identify the likely interpretation, not merely the literal elements on screen. A person may understand that a decorative background is illustrative while assuming a product demonstration, testimonial or before-and-after image records a real event.
    2. Does the synthetic element affect the decision? Color accuracy, dimensions, included features, product condition, customer identity, quoted experience and demonstrated outcomes can all influence a purchase or trust decision. Treat those elements as material.
    3. Can the implied claim be substantiated? You should be able to trace a factual statement or visual implication to an approved product record, documented result or other internal evidence. If the evidence cannot be found, the asset is not ready.
    4. Would knowledge of the AI intervention change the audience’s judgment? If the answer is yes, redesign the asset, disclose the intervention clearly or do both. Do not hide a consequential transformation behind a broad statement that AI was used somewhere in production.

    A synthetic background behind an unchanged product may create little expectation risk. A synthetic person presented in a way that resembles a customer, employee or expert creates much more. A generated product feature that does not exist crosses the truth boundary entirely.

    Disclosure belongs after this truth test, not in place of it. A label can tell someone that an image is simulated. It cannot repair an inaccurate price, fake endorsement, invented review, altered package size or performance claim that your evidence does not support. When the underlying claim could create compliance or legal exposure, pause publication and route it to the appropriate qualified reviewer. A creative approval is not a substitute for legal review.

    Use a four-level integrity ladder for AI-assisted work

    Four ascending studio platforms show increasingly consequential forms of AI-assisted product imagery connected to a real product by a golden thread.

    A practical policy needs more than a general instruction to use AI responsibly. A four-level brand integrity hierarchy gives marketers, agencies and approvers a shared way to classify work before debating individual assets.

    Integrity levelTypical outputDefault decisionRequired control
    AssistanceResizing, cropping, cleanup, formatting or copy variation that preserves the approved meaningAllowed within documented brand rulesRetain the original and confirm that facts, qualifications and visual product attributes did not change
    AdaptationBackground replacement, contextual scenes, localization or audience variants built around a real product or approved claimAllowed with reviewRecord what was synthetic, verify the product representation and decide whether the context needs disclosure
    SynthesisSynthetic people, realistic events, demonstrations or scenes that an audience could interpret as documentary evidenceConditional and escalatedRequire an accountable approver, a documented disclosure decision, substantiation for every implication and confirmation that no real person’s identity is being misrepresented
    FabricationInvented testimonials, nonexistent features, unsupported outcomes, fake certifications or materially altered productsProhibitedDo not publish; correct the brief or obtain valid evidence for a truthful alternative

    Classify the finished output, not the software. The same generator could perform low-risk cleanup in one workflow and create an unacceptable customer simulation in another. Tool-based rules age quickly and invite loopholes; output-based rules remain understandable when platforms change their features.

    Context can also move an asset up the ladder. Replacing the background behind a product is usually adaptation. It becomes more consequential if the new setting implies that the product is certified for a particular environment, fits a space it does not fit or has a capability it does not have. Likewise, a synthetic human used as decorative illustration differs from one presented beside testimonial language that implies a genuine experience.

    Write examples from your own campaigns beside each level. Include one clearly allowed example, one conditional example and one prohibited example for the channels your team actually uses. Those precedents will resolve ordinary decisions faster than an abstract ethics statement.

    Turn the policy into a publishing gate

    Reviewers inspect a marketing image, a physical product and supporting papers as creative assets pass through a transparent publishing checkpoint.

    A governance document does not protect the brand if approval still happens in chat threads, source files disappear and nobody can identify who accepted the risk. The control has to sit inside the publishing workflow.

    Your operating policy should define:

    • Scope: the channels, teams, contractors, agencies and asset types covered by the policy.
    • Allowed uses: transformations that can proceed under standard review.
    • Conditional uses: outputs that require disclosure, specialist review or approval from a more accountable role.
    • Prohibited uses: transformations that cannot be published even when labeled as AI-generated.
    • Evidence requirements: the records that must support factual, comparative, visual and testimonial claims.
    • Disclosure rules: when a disclosure is required, where it must appear and who approves its wording and placement.
    • Responsibility: who creates, verifies, approves, publishes, monitors and withdraws an asset.
    • Exception handling: who can authorize an exception, what evidence is required and when that decision must be revisited.

    Move each asset through the same evidence path

    1. Set the truth boundary in the brief. List the product attributes, claims, qualifications and visual details that cannot change. State what may be synthesized and what the asset must not imply.
    2. Assemble an approved reference pack. Give the creator the current product images, specifications, brand terminology, claim substantiation and required qualifications. Do not make the reviewer reconstruct the ground truth after generation.
    3. Create within the assigned integrity level. Record the tool or production path, the original materials and the meaningful transformations. You do not need to archive every inconsequential interaction, but you do need enough provenance to reproduce the decision and investigate a problem.
    4. Verify the rendered output. Check the actual sizes, crops, overlays, captions, product details and landing-page destination that the audience will see. A correct master file can become misleading when a placement removes a qualification or crops out context.
    5. Approve the claim and the presentation separately. One check asks whether the underlying statement is supported. The other asks what a reasonable person will infer from the combination of words, images and placement. Passing one does not guarantee the other.
    6. Publish with a withdrawal record. Log the channels and destinations where the asset appears. If a claim changes or an error is found, the team should know where to remove or replace every affected version.

    The asset record can be compact. Capture the campaign and channel, source materials, meaningful AI transformations, claims used, disclosure decision, reviewer, approval state and publication locations. What matters is that someone other than the creator can understand why the asset was approved.

    Human review is not a control by itself. The reviewer needs access to the evidence, clear authority to stop publication and enough time to inspect the final placement. A person who can only click approve is part of the production sequence, not an effective safeguard.

    Paid media needs particular care because asset demand, automated combinations and placement variation can multiply one error quickly. Product imagery deserves a hard verification gate: visual inaccuracies can produce disapprovals or account risk in Merchant Center. Compare the rendered product with the approved reference, including packaging, included components, proportions, color and visible features. If the generated scene obscures that comparison, use a more faithful asset.

    Exceptions should be visible and temporary. Record the business reason, risk owner, supporting evidence and condition that ends the exception. The person requesting an exception should not be its sole approver. Otherwise, deadlines will quietly rewrite your policy one campaign at a time.

    Connect creative governance to SEO, AEO, GEO and PR

    Authenticity problems rarely stay inside the ad account. A generated claim can reach a landing page, product feed, public-relations pitch, social caption, FAQ and structured-data field. Each copy may look defensible in isolation while the combined public record becomes contradictory.

    Build a claim register as the shared layer beneath those channels. For each meaningful claim, record:

    • the canonical wording and any required qualification;
    • the internal evidence or approved public page that supports it;
    • the product, market and context in which it applies;
    • the accountable owner;
    • the channels where it may be used;
    • the disclosure or presentation restrictions attached to it;
    • the condition that should trigger review, correction or withdrawal; and
    • the structured-data properties, feed fields and content components that repeat it.

    This register gives your teams one approved truth rather than several channel-specific versions. Copywriters know which qualifications must survive a short format. PPC teams know which visual implications require evidence. SEO and GEO teams know which public pages should explain and substantiate the claim. Schema implementers know which statements are safe to mark up.

    Structured data should describe visible, supported content. It does not validate a claim merely because the markup is syntactically correct. If the page, product feed and JSON-LD disagree about a product attribute, fix the underlying content system instead of choosing the version most likely to attract a machine.

    Citation readiness also belongs in the governance process. Citations in AI-generated answers can contribute to credibility, and understanding how a brand appears through publicly available information can inform PR decisions. That makes the quality of your supporting pages important beyond conventional rankings.

    A citation-ready page should make the supported claim easy to identify, define its scope and keep the qualification beside it. It should also use consistent product and organization names, connect the claim to the relevant entity and avoid implying that a synthetic scene is proof. A citation can carry an unsupported statement farther; it cannot convert that statement into evidence.

    Monitor governance signals that reveal process failure rather than treating campaign performance as proof that the process worked. Useful signals include assets published without complete provenance, unresolved evidence gaps, exceptions still open, corrections caused by product mismatch, platform disapprovals associated with altered creative and the time required to withdraw a faulty claim across channels.

    Audit what is already live

    Start with a representative set of active ads, landing pages, product feeds, social assets, PR materials and structured data. Classify each AI-assisted element on the integrity ladder. Then trace every consequential claim backward to its evidence and forward to every place it appears.

    Prioritize assets with realistic people, demonstrations, testimonials, product alterations or purchase-critical details. If you cannot identify the source fact, the approving person or all publication locations, you have found a governance gap. Pause the highest-risk asset, establish the missing record and use that case to write the first concrete rule in your policy.

    For your next campaign, define the prohibited transformations in the brief, assign the integrity level before production and name the approver before generation begins. Once those decisions become routine, AI can increase creative capacity without multiplying ambiguity about what your audience is being asked to believe.

    References

  • Revamp Your Vehicle Listings with Google’s ‘Build to Order’ Feature

    Revamp Your Vehicle Listings with Google’s ‘Build to Order’ Feature

    When I discovered Google’s latest update to the Merchant Center, I was thrilled. They’ve added a ‘build to order’ option for vehicle listings, offering sellers like me a streamlined way to display customizable models that customers can factory-order.

    I immediately saw how this attribute could revolutionize my listings. It’s designed for dealers who, like myself, don’t always have every model available on the lot. This addition allows us to tag vehicles that aren’t in stock but can be tailored and ordered. It’s a game-changer!

    What needs to change. I’m aware that updating my listings involves two critical steps. First, I need to adjust my structured data by setting availability to BuildToOrder. Secondly, I must align my Merchant Center feed with the same availability code. Ensuring consistency is key to avoid listing disapprovals.

    Instruction on when to use the availability [availability] attribute in GMC 

    Why we care. This update is a breath of fresh air for us sellers. Until now, conveying a vehicle’s unavailability for immediate pickup was challenging. Now, the ‘build to order’ option clearly mirrors the operations of modern automakers, especially those like Tesla and Rivian that offer direct-to-consumer customization. It helps set clear expectations for our customers and ensures our data is pristine for Google.

    ```json
{
  "alt": "Guidelines for product availability status including in stock, out of stock, preorder, backorder, and build to order.",
  "caption": "Explore the different product availability statuses: from in stock and out of stock to preorder, backorder, and even build to order for vehicle ads.",
  "description": "This image illustrates guidelines for product availability statuses required for all products. It lists supported values businesses can use: in stock, out of stock, preorder, backorder, and build to order, with detailed descriptions for each. These values ensure that product feed information matches the website details, facilitating smooth transactions. This guide aids businesses in managing inventory visibility effectively."
}
```

    The fine print. Remember, if a vehicle is categorized as ‘build to order,’ it must have the condition attribute set to ‘new.’ If it’s listed as ‘used,’ it will be disapproved. Google regards build-to-order vehicles as newly configured, not pre-owned.

    Bottom line. For anyone like me selling customizable or factory-order vehicles, this update is a more precise way to reflect vehicle availability. However, it only works if my feed, structured data, and condition fields are in synchronization.

    I first learned about this update from Google Shopping specialist Emmanuel Flossie, who kindly explained how to implement it on his blog.

    Dig deeper. For more insights, check out the “Availability [availability]” Google Merchant Centre help doc


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Keep Modern Content Visible in Google Search

    Your page looks complete in a browser, answers the query well, and still struggles to appear or earn visits from Google. The problem may not be the writing. Modern visibility can break at several points: Google may receive the wrong rendered output, the important answer may be hard to extract, the result may lack the details people use to choose, or an AI response may satisfy the basic need without giving them a reason to click.

    You can diagnose those problems without treating SEO as one mysterious score. Separate visibility into rendering, interpretation, selection, and visitation. Then fix the layer that is actually failing.

    Treat visibility as a chain, not a single SEO score

    A page being technically available does not mean it is easy to understand. A page being understood does not mean it will be selected for a result. Selection does not guarantee a visit. Those are different outcomes, and each calls for a different test.

    Visibility layerQuestion to answerLikely failure signalWhat to inspect
    RenderingDoes Google receive the essential content?Important text, links, or page context are absent from the rendered output.The inspected URL, rendered text, primary links, and content loaded by JavaScript.
    InterpretationIs the page’s purpose and answer unambiguous?The page contains the information, but it is scattered, weakly labeled, or detached from its qualifiers.The title, main heading, opening answer, section labels, terminology, and structured-data parity.
    SelectionDoes the page expose the details needed to choose it?The content is relevant but lacks a concise overview, decision attributes, limitations, or a clear fit for the query.The direct answer, scope, prerequisites, distinguishing details, and useful summary information.
    VisitationIs there a clear reason and route to continue?The result can summarize the basic answer, but the destination promises no obvious additional value.Visible links, result-to-page continuity, deeper analysis, complete instructions, examples, and next-step utility.

    This model prevents two expensive misdiagnoses. The first is rewriting good content when the rendered page is incomplete. The second is rebuilding the front end when Google already sees the page and the real weakness is that the content does not help a searcher make a decision.

    Start every audit by writing down the failing outcome in plain language. Is the page absent? Is the wrong passage appearing? Is an important qualifier being lost? Is the page visible but not compelling enough to visit? A precise symptom gives you a testable next step.

    Prove what Google receives from your JavaScript pages

    JavaScript is not automatically an SEO barrier. Google has successfully rendered JavaScript-loaded content for years, which makes blanket warnings about client-rendered pages obsolete. It does not make every JavaScript implementation reliable.

    The distinction is simple: platform capability is not implementation verification. Google may be able to execute JavaScript while your page still returns an error, delays essential content, requires an interaction, depends on a personalized state, or renders something different from what you expected. You have to inspect your output, not infer it from Google’s general capability.

    1. Select representative URLs from every important template, especially templates that load the main answer, product details, navigation, or internal links dynamically.
    2. Open each URL as a normal visitor and record the elements that make the page useful: its main heading, central answer, important qualifiers, primary links, and any details needed to make a decision.
    3. Use URL Inspection in Google Search Console to verify what Google sees. Compare the inspected output with the visitor-facing page element by element.
    4. Classify every difference. Missing main copy is a rendering problem. Present but poorly labeled information is an interpretation problem. Missing links are a discovery and visitation problem. Do not group all of them under technical SEO.
    5. Repeat the check after changes to rendering, hydration, content APIs, consent handling, navigation, or reusable page components. A successful inspection of one template does not validate unrelated templates.

    Your comparison should focus on meaning, not visual perfection. Google does not need to see the page exactly as a person sees every animation or interface state. It does need the content and relationships that carry the answer. Confirm that headings still label the correct sections, qualifiers remain next to the claims they limit, and links retain descriptive destinations.

    Do not use a blank no-JavaScript view as automatic proof that Google sees a blank page. The old recommendation to disable JavaScript as a proxy for search visibility was removed after becoming outdated. A no-JavaScript test can still expose resilience problems, but it is not an accurate substitute for inspecting Google’s rendered result.

    Keep the essential answer portable

    Google’s rendering strength should not become an excuse to make every crawler reproduce your entire application before it can understand a page. Some emerging AI search systems may not process JavaScript as effectively. Where your architecture allows it, place the page’s purpose, central answer, meaningful headings, and essential links in the initial HTML. Let JavaScript enhance the experience rather than supply every piece of meaning.

    This is a portability decision as much as an SEO decision. A stable semantic layer can serve conventional search crawlers, AI retrieval systems, browser tools, and visitors on constrained devices. It also gives your team a simpler baseline to test.

    Do not maintain a separate hidden answer for machines. That creates a drift problem: the visible page says one thing while the machine-facing version says another. Render the same core facts for everyone, then add interactive controls, personalization, and presentation around them.

    Keep accessibility and search rendering as separate checks

    Google’s removal of old accessibility language from its JavaScript SEO material does not make accessibility optional. It means the earlier warning was no longer a useful description of Google’s rendering capability, and modern assistive technologies can generally process JavaScript. Your implementation can still create inaccessible controls, confusing focus behavior, or content that is difficult to navigate.

    Keep two acceptance criteria in your release process: Google must receive the essential rendered meaning, and people using assistive technology must be able to operate and understand the interface. Passing one check does not prove the other.

    Shape the page into a decision-ready answer

    Rendering gets your content into consideration. It does not make the content a good candidate for an AI-generated result. The page must expose an answer that can be understood without reconstructing it from scattered paragraphs, while preserving the context that keeps the answer accurate.

    Google’s AI Mode recipe experience illustrates the distinction. Searchers can open individual dishes, follow links to recipe creators, read a quick overview, and see details such as cook time. Those details help people decide which option to explore.

    That does not make cook time a universal ranking factor, and it does not mean every content type should imitate a recipe card. The transferable principle is that selection requires decision information. Your page should state not only what the answer is, but also when it applies, what it requires, where its limits are, and what makes the destination useful.

    Build a self-contained answer block

    Near the beginning of the page, give the reader a compact resolution to the primary question. Include the condition that would materially change the answer. Then expose the attributes a person would use to choose whether the page fits their situation.

    • Direct resolution: State the answer before the long explanation. Do not make the reader cross an introductory essay to discover your position.
    • Scope: Name the platform, content type, implementation pattern, or audience for which the answer applies.
    • Decision attributes: Surface prerequisites, compatibility, effort, constraints, or other details that determine fit.
    • Qualifiers: Keep exceptions beside the claim they modify. A distant caveat is easy for both readers and automated systems to miss.
    • Continuation: Indicate what the full page adds, such as the complete workflow, diagnostic branches, worked examples, or implementation details.

    For a page about JavaScript SEO, for example, the useful opening is not merely that Google supports JavaScript. The decision-ready answer is that Google can render it, each implementation still needs inspection, and essential meaning should remain portable when other retrieval systems may not execute the page as well. The additional conditions turn a technically true statement into actionable guidance.

    Apply the same discipline to headings. A heading such as Benefits carries little meaning outside its surrounding page. A heading such as When client rendering creates a visibility risk identifies the question the section resolves. Descriptive headings help the visitor scan and give extracted passages useful context.

    Use JSON-LD as a faithful machine-readable echo

    If you publish JSON-LD, make it agree with the visible page. Names, descriptions, relationships, attributes, and other claims should not conflict with what a person can read. Structured data should clarify an already coherent page, not compensate for missing content or introduce a more attractive machine-only version.

    Include schema parity in editorial QA. When a visible fact changes, identify every place that repeats it: body copy, summary modules, metadata, JSON-LD, and reusable components. A technically valid graph can still be unhelpful if it describes an earlier version of the page.

    Preserve a reason to visit after the basic answer is visible

    AI visibility and referral traffic are related, but they are not the same outcome. An AI result may use your information while resolving the immediate question inside the search experience. Even when Google adds a visible link, the link is only an opportunity. The searcher still needs a reason to follow it.

    The wrong response is to hide the central answer. If the page withholds the useful part, it becomes a weak candidate for selection and a frustrating destination. Instead, divide value by depth.

    • In the extractable layer, provide the direct answer, its scope, critical qualifiers, and the details needed to judge relevance.
    • On the destination page, continue with the complete method, edge cases, evidence you can substantiate, examples, troubleshooting paths, and tools that help the visitor act.
    • At the transition, make the next value explicit. A generic Learn more link hides the payoff; a descriptive destination tells the reader what the click will complete.

    This is especially important when a search result offers a quick overview. The overview can establish relevance, but the destination should resolve the work that remains. A recipe result can help someone choose a dish, while the creator’s page can still provide the full method and context needed to make it. Your content should have an equally clear division between selection value and completion value.

    Check continuity from result to page. The linked destination should open on the content promised by the result, use consistent terminology, and reveal the next useful step quickly. Sending someone from a specific AI citation to a generic category page wastes the moment of intent.

    Internal links deserve the same treatment. If a section introduces a decision that another page resolves, link with words that name that decision. This creates a route through the subject for readers and makes the relationship between pages explicit.

    Diagnose the failing layer before you rewrite

    A modern visibility audit should end with a classified defect, not a list of generic SEO recommendations. Use the observed symptom to choose the work.

    • Essential content is missing from Google’s inspected output: Fix rendering, delivery, or state dependencies before changing the prose. Confirm that the affected template works after the change.
    • The content renders, but the purpose is difficult to state: Tighten the title, main heading, opening answer, and section labels. Remove competing introductions that delay the primary resolution.
    • The answer is accurate but loses its conditions when extracted: Move the qualifier beside the claim, use a self-contained sentence, and keep the same qualification in summaries and structured data.
    • The page answers the topic but does not help a person choose: Add the relevant prerequisites, constraints, compatibility information, or other decision attributes supported by the page.
    • The basic answer is visible but visits remain weak: Clarify what the destination adds. Strengthen the result-to-page promise rather than repeating the same summary at greater length.
    • Google handles the page but other AI systems struggle: reduce dependence on client execution for the essential semantic layer while keeping richer interactions available to visitors.

    Audit at the template level as well as the URL level. If every page using a component loses its main link during rendering, editing individual pages will only conceal the shared defect. If only one page has an unclear answer, a site-wide rebuild is unnecessary.

    Keep a short record for each tested URL: the intended query, the essential visible answer, whether that answer appears in Google’s inspected output, the decision details present, the continuation value, and the defect class. That record gives developers, editors, and schema owners the same definition of done.

    Key takeaways

    • JavaScript is not inherently invisible to Google, but your own rendered output still needs verification in Search Console.
    • A page can pass rendering and still fail because its answer, scope, or qualifiers are hard to extract.
    • AI-oriented content needs decision details, not just a concise summary.
    • JSON-LD should mirror visible, current content rather than act as a substitute for it.
    • A link in an AI result does not guarantee a visit; the destination must promise useful continuation beyond the overview.
    • Classify the failure as rendering, interpretation, selection, or visitation before assigning the fix.

    Begin with one commercially important template. Inspect what Google receives, rewrite its opening as a self-contained answer, verify visible and structured-data parity, and make the next-step value unmistakable. Once that pattern passes all four layers, apply it to the rest of the site.

    References

  • Google Ads Data Operations: A Practical Control System

    Google Ads Data Operations: A Practical Control System

    Your dashboard is off, an audience job failed, or traffic climbed without producing more revenue. Those look like separate Google Ads problems. Operationally, they share one risk: a bad input can trigger a costly decision before anyone proves what changed.

    You need a control system that separates collection, transport, reporting, audience activation, and campaign action. Once those layers are visible, you can pause only the affected decisions, repair the right component, and keep trustworthy signals flowing into automated bidding.

    Key takeaways

    • Do not change bids or budgets until you have classified an unexpected metric movement as a real business change, a collection failure, a transport problem, a reporting delay, or an activation issue.
    • Report availability is not the same as report freshness. Record the last complete timestamp, affected dimensions, and last-known-good comparison before acting.
    • Build a small set of durable first-party audiences around meaningful customer states. Excessive segmentation reduces usable data and creates more failure points.
    • Validate the Customer Match upload path itself. Successful campaign-management requests do not prove that an inactive developer token can still upload Customer Match data.
    • Treat invalid traffic as both a budget problem and a data-integrity problem. Audit the riskiest inventory first, then judge controls by downstream business outcomes.

    Diagnose reporting before you optimize the campaign

    A dashboard number is the endpoint of a pipeline, not an independent source of truth. A conversion can occur correctly while its report is delayed. A report can refresh normally while the conversion tag has stopped firing. A campaign can also deteriorate for real while every technical component is healthy. Those cases can look identical in the interface for a while, but they demand different responses.

    Use an explicit data map so every anomaly has somewhere to go:

    LayerQuestion to answerEvidence to inspect
    Business outcomeDid leads, orders, qualified opportunities, or revenue actually change?Order system, CRM, call records, payment records, and their timestamps
    CollectionDid the expected website or app event occur and carry the required data?Site or app logs, tag diagnostics, analytics events, and test conversions
    TransportDid an upload, import, export, or scheduled integration complete?Job status, response errors, processed record counts, and last successful run
    Processing and reportingIs the interface showing complete, current, and consistently defined data?Freshness timestamps, platform status, report filters, dimensions, and an independent reporting view
    Activation and decisionDid the audience or conversion signal reach the intended campaign, and is a campaign change justified?Audience state, campaign configuration, exclusions, bidding inputs, and account change history

    A Google Ad Manager incident illustrates the distinction. Ad Manager is the publisher product, not the Google Ads buying interface, yet the operational lesson transfers: users could log in while the newest data was unavailable and current reports disagreed with the legacy reporting tool. Platform access therefore proved neither freshness nor consistency.

    Use the same triage sequence every time

    1. Define the anomaly. Write down the metric, affected campaigns or properties, first abnormal timestamp, last-known-good timestamp, reporting timezone, and comparison period. “Conversions are down” is too vague to investigate.
    2. Protect the account from premature action. Pause major bid, budget, targeting, and exclusion changes that depend on the disputed metric. Do not pause healthy campaigns merely because one report is late.
    3. Test freshness before magnitude. Identify the latest complete period. A partially processed period should not be compared with a completed one as if both were final.
    4. Reconcile definitions. Confirm that filters, conversion actions, campaign scope, attribution settings, dimensions, and time boundaries match. Two correctly calculated reports can disagree because they answer different questions.
    5. Trace the outcome upstream. Check whether orders, leads, calls, or qualified opportunities changed in the underlying business system. This separates a reporting fault from a plausible performance event.
    6. Inspect collection and transport. Check event flow, import jobs, API errors, record counts, and the last successful run. A successful login or unrelated API request is not proof that the relevant pipeline worked.
    7. Check the platform status and preserve evidence. Save the affected report configuration, timestamps, screenshots, exports, and error responses. If the issue is not listed, give support a reproducible case rather than a general complaint.
    8. Release decisions selectively. Resume only the actions supported by verified data. Keep decisions tied to the damaged layer on hold until freshness and consistency return.

    Do not force two reports to agree by changing campaign settings. If internal sales remain stable while the newest platform data is incomplete, wait for processing and reconcile later. If the conversion event disappears while sales continue, repair collection. If both business outcomes and verified reporting decline, a campaign or market response becomes reasonable. Classification comes before optimization.

    Turn audience lists into controlled data products

    First-party audiences are not folders you fill once and revisit when someone wants a retargeting campaign. They are production inputs. Their definitions, refresh jobs, permissions, exclusions, and destinations affect how Google interprets your customers.

    Google Ads groups these inputs under “Your data segments.” The practical inputs are website visitors, app users, Customer Match records, and people who engaged with content on Google-owned properties. Website audiences can originate through tagging or analytics; app audiences can flow through Firebase or another analytics setup; Customer Match begins with proprietary customer records; and content engagement can include YouTube viewers or Google Engaged Audiences.

    The first mistake is treating every available behavior as a new audience. A list defined by an incidental detail, such as a visit on a particular weekday, rarely expresses a durable business state. It also divides the available signal into smaller pools, multiplies refresh and QA work, and makes exclusions harder to reason about.

    Start with states that would change a real marketing decision:

    • Known customers: people who completed the outcome your bidding system is meant to find.
    • Qualified prospects: people who reached a meaningful qualification point but have not become customers.
    • High-intent non-converters: people who reached a product, cart, application, booking, or equivalent decision stage without completing it.
    • Broader engaged visitors or users: people with a valid interaction who have not yet shown high intent.
    • Suppression groups: existing customers, employees, test records, disqualified leads, or other groups that should not receive a particular message.

    Keep the states separate only when you will change targeting, creative, bidding interpretation, or exclusion logic because of the distinction. If two lists always receive the same treatment, their separation is probably operational overhead rather than strategy.

    Give every audience a contract

    An audience contract is a short record that lets another operator understand and verify the list without reverse-engineering it. Store these fields in your operating documentation:

    • A plain-language business definition and the decision the audience supports
    • The system of record, technical owner, and business owner
    • Inclusion logic, exclusion logic, and how conflicting states are resolved
    • The refresh trigger or schedule and the last successful refresh
    • Expected record-count behavior, with an alert for an empty or unexpectedly changing result
    • The Google Ads destination and the intended role: targeting, observation, exclusion, or audience signal
    • The campaigns allowed to consume the audience
    • The permissions governing the data and the condition under which the audience must be retired

    Only send customer records your organization is authorized to use for advertising. A secure API can protect transport, but it cannot correct an invalid permission model or a list definition that includes the wrong people.

    The campaign role matters because the same audience can behave differently across campaign types. Search, Shopping, and Display can use data segments for targeting, observation, or exclusion. Performance Max and App campaigns can consume them as audience signals and can also use supported exclusions. A signal is not a promise that delivery will remain inside the list, so document it differently from a hard restriction. Demand Gen can be a useful activation surface when the audience and message support visual storytelling.

    Direct retargeting is not the only reason to maintain these inputs. Clean customer data can also help Smart Bidding and Optimized Targeting recognize the characteristics of real buyers. That makes list quality more important, not less. A stale customer list or an audience mixing customers with low-quality leads teaches a less precise lesson.

    Review audience operations as a lifecycle: create, validate, activate, monitor, update, and retire. Watch both directions. An unexpected collapse can indicate a broken source or upload; an unexplained surge can indicate relaxed logic, duplicated records, or a source-system change. Neither should silently become a new bidding input.

    Make Customer Match transport a supported system

    Anonymous geometric customer records move through a secure validation pipeline into segmented audience containers, with one malformed batch diverted to quarantine.

    A well-designed customer audience can still fail at the transport layer. This is especially easy to miss when the same developer token continues to perform unrelated campaign-management work.

    Google’s announced cutoff for inactive Customer Match upload tokens was April 1, 2026. Under the announced rule, a developer token with no Customer Match upload through the Google Ads API during the previous 180 days would lose that upload capability. Attempts from an affected token would fail, while other Google Ads API campaign-management functions would continue.

    The important word is “upload.” General API activity does not satisfy a condition defined around Customer Match uploads. A green campaign update, reporting request, or authentication check therefore cannot validate this path.

    Run a focused continuity audit:

    1. Inventory every producer. Record the application, developer token, source system, account destination, audience destination, execution schedule, credential owner, and operational owner for each Customer Match job.
    2. Find the last successful upload. Use job logs and API responses, not a developer’s memory or the modification date of a script. Distinguish a completed Customer Match upload from other successful requests made with the same token.
    3. Test the actual path. Use a controlled, authorized dataset and destination. Capture the response, available processed or rejected counts, resulting audience state, and time of the test. Do not expose live customer records merely to diagnose connectivity.
    4. Classify failures precisely. Separate authentication, token eligibility, permissions, malformed data, source extraction, transport, and destination errors. “The API failed” is not an actionable incident category.
    5. Build the Data Manager path. Google directed affected upload operations toward the Data Manager API, positioning it as a unified ingestion system with stronger security, confidential matching, and improved encryption. Validate this path against a controlled destination before changing the production schedule.
    6. Cut over with observability. Alert on failed runs, empty inputs, abnormal count changes, missing destination updates, and repeated retries. Preserve logs and the prior configuration until the replacement has completed its expected operating cycle.
    7. Update ownership documentation. Record where credentials live, who approves source changes, who responds to failures, and how downstream campaign owners are notified when audience freshness is uncertain.

    Do not manufacture meaningless uploads to simulate activity. That leaves the underlying dependency in place and can contaminate a real audience. The durable response is to verify eligibility, move the workflow where required, and make upload success visible to someone who can act.

    Use invalid traffic checks to protect the learning loop

    A transparent verification mesh diverts clusters of repetitive event signals while varied trusted signals continue toward an automated learning system.

    Invalid traffic costs you twice. It can consume spend, and it can distort the observations used to evaluate placements, audiences, and automation. A click with no genuine consumer intent is therefore not just a media-quality issue. It is a measurement contaminant.

    The mechanisms vary. Botnets can generate automated interactions through compromised devices. Click farms manufacture engagement through people or scripts. Malware and ad injection can redirect users or insert unauthorized ads. Pixel stuffing and ad stacking can register delivery even when an ad was not meaningfully visible.

    Do not turn a broad industry estimate into an account threshold. Fraud Blocker estimated an average Google Ads invalid-click rate of 11.4% and reported a trend from 5.9% in 2010 to 12.3% in 2024. That is vendor-supplied analysis, not a universal baseline, a guaranteed refund rate, or proof that any particular account has the same exposure.

    Audit inventory in risk order

    Use campaign type as an investigation priority, not a verdict. Video Partners warrant early scrutiny because delivery extends beyond YouTube into third-party inventory. Display needs placement-level review because publisher quality varies. Shopping and Demand Gen can attract automated price-checking or other non-buying activity that is not always malicious but can still weaken the signal. Performance Max spreads delivery across inventory while offering less direct source visibility. Search is generally the lower-risk starting point, but even a small amount of invalid activity can matter when clicks are expensive.

    Build an exception view around patterns you can investigate:

    • Placements or apps with substantial click activity but little or no downstream business activity
    • Geographic traffic that conflicts with the market you can actually serve
    • Activity concentrated outside the times when legitimate demand normally occurs
    • Click growth that is not accompanied by comparable sessions, qualified actions, or business outcomes in internal systems
    • Campaign changes that suddenly expanded networks, locations, keyword reach, or automated inventory
    • Differences between internally logged activity, Google-reported activity, and invalid-traffic credits or refunds

    None of those patterns proves fraud by itself. A placement can fail because the audience-message fit is poor. Overnight demand can be legitimate. Analytics can undercount because collection is broken. Investigate across the data layers before labeling traffic malicious.

    When the evidence supports containment, tighten the specific exposure rather than rebuilding the whole account at once:

    • Use physical-presence location targeting when interest-based geographic expansion admits traffic you cannot serve.
    • Test focused, high-intent terms against broad generic reach where Search quality is uncertain.
    • Isolate Google Search Network traffic from Search Partners or Display exposure so performance can be evaluated separately.
    • Maintain negative-keyword, placement, and app exclusions based on documented patterns.
    • Align ad schedules with legitimate operating and demand periods when off-hour activity is demonstrably low quality.
    • Review placement data and Google’s detected-invalid-traffic adjustments, while also reconciling clicks with your own session and outcome records.

    These controls trade reach for confidence. Treat them as measured containment, not permanent doctrine. Annotate the change, preserve a comparable baseline, and evaluate qualified leads, orders, revenue, or another real outcome. Click-through rate alone cannot tell you whether the traffic became more valuable.

    Give this system an owner and a cadence appropriate to your spend and sales cycle. Alert immediately when a production upload fails. Review freshness, audience-count behavior, reporting exceptions, and suspicious placements on a schedule. Require a change record for consequential bids, budgets, audience logic, exclusions, and network settings.

    Start by mapping your data layers on one page. Assign an owner to each layer, record its last-known-good evidence, and specify which campaign decisions must stop when it fails. Then validate the Customer Match path directly. The next anomaly will arrive as a bounded operational incident, not an invitation to guess with your budget.

    References