Your Google Ads campaign has almost stopped serving, but billing, policy status, conversion tracking, negative keywords, locations, devices, and schedules all look clean. This is where the interface can send you in the wrong direction: a visible setting may be active without carrying the authority you assume it has.
Before you raise the budget, remove targeting, or abandon automation, identify what the setting actually promises. Some controls block delivery. Others affect eligibility, establish a bidding constraint, or merely give the system context. The useful question isn’t just, “Is this control enabled?” It is, “What happens when this control conflicts with the auction?”
The control hierarchy: five settings, five different promises
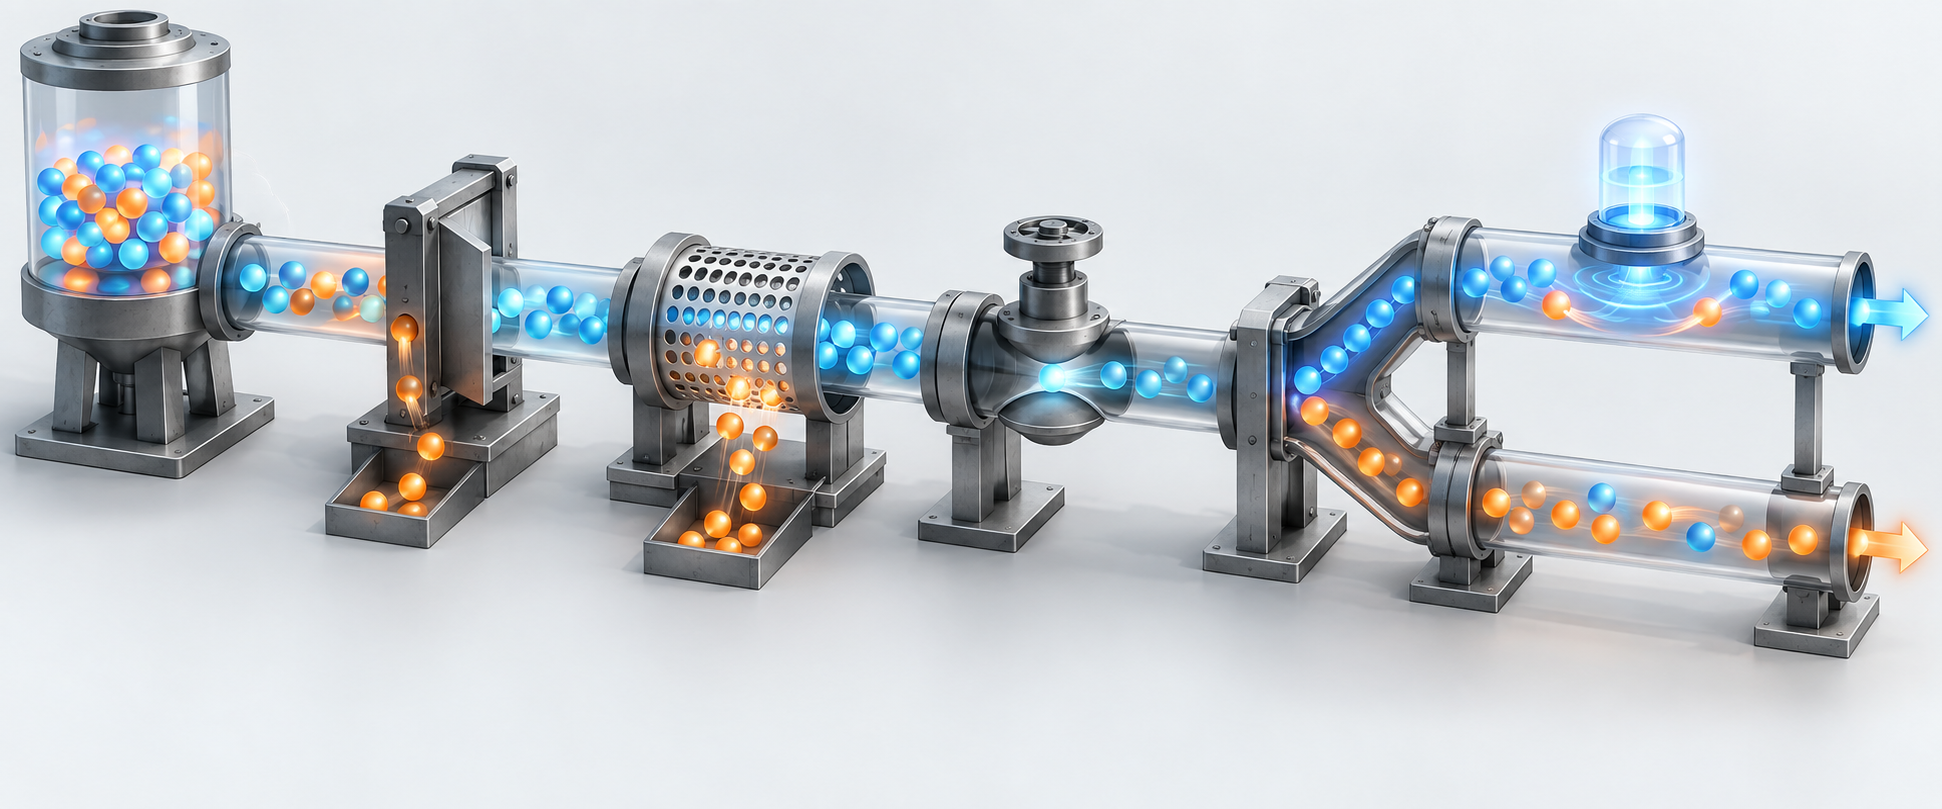
A reliable control is not necessarily one that produces the outcome you want. It is one whose behavior you understand well enough to predict what will happen when market conditions, automation, and your instructions disagree.
| Control class | Google Ads examples | What it can reliably do | What it cannot promise |
|---|---|---|---|
| Hard restrictions | Negative keywords, brand exclusions, URL exclusions | Constrain whether specified traffic or assets can serve | A negative keyword does not block every query related to the same concept |
| Opt-outs | AI Max toggle and ad-group-level search-term matching controls | Disable a defined feature or behavior at a particular scope | A complete return to an older campaign state, especially when related controls or migrated features behave differently |
| Priority rules | Priority for an identical, eligible exact-match keyword | Put one eligible option ahead of another in the selection process | Eligibility, impressions, clicks, or traffic volume |
| Targets | Target CPA and target ROAS | Constrain the range in which automated bidding tries to operate | The requested conversion volume at any market price |
| Contextual signals | Performance Max search themes and the keywords, creative, and URLs used by AI Max | Inform expansion and help automation interpret your intent | A deterministic boundary around every query the campaign can enter |
The details matter most at the edges. Negative keywords, brand exclusions, and URL exclusions are treated as firm boundaries, but a negative keyword is still a precise instruction about the text you entered. Casing and misspellings are handled, while synonyms and singular or plural forms are not automatically covered. If you add job as a negative, do not assume you have also excluded jobs, career, and employment.
At the other end of the hierarchy, search themes and other contextual signals help the system interpret a campaign. They are useful for direction, but they should not carry a must-not-serve requirement. If a query category would create unacceptable cost or brand exposure, use an applicable exclusion control and verify its coverage instead of relying on a theme or creative cue.
Matching guidelines in AI Brief do not fit neatly into either category. They are presented as guidance and boundaries with previews, but Google has not published a deterministic guarantee or an enforcement rate. Treat them as something to test in live query evidence, not as a substitute for a confirmed exclusion.
When delivery collapses, diagnose authority before changing bids
A campaign that has gone quiet invites broad, hurried edits. That makes the underlying problem harder to isolate and can release more spend than you intended. Use a fixed diagnostic sequence instead.
- Mark the beginning of the decline. Identify when impressions, clicks, and conversions changed. You need a date to compare with configuration changes; a current-state screenshot cannot tell you what created the current state.
- Check basic eligibility. Review billing, policy status, location and device targeting, schedules, negative conflicts, conversion configuration, and available budget. “Limited by budget” is an eligibility condition, so even a valid priority rule may not operate as you expect when the campaign is constrained.
- Use the ad preview result as a symptom. A not-serving result confirms that the campaign is not entering or winning that opportunity. It does not, by itself, identify the responsible control.
- Expand change history to the campaign’s full lifetime. A decisive bid-strategy or target change may sit outside a 30-day or 12-month view. A full-lifetime review exposed a consequential change that shorter windows had hidden.
- Classify each relevant setting. Label it as a hard restriction, opt-out, priority rule, target, or contextual signal. Then write down the narrow promise it actually makes.
- Compare bidding targets with attainable economics. Examine whether recent CPA, CPC, competition, and conversion volume still overlap the target. A target based on an older market can be reasonable when it is chosen and still become restrictive later.
- Run one reversible test. Change the suspected constraint without simultaneously rewriting keywords, ads, locations, and budgets. Loosening or removing a bid target can unlock spend quickly, so confirm the campaign budget and conversion measurement before publishing the test.
This sequence separates three very different failures: the campaign is ineligible, the campaign is eligible but constrained by its target, or the campaign is serving outside the conceptual boundary you thought a matching control created. Each failure needs a different fix.
A target CPA is a traffic constraint, not a cost ceiling
Target CPA is easy to misread because its name sounds like a preferred result. In practice, the target constrains the auctions automated bidding can justify. When the available market no longer overlaps that target, the system cannot simply pay substantially more for every desirable prospect and preserve the target at the same time. It can reduce participation instead.
Consider a referral-software campaign that recorded only six impressions during a month in which it had effectively gone dark. Its account showed a $200 target CPA and a $182 actual CPA, which looked superficially healthy. The full change history showed that Maximize Conversions with a $200 target CPA had been introduced in October 2024. That target was about 12% higher than the CPA achieved in the previous year, so it was not an obviously aggressive choice when it was set.
The market had moved. Competition had more than doubled, CPC had risen 51.96%, and CPA had moved from $138.53 to $316.76. The $200 target had become roughly 37% lower than the cost the campaign was encountering per lead. The automation preserved the constraint by finding very little traffic it considered compatible with that constraint.
This is why an actual CPA below target does not automatically prove that a target is healthy. Ask how much delivery produced the number. An apparently efficient CPA based on negligible impressions or conversion volume can coexist with a campaign that is economically unable to scale.
- Check volume before celebrating efficiency. Read actual CPA beside impressions, clicks, and conversions, not as an isolated score.
- Compare the target with recent conditions. The CPA that justified a decision a year ago may describe a market that no longer exists.
- Look for movement in input costs. A major CPC increase can make the old acquisition target unattainable even when the landing page and conversion setup have not changed.
- Align the date of the decline with change history. A target may begin as attainable and become restrictive gradually, so the visible delivery collapse can occur well after the original edit.
If the evidence points to an unrealistic target, test a less restrictive target as a controlled bidding change. Do not simultaneously increase the budget and broaden matching. A higher target can admit more expensive auctions, while a larger budget gives the campaign more money to enter them; changing both prevents you from knowing which lever changed performance and increases the financial exposure of the test.
Match types and opt-outs need boundary tests
Exact match should be read as a priority and relevance mechanism, not as a literal-text firewall. Its boundaries changed in stages: close variants became optional in 2012, mandatory for exact and phrase match in 2014, and broader through later changes involving word order, implied terms, and paraphrases. Same-meaning matching reached phrase match and broad match modifier in 2019. Phrase match absorbed broad match modifier behavior in February 2021, and advertisers could no longer create new broad match modifier keywords by late July 2021.
An identical, eligible exact-match keyword can receive first priority, but that is a queue position rather than a delivery guarantee. The keyword must still be eligible, the campaign must have budget, inventory must exist, and exceptions for advanced search experiences may apply. “We have the exact keyword” therefore does not answer “Why did we receive no impression?”
Use a separate boundary test for each kind of control:
- For negative keywords, test the strings you actually excluded. Add important synonyms and singular or plural forms separately when the concept must be blocked. Do not rely on positive-keyword expansion rules to describe negative-keyword behavior.
- Inspect long searches carefully. On a search longer than 16 words, a negative term appearing after the sixteenth word will not block the ad. A rare long query can therefore cross a boundary without the negative keyword being ignored or malfunctioning.
- For exact match, inspect eligibility and the matched search term. Determine whether the exact keyword was eligible to receive priority before treating the outcome as a matching failure.
- For AI Max opt-outs, verify related behavior after the toggle changes. Some controls housed within the feature stop applying when it is disabled. The migration of Dynamic Search Ads into AI Max also means that switching AI Max off should not be assumed to recreate every aspect of the older campaign state.
- For contextual signals, evaluate direction rather than compliance. Search themes, creative, keywords, and URLs can steer expansion. Confirm the result in search-term evidence instead of treating those inputs as enforceable exclusions.
The practical distinction is simple: verify hard boundaries against prohibited traffic, evaluate priority rules only after confirming eligibility, judge targets by both cost and volume, and assess contextual signals by the traffic they influence. Applying one test to all four produces false confidence.
Key takeaways: build a control-reliability routine
Keep a small control register for each material campaign. It does not need another dashboard. A shared account note or worksheet is enough if it records the setting, its scope, its authority class, the expected effect, the evidence used to verify it, the owner, and the safe rollback.
- Start with authority, not the label. Decide whether a setting blocks, opts out, prioritizes, constrains, or guides before predicting its effect.
- Use full-lifetime change history when delivery has no visible cause. The current configuration may be the accumulated effect of a decision hidden beyond the default date range.
- Judge bid targets against recent attainable economics and meaningful volume. An actual CPA below target means little when the campaign barely enters auctions.
- Test query controls at their real boundaries. Check variants, scope, eligibility, and long-query behavior rather than assuming that a control covers the surrounding concept.
- Change one consequential lever at a time. Record the expected effect and rollback first, and keep the budget within an amount you are prepared to expose while the test runs.
Open the weakest-delivering campaign first. Expand its change history, classify its active controls, and choose the smallest reversible test that can distinguish an eligibility problem from an unrealistic target or a misunderstood matching boundary. Once you can state exactly what each control is allowed to decide, the account becomes much easier to manage without guessing.
References

Leave a Reply