Tag: Automated Advertising

  • Google Ad Creative and Targeting Updates: An Action Plan

    Google Ad Creative and Targeting Updates: An Action Plan

    If your Demand Gen video was approved down to the last line break, you now have a new reason to inspect the campaign settings: Google may place additional text over that finished creative. If your team manages Display & Video 360 through bulk files, you also have a new schema to accommodate before older workflows reach a hard support deadline.

    These changes affect different products, but they create the same operational problem. The ad that gets served or the audience that gets targeted may no longer be defined only by the asset and configuration your team originally approved. You need an audit trail that covers Google’s transformations as well as your own inputs.

    Know which control surface changed

    There are two separate updates to manage. In Google Ads, Demand Gen campaigns can use existing text assets to generate messages that appear over video. In Display & Video 360, Structured Data Files v11 expand bulk targeting controls and change parts of the file structure used by automated workflows.

    Control layerWhat changedMain riskFirst action
    Demand Gen creativeAutomatic text overlays can be generated from existing text assets.Added copy can obscure the composition, repeat burned-in text, or conflict with the approved message.Inspect the Overlay on videos setting and the text assets available to the campaign.
    DV360 audience targetingSDF v11 supports lookalike audience inclusion and exclusion across eligible ad groups.A blanket bulk-edit rule can apply the wrong audience logic or mishandle an exception.Add explicit inclusion, exclusion, and exception checks to the SDF workflow.
    DV360 location targetingBusiness Chain proximity targeting is available in the line item file format.A bulk upload can extend location targeting to unintended line items.Validate the business-chain configuration at line-item level before scaling it.
    DV360 file automationVendor fields and selected YouTube campaign structures have changed.Existing templates, parsers, and round-trip assumptions can fail or silently omit information.Diff a clean v11 file against the production schema and test a limited batch.

    Keep ownership clear. Creative teams should decide whether a video can tolerate generated copy. Media teams should control the campaign setting. Marketing operations or engineering should own the SDF schema migration. One person should reconcile those decisions before launch; otherwise each team can complete its own task correctly while the final campaign is still wrong.

    Audit Demand Gen overlays before the next launch
    A reviewer inspects a vertical video preview partly covered by blank translucent interface overlays before launch.

    The Overlay on videos control sits under Asset optimization with Shorter videos and Resized videos. It has been observed as enabled by default, so silence is a decision: if nobody checks the setting, Google may add text to a video that your team considered complete.

    Run a campaign-by-campaign creative check

    1. Open each Demand Gen campaign and record the current state of Overlay on videos, Shorter videos, and Resized videos. Do not treat the account-level expectation as proof of the campaign-level state.
    2. Review the beginning, middle, and end of every video. Mark areas occupied by burned-in copy, product details, logos, calls to action, prices, and required disclosures.
    3. Review the existing text assets Google can use as overlay inputs. Remove or revise stale promotions, weak generic claims, mismatched calls to action, and language that does not belong in the campaign’s market.
    4. Decide whether the video is suitable for an overlay test, requires a redesigned overlay-safe version, or should remain unchanged.
    5. Record the decision with the campaign identifier, approver, setting state, date, and reason. This turns an invisible optimization toggle into an accountable creative choice.

    A video with open visual space, little burned-in copy, and tightly governed text assets may be a reasonable candidate for a controlled overlay test. A dense product demonstration, carefully typeset brand film, localized creative, or video with disclosures is a poor candidate for unattended text placement. The relevant question is not whether overlays are useful in general. It is whether this particular composition and message can accept another layer without changing their meaning.

    Do not confuse a generated overlay with closed captioning. The overlay draws from advertising text assets and can reinforce a benefit, promotion, or call to action; it does not necessarily reproduce the spoken content. If the video must be understandable without sound, assess captions and visual storytelling separately.

    Use the narrowest control that matches your decision

    You can turn off Overlay on videos by itself or use Disable all for the available video optimization features. Use the individual switch when your video can tolerate shortening or resizing but not added copy. Use Disable all only when the approved composition must not be altered by any of the listed optimizations.

    Review the three settings independently. Turning off the overlay does not express a decision about shorter or resized versions. Equally, accepting alternate dimensions does not mean text can safely cover any part of the frame. Your approval record should state which transformations are allowed rather than reducing the decision to a vague yes or no on automation.

    Account for the AI-edit label

    When these optimization features modify an image or video, the served ad is labeled as created or edited with AI in the European Union, India, and New York state. That does not determine whether the creative is acceptable for your brand, but it does belong in the approval process. Tell brand, legal, and market owners which assets can be transformed and where the label may appear before they sign off.

    Make SDF v11 a controlled migration, not a file swap
    Two specialists guide blank spreadsheet-like grids through validation checkpoints during a staged file-schema migration.

    Display & Video 360 users can now download and upload SDF v11 directly in the platform. For a team that edits files manually, this is a template change. For a team that generates, validates, or ingests SDFs with code, it is a schema migration with targeting consequences.

    The audience change needs an explicit exception. V11 supports lookalike inclusion and exclusion across ad groups except those under YouTube Ad Sequence line items. A bulk updater should identify those sequence line items before it writes audience fields. Do not treat a rejected or missing value as an unexplained upload anomaly when the campaign type itself is excluded.

    Location logic also moves further into bulk management. Business Chain proximity targeting is now available in the line item format. That makes repeated setup easier, but it also increases the reach of a bad mapping. Confirm the intended business chain and destination line items in the generated output, then begin with the smallest reversible batch that can prove the rule works.

    Use this v11 migration sequence

    1. Inventory every workflow that reads, creates, validates, transforms, or archives an SDF. Include spreadsheets, scripts, data pipelines, naming rules, and reporting jobs.
    2. Record the SDF version each workflow expects. Do not assume the version selected for export is also the version understood by an internal parser.
    3. Download a clean v11 file and compare its headers, accepted values, and restrictions with your production template. Treat column names and structures as a contract; do not reconstruct unfamiliar fields from memory.
    4. Update the audience mapping to handle lookalike inclusion and exclusion separately. Add a deliberate branch for YouTube Ad Sequence line items.
    5. Update line-item logic for Business Chain proximity targeting only if the organization intends to use it. A new available field does not need to become a new default.
    6. Inspect the four updated third-party YouTube vendor columns. They now incorporate reporting IDs and allow multiple vendor assignments, while separate reporting ID columns have been removed. Any script that expects those separate columns needs revision.
    7. Test a limited upload and reconcile the accepted campaign structure against the intended file. Check line-item and ad-group counts, audience inclusions, audience exclusions, location settings, and vendor assignments.
    8. Retain the last accepted file and a change log so the team can reconstruct the previous configuration if the upload produces an unintended change.

    YouTube Instant Deals need a separate path. V11 includes columns and restrictions for their line items, ad groups, and ads, but Instant Deals remain in beta for allowlisted partners. They do not appear in downloaded SDFs and can only be uploaded through the dedicated creation workflow. A system that treats an export as a complete round-trip representation of the account will therefore have a known gap. Document that exception instead of letting the next export overwrite the team’s understanding of what exists.

    There is also a firm planning horizon. SDF versions earlier than v10 are deprecated and will stop being supported in January 2027. At minimum, remove every pre-v10 dependency before that point. Moving directly to v11 gives you time to test the current fields and restrictions without turning a support cutoff into an emergency migration.

    Test creative and targeting changes without confounding them

    An overlay changes what a person sees. A lookalike inclusion, exclusion, or proximity rule changes who can see it. If you change both at once and results move, you will not know whether the message or the audience caused the difference.

    1. Choose one question. For example: does an overlay-safe video with generated messaging improve the campaign’s business outcome, or does a particular lookalike configuration improve audience quality?
    2. Define the primary metric before launch. Click-through rate can describe response to an ad, but it should not replace conversion rate, cost per qualified lead, acquisition cost, or another outcome that reflects the campaign’s actual purpose.
    3. Keep the other major inputs as stable as the account allows. Budget, bid strategy, offer, landing page, audience definition, and creative can all obscure the effect you are trying to measure.
    4. Log the exact configuration: overlay state, shorter-video state, resized-video state, SDF version, audience inclusions and exclusions, and proximity targeting.
    5. Inspect the output as well as the metric. A performance lift does not make obscured product details, duplicated copy, an outdated promotion, or an unintended audience exclusion acceptable.
    6. Set rollback conditions from your own baseline before the change. There is no universal performance threshold that fits every account, but brand obstruction, incorrect claims, lost exclusions, or spend directed to unintended locations should trigger immediate correction.

    For overlays, your evidence should include a visual QA record and the downstream business metric. For SDF targeting, reconcile the uploaded configuration first, then evaluate reach, spend, and conversion quality for the affected audience or location. A clean measurement window cannot rescue an incorrectly configured campaign.

    Keep the change log readable by someone outside the activation team. A useful entry includes the campaign, line item, or ad group identifier; the old and new value; who approved it; the hypothesis; the measurement period; and the rollback condition. This is especially important when a platform-generated creative treatment and a bulk-generated targeting rule can both influence the same result.
    Key takeaways

    • Demand Gen can generate video overlays from existing text assets, and the setting has appeared enabled by default. Audit it rather than assuming the approved master is the served creative.
    • Overlay on videos, Shorter videos, and Resized videos are separate asset-optimization decisions. Disable only the transformations your creative cannot safely accept.
    • Modified image or video assets receive an AI creation or editing label when served in the European Union, India, and New York state, so include that behavior in market and brand approvals.
    • SDF v11 adds lookalike inclusion and exclusion for eligible ad groups plus Business Chain proximity targeting at line-item level. YouTube Ad Sequence line items are the stated lookalike exception.
    • The v11 vendor-column changes and Instant Deal workflow can break assumptions in automated imports and exports. Test the schema and document incomplete round-trip cases.
    • Support for SDF versions earlier than v10 ends in January 2027. Migrate while you still have room to validate small batches and correct the workflow safely.

    Start with two inventories: every Demand Gen campaign whose video can be altered, and every workflow that touches an SDF. Assign an owner to each, record the current state, and make one controlled change at a time. That is how you gain the reach of automation without surrendering control of the message, audience, or spend.

    References


  • How to Make AI-Assisted PPC Optimize for Real Profit

    How to Make AI-Assisted PPC Optimize for Real Profit

    Your PPC dashboard can show a healthy return while the campaign quietly consumes the margin you meant to keep. The usual problem is not that automated bidding failed. It is that the bidding system was given revenue, lead counts, or convenient proxy values and asked to treat them as business value.

    You can fix that without abandoning automation. Start by defining the economics outside the ad platform, translate them into usable conversion values and bidding limits, and then let AI control only the decisions it has enough reliable data to make.

    Start with the profit floor, not the platform target

    Coins pass through trays representing product, shipping, payment, service, and return costs before the remainder reaches a protected profit platform.

    Revenue ROAS answers a narrow question: how much reported revenue did you receive for each unit of ad spend? It does not tell you how much money remained after the product, service delivery, transaction, fulfillment, return, and advertising costs attached to that revenue.

    For a campaign whose conversion value represents revenue, the basic relationship is:

    Break-even ROAS = 1 / pre-ad profit margin expressed as a decimal.

    If the relevant margin is 15%, the break-even ROAS is about 6.67, or 667%. At that point, $6.67 of revenue produces about $1 of profit before advertising for every $1 spent on ads. The campaign has covered the advertising cost under that simplified model, but it has not created additional post-ad profit.

    That distinction matters: 667% would be the economic floor in this example, not automatically a sensible operating target. A target ROAS is also a bidding instruction, not a guarantee that every order, day, or campaign will achieve that return.

    If you want a defined post-ad contribution, build it into the calculation. Let m represent the pre-ad margin as a share of revenue and p represent the share you want to retain after ad spend. Your maximum ad-spend share is m – p, so the required ROAS is 1 / (m – p). This forces the profit requirement into the target instead of adding an arbitrary cushion to the break-even number.

    Before applying that formula, settle four inputs with whoever owns the financial numbers:

    1. Confirm what conversion value means. If it is revenue, a revenue-based margin formula can work. If it is already a profit proxy or weighted lead value, applying the same margin again will distort the target.
    2. Define the pre-ad margin consistently. Record which costs are included. Shipping, returns, payment fees, and overhead can materially change true profitability, so a label such as average margin is not enough.
    3. Choose the amount that must remain after advertising. Break-even may be useful for diagnosis, but it is not the same as the return the business needs.
    4. Separate materially different economics. One average can conceal large differences among products, customers, and orders. Do not let high-margin sales make low-margin traffic look sustainable unless that blend is deliberate.

    This calculation gives AI a boundary grounded in your business. It does not make the platform profit-aware by itself.

    Give the bidding system values that survive a finance review

    An automated bidder can optimize only the value and events it receives. If every order is reported as equally valuable, it cannot infer that one product leaves ample margin while another barely covers fulfillment. If every submitted form is called a lead, it cannot know which inquiries can become revenue.

    For ecommerce campaigns

    Choose one value architecture and keep its logic intact:

    • Revenue values with margin-based targets: Report actual revenue, group products or campaign portfolios with reasonably similar economics, and calculate the target from the relevant margin. This preserves the familiar meaning of revenue ROAS.
    • Profit-proxy values: Pass a value that already reflects the economics you want the bidder to favor. Once you do that, stop interpreting the resulting return as revenue ROAS and do not reuse a target calculated on the assumption that conversion value equals revenue.

    The dangerous middle ground is to report revenue, use one blended margin across dissimilar products, and call the result profit optimization. That gives the automation a precise target built on an imprecise economic premise.

    For lead-generation campaigns

    Low-volume lead generation has a different problem: the final sale may arrive too late or too rarely to supply enough bidding signals. Accounts that cannot approach the working benchmark of about 30 conversions in 30 days can use carefully valued micro-conversions to expose progress through the funnel.

    A commercial shipping funnel provides a useful illustration of the structure:

    Those amounts are an example, not a template to copy. Your values should represent the relative economic worth of each stage. A form start is not $10 of booked revenue; it is a bidding signal. If starts are abundant and their assigned value is too generous, the system can hit its target by finding people who begin forms rather than prospects who become qualified opportunities.

    Check three things before using a value ladder:

    • Whether each stage predicts a more valuable business outcome, rather than merely being easy to track.
    • Whether one person can trigger several stages and, if so, whether the cumulative value reflects your intended bidding logic.
    • Whether the final qualified, proposed, and closed outcomes return to the ad platform so earlier assumptions can be compared with reality.

    When your sales system can provide lifecycle outcomes, send them back. Google and Microsoft support integrations with systems such as HubSpot for passing later-stage data into advertising workflows. The important part is not the connector itself. It is replacing a platform’s early proxy with the closest available version of actual customer value.

    Micro-conversions can help campaigns using conversion-based bidding, Performance Max, or AI Max obtain earlier signals. They can also make performance worse when their values are detached from qualification and revenue. More data is useful only when the data teaches the system the right preference.

    Choose how much control AI gets, one decision at a time

    A marketing analyst oversees a modular advertising console where some control units are automated and others remain under human control.

    You do not need one account-wide answer to whether you trust AI. Treat trust as permission granted for a specific job. A practical operating model separates AI-informed, AI-assisted, and AI-delegated work.

    Operating levelWhat AI doesWhat you retainGate before expanding
    AI-informedSurfaces search-term, variant, forecasting, or creative insightsYou choose and apply every campaign changeThe insight maps to a measurable business problem
    AI-assistedRuns a selected task such as bidding or asset generationYou define value, budget, scope, exclusions, and review criteriaTracking is reliable and the task has enough useful signal
    AI-delegatedOptimizes a bounded task end to endYou monitor economics, data quality, and exceptionsA controlled test beats the existing method on business outcomes

    This model prevents a common mistake: treating automated bidding, generated creative, and automated reporting as one indivisible package. They solve different problems and deserve separate permissions.

    Bidding needs signal density and economic constraints

    Bidding is often the easiest task to automate because the system can make more auction-time decisions than a person. It still needs enough useful events. Manual bidding can remain reasonable for low-volume campaigns and narrow industries where sparse conversion data gives automation little to learn from.

    Budget can become a hidden data constraint. One practical setup check uses a budget of at least 10 times the expected cost per click, based on the need to obtain roughly 10 engagements before depending on a conversion rate better than 10% for nonbranded search. Treat that as a diagnostic, not a universal spending rule. If the economics cannot support that traffic, changing the bid strategy will not repair the underlying volume problem.

    Search terms show where automation is buying growth

    Use the matched-by view in search-term reporting to inspect how often a keyword enters auctions through close variants. A high share of stable, cost-effective variants can indicate a useful auction entry point. Large swings in variant mix and bid cost can mean that the same keyword is pulling the campaign into materially different auctions.

    The action is not necessarily to bid on every variant. Choose the keyword or target that gathers enough relevant demand to produce learning, then exclude or restructure traffic that has a different economic purpose. Consolidation helps only when the combined searches deserve the same value signal and target.

    Creative and reporting still need human definitions

    AI-generated assets can increase the number of messages and placements available to a campaign. You still own brand fit, factual accuracy, offer terms, and the landing-page promise. A bidding system cannot compensate for creative that attracts the wrong intent.

    Reporting has a similar division of labor. Automation can assemble platform metrics, but you must translate them into revenue quality, margin, sales progression, and post-ad contribution. A report that ends at platform ROAS is incomplete when the decision in front of you is whether to invest more money.

    Run one test and judge it on post-ad contribution

    You do not have to delegate the whole account to learn whether automation can improve it. Compare the automated approach with the current strategy in a bounded campaign or portfolio where you can keep the economics and tracking definitions stable.

    1. Write the baseline before changing anything. Record spend, reported revenue or lead value, realized margin, qualified outcomes, and post-ad contribution. If some figures arrive later, identify that lag.
    2. State the hypothesis. Examples include finding more conversions above the profit floor, improving qualified opportunity volume within budget, or preserving contribution while increasing scale.
    3. Change one layer of control. Test bidding automation without simultaneously redefining every conversion, rebuilding all creative, and widening targeting. Otherwise, you will not know what caused the result.
    4. Freeze the value definitions during the comparison. If a tracking correction is unavoidable, mark the break and avoid treating the periods as directly comparable.
    5. Watch the traffic and outcome mix. Inspect search terms, product mix, funnel stages, and closed outcomes rather than accepting an aggregate return at face value.
    6. Expand only after the business metric improves. A platform target being met is not sufficient if margin mix, lead quality, or total contribution deteriorates.

    Read combinations of metrics, not isolated wins:

    • ROAS rises while post-ad contribution falls: inspect the product or customer mix and confirm that reported value still maps to the margin used in the target.
    • Conversion volume rises while qualified outcomes fall: reduce the influence of weak micro-conversions and return later sales stages to the platform.
    • Return per conversion rises while total contribution falls: the target may be restricting volume so severely that efficiency improved but the business result did not.
    • Volume and post-ad contribution improve together: broaden the test carefully while keeping the same value definitions and monitoring for mix changes.

    If it appears in your account, a Google Ads beta can translate an average profit margin into a suggested Target ROAS. It can also show weekly estimates for clicks, revenue, ad spend, and total profit as you change the target. Use those figures for scenario planning before applying a setting, not as evidence that the campaign will deliver the estimate.

    The calculator assumes that the reported conversion value is revenue and that the supplied average margin represents the campaign well. It does not directly make Google Ads optimize bids for profit. Your value design, segmentation, cost completeness, and later outcome imports still determine whether the target represents the business you actually have.

    Key takeaways

    • Calculate a break-even ROAS from the pre-ad margin when conversion value represents revenue, then add the post-ad contribution the business needs.
    • Do not apply a revenue-based Target ROAS formula to conversion values that already represent profit proxies or weighted lead values.
    • Use micro-conversions only when their relative values reflect progress toward qualified revenue, and replace proxies with offline outcomes when possible.
    • Grant AI control by task: insight first, selected automation second, and end-to-end delegation only after a bounded test.
    • Judge automation on post-ad contribution and outcome quality, not platform ROAS or conversion count in isolation.

    Your next step is small: take one active campaign, write down what its conversion value actually represents, calculate its economic floor, and compare that floor with the target now in the platform. Any gap you find is the first profitability problem to solve before asking AI to spend more.

    References


  • Demand-Led Google Ads Budgeting Without Losing Cost Control

    Demand-Led Google Ads Budgeting Without Losing Cost Control

    Your strongest campaign reaches its daily limit while qualified searches are still happening. The decision in front of you isn’t simply whether to raise the budget. It’s whether the budget cap or your business economics should decide if you enter the next auction.

    Demand-led budgeting puts the performance requirement first. You define the return the business needs, then let profitable demand determine spend within firm cash, inventory, and operational boundaries. That can capture growth a fixed daily allocation would miss, but only when your conversion values and financial thresholds are trustworthy.

    Demand-led budgeting changes the throttle, not the brakes

    In a conventional budget-led plan, you assign each campaign a fixed amount and ask it to produce the best result available inside that limit. In a demand-led plan, you identify campaigns that can meet an approved target CPA or target ROAS and avoid letting an arbitrary campaign budget suppress additional profitable demand.

    The case has become more relevant as searches become harder to anticipate. Thirty-eight percent of retail queries contain more than eight words, AI Mode queries are more than three times as long as conventional queries, and Google Ads keywords cannot exceed 10 words. A meticulously built keyword list can still fail to represent the language people use. Demand can also jump when a product attracts sudden attention through creator or user-generated content.

    Missing those auctions has a real opportunity cost, although it shouldn’t be exaggerated. Google has presented data indicating that two out of three shoppers ultimately buy a different brand from the one they first discovered. Treat that as a directional warning about weak loyalty, not a universal forecast for every category. Your own repeat-purchase, brand-search, and new-customer data should carry more weight.

    Google also benefits financially when advertisers spend more. That conflict doesn’t make demand-led budgeting wrong, but it does change the burden of proof. A recommendation to remove a constraint should be tested against contribution margin, cash flow, inventory, lead quality, and fulfilled sales – not accepted because the interface predicts more conversions.

    Most businesses therefore need three brakes even when a campaign is no longer tightly budget-capped:

    • An economic brake: Stop buying demand that falls below the approved profit threshold.
    • An operational brake: Slow or stop when stock, fulfillment, sales, or customer support cannot absorb more volume.
    • A financial brake: Keep an absolute company-level ceiling that protects cash flow and respects approved spending authority.

    Set the economic floor before you loosen a budget

    A balance scale with abstract cost and value tokens rests on a solid platform above a defined threshold.

    A target ROAS is only useful when the conversion value behind it reflects the economics you actually care about. Revenue-based ROAS can look healthy while low-margin products, returns, discounts, shipping subsidies, or fulfillment costs consume the apparent gain.

    For ecommerce, start outside Google Ads and calculate:

    • Pre-ad contribution per order = net revenue minus product, payment, fulfillment, return, and other variable costs.
    • Maximum CPA = pre-ad contribution per order minus the contribution you require after advertising.
    • Break-even ROAS = 1 divided by the pre-ad contribution margin rate, when both values use the same revenue basis.

    Break-even is not automatically the right bidding target. It leaves no room for the profit, overhead contribution, or risk buffer your business may require. Use the allowable CPA or minimum ROAS approved by finance, and document which costs and customer value assumptions it includes.

    For lead generation, don’t derive the target from form fills alone. If the bidding conversion is a qualified lead, a basic ceiling is:

    Maximum cost per qualified lead = expected qualified-lead-to-customer rate multiplied by allowable customer acquisition cost.

    Use a rate from your own sales data, and keep the time period and lead definition consistent. If offline outcomes arrive late, judge a budget change only after its normal conversion lag has passed. Otherwise, you can cut good demand before its revenue appears or fund poor demand whose early form count looks deceptively strong.

    Google has positioned changes to target CPA and target ROAS bidding as a safeguard for this model: campaigns are intended to scale while the target remains achievable and reduce or stop serving when it is not. That gives advertisers a performance-based limiter as spend expands. It is still an optimization target, not a contractual guarantee of your realized CPA, ROAS, margin, or cash return.

    Before loosening a cap, make sure the campaign passes this qualification check:

    Decision areaReady for demand-led fundingKeep the tighter cap
    MeasurementPrimary conversions and values represent real business outcomesSoft actions, duplicates, or missing offline outcomes distort performance
    EconomicsFinance has approved an allowable CPA or minimum ROASThe target merely copies the campaign’s recent average
    CapacityStock, fulfillment, sales, and support can absorb a spikeMore orders or leads would create delays, cancellations, or poor follow-up
    Demand qualityQueries, audiences, locations, and product mix are being reviewedAutomation is expanding into irrelevant or low-value demand
    GovernanceA flexible reserve and an absolute company ceiling are definedThe campaign could exceed cash-flow or approval limits before anyone intervenes

    This model can coexist with annual planning. Commit a baseline budget, create a separately approved demand reserve, and specify the conditions under which campaigns may draw from it. Finance retains an absolute limit; marketing gains room to capture qualified spikes without requesting a new campaign budget every time demand changes.

    Give automated reach explicit commercial guardrails

    Broader automation can help cover queries that a finite keyword structure misses, but wider reach and wider spending authority should never be granted without clearer controls. Otherwise, a campaign may technically hit a platform target while reaching the wrong intent, using unsuitable language, or favoring products the business does not want to accelerate.

    Google is using the growing complexity of queries to support the case for AI Max. Its newer control layer, AI Briefs, is designed to accept messaging, matching, and audience instructions. Google has also said support for Performance Max and AI Max for Shopping campaigns will follow. Because these capabilities are relatively new or announced for later expansion, confirm what is actually available in your account before making them part of a required workflow.

    Turn your commercial policy into a short operating brief:

    • Messaging boundaries: List prohibited claims, promises, discount language, and terms that could misrepresent the offer.
    • Matching boundaries: Name irrelevant intents and adjacent categories that should not trigger your ads.
    • Audience direction: Describe the audience and use case you want to prioritize without treating the description as a substitute for observed performance.
    • Product priorities: Identify SKUs that deserve more or less emphasis because of margin, inventory, seasonality, or business importance.
    • Escalation rules: Assign an owner to review unexpected queries, product shifts, and creative outputs before they become a larger spend problem.

    For merchants, Product Value Optimization adds another control point. It is intended to support SKU-level bid adjustments without requiring a new campaign structure or a separate product feed. That can let marketing respond faster to inventory and merchandising priorities. It does not replace accurate product values: bidding up a low-margin SKU merely because it needs exposure can increase revenue while weakening profit.

    Keep a dated log of changes to briefs, targets, product priorities, exclusions, and conversion definitions. When spend or mix changes, that record helps you separate a demand shift from a control change. Without it, automation becomes difficult to diagnose precisely when the financial stakes rise.

    Roll out demand-led funding as a controlled expansion

    Concentric illuminated lanes expand from a central hub through checkpoints represented by a safe, containers, and service stations.

    Do not remove budget constraints across the account in one move. Start with one campaign whose economics, measurement, and operational capacity are already understood, then make the expansion falsifiable.

    1. Select a qualifying campaign. Choose one with trusted conversion data, sufficient stock or sales capacity, and demand that you are willing to serve.
    2. Record a comparable baseline. Capture spend, conversion value, conversions, CPA or ROAS, product or lead mix, contribution margin, and any budget-limited periods. Use a window long enough to include the campaign’s normal conversion lag.
    3. Write the decision rule before spending changes. State the minimum business return, the maximum cash exposure, the operational limits, who may intervene, and which result would trigger a rollback.
    4. Fund from the approved reserve. Raise the restrictive campaign allocation enough that the performance target becomes the main throttle. Do not interpret demand-led as permission to exceed the company’s absolute ceiling.
    5. Watch the mix as well as the average. Review search intent, new versus returning customers where measurable, locations, products, lead quality, cancellations, and returns. A blended ROAS can conceal a deterioration in the incremental traffic.
    6. Measure the increment. Calculate incremental ROAS as additional conversion value divided by additional spend. Compare periods with reasonably similar promotion, inventory, and demand conditions, and avoid claiming causation when those conditions changed materially.
    7. Scale, hold, or reverse. Continue only when the added volume meets the approved business threshold after normal conversion lag. Hold or restore the prior constraint when margin, lead quality, capacity, or cash exposure moves outside the written rule.

    Performance Planner can help estimate how spend might move across campaigns and what return may follow, but forecasting is a planning aid, not certainty about unpredictable demand. Use projections to compare allocation choices. Use observed incremental economics to decide whether the extra budget stays unlocked.

    The crucial distinction is between average and marginal performance. Suppose a campaign’s blended return remains above target after expansion. That alone does not prove the additional spend was worthwhile; strong earlier conversions can support the average while the new portion underperforms. Your decision rule should focus on what the next block of spend added, while acknowledging that auction and demand changes make the estimate imperfect.

    Key takeaways

    • Demand-led budgeting lets approved economics govern campaign spend; it does not eliminate company-level cash and capacity limits.
    • Calculate target CPA or target ROAS from contribution economics, not from the platform’s recent average or a recommendation to spend more.
    • Loosen caps only where conversion values, lead quality, inventory, fulfillment, and sales capacity are reliable enough to support the decision.
    • Broader automated reach needs explicit messaging, matching, audience, and product guardrails.
    • Judge the added spend on incremental business value after normal conversion lag, not solely on blended platform ROAS.
    • Use a pre-approved demand reserve so profitable spikes can be captured without surrendering financial governance.

    Your next move is to identify one budget-limited campaign and write its economic, operational, and cash-flow gates on a single page. If you cannot define those gates from reliable data, keep the cap. If you can, fund a controlled expansion and let the incremental result – not the promise of more volume – earn the next allocation.

    References


  • Google Ads Smart Bidding: The 50-Conversion Benchmark

    Google Ads Smart Bidding: The 50-Conversion Benchmark

    You changed a Smart Bidding strategy, performance moved, and Google Ads now shows a Learning status. The difficult decision is whether to wait, reverse the change, or treat the movement as evidence that something is wrong.

    The short answer is that 50 conversions is not a minimum requirement or a guaranteed turning point. Google says calibration can take up to roughly 50 conversion events or three conversion cycles, with faster learning possible when useful historical data already exists. Treat those figures as planning boundaries for diagnosis, not as a finish line the campaign must cross before it can work.

    The 50-conversion figure is a benchmark, not an entry fee

    A Smart Bidding strategy does not sit idle until conversion number 50. It bids while it is learning. The approximate 50-event figure describes how much feedback calibration may require after a qualifying change; it does not mean every campaign needs 50 conversions before automation becomes usable.

    It is also not a 50-conversions-per-month rule. Calendar months are arbitrary boundaries to a bidding system. What matters is the stream of conversion feedback available after the change and how quickly that feedback arrives.

    The second part of the benchmark matters just as much: three conversion cycles. A conversion cycle is the time between the traffic being generated and the resulting conversion feedback arriving. If customers tend to convert after a delay, the bidder cannot immediately observe the eventual outcome of recent auctions. A week of elapsed time can therefore contain plenty of traffic but little mature conversion evidence.

    That distinction corrects four common misreadings:

    • You do not have to accumulate 50 conversions before enabling Smart Bidding.
    • The 50th event does not guarantee that performance will suddenly stabilize or meet your business target.
    • Fifty clicks, leads in a separate system, or other uncounted actions are not substitutes for the conversion events available to the bidding strategy.
    • A campaign with strong relevant history may calibrate before it reaches the approximate upper benchmark.

    Use the benchmark to answer a narrow question: has the bidder had a reasonable opportunity to observe outcomes since the material change? Keep that separate from the larger question of whether the campaign is profitable.

    Estimate learning time with two clocks

    Two numeral-free clocks connected to a learning system, one surrounded by event signals and the other by three broad cycle rings.

    Asking how many days Smart Bidding needs is usually too imprecise. Two campaigns can be the same age while giving the bidder very different amounts of usable information. Track a volume clock and a feedback-latency clock instead.

    Planning signalQuestion to answerHow to use it
    Conversion-event volumeHow many relevant conversion events have arrived since the change?Compare the observed count with the approximate 50-event calibration benchmark. Do not treat 50 as a required quota.
    Conversion-cycle lengthHow long does it normally take conversion feedback to arrive after traffic occurs?Use up to three cycles as the alternative time frame. Recent traffic may still be too immature to judge.
    Historical conversion dataDoes the strategy already have useful evidence from before the change?Expect that relevant history may shorten calibration, but do not assume that unrelated or obsolete history will settle the current decision.
    Change historyDid another material edit happen during the observation period?Separate the periods in your change log. Otherwise, you may attribute one change’s effect to another.

    For rough capacity planning, you can calculate a volume-only estimate as follows: subtract the conversion events already observed from 50, then divide the remainder by the campaign’s recent average conversion events per day. This is not an official completion forecast. Conversion rates fluctuate, historical data can accelerate calibration, and delayed outcomes can make the most recent days look artificially weak.

    The practical lesson for a low-volume campaign is simple: the same amount of algorithmic feedback can require much more calendar time. If conversion events arrive slowly, checking the campaign every few days does not create new evidence. It only creates more opportunities to interrupt learning with another edit.

    Do not manufacture apparent volume by redefining a shallow action as a primary conversion merely to approach 50. That changes what the bidder is being asked to optimize. More signals are not better when they represent the wrong business outcome.

    Performance Max needs an additional expectation check. It can take longer to reach performance goals when most traffic comes from channels outside Search or Shopping. If that describes your campaign, avoid transferring a Search campaign’s calendar expectations directly onto Performance Max.

    Protect the learning period from overlapping changes

    A glowing network develops inside a protective dome while hands pause above several surrounding control levers and dials.

    A campaign can enter Learning when you create or reactivate a bidding strategy, change its settings, or make certain changes to campaign composition. Changes to conversion goals are also relevant for Search, Shopping, and Performance Max campaigns.

    This creates a change-control problem. If you edit the bidding strategy, alter the goal, adjust the campaign again, and then judge the combined result, there is no clean observation window. You will know that performance changed, but not which intervention deserves credit or blame.

    Before making a material change, create a short learning record with:

    • The exact time and date of the change.
    • The campaign and bidding strategy affected.
    • The setting, campaign composition, status, or conversion goal that changed.
    • The conversion events the strategy is intended to optimize.
    • The typical conversion-cycle length used for planning.
    • The accumulated conversion-event count you will review after the change.
    • The business guardrails that would justify intervening before calibration is complete.

    Then give the change a clean observation period when business risk allows it. This is particularly important during the initial Performance Max learning period, when frequent budget, bidding-strategy, and campaign-status changes can be counterproductive.

    A clean observation period does not mean ignoring the account. Monitor measurement, spend, and lead or transaction quality throughout. The restraint applies to unnecessary optimization edits, not to detecting broken tracking or containing unacceptable cost.

    Know when to wait and when to intervene

    The Learning label is not a command to leave a campaign untouched at any cost. Advertising spend is real exposure. Your decision should combine calibration evidence with measurement integrity and business limits.

    1. Check measurement first. Confirm that the intended conversion events are still being recorded and that the bidder is optimizing toward the outcome you actually value. If tracking is broken or the wrong goal is active, waiting for more data only gives the system more bad information.
    2. Identify the most recent material change. Use that point as the start of the current observation period. If several changes overlap, document each one before drawing a causal conclusion.
    3. Read both learning clocks. Count relevant conversion events and assess how many conversion cycles have had time to mature. Do not substitute impressions, clicks, or elapsed days for conversion feedback.
    4. Apply business guardrails. Continue observing when measurement is sound, the campaign remains within tolerable cost boundaries, and it is still inside the approximate calibration window. If spend is creating unacceptable exposure, protect the budget even though another change may lengthen learning.
    5. Escalate the diagnosis after a fair opportunity. Once the strategy has seen roughly the benchmark amount of evidence or enough conversion cycles, continuing volatility does not automatically prove that Smart Bidding failed. It does mean that learning alone is no longer a sufficient explanation.

    When that last condition applies, inspect the inputs and constraints rather than repeatedly toggling the strategy. Check whether the selected conversion goal represents the desired outcome, whether recent changes altered campaign composition, whether traffic quality shifted, and whether the business target is compatible with the campaign’s available opportunities. These are different problems, and none is solved merely by waiting for a Learning status to disappear.

    The most useful decision rule is therefore conditional:

    • Wait when measurement is valid, the change is understood, the campaign is still accumulating meaningful evidence, and spend remains within your limits.
    • Investigate now when conversion tracking appears broken, the wrong goal is active, or another change has contaminated the observation period.
    • Intervene when the financial exposure is unacceptable. Learning is not a reason to ignore a budget or cost boundary.
    • Broaden the diagnosis when sufficient event volume or conversion-cycle time has passed but the campaign still misses the outcome that matters.

    This framework prevents opposite mistakes: aborting a sound strategy before delayed outcomes arrive, and excusing persistent underperformance indefinitely because automation is supposedly still learning.

    Key takeaways

    • Roughly 50 conversion events is an approximate upper calibration benchmark, not a universal eligibility requirement.
    • Three conversion cycles account for delayed feedback that a simple day count misses.
    • Conversion volume, conversion-cycle length, bidding strategy, and available history can all affect calibration time.
    • Low-volume campaigns may need more calendar time because they accumulate conversion evidence slowly.
    • Frequent changes make the learning period harder to interpret and can prolong the path to a useful decision.
    • Broken measurement, an incorrect conversion goal, or unacceptable spend warrants action before any numerical benchmark is reached.

    For your next Smart Bidding change, record the event count, conversion-cycle expectation, and acceptable spend boundary before you edit the campaign. When performance moves, you will have a defined basis for waiting, investigating, or acting instead of treating day 50 or conversion 50 as a magic answer.

    References


  • Google Ads Automated Bidding Changes: What to Reassess

    Google Ads Automated Bidding Changes: What to Reassess

    Your Google Ads campaign can look less efficient even when automated bidding is doing exactly what you told it to do. If a budget-limited campaign used to beat its target ROAS or CPA but now buys more expensive traffic and exhausts its budget sooner, don’t assume the bidder is broken.

    The more useful question is whether your target still expresses the result your business actually needs. Google has made target-based bidding more literal for budget-constrained campaigns, while a separate retail beta adds product-level value signals. Together, these changes put more responsibility on you to define acceptable economics rather than relying on budget pressure to produce accidental efficiency.

    Budget limits no longer create the same efficiency buffer

    A limited tank of glowing coins drains through an automated bidding machine that sends larger bundles toward several abstract auction gates.

    A target ROAS or target CPA is an instruction, not a label. If you give the bidder a target that is looser than your real business requirement, it has room to pursue additional opportunities until performance approaches that stated target.

    Before the Smart Bidding change, a constrained budget could effectively make bidding more conservative. Some campaigns captured cheaper clicks, stretched their allocations and substantially exceeded their targets. The update that started rolling out on Aug. 17 and finished globally on Aug. 27 was intended to make target-based, budget-limited campaigns perform more consistently around the goals advertisers entered, including when budgets changed.

    The practical consequence is easy to miss. A target CPA campaign set to $10 but previously delivering a $5 CPA could move closer to $10 unless the advertiser tightens the target. The equivalent can happen with target ROAS: historical overperformance is not necessarily a permanent buffer when the system is being asked to deliver only the lower stated return.

    The initial post-rollout pattern was substantial. Median CPC for budget-limited target ROAS campaigns rose 15.8%, while CPC for campaigns that were never budget-limited fell 13%. Before the change, more than half of the constrained campaigns were exceeding their ROAS targets. Only 30% of non-limited campaigns overdelivered, while 57% landed on target.

    Observed medianBefore the rolloutAfter the rolloutWhat you should notice
    CPC for budget-limited campaigns€0.38€0.44The constrained campaigns paid more for each click.
    Impression share lost to rankAbout 45%About 30%Ad rank was responsible for a smaller share of missed impressions.
    Impression share lost to budgetAbout 4%About 33%The budget became the more direct constraint.
    Overall impression share40%31%The campaigns reached a smaller portion of available impressions.

    That combination matters more than any one number. Higher CPC, lower rank loss and sharply higher budget loss indicate that the bidder may be competing more strongly when it enters an auction, then running into the spending limit sooner. It is a different mechanism from simply bidding conservatively all day.

    The findings are early rather than universal. Conversion attribution was still developing, so the long-term ROAS effect was not yet settled. Treat Aug. 17 as a meaningful diagnostic breakpoint, not as proof that every performance change in every account has the same cause.

    Audit affected campaigns without hiding the change in averages

    An account-level average can conceal exactly what you need to see. Separate target-based campaigns that were budget-limited from campaigns that had enough budget. The two groups moved differently after the rollout, so combining them can turn a clear bidding shift into an ambiguous blended trend.

    1. Identify campaigns using a target-based strategy. Separate target ROAS from target CPA so you evaluate each one against the correct efficiency measure.
    2. Flag campaigns that were budget-limited around the rollout. Keep campaigns that were never constrained as a comparison group rather than mixing their results into the same total.
    3. Use Aug. 17 as the beginning of the change and Aug. 27 as the completion point. Avoid treating the rollout interval as a clean before-or-after period.
    4. Allow conversion attribution to mature before making a final ROAS or CPA judgment. CPC and impression-share signals appear sooner than fully attributed conversion value.
    5. Compare actual performance with the target you entered. Record target ROAS versus delivered ROAS, or target CPA versus delivered CPA, rather than looking only at the change from the previous period.
    6. Review CPC, total impression share, impression share lost to rank and impression share lost to budget together where those metrics are available. This shows whether the campaign became less competitive, more budget-constrained or both.
    7. Check the business result behind the platform metric. Revenue, contribution margin, inventory priorities and acquisition value determine whether performance near the target is acceptable.

    Read the metrics as a system

    If CPC rises, rank loss falls and budget loss rises, the campaign is probably bidding more competitively and exhausting its allocation more directly. Review the target before assuming the budget is too small.

    If actual ROAS falls toward target ROAS, or actual CPA rises toward target CPA, the bidder may be using the flexibility you explicitly gave it. Decide whether the additional opportunity is economically worthwhile. Don’t call the movement a failure merely because the old campaign overdelivered, but don’t accept it merely because the platform reached its target either.

    If total impression share falls while budget loss rises, you face a real reach decision. You can accept fewer impressions, tighten the target and potentially reject more opportunities, or fund more of the available demand. The correct answer depends on the value of the next unit of spend, not on a desire to recover an old impression-share percentage.

    If those auction signals are absent, don’t force the bidding update to explain the problem. A conversion-tracking change, product mix, demand shift or landing-page issue can also alter ROAS or CPA. The update is a hypothesis to test against campaign-level evidence, not a universal diagnosis.

    Choose the lever that matches the actual constraint

    You have four defensible responses: accept less reach, tighten the target, increase the budget where the economics support it, or reconsider the bidding strategy. The dangerous response is to raise the budget automatically because the interface says a campaign is limited.

    Tighten a target that understates your real requirement

    If the business needs a higher return than the target ROAS currently entered, raise the target toward the efficiency level you genuinely require. If the business cannot tolerate the current target CPA, lower that target toward the acceptable acquisition cost. Historically delivered performance can inform the change, but it should not replace your unit economics.

    A tighter target can reduce reach because the bidder must reject opportunities that do not fit the new instruction. That is not necessarily a defect. It is the cost of refusing volume that fails your efficiency requirement.

    Increase the budget only when performance at the target is valuable

    A larger budget can make sense when the stated target is profitable and additional demand has value. Evaluate the next dollars as though they will perform near the target, not at the unusually strong ROAS or CPA the constrained campaign used to deliver. The update was designed to bring delivery closer to the entered goal, so historical overperformance is a weak basis for approving more spend.

    This decision creates direct financial exposure. Set the approved spending limit from margin, cash flow and customer value, then decide how much reach to purchase. A platform warning that a campaign is budget-limited does not establish that the missed traffic is profitable.

    Accept reduced reach when the budget is fixed

    If the spending cap cannot move and the target already reflects your economics, reduced reach may be the honest result. You cannot demand the same auction coverage, preserve the same efficiency and keep the same budget when click costs rise. Choose which constraint is real instead of asking automation to satisfy three incompatible requirements.

    Reconsider the strategy when one target cannot express the objective

    A single account-wide or campaign-wide value target can be too blunt when products have materially different commercial value. Before abandoning automation, examine whether the bidding system is receiving the wrong definition of value. For retailers, the Product Value Optimization beta is intended to address part of that problem.

    Whichever lever you select, change it deliberately. Altering the target, budget and value rules together makes the result hard to interpret. Record the reason for the first change, let attributed conversions develop, and then judge whether that lever addressed the constraint you identified.

    Product Value Optimization adds business context to retail bidding

    Generic retail products send layered margin, inventory, customer value, and priority signals into a central automated bidding engine.

    Standard conversion-value bidding can treat equal amounts of reported revenue as equally desirable even when the underlying sales have different margins or inventory consequences. Product Value Optimization is a retail beta that allows value adjustments for individual products or attributes such as brands and categories. Those adjusted signals can guide automated bidding in Performance Max and Shopping campaigns without requiring a campaign restructure.

    This gives you three different controls with three different jobs. The budget limits the spend available. The ROAS or CPA target communicates the desired efficiency. A product value rule tells the bidder which items or sales deserve more emphasis. Confusing those jobs leads to bad fixes, such as raising an entire campaign’s budget when the real need is to favor a profitable category within it.

    The beta identifies profit, seasonal sell-through and best-selling products as possible use cases. Those goals are not interchangeable. A bestseller may produce volume but weak incremental profit. Seasonal inventory may warrant temporary priority because its value falls after the selling window. A high-margin product may deserve emphasis even if it does not lead the revenue report.

    Define the rule before enabling the adjustment

    1. Choose one commercial objective for the rule: profit, seasonal sell-through or another clearly defined inventory priority.
    2. Select the narrowest appropriate level. Use a product rule when the priority is item-specific, or an attribute such as category or brand when the logic genuinely applies across that group.
    3. Write down why the selected sale is more valuable. Higher revenue alone is not enough if margin, returns or inventory costs point in the opposite direction.
    4. Map overlapping product, category and brand logic before activation. The bidder needs a coherent value hierarchy, not competing expressions of internal preferences.
    5. Keep actual revenue and profit as independent business measures. An adjusted optimization value is an instruction to the bidder; it is not proof that the resulting sales created more profit.
    6. Evaluate product mix as well as aggregate ROAS. A stable top-line return can hide a meaningful shift toward or away from the inventory the rule was designed to prioritize.

    If the beta appears in your account, start with the business distinction you can defend most clearly. A rule grounded in margin or time-sensitive inventory has a testable rationale. Prioritizing a product merely because it is already popular risks teaching the bidder to amplify volume that would have occurred anyway.

    Key takeaways

    • Budget-limited target bidding may no longer produce the same conservative bidding and accidental target overperformance it produced before the Aug. 17 rollout.
    • A CPC increase combined with lower rank loss and higher budget loss is more informative than a CPC increase viewed alone.
    • Treat target ROAS and target CPA as permissions the bidder can use, not as passive reporting benchmarks.
    • Model a budget increase at performance near the stated target rather than assuming the campaign will retain its former overperformance.
    • Use Product Value Optimization to express genuine differences in commercial value, not to promote products based on popularity alone.
    • Allow attribution to mature before declaring the long-term ROAS effect, because the available post-rollout evidence was still preliminary.

    Start with the budget-limited campaign where the gap between target and historical performance was largest. Reconstruct what changed across CPC, impression-share losses and actual efficiency, then make the smallest change that brings the bidding instruction back into line with the economics you are prepared to accept.

    References


  • Google Ads Control Reliability: What Settings Really Do

    Google Ads Control Reliability: What Settings Really Do

    Your Google Ads campaign has almost stopped serving, but billing, policy status, conversion tracking, negative keywords, locations, devices, and schedules all look clean. This is where the interface can send you in the wrong direction: a visible setting may be active without carrying the authority you assume it has.

    Before you raise the budget, remove targeting, or abandon automation, identify what the setting actually promises. Some controls block delivery. Others affect eligibility, establish a bidding constraint, or merely give the system context. The useful question isn’t just, “Is this control enabled?” It is, “What happens when this control conflicts with the auction?”

    The control hierarchy: five settings, five different promises

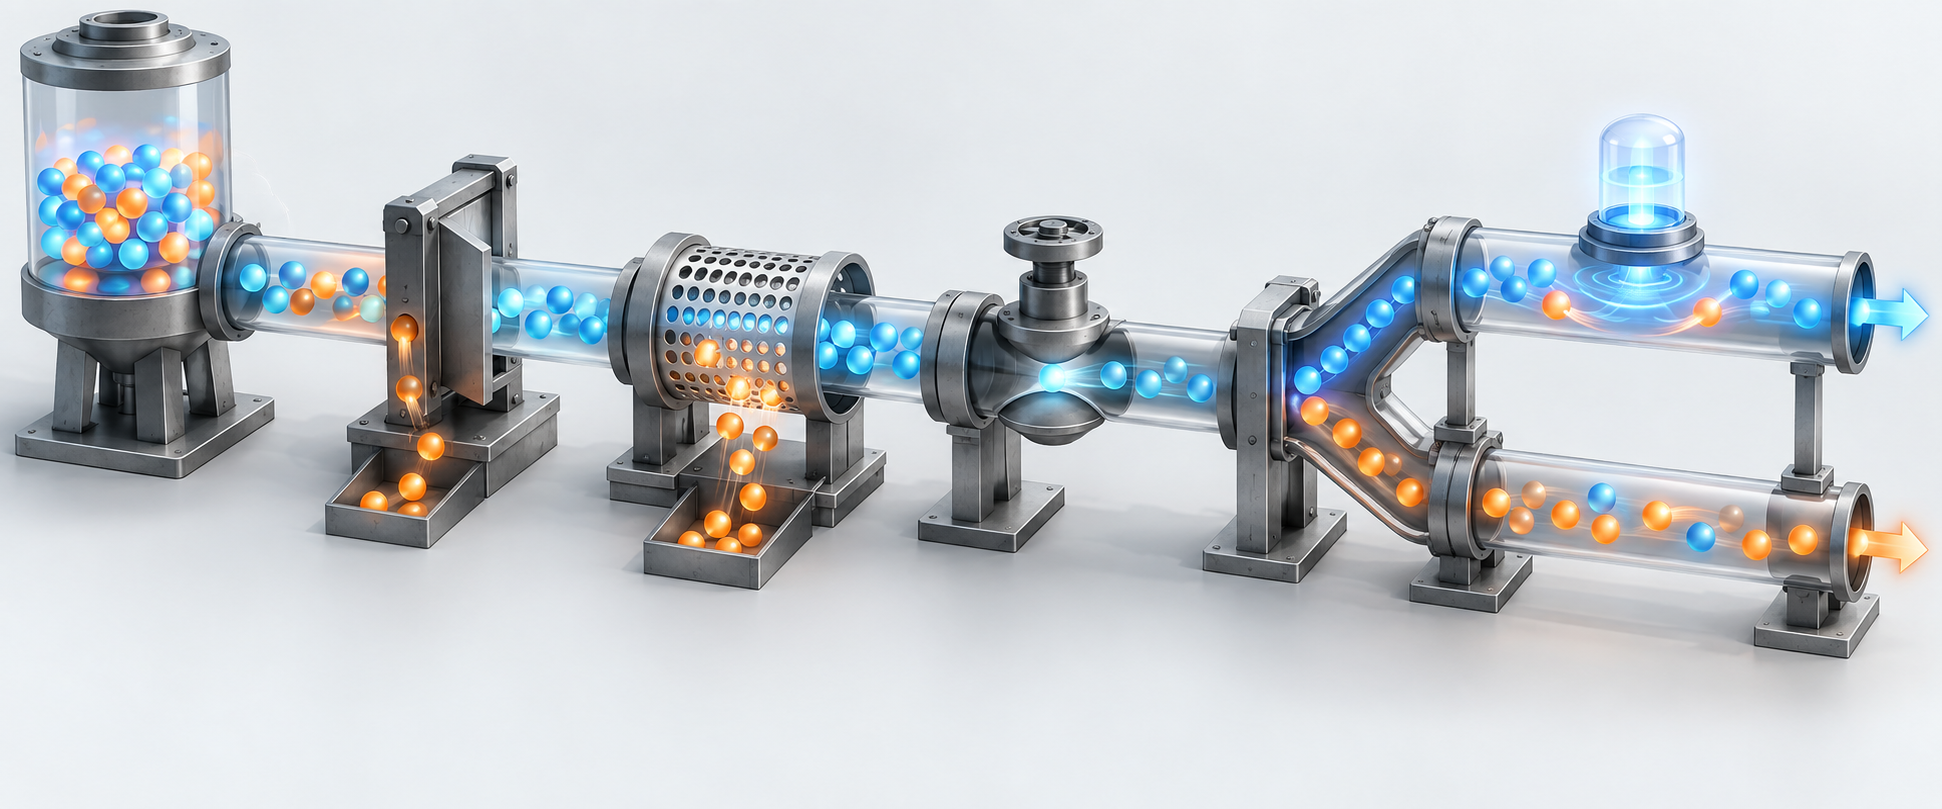
    A stream of glowing tokens passes through a barrier, filter, valve, junction, and signal beacon in an isometric delivery pipeline.

    A reliable control is not necessarily one that produces the outcome you want. It is one whose behavior you understand well enough to predict what will happen when market conditions, automation, and your instructions disagree.

    Control classGoogle Ads examplesWhat it can reliably doWhat it cannot promise
    Hard restrictionsNegative keywords, brand exclusions, URL exclusionsConstrain whether specified traffic or assets can serveA negative keyword does not block every query related to the same concept
    Opt-outsAI Max toggle and ad-group-level search-term matching controlsDisable a defined feature or behavior at a particular scopeA complete return to an older campaign state, especially when related controls or migrated features behave differently
    Priority rulesPriority for an identical, eligible exact-match keywordPut one eligible option ahead of another in the selection processEligibility, impressions, clicks, or traffic volume
    TargetsTarget CPA and target ROASConstrain the range in which automated bidding tries to operateThe requested conversion volume at any market price
    Contextual signalsPerformance Max search themes and the keywords, creative, and URLs used by AI MaxInform expansion and help automation interpret your intentA deterministic boundary around every query the campaign can enter

    The details matter most at the edges. Negative keywords, brand exclusions, and URL exclusions are treated as firm boundaries, but a negative keyword is still a precise instruction about the text you entered. Casing and misspellings are handled, while synonyms and singular or plural forms are not automatically covered. If you add job as a negative, do not assume you have also excluded jobs, career, and employment.

    At the other end of the hierarchy, search themes and other contextual signals help the system interpret a campaign. They are useful for direction, but they should not carry a must-not-serve requirement. If a query category would create unacceptable cost or brand exposure, use an applicable exclusion control and verify its coverage instead of relying on a theme or creative cue.

    Matching guidelines in AI Brief do not fit neatly into either category. They are presented as guidance and boundaries with previews, but Google has not published a deterministic guarantee or an enforcement rate. Treat them as something to test in live query evidence, not as a substitute for a confirmed exclusion.

    When delivery collapses, diagnose authority before changing bids

    A campaign that has gone quiet invites broad, hurried edits. That makes the underlying problem harder to isolate and can release more spend than you intended. Use a fixed diagnostic sequence instead.

    1. Mark the beginning of the decline. Identify when impressions, clicks, and conversions changed. You need a date to compare with configuration changes; a current-state screenshot cannot tell you what created the current state.
    2. Check basic eligibility. Review billing, policy status, location and device targeting, schedules, negative conflicts, conversion configuration, and available budget. “Limited by budget” is an eligibility condition, so even a valid priority rule may not operate as you expect when the campaign is constrained.
    3. Use the ad preview result as a symptom. A not-serving result confirms that the campaign is not entering or winning that opportunity. It does not, by itself, identify the responsible control.
    4. Expand change history to the campaign’s full lifetime. A decisive bid-strategy or target change may sit outside a 30-day or 12-month view. A full-lifetime review exposed a consequential change that shorter windows had hidden.
    5. Classify each relevant setting. Label it as a hard restriction, opt-out, priority rule, target, or contextual signal. Then write down the narrow promise it actually makes.
    6. Compare bidding targets with attainable economics. Examine whether recent CPA, CPC, competition, and conversion volume still overlap the target. A target based on an older market can be reasonable when it is chosen and still become restrictive later.
    7. Run one reversible test. Change the suspected constraint without simultaneously rewriting keywords, ads, locations, and budgets. Loosening or removing a bid target can unlock spend quickly, so confirm the campaign budget and conversion measurement before publishing the test.

    This sequence separates three very different failures: the campaign is ineligible, the campaign is eligible but constrained by its target, or the campaign is serving outside the conceptual boundary you thought a matching control created. Each failure needs a different fix.

    A target CPA is a traffic constraint, not a cost ceiling

    Abstract bid vehicles approach a narrow checkpoint, where only some pass through toward opportunities of different sizes.

    Target CPA is easy to misread because its name sounds like a preferred result. In practice, the target constrains the auctions automated bidding can justify. When the available market no longer overlaps that target, the system cannot simply pay substantially more for every desirable prospect and preserve the target at the same time. It can reduce participation instead.

    Consider a referral-software campaign that recorded only six impressions during a month in which it had effectively gone dark. Its account showed a $200 target CPA and a $182 actual CPA, which looked superficially healthy. The full change history showed that Maximize Conversions with a $200 target CPA had been introduced in October 2024. That target was about 12% higher than the CPA achieved in the previous year, so it was not an obviously aggressive choice when it was set.

    The market had moved. Competition had more than doubled, CPC had risen 51.96%, and CPA had moved from $138.53 to $316.76. The $200 target had become roughly 37% lower than the cost the campaign was encountering per lead. The automation preserved the constraint by finding very little traffic it considered compatible with that constraint.

    This is why an actual CPA below target does not automatically prove that a target is healthy. Ask how much delivery produced the number. An apparently efficient CPA based on negligible impressions or conversion volume can coexist with a campaign that is economically unable to scale.

    • Check volume before celebrating efficiency. Read actual CPA beside impressions, clicks, and conversions, not as an isolated score.
    • Compare the target with recent conditions. The CPA that justified a decision a year ago may describe a market that no longer exists.
    • Look for movement in input costs. A major CPC increase can make the old acquisition target unattainable even when the landing page and conversion setup have not changed.
    • Align the date of the decline with change history. A target may begin as attainable and become restrictive gradually, so the visible delivery collapse can occur well after the original edit.

    If the evidence points to an unrealistic target, test a less restrictive target as a controlled bidding change. Do not simultaneously increase the budget and broaden matching. A higher target can admit more expensive auctions, while a larger budget gives the campaign more money to enter them; changing both prevents you from knowing which lever changed performance and increases the financial exposure of the test.

    Match types and opt-outs need boundary tests

    Exact match should be read as a priority and relevance mechanism, not as a literal-text firewall. Its boundaries changed in stages: close variants became optional in 2012, mandatory for exact and phrase match in 2014, and broader through later changes involving word order, implied terms, and paraphrases. Same-meaning matching reached phrase match and broad match modifier in 2019. Phrase match absorbed broad match modifier behavior in February 2021, and advertisers could no longer create new broad match modifier keywords by late July 2021.

    An identical, eligible exact-match keyword can receive first priority, but that is a queue position rather than a delivery guarantee. The keyword must still be eligible, the campaign must have budget, inventory must exist, and exceptions for advanced search experiences may apply. “We have the exact keyword” therefore does not answer “Why did we receive no impression?”

    Use a separate boundary test for each kind of control:

    • For negative keywords, test the strings you actually excluded. Add important synonyms and singular or plural forms separately when the concept must be blocked. Do not rely on positive-keyword expansion rules to describe negative-keyword behavior.
    • Inspect long searches carefully. On a search longer than 16 words, a negative term appearing after the sixteenth word will not block the ad. A rare long query can therefore cross a boundary without the negative keyword being ignored or malfunctioning.
    • For exact match, inspect eligibility and the matched search term. Determine whether the exact keyword was eligible to receive priority before treating the outcome as a matching failure.
    • For AI Max opt-outs, verify related behavior after the toggle changes. Some controls housed within the feature stop applying when it is disabled. The migration of Dynamic Search Ads into AI Max also means that switching AI Max off should not be assumed to recreate every aspect of the older campaign state.
    • For contextual signals, evaluate direction rather than compliance. Search themes, creative, keywords, and URLs can steer expansion. Confirm the result in search-term evidence instead of treating those inputs as enforceable exclusions.

    The practical distinction is simple: verify hard boundaries against prohibited traffic, evaluate priority rules only after confirming eligibility, judge targets by both cost and volume, and assess contextual signals by the traffic they influence. Applying one test to all four produces false confidence.

    Key takeaways: build a control-reliability routine

    Keep a small control register for each material campaign. It does not need another dashboard. A shared account note or worksheet is enough if it records the setting, its scope, its authority class, the expected effect, the evidence used to verify it, the owner, and the safe rollback.

    • Start with authority, not the label. Decide whether a setting blocks, opts out, prioritizes, constrains, or guides before predicting its effect.
    • Use full-lifetime change history when delivery has no visible cause. The current configuration may be the accumulated effect of a decision hidden beyond the default date range.
    • Judge bid targets against recent attainable economics and meaningful volume. An actual CPA below target means little when the campaign barely enters auctions.
    • Test query controls at their real boundaries. Check variants, scope, eligibility, and long-query behavior rather than assuming that a control covers the surrounding concept.
    • Change one consequential lever at a time. Record the expected effect and rollback first, and keep the budget within an amount you are prepared to expose while the test runs.

    Open the weakest-delivering campaign first. Expand its change history, classify its active controls, and choose the smallest reversible test that can distinguish an eligibility problem from an unrealistic target or a misunderstood matching boundary. Once you can state exactly what each control is allowed to decide, the account becomes much easier to manage without guessing.

    References


  • Google Ads Automation: How to Keep Advertiser Control

    Google Ads Automation: How to Keep Advertiser Control

    Your Google Ads campaign can hit its reported target and still make a decision you would never approve. It can enter a competitor bidding war, learn from queries you already know are irrelevant, favor sales with weak margins, or expand into inventory you did not intend to buy.

    You do not need to rebuild every campaign around manual bidding or revive an account full of single-keyword ad groups. You need a control system: clear business objectives, enough consolidated data for automation to learn, explicit boundaries on where it may explore, and a verification loop that catches strategically wrong behavior before it becomes expensive.

    Key takeaways

    • Automate execution inside boundaries you define. Google Ads can optimize an objective, but it cannot infer every commercial constraint behind that objective.
    • Consolidate campaigns when fragmentation deprives Smart Bidding of conversion data. Split them only when the parts genuinely require different economics, budgets, policies, or market strategies.
    • As a working benchmark rather than a universal platform rule, look for at least 30 monthly conversions per campaign, with 60 or more providing a stronger foundation for consistent automated bidding.
    • Configure negative keywords, brand controls, network settings, and reporting before enabling wider expansion. Do not pay an algorithm to relearn exclusions your business already knows.
    • Inspect search terms, match sources, networks, brand exposure, conversion quality, and profitability from the start. A strong top-line ROAS does not prove that the underlying traffic is acceptable.
    • After a material change, respect conversion lag. Google has advised waiting one to two conversion cycles before drawing conclusions, unless a hard budget or policy boundary is already being breached.

    Define what automation is allowed to decide

    Advertiser control no longer means making every auction decision yourself. It means retaining ownership of the decisions that shape those auctions.

    Google Ads can observe signals, predict the likelihood of a conversion, adjust bids, and expand targeting. It cannot automatically know that a particular competitor must be avoided, that returned orders erase the apparent profit from a product category, or that your sales team cannot handle another wave of low-value leads. Those are business facts, not auction facts.

    The distinction matters because the platform’s definition of success is not automatically the advertiser’s definition. Google benefits when advertisers spend money. You benefit when additional spend produces acceptable incremental business outcomes. Those interests can overlap without being identical.

    Write an automation contract for each campaign

    Before changing a bidding strategy or enabling AI-driven expansion, write down the following decisions in plain language:

    1. Business objective: Name the result the campaign is supposed to produce. Do not substitute ad position, traffic volume, or spend for a business result.
    2. Economic target: Record the CPA, ROAS, margin, or other threshold the business actually uses. If different products have different economics, state how those differences will be represented.
    3. Permitted expansion: Specify whether the system may explore broad queries, competitor searches, Search Partners, new geographic areas, or additional channels.
    4. Prohibited behavior: List the queries, brands, locations, offers, audiences, and traffic sources that are unacceptable even if their reported conversion performance appears strong.
    5. Conversion definition: Identify which recorded actions represent real value. Separate primary outcomes from actions that are useful for observation but should not steer bidding.
    6. Evidence required: Name the reports you will inspect to verify search terms, match sources, networks, conversion quality, and economic performance.
    7. Intervention rule: Define the conditions that require a pause, exclusion, target adjustment, or deeper review. Use thresholds approved by your business rather than inventing them after spend accelerates.

    This contract prevents a common mistake: evaluating automation only by the metric it was instructed to optimize. If a campaign reaches target ROAS by entering strategically unwanted auctions, the bidding system may have completed its assignment perfectly. The assignment was incomplete.

    Treat every platform recommendation as a hypothesis about execution. Ask which part of your contract it supports, which new permissions it requires, and where its effect will be visible. If you cannot answer those questions, investigate before applying it.

    Consolidate learning without flattening business differences

    Distinct colored data streams pass through a shared learning engine and continue as separate coordinated lanes.

    The old response to uncertainty was often more structure: single-keyword ad groups, duplicated match types, traffic-sculpting negatives, and numerous narrowly defined campaigns. Much of that tactical granularity has become unnecessary under automated bidding and matching.

    Excessive structure now creates a different risk. Every additional campaign divides the available conversion history. Automated bidding then has fewer observations from which to estimate performance, while each segment receives a smaller share of the account’s traffic and budget.

    A useful working benchmark – not a guarantee and not a reason to ignore your own variance – is at least 30 conversions per campaign each month, ideally 60 or more, for Smart Bidding to operate consistently. Before creating a split, estimate how much recent conversion volume each resulting campaign would retain. If one side would fall well below that range, the business reason for separating it needs to outweigh the loss of learning density.

    Use a business test for every proposed split

    Create a separate campaign when at least one of these conditions is true:

    • The segment needs a genuinely different CPA, ROAS, or profit target.
    • Its budget must be protected or capped independently for a clear commercial reason.
    • Its geography, availability, compliance requirements, or operating capacity differs from the rest of the account.
    • Its brand, competitor, query, network, or channel policy must be different.
    • The business intends to make a distinct investment decision about that segment and cannot obtain the necessary control through reporting, labels, or exclusions.

    Do not create a campaign merely because a reporting dimension exists. Reporting taxonomy and bidding structure are different tools. You can often preserve a consolidated learning pool while using labels and reports to analyze meaningful groups.

    Margin is a good example. An account divided into many narrow margin buckets, each carrying its own ROAS target, can look financially rigorous while fragmenting the data the bidding system needs. The resulting campaigns may be too small to achieve the targets that justified the structure.

    Instead, use custom labels for information such as margin, sell-through rate, and return rate. Labels do not magically convert profit into a bidding signal, but they let you organize products, inspect performance, and make campaign decisions with context Google does not inherently possess. If you later separate a segment, you can do so because the data reveals a material economic difference, not because a spreadsheet had another row available.

    Put guardrails in place before expansion starts

    A human operator inspects layered guardrails and checkpoints surrounding an expanding network of automated campaign paths.

    Automation should discover what you do not know. It should not spend your budget rediscovering what you already know.

    This is especially important when broad matching or AI-driven expansion can reach searches outside your initial keyword set. Broad match defaults have long created a situation in which inexperienced advertisers can pay to teach the system lessons their businesses could have supplied in advance. If a query category is known to be irrelevant, exclude it before launch rather than waiting for wasted clicks to prove the point.

    Configure the controls that correspond to the risk

    1. Query risk: Add negative keywords for known irrelevant intent. Review whether exclusions need to apply at the campaign or account level based on how broadly the rule should operate.
    2. Brand risk: Decide how your own brand, excluded brands, and competitor brands should be handled. AI Max provides brand inclusions and exclusions, but the advertiser still has to define the policy.
    3. Network risk: Decide whether Search Partner Network traffic is permitted. Set the available network control deliberately, then evaluate actual network performance rather than relying on a general assumption about where AI Max will expand.
    4. Economic risk: Make margin, returns, sell-through, and other meaningful product differences visible through your feed organization, labels, conversion values, reporting, or campaign design.
    5. Measurement risk: Confirm that the conversions guiding bidding represent outcomes the business values. A campaign cannot optimize toward profit if the recorded objective rewards a weak proxy for it.
    6. Visibility risk: Make sure the team knows where to inspect search terms, AI Max match type, match source, network delivery, and brand exposure before more traffic arrives.

    Competitor traffic shows why these controls cannot be reduced to a performance metric. In one documented rollout, AI Max expanded traffic by targeting a much larger competitor. The reported performance looked good, but the advertiser had intentionally avoided those searches to prevent a bidding war. The system found an opportunity inside the data while violating a strategy that had never been encoded.

    That is not an argument against AI Max. It is an argument for declaring competitor policy before enabling it and checking search terms from the first review. Strong aggregate results should increase your curiosity about where the gains came from, not end the investigation.

    Be equally careful with conclusions drawn from a small number of campaigns. Early AI Max observations appeared to show a preference for Search Partner traffic, but additional data did not support that as a general rule. Use account-level findings to form a testable question. Do not turn them into a platform-wide belief until the evidence warrants it.

    Verify patiently, then keep strategy human

    Good oversight separates two jobs that are often confused. Verification asks whether the system is doing what you authorized. Evaluation asks whether the result is good enough to continue. Verification starts immediately; evaluation may need to wait for conversions to mature.

    Inspect behavior in the right order

    Use this sequence when reviewing an automated campaign:

    1. Delivery: Check where spend occurred, including networks, locations, channels, and any other enabled expansion surface.
    2. Matching: Inspect search terms, match type, and match source. Identify which traffic came from your explicit targeting and which came from automation.
    3. Strategic fit: Look for prohibited brands, competitor auctions, irrelevant intent, or traffic that conflicts with your operating policy.
    4. Conversion quality: Determine whether the reported conversions represent qualified leads, completed sales, or another outcome the business can actually use.
    5. Economics: Review CPA or ROAS alongside the margin, returns, sell-through, capacity, and customer value information relevant to the decision.

    This order keeps a blended efficiency metric from concealing an unacceptable mechanism. If the campaign reaches its ROAS target through traffic your business has explicitly rejected, you have enough evidence to tighten the boundary even before the long-term average settles.

    Allow for conversion lag without tolerating a breach

    After a platform update or material campaign change, immediate performance claims are unreliable when conversions take time to arrive. Google has advised advertisers in this context to wait one to two conversion cycles before assessing the effect.

    That waiting period is not permission to ignore the account. Continue checking spend, query relevance, network delivery, and other hard boundaries. If automation exceeds an approved budget limit or enters prohibited traffic, intervene. If the guardrails hold but the efficiency metric fluctuates, let the relevant conversion window mature before declaring success or failure.

    Avoid defensive target changes made only because other advertisers appear worried. Advertisers have raised target ROAS even when their campaigns were not budget-limited, a reaction that can reduce participation without solving an identified problem. A stricter target may be appropriate, but changing it can materially reduce volume. Require an account-specific reason and preserve a baseline against which the effect can be judged.

    Keep a decision log, not just a change history

    For every material adjustment, record:

    • The date and exact setting changed.
    • The business problem the change is meant to solve.
    • The expected effect on traffic, conversions, CPA, ROAS, or profit.
    • The relevant conversion lag or evaluation window.
    • The reports that will confirm where the effect came from.
    • The hard boundary that would justify intervening early.
    • The final decision after enough data has accumulated.

    When possible, avoid stacking several material changes into the same evaluation window. If you alter the target, budget, network access, negatives, and campaign structure together, even a clear performance movement may not tell you which decision caused it.

    Apply the same skepticism to controls whose labels sound clearer than their mechanics. An emerging Performance Max control for channel importance may give Google greater tolerance around a CPA or ROAS target when a channel receives more importance. Do not assume that increasing importance simply buys more of a channel at unchanged economics. Document the intended outcome, monitor actual allocation and efficiency, and reverse the change if the observed tradeoff is unacceptable.

    Finally, do not confuse prominence with profit. Paying whatever it takes to hold the top ad position was an expensive mistake in earlier paid search, and position-driven bidding can sacrifice economics for prestige. Automation does not change that principle. Your objective should describe the business outcome you want, not the visible status you hope to occupy.

    Start with one automated campaign this week. Write its automation contract, remove any split that lacks a business reason, encode known exclusions, capture a baseline, and schedule the evaluation for the end of its relevant conversion window. You will have given the system room to find demand without giving it authority to redefine what your business considers a good customer, an acceptable auction, or a profitable result.

    References


  • Human Judgment Is the Control Layer for Automated Ads

    Human Judgment Is the Control Layer for Automated Ads

    You have an hour-of-day row with spend and no conversions, an automated campaign that feels opaque, and someone asking you to "fix the waste." Excluding the hour looks decisive. It is also exactly where human judgment matters: not because a person can outbid a system one auction at a time, but because only a person can decide whether that row is mature, meaningful, and worth turning into an eligibility rule.

    Your job in automated advertising is no longer to touch every lever. It is to define the right outcome, protect the quality of the inputs, challenge weak evidence, and own changes that remove opportunities. The practical goal is not more manual control. It is better control over what the automation is allowed to decide.

    Put human judgment at the decision boundary

    Automated systems are strongest when they make frequent decisions inside a clearly defined objective. A bidding system can evaluate an auction, combine contextual signals, and adjust its bid faster than a campaign manager could. It cannot decide whether the objective itself represents a profitable customer, whether an overnight lead will receive an acceptable response, or whether the business should trade margin for growth.

    That distinction gives you a usable division of responsibility:

    DecisionWhat automation should doWhat a person must own
    Auction executionEvaluate eligible auctions and adjust bids within the chosen strategy.Choose the business objective, budget, constraints, and acceptable tradeoffs.
    Data preparationGroup records, calculate fields, identify anomalies, and assemble recurring reports.Verify definitions, attribution, data maturity, and whether the records represent real business outcomes.
    Campaign eligibilityRespect targeting, schedules, exclusions, and other account settings.Decide which opportunities the campaign should never be allowed to enter.
    Performance diagnosisSurface patterns and produce candidate explanations.Determine which explanation is credible and what evidence would disprove it.
    Final approvalPrepare a recommendation or execute an approved, bounded workflow.Accept accountability for the consequences and authorize the change.

    A simple boundary works well: let automation make high-frequency, reversible choices within an approved objective. Require human review when a decision changes the objective, conversion definition, customer promise, account eligibility, or exposure to wasted spend.

    Before approving an automated recommendation, ask four questions:

    • What outcome is the system actually optimizing?
    • Which business facts cannot be seen in the platform data?
    • Does this recommendation tune execution, or does it remove an audience, location, device, query, or time period from consideration?
    • Who will decide whether the result was acceptable after conversion lag and downstream sales are visible?

    If nobody can answer those questions, the problem is not insufficient automation. It is an undefined decision boundary.

    An ad schedule is an eligibility rule, not a cleanup tool

    Hour-of-day reports invite a common mistake. You see a weak average, label the period inefficient, and remove it. That reasoning treats every auction in an hour as if it had the same probability and value.

    Google Ads Smart Bidding works at a different level. Target CPA, Target ROAS, Maximize Conversions, and Maximize Conversion Value use auction-time bidding, with time of day and day of week among the contextual signals that can inform an individual bid. Device, location, and audience characteristics can also change the assessment. The system is not deciding that an entire hour is universally good or bad. It is evaluating the eligible auctions that occur during that hour.

    This makes the effect of scheduling easy to misread. Manual ad-schedule bid adjustments are not used by Smart Bidding, but the schedule itself is respected. Removing Tuesday morning does not tell the bidding system to be more selective on Tuesday morning. It makes every Tuesday-morning auction ineligible, including any valuable ones the hourly average concealed.

    A row with four clicks and no conversions proves only that those four recorded clicks did not yet show a conversion. It does not establish that the hour is intrinsically unprofitable. Nor does it estimate what would have happened in future auctions if the campaign had remained eligible.

    Scheduling can still be the correct decision when the restriction represents a real business constraint:

    • Home services and call-driven lead generation: Restricting delivery may be justified if an overnight inquiry cannot be answered promptly and the delayed response materially reduces its value. If those leads perform well when contacted later, the schedule would remove opportunity without fixing a business problem.
    • Appointment-based businesses: Capacity can be the binding constraint. Acquiring more demand may stop being useful once the available appointments are full.
    • Ecommerce: Customers can buy outside office hours. Operating hours alone therefore provide little basis for an exclusion; look for persistent differences in conversion value and profitability.
    • Restaurants: Opening hours, ordering hours, and reservation-search hours are not the same. Someone can make a valuable reservation before the doors open or after service ends.
    • B2B: Research does not stop at the office door. A nighttime search can produce a qualified inquiry that the sales team handles the following day.
    • News and publishing: Breaking events, elections, sports, and entertainment can move demand into hours that looked weak historically. A rigid schedule cannot anticipate every shift in attention.

    The rule is straightforward: use a schedule when you intend to prohibit participation, not merely because you want the bidding system to be cautious. If you would still want the right customer during that period, an absolute exclusion is a blunt response.

    Use a five-part evidence gate before restricting automation

    An analyst examines five visual checkpoints leading to a gated automation system.

    An automated account can generate more segmented data than a person can sensibly act on. There are 168 hours in a week before you add device, location, audience, campaign, or conversion type. Some rows will look unusually strong or weak by chance. Human judgment begins with refusing to confuse a visible pattern with a reliable decision.

    1. Wait for enough observations. Expand the date range until the pattern has had a reasonable chance to repeat. In many accounts, 60 to 90 days is a more useful starting window than a few recent days, but it is not a universal threshold. A high-volume account may mature sooner; a low-volume account or long sales cycle may need more time. The test is repeated evidence, not compliance with an arbitrary number of days.
    2. Let conversions mature. A click can convert hours or days later. Google Ads generally assigns the conversion to the date of the ad interaction, so a recent period may temporarily show its spend before all associated conversions have arrived. Check the account’s typical conversion delay before declaring yesterday evening inefficient. If the outcome data is still arriving, the conclusion is still changing.
    3. Inspect value below the average. Conversion count and average CPA may omit the result that matters. Review conversion value, lead quality, downstream sales, and customer value where those signals are available. A period with fewer conversions may still acquire better customers. Conversely, a superficially efficient period may be producing low-quality actions that never become revenue.
    4. Identify the business mechanism. Ask why the time period would be less valuable. A credible explanation might involve response time, fulfillment, inventory, staffing, or appointment capacity. If you cannot name a mechanism, treat the pattern as a question to investigate rather than a rule to implement. If the mechanism is operational, consider fixing the operation before suppressing demand.
    5. Test the restriction against broader eligibility. When traffic volume supports a meaningful comparison, test the scheduled version against a version that remains eligible for more hours. Use the business KPI that motivated the decision, allow for conversion lag, and change one major eligibility dimension at a time. One documented restaurant test found that unrestricted delivery produced 12% more conversions while reducing CPA by 3%. That is a single account result, not a universal benchmark; its value is showing why the counterfactual must be measured rather than assumed.

    This gate separates two different questions. The report asks, "What performance was recorded during the auctions that occurred?" The decision asks, "Will prohibiting future auctions improve the business result?" You cannot answer the second merely by sorting the first from worst to best.

    Document the decision before launch. Record the proposed restriction, the evidence window, known conversion delay, primary KPI, downstream quality check, operational rationale, test design, owner, and review point. That short record prevents a temporary anomaly from becoming permanent account folklore.

    Build an operating loop that removes labor, not accountability

    Two advertising professionals oversee a circular automated workflow while mechanical arms handle routine tasks.

    There are usually two kinds of automation in the same advertising workflow. The ad platform automates delivery and bidding. Analyst-facing AI can summarize meetings, organize exports, flag anomalies, draft formulas, generate basic scripts, and turn findings into review-ready formats. Both can save time, but neither should silently expand its own authority.

    Use this operating loop for consequential campaign changes:

    1. Frame the decision. Write one sentence naming the action under consideration and the business result it is meant to improve. "Reduce wasted spend" is too vague. "Determine whether overnight eligibility lowers qualified-lead profitability after leads have matured" can be tested.
    2. Assemble the evidence. Let approved tools merge exports, label time periods, calculate recurring fields, and flag unusual movement. AI is well suited to categorizing large datasets and surfacing changes that require investigation. Keep sensitive data inside approved systems and verify calculated fields before relying on them.
    3. Expose what the platform cannot see. Add sales acceptance, revenue, lead disposition, staffing constraints, inventory conditions, and other business context that is absent from the advertising interface. If the optimization signal rewards form submissions while the business needs completed sales, fix or supplement the signal before asking the algorithm to optimize harder.
    4. Generate challenges, not verdicts. Ask AI to find missing information, contradictory evidence, immature periods, unusually small samples, and alternative explanations. Do not ask it to make a final pause-or-expand decision from a summary table. AI can identify where something changed; the causal explanation still needs validation.
    5. Approve a bounded test. A person chooses the hypothesis, success measure, duration appropriate to the conversion cycle, and rollback condition. The system can then execute within those limits. Eligibility changes deserve particular care because the excluded auctions stop producing evidence once they disappear.
    6. Review and record the outcome. Wait for the agreed data to mature, compare the result with the predeclared KPI, check downstream quality, and record what changed. Meeting transcription and task extraction can remove administrative work by capturing decisions, owners, deadlines, and unresolved debates, but the meeting owner should review the output before it becomes the record.

    Prompt design should reinforce that boundary. Instead of asking, "Which hours should we turn off?" ask:

    • List time periods with persistent performance differences and show the observation count, date range, and conversion maturity for each.
    • Separate facts in the export from possible explanations that require validation.
    • Flag periods where conversion count, conversion value, and downstream lead quality point in different directions.
    • Identify which proposed actions tune execution and which actions remove campaign eligibility.
    • Draft a test plan and a list of missing inputs, without making the final approval decision.

    The same principle applies to technical work. AI can draft spreadsheet formulas, SQL, regex, account scripts, or reporting logic. Those outputs are useful because you can test whether they work. Review generated code, run it in a safe and limited context, and verify its output before it can change a production account. Fluent text is not proof of correct logic.

    Measure automation by the labor it removes and the errors it helps catch: rows reviewed, analysis time saved, anomalies surfaced, manual steps eliminated, revision cycles, and error rate. Measure the human control layer by decision quality: valid conversion signals, explicit ownership, mature evidence, reversible tests, and fewer unexplained account restrictions. Faster execution is valuable only when it carries a sound decision forward.

    Key takeaways

    • Let automated bidding make auction-level choices within a business objective that a person has defined and can defend.
    • Treat schedules, exclusions, and targeting limits as eligibility decisions. They remove opportunities rather than instructing Smart Bidding to bid more carefully.
    • Do not act on a weak hourly row until you have enough observations, mature conversions, business-value data, and a plausible mechanism.
    • Test restrictions against broader eligibility when volume permits. Historical averages do not reveal the outcome of auctions you choose not to enter.
    • Use AI to prepare evidence, find gaps, document decisions, and produce testable technical work. Keep strategy, prioritization, approval, and accountability with people.

    At your next account review, take one proposed automation change and label it either an execution aid or an eligibility decision. Automate the labor around the first. Put the second through the evidence gate before approving it. That small distinction is where responsible automated advertising starts.

    References


  • Google vs. Microsoft AI Max: A Practical Testing Plan

    Google vs. Microsoft AI Max: A Practical Testing Plan

    You’re not deciding whether AI can write another ad variation. You’re deciding how much control to give an advertising platform over the searches you enter, the promise your ad makes, and the page a prospect sees after clicking.

    Google and Microsoft AI Max share that basic operating model. The safest way to adopt either one is to treat it as a controlled change to your query-to-conversion system, not an account-wide switch. That means qualifying your conversion data, setting boundaries, and testing against business outcomes before you expand it.

    AI Max is one setting with three linked decisions

    AI Max is an optional setting within a Search campaign, not a separate campaign type such as Performance Max. That distinction matters. You can introduce it inside an existing Search structure and test a defined campaign without rebuilding the account around a new format.

    On both Google and Microsoft, AI Max connects three functions:

    1. Search term matching expands eligible demand. The system uses your keywords, ads, landing pages, user intent, and contextual signals to find relevant searches that a static keyword list may miss. This is particularly useful for longer, conversational queries that do not fit neatly into a conventional keyword taxonomy.
    2. Text customization adapts the message. Existing assets and website content become inputs for additional messaging variations. The platform can test those variations and choose combinations at auction time.
    3. Final URL expansion selects the destination. Rather than sending every click to one fixed landing page, the system can route a prospect to the page it considers the closest match for that person’s intent.

    The value comes from alignment. A newly matched query is less useful if the ad still speaks to a broader keyword theme. A customized ad is risky if it makes a promise that the destination cannot support. Final URL expansion closes that gap by allowing the query, message, and page to change together.

    You do not have to activate all three functions at once. An ecommerce advertiser with many similar-margin products, for example, could begin with text customization and Final URL expansion to improve product coverage while leaving expanded search term matching off. That is a reasonable first test when destination coverage is the opportunity but query expansion is the concern.

    The trade-off is diagnostic clarity. Testing one component tells you more about that component, while testing the full bundle tells you whether the complete intent-to-page system improves the commercial result. Decide which question you need answered before you configure the experiment.

    Qualify your conversion signal before expanding queries

    A stream of mixed digital signals passes through layered filters, leaving a few bright signals connected to a shopping bag, calendar tile, and contract folder.

    Search term matching is the part of AI Max most dependent on conversion quality. Google and Microsoft both require conversion-based bidding when it is enabled. The system is not merely looking for searches that appear semantically relevant; it needs conversion feedback to learn which searches are economically useful.

    An ideal starting point is at least 15-30 conversions during a 30-day period before relying on conversion-based bidding. Treat that as a readiness check, not a promise of success. Volume cannot repair duplicate events, inflated lead counts, missing offline outcomes, or a primary conversion that does not represent meaningful business progress.

    Before enabling expanded matching, verify four things:

    • Your primary conversion fires only when the intended action actually occurs.
    • The optimization goal reflects value to the business, not merely an easy action that happens frequently.
    • Conversion values distinguish materially different outcomes where those outcomes have different economics.
    • Offline outcomes are returned to the platform when the real result occurs after the website session.

    If you cannot reach the conversion-volume range, you have three defensible choices: wait until the account has more signal, test text customization or Final URL expansion without search term matching, or build carefully valued micro-conversions.

    A staged application funnel illustrates the micro-conversion approach. Beginning an application might receive a value of $10, reaching the midpoint $20, completing it $50, and receiving an accepted application its actual value through an offline conversion upload. Those figures are an example of the structure, not values to copy. Your values should reflect the relative economic importance of each stage, and a target ROAS should keep bidding focused on the steps that matter most.

    Arbitrary micro-conversion values create a predictable failure mode: the bidder learns to maximize inexpensive early actions even when they rarely become customers. If you cannot defend the relationship between a stage and eventual value, do not use that stage as a substitute for the outcome you really want.

    Set brand, message, and destination boundaries first

    AI Max amplifies the instructions and content already present in your account and website. A clear brand system gives it useful boundaries. An inconsistent site gives it more inconsistent material to combine.

    Before launch, write down:

    • The brands the campaign may target and any brands it must exclude.
    • The search terms that are unacceptable even if they appear contextually related.
    • The messages, claims, or positioning rules generated text must follow.
    • The pages that can safely receive paid traffic, including whether their offers, availability, geography, and conversion paths are current.

    Both platforms support brand inclusions, brand exclusions, term exclusions, and message constraints, but their list structures differ as of September 2026:

    ControlGoogle AI MaxMicrosoft AI Max
    Brand inclusion lists10 per campaign, up to 5,000 brands per list20 per campaign, up to 100 brands per list
    Brand exclusion lists10 per campaign, up to 5,000 brands per list20 per campaign, up to 100 brands per list
    Term exclusions25 per campaign25 per campaign
    Message constraints40 per campaign40 per campaign

    The practical difference is organizational. Google provides fewer brand-list containers with much larger capacity per list. Microsoft provides more containers with a smaller per-list capacity. Build your taxonomy around the platform you are configuring instead of assuming one brand-list design will transfer unchanged.

    Message constraints deserve the same care as brand exclusions. Identify what generated copy must not imply: unsupported discounts, unavailable services, absolute claims, or promises that only apply to one product or region. Then inspect the pages that Final URL expansion could treat as a match. If the site contains stale promotions, incomplete product pages, or conflicting regional information, use a more conservative component test until those pages are ready for paid traffic.

    Run an experiment that can answer a commercial question

    Two side-by-side advertising test lanes receive the same inputs and collect order boxes, appointment tokens, and coins in separate outcome trays.

    A good AI Max test does not ask whether the platform can find more traffic. It asks whether the added matching, messaging, and routing produce more valuable business outcomes at an acceptable cost.

    Use this sequence:

    1. Write one testable hypothesis. For example: enabling all three AI Max functions will increase conversion value without pushing ROAS below the campaign’s acceptable level. Name the primary metric and the guardrail before the test begins.
    2. Choose a strong, stable campaign. Start where performance is consistent and traffic is sufficient to reveal a meaningful difference. A low-volume or recently restructured campaign makes it harder to separate the effect of AI Max from ordinary volatility.
    3. Record the treatment. Note whether the test enables search term matching, text customization, Final URL expansion, or all three. Also record brand controls, term exclusions, message constraints, bidding goals, and conversion settings.
    4. Split traffic 50/50. An even division gives the control and treatment comparable opportunity and makes attribution of the performance difference more credible.
    5. Respect the platform’s experiment design. Google’s AI Max experiment diverts traffic within the existing campaign. Microsoft’s Search Experiments compare the standard campaign with a cloned test campaign that has AI Max enabled. Check that the Microsoft clone has not introduced unrelated differences.
    6. Allow the system to learn. Do not stop because the first observations look unusually good or bad. AI-powered matching and conversion-based bidding need enough learning data before the comparison is useful. No universal number of days replaces adequate conversion evidence.
    7. Judge the result with business metrics. Compare conversion rate, CPA, ROAS, revenue, and conversion value. Click growth and a larger search-term footprint are diagnostic signals, not success criteria.

    Interpret those metrics together. A higher conversion rate with worse ROAS may mean the system found more easy but low-value actions. A lower CPA can still hide a decline in accepted leads if your offline outcomes are missing. Higher revenue with a modestly lower conversion rate may be worthwhile when average conversion value rises enough to support the campaign’s objective.

    When performance changes, diagnose the entire path. Ask whether the treatment entered different searches, generated a different promise, selected a different page, or optimized toward a different mix of conversion values. AI Max changes all three layers when fully enabled, so a keyword-only explanation will often be incomplete.

    Do not use experimental lift on one platform as proof that the same setup will produce the same lift on the other. Google tests within an existing campaign, while Microsoft uses a cloned treatment campaign. Auction conditions, inventory, account history, and experiment architecture remain platform-specific. Each AI Max treatment needs to beat its own valid control.

    Key takeaways and your next move

    • Google and Microsoft AI Max connect expanded search matching, customized text, and dynamic landing-page selection inside Search campaigns.
    • You can test one, two, or all three functions, but the complete bundle is designed to keep the query, ad promise, and destination aligned.
    • Do not enable search term matching until conversion-based bidding has accurate data; 15-30 conversions in 30 days is the ideal readiness range.
    • Configure brand inclusions, exclusions, term exclusions, message constraints, and destination quality before exposing more traffic to automation.
    • Use an even experiment split and decide on CPA, ROAS, revenue, or conversion value – not clicks – as the basis for rollout.

    Your next move should be deliberately small: select one stable campaign, document the conversion outcome and constraints, and launch a 50/50 experiment. Expand AI Max only after the treatment proves it can improve the business result without breaking the relationship between the search, the message, and the page.

    References


  • How to Test ChatGPT Ads Bidding and Platform Targeting

    How to Test ChatGPT Ads Bidding and Platform Targeting

    You are deciding whether to turn on Maximize results, separate iOS, Android and Web traffic, or trust a larger conversion total. Those look like three independent choices. They are actually one measurement problem: automated bidding can only optimize the goal and conversion signals you give it.

    The safest rollout is deliberate. Use platform controls to isolate meaningful behavior differences, automate bids only after the outcome is trustworthy, and keep view-through attribution separate from evidence of incremental growth.

    Platform targeting controls surfaces, not audiences

    A single crowd connects through separate illuminated routes to smartphone, mobile device, and desktop surfaces.

    The Eligible platforms setting lets you choose one or more of the iOS app, Android app and Web when creating a campaign. This answers where an eligible ad can appear. It does not tell the system which customer is valuable, make the conversion event more reliable or replace your campaign goal.

    That distinction matters because platform selection can look more precise than it is. Excluding Android, for example, is not an audience strategy. It is a distribution decision that removes Android opportunities from that campaign. You need evidence that the surface itself changes the economics or user journey before you make that trade.

    What you knowPractical campaign structureMain risk
    You have no reliable evidence that iOS, Android and Web perform differentlyKeep the eligible surfaces together and report them separately where possibleAggregated results can conceal a weak surface
    A surface has a repeatable difference in conversion quality, customer value or user behaviorCreate a separate campaign for that surface so its eligibility and budget decisions can be managed independentlyEach campaign receives a smaller pool of conversion signals
    Conversion tracking is inconsistent between an app and the WebRepair and validate the measurement path before using reported performance to exclude or scale either surfaceAutomated bidding may optimize toward a tracking difference rather than a business difference

    Do not split campaigns because one platform has a lower click-through rate. First compare the result that matters after the click or view: accepted leads, completed purchases, retained customers or another outcome your business can verify. A surface can attract fewer clicks yet produce better customers. It can also produce cheap conversions that your sales or fulfillment systems later reject.

    Before separating platforms, write down the hypothesis in a falsifiable form. For example: Web traffic produces a higher rate of accepted applications than app traffic when both use the same qualification rules. Then confirm that the conversion event, attribution treatment and downstream acceptance rule are comparable. If you cannot make that comparison cleanly, segmentation will create more campaign controls without creating more knowledge.

    Maximize results needs a business constraint outside the algorithm

    Maximize results automatically sets and adjusts bids toward the campaign’s selected goal, with the aim of generating as many results as possible from the available budget. That is a volume objective. It should not be read as a promise to maximize profit, customer lifetime value or qualified pipeline.

    The selected conversion therefore becomes an operating instruction. If you optimize for a shallow event because it happens frequently, the system can become efficient at producing that shallow event. The campaign dashboard may improve while the commercial outcome stays flat.

    Write a short optimization contract before enabling automation:

    • Primary result: Name the exact event the campaign will optimize. Avoid labels such as qualified conversion unless the qualification rule is explicit.
    • Business acceptance rule: Define what makes the result useful after it enters your CRM, commerce system or other system of record.
    • Quality metric: Choose the downstream rate or value you will inspect alongside campaign conversion volume.
    • Budget boundary: Decide how much spend you are willing to treat as test exposure before the business outcome is validated.
    • Scale rule: State what must improve before you increase the allocation. A higher platform-attributed conversion count is not sufficient by itself.
    • Stop rule: Identify the signal that will pause the test, such as deteriorating accepted-result cost or a measurement failure.

    Because automated bidding spends real money, start with a deliberately limited test allocation. Do not use an amount that would create a material problem if the selected event turns out to be a poor proxy for revenue or qualified demand.

    Change one major variable at a time. Expanding platform eligibility and enabling Maximize results in the same test makes a positive result ambiguous: you will not know whether the improvement came from new inventory, different bids or a changed conversion mix. Test the platform structure while holding the bidding approach steady, then test the bid strategy while preserving the chosen platform mix. Keep the goal, creative, offer, landing experience and conversion implementation as stable as the campaign permits.

    Evaluate the test over a period that covers your normal conversion delay and business cycle. There is no universal number of days that makes a low-volume campaign conclusive. If the campaign produces too little verified outcome data to distinguish improvement from ordinary variation, keep the decision provisional rather than inventing certainty from percentages.

    View-through conversions change the report, not necessarily demand

    ChatGPT Ads Manager reports one-day view-through conversions at the campaign, ad group and ad levels. A view-through conversion is attributed when a person converts within one day of seeing an eligible ad and no qualifying ad click receives credit for that conversion.

    A view-through conversion is not automatically invalid. It answers a different question from a click-through conversion. It shows that an ad exposure preceded the conversion within the defined window. It does not, by itself, establish that the ad caused a conversion that otherwise would not have happened.

    Keep three measurement questions separate

    • Did the person click before converting? Use click-through conversion reporting to understand the measurable engagement path.
    • Did an eligible ad view precede the conversion? Use the one-day view-through metric to understand attributed exposure without a credited click.
    • Did advertising create additional business? Use a controlled incrementality method where the decision warrants it. Attribution reporting alone cannot answer this causal question.

    The addition of view-through reporting means more conversions can be attributed beyond conversions generated directly from clicks. Annotate the point at which this reporting became visible in your account. Otherwise, a pre-and-post chart may look like campaign performance improved when only the attribution coverage changed.

    Build a compact scorecard with four lines:

    • Click-through conversions and their cost.
    • One-day view-through conversions and their share of all ChatGPT-attributed conversions.
    • Verified business outcomes from your system of record and their cost.
    • The acceptance rate or realized value of the results attributed to the campaign.

    The view-through share is a diagnostic, not a quality score. Calculate it by dividing view-through conversions by all ChatGPT Ads-attributed conversions for the same scope and period. If that share rises sharply, investigate the composition before declaring better performance. Ask whether the eligible platform mix, ad exposure, reporting availability or customer behavior changed.

    Use conversion integrations to improve signals, not inflate counts

    Advertisers can connect WorkMagic to view ChatGPT campaign performance with other channels and send conversion signals to OpenAI through the Conversions API. That can make downstream outcomes more useful to campaign measurement, but connecting systems does not validate the data automatically.

    Document each event name, timestamp, originating system, business definition and rejection rule. Confirm how the same real-world outcome is handled if it can arrive through more than one measurement route. A cross-channel dashboard is useful for reconciliation, but it does not turn overlapping attribution claims into incremental customers.

    Use a staged rollout that preserves a readable baseline

    Four separated testing chambers show a baseline, added device traffic, constrained automation, and distinct conversion signals.

    A clean rollout gives each new control one job. Use this sequence:

    1. Record the baseline. Save the current bid approach, eligible surfaces, goal, conversion definitions, spend and downstream outcome metrics. Include a representative period that covers your usual conversion lag.
    2. Validate the goal event. Trace reported conversions into the system of record. Check that the event fires at the intended moment and maps to the business result named in your optimization contract.
    3. Form a platform hypothesis. Decide whether iOS, Android or Web should differ based on repeatable outcome quality or customer value, not a single top-of-funnel metric.
    4. Test platform eligibility first. Hold the bid strategy and other major inputs steady while you learn whether a surface warrants separate management.
    5. Test Maximize results second. Preserve the selected platform structure so you can judge the automated bidding change against a readable reference.
    6. Separate attribution types. Review click-through and one-day view-through conversions independently, then reconcile both with verified business outcomes.
    7. Scale on commercial evidence. Increase the allocation only when volume and downstream quality support the decision. If they disagree, repair the goal or signal before giving the system more budget.

    ChatGPT Ads is also expanding into Brazil and Mexico. If either market is part of your plan, treat geographic expansion as another major variable. Launching a new market while changing platforms and bidding creates several plausible explanations for any movement in performance. Keep the market, offer, language, conversion path and bid test documented separately so you know what you are scaling.

    Keep paid ChatGPT performance separate from organic AI visibility as well. Ad-attributed conversions tell you about the paid campaign under its attribution rules. They do not measure whether your brand is cited, recommended or discovered organically in AI-generated answers. Use distinct reporting for those two jobs.

    Key takeaways

    • Platform targeting determines whether a campaign can run on iOS, Android, Web or a combination; it is not a substitute for audience or conversion strategy.
    • Separate platforms only when repeatable differences in business outcomes justify smaller data pools and additional campaign management.
    • Maximize results seeks more results from the available budget, so the quality of the selected goal determines what the automation learns to pursue.
    • Test platform eligibility and bidding changes separately. Changing both at once makes the outcome difficult to interpret.
    • Report one-day view-through conversions separately from click-through conversions, and do not label attributed exposure as incremental lift.
    • Scale only when campaign metrics agree with accepted leads, revenue or another verified outcome in your system of record.

    Your next move should be a measurement decision, not a settings decision. Name one verified business result, confirm how it reaches ChatGPT Ads, and choose the eligible platform structure that gives you a clean test. Only then should Maximize results receive more budget to optimize.

    References