Tag: Content Optimization

  • Google Discover’s “Dive Deeper” Test: A Publisher Playbook

    Google Discover’s “Dive Deeper” Test: A Publisher Playbook

    If Google Discover sends you meaningful traffic, the new “Dive deeper” experiment deserves a measurement plan, not a panic rewrite. The AI-powered card can occupy a feed position that might otherwise show publisher content, then answer part of the user’s need before offering links to the web.

    Your immediate job is to separate a plausible traffic risk from an observed traffic loss. Establish a Discover baseline, isolate the content most exposed to the test, and make the value of clicking unmistakable. You can do all of that without guessing at an undisclosed ranking factor or inventing a new schema strategy.

    What the test changes in the Discover journey

    A normal publisher card offers a relatively direct choice: open the content or continue scrolling. “Dive deeper” introduces another route. A person can enter an AI-generated topic overview and then decide whether one of its linked stories, community reactions, or pieces of original reporting deserves another click.

    Google describes those destination links as prominent, but prominence doesn’t remove the added decision point. The overview itself may satisfy a casual reader. A publisher also has to win selection among several related resources rather than win the initial feed interaction alone.

    That creates three distinct risks for publishers:

    • Displacement: the topic card may use feed space that could have carried a publisher’s individual item.
    • Intermediation: the user reaches an overview before reaching a publisher, adding another choice between discovery and the site visit.
    • Substitution: the generated overview may provide enough context that some people no longer need the underlying coverage.

    Those are mechanisms, not measured outcomes. Google is starting the experiment with videos and trying multiple designs. That makes it premature to treat the interface as a completed rollout, assume every Discover user can see it, or attribute every traffic decline to it.

    Measure the test without mistaking correlation for cause
    Two streams of content tiles pass through separate test pathways while a magnifying lens and measuring vessels represent controlled analysis.

    A total traffic chart won’t tell you whether “Dive deeper” affected your site. Publishing volume, subject mix, headline quality, seasonality, and changing audience interest can all alter the same line. You need a Discover-specific view and enough page-level detail to identify the shape of the change.

    1. Preserve your baseline. Export Discover clicks, impressions, click-through rate, and landing-page performance from Google Search Console. Use a period long enough to show your site’s normal range rather than selecting only a convenient high point.
    2. Record editorial context. Annotate major changes in publishing frequency, topic selection, video output, headlines, and distribution. Otherwise, a newsroom decision can look like a platform effect.
    3. Separate video-led content. Because the experiment begins with videos, compare pages built around video with the rest of your Discover inventory. Keep the classification consistent; don’t move a page between groups merely because its performance changed.
    4. Inspect pages before aggregates. Identify which landing pages lost impressions, which retained exposure but lost clicks, and which continued to convert after the visit. A sitewide average can conceal all three patterns.
    5. Connect visits to outcomes. Pair Discover traffic with the action that matters on your site, such as engaged reading, registration, subscription, or revenue. Fewer visits would still be harmful at scale, but a publisher should know whether the remaining visits became more or less valuable.

    Use the pattern below as a diagnostic guide, not as proof of exposure to the experiment.

    Pattern in your dataWhat it may indicateWhat to check next
    Impressions fall while CTR stays near its normal rangeReduced feed exposure or weaker topic relevanceCompare publishing volume, subject mix, and video-led versus non-video pages
    Impressions hold while CTR fallsA more competitive or more satisfying interface, or weaker packagingReview the affected headlines, media, and the distinctive value promised by each page
    Clicks fall while value per visit holdsA volume problem rather than a visitor-quality problemModel the total subscription or revenue impact and reduce channel concentration
    Only a small group of pages declinesA page, format, or topic issue rather than a sitewide platform effectCompare those pages with stable content before changing the whole editorial plan

    If you cannot identify which users encountered “Dive deeper,” describe any relationship as an association. A decline that begins during a platform experiment is worth investigating, but timing alone doesn’t establish causation.

    Give readers a reason to continue beyond the overview
    A reader moves from a small translucent summary card into a series of deeper chambers filled with visual research and practical resources.

    The wrong response is to make content longer or more mysterious. An overview competes most easily with generic coverage that repeats known facts. Your stronger position is content whose useful part cannot be reproduced by a short topic summary.

    Google says the expanded experience can link to related stories, community reactions, and original reporting. Treat those labels as clues about the types of destination that can complete a reader’s journey, not as confirmed ranking factors.

    • Make the unique asset visible in the headline. Name the interview, analysis, data, demonstration, timeline, local detail, or expert interpretation the reader will receive. A broad topic label gives the overview little reason to send the user onward.
    • Put original evidence near the top. If the page contains reporting, show what was learned and how. Don’t bury the differentiating material beneath a generic explanation that an overview can already provide.
    • Define the unanswered question. A useful headline and opening should reveal what the short overview cannot settle: why an event happened, what changed, who is affected, how competing claims differ, or what the viewer can verify in the full video.
    • Match the promise to the page. A headline that implies original reporting must lead to original reporting. Artificial curiosity may win an occasional click, but it creates a poor destination and weakens the value of being selected.
    • Build a useful next step on your own site. Connect the landing page to genuinely related analysis, primary material, or an update path. If Discover supplies a more fragmented entry point, your internal journey has to restore context quickly.

    For video-led pages, audit the complete package: title, thumbnail, opening text, video, transcript or summary, and supporting evidence. The page should make clear what the video contributes beyond the surrounding topic overview. Don’t assume that embedding a video makes otherwise generic coverage distinctive.

    Do not invent a schema fix for a user-interface test

    This is where technical teams can lose time. Google’s disclosed description of “Dive deeper” does not specify a new structured-data type, an opt-in setting, or a publisher control for the feature. There is therefore no responsible basis for promising that a markup change will secure placement or prevent summarization.

    Keep existing Article or VideoObject markup accurate when those types properly describe the page. Make sure visible titles, dates, authorship, media, and structured properties agree. That is sound technical hygiene, but it shouldn’t be presented internally as a “Dive deeper optimization.”

    Use this decision rule before approving Discover-related technical work:

    • If the change repairs inaccurate or inconsistent markup, make it.
    • If the change improves how people understand and navigate the page, evaluate it on that merit.
    • If the change depends on an undocumented “Dive deeper” signal, hold it until Google provides supporting guidance or your own controlled evidence justifies the work.

    Also keep the product distinction clear in reports. “Dive deeper” is an experiment inside Discover; it is not evidence that every Discover card is being replaced, and it should not be casually relabeled as the search results feature commonly called AI Overviews. Blurring those surfaces makes your measurements and recommendations less reliable.

    Reduce the business risk before the interface settles

    You don’t need to predict the final design to manage the exposure. Start with channel concentration. Calculate how much traffic, engagement, subscription activity, and revenue comes from Discover, then identify the pages and formats responsible for most of that contribution.

    Build scenarios from your own historical range rather than borrowing an arbitrary industry percentage. Your baseline scenario can reflect normal variation. A lower-range scenario can show what happens when Discover underperforms without disappearing. A stress scenario can show which editorial products become uneconomic if referral volume contracts materially.

    Assign an action to each scenario before traffic moves. That action might be protecting distinctive reporting, changing the volume of generic video coverage, improving conversion on the visits you retain, or accelerating channels you control more directly. Email subscriptions, direct visits, feeds, memberships, and durable search demand won’t reproduce Discover’s feed distribution exactly, but they can reduce the damage caused by dependence on any single interface.

    Avoid across-the-board cuts based on one weak reporting period. A narrow decline in commodity coverage calls for a different response from a broad loss of impressions across original work. The first may be a content-positioning problem; the second may justify a larger distribution and revenue review.

    Key takeaways

    • “Dive deeper” inserts an AI-generated topic overview between parts of the Discover experience and publisher destinations, creating a credible risk of click compression.
    • The experiment begins with videos and may use multiple designs, so its current form should not be treated as a settled, universal rollout.
    • Track Discover impressions, clicks, CTR, landing pages, content format, and downstream value separately; aggregate traffic alone cannot diagnose the cause.
    • Make original evidence and the reason to continue beyond a summary explicit in the headline, opening, and page experience.
    • Do not promise a structured-data solution when Google has not identified special markup or a publisher control for the test.
    • Model Discover dependency now so your response is based on business impact rather than fear generated by an unfamiliar interface.

    Start with a clean export of your current Discover performance. Classify the leading pages as video-led or non-video, note the distinctive value each one offers, and record the editorial conditions behind the baseline. If the interface begins affecting your audience, you will have evidence for a targeted decision instead of a reason to overhaul everything at once.

    References


  • SEO for Task Completion: Turn Rankings Into Outcomes

    SEO for Task Completion: Turn Rankings Into Outcomes

    You can rank first for a valuable query and still have an underperforming page. If visitors cannot find the price, confirm that your offer fits, or take the next step without hunting for it, visibility has delivered traffic but not the outcome they came to achieve.

    SEO for task completion closes that gap. It treats the searcher’s finished job as the target, then aligns the content, user experience, conversion path, and measurement around that job. The result is a page that does more than attract a click: it helps the right person reach a useful conclusion or complete a meaningful action.

    Treat the searcher’s finished job as the SEO target

    A keyword tells you how somebody expressed a need. It does not fully describe what they must accomplish after clicking.

    Consider a search for enterprise marketing automation pricing. The literal request is for a price, but the practical job may be to establish whether the product fits an approved budget and gather a defensible number for finance. A page that replaces pricing with a feature tour has covered the topic without completing the task.

    This distinction applies beyond commercial queries. Someone searching for an integration wants to know whether two systems work together and what limitations apply. Someone searching for a comparison needs enough evidence to eliminate unsuitable options. Someone following a technical how-to needs to reach a working end state, not merely read an explanation.

    The primary task is also not automatically your preferred conversion. A reader may need an honest compatibility answer before a trial makes sense. If you hide that answer behind a form, you have optimized the page for lead capture at the expense of the reason the visitor arrived.

    Key takeaways

    • Define what the visitor must decide, obtain, or complete before you revise the copy.
    • Put the decisive answer before background information and brand messaging.
    • Map the entire route from the search result to the confirmation state, including forms and other pages.
    • Measure completed tasks and intermediate drop-offs alongside rankings and organic traffic.
    • Use structured content and schema to clarify a useful page, not to compensate for missing answers or a broken journey.

    Write a task statement before changing the page

    Start each important landing page with one plain sentence that defines success. A useful template is: For this specific searcher, help them make this decision or complete this action by providing this information or proof, then give them a clear finish line.

    That produces statements such as:

    • Help a marketing leader determine whether the platform fits a 50-person sales team, collect evidence for an internal recommendation, and book a relevant demonstration.
    • Help a buyer establish the realistic price range and cost drivers, then request an exact quote if the range fits the budget.
    • Help an administrator confirm that the integration supports the required system and understand the setup path before starting configuration.
    • Help a prospective franchise owner confirm territory availability and investment requirements before requesting a call.

    If your statement says only that the visitor wants to learn about a subject, it is probably too broad. Replace learn with an observable verb: choose, compare, calculate, verify, configure, book, buy, apply, or call. The verb forces you to identify what done looks like.

    A strong task statement contains four parts:

    • The person and context: Who is searching, and what constraint shapes the decision?
    • The immediate job: What must the person decide or do during this visit?
    • The required evidence: Which price, limitation, comparison, proof point, instruction, or eligibility condition makes that decision possible?
    • The finish line: What visible event shows that the task was completed?

    Use the statement to control scope. Every major section should either answer a necessary question, reduce uncertainty, or move the visitor toward the finish line. Content that does none of those things is competing with the task.

    Choose one primary task per landing page. You can support secondary actions, such as downloading specifications or contacting support, but they should not compete visually with the main path. If two audiences need substantially different answers and finish lines, separate pages will usually produce a clearer experience than one page trying to serve everyone.

    Map every step between the search result and completion

    Overhead illustration of a person following a connected route from search results through information, decision, and action stages to a completion point.

    The journey begins before the landing page. The title and search snippet make a promise; the first screen must confirm it. If the result promises pricing but the visitor lands on a general product overview, the path is already broken.

    Write the shortest credible route as a sequence. A commercial path might look like this:

    1. Recognize that the page answers the query.
    2. Confirm essential fit, such as price range, compatibility, availability, or eligibility.
    3. Review enough evidence to make the decision defensible.
    4. Take the next action, such as booking, purchasing, applying, or calling.
    5. Reach a confirmation state that explains what happens next.

    Do not stop the map at the call-to-action button. Include the form, calendar, cart, account requirement, payment step, confirmation screen, and any page transition between them. A landing page can perform well while an unavailable appointment calendar or confusing form destroys the overall completion rate.

    For each step, record four things: the question in the visitor’s mind, the page element that answers it, the action that advances the task, and the failure mode that can stop progress. This makes vague concerns such as weak UX diagnosable.

    Typical blockers include:

    • A decisive fact is absent, qualified beyond usefulness, or placed far below promotional copy.
    • Supporting information lives on another page with no obvious link from the decision point.
    • The CTA uses a vague label such as Learn more even though the next step is specific.
    • A form asks for information that is not needed to deliver the requested response.
    • The mobile layout hides the action, rearranges the evidence, or makes input difficult.
    • The confirmation screen fails to say whether the submission worked or what the visitor should expect next.

    Pay attention to searches that occur in the middle of a larger task. A calculator, compatibility checker, territory finder, or structured comparison can be more useful than another broad landing page because it meets the visitor at the precise point where progress has stopped. Connect that tool directly to the next logical action instead of leaving it as an isolated traffic asset.

    Walk the path yourself on a mobile device while signed out. Start from the search-result promise, use only the information a new visitor would have, submit the form, and inspect the confirmation. Mark blockers before cosmetic imperfections. A missing price range matters more than a button color; a failed form matters more than either.

    Build the page in answer, decision, and action layers

    A task-focused page needs three layers in a deliberate order. The answer layer confirms relevance. The decision layer supplies evidence and constraints. The action layer makes completion obvious. This structure serves human readers while also making the page easier for search and answer systems to interpret.

    Lead with the decisive answer

    The first screen should resolve the visitor’s largest uncertainty. For pricing intent, show a real price, a useful range, or a clear explanation of the variables required to calculate one. For integration intent, state whether the connection exists and name important limitations. For local availability, let the visitor check the relevant market without reading the company history first.

    Supporting detail can follow. The order should mirror the decision: direct answer, qualification, evidence, action. A hero video or broad claim about innovation should not push the requested information several screens down.

    Use descriptive headings, short definitions, lists for criteria, and tables only where readers genuinely need row-by-row comparison. These elements improve scanning and create self-contained passages that answer engines can understand without stripping away essential context.

    Remove technical and interaction friction

    Performance is part of task completion. If the largest page element takes longer than about 2.5 seconds to render, it has missed Google’s benchmark for a good Largest Contentful Paint score. A visitor cannot act on an answer that has not appeared. Layout movement is similarly disruptive when it shifts a button or form just as someone tries to use it.

    Audit forms field by field. Keep a field only if it is required to complete the request, route it correctly, or support an agreed follow-up. If the immediate response only requires a name, email address, and contact method, extra qualification fields create work before the visitor has received value. Put deeper qualification into the later conversation when possible.

    Error messages should identify the exact problem without clearing valid entries. Buttons should describe the action they initiate: Book a demo, Check availability, Calculate cost, or Start the application is clearer than Submit or Continue. Place the primary CTA close to the decisive answer and repeat it after substantial evidence when the page is long.

    Connect SEO, AEO, GEO, and conversion without confusing them

    An extractable answer and a usable next step serve different parts of the same journey. Concise answers, clear entities, descriptive headings, and accurate structured data can help search and AI systems understand the page. They cannot make an unavailable product purchasable or turn a confusing form into a completed application.

    If you add JSON-LD, make it describe content and offers that visitors can actually see and use. Schema is a machine-readable representation of the experience, not a substitute for the experience. The price, availability, eligibility rule, or answer must exist on the page before its markup can clarify anything.

    The need for a strong action layer grows as AI results absorb informational demand. In Seer Interactive’s tracking, organic CTR on queries with AI Overviews reached 1.3% in December 2025 and recovered to 2.4% by February 2026, compared with roughly 3.8% on searches without an AI Overview. Those figures describe that tracked dataset rather than a universal forecast for every site, but the operational lesson is useful: the clicks that remain deserve a page capable of completing work an AI summary cannot perform, such as booking, buying, applying, or calling.

    Measure the completed task and locate the failed step

    Analyst examining an abstract multistage user pathway on a monitor where several user markers drop off before completion.

    Rankings, impressions, click-through rate, and organic sessions tell you whether people can discover and enter the page. They do not tell you whether the page helped them finish. Add an outcome metric and a small set of diagnostic events to every priority landing page.

    Use a measurement hierarchy:

    • Primary completion: The event that represents the finished task, such as a confirmed booking, completed purchase, submitted application, successful quote request, or completed configuration step.
    • Next-step progression: The proportion of eligible organic visitors who move from the landing page into the required next stage.
    • Form completion: Completed forms divided by form starts. This separates weak intent from a form that loses people after they begin.
    • Diagnostic events: Interactions that expose where progress stopped, such as opening pricing details, starting an eligibility check, clicking the CTA, encountering an error, or abandoning a required field.

    Define the denominator before reporting a rate. Task completion rate should usually be completed primary tasks divided by eligible organic landing sessions, not all site sessions. Exclude traffic that could not reasonably perform the action, such as visitors landing on support content when you are evaluating a sales journey.

    Read search and completion metrics together. The combination narrows the diagnosis:

    Observed patternMore likely problemInspect next
    Rankings and impressions declineDiscovery, relevance, or technical visibilityIndexing, query fit, internal links, and whether the page still satisfies the search
    Rankings remain stable but organic visits declineSearch-result click-through or a changing results pageTitle and snippet promise, competing result formats, and AI Overview presence
    Organic visits remain stable but completions declineLanding-page or journey frictionAnswer placement, device performance, CTA visibility, and changes to the offer
    CTA clicks remain stable but completed actions declineDownstream failureForm errors, unnecessary fields, calendar availability, cart steps, and confirmation behavior

    A quick return to the results page deserves attention because Google’s ranking systems, including Navboost, distinguish click patterns associated with satisfied and unsatisfied searches. That does not make every short visit a penalty or every single-page session a failure. Someone may find a phone number, copy a configuration value, or get a complete answer without triggering another pageview. Treat repeated return-to-search behavior as a risk signal, then confirm the likely cause with the funnel data you can observe.

    When you test a change, start at the largest observed drop rather than the easiest element to redesign. Set one primary success event, record the current path, make one coherent change, and watch downstream guardrails such as lead quality or purchase completion. If traffic is too limited for a reliable controlled test, use the form errors, device breakdowns, progression rates, and support questions you already have to choose the clearest blocker, then document the change and compare the same metrics after release.

    Keep a task record for each priority page: query group, task statement, primary completion event, path stages, largest observed drop, current owner, and next change. Revisit it during the normal SEO reporting cycle and whenever pricing, availability, forms, page templates, or search-result features change. That turns task completion from a one-time conversion project into a durable part of SEO operations.

    Start with the high-traffic landing page whose business outcome is weakest. Write its task statement, walk the full path on mobile, and remove the first blocker that prevents a qualified visitor from finishing. Keep the ranking report, but judge the next release by whether more people reach the end of the job.

    References


  • Google Search Live: An SEO Playbook for Gemini Conversations

    Google Search Live: An SEO Playbook for Gemini Conversations

    If your AI-search plan still begins and ends with a typed keyword, Google Search Live creates a blind spot. A user can ask a question aloud, refine it through follow-ups, switch languages, hear an answer, and open a web result only when more detail or proof is needed.

    The practical response is not to make your copy sound robotic or to chase a new set of supposed Gemini ranking tricks. It is to build pages that can answer one part of a conversation clearly, support that answer credibly, and help the user take the next step.

    What Search Live changes, and what remains unknown

    Gemini 3.8 Live is rolling out as the model behind real-time conversations in Search Live in the Google app. The user taps the Live icon, asks a spoken question, hears an AI-generated response, and can continue with another question.

    This is not merely voice input attached to a conventional results page. The interaction can develop over several turns. Search Live can also place web links on the screen while delivering the audio response, so the spoken answer and the visible destinations perform different jobs. The answer handles the immediate exchange; a linked page can provide verification, depth, comparison, or a path to action.

    Users are not locked into the live audio session. They can open a transcript, continue by typing, and return through AI Mode history. That makes Search Live a multi-format journey rather than an isolated voice interaction.

    Selection mechanics remain unknown. The confirmed change is the interface and its underlying model, not a disclosed Search Live ranking formula. There is no sound basis for claiming that a particular word count, schema type, conversational tone, or formatting trick will secure a link in a live response.

    That distinction should shape your strategy. Preserve the technical SEO that makes a page discoverable. Improve the parts that make it usable as an answer. Then measure business outcomes without pretending that correlation reveals a private selection system.

    Map the follow-up journey before rewriting content

    A person with a phone follows a branching illuminated path through abstract clarification, comparison, verification, and action stages.

    A keyword cluster groups searches with similar meanings. A live conversation adds another dimension: each answer can produce a new constraint, objection, comparison, or request for proof. Optimizing only for the opening question leaves the rest of that journey to chance.

    Build a follow-up map for each commercially important task. Start with questions already visible in Search Console, site search, support requests, sales calls, and customer research. Do not treat every possible wording as a separate content opportunity. Group questions by the decision the user is trying to make.

    Conversation stageWhat the user needsWhat the destination page should provide
    Opening questionOrientation or a direct recommendation boundaryA concise answer, scope, and clear definitions
    ConstraintFit for a particular use case, market, budget, or requirementEligibility criteria, limitations, and relevant alternatives
    ComparisonA defensible choice between named optionsConsistent comparison dimensions and evidence for each distinction
    Trust checkProof that the answer is current and credibleNamed evidence, methodology, dates, ownership, and material caveats
    Action questionA safe next stepInstructions, prerequisites, expected outcome, and an appropriate conversion path

    For every row in your map, assign the strongest existing URL. If several near-duplicate pages compete for the same job, decide which one should be canonical and improve its internal links. If no page can answer the question without forcing the reader to assemble fragments from several URLs, you have found a genuine content gap.

    Then test the sequence aloud. Ask the opening question and write down the most natural follow-up. Repeat until the user reaches a decision or an action. This exposes missing transitions that a spreadsheet of keywords often hides. A pricing page may answer cost but fail to explain who qualifies. A comparison page may list features but omit the limitation that determines the choice. A tutorial may explain setup without telling the reader what successful completion looks like.

    The goal is not one enormous page that attempts to answer every branch. Use a focused page for each distinct intent, then connect related pages with descriptive internal links. A live conversation can move between needs; your site architecture should make the same movement possible.

    Make every destination useful as evidence and a next step

    Visitors examine source documents at a page-shaped evidence station connected by light to several next-step doorways.

    A Search Live link can appear while the audio response is still being delivered. The page therefore has to earn the click and satisfy it. A vague introduction, an unexplained claim, or a page that hides the answer below promotional copy creates friction at exactly the moment the user wants confirmation.

    Use a repeatable answer unit for important questions:

    • Descriptive heading: Name the decision or question in ordinary language.
    • Direct response: Give the useful answer immediately, including the condition that could change it.
    • Scope: State the market, product version, audience, plan, or scenario to which the answer applies.
    • Support: Provide the fact, calculation, process, or primary evidence that justifies the answer.
    • Limitation: Put material exceptions beside the claim rather than burying them in a general disclaimer.
    • Next action: Tell the reader what to check, compare, configure, or read next.

    This structure serves both people and machine-assisted retrieval without requiring awkward question stuffing. It also gives editors a useful test: if the direct response cannot stand on its own without becoming misleading, its scope or caveat is missing.

    Write for audio clarity, but do not assume Search Live reads page copy verbatim. Use explicit nouns where a pronoun could refer to several entities. Expand an acronym on first use. Keep units attached to quantities. Name both sides of a comparison. Put a decisive exception in the same paragraph as the recommendation it limits. These choices reduce ambiguity for readers and extraction systems; they do not guarantee inclusion in a generated answer.

    Use JSON-LD to confirm meaning, not manufacture it

    Structured data should describe the visible page accurately. It should not introduce claims, reviews, prices, authors, dates, or relationships that a visitor cannot verify on the page.

    • Choose the schema type that matches the actual entity or content, not the type that appears to offer the richest result.
    • Keep names, URLs, identifiers, authorship, and publisher information consistent between JSON-LD and visible content.
    • For an Article, align the headline, author, datePublished, and dateModified values with the page. Change dateModified only when the content has been materially reviewed or updated.
    • For a Product, expose offers, currency, availability, brand, and identifiers only when those properties are genuine and maintained.
    • Validate syntax after template or deployment changes, then check that dynamically generated values still agree with the rendered page.

    JSON-LD can remove ambiguity about entities and page relationships. It cannot turn weak content into reliable evidence, and no confirmed rule makes it a shortcut into Search Live. Treat it as part of semantic and technical quality, not as a visibility guarantee.

    Preserve the journey when users switch languages

    Search Live supports switching languages during the same conversation. That capability exposes a common international SEO weakness: a translated landing page exists, but its comparison, support, pricing, or conversion pages do not.

    Audit complete decision paths rather than counting translated URLs. For each priority market, check whether the user can move from the opening explanation to constraints, evidence, comparison, and action without an unexpected language change.

    • Localize meaning, examples, units, market conditions, and calls to action instead of translating words in isolation.
    • Connect genuine language or regional equivalents with accurate hreflang annotations.
    • Keep product names and stable entity identifiers consistent across localized JSON-LD while allowing the visible wording to fit the language.
    • Avoid sending every localized page to one default-language conversion page unless that is genuinely the only supported path.
    • Review spoken questions with fluent speakers. Literal translations often miss the vocabulary customers actually use when asking for help.

    Do not publish thin machine-translated pages merely to cover more languages. An incomplete local journey creates a larger gap between the answer and the action, which is the opposite of what a conversational interface needs.

    Measure the journey without inventing Search Live attribution

    Search Live can show links during the conversation, while its transcript and AI Mode history let users revisit the exchange later. A click can therefore happen during the spoken interaction, after the user reads the transcript, or after returning to history.

    Do not assume an ordinary analytics session will identify that entire path or label it cleanly as Search Live. Use three separate evidence layers:

    • Manual observations: Record the question sequence, language, visible links, and date of each check. Treat these as samples of interface behavior, not as a visibility score.
    • Discovery data: Watch relevant landing pages and query groups in Search Console. Segment by country, language, device, and page template where the available data supports it. Look for sustained changes rather than reacting to one query or one manual check.
    • Business outcomes: Measure qualified leads, purchases, sign-ups, support resolution, or another outcome appropriate to the page. A visible link has little value if the destination does not help the user complete the task.

    Annotate material content, schema, internal-link, and localization changes so you can interpret later movement. Change one coherent part of the journey at a time when practical. If you rewrite the page, alter the template, change schema, and restructure navigation together, any improvement will be difficult to diagnose.

    Be equally careful with assisted signals. Growth in branded searches, direct visits, or returning users may be consistent with exposure in an AI experience, but it does not prove that Search Live caused it. Report those signals as directional unless your measurement system provides a defensible connection.

    Model changes add another source of volatility. As Gemini models evolve, generated responses and displayed links can change even when your pages do not. Build reporting around trends, outcomes, and documented observations rather than promising permanent placement from a single appearance.

    Key takeaways

    • Search Live turns one query into a spoken, multi-turn journey, but visible web links still give publishers a role beyond the generated answer.
    • Optimize for the sequence of decisions: opening need, constraint, comparison, trust check, and next action.
    • Give each important question a focused destination with a direct answer, explicit scope, evidence, limitations, and a useful next step.
    • Keep JSON-LD accurate and consistent with visible content. Treat structured data as clarification, not a guaranteed route into Search Live.
    • For multilingual audiences, audit the whole decision path rather than translating only the first landing page.
    • Separate manual observations, discovery data, and business outcomes. Do not claim Search Live attribution that your analytics cannot establish.

    Start with your highest-value decision journey. Say the opening question aloud, follow the natural branches, and assign one strong URL to each distinct need. The first missing or unconvincing answer you uncover is the next page worth improving.

    References


  • Amazon Alexa Listing Optimization: A Practical Framework

    Amazon Alexa Listing Optimization: A Practical Framework

    Your Amazon listing can be easy for a person to read and still be difficult for a shopping assistant to use. A shopper may describe a device, material constraint, room, task, recipient, or problem without using your primary keyword. If the deciding fact is missing, buried, or contradicted elsewhere, your listing gives Alexa weak evidence for a confident match.

    Alexa optimization starts with answerability. Your job is to turn verified product facts into clear, structured, consistent answers, then test whether those answers improve discovery without attracting shoppers the product cannot satisfy.

    Optimize the buying decision, not an imagined Alexa formula

    The platform context has changed: Alexa for Shopping has replaced Rufus as Amazon’s default AI assistant. That makes conversational product discovery an important optimization surface. It does not make an unverified ranking-factor checklist reliable.

    The Amazon catalog record is the asset you control. Improve it around the sequence a shopper follows when narrowing a purchase:

    • Relevance: Is this the right type of product for the need expressed in the request?
    • Qualification: Does it meet the shopper’s compatibility, size, material, care, capacity, or use-case constraints?
    • Choice: What verified difference gives the shopper a reason to choose it over another eligible option?

    This distinction matters because broad visibility is not automatically useful visibility. Vague claims may make a product sound suitable for more situations, but they also increase the risk of a poor match. Optimize to become the right answer to a defined need, not merely an answer that can be mentioned.

    Keywords still help label the product. They are not the whole task. A phrase such as portable fan identifies a category, while a request such as a fan that fits on a narrow desk and runs from a particular power source introduces conditions. Your listing needs accurate facts that resolve those conditions. Repeating the category phrase cannot do that work.

    Build a query-to-attribute map for one ASIN

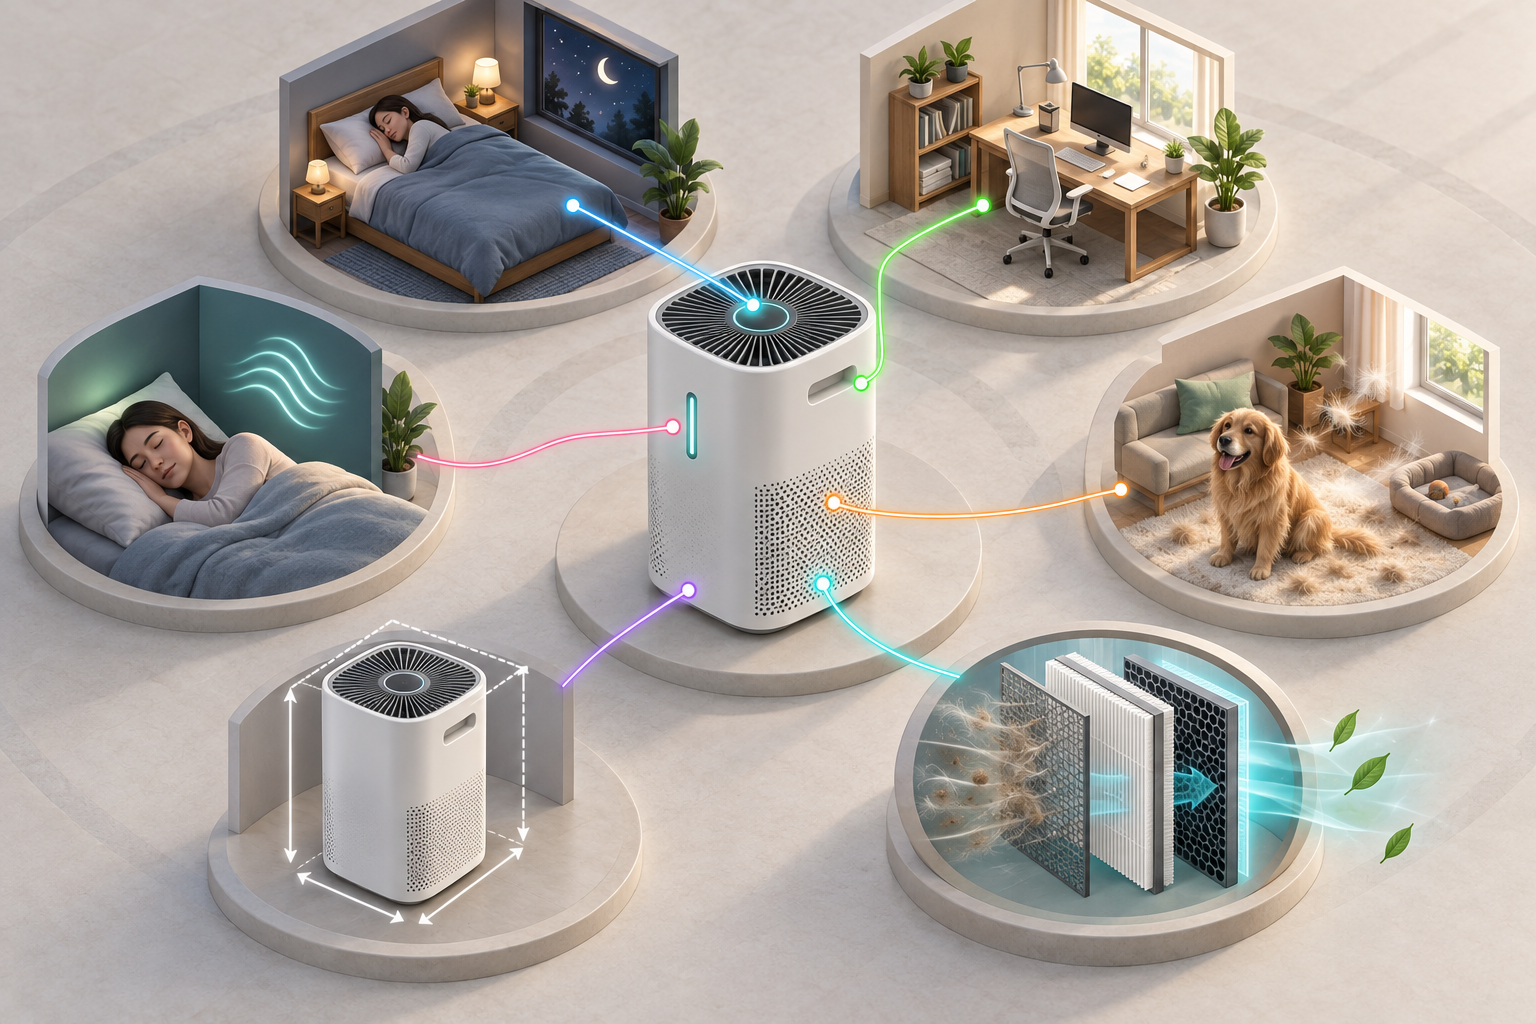
    A central air purifier is connected by colored paths to visual scenes representing room, pet, filtration, size, office, and quiet-use needs.

    Start with one Amazon Standard Identification Number rather than rewriting an entire catalog. Gather recurring language from customer questions, service tickets, reviews, return reasons, and search-term records you already use. Do not copy customer claims into the listing. Use the language to identify decisions that the current listing may leave unresolved.

    Turn each important question into a row in a query-to-attribute map. The map connects what a shopper asks to the exact product fact that should answer it.

    IntentTypical shopper questionEvidence the listing needsCommon failure
    CompatibilityDoes it work with a particular model or system?Exact supported identifiers, required conditions, and known exclusionsBroad compatible wording with no model boundary
    Use caseCan I use it for a particular task or environment?An explicit supported use and any relevant limitationA feature is named, but its practical use is left for the shopper to infer
    Dimensions or capacityWill it fit or hold what I need?Exact measurement, unit, and variant-specific valueThe value appears only in an image or differs between fields
    Material or careWhat is it made from, and how is it maintained?Precise materials and care instructions for the affected componentsAn umbrella term hides component-level differences
    Included itemsWhat arrives in the package?A clear distinction between included, optional, and merely compatible itemsAccessories shown or mentioned appear to be included
    Audience or constraintIs it suitable for a particular user or requirement?Verified suitability criteria and an honest boundarySuitability is inferred from marketing language rather than supported by a product fact

    Prioritize questions whose answers can change the purchase or prevent the wrong purchase. A color preference may matter, but an incompatible connector, incorrect dimension, missing accessory, or unsupported environment can make the product unusable. Those decisive facts deserve the clearest fields and the most visible copy.

    For each row, write one canonical answer before editing Amazon. A compatibility answer might follow this pattern: [product and variant] is compatible with [verified models] when [required condition]. It does not support or include [important boundary]. The placeholders force you to separate an actual product fact from a phrase that merely sounds persuasive.

    You do not need to insert every possible spoken variation into the visible listing. Establish the fact in plain language, then add natural synonyms only where they remove a genuine vocabulary gap. Repetition without new meaning makes the copy harder to scan and does nothing to resolve an unanswered constraint.

    Put each product fact in the field best suited to it

    A strong Alexa-oriented listing is not one long block of optimized prose. It is a coordinated catalog record. Structured attributes hold precise values. The title establishes identity. Bullets resolve major decisions. Longer content supplies context. Search-term fields cover relevant language that would be awkward in visible copy.

    Complete structured attributes before polishing prose

    Fill every applicable product-detail field with the verified value for that exact variant. Depending on the product, this may include product type, material, dimensions, capacity, color, model, power requirements, care instructions, compatibility, or included components.

    Do not force a value into an attribute that does not apply, and do not guess when product documentation is unclear. An incomplete record can be corrected after the fact is verified. An invented value can mislead the shopper, increase returns, and create a conflict that spreads across the listing.

    Keep the title focused on product identity

    The title should let a shopper identify the item and its defining variant without decoding a chain of claims. Include the product type and the details required to distinguish the purchasable item. Do not turn the title into a compressed FAQ or repeat near-identical phrases in the hope of covering more requests.

    If a term changes what the product is, it may belong in the title. If it explains when, why, or how the product is useful, it usually belongs in a bullet, attribute, or longer description. That division keeps identity separate from persuasion.

    Give every bullet a decision to resolve

    Assign each bullet to a high-priority row from the query-to-attribute map. A useful construction is: verified property, practical consequence, then boundary. For example: [component] measures [verified dimension], which allows [supported use]; it does not fit [known exclusion].

    The boundary is often the most useful part. Words such as premium, versatile, convenient, and advanced leave the assistant and the shopper to infer meaning. A measurement, named material, supported model, care requirement, or package-content statement answers a question.

    Use longer content for context and distinctions

    Use the description and any available enhanced content to explain scenarios that need more than a compact bullet. Show how related features work together, distinguish similar variants, and clarify setup or care where that affects suitability. Keep purchase-blocking facts in attributes or bullets as well; do not hide an exclusion deep in promotional copy.

    Where Seller Central provides non-visible search-term fields, use them for accurate synonyms and alternative language omitted from the visible copy. These fields can broaden vocabulary coverage, but they cannot repair a missing specification or make an unsupported claim true.

    Make every variant tell the same product truth

    Three color variants of the same air purifier display identical features and matching icon-based product information.

    An assistant-ready listing needs internal agreement. When the title, attributes, bullets, images, and variant labels disagree, no amount of elegant wording tells a dependable story. Resolve the underlying value before deciding which phrase sounds best.

    Run a field-by-field consistency audit:

    • Confirm that measurements, units, materials, model names, and package quantities agree wherever they appear.
    • Check each purchasable variant independently. A size, capacity, color, accessory, or capability belonging to one child item must not appear to apply to every child item.
    • Separate included items from products that are merely compatible, optional, or shown for context.
    • Qualify compatibility and suitability claims with the conditions that make them true.
    • Make sure synonyms preserve the same meaning. Related terms are not interchangeable when they describe different materials, product types, or technical standards.
    • Compare text embedded in images with the current catalog values. Old creative can preserve a contradiction after the written listing has been corrected.

    The parent-child relationship deserves special attention. Shared copy is efficient, but it can quietly transfer a fact from one variant to another. Treat each purchasable option as its own truth set, then share only claims that are genuinely common to the family.

    Keep a simple claim ledger outside Amazon. For each important claim, record the canonical value, the variants it covers, the evidence that supports it, and every field where it appears. When product specifications or packaging change, the ledger shows what must be updated. It also prevents one team from correcting a bullet while another republishes an outdated image or description.

    Do not use Alexa optimization as a reason to stretch a claim beyond your product documentation. The likely downside is not limited to an inaccurate answer. It can include unqualified traffic, avoidable returns, support costs, and disappointed customers. The safe alternative is to state the verified boundary clearly and optimize for shoppers whose requirements the product actually meets.

    Test assistant visibility without confusing observation with proof

    You cannot safely infer a secret ranking weight from one response. Assistant output can vary, and competing listings can change independently of your edits. Use a controlled observation process to determine whether a clearer catalog record produces a repeatable, useful direction.

    1. Create a fixed prompt set. Cover category discovery, a supported use case, a decisive constraint, compatibility, and an exclusion. Include unbranded requests so you are testing discovery rather than simple brand recall.
    2. Record a baseline. Save the exact prompt wording, marketplace, relevant account or device context, listing version, and what happened. Note whether the product appeared and whether important facts were described accurately.
    3. Change one fact cluster. Correct a related group such as compatibility, dimensions, materials, or package contents. Avoid rewriting every field at once, because a broad rewrite makes the cause of any change impossible to interpret.
    4. Wait until the listing edit is live, then repeat the same prompts. Keep the wording and testing context stable. Repeat observations rather than treating one appearance or disappearance as a verdict.
    5. Check commercial quality as well as visibility. Use the business metrics you already trust to see whether the change attracts qualified shoppers. More exposure accompanied by weaker conversion, more confusion, or more returns can indicate that the listing became broader without becoming more accurate.

    Label failures by type. A product may not be surfaced, may be surfaced for the wrong need, may appear with a deciding attribute omitted, or may be described with an incorrect value. Those failures require different responses. Missing visibility may justify broader relevant language. An omitted fact may point to poor placement. A wrong fact should trigger a consistency check before you add more copy.

    If your listing is consistent but Alexa still states a fact incorrectly, log the observation and keep the catalog truth intact. Distorting the listing to imitate an erroneous answer creates a second problem instead of solving the first.

    Judge the edit across the whole prompt group. A useful change improves matching for supported needs, preserves important exclusions, and does not degrade shopper quality. That is stronger evidence than an isolated change in apparent placement.

    Key takeaways for Amazon Alexa listing optimization

    • Optimize the relationship between a shopper’s question and a verified product fact, not keyword repetition alone.
    • Prioritize compatibility, dimensions, included items, and other constraints that can determine whether a purchase succeeds.
    • Correct structured attributes and variant data before polishing persuasive copy.
    • Use titles for identity, bullets for major decisions, longer content for context, and search-term fields for accurate vocabulary coverage.
    • Resolve contradictions across fields and creative assets before adding more language.
    • Test with fixed prompts and downstream business signals, treating repeated observations as directional evidence rather than proof of a ranking formula.

    Your next move is narrow and practical: choose one representative ASIN, map its most decisive shopper questions to verified attributes, and fix the highest-risk ambiguity. Save the baseline, rerun the same prompt set after the changes are live, and scale only the patterns that improve both answer quality and shopper fit.

    References


  • How to Build Content That Earns Visibility in AI Search

    How to Build Content That Earns Visibility in AI Search

    Your team can publish useful pages, rank for relevant terms, and still disappear when ChatGPT, Gemini, Claude, or Perplexity assembles an answer. More content will not necessarily fix that. The missing piece is often a clear, extractable answer backed by information and external signals the system has reason to trust.

    If you are deciding whether to produce another batch of articles or improve what you already have, start with the unit of value: a defensible answer that helps someone make a decision. Then make that answer easy to retrieve, cite, verify, and maintain.

    Key takeaways

    • Put the direct answer near the top. In structured GEO testing, pages performed better when the answer appeared within the first 100 words.
    • Use question-based headings, self-contained sections, and visible FAQ answers. Do not make a machine or a hurried reader assemble the conclusion from scattered paragraphs.
    • Create dedicated assets for commercially important queries when the intent or evaluation criteria genuinely differ. A semantically similar page may not cover the exact decision an AI system is trying to resolve.
    • Treat third-party authority as part of the content system. A strong page on your site, a relevant editorial placement, PR reinforcement, and credible references can support one another.
    • Measure citation durability, not just first appearance. In one test, roughly half of cited sources stopped appearing within 30 days.
    • Judge content by the decision it improves and the business result it supports, not by word count, publishing cadence, or whether a human or an AI typed the first draft.

    Make the answer usable before you make the page longer

    An AI answer system cannot reliably cite an implication. If the useful conclusion appears only after a long introduction, several caveats, and a loose comparison, the page forces both machines and people to reconstruct your position. State the answer first. Use the rest of the page to prove it, qualify it, and help the reader act.

    The opening answer should not be a slogan. It should identify the situation, give the conclusion, and name the most important boundary. For a selection query, that might mean saying which option fits which buyer. For a process query, it means naming the next step and the condition that changes it. For a definition, it means giving the definition before discussing its history.

    Build each important section as a small answer unit:

    1. Use the real question as the heading. Testing found that a heading such as How is AI SEO different from traditional SEO? performed better than a compressed label such as AI SEO vs. traditional SEO.
    2. Answer it in the first sentence. Do not begin with background the reader must cross before reaching the conclusion.
    3. Support the answer immediately. Add the criteria, evidence, example, or mechanism that makes the conclusion defensible.
    4. State the boundary. Explain when the answer changes, what it does not cover, or which audience it applies to.
    5. Give the reader a next step. A useful answer should change what the reader checks, chooses, or does.

    Keep related sections self-contained. A section on what to look for when hiring an AI SEO consultant should answer that question without relying on a later section about where to find one. This does not require repeating the entire page. It requires putting the essential noun, conclusion, and qualification in the same answer block.

    Apply the same rule to FAQs. Answers hidden behind expandable controls produced weaker results than answers visible by default in the documented tests. If a question matters enough to target, place its answer in the rendered page. Structured data can describe visible entities and relationships, but it cannot rescue an answer that the page never states clearly. Treat JSON-LD as accurate packaging for the content, not as a substitute for the content.

    Exact intent also deserves more care than generic topical coverage. A page targeting Best LLM SEO Consultant gained visibility while the same brand barely appeared for Best AI SEO Consultant; the first query had a dedicated asset and the second did not. That is evidence from a particular experiment, not permission to manufacture a thin page for every wording variation.

    Use one page when two phrases express the same decision and require the same answer. Consider separate assets when the audience, criteria, recommendation, or source set changes. For a valuable query, a persistent visibility gap across repeated checks is a reason to test a dedicated page. Mere keyword variation is not.

    Invest in the information, not the production of words

    A compact prism built from research materials sits beside a tall stack of blank, repetitive paper sheets on a worktable.

    The cost of producing competent sentences has fallen sharply. That changes where content value lives. Drafting speed is useful, but readers and answer engines do not need another smooth explanation assembled from familiar claims. They need information that reduces uncertainty.

    The practical distinction is not human content versus AI content. Human writers produced generic filler long before generative AI, and an AI-assisted workflow can still support research, critique, restructuring, and editing. The real distinction is between content with a contribution and content without one. An absence of ideas, evidence, and judgment remains an absence no matter who drafted the prose.

    Before approving a page, identify the contribution it will make. Useful contributions include:

    • First-party data you are permitted to publish, with enough context for the reader to interpret it.
    • A decision rule that explains which option fits which situation and where the rule stops applying.
    • A comparison conducted with consistent, disclosed criteria rather than a list of unrelated features.
    • Operational detail that only someone close to the product, process, market, or customer problem can supply.
    • A current explanation that corrects an outdated assumption and shows what changed.
    • A synthesis that resolves an apparent conflict instead of merely repeating both sides.

    This changes the content brief. Do not lead with a target length and a keyword count. Require the brief to name the query, the reader’s decision, the information gap, the original input, the central claim, the proof, the limitations, and the condition that will trigger an update. AI can help turn those materials into a coherent draft. It should not be asked to invent the materials.

    Content value should also be defined before publication. A page may be intended to earn citations, qualify buyers, explain a difficult feature, reduce sales friction, support customer success, or create a reusable reference for other channels. One page can contribute to several goals, but one primary job keeps the editorial choices honest.

    Traffic is only one possible output. A low-cost content program can lose rankings later and still have produced a positive return while it was visible; a rising traffic graph can also hide weak commercial results. Cost, outcome, and return belong in the same evaluation. Moral arguments about who typed the sentences do not answer whether the investment worked.

    The market may eventually attach more explicit economic value to contribution. Google’s limited AI Contribution pilot is testing payments to some publishers when their material contributes significantly to responses in AI Mode, AI Overviews, and Gemini. It is an early-stage experiment, not a public revenue model or a reason to forecast licensing income. It does, however, reinforce an important distinction: the value under examination is contribution to an answer, not the number of words delivered.

    Match the query, content format, and authority layer

    On-page quality is necessary, but it is not the entire visibility system. AI products may retrieve search results, consult third-party pages, or prefer sources already associated with a category. Your owned page establishes the canonical answer. Relevant external coverage helps establish that other credible places recognize the same entity and claim.

    The size of this effect can be highly concentrated. In one multi-month experiment, listicles accounted for 72.4% of citation events and PR accounted for 24.1%. One comprehensive listicle generated 190 mentions, more than the other placements combined. Those percentages are not universal benchmarks. They show why source selection and content depth can matter more than accumulating a large number of interchangeable mentions.

    Use a query-first placement process:

    1. Build a commercial query map. Record the exact questions that precede evaluation, comparison, hiring, or purchase. Keep informational questions separate from decision queries.
    2. Inspect the sources that recur. Run the fixed prompts across the AI products your buyers use and note which domains, page types, and individual URLs receive citations.
    3. Match the placement to the query. In the documented tests, software and tool queries tended to favor authoritative review sites, while service queries more often surfaced listicles. Treat that as a hypothesis to verify in your own result set.
    4. Improve the strongest relevant opportunity. Aim for substantive inclusion in a comprehensive resource rather than a passing brand mention on a generic site.
    5. Reinforce the same defensible claim. PR and guest contributions can extend a strong placement when they add corroboration and context. They are unlikely to turn a weak, irrelevant source into a durable citation.
    6. Maintain the owned answer. Keep the canonical page current, internally linked, indexable, and aligned with the claim appearing elsewhere.

    Authority and relevance must be considered together. The experiments produced a working hierarchy in which government and educational sites were strongest, followed by news publications, industry-relevant sites, and then general sites. A cold-start test also found that better-written listicles on general sites produced little visibility. You should not chase an authoritative domain that has no legitimate relationship to the query. Look for the strongest source that naturally covers the decision.

    Context around the brand may matter as well. Placement beside recognized experts correlated with better performance, and removing those peer names was followed by a decline. That finding is preliminary, but the next action is sensible: make category relationships explicit and accurate. Describe who the product is for, what market it belongs to, which alternatives a buyer considers, and how it differs. Do not manufacture endorsements or artificial peer associations.

    Traditional search visibility still supports this work. When ChatGPT used web search to resolve queries in the experiment, brands missing from the retrieved results were also missing from the answer. Indexability, internal linking, crawlable copy, relevant rankings, and useful third-party pages therefore remain part of GEO. AI optimization is not a replacement layer placed on top of neglected SEO.

    Measure visibility as a changing system, not a screenshot

    A stable knowledge object is surrounded by shifting translucent pathways and nodes observed through a monitoring lens.

    A single favorable response is not a result. AI outputs vary by product, query wording, retrieval behavior, timing, and possibly location. Two structured experiments logged 775 citation events, yet one initial conclusion did not survive the second experiment. That is a warning against turning one campaign, one screenshot, or one platform response into a universal rule.

    Use a fixed prompt set and a repeatable log. Record:

    • The exact prompt, including capitalization and meaningful wording variants.
    • The platform, date, location condition, and whether the response used web retrieval when that is visible.
    • Whether the brand was absent, mentioned, recommended, or directly cited.
    • The cited URL, source type, and the brand’s position within the answer.
    • Which competing entities appeared and which sources supported them.
    • The corresponding conventional search results for web-assisted queries.
    • Any qualified visit, lead, assisted conversion, or other business action you can responsibly associate with the exposure.

    Capitalization belongs in the log because capitalized and lowercase versions returned different citations in three repeated checks. That behavior still requires validation, so do not build a capitalization doctrine around it. Test the variants your customers genuinely use and preserve the exact input so another check can reproduce it.

    Review the set weekly and continue beyond the first 30 days. Track query coverage, recommendation rate, citation frequency, citation survival, source diversity, and dependence on a single URL. A sharp first-week lift can be less valuable than a smaller presence that persists through updates and changing retrieval sets.

    Use the pattern of results to choose the next test. These are diagnostic hypotheses, not proof of causation:

    Observed patternLikely issue to investigateNext test
    Your page is not retrieved for a web-assisted answerDiscoverability, ranking, or query-page mismatchCheck indexability and the live result set, then strengthen the page that most directly answers the exact query.
    Your page is retrieved but not usedThe answer may be buried, weakly supported, or less specific than competing materialMove the conclusion into the first 100 words and add the evidence or qualification needed to make it citable.
    A citation appears and then disappearsSource decay, freshness, or a changing retrieval setUpdate substantive facts and examples, verify the publication date, and reassess the authority of the supporting placement.
    The brand is visible but produces no useful actionThe tracked query may have weak business relevance, or the page may not help the reader continuePrioritize a closer decision query and give the reader a clear, appropriate next step.
    Most visibility comes from one external URLConcentration riskEarn corroboration from additional relevant, authoritative sources while maintaining the owned canonical answer.

    Do not report citation counts without their business context. Attach production and placement costs to the program. Separate mentions from recommendations, citations from qualified visits, and traffic from outcomes. If attribution is incomplete, label it as directional rather than assigning false precision.

    Your next move should be small enough to evaluate. Choose one commercially important query where your brand is consistently absent. Improve the opening answer, separate any tangled sections, add one defensible contribution, identify the relevant sources already being retrieved, and begin a weekly log. Do not scale the playbook until the result persists and supports a business outcome you actually value.

    References


  • International SEO Keyword Localization: A Practical Workflow

    You have a translated landing page, a target-country keyword database, and a discouraging result: the obvious phrase has little volume or no data at all. Before you question the market, question the phrase you used to enter it.

    International keyword localization is the work of discovering how people in a specific market describe the category, their role, the outcome they need, and any local qualification or institution that shapes the search. Done properly, it tells you whether to translate an existing page, rewrite it around a different concept, or create a market-specific page from scratch.

    Start with the market’s vocabulary, not a translation

    Translation answers, “How do we express this phrase in another language?” Keyword localization answers, “What does someone in this market actually search when they need this product, service, qualification, or outcome?” Those questions overlap, but they aren’t interchangeable.

    A translated category can be accurate, fluent, and almost useless as a research seed. People may organize the same need around an occupational title, exam, license, professional card, regulatory code, agency acronym, or locally familiar shorthand. These terms are market artifacts: labels created by the institutions and practices of the market rather than by the generic category itself.

    The effect can be large enough to resemble an absence of demand. In one U.S. Semrush lookup, “commercial drone operator training” returned no related keywords, while “drone pilot training” opened a 26,520-keyword set. FAA Part 107 appeared at rank 17 within the first 1,000 deduplicated rows. In Spain, “curso de operador profesional de drones” returned no data, while “curso de piloto de drones” produced 338 raw terms and 292 after normalization; “AESA A1 A3” appeared at rank 14.

    Those snapshots don’t prove that occupational wording always beats descriptive wording, and the numbers shouldn’t be reused as forecasts for another market. They demonstrate a more important mechanism: a seed controls which keyword neighborhood a tool can enter. If the seed sits outside the market’s normal vocabulary, the tool may return nothing. If it enters the wrong neighborhood, it may return an impressive list that still excludes the terms that govern real demand.

    Build a market vocabulary map

    Before collecting volume, map the different ways the market can name the need. A useful map separates five layers:

    Vocabulary layerQuestion it answersTypical seed types
    CategoryWhat is being sold or learned?Training, software, insurance, certification course
    RoleWhat does the searcher call the person or occupation?Drone pilot, security guard, technician, adviser
    QualificationWhat proves eligibility or competence?License, card, certificate, exam, statutory title
    Institutional systemWhich authority, law, framework, or code organizes the activity?FAA Part 107, AESA A1/A3, TIP, EPA 608
    Task or outcomeWhat is the person trying to do next?Qualify, prepare, renew, apply, comply, become eligible

    One concept may need seeds from every layer. A generic training phrase can reveal broad informational demand, while a license or exam term reveals the route taken by people closer to enrollment. Neither should automatically replace the other. Their jobs are different.

    This is also why “ask a native speaker” is incomplete advice. A native speaker can produce natural wording without knowing the specialist vocabulary of private security, aviation, financial licensing, healthcare, or another regulated field. You need linguistic fluency and market knowledge.

    Give your local reviewer concrete questions instead of asking for a translation:

    • What do practitioners and customers call the occupation?
    • Which license, card, certificate, exam, or membership is associated with entry?
    • Which agency, regulator, law, or code appears in ordinary conversation?
    • What language appears in job listings, training catalogs, and provider navigation?
    • What would a beginner search, and what would an experienced practitioner search?
    • Which acronyms are used on their own, and which full names should accompany them?
    • Does the term describe a legal requirement, an industry convention, or merely a popular course name?

    That last distinction matters. Do not infer a legal obligation from keyword volume, competitor copy, or an AI answer. When a credential or regulation affects eligibility, verify its current name, scope, and issuing authority with the relevant regulator or a qualified local specialist before publishing. Search data can reveal the vocabulary; it isn’t a legal authority.

    Run native keyword research as a controlled workflow

    A reliable process preserves the path from the business concept to the localized page. It should be possible to see which seed produced a term, which tool and discovery route returned it, how a local reviewer interpreted it, and which page will satisfy it.

    1. Define one market, one audience, and one offer. A language isn’t a market. Record the country, language or locale, audience, product availability, conversion action, and any eligibility restrictions before opening a keyword tool.
    2. Write a neutral concept statement. Describe what the offer does and who it serves without treating the home-market keyword as universal. This statement keeps the meaning stable while local terminology changes.
    3. Collect market artifacts before expansion. Review local regulator terminology, professional bodies, training catalogs, job listings, competitor navigation, result-page titles, and recurring questions. Record full names, acronyms, spelling variants, and the relationship between each artifact and the offer.
    4. Create a seed portfolio. When the evidence supports them, use two or three candidates from the category, role, qualification, institutional, and task layers. A portfolio protects the project from the failure of any single translated phrase.
    5. Run lexical and discovery routes separately. A broad-match route may mainly return phrases containing variations of the seed. Related-keyword or keyword-idea routes attempt to construct a broader neighborhood. Label the route in your export so a term that appeared because you typed it directly isn’t mistaken for an independently discovered opportunity.
    6. Preserve raw data, then normalize a copy. Keep the original query, accents, punctuation, and tool metrics. In separate fields, create a canonical form for deduplication, group obvious singular-plural or word-order variants, and assign intent. Never destroy the form people actually use just to make the spreadsheet tidy.
    7. Complete native and commercial review before prioritizing volume. Confirm what the query means, whether its result pages match the assumed intent, whether the offer can serve that intent in the market, and whether the term belongs on an existing page or needs a new one.

    Your working sheet should include more than keyword and volume. At minimum, retain the market and locale, original query, normalized cluster, seed, vocabulary layer, provider, retrieval route, intent, market artifact, relevance status, proposed page, reviewer, and verification status. This provenance becomes essential when two tools disagree or a stakeholder asks why a local page doesn’t mirror the home-market one.

    Keep discovery separate from prioritization

    Discovery asks whether you have found the vocabulary of the market. Prioritization asks which validated clusters deserve content and investment. If you sort by volume before discovery is credible, generic phrases will dominate while lower-volume institutional terms may disappear from view.

    Start by classifying each query into intent and vocabulary layers. Then assess relevance, page fit, commercial value, and available metrics. Avoid summing every close variant as though each represents a separate audience. Keep both cluster-level demand and the underlying query forms so writers know which wording sounds natural.

    Diagnose empty and convincing result sets differently

    An empty result set is visible, so teams often notice it. A populated but incomplete result set is more dangerous because it looks like successful research.

    A controlled comparison run on August 21, 2026 illustrates both failure modes. It used eight predetermined U.S. and Spanish cases and 80 combinations across Semrush and DataForSEO, with seeds, aliases, normalization rules, analysis limits, and decision thresholds fixed before retrieval. In Semrush Related, neutral descriptive seeds recovered the predetermined market artifact in two of seven observable cases; the other five cases returned empty sets. DataForSEO Keyword Ideas recovered the artifact in two of eight cases, but every neutral seed returned a populated set. In six cases, the artifact was absent from the first 1,000 canonical rows.

    These are results from a small, constructed comparison, not universal recovery rates for either provider. Their value is diagnostic. Similar-looking success rates concealed different problems: failure to enter a keyword neighborhood in one route and failure to expose the institutional layer in another. The providers also disagreed about which cases they recovered, so adding another tool is useful as a coverage check, not as an automatic tie-breaker.

    What you seeWhat may be happeningWhat to do next
    No keywords returnedEntry failure: the seed didn’t connect to a usable neighborhoodTry role, qualification, institution, and task seeds. Confirm the country database. Do not record zero demand.
    Many keywords, but no known credential or codeDiscovery failure: a neighborhood exists, but its institutional layer is missingSearch verified artifacts directly, add their aliases, use another discovery route, and inspect local result pages.
    The artifact appears only when used as the seedLexical retrieval rather than independent discoveryKeep the term, but label its provenance correctly. Test whether related seeds can recover it.
    Providers return different artifactsDifferent databases or retrieval methods expose different neighborhoodsTake the union of relevant terms, preserve provider provenance, and let local validation resolve meaning.
    Generic high-volume terms dominateThe seed may be too broad or aligned with the wrong intentAdd occupation, eligibility, exam, application, or compliance language and recheck page-level intent.

    Use coverage gates before calling the map complete

    Create a verified artifact list for the market, then give every item one of four statuses: independently discovered, found only when seeded, absent, or irrelevant to the offer. A simple artifact-coverage measure is the number of relevant artifacts recovered through discovery divided by the number of relevant artifacts verified outside the tool. It isn’t a ranking metric. It tells you whether the research process can see the market vocabulary you already know matters.

    Apply four additional gates:

    • Semantic gate: a native reviewer confirms that the term means what the team thinks it means.
    • Intent gate: the target-market results represent an intent the proposed page can satisfy.
    • Institutional gate: names, acronyms, credentials, and legal claims have been checked against a current authoritative source.
    • Commercial gate: the business can actually provide the product, pathway, or outcome implied by the query in that jurisdiction.

    Only after those gates should search volume, competition, conversion proximity, and production cost determine priority. A term with attractive volume but the wrong qualification, jurisdiction, or user expectation isn’t an opportunity. It is a mismatch.

    Turn localized clusters into the right page architecture

    Keyword localization isn’t complete when the spreadsheet is approved. Its value appears in the decision you make about each page.

    • Localize the existing page when the dominant intent, offer, and user journey remain substantially the same and only the language changes.
    • Rewrite the page around a local frame when the offer is the same but people enter through a different role, credential, or institutional term.
    • Create a market-specific page when eligibility, required steps, proof, or conversion paths differ enough that translated copy would mislead the reader.
    • Exclude the cluster when the business cannot serve the implied jurisdiction, requirement, or outcome. Traffic isn’t useful if the page creates a false expectation.

    A localized content brief should identify the primary cluster, supporting variants, user stage, dominant local role, relevant market artifacts, jurisdiction, page purpose, required answers, internal-link targets, and claims that need authoritative verification. It should also flag home-market language that must not be carried over automatically.

    Use the local terminology in the visible content before considering structured data. Name the qualification, institution, product, and jurisdiction clearly; expand ambiguous acronyms on first use; and explain how the entities relate. JSON-LD should represent what the page actually says. Schema markup can’t repair a page built around the wrong market concept, and adding an entity name only in markup doesn’t make the visible answer useful.

    The same clarity supports answer-engine and generative-search optimization. Give important market questions direct, self-contained answers. If a credential controls the journey, state who issues it, which market it applies to, who needs it, and what action the reader is trying to complete. Keep those statements current and evidence-backed. This creates a clearer entity-and-intent structure for search systems without pretending that formatting or schema guarantees visibility.

    Technical international SEO comes after that editorial decision. Hreflang, canonicals, language targeting, and localized URLs help search engines understand page relationships, but they can’t make a literal translation satisfy a different local intent. Decide what each market needs first; then encode the relationship accurately.

    Measure each localized cluster by market rather than blending language-level performance. Track impressions, clicks, qualified conversions, and page-level intent. If you monitor AI answers, record the prompt, language, market setting, date, response, and cited URL so results can be compared consistently. Revisit the vocabulary map when the offer, qualification pathway, or regulatory terminology changes.

    Key takeaways

    • Translate the business concept, then research the query language natively.
    • Use a seed portfolio spanning category, role, qualification, institution, and task language.
    • Treat licenses, exams, cards, agency acronyms, and regulatory codes as first-class keyword candidates.
    • An empty keyword set indicates a failed entry route, not proof that the market has no demand.
    • A large keyword set can still be incomplete if it omits verified market artifacts.
    • Keep lexical and discovery routes separate, preserve provenance, and validate meaning before prioritizing volume.
    • Let localized intent determine whether you translate, rewrite, create, or exclude a page.

    Start with one high-value page and one target market. Build its artifact list, run seeds from each vocabulary layer, and mark what every route recovers or misses. You will quickly learn whether your existing plan reflects the way that market searches or merely the way your home market describes itself.

    References


  • Profound Sheets Templates: Build an AI Visibility Workflow

    Profound Sheets Templates: Build an AI Visibility Workflow

    Someone has asked you to explain why your brand appears in some AI answers and disappears from others. You do not need another dashboard screenshot. You need a working sheet that turns observations into a prioritized, defensible next step.

    Profound Sheets Templates can reduce setup work because they provide a starting point for common ways teams put Sheets to work. Treat that starting structure as an analysis contract: define what each row means, keep comparisons stable, and decide what action a result is allowed to trigger before you start interpreting it.

    Start with the decision the sheet must support

    The easiest mistake is choosing a template because its output looks useful. A table of brand mentions, citations, prompts, or competitors can be interesting without resolving the decision in front of you. Start with the decision, then select the template whose row structure can support it.

    Most AI visibility work begins with one of these questions:

    • Content prioritization: Which audience questions need a new page, a clearer answer, or stronger supporting evidence?
    • Brand accuracy: Which recurring claims about your company, products, or category require verification or correction?
    • Competitive analysis: On which relevant themes do competitors appear while your brand does not?
    • Source analysis: Which pages or domains are being cited, and what makes those resources useful for the question being answered?
    • Monitoring: How does a fixed set of observations change across models, markets, languages, or reporting periods?

    Write the purpose of your sheet as a single sentence: “This sheet will help [owner] decide [action] for [scope] during [decision cycle].” If you cannot complete that sentence precisely, the analysis is not ready to run.

    DecisionUseful row unitOutput to produce
    Prioritize contentOne topic or intent clusterAn ordered backlog with a reason for each recommendation
    Investigate brand accuracyOne claim observed in one answer environmentA verification queue linked to evidence
    Compare competitorsOne brand-by-theme observationSpecific gaps that require inspection
    Monitor changeOne repeatable observation for a named model, interface, and periodA like-for-like change log

    Do not force several incompatible decisions into one table. A content backlog, a competitor matrix, and a time-series log often require different row units. Combining them produces duplicate records, unclear denominators, and summaries that nobody can reproduce.

    Define what each row represents before trusting the output

    A floating blank grid contains consistent sequences of abstract objects in each row, with one fragmented row shown out of alignment.

    A row is not merely a place where a result lands. It is the smallest observation your analysis treats as distinct. The same prompt run in a different model, interface, market, language, or period may be a different observation. If those contexts are collapsed, a change in conditions can look like a change in brand performance.

    Create a short data dictionary before you customize a Profound Sheets Template. Your process should preserve these details, whether they live in the template itself or in an accompanying methodology record:

    • Scope: The brand, product, website, market, and language included in the analysis.
    • Prompt definition: The exact prompt or a stable cluster name, plus the rule used to place prompts in that cluster.
    • Answer environment: The named model or answer engine and the interface through which the answer was observed.
    • Observation time: When the answer was collected, so later changes are not mistaken for inconsistent analysis.
    • Entity rule: Which company, product, abbreviation, and accepted aliases count as the same entity.
    • Evidence: The answer text, cited URL, captured result, or another durable reference that lets a reviewer inspect the observation.
    • Review state: Whether the row is unreviewed, checked, disputed, or ready to support a decision.
    • Ownership: The person or function responsible for verifying the result and taking the next action.

    Keep visibility concepts separate. A brand mention is not necessarily a citation. A citation is not necessarily an endorsement. Prominent placement is not proof of factual accuracy. Positive language is not proof that the correct product or entity was identified. Give each concept its own field instead of hiding them inside one broad “visibility” label.

    Rates need visible denominators. Store the underlying count and the eligible observation set alongside any percentage or share. Otherwise, a filtered view can change the meaning of the metric without changing its label. Define how blank, unavailable, duplicate, and ambiguous results are handled as well; none of those states should silently become zero.

    Customize the template without breaking comparability

    A template is a scaffold, not a universal measurement standard. You will usually need to adapt it to your market, taxonomy, content inventory, and reporting workflow. The safe approach is to change it in controlled layers so you can still trace every conclusion back to an observation.

    1. Preserve a baseline. Keep an untouched copy or a clear record of the original structure. Overwriting the only version can make previous calculations and field meanings impossible to recover.
    2. Test the unmodified workflow on a representative subset. Include an expected positive result, an expected absence, and an ambiguous case. This reveals how the template handles edge cases before you commit to a full analysis.
    3. Add only fields tied to the decision. A column should help you segment observations, validate evidence, assign work, or choose an action. If it does none of those things, leave it out.
    4. Document derived measures. Record the numerator, denominator, filters, exclusions, and grouping logic behind every calculated metric. A label such as “share” or “score” is not a definition.
    5. Check outliers against the underlying answer. An unusually strong or weak result may be real, but it may also reflect an alias mismatch, prompt classification error, missing result, or changed answer environment.
    6. Freeze the method for the reporting cycle. When you change the prompt set, entity rules, model scope, or calculation logic, create a new version and record the change. Do not silently rewrite historical results to match a new method.

    Run a quality check before distributing any summary. Look specifically for duplicate aliases, inconsistent topic labels, missing market or language values, citations counted as mentions, mentions counted as citations, blank cells treated as negative observations, and manual notes mixed into raw fields. These errors are mundane, but they can reverse the apparent direction of a result.

    Keep exploratory prompts separate from monitoring prompts. Exploration is allowed to change as you discover new questions. Monitoring needs a stable comparison set. Mixing the two makes growth in prompt coverage look like a movement in visibility, even when the underlying comparable observations did not improve.

    Turn observations into SEO, AEO, and GEO actions

    Evidence tokens pass through a blank decision grid and branch toward search, direct-answer, and networked-globe action streams.

    An observed result tells you what appeared under defined conditions. It does not, by itself, tell you why it appeared. A competitor citation does not prove that a particular page element caused inclusion. Your brand’s absence does not prove that your content is poor. Treat the sheet as a diagnostic queue, then investigate the relevant answer, prompt intent, cited resources, and owned content before prescribing a change.

    ObservationWhat to verifyPossible action
    An important brand fact is wrongThe exact claim, entity identity, cited resources, and corresponding information on owned pagesCorrect the authoritative owned page and make the factual statement consistent across relevant properties
    The brand is absent for a relevant topicWhether the prompt represents real audience intent and whether an existing page answers it directlyCreate or improve a focused resource if a genuine information gap exists
    A competitor appears repeatedlyThe cited URLs, answer format, evidence, scope, and task those pages satisfyClose the specific information or evidence gap rather than copying the competitor’s page
    The result changes frequentlyThe model, interface, prompt wording, market, language, and collection periodContinue controlled monitoring before making an expensive content change
    The brand appears accurately and is supported by a relevant pageThe cited asset, its freshness, and neighboring audience questionsMaintain the resource and extend coverage only where a related intent is demonstrably useful

    Prioritize a finding through four gates:

    • Business relevance: Does the topic affect a product, audience, reputation concern, or decision your organization actually serves?
    • Recurrence: Does the pattern persist across comparable observations, or is it a single volatile answer?
    • Evidence quality: Can a reviewer inspect the answer, prompt, context, and cited material?
    • Controllability: Is there a specific owned asset, factual inconsistency, or content gap your team can address?

    A finding that fails one of these gates belongs in investigation or monitoring, not an implementation backlog. This prevents your team from spending time on visible but low-value anomalies.

    For findings that do become content work, connect the sheet to your content inventory. Assign a canonical URL or planned asset, an owner, the audience question, the factual evidence required, and a review state. The finished page should answer the task plainly, support important claims, identify the relevant entity consistently, and expose useful information in visible content.

    Structured data should describe that visible content accurately. JSON-LD is not a patch for a weak answer, an unsupported claim, or an ambiguous entity. Use the most specific applicable schema only when the page genuinely contains the corresponding information, and keep the markup aligned when the page changes.

    Maintain three distinct layers as the workflow grows: raw observations, reviewed findings, and approved actions. Raw evidence should remain stable. Review can add interpretation and confidence. The action register can then track the canonical URL, owner, status, rationale, and expected user outcome. Separating these layers stops an editorial opinion from being mistaken for collected data.

    Key takeaways

    • Choose a Profound Sheets Template from the decision you need to make, not from the most appealing output.
    • Define the row unit, prompt rules, entity rules, answer environment, and evidence requirements before interpreting results.
    • Keep mentions, citations, placement, sentiment, and factual accuracy as separate observations.
    • Preserve raw results and version every methodological change so reporting periods remain comparable.
    • Require business relevance, recurrence, inspectable evidence, and a controllable next step before turning a finding into SEO, AEO, or GEO work.

    Start with one decision from your current reporting cycle. Write its row definition, select the closest template, and test the workflow on a representative subset. Once another person can reproduce the conclusion from the stored evidence, you have a process worth scaling.

    References


  • How Law Firms Earn AI Citations and Search Visibility

    How Law Firms Earn AI Citations and Search Visibility

    Your firm can rank well in conventional search and still disappear when a prospective client asks an AI assistant who can help. It can also appear by name while another website receives the citation. Those are different visibility problems, and they require different fixes.

    The practical goal is to make your expertise easy to retrieve, verify and attribute for the questions that lead to suitable matters. That is what AEO for law firms across ChatGPT, Gemini and Claude is meant to address. It is not a shortcut to a recommendation. It is a disciplined way to connect a client’s question with a clear answer, a credible lawyer, a defined jurisdiction and evidence that supports the firm’s claims.

    Diagnose the citation gap before changing your website

    A magnifying glass examines two digital paths, one leading directly to a law office and another splitting between a firm and an outside publication.

    You are not optimizing the firm in the abstract. You are optimizing individual questions and the evidence paths an answer engine can use to resolve them. A firm may be visible for a procedural question but absent from a local hiring question. It may be mentioned as an option without having its website cited. It may even be cited accurately on one prompt and misrepresented on a closely related one.

    Start with unbranded questions drawn from the decisions clients actually face. Do not begin with a vanity prompt that contains the firm’s name. A branded query mainly tests whether the system recognizes an entity it has already been given. It does not show whether the firm can be discovered when the user has not chosen a provider.

    Build your prompt set around distinct forms of intent:

    • Understanding: What does a legal term, process or notice mean?
    • Preparation: What information or documents should someone gather before speaking with counsel?
    • Decision: What factors should someone consider when choosing the right type of lawyer?
    • Location: Which firms handle the relevant matter in the user’s jurisdiction?
    • Firm evaluation: What experience, credentials or service characteristics distinguish a suitable provider?

    For every prompt, record the answer, every cited URL, whether the firm was named, whether its own page was cited and whether the description was accurate. Then inspect the cited pages for the exact job each one performed. One may define the issue. Another may establish local relevance. A professional profile may verify a lawyer’s credentials. A review platform may supply reputation evidence. Your gap is the missing job, not merely the missing keyword.

    Keep four outcomes separate: a mention, a citation, a recommendation and a visit. A mention means the system recognizes the firm. A citation means a particular page was selected as support. A recommendation adds evaluative language. A visit shows that the response produced measurable website activity. Treating all four as one ranking hides the work that needs to be done.

    Build pages around answerable client questions

    A broad service page can establish that you practise in an area, but it often cannot answer the narrower question in front of a client. A page headed with a generic service label usually leaves the system to infer who the advice applies to, which jurisdiction governs it and what information is actually useful.

    Give each important question a self-contained answer unit. That does not mean manufacturing a thin page for every wording variation. It means organizing substantial pages so that each section resolves one recognizable question without requiring the reader or the engine to reconstruct the answer from promotional copy.

    1. Name the situation. Make the heading match the problem in language a client would understand.
    2. State the applicable scope. Identify the jurisdiction, audience and material conditions before the answer can be mistaken for universal advice.
    3. Give the direct answer. Put the useful response before the firm’s history, awards or consultation pitch.
    4. Explain what changes the answer. Surface exceptions, dependencies and facts that require an individualized assessment.
    5. Show the next safe step. Tell the reader what to gather, verify or ask, without pretending a web page can decide an individual legal matter.
    6. Identify responsibility. Display the author or legal reviewer, their relationship to the firm and a meaningful review date.

    The page title and opening should promise only what the page delivers. A heading such as Our Litigation Services says what the firm sells. A heading framed around what someone should prepare before a litigation consultation says what the visitor will learn. The latter creates a much clearer answer target while still giving the firm room to explain where professional advice becomes necessary.

    Build a connected content structure rather than a pile of isolated posts. A service hub should link to the questions arising before, during and after the relevant process. Those pages should link to the responsible lawyers, appropriate offices and a clear contact route. Lawyer biographies should link back to the matters they actually handle. This creates a navigable chain from question to answer to qualified professional.

    Do not hide the useful portion behind a contact form. A page can explain a general process, the information a lawyer will need and the limits of general guidance without giving individualized advice. The consultation is for applying the law to the person’s facts, not for revealing basic information the page promised to provide.

    Legal marketing controls still apply. Before publishing testimonials, prior outcomes, fee language, comparisons, claims of specialization or client details, route the copy through the person responsible for advertising-rule and confidentiality compliance in every jurisdiction where it will appear. Never turn a client’s confidential facts into citation bait, and never frame a previous result as a promise about a future matter.

    Connect the answer to a verifiable firm and lawyer

    An answer page on a desk is linked by glowing threads to an attorney portrait, a law office, a seal, source documents and contact details.

    A well-written answer is only part of the job. An answer engine also needs to determine who published it, which lawyer stands behind it, where the firm operates and whether other accessible records describe the same entity consistently.

    Create an internal facts record that controls how the firm is represented. Include the legal name, public brand name, office details, contact information, jurisdictions, practice areas, lawyer names, professional roles and official profile URLs. Use that record when updating the website, professional directories, business profiles, press biographies and social accounts. Small inconsistencies can create separate or ambiguous entity trails even when each version looks reasonable to a human reader.

    On the website, make the relationships explicit:

    • Place the firm’s full identity and appropriate office information on location and contact pages.
    • Give each lawyer a dedicated biography with their role, relevant practice areas, jurisdictions and links to the pages they author or review.
    • Use bylines that lead to real biography pages rather than generic author archives.
    • Connect service pages to the offices and lawyers that genuinely provide the service.
    • Keep credentials, addresses and service descriptions consistent wherever the firm controls the record.
    • Correct obsolete profiles instead of publishing additional variants that compete with them.

    JSON-LD can reinforce those visible relationships. Use applicable types such as Organization or LegalService for the firm, Person for lawyers, and the relevant page or article type for content. The selected type matters less than accuracy and internal consistency. Every property should correspond to information a visitor can verify on the page or through the official URL it references.

    Structured data does not manufacture authority, override weak content or compel an AI citation. Its job is disambiguation. It helps machines connect a page with the correct organization, person, location and subject. Validate the markup after deployment, check that generated values match the visible page and repeat the check whenever a template, plugin or content model changes.

    Independent corroboration adds another layer. Relevant professional profiles, directory records, earned coverage and permitted client reviews can confirm identity or reputation claims. Look for agreement, not raw volume. A smaller set of accurate references that clearly points to the same firm is more useful than a large collection of neglected profiles with conflicting names, addresses or practice descriptions.

    Measure citations without depending on a stable source mix

    Social platforms deserve attention, but they are not a stable foundation. Within one vendor’s dataset, social platforms’ share of AI citations grew 47% in seven months while the sourcing pattern changed 16 times without warning. That is a directional observation from one dataset, not a universal law for every engine or legal query. Its practical value is the warning: a channel can become more visible while the rules governing that visibility continue to move.

    Use the firm’s website as the canonical home for complete, reviewed answers. Use social posts to distribute those answers in the language and format of each community. Keep the firm name, lawyer identity, jurisdiction and central claim aligned with the canonical page. Link back when the platform and context make that useful. If the legal position or firm information changes, update the canonical page first and then correct controlled social versions rather than allowing them to become competing records.

    A social response should be genuinely useful on its own, but it should not become improvised advice for an individual’s facts. Move sensitive or fact-dependent issues into an appropriate professional conversation. That protects the person asking and prevents a decontextualized reply from circulating as the firm’s definitive position.

    Test visibility with the same prompt bank under documented conditions across ChatGPT, Gemini and Claude. Record the date, account or access context when relevant, exact prompt, response, cited pages and factual errors. Repeat the test on a consistent cadence and after substantive changes. AI outputs can vary, so one successful response is an observation, not a durable ranking.

    What you observeWhat it may indicateWhat to do next
    The firm is neither named nor citedA possible relevance, retrieval or corroboration gapCompare the cited answer units with your best page and identify the missing job.
    The firm is named, but another domain is citedThe entity may be recognized while the firm’s site is not selected as evidenceStrengthen the official page, its authorship and the proof supporting the claim.
    A firm page is cited, but the firm is not clearly identifiedThe content may be useful while the publisher relationship remains weakClarify the byline, lawyer biography, organization identity and page relationships.
    The firm is named or cited inaccuratelyCurrent and obsolete facts may be conflictingCorrect the canonical page and controlled profiles, then document the change for retesting.
    The citation is accurate but produces no suitable inquiriesVisibility may exist without commercial alignmentCheck whether the prompt represents useful intent and whether the landing page offers an appropriate next step.

    Report citation coverage, brand mentions, factual accuracy, qualified visits and suitable inquiries separately. A citation proves that a page was used as support in that response. It does not prove endorsement, preference or commercial value. Keeping the measures separate stops a rising citation count from masking inaccurate descriptions or irrelevant exposure.

    Key takeaways

    • Optimize specific client questions and evidence paths, not a generic claim that the firm should rank everywhere.
    • Separate mentions, citations, recommendations and visits because each points to a different opportunity or problem.
    • Write direct, scoped answers that identify the jurisdiction, material conditions, author or reviewer and safe next step.
    • Connect content, lawyers, offices and services through visible links and accurate JSON-LD that describes the same facts.
    • Use independent profiles and social distribution as corroboration, while keeping the reviewed website page as the canonical record.
    • Retest a fixed prompt set under documented conditions and track accuracy alongside visibility.

    Choose one high-intent question tied to a priority practice area. Capture the current answers and citations, publish the strongest answer your evidence can support, align its lawyer, location and structured data, then test the same question again. That gives you a repeatable optimization loop grounded in what clients ask and what answer engines can verify.

    References


  • Unified Content Performance Monitoring for AI Search

    Unified Content Performance Monitoring for AI Search

    A page disappears from the AI answers you monitor. Your search rankings look stable, server logs still contain crawler requests, and analytics shows no obvious break. Those signals do not tell you whether to repair the page, rewrite it, or leave it alone.

    You need one diagnostic record that follows the page from technical eligibility to automated access, answer-engine selection, and business outcome. Bringing citations, bot activity, and page health into a page-level view is the foundation. The real value comes from preserving the distinctions between those signals so that each change leads to the right action.

    Key takeaways

    • Monitor page health, bot access, citations, and outcomes as connected layers, not interchangeable measures of success.
    • Attach every observation to a canonical URL, defined monitoring scope, time window, and raw evidence.
    • Diagnose changes in order: measurement scope, page identity, technical health, bot access, citation selection, then outcomes.
    • Alert people only when a signal maps to an action. Keep ordinary fluctuations in a review queue instead of creating constant emergencies.
    • Annotate releases and content changes. Change one class of variable at a time when you want to learn what affected performance.

    Measure four layers without collapsing them

    Four separated translucent monitoring layers rise above a blank web page, with visual elements for technical health, crawler access, answer selection, and audience outcomes.

    A unified monitor is not a collection of charts placed on the same screen. The records must share the same page identity, observation period, and filters. Otherwise, you can easily compare a bot request for one URL variant with a citation of another and an analytics total covering the entire site.

    Use four layers. Each answers a different question and has a different failure mode.

    LayerQuestion it answersEvidence to retainWhat it does not prove
    Page healthCan the intended page be fetched and interpreted as configured?Final destination, response class, canonical target, access directives, render result, and structured-data validationThat an AI system visited, selected, or cited the page
    Bot activityDid an identified or claimed automated agent request this URL?Agent classification, verification method, requested path, time, response class, and resource typeThat the main content was processed, retained, or used in an answer
    Citation visibilityDid a monitored answer point to this URL or domain?Surface, query or prompt, market, language, observation time, answer capture, and citation typeVisibility across every possible query, user, model, or session
    OutcomeDid the exposure connect with a useful audience or business action?Landing-page visits, engagement, qualified actions, conversions, and attribution notesThat a citation caused the outcome when the journey cannot be observed directly

    Do not compress these layers into a single score too early. A composite score can fall while hiding the only fact your team needs: whether the page became technically unavailable, stopped receiving bot requests, lost citations within a monitored query set, or simply generated fewer visits. Keep the component states visible even if executives also receive a summary indicator.

    Define the denominator before reporting citation growth

    A raw citation count is not comparable when the monitored query set changes. Define citation coverage as cited observations divided by eligible observations within a named scope. That scope should preserve the answer surface, query set, language, market, and any other controllable setting. If you add queries or change the mix, mark a new baseline rather than presenting the result as uninterrupted growth.

    Separate direct URL citations from domain mentions, unlinked brand mentions, and citations of a different page on your site. They may all matter, but they are not the same event. Decide which types count toward each metric before a stakeholder asks why the number moved.

    Count bot requests as access evidence, not visibility

    Bot activity begins with a request in a log. It does not establish that the agent rendered the page, understood the primary content, stored anything, or used the page in a generated response. Check whether the request reached the canonical document or only an asset, redirect, parameterized variant, or error response.

    A user-agent label is also a claim, not automatic proof of identity. Record how the agent was classified and keep categories such as verified, claimed, and unknown separate. This prevents spoofed or ambiguous requests from making an access trend look more certain than it is.

    Build one operating record for every canonical page

    The canonical URL should be the join key for your monitor, but a URL alone is not enough. Your team also needs to know what the page is supposed to do, who owns it, and what changed before a signal moved.

    1. Identity: canonical URL, page identifier, template, content type, topic cluster, language, and market.
    2. Purpose: primary audience question, intended search intent, conversion role, and the monitored query set associated with the page.
    3. Lifecycle: publication state, original publication time if known, meaningful revision times, and planned review state.
    4. Health: destination resolution, access directives, canonical consistency, renderability, structured-data validity, and agreement between markup and visible content.
    5. Bot evidence: agent category, identity confidence, request time, requested resource, response class, and any relevant delivery or firewall decision.
    6. Citation evidence: answer surface, exact query or prompt, visible model or product label, locale, observation time, cited URL, citation type, and captured response.
    7. Outcome evidence: landing activity, meaningful engagement, qualified action, conversion, and the limits of the available attribution.
    8. Change history: content edits, schema changes, template releases, internal-link changes, redirects, access-control changes, and analytics modifications.
    9. Ownership: responsible person or team, current status, next diagnostic step, and the evidence required to close the issue.

    Store the raw observation beside the normalized status whenever practical. A label such as “citation lost” is easy to scan, but the captured answer, monitored prompt, cited URL, and observation context are what let someone verify it later. The same rule applies to health checks and bot logs.

    Preserve unknowns instead of filling them with assumptions

    Some answer surfaces do not expose every model, retrieval, personalization, or session detail. Mark unavailable fields as unknown. Do not silently substitute a product name for a model version or assume two sessions had identical conditions. Your trends become more credible when the monitor shows where comparability ends.

    Apply the same discipline to attribution. A citation and a later conversion may be associated in time without being causally connected. Use direct attribution where it exists, assisted attribution where the journey supports it, and an explicitly labeled association everywhere else.

    Diagnose signal changes in a fixed order

    A blank web page moves through four sequential inspection stations for structure, crawler access, answer selection, and audience response.

    When a metric moves, begin with the cheapest explanations to verify. Rewriting content before checking measurement scope, redirects, or access controls creates work and can erase a page that was not actually underperforming.

    1. Confirm comparability. Check that the answer surface, monitored queries, locale, page mapping, observation schedule, and classification rules are consistent with the baseline.
    2. Resolve page identity. Verify that the observed URL, final destination, and canonical target refer to the same intended page. Inspect redirects and duplicate variants.
    3. Check technical health. Look for delivery failures, unintended access directives, rendering problems, canonical conflicts, broken markup, or structured data that no longer matches visible content.
    4. Inspect bot access. Determine whether relevant agents requested the document, what response they received, and whether a firewall, cache, consent layer, or delivery change altered access.
    5. Evaluate citation selection. Within a stable monitoring scope, inspect whether the page is still cited, whether another page from your domain replaced it, and which answer contexts changed.
    6. Connect the result to outcomes. Only after the earlier layers are sound should you decide whether the movement affected useful visits, engagement, leads, sales, or another defined goal.

    Health fails and bot activity falls

    Treat this as a delivery or access problem first. Review recent releases, redirect rules, canonical changes, access directives, firewall decisions, and server failures. Do not commission a rewrite while the intended page cannot be reached or interpreted reliably. Confirm the technical repair from outside the content management preview before closing the issue.

    Health is clean and bots visit, but citations remain weak

    You do not yet have evidence of a crawl problem. Review the page against the questions in the monitored set. Check whether it answers the central question directly, names entities unambiguously, separates distinct claims, supports important assertions, and keeps relevant facts consistent across visible copy and structured data.

    Also inspect page fit. A broad category page may receive requests while a focused explanatory page is a better citation candidate for a specific question. Map each monitored query to the URL that should answer it. If several pages compete for the same role, consolidate or differentiate them before adding more copy.

    Citations appear, but traffic stays flat

    A citation is not a click. Verify whether the citation is prominent, directly linked, attached to your preferred URL, and presented in a context that gives the user a reason to continue. Then inspect the landing page: the next step should be obvious and should extend the answer rather than merely repeat it.

    Do not manufacture traffic attribution when referral data is incomplete. Report the citation as visibility, report observed visits and outcomes separately, and describe any relationship between them at the confidence level your data supports.

    Bot activity moves while citations remain stable

    A crawl spike or decline is not automatically a performance event. It may reflect recrawling, release activity, duplicated URL discovery, asset fetching, or a change in agent classification. Compare requested resources and response patterns before escalating. If citations, health, and outcomes remain stable, keep the change in observation rather than forcing a content task.

    Traffic changes without a citation change

    Investigate conventional search, referrals, campaigns, seasonality, tracking changes, and site experience before blaming AI visibility. Unified monitoring is useful partly because it shows when the explanation probably sits outside the AI citation layer.

    Turn the monitor into a calm operating loop

    A dashboard does not improve content. A decision rule does. Define which conditions trigger an immediate technical response, which enter a scheduled investigation, and which remain under observation.

    • Immediate exceptions: an important page becomes unavailable, resolves to the wrong destination, acquires an unintended access restriction, develops a canonical conflict, or repeatedly returns a server failure. Verify the condition before making a destructive rollback.
    • Weekly triage: repeated citation movement within a stable query set, meaningful changes in verified bot access, unresolved page-level health warnings, and newly detected overlap between pages targeting the same question.
    • Monthly portfolio review: patterns by template, topic cluster, market, content type, and owner. Use this view to identify systemic issues that page-by-page tickets would hide.
    • Release checks: annotate migrations, redesigns, schema deployments, content refreshes, analytics changes, firewall updates, and redirect work. Recheck the affected layer after deployment.

    Each investigation ticket should state the observed change, comparison scope, raw evidence, affected layer, plausible cause, next test, owner, and safe reversal path. “AI visibility is down” is not a usable ticket. “Citation coverage fell across the unchanged monitored query set while health and verified document requests stayed stable” gives the owner a real starting point.

    Use page-specific baselines instead of universal benchmarks

    A citation count has meaning only within its observation scope, and bot volume depends on page type, site architecture, releases, and crawler behavior. Compare a page with its own stable baseline first. Use cluster or template comparisons only after confirming that the pages were measured under compatible conditions.

    Require repeated evidence across scheduled observations before rewriting a healthy page, unless you have a confirmed technical break or factual error. Generated answers and crawler activity can fluctuate. A reaction to every isolated movement will fill your change log with noise and make later diagnosis harder.

    Change one layer when you need a causal answer

    If you rewrite copy, replace schema, restructure internal links, and change the template in the same release, an improvement will not tell you which intervention mattered. Group urgent fixes when necessary, but use controlled, separately annotated changes for optimization work. Preserve the prior version and its observation scope so a rollback or comparison remains possible.

    Start with a bounded set of pages tied to real audience demand or business value. Create one record per canonical URL, capture the current state of all four layers, and assign an owner. The next time a metric moves, follow the diagnostic order before touching the content. That small discipline is what turns disconnected visibility data into a performance system.

    References