Tag: Content Optimization

  • AI Marketer Image Generation: A Practical Publishing Workflow

    AI Marketer Image Generation: A Practical Publishing Workflow

    You need a campaign image, but a blank prompt box is not a creative brief. If you ask an AI marketer for something that looks professional without defining the image’s job, you can get a polished asset that is unusable, off-brand, or disconnected from the page it is supposed to support.

    The useful shift is that image generation can now sit inside an AI marketer workflow. That can shorten the distance between an idea and a draft. It does not remove the need for direction, review, accessibility, or measurement. The workflow below turns that faster first draft into an image you can publish with confidence.

    Define the image’s job before describing its appearance

    Start with the placement, not the visual style. A blog hero, a paid social creative, a product illustration, and a supporting diagram may cover the same subject, but they solve different communication problems. The placement determines how much detail the image can carry, where the focal point belongs, whether text will be added later, and what the viewer should understand at a glance.

    Write a short image brief with six decisions:

    1. Placement: Name the exact destination, such as the hero area of a landing page, the opening image for an article, or a paid social placement.
    2. Communication goal: Complete the sentence: After seeing this image, the viewer should understand that…
    3. Audience: Identify who should recognize themselves, their work, or their problem in the scene.
    4. Focal subject: Choose the one element that must remain clear when the image is viewed at its final size.
    5. Brand constraints: Specify the visual characteristics that must stay consistent, including approved colors, level of realism, composition, mood, and any recurring visual motifs.
    6. Exclusions: List what must not appear, especially unsupported product details, invented interfaces, competitor marks, illegible text, visual cliches, or sensitive representations.

    A workable brief is concrete enough to reject the wrong image. For example: Create a wide editorial hero for an article aimed at B2B content leaders. Show one marketer directing an AI-assisted image workflow, with the review step visually prominent. Use a restrained, credible visual language with generous negative space on the left for a headline. Do not include logos, embedded words, dashboards, or futuristic humanoid robots.

    If your brief only contains adjectives such as modern, bold, premium, or innovative, it is not finished. Replace each adjective with a visible choice. Premium might mean restrained color, deliberate lighting, a limited number of objects, and generous negative space. Modern might mean a clean editorial composition rather than neon circuitry. The model can act on visible instructions; it cannot infer your internal definition of taste.

    Generate controlled variations instead of unrelated options
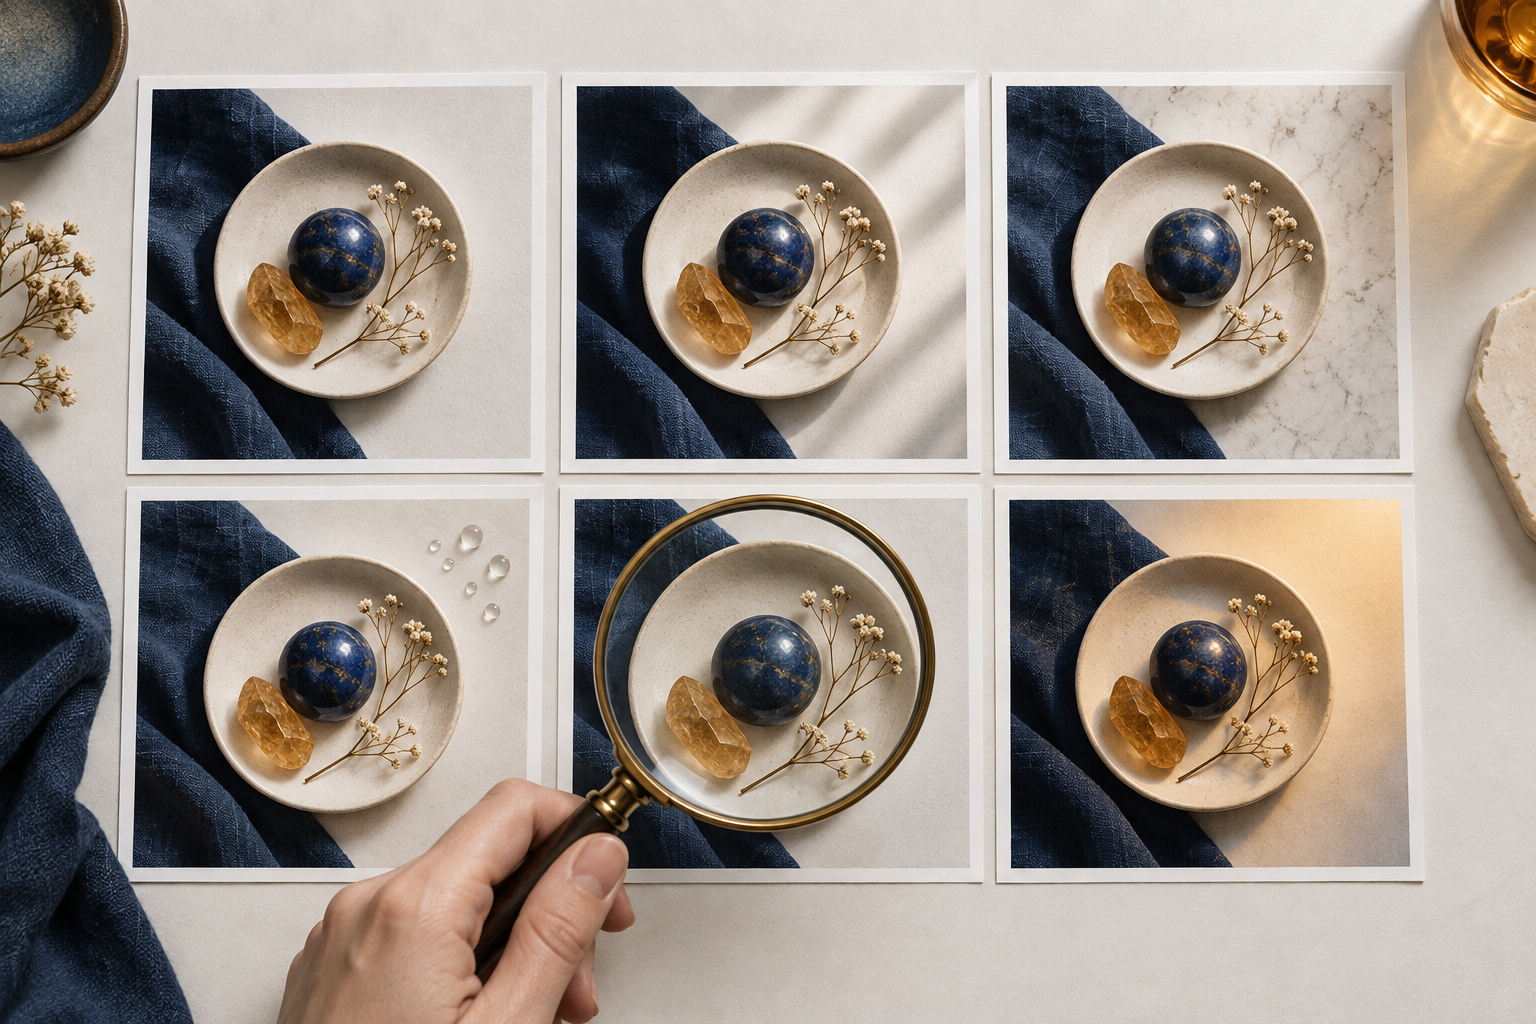
    A hand compares six closely related campaign image variations arranged on a studio table.

    The fastest route to a usable result is not asking for many unrelated concepts. Generate around one approved direction, then vary one decision at a time. This makes feedback precise and prevents the team from restarting the creative conversation with every draft.

    Build the prompt in this order: deliverable, purpose, subject, action, environment, composition, visual treatment, brand constraints, and exclusions. Put the non-negotiable information near the beginning. If the focal subject or empty space matters more than the color palette, say so first.

    • Composition variation: Keep the subject and visual treatment fixed, but test centered, off-center, close, and wide framing.
    • Concept variation: Keep the intended message fixed, but test a literal scene against a simple visual metaphor.
    • Tone variation: Keep the composition fixed, but adjust the level of warmth, energy, realism, or formality.
    • Channel variation: Preserve the concept while adapting the crop and visual density for each destination.

    Evaluate every candidate at the size and crop in which people will encounter it. A detailed scene can look impressive when enlarged and turn into visual noise in a card or mobile feed. The reverse also happens: a simple image may look sparse in isolation but work well once the headline, navigation, and call to action surround it.

    Do not rely on generated pixels for exact copy, product labels, interface text, pricing, or legal language. If wording must be correct, reserve clean space and add the approved text during layout. The same rule applies to a real product interface: use an approved screenshot or a clearly conceptual treatment instead of letting the generator invent controls that customers might mistake for actual functionality.

    Keep a small decision record for the selected asset: the brief, prompt, chosen output, intended placements, edits, reviewer, and approval status. That record gives you a reusable starting point when another channel needs a related image. It also separates approved creative direction from the accidental details of one generation.

    Run a four-part review before the image reaches WordPress
    A campaign image sits at the center of a desk surrounded by tools for checking color, defects, page context, and accessibility.

    Visual appeal is only one approval criterion. Review the candidate through four separate gates so that a striking image does not distract you from a factual, production, or governance problem.

    1. Truth and context

    • Does the image imply a capability, result, customer, partnership, location, event, or product detail that you cannot substantiate?
    • Could a conceptual interface be mistaken for the real product?
    • Are charts, maps, signs, screens, packages, or technical equipment plausible enough to mislead a viewer?
    • Does the representation of people fit the actual audience and context without leaning on a stereotype?

    Treat an unsupported visual claim the same way you would treat unsupported copy. Remove it, replace it with an approved asset, or make the conceptual nature unmistakable.

    2. Brand fit

    • Would the image still feel connected to your brand if the logo were absent?
    • Does its level of polish match the surrounding page rather than overpowering it?
    • Are lighting, color, subject treatment, and visual density consistent with the rest of the campaign?
    • Does it avoid the generic motifs your brand has decided not to use?

    Brand consistency is easier to review when you describe it as repeatable visual constraints. A request to make an image feel more on-brand gives the next operator little guidance. A direction to reduce the palette, remove glowing interface elements, retain natural lighting, and preserve negative space can be repeated.

    3. Production quality

    • Inspect faces, hands, reflections, repeated objects, edges, shadows, and background details at full size.
    • Check every required crop instead of assuming one master image will survive them all.
    • Confirm that overlays remain readable against the image in the final layout.
    • Remove embedded gibberish, accidental marks, and elements that resemble logos.
    • Export an appropriately sized web asset rather than uploading a needlessly heavy working file.

    4. Rights and accountability

    • Verify the image tool’s current usage terms for your intended commercial or editorial context.
    • Do not prompt for a living artist’s signature style or use a real person’s likeness without the permissions your use requires.
    • Retain the generation and approval record where your content team can retrieve it.
    • Follow any disclosure, labeling, or provenance policy that applies to your organization, market, or publishing platform.

    If the image depicts a real person, regulated product, medical situation, financial outcome, or news event, move it out of the routine approval queue. The downside is not merely an awkward visual. A synthetic depiction can create a false factual impression, so use approved documentary material or obtain the appropriate specialist review.

    Publish the image as part of the page’s meaning

    An attractive image does not make a thin page authoritative, and image generation by itself does not create SEO or AI-search visibility. The asset should clarify the same entity, problem, process, or product that the surrounding text explains. If the image and page target different ideas, no metadata can repair the mismatch.

    • Use a descriptive filename: Name the actual subject and function of the image. Avoid camera-roll names, prompt fragments, and keyword strings.
    • Write alt text for purpose: Describe the useful information the image contributes in its page context. Do not begin with image of, repeat the caption, or pack in search terms. If the image is purely decorative, handle it as decorative rather than forcing a redundant description.
    • Keep nearby copy explicit: Introduce the concept in the heading, caption, or paragraph around the image. Do not make readers infer a critical claim from pixels alone.
    • Use a real caption when context is needed: A caption can explain that a visual is conceptual, identify what a diagram shows, or connect an illustration to the point being made.
    • Preserve consistency in structured data: If the page’s JSON-LD identifies an image, use the public URL of the image actually associated with the visible page. Do not invent creator, license, or ownership information merely to fill properties.
    • Check the delivered page: Confirm that the image loads, remains legible on small screens, has not been cropped around the wrong focal point, and does not push the page’s main answer below an oversized hero.

    The practical objective is alignment. The page title, main answer, visible image, alt text, caption, and structured representation should describe the same thing without duplicating one another mechanically. That gives human readers a coherent page and reduces ambiguity for systems trying to interpret it.

    Measure whether the image improved the marketing outcome

    Generation volume is not a performance metric. Neither is the number of minutes removed from the drafting stage if review and rework simply move downstream. Choose the image’s success measure from its job: engagement with an ad, progression from a landing-page hero, comprehension of an explained process, or completion of the action the surrounding content requests.

    When you test an image, hold the headline, offer, audience, placement, and call to action steady. Change one meaningful visual variable, such as human subject versus product detail, literal scene versus diagram, or close crop versus environmental context. If multiple elements change together, the result cannot tell you which decision mattered.

    Pair quantitative performance with a review of failure reasons. Track why generated candidates were rejected: weak message fit, brand mismatch, factual risk, poor crop, unusable text, or production artifacts. A repeated rejection reason is a briefing problem you can fix upstream. It is more actionable than simply asking the model for better images.

    Key takeaways

    • Start with the image’s placement and communication job, not a list of visual adjectives.
    • Generate controlled variations around one approved direction so feedback produces a decision.
    • Add exact wording, product interfaces, and other factual details through an approved production process.
    • Review truth, brand fit, production quality, and rights as separate approval gates.
    • Connect the image to the page with useful alt text, nearby context, consistent metadata, and a working public URL.
    • Judge the asset by the marketing outcome it supports, then use rejection patterns to improve the next brief.

    For your next asset, do not begin by polishing a longer prompt. Write the six-part brief, generate one controlled set of variations, and send only the strongest candidate through the four review gates. That small operating discipline is what turns AI image generation from a novelty into a dependable part of content production.

    References


  • How to Make Products Visible to AI Personal Shoppers

    How to Make Products Visible to AI Personal Shoppers

    Your product can rank in conventional search and still disappear when a shopper asks an AI assistant what to buy. The missing piece is usually not another generic category paragraph. It is making the product easy to identify, test against constraints, and defend in a recommendation.

    AI personal shoppers can shape which products make the shortlist. That changes your visibility target. You are no longer optimizing only for a page visit; you are helping a system decide whether your product is eligible, relevant, credible, and safe to recommend for a particular request.

    AI shopping visibility is a three-gate problem

    There is no universal ranking formula for AI shopping. Assistants use different catalogs, retrieval systems, merchant feeds, pages, and models. Their answers can also change as availability, prices, prompts, and underlying systems change. A practical three-gate model is more useful than pretending every platform works the same way.

    1. Discovery: Can the assistant find and identify the correct product or variant?
    2. Qualification: Can it determine whether the product satisfies the shopper’s stated constraints?
    3. Selection: Is there enough relevant evidence to choose the product and explain that choice?

    A product has to pass the gates in that order. Better promotional copy cannot rescue a product the system cannot identify. Strong reviews cannot compensate for an unspecified compatibility requirement. Complete structured data does not prove a broad superiority claim.

    This sequence gives you a diagnostic method. If the product never appears, inspect discovery before rewriting the sales copy. If it appears for broad prompts but disappears when a constraint is added, inspect the relevant attribute. If it remains eligible but another product receives the recommendation, inspect comparative relevance and supporting evidence.

    The important distinction is between being mentioned and being recommendable. A system may know that your product exists while lacking the facts needed to place it in a defensible shortlist.

    Build one canonical product truth

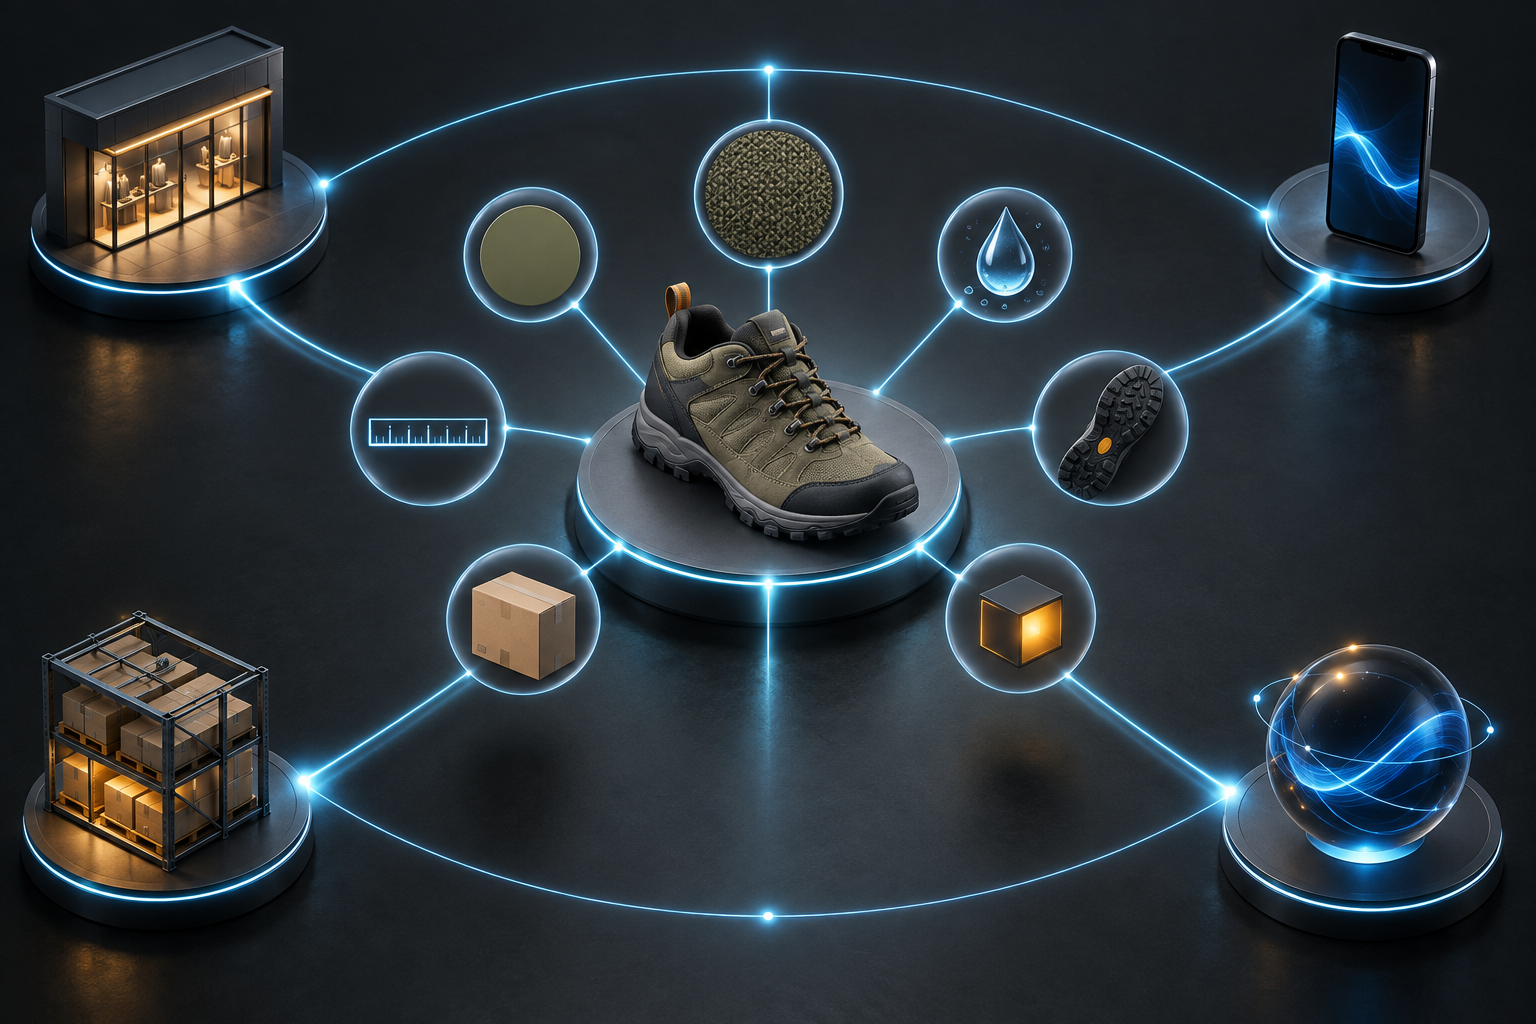
    A hiking shoe on a central platform sends the same set of visual product attributes to a storefront, phone, warehouse shelf, and AI orb.

    Start with an internal product record, not a block of marketing copy. This record should be the authoritative source for the product page, structured data, merchant feeds, marketplace listings, comparison pages, and support content. When those surfaces disagree, an assistant has to choose among conflicting claims or avoid repeating them.

    For each product and meaningful variant, define the following fields explicitly:

    • Identity: brand, product name, model, assigned SKU or GTIN, canonical URL, and product category.
    • Variant: color, size, capacity, material, pack quantity, configuration, and the relationship to the parent product.
    • Eligibility attributes: dimensions, weight, compatibility, intended use, required accessories, included components, operating conditions, and other category-specific constraints.
    • Commercial facts: price, currency, condition, availability, fulfillment terms, returns, and warranty terms.
    • Evidence: certifications, documented test conditions, review data, manuals, specifications, and the exact scope of each claim.

    Do not populate a field because competitors use it or because a schema validator permits it. An unknown value should remain unknown until the business can verify it. A precise false claim is worse than an honest omission because the false claim can be repeated in a recommendation, create a poor purchase, and undermine trust in the rest of your data.

    Keep the visible page, schema, and feeds aligned

    Product structured data should encode facts that a shopper can also verify on the page. Use Product markup to identify the item and its attributes. Use Offer data only for an offer that actually exists. Add rating or review properties only when the corresponding information is genuine, visible, and attached to the correct product or variant.

    JSON-LD does not create product truth. It translates product truth into a machine-readable form. If the page says one material, the markup says another, and the feed omits the field, adding more schema will multiply the ambiguity rather than fix it.

    Variant handling deserves particular attention. A family page may describe several configurations, but price, dimensions, availability, ratings, and compatibility can belong to only one of them. Give meaningful variants stable identities and make the selected variant unambiguous in the page content, URL behavior, structured data, and feed.

    Separate durable facts from fast-changing facts

    Product data fails at different speeds. Model identity, dimensions, materials, compatibility, and included components are usually durable. Price, availability, promotions, delivery estimates, and review aggregates can change much faster.

    Give each fast-changing field an owner, a system of record, and a refresh trigger. Avoid embedding volatile values in editorial prose unless that prose is updated from the same source. A stale promotional page and a current product feed can leave an assistant with two plausible answers and no reliable way to reconcile them.

    Match shopper constraints and support every important claim

    Traditional product copy often begins with a head keyword and expands into benefits. AI shopping requests are more likely to combine a job, a hard constraint, and a preference: a product for a particular use, compatible with something the shopper already owns, within a budget, and with a preferred trade-off.

    Create a prompt set from the decisions people make, not just the phrases with the highest search volume. Include several distinct request types:

    • Job prompts: What is the shopper trying to accomplish?
    • Constraint prompts: What would make a product ineligible, such as size, compatibility, material, price, or availability?
    • Trade-off prompts: Which quality matters more when no option maximizes everything?
    • Comparison prompts: Which alternatives are genuinely close enough to compare?
    • Risk prompts: What must the shopper verify before buying?

    Then map every consequential question to a field and a piece of evidence. The map exposes a common failure: the marketing team believes a benefit is obvious, but the product page never supplies the fact an assistant would need to infer it safely.

    Shopper questionMachine-readable answerHuman-verifiable support
    Will it fit?Dimensions, weight, capacity, or supported size rangeSpecification table, diagram, or installation instructions
    Will it work with what I own?Compatible models, interfaces, versions, or required accessoriesCompatibility page, manual, or clearly scoped support content
    Can I buy it under my stated conditions?Current price, currency, condition, availability, and offer detailsVisible offer and fulfillment information
    Is it suitable for this use?Intended use and relevant product attributesUse-case explanation tied to specifications rather than slogans
    Can I trust this claim?Named evidence and its scopeCertification details, documented method, policy, or attributable review data

    State who the product is and is not for

    A useful product page helps an assistant eliminate the wrong matches. State the primary use, the buyer or environment it suits, the constraints it satisfies, and any condition that would make another option more appropriate.

    This does not weaken the offer. A clear limitation can make the positive recommendation more credible. If a product requires an adapter, has a fixed dimension, excludes a particular model, or is designed for one usage pattern rather than another, say so close to the relevant benefit. Hiding the qualifier may generate more initial interest, but it gives an assistant less reason to trust or repeat the claim.

    Comparison content should use decision criteria rather than a list of adjectives. Explain which product fits which condition and why. Avoid declaring an item the best without naming the use case, comparison set, and evidence. An unqualified superlative is difficult to defend and easy for a recommendation system to ignore.

    Maintain a claim-to-evidence ledger

    For every claim that could change a purchase decision, keep an internal ledger containing the claim, its exact qualifier, the supporting evidence, the page where that evidence is visible, the responsible owner, and the event that should trigger a review.

    The qualifier matters. A certification may apply to one variant, a test may use specific conditions, and a warranty may differ by market. Preserve that scope everywhere the claim appears. Do not turn narrow evidence into a product-wide promise.

    Customer reviews can help describe recurring strengths and limitations, but keep review data attached to the product or variant it evaluates. Combining materially different variants may produce a stronger aggregate while giving the assistant a less accurate picture of the item in front of the shopper.

    Support pages, manuals, compatibility resources, return policies, and comparison pages should link back to the canonical product and use the same names and identifiers. That creates a coherent evidence trail instead of a set of disconnected documents with slightly different terminology.

    Audit the complete path from prompt to recommendation

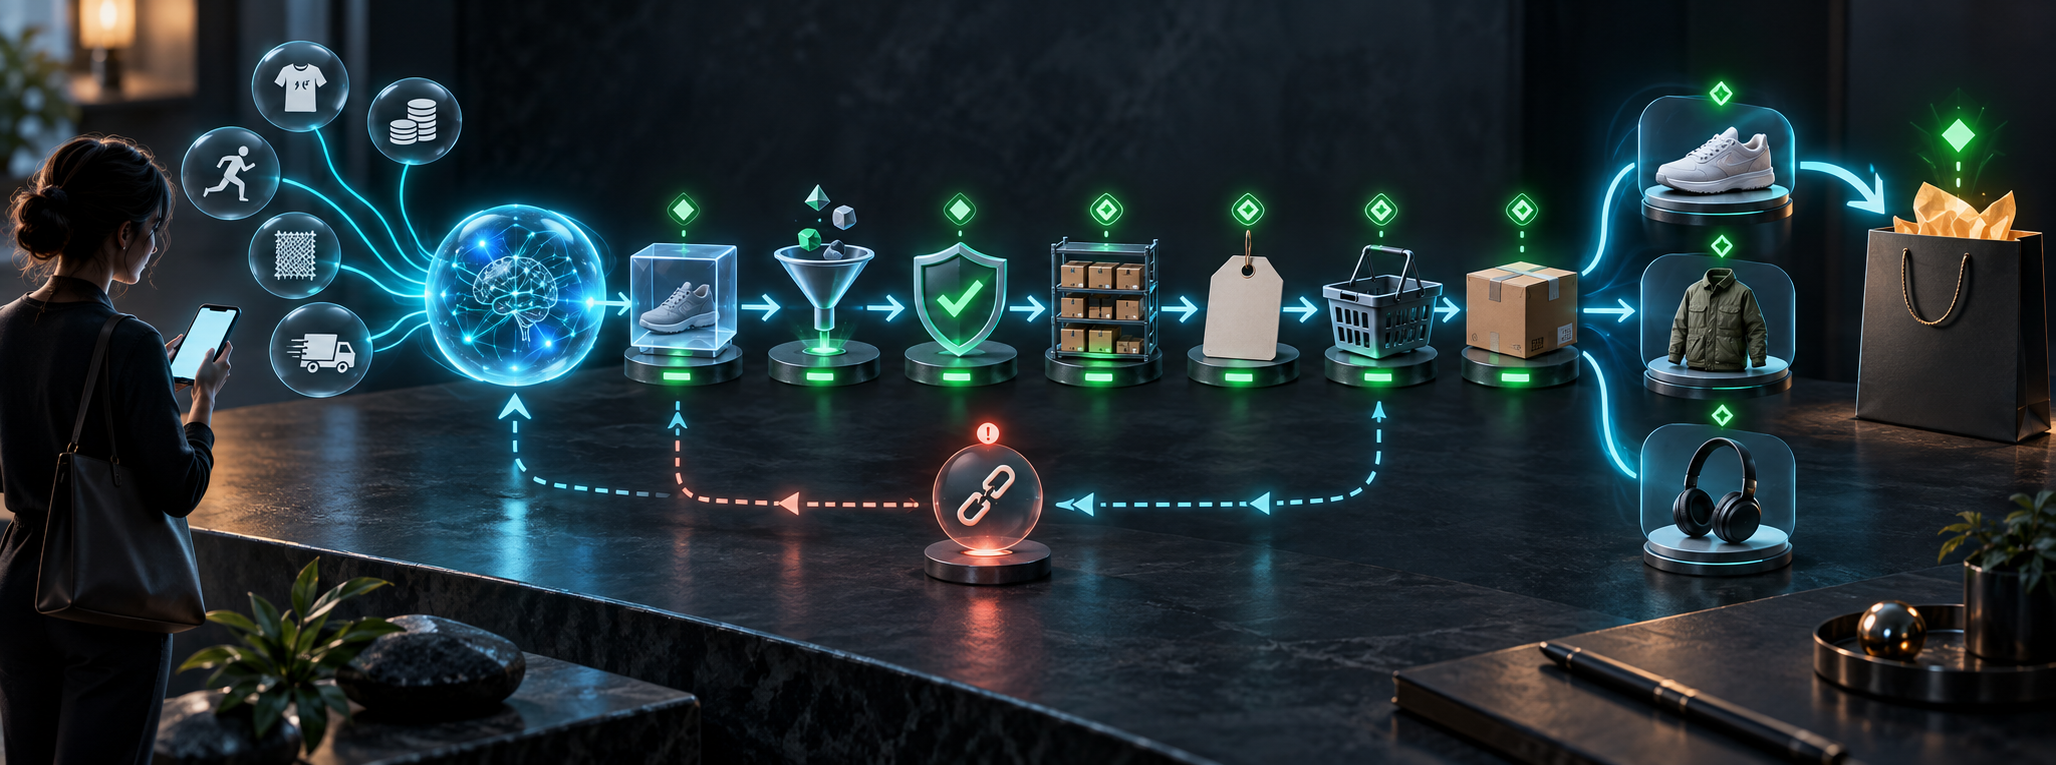
    A shopper request travels through product, evidence, inventory, checkout, and delivery checkpoints before reaching an unbranded product shortlist.

    Do not reduce AI shopping visibility to a rank check. You need to see where the product exits the decision process and whether the answer is factually correct when it does appear.

    1. Choose eligible prompts. Test requests for which the product could honestly be a suitable answer. Irrelevant prompts distort the score and tempt teams to broaden claims beyond the product’s real fit.
    2. Record a baseline. Save the exact prompt, assistant, date, market or locale, response, recommended products, stated reasons, and any surfaced links.
    3. Label the outcome. Distinguish absence, failed qualification, incorrect description, unsupported mention, and an eligible product that lost on a documented trade-off.
    4. Trace the earliest failed gate. Repair identity and discovery before attributes, attributes before evidence, and evidence before promotional expansion.
    5. Rerun the same prompt set. Compare changes in coverage and accuracy while recognizing that any individual generated response can vary.
    6. Inspect the commercial handoff. If the recommendation is accurate but the shopper does not proceed, examine the offer, availability, landing experience, and product-market fit rather than calling every weak outcome an AI visibility problem.

    The failure pattern tells you where to look first:

    Observed resultLikely failure areaFirst inspection
    The product never appearsDiscoveryIndexability, canonical URL, feed inclusion, product identity, and internal linking
    The wrong variant appearsIdentityVariant names, identifiers, URLs, parent relationships, and selected-offer data
    The product disappears after a valid constraint is addedQualificationThe missing, ambiguous, or conflicting attribute associated with that constraint
    The assistant states an incorrect factProduct truthConflicts and stale values across the page, schema, feed, marketplace, and support content
    The product is considered but not recommendedSelectionUse-case specificity, comparison criteria, limitations, and claim-level evidence
    The recommendation is accurate but does not convertCommercial handoffPrice, availability, trust, offer clarity, landing experience, and actual product fit

    Track metrics that correspond to those states. Prompt coverage shows whether the product appears for eligible requests. Attribute resolution shows whether the assistant can answer the important constraint questions. Answer accuracy catches misdescription. Evidence visibility shows whether useful supporting pages are surfaced. Recommendation share shows how often the product is selected when it is genuinely eligible. Commercial outcomes tell you whether improved visibility creates useful demand.

    Keep the prompt set and eligibility rules stable while evaluating a change. If you change the content, prompts, markets, and success definition at the same time, you will not know what improved. Treat assistant outputs as observations, not permanent rankings.

    Key takeaways

    • Optimize for discovery, qualification, and selection as separate gates.
    • Create one canonical product record before expanding copy, schema, feeds, or comparison content.
    • Make decisive constraints explicit; do not ask an assistant to infer compatibility, fit, or eligibility from vague prose.
    • Keep visible content, Product structured data, offers, variants, and merchant feeds consistent.
    • Attach meaningful claims to scoped evidence and state important limitations plainly.
    • Measure eligible prompt coverage and factual accuracy before treating recommendation share as the main result.

    Start with one commercially important product family. Establish its canonical facts, build prompts around real purchase constraints, and fix the earliest gate that fails. Once that path is reliable, extend the same operating model to the rest of the catalog. That gives you a repeatable visibility system instead of a collection of schema additions and copy changes whose effect you cannot explain.

    References

  • Content Refresh or New Page? A Decision Guide for AI Search

    Content Refresh or New Page? A Decision Guide for AI Search

    You have a page whose answer is getting stale, but the URL may still hold useful search visibility, links, and recognition. Editing it too aggressively could erase what made it useful. Publishing another page could split one clear answer across two competing URLs.

    The decision turns on continuity: does the existing URL still represent the question you want to answer? The right planning question is not simply how often to update. It is when to refresh and when to create something new for AI search. Use the framework below to make that call before anyone starts rewriting.

    Start with answer continuity, not publication age

    Every useful URL makes an implicit promise. Its title, opening, headings, internal links, and search snippets tell a reader what question the page will resolve. A refresh is appropriate when that promise remains valid and the answer needs to become more accurate, complete, or usable. A new page is appropriate when the promise itself has changed.

    This distinction matters more than the size of the edit. You can rebuild most of a page and still call it a refresh if the same reader arrives with the same question and should reach the same kind of outcome. Conversely, a short addition can deserve a separate URL if it serves a materially different intent, audience, entity, version, or decision.

    Use this three-step test before looking at traffic charts:

    1. Write the existing page’s primary question in one sentence, using the language a reader would use.
    2. Write the proposed page’s primary question in another sentence. Do not describe the content format; describe the decision or task the reader needs to complete.
    3. Compare the expected outcomes. If both questions lead to the same outcome, refresh the existing page. If they lead to different outcomes and both remain useful, create a new page.

    Suppose an existing page explains what answer engine optimization is. Adding current terminology, clearer examples, better sourcing, and a stronger definition would preserve its promise. A page that helps a marketing lead choose an AEO measurement platform serves a different job. Forcing that purchasing decision into the definition page would make both answers harder to extract and harder to trust.

    A refresh is usually the cleaner choice when the target question, intended reader, principal entity, and required answer format remain stable. It is also appropriate when outdated claims can be replaced without changing the page’s central conclusion.

    Create a new page when the reader now needs a different task completed, such as moving from learning to comparing, implementing, troubleshooting, or buying. A separate page is also warranted when a new product version, market, audience, or use case has enough distinct constraints to support its own complete answer.

    Do not let a traffic decline make the decision for you. Declining traffic can trigger an audit, but it does not prove that the URL is obsolete. The page may have weak evidence, an indirect opening, an outdated title, changed search demand, stronger competition, or technical problems. Diagnose the mismatch before choosing the remedy.

    Audit the question, claims, entities, and page structure

    A magnifying lens examines layered document components, connected spheres, evidence tiles, and modular page blocks.

    A useful content audit separates five layers that teams often collapse into one vague judgment about freshness. Review each layer independently. One outdated statistic may require a correction; a changed audience may require an entirely new page.

    Audit layerQuestion to askSignal to refreshSignal to create a new page
    QueryWhat specific question should this URL answer?The wording has evolved, but the reader’s task is unchanged.The proposed query represents another task or decision stage.
    AnswerWhat must the reader know or do after reading?The conclusion still holds and needs better support or explanation.The new conclusion would conflict with or displace the existing answer.
    AudienceWho is the answer for, and what do they already know?The same audience needs a clearer or more current explanation.A distinct audience needs different assumptions, terminology, or actions.
    EntityWhich product, organization, concept, location, or version is central?The same entity needs corrected attributes or relationships.A separate entity or version deserves independent treatment.
    StructureCan the answer remain coherent on the current page?Sections can be repaired without changing the page’s purpose.The proposed material would overwhelm the original answer or create two competing introductions.

    Begin the audit with the rendered page, not just the draft in your content management system. Record the title, opening answer, headings, important claims, citations, internal links, media, structured data, canonical target, and displayed publication or modification dates. Save a version before editing so you can distinguish the effect of the change from your memory of the old page.

    Next, label every consequential claim as current, obsolete, unsupported, ambiguous, or outside the page’s scope. Pay particular attention to claims that can change independently of the main topic: product features, prices, eligibility rules, named executives, legal requirements, performance figures, dates, and version-specific instructions. Do not preserve an unsupported statement merely because the page performs well.

    Then inspect the answer a machine or hurried reader is likely to encounter first. If the title promises one question while the opening answers another, the page has an alignment problem. If the direct answer appears only after a long historical preamble, the page has an extraction problem. Both are refresh problems when the underlying intent remains stable.

    Entity ambiguity deserves its own pass. A page that alternates between a company, its platform, a feature, and an industry category without defining their relationships may be readable to an insider but unclear outside that context. Introduce the principal entity explicitly, use consistent names, and clarify relationships that affect the answer. Structured data cannot repair contradictory prose.

    Use performance evidence after the semantic audit. Review the queries and landing-page behavior available to you, conversions tied to the page’s intended outcome, internal-search terms, links, and any reliable records of AI referrals or citations. Treat AI answer observations as directional rather than deterministic: outputs can vary by prompt, model, context, location, and time. A single missing citation is not enough evidence to replace a URL.

    Calendar age should trigger inspection, not automatic rewriting. Set review frequency according to the page’s rate of change. Version-dependent instructions should be reviewed when the product changes. Pages built around external rules or figures should be checked when the underlying authority changes. Stable conceptual pages can be reviewed when query patterns, audience needs, or the evidence base shifts. The useful cadence is therefore page-specific rather than one site-wide interval.

    Refresh the URL without blurring its original promise

    Once you choose a refresh, define what will remain unchanged. Write a one-sentence content brief containing the primary question, intended reader, required outcome, and central entity. That sentence becomes the boundary for the revision. Any proposed section that serves another substantial question goes into a separate-page backlog.

    1. Capture a baseline. Save the current page, record the change date, and preserve the available query, engagement, conversion, link, and AI-visibility evidence. Without a baseline, a later increase or decline will be difficult to interpret.
    2. Repair the opening answer first. Make the page’s conclusion or recommended action visible near the start. State important conditions and exceptions where they affect the answer rather than hiding them in a closing note.
    3. Replace obsolete material in place. Do not leave a wrong claim in the main text and append a correction at the bottom. Remove or rewrite passages that no longer help the reader complete the stated task.
    4. Strengthen the evidence chain. Connect consequential claims to appropriate supporting references, identify versions and dates when they matter, and distinguish established facts from editorial judgment or uncertain observations.
    5. Rebuild the heading structure around real subquestions. Each section should resolve a distinct part of the primary question. If two sections repeat the same conclusion in different language, combine them.
    6. Align internal links with the revised role of the page. Links pointing in should accurately describe what the reader will find. Links pointing out should handle adjacent questions without making this page compete with them.
    7. Update machine-readable information to match the visible page. Structured data should describe the content that is actually present, use the applicable type, and remain consistent with names, dates, authorship, and entities shown to readers.
    8. Publish with an honest modification signal. Update a modification date when a substantive revision occurred, not as a cosmetic attempt to make unchanged material look current. Keep an internal change log so the team knows what was altered and why.

    Preserve the existing slug unless changing it solves a real information-architecture problem. A refreshed page does not need a new URL merely because its title changed. If a slug must change, map the old URL to the most appropriate replacement and update important internal links; otherwise, you introduce avoidable routing and measurement noise.

    Be equally disciplined with schema. Adding more JSON-LD types does not compensate for a weak answer. Markup should represent visible, accurate information and should not imply reviews, FAQs, authorship, products, or organizational relationships the page does not substantiate. Validate the markup after publishing, but treat technical validity as a floor rather than proof that the content is useful.

    After publication, confirm that the page renders correctly, remains indexable where intended, exposes the expected canonical URL, and includes the revised structured data. Annotate the release in your reporting. Then watch the same measures captured in the baseline. Do not change the page repeatedly in response to isolated fluctuations; overlapping revisions make it impossible to learn which change mattered.

    Create a new page when the reader needs a separate answer

    A luminous information stream divides into two non-overlapping paths leading to separate pavilions with distinct clusters of connected nodes.

    A new page should exist because it resolves a distinct question, not because the editorial calendar needs another URL. Before commissioning it, complete this sentence: “Unlike the existing page, this page helps [audience] accomplish [outcome] under [relevant conditions].” If the difference cannot be expressed without vague words such as deeper, broader, or updated, the proposed page probably belongs in the refresh.

    Distinct search intent is the strongest reason to separate pages. A definition, implementation tutorial, vendor comparison, troubleshooting workflow, and measurement plan may concern the same topic while serving different decisions. Giving each substantial task a clear home lets you answer it directly without turning one page into a collection of half-developed responses.

    A separate audience can also justify a new URL, but only when the difference changes the answer. Replacing “marketing leader” with “agency” in the title is not enough. The agency page should have meaningfully different constraints, examples, evaluation criteria, responsibilities, or actions. Otherwise, you have created a near-duplicate with a new label.

    When both pages will remain live, design their relationship before publishing:

    • Assign one primary question and one intended outcome to each page.
    • Give each page a distinct title, opening answer, heading plan, and internal anchor language.
    • Link between the pages with explanatory context, such as moving from a definition to an implementation process, rather than using the same generic anchor everywhere.
    • Keep each page’s canonical treatment consistent with its intended indexing role. Do not point one page at another as canonical while also expecting both to function as independent search results.
    • Avoid copying a large shared introduction into both pages. State only the background each reader needs, then move into the page-specific answer.
    • Update relevant hub pages, breadcrumbs, navigation, and XML sitemap handling so the new page has a clear place in the site architecture.

    If the new page replaces the old answer rather than complementing it, decide whether any meaningful reason remains to visit the old URL. When the old page has no independent purpose, consolidate useful material into the replacement and route the old URL appropriately. When the old question still matters, retain it and narrow its content so the boundary between the two pages is obvious.

    Define measurement before launch. The old and new pages should have separate expected query themes and reader outcomes. Track whether each URL begins attracting the intended demand, whether internal and external references point to the appropriate page, and whether conversions or downstream actions match the page’s role. If you monitor AI answers, use a stable prompt set and record the model, context, and observation date so comparisons are at least directionally consistent.

    When the pages begin appearing for the same queries, do not assume consolidation is immediately necessary. First inspect whether the queries are genuinely identical in intent. Tighten titles, openings, headings, and internal links if the distinction exists but is poorly communicated. Merge only when you cannot maintain a useful boundary or when one page adds no independent value. If you do consolidate, preserve the strongest answer, update links, and redirect deliberately rather than simply deleting the weaker URL.

    Key takeaways

    • Refresh an existing page when the same audience still asks the same primary question and needs the same kind of outcome.
    • Create a new page when intent, audience needs, central entity, version, or decision stage changes enough to require an independent answer.
    • Treat page age and traffic decline as audit triggers, not automatic reasons to rewrite or replace a URL.
    • Audit the query, answer, audience, entities, claims, structure, links, and structured data before choosing an editorial action.
    • When refreshing, preserve the page’s promise while replacing obsolete claims, strengthening evidence, and aligning JSON-LD with visible content.
    • When creating a page, define its boundary, relationship to existing URLs, indexing role, and success measures before publication.

    Start with one page that is due for review. Write its current question and proposed question side by side. If the reader and outcome remain continuous, refresh it with a recorded baseline. If the outcome changes, write the new page’s distinct job before creating the URL. That small decision document will prevent most accidental duplication and unfocused rewrites.

    References


  • Long-Term SEO Lessons for Durable AI Search Visibility

    Long-Term SEO Lessons for Durable AI Search Visibility

    If you are deciding whether AI search means rebuilding your SEO program, do not begin by renaming every task GEO. First separate what has changed from what has not. Interfaces now accept longer prompts, follow-up questions, images, and richer context. Your underlying job is still to understand what someone needs, make the answer accessible, support it with credible evidence, and connect that answer to a useful next step.

    The durable advantage is not predicting the next interface. It is building an SEO system that can absorb interface changes without abandoning sound diagnosis, technical access, content quality, or business judgment.

    Search interfaces change; the user’s job survives

    A person in a circular workspace follows one illuminated path past a keyboard, conversation form, camera, and context panels toward a practical solution.

    A keyword is not the need itself. It is the amount of that need a particular search box allows someone to express. Short search fields encouraged compressed phrases. Conversational systems let people add requirements, objections, examples, and follow-up questions. Multimodal systems can accept a screenshot instead of forcing the user to describe what is on it.

    This matters because a keyword list can capture familiar language while missing much of the context people now supply. A 17-month Semrush clickstream analysis credited to Luke Harsel found that 65% to 85% of ChatGPT prompts matched no term in a database of 27 billion keywords. That finding does not make keyword research obsolete. It shows why keyword volume cannot be treated as a complete map of demand.

    Use keywords as clues, then build around intent. For every important page or topic, create an intent brief with five fields:

    <!– wp:list {
  • Google Search Visibility Data Changed: What to Trust Now

    Google Search Visibility Data Changed: What to Trust Now

    Your SEO dashboard can look worse even when your site has not lost meaningful Google visibility. If total ranking keywords or SERP features suddenly collapse while clicks and leads remain steady, do not declare a ranking loss until you determine whether the site changed or the measurement system did.

    Google has changed how third-party tools can collect search results, altered an important result-depth parameter, and added first-party reporting for multimodal searches. The practical challenge is no longer choosing one perfect metric. It is knowing which question each metric can still answer.

    Three breakpoints changed the meaning of your trend lines

    A rank tracker can lose the ability to observe a result without your page losing its position. That distinction became more important after three Google changes:

    Each change makes large-scale collection more difficult or expensive. Losing num=100 means a provider can no longer request the first 100 results in one operation. Resolving passthrough links adds work for each affected result. A provider may respond by collecting fewer positions, sampling more aggressively, refreshing less frequently, or charging more for equivalent coverage.

    The distortion is most likely to appear deep in the results because positions below the first page are expensive to collect and usually less valuable to customers. This turns a platform’s total keyword count into two measurements at once: your site’s search footprint and the platform’s ability to observe that footprint. Treating it as a pure performance metric is now a category error.

    Recognize the signature of a collection failure

    Luminous result tiles pass through a scanning tunnel, where a blocked aperture causes only part of the continuing stream to reach the collection trays.

    A genuine visibility loss and a collection failure can both produce a falling graph. The distribution of the decline tells you which explanation is more plausible.

    For Reddit, Semrush data from May to June 2026 showed more than 60 million fewer ranking keywords and more than 13 million fewer SERP features. Those represented month-over-month declines of 25% and 21%, respectively, while estimated traffic remained steady. The loss also became progressively larger at deeper positions:

    Position bandChange from May to June 2026What the pattern indicates
    Position 1+16%The most visible rankings remained observable
    Top 3+11%High-value coverage did not collapse
    Positions 4-10-8%Loss began within the remaining first-page results
    Positions 11-20-28%Missing coverage accelerated beyond page one
    Positions 21-50-34%Deep-result visibility deteriorated sharply
    Positions 51+-35%The deepest rankings were the least observable

    This is not a universal benchmark. It is a diagnostic pattern. A real sitewide ranking collapse of that scale would not normally erase progressively more deep positions while expanding Position 1 and Top 3 counts and leaving estimated traffic unchanged. A depth-weighted decline points more strongly to reduced collection coverage.

    It can also make the surviving data look deceptively healthy. If a tool stops observing positions 40 through 80 but retains positions 1 through 10, the reported keyword total falls while the average position may improve. That apparent improvement is survivor bias, not necessarily better SEO.

    Use this sequence whenever a visibility graph breaks:

    1. Start with business outcomes. Check whether organic leads, sales, sign-ups, or other meaningful actions declined during the same period. Stable outcomes do not prove that rankings were stable, but they reduce the likelihood of a commercially significant collapse.
    2. Check Google Search Console clicks and landing pages. If third-party keyword totals plunge while clicks and the pages receiving those clicks remain broadly stable, investigate collection coverage before changing content.
    3. Split rankings into Position 1, Top 3, positions 4-10, 11-20, 21-50, and 51+. A drop concentrated in the deepest bands is more consistent with an observation problem than an across-the-board ranking loss.
    4. Compare branded and non-branded priority queries separately from the provider’s entire discovered keyword universe. A controlled set of commercially important queries is more useful for tactical decisions than a volatile inventory of every term the tool happened to find.
    5. Look for provider-specific discontinuities. If one platform changes abruptly while first-party clicks, outcomes, and another independent ranking view do not, label the event as a probable measurement break.
    6. Allow for mixed diagnoses. A collection change and a real traffic decline can happen together. If clicks, conversions, important landing pages, and high-ranking priority queries all deteriorate, continue the SEO investigation even if deep-result coverage also changed.

    Rebuild reporting around questions, not one visibility score

    No single visibility number can now support every decision. Give each reporting layer a defined job and state its limitation beside it.

    Reporting layerUse it to answerMain limitation
    Business outcomesIs organic search contributing qualified leads, sales, or other valuable actions?Demand, attribution, and conversion behavior can change independently of rankings
    Google Search Console clicks and pagesDid Google Search send traffic, and which landing pages received it?Reporting definitions and automated search activity can affect historical comparability
    Priority rank setDid a controlled set of branded, commercial, and strategically important queries move?Results vary by location, device, and the provider’s collection method
    Total keywords and SERP featuresWhere might new topics, competitors, or result features be emerging?These inventory metrics are highly exposed to collection-depth changes
    Multimodal performanceAre visual search experiences discovering the site’s content?It is a distinct search surface and does not replace conventional ranking or generative AI query data

    Your report also needs a measurement change log. Record the date, affected tool, affected metric, likely mechanism, position bands involved, and whether the provider changed its collection method. Put the annotation on the chart itself. A note hidden in a separate methodology document will not stop someone from treating the break as a performance event.

    Keep the original series, but do not draw an unqualified continuous trend across an incompatible baseline. Compare periods collected under the same method where possible. If that is not possible, present pre-change and post-change periods as separate regimes and label the comparison as measurement-affected. Do not invent a correction factor unless you have enough overlapping data to defend it.

    September 2026 year-over-year reports require particular care. Search Console impressions fell after num=100 disappeared in September 2025 because automated requests had previously generated impressions for deep results. That creates a suppressed comparison baseline, so double-digit year-over-year impression growth can appear without an equivalent improvement in actual performance.

    Do not present that percentage alone. Put absolute clicks, business outcomes, priority-query movements, and landing-page performance beside it. If only impressions rebound against the lower baseline, describe the result as affected by measurement history rather than evidence of equivalent SEO growth.

    Measure multimodal discovery as a separate search surface

    An object on a pedestal is examined through three separate pathways represented by a visual sensor, an acoustic sensor, and a magnifying lens.

    While third-party result coverage is becoming less complete, Search Console is adding a first-party view of visual discovery. Its multimodal search filter covers Google Lens, Circle to Search on Android, image uploads to Google Search, and Chrome’s Search this image action. The data is rolling out globally and appears when a site receives traffic from those experiences.

    Multimodal visibility should not be folded silently into a general visibility score. A person searching with an image is expressing intent differently from someone typing a conventional query, and the optimization work is often different. Track the surface separately so you can see whether visual discovery is growing, which pages participate, and whether that exposure leads to useful behavior.

    • Record when multimodal data first becomes available for your property. Do not interpret the first visible reporting period as the date your site first appeared in visual search.
    • Review the landing pages associated with multimodal activity. Check that their images are useful to the page’s purpose, accessible to crawlers, supported by clear nearby text, and described with accurate text alternatives.
    • Keep structured data faithful to the visible page. Schema can clarify products, organizations, articles, and other entities, but it should not describe an image, offer, or claim that users cannot find on the page.
    • Connect multimodal reporting to page-level outcomes. More visual discovery is interesting; it becomes valuable when the discovered pages attract relevant engagement or conversions.
    • Do not manufacture query-level precision where Google does not supply it. The generative AI search performance report still lacks click and query data, so a generative visibility narrative should acknowledge that blind spot.

    The new filter is an additional lens, not compensation for missing third-party keyword coverage. It answers a new question: whether people are finding your content through visual and multimodal behavior. It does not tell you that a disappearing position-50 keyword remained stable, and it does not provide the prompt-level attribution many teams want from generative search.

    Key takeaways for your next SEO report

    • A falling third-party keyword count is not, by itself, evidence of lost Google traffic.
    • A decline concentrated below positions 10 or 20 is more suspicious as a collection problem than a uniform loss across top rankings.
    • Clicks, landing pages, and business outcomes should determine the severity of the response; discovered keyword totals should support exploration, not act as the verdict.
    • January 2025, September 2025, and August 2026 belong in your reporting change log because each altered how search visibility could be observed.
    • September 2026 year-over-year impression growth may be inflated by the lower post-num=100 baseline from September 2025.
    • Multimodal reporting deserves its own baseline, goals, and page-level analysis. Do not merge it into conventional web or generative AI visibility without a label.

    Before your next report goes out, annotate the three collection breakpoints, split ranking data by depth, and place first-party clicks and business outcomes ahead of total keyword counts. Then establish a separate baseline for multimodal discovery. That small reporting redesign can keep a measurement change from triggering the wrong content rewrite, budget decision, or performance diagnosis.

    References


  • Google Search Ranking Factors in 2026: What to Prioritize

    Google Search Ranking Factors in 2026: What to Prioritize

    If your rankings have stalled, the answer probably is not another hundred-item SEO checklist. The useful question is narrower: which improvements can still separate your page from competent competitors, and which ones merely keep you eligible to compete?

    In 2026, the strongest plan starts with satisfying content, deep subject coverage, and evidence that real searchers find the page useful. Titles, links, trust, brand recognition, freshness, and technical health still matter, but they play different roles. You need to know whether each signal creates an advantage, confirms relevance, supplies proof, or clears a minimum threshold.

    The 2026 priority map: advantage signals versus thresholds

    Use the percentages below as a directional resource-allocation model, not as Google’s official formula. These estimated 2026 weights come from a single long-running agency dataset. They can help you decide where to invest, but they cannot predict the ranking of every page for every query.

    Ranking factorEstimated 2026 weightChange from 2025Practical role
    Consistent publication of satisfying content24%Up 1 pointPrimary competitive advantage
    Niche expertise14%Up 1 pointTopical depth and retrieval coverage
    Searcher engagement13%Up 1 pointEvidence that the page resolves the visit
    Keyword in the meta title12%Down 2 pointsRelevance and click expectation
    Backlinks12%Down 1 pointExternal authority and corroboration
    Freshness6%UnchangedContinued accuracy and usefulness
    Trustworthiness5%Up 1 pointAuthorship, evidence, and accountability
    Mobile-friendly, mobile-first site4%Down 1 pointTechnical threshold
    Link distribution diversity3%UnchangedBreadth of external validation
    Page speed2%Down 1 pointTechnical threshold and usability
    Brand mentions2%New as a standalone factorEntity recognition and reputation
    Site security and SSL1%Down 1 pointTechnical threshold
    Internal links1%UnchangedDiscovery, hierarchy, and context
    Meta descriptions and 22 other factors1% combinedNot specifiedSupporting signals

    Do not turn this table into a page score. A technically perfect page does not earn a fixed number of ranking points, and publishing more often does not compensate for failing the searcher’s task. The weights are most useful at the portfolio level: they show where marginal investment is likely to produce differentiation and where compliance has become commonplace.

    Key takeaways

    • The three leading content and audience factors account for 51% of the estimated weighting: satisfying publication at 24%, niche expertise at 14%, and searcher engagement at 13%.
    • Titles and backlinks still account for 24% combined. Their declining weights mean they are no longer adequate substitutes for a weak page, not that you can ignore them.
    • Mobile friendliness, page speed, and security total 7% in the model. They behave more like eligibility thresholds because competent sites commonly meet them.
    • Schema markup, header keywords, URL keywords, meta-description keywords, and numerous smaller signals share a 1% residual group. Treat them as supporting implementation, not the center of your ranking strategy.

    Build content around complete search tasks, not publishing quotas

    A researcher at a desk brings connected source materials and visual information fragments together into one complete solution.

    Consistent publication leads the model only when the content satisfies the search. Across one agency’s client sites during the March and May 2026 core updates, sites publishing weekly gained an average of 3.8 positions on their hub keywords, while sites publishing less than monthly lost an average of 2.7 positions. That is useful directional evidence, but it does not make weekly publishing a universal rule. The meaningful variable is a sustainable flow of pages that finish a real search task.

    Volume without satisfaction can become a liability. If your team can produce one defensible page that answers the question, shows its reasoning, and helps the reader decide what to do, that page is more valuable than a cluster of near-duplicates written to occupy keyword variations.

    Design a hub for query fan-out

    Google’s AI Mode can use query fan-out to break a question into related sub-searches and retrieve different pages for the resulting needs. That favors sites with coherent depth across a subject. It does not justify making a page for every minor wording change.

    1. Name the hub’s core problem. Write it as a task the reader needs to complete, not as a broad category your company wants to own.
    2. Map meaningful dimensions. Look for genuinely different industries, use cases, customer types, specialties, constraints, and decision stages. A dimension deserves its own page only when the answer materially changes.
    3. Assign one best page to each intent. If several URLs would give essentially the same answer, consolidate them instead of forcing artificial distinctions.
    4. Give every supporting page a job. It should answer its own question, connect back to the hub, and direct the reader to the next relevant decision.
    5. Identify the missing evidence. Add the comparison, process, example, definition, limitation, original data, or decision rule that competing pages leave unresolved.

    This approach builds niche expertise through coverage and coherence. A site becomes easier to retrieve across related sub-searches because each page has a distinct purpose inside a recognizable body of work.

    Use engagement to diagnose the page, not manipulate a metric

    Searcher engagement rose to 13% for the fourth consecutive annual increase. AI Overviews and AI Mode can resolve simple informational needs before a website visit, leaving a smaller pool of people who click because they need detail, evaluation, or action. Those visitors notice generic content quickly.

    Do not reduce this to a campaign to increase time on page. Google has not handed you a public formula that converts an analytics metric into ranking points. Use behavior as diagnostic evidence instead:

    • Does the opening answer the query immediately, or make the reader cross an essay-length preamble?
    • Can a visitor find the relevant comparison, instruction, definition, or limitation without hunting through unrelated sections?
    • Does the page support the likely next action, such as checking a requirement, choosing an option, or moving to a more specific page?
    • Are visitors encountering a mismatch between the title’s promise and the page’s actual depth?

    Fix the underlying experience. Removing padded introductions, making distinctions explicit, and placing the decisive information where it is needed are more durable choices than adding interaction for its own sake.

    Make relevance, authority, trust, and brand reinforce one another

    Titles, backlinks, trust signals, and brand mentions answer different versions of the same question: why should Google select this page from this site for this search? Treating them as one coordinated proof system produces a stronger result than optimizing each in isolation.

    Write titles for clear meaning rather than exact-match repetition

    The keyword in the meta title fell from 14% to 12%, the largest decline in the 2026 weighting. Google’s May 2026 search-box redesign encouraged longer, conversational queries, making the page’s overall meaning more important than an exact string match. The title still functions as a prerequisite-level relevance signal and sets the searcher’s expectation.

    • State the main subject in language your intended reader will recognize.
    • Add the qualifier that changes the answer, such as the year, platform, audience, use case, or decision type.
    • Describe the value of the page without promising a result the content cannot deliver.
    • Remove repeated keyword variants that make the title less readable without clarifying its scope.

    A good title is not a bag of terms. It is a compact contract: this is the subject, this is the version of the problem being addressed, and this is what the reader can expect to resolve.

    Earn links with something worth citing

    Backlinks declined to 12%, continuing an eight-year downward trend, while link distribution diversity remained at 3%. Links are still meaningful evidence, but the useful links are increasingly editorial: another publisher chooses to reference your original data, resource, or explanation because it improves their own work.

    Before running outreach, ask what the recipient would actually cite. A well-defined dataset, transparent benchmark, reusable template, calculator, primary-source collection, or unusually clear decision framework gives outreach a reason to exist. A routine article with no distinctive evidence leaves you negotiating for a link rather than earning one.

    Avoid manufactured link patterns. Recent spam enforcement has focused on attempts to borrow or fabricate authority, so the downside is not limited to wasting budget. The safer strategy is to create a reference-worthy asset, identify publications whose readers genuinely need it, and explain the precise section where it contributes evidence.

    Make trust visible at the claim level

    Trustworthiness rose from 4% to 5% as low-cost AI-generated content increased the supply of plausible-looking pages. Clear authorship and credible support now help distinguish accountable information from text that merely sounds confident.

    • Identify who wrote or reviewed the page and why that person is qualified to address the subject.
    • Link factual claims to the evidence that supports them, placing the citation beside the relevant claim.
    • Separate documented facts from your interpretation, recommendation, or forecast.
    • Disclose material limitations instead of hiding the conditions under which the advice stops working.
    • Show a meaningful update date when the page has actually been reviewed or changed.
    • Make the site’s ownership, editorial responsibility, and contact path easy to verify.

    Do not assume a trusted domain can safely publish unrelated third-party material. Google’s enforcement of its site-reputation-abuse policy specifically challenges the idea that content can inherit authority merely by being hosted on a strong domain. Topical fit and editorial accountability still have to be real.

    Treat brand mentions as external corroboration

    Brand mentions entered the standalone list at an estimated 2% in 2026. Relevant mentions in authoritative publications can help establish that a company is a recognized entity with a reputation, even when every mention does not carry a link. The same public evidence can also influence whether generative systems encounter and understand the brand.

    This is not permission to flood low-quality sites with a company name. Pursue coverage where the brand contributes something verifiable: data, expert analysis, a useful tool, a documented initiative, or a defensible point of view. Track linked and unlinked coverage separately, correct naming inconsistencies, and make sure the facts on your own site agree with the facts publishers can verify elsewhere.

    Keep technical SEO above the floor and use freshness for gains

    Mobile friendliness declined to 4%, page speed to 2%, and site security to 1%. Those drops do not mean the requirements stopped mattering. Compliance is now common enough to differentiate fewer competent sites, while falling below the expected standard can still hurt disproportionately.

    Think of technical health as the floor beneath the content strategy. Before polishing a title or commissioning outreach, verify that:

    • The important page can be crawled, rendered, indexed, and assigned the intended canonical URL.
    • The mobile version contains the primary content and actions rather than a reduced or obstructed experience.
    • Core templates load without unnecessary delay or disruptive layout movement.
    • HTTPS works consistently, with no broken redirects or insecure resources undermining the page.
    • Navigation and internal links expose the hub structure to users and crawlers.

    Once those conditions are stable, another marginal technical tweak may have less value than improving the answer or adding missing topical coverage. Fix genuine failures; do not keep rebuilding an already competent foundation because technical work is easier to measure than content quality.

    Refresh substance, not timestamps

    Freshness held at 6%, and pages updated within the preceding year continued to outrank comparable untouched pages in the tracked client data. The useful interpretation is not that every page needs an annual date change. A refresh should remove decay and restore usefulness.

    • Recheck claims, dates, product behavior, screenshots, citations, and outbound links.
    • Compare the page’s scope with the current search task and add newly important distinctions.
    • Replace obsolete examples rather than placing a new paragraph above them.
    • Review internal links in both directions so newer supporting pages strengthen the hub.
    • Update the visible date only when the review produced a meaningful change.

    Keep schema in its proper role

    Schema markup, header keywords, URL keywords, meta-description keywords, and 19 other signals sit inside a combined 1% group. The tracked results did not show measurable ranking movement from structured data itself, despite broad claims that schema is the key to inclusion in AI-generated answers.

    That does not make schema useless. Keep accurate structured data that describes the visible page and its entities, but do not mistake machine-readable labels for substantive authority. Schema cannot supply missing evidence, topical depth, trustworthy authorship, editorial links, or a satisfying answer. The correct sequence is to create the real information first and mark it up faithfully second.

    Use a page-level decision order instead of a flat checklist

    An isometric web page follows an ascending path through technical, relevance, evidence, and user-engagement stages.

    A flat audit encourages teams to fix whichever issue is easiest to count. A decision order forces you to address dependencies first. Run each important page through these gates:

    1. Can the page compete at all? Resolve crawling, indexing, canonical, mobile, security, and serious performance failures before making editorial refinements.
    2. Does it resolve one identifiable search task? If the purpose is vague, choose the intended query and reader decision before rewriting individual sections.
    3. Is it the strongest page on your site for that task? Merge overlapping URLs, redirect obsolete versions where appropriate, and stop internal competition.
    4. Does it belong to a coherent hub? Connect the page to broader and narrower resources, then identify genuinely missing industry, use-case, customer-type, or specialty coverage.
    5. Does the title set the right expectation? Make the subject and decisive qualifier clear without repeating keyword variants.
    6. Can the reader verify the important claims? Add accountable authorship, direct citations, transparent reasoning, limitations, and a meaningful update record.
    7. Is there a reason for outside recognition? Develop evidence or a reusable asset that can earn editorial links, diverse references, and credible brand mentions.
    8. Does visitor behavior expose an unresolved need? Look for title-content mismatch, buried answers, missing comparisons, weak next steps, and sections that do not help the intended decision.

    The order matters. Schema refinements will not rescue an inaccessible page. A faster template will not make a generic answer distinctive. Outreach will not create durable authority when the target page offers nothing worth citing.

    Start with your most commercially important hub. Map the search tasks it must cover, choose the page that most clearly fails its reader, and repair that page from the technical floor upward. Then fill one meaningful coverage gap and create one asset that deserves external recognition. That sequence turns ranking-factor theory into work your team can assign, review, and improve.

    References


  • How to Segment Multi-Location SEO Data for Real Insight

    How to Segment Multi-Location SEO Data for Real Insight

    Your network’s organic traffic is up, yet several location managers say calls or bookings are down. Both can be true. A few high-volume markets can lift the total, while new locations can add traffic and conversions simply because they were absent from the earlier comparison period.

    You need reporting that separates portfolio expansion from SEO improvement, shows whether a problem is local or widespread, and points to the next action. That requires a stable location data model, like-for-like cohorts, and several connected views rather than one network-wide dashboard.

    Start with the decision, not the dashboard

    Segmentation becomes useful when each view answers a specific question. If you begin by collecting every available metric, you will usually end up with a crowded report that describes movement without explaining it.

    Write down the decisions the report must support before building filters or charts. For a multi-location SEO program, the practical questions usually include:

    • Are established locations growing, or is total growth coming from newly opened locations?
    • Is a decline limited to one location, shared across a metro, or visible throughout the network?
    • Is the change specific to Organic Search, or are all website channels moving in the same direction?
    • Are people finding the business through its name, or discovering it through services, products, cities, neighborhoods, and local-intent searches?
    • Is search visibility weakening, or are users still finding the location but taking fewer actions afterward?
    • Which locations deserve intervention, and which high performers contain a practice worth applying elsewhere?

    Each question needs a different denominator. A regional executive may need the total contribution from every location. An SEO manager diagnosing page quality needs location-page traffic and conversions. An analyst judging ongoing performance needs only locations that existed in both comparison periods.

    Keep three kinds of network measure visible: the portfolio total, the typical location, and the distribution across locations. The total shows business impact. A median or peer-group benchmark shows whether the typical branch is improving. The distribution reveals whether the result is broad or concentrated in a few outliers. None can safely replace the others.

    Build a location spine before joining SEO metrics

    An isometric central spine connects storefront and map-pin modules while colored data streams join the matching locations.

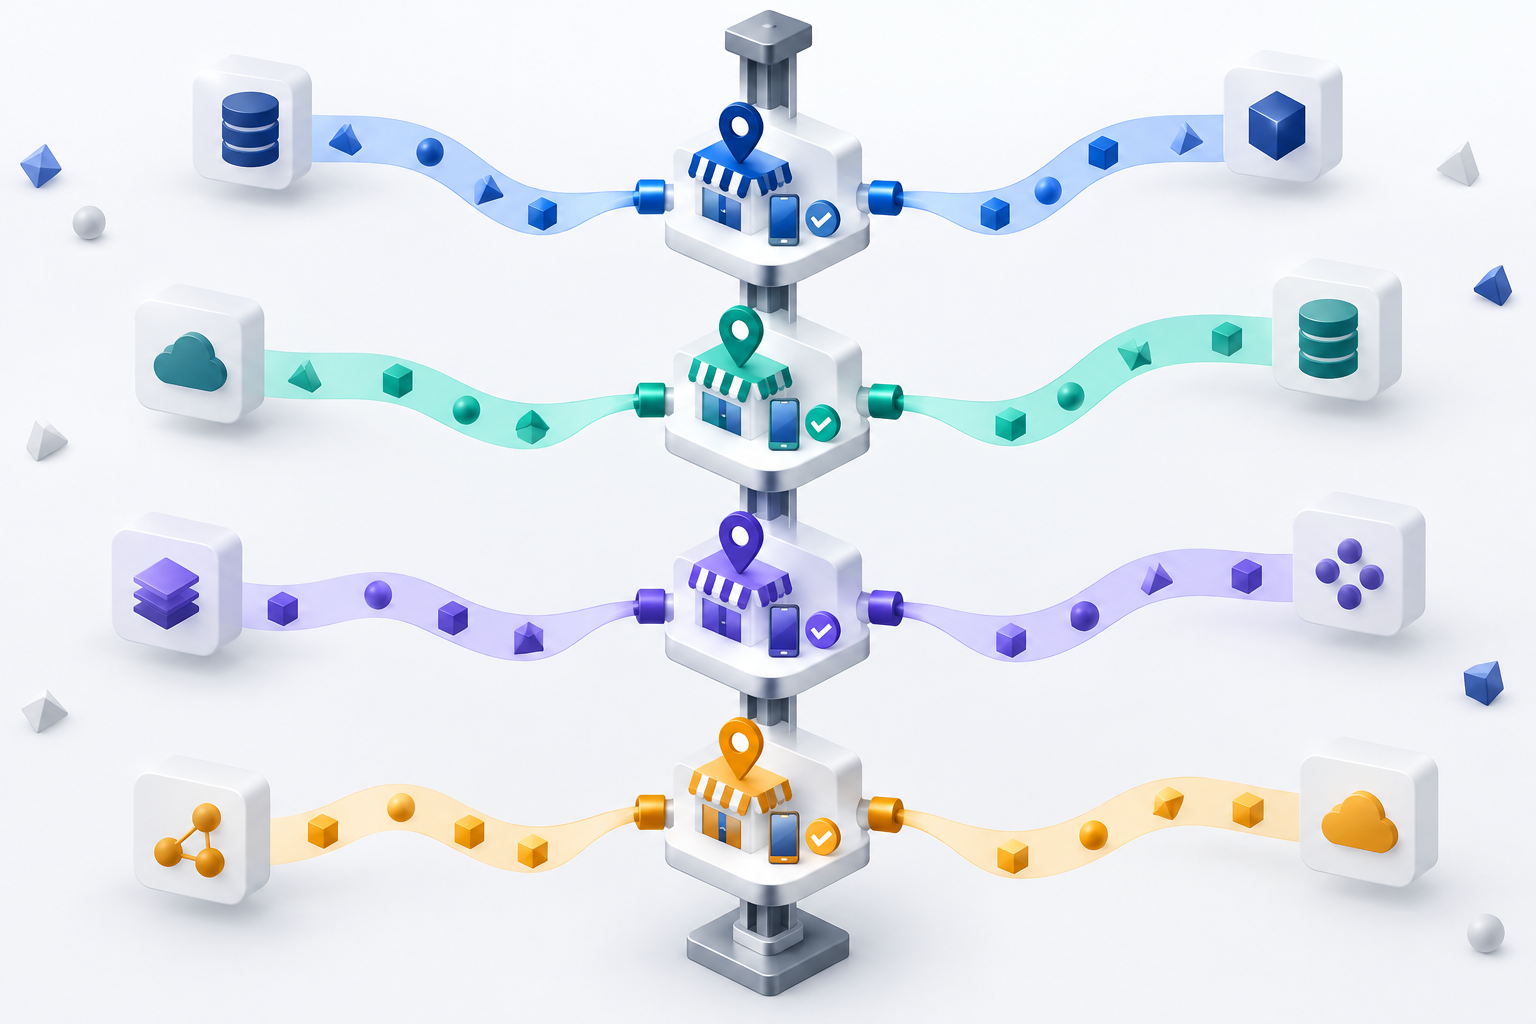
    Your reports need one durable record for every physical location. Think of this as the location spine: a controlled table that connects analytics, landing pages, search performance, local rankings, Google Business Profile data, reviews, and business events.

    Do not use a display name as the primary key. Names change, abbreviations vary, and two branches can share similar labels. Assign an immutable internal location key, then map every platform identifier and URL to it.

    FieldWhat it controlsWhy it matters
    Location keyThe permanent join key across systemsPrevents renames or URL changes from splitting one location into several records
    Operating statusOpen, temporarily unavailable, closed, relocated, or otherwise excludedKeeps inactive locations from being mistaken for SEO declines
    Lifecycle datesOpening, closing, relocation, and material expansion datesDetermines whether a location belongs in a like-for-like comparison
    Geographic hierarchyProvince or state, region, metro, city, and neighborhood where relevantSupports realistic market comparisons and isolates geographic patterns
    Location URL setCurrent page plus any mapped service or market pagesConnects page-level analytics and search visibility to the right branch
    Profile identifierThe associated Google Business Profile recordConnects Search and Maps visibility, actions, and review context
    Peer groupLocations with reasonably similar market conditions or operating modelsAvoids judging a small market against a major metro with different demand and competition
    Comparison cohortComparable, opening, closing, relocated, or exceptionSeparates organic improvement from changes in the location portfolio

    Decide how a relocation should be represented before the reporting period starts. If the business considers it the same branch but its page, profile, catchment area, or local competitors changed materially, preserve the permanent location key while flagging the affected periods as an exception. That retains operational history without pretending the local search environment remained constant.

    URL mapping needs the same discipline. A location may receive organic traffic through its main location page, a city page, or service pages associated with that market. Define which URLs belong to which reporting view. Do not silently attribute every site visit from a city to the nearest branch unless that allocation rule is explicit and defensible.

    If URL structure permits a simple landing-page filter, use it. If it requires regular expressions, test the expression against known included and excluded URLs before interpreting the results. Then compare the filtered inventory with the location spine. A broken filter can create a persuasive but false outlier, especially after a migration or naming change.

    Read every location through four evidence layers

    A storefront is surrounded by four translucent layers of discovery, engagement, conversion, and neighborhood-context symbols.

    No single metric explains local SEO performance. Treat analytics, search visibility, local rankings, and profile activity as connected evidence layers. When they disagree, the disagreement is diagnostic information rather than a reason to choose the most flattering metric.

    Evidence layerUseful measuresQuestion it answersCommon misreading
    Website analyticsOrganic traffic, engagement, conversion events, and corresponding all-channel measuresWhat did visitors do after reaching the site?Treating a tracking or sitewide conversion change as an organic-search problem
    Search visibilityClicks, impressions, click-through rate, average position, landing pages, and queriesHow often did the location appear, and what searches produced exposure or visits?Reading a network average without separating locations or query intent
    Local rank trackingCity-, service-, ZIP-code-, and near-me visibility, including grid or radius viewsWhere can a searcher actually see the location for priority local intent?Using one point ranking as though every searcher in the market sees the same result
    Google Business Profile and reviewsSearch and Maps views, website clicks, calls, directions, review volume, recency, and ratingWhat happened directly in local results, and what may affect user response?Assuming every profile action carries the same business value

    Website behavior: compare organic with the whole site

    Use GA4, Adobe, or the analytics platform already trusted by the business to review location-page traffic, engagement, and conversion events. Define a conversion in operational terms. Depending on the business, that may be an appointment request, booking, submitted form, phone call, or another recorded action.

    Always place the Organic Search view beside the equivalent all-channel view. If conversion activity falls across every channel, investigate tracking, page behavior, availability, or a broader business change before blaming rankings. If the decline appears only in organic traffic, continue into search visibility and query data.

    Do not average location conversion rates to create a network rate. Add the relevant conversion counts, add the corresponding traffic totals, and calculate the rate from those combined values. A simple average gives a small branch the same influence as a high-volume location and can distort the network result.

    Search visibility: split discovery from existing demand

    Use Google Search Console and Bing Webmaster Tools to examine clicks, impressions, click-through rate, average position, pages, and queries by location. Compare month over month for recent movement and year over year where the business needs a seasonal comparison.

    Classify queries with documented rules. At minimum, separate branded searches from non-branded discovery. The branded group should include the approved business and brand terms relevant to the network. The non-branded group can then be divided into service or product intent, explicit city or neighborhood terms, and near-me intent where the available query data supports that classification.

    This distinction changes the diagnosis. Rising branded clicks can reflect stronger existing awareness without proving that a location has become easier to discover for its services. Improving non-branded visibility is a clearer sign that the location is reaching people who have not already decided which business to find.

    Keep query taxonomy rules stable between periods. If you add brand terms or change classification logic, mark that change in the report. Otherwise, a reporting edit can look like a shift in customer behavior.

    Where a webmaster platform exposes AI-search performance, keep it as a clearly labeled view with its own available measures. Do not blend unlike visibility or traffic fields into a conventional web-search total. The label should tell the reader what the platform actually measured.

    Local rankings: measure the searcher’s geography

    Track priority local-intent searches at the city or ZIP-code level. In competitive markets, use grid or radius reporting to see how visibility changes as the searcher’s position changes. A branch may be prominent near its address and nearly absent elsewhere in the same metro; one rank captured from one point cannot represent that pattern.

    When visibility moves, inspect more than the recorded rank. Check whether the results page layout changed, whether a new search feature appeared, and whether new competitors entered the result set. A lower click-through rate with stable rankings may begin to make sense once you see that the page surrounding the listing has changed.

    Profile actions and reviews: interpret them by business model

    Google Business Profile activity covers visibility and actions that can occur before a user reaches the website. Review Search and Maps views alongside website clicks, calls, and direction requests. Calls may be more meaningful for a service business, while directions may better reflect intent for an in-person location. Choose the primary action based on how that business actually converts demand.

    Place review volume, recency, and average rating beside profile performance. These measures do not prove why a user acted, but they can explain why locations with similar visibility receive different engagement. Treat them as context to investigate, not as automatic causation.

    Separate portfolio growth from comparable-location growth

    A clean year-over-year report needs more than a date comparison. It needs a population definition. If the network opened, closed, relocated, or expanded locations, the locations contributing to the current period may not match those in the prior period.

    Publish separate views instead of forcing every branch into one percentage:

    • All-network view: every valid location in each period. Use this to show the total portfolio outcome.
    • Comparable-location view: only locations with a stable identity and valid data in both periods. Use this to judge underlying performance.
    • Opening cohort: locations that began operating after the earlier period. Use this to show incremental contribution without calling it like-for-like growth.
    • Closing cohort: locations that ceased operating or left the portfolio. Use this to explain lost contribution.
    • Exception cohort: relocations, material expansions, URL migrations, tracking interruptions, or other changes that make a direct comparison misleading.

    The all-network view answers, “How much organic activity did the business receive?” The comparable view answers, “Did the established footprint improve?” Those are both legitimate questions, but they are not interchangeable.

    Calculate comparable change from the same location keys in both periods. For an additive measure such as clicks or conversions, sum the current values for the matched cohort and compare them with the prior values for that exact cohort. For a rate such as click-through rate, combine the cohort’s numerators and denominators first, then calculate the rate. Do not average the individual location percentages.

    Also show each location’s contribution to the network change. A portfolio gain can be concentrated in a few branches even when most locations are flat or declining. Conversely, one closure or market-specific loss can pull down an otherwise healthy comparable cohort. Geographic and lifecycle segmentation exposes those drivers before they become a misleading network narrative.

    Apply cohort rules consistently across traffic, visibility, profile actions, and conversions. If the analytics table excludes openings but the profile table includes them, the dashboard will invite comparisons between different populations. Put the cohort definition and any exceptions directly in the report so a stakeholder can see what the result represents.

    Turn outliers into a prioritized SEO work queue

    A location is not an outlier merely because it trails the network average. Market demand, competition, maturity, and the number of nearby branches all affect the opportunity. Compare locations within relevant geographic and operating peer groups first: region, metro, city, or another grouping that reflects the business.

    This matters most when a network spans very different markets. A small city should not inherit the traffic target of a major metro. A dense metro with several branches may also have an internal differentiation problem: location pages can compete for the same broad city terms when neighborhood language would better distinguish their service areas.

    Use the pattern across evidence layers to choose the first investigation:

    Observed patternWhat to inspect nextPotential action
    Impressions and local rankings fall in one marketPriority queries, Map Pack visibility, new competitors, demand, page coverage, and profile accuracyCorrect listing data, strengthen the relevant location page, or build justified market-level coverage
    Impressions hold while clicks and click-through rate fallActual result pages, layout changes, new features, competing listings, and how the page or profile is presentedImprove the search-facing information that is within your control and monitor the changed result environment
    Organic traffic holds while conversions declineEngagement, conversion tracking, landing-page behavior, and all-channel conversion trendsRepair measurement or address the page-level conversion issue before treating it as a visibility problem
    Profile views hold while calls, clicks, or directions declineProfile completeness, business information, reviews, and whether the selected action still reflects customer behaviorUpdate the profile, address review weaknesses, or revise the primary action used for evaluation
    Several branches in one metro weaken while the wider region is stableShared competitors, overlapping pages, local rankings, neighborhood differentiation, and market conditionsUse a metro-level plan rather than repeating isolated page edits at every branch
    Every channel declines for the same locationTracking, operating status, availability, page function, and broader market or business changesResolve the cross-channel cause before assigning an organic SEO fix
    One peer location substantially outperforms comparable branchesQuery mix, page completeness, profile quality, review context, competition, and local involvementIdentify a transferable practice, then validate it in another appropriate peer market

    These patterns are starting points, not verdicts. Stable impressions with falling clicks, for example, can indicate a result-page change, weaker presentation, or a different query mix. Open the location, page, and query views before selecting the remedy.

    Every item in the work queue should contain the affected location or cohort, the observed evidence, the working explanation, the next check or change, an owner, and a review point. Keep observation and hypothesis in separate fields. “Non-branded impressions declined” is an observation. “A new competitor displaced the location” remains a hypothesis until the result and competitor data support it.

    Prioritize with three considerations: potential business impact, confidence in the diagnosis, and whether the team can act on it. A high-volume location with a clear profile error may deserve attention before a larger but poorly understood fluctuation. A strong outlier can be just as valuable as a weak one if it reveals a repeatable page, profile, or market practice.

    Key takeaways

    • Use a permanent location key to connect pages, analytics, search visibility, rankings, profiles, reviews, and lifecycle events.
    • Report the all-network portfolio and the comparable-location cohort separately; they answer different business questions.
    • Compare Organic Search with all-channel performance before assigning an organic cause to a conversion decline.
    • Split branded demand from non-branded discovery, and keep the classification rules consistent between periods.
    • Benchmark locations against relevant peers, then use cross-layer patterns to decide what to inspect and change.

    Start by creating the location spine and three saved views: all-network, comparable locations, and lifecycle exceptions. Then select one underperforming market and trace it from query visibility through page behavior and profile actions. Your reporting has done its job when that trail produces a specific, owned action rather than another network average.

    References


  • SEO for AI-Mediated Search: A Practical Visibility Plan

    SEO for AI-Mediated Search: A Practical Visibility Plan

    Your rankings can look healthy while your brand is missing from the answer a customer actually sees. Or an AI system can mention you, describe you incorrectly, and send no visit that your analytics can attribute. If you still judge organic performance only by positions and clicks, those failures stay hidden.

    The practical response is not to abandon SEO for a new acronym. It is to extend your existing search system so that machines can retrieve your pages, understand your entities, quote your claims, represent your brand accurately, and give an interested person a clear route to act.

    Run SEO and AI visibility as separate, connected scorecards

    Traditional rankings tell you whether a URL can compete in a search results page. They do not tell you whether ChatGPT, Gemini, Google AI Mode, or another generated-answer experience mentions your brand, cites your site, or repeats the right facts. AI visibility therefore needs its own measurements.

    This distinction matters because an answer interface can satisfy part of a search without passing the user to a website. In a March 2026 randomized field experiment involving 1,100 U.S. Chrome users, forcing nearly 95% of searches through Google AI Mode reduced the share that led to an external website by 18.8 percentage points. Participants also reported lower satisfaction, usefulness, control, personalization, and trust than people using Google normally.

    Do not turn that number into a universal traffic forecast. The treatment lasted seven days, the sample skewed younger, highly educated, and politically left-leaning, and participants were pushed into AI Mode rather than choosing it. The sound conclusion is narrower: AI-mediated discovery can materially reduce referral opportunities, and fewer clicks do not necessarily mean the answer experience served the user better.

    Build your reporting around three connected outcomes:

    • Retrieval: Can search engines and answer systems find the right page for the question? Track crawlability, indexation, rankings, relevant internal links, and whether the page appears as a cited or consulted resource.
    • Representation: Does the generated answer name the correct entity, describe it accurately, preserve important qualifications, and link to the appropriate URL? A positive-sounding mention is still a failure if it assigns the wrong feature, location, price, audience, or availability.
    • Response: What happens after exposure? Track referral visits where they are available, branded demand, assisted conversions, leads, sales, bookings, subscriptions, or the business action appropriate to the page.

    Keep these columns separate. A mention is not a citation. A citation is not a visit. A visit is not a conversion. Combining them into one visibility score hides the exact problem you need to fix.

    Turn keyword research into a prompt-and-decision map

    An overhead worktable displays blank cards, colored markers, branching threads, and comparison objects arranged from broad research to final choices.

    Keywords still reveal language, demand, and the pages competing for attention. Prompts reveal something different: the decision a person is trying to make, the conditions attached to it, and the comparison set an AI system may assemble before answering.

    A query such as “project management software” names a category. A prompt such as “Which project management platform suits a distributed agency that needs client approvals but has no dedicated administrator?” also supplies an audience, operating constraint, required capability, and evaluation criterion. A generic category page may rank for the first expression and still be unusable for the second.

    Create a prompt map for each product, service, location, person, or topic that matters commercially:

    1. Choose the entity. Start with one thing you need an answer engine to understand unambiguously: a product, service, organization, location, event, or expert.
    2. List the decisions surrounding it. Include discovery, comparison, validation, objection handling, and action. These are different information needs and may require different pages.
    3. Add real constraints. Capture the audience, use case, location, compatibility requirement, budget condition, risk, or desired outcome that changes the answer.
    4. Assign a canonical destination. Decide which page should answer each prompt family. If several URLs compete to make the same claim, consolidate the information or define a clear primary page.
    5. Record the proof required. Specifications, policies, examples, qualifications, prices, availability, authorship, and dates should sit close to the claims they support.
    6. Define the next action. A person who wants more than the generated answer should land on a page that continues the same task rather than restarting the journey.
    Decision momentPrompt patternJob of the destination pageUseful visibility signal
    DiscoverWhat approaches solve this problem for this audience?Explain the category, tradeoffs, and situations in which each approach fits.Your entity appears in the correct category and context.
    CompareWhich option fits these requirements or constraints?Make differentiators, exclusions, and supporting evidence easy to verify.The comparison includes you and states the right distinctions.
    ValidateDoes this option support a particular requirement?Provide an explicit answer, scope, conditions, and authoritative details.The answer uses the correct fact and cites its canonical page.
    ActWhere can I buy, book, apply, contact, or begin?Present current availability and a direct next step.The answer sends the user to the correct action page.

    For every tracked prompt, save the exact wording, platform, language, market or location, intended destination, expected facts, observed competitors, and business stage. This prevents a common reporting error: treating two prompts as equivalent even though one asks for information and the other asks for a recommendation.

    Your tooling should preserve this prompt-level detail. Rank Math AI, for example, tracks brand appearances in ChatGPT and Gemini separately from traditional rankings, with daily, weekly, or monthly monitoring in more than 30 languages. If you use a different platform or an internal process, require the same basic separation. The tool is instrumentation; your prompt set and evaluation criteria are the strategy.

    Make important pages easy to quote and hard to misread

    An answer engine should not have to assemble your central claim from an opening anecdote, a feature grid, a footnote, and a support page. Put the answer where a person can find it quickly, then place the evidence and limitations beside it.

    Use this structure on pages mapped to consequential prompts:

    • Direct answer: State the conclusion in plain language near the relevant heading. Answer the question before expanding it.
    • Named entity: Identify exactly which product, service, organization, location, event, version, or plan the statement concerns. Pronouns and vague category labels create avoidable ambiguity.
    • Qualifications: State who the answer applies to, where it applies, and which conditions or exclusions can change it.
    • Supporting evidence: Put specifications, policies, examples, definitions, and source links close to the claims they substantiate.
    • Freshness signal: Show a meaningful updated date when the information can change, and remove stale claims rather than leaving conflicting versions around the site.
    • Next step: Link to the comparison, documentation, product, booking, contact, or transaction page that continues the reader’s task.

    This is not permission to flatten every page into short answers. A concise answer earns comprehension; depth earns confidence. The page still needs the reasoning, evidence, alternatives, and boundaries a serious reader requires.

    Use structured data to corroborate visible facts

    JSON-LD should describe the same reality a visitor can see. It does not repair weak content, create an entity by itself, or make a stale offer current. Its useful role is to make entities, attributes, and relationships explicit without forcing a machine to infer them from presentation alone.

    Select the type that matches the actual entity. A product page may support Product markup; a property page may call for Hotel; an event page may use Event; and an important visual may be represented with ImageObject. Then verify that names, URLs, images, locations, dates, attributes, prices, and offers agree with the visible page and any current feed, inventory, booking, or location data.

    Audit these relationships as a system:

    • The entity has one preferred name and a stable canonical URL.
    • Alternate names do not accidentally create what looks like a second entity.
    • The structured description does not make claims absent from the page.
    • Offer, availability, date, location, and attribute data match operational systems.
    • Images and videos point to the entity and variant they actually depict.
    • Third-party profiles and distribution feeds do not contradict the first-party record.

    More markup is not the goal. Fewer unresolved contradictions is the goal.

    Use internal links to define the evidence path

    Internal links help a crawler discover URLs, but their strategic value goes further. They show how an overview, a detailed claim, its supporting documentation, and the action page relate to one another.

    Run a crawl and fix the basics first: broken destinations, redirect chains, and important pages with no contextual internal links. Then connect each canonical page in both directions. A category overview should point to the relevant detail page; the detail page should connect back to its parent and onward to proof or action. Use anchor text that names the relationship instead of repeating “learn more” throughout the site.

    Do not add links to every possible page. A dense but indiscriminate link graph blurs hierarchy. Link when the destination answers the next reasonable question, verifies the current claim, distinguishes a related entity, or enables the next action.

    Treat images and video as evidence, not decoration

    A tabletop studio photographs a generic mechanical component alongside close-up tools, material samples, and separated parts that reveal its construction.

    Visual optimization is no longer limited to image rankings or faster page loads. AI systems can interpret objects, attributes, surroundings, and relationships within a scene, then connect those observations to a product, place, business, or other entity. Google reports that Lens supports more than 25 billion visual searches per month, with one in five showing commercial intent.

    The important unit is therefore not the image alone. It is the relationship among the asset, the entity it depicts, the page around it, the metadata describing it, and the operational data that keeps the claim current.

    For every decision-relevant image or video:

    • Show useful attributes clearly. Original imagery should reveal the color, material, configuration, room type, amenity, dish, location, feature, or experience that affects a customer’s decision.
    • Identify the correct entity. A product image must connect to the right product and offer. A hotel image must connect to the correct property, room type, amenity, and location.
    • Write literal metadata. Use a descriptive filename, accurate alt text, and a caption when the caption adds context. Do not stuff the target phrase into descriptions of things the asset does not show.
    • Add explanatory surroundings. The heading, nearby copy, and page purpose should reinforce what the asset depicts and why it matters.
    • Make video language accessible. Supply a transcript and useful metadata so the information is available without requiring a system to infer everything from frames and audio.
    • Connect structured data. Associate the visual with the same entity, attributes, and canonical URL described on the page.
    • Keep distribution consistent. Website pages, profiles, publishers, booking platforms, product feeds, and social channels should not attach contradictory names or attributes to the same visual.

    Consider a hypothetical hotel image labeled as a rooftop pool on the property page while a booking feed assigns it to a different room category and a third-party profile calls the pool indoor. A person sees an appealing photograph; a machine sees competing entity relationships. Rewriting the alt text will not resolve that conflict. The property record, amenity data, page copy, structured data, and distribution feeds must agree.

    An asset register makes this manageable at scale. For each important visual, record its URL, depicted entity, visible attributes, canonical page, relevant structured-data type, associated feed or listing, usage rights, and last verification date. That turns visual SEO from a tagging task into a maintainable information system.

    Measure what the answer changed, then fix the weakest link

    Generated answers are observations at a point in time, not permanent rankings. Save enough context to reproduce each check: exact prompt, platform, language, location when relevant, date, answer text, cited URLs, brand description, competitors included, and the intended destination page.

    Use separate rates instead of one opaque score:

    • Mention coverage: tracked prompts in which your entity appears, divided by prompts tested.
    • First-party citation rate: answers citing your site, divided by answers in which your entity appears.
    • Representation accuracy: audited brand claims that are correct and properly qualified, divided by brand claims checked.
    • Destination accuracy: citations that lead to the canonical page for the task, divided by first-party citations observed.
    • Response value: attributable visits, engaged sessions, assisted outcomes, and completed business actions associated with AI discovery.

    Choose a monitoring cadence based on how quickly the underlying information and competitive answer set can change. A fast-moving offer or event warrants closer observation than an evergreen definition. Whatever cadence you choose, compare like with like; changing the prompt wording, language, geography, and platform at once makes the result impossible to diagnose.

    When performance changes, work through the failure in order:

    1. Not retrieved: Check indexation, crawl access, canonicalization, internal links, page relevance, and whether the necessary information exists in accessible text.
    2. Retrieved but absent from the answer: Tighten the direct answer, make the entity explicit, add the missing qualification or proof, and remove competing pages that make the canonical source unclear.
    3. Mentioned inaccurately: Locate contradictions across visible copy, JSON-LD, feeds, profiles, media metadata, and older pages. Correct the underlying record before adding more content.
    4. Mentioned but not cited: Strengthen the first-party page as the clearest source for the claim. Put evidence and the canonical fact together rather than distributing them across weak fragments.
    5. Cited but not visited: Determine whether the answer already completed the task. If a click is still useful, make the linked page promise a clear next layer: a tool, full comparison, current inventory, detailed method, documentation, or transaction.
    6. Visited but not converted: Treat this as a landing-page and journey problem. Ensure the page fulfills the prompt’s intent and makes the appropriate next action obvious.

    Do not judge an optimization by mention growth alone. A larger number of inaccurate mentions can damage understanding, while a smaller number of well-qualified citations on high-intent prompts may be more useful. Read representative answers, not just dashboard totals.

    Key takeaways

    • Keep classic rankings, AI mentions, citations, representation accuracy, visits, and conversions as distinct metrics.
    • Map prompts to customer decisions, constraints, expected facts, canonical pages, and next actions.
    • Place direct answers, qualifications, proof, and freshness signals together on the page that owns the claim.
    • Use JSON-LD, internal links, feeds, profiles, and visual metadata to reinforce one consistent entity record.
    • Diagnose the stage that failed before changing content: retrieval, inclusion, accuracy, citation, visit, or conversion.

    Start with one commercially important entity and the prompt family closest to a real decision. Record a baseline in the answer systems your audience uses, audit the canonical page and its supporting signals, correct the largest contradiction, and run the same prompts again. That small loop will teach you more than a sitewide program built around an undefined AI visibility score.

    References


  • People-First Content for AI Search: A Practical Framework

    People-First Content for AI Search: A Practical Framework

    You need content that can appear in AI-generated answers without turning your site into a warehouse of robotic definitions. The difficult part is not choosing between people and machines. It is making the useful answer obvious to a machine while preserving the context, judgment, and next step that make a person trust it.

    The right standard is simple: a reader should be able to make a better decision after visiting the page, even if no search engine existed. AI optimization then becomes a matter of structure, clarity, and accurate representation – not a separate style of writing.

    Start with the reader’s decision, not a target phrase

    A keyword can tell you what someone typed. It does not tell you what they need to decide, what they already understand, or what would make the answer usable. If your brief stops at a phrase such as people-first content, AI SEO, or conversational search optimization, the draft will usually become a broad explanation with no practical destination.

    Write a reader-task sentence before you outline the page:

    After reading this page, a specific reader should be able to make a specific decision or complete a specific task without making a predictable mistake.

    For this topic, that sentence might be: After reading, a content lead should be able to revise an AI-assisted draft so it answers the searcher’s question clearly, retains expert judgment, and can be quoted without losing an important qualification.

    That sentence gives you an editorial boundary. A paragraph belongs only if it helps the reader reach the stated outcome. Background that does not change a decision can be shortened, linked elsewhere, or removed.

    Build the brief around the reader’s unresolved questions

    A useful brief should answer these points before drafting begins:

    • Reader: Who is acting on this information? Name a role or situation, not a demographic label.
    • Immediate question: What do they need answered before they can continue?
    • Decision: What choice will the answer help them make?
    • Constraint: What condition could change the recommendation?
    • Failure mode: What plausible but wrong interpretation should the page prevent?
    • Next action: What should the reader inspect, change, compare, or document after reading?

    This framing also prevents keyword coverage from becoming topic sprawl. You do not need a paragraph for every variation of a query. Group variations by the decision behind them, answer that decision once, and use the language a reader would naturally recognize.

    The enduring core of search copywriting is still clear content written for people. AI can assist with analysis, brainstorming, and feedback, but the writer still supplies the voice, brand knowledge, and connection to the reader. Treating those contributions as optional is how efficient production turns into interchangeable content.

    Build answer units that remain useful outside the page

    Modular information tiles move from a central page into several different digital interface frames while retaining their complete visual structure.

    People normally read with context: they see the title, scan nearby headings, and understand how one paragraph relates to the next. An AI search product may retrieve or quote a smaller passage. If the definition is in one section, the qualification is much later, and the recommended action appears somewhere else, the extracted answer can be incomplete even when the full page is accurate.

    The practical response is to write in self-contained, citable chunks. This does not mean reducing the page to disconnected snippets. It means giving each section a complete local purpose while arranging those sections into a coherent journey.

    Use a repeatable anatomy for important sections

    For every question the page must resolve, use this sequence:

    1. Name the question in the heading. A heading such as When human review is required carries more meaning than Considerations or Best practices.
    2. Give the direct answer immediately. Do not make the reader cross an origin story, trend summary, or sales preamble to find your position.
    3. State the boundary. Explain when the answer applies, when it does not, and which missing fact could change it.
    4. Support the answer. Add an example, process detail, definition, documented fact, or clearly attributed observation.
    5. Close with an action. Tell the reader what to inspect or do with the answer.

    Consider a section answering whether an AI-generated draft can be published without review. A vague version says that the choice depends on business needs and that quality is important. A useful version says that an AI draft should be treated as unverified input; a qualified reviewer must check factual claims, scope, examples, links, and promises before publication. It then distinguishes a wording edit from a claim that requires subject-matter validation and gives the editor a review checklist.

    The second version works better for both audiences. A person can act on it. An answer system can quote it without having to infer what quality means.

    Keep the qualification beside the claim

    A claim and its limiting condition belong in the same passage. Do not write AI-generated content is safe to publish in one paragraph and place only after expert review several screens later. The first sentence is not merely incomplete; it can become false when separated from the later condition.

    Use nouns when a pronoun could become ambiguous outside the section. Replace This improves it with Descriptive headings make the answer easier to scan and retrieve. Define specialist terms where they first affect the decision. Repeat an essential qualifier when necessary; elegant variation matters less than accurate extraction.

    Lists should also carry meaning in isolation. Each item needs a parallel structure and enough context to remain understandable when quoted. A list containing Accuracy, Voice, and Check it is not a usable framework. Factual verification, brand-voice review, and final human approval are distinct, actionable checks.

    Do not mistake an FAQ farm for answer engineering

    Breaking every keyword variation into a separate question creates repetition and weakens the reading experience. Put foundational questions in the main narrative where the answer changes what comes next. Reserve an FAQ for genuine follow-up questions that can be answered independently and do not deserve full sections.

    No heading pattern guarantees that ChatGPT, Perplexity, an AI Overview, or another answer system will cite a page. The controllable goal is narrower: make the passage accurate, self-contained, easy to interpret, and worth selecting. That is useful even when the reader arrives through a conventional result, a shared link, or an internal knowledge base.

    Put human judgment where it changes the answer

    People-first does not mean conversational filler, personal anecdotes added for texture, or repeatedly saying you understand the reader. It means using knowledge of the reader to improve the substance of the answer.

    The human contribution is most valuable at decision points. That is where a competent writer or subject-matter expert can distinguish similar options, notice a dangerous assumption, explain a tradeoff, or say that the available evidence does not support a confident conclusion.

    Look for these forms of human value during editing:

    • Judgment: State which option you recommend and identify the criteria behind that recommendation.
    • Boundaries: Name the situation in which the usual answer stops applying.
    • Operational detail: Show what the work involves, who needs to review it, and what must be true before the next step.
    • Original evidence: Use relevant analytics, customer questions, interviews, product documentation, or internal observations only when you genuinely have them and are authorized to publish them.
    • Reader context: Explain how the answer changes for the role or situation addressed by the page.
    • Accountability: Separate verified facts from editorial recommendations and make ownership of the final claim clear.

    A useful test is to remove your company name from the draft and ask whether any competent competitor could publish it unchanged. If the answer is yes, the page probably contains category knowledge but little distinct judgment. Add what your qualified team can responsibly contribute: a decision rule, a better explanation of the tradeoff, a real workflow, or an evidence-backed correction to a common misunderstanding.

    Do not manufacture distinctiveness. Invented customer stories, fabricated tests, unnamed experts, and synthetic quotations make a page look specific while making it less trustworthy. If you lack original evidence, say what is known, label your recommendation as a recommendation, and narrow the claim to what you can support.

    Separate fact, interpretation, and recommendation

    Many weak pages blur these categories. A descriptive fact becomes a rule, an internal preference becomes an industry standard, or a plausible explanation becomes a proven cause. Mark the difference in the language itself:

    • Fact: State what can be checked and link the words that carry the claim to supporting material.
    • Interpretation: Explain what the fact may mean and preserve any uncertainty.
    • Recommendation: Say what you advise the reader to do and identify the criterion behind that advice.

    This separation improves more than credibility. It gives an answer system fewer opportunities to present your opinion as a settled fact or strip a recommendation from the condition that justifies it.

    Use AI for leverage, then run a human-led audit

    An editor reviews content cards at a desk using a magnifying glass, balance scale, compass, and human figure as visual quality checks.

    AI is well suited to expanding the editor’s field of view. It can organize questions, compare wording, identify repetition, test whether a passage depends on missing context, and point to claims that need verification. It should not be asked to supply experience, evidence, or authority that your organization does not possess.

    A disciplined workflow keeps that boundary visible:

    1. Write the human brief. Define the reader, decision, constraint, failure mode, and intended next action before generating prose.
    2. Assemble approved material. Gather the facts, product details, internal expertise, links, and examples the page is allowed to use.
    3. Use AI to map the problem. Ask it to group reader questions by underlying intent, expose overlaps, and identify missing objections. Treat the output as suggestions, not demand data.
    4. Create the answer structure. Give each major decision a descriptive heading and plan the direct answer, condition, support, and action beneath it.
    5. Draft with ownership. A writer may use AI to explore phrasing or alternatives, but a responsible human chooses the claim, preserves the brand’s meaning, and rejects unsupported additions.
    6. Audit every claim. Mark each substantive statement as verified fact, established background, interpretation, or recommendation. Investigate anything that does not fit.
    7. Approve the final page. The person signing off should be qualified to judge both factual accuracy and whether the advice is appropriate for the intended reader.

    Useful AI review requests are narrow. Ask it to list factual statements that lack visible support, identify pronouns with unclear antecedents, find conclusions that appear before their necessary conditions, or show where two sections answer the same question. Tell it not to rewrite while it diagnoses. You want an inspection report before you accept new prose.

    Be especially cautious when the model makes the copy smoother by removing qualifications. Words such as may, generally, only when, and for this audience can carry the factual boundary of the claim. Concision is not an improvement if it changes what the sentence promises.

    Run a people pass

    Read the page as someone trying to act, not as the person who commissioned it. Check whether:

    • The opening identifies the reader’s real problem and offers a useful direction without a long preamble.
    • Each major question receives a direct answer before supporting detail.
    • The recommendation names the condition under which it applies.
    • Examples clarify the decision instead of merely decorating the prose.
    • Technical terms are explained when understanding them affects the action.
    • The reader can tell which statements are facts and which are your editorial judgment.
    • The close gives the reader a realistic next move.

    Run an extraction pass

    Then inspect each important section as if it had been removed from the rest of the page. Check whether:

    • The heading names the question or decision accurately.
    • The opening sentence answers that heading rather than introducing the general topic again.
    • Essential subjects are named instead of hidden behind vague pronouns.
    • Definitions, limitations, and version or audience constraints sit beside the claims they govern.
    • List items remain meaningful when read without the preceding paragraph.
    • Link text describes the supported claim instead of saying click here or learn more.
    • A quoted passage would represent your actual position without requiring a distant correction.

    Check the publishing layer without expecting it to rescue the copy

    The title, visible headings, metadata, internal links, and structured data should describe the same subject and purpose. If you use schema, its claims must match content a visitor can actually see. Markup can clarify the meaning of a sound page; it cannot supply missing expertise, fix an evasive answer, or make an unsupported claim reliable.

    After publication, keep a small query log for the decisions that matter to your business. Record the question tested, the search or answer surface, the page surfaced or cited, the wording represented, and the action you want a qualified visitor to take. Use that record to find content gaps and misrepresentation. Do not treat a citation by itself as proof that the page served the reader or the business.

    Key takeaways

    • Define the reader’s decision before selecting headings or generating copy.
    • Give each important section a direct answer, its limiting condition, meaningful support, and a next action.
    • Keep qualifications beside the claims they govern so an extracted passage remains accurate.
    • Add human value through judgment, boundaries, operational detail, and genuine evidence – never invented experience.
    • Use AI to organize, question, and inspect the work while a qualified human owns every published claim.
    • Audit the page twice: once for the person completing a task and once for the system that may retrieve a passage.

    Start with one page that influences a real decision. Rewrite its opening around the reader’s task, turn its major sections into complete answer units, and challenge every unsupported sentence. When the page becomes easier for a person to trust and use, you have also created a stronger candidate for accurate representation in AI search.

    References


  • Title Tag SEO: A Practical Guide to Relevance and Clicks

    Title Tag SEO: A Practical Guide to Relevance and Clicks

    Your page can hold its position in search and still become easier to ignore. The usual problem is not a missing keyword. It is a title tag that names the topic without showing why this result is the right one for the searcher.

    A strong title tag makes relevance obvious, sets an accurate expectation, and gives the listing a reason to be chosen. Here is how to write one, evaluate it in context, and diagnose it when rankings and clicks tell different stories.

    Make relevance unmistakable before you try to be clever

    The title tag is the HTML <title> element that summarizes a page. Google may use it as the clickable title link in search results, but that wording is not guaranteed to appear unchanged. It is also different from the H1: the title tag describes the page in search and other external contexts, while the H1 introduces the content on the page itself.

    Before writing the title, answer three questions:

    • What phrase or entity would the intended searcher recognize immediately?
    • What specific task, answer, product, or outcome does the page provide?
    • What truthful detail distinguishes this page from neighboring results?

    A dependable working structure is: recognizable topic + specific value + useful qualifier. That might produce Title Tag SEO: A Practical Writing Guide, Invoice Approval Software for Small Teams, or Family Red T-Shirts: XS-XXL Under $25. The structure is not a template you must fill mechanically. It is a check that each word has a job.

    Include the keyword phrase or entity you want the page associated with, using the language your audience actually uses. Exact wording can be especially helpful when someone is new to a subject and does not know its synonyms, product nicknames, or category jargon. Search systems may understand related entities, but that does not remove the need for clear user-facing terminology.

    Consider meal replacement shakes and mass gainers. The products may overlap, but the phrases imply different needs. A page can be technically relevant to both while its title speaks convincingly to neither. Choose the primary audience for that page, use that audience’s term in the title, and handle secondary language naturally in the body.

    Do not treat the keyword as a guarantee of ranking. Its more immediate value is recognition: the searcher should not have to infer whether the page addresses the query. We would usually place the subject near the beginning when it reads naturally, not because the first position is a magic signal, but because the page should identify itself before secondary wording consumes the visible space.

    This clarity also matters beyond the conventional results page. AI systems can use search results to ground answers and select material to recommend. A title tag is not a command that makes an AI system cite you, but weakening organic discoverability can also reduce your opportunity to be found through AI-assisted search.

    Keep the important meaning inside the visible title

    Essential page and search symbols remain visible inside a title-shaped frame while decorative shapes are cropped at the right edge.

    A practical character-based recommendation is to keep a title tag at roughly 55 characters or fewer, including spaces. Treat that as a planning constraint, not a universal law. Search results are rendered by width, so different words consume different amounts of visible space. A content management system may also append a brand name or separator that was not present in your draft.

    Long titles create two presentation risks: the visible title may end with an ellipsis, or Google may choose different wording. Neither outcome automatically means the page cannot rank. It means you have surrendered some control over the message a searcher sees.

    Use this editing sequence:

    1. Write a natural draft that states the page’s subject and benefit.
    2. Move the essential topic and qualifier into the opening portion.
    3. Delete repeated category words, empty adjectives, and phrases already implied by the topic.
    4. Count the complete title, including spaces, separators, dates, and any brand text added by the site.
    5. Read the shortened version as a promise. If it becomes vague or misleading, restore the words needed for accuracy.
    6. Compare it with the live results for the target query before publishing.

    For example, Complete Guide to Title Tag SEO: Everything You Need to Know spends much of its space announcing comprehensiveness. Title Tag SEO: A Practical Writing Guide identifies the subject and the utility with less ceremony. The second title is not better merely because it is shorter. It is better if the page genuinely provides a practical writing process.

    Do not add filler to reach the available limit. When surrounding listings use nearly all of their space, a shorter, specific title can become visually distinct. Length is therefore an upper constraint and a competitive choice, not a target you need to hit.

    Stand out with evidence, not decoration

    You cannot judge differentiation inside a spreadsheet. Search the primary query and inspect the titles around yours. You are looking for repeated structures: the same adjective, the same year, the same question, the same long chain of benefits, or the same punctuation-heavy formula.

    Then work through this SERP review:

    1. List the dominant title patterns on the results page.
    2. Mark the words every result uses because the query requires them.
    3. Separate those necessary terms from language that merely copies the category.
    4. Choose one concrete distinction the page can prove.
    5. Rewrite the title so the shared topic remains recognizable and the distinction is visible.

    Useful distinctions often come from the decision the visitor is already making. For a product page, that could be price, discount, size, or length. For software, it could be the intended team or task. For an instructional page, it could be the precise deliverable. Numbers and symbols can attract attention when they communicate one of those real details rather than decorating a generic claim.

    • Family Red T-Shirts: XS-XXL identifies the available size range.
    • Red T-Shirts Under $25 identifies a spending threshold.
    • Invoice Approval Software for Small Teams identifies the intended user.
    • Title Tag Audit: A Six-Step Workflow identifies a concrete format.

    Every modifier creates an obligation. If the title says Under $25, the landing page must honor that threshold. If it promises six steps, the page must contain six usable steps. If a price or promotion changes frequently, connect the title-update process to the same operational change or choose a more durable distinction. A stale claim may win the wrong click and lose trust on arrival.

    Avoid relying on Best, Ultimate, Complete, or Essential unless the page demonstrates what the word means. These terms are not automatically forbidden, but they rarely distinguish a listing when every competitor uses them. Formulaic question titles, stacked separators, parenthetical asides, and repeated keyword variants can also make a title look machine-assembled. One clear proposition usually communicates more than a chain of loosely related promises.

    Diagnose title problems from the symptom you can observe

    A magnifying glass connects two abstract search-result symptoms to separate diagnostic paths on a dark digital workbench.

    Do not rewrite a title simply because traffic fell. Ranking movement, result-page changes, terminology, and the title itself are different variables. Check them separately so the edit addresses the actual problem.

    Observed symptomPossible readingFirst action
    Rankings and the results layout are stable, but traffic has fallenThe title may use a product or service name that searchers no longer preferCompare the wording in the title with the current language used in relevant queries and competing results
    The visible title is cut off before the differentiatorThe essential value appears too lateMove the topic and deciding detail forward, then remove repetition
    Google displays substantially different wordingThe HTML title may be long, vague, repetitive, or less useful than another page labelCompare the displayed wording with the title tag, H1, and actual page purpose before revising
    Visibility is healthy, but clicks lagThe title may be relevant without being distinctive or may answer the wrong intentInspect adjacent results and add one truthful qualifier tied to the searcher’s decision
    Clicks rise, but qualified actions weakenThe title may attract an audience the page is not designed to serveMake the audience, scope, price condition, or use case more explicit

    The first pattern deserves particular attention. When ranking and the SERP layout have not materially changed, a traffic decline can point to a mismatch between the title’s terminology and the audience’s current wording. A competitor using the more familiar name can earn the click without displacing your ranking.

    Keep a simple change record for every meaningful revision: the previous HTML title, the replacement, the target query, the displayed search title, the date, and the reason for the change. Hold other page changes steady where practical. That makes the result interpretable instead of leaving you to guess whether the title, content, or layout change moved the metric.

    Evaluate the outcome against the hypothesis. If you changed terminology, look for stronger response from the intended queries. If you shortened the title, verify that the deciding words now appear. If you added a price or size, check whether the arriving audience behaves like the audience that qualifier was meant to attract. A ranking check alone cannot tell you whether the title is doing its user-facing job.

    Key takeaways

    • Lead with the phrase or entity your intended searcher will recognize, then state a concrete value or qualifier.
    • Use roughly 55 characters, including spaces, as a practical editing constraint rather than a quota.
    • Inspect the live results page before writing; differentiation depends on what appears beside your listing.
    • Use prices, percentages, sizes, lengths, and other modifiers only when the page can prove and maintain them.
    • When rankings stay steady but traffic falls, check audience terminology before assuming the page has lost relevance.
    • Treat AI visibility as an extension of sound search visibility, not as a reason to stuff conversational phrases into the title.

    Start with one page that has stable visibility but an underperforming search listing. Write down its audience, primary phrase, promise, and strongest truthful distinction. Reduce those four inputs to one clear title, log the change, and judge it by whether it attracts more of the right clicks.

    References