Tag: Content Optimization

  • AI-Assisted SEO Content Operations: A Scalable Framework

    AI-Assisted SEO Content Operations: A Scalable Framework

    AI can make SEO production faster, but speed does not resolve the central challenge of content operations: ensuring that business economics, workflow systems and editorial judgment continue to support the same goal. If those elements drift apart, greater output can simply multiply weak decisions.

    A durable AI-assisted operation therefore begins with the publishing model, not the model prompt. The practical objective is to encode useful expertise into repeatable workflows while preserving human control over strategy, evidence, quality and investment.

    Key takeaways

    • Content volume should follow audience demand and unit economics rather than the availability of inexpensive AI production.
    • Generic AI output becomes more useful when an organization supplies its own customers, priorities, standards and SEO process as context.
    • Custom assistants are best treated as workflow infrastructure: they can apply a defined method repeatedly, but they do not replace editorial judgment.
    • Quality controls and performance feedback must be designed into the operation before production expands.

    Scalability starts with economic and editorial fit

    The first source describes a structural problem that appears when content businesses grow: economic objectives, operating systems and editorial decisions can become disconnected. A small team may coordinate through experience and close working relationships, while a large network needs explicit systems and data to keep production coherent. AI increases the importance of that distinction because it makes additional drafts easier to create without proving that additional publishing is warranted.

    Volume is also category-dependent. The scaling article contrasts a niche B2B product, where very high output could waste resources, with sports publishing, where games, teams, players and continuing developments can support frequent coverage. Its example of The Athletic reports $54 million in revenue during one quarter and says direct consumer subscriptions provided most of that revenue. In that model, editorial quality is closely connected to the value customers are purchasing.

    The same source presents a more fragile equation for advertising-supported publishing: revenue equals pageviews divided by 1,000, multiplied by revenue per thousand impressions, while profit subtracts production cost. It illustrates the pressure with an article receiving 4,000 pageviews at a $16 RPM, producing $64 before production costs. These figures are an example reported by the source, not a universal benchmark. Their operational lesson is broader: when expected value per article is constrained, producing more content can magnify both small efficiencies and small quality failures.

    DecisionQuestion to resolve before scalingOperational consequence
    DemandDoes the audience have enough distinct, continuing needs to justify more pages?Sets a defensible ceiling for publishing volume.
    RevenueHow is each content type expected to contribute to the business?Determines what production cost and quality level the model can support.
    DifferentiationWhat knowledge, evidence or perspective makes the content worth choosing?Defines what must remain intact when AI assists production.
    GovernanceWho can approve, revise, pause or retire content?Prevents workflow speed from becoming uncontrolled publication.

    AI is most useful when it carries a specific SEO process

    The second source examines the workflow side of the problem. It reports that general-purpose tools such as ChatGPT and Google’s Gemini can perform standard on-page reviews, but their initial recommendations often remain generic because they lack the organization’s business context. Broad advice about improving content or acquiring links may be reasonable in the abstract while still failing to identify the best action for a particular company.

    That limitation points to the appropriate role for AI in content operations. The model should not be expected to discover the business strategy from a bare keyword or URL. It should receive a defined method: who the customer is, what the page is meant to accomplish, which competitive conditions matter, how evidence should be handled and what an acceptable deliverable contains.

    The workflow article highlights GPTs, Gems and Claude Projects as accessible ways to package such context without extensive coding. Its central claim is that the organization’s expertise is the valuable input; the assistant helps apply that expertise repeatedly. Combined with the scaling article, this suggests a clear division of labor: systems preserve and distribute an approved process, while editors decide whether that process is appropriate for a particular topic and business objective.

    A controlled operating loop connects strategy to publication
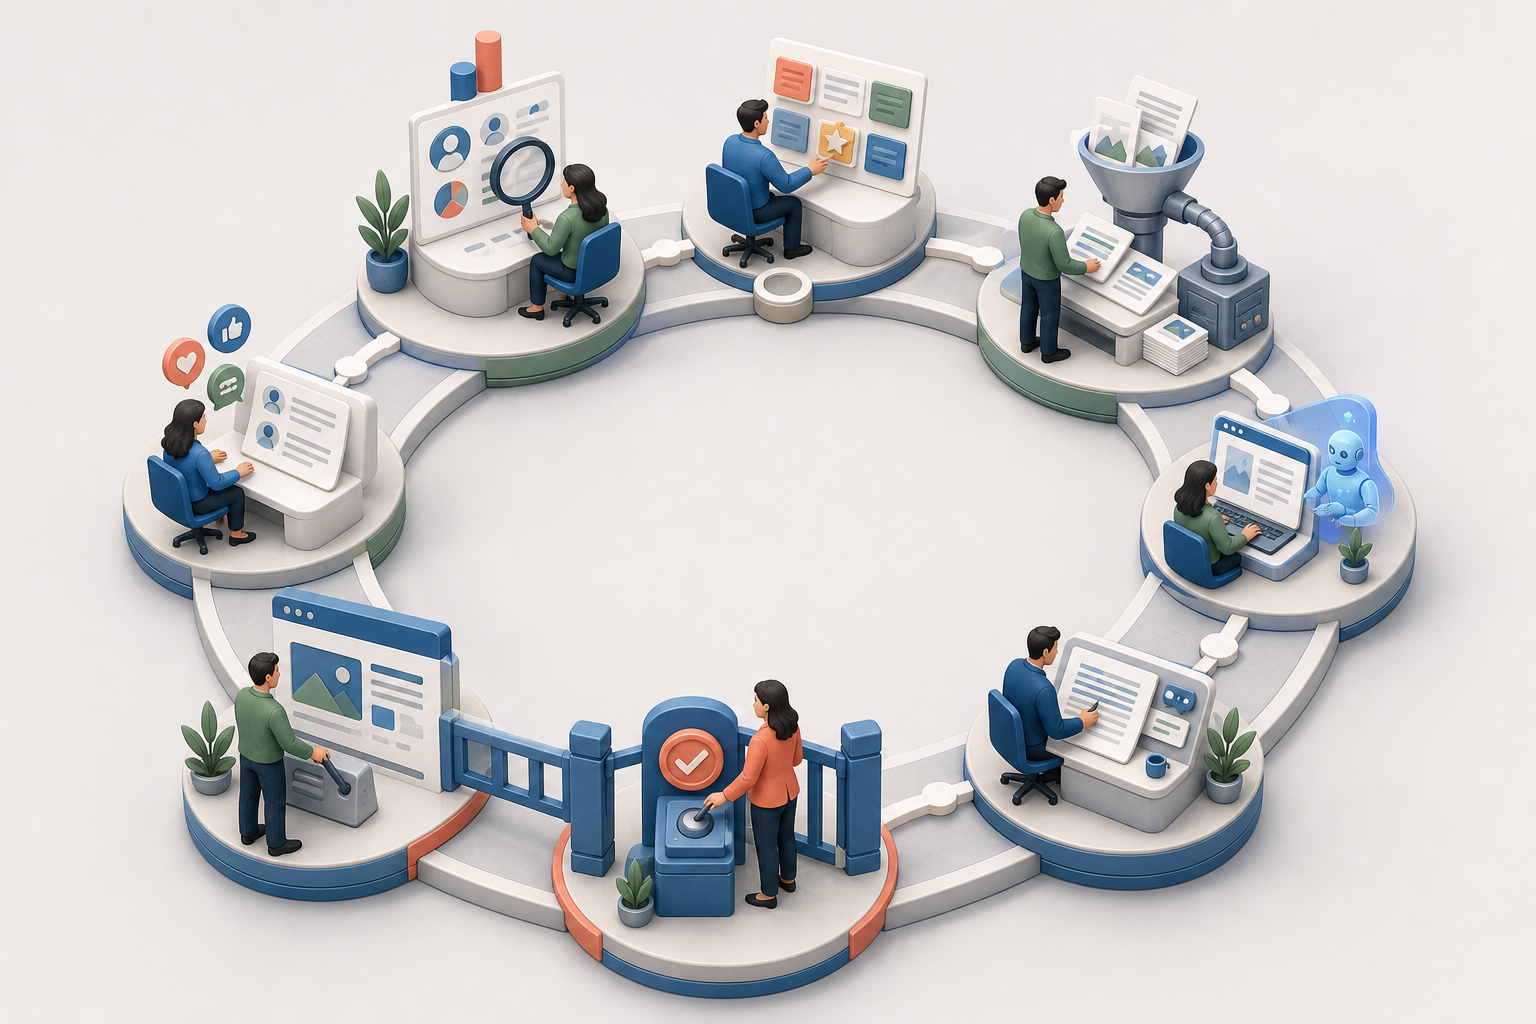
    An isometric circular workspace shows people guiding content through research, drafting, editing, approval, publication and feedback stages.

    Define the assignment before invoking AI

    Each assignment needs a business purpose, intended audience, search need, content type and success criterion. This brief is the bridge between economics and execution: it prevents a production system from treating every keyword as equally valuable and gives the assistant enough context to apply the organization’s method.

    Encode the repeatable method

    A custom assistant can carry reusable instructions for research organization, page analysis, outlines, optimization checks and editorial formatting. Stable standards can be embedded in the workflow, while changing inputs such as the audience, offer, competitors and source material should be supplied with each assignment. This separates institutional knowledge from task-specific evidence.

    Place human judgment at consequential gates

    Editorial review should concentrate on decisions with business or reputational consequences: whether the premise deserves publication, whether claims are supported, whether the page adds something useful, whether it matches the intended voice and whether optimization compromises clarity. The goal is not human intervention in every mechanical step; it is accountable control where errors would matter most.

    Return outcomes to the system

    Publication completes a production cycle, not a learning cycle. Performance observations, recurring editorial corrections and failed assumptions should inform briefs, assistant instructions and topic selection. Otherwise, an organization may automate the same avoidable weakness across an expanding library.

    Measure the operation at three connected levels
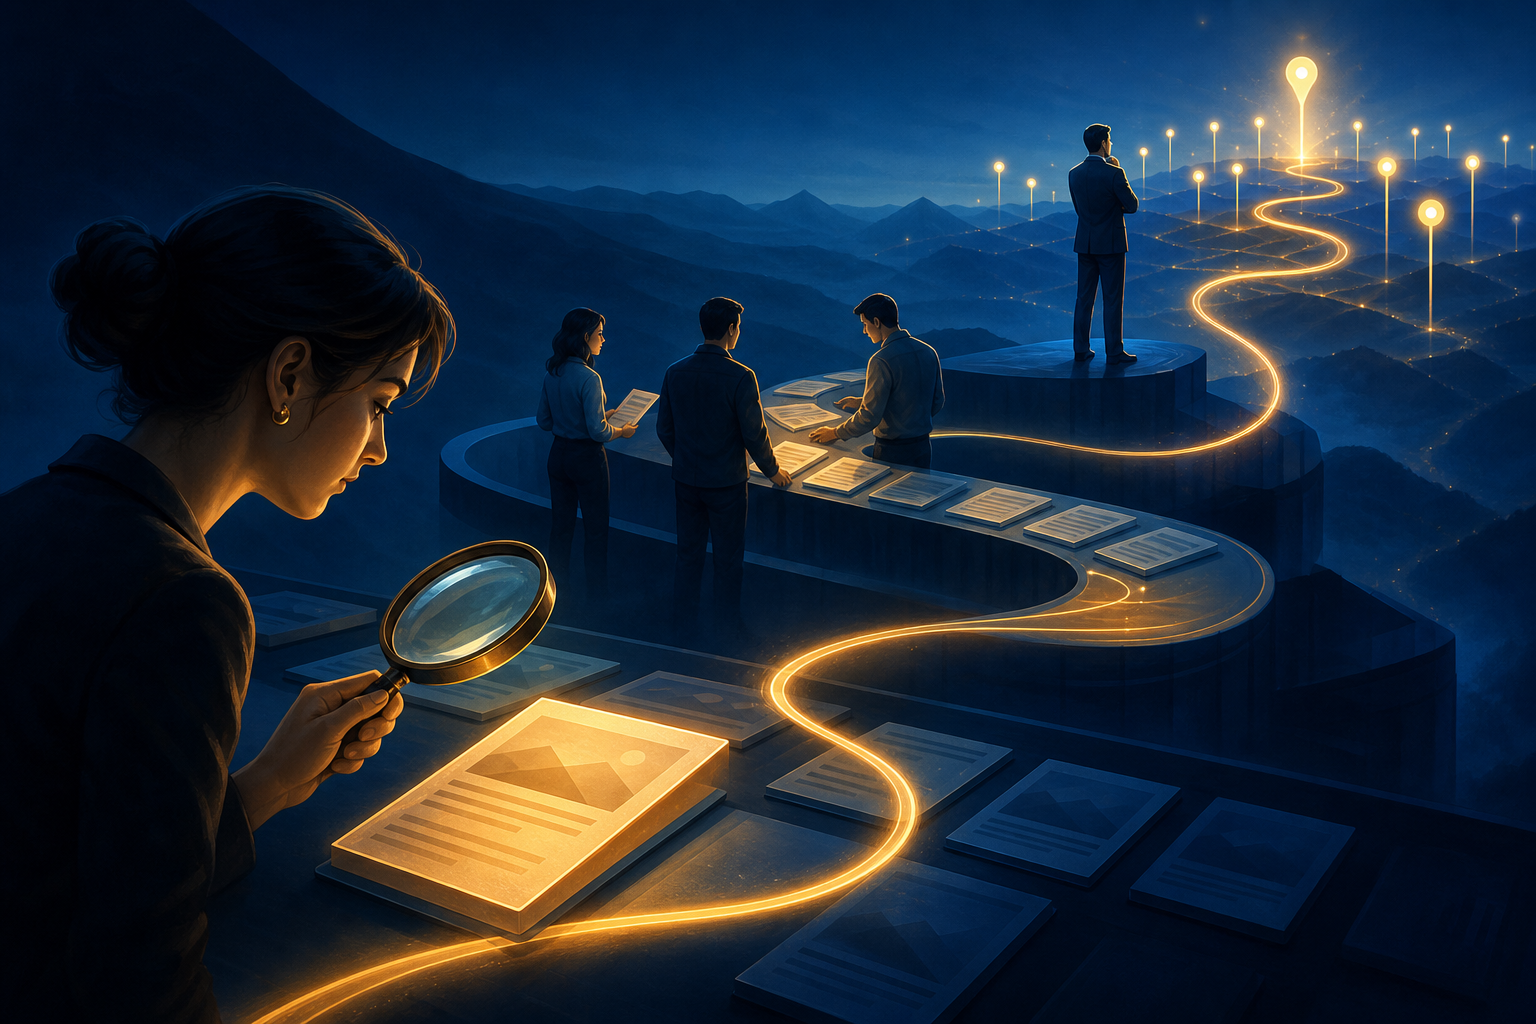
    Three connected scenes show an editor assessing an article, a team monitoring a content workflow and a leader observing business outcomes.

    Production metrics reveal whether work moves efficiently, but they cannot establish whether the work was worth producing. Editorial indicators examine accuracy, usefulness, distinctiveness and the amount of correction required. Business outcomes then show whether the content contributes to the economic model, whether that contribution comes from subscriptions, advertising, leads or another defined purpose.

    These levels should be interpreted together. Faster drafting with heavier editorial repair is not an unqualified efficiency gain. Higher traffic with production costs that exceed the resulting value is not sustainable growth. Strong individual pages in a category with insufficient demand do not justify unlimited expansion. The two source articles approach the issue from different directions, but they converge here: scalable content requires operational systems and contextual expertise, not output capacity alone.

    The next stage of AI-assisted SEO will belong to organizations that can make their judgment explicit, test it against business outcomes and revise the system without lowering the editorial standard that gives the content value.
    References

  • How to Build Content Authority Across AI Search Engines

    How to Build Content Authority Across AI Search Engines

    Content authority in AI search is not a single score that a brand earns once and carries everywhere. The source reports point to a more conditional system: visibility depends on the AI engine, the topic and prompt, the sources retrieved, and whether a useful passage can be extracted from the page.

    That changes the optimization task. Instead of producing one broad guide and accumulating undirected mentions, publishers need to decide where they want to appear, understand what that system retrieves for the topic, and create evidence-rich passages that can survive the final selection process.

    Authority now operates at three distinct layers

    A cutaway illustration shows a source network, modular content blocks, and selection lenses arranged in three layers.

    Taken together, the sources suggest that AI visibility has three layers: engine selection, topical trust, and passage extractability. A weakness at any layer can prevent a brand from being cited even when its conventional search performance is strong.

    The engine layer determines which index, retrieval process, and content formats are likely to enter consideration. Uncover 7 Unmissable AI Search Trends Transforming Marketing reports that ChatGPT and Claude shared only 8% of citations in the analysis it covered. It also reports substantial format differences: community sites accounted for about 16% of ChatGPT citations, while Claude cited listicles 36% of the time and opinion content 13.2% of the time, compared with approximately 20% and 7.2%, respectively, for ChatGPT.

    The topic layer determines whose evidence the system treats as relevant and credible. Boosting AI Visibility: Mastering Topic-Driven Authority argues that citation sources cluster by subject rather than following one universal hierarchy. Its examples indicate that competitor domains had a larger role in invoicing queries than in starting-a-business queries. A publication that matters for one part of a market may therefore contribute little authority to an adjacent part.

    The passage layer determines whether the system can isolate a clear answer from the selected document. Mastering AI Search: Building Machine-Friendly Content reports a 66% extraction rate for pages under 5,000 characters and 12% for pages over 20,000 characters. Those figures should be treated as findings reported by that article, not as a universal length rule. Their strategic significance is that authority without retrievable statements may never become a citation.

    Choose the engine and prompt class before optimizing

    An AI-search plan should begin with the audience and the engine it uses, not with a generic content calendar. The trends report says 64% of sites cited by Claude appeared in Google’s top 50 for corresponding queries, compared with 37% of sites cited by ChatGPT. It further reports that 79.2% of Claude citations aligned directly with the top 10 Brave Search results in the analysis it references. Within that reported environment, Brave rankings offer a more observable diagnostic for Claude than conventional Google rankings alone.

    Audience context may also affect prioritization. Citing Ramp’s AI Index, the trends article reports Anthropic usage at 34.4% of businesses and OpenAI at 32.3%. It also says approximately 85% of Anthropic’s revenue came from enterprise and API usage. These figures do not establish that every B2B organization should optimize for Claude first, but they support testing Claude as a distinct business channel rather than treating its consumer web traffic as a complete measure of relevance.

    Even a priority engine is not equally optimizable for every prompt. According to the same report, ChatGPT initiated web searches for nearly 95% of prompts in the cited analysis, while Claude did so about one-third of the time. Claude was reportedly more likely to search for current-event, ranking, location, and comparison prompts, with reported search rates of 81%, 67%, 55%, and 51%, respectively. Definitions and procedures were described as much less likely to trigger retrieval.

    This distinction prevents a common measurement error. A page cannot win a fresh web citation when an engine answers from internal model knowledge without searching. Prompt testing should therefore record whether retrieval occurred before a team interprets a missing citation as a content or authority failure.

    Query expansion adds another engine-specific variable. The trends report characterizes ChatGPT fan-out queries as changeable, while reporting that Claude produced the same fan-out strings 65% of the time and attached the current year to 94% of them, compared with 17% for ChatGPT. Stable expansions may support tightly targeted pages; volatile expansions call for broader coverage across owned, earned, community, and other relevant sources.

    Design passages around problems, claims, and constraints

    A modular claim block is supported by source, context, and constraint pieces while a scanning beam isolates it from surrounding blocks.

    Machine-friendly content is not simply shorter content. The more useful objective is modularity: each section should resolve a recognizable subproblem without requiring an AI system to reconstruct the answer from a long narrative.

    The machine-friendly content report recommends replacing broad category positioning with problem-specific positioning. Its illustrative shift is from identifying a company merely as an insurance provider to explaining that it addresses underwriting for first-time drivers under 25 who have been declined by standard insurers. The example also shows why constraints matter. Stating who a solution is not for, where it applies, or what condition changes the answer can make a claim more precise and credible.

    Headings should name the outcome or question addressed by the section. Paragraphs should open with a direct answer or citable claim, then add conditions, evidence, and explanation. The same source reports that explicit headings increased retrieval likelihood by 17.54% and says Gemini may use approximately 380 words for query grounding. These reported limits reinforce the value of self-contained sections, although they do not justify stripping away evidence or necessary nuance.

    The synthesis is a two-level editorial model. At page level, the article should offer a coherent argument for a human reader. At passage level, it should state entities, relationships, qualifications, and evidence clearly enough to be extracted independently. Narrative still has a role, but it should extend a usable answer rather than delay it.

    Build off-site authority inside the relevant source network

    On-site clarity makes a document usable; it does not make the publisher trusted by every system or for every topic. The topic-driven authority report recommends mapping the domains, publications, experts, and platforms that repeatedly appear in answers for the exact subject a brand wants to own. This is more focused than pursuing links or publicity from generally prominent sites without checking their topical role.

    That mapping should also distinguish content formats. The topic-authority report describes YouTube as an exception that can surface across larger language models and recommends working with recognized subject-matter experts and relevant LinkedIn voices. The engine trends report, meanwhile, finds that community content was more prominent in ChatGPT citations and that listicles and opinion pieces were more prominent in Claude citations. Together, these observations suggest that the right distribution mix depends on both the topic’s trusted entities and the target engine’s retrieval preferences.

    Concentration may matter more than raw mention volume. The authority report argues that recognition can move in jumps when a brand earns coverage from a highly trusted topical source, and it recommends ranking potential collaborators by authority tier. This remains a strategic recommendation from the source rather than proof that every high-profile placement will produce citations. Teams should validate it by comparing citation frequency before and after individual placements.

    Measurement should follow the same conditional structure. For each priority prompt, a useful record includes the engine, whether it searched the web, the apparent query expansions, cited domains, cited passage types, the brand’s inclusion, and the presence of paid placements. The trends report says ChatGPT ads can appear around competitor mentions, so organic citation monitoring and paid competitive monitoring should be kept separate. Otherwise, a purchased appearance can be mistaken for earned authority, or a strong organic mention can obscure a competitor’s paid defense.

    Key takeaways

    • Define authority by engine and topic; citation strength in one model or subject does not automatically transfer to another.
    • Confirm that the target prompt triggers web retrieval before investing in pages intended to earn fresh citations.
    • Build problem-specific, self-contained sections with direct claims, explicit conditions, and enough evidence to stand alone.
    • Concentrate outreach on the publications, experts, communities, and formats that already shape answers for the target topic.
    • Measure retrieval, organic citations, and paid placements separately so each visibility mechanism can be diagnosed accurately.

    As retrieval systems, source preferences, and advertising models change, durable advantage will come from maintaining this engine-topic-passage map as a living operating system rather than treating AI optimization as a one-time rewrite.

    References

  • From Search Intent to Citation Share: Measuring AI Visibility

    From Search Intent to Citation Share: Measuring AI Visibility

    AI search visibility is becoming easier to observe, but measurement alone does not explain what content should change. Bing’s emerging reporting describes where a site appears across intents, topics and citations; the next-question intent framework examines whether its pages contain enough detail to support the comparisons and decisions behind those appearances.

    Used together, these perspectives create a practical loop: identify the contexts in which a site is being cited, inspect whether the underlying content supports the user’s full decision path, and then monitor how citation visibility changes.

    Two layers of intent explain different parts of visibility

    The Bing reporting source says the preview of its enhanced AI performance report classifies grounding queries by intent, including Informational, Commercial and Navigational categories. This is a reporting layer: it helps publishers understand the broad purpose associated with the queries for which their content surfaces.

    Next-question intent is an editorial layer. The separate analysis defines it as the information a person will need after the opening query to compare options, establish trust or make a decision. A page can therefore match an initial commercial query while still failing to answer the more specific questions that determine which option is suitable.

    The distinction matters because the two concepts should not be treated as competing taxonomies. Reported intent describes an observed visibility context. Next-question intent helps diagnose whether a page has enough substance to remain useful as that context becomes more specific.

    Key takeaways

    • Bing’s reported intent and topic views organize AI visibility by user purpose and thematic context rather than isolated queries alone.
    • Citation Share and Compare provide directional evidence about visibility, but they are not rankings, quality scores or proof of business impact.
    • Next-question intent connects reporting to content decisions by identifying the follow-up information users need to trust, compare and choose.
    • The strongest workflow reads intent, topic and citation signals together, then validates the relevant pages for specificity, evidence and decision support.

    How Bing’s reporting dimensions fit together

    An isometric website tile connects to groups of intent gateways, topic spheres, and citation markers.

    According to the Bing reporting article, the new enhancements are being introduced globally as a preview. The source says Bing had launched its underlying AI performance report in February and that a similar Google Search Console feature arrived in June. Those dates and the characterization of Google’s release come from the source and are not independently verified here.

    Reporting dimensionWhat the source says it showsUseful question for publishers
    IntentsGrounding queries classified into broad purposes such as Informational, Commercial and NavigationalIn what kinds of user situations is the site appearing?
    TopicsRelated queries grouped into thematic clustersWhich broader subjects are producing visibility?
    Citation ShareThe site’s percentage of citation visibility relative to other sourcesIs the site’s presence expanding or contracting within the measured set?
    ComparePrevious data overlaid on current reportingHow has citation activity changed between the displayed periods?

    These dimensions become more informative when read as a sequence. An intent indicates the general task, a topic identifies the subject area, Citation Share supplies a relative visibility signal, and Compare adds a time dimension. No individual metric provides the whole explanation.

    The source illustrates topic clustering with queries about solar panels and solar energy efficiency being grouped under a broader Solar Energy theme. It also cautions that labels may remain broad for niche domains during the preview. Topic names should therefore be treated as navigational aids for analysis, not as exact descriptions of every underlying query.

    Next-question intent turns observations into content diagnosis

    A report might reveal visibility in commercial, comparison-oriented experiences, but it cannot by itself determine whether a page answers the questions that shape a purchase. The next-question analysis uses a search for the best customer relationship management software for a small business to make this problem concrete. The opening request does not settle which product fits a two-person team, integrates with QuickBooks, works without a formal sales department or suits a local service company.

    Those follow-ups expose the difference between category relevance and decision utility. A page can accurately describe several products yet give an AI system little usable material for distinguishing who each product serves, when it is appropriate, how it differs from alternatives or what supports its claims.

    The analysis applies the same test to broad brand language. Claims such as customized strategies, family safety or suitability for small businesses remain underspecified unless the page explains how the offer is customized, which family members are covered, or which kinds of small businesses are meant. This is not a call to make pages longer by default. It is a call to replace ambiguity with relevant conditions, distinctions and evidence.

    For an informational intent, the next question may concern method, limitations or applicability. For a commercial intent, it may concern trade-offs, compatibility or fit. For a navigational intent, it may concern the exact destination or action available there. These examples are an analytical extension of the source framework rather than categories reported by Bing.

    A reporting-to-content workflow for AI visibility

    A circular sequence links citation observation, branching questions, expanded content blocks, and ongoing monitoring.

    Start with the intersection of intent and topic rather than a sitewide citation total. A change within a particular context is more actionable than an aggregate movement because it narrows the pages and user needs that deserve investigation. Citation Share can then indicate whether the site’s relative presence in that measured environment is moving, while Compare provides the period-over-period view described by the Bing source.

    Next, inspect the pages associated with that context as decision resources. The relevant test is whether they explain what the offering or subject is, whom it applies to, when it is useful, how alternatives differ and what evidence supports consequential claims. The next-question source argues that this substantive layer gives AI systems material they can synthesize, compare and use in recommendations.

    Content changes should address identifiable gaps rather than chase a metric mechanically. If a page appears around a comparison topic but lacks selection criteria, the useful revision is to clarify fit and trade-offs. If a niche topic label is broad, analysis should begin with the underlying pages and their actual subject matter instead of assuming that the dashboard label precisely captures demand.

    Finally, monitor the same intent-topic context over time. The Bing source notes that citation activity can be affected by AI model updates, changes in user demand and other factors. A rise or fall after an edit is therefore a signal for further investigation, not automatic evidence that the edit caused the movement.

    What current visibility reporting cannot establish

    Citation visibility is not equivalent to a conventional ranking. The Bing article explicitly describes Citation Share as directional and says it does not provide a ranking or quality score. A citation also does not, on its own, show whether the user clicked, converted, trusted the source or ultimately selected the brand.

    The source further says click and click-through rate data were still awaited. Without those measures, the reported tools are best suited to visibility diagnosis and trend monitoring. They should not be presented as a complete attribution system or as proof of commercial performance.

    Next-question intent has a boundary as well: it is a framework for improving content utility, not a guaranteed formula for earning citations. Its value is in making pages more explicit and decision-ready while reporting supplies evidence about where visibility exists and how it changes.

    As AI reporting develops, the durable advantage will come from connecting clearer measurements to better editorial questions. Publishers that preserve the distinction between an observed citation, an inferred cause and a verified outcome will be better positioned to improve content without overstating what the dashboards prove.

    References

  • What Google Content Visibility Signals Really Tell Publishers

    What Google Content Visibility Signals Really Tell Publishers

    Google visibility is often discussed as if it could be improved through a single tactical change: choose a more successful headline pattern, add a machine-readable file, or imitate whatever appears to perform best across a large dataset. The source reporting points to a more demanding conclusion.

    A study of Google Discover headlines shows how an apparent format advantage can be driven by publisher and audience differences, while Google’s reported guidance on llms.txt says the file has no effect on Search rankings. Together, these accounts offer a practical way to distinguish an observable characteristic from a credible visibility lever.

    Visibility is not one outcome or one mechanism

    The two source articles address different Google environments. The Discover analysis concerns how often editorial articles appeared across the 1492.vision fleet. Its metric was hits per article, which the source described as a proxy for visibility rather than a count of Discover clicks. The llms.txt article, by contrast, concerns whether a site-level file affects visibility in Google Search.

    That distinction matters because a feature associated with frequent appearances on one surface is not automatically a ranking factor, a cause of traffic, or a general rule for Google visibility. A Discover headline can be correlated with exposure without causing it. A file can help another service understand a site while remaining irrelevant to Google Search. The surface, measured outcome, and proposed mechanism must therefore be identified before a result becomes actionable.

    Headline format looks powerful until publisher context is added

    Two contrasting publisher environments show different content-card styles, audience sizes, and distribution conditions around a central magnifying lens.

    The Discover report described an analysis of 1,674,518 English articles and 1,690,295 French articles from the 1492.vision corpus. When publishers were pooled, quote-led headlines produced 37% more hits per article than statements in English and 48% more in French. Questions also exceeded statements in the aggregate, by 7% in English and 16% in French.

    Those figures appear to support a simple editorial prescription. Yet the report argued that the aggregate comparison mixed together publishers with different audiences, subject matter, editorial styles, and patterns of Discover exposure. Celebrity publications, regional news organizations, and outlets focused on trending topics were among the types said to use quotations more often. Their underlying visibility could therefore make the quotation format look more effective than it was.

    The source identified this as an example of Simpson’s paradox: a relationship visible in pooled data can weaken, disappear, or reverse after the data is separated into meaningful groups. In this case, the relevant test is not simply whether all quote headlines outperform all statements. It is whether the formats perform differently within comparable publishers and contexts, with each publisher serving as its own baseline.

    This does not make headline construction irrelevant. It changes the claim that the evidence can support. The reported aggregate results describe where visibility occurred across a mixed population; on their own, they do not establish that converting a statement into a quotation will create the same lift for an individual publisher.

    Google’s llms.txt position removes a different false lever

    The second source reported that Google updated its AI Search optimization guidance to say that llms.txt files do not affect Search rankings. According to that account, Google Search does not use the files, and publishers do not need to create new AI-oriented text or Markdown files to qualify for inclusion in Search experiences involving generative AI.

    The reported guidance includes an important qualification: Google may still discover, crawl, and index various file types. That general ability does not mean llms.txt receives special ranking treatment. The source also noted that a site may maintain the file for other services without improving or damaging its Google Search visibility.

    This is a more direct finding than the Discover correlation. The headline analysis asks whether an apparent advantage survives contextual controls. The llms.txt guidance says the proposed mechanism is not used for the claimed Google Search benefit. One tactic requires better causal analysis; the other has been explicitly ruled out as a Google ranking aid in the source’s account.

    A stronger test for proposed visibility signals

    Glowing signal tokens move through a sequence of evidence checkpoints, with weaker signals diverted and stronger signals reaching an illuminated content card.

    The synthesis suggests that publishers should evaluate any claimed signal along three dimensions. First, the claimed outcome should be precise: ranking position, impressions, Discover appearances, clicks, or another measure. Second, comparisons should account for publisher, audience, topic, language, and surface whenever those factors could influence both the tactic and the outcome. Third, the proposed mechanism should be checked against Google’s stated use of the feature when relevant guidance exists.

    For headline decisions, the most informative evidence would come from comparisons within the same publication and from controlled editorial tests that keep topic and distribution conditions as comparable as possible. Hits per article can reveal exposure patterns, but it should not be presented as click performance or as proof that punctuation and syntax independently caused the result.

    For machine-readable files, the decision can be separated by beneficiary. An llms.txt file may be maintained for a non-Google service that uses it, but the reported Google guidance provides no basis for treating its creation as a Search ranking project. This prevents an implementation task from being justified with an unsupported visibility promise.

    Key takeaways

    • Google visibility claims must name the surface and metric; Discover hits, clicks, and Search rankings are not interchangeable outcomes.
    • The reported quote-headline advantage appeared in pooled English and French data, but publisher and audience differences made a simple format-based explanation unreliable.
    • Within-publisher comparisons are more useful than global averages when editorial conventions and baseline visibility vary across outlets.
    • According to the llms.txt source, Google Search does not use the file as a ranking aid, although sites may keep it for other services.
    • An observable pattern becomes actionable only after plausible confounders and the proposed mechanism have been examined.

    As new visibility tactics emerge, the durable editorial advantage will come from asking what was measured, what else could explain it, and whether the platform recognizes the proposed mechanism. That discipline leaves room for experimentation while keeping correlation, platform guidance, and causal claims in their proper roles.

    References

  • SEO Expertise in the AI Era: From Output to Prioritization

    SEO Expertise in the AI Era: From Output to Prioritization

    AI is making many familiar SEO outputs faster and cheaper to produce, but it is not making the underlying decisions easier. The emerging premium is on expertise that can distinguish plausible advice from worthwhile action, connect search work to business outcomes, and carry priorities through implementation.

    Across technical SEO, content, and AI visibility, the practical question is therefore no longer how many recommendations a team can generate. It is which intervention deserves scarce time, what evidence supports it, and how success should be measured.

    Recommendation volume is becoming a weak proxy for expertise

    The career analysis in Search Engine Land argues that AI is changing the value of SEO skills more than it is directly targeting the profession. Audits, briefs, keyword work, and optimization suggestions remain useful, but AI can produce versions of them quickly. If recommendations become inexpensive, a long report is less persuasive evidence of expertise than the judgment used to select, sequence, and implement its best ideas.

    The same pressure is visible in content. Search Engine Land’s article on firsthand experience describes a web crowded with interchangeable advice and says AI has made generic production still easier. Its proposed differentiators are concrete examples, test results, candid opinions, client outcomes, and lessons from failed work. That is the content equivalent of the career shift: readily generated output loses relative value, while evidence rooted in actual decisions and consequences gains it.

    Together, these accounts suggest a more demanding definition of SEO expertise. Knowledge remains the foundation, but the differentiating layer is the ability to challenge an answer, identify the assumptions behind it, and convert a recommendation into an outcome. AI can accelerate analysis and drafting without deciding which organizational constraint, commercial objective, or uncertain premise matters most.

    Prioritization should operate as a portfolio discipline

    A hand allocates a limited number of glowing tokens among abstract website, content, audience, and AI-system models on a circular table.

    A backlog cannot be prioritized credibly when every item is labeled urgent. Search Engine Land’s forecasting framework contrasts a minor schema issue with a title-tag problem affecting thousands of pages to show why technical seriousness and business impact are not necessarily the same. It recommends estimating likely traffic impact before work begins, while acknowledging that traffic is not the only objective when brand visibility or user experience is at stake.

    Estimate the opportunity that is actually exposed

    The first distinction is scope: a sitewide change, a template-level repair, and a single-page optimization create different opportunity sizes. The forecasting source recommends filtering affected URLs in Google Search Console and examining current clicks, impressions, ranking positions, and the surrounding search-result features. It identifies pages ranking from positions 8 through 15 as potential near wins, but also warns that an improvement can produce very different click gains depending on the result layout and the presence of AI experiences.

    Replace a precise promise with explicit scenarios

    Potential lift can then be grounded in outcomes from similar past changes, competitor and search-result analysis, and assumptions appropriate to AI-influenced click behavior. Rather than presenting one apparently certain number, the source recommends conservative, expected, and aggressive scenarios. That approach makes uncertainty visible: partial implementation and competitive responses can be represented separately from stronger execution and faster indexing.

    Compare expected value with delivery cost

    The forecast becomes useful only when it changes the roadmap. Comparing the expected effect with effort through a framework such as RICE can expose large, scalable opportunities that would otherwise lose attention to smaller and more appealing technical tasks. For initiatives whose primary outcome is not traffic, the same discipline still applies: define the intended result, select an observable measure, state the uncertainty, and compare the opportunity cost with competing work.

    Evidence must cover both execution and search context

    The sources point to two complementary forms of evidence. Internal evidence comes from implementation: previous fixes, controlled tests, client work, failures, and observed results. External evidence comes from the environment in which a brand or page must compete: result layouts, competitors, third-party coverage, and the associations AI systems appear to use.

    This distinction helps explain why AI fluency alone is insufficient. The career article recommends evaluating how an SEO handled a disagreement, responded to a failed test, or caught an AI mistake. Those questions test whether the candidate can reason under uncertainty and continue after an initial plan breaks down. The content article makes a parallel case for publishing details that could come only from real practice rather than another summary of established advice.

    A useful workflow therefore treats AI output as a hypothesis generator. An audit suggestion, content angle, or visibility diagnosis should be checked against the site’s data, the actual search environment, and relevant operational experience. When evidence is incomplete, the appropriate response is a bounded test or a qualified forecast, not greater confidence in the wording of the recommendation.

    AI visibility requires separating recognition from recommendation

    A network of web sources passes through two transparent filtering chambers before a small selection reaches a human silhouette.

    Prioritization becomes more complicated when the objective extends beyond conventional rankings and clicks. A Search Engine Land study conducted through Friction AI examined 12 activewear brands across more than 14,000 API tests. The researchers reported that strong Knowledge Graph recognition did not consistently translate into recommendations for related prompts, describing the difference as a framing gap.

    The study’s co-mention analysis suggests why those outcomes may diverge. It found that brands could become associated with particular competitors and category leaders through the contexts in which they appeared together. Nike, for example, was reported to appear prominently in recommendation prompts despite sharing a broad company description with other footwear brands; the researchers connected that result to its recurring association with category leaders.

    This was an exploratory study in the UK athleisure sector, and its authors said additional categories and regions would need examination. It should not be treated as a universal ranking formula. It does, however, identify an important planning distinction: improving the clarity of a brand’s own pages may support recognition, while earning relevant third-party coverage and category associations may support recommendation. Those are related objectives, but they call for different actions and should not be collapsed into a single visibility score.

    The distinction also changes content strategy. Firsthand case studies and specific results can make owned content more credible, as the experience-focused source argues. Yet the co-mention research indicates that a brand’s self-description is only part of its AI-visible context. A mature plan must consider both what the brand demonstrates directly and how independent sources position it within the market.

    Key takeaways

    • Judge SEO work by the quality of decisions and delivered outcomes, not the number of recommendations produced.
    • Estimate scope, exposed traffic, potential lift, uncertainty, and implementation effort before assigning roadmap priority.
    • Use AI to accelerate hypotheses and production, then validate its output against data, search context, and firsthand experience.
    • Preserve real examples, failed tests, observed results, and informed opinions because generic information is increasingly easy to reproduce.
    • Measure brand recognition and AI recommendation separately; owned-page clarity and third-party category associations may require different investments.

    As AI lowers the cost of producing SEO artifacts, teams will need clearer decision records, stronger testing habits, and measures tied to the outcome each initiative is meant to change. The durable advantage will belong to practitioners who can make uncertainty legible and direct limited resources toward work that survives contact with real users, search systems, and organizational constraints.

    References

  • How to Align SEO and Affiliate Strategy Without Wasting Spend

    How to Align SEO and Affiliate Strategy Without Wasting Spend

    Your SEO team is trying to win valuable search demand. Your affiliate team is paying partners to influence many of the same buyers. If those efforts are managed separately, you can end up paying commission on demand your brand already created while leaving more valuable third-party coverage to chance.

    The answer isn’t to restrict affiliates across the board. It is to decide which searches your brand should own, where partners add incremental reach, and how both teams will measure the difference.

    Key takeaways

    • Keep high-intent branded searches under SEO ownership when your own pages can satisfy the user.
    • Use affiliates to reach comparison, review, and best-of searches where independent coverage adds credibility and discovery.
    • Separate incremental affiliate sales from conversions captured on demand the brand already generated.
    • Prevent affiliate tracking URLs from becoming competing indexed pages.
    • Give SEO and affiliate managers one scorecard tied to revenue, cost, visibility, and partner contribution.

    Draw an ownership line around branded search

    A central website sits inside a highlighted boundary while affiliate pathways operate outside it.

    Start with the queries closest to a purchase. Searches such as “[brand] discount code” and “[brand] promo code” usually come from people who already know you. If an affiliate ranks above your brand for that demand, the buyer may click through the partner and complete the same purchase with an added commission attached.

    Build a query ownership sheet before changing partner terms. For every important branded query, record the current ranking page, the page your brand wants to rank, the leading affiliate result, search intent, and the commercial action available on your site.

    Query typePreferred ownerReasonNext action
    Brand plus discount or promo codeBrandThe customer already has strong brand intentCreate or improve an official offers page
    Brand plus login, delivery, returns, or supportBrandThe user needs an authoritative answerImprove the relevant service page
    Best product for a use caseBrand and selected affiliatesFirst-party education and independent evaluation can both helpPublish useful guidance and recruit relevant partners
    Brand versus competitorBrand and selected affiliatesBuyers may want both your explanation and an outside viewSet evidence and disclosure standards

    This isn’t a universal ban on affiliates bidding or ranking for brand terms. It is a commercial decision. If a partner reaches a customer you couldn’t otherwise reach, that may be incremental. If the partner simply intercepts a buyer immediately before checkout, you are paying for conversion capture rather than acquisition.

    Reclaim searches your brand should already win

    Run a manual search review for your priority branded terms. Check whether your intended page appears, whether its title and heading match the query, whether the offer is current, and whether a visitor can complete the expected action without hunting around.

    The commercial cost can be meaningful. In one example, “trainline promo code” attracted 17,000 monthly searches in the UK while Trainline’s promotional page was not optimized for the term. That gap allowed affiliates to capture traffic from people explicitly looking for the brand.

    Fix the page in this order:

    1. Confirm that the page satisfies the query. A promo-code page should show valid offers, eligibility conditions, expiry information when available, and what to do if no code is required.
    2. Align the title, main heading, and introductory copy with the language customers use. Don’t force a term onto an unrelated page.
    3. Link to the page from relevant navigation, offer, campaign, and help content so visitors and search engines can find it.
    4. Compare rankings, organic conversions, affiliate-assisted conversions, and commissions after the change.
    5. Review affiliate terms if partners continue targeting searches that have been assigned to the brand.

    Small on-page changes can move commercial visibility quickly when the right page already exists. One managed brand increased search share of voice from 14% to 31% after a focused content update. Treat that as a reason to test neglected pages, not as a guaranteed outcome for every site.

    Use affiliates where independent coverage adds value

    Once you protect the demand your brand should own, redirect affiliate effort toward searches where partners can create new discovery. Comparison pages, category roundups, and best-of lists can put your product in front of buyers who have not chosen a brand yet.

    These placements can serve two channels at once. A relevant partner may drive referral traffic and sales, while repeated mentions across reputable niche content can strengthen the signals that help AI systems recognize and recommend a brand. The goal is not indiscriminate mention volume. Relevance, accuracy, context, and publisher credibility matter.

    Give partners a usable brief rather than asking them to “feature the brand.” Include:

    • The audience and use case your product genuinely fits.
    • Accurate product names, positioning, availability, and limitations.
    • Claims that can be supported and claims they must not make.
    • Comparison topics where an independent evaluation would help a buyer decide.
    • The preferred destination page and approved tracking method.
    • A request to update outdated prices, offers, features, and availability.

    Let publishers keep editorial control. Coverage that reads like copied brand copy is less useful to the reader and less persuasive as independent evidence. Your job is to make accuracy easy, not to manufacture a verdict.

    Keep tracking URLs out of the search index

    Affiliate tracking is necessary for attribution, but tracking variants shouldn’t become alternative search results. Indexed tracking URLs can split visibility across duplicates, expose campaign parameters, and create pages that compete with the destination you actually want people to find.

    Ask SEO and engineering to map every tracking pattern used by the affiliate program. Apply a noindex directive to templates that should never appear in search, and make sure search engines can access the URL long enough to process that directive. Then monitor for newly indexed parameter and redirect URLs instead of waiting for them to appear in a reporting dispute.

    Your recurring check should cover:

    • New indexed URLs containing affiliate or campaign parameters.
    • Tracking links that resolve to errors, expired offers, or irrelevant destinations.
    • Multiple URL versions ranking for the same branded query.
    • Partners linking to a weaker page when a better converting canonical destination exists.
    • Unexpected growth in indexed URL counts after a campaign launch.

    Assign one owner to resolve each issue. SEO can identify indexation and ranking risk, affiliate operations can contact the partner, and engineering can correct the underlying URL behavior.

    Manage both channels with one commercial scorecard

    SEO and affiliate streams feed into one shared measurement console that filters out duplicate spend.

    Traffic and total affiliate revenue aren’t enough to show whether alignment is working. The shared scorecard should reveal where the company gained new demand, where it recaptured existing demand, and where it paid twice for the same customer journey.

    • Branded search ownership: Which priority queries are won by your pages, affiliates, competitors, or coupon sites?
    • Organic commercial performance: How much qualified traffic and revenue reach the brand’s intended landing pages?
    • Affiliate incrementality: Which partners introduce new customers or influence earlier consideration, rather than appearing only at the final click?
    • Commission efficiency: Did commission costs fall on brand-owned demand without reducing total sales?
    • Independent visibility: Is the brand appearing in relevant comparisons and recommendations, and are those descriptions accurate?
    • Technical hygiene: How many tracking URLs were indexed, and how quickly were they removed?

    Review this scorecard with both teams on a fixed cadence. Use the meeting to approve query ownership changes, prioritize pages, choose partner opportunities, and resolve tracking problems. Avoid rewarding one team for a metric that makes the other team’s economics worse.

    Your first move is simple: export your highest-value branded queries, mark who owns each result, and investigate every affiliate ranking above a weak or missing brand page. That gives SEO and affiliate managers a concrete place to start, with revenue and cost attached.

    References

  • Google May 2026 Core Update: A Practical Recovery Plan

    Google May 2026 Core Update: A Practical Recovery Plan

    Your traffic graph dropped during the May core update, and now you need to know whether to rewrite pages, change your SEO strategy, or simply wait. Start by resisting the urge to make sitewide edits. A core update can expose weak content, but it can also coincide with changes in demand, search-result layouts, competitors, or tracking.

    The useful response is a page-level diagnosis. You want to identify where visibility changed, determine what those pages now fail to deliver, and improve them without destroying content that still works.

    Anchor your diagnosis to the actual rollout

    The official rollout ran from May 21 through June 2. Noticeable ranking movement appeared by May 23 and continued into the following week. This was the second core update of 2026, so earlier changes in your reporting may belong to a different event.

    Build clean comparison periods

    In Google Search Console, compare May 7-20 with June 3-16. These are equal 14-day periods immediately before and after the rollout, without mixing rollout days into either side. If your business has strong weekly or seasonal patterns, compare each period with the equivalent days from a normal prior period as a second check.

    Export clicks, impressions, click-through rate, and average position by query and page. A chart of total clicks is not enough. It can tell you that performance changed, but not why.

    Separate ranking losses from other traffic losses

    If positions declined across several important queries for the same pages, investigate relevance, usefulness, and competition. If impressions declined while positions remained broadly stable, check whether search demand or the set of queries triggering those pages changed. If positions and impressions held steady but click-through rate fell, inspect the live results for new answer features, stronger titles, or a changed search intent.

    Also rule out unrelated technical problems. Check whether affected URLs are indexed, canonicalized as intended, crawlable, and returning the correct status code. Review analytics changes, security incidents, migrations, and major template releases. A core-update diagnosis cannot fix a broken canonical or missing tracking tag.

    Find the losses that actually need intervention

    A magnifying glass isolates three webpage tiles connected to abstract signals for demand, competition, search layout, and measurement.

    Sitewide averages hide the decisions you need to make. Group affected URLs by topic, search intent, template, author, and content type. Then calculate the change for each group. A fall concentrated in old comparison pages calls for a different response than a decline across every page using the same template.

    Start with URLs that combine three traits: a material visibility loss, meaningful business value, and a problem you can clearly describe. Do not prioritize a page merely because its percentage decline looks dramatic. A page that fell from ten impressions to two is usually less urgent than one that lost a large share of qualified visits.

    Inspect the queries that disappeared

    For each priority URL, compare its pre-update and later query sets. Ask whether it lost its main query, a cluster of secondary questions, or visibility for terms that never matched its real purpose. Losing poorly matched impressions may not require a repair. Losing the queries that express the page’s central promise does.

    Search those important queries manually and examine the pages now appearing above yours. Look for differences in intent, scope, specificity, first-hand evidence, freshness, and format. The goal is not to copy competitors. It is to understand what searchers can accomplish with the current results that they cannot accomplish with yours.

    Look for patterns across winners and losers

    Your unaffected and improving pages are useful controls. Compare them with declining pages from the same site. If both groups share the same design, author box, and schema, those elements are less likely to explain the difference. If losses cluster around thin location pages, outdated tutorials, or articles built from the same generic outline, you have a stronger hypothesis to test.

    Audit for satisfaction, not an imaginary update factor

    The update was intended to favor relevant and satisfying content. That direction is more useful than hunting for a new word-count target, schema type, or keyword-density rule. Google has not provided a single prescribed fix for pages that lost visibility.

    Test whether the page fulfills its promise

    Read the title, opening, and major headings without relying on your memory of the page. They should define one clear task or question. Then check whether a reader can complete that task without returning to search for missing steps, definitions, evidence, or limitations.

    Remove introductions that delay the answer. Put the central answer or decision criteria near the relevant heading, then support it with explanation. If the query requires a procedure, make the sequence explicit. If it requires a choice, explain who each option suits and what changes the decision.

    Add value that another generic page cannot reproduce

    A rewrite that merely changes wording preserves the original weakness. Add the missing substance: a worked example, a transparent method, a limitation, an expert interpretation, a screenshot that proves a step, or an explanation of what happens when the standard advice fails. Keep only material that helps the reader act or decide.

    For factual or high-consequence claims, make the basis visible. Identify the responsible organization or expert where that identity matters. Link to supporting material you actually used. Show when the page was reviewed, and update that date only after a meaningful review. An unexplained assertion does not become trustworthy because it sounds confident.

    Check ownership, duplication, and internal competition

    Decide which URL should own each core intent. Several pages targeting the same question can divide internal links and leave each version incomplete. Consolidate genuine duplicates when one stronger destination can serve the reader. Keep separate pages when the intents, audiences, or required answers are materially different.

    Update internal links so descriptive anchor text points to the intended owner. Make sure related pages support one another instead of repeating the same opening-level information. Do not delete a large group of URLs solely because traffic fell during the rollout; first determine whether each page has a distinct, supportable purpose.

    Improve search and AI visibility without conflating them

    A Google core update and visibility inside frontier language models are not the same measurement system. A decline in Google rankings does not prove that ChatGPT, Claude, or another answer engine stopped citing you for the same reason. Track conventional search performance and AI citations separately, even when the same content improvements may benefit both.

    For answer-oriented visibility, make important facts easy to locate and interpret. Use descriptive headings, answer the stated question directly, name entities consistently, and keep qualifications beside the claim they modify. Tables should represent real comparisons, while lists should represent genuine steps or criteria. Formatting cannot compensate for an unsupported answer, but it can make a strong answer easier to extract correctly.

    Apply JSON-LD only when it accurately describes visible content and the page’s real entity relationships. Schema is packaging, not evidence. Adding more markup will not repair stale facts, unclear authorship, duplicated intent, or an answer that misses the query.

    Measure AI visibility with a stable set of prompts tied to your customers’ questions. Record whether your brand is mentioned, cited, represented accurately, or omitted. Keep that record beside, but not merged into, your Search Console analysis. This prevents a gain in one channel from concealing a loss in another.

    Make controlled changes and preserve what you learn

    Two parallel sets of webpage cards show one controlled change while the original version remains preserved for comparison.

    Create a change log for every priority URL. Record the date, the affected query or intent, your diagnosis, and the substantive edits. That turns recovery work into a testable process. Without a log, several teams can modify the same page and leave you unable to connect later movement with a plausible cause.

    Work in related batches rather than changing the entire site at once. Start with a small group that shares a documented weakness. Recheck query-level performance after those pages have accumulated enough impressions for a meaningful comparison. Keep the changes if the intended queries recover without harming conversions or accuracy; revise the hypothesis if they do not.

    Do not judge success only by restored clicks. A revised page may attract fewer but better-matched visits. Review conversions, qualified leads, engaged visits, and the queries now associated with the page. The objective is durable visibility for the right need, not the recreation of every impression that existed before May 21.

    Key takeaways

    • Use May 21 through June 2 as the rollout window, and keep those dates out of your before-and-after comparison periods.
    • Diagnose changes by page and query; total traffic alone cannot distinguish ranking, demand, click-through, and technical problems.
    • Prioritize valuable pages with a clear loss and a specific weakness instead of rewriting the whole site.
    • Improve intent match, distinct value, evidence, ownership, and internal linking before reaching for more schema.
    • Measure Google rankings and AI-answer visibility separately, with a written change log for both.

    Your next move is simple: export the two 14-day comparison periods, select the five affected URLs with the greatest business value, and write one testable diagnosis for each. Make only the changes that diagnosis supports. That gives you a recovery plan you can measure instead of a collection of update myths.

    References

  • AI-Ready SEO Strategy: A Practical Visibility Framework

    AI-Ready SEO Strategy: A Practical Visibility Framework

    If your pages rank in search but rarely appear in AI-generated answers, adding a few schema fields won’t solve the whole problem. AI visibility depends on whether a system can find your answer, understand what it means, judge it worth referencing, and connect it to a credible brand.

    You need an operating system for those four jobs. The framework below connects query selection, brand context, citation-worthy content, structured data, and measurement so you can improve AI readiness without abandoning the SEO work that already drives traffic and revenue.

    Choose the answers your business needs to own

    “Get mentioned by AI” is too vague to guide a content team. Start with the questions that matter during a real buying journey. A software company might need to appear when someone compares approaches, checks compatibility, evaluates risk, or looks for implementation help. A local business may care more about suitability, location, availability, and service details.

    Create a query-to-page map before you create new pages. For every priority question, record:

    • The exact decision the searcher is trying to make.
    • The audience and level of knowledge behind the question.
    • The page that should provide the best answer.
    • The facts, examples, or evidence that would make that answer credible.
    • The next action you want a qualified visitor to take.
    • Whether the answer is already complete, partly covered, or missing.

    This exercise exposes a common failure: several pages loosely target the same subject, but none gives a self-contained answer. Consolidate overlapping pages when they serve the same intent. Keep separate pages when the reader, decision, or required evidence is materially different.

    Write the direct answer early on the chosen page. Then support it with definitions, constraints, evidence, alternatives, and next steps. A reader should be able to extract a useful answer without interpreting marketing language, while someone making a serious decision should have enough depth to keep reading.

    Give your team and its AI tools durable brand context

    Geometric AI devices connect to one organized central library of product objects, documents, profiles, and evidence folders.

    AI-assisted SEO drifts when each task begins with a fresh prompt. The tool doesn’t know which audience matters most, which claims require caution, why an old keyword was rejected, or what your CMS can actually support. Team handoffs create the same problem when important decisions live in someone’s memory.

    A compact, shared account knowledge base can preserve that context. Separate stable brand rules from changing operational knowledge so people and AI systems can retrieve the right information without treating every old note as permanent policy.

    Record the stable rules

    Your stable layer should cover five things in plain language:

    • Company profile: what you sell, where you operate, and what makes the business meaningfully different.
    • Audience: who you help, what they already understand, and what makes them hesitate.
    • Style: voice, terminology, claim standards, and examples of acceptable writing.
    • Keyword and topic map: priority subjects, intended pages, and known overlaps.
    • Never-do rules: prohibited claims, unwanted angles, legal constraints, and tactics the brand has rejected.

    Record decisions and outcomes separately

    Your changing layer should capture what was decided, why it was decided, what happened afterward, and what evidence supports the entry. Include campaign outcomes, recurring editorial feedback, technical limitations, experiments, and unresolved questions. Add dates and owners so an old constraint isn’t mistaken for a current one.

    You can create a useful first version in a focused 90-minute working session with the people who know the account best. Keep the format simple. Plain-text files in a shared, controlled location are enough to begin. Assign an owner to approve stable-rule changes, while making it easy for the wider team to add new observations to the changing layer.

    Require every AI-assisted brief, draft, optimization, and analysis to load the relevant context first. Small teams can load the whole knowledge base. Larger teams can route only the files needed for a task. In either case, a person remains responsible for checking factual accuracy, current policy, and strategic fit.

    Publish assets that other people would choose to cite

    Clear answers make a page extractable. They don’t automatically make it authoritative. Search engines and AI systems still need reasons to distinguish your page from dozens of competent alternatives.

    Build link intent into the brief. Before drafting, ask who would reference the finished work and what they would gain by doing so. Links and references continue to support authority and discovery, but outreach works best when the page supplies something genuinely useful to the recipient’s audience.

    A citation-worthy asset usually contains at least one element that isn’t easy to replace:

    • A clear method that lets someone repeat a process.
    • A comparison built around explicit, defensible criteria.
    • First-party observations or data with enough methodology to evaluate them.
    • A practical framework that simplifies a difficult decision.
    • A maintained reference page that resolves a recurring question.
    • A timely interpretation that adds useful context rather than repeating news.

    Specificity is the test. “Improve your content” gives nobody a reason to cite you. A documented audit process, decision tree, calculation method, or constraint-based recommendation can become a working reference.

    Plan distribution only after the asset passes that test. Identify journalists, practitioners, publishers, partners, and community leaders who already cover the problem. Explain which part of the asset helps their audience. Don’t lead with a link request, a quota, or a swap. Lead with the useful finding, framework, or resource.

    Track more than the number of backlinks. Review which pages earned references, the relevance of the referring sites, referral visits, qualified conversions, and whether the asset prompted branded searches or further coverage. Those signals tell you what your market considers worth repeating.

    Make page meaning explicit with structured data

    An unlabeled web page separates into connected semantic objects that are recognized through a glowing AI lens.

    Once a page deserves to be found, reduce the effort required to interpret it. Structured data gives machines explicit labels for entities, attributes, and relationships that might otherwise be buried in layout and prose. That matters as search systems move from displaying links toward answering questions and completing tasks.

    Google and Bing can use structured data in search experiences, while AI systems can use explicit fields to evaluate relevance and actionability. Clean markup also makes a page less costly to interpret than relying entirely on unstructured HTML. This is why schema is becoming part of the infrastructure for agentic discovery.

    Treat schema as a site-wide knowledge graph, not a collection of isolated rich-result tricks. Use this implementation sequence:

    1. Inventory the entities. Identify the organizations, people, products, services, places, events, and resources that your pages describe.
    2. Establish canonical pages. Decide which URL is the primary description of each important entity or concept.
    3. Select appropriate schema types and properties. Mark up what the page actually contains, not what you wish it contained.
    4. Implement JSON-LD consistently. Use templates for repeatable page types while preserving page-specific facts.
    5. Connect relationships. Link an author to their profile, an offering to its provider, and related entities to their canonical identifiers.
    6. Validate against visible content. Every material claim in the markup should agree with what a visitor can read on the page.
    7. Monitor templates after changes. A CMS or design release can quietly remove fields, duplicate entities, or leave stale values across many URLs.

    Completeness matters more than decorative volume. Populate relevant properties with accurate values, but don’t add unsupported ratings, prices, authors, FAQs, or availability. Schema clarifies evidence; it doesn’t create evidence and can’t guarantee that an AI system will cite the page.

    Also check that the human-readable page provides the details an agent would need to act. If a service page never states eligibility, location, limitations, or the next step, structured data cannot repair the missing information. Improve the page first, then encode its meaning.

    Measure AI readiness as a learning system

    A single AI visibility score won’t tell you what to fix. Review performance by question, page, and business outcome. Run a repeatable set of representative prompts, record whether your brand appears, note which page or competitor is cited, and compare the response with your intended positioning. Because generated answers can vary, look for recurring patterns rather than treating one response as a verdict.

    Pair those observations with conventional evidence: crawl and indexation status, organic queries, referring domains, referral traffic, assisted conversions, and leads or sales. Diagnose the weakest link in the chain:

    • Not discovered: improve crawlability, internal linking, and distribution.
    • Discovered but misunderstood: clarify the answer, entities, terminology, and schema.
    • Understood but not selected: strengthen evidence, differentiation, references, and brand authority.
    • Selected but not converting: align the cited answer with a useful landing experience and next action.

    Record each meaningful change and its result in the changing layer of your knowledge base. That prevents the team from repeating failed ideas and gives future AI-assisted work the context needed to build on what you learned.

    Key takeaways

    • Map commercially useful questions to one clear, complete answer page.
    • Give people and AI tools a maintained record of brand rules, decisions, constraints, and outcomes.
    • Create resources with a specific reason for credible people to link to or cite them.
    • Use accurate JSON-LD to express entities and relationships already supported by visible content.
    • Measure discovery, interpretation, selection, and conversion separately so you know what to improve.

    Start with one high-value question this cycle. Improve its answer, document the relevant brand context, add defensible schema, and put the finished resource in front of people who genuinely need it. That small end-to-end test will teach you more than rolling out disconnected AI SEO tactics across the whole site.

    References

  • SEO in the AI Era: What Changes and What Still Works

    SEO in the AI Era: What Changes and What Still Works

    If you’re wondering whether AI makes your SEO program obsolete, the useful answer is no. It changes where discovery happens, how answers are assembled, and what success looks like. It doesn’t remove the need for accessible pages, clear information, credible evidence, or a recognizable brand.

    Your job is expanding. You still need to help a page rank, but you also need to make its information easy for an answer engine to retrieve, interpret, trust, and represent accurately.

    Key takeaways

    • SEO is evolving from ranking pages alone to making a brand and its knowledge retrievable across search and AI interfaces.
    • Technical access, search intent, useful content, internal links, and authority remain the foundation.
    • AI optimization adds clearer answer structure, stronger entity signals, supported claims, and structured data that matches visible content.
    • Clicks are no longer a complete scorecard. Track visibility, citations, brand representation, qualified visits, and conversions together.
    • Start with one commercially relevant topic cluster and improve the full path from question to evidence to action.

    SEO has changed before, but the target is broader now

    Early search optimization often focused on exploiting visible ranking signals. Practices such as keyword stuffing and cloaking could influence engines that were easier to manipulate. The landscape included names such as Excite, AltaVista, and Northern Light, and much of the discipline was learned through experimentation and informal community knowledge.

    That model became less dependable as search systems improved. Panda and Penguin became major milestones because they forced site owners to confront content quality and manipulative promotion. The durable lesson wasn’t that optimization had stopped working. It was that tactics built around weaknesses in a system had a shorter life than work built around users.

    AI is another shift in the interface, but it is not a clean break from search. A conventional results page gives a user several candidates to evaluate. A generative interface can combine information into a response before the user visits a website. Your page may influence that response, earn a citation, receive a click, or remain invisible even when it ranks well elsewhere.

    This widens the optimization target. You are no longer working only for a blue-link position. You are working to become a reliable candidate whenever a system needs information about your topic, product, organization, or expertise.

    What remains essential and what AI adds

    A shared foundation connects organized web content on one side with AI retrieval and answer assembly on the other.

    It helps to separate enduring SEO work from the additional demands of answer-driven discovery. If the foundation is weak, adding schema or rewriting a few headings won’t rescue it.

    AreaEnduring SEO requirementAdditional AI-era requirement
    AccessPages must be crawlable, indexable, and internally connected.Important facts must be available in readable page content rather than hidden behind an interaction.
    IntentA page should satisfy the reason behind a query.It should also answer the follow-up questions a synthesized response is likely to combine.
    ContentInformation should be useful, original, and easy to navigate.Definitions, distinctions, conditions, and conclusions should be explicit enough to extract without losing context.
    AuthorityRelevant links, reputation, and subject expertise support trust.Consistent entity information and independent corroboration help systems identify who you are and why your claims matter.
    Structured dataValid markup can clarify page type and important attributes.Connected, accurate entities can reduce ambiguity, but markup must agree with what a visitor can see.
    MeasurementRankings, impressions, clicks, engagement, and conversions show search performance.Answer inclusion, citations, brand mentions, representation accuracy, and assisted discovery provide additional signals.

    Do not treat the right-hand column as a replacement checklist. It is an extension of the left-hand column. A fast, well-linked, authoritative page with a precise answer is useful in either environment.

    Build an AI-ready SEO workflow around real questions

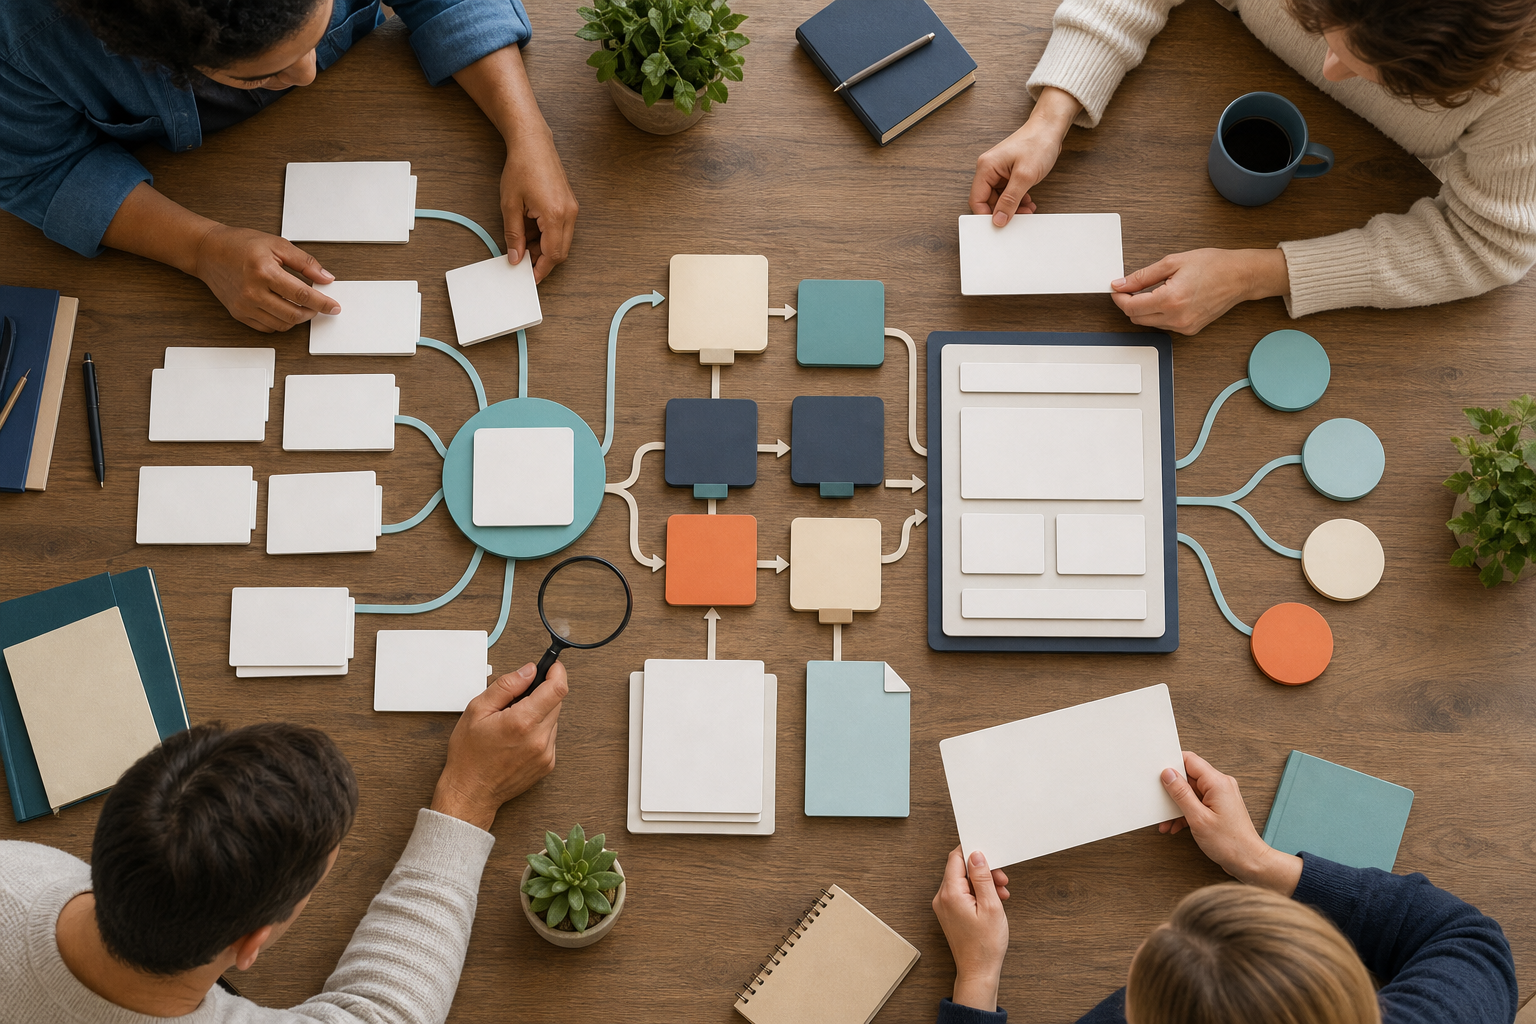
    A team organizes blank question cards, content modules, and source documents into a connected publishing workflow.

    You don’t need to rebuild your entire site at once. Choose a topic connected to revenue, retention, or a recurring customer problem, then work through the following sequence.

    1. Collect the language your audience uses. Pull questions from sales calls, support conversations, on-site search, keyword data, and Search Console. Group them by discovery, comparison, decision, and post-purchase intent. This prevents you from creating a disconnected page for every wording variation.
    2. Choose one primary page for the topic. Decide which URL should carry the clearest, most complete answer. Merge overlapping material where it creates confusion, and use supporting pages only when a subtopic deserves separate treatment.
    3. Put the answer before the expansion. State the central answer near the beginning. Then explain conditions, exceptions, evidence, examples, and next steps. A reader should not have to cross several promotional paragraphs to learn whether the page addresses the question.
    4. Make important relationships explicit. Use consistent names for your company, products, services, people, and locations. Connect relevant author biographies, About information, policy pages, and supporting resources with descriptive internal links. Do not expect a machine to infer that two inconsistent labels refer to the same entity.
    5. Add only defensible structured data. Select schema types that describe the visible page. Keep names, authorship, dates, offers, and organizational details aligned with the content. Validate the syntax, but also inspect whether the markup tells the truth. Technical validity does not correct a false or unsupported claim.
    6. Strengthen the evidence layer. Replace vague assertions with demonstrations, documented methods, primary references, or clearly attributed expertise. Seek relevant third-party mentions because a claim repeated only across your own pages is not independent confirmation.
    7. Design the next action. Match the call to action to the question’s stage. An educational query may need a related explainer or checklist. A comparison query may need specifications, constraints, or pricing context. A decision query may justify a demo, trial, purchase, or contact option.

    Review the finished page as if its paragraphs might be separated from the layout. Check whether a definition still makes sense without the heading above it, whether a recommendation names its conditions, and whether a quoted fact remains connected to its evidence. This is good editing for people and useful preparation for machine retrieval.

    Measure visibility without mistaking mentions for results

    AI answers can change the relationship between visibility and traffic. A user may learn your name without clicking, or an assistant may cite your page while sending few visits. The opposite can also happen: a small amount of highly qualified traffic can produce meaningful business results.

    Use a scorecard with four layers:

    • Search presence: impressions, relevant rankings, indexed URLs, click-through behavior, and the mix of branded and non-branded discovery.
    • AI presence: whether your brand appears for a stable set of important questions, whether it receives a citation, and whether the description is accurate.
    • On-site behavior: landing-page engagement, progression to another useful page, leads, sales, subscriptions, or other outcomes tied to the page’s purpose.
    • Business quality: lead relevance, conversion value, sales feedback, and the customer questions that remain unanswered.

    Treat AI visibility checks as sampled observations, not permanent rankings. Responses can vary with phrasing and context. Keep a consistent set of questions, record the wording you used, and compare patterns over time. A single favorable response is not a strategy, and a citation that misrepresents your company is not a clean win.

    Start with the strongest page in one valuable topic cluster. Clarify its answer, repair its evidence and entity signals, align its structured data, and give the reader a sensible next step. That work improves your odds across traditional search and emerging answer interfaces without betting your entire program on one platform.

    References

  • How to Make Your Content Visible in Agentic AI Search

    How to Make Your Content Visible in Agentic AI Search

    Your pages rank, your facts are accurate, and your technical SEO is sound. Yet ChatGPT Search or Google AI Mode still cites a competitor. The missing piece may be how well your content survives the steps between a user’s question and an AI-generated answer.

    AI search is no longer a simple contest to appear in one set of retrieved results. You need content that can support several related searches, answer at passage level, connect entities, and remain credible when a system checks its own work.

    AI search now investigates before it answers

    Classic retrieval-augmented generation, or RAG, followed a mostly linear path: interpret a query, retrieve relevant passages, and generate an answer. Visibility depended heavily on making the initial retrieval set.

    Agentic RAG adds a decision-making loop. A system can break the original request into smaller questions, choose different tools, retrieve more evidence, evaluate what it found, and repeat the process. Some workflows can involve up to twenty sub-retrievals before the answer is finalized.

    Four capabilities shape that process:

    • Planning: turning the user’s request into a sequence of sub-questions and deciding how to investigate them.
    • Tool use: selecting web search, APIs, code execution, databases, or other available methods for each step.
    • Iteration: retrieving additional material when the first pass leaves gaps or creates new questions.
    • Reflection: checking whether the collected evidence is sufficient, consistent, and diverse enough to support an answer.

    This changes the visibility problem. Your page might not answer the user’s original wording directly, but it can still become useful during a sub-query. The reverse is also true: ranking for the broad query won’t guarantee inclusion if your page can’t support the narrower checks that follow.

    Map the questions hidden inside the main query

    A glass orb branches into connected smaller orbs containing symbols for research, documents, time, location, relationships, and comparison.

    Start with a real decision your audience needs to make. Then model the investigation an AI system may perform around it. A person asking how to choose an AI visibility platform may also need definitions, evaluation criteria, integration requirements, pricing logic, limitations, and measurement methods.

    Build a sub-query map before revising the page:

    1. Write the primary question in the reader’s own language.
    2. List the facts required to answer it without making assumptions.
    3. Add the likely comparison, verification, and follow-up questions.
    4. Mark which questions your page answers completely, partially, or not at all.
    5. Expand only where the added material serves the same reader and decision.

    Don’t turn one page into an encyclopedia. If a sub-question has a different intent, give it a dedicated page and link the two with descriptive anchor text. The goal is a connected body of coverage, not a single bloated URL.

    Pay particular attention to bridge entities: the products, standards, organizations, methods, and concepts that connect one part of the investigation to another. Name them precisely and explain the relationship. A sentence such as “Platform A exports citation records to BigQuery for longitudinal analysis” carries more usable connections than three separate paragraphs that mention the platform, export feature, and database without relating them.

    Engineer passages that can stand on their own

    Retrieval often operates on passages rather than entire pages. Each important section therefore needs enough context to remain useful when separated from the surrounding copy.

    Audit a passage with five questions:

    • Does the heading name the exact question or decision?
    • Does the opening sentence answer it directly?
    • Are important entities named instead of replaced with “it,” “they,” or “this tool”?
    • Are conditions, limitations, and exceptions close to the claim they qualify?
    • Could someone understand the passage without reading the introduction?

    A strong passage usually starts with the answer, then supplies the reasoning, evidence, and boundary conditions. That structure helps both hurried readers and retrieval systems. It also prevents a qualified claim from being extracted without the sentence that explains when it applies.

    Use lists for steps, tables for genuine comparisons, and descriptive headings for navigation. Add relevant structured data when it accurately represents visible page content, but don’t treat schema markup as a substitute for clear writing. Machines still need an accessible, coherent answer in the page itself.

    Make facts easy to verify and retrieve

    A hovering scanner examines one illuminated modular information block connected to organized evidence objects in the background.

    An agent may return to a page, compare it with other evidence, or use a tool to inspect supporting data. Reduce friction at each of those points.

    • Expose important information in HTML. Don’t hide the only useful answer inside an image, video, or interaction that requires several clicks.
    • Use stable names and units. Keep product names, feature labels, dates, and measurements consistent across copy, tables, metadata, feeds, and documentation.
    • Show how claims are supported. Link factual assertions to the most direct available evidence and keep qualifications beside the claim.
    • Offer structured access where it serves users. Accurate feeds, APIs, downloadable data, and well-formed markup can make changing information easier for tools to inspect.
    • Remove conflicting leftovers. Old pricing, renamed features, duplicate definitions, and stale comparison pages create ambiguity during verification.

    Freshness is not a decorative “updated” date. Review the claims that can change, correct the visible copy, update any structured representation, and record a meaningful revision date. If a page remains accurate, don’t rewrite it merely to make it look new.

    Measure coverage across the retrieval journey

    A single prompt check can’t tell you whether your strategy works. Agentic systems can take different routes through the same topic, and only the final answer is visible. You need a repeatable prompt set that represents the routes most likely to matter.

    Create a small measurement sheet with one row per prompt. Include the main question, comparison prompts, verification questions, follow-ups, and adjacent sub-queries from your map. For every check, record:

    • whether your brand or page appeared;
    • whether it received a citation or an unlinked mention;
    • which URL and passage were used;
    • what claim the answer attributed to you;
    • which competing pages appeared;
    • whether the answer was accurate, incomplete, or misleading.

    Run the same set after material content changes. Look for patterns rather than celebrating one citation. If you appear for definitions but disappear from comparison prompts, your weakness is probably decision support. If you appear for a broad prompt but not its verification questions, strengthen the evidence and qualifications around the relevant claims.

    Conventional analytics still matters, but referral traffic alone is incomplete. AI visibility can influence a decision without producing a click. Combine citation tracking with branded search, qualified conversions, sales conversations, and the accuracy of how your brand is represented.

    Key takeaways

    • Optimize for the sub-questions an AI system may investigate, not only the user’s opening query.
    • Give each important passage a clear heading, direct answer, named entities, and nearby qualifications.
    • Connect related concepts explicitly so your content can support multi-step retrieval.
    • Keep visible copy, structured data, feeds, and documentation consistent and current.
    • Measure citations and representation across a stable set of task-shaped prompts.

    Choose one commercially important topic this week. Map its hidden questions, repair the weakest passages, and establish a baseline prompt set before you publish changes. That gives you a practical starting point for improving visibility even when the retrieval path itself remains hidden.

    References