Tag: Business Strategy

  • How to Delegate Work to AI Without Giving Up Judgment

    How to Delegate Work to AI Without Giving Up Judgment

    AI may already be drafting your client updates, interpreting search data, prioritizing content ideas, and recommending what to do next. The risk isn’t frequent use. It’s failing to notice when the assistant moves from handling work to deciding what matters.

    You don’t need to pull AI out of the workflow. You need a visible boundary between assistance and authority. The framework below will help you set that boundary, supply the context a model cannot discover on its own, and keep a named person accountable for every consequential decision.

    Define authority before you automate the workflow

    Assistant adoption is no longer limited to occasional drafting. By August 2026, one weighted model estimated that Claude had 271.3 million monthly active users and 148.2 million weekly active users. Business strategy and operations represented 8.7% of sampled consumer conversations, excluding Claude Code sessions. Those estimates come from a third-party model, so they shouldn’t be treated as audited platform disclosures. They still illustrate the operational shift: people are bringing assistants into recurring work, not merely testing them.

    That makes the number of AI users a weak governance metric. What matters is the authority those users give the system. A team that uses AI every day to organize material may carry less risk than a team that uses it once a month to approve a budget, publish an unsupported claim, or change a production website.

    Classify each workflow by the decision right being delegated:

    LevelWhat the assistant doesWhat a person still owns
    PrepareFormats, summarizes, restructures, or drafts from supplied materialChecks accuracy, meaning, tone, and omissions
    AnalyzeCalculates changes, groups data, detects patterns, or surfaces anomaliesValidates definitions, measurement quality, segmentation, and business relevance
    RecommendProposes or ranks options against stated criteriaTests assumptions, adds missing context, compares alternatives, and selects the action
    DecideSelects an option within a clearly bounded policySets the policy, exceptions, limits, escalation rules, and accountability
    ActExecutes an approved or pre-authorized changeControls permissions, monitors results, preserves a log, and can reverse the change

    Most teams can delegate preparation broadly. Analysis needs better controls because bad definitions can produce correct calculations with misleading meaning. Recommendations need explicit criteria. Decisions and actions require the strongest limits because they can create financial, technical, reputational, or client consequences.

    For an SEO or GEO team, an assistant might cluster queries, extract recurring questions, compare page structures, or draft candidate JSON-LD. It should not silently choose the business’s priority audience, turn uncertain evidence into a factual claim, or publish structured data that misrepresents the visible page. A person must own those choices.

    Write one authority sentence for every recurring AI workflow: AI may perform this task using these inputs, but this role approves this decision before this action occurs. Add the conditions that require escalation and the method for reversing an action. If you can’t complete that sentence clearly, the workflow isn’t ready for autonomous execution.

    Give the assistant a decision brief, not just an export
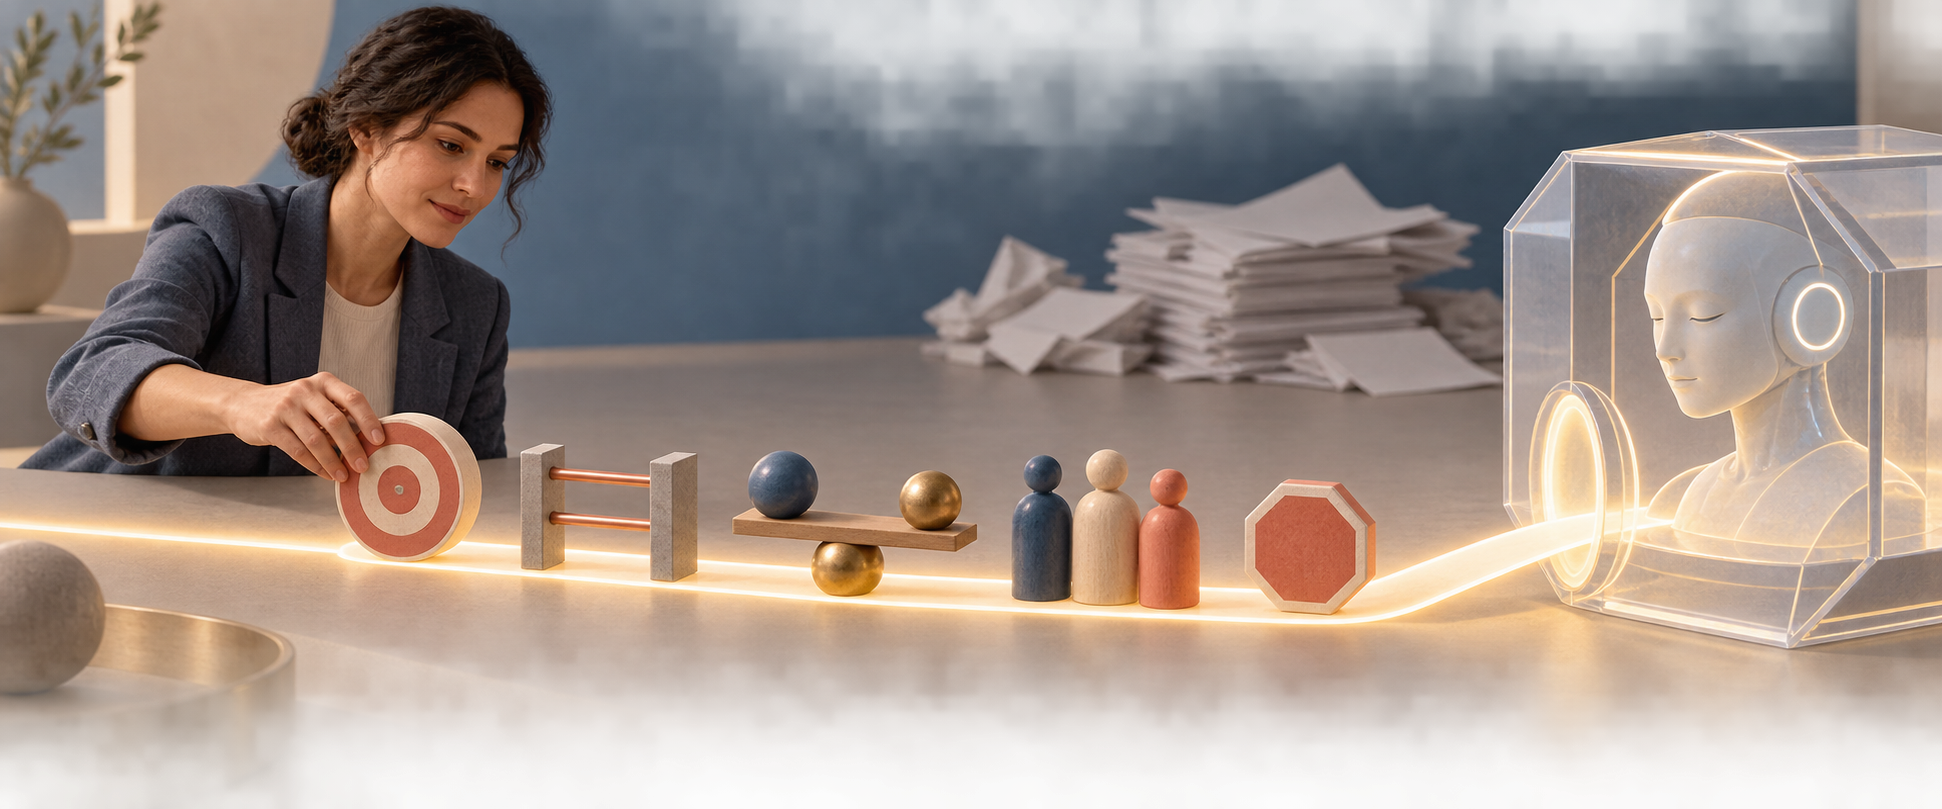
    A manager arranges symbols for goals, constraints, tradeoffs, stakeholders, and escalation before sending them into an abstract AI device.

    Uploading data does not upload the business that produced it. Search Console can show queries, pages, clicks, impressions, and positions. Analytics can show recorded sessions and conversions. Neither automatically explains that a promotion ended, a price changed, a key product went out of stock, a form broke, a consent configuration changed, margins moved, or the sales team altered its follow-up process.

    This is why accurate data can still support the wrong recommendation. The system may describe its input correctly while missing the event that determines what the business should do.

    Before asking an assistant to recommend an action, give it a compact decision brief containing:

    • The decision: State the choice that must be made. Replace a broad request such as analyze performance with a decision such as determine whether to expand, repair, consolidate, or pause this content program.
    • The business outcome: Name what success actually means: qualified leads, profitable sales, renewals, booked appointments, adoption, or another commercial result. Traffic is not a substitute unless traffic itself is the goal.
    • The metric definitions: Explain what counts as a lead, conversion, branded query, priority page, new customer, or qualified opportunity. Include known measurement gaps.
    • The relevant segments: Separate branded from non-branded demand, informational from commercial intent, priority services from peripheral topics, and new performance from recurring demand where those distinctions affect the choice.
    • The business events: Record launches, stock constraints, pricing changes, promotions, sales-process changes, site releases, tracking changes, and market events that overlap the period.
    • The constraints: Identify budget, capacity, compliance, brand, technical, contractual, and timing limits. A recommendation that ignores a real constraint is not actionable.
    • The missing evidence: Say what the model cannot see and who can supply it. This might require input from sales, customer service, product, finance, engineering, or the client.
    • The decision owner: Name the person who will evaluate the recommendation and accept responsibility for the final choice.

    Consider rising impressions with flat clicks. A surface-level reading might celebrate wider visibility. Segmenting the change may reveal that broad informational queries produced the extra impressions while clicks to commercially important services declined. The top-line observation remains true, but its meaning changes. Before approving more content, inspect query intent, landing pages, priority topics, click behavior, and downstream outcomes separately.

    Apply the same discipline when reported organic sessions fall. Verify whether tracking, consent, form behavior, or analytics configuration changed before treating the decline as lost demand. Otherwise, you may authorize a content overhaul to fix a measurement problem.

    Require the assistant to divide its response into four parts: observations, inferences, recommendations, and unknowns. Observations should stay close to the supplied evidence. Inferences should expose their assumptions. Recommendations should identify the criteria used. Unknowns should state what could materially change the answer. This format won’t guarantee a good decision, but it makes weak reasoning easier to challenge.

    For AI-search and structured-data work, include a factual source map in the brief. Connect each proposed answer, entity attribute, credential, product detail, price, review claim, and schema property to an approved page or business record. If the supporting fact is absent, the model may flag the gap; it may not fill it with a plausible invention.

    Use AI to shorten communication, not distance people

    A simple message can become a long, polished email when the sender asks an assistant to make it sound professional. The recipient then asks another assistant to summarize it and draft a reply. The machines expand, compress, and expand the message while both people search for the actual request.

    That loop adds more than wasted words. Repeated transformation can weaken hesitation, exaggerate urgency, or convert a tentative suggestion into something that reads like a commitment. Tone and intent can degrade as a message is generated, summarized, and generated again.

    Set communication rules around the human outcome:

    • Start with the point. Put the answer, request, decision, or risk in the first sentence. Context belongs after it.
    • Preserve uncertainty. If the sender is unsure, the message must remain unsure. Do not let polished language manufacture confidence.
    • Keep commitments explicit. State who is doing what and when. Do not allow the assistant to infer agreement from a vague discussion.
    • Delete decorative expansion. Professional writing is clear and proportionate. A one-sentence answer should remain one sentence when no further context is needed.
    • Make the sender approve meaning. Reviewing grammar is not enough. The sender must confirm that the message reflects the intended position and requested action.
    • Switch channels when needed. Use a direct conversation when the issue is sensitive, disputed, ambiguous, or likely to produce follow-up questions. Summarize the resulting decision afterward.

    Client reporting needs particular care. A generated update can describe movement without explaining whether that movement matters. It also cannot notice an unexpected comment, ask why lead quality changed, or recognize that a neat recommendation conflicts with the client’s operations unless someone supplies that context.

    A useful client update separates five things: what changed, what it may mean, what is still unknown, what the team will verify, and what decision or action is required. That structure prevents a polished narrative from disguising uncertainty. It also gives the client obvious places to add information that isn’t present in the reporting system.

    The same rule applies to public content. AI can help reorganize an explanation, draft an FAQ, or format JSON-LD, but the brand must own the position and every factual assertion. Validate machine-generated structured data against the visible page and authoritative business records before publication. Never allow an assistant to invent reviews, prices, availability, credentials, authorship, or other claims simply because the markup expects a value.

    Match review gates to consequences and measure decision quality
    Three AI-assisted workflow paths show routine items passing automatically, one item receiving a quick human check, and a consequential item undergoing joint review.

    Human review is not one generic approval step. The gate should depend on consequence, reversibility, observability, and uncertainty.

    • Low-consequence work: Allow automatic handling when errors are easy to see, easy to reverse, and limited in impact. Formatting internal notes is different from changing a live canonical tag.
    • Moderate-consequence work: Queue the output for review when it influences priorities, client interpretation, or published content but has not yet committed resources or changed production systems.
    • High-consequence work: Require named approval before spending money, making a client commitment, publishing a material claim, changing permissions, handling customer data, or applying a broad technical change. Preserve a tested rollback path where reversal is possible.

    Every consequential recommendation should leave a short decision record. Capture the input set, known context, assumptions, recommendation, material alternative, approver, action taken, and result. This is not bureaucracy for its own sake. Without a record, you cannot tell whether a poor outcome came from missing data, weak reasoning, a bad instruction, an execution error, or a reasonable decision under uncertainty.

    Measure the quality of delegation rather than celebrating output volume. Useful operating measures include:

    • Context-correction rate: How often did the recommendation materially change after operational context was added?
    • Unsupported-assumption rate: How often did the assistant rely on a claim, definition, relationship, or constraint that the input did not establish?
    • Human override pattern: Which recommendations were changed, and why? Group overrides by missing context, risk, strategy, factual error, or stakeholder knowledge instead of treating every override as model failure.
    • Reversal rate: How often did the team need to undo an AI-influenced action? Record the consequence as well as the count.
    • Outcome fit: Did the action improve the business outcome named in the decision brief, or only an intermediate metric that was easier to measure?
    • Communication rework: How often did recipients need clarification because the generated message hid the request, distorted uncertainty, or implied an unintended commitment?

    A low human-override rate is not automatically a success. It may indicate strong recommendations, passive reviewers, or an organization that has stopped challenging the system. Review the reasons, outcomes, and consequences together.

    Audit a fixed sample of routine decisions at a regular cadence, not only the failures that become visible. Escalate whenever important data is missing, evidence conflicts, the recommendation depends on unstated business conditions, the action cannot be reversed safely, or nobody is clearly willing to own the outcome.

    Key takeaways

    • Govern AI by the authority it receives, not by how often employees use it.
    • Let assistants prepare and analyze broadly, but require explicit criteria and accountable ownership before recommendations become decisions.
    • Supply commercial goals, metric definitions, operational events, constraints, missing evidence, and a decision owner with every consequential request.
    • Separate observations, inferences, recommendations, and unknowns so confidence cannot conceal a weak evidence chain.
    • Use AI to make human communication shorter and clearer. Do not let generated polish alter uncertainty, urgency, or commitment.
    • Measure context corrections, unsupported assumptions, reversals, communication rework, and business outcomes rather than generated output.

    Choose one recurring AI-assisted workflow this week. Write its authority sentence, create its decision brief, set the review gate, and record the next outcome. Expand delegation only after that workflow shows that people can see the assumptions, challenge the recommendation, reverse the action, and identify who owns the result.

    References


  • Fractional SEO Leadership: When It Fits and How to Hire

    Fractional SEO Leadership: When It Fits and How to Hire

    Your SEO agency delivers recommendations, your content team publishes, and engineering handles requests when capacity opens up. Yet nobody can give a defensible answer when leadership asks what should happen next, what can wait, or how search visibility connects to growth.

    That is the problem fractional SEO leadership is built to solve. You are not renting another pair of hands. You are giving an experienced search leader a defined mandate to set priorities, coordinate teams, and make the work commercially coherent without immediately adding a full-time executive.

    Key takeaways

    • Hire a fractional SEO leader when you already have people who can execute but lack one senior owner for priorities, tradeoffs, and cross-functional coordination.
    • Use the model during leadership gaps, migrations, replatforming, expansion, acquisitions, launches, or other periods when the cost of a poor search decision is unusually high.
    • Do not use fractional leadership as a cheaper substitute for the writers, developers, analysts, outreach specialists, or production capacity you actually need.
    • Define decision rights, execution owners, expected outputs, measurement, and exit conditions before negotiating hours or retainer terms.
    • Evaluate candidates by the quality of their judgment and operating discipline, not by the size of the audit they promise.

    Start with the ownership gap, not the job title

    A senior leader places a connecting piece between three separate team workflows at a central junction.

    Put your active SEO work in one place and ask four questions: Who can reorder this list? Who can commit another team’s resources? Who decides that an opportunity is not worth pursuing? Who explains those decisions to senior leadership?

    If the answer changes from project to project, you probably have coordination but not ownership. That distinction matters because organic visibility now crosses content, product, engineering, digital PR, brand, analytics, and AI-powered search. Each function can complete its own tasks while the overall program still drifts.

    The symptoms are usually visible before the missing role is:

    • Technical audits accumulate, but engineering cannot tell which fixes protect revenue or unlock growth.
    • Content planning follows keyword volume while product priorities, buyer intent, and sales evidence sit elsewhere.
    • An agency reports completed deliverables but repeatedly waits for internal approvals or strategic direction.
    • Marketing launches an AI-visibility initiative without clear access to product facts, subject-matter experts, analytics, or reputation work.
    • Different teams use different definitions of success, so meetings become debates about metrics rather than decisions about investment.

    A fractional leader can address those conditions only if the underlying need is leadership. Use the following distinction before you start interviewing.

    ModelWhat you are primarily buyingBest fitCommon mismatch
    Fractional SEO leaderSenior judgment, prioritization, governance, cross-functional alignment, and executive communicationYou have execution capacity but no strategic owner, or you temporarily need experienced leadershipYou expect the leader to personally complete a large production backlog
    SEO agencyA team, production capacity, specialist services, or a defined program of workYou need repeatable execution across an agreed scopeNo internal owner can make decisions, remove dependencies, or assess agency recommendations
    SEO freelancer or consultantFocused expertise or a specific deliverable such as an audit, analysis, or implementation projectThe problem is bounded and you know what output you needThe real problem spans departments and requires continuing authority
    Full-time SEO leaderContinuously embedded ownership, organizational development, and often people managementThe strategic and management workload is durable enough to require a permanent roleThe company needs senior input only during a transition or for a limited set of decisions

    When fractional leadership is a strong fit

    • Your execution engine already exists. Internal marketers, developers, content specialists, freelancers, or an agency can do the work once priorities and requirements are clear.
    • You are between SEO leaders. A fractional appointment can preserve strategic continuity while you determine whether and how to fill a permanent role.
    • You are entering a consequential change. A migration, replatforming, international expansion, acquisition, or product launch creates decisions that cut across normal team boundaries.
    • Your agency needs an informed counterpart. The fractional leader can test recommendations against business priorities, settle internal tradeoffs, and hold both the agency and the company accountable.
    • The work is complex but not continuous enough for a permanent executive. You need senior judgment at important decision points rather than full-time supervision.

    When you need something else

    • You have nobody to implement the plan. Hire execution capacity first or combine leadership with an explicitly staffed delivery team.
    • The role is expected to manage employees every day. That points toward an embedded leader unless the arrangement is clearly temporary.
    • No executive sponsor will resolve conflicts. A fractional leader cannot coordinate teams that are free to ignore every decision.
    • You want guaranteed rankings or guaranteed inclusion in AI answers. Neither can be responsibly promised. Treat the promise itself as a warning sign.
    • Your problem is already narrow and understood. If you need a crawl diagnosis, a schema implementation, or a content brief, a specialist engagement is likely more efficient.

    Write the leadership charter before you hire

    A vague mandate such as improve SEO invites activity without accountability. It also lets every department assume that someone else owns implementation. Write a short charter that answers six questions before you discuss retainer size.

    1. What business objective does organic visibility support? Name the market, product, audience, or growth constraint. Traffic by itself is not a business objective.
    2. What is in scope? Specify whether the mandate includes technical SEO, content strategy, digital PR coordination, local or international search, AI-search visibility, analytics, agency management, or migration governance.
    3. Which decisions can the leader make? Separate authority to decide from authority to recommend. If an executive must approve resource changes, name that person and define the escalation path.
    4. Who executes? Assign owners for engineering, content, design, analytics, PR, product data, and external vendors. Do not hide these dependencies inside the fractional role.
    5. What evidence will guide priorities? List the analytics, search data, customer evidence, business forecasts, technical diagnostics, and AI-response observations that are reliable enough to use.
    6. What should exist when the engagement ends? Examples include a functioning operating cadence, an approved roadmap, documented measurement, a completed transition, or a permanent leader who can take over cleanly.

    Sample mandate: Own the organic and AI-search strategy for the selected market; maintain a prioritized roadmap; coordinate internal teams and external partners; document material tradeoffs; and report progress, constraints, and investment choices to the executive sponsor.

    That mandate is intentionally about decisions. The expected outputs should make those decisions usable:

    • A baseline that distinguishes technical constraints, demand opportunities, authority gaps, representation problems, and measurement limitations.
    • One prioritized backlog instead of separate agency, content, engineering, and AI-search wish lists.
    • A roadmap that records expected value, confidence, effort, dependencies, risk, owner, and next decision for each major initiative.
    • Decision briefs for expensive or difficult choices, including the alternatives considered and the cost of waiting.
    • A measurement model connecting implementation and visibility indicators to qualified demand and business outcomes.
    • A durable handoff containing open risks, assumptions, data definitions, vendor responsibilities, and pending decisions.

    Set the operating cadence around decision latency. If your site changes frequently, a meeting that occurs only after several releases will arrive too late. If the roadmap changes slowly, constant meetings will add noise. Every review should end with a recorded decision, owner, deadline, dependency, or explicit reason to defer.

    Access is part of the operating model. The leader may need relevant analytics, Search Console, crawl data, CMS and release context, product roadmaps, conversion definitions, agency work, content inventories, brand research, and the people who own them. Grant the least access required, but do not expect accountable leadership from partial evidence and second-hand summaries.

    Hire for judgment, not an impressive audit

    The most revealing interview is not a request for more tactics. Give the candidate a realistic conflict from your organization and ask how they would decide. A strong answer will expose assumptions, request missing evidence, identify affected teams, and explain what would change the recommendation.

    Use questions that force the candidate to demonstrate prioritization:

    • Show us a roadmap where you decided not to pursue plausible SEO opportunities. What was rejected, and what evidence made another investment more important?
    • Walk us through a technical issue that competed with product work. How did you describe the risk, estimate the opportunity, and reach a decision with engineering?
    • How would you decide whether an AI-search problem belongs in content, technical SEO, digital PR, product data, or brand work? Look for diagnosis across functions, not a default answer tied to one service.
    • Which measures would you use first, and which would you refuse to treat as proof? A credible leader should distinguish business outcomes, visibility indicators, operational progress, and attribution limits.
    • What authority and access would you need from us? Candidates who promise ownership without asking about decision rights and dependencies are skipping the organizational problem.
    • What would tell you that we need a full-time leader instead? Fractional status should not be defended after the role has become permanently embedded and operational.
    • How will your work remain usable after you leave? Listen for shared systems, documentation, knowledge transfer, and clear ownership rather than personal spreadsheets and private dashboards.

    Ask to see sanitized examples of decision documents, roadmaps, measurement definitions, and executive updates where confidentiality permits. You are assessing whether the person can turn specialist evidence into choices that other teams can understand and execute. A technically detailed audit can be useful, but it does not prove leadership.

    References should include people who received the candidate’s recommendations and people expected to implement them. Ask whether priorities became clearer, whether conflicts were resolved, whether risks were communicated early, and whether the organization was less dependent on the consultant by the end.

    Watch for predictable warning signs:

    • A large audit is proposed before the candidate understands the business decision it must support.
    • The pitch treats traffic, rankings, AI citations, or content volume as the goal without connecting them to qualified demand.
    • Every problem leads to the same familiar service, tool, or content format.
    • The candidate avoids responsibility for prioritization while still asking to be treated as the strategic owner.
    • Reporting centers on tasks completed rather than decisions made, work shipped, constraints removed, and outcomes observed.
    • The engagement depends on proprietary data or undocumented processes that you cannot retain after termination.

    Your agreement should reflect the same discipline. Define scope, availability, response expectations, conflicts of interest, data handling, ownership of work products, vendor relationships, termination, and handoff. Hours matter for capacity, but they are a poor substitute for a clear mandate.

    Measure whether leadership turns into shipped work

    A leader and cross-functional team move prioritized task tiles from a planning table through production toward a completed launch.

    A fractional leader should not be judged only by rankings, and they should not be insulated from outcomes by reporting only meetings and recommendations. Use three connected layers of measurement.

    • Business outcomes: qualified leads, transactions, revenue, retention-supporting discovery, or another outcome the company already trusts. State attribution limits instead of forcing every change into a false direct-revenue claim.
    • Search and discovery outcomes: qualified organic demand, visibility for commercially relevant topics, landing-page performance, crawl and index health, brand representation, and observed presence in relevant AI responses.
    • Operating outcomes: important work implemented, decision delays reduced, dependencies resolved, roadmap items aging for explicit reasons, and teams using the same priorities and definitions.

    Establish the baseline before major plan changes. Annotate launches and releases. Keep recommendations separate from implementation, because an idea sitting in a backlog cannot produce a result. When work is blocked, report the dependency, its owner, the consequence, and the decision required. This makes accountability fair to both the fractional leader and the teams doing the work.

    AI-search measurement needs particular care. A prompt set is a sample, not a census of everything users might ask or everything a model might answer. Record the prompts, market, model or surface, observation date, response, cited domains, brand inclusion, and factual accuracy so later checks are comparable. Then connect observed gaps to work you can actually own: clearer product information, stronger expert content, technical accessibility, consistent brand facts, or credible third-party mentions.

    Automation can accelerate parts of research, analysis, and production, but the higher-value decisions are what to automate, what to test, what to prioritize, and how visibility connects to business results. If your reporting celebrates faster output without checking accuracy, differentiation, implementation, or commercial relevance, the program is optimizing motion.

    Build the transition into the engagement from the start. Move toward a full-time hire when strategic work, people management, and cross-functional decisions have become continuous. End or narrow the engagement when the defined transition is complete and internal owners can run the system. Expand execution separately when leadership is working but delivery capacity is still the constraint.

    Before contacting candidates, bring marketing, content, product, engineering, analytics, PR, and your current agency into one working session. List the consequential search decisions that lack an owner, the work already ready to ship, and the authority a temporary leader could realistically hold. If the list is mostly production tasks, buy execution. If it is dominated by priorities, tradeoffs, dependencies, and executive decisions, you have a credible case for fractional SEO leadership.

    References


  • What Conductor’s Leadership Transition Means for AEO

    What Conductor’s Leadership Transition Means for AEO

    If you use Conductor, compete with it, or are considering it for enterprise search, the CEO change matters for a reason that goes beyond the name on the leadership page. A product executive closely associated with Conductor’s AI and data foundation is taking control just as the company puts answer engine optimization at the center of its strategy.

    Your immediate task isn’t to react to the announcement. It is to determine whether the transition will turn AI visibility data into reliable explanations and useful website decisions. That measurement-to-action handoff is where an AEO platform proves its value.

    The handoff signals continuity, but not business as usual

    Co-founder Seth Besmertnik is stepping down after two decades as CEO. Chief Product Officer Wei Zheng is succeeding him, while Besmertnik remains on Conductor’s board and plans to support the company as a major shareholder. This is an internal succession with continued founder involvement, not a clean break led by an outside turnaround executive.

    Continuity should not be confused with stasis. Zheng spent the previous five years overseeing product strategy. She led the development of Conductor AI and the company’s wider AI and data strategy, including the data foundation beneath its enterprise platform. Besmertnik also credited her with pushing Conductor to build a data platform four years before the leadership change. That platform now brings together signals used to measure visibility in AI search.

    The change closes an unusually long founder-led chapter. Besmertnik co-founded the business in 2006, when it operated as LinkExperts, before it became Conductor in 2008. He later led the company through its 2018 acquisition by WeWork and a 2019 employee buyback that restored its independence and gave more than 250 employees co-founder status. That history makes this succession significant even though the founder is staying involved.

    Key takeaways

    • Conductor is moving from a long-serving founder-CEO to an internal product leader, while preserving board-level founder involvement.
    • Wei Zheng’s prior remit connected product strategy, AI development and the enterprise data foundation, so her appointment reinforces the direction already underway.
    • Conductor is explicitly placing AEO at the center of platform development, customer service and growth investment.
    • The important product test is no longer whether a tool can count AI mentions. It is whether it can explain recommendation patterns and guide changes that can be evaluated afterward.
    • Customers should separate announced direction, currently available functionality and independently demonstrated outcomes.

    The strategic shift is from rankings to recommendations

    Stacked translucent result tiles feed through streams of light into a focused group of illuminated recommendation objects.

    Conductor says AEO will shape how it develops its platform, works with customers and invests for growth. That is more consequential than simply adding another dashboard. Traditional search programs usually begin with rankings, impressions, clicks and landing-page performance. AEO adds a different question: when an answer engine constructs a response, why does it represent or recommend one brand instead of another?

    The distinction matters because an AI appearance is not a single outcome. A brand can be mentioned without being recommended. A page can be cited without the brand becoming the preferred choice. An answer can also describe a company accurately while excluding it from a shortlist. If a platform combines those events into one visibility score, the number may be easy to report but difficult to act on.

    Conductor’s stated next phase is to move beyond checking whether a brand appears in an AI answer. The company wants to help teams understand why a brand is or is not recommended, then translate that diagnosis into content and website changes. Treat that as a strategic destination rather than proof that every part of the workflow is already available at the same level of maturity.

    AEO layerQuestion it must answerEvidence you should expectCommon failure
    MeasurementWhere and how does the brand appear?Prompt set, answer engine, market, date, answer text, citation and recommendation statusReducing every appearance to one visibility score
    DiagnosisWhat may explain the inclusion or exclusion?Traceable connections to pages, entities, claims, citations, competitors or technical conditionsPresenting a plausible explanation as proven causation
    ActivationWhat should the team change?A prioritized action tied to an owner, affected asset and intended question or entityGenerating a generic content task with no relationship to the observed answer
    ValidationDid the change improve the intended outcome?A controlled change log and repeated measurement using a consistent methodClaiming success from a single variable AI response

    This is the standard to carry into any AEO conversation. Measurement tells you what happened. Diagnosis proposes why. Activation gives someone a bounded change to make. Validation checks whether the expected movement followed. A tool that stops after the first layer is monitoring software, even if the dashboard is labeled AEO.

    What customers and buyers should ask Conductor now

    A leadership transition does not require you to pause a procurement process or rewrite an existing search program. It does justify a more precise product review. Use one real customer question throughout the next demonstration, renewal discussion or roadmap session, and ask the team to show the complete path from observed answer to validated action.

    1. Separate shipped capabilities from strategic intent. Ask which AEO functions are generally available, which are limited releases or tests, and which remain on the roadmap. A future direction can be credible without being a current product feature, but the distinction belongs in your decision.
    2. Inspect the measurement frame. Ask which answer engines are covered and how prompts, locations, languages and time periods are handled. Find out whether the system stores the underlying answer and citations or only a derived score. Without that context, you cannot investigate a visibility change.
    3. Clarify what counts as visibility. Require separate treatment of mentions, citations and recommendations. Then ask how sentiment, factual errors and competitor inclusion are represented. A single blended metric can conceal the event your team actually needs to fix.
    4. Challenge every explanation. When the platform says why a brand was excluded, ask which observable evidence supports that conclusion. A diagnosis should identify its inputs and uncertainty. It should not turn correlation into a promise that one page edit will change a model’s answer.
    5. Follow the recommendation into the website. Ask whether an insight points to a specific URL, template, entity, claim or technical issue. Check whether your team can assign the work, record what changed and rerun the same analysis later. Advice that cannot survive this handoff tends to become another unprioritized content backlog.
    6. Verify how the platform’s components work together. Conductor expanded through the acquisitions of ContentKing and Searchmetrics. Do not assume acquired data or capabilities automatically form one workflow. Ask the vendor to demonstrate exactly how monitoring, search intelligence, AI visibility and recommended actions connect in the product you would license.
    7. Define the business outcome before discussing the score. Decide whether you need accurate brand representation, shortlist inclusion, cited authority, qualified visits, assisted conversions or sales enablement insight. You can then judge whether the platform supplies evidence for that outcome rather than accepting visibility as a substitute for it.

    Use the same scenario with every platform you evaluate. A consistent task exposes differences that a polished feature tour can hide. It also keeps the buying decision anchored to your workflow instead of each vendor’s preferred terminology.

    Run a vendor-neutral AEO test before changing strategy

    Three unbranded AI systems process identical source materials through the same transparent verification setup in a neutral laboratory.

    You do not need to wait for Conductor’s roadmap to mature before improving your AEO practice. Build a small, vendor-neutral test that you can later run through Conductor or another platform. The goal is to preserve your own evidence and decision logic.

    1. Create a stable question set. Start with real questions a buyer asks while defining a problem, comparing approaches or selecting a provider. Group them by intent. Save the exact wording rather than keeping only a topic label.
    2. Capture the complete response context. Record the answer engine, date, market, prompt, response text, cited pages, named competitors and whether your brand was mentioned, cited or recommended. This becomes the baseline against which later changes are judged.
    3. Write one evidence-based hypothesis for each problem. A missing recommendation might relate to weak comparative evidence, an unclear entity, inconsistent claims, inaccessible content or insufficient support for the answer being requested. Treat each as a hypothesis to test, not a diagnosis already proven by the output.
    4. Make a bounded change. Update the smallest defensible set of pages or templates. Record the URLs, the claims added or corrected, the technical changes and the publication date. If you change the whole site at once, you lose the ability to learn which intervention mattered.
    5. Repeat the same collection method. Generative answers can vary, so do not treat one favorable response as proof. Look for repeated directional change while keeping the prompt set and observation method as consistent as possible.
    6. Connect the result to an operating decision. Decide whether the evidence supports expanding the change, revising the hypothesis or leaving the page alone. The purpose of an AEO system is to improve this decision loop, not merely produce a larger report.

    If a recommendation involves schema or JSON-LD, treat structured data as machine-readable corroboration rather than a switch that guarantees inclusion. The markup should match the visible page, describe the relevant entity and relationship precisely, and avoid claims the page cannot substantiate. Your AEO workflow should also explain which observed question or ambiguity the markup is intended to address.

    This test gives you an asset the vendor cannot own: a stable set of questions, observations, hypotheses and change records. You can use it to evaluate new functionality without resetting your measurement whenever a platform changes its labels or scoring model.

    Watch for evidence that AEO has become an operating system

    Conductor launched Conductor AI about a year before announcing the succession and says hundreds of enterprises have adopted it. That indicates market uptake, but adoption is not the same as a demonstrated customer outcome. The next phase should be judged by what teams can reliably do after they receive an AI visibility result.

    Look for four forms of evidence as Wei Zheng takes over: transparent measurement methods, diagnoses linked to inspectable signals, actions tied to specific website assets, and validation that distinguishes a repeated pattern from a single fluctuating answer. Customer examples become more meaningful when they show this chain rather than reporting adoption or visibility growth without the underlying method.

    Also watch how the company balances AEO with the search work enterprises still have to run. AI recommendations depend on accessible, accurate and well-supported information. Technical health, content quality, entity clarity and conventional search discovery remain inputs to that work. A credible AEO strategy should connect those disciplines instead of treating AI visibility as a detached channel.

    Your next move is straightforward: put one real question set through the measurement, diagnosis, activation and validation loop, then ask Conductor to show its evidence at every handoff. If the new strategy makes that loop clearer and faster, the transition will matter to your program. If it produces only a renamed visibility report, keep your AEO decisions anchored to the evidence you control.

    References


  • SEO Career Signals That Prove You Can Drive Business Value

    SEO Career Signals That Prove You Can Drive Business Value

    You can be excellent at keyword research, technical audits, content briefs, internal linking, and structured data and still struggle to explain why you should be hired, promoted, or protected when budgets tighten. If your evidence stops at completed tasks, you are showing competence in work that software can increasingly accelerate.

    The career question has shifted from Can you find SEO work? to Can you identify the work worth doing, earn its priority, and connect it to a business result? This is how you build career signals that answer that question with evidence.

    Key takeaways

    • SEO fundamentals remain necessary, but they no longer distinguish you on their own.
    • Your strongest career signal is a well-supported decision under real constraints, not the size of an audit or task list.
    • A recommendation should identify the business effect, proposed action, tradeoff, dependency, and proof of success.
    • Your portfolio should show how your reasoning changed a decision, influenced implementation, and affected an outcome.
    • AI fluency matters when you can verify its output and apply judgment, not merely generate more deliverables.

    Make business judgment your primary SEO signal

    AI can already draft audits, summarize search results, suggest content briefs, write metadata, identify schema gaps, and assemble roadmaps. Knowing how to produce those deliverables still matters. Treating their production as your main value does not.

    A strong career signal is observable evidence that you can make a useful choice when the answer is not sitting in a checklist. It shows that you understand what the company sells, why customers choose it, where organic discovery supports the buying journey, and what the business would have to give up to pursue your recommendation.

    Before proposing work, force the opportunity through these questions:

    • Which business or customer outcome is constrained? Name the decision, transaction, lead, adoption step, or customer need that the work is meant to support.
    • What evidence makes this an organic-search problem? Separate observed search behavior, crawl or indexation evidence, page performance, and customer behavior from assumptions.
    • What happens if the company does nothing? Describe the likely cost of delay without manufacturing urgency.
    • What are the realistic alternatives? Compare the SEO proposal with product, engineering, content, brand, paid distribution, or no action.
    • What is the smallest useful move? Define the change that can test the reasoning before asking for a broad program.
    • What evidence would change your mind? Decide in advance what would cause you to expand, revise, or stop the work.

    Put the answers into a short opportunity brief. Its purpose is not to display everything you know. It should help someone choose among competing uses of time and money.

    • Situation: the relevant business context and verified search condition.
    • Effect: the customer or commercial consequence of that condition.
    • Options: plausible responses, including doing nothing.
    • Recommendation: the action you prefer and why it is the best available choice.
    • Tradeoff: the engineering, editorial, design, or analytical capacity the action requires.
    • Dependency: the people, systems, approvals, and release conditions needed for implementation.
    • Evidence plan: the leading and business indicators you will examine, plus any limits on interpretation.

    This format exposes weak reasoning early. If you cannot connect a proposed content cluster, template change, or schema implementation to a meaningful problem, you may have found a valid best practice without finding a priority.

    Use a simple prioritization ladder when requests compete:

    • Act: the evidence is strong, the affected journey matters, and delay has a credible cost.
    • Validate: the opportunity is plausible, but a limited investigation or reversible test should come before substantial investment.
    • Schedule: the work has a reasonable path to value but loses to a more consequential constraint.
    • Decline: the request has no convincing path to a customer or business outcome, or another intervention addresses the problem more directly.

    Saying no is part of this skill. The useful version of no sounds like this: The concern is real, but this action is unlikely to resolve it because the evidence points to a different constraint. We recommend addressing that constraint first, then reassessing this request with the resulting data. You are not blocking work; you are making the opportunity cost visible.

    You also need to recognize when the problem is not SEO. A page that earns visits but fails to move people forward may have a product, pricing, positioning, user-experience, or conversion-path problem. Weak brand recognition may limit demand that another content campaign cannot create by itself. Strategic SEOs can identify those boundaries instead of prescribing SEO for every symptom.

    Your career signal is not that you can personally fix every adjacent problem. It is that you can diagnose the boundary, involve the right owner, and prevent the company from spending on the wrong remedy.

    Build a portfolio around decisions, influence, and outcomes

    Two colleagues review a portfolio-like case containing abstract research cards, prioritization tokens, a product model, and illuminated outcome blocks.

    A ranking chart, audit export, or traffic graph shows an event. It does not show whether you understood the business, selected the right intervention, influenced the people who controlled implementation, or interpreted the result responsibly. Even a long tenure is not proof that your decisions made the business better.

    Rebuild each portfolio example as an evidence chain:

    • Context: what the company sold, who the relevant customer was, and where organic discovery fit in the journey.
    • Constraint: the verified problem and why it mattered at that moment.
    • Diagnosis: the evidence you used, the uncertainty that remained, and the non-SEO explanations you considered.
    • Decision: what you recommended, what you explicitly did not recommend, and why.
    • Influence: how you adapted the case for the people whose support or work was required.
    • Implementation: what actually shipped, how it differed from the original proposal, and what compromises were accepted.
    • Outcome: what changed in search behavior, customer behavior, or business performance, without claiming causation the evidence cannot establish.
    • Learning: what the result confirmed, what it disproved, and what you changed next.

    The rejected options are important. They reveal judgment. If you chose a template-level fix over manually editing many pages, explain the operational reason. If you accepted a technically imperfect release because the remaining issue did not justify delaying a customer-facing launch, describe the tradeoff. If you stopped a content plan after discovering that product positioning was the real constraint, show that decision.

    Do not retrofit a commercial success story onto evidence that only supports a search result. Use the strongest claim the data permits:

    • If you only know that the recommendation was accepted, say that.
    • If you know the change shipped and technical validation passed, show that implementation proof.
    • If visibility or qualified visits changed, distinguish that from revenue or lead impact.
    • If conversions changed but attribution is uncertain, state the uncertainty and identify other contributing factors.
    • If nothing improved, explain what you learned and why the next decision became better.

    This makes modest projects useful portfolio material. You do not need to manufacture a dramatic win. Preventing low-value work, clarifying measurement, narrowing an oversized initiative, or uncovering a non-SEO constraint can demonstrate better judgment than a lucky ranking gain.

    Select examples that match the level of role you want. Early-career evidence should make your analytical discipline and ownership visible. Mid-career evidence should show prioritization, cross-functional execution, and measurement. Senior evidence should show how you allocated scarce resources, managed uncertainty, improved the decision system, and connected search investments to company strategy.

    Keep confidential information out of public materials. Replace identifying details with truthful descriptions, remove proprietary data, and never imply that anonymized figures are precise if you have transformed them. You can demonstrate reasoning without exposing an employer or client.

    Make communication part of SEO delivery

    A technically correct recommendation that nobody implements creates no business result. That is why communication determines whether SEO receives resources, priority, implementation, and a connection to revenue. It is not decoration added after the analysis. It is part of delivering the work.

    A line item such as implement schema or improve internal linking describes activity. It leaves the decision-maker to work out why the activity matters, whether it outranks other work, and how anyone will know it helped. A decision-ready recommendation supplies that missing logic:

    • What is happening: the condition you verified, stated without unnecessary jargon.
    • Why it matters here: the affected customer journey, product area, operational process, or commercial objective.
    • What inaction means: the credible consequence of waiting or declining.
    • What should happen first: a specific, bounded action rather than a broad aspiration.
    • What the team is trading: the capacity, release risk, or competing work involved.
    • How you will evaluate it: implementation checks, leading indicators, business measures, and interpretive limits.

    For example, turn a generic schema ticket into a decision: the affected template currently presents inconsistent product facts between visible content and machine-readable fields; standardize the underlying fields and generate matching structured data from that source; prioritize the work only if it addresses a verified inconsistency on commercially important pages or supports a relevant eligible search experience; acknowledge the required template engineering time; validate the output and observe the intended search behavior without promising that a platform will display it.

    The technical action is still present, but the recommendation now tells a team why it deserves attention and what success does and does not mean.

    Adapt the same recommendation to the person receiving it:

    • Leadership needs the outcome, confidence level, resource request, downside of delay, and opportunity cost.
    • Engineering needs a reproducible condition, affected scope, constraints, acceptance criteria, release risk, and validation method.
    • Content teams need the audience need, editorial gap, evidence standard, distribution path, and definition of a useful page.
    • Analytics teams need the question being measured, required data, event logic, comparison method, and known attribution limits.

    Do not end an update with information alone. State the decision you need, who needs to make it, what input remains unresolved, and what happens after approval. Record the owner and next checkpoint. This turns communication into forward movement instead of another status artifact.

    Measure your influence as well as the search result. Useful evidence includes whether the recommendation was understood, accepted, funded, correctly implemented, and incorporated into later planning. Those milestones do not replace business outcomes, but they show where delivery succeeded or failed.

    Use AI to raise the standard of your work

    An SEO specialist reviews abstract AI-generated options, verifies one with research tools, and shares the refined result with two colleagues.

    AI lowers the cost of producing plausible SEO output. It does not remove the need for technical knowledge, content judgment, analytics, distribution, or an understanding of how search and answer engines work. It raises the standard for what you do after the first draft appears.

    Prompt fluency alone is a weak career signal. A stronger AI workflow makes your judgment auditable:

    • Frame the question: define the business decision before asking a model for an audit, summary, classification, or plan.
    • Control the inputs: provide relevant first-party information and distinguish it from assumptions or generic best practices.
    • Verify the output: check technical claims against the site, search behavior, platform requirements, analytics, and customer context.
    • Find the omission: look for product, brand, pricing, user-experience, operational, and measurement factors the generated answer did not consider.
    • Make the decision: choose what to act on, test, defer, or reject, and document the tradeoff.
    • Close the loop: compare the result with the original reasoning so the next decision improves.

    This distinction is especially important in AI SEO, AEO, and GEO work. A third-party visibility score may help you observe change, but it is not the business outcome. Search rankings, sessions, and third-party AI visibility scores should not be mistaken for the purpose of the work. Use them as diagnostic indicators and connect them, where the evidence allows, to relevant queries, brand representation, qualified behavior, customer decisions, conversions, or another defined business objective.

    You should also be able to explain the boundary between what your team controls and what a search or answer platform controls. You can improve accessible content, factual consistency, structured data, internal connections, source clarity, and technical availability. You cannot guarantee that a platform will crawl, index, rank, cite, summarize, or display the material in a particular format. Clear boundary-setting is a professional signal because it protects decision quality from inflated promises.

    Before your next interview or performance review, open a recent deliverable and remove the task list from its opening. Replace it with the constrained outcome, verified evidence, options considered, recommended decision, required tradeoff, implementation record, and strongest defensible result. Then ask whether someone outside SEO could understand why the work mattered.

    If the answer is no, you do not need another checklist yet. Rewrite that project until it proves that you can choose well, bring other people with you, and connect organic discovery to a result the organization actually values. That is the career signal worth building next.

    References


  • Build, Buy, or Outsource Marketing AI: A Decision Framework

    Build, Buy, or Outsource Marketing AI: A Decision Framework

    Your team has found a marketing workflow worth improving with AI. A vendor can sell you a platform, a specialist can configure a solution, and someone internally is probably confident they can build a prototype. The dangerous question is which option looks cheapest at the start.

    The useful question is where repeatable software should end, where your workflow needs specialist implementation, and where qualified human judgment must remain. A focused 30-minute sorting exercise can answer that before an interesting prototype becomes an unsupported internal product.

    Key takeaways

    • Buy software when the capability is common across companies and the vendor can absorb maintenance, updates, and support.
    • Outsource implementation knowledge when your workflow is custom but the expertise needed to build it is temporary.
    • Build internally when the logic is genuinely differentiating, your team will improve it regularly, and you can support it after launch.
    • Do not deploy an AI workflow unless a named person can verify its output using evidence and subject knowledge.
    • Make the decision for each workflow step, not for an entire department, role, or AI initiative.
    • Compare lifecycle cost, including review and maintenance, and validate the choice with a controlled pilot before allowing autonomous action.

    Treat the workflow as layers, not one build-or-buy choice

    An exploded three-layer workflow combines standard software modules, configurable connections, and a human approval checkpoint.

    A marketing automation is rarely one indivisible system. A visibility report, for example, may collect data, normalize names, identify changes, interpret those changes, route exceptions, obtain approval, and distribute a finished report. Those steps do not have to come from the same place.

    Break the workflow into boxes before comparing solutions. For every box, record its input, transformation, output, owner, reviewer, and downstream decision. You can then route each layer according to what makes it difficult.

    Workflow layerMarketing examplesSensible defaultYour continuing responsibility
    Common software capabilityRank tracking, citation monitoring, brand-mention tracking, crawl diagnostics, and content scoringBuyConfiguration, data access, quality checks, and vendor oversight
    Company-specific implementationApproval routing, data mapping, reporting cadence, subject-matter-expert intake, and approved CTA insertionOutsource the initial design or implementation, then own itRequirements, acceptance tests, documentation, and an internal process owner
    Differentiating logicYour prioritization rules, proprietary data relationships, brand judgment, and decision criteriaBuild or retain internallyRoadmap, maintenance, testing, and knowledge continuity
    Human controlAccuracy review, exception handling, interpretation, and final approvalKeep qualified ownership inside the teamEvidence standards, escalation rules, and accountability for the resulting decision

    This is a deliberate hybrid, not a compromise. You might buy the monitoring engine, hire a specialist to connect it to your reporting process, build a narrow layer containing your prioritization rules, and keep final interpretation with an analyst. Recreating the monitoring platform would add little advantage; handing your judgment to an opaque system would surrender too much.

    An MIT review of enterprise generative AI projects reported zero return among 95% of the organizations it examined, while external partnerships represented a higher share of successful deployments than internal development. That should not be converted into a universal failure probability: the initiative volumes were uneven, and there was too little hybrid build-buy evidence to quantify that route. The practical warning is narrower. A working prototype is not a successful deployment, especially when the system does not fit the way people already work.

    Do not automate work that nobody can verify

    Two people inspect assets at a checkpoint in an automated production line before approved items continue.

    Before discussing price or architecture, ask one gating question: can a named person on your team perform the task manually or reliably check the result? If the answer is no, pause the automation. You would be installing a system whose failures your team cannot recognize.

    Fluent output makes this risk easy to underestimate. A model can turn a spike in a group of Google Search Console queries into a confident claim that AI visibility is rising, even though the data does not establish that conclusion. The error can look polished enough to enter a leadership meeting unless someone understands both the data and the inference being made.

    Only 13% of marketers fully trust AI output without a human reading it. That is not merely an adoption problem. It is a staffing and workflow requirement: the review still needs time from someone qualified to judge the work.

    The State of CRM Data Report 2026 found that nearly 78% of C-suite respondents and 92% of SVP or VP respondents had acted on an AI recommendation they later suspected was wrong because of poor underlying data. The corresponding figure among individual contributors was 41%. These are self-reported suspicions, not measured model error rates, but they expose an important control problem: the person with authority to act may be farther from the evidence needed to challenge the recommendation.

    Create a verification contract before you automate. It should answer:

    • What decision can this output influence? A draft that stays in an editor is different from a report that changes budget or reaches an executive.
    • What evidence should support the answer? Require links, source records, query data, calculation inputs, or another trace that the reviewer can inspect.
    • Who is qualified to review it? Assign a person or role, not an unspecified human in the loop.
    • What counts as an unacceptable error? Define concrete failure classes such as fabricated facts, incorrect data mapping, unsupported attribution, missing exceptions, or off-brand recommendations.
    • What happens when confidence is low or evidence is missing? Route the case to a person rather than letting the system improvise.
    • Which outputs always require approval? Keep review on every output that can publish content, contact a customer, alter spending, or materially influence a leadership decision.

    If no one can fill in that contract, your next investment is expertise, not automation. Narrow the task, train an owner, or obtain specialist help before deploying the tool.

    Buy common capability, outsource the learning curve, build your edge

    Buy when the underlying problem is common

    Buying is usually the sound route when thousands of other teams need substantially the same capability. Tracking, monitoring, crawling, diagnostics, and scoring all require unglamorous infrastructure work: connectors change, interfaces break, usage grows, and edge cases accumulate. A mature vendor spreads that work across its customers and provides someone to fix the product when it fails.

    Do not evaluate only the demo. Ask the vendor to show how the product handles your real inputs and exceptions. Confirm:

    • whether it supports the data systems you actually use;
    • how it logs inputs, changes, failures, and human approvals;
    • whether reviewers can inspect the evidence behind an output;
    • how data, configurations, and results can be exported;
    • which maintenance and support work is included;
    • how usage, seats, or additional integrations affect cost;
    • what happens to your workflow when the vendor changes a model or feature; and
    • what access controls apply before customer, employee, or proprietary data enters the system.

    The product does not need to mirror your process perfectly out of the box. It does need to cover the commodity layer without forcing your team to become its unpaid engineering and support department.

    Outsource when the workflow is yours but the learning is temporary

    Your approval chain, internal taxonomy, reporting schedule, subject-matter-expert process, and pre-approved copy may be unique. The implementation problems hiding underneath them often are not. Someone who has configured similar workflows already knows where handoffs fail, which exceptions need human input, and which apparently simple steps become brittle when automated.

    Use a practical test: will your team apply the knowledge gained from building this every week? If not, paying employees to discover each failure mode for the first time is an expensive way to acquire one-use expertise. Buy the learning curve through a validated template, a focused consultation, a short implementation engagement, or a specialist resource library.

    Outsourcing should leave you with an operable system, not a permanent mystery. Put these deliverables into the engagement:

    • a map of the workflow, inputs, outputs, owners, and exceptions;
    • documented configuration and administrator access;
    • acceptance tests covering normal, messy, and missing inputs;
    • a failure log describing known limits and escalation paths;
    • training for the internal owner and reviewers;
    • a handover plan, maintenance estimate, and change process; and
    • clear ownership and export rights for data, prompts, rules, documentation, and other deliverables.

    Keep an internal owner involved throughout. A handoff at the end cannot recover reasoning and decisions that were never documented.

    Build when the capability creates durable advantage

    Building internally makes sense when the system encodes something meaningfully different about how you market, not merely because your workflow has custom field names. Your team should be able to answer yes to all of these questions:

    • Does the logic create a real advantage rather than duplicate a standard product feature?
    • Will your team use and improve the resulting technical or operational knowledge regularly?
    • Are your requirements unlikely to be met through configuration, integration, or a narrow extension of existing software?
    • Can you assign an enduring product owner and the people needed to test, monitor, document, and repair it?
    • Will ownership survive if the original builder changes roles or leaves?
    • Can a qualified person verify the system’s output and stop it when it behaves incorrectly?

    An internal prototype may appear inexpensive because its future obligations are invisible. Once colleagues depend on it, the team owns permissions, changing integrations, model behavior, tests, documentation, support, incident response, and every request for a small improvement. If those duties do not have owners, the organization has created software without creating a software function.

    Build the narrowest layer that contains your advantage. Purchasing a stable platform and adding your own orchestration or decision rules is often more defensible than rebuilding data collection, authentication, dashboards, and administrative features around it.

    Use a hybrid route deliberately

    A strong marketing AI workflow may use all three routes. A vendor collects visibility data. A specialist maps the data to your taxonomy and approval path. Your team encodes its prioritization rules and approved CTA library. An analyst reviews anomalies and interpretation before the report reaches leadership.

    Write the boundary between those layers down. Specify who owns the data, configuration, custom logic, review, maintenance, and recovery process. Hybrid systems become fragile when every participant assumes somebody else owns the seam.

    Make the decision in 30 minutes, then test one handoff

    You do not need a long procurement exercise to choose an initial route. You do need a disciplined comparison that counts work beyond the visible fee.

    Use this 30-minute decision agenda

    1. Minutes 0-5: define the outcome. Name the marketing result, the user, and the decision the workflow should improve. Reject objectives such as use AI or automate content; they do not define value.
    2. Minutes 5-10: map the steps. Draw each input, transformation, review, exception, and output. Do not route the workflow until you can see its parts.
    3. Minutes 10-15: classify the layers. Mark each step as common capability, company-specific implementation, differentiating logic, or human control.
    4. Minutes 15-20: apply the verification gate. Name the reviewer, required evidence, unacceptable errors, and escalation path.
    5. Minutes 20-25: compare lifecycle cost. Add internal labor, implementation, review, maintenance, support, and displaced marketing work to the visible price.
    6. Minutes 25-30: choose a route and pilot boundary. Decide what to buy, outsource, build, or leave manual. Assign an owner and state what evidence would justify expansion.

    Compare total cost on the same basis

    A subscription price cannot be compared directly with a development estimate. Use the same operating horizon and the same labor assumptions for every option.

    • Buy: subscription or usage charges, implementation, integrations, internal administration, review, training, migration, and eventual exit work.
    • Outsource: specialist fees, required software, internal subject-matter-expert time, review, training, handover, and ongoing maintenance.
    • Build: discovery, meetings, design, development, testing, infrastructure, documentation, monitoring, support, review, repairs, and the marketing work displaced by those hours.

    Calculate internal labor using the time of every contributor, not just the person writing prompts or code. Include the people clarifying requirements, attending meetings, preparing data, testing outputs, correcting errors, approving work, and responding when the workflow breaks.

    Then name the opportunity cost in operational terms. Which campaign, analysis, customer interview, content update, or technical fix will wait while the team builds and maintains this? If no displaced work appears in the comparison, the internal option has been priced as though staff time were unlimited.

    Keep consequence separate from speculative arithmetic. If a bad output could publish an unsupported claim, misclassify performance, expose sensitive data, or redirect budget, record that failure and the control that prevents it. Do not invent a precise dollar value merely to make the spreadsheet look complete.

    Pilot a bounded step before replacing a job

    Test one handoff whose output can be compared with the existing process. A narrow pilot reveals whether the proposed route reduces work or merely moves it into checking, correction, and maintenance.

    1. Capture the baseline. Record the current input, output, turnaround, human effort, recurring errors, and approval path.
    2. Prepare test cases. Include normal inputs, incomplete data, unusual cases, and situations that should be escalated rather than answered.
    3. Define acceptance before testing. State the required evidence, allowed error classes, review time, and conditions that would stop the pilot.
    4. Run in shadow mode. Compare results without letting the system publish, send, spend, or change a production record on its own.
    5. Log every intervention. Separate factual corrections, data-mapping problems, brand edits, integration failures, and exceptions. That log shows whether the problem is the model, the implementation, the input, or the process itself.
    6. Calculate net value. Subtract review, repair, administration, and maintenance effort from gross time saved. Include improvements in consistency or turnaround only when the pilot demonstrates them.
    7. Decide explicitly. Expand, revise, change the sourcing route, keep the step manual, or stop. Name the production owner and rollback method before expansion.

    Stop or narrow the automation when failures are hard to detect, review consumes most of the apparent saving, changing inputs repeatedly break the workflow, or nobody accepts maintenance ownership. That is useful pilot evidence, not a reason to keep investing until the original idea appears justified.

    Take the next proposed marketing automation and draw its steps on one page. Mark each box buy, outsource, build, or human control. Do not approve procurement or development until every box has a verification owner and the resulting system has a lifecycle owner. The goal is not to own more AI software. It is to improve a marketing outcome with the smallest reliable system that your team can understand and sustain.

    References


  • Professional Ghosting: How to Close the Loop in Business

    Professional Ghosting: How to Close the Loop in Business

    The promised update has passed. You delivered the proposal, joined the interview, signed the paperwork, or took the call. Now the other person has disappeared, and you are deciding whether to follow up again, wait quietly, or write off the relationship.

    You do not need to keep guessing. A clear follow-up boundary can protect your time without turning a delayed reply into a confrontation. The same standard can help your team stop creating this problem for candidates, vendors, partners, clients, and professional contacts.

    Professional ghosting begins where commitment ends

    A slow reply is not automatically ghosting. People get pulled into urgent work, approvals stall, budgets change, and decisions take longer than expected. The defining problem is not the delay. It is the abandoned commitment.

    Professional ghosting happens when someone initiates or actively advances a business process, creates a reasonable expectation of another step, and then stops communicating without closing that process. The pattern is especially clear when a person requests a proposal, paperwork, an introduction, or participation in an interview process and does not acknowledge the work after it arrives.

    This distinction matters because it tells you what to respond to. You are not demanding instant access to another person. You are asking them to account for a commitment they chose to make.

    A useful test is to identify the last explicit agreement. Did someone promise an update by a named date? Ask you to prepare something? Say they would arrange another conversation? Accept responsibility for getting an answer? If no commitment was made, you may simply have an undeveloped lead. If a commitment was made and abandoned, you have an open loop that needs a boundary.

    The business cost extends beyond an unanswered inbox:

    • Calendar uncertainty: You may hold time, delay another decision, or reserve delivery capacity for work that is no longer moving.
    • Unpaid effort: A customized proposal, interview, review, introduction, or contract document consumes real attention even when no transaction follows.
    • Distorted pipeline data: An opportunity that is functionally dead can remain marked as active because nobody recorded the decision.
    • Reputational spillover: Candidates, consultants, vendors, and former colleagues may remember how the process ended and share that experience when your name comes up.
    • Weaker future communication: Once missed commitments become normal, people stop trusting dates and next steps from the organization.

    The answer does not have to be yes. Nobody is entitled to a contract, job, partnership, or detailed explanation. But silence transfers the follow-up work and planning cost to the person who did not create the uncertainty. A direct no is usually easier to manage because it lets everyone release time and make the next decision.

    Follow up from the commitment, not from your anxiety

    A calm professional reviews a blank planner at an organized desk with one sealed envelope, a face-down phone, and a closed laptop.

    Repeatedly checking in without a decision rule makes you feel active while leaving the underlying uncertainty untouched. A better follow-up points to the agreed next step, asks for a small status decision, and explains what you will do if no answer arrives.

    Match the message to the state of the conversation

    • A promised update is overdue: Follow up after the promised date has passed. Name that date without accusation and ask whether the matter is active, paused, or closed.
    • You sent a requested deliverable: Confirm that it arrived, then ask what decision or review step follows. Do not keep producing additional work to provoke a reply.
    • No next step was agreed: Treat the conversation as interest, not an active opportunity. Ask for a concrete next action only if you still want one.
    • You are holding time or capacity: State when you need to release it. This is operational information, not a threat.
    • The other person already missed several self-imposed commitments: Stop asking for another vague update. Close the opportunity on your side and require a fresh plan if they return.

    Use one message to request a decision

    Subject: Status of [project or opportunity]

    Hi [Name], you mentioned that I would receive an update by [promised date], so I wanted to close the loop. Is this moving forward, paused, or no longer under consideration? Any of those answers is fine; I need the current status so I can plan [capacity, scheduling, or the next deliverable]. If the timing is still uncertain, a simple paused is enough.

    This works because it lowers the effort required to answer. The recipient does not have to compose a defense or manufacture certainty. They only have to identify the present state.

    Avoid messages such as just checking in or circling back. They do not tell the recipient what you need, and they do not establish what happens next. Also avoid writing a long account of the work you completed. If the person already knows what they requested, repeating every detail can make a straightforward status request sound like a dispute.

    Close the opportunity when waiting has a cost

    If your decision request remains unanswered and you need to plan around the uncertainty, send a final operational note:

    Hi [Name], since I have not received an update, I am marking this opportunity inactive and releasing the time associated with it. If the project becomes active again, feel free to reconnect. We can review the scope, timing, and availability based on the situation then.

    This is not a tactic for forcing a response. It is a record of the decision you are entitled to make: you will no longer reserve attention or capacity for an unconfirmed opportunity. Once you send it, act accordingly. Update the pipeline, release the calendar hold, and stop chasing.

    Handle warm introductions without recruiting the introducer

    A warm introduction carries an extra relationship. The person who connected you has attached some of their reputation to the exchange, so the introduction should create more accountability, not less.

    Do not immediately ask the introducer to pressure the silent party. Follow up directly first. If the process stays unresolved, give the introducer a neutral closure update:

    Thanks again for connecting us. We spoke, but we did not establish a next step, and I have now closed the conversation on my side. No action is needed from you; I just did not want to leave your introduction unresolved.

    That message protects the introducer from wondering what happened without turning them into a collections agent for attention. Keep it factual. Do not speculate about motives or invite them to take sides.

    Decide whether to reopen the relationship

    People sometimes return after a long silence. You do not have to punish them, but you also do not have to restore the old assumptions. Evaluate the return using three questions:

    • Did they acknowledge the gap? Ownership is more useful than an elaborate excuse. Someone who pretends nothing happened may repeat the pattern.
    • Is there a real decision now? Ask what changed, who owns approval, and what the next committed action is.
    • Can you reduce the cost of another disappearance? Restart with a smaller defined step, written responsibilities, and no speculative work beyond what the opportunity justifies.

    A returned email does not restore expired availability. Reconfirm scope and timing instead of silently absorbing the disruption into your schedule.

    Say no clearly without damaging the relationship

    Most closure messages do not require a long explanation. They need a decision, the current status, and any legitimate next step. Clarity is kinder than a soft phrase that keeps the recipient waiting.

    SituationWhat to sayWhat to avoid
    The fit is wrongWe will not be moving forward because this does not match our current requirements.Excessive praise followed by an ambiguous maybe.
    Priorities changedThe project is paused, and we do not have an approved restart point.We will circle back soon when no follow-up is planned.
    Another option was selectedWe chose a different direction and have closed this evaluation.A defensive comparison of every candidate or vendor.
    The decision is delayedWe have not made the decision. I missed the update I promised, and the next checkpoint is [date].Letting the original deadline pass without acknowledgment.
    You dropped the ballI failed to close this loop. I am sorry. The current status is [status].Restarting the thread as though the silence never happened.

    Decline a proposal or partnership

    Hi [Name], thank you for the time and work you put into this. We have decided not to move forward with [proposal or partnership]. The reason at a high level is [brief, accurate reason, if useful]. This closes the evaluation on our side. I appreciate your participation and wanted to give you a definite answer.

    Do not offer future work merely to soften the no. If you genuinely want to revisit the relationship under identifiable conditions, name them. Otherwise, a clean ending is more respectful than a fictional possibility.

    Report a delay before it becomes ghosting

    Hi [Name], I promised an update by [date], but the decision is not ready. [Approval, budget, or priority] remains unresolved. The next real checkpoint is [new date or event]. You do not need to do anything in the meantime. If that timing no longer works for you, I understand.

    A delay notice is valuable even when it contains no new decision. It proves that someone still owns the process and prevents the recipient from having to chase information you already know is missing.

    Own a missed commitment

    Hi [Name], I said I would update you and did not. That was my mistake. The current status is [active, paused, or closed]. [State the next action, if one exists.] I am sorry I left you without an answer.

    Do not bury the acknowledgment under an account of how busy the team became. The recipient needs the truth and the status. An explanation is optional; ownership is not.

    Build closure into the workflow, not into good intentions

    Two professionals exchange an unmarked folder over a project table where blank wooden tiles form a complete circle.

    Ghosting often persists because the organization records acquisition activity but not closure responsibility. A system may track calls booked, interviews completed, proposals requested, and documents sent while leaving nobody accountable for the final message.

    Every active external conversation should have four visible fields:

    • Current state: Exploratory, active evaluation, waiting on us, waiting on them, paused, accepted, or declined.
    • Named owner: One person responsible for the next communication. A department cannot send an email.
    • Next commitment: The specific decision, document, meeting, or update that has been promised.
    • Trigger: The date or event that tells the owner to act, even if the decision is still pending.

    At the end of a meeting, say the handoff aloud: who will do what, what the recipient should expect, and what will happen if the answer is not ready. A transcript or meeting summary can preserve that agreement, but recording a promise is not the same as fulfilling it.

    Make the initiator responsible for closure

    A practical ownership rule is that the person or team requesting effort owns the next acknowledgment until another person explicitly accepts the handoff. If your company asks for an interview, custom proposal, security review, NDA, sample, introduction, or planning session, assign the response owner before the request goes out.

    Before asking someone to do substantial work, confirm internally:

    • What decision will this work inform?
    • Who can actually make or approve that decision?
    • Who will acknowledge receipt?
    • Who will communicate a delay or rejection?
    • What event closes the process if the project loses priority?

    If nobody can answer those questions, the process is not ready to consume another person’s time.

    Use automation to surface promises

    Automation can create a reminder when an update is promised, flag a waiting-on-us record, prepare a draft, or show an owner all overdue commitments. It should reduce the chance that a relationship disappears inside a crowded inbox.

    It should not invent a decision, send an insincere rejection, or remove human judgment from a sensitive relationship. Efficiency should leave more room for judgment and professional courtesy. It should not enable a team to open more conversations than it can responsibly finish.

    Audit closure debt at your normal planning cadence

    When you review work in progress, filter for external conversations marked waiting on us, records whose trigger has passed, and opportunities with no defined next step. For each one, choose an actual state: advance it, pause it with an update, decline it, or assign a new owner.

    Do not measure professionalism by inbox volume. Track the conditions that reveal whether your process can finish what it starts: overdue external commitments, open records without an owner, requested deliverables without an acknowledgment, and inactive opportunities still counted as live. Your own trend is the useful benchmark. The purpose is to reduce unresolved commitments, not create a decorative score.

    Key takeaways

    • Professional ghosting is an abandoned commitment, not merely a slow response.
    • Follow up by naming the agreed next step and asking whether the matter is active, paused, or closed.
    • If waiting affects your schedule or capacity, send a final closure note and release the time.
    • A warm introduction deserves extra care because the introducer’s reputation is part of the exchange.
    • You can decline without a detailed defense. State the decision, give a concise reason when useful, and remove false ambiguity.
    • Assign an owner, next commitment, and trigger whenever your team asks an external person to invest effort.
    • Use automation to reveal overdue promises, while keeping consequential relationship decisions under human ownership.

    Choose one unresolved conversation you own and close it now. Send the decision if you have it. If you do not, send the current status and the next honest checkpoint. That small habit is how professional trust survives changing priorities, crowded calendars, and uncomfortable answers.

    References


  • Beyond SEO Dogma: The Business Value of Human Judgment

    Beyond SEO Dogma: The Business Value of Human Judgment

    Your crawler has returned 10,000 warnings. An AI platform can group them, draft tickets, recommend pages, and generate enough activity to fill the next planning cycle. The dashboard looks decisive. You still have not answered the question that matters: which work deserves to happen?

    That question is where an SEO practitioner earns their place. The valuable work is not reciting rules or producing more deliverables. It is separating a material threat from a harmless convention, connecting the recommendation to a business outcome, and accepting responsibility for what the team does next.

    SEO dogma begins when the reason disappears

    Most best practices began as useful shorthand. Use one H1. Keep title tags within a familiar length. Place the target phrase in prominent locations. Improve Core Web Vitals until the report is green. Add schema. Publish fresh content. These recommendations can be sensible, but their usefulness depends on the conditions that made them sensible.

    Repetition strips those conditions away. A tactic that worked for a particular site, template, query set, or search environment becomes a universal checklist item. The recommendation survives; the mechanism does not. A crawler then gives the item a severity label, and the label begins to stand in for analysis.

    The correction is not to reject every established practice. Treat each one as a starting hypothesis. Rewrite it in this form: When an observable condition exists, make a specific change because a named mechanism is causing harm, then evaluate a relevant signal.

    For example, delayed JavaScript rendering on an important page template can interfere with discoverability, so the team should investigate how meaningful content becomes available. A few CMS-generated H1 elements on otherwise understandable pages present a different situation. Both appear in an audit, but only evidence can tell you whether either condition warrants engineering time.

    Key takeaways

    • A best practice should begin an investigation, not end one.
    • An issue count measures inventory, not impact.
    • Automation can scale observation and production; a person must still choose the outcome worth pursuing.
    • A useful practitioner makes reasoning, uncertainty, and tradeoffs visible.
    • Leaving a condition unchanged can be a responsible decision when the evidence, accepted risk, and review trigger are documented.

    Run every recommendation through a consequence test

    A hand considers several levers connected by mechanical linkages to different miniature business outcomes.

    A priority score supplied by a tool is an input. It is not a business case. Before a recommendation reaches the backlog, require clear answers to the following questions.

    1. What condition did we actually observe? Identify the affected URL, template, content type, or journey. Do not substitute a rule violation for an observation.
    2. What problem could the condition cause? Name the mechanism: failed discovery, incorrect canonical selection, muddled intent, poor usability, lost qualified demand, or another concrete consequence.
    3. What evidence connects the condition to that problem? Look for changes in access, indexing, visibility, user behavior, qualified traffic, or business performance. If the connection remains hypothetical, say so.
    4. How much valuable surface area is affected? Count pages only after identifying whether those pages matter. One template controlling important URLs may deserve more attention than thousands of isolated warnings on obsolete assets.
    5. What happens if we leave it alone? Describe the likely downside, its confidence level, and the point at which waiting would become unacceptable.
    6. What are we giving up to fix it? Compare the recommendation with the best alternative use of content, engineering, design, and review capacity.

    This test changes how familiar audit findings are handled. It also exposes why blanket priorities fail:

    Audit findingQuestion that determines priorityDefensible disposition
    Misconfigured canonical directivesAre important duplicate or competing URLs causing search engines to ignore the intended canonical signal?Act when the condition affects valuable pages or creates a material cannibalization risk.
    Delayed JavaScript renderingIs meaningful content on an important template difficult for search engines to access or discover?Investigate the template and prioritize the root cause over individual URL tickets.
    Core Web Vitals outside a recommended thresholdIs an important product, service, or conversion page slow enough to affect user behavior, or did a low-traffic resource page miss a benchmark by a small margin?Investigate demonstrated user friction. Monitor a marginal benchmark miss when no meaningful consequence is evident.
    Multiple H1 elementsIs the content hierarchy genuinely confusing, or is the warning a side effect of the CMS and design system?Fix a communication or template problem. Do not create urgent work solely to satisfy the crawler.
    Missing meta descriptions on legacy pagesDo the pages attract meaningful search demand or support the current content strategy?Improve descriptions where better search presentation could matter; defer low-value legacy inventory.

    The same logic applies beyond SEO. Alt text, semantic structure, and performance can matter for users even when their immediate ranking effect is limited. Do not dismiss a wider accessibility or usability responsibility merely because an item loses an SEO prioritization contest. Route it to the right owner and evaluate it on the right grounds.

    Give AI the inventory, but keep a person on the decision

    Robotic arms organize trays in a large archive while a person selects one object at an illuminated workbench.

    AI is well suited to reducing the cost of seeing and producing things. It can accelerate keyword research, organize large datasets, prepare first-draft briefs, group repeated technical findings, monitor changes, and generate implementation options. Those are valuable capabilities, especially when they remove repetitive work from a skilled team.

    The boundary appears when an observation must become a commitment. Keyword volume does not establish that the query attracts the right customer. A distinct-looking phrase does not prove the site needs another URL. A technically valid page idea can still conflict with product positioning, legal review, sales priorities, brand standards, or existing content competing for the same intent.

    Consider an automated audit that returns 100 flags. A responsible practitioner may advance five, defer 90, and reject five after tracing each one to the pages, users, and systems involved. The valuable output is the explanation for that distribution, not the speed at which the original list appeared.

    Use automation for work such as:

    • Crawling, collecting, classifying, and deduplicating observations.
    • Preparing keyword, page, competitor, and performance inventories for review.
    • Drafting briefs, acceptance criteria, test cases, and implementation alternatives.
    • Repeating defined checks and surfacing changes that deserve investigation.
    • Producing content or code drafts within constraints set by accountable reviewers.

    Keep a named person accountable for:

    • Defining which customer and business outcomes the search work should support.
    • Choosing among a new page, a consolidation, a revision, a technical fix, a test, or no action.
    • Distinguishing a systemic failure from a cosmetic warning.
    • Weighing product, engineering, legal, sales, brand, and customer-service constraints.
    • Explaining the tradeoff to the people whose time or risk the recommendation consumes.
    • Changing course when the original recommendation does not produce the expected result.

    This is not an argument for preserving manual work. An internal team may reasonably automate production or replace some external execution. The mistake is removing the decision owner along with the repetitive task. Software can create activity, but it does not own the downside when the activity was pointed in the wrong direction.

    Volume makes this distinction more important. Expanding five thoughtful articles into 50 mediocre ones does not become a sound strategy because generation is inexpensive. If the pages do not earn attention, trust, qualified visits, or business value, automation has only scaled the original error.

    Make human judgment visible, testable, and accountable

    Human expertise should not be defended as intuition that others must accept on faith. An unexplained opinion is no better than an unexplained tool score. Judgment becomes valuable to a team when someone can inspect the reasoning, challenge the assumptions, and evaluate what happened afterward.

    This also changes how practitioners present their work. If SEO is sold as a bundle of audits, spreadsheets, briefs, reports, and pages per month, software will usually look cheaper and faster. The practitioner has framed the engagement around the part that is easiest to automate. The differentiating deliverable should be a decision with evidence and ownership.

    Use a compact decision record

    Attach the following record to any recommendation that will consume meaningful time or introduce risk:

    • Observed condition: What exists now, stated without the audit tool’s judgmental language.
    • Evidence: The data or inspection that supports the diagnosis, plus any important gaps.
    • Affected surface: The pages, templates, queries, audiences, or journeys exposed to the condition.
    • Consequence: The search, user, or business outcome that may be harmed.
    • Options: Fix, test, monitor, accept, consolidate, remove, or choose another relevant response.
    • Recommendation: The selected option and the reason it outranks the alternatives.
    • Risk: What could go wrong if the team acts, and what could go wrong if it does not.
    • Success signal: The observable change that would support the recommendation.
    • Owner and review trigger: The person responsible and the evidence or event that will cause the decision to be reconsidered.

    Apply that format to a familiar H1 warning. Suppose a CMS produces three H1 elements on a small service site. Inspect whether the visible hierarchy is confusing, whether the main subject is unclear, and whether the affected pages show a related access or discoverability problem. If those checks reveal no meaningful consequence, record the decision to accept the condition for now and revisit it when the template changes or new evidence appears. If the hierarchy is genuinely broken, fix the shared template instead of opening repetitive page-level tickets.

    No action is not the absence of a decision when the evidence, risk, and review trigger are explicit. It is often the clearest sign that someone is prioritizing outcomes instead of performing compliance.

    Report decisions instead of completed activity

    Closing 2,000 crawler warnings may sound productive, but the number of issues closed is not an outcome. A useful reporting cycle should show:

    • The highest-consequence conditions found and the evidence behind them.
    • Which items were assigned to action, testing, monitoring, or acceptance.
    • Why the selected work outranked competing opportunities.
    • What changed after implementation and what remains uncertain.
    • Which risks the team knowingly accepted and what would trigger another review.
    • Which low-value projects were avoided, preserving capacity for more consequential work.
    • Which decision or dependency now requires leadership, engineering, product, or legal input.

    This format makes expert value inspectable. It also gives AI a better operating environment because the system can work from explicit objectives, classifications, constraints, and review conditions instead of an unexamined collection of SEO maxims.

    Change the next SEO planning conversation

    You do not need to redesign the whole operating model before improving the next decision. Start with the loudest warning in the current audit and force it through a disciplined sequence.

    1. Group repeated instances by root cause, template, or content type so the team is discussing conditions rather than raw counts.
    2. Inspect representative affected pages, including the ones most important to discovery, customers, or revenue.
    3. Rewrite the recommendation as a conditional claim with a mechanism and an expected signal.
    4. Choose an explicit disposition: act, test, monitor, accept, consolidate, remove, or investigate further.
    5. Name the person who owns the choice and the evidence that would cause it to change.

    If you are deciding whether software can replace a practitioner, ask questions that expose the missing layer:

    • Who decides whether a keyword represents valuable demand rather than available demand?
    • Who checks whether a proposed page should instead become a consolidation?
    • Who can explain why one template problem outranks thousands of isolated warnings?
    • Who carries the recommendation into engineering, product, legal, or leadership discussions?
    • Who owns the downside and changes the plan when the expected result does not appear?

    If no named person owns those decisions, you have bought throughput rather than strategy. The problem is not that the system lacks enough rules. It is that nobody is accountable for deciding when those rules apply.

    Use AI aggressively to reduce repetitive work and widen the field of evidence. Then require a human to connect that evidence to consequences, opportunity cost, and a defensible next action. On your next planning call, do not approve a ticket until its owner can name the harmed page or journey, explain the mechanism, and state what improvement would justify the work. That is the practical difference between SEO compliance and SEO judgment.

    References


  • Business Context for AI Marketing: A Practical Operating System

    Business Context for AI Marketing: A Practical Operating System

    Your AI can sound polished and still make the wrong marketing decision. It may address the wrong buyer, lead with a secondary benefit, treat an internal ambition as an approved claim, or pursue search demand that has little connection to your offer.

    If better prompting has not fixed that pattern, the missing input is probably business context. You need an approved, current layer of knowledge that tells AI what your business means, which facts it may use, and where its judgment must stop. Build that layer before you scale content generation or marketing automation.

    Why prompt polishing cannot supply missing business truth

    A prompt describes a task. It might specify the format, channel, topic, length, or desired action. It cannot reliably stand in for everything your organization knows about its customers, products, priorities, proof, and restrictions.

    When that knowledge is absent, the model has to complete the task using broad patterns. The result can be grammatically strong and strategically interchangeable. The problem is not necessarily weak writing. It is that the model has no basis for choosing your priority audience over a plausible adjacent audience, an approved product benefit over a popular category claim, or a defensible answer over a more confident one.

    A dedicated context layer is designed to hold, structure, and apply business knowledge so an AI marketer can tailor recommendations and outputs. That is a useful design principle, but reduced manual intervention should be treated as an outcome to validate in your own workflows, not as an automatic result of buying a tool.

    Separate four things that are often mixed into one oversized prompt:

    • Instructions: what the AI should do in this task.
    • Business context: what it needs to know to make choices consistent with your organization.
    • Evidence: what supports the claims it may publish.
    • Guardrails: what it must not infer, disclose, promise, or change.

    This separation makes defects diagnosable. If the format is wrong, fix the instruction. If the audience is wrong, fix the context. If a claim is unsupported, fix the evidence policy. If confidential information appears, fix access and publication controls.

    Key takeaways

    • Business context should change marketing decisions, not merely make prose sound more branded.
    • Store approved facts, priorities, boundaries, and evidence separately from task instructions.
    • Give each context item an owner, scope, status, and rule for resolving conflicts.
    • Retrieve only the context relevant to the current audience, market, offer, and channel.
    • Test context with real marketing tasks and evaluate factual fit, strategic fit, and claim discipline.

    Build context around the decisions AI must make

    Organized groups of customer, product, proof, priority, and constraint objects connect to a central processing device on a strategy table.

    Do not begin by uploading every document your company has produced. A document archive can contain useful knowledge, but it can also contain expired offers, unsupported claims, conflicting terminology, abandoned strategies, and information that should never reach a public workflow.

    Begin with a recurring marketing decision. For example: which angle should lead a landing page, which audience should receive a campaign, which questions deserve answer pages, or whether a query belongs in your organic search plan. Record the business knowledge required to make that decision correctly.

    Business layerContext to recordDecision it should change
    Strategic directionCurrent objective, priority market, priority offering, planning horizon, and explicit non-goalsWhat the AI recommends and what it deprioritizes
    AudienceTarget roles, situations, knowledge level, pains, desired outcomes, objections, and excluded segmentsWho the work addresses and which problem leads
    OfferApproved name, included capabilities, exclusions, prerequisites, availability, and customer responsibilityWhat the AI may promise or compare
    PositioningCategory, differentiation, alternatives, message hierarchy, and claims that require qualificationHow the offer is framed
    EvidenceApproved proof, claim-to-evidence relationships, citation locations, and unsupported assertionsWhich statements can be published confidently
    Brand languagePreferred terminology, prohibited wording, tone rules, definitions, and representative examplesHow the decision is expressed
    Search and discoveryCanonical entity names, topics, audience intent, query groups, answer boundaries, and relevant pagesWhat the organization should be discoverable for
    Operating constraintsGeographic scope, channel restrictions, required reviews, access limits, and escalation ownersWhat can be generated, published, or routed automatically

    For each layer, keep only information that changes a choice or constrains an output. A corporate history may be valuable background, but it does not belong in every content task. An approved definition of your product category may affect almost every page. Context earns its place through decision value, not document length.

    Separate durable knowledge from current work

    Context becomes unreliable when stable business facts and temporary campaign choices occupy the same undifferentiated file. Divide it by scope:

    • Durable business context covers identity, approved terminology, product boundaries, standing evidence rules, and persistent audience definitions.
    • Initiative context covers a launch, campaign, market, offer, or strategic priority that applies only within a named scope.
    • Task context covers the query, page, channel, format, deadline, and action required for the current output.

    Consider a hypothetical software company that generally serves finance teams but is running a campaign for controllers. Durable context defines the product and its approved capabilities. Initiative context makes controllers the priority audience for that campaign. Task context asks for an answer page addressing a controller’s specific question. The campaign should not silently redefine the company’s entire market, and the task should not rewrite product truth.

    Resolve contradictions before generation

    AI should not have to arbitrate between a sales deck, an old web page, and a current product record. If those materials disagree, more retrieval can make the result less reliable.

    Assign a canonical owner for each context type. Mark every item as approved, draft, disputed, or retired. Record which rule wins when scopes overlap. If the business has not resolved a conflict, label it as unresolved and prevent the system from converting either position into a public claim.

    A useful context layer does not pretend the organization is more certain than it is. It gives the AI a safe way to say that information is unavailable, request review, or leave a claim out.

    Make every context item usable and governable

    Long prose is easy to collect but hard to govern. One paragraph can mix an approved fact, a preference, a prediction, and an exception. When one part changes, nobody knows whether the whole paragraph remains valid.

    Store important knowledge as small records that can be approved, retrieved, superseded, or retired independently. Each record should contain:

    • Identifier: a stable name that workflows and reviewers can reference.
    • Statement: one clear fact, rule, priority, definition, or boundary.
    • Type: audience, offer, evidence, positioning, terminology, restriction, or another controlled class.
    • Scope: the brands, products, markets, audiences, channels, and initiatives to which it applies.
    • Status: approved, draft, disputed, or retired.
    • Authority: the internal system or person responsible for confirming it.
    • Evidence: the supporting material, where substantiation is required.
    • Effective condition: when the record applies and which event should trigger review.
    • Precedence: what should happen if another applicable record conflicts with it.
    • Publication permission: whether it is public, internal, restricted, or prohibited from generated output.

    This structure is useful even if you begin in a spreadsheet or content management system. The technology matters less than whether your team can tell what is true, where it applies, who approved it, and what happens when it changes.

    Translate adjectives into decision rules

    Context such as “sound professional” or “focus on quality” gives the model almost no business-specific direction. Replace abstract preferences with observable rules.

    • Replace “sound authoritative” with rules such as: lead with the decision, define specialist terms on first use, distinguish approved facts from recommendations, and omit claims that lack named support.
    • Replace “target enterprise buyers” with the roles involved, the problem each role owns, the objections that matter, the expected knowledge level, and the situations outside the campaign.
    • Replace “highlight our flexibility” with the exact configurable elements, fixed constraints, prerequisites, and wording that must not imply unlimited customization.
    • Replace “optimize for AI search” with the questions the page should answer, the entity names it must use consistently, the evidence available for each material claim, and the pages that establish supporting detail.

    The test is simple: could a reviewer look at the output and determine whether the rule was followed? If not, the context is still a mood rather than an operating instruction.

    Set an explicit order of authority

    Context records will eventually overlap. Establish an order before they do. A practical starting point is to let mandatory legal, security, privacy, and compliance restrictions override approved product facts; let approved facts override campaign language; and let campaign instructions override stylistic preferences. Your actual order should reflect your governance, but it must be visible to the workflow.

    Do not let recency win automatically. A newer brainstorm is not more authoritative than an approved product record merely because its timestamp is later. Status, ownership, and scope are stronger signals than freshness alone.

    Limit what each workflow can see

    Business context may contain unreleased plans, contractual restrictions, customer information, pricing logic, or competitive intelligence. Do not assume every model, integration, user, or publishing workflow should receive every field.

    Create separate public, internal, and restricted views. A public content workflow should receive only facts approved for publication. An internal planning workflow may receive confidential priorities but should be blocked from publishing them. Customer-level or personally identifiable information should not enter an AI workflow unless the organization has explicitly approved the tool, purpose, access controls, and handling process.

    Apply context to SEO, AEO, GEO, and campaign workflows

    A central repository is not enough. Context creates value only when the right records reach the right task. Passing the entire repository into every prompt can introduce irrelevant instructions and hidden conflicts. Retrieve the smallest approved bundle that can support the decision.

    Use this execution flow for a recurring marketing task:

    1. Name the decision, audience, market, offer, channel, and intended action.
    2. Retrieve context whose scope matches those fields.
    3. Resolve precedence and remove draft, retired, restricted, or irrelevant records.
    4. Ask the AI to produce the strategic decision or brief before it produces the finished asset.
    5. Check proposed claims against the approved evidence records.
    6. Generate the asset using only the approved decision, facts, and boundaries.
    7. Route missing evidence, conflicting context, and policy exceptions to the named owner.

    Generating the decision first matters. If you ask for the finished page immediately, a polished draft can hide an incorrect audience or message choice. A short brief exposes those errors while they are still cheap to correct.

    For SEO briefs

    Give the system more than a keyword. Supply the target audience, market, search intent, relevant offering, approved entity names, business objective, available evidence, existing page relationships, and topics that fall outside the offer.

    Require the brief to explain why the query belongs in your strategy. It should connect the query to a real audience problem, an answer your organization can support, and a useful next step. If the connection is weak, the correct output may be to deprioritize the query rather than manufacture relevance.

    For AEO and answer content

    Record the answer boundary as well as the answer. The system needs to know which conditions change the response, which terms require definition, which claims need evidence, and when a general answer would overstate what your business can support.

    Ask for a direct response that can stand on its own, followed by qualifications and supporting detail. Then verify that the visible page actually contains the facts used in summaries, metadata, and structured representations. A concise answer is useful only if compression has not removed a material condition.

    For GEO and AI discovery

    Use context to keep entity identity, product names, audience definitions, category language, and material claims consistent across related pages. Create a claim ledger for each important page with the claim, its supporting evidence, its visible location, its approval status, and any structured-data property that represents it.

    This discipline can make your published information clearer and more internally consistent. It cannot guarantee that a frontier model, answer engine, or AI search feature will retrieve, cite, summarize, or rank the page. Treat visibility as an external outcome to measure, not a promise encoded in the context layer.

    Schema markup should consume approved public facts; it should not become a back door for unverified or confidential context. The visible page, structured data, and canonical business record should agree. Schema is a publication format, not a truth engine.

    For campaigns and content operations

    Keep the strategic decision stable while adapting execution to the channel. The audience, offer boundaries, evidence policy, and intended action can remain consistent, while format, length, sequencing, and creative treatment change for email, paid media, social, landing pages, or sales enablement.

    Route human review to consequential points: new claims, unsupported comparisons, policy exceptions, sensitive audience targeting, and conflicts between records. When approved context already covers a routine choice, reviewers should not have to reconstruct the same business logic for every asset.

    Test the context system, not just the prose

    An analyst observes two parallel AI marketing test pipelines, one producing scattered results and the other producing consistent outputs through organized context modules.

    Do not judge the system by whether one draft sounds impressive. A fluent output can still be wrong, and a stylistic preference can distract reviewers from a serious context failure.

    Build a test set from real, recurring work: a search brief, an answer page, a campaign angle, a product comparison decision, a content refresh, or another task your team already reviews. Include ordinary cases, boundary cases, missing-information cases, and cases in which the correct response is to escalate or refuse a claim.

    For each task, compare a context-enabled run with a baseline using the same task and model settings. Evaluate the decision and evidence use before evaluating style. Your review should answer:

    • Did it select the intended audience, market, offer, and objective?
    • Did it use the approved terminology and canonical entity names?
    • Did it distinguish a verified fact from a recommendation, hypothesis, or unknown?
    • Did every material claim stay within the available evidence?
    • Did it obey exclusions, publication permissions, and review requirements?
    • Did it explain why the recommendation fits the current business priority?
    • Did it avoid dragging irrelevant context into the output?
    • Did the same approved facts remain consistent across channels and formats?

    Record failures against the context system rather than patching each draft in isolation.

    Observed failureLikely context defectCorrective action
    The output is polished but aimed at the wrong buyerAudience scope is vague, overlapping, or not retrievedAdd inclusion and exclusion rules, then test retrieval against the task scope
    The output contains a plausible but unsupported benefitClaims are not linked to evidence or unsupported claims are not prohibitedCreate a claim-to-evidence record and require escalation when support is absent
    The recommendation follows an outdated priorityInitiative status or precedence is unclearRetire the old record and specify which current initiative overrides durable defaults
    The answer is correct but interchangeable with competitorsPositioning is expressed as adjectives rather than decision rulesRecord the actual category, differentiators, alternatives, and message hierarchy
    Different workflows describe the same offer differentlyCanonical names and offer boundaries are duplicated across systemsReference one approved record and distribute channel-specific views from it
    The AI exposes internal plans in public copyPublication permissions or access scopes are missingSeparate public and restricted views, then block restricted fields from publishing workflows
    The system asks for manual review on every taskApproval status, boundaries, or exception rules are incompleteApprove routine cases explicitly and reserve escalation for named exceptions

    Define what ready means

    Your context layer is ready for a workflow when the AI can make the intended decision, identify the applicable evidence, respect the stated boundaries, and surface uncertainty without a reviewer rebuilding the brief from scratch. It is not ready merely because the repository is large or the generated copy sounds on-brand.

    Start with one recurring decision before attempting an organization-wide knowledge project. Capture only the context needed for that decision, assign authority and publication status, compare it with the baseline, and repair the defects you observe. Expand to another workflow only when the first context bundle consistently changes decisions in the intended way.

    The goal is not maximum context. It is the minimum approved context required for AI to do useful marketing work without inventing the business around your prompt.

    References


  • Leading RevOps Firms: How to Choose a Fractional Agency

    Leading RevOps Firms: How to Choose a Fractional Agency

    You are not buying RevOps in the abstract. You are deciding whether an outside team can repair your revenue engine without slowing sales, damaging CRM data, or leaving you with an expensive system nobody internally knows how to run.

    The difficult part is that fractional leadership, managed operations, CRM implementation, enablement, and AI automation are often sold under the same label. The right choice depends less on which firm tops a general leaderboard and more on the work you need someone to own. This guide helps you identify that work, match it to leading RevOps firms, and test whether a candidate can deliver it.

    Key takeaways

    • Choose the engagement model before the agency. Embedded fractional ownership, managed RevOps, project implementation, and coaching solve different problems.
    • Match lifecycle breadth to the actual break. A problem spanning marketing, sales, onboarding, retention, and expansion needs broader coverage than a contained CRM or outbound project.
    • Do not mistake a long platform list for operational depth. Test the candidate against a real workflow, data model, integration, or handoff from your environment.
    • Make every AI claim concrete. Require a named workflow, defined data access, approval rules, evaluation criteria, logs, failure handling, and a human owner.
    • Replace generic ranking weights with your own priorities. Published 2026 methodologies give substantially different weight to leadership, platforms, AI implementation, and lifecycle scope.
    • Treat recognizable client logos as context, not proof of fit. Even the ranking methodologies used for this shortlist assigned notable clients only 5% of the total score.

    Choose the RevOps engagement model before the firm

    A leadership team compares three visual pathways representing fractional leadership, managed operations, and technical implementation services.

    Fractional describes how you access leadership or operating capacity. It does not guarantee that a senior operator will be embedded in your team, that the agency will configure systems, or that it will cover the complete customer lifecycle. Confirm the operating model in the contract rather than relying on the label.

    • Embedded fractional ownership: Choose this when no internal leader owns the revenue system across functions. The outside operator should make decisions, coordinate stakeholders, prioritize work, and remain accountable for implementation rather than merely recommend changes.
    • Managed RevOps or RevOps as a Service: Choose this when you have an ongoing queue of administration, reporting, automation, data, and process work but do not want to assemble an internal team. The central buying question is how strategic decisions and recurring execution are divided.
    • Project-based specialist: Choose this for a bounded migration, CRM rebuild, routing redesign, CPQ implementation, outbound system, or integration. A contained scope should have explicit deliverables, acceptance tests, change controls, and a handoff owner.
    • Coaching, methodology, or enablement: Choose this when your internal team can implement but needs a common sales process, operating language, management cadence, or training system. Do not buy advisory work if your real constraint is a lack of hands-on capacity.

    Map the failure before contacting vendors. Trace the customer path from acquisition through qualification, opportunity management, closed-won, onboarding, adoption, renewal, and expansion. Mark the point where ownership becomes unclear, data stops moving, or teams begin using conflicting definitions.

    If failures appear across Marketing Operations, Sales Operations, and Customer Success Operations, favor a full-lifecycle team. If the problem stays inside a known system or workflow, a specialist may be faster and easier to govern. If your team knows what to do but applies it inconsistently, coaching may be sufficient. If nobody has authority to decide what should happen, you need an accountable fractional leader before you need more tools.

    A useful buying brief fits in one sentence: We need an accountable owner to improve this lifecycle handoff in these systems, with success judged by these business and operational measures. If you cannot complete that sentence, use discovery to define the problem before committing to a large implementation.

    Leading RevOps firms, organized by the work they fit

    No firm is the universal best choice. The table below treats leading RevOps companies as a fit map: what each appears equipped to handle, followed by the issue you should validate before signing.

    FirmConsider it whenWhat to validate
    DomestiqueYou are a B2B SaaS company seeking embedded, full-lifecycle coverage across Marketing Operations, Sales Operations, Customer Success Operations, platform implementation, and agentic infrastructure. Its reported capabilities include more than 60 senior operators, work with more than 250 B2B organizations, and hands-on AI agents and MCP integrations.Confirm which senior operators will work on your account, their allocated capacity, and the leadership participation expected from your team. The fractional-agency assessment specifically notes that active client leadership involvement is important at the strategy layer.
    Go NimblyYou run a Salesforce- or HubSpot-centered growth-stage SaaS environment and need revenue architecture, technical execution, AI readiness work, or RevOps coaching. Its positioning combines AI-enabled GTM strategy with Salesforce, HubSpot, Outreach, and Salesloft experience.Define how much hands-on Customer Success Operations coverage is included. Also identify the exact team composition because reported delivery pace can depend on scope and staffing.
    SkaledYou need a modular intervention rather than complete outsourced ownership. Available services span fractional CRO or VP leadership, CRM and automation support, revenue enablement, outbound performance, and an AI GTM system. A NoFraud case study reports a 126% pipeline increase and 95% MQL growth over eight months, but that result is case-specific rather than a forecast for another company.Ask who coordinates work when your scope crosses leadership, administration, enablement, and AI practices. Confirm which result from the relevant case work is transferable to your market, team, and funnel.
    RevPartnersYou are committed to HubSpot and want an ongoing RevOps-as-a-Service model, lifecycle measurement, GTM engineering, or Clay-powered outbound automation. Its Revenue Performance Model connects acquisition, conversion, retention, and expansion.Test the required depth outside HubSpot and Clay. Salesforce-primary companies and teams requiring extensive hands-on Customer Success Operations should define those needs explicitly before assuming they are covered.
    FullFunnelYou need broad B2B GTM strategy plus Sales Operations, Marketing Operations, or managed RevOps. Its listed platform footprint includes HubSpot, Salesforce, Clay, Apollo, and n8n.Ask which lifecycle stages the proposed team will own, which it will support, and which remain with you. Platform breadth should be converted into named deliverables and accountable operators.
    OperatusYour requirements center on Salesforce CPQ, MuleSoft, systems integration, or managed RevOps in a stack that may also include HubSpot, Apollo, Salesloft, LeanData, Outreach, or Marketo. Those platform and consulting specialties distinguish its systems-oriented offer.Verify whether your scope needs a technical implementation partner, a cross-functional operating leader, or both. Do not assume CPQ and integration expertise automatically includes deep marketing and post-sale ownership.
    Winning By DesignYou already have people who can execute and primarily need GTM methodology, the SPICED framework, revenue coaching, or certification. Its listed specialty is methodology training and advisory rather than comprehensive outsourced operations.Separate enablement deliverables from system-building deliverables. If you need CRM administration, integration work, data remediation, or ongoing workflow ownership, identify who will perform it.
    Think RevOpsYou want RevOps as a Service or stack optimization across HubSpot, Salesforce, and Gainsight. The inclusion of Gainsight makes it worth considering when customer-success tooling is part of the operating problem.Request direct evidence for any AI implementation requirement. AI or agentic capability was not listed for the firm in the 2026 fractional-agency comparison.
    RevOps AutomatedYou need GTM strategy, system integration, managed services, or AI-powered workflow automation in HubSpot and Salesforce. Its positioning emphasizes automation and AI-powered GTM workflows.Ask to see the architecture, controls, and operational results of a comparable workflow. Also define the required Customer Success Operations depth rather than inferring it from the managed-services label.
    Process Pro ConsultingYou have a focused HubSpot build, cleanup, or optimization requirement and prefer a specialist over a broad multi-platform firm. Its listed proficiency and specialty are centered on HubSpot.Inventory every system that must exchange data with HubSpot. If Salesforce, customer-success platforms, or agentic automation are material to the scope, determine whether another specialist will be needed.

    Your preferred order can change simply by changing the scoring weights. The fractional-agency methodology assigned 30% to platform proficiency and 30% to AI and agentic capability. The broader RevOps methodology assigned 30% to leadership, 25% to platforms, 20% to customer reviews, and 10% each to AI capability and lifecycle scope. A company prioritizing AI infrastructure could therefore reach a different answer from one prioritizing executive leadership or full-lifecycle operations.

    Rewrite those weights around your own risk. If your CRM is unstable, architecture and implementation depth should dominate. If functions disagree about stages, ownership, or forecasting, leadership and lifecycle scope matter more. If you already have strong operators and need a repeatable selling method, coaching quality should carry more weight than platform breadth.

    Do not let a logo wall override this work. Notable clients accounted for only 5% in the fractional-agency methodology and 5% in the broader company methodology. A famous client proves that some relationship existed; it does not establish that the agency handled your use case, systems, lifecycle stage, or engagement model.

    Use a buying process that exposes delivery risk

    Client and agency teams test a modular revenue workflow together while reviewing handoffs, system access, and contingency paths.

    Give every candidate the same written brief and ask for the same evidence. Otherwise, the most polished pitch will seem like the strongest capability even when candidates are solving different versions of your problem.

    Identify the operator who will actually own the work

    A senior leadership page does not tell you who will attend your operating meetings, make architecture decisions, configure systems, or resolve conflicts between marketing, sales, finance, and customer success. Ask the candidate to name the proposed operator and explain the delivery chain.

    • Who is accountable for the business outcome, and who performs the implementation?
    • Which proposed team members are employees, contractors, specialists, or executive sponsors?
    • How much concurrent client work does each assigned operator carry?
    • Who has authority to approve process, data-model, and automation decisions?
    • What happens when a requirement crosses practice areas or falls outside the original platform specialty?
    • Which responsibilities remain with your internal leaders, administrators, analysts, and front-line managers?

    Listen for clear ownership, not a large roster. A fractional executive who cannot direct implementation may leave you coordinating multiple delivery teams. An administrator without authority may complete tickets while the underlying operating disagreement remains untouched.

    Test platform depth with one of your real workflows

    Partner status and certifications are useful screening signals, but they do not prove that the proposed operator has solved your specific architecture problem. Bring a representative workflow to the evaluation: lead routing, account matching, opportunity-stage governance, CPQ approval, marketing attribution, closed-won handoff, renewal management, or expansion identification.

    Ask the candidate to map the systems of record, objects, fields, triggers, dependencies, permissions, exception paths, and reporting effects. Strong operators will surface ambiguities before proposing automation. Weak answers jump directly to a tool or produce a generic diagram that could apply to any company.

    Protect production data during implementation. Do not permit bulk CRM writes, object changes, routing changes, destructive merges, or new automations without an approved backup or export, a test environment where the platform supports one, defined validation checks, a release owner, and a rollback plan. A failed routing rule can hide demand; a poorly governed merge or overwrite can destroy history needed for attribution, forecasting, or account management.

    Trace ownership through the complete customer lifecycle

    Full-funnel language can describe measurement rather than hands-on ownership. Ask each candidate to walk through the lifecycle and identify who designs, implements, monitors, and improves every important handoff.

    • Acquisition to qualification: Who defines fit, intent, routing, response expectations, and rejection reasons?
    • Qualification to opportunity: Who governs stage entry, required fields, ownership changes, and pipeline reporting?
    • Closed-won to onboarding: Which data crosses the handoff, where is it stored, and who checks completeness?
    • Onboarding to adoption: How do product, service, or customer-success signals become visible to the revenue team?
    • Adoption to renewal: Who owns renewal dates, risk signals, commercial actions, forecasts, and escalation?
    • Renewal to expansion: How are expansion opportunities identified, assigned, measured, and separated from retention?

    If the answer becomes vague after closed-won, you are probably evaluating a sales-and-marketing operations firm rather than a complete lifecycle partner. That may be the right fit, but it should be an explicit decision rather than a discovery made after the engagement begins.

    Turn AI positioning into an auditable system design

    AI readiness, AI strategy, agent deployment, and agentic infrastructure are different deliverables. Domestique lists MCP server deployments, a deterministic harness framework, and Claude and Clay agents. Go Nimbly emphasizes AI-enabled architecture and readiness. Skaled combines maturity benchmarking, deployment, training, and certification. RevPartners focuses on Clay-powered allbound automation, while RevOps Automated emphasizes AI-powered GTM workflows. Put the exact capability you need into the scope instead of purchasing the broadest label.

    • Use case: What specific decision or task will the system assist, automate, or execute?
    • Inputs: Which CRM records, conversations, documents, enrichment data, or customer-success signals can it read?
    • Permissions: Can it only recommend an action, or can it create, update, route, message, or delete?
    • Control: Which actions require human approval, and who is accountable for that approval?
    • Evaluation: How will you test accuracy, completeness, consistency, and business usefulness before release?
    • Observability: What prompts, tool calls, outputs, errors, and record changes are logged?
    • Failure handling: What happens when the model is unavailable, uncertain, wrong, or given incomplete data?
    • Ownership: Who maintains instructions, integrations, permissions, evaluations, and vendor dependencies after launch?

    A working demo is more valuable than an AI strategy slide. Use representative but non-sensitive data and ask the candidate to show the complete path from input through reasoning or rules to the resulting CRM action. If the workflow can change customer records, routing, forecasts, or outbound messages, require approval boundaries and a recoverable path before production access is granted.

    Read reviews for engagement similarity, not just stars

    Review averages compress important differences. One 2026 methodology aggregated verified G2, Clutch, and Google ratings and rounded them to the nearest half star; the broader methodology weighted RevOps-specific engagements and rounded ratings to whole stars. Neither treatment tells you whether a positive review came from an embedded transformation, a migration, a small administration project, or executive coaching.

    Ask for references that match your company stage, primary platform, lifecycle problem, and engagement model. Questions about setbacks are more revealing than requests for general satisfaction: what slipped, which assumption proved wrong, how scope changed, who resolved cross-functional conflict, and what the client had to own internally.

    Scope the first engagement so you can judge real progress

    A strong statement of work turns RevOps language into operating commitments. It should make clear what will change, how you will accept it, who can decide, and how your team will run the result after the agency leaves.

    • Problem boundary: Name the lifecycle failure, affected teams, systems, records, and processes. Also state what is out of scope.
    • Baseline and outcome: Record the current operational and business measures that matter. Distinguish outputs such as workflows built from outcomes such as cleaner routing, more reliable stage data, better handoff completeness, or usable renewal visibility.
    • Target operating design: Define stages, ownership, systems of record, required data, decision rights, and escalation paths before automating them.
    • Deliverables: List the actual artifacts and system changes: architecture maps, data dictionaries, lifecycle definitions, configured workflows, dashboards, documentation, training, and governance procedures.
    • Acceptance criteria: State how each deliverable will be tested and who can approve it. Completion should not depend solely on the agency declaring a task done.
    • Change control: Specify test procedures, production permissions, release approval, backups, rollback, and incident ownership.
    • Internal participation: Name the executive sponsor, operational owner, system administrator, subject-matter experts, and front-line users whose decisions or feedback are required.
    • Handoff: Require accessible documentation, administrator training, unresolved-risk tracking, credential and integration ownership, and a prioritized backlog for work that remains.
    • Commercial boundaries: Clarify which work is included, what triggers additional fees or a change request, and how staffing changes affect delivery.

    If your problem is still poorly defined, make the first phase a diagnostic with implementation-ready outputs: a current-state map, target-state design, prioritized backlog, ownership model, dependencies, risks, and acceptance criteria. Do not accept a generic strategy presentation that forces the implementation team to rediscover the same requirements.

    Before your next agency call, write the one-sentence problem, list the systems involved, mark the affected lifecycle handoffs, and identify the proof you need to see. Send the same brief to each candidate. The safer choice is usually the firm that sharpens your scope, names tradeoffs, assigns an accountable operator, and makes its implementation testable.

    References


  • SEO Roadmap Planning: From Backlog to Measurable Outcomes

    SEO Roadmap Planning: From Backlog to Measurable Outcomes

    Your SEO plan probably is not short on work. The problem starts when leadership asks what will ship, which result it should change, and why it should receive scarce content, product, or engineering capacity.

    A useful roadmap answers those questions before work begins. It turns SEO from a stream of recommendations into a set of deliverable, measurable commitments without pretending that every good idea is ready to be scheduled.

    Key takeaways

    • Keep the backlog as your intake system. Reserve the roadmap for initiatives that have a business outcome, an owner, a delivery path, and a measurement plan.
    • Qualify initiatives with SCOPE: strategic alignment, confidence in delivery, ownership of execution, potential impact, and effort plus elapsed time.
    • Run quick, high-confidence work alongside longer initiatives so early results do not come at the cost of future growth.
    • Turn unresolved dependencies into discovery milestones. Do not present an initiative as committed delivery until the required team has accepted the work.
    • Report outcome evidence, not just task completion. Shipping is a milestone; it is not proof that SEO performance changed.

    First, separate roadmap commitments from backlog ideas

    A backlog and a roadmap solve different problems. Your backlog stores ideas, defects, requests, maintenance work, and opportunities that may deserve attention. Your roadmap communicates what SEO is expected to deliver, why it matters, who will deliver it, and how success will be judged.

    That distinction matters because an activity can be sensible without being roadmap-ready. Fixing canonical tags, adding schema, updating category pages, and building a programmatic directory can all be valid ideas. Their presence on a list tells you nothing about whether they support the current business goal, can obtain the necessary capacity, or should happen before something else.

    Before an initiative enters the roadmap, make its row answer these questions:

    1. What business outcome does this support? Name the commercial, customer, or risk-reduction result rather than using SEO improvement as the outcome.
    2. What will change? Define the affected templates, page groups, systems, or workflows precisely enough for another team to estimate the work.
    3. Why should it happen in this planning period? State the opportunity, problem, or dependency that makes the timing matter.
    4. What happens if it slips a quarter? Distinguish a genuine cost of delay from a preference to finish sooner.
    5. Who owns execution? Name the accountable team and confirm that it has capacity. A department mentioned in a spreadsheet is not an accepted commitment.
    6. What must happen first? Record technical, editorial, legal, data, design, and approval dependencies.
    7. What kind of impact do you expect? Label it as direct growth, protection of existing performance, or an enabler for later work. Do not force every initiative into a net-new traffic claim.
    8. How will you know whether it worked? Choose a delivery measure and an outcome measure before implementation starts.

    If you cannot answer those questions, keep the item in the backlog. The next action may be research, estimation, stakeholder alignment, or a technical proof rather than full delivery.

    Rewrite tasks as outcome-bearing initiative cards

    A weak roadmap row says rebuild internal linking. A usable initiative card says that the team will improve authority flow toward priority commercial pages through a CMS-supported linking system; SEO owns the analysis, development owns implementation, CMS support is a dependency, and success will be assessed through implementation coverage and subsequent search and business performance across the target page set.

    The wording exposes the real plan. If development has not accepted the dependency, the roadmap should commit to validating the linking design and securing an implementation estimate. It should not promise the completed system.

    Apply the same test to content and structured-data work. Adding schema is a deliverable, not an outcome. Publishing category copy is a deliverable, not an outcome. The roadmap needs to identify what the change is intended to influence and the evidence you will examine afterward.

    Use SCOPE to decide what is ready for the roadmap

    Project tiles move through a five-part inspection mechanism, with complete tiles advancing and incomplete tiles remaining in a holding area.

    SCOPE provides a practical qualification layer between collecting an idea and scheduling it. It evaluates strategic alignment, confidence in delivery, ownership of execution, potential impact, and effort plus elapsed time.

    DimensionQuestion to answerEvidence that makes the initiative roadmap-readyWarning sign
    Strategic alignmentWhich current business goal does this support?A named goal, audience, page group, and intended business effectThe only rationale is that the work is an SEO best practice
    Confidence in deliveryCan the work ship as designed?Known technical path, accepted dependencies, and clear acceptance criteriaThe plan assumes CMS, data, or engineering support that has not been validated
    Ownership of executionWho is accountable, and do they have capacity?A named owner for each material handoff and an agreed delivery windowSeveral teams are listed, but none has accepted responsibility
    Potential impactWhat value could the work create or protect?A defensible impact mechanism, affected scope, and relevant outcome measureHigh impact is asserted without explaining what should move or why
    Effort and elapsed timeWhat will the work consume, and how long will delivery take?An estimate that includes implementation, queues, reviews, QA, and observationOnly hands-on SEO time is counted while cross-team waiting time is ignored

    Score each dimension with a simple scale such as high, medium, or low, but always include a one-sentence rationale. The explanation is more useful than the label. It lets a reviewer challenge an assumption without reopening the entire strategy.

    Treat SCOPE as a set of gates, not a points contest

    Do not let a large potential impact conceal a missing owner or an impossible delivery path. Averaging all five dimensions into one number can make a speculative initiative look deceptively ready.

    Use three decision states instead:

    • Commit: The outcome matters, the delivery route is credible, ownership is accepted, and measurement is defined.
    • Investigate: The opportunity may be valuable, but feasibility, impact, effort, or dependency questions still need answers. Put the investigation itself on the roadmap when resolving that uncertainty is strategically important.
    • Backlog: The work may be useful, but it lacks sufficient alignment, urgency, evidence, or capacity for the current planning period.

    This prevents false precision. A programmatic SEO directory, for example, may have substantial upside while still belonging in the investigate state because engineering capacity, data quality, template design, or quality assurance remains unresolved.

    Sequence quick wins beside long-horizon initiatives

    Prioritization decides what deserves attention. Sequencing decides what starts first, what runs in parallel, and which dependency must clear before another team can act.

    The following delivery windows are illustrative planning examples, not universal benchmarks. Your architecture, review process, release cycle, and team capacity can change them substantially.

    Illustrative initiativePrimary valueIllustrative delivery patternLikely roadmap role
    Correct canonical tags on product pagesProtect or recover existing ranking signalsLow effort; about two weeks in the exampleHigh-confidence quick win
    Add schema to priority commercial pagesSupport search visibility and click-through performanceLow effort; about three weeks in the exampleQuick win with incremental upside
    Consolidate thin category pagesReduce cannibalization and prevent additional problemsMedium effort; about six weeks in the exampleProtective work requiring stakeholder alignment
    Rebuild internal linking architectureImprove authority flow across the siteMedium effort; roughly one quarter for data-led analysis in the exampleLonger, compounding initiative
    Build a programmatic directory from product dataCapture net-new organic demand at scaleHigh effort; about half a year in the exampleLarge bet with engineering and QA dependencies

    A balanced roadmap usually needs three lanes:

    • Ship-now work: Low-effort, high-confidence improvements that can produce evidence while larger projects are still moving through their dependencies.
    • Compounding work: Initiatives such as internal-linking architecture or scalable landing-page systems whose effects arrive later but can influence a much larger part of the site.
    • Risk-reduction work: Technical discovery, prototypes, data validation, stakeholder decisions, and estimates that convert an uncertain opportunity into a deliverable initiative.

    Start the dependency path for the long bet while the quick wins are being delivered. Waiting until every small task is finished creates a gap: early wins become exhausted before the larger work is ready to produce an effect. A plan dominated by short tasks can encounter an outcome wall around the fourth month while initiatives with compounding potential are still waiting to begin.

    Sequence by the critical path, not by the apparent size of the SEO task. If a CMS change needs an architecture review, begin that conversation before completing analysis that depends on the proposed implementation. If a content consolidation needs commercial approval, obtain agreement on the decision criteria before writers revise pages that stakeholders may later insist on keeping.

    Also separate protection from growth. Canonical corrections may recover or preserve existing equity without creating new search demand. A new directory may address demand that the site cannot currently capture. Both can deserve investment, but they should not carry the same outcome claim.

    Plan around the capacity and dependencies you really have

    SEO initiatives do not compete only with one another. They compete with product features, platform maintenance, design work, content commitments, and engineering priorities. A technically sound recommendation can still be a poor roadmap commitment when the delivery team cannot accept it.

    Before assigning a delivery period, complete a dependency handshake with every team whose work is essential:

    • Name the person or team accountable for the handoff.
    • Confirm the earliest realistic point at which the work can enter that team’s queue.
    • Provide the inputs they need to estimate it, including affected templates, business rules, data requirements, and acceptance criteria.
    • Include review, release, rollback, and QA requirements in elapsed time.
    • Record what the SEO team can progress independently while the dependency is pending.
    • Define what changes in the roadmap if the dependency moves.

    If that handshake has not happened, change the commitment. Replace launch a dynamic internal-linking system with validate the CMS approach, complete the specification, and obtain an accepted engineering estimate. This is not weaker planning. It is an accurate description of the outcome the team can control.

    Use stage gates for programmatic SEO

    Programmatic SEO exposes unrealistic roadmaps quickly. Generating useful pages from a database can require data work, page logic, reusable components, editorial standards, engineering, and quality assurance. Scaling before those pieces are proven can produce large numbers of thin pages rather than a useful directory.

    Structure the initiative as a sequence of decisions:

    1. Validate the opportunity. Define the demand, intended user task, page entities, and reason each page deserves to exist.
    2. Audit the data. Identify which fields are complete, reliable, unique, and suitable for public presentation.
    3. Prototype representative pages. Prove the template, content logic, useful components, and internal-linking path before committing to scale.
    4. Set quality acceptance criteria. Specify what makes a page complete and useful, which conditions prevent publication, and how exceptions will be handled.
    5. Confirm production ownership. Assign responsibility for data changes, template defects, QA, and ongoing maintenance after launch.
    6. Authorize scale only after the gates pass. A large inventory is not valuable merely because it can be generated. The roadmap should prioritize rich, differentiated pages and explicitly manage the quality risk of producing thin pages at scale.

    This approach lets you preserve a high-upside idea without disguising uncertainty. Early roadmap periods can contain the work required to earn a scale decision; later delivery remains conditional on what that work reveals.

    Run the roadmap as a measurement and decision system

    A team studies connected initiative blocks on a circular table as signals flow to options for continuing, adjusting, or pausing the work.

    A roadmap becomes another task tracker if its reporting stops at done. Every initiative needs a baseline, a delivery signal, an SEO outcome signal, and a business measure that matches the type of impact being claimed.

    • Canonical correction: Track implementation across the affected template or URL set, then examine canonical selection, indexation behavior, organic landing-page performance, and the business results of affected pages. Frame the expected value as protection or recovery unless the change also creates new eligible pages.
    • Schema implementation: Track valid deployment on the intended commercial pages, eligibility for the relevant search appearance, impressions and click-through behavior where measurable, and downstream qualified visits or conversions. Do not promise an appearance that a search engine controls.
    • Category consolidation: Track redirects, canonicalization, content migration, and internal-link updates, then assess whether competing URLs have been reduced and whether the retained pages are capturing the intended queries and business activity.
    • Internal-linking architecture: Track whether the target page set receives the intended links and paths, then assess crawl and discovery signals, relevant rankings, organic entry traffic, and conversions on priority pages.
    • Programmatic directory: Track template quality, data completeness, published inventory, and QA outcomes, then assess indexation, organic demand captured by the directory, engagement with its useful features, and attributable business results.

    Write the measurement plan before work starts. Record the affected scope and baseline date, the expected direction of change, the evidence needed to continue investing, and the conditions that would trigger revision or cancellation. This reduces the temptation to select a flattering metric after launch.

    Your roadmap review should answer five questions for each active initiative:

    1. What changed since the previous review?
    2. What evidence do we have from delivery, search performance, and business performance?
    3. Which assumption has been confirmed or weakened?
    4. What decision follows from that evidence?
    5. Which dependency or capacity risk could change the next commitment?

    This changes the status conversation. Instead of reporting that schema was added or category pages were updated, you can state whether deployment is complete, whether the expected search behavior is observable, whether business impact can yet be evaluated, and what the team will do next.

    Start with your current backlog. Move only the initiatives with a clear outcome, credible owner, understood dependencies, honest impact claim, feasible delivery path, and measurement plan into the roadmap. Put a quick, high-confidence improvement in motion while beginning the dependency work for a larger bet. Everything else can wait in the backlog or become a defined investigation until it is ready to earn a commitment.

    References