Tag: Business Strategy

  • How to Choose the Right eCommerce Website Design Agency

    How to Choose the Right eCommerce Website Design Agency

    Choosing an eCommerce design agency gets risky when every proposal promises the same things: a modern storefront, better conversion, and seamless integration. Those phrases will not tell you whether the team can preserve organic visibility, model customer-specific pricing, or move a live catalog without breaking the buying path.

    The useful question is not, “Which agency is best?” It is, “Which team can prove it has solved the operating problem our store actually has?” The process below turns that question into requirements, evidence, a weighted decision, and a contract you can enforce.

    Define the store’s operating job before you shortlist agencies

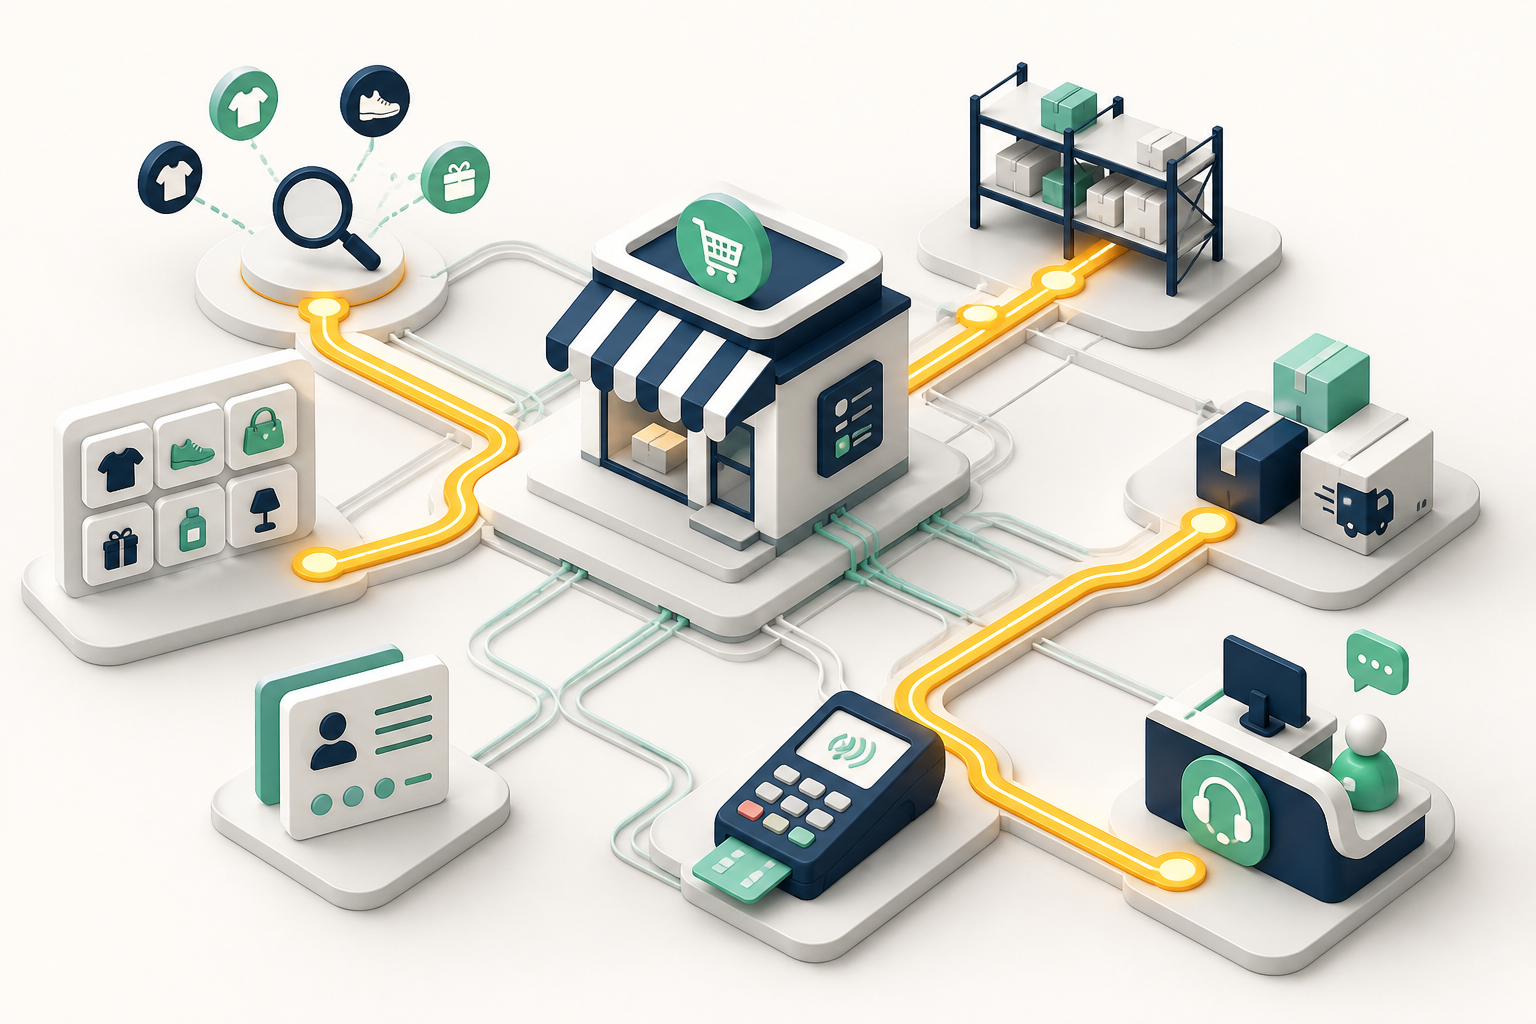
    An isometric online storefront connects to catalog, inventory, payments, shipping, customer accounts, search, and support systems.

    An attractive interface is only the visible layer of an eCommerce system. Underneath it sit product data, pricing rules, customer accounts, inventory, payments, fulfillment, analytics, search visibility, and the operational systems your team already uses. Your shortlist will be unreliable until you decide which of those problems the project must solve.

    Start by writing one sentence that describes the commercial job, the customer, and the change you need. Use a form such as:

    • For a direct-to-consumer business: “Replace our current storefront with a faster, easier product-discovery and checkout experience without losing valuable organic landing pages.”
    • For a manufacturer or distributor: “Give logged-in buyers customer-specific pricing, live availability, repeat ordering, and account self-service using data from our ERP.”
    • For a migration: “Move the existing catalog, customers, orders, content, and search equity to the selected platform while reducing the custom code we must maintain.”

    That sentence forces an important distinction. A consumer brand may need merchandising, storytelling, acquisition landing pages, and checkout optimization. A B2B seller may need account hierarchies, approval rules, negotiated prices, payment terms, quick-order tools, and an ERP-backed buyer portal. These are not different visual styles. They are different operating models.

    For manufacturers and distributors, buyer-portal capability and ERP design experience warrant separate evaluation. They were weighted at 15% and 13%, respectively, in a B2B agency assessment. That separation matters because a team can design a polished account dashboard without knowing how to make its inventory, pricing, and order status agree with the system of record.

    Turn the operating job into a requirements sheet covering:

    • Customer model: anonymous shoppers, account customers, dealers, distributors, procurement teams, or a mixture.
    • Critical buying journeys: product discovery, quote request, purchase, approval, reorder, subscription, return, or account service.
    • Catalog and commercial rules: variants, bundles, large assortments, market-specific catalogs, contract prices, volume rules, and restricted products.
    • Systems and data ownership: eCommerce platform, ERP, product information system, CRM, payment service, tax service, fulfillment tools, analytics, and marketing platforms.
    • Discovery requirements: existing organic landing pages, internal search, product feeds, structured data, indexation rules, redirects, and content workflows.
    • Delivery constraints: launch dependencies, internal approvers, compliance needs, content readiness, available technical staff, and the support model after launch.

    Label each requirement as mandatory for launch, valuable if the budget allows, or suitable for a later phase. An agency should not be able to turn an essential workflow into a surprise change request simply because it appeared deep in an unprioritized feature list.

    Do not let a preferred platform reverse this sequence. Platform credentials can show that an agency knows a technology, but the platform still has to support your commercial rules and integrations. Define the job first, select the platform against that job, and then evaluate whether the agency has relevant people available to deliver it.

    Ask for proof at the level of the use case

    Logo walls, awards, aggregate ratings, and attractive screenshots are useful screening signals. None proves that the proposed team can handle your project. The closer the evidence is to your actual use case, the more weight it deserves.

    The limits of ratings are easy to see. Among seven selected agencies in a 2026 market set, average review scores ranged only from 4.0 to 4.8 while buyer-portal capability ranged from minimal to extensive and ERP experience ranged from unreported or limited to extensive. A strong rating can support your decision, but it cannot tell you whether the agency has the capability your store needs.

    Ask each candidate for an evidence pack tied to your requirements. It should include:

    • A case study with the same commerce model, not merely the same industry or platform.
    • A live or recorded walkthrough of the relevant workflow, including account, mobile, empty, error, and exception states where applicable.
    • A clear account of what the agency actually delivered. Strategy, design, platform configuration, integration, data migration, SEO, and ongoing marketing may have been divided among several parties.
    • The business or operational outcome, how it was measured, and which constraints affected it.
    • The names, roles, platform credentials, and expected availability of the people proposed for your project.
    • A client reference whose project involved the capability you consider most difficult or risky.

    “Similar project” needs a precise meaning. Match evidence across the dimensions that create complexity: customer type, platform, catalog, pricing model, integrations, geographic reach, migration scope, and internal operating model. A fashion storefront on Shopify is not strong evidence for a distributor that needs account pricing from an ERP, even when both businesses sell online.

    Audit each case study with direct questions:

    • What problem existed before the project?
    • Which requirements forced a custom solution, and which were handled natively by the platform?
    • Which systems supplied product, price, inventory, customer, and order data?
    • What failed or changed during delivery, and how did the team respond?
    • Which result can be attributed to the redesign, and what else changed at the same time?
    • What does the agency maintain now, and what does the client’s team own?

    If an agency cannot explain how an outcome was measured, treat the work as evidence of creative quality rather than commercial impact. If it cannot identify its responsibility, do not credit it for the whole implementation. If the proposed delivery team differs from the case-study team, assess the people you will actually receive.

    Use a weighted scorecard without letting averages hide deal-breakers

    Three storefront models are evaluated with colored priority tokens, while only one has a complete path to a checkout parcel.

    A scorecard prevents the most polished presentation from winning by default. For a manufacturer or distributor, the following B2B weighting provides a practical starting point. It reflects the greater delivery risk carried by portals, commercial rules, and ERP-connected experiences. It should not be copied unchanged for a direct-to-consumer brief.

    CriterionStarting weightEvidence worth scoringWeak evidence
    B2B specialization and platform certifications25%Relevant credentials held by the assigned team plus comparable technical workA large badge collection with no matching workflow or named delivery team
    Average online review score20%A consistent pattern across established review platforms, with comments relevant to deliverySelected testimonials with no independent context or explanation of project scope
    Portfolio and client success17%Comparable implementations, attributable responsibilities, and measurable outcomesScreenshots, brand names, or unverified claims without operational detail
    Buyer portal and self-service UX15%Working account dashboards, repeat ordering, approvals, quotes, and customer-specific experiencesA generic login page or mockup presented as a complete portal
    ERP integration and operational design13%Clear data ownership, interface behavior, failure handling, reconciliation, and order workflows“We integrate with anything” without architecture or comparable implementation evidence
    Industry experience and specialization10%Understanding of the industry’s catalog, buying process, operating constraints, and terminologyIndustry logos that do not connect to the requirements in your brief

    Give every agency the same evidence grades: absent, weak, acceptable, strong, or exceptional. Define what each grade means before reviewing proposals, convert the grades to a consistent numeric scale in your spreadsheet, apply the weights, and record a short justification beside every score. A score without a note will be hard to defend when stakeholders remember the presentations differently.

    Keep hard gates outside the weighted total. These are conditions that cannot be averaged away, such as an unsupported required platform, missing security or compliance capability, inability to meet a fixed business dependency, an unacceptable subcontracting model, or refusal to accept essential contract terms. An agency that fails a hard gate should not win because it scored well on brand design.

    Change the weights before proposals arrive if your project is not B2B manufacturing or distribution. A consumer retailer may put more emphasis on merchandising, mobile shopping, brand expression, experimentation, content, conversion, and SEO migration. A platform migration may put more emphasis on data mapping, redirects, integrations, cutover planning, and maintainability. Changing weights after seeing the candidates simply lets preference masquerade as analysis.

    Turn the final pitch into a working session, then contract the details

    Use one scenario to expose how the team thinks

    Give every finalist the same realistic scenario from your requirements sheet before the meeting. Ask the people who would do the work to walk through their response. For a B2B seller, that might be a logged-in buyer seeing an account price, discovering that requested quantity is not fully available, seeking approval, and placing an order that must reach the ERP. For a migration, it might be preserving a valuable category URL while product taxonomy, filters, and platform templates change.

    Use the session to ask:

    • Which part would you solve with native platform functionality, an application, configuration, or custom code, and why?
    • Where is the source of truth for each piece of data, and what should the customer see when that source is unavailable?
    • Which assumptions must be validated during discovery?
    • How will design decisions be tested against real catalog content and exception cases?
    • How will URL changes, redirects, indexation, internal links, structured data, product feeds, and analytics be handled?
    • Who makes the technical decision, who performs the work, and who remains accountable when another vendor is involved?
    • What is explicitly excluded from the proposal?

    Good answers reveal choices, dependencies, and tradeoffs. Be wary of answers that make every integration sound routine or every requirement sound native. The purpose of the session is not to demand a complete solution before discovery. It is to see whether the team notices the hard parts and has a credible method for resolving them.

    Communication also needs evidence. Ask who owns decisions, how unresolved issues are recorded, what you will see during delivery, and how scope changes are approved. Then compare those answers with the client reference. A personable salesperson is not a substitute for a delivery system.

    Replace vague promises with acceptance criteria

    Do not accept “custom eCommerce website,” “seamless ERP integration,” “SEO-friendly build,” or “AI-ready content” as complete deliverables. The statement of work should identify the artifact, owner, review process, dependency, and acceptance condition for each project area.

    • Discovery: approved requirements, customer journeys, functional decisions, system map, data ownership, risks, and delivery plan.
    • Experience design: named templates and components, responsive behavior, account states, error states, accessibility requirements, and content responsibilities.
    • Platform and integration: native features, applications, custom code, interfaces, field mappings, synchronization behavior, failure handling, reconciliation, and technical documentation.
    • Content and migration: catalog mapping, customer and order history, editorial content, asset handling, validation, and ownership of cleanup work.
    • Search and machine-readable discovery: URL inventory, redirect map, canonical and indexation rules, internal linking, metadata ownership, XML sitemaps, product feeds, and responsibility for relevant Product and Organization structured data.
    • Quality and launch: test responsibilities, supported environments, performance and accessibility measurements, analytics validation, cutover steps, backups, rollback conditions, and post-launch monitoring.
    • Support: warranty boundaries, response process, maintenance ownership, documentation, training, and the transition to internal staff or another provider.

    For AI search and answer-engine visibility, insist on concrete implementation language. Product facts, prices, availability, policies, brand information, and supporting content should remain accessible on stable, crawlable pages and be represented consistently in visible copy, structured data, and feeds where applicable. No agency can contractually guarantee inclusion or ranking in an AI-generated answer. “AI-ready” without named outputs and validation steps is not an acceptance criterion.

    The commercial terms should also state how assumptions, dependencies, delays, and change requests affect cost and delivery. Confirm code and design ownership, application and platform fees, third-party licenses, data access, subcontractors, termination assistance, and what happens to unfinished work. For provisions affecting intellectual property, personal data, liability, indemnity, or termination rights, have qualified counsel review the actual agreement; an agency scorecard cannot resolve legal exposure.

    Before signing, speak with a reference whose implementation resembles yours. Ask what changed after discovery, which responsibilities were unclear, how the agency behaved when delivery became difficult, what the client still depends on the agency to operate, and whether the team named in the sale remained involved. Those answers help you distinguish a successful launch from a maintainable commerce operation.

    Key takeaways

    • Select for your commerce model and operating complexity, not for the most attractive generic portfolio.
    • Write critical buying journeys, systems, data ownership, discovery requirements, and exception cases before requesting proposals.
    • Score proof that matches your use case. Ratings, credentials, and brand names are supporting signals, not substitutes for comparable delivery evidence.
    • Use preset weights and separate pass/fail gates so a strong presentation cannot conceal a missing essential capability.
    • Put the proposed delivery team through the same working scenario and listen for dependencies, failure states, and honest tradeoffs.
    • Contract specific artifacts and acceptance conditions for design, integration, migration, SEO, structured data, launch, and support.

    Your next move is to write the operating brief and hard gates before booking another pitch. Send the same brief to every shortlisted agency and refuse to score a claim that has no relevant evidence behind it. Once that discipline is in place, agency selection becomes a controlled business decision rather than a contest between sales presentations.

    References

  • How to Align SEO and AI Sales Promises With Delivery

    How to Align SEO and AI Sales Promises With Delivery

    The contract is signed. The client expects a ranking, a traffic result, or inclusion in AI answers. Then the delivery team discovers that nobody validated the promise before it became a commitment.

    By kickoff, this is no longer a wording problem. The client may already have repeated the promise to executives, attached a deadline to it, and put their own credibility behind it. You need a sales process that protects that trust before the proposal is sent, without forcing every salesperson to become a technical SEO or AI search specialist.

    Treat misalignment as a system failure, not a sales personality problem

    Most sales-delivery conflict starts with incentives. The people closing work are commonly rewarded for signing customers, increasing contract value, renewing accounts, and shortening the sales cycle. The delivery team is judged by whether the work can be executed and whether the client sees value.

    That structure encourages certainty at exactly the point where SEO and AI visibility require qualification. A hesitant buyer wants a direct answer about rankings, timelines, traffic, citations, or appearances in ChatGPT and Google AI Overviews. A rep can make the deal easier to close by removing caveats. But the uncertainty has not disappeared; it has merely moved into delivery.

    Sales still performs work the delivery team cannot replace. A strong rep uncovers the commercial problem, qualifies the buyer, translates technical capabilities into business value, manages follow-up, and earns enough trust to move a decision forward. Alignment should preserve those strengths while creating clear points where technical judgment is required.

    Use this test before approving any SEO, AEO, or generative engine optimization proposal:

    • Can delivery identify exactly what work has been sold?
    • Can delivery separate the promised work from the hoped-for business outcome?
    • Are the client’s implementation duties written down?
    • Has someone qualified the website, brand, competition, authority, demand, and internal constraints relevant to the promise?
    • Does the measurement plan define what will be observed without implying control over a search engine or AI platform?
    • Would the client hear the same explanation from the salesperson and the specialist?

    If any answer is no, the proposal is not ready. A better pitch deck will not fix it. You need operating controls around the deck.

    Build six controls around every SEO and AI offer

    A cross-functional team moves a project through six unlabeled verification and handoff checkpoints in an operations room.

    A sales enablement system should tell a rep what can be sold, to whom, under which conditions, and when an expert must become involved. The following controls are small enough to use during a live deal and specific enough to prevent an unsupported claim from reaching a contract.

    ControlQuestion it must answerRelease condition
    Boundary sheetWhat can never be promised?The proposal contains no guarantee of rankings, traffic, revenue, citations, or AI-answer inclusion.
    Qualification cardCan this prospect use the service successfully?The business goal, starting condition, implementation capacity, access, decision owner, and measurement method are recorded.
    Approved claim libraryHow may the offer and its likely value be described?Outcome language identifies uncertainty, dependencies, and the part the provider actually controls.
    Responsibility mapWho must approve, provide, publish, or implement each item?Provider and client responsibilities appear in the scope, not only in internal notes.
    Case-study context sheetWhich conditions made a past result possible?Sales can explain the relevant starting point, service mix, client participation, and why the result is not a guarantee.
    Exception and feedback logWhich sales claims or deal types repeatedly create delivery problems?Each recurring issue changes a boundary, qualification rule, claim, or escalation trigger.

    The boundary sheet should be short enough to consult during a call. It should prohibit guaranteed rankings, fixed outcome dates set before discovery, guaranteed appearances in AI answers, and any statement that hides required client work. It should also distinguish a committed deliverable from an outcome hypothesis. Completing an audit is a deliverable. Achieving a particular ranking is not.

    The claim library should be equally practical. Give reps approved language for common questions, objection handling, proposals, and follow-up emails. Include a prohibited version beside each approved version so the difference is unmistakable. Review the library whenever delivery has to correct an expectation that originated before kickoff.

    Case studies need context, not just a chart. A result may have depended on a technically capable client, fast implementation, an established brand, sufficient authority, a particular competitive environment, or a broader combination of services. If those conditions are missing from the sales story, the buyer may reasonably assume the result came from the named service alone.

    Qualify the client’s ability to act before prescribing the service

    A prospect can have a real visibility problem and still be a poor fit for the proposed engagement. The deciding issue is often not desire or budget. It is whether the organization can supply access, approve recommendations, publish changes, and keep the necessary people involved.

    Require the salesperson to answer these questions before recommending a service package:

    1. What business decision is driving the request? Clarify whether the buyer needs discovery, qualified demand, reputation support, competitive intelligence, lead growth, or evidence for an internal strategy.
    2. What does the buyer think is broken? Capture their diagnosis without treating it as proven. A request for schema, content, links, or AI optimization may be a requested tactic rather than the actual problem.
    3. What has been reviewed? Do not commit to an outcome timeline or service mix before the relevant website, content, technical condition, authority signals, and measurement setup have been examined.
    4. Who can implement the work? Name the people responsible for development, content, legal review, brand approval, analytics, and publishing where those functions affect delivery.
    5. What can block implementation? Record release cycles, approval queues, compliance constraints, platform limitations, and any other dependency already known to the buyer.
    6. How will progress be judged? Define the search surfaces, reporting inputs, agreed deliverables, and business indicators before anyone promises a dashboard.
    7. Which assumption could invalidate the proposed solution? Surface it while the scope can still be changed, not after delivery begins.

    Turn the answers into decision rules. If the relevant properties have not been reviewed, sell discovery or an audit before prescribing a full program. If the client cannot name an implementation owner, do not attach outcome expectations to a delivery schedule. If the right service mix is uncertain, route the deal to a specialist. If a critical assumption cannot be tested before signing, label it in the proposal and make the next decision contingent on what discovery finds.

    AI visibility requires an additional qualification step. Ask which platforms, topics, prompt families, audiences, and business outcomes matter. Appearing for an isolated prompt is not the same as becoming consistently discoverable for a commercially relevant topic. Likewise, a visibility score is a measurement produced by a particular methodology, not proof that a provider controls an AI system.

    A handful of prompts, a third-party visibility score, a mention dashboard, or a competitor’s appearance in an answer can create urgency without proving that a specific intervention will produce inclusion. Treat those signals as inputs to investigation. Record the platform and prompt set being monitored, explain what the metric does and does not represent, and never convert an observation into a guarantee.

    Turn every promise into an auditable claim

    A salesperson and technical specialist inspect a transparent service commitment while a delivery professional connects it to a workflow.

    A safe claim is not merely cautious. It tells the buyer what will happen, what success means, what remains uncertain, and what they must do. If a statement cannot be translated into scope, responsibility, evidence, and a review point, it should not appear in the proposal.

    Build each material claim from five parts:

    • Objective: the business or visibility problem the engagement is intended to address.
    • Controlled work: the audits, analysis, strategy, implementation, content, technical changes, or monitoring actually included.
    • Evidence: the deliverables and agreed measurements that will show what was completed and what changed.
    • Dependencies: the client actions, platform behavior, competitive conditions, and other factors outside the provider’s control.
    • Decision point: when the evidence will be reviewed and how the next action will be chosen.

    Use the following rewrites as patterns, then adapt them to the service you genuinely provide:

    Claim that creates delivery riskDefensible version
    "We will get these pages to the top of Google.""We will identify and prioritize the technical, content, and authority constraints affecting these pages, complete the work listed in scope, and measure agreed search indicators. Rankings are not guaranteed."
    "We will get your brand into AI answers.""We will assess how the brand and its information are represented across the agreed AI search topics, improve the eligible assets included in scope, and monitor the defined prompt set. Inclusion and citation are controlled by the platforms and cannot be guaranteed."
    "You should see the result by this date.""We will complete the listed deliverables by the agreed dates if dependencies are met. The timing of search or AI visibility changes depends on implementation and platform behavior, so outcome timing is not guaranteed."
    "Our dashboard proves your AI visibility is improving.""The dashboard tracks the defined prompts, mentions, citations, and other stated inputs. We will interpret those measurements alongside business and search data; the score is not a universal measure of visibility."
    "Our team handles everything.""Our team owns the items assigned to us in the responsibility map. Your team must provide the listed access, reviews, approvals, subject knowledge, and implementation support by the agreed checkpoints."

    Do not bury the defensible language in disclaimers while leaving the headline claim untouched. The proposal title, sales call, scope, statement of work, and kickoff explanation must describe the same engagement. A caveat cannot repair a sales narrative built around certainty.

    Separate reporting into three layers so the client can see what each metric means:

    • Delivery evidence: what was analyzed, created, changed, published, or implemented.
    • Visibility evidence: what happened in the agreed search results, AI answers, mentions, citations, rankings, or other monitored surfaces.
    • Business evidence: what happened to relevant traffic, leads, revenue, or another agreed commercial indicator where reliable measurement is available.

    This prevents a completed task from being presented as a business result, and it prevents a third-party score from being treated as proof of commercial value. It also gives delivery a useful way to explain progress when the work is complete but an external system has not produced the hoped-for outcome.

    Put delivery inside the deal and keep sales accountable after signature

    Delivery does not need to attend every sales call. It does need a defined gate for opportunities where technical uncertainty could materially change the scope, price, timeline, or likelihood of success.

    Require specialist review when any of these conditions appears:

    • The buyer requests a guarantee, a specific ranking, an AI citation, or an outcome by a fixed date.
    • The website, data, or implementation environment has not been reviewed.
    • The engagement combines services and the correct mix is unclear.
    • The buyer’s requested tactic does not clearly match the stated business problem.
    • The client has limited development, content, analytics, legal, or approval capacity.
    • The measurement method relies heavily on a proprietary visibility score or a narrow prompt sample.
    • The scope needs a custom claim, exception, or responsibility model that is not already approved.

    The specialist’s job is to validate fit, identify missing discovery, correct claims, and approve the service combination. Record that decision in the deal file. A quick private conversation can improve a pitch, but it cannot protect the handoff if nobody can see what was approved.

    Use a closed-loop sequence:

    1. Sales completes the qualification card and records the buyer’s requested outcome in the buyer’s own terms.
    2. Delivery reviews any triggered risk and marks the opportunity approved, approved with changes, or not ready pending discovery.
    3. The proposal is assembled from approved scope and claim language, with responsibilities and assumptions visible.
    4. Before kickoff, sales transfers the decision history, stakeholder concerns, objections, approved claims, dependencies, and unresolved risks to delivery.
    5. At kickoff, the client hears the same objective, scope, limitations, responsibilities, and measurement method used during the sale.
    6. After the first meaningful delivery checkpoint, sales and delivery review any expectation correction, missing dependency, or scope surprise and update the operating controls.

    Shared accountability should extend beyond signed revenue. Add indicators that show deal quality: qualification completeness, handoff completeness, sales-originated scope changes, missing client dependencies, expectation corrections, and whether specialist-review rules were followed. These measures should be used to improve judgment and incentives, not to punish a rep for documenting genuine uncertainty.

    Delivery also needs accountability. Specialists must respond within the internal sales process, explain risk in commercial language, and offer a viable next step when the original request is not supportable. That next step might be discovery, a narrower scope, a different service combination, or a decision not to sell the work.

    Key takeaways

    • Do not try to solve sales-delivery conflict by asking salespeople to become technical experts. Give them boundaries, qualification rules, approved claims, and access to specialists.
    • Separate controllable deliverables from desired rankings, traffic, leads, citations, and AI-answer appearances.
    • Qualify implementation capacity as carefully as budget and buyer interest.
    • Define AI visibility by platform, topic, prompt set, and measurement method; never treat a dashboard score as proof of control.
    • Trigger delivery review when uncertainty could change scope, timing, price, or feasibility.
    • Measure deal quality after signature and feed recurring handoff problems back into the sales system.

    Start with the most recent deal that required delivery to correct a pre-sale expectation. Find the exact sentence that created the gap. Then change the boundary, qualification question, approved claim, or review trigger that allowed it through. Repeating that process turns painful handoffs into a sales system your team can actually deliver.

    References


  • How to Make Evidence-Based SEO Investments Under Uncertainty

    How to Make Evidence-Based SEO Investments Under Uncertainty

    Your leadership team wants a yes-or-no answer: keep funding SEO while AI answers reshape discovery, or wait until the channel becomes predictable. That is the wrong decision frame. Uncertainty increases the value of protecting durable assets and buying useful information through controlled tests. It does not make inactivity free.

    You do not need to predict the final form of search. You need an investment system that distinguishes essential maintenance from speculative work, contains downside risk, and gives every experiment a clear path to scale, stop, or further investigation.

    A pause is a position, not a neutral baseline

    A budget freeze can feel reversible because no new campaign has been launched and no visible loss appears on day one. Organic visibility does not behave that way. Content freshness, technical health, trust, and authority develop over time. When that work stops, competitors can occupy the space while your recovery becomes slower and potentially more expensive. The resulting costs can appear as lost share of voice, weaker pipelines, and a longer route back to your previous position.

    That means “spend nothing” belongs in the same investment analysis as any proposed initiative. Make the pause defend itself. For each important site segment, document what would stop, what would probably deteriorate, how you would notice the deterioration, and what would have to be rebuilt when funding returned.

    • Maintain: What recurring work protects discoverability, accuracy, technical reliability, and commercially important pages?
    • Reduce: Which assets will still be maintained, and which slower deterioration are you consciously accepting?
    • Pause: What signals will warn you that the decision is damaging visibility or demand, and who has authority to restart work?

    Assess those consequences by page group, product line, audience, or market rather than relying on one sitewide average. A healthy brand section can hide a weakening non-brand category. Stable total traffic can conceal lost visibility on the queries that introduce new buyers. The investment decision should follow the exposed asset, not the reassuring aggregate.

    This does not mean every SEO budget should stay untouched. It means that reducing investment should be an explicit trade: a known saving now in exchange for defined maintenance risk, lost learning, and uncertain recovery later.

    Give every SEO dollar one of three jobs

    A stream of metallic tokens divides among crews maintaining a digital library, testing a module in a laboratory, and expanding a modular structure.

    An evidence-based budget becomes easier to defend when every line item has a distinct job. Separate foundation work, market observation, and experimentation instead of placing all three in a single “SEO growth” bucket.

    1. Protect the foundation. Keep commercially important content current, maintain technical accessibility, audit the site, preserve authority-building activity, and continue producing original information that helps people make decisions. These are durable inputs to visibility across traditional and AI-mediated search, even when individual interfaces and tactics change.
    2. Observe the environment. Monitor the parts of search that could change the return on your work: audience priorities, product strategy, competitor movement, algorithms, and LLM behavior. Observation earns its budget by producing a decision, not by producing another dashboard.
    3. Buy information through experiments. Test uncertain changes on a controlled scope, measure their incremental effect, and expand only when the evidence supports expansion. Experiments are a learning mechanism within the strategy, not a substitute for the foundation.

    Fund the maintenance floor before funding speculative tactics. If the budget cannot support the whole site, narrow the protected scope deliberately. Start with assets that combine commercial importance, evidence of existing demand, and meaningful consequences if they deteriorate. Do not spread cuts evenly merely because an even reduction is administratively simple.

    Then rank discretionary proposals with a consistent filter:

    • Expected value: What business outcome could improve if the idea works?
    • Evidence strength: Is the proposal based on your own relevant data, a credible external pattern, or an untested assumption?
    • Reversibility: Can the change be removed quickly without damaging valuable pages, revenue, or measurement?
    • Learning value: Would the result guide decisions across a meaningful group of pages, or answer only a narrow question?
    • Measurement readiness: Are the affected pages, success metric, guardrails, comparison group, and tracking already available?

    Keep expected return and learning value separate. A low-risk test can deserve funding even when its immediate upside is uncertain if the answer will improve many later decisions. A sweeping change to high-revenue pages needs stronger prior evidence because the cost of being wrong is higher.

    Turn an uncertain tactic into a decision-grade test

    A modular tile passes through a transparent two-lane testing apparatus and reaches routes for scaling, further inspection, or stopping.

    “Add more schema,” “refresh the content,” and “optimize for AI” are activities, not hypotheses. None specifies where the change applies, what should move, what must not get worse, or what you will do with the result.

    Write a hypothesis that can lose

    Use this structure: For this eligible group of pages, making this consistent change should improve this primary outcome over this measurement period, compared with this control, without causing an unacceptable decline in these guardrail metrics.

    A useful hypothesis must be actionable, consistently implemented, measurable, and allowed enough time and exposure to reveal an effect. Tiny edits on a few low-traffic pages rarely justify formal experimentation because the result is unlikely to resolve the decision. As an illustration of test scale rather than a universal benchmark, changing a word in the H1 across 30 pages receiving more than 100 monthly sessions and observing them for four weeks is more testable than changing a word buried in the body copy of a few quiet pages.

    Before approval, put the hypothesis on a one-page test record with the affected page set, excluded pages, implementation owner, launch window, primary metric, business guardrails, control group, known confounders, monitoring cadence, rollback condition, and decision owner. If the team cannot fill those fields, the proposal is not ready to consume an experimentation budget.

    Match the method to the question

    MethodQuestion it can answerMain limitation
    User-level A/B testDoes one experience improve engagement, interaction, or conversion for users who see it?Splitting visitors between versions does not isolate the ranking effect of changing the page for search engines.
    Pre/post testDid performance change after an update to the same page or page group?Seasonality, algorithm changes, competitors, and other outside factors can create the apparent difference.
    Incrementality testDid changed pages outperform comparable unchanged pages during the same period?It requires a sufficiently similar control group and clean implementation across both groups.

    Use A/B testing for user experience or conversion questions. Use pre/post analysis when a credible control is unavailable and you need directional evidence. For rankings, visibility, or organic traffic, a concurrent comparison between changed and unchanged page groups provides the strongest isolation of the three methods because both groups experience the same period while only the test group receives the intervention.

    If you must use pre/post analysis, lower the confidence of the conclusion. Check sitewide movement, seasonal patterns, other campaigns, algorithm changes, and competitor activity before assigning the difference to your change. A later staged rollout across more eligible pages can show whether the pattern repeats.

    Contain the downside before launch

    Risk planning belongs in the test design, not in the incident response. A conservative rollout can use cross-browser and device QA, a lower-value pilot page, a tracking check after three days, weekly monitoring, and a prepared rollback plan. Avoid launching immediately before a weekend or another period when nobody can respond.

    • Confirm that pages load, render, link, and report analytics as expected.
    • Test on lower-value eligible pages before exposing the pages responsible for the most leads or revenue.
    • Record the original state and the exact reversal procedure before publishing the change.
    • Increase monitoring frequency when the possible impact on revenue, conversions, or site function is high.
    • Leave enough time to complete the test and any rollout before a busy season complicates measurement or raises the cost of failure.

    Reversibility should affect test scope. A cheap, easily reversed change can justify a broader initial test. A technically risky or revenue-sensitive change should begin small even when the projected upside looks attractive.

    Read the result as a business decision, not a traffic result

    An organic sessions increase is not automatically a win. Sessions can rise while conversion rate falls, or visibility can expand around queries that do not match the audience you intended to attract. That is why result analysis must check the full data set, validate surprising numbers, and look beneath the headline metric.

    Read every completed test in the same order:

    1. Verify implementation and tracking. Confirm that the intended pages received the intended change, the control did not, and both groups produced reliable data.
    2. Inspect the before-and-after movement. Establish what changed in the test group after launch.
    3. Compare the control. Determine whether similar unchanged pages moved in the same direction during the same period.
    4. Check the site context. Look for sitewide shifts that could indicate an algorithm event, demand change, tracking problem, or another marketing campaign.
    5. Check seasonality. Compare with the relevant prior seasonal period where that context is available rather than treating every temporal pattern as a test effect.
    6. Inspect quality and business impact. Review query intent, qualified traffic, conversion behavior, leads, revenue, or the closest valid downstream outcome.

    Decide the response before stakeholders debate the most flattering chart:

    • Scale: The primary metric improves against the control, the data checks out, and important business guardrails remain acceptable. Expand in stages so the rollout continues to confirm the effect.
    • Hold: The result is inconclusive but the implementation and measurement are valid. Record what remains unknown, then decide whether more exposure or a redesigned test is worth the cost.
    • Investigate: Visibility improves while conversion quality deteriorates. Examine query and landing-page intent before calling the change successful.
    • Stop or roll back: A guardrail deteriorates, the page malfunctions, tracking becomes unreliable, or the downside exceeds the value of additional learning.

    Do not keep extending a weak test until the chart finally looks favorable. An inconclusive result is evidence about the design, exposure, or effect size; it is not permission to declare a win. Preserve the record so the next proposal starts with what you already learned.

    A winning result is not permanent law either. Search systems, competitors, content, and user behavior continue to change, so a tactic that works during one period may not retain the same value indefinitely. Monitor scaled changes as part of the maintained foundation.

    Finally, define trigger events that require the portfolio to be reviewed. Relevant triggers include a shift in products, services, audiences, internal goals, competitor behavior, major algorithms, or LLM behavior. A trigger should prompt a fresh assessment, not an automatic budget increase or shutdown. Recheck the original assumptions, then choose whether to maintain the course, expand an experiment, reduce exposure, or move resources.

    Key takeaways

    • Treat pausing SEO as an investment scenario with its own costs, risks, warning signals, and recovery requirements.
    • Protect foundational work first, fund monitoring that can trigger decisions, and isolate speculative tactics inside experiments.
    • Require every experiment to name its page set, intervention, primary metric, guardrails, comparison group, measurement period, and decision rule.
    • Use user-level A/B tests for experience and conversion questions, pre/post tests for directional evidence, and concurrent test-control groups for stronger ranking evidence.
    • Scale only when the incremental result survives data validation and business guardrails; hold, investigate, or reverse the rest.
    • Revisit the portfolio when meaningful internal, competitive, algorithmic, or LLM changes invalidate its assumptions.

    At your next budget review, bring the portfolio rather than a prediction. Approve the maintenance floor, name the next controlled bet, document its scale and rollback rules, and identify the events that would change your allocation. You may not remove uncertainty from search, but you can stop paying for it blindly.

    References

  • How to Choose a HubSpot Revenue Operations Consulting Firm

    How to Choose a HubSpot Revenue Operations Consulting Firm

    If your HubSpot portal is messy, the tempting brief is simple: fix HubSpot. That brief is usually too small. A consultant can clean fields and rebuild workflows while leaving lead ownership, lifecycle definitions, forecasting, and customer handoffs just as fragmented as they were before.

    Your real decision is whether you need a HubSpot specialist, a Revenue Operations operator, or a firm that can do both. The framework below will help you define the job, build a relevant shortlist, test delivery depth, and contract for a system your team can operate after the consultants leave.

    Key takeaways

    • Hire a HubSpot specialist when the main problem is platform architecture, migration, integration, or configuration. Hire a RevOps firm when ownership, definitions, incentives, and handoffs are broken across marketing, sales, and customer success.
    • Use a hybrid firm when the operating model and the HubSpot build must change together. Confirm that it supplies both a senior process owner and a hands-on technical lead.
    • Shortlist firms by engagement shape, platform coverage, functional depth, and execution model. Partner tier, awards, reviews, and client logos are useful filters, not substitutes for fit.
    • Require concrete artifacts: a lifecycle map, data dictionary, automation inventory, integration design, migration controls, reporting definitions, enablement plan, and administrator runbook.
    • Ask who will work in the portal, how destructive changes will be tested, and what happens when an integration or automation fails.
    • If AI is included, insist on a named workflow, approved data inputs, human-review rules, logging, and a fallback path. An AI label is not an operating design.

    Decide which problem you are actually paying to solve

    A revenue operations specialist inspects broken and duplicated connections among five stages of a business process before opening a toolkit.

    Revenue Operations treats marketing operations, sales operations, and customer success operations as connected parts of the same revenue system. HubSpot is one place where that system can be implemented, but the platform cannot decide what your teams mean by qualified, who owns an idle opportunity, or when sales should return a lead to marketing.

    Automation encodes operating decisions. If those decisions are unresolved, faster automation produces faster confusion. Start with the failure you can observe, then choose the engagement that addresses its cause.

    What you can observeLikely engagementWhat completion should look like
    Duplicate properties, unreliable syncs, brittle workflows, or an incomplete migrationHubSpot implementation, integration, or platform optimizationA documented data model, tested integrations, controlled migration, monitored automation, and an administrator handoff
    Marketing and sales disagree about qualification, ownership, attribution, or pipeline stagesCross-functional RevOps design with CRM implementationAgreed definitions, entry and exit rules, named owners, exception paths, and corresponding HubSpot configuration
    The roadmap is understood, but nobody has the capacity or authority to operate itFractional RevOps or marketing operationsA prioritized operating backlog, a clear decision cadence, hands-on system ownership, and a plan for eventual internal ownership
    The portal is configured, but representatives work around it or managers maintain shadow spreadsheetsSales enablement, process redesign, and role-based adoption workFewer duplicate paths, usable views, manager inspection routines, role-specific training, and an explicit feedback process
    Ticketing, help desk work, renewals, and customer health are disconnected from the sales lifecycleService Hub and customer operations implementationDocumented support and escalation flows, connected customer records, ownership rules, and lifecycle reporting across the handoff

    Several rows may describe your situation. That does not automatically mean you need the broadest firm. It means one person must own the end-to-end architecture while specialists handle bounded work beneath it. Without that owner, a marketing workflow, sales process, customer service design, and integration can each be locally correct while the complete system remains incoherent.

    Write down the disputed operating decisions before you discuss software. Define your lifecycle stages, qualification rules, record ownership, system of record, revenue metrics, and exception paths. Mark any unresolved item as a decision the engagement must facilitate. Do not let an implementation team silently convert its preferred defaults into company policy.

    Build a shortlist around the work, not the badges

    The labels agency, consultancy, solutions partner, and fractional operator do not tell you who will design the process or touch the configuration. Look through the label to the firm’s actual operating model.

    For HubSpot work, leadership experience, customer reviews, partner tier, and HubSpot awards can narrow the market. For broader RevOps work, GTM platform breadth, experienced leadership, customer evidence, and complex-account experience add useful context. None of those signals tells you whether the proposed team has solved your type of handoff, whether its senior architect will remain involved, or whether it will perform the keyboard-level work.

    The following firms are useful names to investigate for particular engagement shapes. This is a starting map, not a universal ranking. Your scope, stack, industry constraints, internal capability, and desired working model determine the fit.

    Firm to investigateRelevant engagement shapeWhat to pressure-test
    DomestiqueFractional RevOps and marketing operations across the customer lifecycle, including migrations, technical implementation, funnel work, and a multi-platform GTM stackWhich senior operator owns cross-functional decisions, who performs weekly system work, and how knowledge transfers to your team
    Aptitude 8Complex HubSpot implementations, custom integrations, multi-hub architecture, platform optimization, and extensions beyond standard configurationArchitecture ownership after launch, integration monitoring, failure handling, and the boundary between custom development and maintainable native configuration
    SmartBug MediaService Hub, customer experience workflows, CRM implementation or migration, and sales coaching or trainingHow ticketing, service, sales, and customer-success data will share definitions and ownership rather than becoming separate HubSpot projects
    New BreedSales Hub and broader HubSpot migrations or implementations, including complex sales motions and integration workData reconciliation, sales-stage governance, representative adoption, manager inspection, and the post-launch administration model
    Six & FlowHubSpot-first RevOps, sales and marketing alignment, sales enablement, and AI or CRM enablementWhether a HubSpot-first recommendation matches your actual architecture, especially if Salesforce or multiple CRMs remain in scope
    SkaledOutbound performance, technology migration and support, sales alignment, and AI-enabled go-to-market executionWhich result depends on process, data, staffing, tooling, or message changes, and which part of the program the firm will directly own
    Go NimblyEmbedded RevOps work, revenue and technical architecture, fractional support, coaching, and AI-ready GTM foundations for SaaS or technology teamsThe embedded consultant’s decision rights, delivery cadence, technical contribution, and relationship with your functional leaders
    Winning by DesignRevenue architecture, GTM training, and methodology work built around the SPICED Framework and Bowtie ModelWhether you need methodology and enablement, system implementation, or both – and who translates the method into CRM fields, workflows, and reporting
    OperatusSalesforce CPQ, MuleSoft, RevOps as a service, and a stack spanning HubSpot, Salesforce, outbound, routing, and marketing automation toolsWhich platform is authoritative for each entity, how cross-platform changes are governed, and who supports the integration layer

    Apply hard gates before you debate presentation quality. A candidate should understand every critical platform in scope, have delivered the same shape of engagement, cover the functions affected by the change, and agree to an explicit execution model. It should also name the people who will do the work, not just the executives who join the sales call.

    • Platform gate: Can the team safely operate your real stack, including the systems that will remain outside HubSpot?
    • Engagement-shape gate: Has it handled a migration, fractional operating role, Service Hub build, outbound redesign, or custom integration comparable to yours?
    • Functional gate: Can it work with every team whose definitions or behavior must change?
    • Execution gate: Will it configure, test, document, and train, or will it stop at recommendations?
    • Accountability gate: Is there one named owner for architecture, decisions, risks, and acceptance?
    • Handoff gate: Will your internal team be able to diagnose, maintain, and extend the system at the end?

    A firm that fails a hard gate should not advance because it has a higher partner tier or a more recognizable client list. Those credentials may break a tie after delivery fit has been established.

    Turn the brief into a measurable engagement

    A vague request for HubSpot optimization invites vague proposals. Give every candidate the same one-page brief so differences in approach become visible.

    1. State the business failure. Describe what is happening in operational language: leads have no clear owner, managers cannot explain stage movement, renewals are missing from the customer record, or an integration creates conflicting values.
    2. Attach current-state evidence. Include the relevant portal inventory, object and property lists, workflow inventory, integration list, sample records, reports, process documents, and known data-quality problems. Remove or protect sensitive data before sharing it during procurement.
    3. Name the affected functions. Identify which marketing, sales, service, finance, operations, and technical owners must approve definitions or change their behavior.
    4. Set the system boundary. List what is moving into HubSpot, what remains elsewhere, which system should govern each important record type, and which integrations are in or out of scope.
    5. Expose unresolved decisions. Separate missing configuration from missing policy. If leadership has not agreed on qualification, attribution, ownership, or stage criteria, say so explicitly.
    6. Define done. Specify the artifacts, configured behavior, validation evidence, training, documentation, and ownership transfer required for acceptance.

    Use your own baselines and business targets. A consultancy can help validate how a metric is calculated, but it should not invent a success threshold merely because procurement expects a number. If your baseline is not trustworthy, establishing one is part of the work.

    Require artifacts that survive the engagement

    Strategy becomes operable when it is expressed as maintained artifacts, configured behavior, and acceptance evidence. The exact package will vary, but the following deliverables prevent essential knowledge from remaining in meeting notes or in a consultant’s head.

    DeliverableMinimum acceptance test
    Current-state and future-state lifecycle mapEach stage has a definition, entry rule, exit rule, owner, handoff, exception path, and corresponding system behavior
    CRM data model and dictionaryObjects, properties, associations, allowed values, naming rules, required fields, owners, and systems of record are documented
    Automation and routing inventoryEvery active workflow has a purpose, trigger, conditions, exclusions, owner, failure path, and retirement rule
    Integration architectureData direction, identity matching, overwrite behavior, conflict handling, permissions, monitoring, and support ownership are explicit
    Migration and cleanup planMapping, deduplication rules, test imports, approvals, reconciliation, backup, rollback, and exception handling are defined before production changes
    Reporting specificationEvery key metric has a plain-language definition, calculation logic, filters, data origin, refresh behavior, and accountable owner
    AI-assisted workflow specification, if applicableThe approved inputs, intended output or action, model and tool boundary, permission scope, human-review rule, logging, error handling, and fallback path are documented
    Enablement and administrator handoffRole-based instructions, governance rules, troubleshooting steps, open risks, credentials ownership, and the post-launch backlog are transferred to named internal owners

    Weak scope: Implement HubSpot for marketing and sales.

    Stronger scope: Facilitate agreement on the lead and opportunity lifecycle, map the approved CRM data model, migrate agreed records, configure ownership and routing, validate integrations and reporting, train each operating role, and deliver an administrator runbook with unresolved risks.

    If the lifecycle, data model, and system boundaries are still uncertain, make discovery an explicit deliverable before committing to the complete build. Discovery should finish with decisions, maps, risks, assumptions, a prioritized backlog, and an implementable scope. A slide deck that merely confirms the original ambiguity is not enough.

    Ask candidates to label assumptions and dependencies in their proposal. This reveals where pricing and timing could change: unavailable internal owners, undocumented integrations, poor data quality, conflicting executive definitions, limited API access, or a separate vendor that controls part of the stack. Change is easier to govern when the trigger is visible before the contract is signed.

    Interview and contract for a safe handoff

    A consultant transfers a key, an unmarked binder, and a toolkit to an internal administrator beside a completed modular business system.

    A polished sales presentation shows that a firm can sell an engagement. Your interview must show how it diagnoses, decides, builds, tests, escalates, and hands over the result.

    Ask questions that expose the delivery model

    1. Walk us through a comparable handoff from beginning to end. Listen for definitions, decision owners, system behavior, exceptions, testing, adoption, and measurement – not just a list of HubSpot features.
    2. Who will lead our work, who will configure the portal, and who reviews the configuration? Ask for named roles and expected involvement. Clarify what happens if a proposed team member is replaced.
    3. Show us an anonymized example of the artifacts we will receive. A lifecycle map, data dictionary, integration design, test plan, or administrator runbook reveals more than a general methodology diagram.
    4. How do you handle disagreement between marketing, sales, and customer success? A strong answer should explain facilitation, decision rights, documentation, and escalation. The consultant should not disguise an unresolved leadership decision as a software setting.
    5. How do you choose between native configuration, custom code, and another tool? Look for attention to maintainability, permissions, failure modes, administrator skill, and total operational burden.
    6. How will you test a migration or destructive cleanup? Require a staged approach, backup, reconciliation method, approval point, exception log, rollback path, and named decision-maker.
    7. What happens when a sync or workflow fails after launch? The answer should identify monitoring, alert ownership, triage, remediation, documentation, and the boundary between project support and ongoing operations.
    8. How will you establish the baseline and connect the work to an outcome? Listen for metric definitions and data validation. Be cautious if a firm promises a business result before it understands your baseline, dependencies, and adoption risks.
    9. How will users and managers change their behavior? Training alone is not adoption. Ask about role-specific processes, manager inspection, feedback, documentation, and who owns reinforcement after launch.
    10. What exactly does AI do in the proposed solution? Ask which decision or task it supports, which CRM data it can access, where data is sent, how output is reviewed, how errors are logged, and what happens when the model or external service is unavailable.
    11. What can our administrator operate without you at the end? The answer should connect system complexity to your team’s actual skills and identify any continuing dependency clearly.

    Watch for signals that the engagement will drift

    • The firm recommends a new tool or major reimplementation before inspecting your process, portal, data, and integration boundaries.
    • The senior operator runs discovery and then disappears, leaving an implementation team with no authority to resolve cross-functional decisions.
    • Every problem is described as a HubSpot configuration issue even when ownership, incentives, definitions, or management routines are clearly involved.
    • The proposal promises dashboards before defining the lifecycle, metric logic, required fields, and data-quality controls beneath them.
    • Migration language covers importing records but not matching identities, reconciling totals, logging exceptions, obtaining approval, or rolling back.
    • AI is presented as a general capability rather than a bounded workflow with approved data, evaluation, human oversight, logging, and fallback behavior.
    • Partner tier, certification volume, awards, or client logos are used in place of showing the proposed team’s relevant work products.
    • Post-launch ownership is vague. Nobody is named to monitor integrations, approve changes, maintain documentation, or manage the backlog.

    Put acceptance, control, and ownership in the contract

    • Named delivery team: Identify the engagement owner, architect, implementers, reviewers, trainers, and escalation contact, along with the process for substitutions.
    • Phases and acceptance: Tie each phase to deliverables, review responsibilities, approval criteria, and the consequence of rejected or incomplete work.
    • Decision rights: Record which decisions the consultant may make, which require client approval, and who resolves cross-functional disputes.
    • Assumptions and dependencies: Make access, internal participation, third-party vendors, data condition, and technical constraints visible.
    • Change control: Define how new requirements, unexpected data conditions, or platform limitations change scope, cost, sequencing, or delivery expectations.
    • Security and access: Require least-privilege access, approved handling of sensitive data, credential ownership, access removal, and disclosure of relevant subcontractors or external systems.
    • Configuration and data ownership: Confirm that your organization retains its portal, data, custom assets, configuration documentation, and administrator access.
    • Operational support: Define what is covered after launch, how issues are reported, who monitors failures, and what becomes a separate managed-service engagement.
    • Exit package: Require final diagrams, inventories, decision records, test evidence, unresolved risks, training materials, and the prioritized backlog.

    Do not approve property deletion, irreversible deduplication, workflow retirement, association changes, or a production migration without a recoverable backup, a controlled test, reconciliation evidence, an approval point, and a rollback owner. The downside is not merely a delayed project. It can be permanent data loss, incorrect routing, broken reporting, or customer-facing automation triggered from bad records.

    Give each finalist the same brief and ask for the same response structure: problem interpretation, approach, named team, assumptions, dependencies, risks, deliverables, acceptance process, and support model. This makes omissions visible. Then speak with references whose engagement resembles yours and ask what broke, how scope changes were handled, whether senior people stayed involved, and whether the internal team could operate the system afterward.
    Start by writing the failing lifecycle or handoff in one sentence and attach the evidence behind it. Send that brief to firms selected for the shape of the work. The right HubSpot and RevOps consulting firm will make the process, data, ownership, risks, and handoff more specific before it asks you to trust its brand.

    References
  • Google’s €890M DMA Fines: A Search Visibility Action Plan

    Google’s €890M DMA Fines: A Search Visibility Action Plan

    If you depend on organic visibility in shopping, hotels, transport or sports, Google’s €460 million Search fine gives you a reason to watch European result pages closely. It does not give you a reason to rewrite your site, declare an algorithm update or forecast a traffic windfall.

    The useful question is narrower: what evidence would show that Google’s response to the Digital Markets Act is changing your actual search opportunity? You need a baseline that captures interface prominence as well as rankings, followed by disciplined comparisons when a confirmed change appears.

    Two DMA findings address two different platform problems

    The combined penalties total €890 million: €460 million for Google Search and €430 million for Google Play. Combining the amounts is useful when describing the enforcement action, but combining the underlying conduct will confuse your response.

    FindingGoogle SearchGoogle Play
    Fine€460 million€430 million
    Conduct identifiedPreferential treatment for Google’s own shopping, hotel, transport and sports servicesRestrictions on developers communicating, promoting and concluding outside-store offers
    Required outcomeFair and non-discriminatory treatment of third-party services relative to Google’s own servicesTechnical and contractual freedom for developers to communicate, promote offers and conclude contracts inside or outside Google Play

    The European Commission required compliance within 60 days and warned of periodic penalty payments of up to 5% of Google’s total worldwide turnover if Google does not comply. That creates a concrete compliance window. It does not tell you which search design Google will choose or guarantee that every affected result page will change in the same way.

    Key takeaways

    • The Search decision concerns the comparative treatment and prominence of Google’s services and similar third-party services.
    • The Play decision concerns app-store steering. It should not be used to explain a movement in organic search traffic.
    • The 60-day requirement makes baseline collection urgent, but it is not a promised rollout schedule for a particular search interface.
    • Rank position alone cannot reveal whether a search redesign has improved or reduced the click opportunity available to you.

    Search self-preferencing is a presentation problem as well as a ranking problem

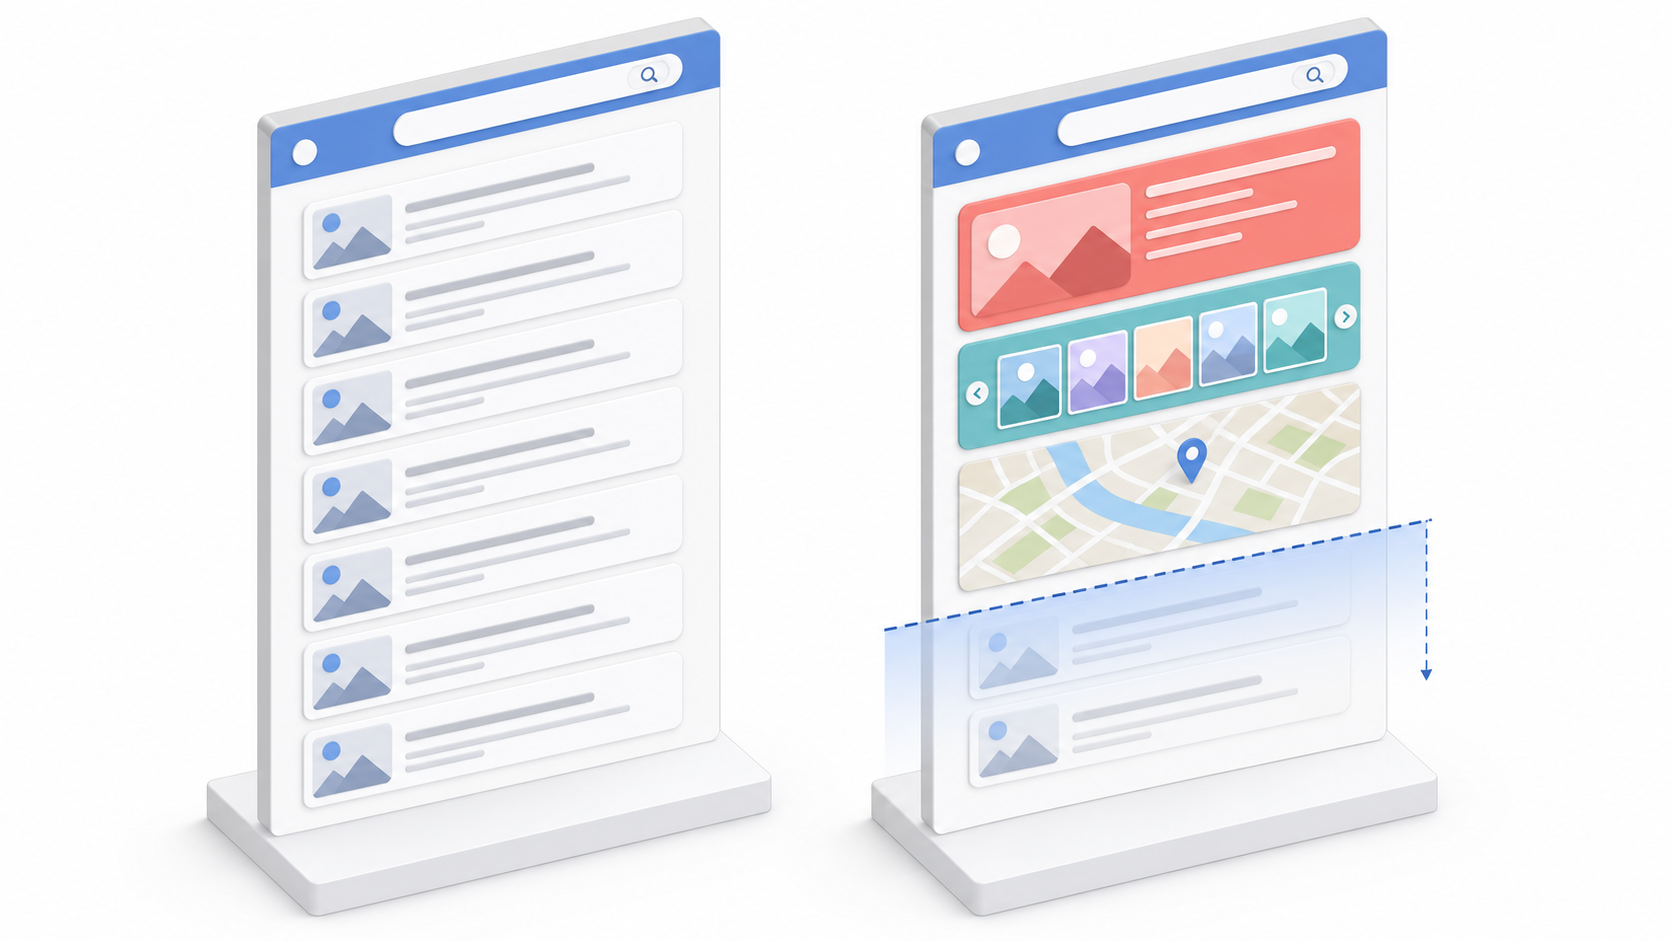
    Two search-result layouts show identical result cards, but large interface modules push most cards below the visible area on the second screen.

    The Search finding is broader than a complaint about which blue link ranks first. Google was found to give its own services greater prominence, including placement at the top of results and the use of enhanced visuals and filters that comparable third-party services did not receive.

    That distinction changes what you should measure. A third-party page can retain the same nominal organic position while losing practical visibility because a large Google-owned module occupies the area above it. The reverse can also happen: a new third-party feature or direct link can improve exposure without moving the conventional listing.

    Audit the result page in layers rather than reducing it to a rank number:

    • Order: Record which component appears first and what sits between the search box and your listing.
    • Visual weight: Note images, expanded cards, labels, filters and other treatments that make one service more noticeable than another.
    • Destination: Distinguish links that lead into a Google service from links that send the user directly to a third-party provider.
    • Interaction: Test what happens after a user selects a filter, card or comparison option. The initial screen is only part of the journey.
    • Parity: Compare how equivalent information from Google and third parties is presented, including whether either side receives richer controls or more prominent placement.

    This is an SEO observation framework, not a legal test. A screenshot can document treatment, but it cannot by itself establish a DMA breach. If your business is considering a complaint or another legal response, preserve the evidence and have competition counsel assess it against the Commission’s decision.

    Build a baseline that can survive a search redesign

    A laptop, tablet, phone, page thumbnails, ruler, markers, and magnifying glass are arranged for comparing search-result layouts across devices.

    Do not wait for traffic to move before documenting the current experience. By then, you may know that performance changed without knowing whether the cause was a new interface, a conventional ranking movement, demand, seasonality or something on your own site.

    Create a query set around the verticals named in the finding: shopping, hotels, transport and sports. Include the commercial searches that matter to your business, then add a comparison group of queries where Google-owned vertical features are absent or less central. Keep market, language, device type and other test conditions consistent so that you are comparing like with like.

    For each observation, store:

    • The exact query, market, language, device type and observation time.
    • A full-page capture showing the order and size of major result components.
    • Which components represent Google services, third-party services or conventional organic results.
    • The presence of enhanced visuals, comparison controls and filters.
    • The number and location of direct links available to third-party sites.
    • Your impressions, clicks, click-through rate and average organic position for the same query cohort.
    • Engaged visits, conversions or other business outcomes from the affected landing pages.

    Annotate the date of a confirmed interface or policy change separately from the date of the fine. This prevents a common analytical error: treating the enforcement announcement as the moment Google’s implementation necessarily reached every user.

    When the interface changes, compare the affected cohort with your stable comparison queries. If rankings hold steady but click-through rate changes where Google-owned modules were altered, presentation becomes a stronger explanation. If both groups move together, investigate broader demand, technical or ranking causes before crediting the DMA response.

    Change your SEO tactics only when the evidence supports the move

    A regulatory order defines the result Google must achieve, not the exact search design it must ship. Google could respond through placement, visual treatment, filters, direct links, eligibility rules or some combination of those elements. Build for credible scenarios, but do not bet your roadmap on one speculative layout.

    1. Protect technical eligibility. Keep important pages crawlable and indexable, use accurate canonical signals, and maintain relevant structured data or feeds. These measures do not guarantee feature inclusion, but prevent avoidable technical defects from obscuring whether access has changed.
    2. Make comparable information explicit. If a result could be filtered by price, location, availability, category or another material attribute, represent that information consistently on the page and in supported machine-readable formats. A new third-party filter is of little value if your data cannot qualify for it.
    3. Strengthen the destination. A direct third-party link only helps when the landing page immediately satisfies the query. Align the page title, visible heading, primary information and conversion path with the specific search intent you are monitoring.
    4. Watch click paths, not just inclusion. Being displayed inside a feature is not equivalent to receiving a visit. Record whether users can reach your site directly, must pass through another Google screen or are encouraged to complete the task without leaving the result page.
    5. Require repeatable evidence before major edits. Do not delete useful pages, rebuild templates or change information architecture because of an isolated result-page test. Confirm that the treatment persists under controlled conditions and that it affects performance before making a costly or difficult-to-reverse change.

    If third-party services begin receiving more direct links or comparable visual treatment, prioritize data accuracy, landing-page quality and measurement of the new referral paths. If no visible change appears in your sample, continue collecting evidence. Absence from your tracked queries does not prove that Google has made no changes elsewhere, while one unusual result does not prove that broad compliance has arrived.

    Keep the Google Play finding out of your search diagnosis

    The €430 million Google Play fine addresses a separate restriction. Google prevented app developers from freely communicating and promoting offers, and from concluding contracts with users through distribution channels of their choice, including third-party app stores. Google may receive a fee for facilitating an initial customer acquisition through Play, but the Commission found that the steering-related fee level and charging period went beyond DMA compliance.

    If you operate an app, route that issue to the people responsible for distribution contracts, checkout paths, customer acquisition economics and developer communications. Keep their implementation log separate from the SEO change log. A revised external-offer flow could affect app revenue or attribution, but it is not evidence that Google Search changed how a web page ranks or appears.

    Your next move is simple: capture the current European search experience for the queries that matter, preserve the underlying performance data, and wait for a confirmed implementation before changing strategy. The teams that can distinguish a ranking movement from a presentation change will be able to act while everyone else is still arguing about what the fine was supposed to do.

    References

  • The Economics Behind ChatGPT’s $100 Billion Ad Target

    The Economics Behind ChatGPT’s $100 Billion Ad Target

    ChatGPT advertising is being framed as a potential bridge between conversational AI and the large budgets already committed to digital media. The central economic question, however, is not whether ads can appear in a chatbot. It is whether the format can attract enough demand, usage and measurable commercial activity to support OpenAI’s reported revenue ambitions.

    A comparison reported by CrushPress.AI illustrates the uncertainty: OpenAI’s projection for its own advertising business is dramatically larger than Emarketer’s forecast for the entire U.S. standalone-chatbot advertising market. Understanding that discrepancy requires separating the headline numbers from their scope and underlying assumptions.

    Key takeaways

    • CrushPress.AI reported that OpenAI projected $2.5 billion in advertising revenue for the year discussed in the source and $100 billion by 2030.
    • The same article cited Emarketer’s forecast of less than $1 billion for the U.S. standalone-chatbot advertising market in that year and $5.41 billion by 2030.
    • The figures signal a major expectations gap, but they are not necessarily like-for-like because Emarketer’s estimate is limited to the United States and a defined set of standalone chatbot experiences.
    • Reaching OpenAI’s target would likely require more than inserting conventional ads into conversations; it would depend on substantial advertiser demand, commercial user activity and credible measurement.

    The forecasts describe radically different economic outcomes

    According to CrushPress.AI, OpenAI began testing ChatGPT ads in February and, by April, was projecting that advertising revenue would reach $100 billion within five years. The article also reported a $2.5 billion advertising-revenue projection for the year covered by the forecast.

    Emarketer’s outlook, as presented in the article, is much smaller. It estimated that U.S. advertising across standalone chatbots would generate less than $1 billion in the same year and rise to $5.41 billion by 2030. CrushPress.AI characterized OpenAI as being on course to miss its 2030 target by roughly 90% if the market develops along Emarketer’s forecast.

    ForecastNear-term figure reported2030 figure reportedStated scope
    OpenAI advertising projection$2.5 billion$100 billionOpenAI’s advertising business; geography was not specified in the supplied report
    Emarketer market forecastLess than $1 billion$5.41 billionU.S. standalone-chatbot advertising market

    The contrast is economically significant even before attempting a direct comparison. One outlook anticipates a very large revenue stream for a single company, while the other expects the defined market category to remain comparatively modest through 2030.

    The scope mismatch matters as much as the revenue gap

    A large sphere of conversation bubbles outweighs a smaller geographically bounded cluster on a balance scale.

    Emarketer’s forecast covered standalone chatbot products in the United States. CrushPress.AI said the category included ChatGPT, Microsoft Copilot, Google AI Mode and Amazon Alexa for Shopping, formerly known as Rufus. OpenAI’s target, by contrast, was presented as a company advertising goal without an equivalent geographic or product-boundary definition in the supplied article.

    That makes the comparison useful as a stress test, but not a definitive like-for-like verdict. OpenAI could be assuming revenue from markets outside the United States, advertising products that extend beyond a narrow standalone-chatbot definition, or commercial experiences that Emarketer classifies elsewhere. The source does not establish that those possibilities are included, so they should be treated as potential explanations rather than facts.

    The reverse caution also applies. A broader addressable market does not automatically produce broader revenue. OpenAI would still need to turn that potential into inventory advertisers value, demand they are willing to fund and outcomes they can evaluate.

    What would have to be true for the target to work

    A central conversational portal connects to an audience, a storefront, a measurement gauge and a privacy shield.

    CrushPress.AI described OpenAI’s forecast as resting on several ambitious assumptions: capturing search-advertising budgets at scale, leading a mature chatbot-ad market and outperforming previous advertising formats. Each assumption represents a separate economic hurdle.

    • Budget transfer: Advertisers would need to treat conversational placements as a meaningful destination for money currently assigned to established channels, rather than merely adding small experimental budgets.
    • Commercial intent: ChatGPT usage would need to produce enough moments in which an ad is relevant to a purchase or business decision. High overall usage alone does not establish high-value advertising inventory.
    • Pricing power: Advertisers would need evidence that chatbot placements generate sufficient value to support attractive prices. That normally depends on relevance, scarcity, audience quality and demonstrated outcomes.
    • Measurement: The format would need dependable ways to distinguish exposure, influence and conversion. Conversational journeys can complicate familiar attribution models because an answer may inform a decision without producing an immediate click.
    • User acceptance: Commercial messages would have to coexist with useful answers without weakening confidence in the product. If monetization reduces engagement, additional ad load can undermine the inventory it was intended to create.

    These conditions are connected. Strong purchase intent can improve pricing, credible measurement can accelerate budget movement, and user trust can protect continued engagement. Weakness in any one of them can constrain the others.

    How advertisers should interpret the opportunity

    The reported forecasts do not support treating chatbot advertising as either a guaranteed successor to search advertising or an irrelevant niche. They support a staged approach in which advertisers evaluate the channel based on observed behavior rather than the platform owner’s long-range target.

    Early assessments should distinguish inventory volume from inventory quality. Useful indicators would include whether placements appear during commercially relevant conversations, how clearly sponsored material is identified, what controls advertisers receive and which outcomes can be measured. Comparisons with paid search or other performance channels should use consistent conversion definitions and time horizons.

    The most informative signal will be whether chatbot advertising develops incremental demand of its own or primarily redistributes existing digital-ad budgets. OpenAI’s reported goal appears to require a market much larger than Emarketer’s defined U.S. category, making the eventual boundaries of the product and the source of advertiser spending central to the economics.

    As testing develops, the debate should become less dependent on top-down forecasts and more grounded in observable pricing, advertiser retention, measurable commercial outcomes and the effect of ads on user behavior.

    References

  • How I Justify GEO Investment Without Perfect Attribution

    How I Justify GEO Investment Without Perfect Attribution

    Fractured attribution

    My eight-year-old daughter desperately wanted a Nintendo Switch. Her “evil” parents—my spouse and I—refused to buy one for her.

    She was too young to get a job, so she did what any resourceful child would do: she opened a lemonade stand in front of our house.

    She did more than set out a table and a pitcher, though. She designed what amounted to a high-stakes A/B test.

    Her hypothesis was simple: if she could persuade more people to stop, she could sell more lemonade and reach her Nintendo Switch goal faster.

    Variant A was her two-year-old sister, Julie, stationed out front to attract attention.

    Variant B was our dog, Ginger.

    Lemonade stand visibility A/B test comparing Julie and Ginger

    I know what I would have guessed.

    The dog. Obviously, the dog.

    But Julie won—and it was not even close.

    The only metric that mattered

    The funny part is that my daughter did not really care about the A/B test result. She was not interested in how many people stopped at the stand or which variant produced the best response.

    She cared about one outcome and one outcome only:

    Side-by-side lemonade stand A/B test comparing a smiling young sister with a golden retriever, with Variant A marked the winner.
    At this lemonade stand, the cute-dog advantage loses: Variant A, featuring the seller’s young sister, wins the visibility A/B test over Variant B’s golden retriever.

    Did she make enough money to buy the Nintendo Switch?

    I believe marketers are facing a similar problem right now.

    Generative engine optimization (GEO) is the practice of increasing a brand’s visibility in AI-generated answers across platforms such as ChatGPT, Gemini, Perplexity, and AI Overviews.

    I can track AI visibility, citation share, impressions, rankings, and nearly every other signal available. Meanwhile, leadership is asking a much simpler question:

    Is any of this helping the business grow?

    I answer that question with a simple test I call the Dollar Rule: if I cannot put a dollar sign in front of a metric, I treat it as a channel metric rather than a business metric.

    That distinction captures the central measurement challenge in GEO.

    Most of the numbers we track are valuable operational signals. They show us what is happening within the channel, but leadership wants to understand the resulting business impact.

    GEO emerged at precisely the moment attribution was becoming less reliable.

    Traditional SEO measurement relied on a straightforward journey: someone searched, clicked, visited a website, and converted. We could trace that path and connect it to an outcome.

    Dollar Rule Framework infographic showing Align, Verify, and Translate steps for connecting imperfect GEO data to measurable financial impact.
    The Dollar Rule turns imperfect GEO attribution into a business case: align metrics with outcomes, verify directional signals, then translate performance into financial language leaders value.

    AI search disrupted that model.

    I now see buyers forming opinions and making decisions before they ever reach a company’s website. That makes AI’s influence much harder to capture with conventional attribution.

    AI search broke attribution

    I see buyers discovering brands through AI-generated answers, citations, publishers, forums, reviews, videos, and many other sources. Those touchpoints can shape a decision long before a click occurs, and much of that influence never appears cleanly in analytics.

    That is why I see so many teams struggle to justify GEO investments. The visibility is real, and the influence is real, but the attribution is frequently incomplete.

    I do not believe waiting for perfect attribution is a sound strategy. Increasingly, it is simply a convenient reason to avoid acting.

    When I want leadership to support GEO, I need to connect its influence to business outcomes—even when I cannot connect every interaction to a conversion.

    How I make the financial case for GEO

    The biggest mistake I see marketers make is trying to prove attribution before proving value.

    Before I worry about attribution, I ask whether I am measuring something the business actually considers important. That is where the Dollar Rule becomes useful.

    I have found that justifying a GEO investment usually comes down to three actions:

    • I align my metrics with business outcomes.
    • I verify that those metrics reliably point me in the right direction.
    • I translate the evidence into language a CFO understands.
    The Dollar Rule framework for connecting GEO metrics to financial impact

    My Dollar Rule is deliberately simple:

    Split target infographic contrasting high precision but low accuracy, with clustered misses, against high accuracy but low precision around the bullseye.
    Precision can form a tight cluster in the wrong place; accuracy keeps evidence centered on the outcome that matters. For GEO measurement, a useful estimate can beat an exact but irrelevant metric.

    If a number does not translate into dollars, I treat it as a channel metric, not a business metric.

    I focus on revenue opportunity, revenue at risk, payback period, and customer acquisition cost. Those metrics live on a P&L, and they are the numbers leadership teams use to evaluate investments.

    In my experience, CFOs do not allocate budget because an attribution model looks impressive. They allocate budget based on credible expectations of financial return, risk, and growth.

    That principle changes how I measure and present GEO.

    I measure influence, not just attribution

    AI search did more than change discovery. It changed what I can realistically measure.

    Traditional organic attribution assumes a clean sequence: search, click, visit, convert.

    AI platforms increasingly answer questions before a click, influence buyers across multiple touchpoints, and withhold the referral data marketers once relied on.

    That leaves me in an unusual position: a GEO campaign may be influencing pipeline even while the analytics platform struggles to prove it.

    One estimate illustrates the gap. Loamly estimates that roughly 70% of AI-influenced traffic appears as Direct traffic in GA4, making a substantial share of AI’s contribution difficult to trace through traditional attribution models.

    I do not take that measurement gap to mean measurement is impossible. I take it as a reason to broaden the evidence I examine.

    Quote graphic stating that a rough estimate of revenue impact beats a precise click count, illustrated by a scale weighing clicks against revenue impact.
    When attribution is incomplete, business value tips the scale: a credible estimate of revenue impact can guide GEO investment better than a perfectly precise tally of clicks.

    Instead of asking only, “How many clicks did we receive from AI search?” I ask:

    • Is our branded search growing?
    • Are prospects arriving already familiar with our positioning?
    • Are we being cited in AI answers for questions that drive revenue?

    I would not treat any one of these signals as definitive. When I combine them, however, they can create enough confidence to support a responsible investment decision.

    That is the essential difference between GEO measurement and traditional SEO measurement. I am not simply measuring a click path; I am measuring market influence.

    I believe the marketers who adapt fastest will stop treating attribution as a traffic-sorting exercise. We will combine quantitative signals with qualitative evidence because the goal is not absolute certainty. The goal is confidence that our GEO investment is moving the business in the right direction.

    Why I may be measuring the wrong thing

    I do not think SEO or GEO metrics are inherently wrong. The problem is that they can be highly precise without being relevant to the business outcome I am trying to influence. They tell me exactly what happened inside a channel, but not whether the business is moving in the right direction.

    SEO tools are packed with precise numbers. The challenge is that many of those numbers have only a weak connection to business outcomes.

    Precise = exact

    Accurate = connected to business outcomes

    I have found that leadership would rather receive a roughly correct estimate of revenue impact than a perfectly precise count of clicks.

    I studied engineering in school, where we spent a great deal of time discussing precision: how exact and repeatable a measurement is, right down to the decimal point.

    Infographic showing fuzzy math: 10% mention rate × 1,200 sales calls × $500K contract value × 20% win rate equals $12M in pipeline at risk.
    The fuzzy math equation turns a qualitative sales signal into a figure leaders understand: a 10% competitor-content mention rate translates to $12 million in annualized pipeline at risk.

    In marketing, I see that kind of precision in organic clicks, rankings, impressions, and click-through rates. Tools such as Google Search Console can give me extremely exact figures for those channel activities.

    Precision compared with accuracy in GEO and SEO measurement

    The problem is that a precise channel number is not necessarily accurate in the business sense. I consider a measurement accurate when it tells me whether I am getting closer to an outcome that matters.

    Even when those measurements are not perfectly precise, I find them more useful if they point toward the bullseye: the business outcomes leadership cares about.

    Knowing that a page received 40 organic clicks is precise. It tells me almost nothing about whether we are winning or losing in the market—just as a visitor count did not tell my daughter whether she was close to buying her Nintendo Switch.

    Revenue impact compared with a precise click count

    That is how I apply the Dollar Rule in practice. When attribution is incomplete, I translate the evidence I do have into a directional estimate of business impact.

    Why I put revenue ahead of attribution

    For me, a rough number tied to revenue beats an exact number tied only to channel activity.

    When reliable attribution is unavailable, I build the case from signals I can actually access and then work through the math.

    I do not use fuzzy math to replace SEO metrics or attribution. I use it alongside them when traffic-based attribution cannot capture the influence taking place.

    One of our healthcare clients gave us a useful example.

    Prospects were arriving at sales calls already convinced of claims that were not true.

    Vertical ladder infographic titled “Translating SEO Metrics for Your Leadership,” moving from impressions and citations to business outcomes and $122K in revenue.
    Climb from channel data to executive value: translate SEO impressions and citations into pipeline and lower CAC, then show leadership what matters—$122K in revenue and a three-month payback.

    We traced the source to a competitor’s comparison page. That page was shaping buyer perceptions long before our client had an opportunity to present its side of the story.

    We recommended publishing content that would counter the narrative, but the leadership team did not believe there was enough evidence to justify a response. We needed to make a stronger business case.

    SEO tools estimated that the competitor’s page received roughly 40 organic visits per month. Whether that estimate was right or wrong was beside the point: it did not measure the page’s influence on active buyers.

    So we looked for evidence that was closer to the business outcome.

    We spoke with our client’s salespeople. They told us that roughly 10% of qualified B2B discovery calls included unprompted mentions of specific claims from the competitor’s page.

    That was not a clean number suitable for an exact attribution model, but we could not dismiss it. The influence was real, and it was showing up during live sales conversations.

    We used that evidence to build a directional calculation:

    10% mention rate on discovery calls

    × 1,200 qualified B2B sales calls per year

    × $500,000 average contract value

    Quote graphic stating a competitor wins 64% of AI citations, appears in 10% of discovery calls, and influences $12 million in pipeline.
    A competitor’s comparison page earns 64% of citations on decision-stage AI questions and surfaces in 10% of discovery calls—putting an estimated $12 million in pipeline under its narrative.

    × 20% average win rate

    = $12 million in annualized revenue being influenced by the competitor’s narrative

    I did not present this as a forecast or a formal attribution model. It was a directional estimate of how much revenue the competitor’s messaging could influence.

    That reframing changed the conversation. We stopped debating 40 clicks per month and started discussing $12 million in influenced revenue.

    Fuzzy math equation estimating revenue influenced by a competitor narrative

    That is the number we brought to leadership—not impressions or citation share, but $12 million in revenue being influenced by a page our client had declined to counter. That is a number a CFO immediately understands.

    I lead with value metrics

    If we enter a GEO campaign review and lead with rising citation share or growing impressions, our CMO may lose interest and our CFO may wonder what those numbers mean financially. In the worst case, we can lose budget because leadership cannot see the return.

    Translating SEO and GEO channel metrics for leadership

    Here is how we framed the situation for our client’s leadership team:

    Executive talking points connecting market influence to revenue

    I have learned that leadership funds marketing campaigns based on business impact. Translating a problem into dollars changes the nature of the discussion.

    The decision-makers did not need certainty. They needed a credible financial story supported by leading indicators, observable momentum, and enough evidence to inspire confidence.

    I focus on what the business values

    That is what my eight-year-old intuitively understood at her lemonade stand. Her goal was never to count visitors. Her goal was to buy the Nintendo Switch.

    Angled smartphone displaying a ChatGPT screen with an Advertisement card, illuminated by blue and magenta neon light against a dark background.
    A neon-lit smartphone imagines advertising inside ChatGPT, highlighting how AI platforms are reshaping brand discovery, GEO strategy, and the measurement of marketing influence.

    GEO has created anxiety because it disrupted attribution models we relied on for years. But I remind myself that attribution was never the ultimate objective.

    The real objective is business growth.

    If I can connect GEO activity to revenue opportunity, revenue at risk, pipeline influence, or customer acquisition, I do not need perfect certainty to justify the investment.

    I need credible evidence that our GEO campaigns are moving the business in the right direction.

    Precise metrics tell me what happened. Relevant metrics tell me whether we are winning.

    Before I deliver my next GEO report, I can examine every metric on the page and ask one question:

    If this metric doubled tomorrow, would the business care?

    Then I ask the follow-up:

    Can I translate this metric into revenue opportunity, revenue at risk, pipeline influence, or customer acquisition cost?

    If I cannot, I am probably reporting channel impact rather than business impact—and that is unlikely to justify the next GEO investment.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Growth Marketing Investment: Earning the Right to Scale

    Growth Marketing Investment: Earning the Right to Scale

    Growth marketing discipline is not simply a matter of spending less. It is the practice of matching each investment to the strength of the evidence, the speed of the feedback loop, and the financial risk the business can absorb.

    Viewed together, the source articles expose two sides of the same capital-allocation problem. Paid media can consume cash before a campaign has learned enough to use it efficiently, while underinvesting in SEO can create a slower, compounding liability. The practical goal is therefore neither maximum growth nor minimum cost, but evidence-based investment across different time horizons.

    Key takeaways

    • Budget consumption is an input, not evidence of business performance.
    • Paid campaigns should generally earn larger budgets through validated conversion quality, unit economics, and operational learning.
    • SEO should be judged partly by the future acquisition costs and competitive exposure that sustained investment may prevent.
    • Channel metrics become decision-useful only when connected to pipeline, revenue, payback, or measurable risk.
    • Growth plans need explicit scale, hold, reduce, and stop conditions before spending begins.

    The same budget can create very different financial risks

    A dollar allocated to paid acquisition and a dollar allocated to SEO do not mature on the same schedule. Paid media can generate immediate traffic and relatively fast campaign signals, but it can also amplify weak targeting, immature bidding, poor creative, or an unproven offer. SEO usually takes longer to affect commercial outcomes, yet reducing it may allow competitive positions and accumulated authority to deteriorate over time.

    The paid-media source argues that most campaigns should begin with a measured rollout because algorithms are still learning and the strongest audiences, keywords, and creative assets are not yet known. It also warns that a long or variable sales cycle limits the value of forcing more spend into an early period: if sales arrive months after the first exposure, the campaign cannot quickly convert additional volume into reliable learning.

    The SEO source describes almost the inverse danger. Organic positions are presented as contested rather than permanent, so a budget reduction may produce a delayed and potentially compounding decline. Competitors can continue publishing and building authority while the withdrawing company loses visibility, and replacing lost organic demand with paid acquisition may increase customer acquisition costs. That makes maintenance investment relevant even when its short-term incremental return is difficult to isolate.

    This distinction changes the budgeting question. Paid media requires protection against premature amplification; SEO requires protection against deferred deterioration. A disciplined portfolio accounts for both instead of applying one universal demand for immediate return.

    Commercial evidence must replace activity as the investment case

    Both sources reject the idea that channel activity is a sufficient measure of progress. The paid-media article states that the amount spent is not a key performance indicator. The SEO article reaches a parallel conclusion about rankings, traffic, and keyword opportunities: those metrics cannot support a capital request unless their commercial implications are made clear.

    The SEO source illustrates the gap with an enterprise software example. It reports that one product line produced 291 inbound demo requests in a month in 2008 and 274 in the corresponding month of 2026, despite a digital marketing budget that had grown to roughly eight times its earlier size. The example is not proof that any single channel failed, but it shows why a finance leader may focus on qualified opportunity output and acquisition efficiency rather than favorable channel charts.

    The paid-media source reports a similarly consequential measurement failure at a startup that had raised more than $250 million. According to the article, most of the funding had been consumed before measures such as revenue-producing new accounts and lifetime revenue from those accounts became serious priorities. The lesson is broader than paid search: measurement introduced after capital is depleted cannot restore the option value that early discipline would have preserved.

    A credible investment case should therefore connect leading indicators to a commercial chain: exposure creates qualified demand, qualified demand creates customers, and customers create revenue and margin over time. Where that chain cannot yet be demonstrated, the uncertainty should be visible in the size and reversibility of the commitment.

    A stage-gated model connects experimentation to capital allocation

    An isometric pathway sends small experiments through checkpoints, stopping weak paths while stronger evidence unlocks progressively larger pools of investment.

    The synthesis of the two sources suggests a stage-gated approach. It preserves the paid-media article’s principle of testing before scaling while incorporating the SEO article’s emphasis on business risk, counterfactuals, and the cost of withdrawal.

    1. Define the commercial outcome. Specify the qualified action, customer, revenue, or risk outcome the investment is expected to influence. Channel metrics can remain diagnostic measures, but they should not become the final objective.
    2. State the uncertainty. Identify what is not yet known about audience quality, conversion value, attribution, sales-cycle delay, competitive response, or organic displacement. This prevents confidence from being inferred merely from a large budget.
    3. Choose a reversible initial commitment. For an unproven paid campaign, this generally means enough volume to produce useful signals without treating the entire available budget as test capital. For SEO, it means distinguishing experimental expansion from the baseline work needed to protect strategically important visibility.
    4. Set decision thresholds in advance. Establish what evidence will trigger scaling, continued observation, redesign, reduction, or termination. Thresholds should include commercial quality and payback considerations, not only clicks, traffic, or conversion counts.
    5. Increase investment in calibrated increments. Each increase should answer a defined question, such as whether performance persists in a broader audience or whether greater content investment protects or expands commercially valuable visibility.
    6. Reassess the portfolio effect. Evaluate whether one channel is creating, capturing, or merely receiving credit for demand, and estimate what another channel would need to spend if that contribution disappeared.

    This process does not require every channel to meet the same payback schedule. It requires every channel to have a defensible role, an appropriate evidence standard, and a known consequence if investment rises or falls.

    Governance should make both upside and downside visible

    Business leaders examine a transparent tabletop model showing both an illuminated opportunity route and a guarded downside route beside a finite pool of investment tokens.

    Investment discipline weakens when the person advocating aggressive growth does not bear the full consequences of failure. The paid-media source highlights this risk asymmetry and reports observing a recurring pattern across close to 1,000 ad accounts: advertisers that overspent early in pursuit of rapid growth often exhausted momentum and stakeholder support. That reported experience is not a universal causal estimate, but it reinforces the need for governance before enthusiasm becomes an irreversible commitment.
    Finance and marketing can reduce that asymmetry by reviewing paired scenarios. The upside case asks what additional investment could produce if the thesis works. The downside case asks how much capital can be lost, how quickly the result will become observable, and whether the company will still have enough runway to adapt. For durable channels such as SEO, the downside analysis should also examine what withdrawal could cost through lost visibility, higher replacement acquisition expense, and a more difficult recovery.
    Counterfactual thinking is essential in both directions. The SEO source identifies the central attribution challenge as whether credited revenue would have happened without the investment. The corresponding question for budget cuts is whether apparent savings will simply reappear as higher costs elsewhere. Neither question can always be answered with precision, but an explicit range of outcomes is more useful than presenting attributed revenue or budget savings as certain.

    The most resilient growth plans will treat capital as a sequence of informed commitments. Paid acquisition can expand as customer quality and economics become clearer, while SEO can be funded according to both its growth potential and the liability created by neglect. That balance allows a company to pursue opportunity without spending away its ability to learn.

    References

  • A Framework for Technical SEO Risk, ROI and Indexing

    A Framework for Technical SEO Risk, ROI and Indexing

    Technical SEO decisions become difficult when the highest-impact changes also create the widest failure surface. URL structures, canonical rules, robots.txt directives, internal links and migrations can improve discovery and indexing, yet an error in any of them can affect large parts of a site.

    The measurement environment is equally imperfect. Benefits may emerge only after recrawling and reindexing, avoided losses leave no clean counterfactual, and even a primary diagnostic such as Google Search Console can be delayed. A useful operating model must therefore connect three disciplines: risk-based prioritization, layered indexing diagnosis and evidence-based ROI reporting.

    Technical SEO combines implementation risk with measurement uncertainty

    The implementation challenge and the measurement challenge are closely related. The changes most likely to affect organic performance are often sitewide or template-level changes, which makes them difficult to isolate and dangerous to test carelessly.

    One Search Engine Land contributor identified URL updates, canonical changes, robots.txt edits, internal linking work and migrations as initiatives that deserve extra caution. Their common characteristic is scale: a rule or template change can alter how search engines encounter, interpret or prioritize many URLs at once. A small configuration mistake can consequently have a much larger effect than an isolated metadata edit.

    A separate Search Engine Land analysis explains why the return from this work can be hard to prove. Technical changes rarely occur in a closed system, search engines recrawl and reindex on their own schedules, and multiple teams may release changes together. Sitewide work can also remove the possibility of an untreated control group. The result is an inference problem, not merely a reporting gap.

    This distinction matters for funding. Some technical SEO work seeks measurable growth, while some maintains access, resolves technical debt or reduces the probability and cost of a future loss. A migration that preserves traffic may be successful even if its performance chart is flat. Treating every project as a short-term acquisition campaign undervalues resilience and encourages false precision.

    Prioritize changes by exposure, value and failure cost

    An audit finding is not automatically an implementation priority. Automated crawlers are effective at finding patterns, but a warning may represent a serious defect, an intentional configuration, a platform limitation or a low-value imperfection. Manual validation and business context should come before a development ticket.

    A practical prioritization decision can be organized around five questions:

    1. Is the issue real? Confirm representative examples and determine whether the observed behavior is intentional.
    2. What is exposed? Establish how many URLs, templates or sections could be affected, with extra weight given to commercially or strategically important pages.
    3. What outcome is expected? State whether the work is intended to improve discovery, consolidate signals, preserve existing visibility, reduce wasted crawling or prevent a known failure mode.
    4. What does implementation require? Account for engineering effort, platform constraints, cross-team dependencies and the testing needed before release.
    5. What happens if the change is wrong? Consider the scale of lost crawl access, unintended consolidation, broken discovery paths or migration-related visibility loss.

    This framework prevents easily counted issues from crowding out consequential work. For example, an automated report may flag metadata on low-priority pages, while a canonical rule affecting an important template could receive less attention because it requires manual investigation. The number of warnings is not a reliable measure of business impact.

    Different changes also require different controls. URL moves need explicit redirect mappings, updated internal links and refreshed XML sitemaps. Canonical changes require validation of both the emitting template and its targets. Robots.txt edits should be checked against intended URL patterns and the production environment. Navigation changes need checks for orphaned pages, removed pathways and links pointing to non-public locations. A migration needs all of these controls coordinated because it can combine several high-risk changes in one release.

    Indexing diagnosis should start by testing the evidence itself

    Hands examine layered website pages and crawl paths with a magnifying lens, revealing a broken route and conflicting signal.

    An indexing chart can look authoritative while describing an older state of the site. One source reported that the Google Search Console page indexing report was more than two weeks behind, with June 11, 2026 shown as its latest timestamp. The report normally helps distinguish indexed from non-indexed pages, presents reasons for exclusion and can overlay impressions, but delayed processing limits its value for investigating recent events.

    The first diagnostic question should therefore be whether the evidence is current enough for the period under investigation. A stale report is not proof of a new indexing loss, nor does it prove that a recent fix failed. It establishes an observation boundary: aggregate conclusions about the missing period must remain provisional.

    When aggregate reporting is delayed, diagnosis can move through a layered sequence:

    1. Record report freshness. Note the visible processing date before comparing deployments with indexed-page totals or exclusion reasons.
    2. Inspect representative URLs. Use Search Console’s URL inspection capability for important examples, recognizing that this is a page-by-page investigation rather than a fresh sitewide report.
    3. Trace the technical signal chain. Check whether the URL can be reached through intended internal links, whether redirects lead to the expected destination, and whether canonical or noindex signals point elsewhere.
    4. Review crawl controls. Compare robots.txt rules with the affected URL patterns, particularly after a deployment or migration.
    5. Check discovery sources. Confirm that internal links and XML sitemaps contain the intended current URLs rather than old, redirected or non-public versions.
    6. Segment the pattern. Determine whether examples share a template, directory, parameter pattern or release. A common boundary can identify a systemic cause without treating every exclusion as the same problem.
    7. Separate visibility from index status. Use impressions and other available performance evidence as supporting context, not as a substitute for current indexing data.

    This sequence connects the indexing report’s categories with the implementation risks highlighted in the rollout guidance. Duplication, redirects, canonical choices, crawl restrictions and internal discovery are not independent dashboard labels; they are interacting signals. Conflicts between them can produce a symptom that looks like a single indexing problem even when the cause sits in a template or release process.

    Deployment controls create better evidence as well as safer releases

    Website components pass through staged safety gates while a defective module is diverted before reaching the production network.

    Testing is not only a safeguard. It also improves attribution by documenting what changed, where it changed and what successful behavior should look like. Without that record, a later movement in crawling, indexing or visibility is difficult to connect to a release.

    Before launch, teams should define the affected templates and priority sections, preserve a set of representative URLs, specify expected signals and agree on rollback criteria. Redirect mappings, canonical destinations, robots.txt patterns, internal links and sitemap entries should be validated in an appropriate test environment when the platform permits it. Early alignment with developers, content teams, product owners and other stakeholders is especially important when a change spans systems.

    After launch, the same examples should be checked again in production. Redirect destinations, canonical outputs, crawl directives, internal links and sitemap contents should match the approved plan. Monitoring should distinguish release timing from Search Console’s data timestamp so that reporting latency is not mistaken for implementation failure.

    Measurement can then be matched to the type of return:

    • Enhancement: evidence that a targeted change improved discovery, indexing or search visibility in the intended segment.
    • Maintenance: evidence that known technical defects or inefficient processes were removed and the expected technical state was restored.
    • Resilience: evidence that important pages retained access, signals and visibility through a migration, platform change or external search disruption.

    Where segmentation is feasible, the ROI source recommends a proof of concept resembling an SEO A/B test: apply a change to one segment, leave a comparable segment untreated and evaluate the relative result before expanding it. Sitewide infrastructure work may make that impossible. In those cases, relative trends, competitor movement around shared external events and longer-term performance can support an inference, but they should be labeled as proxies rather than causal proof.

    Funding discussions become more credible when the claim matches the evidence. Growth work can be evaluated against an expected improvement, while maintenance and resilience work can be framed in the language used for infrastructure, security and insurance: exposure, likelihood, consequence and cost of control. Scenario assumptions should remain visible instead of being converted into a single guaranteed revenue figure.

    Key takeaways

    • Audit counts do not determine priority; validate the issue, affected scope, business importance, effort and failure cost.
    • URL, canonical, robots.txt, internal linking and migration changes require controls proportionate to their sitewide exposure.
    • Check the processing date before using Search Console’s page indexing report to judge a recent release or indexing event.
    • When aggregate data is stale, inspect representative URLs and trace redirects, canonical signals, crawl controls, discovery paths and sitemap entries.
    • Report technical SEO as a mix of enhancement, maintenance and resilience, using experiments where possible and clearly labeled proxies where they are not.

    As search behavior and site platforms continue to change, technical SEO programs will need stronger release records and more explicit uncertainty, not more confident-looking dashboards. Teams that connect engineering controls with indexing evidence and financial framing will be better equipped to pursue meaningful gains without hiding the risk required to achieve them.

    References