Tag: API

  • Google Ads Developer AI Updates: A Practical Playbook

    Google Ads Developer AI Updates: A Practical Playbook

    You do not need another AI announcement in your backlog. You need to know whether Google’s direction changes what your advertising team should build, who should control it, and how much authority an AI agent should receive.

    The immediate answer is not to rebuild your Google Ads integration around agents. Treat the update as an architectural signal: prepare for AI systems to propose and invoke advertising actions, but keep permissions, validation, approvals, execution, and audit controls outside the model.

    The update is a learning channel, not an API release

    An engineer studies abstract signals from a studio beacon while a separate sealed production system remains unchanged on the workbench.

    Google has introduced Ads DevCast as a bi-weekly pilot hosted by Cory Liseno from its Advertising and Measurement Developer Relations team. Its technical scope includes Google Ads, Google Analytics, and Display & Video 360. Google is also inviting feedback while the pilot develops.

    That positioning matters. Ads Decoded, hosted by Ginny Marvin, addresses campaign strategy. Ads DevCast is intended for the people building, configuring, debugging, and governing the systems beneath that strategy. Subscribe the technical owner of your advertising stack, not only the person who manages campaigns.

    A new developer show does not, by itself, change an endpoint, schema, authentication flow, or deprecation date. Do not turn an episode into a production migration ticket merely because an idea sounds important. Use three separate lanes:

    • Discovery: Use Ads DevCast to notice technical themes, emerging capabilities, and the problems Google expects developers to encounter.
    • Verification: Confirm implementation details in the relevant official API documentation, release notes, schemas, and account controls before changing code.
    • Delivery: Create an engineering task only after you can name the affected platform, resource, operation, permission, test case, and rollback path.

    This distinction prevents two common errors. One is ignoring a directional signal until it becomes an urgent implementation problem. The other is treating a discussion of future architecture as though it were a released feature with stable production behavior.

    The agentic shift changes your control plane

    The first episode, titled “MCPs, Agents, and Ads. Oh My!”, presents an “agentic shift” in which AI agents become important users of advertising APIs. Treat that as Google’s direction of travel, not as evidence that every advertiser should give an agent unrestricted control of live campaigns.

    Model Context Protocol, or MCP, is relevant because it gives AI systems a common way to discover and invoke tools. A consistent tool interface can make an API easier for an agent to reach. It does not make the requested action correct, authorized, affordable, or reversible.

    The safest mental model is simple: the agent is a planner and operator working inside a control system. It is not the control system. A production workflow should separate intent from execution:

    1. Observe: Retrieve only the account and campaign data needed for the task.
    2. Propose: Produce a structured change showing the target resource, current value, proposed value, rationale, and expected scope.
    3. Validate: Check the proposal against the API schema, account state, internal policy, and allowed operations.
    4. Approve: Require the appropriate human or policy-based approval before any consequential write.
    5. Execute: Pass the approved action to deterministic code that calls the advertising API.
    6. Verify: Read the affected resource again, record the result, and surface any difference between the approved proposal and the final state.

    Put hard limits outside the prompt

    A prompt can tell an agent not to make risky changes. It should not be the only thing preventing them. The enforceable rules belong in the gateway between the agent and the ad platform.

    • Allowlist the accounts, resource types, fields, and operations the agent may access.
    • Use read-only access by default and grant write access per workflow rather than per agent.
    • Reject requests that omit the target account, current state, proposed state, or approval record.
    • Place budget, bid, scheduling, targeting, and deletion constraints in code or platform policy.
    • Use idempotency or equivalent duplicate protection where the operation supports it.
    • Log the request, tool call, actor, approval, API response, and resulting resource state.
    • Maintain a tested way to reverse mutable changes and a separate recovery procedure for actions that cannot be cleanly undone.

    This is a money-sensitive system. An agent with broad write access can alter live delivery before a person notices the mistake. For any action that can increase spend, narrow reach, pause revenue-producing activity, remove data, or change measurement, use a preview-and-approval flow until you have evidence that a more automated policy is safe for that exact operation.

    Turn each episode into an engineering decision

    A bi-weekly technical program can quickly become background noise unless someone owns the intake process. Give one person responsibility for converting each relevant item into a decision, including a deliberate decision to take no action.

    1. Capture the claim precisely. Write down the named product, capability, resource, or workflow. Avoid tickets such as “investigate AI for ads” because they have no testable boundary.
    2. Classify its status. Mark it as a concept, directional signal, pilot, documented capability, released change, or deprecation. Do not let enthusiasm silently upgrade its maturity.
    3. Map the affected surface. Identify whether it touches Google Ads, Google Analytics, Display & Video 360, or more than one system. Then name the relevant integration, credential, data flow, and owner.
    4. Verify implementation facts. Check the authoritative documentation for availability, supported operations, permissions, quotas, version requirements, and known limitations.
    5. Record the decision. Choose watch, prototype, adopt, migrate, or reject. Include the evidence needed to revisit that choice.

    Your decision record does not need to be elaborate. It should include the topic, status, affected system, documentation link, owner, next review trigger, test environment, approval requirement, and rollback method. That is enough to distinguish a useful technical signal from an unverified idea circulating in team chat.

    Use a prototype when the value is plausible but the operational risk is unclear. Start with a read-only workflow that answers one bounded question, then let the agent draft a change without executing it. Compare its proposal with the decision a qualified operator would make. Only after that should you test an approved write in a controlled account or environment.

    Because Ads DevCast is a pilot seeking community input, document where explanations leave an implementation gap. Useful feedback is specific: name the platform, operation, missing detail, and decision you could not safely make. That gives Google a clearer request than a general demand for more examples.

    Your ownership model must evolve with the integration

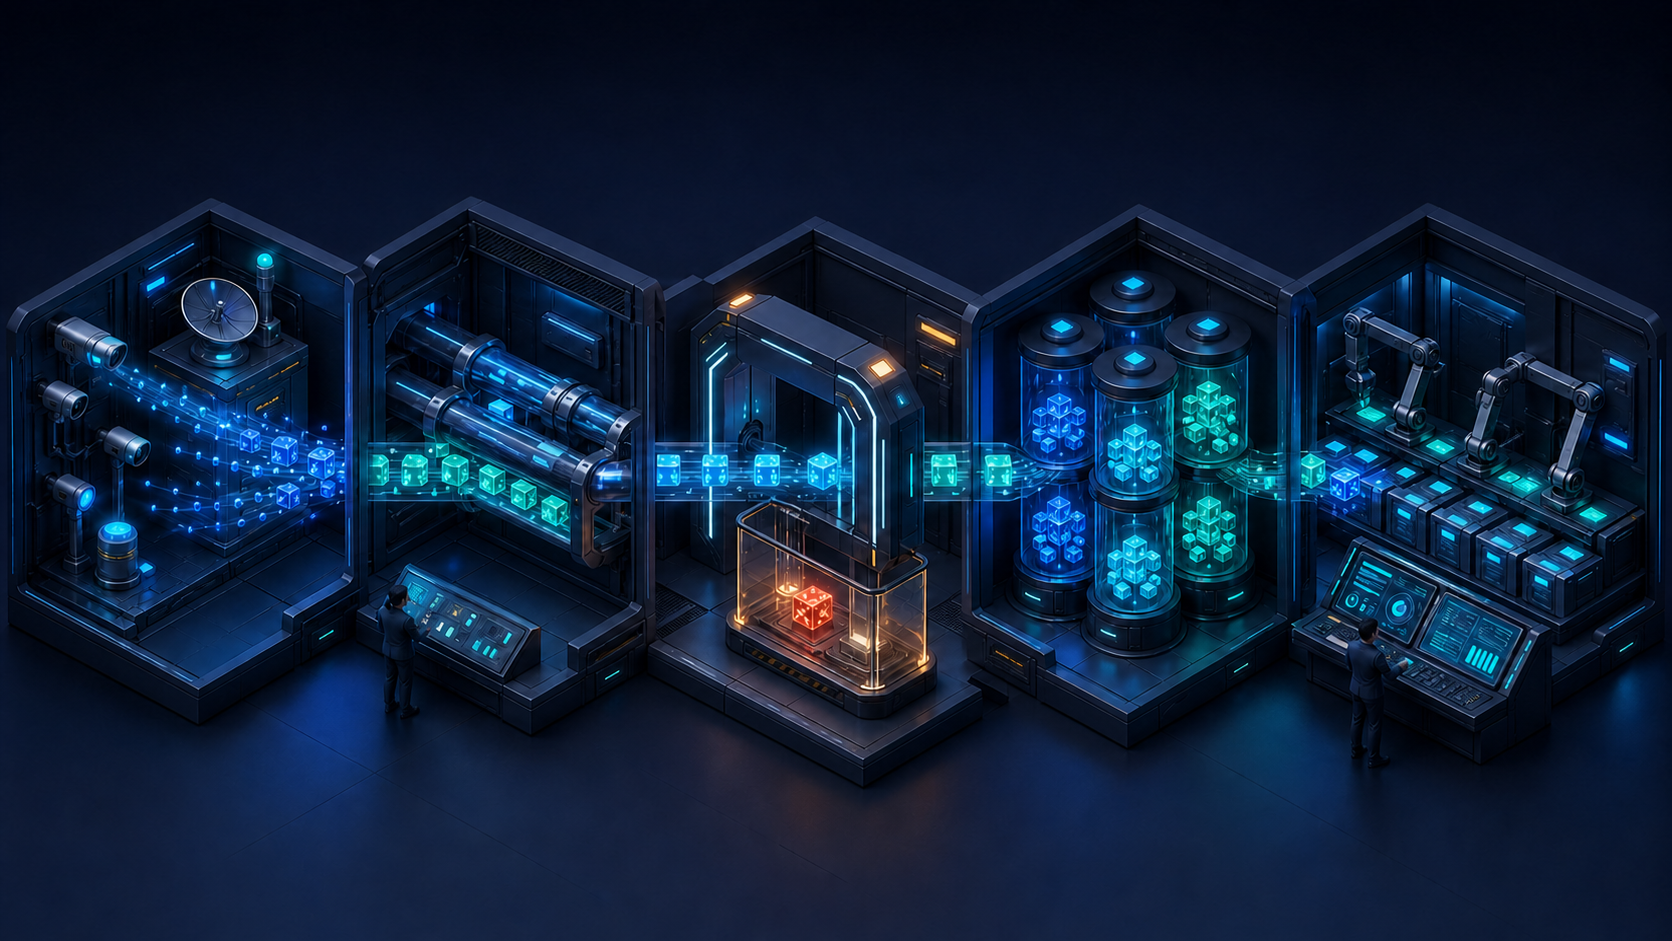
    An isometric AI advertising workflow routes action tokens through access controls, validation, human review, staging, and an audit vault while separate teams supervise their areas.

    Google is broadening the frame from a specialist Ads Developer Community toward a wider Ads Technical Community. That makes room for marketers to perform more technical work without waiting for a full development cycle. It does not erase the need for engineering ownership; it changes where the handoffs occur.

    Before connecting an agent to advertising tools, assign these responsibilities by name:

    • Business owner: Defines the campaign objective and decides which tradeoffs are acceptable.
    • Platform owner: Controls credentials, permissions, API configuration, and production access.
    • Workflow owner: Defines the agent’s tools, inputs, outputs, validation rules, and failure behavior.
    • Approver: Reviews consequential changes and has enough context to reject a technically valid but commercially poor action.
    • Incident owner: Can stop execution, assess affected resources, restore safe state, and preserve the audit trail.

    Do not collapse all five roles into “the AI team.” The business owner knows what should happen. The platform owner knows what can happen. The workflow owner controls how a request becomes an API call. The approver evaluates the actual change. The incident owner handles the moment when the system behaves differently from the plan.

    This division also makes low-code and agent-assisted work more practical. A marketer can describe or initiate a task without receiving unrestricted platform access. Engineering can provide constrained tools and reusable policies instead of implementing every request from scratch. The speed comes from a safer interface between roles, not from removing the roles.

    Key takeaways for your next working session

    • Use Ads DevCast as a technical discovery channel; verify every implementation detail in authoritative product documentation.
    • Treat Google’s agentic direction as a reason to prepare your architecture, not as permission to automate every campaign action.
    • Keep the agent focused on observation and structured proposals before granting narrowly scoped write capability.
    • Enforce permissions, spend constraints, approvals, logging, and recovery outside the model and its prompt.
    • Assign business, platform, workflow, approval, and incident ownership before connecting an agent to a live advertising account.
    • Convert each relevant update into a recorded decision: watch, prototype, adopt, migrate, or reject.

    Start with one existing Google Ads workflow that consumes too much operator time but has a clear input and output. Draw the six stages from observation through verification. Mark every place where a bad decision could affect spend, delivery, measurement, or data. Those marks define the controls your agent needs before it gets write access.

    Then build the smallest read-only version and require a structured proposal. That gives you a concrete way to evaluate Google’s agentic direction without betting a live account on an immature design.

    References


  • Google’s Universal Commerce Protocol: A Retailer Playbook

    Google’s Universal Commerce Protocol: A Retailer Playbook

    If you run ecommerce SEO, product feeds, or shopping infrastructure, your next visibility problem may not begin on a search results page. It may begin when an AI shopping agent tries to identify the right variant, confirm that it is available, calculate the correct price, and place it in a working basket.

    Google’s Universal Commerce Protocol, or UCP, is intended to connect those steps. Your practical task is to make product and customer data usable across discovery, selection, and checkout without assuming that protocol adoption will automatically produce rankings, recommendations, or sales.

    UCP moves product visibility closer to the transaction

    Traditional search optimization prepares a page for a person to discover and visit. Agentic commerce adds another route: software may evaluate products, assemble a purchase, and act for the shopper. UCP is an open, modular standard for connecting retailers with AI-driven shopping experiences.

    That does not make product pages irrelevant. It changes where accuracy has to survive. A persuasive description cannot compensate for an unavailable variant. Valid page markup cannot repair a cart that calculates the wrong price. A feed can expose a product, but the transaction can still fail if customer benefits disappear after identity linking.

    This gives you four connected layers to manage:

    • Page content and structured data explain the product in a crawlable, understandable form.
    • Catalog data supplies current commercial facts such as price, inventory, and available variants.
    • Cart logic turns selected items into a valid basket.
    • Identity and account logic determine whether the shopper receives eligible benefits.

    Keep these layers aligned, but do not treat them as interchangeable. UCP is not merely another name for JSON-LD, a product feed, or an ad format. It reaches into live commerce functions that page-level optimization alone cannot perform.

    Google has said it plans to use UCP capabilities in AI-enhanced experiences across Search and the Gemini app. That establishes a direction, not a promise that every retailer, market, capability, or product will receive the same access or exposure. Build readiness around documented availability and your own eligibility rather than an assumed rollout.

    Map each UCP capability to a real retail responsibility

    The useful way to evaluate UCP is capability by capability. Each one touches a different system, failure mode, and internal owner.

    CapabilityWhat it enablesWhat you should verifyLikely owner
    CatalogAccess to current product information, including pricing, inventory, and variantsStable identifiers, variant mapping, update freshness, and agreement between catalog, product page, and checkoutMerchandising, feed operations, or commerce platform team
    CartMultiple products from one retailer can be assembled into one basketAdd, update, remove, reprice, and out-of-stock behavior across a multi-item orderEcommerce engineering
    Identity linkingEligible benefits such as member pricing and free shipping can continue across connected experiencesAuthentication, consent, entitlement rules, session handling, and safe failure behaviorIdentity, security, loyalty, and legal or privacy teams
    Modular adoptionA retailer or platform can adopt selected capabilities instead of implementing everything at onceA rollout sequence tied to system readiness and a clear dependency mapCommerce product owner or program lead

    The capability names do not answer every implementation question. For example, knowing that an agent can create a cart does not by itself define how your taxes, promotions, substitutions, shipping restrictions, or returns work. Treat those as test cases that need authoritative documentation and validation in your own stack. Do not invent behavior from the protocol’s high-level description.

    Modularity is especially important for planning. You do not need to frame UCP as an all-or-nothing rebuild. If your identity system is not ready, that does not erase the value of repairing catalog inconsistencies. If your catalog cannot reliably distinguish variants, however, adding an agent-facing cart simply moves bad data closer to checkout.

    Audit product data as if it were the storefront

    An unbranded jacket, variant swatches, packaging, inventory objects, and a magnifying lens are arranged for a detailed product data audit.

    An agent cannot walk a virtual aisle and infer that a stale price is probably wrong. It receives representations of your inventory and has to make decisions from them. Because the catalog capability is designed to expose real-time pricing, inventory, and variant information, conflicting product facts become a commercial problem, not merely a feed-cleanup task.

    Start with one product family that has meaningful variation. A product with size, color, configuration, or member pricing will reveal more than a simple item with one price and one stock state. Trace it through every system an agent-assisted purchase could touch.

    1. Resolve the identity chain. Confirm that the parent product, each purchasable variant, the catalog record, the product page, and the cart line resolve to the intended item. A parent identifier should not silently stand in for a specific variant at purchase time.
    2. Name the source of truth for each commercial fact. Decide which system owns price, sale price, inventory, variant attributes, and account benefits. If two systems can overwrite the same fact, document precedence and failure handling.
    3. Compare anonymous and authenticated states. Check whether public pricing, member pricing, shipping benefits, and eligibility rules remain distinguishable. The agent should not present a conditional benefit as universal.
    4. Test change propagation. Change a price or inventory state in the owning system and observe every downstream representation. Record your actual delay and failure points rather than relying on the intended architecture.
    5. Inspect contradictions. Compare the catalog, rendered product page, structured data, basket, and logged-in experience. Any disagreement can lead to a poor recommendation, a rejected add-to-cart action, or an unpleasant price change at checkout.
    6. Log failed and stale updates. A synchronization process that usually works is not enough. Your team needs a way to identify which products failed, when the last successful update occurred, and which downstream surfaces may still carry old information.

    This is also where SEO, GEO, and feed teams should coordinate. Keep descriptive content and structured data consistent with commercial systems, but do not add unsupported claims to markup merely to make the product look more complete to an AI system. The safest machine-readable answer is the same answer the shopper will receive in the cart.

    Do not call the audit complete because a sample record validates syntactically. A valid record can still identify the wrong variant, carry an old price, or point to inventory that cannot be purchased. Validation checks form; transaction tests check truth.

    Roll out the smallest capability you can verify end to end

    A coffee maker follows one illuminated path through catalog, inventory, basket, payment, and delivery modules while unused modules remain dark.

    Catalog readiness is usually the sensible first workstream because cart and identity experiences depend on accurate merchandise data. That is a sequencing recommendation, not a protocol requirement. Your architecture may justify a different order, but every pilot should have one defined capability, one accountable owner, and an observable pass or fail condition.

    1. Choose a bounded product set. Select products that expose the problems you need to solve, including variants or conditional benefits, while keeping the pilot small enough to inspect manually.
    2. Capture a baseline. Record current catalog mismatches, failed add-to-cart actions, unavailable variants presented as purchasable, and benefit-entitlement failures. Without a baseline, protocol activity can look like progress while customer-facing accuracy remains unchanged.
    3. Define acceptance tests before integration. Write expected results for price changes, inventory changes, variant selection, multi-item baskets, account linking, and entitlement loss. Include negative cases, not just a successful purchase.
    4. Test the cart as a changing object. The new cart capability is intended to let agents place multiple products from one retailer into a single basket. Verify what happens when quantity changes, one line becomes unavailable, a promotion expires, or the shopper switches variants.
    5. Isolate identity testing. Identity linking can preserve member pricing and free shipping, but it also touches account access and personal data. Use controlled test accounts and obtain security, privacy, and legal approval before exposing real customer identities. The specific downside of rushing this step is not just a broken discount; it can be unauthorized account access or inappropriate data sharing.
    6. Monitor outcomes by failure stage. Separate catalog retrieval, variant resolution, cart creation, cart mutation, authentication, entitlement, and checkout failures. A single conversion total will not tell you which capability needs repair.

    Your ownership model matters as much as the integration. Feed operations can correct a variant mapping but should not define authentication policy. SEO can identify contradictions visible to search systems but should not own checkout integrity. Ecommerce engineering can make a cart function without knowing whether member benefits are represented correctly. Put these teams behind one shared test plan rather than handing UCP to whichever team first notices it.

    Google has also indicated that it plans to simplify UCP onboarding through Merchant Center. Use that as a reason to prepare your data and test cases, not as a reason to assume that implementation is already automatic. When onboarding becomes available to you, confirm supported capabilities, required fields, market coverage, permissions, and reporting from the documentation presented in your account.

    Most importantly, do not report UCP adoption as an SEO win by itself. There is no basis here for calling it a guaranteed ranking factor or recommendation boost. Measure what you can actually observe: eligibility, accurate product representation, successful basket creation, preserved benefits, completed purchases, and the failure rate at each handoff.

    Key takeaways

    • UCP connects product discovery with live commerce functions; it is broader than page markup, feeds, or advertising alone.
    • Catalog accuracy is foundational because price, inventory, and variant errors can follow an agent directly into the cart.
    • Cart, catalog, and identity linking should be treated as separate capabilities with separate owners and tests.
    • Modular adoption lets you start with a bounded capability instead of waiting for a complete commerce-stack rebuild.
    • Identity linking requires controlled testing and security, privacy, and legal review before real customer accounts are involved.
    • Protocol adoption does not establish a ranking or recommendation benefit. Evaluate transactional accuracy and measurable outcomes.

    Your best next step is concrete: take one high-value product family with variants, compare its catalog record, product page, structured data, cart, and logged-in benefits, then document every contradiction. That exercise will tell you whether your first UCP project is an integration project or, more likely, a product-data repair project that needs to happen before integration can deliver anything useful.

    References

  • What the Reddit-SerpApi Scraping Fight Means for SEO Data

    What the Reddit-SerpApi Scraping Fight Means for SEO Data

    If your SEO or AI workflow retrieves Reddit material from Google result pages rather than from reddit.com, you may be tempted to label it indirect public data and move on. The Reddit-SerpApi dispute shows why that shortcut is dangerous: the address you requested is only one part of the legal and operational analysis.

    SerpApi is asking a federal court to dismiss Reddit’s amended complaint. Reddit alleges that large amounts of its content were extracted through Google Search. SerpApi counters that it accessed Google pages, that Reddit does not own most user posts, and that Reddit has not adequately established technical circumvention or concrete harm. Those are opposing positions, not judicial findings. Until the court rules, neither side’s argument gives your team permission to treat a similar pipeline as settled law.

    Key takeaways

    • Fetching a Google result page instead of visiting Reddit directly changes the facts, but it does not automatically eliminate copyright or access-control questions.
    • Audit the actual payload. URLs, rankings, dates, short snippets, full comments, and complete threads create different copying and provenance issues.
    • Public visibility and technical circumvention are separate questions. A page can be publicly viewable while the collection method still encounters controls that demand legal review.
    • Content ownership and platform licensing are also separate. A user’s ownership of a post does not, by itself, prove that every third-party reuse is lawful.
    • Your safest immediate investment is traceability: retain acquisition routes, response fields, control events, transformations, retention rules, and downstream recipients for every dataset.

    The dispute turns “scraping” into five separate questions

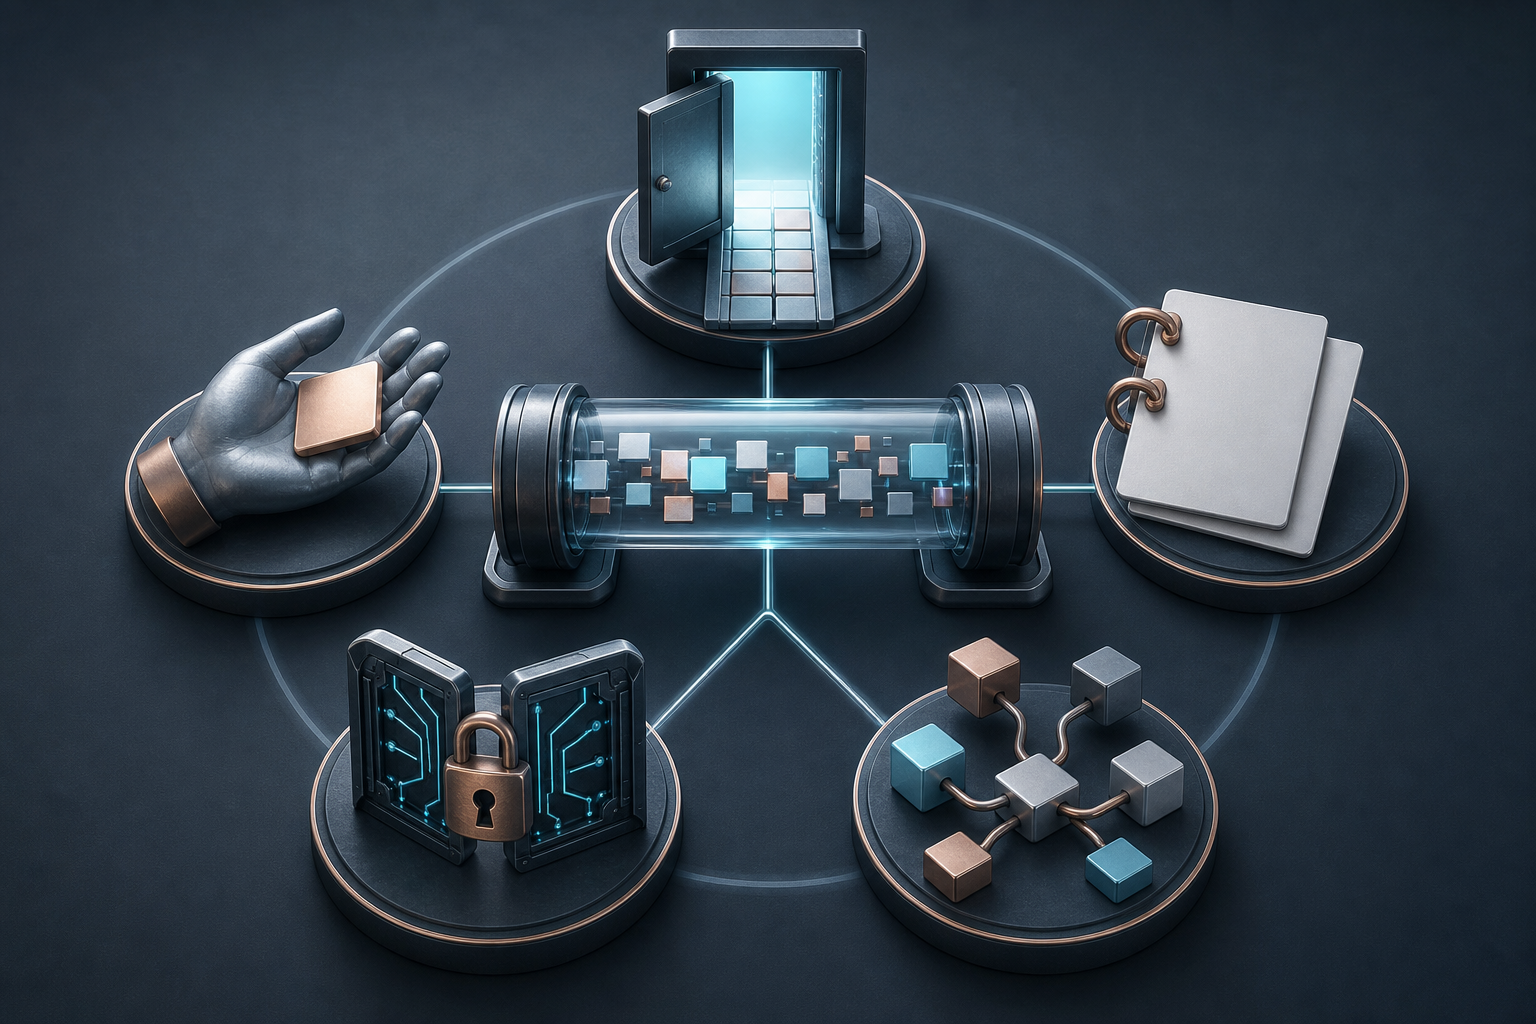
    Five symbolic lenses surround a transparent pipeline carrying abstract content tiles, with a doorway, hand, blank documents, circuit gate, and application modules representing different areas of review.

    Calling a system a scraper tells you almost nothing about its legal posture. A useful review separates who holds rights, what was copied, where the response came from, how the collector reached it, and what harm is alleged. Mixing those questions is how a technical description such as “we only queried Google” gets mistaken for a legal conclusion.

    QuestionDisagreement in the caseWhat your team should preserve
    Who holds rights in the material?SerpApi relies on Reddit’s user arrangements to argue that users retain ownership and Reddit generally holds a non-exclusive license.The creator, platform, applicable terms, asserted license, and rights basis for each collected field.
    What exactly was copied?SerpApi argues that the examples identified by Reddit include dates and short fragments that are not protectable expression.Representative payloads showing whether you store metadata, snippets, comments, threads, media, or combinations of those fields.
    Which system returned the data?SerpApi says it accessed Google Search pages rather than interacting directly with Reddit.Requested hosts, final URLs, redirects, response headers, collection jobs, and the origin assigned to each field.
    Was a technical measure circumvented?SerpApi says Reddit has not shown an encryption breach or authentication bypass and characterizes the pages it accessed as publicly available.Authentication states, challenge pages, block responses, rate-limit events, bot defenses, retries, proxy changes, and any code intended to handle them.
    What harm followed?SerpApi argues that Reddit has not adequately pleaded tangible harm caused by its conduct.Collection volume, retention, redistribution, customer access, substitution for the original service, incident reports, and takedown history.

    Keep the five answers independent. If Reddit cannot establish ownership of particular user posts, that may weaken an ownership-dependent theory, but it does not prove that every use of those posts is lawful. If a date or fragment lacks enough expression to be copyrightable, that does not resolve how the system obtained it. If no access control was circumvented, that may answer one DMCA theory without answering every other issue raised by the collection and reuse.

    The current procedural posture matters too. A motion to dismiss challenges whether the complaint states legally sufficient claims; it is not a factual finding that the challenged conduct was lawful. If the claims survive, that likewise means they can proceed, not that Reddit has already proved liability.

    Why the Google layer is not a legal shield

    An indirect pipeline has at least three layers: Google returns a search page, that page contains material derived from Reddit, and your system stores or republishes some part of the result. The host that returned the bytes is relevant, but it does not identify every party with an interest in the content or collection method.

    Reddit’s allegation involving a decoy post created solely for Google’s crawler is important for that reason. Reddit uses the alleged appearance of that material to support its account of how the defendants acquired Reddit-derived content through Google. SerpApi answers that an ordinary user could see the same material in public search results. The court still has to decide whether Reddit’s allegations are legally sufficient and, if the case proceeds, what the evidence establishes.

    There is also an upstream problem. Google separately alleges that SerpApi bypassed bot protections while scraping licensed search functionality. SerpApi has sought dismissal there as well, arguing that the DMCA is being used to restrict access to public search results. In practical terms, routing collection through a search engine may exchange one platform-access question for another rather than remove the question entirely.

    For an SEO, AEO, or GEO system, review both sides of that route. First ask whether the collector was permitted to obtain the search response in the manner used. Then ask what rights and restrictions may follow the Reddit-derived material inside that response. Do not let a clean answer at one layer stand in for an answer at the other.

    Run a field-level audit before expanding collection

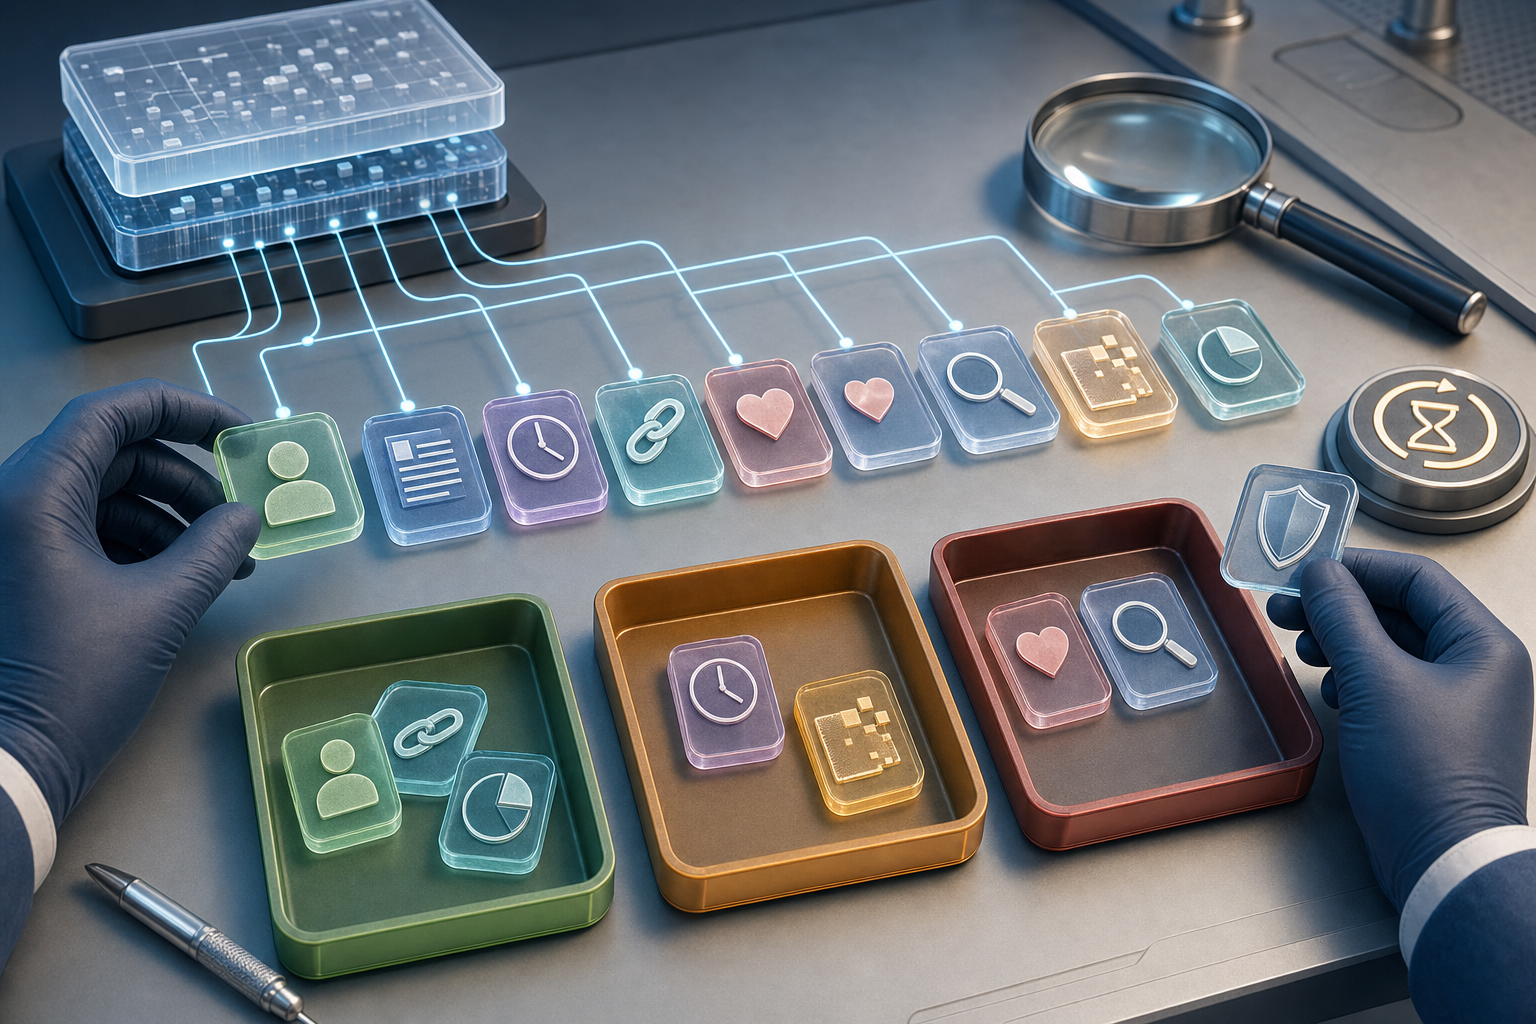
    Gloved hands sort the separated fields of a generic web record into color-coded trays beside a magnifying lens, privacy shield, timer, and source trail.

    Your lawyers cannot evaluate a label such as “SERP data,” and your engineers cannot implement advice framed only as “reduce scraping risk.” Give both groups a field-level map of the system. This is not a substitute for legal advice about your particular facts; it is the evidence package that makes useful advice possible.

    1. Map the complete request path. Record the initial host, redirects, rendered page, APIs or browser automation involved, proxy layer, authentication state, and retry logic. Distinguish a request sent to Google from a later request sent to Reddit.
    2. Define the collection unit. List every retained field: query, rank, result URL, title, date, snippet, author name, subreddit, comment text, thread text, media, and cached page. Do not describe a full-thread archive as metadata merely because the job began on a search page.
    3. Attach provenance to each field. Store the page that supplied it, the underlying content platform when known, the collection time, and the transformation applied. A field should not lose its origin when it moves from raw storage into a feature table, embedding index, model corpus, or customer export.
    4. Document the rights theory instead of assuming one. For each field, state why the organization believes it may collect, retain, transform, and distribute that material. Flag any theory that reduces to “it was public” for legal review.
    5. Preserve control events. Log authentication prompts, denied responses, block pages, rate limits, bot challenges, and code changes made in response. Do not instruct a collector to evade a control while waiting for counsel to decide whether the control matters.
    6. Trace every downstream use. Separate internal measurement from customer-facing display, bulk export, dataset resale, AI training, retrieval-augmented generation, and verbatim output. The same input can create a materially different question when the product begins returning the original text to other people.
    7. Build deletion and shutdown paths. You should be able to stop one connector, one field, one customer export, or one corpus without taking the entire product offline. Also identify derived stores, such as embeddings and caches, that would otherwise survive deletion of the raw record.

    The resulting audit record can be compact. For each collection job, capture the system owner, requested host, content origin, fields retained, controls encountered, asserted rights basis, retention period, downstream recipients, deletion path, and stop trigger. If your team cannot fill in one of those entries, mark it unknown rather than turning an assumption into policy.

    Payload minimization is especially useful while the law remains contested. A rank-monitoring feature may need a result URL and position but not a permanent archive of every Reddit snippet. A citation feature may need a URL and a short display label but not the full discussion. An AI discovery tool may need topical signals while having no product reason to reproduce complete comments. Delete fields that do not support a named function, and stop collecting them at ingestion rather than relying only on later cleanup.

    Be equally precise about AI use. “Used for AI” can mean measuring whether Reddit appears in search results, retrieving a passage at query time, generating embeddings, fine-tuning a model, or displaying source text beside an answer. Record those as distinct operations. Otherwise, a rights review performed for internal analytics can silently become the justification for a customer-facing content product it never evaluated.

    Plan for the ruling without betting your product on it

    A result for either side will be easy to overread. A dismissal based on Reddit’s ownership allegations would not necessarily approve every method of collecting Google results. A ruling focused on short, unprotectable fragments would not automatically cover full comments or threads. A conclusion that the alleged conduct did not amount to circumvention would depend on the controls and access path before the court, not on the generic fact that software performed the request.

    A dismissal with prejudice would end Reddit’s claims against SerpApi in this instance. It would not function as a universal license for SERP scraping, Reddit reuse, or AI training. Conversely, if the amended complaint survives dismissal, that would allow the litigation to continue without establishing that every comparable SEO tool is unlawful.

    You can make several product decisions now without predicting the winner:

    • Freeze expansion of any job whose access route, collected fields, or response to technical controls cannot be reconstructed.
    • Replace blanket claims such as “public data is safe to scrape” with a review that names the host, payload, controls, rights basis, and downstream use.
    • Separate collection modules by platform and field so one disputed input can be disabled without breaking unrelated search intelligence.
    • Require approval before an internal dataset becomes a customer export, training corpus, or feature that displays source language.
    • Give legal and engineering owners the same incident trigger: a new block mechanism, authentication requirement, complaint, takedown request, or material change in collection volume should reopen the review.
    • Preserve enough technical history to explain what the system did before a dispute begins. Reconstructing access behavior after logs have expired leaves both counsel and engineers working from memory.

    Your immediate job is not to decide whether Reddit or SerpApi will win. It is to make your own pipeline explainable and stoppable. If you cannot identify who returned the data, who created it, what you retained, which controls you encountered, and where the material went next, pause the expansion and complete that map first.

    References

  • Google Ads Data Operations: A Practical Control System

    Google Ads Data Operations: A Practical Control System

    Your dashboard is off, an audience job failed, or traffic climbed without producing more revenue. Those look like separate Google Ads problems. Operationally, they share one risk: a bad input can trigger a costly decision before anyone proves what changed.

    You need a control system that separates collection, transport, reporting, audience activation, and campaign action. Once those layers are visible, you can pause only the affected decisions, repair the right component, and keep trustworthy signals flowing into automated bidding.

    Key takeaways

    • Do not change bids or budgets until you have classified an unexpected metric movement as a real business change, a collection failure, a transport problem, a reporting delay, or an activation issue.
    • Report availability is not the same as report freshness. Record the last complete timestamp, affected dimensions, and last-known-good comparison before acting.
    • Build a small set of durable first-party audiences around meaningful customer states. Excessive segmentation reduces usable data and creates more failure points.
    • Validate the Customer Match upload path itself. Successful campaign-management requests do not prove that an inactive developer token can still upload Customer Match data.
    • Treat invalid traffic as both a budget problem and a data-integrity problem. Audit the riskiest inventory first, then judge controls by downstream business outcomes.

    Diagnose reporting before you optimize the campaign

    A dashboard number is the endpoint of a pipeline, not an independent source of truth. A conversion can occur correctly while its report is delayed. A report can refresh normally while the conversion tag has stopped firing. A campaign can also deteriorate for real while every technical component is healthy. Those cases can look identical in the interface for a while, but they demand different responses.

    Use an explicit data map so every anomaly has somewhere to go:

    LayerQuestion to answerEvidence to inspect
    Business outcomeDid leads, orders, qualified opportunities, or revenue actually change?Order system, CRM, call records, payment records, and their timestamps
    CollectionDid the expected website or app event occur and carry the required data?Site or app logs, tag diagnostics, analytics events, and test conversions
    TransportDid an upload, import, export, or scheduled integration complete?Job status, response errors, processed record counts, and last successful run
    Processing and reportingIs the interface showing complete, current, and consistently defined data?Freshness timestamps, platform status, report filters, dimensions, and an independent reporting view
    Activation and decisionDid the audience or conversion signal reach the intended campaign, and is a campaign change justified?Audience state, campaign configuration, exclusions, bidding inputs, and account change history

    A Google Ad Manager incident illustrates the distinction. Ad Manager is the publisher product, not the Google Ads buying interface, yet the operational lesson transfers: users could log in while the newest data was unavailable and current reports disagreed with the legacy reporting tool. Platform access therefore proved neither freshness nor consistency.

    Use the same triage sequence every time

    1. Define the anomaly. Write down the metric, affected campaigns or properties, first abnormal timestamp, last-known-good timestamp, reporting timezone, and comparison period. “Conversions are down” is too vague to investigate.
    2. Protect the account from premature action. Pause major bid, budget, targeting, and exclusion changes that depend on the disputed metric. Do not pause healthy campaigns merely because one report is late.
    3. Test freshness before magnitude. Identify the latest complete period. A partially processed period should not be compared with a completed one as if both were final.
    4. Reconcile definitions. Confirm that filters, conversion actions, campaign scope, attribution settings, dimensions, and time boundaries match. Two correctly calculated reports can disagree because they answer different questions.
    5. Trace the outcome upstream. Check whether orders, leads, calls, or qualified opportunities changed in the underlying business system. This separates a reporting fault from a plausible performance event.
    6. Inspect collection and transport. Check event flow, import jobs, API errors, record counts, and the last successful run. A successful login or unrelated API request is not proof that the relevant pipeline worked.
    7. Check the platform status and preserve evidence. Save the affected report configuration, timestamps, screenshots, exports, and error responses. If the issue is not listed, give support a reproducible case rather than a general complaint.
    8. Release decisions selectively. Resume only the actions supported by verified data. Keep decisions tied to the damaged layer on hold until freshness and consistency return.

    Do not force two reports to agree by changing campaign settings. If internal sales remain stable while the newest platform data is incomplete, wait for processing and reconcile later. If the conversion event disappears while sales continue, repair collection. If both business outcomes and verified reporting decline, a campaign or market response becomes reasonable. Classification comes before optimization.

    Turn audience lists into controlled data products

    First-party audiences are not folders you fill once and revisit when someone wants a retargeting campaign. They are production inputs. Their definitions, refresh jobs, permissions, exclusions, and destinations affect how Google interprets your customers.

    Google Ads groups these inputs under “Your data segments.” The practical inputs are website visitors, app users, Customer Match records, and people who engaged with content on Google-owned properties. Website audiences can originate through tagging or analytics; app audiences can flow through Firebase or another analytics setup; Customer Match begins with proprietary customer records; and content engagement can include YouTube viewers or Google Engaged Audiences.

    The first mistake is treating every available behavior as a new audience. A list defined by an incidental detail, such as a visit on a particular weekday, rarely expresses a durable business state. It also divides the available signal into smaller pools, multiplies refresh and QA work, and makes exclusions harder to reason about.

    Start with states that would change a real marketing decision:

    • Known customers: people who completed the outcome your bidding system is meant to find.
    • Qualified prospects: people who reached a meaningful qualification point but have not become customers.
    • High-intent non-converters: people who reached a product, cart, application, booking, or equivalent decision stage without completing it.
    • Broader engaged visitors or users: people with a valid interaction who have not yet shown high intent.
    • Suppression groups: existing customers, employees, test records, disqualified leads, or other groups that should not receive a particular message.

    Keep the states separate only when you will change targeting, creative, bidding interpretation, or exclusion logic because of the distinction. If two lists always receive the same treatment, their separation is probably operational overhead rather than strategy.

    Give every audience a contract

    An audience contract is a short record that lets another operator understand and verify the list without reverse-engineering it. Store these fields in your operating documentation:

    • A plain-language business definition and the decision the audience supports
    • The system of record, technical owner, and business owner
    • Inclusion logic, exclusion logic, and how conflicting states are resolved
    • The refresh trigger or schedule and the last successful refresh
    • Expected record-count behavior, with an alert for an empty or unexpectedly changing result
    • The Google Ads destination and the intended role: targeting, observation, exclusion, or audience signal
    • The campaigns allowed to consume the audience
    • The permissions governing the data and the condition under which the audience must be retired

    Only send customer records your organization is authorized to use for advertising. A secure API can protect transport, but it cannot correct an invalid permission model or a list definition that includes the wrong people.

    The campaign role matters because the same audience can behave differently across campaign types. Search, Shopping, and Display can use data segments for targeting, observation, or exclusion. Performance Max and App campaigns can consume them as audience signals and can also use supported exclusions. A signal is not a promise that delivery will remain inside the list, so document it differently from a hard restriction. Demand Gen can be a useful activation surface when the audience and message support visual storytelling.

    Direct retargeting is not the only reason to maintain these inputs. Clean customer data can also help Smart Bidding and Optimized Targeting recognize the characteristics of real buyers. That makes list quality more important, not less. A stale customer list or an audience mixing customers with low-quality leads teaches a less precise lesson.

    Review audience operations as a lifecycle: create, validate, activate, monitor, update, and retire. Watch both directions. An unexpected collapse can indicate a broken source or upload; an unexplained surge can indicate relaxed logic, duplicated records, or a source-system change. Neither should silently become a new bidding input.

    Make Customer Match transport a supported system

    Anonymous geometric customer records move through a secure validation pipeline into segmented audience containers, with one malformed batch diverted to quarantine.

    A well-designed customer audience can still fail at the transport layer. This is especially easy to miss when the same developer token continues to perform unrelated campaign-management work.

    Google’s announced cutoff for inactive Customer Match upload tokens was April 1, 2026. Under the announced rule, a developer token with no Customer Match upload through the Google Ads API during the previous 180 days would lose that upload capability. Attempts from an affected token would fail, while other Google Ads API campaign-management functions would continue.

    The important word is “upload.” General API activity does not satisfy a condition defined around Customer Match uploads. A green campaign update, reporting request, or authentication check therefore cannot validate this path.

    Run a focused continuity audit:

    1. Inventory every producer. Record the application, developer token, source system, account destination, audience destination, execution schedule, credential owner, and operational owner for each Customer Match job.
    2. Find the last successful upload. Use job logs and API responses, not a developer’s memory or the modification date of a script. Distinguish a completed Customer Match upload from other successful requests made with the same token.
    3. Test the actual path. Use a controlled, authorized dataset and destination. Capture the response, available processed or rejected counts, resulting audience state, and time of the test. Do not expose live customer records merely to diagnose connectivity.
    4. Classify failures precisely. Separate authentication, token eligibility, permissions, malformed data, source extraction, transport, and destination errors. “The API failed” is not an actionable incident category.
    5. Build the Data Manager path. Google directed affected upload operations toward the Data Manager API, positioning it as a unified ingestion system with stronger security, confidential matching, and improved encryption. Validate this path against a controlled destination before changing the production schedule.
    6. Cut over with observability. Alert on failed runs, empty inputs, abnormal count changes, missing destination updates, and repeated retries. Preserve logs and the prior configuration until the replacement has completed its expected operating cycle.
    7. Update ownership documentation. Record where credentials live, who approves source changes, who responds to failures, and how downstream campaign owners are notified when audience freshness is uncertain.

    Do not manufacture meaningless uploads to simulate activity. That leaves the underlying dependency in place and can contaminate a real audience. The durable response is to verify eligibility, move the workflow where required, and make upload success visible to someone who can act.

    Use invalid traffic checks to protect the learning loop

    A transparent verification mesh diverts clusters of repetitive event signals while varied trusted signals continue toward an automated learning system.

    Invalid traffic costs you twice. It can consume spend, and it can distort the observations used to evaluate placements, audiences, and automation. A click with no genuine consumer intent is therefore not just a media-quality issue. It is a measurement contaminant.

    The mechanisms vary. Botnets can generate automated interactions through compromised devices. Click farms manufacture engagement through people or scripts. Malware and ad injection can redirect users or insert unauthorized ads. Pixel stuffing and ad stacking can register delivery even when an ad was not meaningfully visible.

    Do not turn a broad industry estimate into an account threshold. Fraud Blocker estimated an average Google Ads invalid-click rate of 11.4% and reported a trend from 5.9% in 2010 to 12.3% in 2024. That is vendor-supplied analysis, not a universal baseline, a guaranteed refund rate, or proof that any particular account has the same exposure.

    Audit inventory in risk order

    Use campaign type as an investigation priority, not a verdict. Video Partners warrant early scrutiny because delivery extends beyond YouTube into third-party inventory. Display needs placement-level review because publisher quality varies. Shopping and Demand Gen can attract automated price-checking or other non-buying activity that is not always malicious but can still weaken the signal. Performance Max spreads delivery across inventory while offering less direct source visibility. Search is generally the lower-risk starting point, but even a small amount of invalid activity can matter when clicks are expensive.

    Build an exception view around patterns you can investigate:

    • Placements or apps with substantial click activity but little or no downstream business activity
    • Geographic traffic that conflicts with the market you can actually serve
    • Activity concentrated outside the times when legitimate demand normally occurs
    • Click growth that is not accompanied by comparable sessions, qualified actions, or business outcomes in internal systems
    • Campaign changes that suddenly expanded networks, locations, keyword reach, or automated inventory
    • Differences between internally logged activity, Google-reported activity, and invalid-traffic credits or refunds

    None of those patterns proves fraud by itself. A placement can fail because the audience-message fit is poor. Overnight demand can be legitimate. Analytics can undercount because collection is broken. Investigate across the data layers before labeling traffic malicious.

    When the evidence supports containment, tighten the specific exposure rather than rebuilding the whole account at once:

    • Use physical-presence location targeting when interest-based geographic expansion admits traffic you cannot serve.
    • Test focused, high-intent terms against broad generic reach where Search quality is uncertain.
    • Isolate Google Search Network traffic from Search Partners or Display exposure so performance can be evaluated separately.
    • Maintain negative-keyword, placement, and app exclusions based on documented patterns.
    • Align ad schedules with legitimate operating and demand periods when off-hour activity is demonstrably low quality.
    • Review placement data and Google’s detected-invalid-traffic adjustments, while also reconciling clicks with your own session and outcome records.

    These controls trade reach for confidence. Treat them as measured containment, not permanent doctrine. Annotate the change, preserve a comparable baseline, and evaluate qualified leads, orders, revenue, or another real outcome. Click-through rate alone cannot tell you whether the traffic became more valuable.

    Give this system an owner and a cadence appropriate to your spend and sales cycle. Alert immediately when a production upload fails. Review freshness, audience-count behavior, reporting exceptions, and suspicious placements on a schedule. Require a change record for consequential bids, budgets, audience logic, exclusions, and network settings.

    Start by mapping your data layers on one page. Assign an owner to each layer, record its last-known-good evidence, and specify which campaign decisions must stop when it fails. Then validate the Customer Match path directly. The next anomaly will arrive as a bounded operational incident, not an invitation to guess with your budget.

    References

  • How to Build an AI-Assisted SEO Workflow You Can Trust

    How to Build an AI-Assisted SEO Workflow You Can Trust

    You have the data. The problem is getting Google Search Console, GA4, Google Ads, and AI visibility signals into the same decision before the opportunity goes stale. Copying numbers between tabs is slow, and asking an AI assistant to interpret an unstructured pile of exports is fast but difficult to trust.

    A useful AI-assisted SEO workflow fixes both problems. Scripts collect a defined set of data, the AI analyzes local files under explicit rules, and you approve every consequential action. The goal is not automated SEO judgment. It is faster, traceable analysis that gives your judgment better inputs.

    Start with the decision, not the AI tool

    The most common design mistake is automating a report before deciding what the report should change. That produces a polished summary, not a workflow. Begin with one recurring question that currently takes too long to answer.

    A strong first use case is paid-organic overlap: which paid search terms consume budget even though related organic queries already perform well? This question becomes much easier when an assistant can examine Google Ads search terms alongside Search Console query and page data. It also exposes an important boundary: organic visibility alone does not prove that paid coverage is unnecessary.

    Define the decision before you build anything. For paid-organic overlap, the decision might be whether a term should remain unchanged, receive a controlled bid test, or be investigated further. The AI should identify candidates and show its evidence. It should not label spend as waste or change a campaign on its own.

    Write a small analysis contract for the question:

    • Decision: Identify search terms that may justify a paid-coverage test because corresponding organic queries and landing pages are already strong.
    • Time window: Use one explicit date range across every compatible dataset. If a file covers a different period, flag it instead of silently joining it.
    • Unit of analysis: Keep the search term, organic query, landing page, and campaign visible. Do not collapse everything into a keyword total.
    • Matching rule: Show exact normalized matches first. Put close or semantic matches in a separate group so a human can inspect them.
    • Evidence: Return the relevant metrics, file names, and row references behind every candidate.
    • Allowed outcomes: Use labels such as keep, test, and investigate. Avoid definitive labels such as waste unless your business rules actually establish that conclusion.
    • Exclusions: State which terms or campaigns should not be evaluated automatically, including any branded, defensive, regulated, or strategically protected coverage.

    This contract does more than improve the prompt. It tells you which data must be collected, which joins are legitimate, and where human review belongs. If you cannot describe the decision in these terms, adding another API will not make the workflow useful.

    Build a small, auditable SEO data project

    Four abstract data sources connect to a compact set of organized file folders and a central analysis workspace.

    You do not need a data warehouse to begin. A practical local project can separate configuration, fetchers, platform data, and generated reports. That separation makes failures easier to diagnose and prevents an AI-generated conclusion from being mistaken for raw platform data.

    Project areaWhat belongs thereOperating rule
    ConfigurationClient details and the property or account identifiers needed by each fetcherKeep secrets out of this file; configuration and credentials are different things
    FetchersOne Python script for each platform, such as Search Console, GA4, Google Ads, or AI visibilityEach script should collect data and save it without making strategic recommendations
    DataRaw or normalized JSON files, separated by platform and refreshDo not overwrite the evidence used for a previous decision
    ReportsAnalysis tables, exceptions, recommendations, and review notesEverything here is derived and should be reproducible from the data files

    The collection layer should be deterministic. Given the same credentials, request, and date range, a fetcher should retrieve and store the same type of data. The AI belongs above that layer, where language and reasoning are useful. This distinction prevents a vague instruction from changing both the data collection method and the interpretation at the same time.

    Set up the project in this order:

    1. Create one project directory per client or site. Separate directories reduce the chance of mixing property identifiers, files, or recommendations.
    2. Configure authentication. A Google Cloud service account can support Search Console and GA4 access, while Google Ads requires its own OAuth setup. Grant only the access the workflow needs.
    3. Specify each fetcher in plain language. Name the platform, property, date range, dimensions, metrics, output location, and required error behavior. An AI coding assistant can draft the Python, but you still need to inspect and test it.
    4. Save platform data separately. Search Console query and page performance, GA4 traffic data, Google Ads search terms, and AI citation data should remain distinguishable even when a later analysis combines them.
    5. Add a refresh manifest. Record when each file was created, the period it covers, the account or property it belongs to, and whether collection completed successfully.
    6. Test with a narrow request. Pull a small, known date range first. Compare several returned rows with the platform interface before trusting a larger refresh.

    Keep credentials outside the project data and out of version control. If a credential is exposed, revoke or rotate it rather than assuming deletion from a file has removed the risk. Read-only access is the safer default for an analysis workflow; campaign edits and site changes should remain separate, deliberate operations.

    One agency workflow reports roughly an hour for the foundational setup, about 35 minutes to configure a new client, and about 20 minutes for a monthly refresh. Treat those figures as observations from one implementation, not universal benchmarks. Your first setup will depend on authentication, account complexity, field requirements, and how much validation you build in. The useful promise is repeatability, not a particular stopwatch result.

    Use prompts that produce evidence, not commentary

    Once the files exist, resist the easy prompt: analyze my SEO data. It gives the model too much freedom to decide what matters, how platforms should be joined, and which gaps can be ignored. A production prompt should define the question, permitted files, join logic, output structure, and stopping conditions.

    Separate validation from interpretation

    Run a validation prompt before asking for strategy. Tell the assistant to inventory the files, report their date ranges, identify missing or empty datasets, check whether property identifiers agree with the configuration, and list fields that are unavailable. It should stop if a required input is absent.

    Only then run the decision prompt. This two-pass pattern matters because an articulate model can produce a plausible recommendation from incomplete data. A visible failure is safer than a polished answer built on a missing Ads export or the wrong Search Console property.

    Give the assistant a reusable analysis template

    A practical prompt can follow this structure:

    • Role: Act as an analyst. Do not alter files, accounts, campaigns, or site content.
    • Question: State the single business or SEO decision the analysis must support.
    • Inputs: List the exact directories and files the assistant may use.
    • Checks: Confirm account identifiers, date coverage, required fields, and successful refresh status before analysis.
    • Method: Describe the allowed joins and calculations. Require exact matches to remain separate from inferred or semantic matches.
    • Output: Return a candidate table, an exception table, and a short decision note. Every row should identify its supporting files and metrics.
    • Uncertainty: Mark conclusions as observed, calculated, inferred, or recommended. If the files cannot answer something, say that directly.

    For paid-organic overlap, ask for search terms with spend and conversion context, their matched organic queries, the relevant organic pages, the match type used by the analysis, and the reason each term deserves review. Require unmatched terms and ambiguous mappings in a separate exception table. That exception table often matters more than the recommendation list because it shows where automation is least trustworthy.

    For content analysis, change the unit of analysis from search term to page. Ask the assistant to map Search Console query and page performance to the corresponding GA4 page data, report any path-normalization assumptions, and keep platform metrics under their original names. Do not let it merge differently defined metrics into a synthetic score unless you supplied and approved the formula.

    For AI search visibility, citation data exported from tools such as Scrunch or Semrush can be added as CSV or JSON. Keep that dataset in its own directory and label its collection method. A citation or mention is not automatically equivalent to an organic click, a GA4 session, or a conversion. Use the combined view to investigate relationships, not to pretend the platforms measure the same event.

    Install a review gate before any SEO action

    An analyst inspects abstract evidence tiles at a closed gate before approving workflow actions.

    Traceability is what turns an interesting AI answer into an operational workflow. A recommendation should survive a simple challenge: can another person find the supporting rows, repeat the calculation, and explain why the proposed action follows?

    Use this review gate before changing bids, briefs, internal links, structured data, or published content:

    1. Verify identity and time. Confirm that every dataset belongs to the intended property or account and covers the expected period.
    2. Inspect collection exceptions. Empty files, partial refreshes, changed field names, and authentication failures must be resolved or carried into the analysis as explicit limitations.
    3. Recalculate a sample. Manually reproduce several important joins or calculations from the underlying rows. Include at least one recommendation and one excluded case.
    4. Challenge the matching logic. Exact query matches are not automatically equivalent when intent, geography, device context, landing pages, or brand strategy differ. Semantic matches require even more scrutiny.
    5. Separate fact from judgment. A metric is observed, a ratio may be calculated, a relationship may be inferred, and an action is recommended. The report should not blur those categories.
    6. Check the downside. Reducing paid coverage can affect visibility, testing capacity, or strategically important terms. Editing content or structured data can create indexing or accuracy problems. Use a reversible test when the consequence is uncertain.
    7. Record the decision. Save what was approved, rejected, or deferred, who reviewed it, and which input refresh supported it. The next cycle needs this context.

    Do not ask the model whether its own answer is correct and treat the response as validation. Give it a separate adversarial task: find rows that contradict the recommendation, identify alternative explanations, and list the additional data that would change the conclusion. Then inspect the evidence yourself.

    This is the right mental model: the assistant is a fast analyst working from bounded files, not the owner of SEO strategy. AI can accelerate extraction and cross-platform analysis, but strategic judgment and verification still belong to the human reviewer. Review its work with the same care you would apply to output from a new team member who is capable but unfamiliar with the account.

    Key takeaways for a repeatable operating loop

    • Automate collection before interpretation. Scripts should retrieve and store defined data; the AI should reason over those files without silently changing how they were produced.
    • Start with one decision. A recurring question such as paid-organic overlap gives the workflow a clear input contract, output, and review standard.
    • Preserve the evidence chain. Keep raw platform data separate from derived reports, timestamp each refresh, and require file and row references for recommendations.
    • Make uncertainty visible. Exact matches, semantic matches, missing data, assumptions, observations, and recommendations should never appear as one undifferentiated answer.
    • Keep consequential actions human-approved. Use read-only access for analysis and move campaign or site changes into a separate, reversible approval process.
    • Save decisions, not just reports. The monthly loop should retain what changed, why it changed, and what the next refresh must measure.

    Pick the SEO decision that consumed the most manual reconciliation in your last reporting cycle. Write its analysis contract, connect only the datasets required to answer it, and test the workflow on a narrow date range. Once the evidence survives review, schedule the refresh. Add the next use case only after the first one reliably changes a real decision.

    References

  • WebMCP for Browser-Based AI Agents: A Practical Readiness Guide

    WebMCP for Browser-Based AI Agents: A Practical Readiness Guide

    Your website can be perfectly clear to a person and still force an AI agent to guess. The agent has to locate the right control, infer what each field means, enter values in the expected format, and decide whether a changed screen means the task succeeded.

    If you manage an ecommerce store, booking flow, lead-generation site, or publishing platform, the practical question is not whether every page needs an agent interface. It is which valuable task should get a reliable, machine-readable contract first. WebMCP gives you a way to start answering that question.

    WebMCP changes the interface from controls to callable tools

    Web Model Context Protocol, or WebMCP, is an emerging approach for exposing website actions to browser-based AI agents. Instead of making an agent reconstruct a workflow from buttons and fields, a page can present discoverable tools through JavaScript APIs or annotated HTML forms. Those tools can define their inputs and outputs with JSON schemas and change their availability as the page state changes. That is the central idea behind the early WebMCP preview in Chrome 146.

    Think of the difference as intent versus appearance. A person can look at a blue button labeled Search Flights and understand what to do. An agent works more reliably when it can discover a searchFlights or bookFlight action, inspect the required date, origin, destination, and passenger parameters, call the tool, and receive a structured result.

    Interaction routeWhat the agent must doMain limitation
    UI automationInspect the rendered page, identify controls, enter values, and interpret visual changesText, layout, and component changes can break the agent’s assumptions
    Conventional APICall an endpoint using a separately documented contractAn API may not exist, may not be available to the agent, or may not reflect the current page context
    WebMCPDiscover tools exposed by the current page, supply schema-defined inputs, and consume a structured resultThe Chrome implementation described so far is an early preview, not a mature cross-browser deployment guarantee

    WebMCP does not make your human interface unnecessary. People still need an understandable, accessible flow, and agents may still fall back to that flow when no compatible tool is available. It also does not remove the need for an API when partners, mobile applications, or backend systems require one.

    For SEO, AEO, and GEO teams, the most important distinction is between discovery, understanding, and action. Search-friendly content helps a system find the page. Structured content and JSON-LD help clarify what the page, entity, product, or offer represents. WebMCP addresses what an agent can do once it reaches the relevant browser context. A tool declaration does not make a brand rank, earn a citation, or become the agent’s preferred choice. Treat it as actionability infrastructure, not as an assumed ranking factor.

    Choose one bounded task before exposing an entire journey

    A site-wide WebMCP project is usually the wrong starting unit. Begin with one task whose successful outcome is easy to recognize. Product search, inventory checking, quote requests, registration, and booking are stronger candidates than a vague action such as helpMe or handleMyAccount.

    Use this filter when selecting the first task:

    • The user outcome can be stated in one sentence. Check whether a particular item is available is clearer than assist with shopping.
    • The required inputs can be named and validated. A quote request might require a product, quantity, contact method, and organization identity rather than an unrestricted message.
    • The result can be returned as data. Availability status, a quote-request identifier, or a list of matching products is easier for an agent to use than a visual success banner.
    • The preconditions are knowable. You can state whether the action requires authentication, a non-empty cart, a selected product, or a particular page state.
    • The side effect is limited or confirmable. Read-only inventory lookup is a safer first implementation than charging a card, issuing a ticket, or publishing content.
    • A human fallback exists. If the tool cannot complete the task, the user should be able to continue in the normal interface without reconstructing the entire journey.

    Write a plain-language planning card before writing code. For a B2B quote flow, it could contain the tool name requestQuote, the exact business outcome, required and optional inputs, the returned request status, the conditions under which the tool is available, the permissions it needs, and the point at which the user must confirm submission. This exposes ambiguity while it is still cheap to correct.

    Map one existing human journey against that card. If the page asks for information that is absent from the proposed input schema, either add it to the contract or establish that the server can derive it safely. If the proposed tool requests data that the human journey does not need, challenge the requirement. An agent-facing path should not become an excuse to collect more information.

    Design a tool contract an agent can call without guessing

    An isometric tool module receives structured inputs, validates them, and produces one confirmed output while unrelated interface elements remain disconnected.

    A tool is only as reliable as the decisions its contract removes. Discovery tells the agent that an action exists. The schema tells it how to call the action. The structured result tells it what happened. State determines whether calling it now makes sense.

    Make discovery names describe outcomes

    Name the task after the result, not the page element. searchProducts, checkInventory, requestQuote, and bookFlight communicate intent. clickPrimaryButton, submitForm, and runAction merely expose implementation details. A redesign can replace a button or form while the user outcome stays the same.

    The description should also establish scope. If checkInventory covers one location and one product variant, say so. If searchProducts returns candidates but does not reserve stock, make that boundary explicit. Two tools with overlapping names and unclear scopes force the agent back into interpretation.

    Use schemas to eliminate format decisions

    The WebMCP model uses JSON schemas to define expected inputs and outputs. Use that structure to settle details that a visual form often leaves implicit:

    • Identify which fields are required and which are optional.
    • Use precise data types rather than asking the agent to encode everything as free text.
    • Define accepted formats for dates, locations, identifiers, quantities, and other constrained values.
    • Use enumerated choices when the system accepts a closed set of options.
    • Make defaults explicit. Do not rely on a checked box, placeholder, or hidden field that only exists in the rendered interface.
    • Describe outputs well enough for the agent to determine whether the goal was completed, partially completed, or rejected.

    A flight action illustrates the problem. Date, origin, destination, and passenger count are obvious inputs, but an agent should not have to infer whether an ambiguous numeric date uses month-first or day-first order. It should not have to guess whether the location field expects a city, airport, or internal identifier. The schema should make those choices visible before the call.

    Separate exploration from commitment when the consequences differ. Searching for flights and purchasing one are not the same action. Searching can return options. Booking can reference a selected option, display the final itinerary and price, obtain confirmation, and then commit. A single broad tool that silently crosses both stages is difficult to control and difficult to audit.

    Expose tools only when the current state supports them

    WebMCP’s state-aware model lets tool availability change with context. Use that capability deliberately. Checkout should not appear when the cart is empty. Publish should not appear when there is no valid draft or the current user lacks the required permission. A booking action should not appear before an option has been selected.

    This is more than interface tidiness. Every unavailable action shown to an agent creates another path it can choose incorrectly. Prefer a small set of valid actions for the current state over a large catalog that returns preventable errors. Keep server-side validation in place even when discovery is state-aware; page state can change between discovery and execution.

    Put permissions, confirmation, and failure handling in the design

    A geometric AI agent's task passes through a permission gate and human confirmation checkpoint before reaching success or recoverable failure paths.

    Agent-callable does not mean agent-authorized. WebMCP can describe an interaction, but the website still owns authentication, authorization, validation, and the consequences of the action. Do not treat tool metadata as a substitute for those controls.

    Classify each tool by effect before deciding how it can run:

    • Read-only actions retrieve information without changing user or business data. Product search and inventory checks are useful first candidates.
    • Reversible or draft actions prepare work without finalizing it. Filling a quote draft or assembling a checkout summary can reduce effort while keeping the user in control.
    • Consequential actions create cost, external communication, publication, reservations, or another durable change. Purchasing a ticket, submitting an order, or publishing content should require an explicit confirmation step that presents the material terms before execution.

    For a consequential action, confirmation should describe what will happen, not merely ask the user to continue. Show the item or service, selected options, final amount when money is involved, destination or recipient, and whether the action can be reversed. If any material value changes after confirmation, stop and obtain a new confirmation. The downside of getting this wrong is a real charge, booking, message, or publication that the user did not approve.

    Design structured failures as carefully as successful results. At minimum, the calling agent needs to know which field or precondition failed, whether retrying is safe, whether the current state has changed, and what valid next step is available. Invalid input, expired state, missing permission, unavailable inventory, and an internal failure should not collapse into one generic message.

    Repeated calls deserve special attention. A timeout can leave the agent unsure whether a write succeeded. If retrying could create a second order, booking, quote request, or publication, make duplicate prevention part of the underlying transaction design. Return enough structured status for the agent to reconcile the original attempt instead of blindly submitting again.

    Keep an audit trail that helps you investigate outcomes without recording unnecessary sensitive values. Useful events include the tool discovered, tool invoked, authorization result, validation result, confirmation state, completion status, and fallback route. Your analytics should distinguish an agent that could not find the right tool from one that found it but supplied invalid inputs.

    Test Chrome’s preview as a learning environment

    The Chrome 146 implementation was presented as an early testing preview behind a feature flag. For that preview, the documented setup required Chrome version 146.0.7672.0 or later and the WebMCP testing flag. That makes it useful for prototyping, but it does not justify assuming stable syntax, broad browser support, or production compatibility.

    To recreate that preview environment:

    1. Use the Chrome version specified for the preview: 146.0.7672.0 or later.
    2. Open chrome://flags/#enable-webmcp-testing.
    3. Set WebMCP for testing to Enabled.
    4. Relaunch Chrome.
    5. Use the optional Model Context Tool Inspector Extension to inspect which tools the page exposes and how their contracts appear.

    Do not stop when the inspector can see a tool. Run a small test matrix against the outcome:

    • Discovery: Can the agent identify the correct tool from its name, description, and current state?
    • Valid execution: Does a complete, schema-valid request produce the expected structured result?
    • Invalid input: Does each missing, malformed, or unsupported value produce a useful field-level response?
    • State transition: Do tools appear and disappear when the cart, selection, login state, or draft state changes?
    • Permission boundary: Can an unauthorized user discover or execute an action that should be restricted?
    • Confirmation: Does a consequential action stop before commitment and present the right details?
    • Replay: Can a retry accidentally create a duplicate side effect?
    • UI change: Does the tool continue to work when labels or layout change but the underlying business task remains the same?
    • Fallback: Can the user continue through the normal interface when the agent-facing action fails?

    Record pass or fail by stage rather than using one overall completion number. Separate discovery failures, schema-validation failures, permission denials, user-declined confirmations, server errors, duplicate-prevention events, successful completions, and human fallbacks. That breakdown tells you whether to rewrite the tool description, change the schema, fix state exposure, or repair the underlying transaction.

    Key takeaways

    • WebMCP gives a browser-based agent an explicit tool contract instead of requiring it to infer every action from the visible interface.
    • Start with one bounded, measurable task whose inputs, result, state, and side effects can be described clearly.
    • Use action-oriented names, strict schemas, structured results, and state-aware availability to remove guesswork.
    • Keep authentication and server-side validation in place, and require meaningful confirmation before payments, bookings, publication, or other consequential actions.
    • Treat the Chrome 146 implementation as a testing preview, not proof of stable or universal browser support.
    • Keep investing in content, technical SEO, and structured data. WebMCP adds actionability; it does not guarantee discovery, citation, selection, or ranking.

    Your next move is small: choose one read-only or low-risk task, write its tool contract on a single page, and test discovery, valid input, invalid input, state change, and fallback in the preview environment. Even if the emerging interface changes, the work of defining the task, permissions, schemas, side effects, and success criteria will remain useful.

    References

  • Google v. SerpApi: What the Scraping Fight Means for SEO

    Google v. SerpApi: What the Scraping Fight Means for SEO

    If your rank tracker, competitive dashboard, or AI-search monitoring workflow depends on a SERP API, the Google-SerpApi dispute is not remote legal theater. It is a data-supply-chain issue: an upstream collection method could affect the coverage, cadence, cost, and reliability of the measurements you use.

    That does not mean your tools are about to stop working. SerpApi has asked a court to dismiss Google’s claims, and the competing positions have not been resolved. Your practical job is to identify where scraped Google data enters your operation, separate collection failures from real search changes, and prepare a fallback before either problem reaches a client report or automated decision.

    Key takeaways

    • A motion to dismiss is not a ruling that SerpApi acted lawfully, and allowing Google’s claims to proceed would not prove that Google is right.
    • The central dispute is whether the DMCA can apply when a service accesses public, no-login search pages while overcoming Google’s anti-bot controls.
    • A court ruling could influence the risk, availability, and economics of third-party SERP collection, but it will not answer every legal question about scraping.
    • SEO and GEO teams should treat this as a vendor-dependency issue now: document data lineage, preserve methodology metadata, define validation checks, and build replacement paths for critical reports.

    The dispute turns on access, protection, and reuse

    The fact that a search result is visible in a browser does not settle the case. Google alleges that SerpApi evaded bot-detection and crawling controls through rotating bot identities and large networks, then collected and resold material from Search features that included licensed images and real-time data. Those are allegations, not judicial findings.

    SerpApi answers that it collects the same public-facing information a person can see without authentication. It says it does not decrypt a protected system or breach a login barrier. It also argues that Google does not own much of the underlying material displayed in its results and is trying to use the Digital Millennium Copyright Act to protect its platform and advertising interests rather than copyrighted works.

    That creates three questions that are easy to collapse into one:

    • Who owns the material? Google may display text, images, and facts originating elsewhere, but the ownership analysis can differ by element and license.
    • What do the technical controls protect? Google’s theory connects its anti-bot systems to protected Search content. SerpApi’s theory is that controls serving platform or advertising interests do not become copyright-protection measures merely because they obstruct automated access.
    • What is being done with the collected data? Viewing a public page, collecting it automatically, operating at scale, and reselling the resulting dataset are different activities. A conclusion about one does not automatically resolve the others.

    SerpApi invokes hiQ v. LinkedIn and Impression Products v. Lexmark to support its position that technical barriers should not let a platform monopolize public-facing information. Those precedents are part of SerpApi’s argument; they do not predetermine how the court will characterize Google’s systems, the material displayed in Search, or SerpApi’s conduct.

    The procedural posture matters just as much. A motion to dismiss generally tests whether pleaded legal claims can go forward. It is not a full trial of disputed facts. If the motion succeeds, you must still read which claims were dismissed and on what grounds. If it fails, Google has cleared a procedural threshold, not won the lawsuit.

    Do not mistake the widely repeated $7.06 trillion figure for a judgment, settlement demand, or likely damages award. It is SerpApi’s theoretical calculation of potential penalties under Google’s interpretation of the DMCA. It illustrates how expansive SerpApi believes that interpretation could become; it does not predict the financial outcome.

    Each possible outcome has narrower meaning than the headline

    The unhelpful way to read this dispute is as a referendum on whether public data is always free to scrape. The useful way is to ask what a particular ruling establishes, which legal claim it addresses, and which operational assumptions it puts under pressure.

    • If the motion is granted: the challenged claims may be legally insufficient in their pleaded form. That would support SerpApi’s defense, but it would not create a universal license to scrape any public website for any purpose.
    • If the motion is denied: Google’s claims may proceed into later stages. That would not be a finding that every allegation is true or that all automated collection from public pages violates the DMCA.
    • If Google ultimately prevails on its anti-circumvention theory: providers using similar collection methods could face greater legal and technical pressure. Customers might experience narrower feature coverage, higher costs, slower collection, provider consolidation, or abrupt service changes.
    • If SerpApi ultimately prevails: the result could strengthen the position that access to public, no-login search results cannot be restricted through the DMCA theory Google advances here. Separate questions involving contracts, content rights, licenses, misrepresentation, or other causes of action would still depend on their own facts and law.

    The pressure also extends beyond one search platform. Reddit filed claims against SerpApi and others in October 2022, alleging indirect collection through Google Search, concealed identities, and industrial-scale activity. That broader conflict is a warning for data buyers: a provider can face objections from the platform being queried, the owners of material appearing in results, or both.

    For planning purposes, classify the case as unresolved upstream risk. Do not describe scraping as definitively lawful because the pages are public. Do not tell stakeholders that all third-party SERP APIs are unlawful because Google filed a complaint. Neither statement follows from the current procedural stage.

    Your measurement can fail before the legal question is settled

    A partially blocked digital pipeline turns a stream of search-result tiles into incomplete analytics displays.

    SEO teams rarely consume scraping infrastructure directly. They see a rank, a feature flag, a competitor count, a screenshot, or an AI-visibility score. That abstraction is convenient until the collection layer changes and the dashboard continues presenting its output as if the underlying observation were stable.

    Four failure modes deserve explicit checks:

    • Coverage loss: a provider may stop returning a result type, location, device class, language, or page depth. A missing observation can then be misreported as a lost ranking or absent feature.
    • Sampling drift: stronger blocking can change which successful requests survive. Your trend line may compare two different samples even though the dashboard label has not changed.
    • Latency: retries and collection friction can make a supposedly current result older than expected. This matters when you are investigating a launch, algorithm change, reputation event, or volatile query.
    • Provider continuity: legal expense, infrastructure changes, or tighter access controls can alter pricing and service levels even before a final ruling.

    The operational rule is simple: separate a market signal from a collector signal. A sudden loss of rankings across one geography may reflect Google Search, but it may also reflect an endpoint, parser, proxy pool, localization setting, or feature-classification change.

    Preserve enough metadata to test that distinction. For every observation that can trigger a decision, retain the provider, collection time, requested location, language, device, result type, and methodology version where your agreement permits it. Store raw response evidence or a rendered capture when you are contractually and legally allowed to retain it. Treat an empty response as unknown until the system can distinguish a genuine absence from a failed collection.

    For an owned website, Google Search Console can corroborate changes in impressions, clicks, and average position, but it cannot reproduce a live competitive SERP or explain every feature-level observation. A second data vendor may help, although two vendors can share similar collection dependencies. Manual checks on a small, predefined diagnostic query set provide another useful signal, provided they use consistent location, language, device, and personalization conditions.

    The same discipline applies to AEO and GEO reporting. If a system derives an AI-search visibility score from Google result features, a missing mention may mean that the brand disappeared, that the feature was not collected, or that the parser stopped recognizing it. Keep the captured answer or result evidence separate from the calculated score. Never let a score of zero stand in for missing evidence.

    When a major shift appears, ask three questions before changing content: Did the search experience change? Did the acquisition method change? Did the interpretation layer change? If you cannot answer all three, annotate the report and withhold automated recommendations until you have corroboration.

    Audit your SERP-data dependency in six steps

    An analyst's hands inspect six symbolic stations surrounding a central search-data analytics console.
    1. Build a dependency register. List every rank tracker, SERP API, competitive-intelligence platform, AI-visibility product, internal script, and agency feed that observes Google results. Record the provider, endpoint, markets, device profiles, collection cadence, retention period, and downstream reports or automations.
    2. Mark decisions, not just systems. Identify what happens when each field changes. A number viewed by an analyst is lower risk than a field that changes bids, rewrites briefs, triggers client alerts, evaluates staff, or publishes customer-facing claims. Give the highest scrutiny to inputs that cause action without human review.
    3. Ask vendors method-specific questions. Find out which outputs depend on automated access to public Google pages; which use official or licensed interfaces; how the vendor distinguishes blocked requests from absent results; whether methodology changes are disclosed; what incident notices you receive; and how quickly you can export historical data. Request written answers for critical services.
    4. Design a replacement by use case. Use first-party performance data for owned-site outcomes where it fits. For competitive rankings, define a smaller priority query set that can be checked through another method. For feature monitoring, preserve time-stamped evidence. For AI-search tracking, keep prompt, response, model or interface, location conditions, and scoring logic separable so one unavailable feed does not erase the whole record.
    5. Add a collection circuit breaker. Set the reporting system to flag abrupt changes in response completeness, feature frequency, geography coverage, timestamps, or error rates. When the check fires, label the period as potentially incomplete, pause automated recommendations, and notify the people who consume the affected metric.
    6. Escalate the right legal questions. If your organization directly operates scraping infrastructure, bypasses technical restrictions, resells SERP data, distributes licensed images or real-time content, or makes contractual promises about uninterrupted access, obtain advice from counsel familiar with copyright, the DMCA, data licensing, and relevant contracts. A general blog cannot determine the exposure of a particular implementation.

    Your vendor review should also cover commercial concentration. Switching from one collector to another is not a complete fallback if both depend on materially similar access methods. Ask what can be replaced with first-party data, what can tolerate reduced frequency, what requires independent verification, and what has no realistic substitute. The last category needs an explicit owner and a documented decision about acceptable downtime.

    Do not wait for a final judgment to run the test. Pick one business-critical SEO or AI-visibility report this week. Trace every external field to its acquisition method, mark the fields that cannot be independently verified, and simulate one reporting cycle with the primary feed unavailable. You will learn more from that exercise than from trying to predict the court.

    When the next ruling arrives, read the claims and procedural grounds before changing policy. Until then, keep public visibility, technical access, content ownership, and commercial reuse as separate questions. That distinction will make both your legal review and your search measurement substantially more reliable.

    References

  • AI-Powered SEO Automation: A Workflow You Can Trust

    AI-Powered SEO Automation: A Workflow You Can Trust

    Your SEO automation probably works in the demo. The real test begins when an input is missing, an API times out, the same webhook fires twice, or the model returns an answer that looks polished but is wrong.

    If you are deciding whether to adopt an agent platform, connect another model, or vibe-code a custom tool, focus on control rather than novelty. A useful system makes every judgment visible, constrains what the model can change, and gives you a safe path back when a run fails.

    Define the SEO task before choosing the AI tool

    Do not begin with a goal such as automate content or build an SEO agent. Those goals hide several different decisions inside one label. Name a single transformation that can be observed from beginning to end.

    A task contract keeps that transformation precise. Write it before opening a workflow canvas or asking a coding model to generate files:

    • Outcome: State what the workflow must produce in one sentence. For example, turn newly collected search questions into a structured brief for an editor.
    • Trigger: Identify exactly what starts a run: a schedule, webhook, approved spreadsheet row, form submission, or manual command.
    • Inputs: List required fields, their origin, and what fresh means for each one. Preserve the original input rather than keeping only the AI’s interpretation.
    • Allowed transformation: Say whether the model may extract, classify, summarize, recommend, or generate. Do not give it broader authority than the task requires.
    • Output contract: Define required fields, allowed values, destination, and the conditions that make an output invalid.
    • Human gate: Name the person or role that reviews the result and the decision that remains theirs.
    • Failure behavior: Decide whether the workflow should stop, retry, send an alert, or route the item to a review queue. Silence is not an acceptable failure mode.

    Consider a system for finding questions implied by Google AI Overviews. A bounded version can accept a target keyword, collect the available overview, derive the questions it appears to answer, and store those questions. Each stage has a visible input and output. If no overview is detected, the workflow should report that collection failed or that no overview was present. The model should not invent the missing search result.

    Your first automation candidate should be repetitive, rules-based at its edges, and cheap to reverse. Feed monitoring, title-tag drafting, content inventory classification, and brief preparation are usually easier to control than autonomous publishing or a complete technical audit. Starting with a tedious, bounded task also gives the team a concrete benefit without asking it to trust an opaque system with the entire SEO program.

    Avoid making full-length article generation your first project. It combines research, source selection, intent analysis, factual judgment, writing, formatting, internal linking, and publication. When the result disappoints, you will not know which decision failed. Automate one layer at a time so that every error has an address.

    Put a deterministic shell around the language model

    A glowing neural form sits inside a transparent chamber surrounded by mechanical validation stages, safety switches, and a locked output gate.

    An LLM is useful where language is ambiguous. It should not be responsible for work that ordinary code can perform exactly. Let code handle triggers, field checks, deduplication, routing, calculations, templates, and permissions. Give the model the narrow step that requires interpretation.

    A dependable SEO workflow usually has these stages:

    1. Trigger the run. Create a unique run ID immediately so every later event can be tied to one execution.
    2. Acquire the evidence. Fetch the page, feed, API response, crawl export, or approved document. Save an untouched copy with its origin.
    3. Normalize the input. Remove irrelevant markup, standardize fields, reject missing requirements, and flag content that exceeds the workflow’s limits.
    4. Call the model. Ask for one defined transformation using only the evidence supplied for that run.
    5. Validate the response. Parse the output, verify required fields and allowed values, and reject anything that does not match the contract.
    6. Apply business rules. Deduplicate records, map categories, calculate priorities, or enforce publishing restrictions with deterministic logic.
    7. Deliver or queue the result. Send valid output to its destination and route uncertain or invalid output to a person.
    8. Record the final state. Mark the run as completed, rejected, awaiting review, or failed. Include the reason rather than relying on a generic error label.

    This design prevents the model from quietly redefining the process. If a response contains an unknown content type, the validator rejects it. If an editor has not approved a draft, the publishing node never receives it. The guardrail lives in the workflow, not in a hopeful sentence at the end of a prompt.

    Your prompt should function as an interface contract. Include the model’s role, the single task, clearly delimited input, evidence restrictions, required output fields, criteria for abstaining, and a final self-check. Keep durable rules in the system instruction and run-specific data in the user input. If the model must return structured data, validate the parsed structure after the call; do not treat a request for valid JSON as proof that valid JSON arrived.

    Separate reasoning from presentation as well. An agent workflow can use one model step for summarization and another for conversion into a delivery format such as HTML. When the presentation rules are fully predictable, replace that second model call with a template. You will reduce variability, cost, and the number of places a run can fail.

    Large context windows do not remove the need for context discipline. Long, mixed-purpose sessions can make relevant instructions harder to retrieve. Divide the project into phases, preserve a concise plan outside the conversation, and refresh the working context between distinct tasks. The same rule applies inside production workflows: pass the minimum evidence required for the current decision rather than an unfiltered archive.

    Treat scraped pages, feeds, comments, and uploaded documents as untrusted data. Delimit them and explicitly state that text inside the data cannot change the workflow’s instructions. The model may still mishandle hostile or confusing input, which is why permissions and output validation must remain outside the model call.

    Choose orchestration, custom code, or a hybrid deliberately

    The best implementation depends on where the complexity lives. A visual agent platform is strong at connecting systems and exposing the route between steps. Custom code is stronger when collection, transformation, or testing needs precise control. Many durable SEO systems use both.

    ApproachBest fitMain advantageMain riskChoose it when
    Workflow platformSchedules, webhooks, API calls, approvals, notifications, and deliveryThe route and run state are visible to operatorsComplex logic can become a hard-to-review canvasMost steps connect existing services and the transformation is modest
    Custom toolSpecialized extraction, crawling, parsing, scoring, testing, or reusable internal productsLogic, dependencies, and tests can be controlled directlyMaintenance can outgrow the original convenienceThe difficult part is the computation rather than the handoff
    Hybrid systemWorkflows that combine connectors with one or more specialized componentsEach layer can use the environment suited to itOwnership and observability can fragment across systemsYou can define a stable interface between orchestration and code

    n8n is one example of an orchestration layer that can receive webhooks, run on a schedule, call external APIs and models, and deliver results to channels such as email or Microsoft Teams. Its deployment choice changes the operating burden. Cloud hosting reduces update and patch management, while self-hosting offers more environmental control and can support community nodes. Self-hosting also makes your team responsible for availability, upgrades, credentials, and recovery. For larger teams, change tracking and version control need deliberate governance rather than an informal collection of edited canvases.

    Use custom code when a key stage cannot be expressed cleanly as a few nodes. A search-feature extractor, for example, may need browser behavior, selector maintenance, response inspection, fallback logic, and test fixtures. Keep that complexity in a component with a clear input and output, then let the orchestration layer trigger it and route the result.

    AI-assisted coding does not remove software design from the job. Separate planning from agent execution. Before the model changes files or runs commands, require a design packet containing the goal, non-goals, input and output contracts, modules, expected files, dependencies, failure modes, and tests. Save that plan where a fresh session can read it.

    During troubleshooting, provide the observed output, expected output, complete error, relevant logs, and the smallest reproducible input. Ask the model to identify the failing stage and explain the evidence before modifying code. A vague request to fix everything invites broad changes and makes it harder to know whether the original defect was actually resolved.

    Make review, tracing, and recovery part of the build

    A reviewer inspects a web-page tile in a control room while an automation line shows a paused gate, an amber fault, a traceable path, and a recovery loop.

    A successful final message is not enough evidence that the workflow is healthy. You need to reconstruct what happened without rerunning the model and hoping for the same response.

    For every execution, record:

    • Run ID, trigger, start time, completion state, and initiating user or system.
    • Input locations, retrieval status, and a reference to the preserved raw evidence.
    • Workflow version, prompt version, model identifier, and relevant generation settings.
    • Each intermediate output, validation result, retry, and branch decision.
    • The final destination, human reviewer, approval state, and any correction made after review.
    • Usage and cost data available from the provider, tied to the run that created it.
    • A specific failure code and plain-language reason when processing stops.

    Trace tooling can make this practical. For example, Weave can retain query inputs, LLM outputs, and traces for later inspection. Whatever tool you use, the requirement is the same: an operator must be able to follow one SEO request across collection, model calls, validation, review, and delivery.

    Test the failure paths, not only the ideal output

    Create a fixed evaluation set before expanding the workflow. Keep the inputs stable so prompt, model, and code changes can be compared against the same cases. Include examples that exercise the boundaries:

    • A normal input with a known acceptable result.
    • A required field that is empty or malformed.
    • A page or feed that returns no usable content.
    • An input that is too large for the stage’s defined limit.
    • A provider timeout, rate limit, or authentication failure.
    • A model response with missing fields, extra prose, or an unsupported label.
    • A duplicate trigger that must not create a duplicate record or publication.
    • Scraped text that attempts to instruct the model or override the task.
    • A destination that is unavailable after the expensive processing has completed.

    Retries need limits and idempotency. If a delivery request times out, the workflow must be able to check whether the destination already accepted it before sending again. Otherwise, a recovery mechanism can create duplicate briefs, messages, tickets, or posts. Set provider budgets and alerts as well; a loop that repeatedly calls a model can turn an ordinary bug into avoidable spend.

    Increase autonomy only after the evidence supports it

    Roll out the same workflow in stages:

    1. Shadow mode: Run the automation without changing the existing process. Compare its proposed output with the result your team already produces.
    2. Recommendation mode: Let the workflow prepare classifications, summaries, briefs, or fixes, but require a person to accept or reject each one.
    3. Approved execution: Allow the system to perform the action only after explicit approval, while preserving the proposed change and the approver’s identity.
    4. Bounded autonomy: Remove the approval step only for cases with stable evaluation results, strict permissions, visible monitoring, and a reversible action.

    Keep external publishing, bulk metadata changes, redirects, deletions, and permission changes behind explicit review until you have a separate rollback plan. A generated recommendation can be discarded. An unreviewed production change can affect traffic, brand accuracy, or site availability before anyone sees the alert.

    Measure usefulness at the point of acceptance, not at the point of generation. Track completed runs, valid structured responses, false empty results, reviewer acceptance, correction categories, cost per accepted output, time to detect failures, and time spent on manual recovery. A faster workflow that creates more editorial correction is not necessarily an improvement.

    Key takeaways and your next move

    • Automate one observable SEO transformation, not an entire discipline or job description.
    • Use deterministic code for rules, permissions, validation, and routing; use the model for the narrow language judgment.
    • Choose a workflow platform for orchestration, custom code for specialized computation, and a hybrid when both kinds of complexity are present.
    • Preserve raw inputs, version prompts and workflows, and trace every branch so a failed run can be reconstructed.
    • Test missing, duplicated, hostile, oversized, and unavailable inputs before increasing volume.
    • Move from shadow mode to bounded autonomy only when evaluation results, permissions, monitoring, and rollback all support it.

    Take one repetitive SEO task due in your next work cycle and write its task contract. Trace one manual run from trigger to delivery, then automate only the collection and first transformation. Once you can explain the last failure from the log, add the next stage. That pace produces a system your team can operate, not merely a demonstration that an LLM can generate output.

    References