Tag: API

  • How to Make Ecommerce Sites Ready for AI Shopping Agents

    How to Make Ecommerce Sites Ready for AI Shopping Agents

    Your product page can be perfectly usable by a person and still be unreliable for an AI shopping agent. A shopper can interpret layout, infer which option is selected, notice a warning, and back out of a mistake. An agent needs explicit facts, unambiguous choices, and a safe path from finding an item to taking an action.

    If you run an ecommerce or transactional site, the question is no longer just whether an AI system can mention your brand. You also need to know whether an agent can identify the right product, resolve its options, understand the commercial constraints, and complete the next permitted step without guessing. You can prepare for that shift now without treating an experimental protocol as a finished standard.

    The agent journey has four separate failure points

    AI-driven shopping discovery changes the job of a product page. It still has to persuade a person, but it increasingly has to help a machine determine whether a particular product satisfies a particular set of constraints.

    That journey has four layers: discovery, decision, action, and confirmation. Traditional search optimization concentrates heavily on the first. An agent-driven experience can fail at any of the other three even when the page ranks, gets cited, or receives a visit.

    Journey stageWhat the agent must establishTypical site-level failureWhat to fix
    DiscoverWhether the page and product match the user’s needImportant facts exist only in images, interface states, or vague promotional copyPut essential product facts in clear HTML and consistent structured data
    DecideWhich exact product and variant satisfy the constraintsSizes, units, compatibility, availability, or variant relationships are ambiguousTie every choice to a stable product or variant identifier and its current commercial facts
    ActWhich operation is allowed and which inputs it requiresThe agent must guess what buttons do or manipulate a changing document structureExpose narrow, named actions with explicit inputs, outputs, and errors
    ConfirmWhat changed, what it will cost, and whether further approval is requiredA side effect occurs without a review step or a clear resultReturn the resolved item, quantity, price, status, and next required decision

    Use those four stages as separate audit columns. If an agent finds the page but selects the wrong size, you have a decision-layer problem. If it selects the correct variant but cannot add it to a cart reliably, you have an action-layer problem. If it can place the same order twice, you have a confirmation and transaction-safety problem. Calling all three problems “AI visibility” hides the work that actually needs to be done.

    Build a reliable product truth layer before adding agent actions
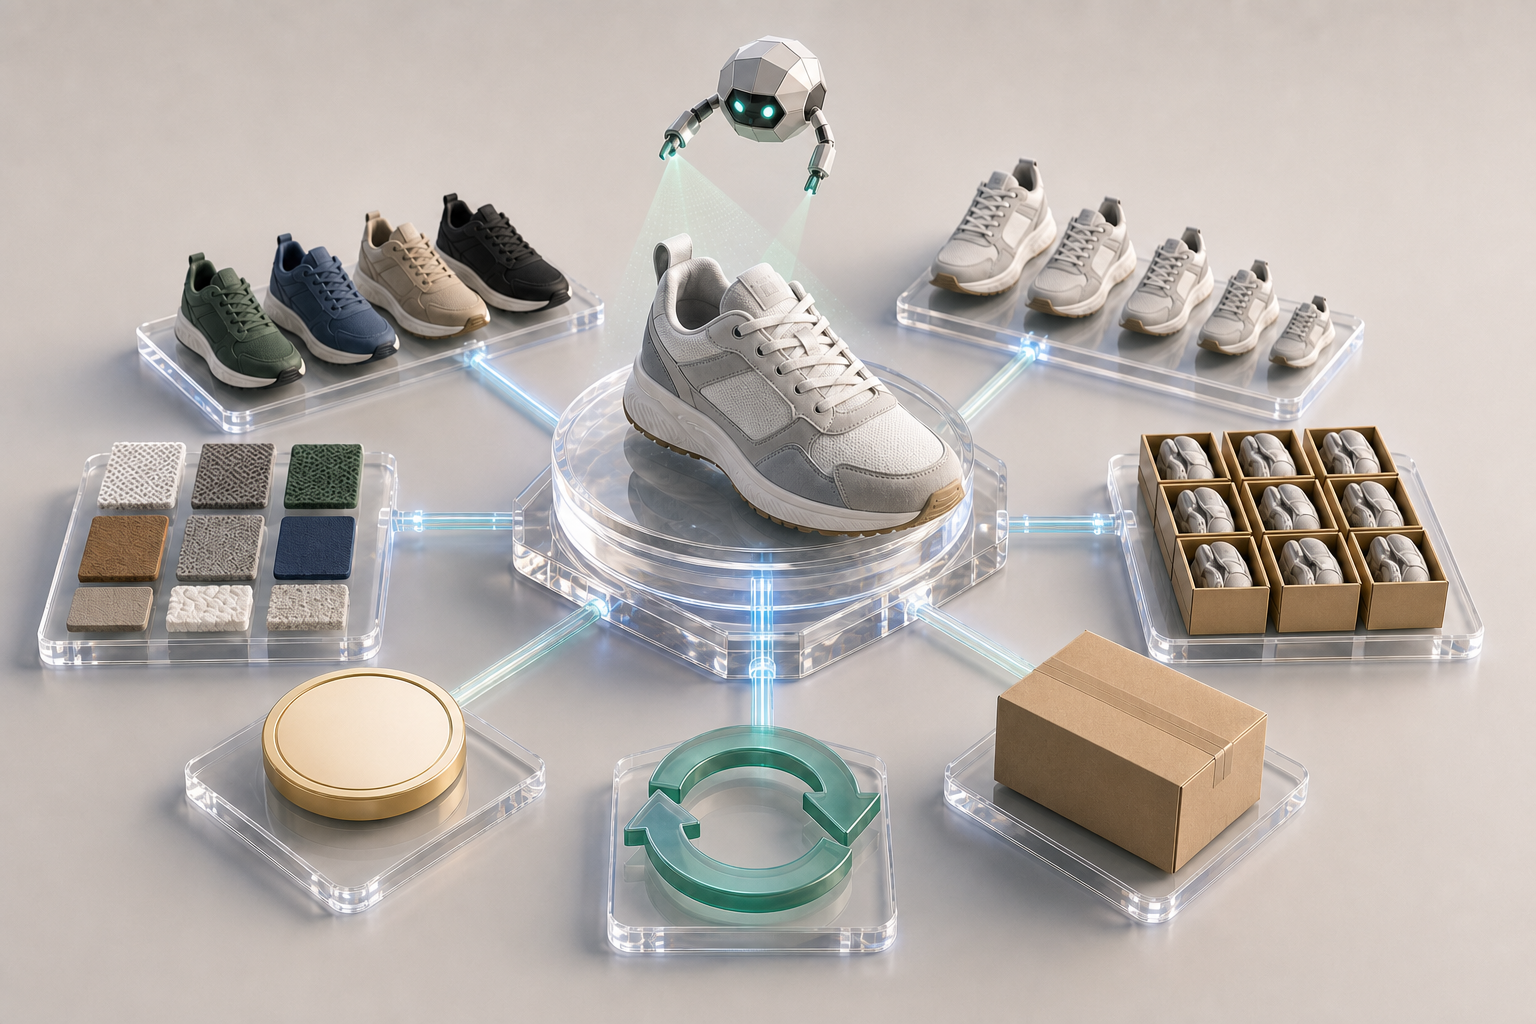
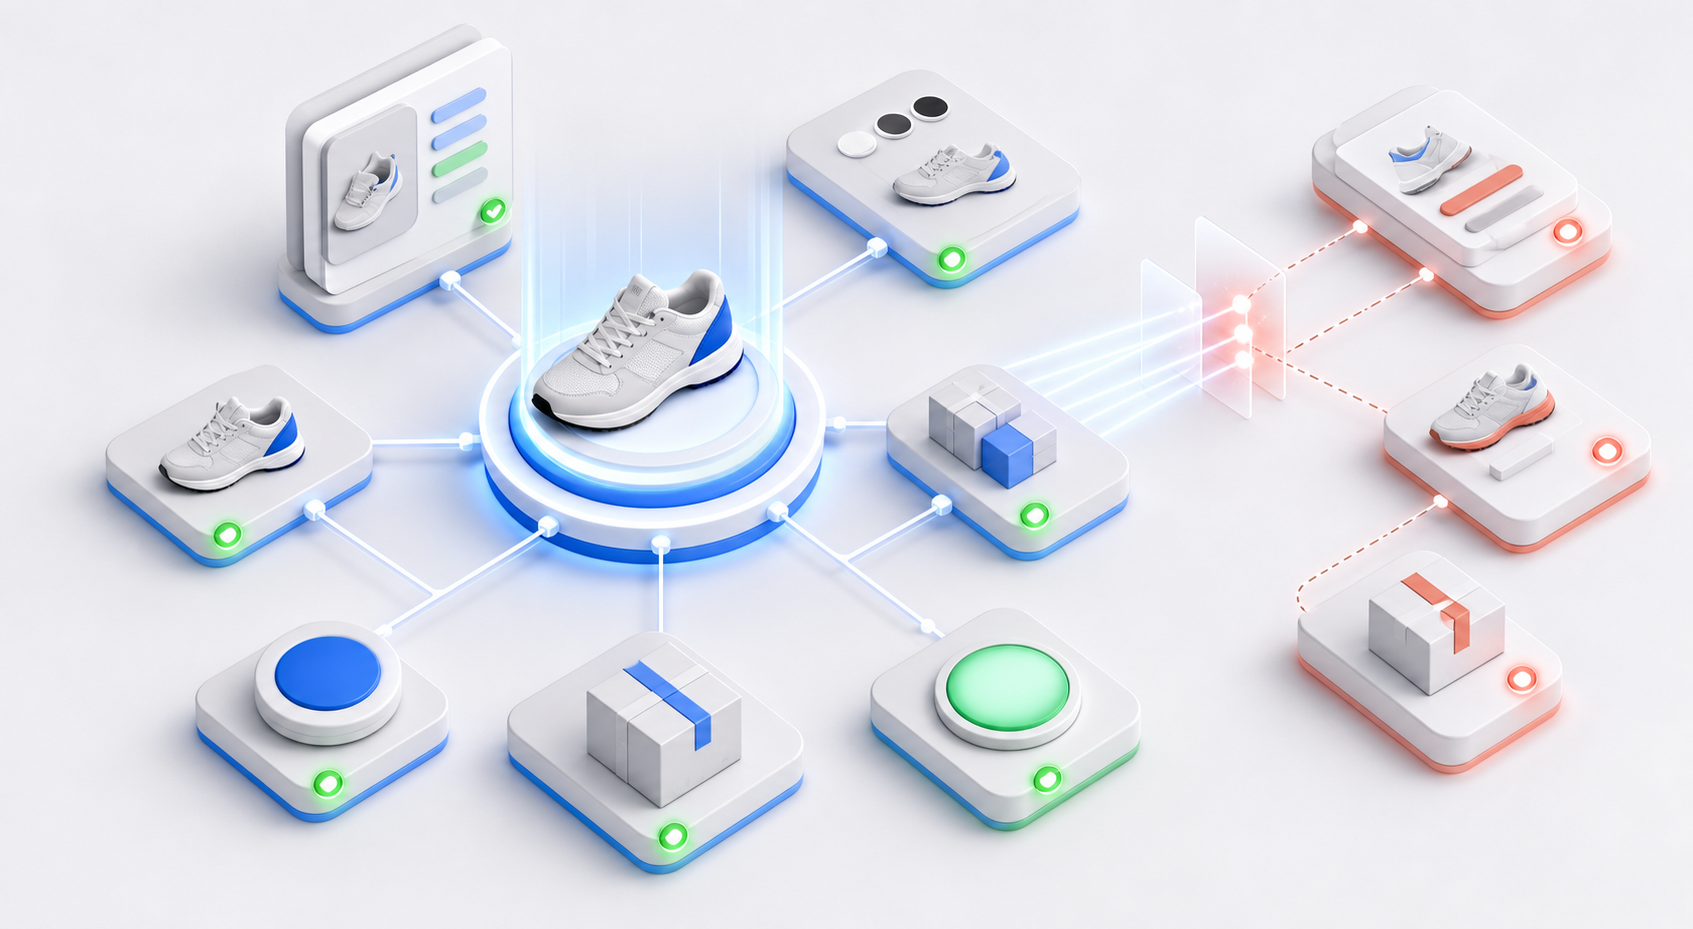
    An unbranded sneaker and its color, size, material, inventory, price, shipping, and return details connect to a transparent structured foundation.

    An action contract cannot repair an unclear catalog. Before you expose callable tools, make sure an agent can resolve one user request to one exact purchasable item. That requires more than a polished product name and a paragraph of sales copy.

    Create a product record an agent can resolve

    • Give the product, offer, and purchasable variant stable identifiers. Do not make an agent rely on a position in a product grid or a temporary interface label.
    • State concrete attributes with their units and scope. “Lightweight” may help a person scan the page; an actual weight and unit let an agent test a constraint.
    • Connect every option combination to the correct availability, price, image, identifier, and purchasing state. A parent product being available does not establish that the requested variant is available.
    • Make compatibility and exclusions explicit. If a part fits only certain models, regions, account types, or configurations, put that boundary next to the applicable item.
    • State fulfilment and return constraints in language that can be applied to a decision. Avoid scattering a decisive restriction across a tooltip, an image, and a generic policy page.
    • Distinguish a one-time purchase, subscription, reservation, quote request, and other commercial models. An agent should not have to infer the commitment from button copy.

    The same facts may appear in rendered HTML, Product and Offer structured data, a catalog feed, an internal API, a form, and an agent tool response. They should resolve to the same item and current state. If JSON-LD presents one price, visible copy presents another, and the cart calculates a third, an agent has no unambiguous value on which to act.

    Keep description and execution separate

    Schema markup and an agent tool contract solve related but different problems. Product structured data can describe an item, its offer, and its availability. It does not, by itself, grant an agent a reliable function for configuring the item or changing a cart. A tool contract describes an operation the site is prepared to accept.

    A useful shorthand is: schema explains what something is; a tool contract explains what can be done with it. You need both layers to agree, but you should not treat one as a substitute for the other. Keep the human-readable page as the visible source of context, terms, and control as well.

    If you can only fix one layer first, fix product truth. A fast agent action that operates on an ambiguous variant is worse than a slower path that asks the user to choose.

    Expose narrow tools instead of making agents operate your interface

    Google’s early WebMCP preview proposes a structured way for websites to expose tools to browser agents. A site can publish a Tool Contract through the navigator.modelContext browser API so an agent receives named functions instead of having to infer the meaning of links and buttons from the document structure.

    That distinction matters. Raw interface operation is fragile because labels, layouts, overlays, and component states change. A named action can state its purpose, required inputs, expected result, and failure conditions directly. The agent still has to reason about the user’s request, but it should not have to reverse-engineer your checkout interface.

    Choose the API style that matches the interaction

    WebMCP describes two approaches. The declarative API is intended for standard actions that can be defined through HTML forms. The imperative API supports more complex or dynamic interactions that require JavaScript execution.

    • Use a declarative action when the operation already maps cleanly to a form with explicit fields, constraints, and submission behavior.
    • Use an imperative action when the workflow depends on changing state, a multi-part configuration, asynchronous validation, or other logic that a normal form cannot express clearly.
    • Keep the ordinary page and form working as a fallback. An experimental agent layer should enhance the purchasing path, not become its only usable route.

    WebMCP is an early preview, so its details may change. Do not rebuild your checkout around it or assume that implementing it creates a search-ranking advantage. Treat the protocol as an experimental delivery mechanism for an interaction model you should design carefully regardless of which standard eventually carries it.

    Write each tool contract like a small public promise

    1. Name the action after the user’s intent. Search products, retrieve a product, select a variant, add an item to a cart, and begin checkout are clearer responsibilities than click button or process page.
    2. Request only the inputs needed for that action. Define allowable values and identify which fields are required instead of accepting an undifferentiated text payload.
    3. Separate read-only operations from operations that change state. Searching a catalog and submitting an order should not share the same permission or confirmation behavior.
    4. Return stable identifiers and the resolved current state. An add-to-cart result should identify the exact variant, quantity, current price, cart state, and any remaining decision.
    5. Return structured failures. Unavailable variant, unsupported destination, authentication required, invalid quantity, and price changed are outcomes an agent can handle; a generic failure message is not.
    6. Make consequential actions explicit. The contract should reveal when an operation reserves inventory, starts a subscription, submits payment, or creates an order.

    An illustrative shopping sequence might expose searchProducts, getProduct, selectVariant, addToCart, and beginCheckout as separate operations. A submitOrder action would sit behind an explicit review and approval step. Those names illustrate separation of responsibility; they are not prescribed WebMCP syntax.

    Resist the urge to publish one general-purpose function that accepts a natural-language instruction and performs an entire purchase. It may look flexible, but it conceals intermediate decisions, makes permissions harder to enforce, and leaves fewer points where the user can inspect or correct the result.

    Design checkout around permission, reversibility, and proof
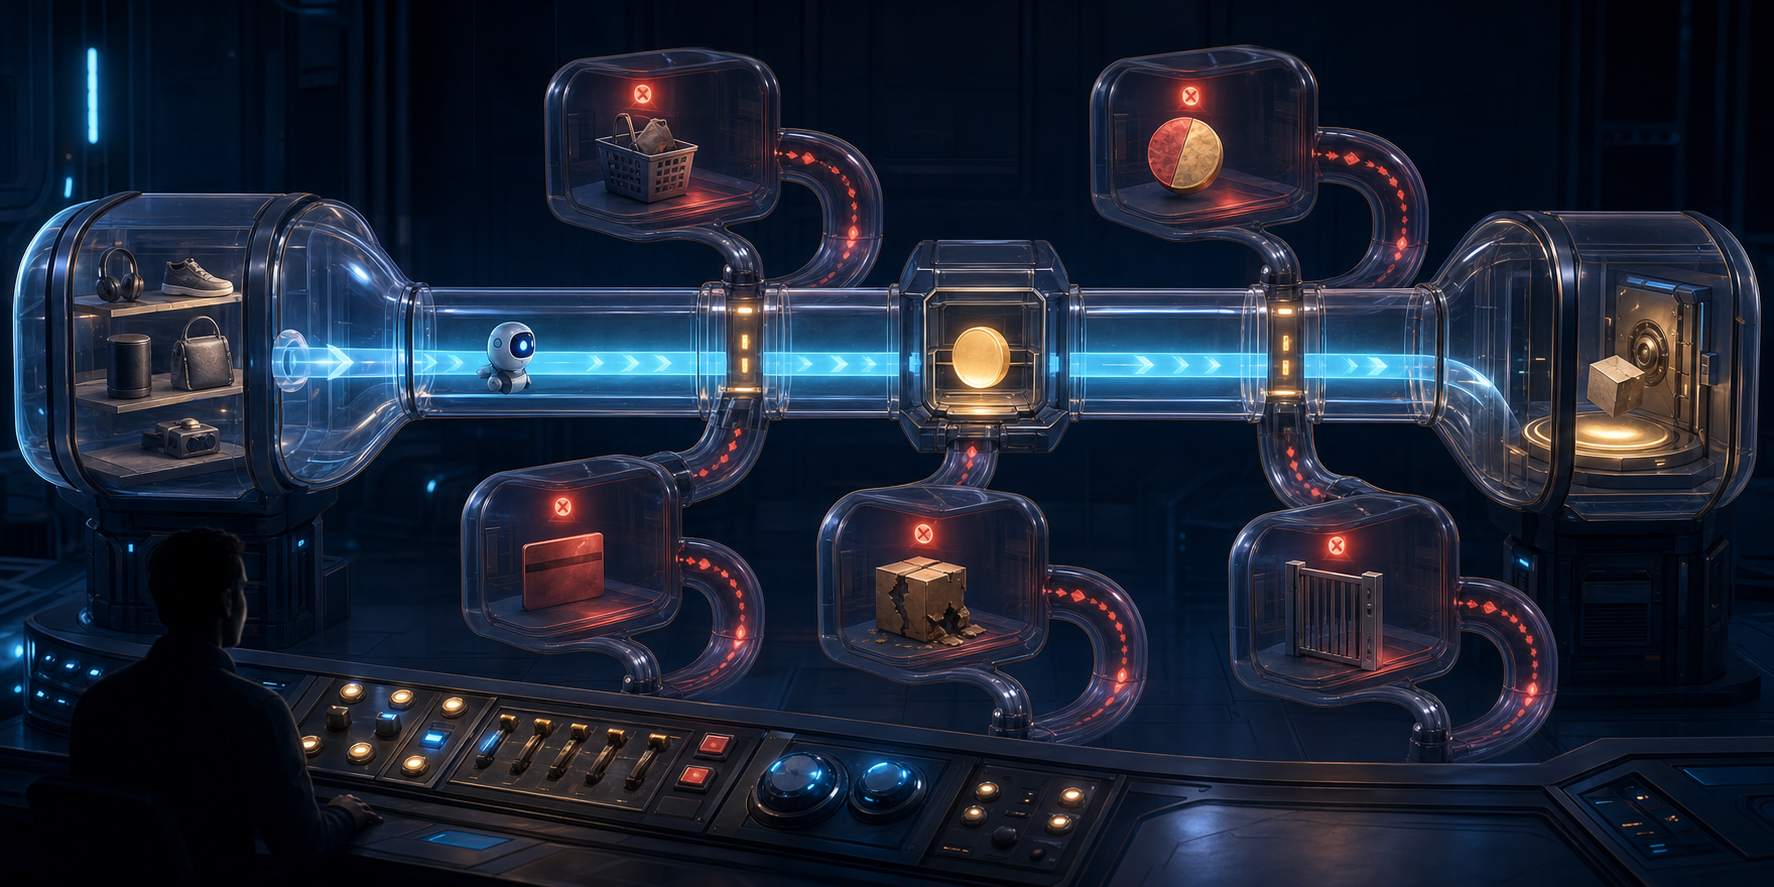
    A geometric shopping agent presents a basket as a human hand authorizes checkout through a shield checkpoint, with a parcel, proof token, and return path beyond it.

    An agent acting on behalf of a shopper can create financial consequences. The site therefore needs a permission model based on what an action changes, not merely on whether the agent knows how to call it.

    Use a simple action-risk ladder

    • Read-only actions: searching, filtering, comparing, and retrieving current details can normally run without transactional confirmation.
    • Reversible state changes: adding an item to a cart, removing it, or changing a quantity can proceed when the result is reported clearly and the user can undo it.
    • Commitment actions: placing an order, accepting changed terms, starting a paid subscription, or making a non-refundable booking should require the user to review the resolved details and confirm the commitment.

    Do not let an agent infer a missing variant, quantity, shipping destination, or commitment period when the choice affects the transaction. Return the missing field as a required decision. A short clarification is safer than a confidently completed wrong order.

    Make repeated requests safe

    Agents, browsers, and networks can retry an operation after an interrupted response. Your transaction design should ensure that repeating the same confirmed request does not silently create duplicate orders or charges. In engineering terms, the consequential operation should be idempotent or protected by an equivalent duplicate-prevention mechanism.

    • Assign the attempted transaction a stable request or confirmation identifier.
    • Return a definite status such as pending, completed, rejected, or requiring confirmation rather than an ambiguous success message.
    • If the price or selected item changes before commitment, return the new state and require confirmation again.
    • If the requested variant becomes unavailable, stop and offer alternatives as new choices. Do not substitute a different variant automatically.
    • Record the action invoked, resolved item, result, confirmation event, and safe request identifier so a failed workflow can be investigated.

    Keep payment credentials, authentication secrets, and unnecessary prompt content out of general agent analytics. Operational visibility is useful, but it does not justify collecting sensitive data that the team does not need for diagnosis.

    Preserve a visible human handoff

    The shopper should be able to inspect what the agent selected, edit it in the ordinary interface, and continue without starting over. Before a commitment, show the exact line items and variants, quantities, current charges, applicable fulfilment details, and the action that confirmation will trigger.

    A handoff is not necessarily an agent failure. It is the correct result when authentication, policy, missing information, or financial approval requires the person. Design it as an intentional state with preserved context, not as an error page.

    Test complete shopping tasks, including safe failures

    Testing whether an agent can call a function is not enough. The real unit of quality is a complete user task: the right item is found, the right option is selected, the allowed action succeeds, and the shopper receives an accurate result. A safe stop also counts as correct behavior when required information or permission is missing.

    1. Start with a constrained search, such as a product that must satisfy a compatibility requirement and a specific option.
    2. Test a parent product whose requested variant is unavailable even though another variant remains purchasable.
    3. Change a price or availability state between selection and checkout, then verify that the agent presents the change instead of continuing on stale information.
    4. Attempt a state-changing action without authentication or a required field and verify that the response identifies the next necessary step.
    5. Repeat the same transactional request and verify that it cannot produce a duplicate commitment.
    6. Move from the agent flow to the visible interface and confirm that the exact cart or configuration survives the handoff.

    Track outcomes by journey stage. Useful measures include product-resolution accuracy, completed-task rate, clarification rate, invalid-action rate, duplicate-attempt handling, safe-stop rate, recovery after a structured error, and successful human handoff. Keep discovery events separate from tool invocations and completed actions. Otherwise, an increase in AI-originated visits can conceal a broken decision or checkout path.

    Review failures by cause, not only by agent or channel. If several agents choose the wrong variant, inspect the catalog relationships and labels before tuning prompts. If they choose correctly but fail at cart mutation, inspect the action contract and transaction state. That diagnosis tells you whether the next fix belongs in content, schema, product data, interface logic, or the agent tool layer.

    Key takeaways

    • Treat agent readiness as four connected capabilities: discovery, decision, action, and confirmation.
    • Fix product identity, variant relationships, commercial facts, and policy constraints before exposing purchase tools.
    • Use structured data to describe products and a narrow tool contract to expose permitted actions.
    • Separate read-only, reversible, and commitment actions so confirmation matches the consequence.
    • Make consequential requests duplicate-safe, return structured errors, and preserve a visible human handoff.
    • Treat WebMCP as an early experimental layer and measure complete task outcomes rather than assuming an SEO benefit.

    Choose one high-value journey this week: product search, variant selection, and add to cart is a sensible starting boundary. Resolve every ambiguity in that path, document its allowed actions and failures, and leave order submission behind an explicit user confirmation. Once that narrow journey works reliably, expand one consequential step at a time.
    References

  • How to Target Google Ads and See Where PMax Performs

    How to Target Google Ads and See Where PMax Performs

    Your Search campaigns can be well built and still leave growth on the table. Keywords meet people after they express intent; they do not automatically reach every suitable buyer who has not started searching. If you answer that gap by handing more work to Performance Max, you inherit a second problem: knowing which Google channel produced the result.

    You can solve both problems without pretending automation is transparent. Define targeting as a two-part decision – where relevant intent appears and who qualifies – then use Google Ads API v23 channel reporting to inspect how Performance Max distributed and converted traffic. That gives you a practical operating loop: targeting hypothesis, channel evidence, focused correction, and cost-per-acquisition review.

    Separate where an ad can appear from who should see it

    A targeting plan becomes much easier to audit when you stop treating every setting as interchangeable. Google Ads targeting falls into two functional groups: content targeting and audience targeting.

    DecisionContent targetingAudience targeting
    Question it answersIn what query or content environment can the ad appear?What kind of person should be eligible to see the ad?
    Main optionsKeywords, topics and placementsGoogle data, your data, custom segments and automated targeting
    Best useCapturing a relevant moment or contextImproving the fit between the person, message and offer
    Common mistakeAssuming a relevant query always identifies the right buyerAssuming a plausible audience is ready for the same offer at the same time

    Keyword targeting reaches people through searches and also extends into dynamic ad groups and Performance Max. Topic targeting places ads alongside content about a selected subject in display and video campaigns. Placement targeting lets you choose particular websites, apps, YouTube channels or videos.

    Audience targeting works on a different axis. Google’s prebuilt options include detailed demographics, affinity segments, in-market segments and life events. Your own data can include website visitors, app users, people who engaged with your Google content and eligible Customer Match data. Custom segments can be based on relevant searches, interests, websites or apps. Automated options can expand from the signals and data you provide, although their names and exact behavior vary by campaign type.

    The distinction matters because a keyword can reveal intent without identifying the buyer. Someone searching for vacation packages could be planning a family trip, honeymoon or retirement holiday. The query is the same, but the useful message, proof and offer can be completely different. Treat the keyword as evidence of a moment, not as a complete persona.

    Build the targeting stack before automation expands it

    An isometric targeting system shows layers for intent, context, audience qualification, and controlled automated expansion.

    Before changing campaign settings, write down the answers to two separate questions: How can Google Ads promote this offer, and how can Google Ads reach this particular audience? If you can answer only the first, you have a distribution plan without an audience strategy. If you can answer only the second, you have a persona without a reliable way to reach it.

    1. Define the action that creates business value. Name the conversion you actually want, the offer attached to it and the page where it happens. This prevents cheap but irrelevant traffic from becoming the campaign’s de facto objective.
    2. Describe audience fit independently of search behavior. State who has the problem, what makes the offer relevant and what language that person would immediately recognize. Do this before selecting a Google segment.
    3. Choose the content signals that reveal a useful moment. Use keywords for expressed search intent, topics for subject context and placements when you know the specific sites, apps, channels or videos where the audience spends attention.
    4. Add the audience data you can legitimately use. Consider Google’s segments, eligible first-party data and custom segments. Treat automated expansion as another layer of reach, not as a substitute for defining the audience yourself.
    5. Make the creative perform a targeting job. Use the buyer’s vocabulary, problem, context and expected outcome. A broad audience paired with precise creative can filter attention more effectively than generic creative placed in a narrowly named segment.
    6. Set the success hierarchy before launch. Put conversions and cost per acquisition ahead of click volume and cost per click. Otherwise, an apparent traffic improvement can move the campaign away from qualified demand.

    For example, lead-generation software intended for Google Ads professionals could use custom segments informed by searches for terms such as Performance Max, visits to relevant industry sites or use of the Google Ads app. Content targeting could add placements on industry education channels and topics around search marketing. The creative should then speak in the terminology of campaign management rather than generic business-software language.

    This is a coordinated stack, not necessarily an instruction to combine every setting as a restrictive intersection. Campaign types interpret signals differently. Your planning document should show what each input contributes: context, identity, prior relationship, expansion or creative qualification.

    When remarketing or custom segments are restricted

    Some sensitive-interest campaigns, including certain legal or healthcare advertising, may not be eligible for custom segments or remarketing. When those options are unavailable, do not treat the restriction as a technical obstacle to work around. Start with an eligible Google data audience that has plausible overlap, then let the creative filter for relevance.

    Industry terminology, recognizable acronyms and specialist visuals can make the intended audience pay attention while other people move on. That approach is especially useful when you can target a broad eligible group but cannot encode the sensitive trait directly. Confirm which options are available in the account and campaign you are actually running before finalizing the plan.

    Use API v23 to turn PMax delivery into channel evidence

    An analyst observes one automated advertising stream separated into visible paths for search, video, shopping, web, and map channels.

    Older Google Ads API versions returned MIXED for the Performance Max ad_network_type segment. API v23 can instead break results out across Search, YouTube, Display, Discover, Gmail, Maps and Search Partners. That changes Performance Max reporting from a single blended row into a view of where delivery occurred.

    The visibility is available at three useful levels:

    • Campaign level: See the overall channel mix and identify which channels deserve a closer look.
    • Asset group level: Determine whether a channel pattern belongs to the whole campaign or is concentrated in one audience-and-creative grouping. This channel breakdown is available through the API, not the Google Ads interface.
    • Individual asset level: Connect channel delivery to particular creative assets instead of judging every asset against one blended campaign result.

    There are three implementation constraints you should record in the reporting specification. Channel-specific data is available only for dates beginning June 1, 2025. A blank result before that date means the breakdown is unavailable, not that the channel delivered nothing. Asset-group channel reporting must come from the API, so a UI-only review will not reproduce the same analysis. Any pipeline that expects the old MIXED value must also be updated to accept and store the distinct channel enums.

    Your export should retain the campaign, asset group and asset identifiers alongside the date, channel, cost, clicks, conversions and whichever business-value metric governs the account. Keep the v22 segments ad_using_video and ad_using_product_data in the analysis where relevant. They let you distinguish video-supported delivery from product-data-supported delivery rather than assuming that every result inside a channel used the same ad format.

    This is reporting visibility, not proof that each channel should receive a manual budget or that the channel caused the conversion by itself. Use the channel enum to locate a pattern. Then use the asset group, asset type, audience hypothesis and conversion outcome to explain what may be producing it.

    Turn channel visibility into a focused optimization decision

    A channel report is useful only when it changes the next decision. Start at campaign level, narrow the pattern to an asset group or asset, and then change the smallest controllable input that could explain it.

    1. Validate the conversion basis. Make sure the report is evaluating the action the campaign is meant to produce. A channel comparison built on the wrong conversion cannot guide useful optimization.
    2. Read conversion rate and cost per acquisition before CPC. High click costs can be acceptable when those clicks convert efficiently. Low click costs are not a win when they buy unqualified visits.
    3. Compare channels at campaign level. Look for meaningful differences in delivery, conversion rate and acquisition cost. Do not label the largest channel good or bad solely because it received the most traffic.
    4. Drill into asset groups. If the pattern appears across every asset group, investigate campaign-wide assumptions such as the offer, audience definition or landing experience. If it appears in one asset group, keep the correction confined to that group.
    5. Inspect the relevant assets and format flags. For YouTube delivery, use the video segment and asset results to inspect whether the video communicates the offer clearly. For Search delivery involving product data, separate that traffic from other Search behavior before deciding what needs to change.
    6. Correct the closest mismatch. If clicks arrive but conversions do not, examine the continuity between targeting, creative promise, offer and landing page. If one asset performs poorly only within one channel, revise that asset before rebuilding the entire campaign.
    7. Recheck a comparable reporting window. Keep the conversion definition and analysis scope consistent so the next result answers whether the focused change improved acquisition quality.

    The metric order has a large financial consequence. In an illustrative comparison, a $10 click with a 10% conversion rate implies a $100 cost per acquisition. A $1 click with a 0.02% conversion rate implies a $5,000 cost per acquisition. The cheaper click is fifty times more expensive at the outcome that matters. This is why low-quality traffic is a more serious problem than a high CPC.

    Channel visibility also limits the blast radius of your changes. If weak YouTube results are concentrated in one asset group and one video, you have a creative diagnosis, not yet a reason to rewrite the entire campaign. If inefficient traffic appears across channels and asset groups, the shared offer, conversion setup or audience premise deserves attention first.

    Key takeaways

    • Ask two targeting questions: where relevant intent appears and which people fit the offer.
    • Use keywords, topics and placements for context; use Google data, your data, custom segments and automation for audience reach.
    • Make creative specific enough to qualify attention, especially when sensitive-interest restrictions limit audience options.
    • Google Ads API v23 reports Performance Max delivery across Search, YouTube, Display, Discover, Gmail, Maps and Search Partners for dates beginning June 1, 2025.
    • Use the API for asset-group channel reporting; that breakdown is not available in the Google Ads interface.
    • Treat channel data as a diagnostic dimension and judge outcomes by conversion quality and cost per acquisition, not cheap clicks alone.

    Start with the Performance Max campaign carrying the most financial consequence. Write its targeting hypothesis in one sentence, then export v23 channel data at campaign, asset-group and asset level. If your reporting cannot preserve those levels, fix the reporting path before changing the campaign. Once the pattern is visible, correct the narrowest mismatch you can support with conversion evidence.

    References

  • Google Ads API v23: A Practical Upgrade Plan for 2026

    Google Ads API v23: A Practical Upgrade Plan for 2026

    Your Google Ads integration may be stable, but that does not make the v23 decision automatic. You need to know whether upgrading will close a real operational gap: opaque Performance Max reporting, difficult invoice reconciliation, date-only scheduling, fragmented store data or an audience workflow that still depends on manual interpretation.

    Google Ads API v23 brings those changes into the same release, while also beginning a faster API release cycle for 2026. The practical response is not to adopt every feature at once. It is to connect each capability to a decision, migrate the safest read paths first and put tighter controls around anything that can change targeting, schedules or spend.

    Choose the upgrade scope from the decisions you need to improve

    Start with the workflow that consumes the data, not the endpoint that exposes it. A feature has upgrade value only when someone can name the decision it will improve, the current workaround it will replace and the failure you need to prevent.

    v23 capabilityDecision or workflow it can improveFirst acceptance test
    Performance Max breakdown by ad network typeExplaining where campaign results are occurringSegmented values reconcile with the unsplit control query for every additive metric you publish
    Campaign-level invoice details, regulatory fees and adjustmentsBilling reconciliation and client cost allocationEvery amount remains traceable to its original charge type instead of being forced into media spend
    Campaign start and end date-timesPrecise launch, promotion and shutdown schedulingA controlled write-read test preserves the intended date, time and governing timezone convention
    PerStoreView location detailsStore-level reporting and local performance analysisThe account and location scope agrees with the corresponding Stores report
    LIFE_EVENT_USER_INTERESTLife-event dimensions in audience insight workflowsThe new dimension survives extraction, storage and review without being collapsed into a generic interest label
    Surface-specific Demand Gen conversion-rate forecastsPlanning separately for placements such as Gmail and ShortsSurface remains part of the forecast key through the planning layer
    Free-text descriptions converted into structured audience attributesDrafting audience definitions from a strategist’s briefThe generated attributes are visible, validated and approved before downstream use
    Additional Shopping competitive and conversion-date metricsCompetitive analysis and conversion reportingEvery metric carries its date basis and aggregation rule into the dashboard

    This map also exposes ownership. Performance Max and Shopping changes usually begin with analytics engineering. Invoice changes require a finance or billing consumer. Date-time scheduling belongs to the team that owns campaign mutations. Audience generation needs both a technical owner and the person accountable for targeting decisions.

    A low-risk migration sequence starts on the read side. Capture representative outputs from your existing integration, upgrade the required client libraries and code in an isolated path, add one v23 capability, and compare its result with your control data. Move write operations only after your storage, validation and monitoring layers understand the new values.

    1. List every query, scheduled job, report, billing export and campaign writer affected by the upgrade.
    2. Record the account scope, selectors, reporting window and downstream consumer for each path.
    3. Capture baseline responses and the totals currently shown to users.
    4. Upgrade the client dependency and generated types without changing business logic in the same step.
    5. Add one v23 capability behind a separately testable query or writer.
    6. Define a reconciliation rule, an owner and a rollback condition before releasing it.
    7. Keep the old output available until the new consumer passes both data and operational checks.

    Rebuild reporting around the new data grain

    An analyst examines an opaque campaign object as it passes through a prism and separates into distinct reporting components.

    The reporting additions are useful because they expose distinctions that were previously difficult to retrieve. They can also break a pipeline that assumes one row per campaign, one meaning for a date or one reporting grain across every metric.

    Performance Max network breakdowns need a new row key

    Google Ads API v23 adds an ad-network-type breakdown for Performance Max reporting. Once that segment enters a result, a campaign can occupy more than one row. Any transformation keyed only by campaign can overwrite rows, duplicate joined values or accidentally recombine the split before an analyst sees it.

    Add the network dimension to the unique key at ingestion. Then run a paired query: one result at the original campaign grain and one with the network split. Reconcile metrics that your reporting contract treats as additive. For ratios and calculated metrics, recompute from their underlying components where your data model supports that; do not sum percentages merely because they arrived in separate rows.

    Label the output narrowly. A network breakdown provides a more useful view of distribution, but it should not be presented as complete Performance Max transparency. That wording matters because analysts will otherwise infer visibility into decisions the field does not actually expose.

    Shopping conversion-date metrics need an explicit time basis

    Expanded Shopping reporting includes new competitive and conversion metrics organized by conversion date. A conversion-date series answers a different question from a series organized around the ad interaction. If your warehouse stores both under an undifferentiated date column, a dashboard can produce a plausible trend with the wrong meaning.

    Give every affected metric a semantic contract. At minimum, record its metric name, date basis, source grain and permitted aggregation behavior. Carry the date basis into the BI model and display label. If you show conversion-date and interaction-date views together, identify them explicitly instead of blending them into one unlabeled total.

    Competitive metrics deserve the same discipline. Do not assume a newly available value can be summed across products, campaigns or dates. Preserve the returned grain first, then implement only the aggregation behavior your reporting definition supports.

    Use PerStoreView as a controlled local-data migration

    PerStoreView exposes store location details aligned with the Stores report. That alignment gives you a practical acceptance test. Select a known account and location scope, retrieve both views, and compare the location set and identifying details before replacing an existing store feed.

    Preserve the identifiers exposed by the API instead of matching stores only by display name. Names can be formatted inconsistently in downstream systems, while a durable identifier gives you a defensible join. Keep store attributes separate from campaign measures as well; duplicating a location attribute across performance rows does not make it an additive metric.

    Your exception report should show missing locations, duplicate mappings and conflicting attributes. Do not hide those cases inside an inner join. A clean-looking dashboard that silently drops an unmatched store is harder to repair than a visible migration exception.

    Keep billing detail and scheduling precision from creating new errors

    Two v23 features move beyond analytical convenience. More detailed invoices affect financial reconciliation, while precise campaign date-times affect when ads can run. Both deserve stronger controls than a new reporting column.

    Model invoice charges by type before calculating totals

    InvoiceService can now return campaign-specific costs, regulatory fees and adjustments. Those amounts may contribute to the same billing reconciliation, but they do not mean the same thing. Putting all of them into an internal field named spend destroys the distinction that makes the new detail valuable.

    Retain the raw response, then normalize each amount into a typed financial record. Your internal model should distinguish campaign cost, regulatory fee and adjustment, preserve the campaign association when supplied, and record the sign convention used by your system. Never change the raw value to make a reconciliation pass.

    • Reconcile typed amounts to the billing total your finance workflow expects.
    • Flag an adjustment whose sign cannot be interpreted confidently instead of silently treating it as a cost.
    • Keep fees visible as fees in client and internal reports.
    • Surface campaign references that cannot be mapped to your internal campaign table.
    • Make repeated ingestion idempotent so rerunning a billing job does not duplicate a charge.

    Release the richer invoice feed beside the existing reconciliation for at least one normal billing run in your own workflow. The purpose is not merely to reach the same final number. Finance should be able to explain which campaign costs, fees and adjustments produced it.

    Treat date-time scheduling as a write-path migration

    Campaigns can use precise start and end date-times rather than date-only boundaries. That is an operational change, not just a more detailed field. A database column, serializer or form built around dates can strip the time and still produce a syntactically valid value with the wrong schedule.

    Trace the value from the user’s input through storage, request construction and the returned campaign state. Confirm the timezone or normalization convention required by the API and your client library rather than guessing. Keep the user’s intended local time available for audit even if your integration also stores a normalized representation.

    • Test a same-day start and end.
    • Test a boundary near midnight.
    • Test a date affected by a daylight-saving transition when the campaign’s market uses one.
    • Test that an end earlier than the start is stopped by your own validation.
    • Read the campaign back after writing and compare the returned schedule with the submitted intent.
    • Verify that legacy date-only jobs do not overwrite the newer time values on their next run.

    Do not move this writer into production while the timezone or end-boundary behavior remains ambiguous. An incorrect boundary can allow spend outside the intended promotion window or stop a campaign while it should still be active. Use a controlled, low-risk campaign for the final lifecycle check and require an explicit rollback path.

    Put human review between AI assistance and campaign changes

    A campaign manager reviews AI-generated adjustment modules before allowing one to pass through an approval gate into an advertising system.

    Google Ads API v23 expands AI-assisted audience and planning workflows in three different ways: a new life-event dimension, free-text audience generation and surface-specific Demand Gen forecasting. They should not be merged into one opaque automation step. Each produces a different kind of planning input and needs a different validation rule.

    Preserve LIFE_EVENT_USER_INTEREST as its own dimension

    The new LIFE_EVENT_USER_INTEREST audience dimension gives Insights workflows a structured way to work with life-event interests. Store the dimension type separately from its returned value. Mapping it immediately into a generic interest bucket removes the distinction before a strategist can use it.

    Add explicit handling for unknown or newly returned values. A resilient integration should retain a value it does not recognize, route it for review and continue processing the rest of the response. Hard-coded mappings that discard an unfamiliar value make API evolution look like missing audience demand.

    Handle generated audience attributes as a proposal

    Generative audience tooling can translate a free-text audience description into structured attributes. That can reduce manual setup, but the structured result is still the consequential output. The input may sound reasonable while the generated attribute set is broader, narrower or simply different from what the strategist intended.

    Make generation a reviewable draft. Store the original description, the complete structured result, the version of your internal mapping logic, the reviewer decision and the eventual change applied downstream. Show the strategist a diff between the current audience definition and the proposed one. Empty attributes, unsupported values and unexpectedly broad additions should block automatic application.

    This audit trail is also how you make the feature debuggable. If campaign behavior later raises a question, you can distinguish the user’s brief, the generated interpretation and the approved configuration instead of treating them as one decision.

    Keep Demand Gen forecasts separated by surface

    Demand Gen conversion-rate forecasts can now vary across surfaces such as Gmail and Shorts. Include surface in the storage key, API-to-warehouse mapping and planning view. Otherwise, one surface can overwrite another or an early average can erase the difference the feature was designed to expose.

    Use each forecast as a planning input, not a guaranteed outcome. Retrieve the forecast without automatically changing budget or targeting, show the surface-level values to the planner, record the decision they support and compare eventual performance using the same surface distinction where your measurement data permits it.

    Key takeaways for your v23 upgrade sequence

    • Adopt v23 by workflow value, not by feature count. Tie every capability to a named decision and consumer.
    • Move read-only reporting first. Baseline, dual-run and reconcile before replacing an existing output.
    • Add the new dimension to your data key. Network, store, surface and date-basis distinctions must survive ingestion.
    • Keep financial meanings separate. Campaign costs, regulatory fees and adjustments should remain typed and traceable.
    • Test scheduling end to end. Database precision, serialization, timezone handling and legacy writers can all alter the intended date-time.
    • Keep AI-generated audience attributes behind validation and human approval.
    • Build reusable migration checks now. A faster 2026 release cadence makes a repeatable test harness more valuable than a one-off v23 patch.

    Your next step is to create one migration ticket for each capability you intend to use. Give it an owner, affected consumer, baseline sample, reconciliation rule, failure alert and rollback condition. Start with the highest-value read-only gap. Move invoice and scheduling changes only when the teams responsible for billing and campaign operations have approved the acceptance tests.

    That approach lets you capture v23’s useful reporting and planning gains without turning the upgrade into an uncontrolled rewrite. It also leaves you with a migration pattern you can reuse as the Google Ads API release pace increases.

    References

  • Google Merchant API Migration: A No-Surprises Checklist

    Google Merchant API Migration: A No-Surprises Checklist

    If your Shopping or Performance Max campaigns rely on an API-fed catalog, the Merchant API migration is a delivery dependency, not routine backend maintenance. Letting a legacy Content API connection reach its cutoff can interrupt campaigns that depend on its product feed.

    The dangerous version of this failure is not always an obvious API error. Products may arrive through the new connection while feed labels, campaign structure, or bidding logic no longer match. Your migration is complete only when the new API writes the right product data and the campaigns consuming that data still behave as intended.

    Confirm whether your account is exposed

    Start in Merchant Center Next. Open Settings > Data sources and inspect the type shown for every product source. Any source marked Content API belongs in your migration inventory. Do not assume that an ecommerce app, scheduled file, or newer integration elsewhere in the account means the legacy connection has already been replaced.

    For each Content API source, record:

    • The Merchant Center account and data source name.
    • The application, connector, platform, or custom code that writes the product data.
    • The person or provider able to change and deploy that integration.
    • How updates are triggered, including scheduled jobs and manual runs.
    • The Shopping and Performance Max campaigns that consume the products.
    • Every feed label associated with the source and what that label controls.
    • The evidence you will require before declaring the migration complete.

    If a third-party platform manages the connection, ask for more than a general confirmation that it supports Merchant API. You need four explicit answers: which connection will be replaced, when the change will reach your account, whether feed labels will be recreated or mapped, and whether you must reconnect anything inside Merchant Center Next. The provider may own the deployment, but you still own campaign validation.

    The transition began in mid-2024, and the communicated migration path cited February 28 for beta participants and August 18 for other Content API users. Those month-and-day references are not safe planning dates without the applicable year and account context. Use the dated notice attached to your own account as the operative cutoff. If nobody can produce that notice, treat the connection as an active risk rather than assuming you have more time.

    Preserve feed labels before moving product data

    Generic retail products with colored geometric tags cross a bridge between two database structures with their tags still attached.

    Feed labels can be part of your campaign architecture. They may separate inventory or support bidding decisions, yet they do not transfer seamlessly during this migration. That creates a misleading success state: the new connection works, products appear, and the technical ticket closes, but a label-dependent campaign no longer addresses the same inventory.

    Build a label map before changing the connection. For each existing label, capture:

    • The exact current value, including spelling and capitalization.
    • A small set of representative products that should carry it.
    • The campaign structure or bidding rule that depends on it.
    • The value expected after migration.
    • The person responsible for checking it in the advertising account.

    Include products from every label and at least one product that intentionally has no label. That last case helps you distinguish a valid blank value from a failed transfer. Compare the same products before and after cutover instead of checking whichever items happen to be easiest to find.

    Do not rename, consolidate, or reorganize labels during the API migration unless the old structure makes the cutover impossible. Combining cleanup with migration destroys your baseline: when inventory changes, you will not know whether the API, the new label design, or the campaign edit caused it. Move the existing behavior first, prove parity, and schedule cleanup as a separate change.

    Run the migration as a controlled cutover

    A useful migration plan separates preparation, technical cutover, and advertising validation. It also names the person who can stop or reverse the change. Use this sequence:

    1. Assign two owners. The technical owner changes the integration. The paid media owner verifies labels, inventory coverage, and campaign behavior.
    2. Freeze unrelated changes. Avoid simultaneous feed restructures, label renaming, and major campaign edits from baseline capture through validation.
    3. Capture the baseline. Save the current data source type, label map, representative products, update process, and dependent campaigns.
    4. Configure the Merchant API connection. Update the system that actually writes product data, then reconnect the data feed where the migration flow requires it. A code deployment alone does not prove that Merchant Center is receiving the new writes.
    5. Preserve rollback material. Keep the previous configuration, mappings, and baseline evidence until validation finishes. Do not allow two uncontrolled connections to write conflicting versions of the same products.
    6. Send a controlled update. If the integration permits it, change a representative product through the real production path. Choose a field whose before-and-after state is easy to verify.
    7. Check every label path. Compare the representative products against the label map and confirm that dependent campaign structures still include the intended inventory.
    8. Observe a scheduled run. A successful manual request does not prove that the recurring job, connector, or automation has been migrated.
    9. Retire the legacy connection only after sign-off. Require approval from both the technical owner and the paid media owner.

    Define rollback triggers before cutover. Missing labels, a test update that never reaches Merchant Center, or a campaign structure that loses its intended inventory are reasons to stop and investigate. A rollback should restore a known configuration, not blindly reactivate every old process.

    Validate business behavior, not just API success

    An operator oversees parallel product-data pipelines as checkpoints verify deliveries to a storefront, campaign engine, and bidding controls.

    An authenticated request proves only that one request was accepted. End-to-end validation has three layers: the connection, the product data, and the campaign consuming that data.

    Connection validation

    • Confirm that Merchant Center Next shows the intended new data-source connection rather than the legacy Content API source.
    • Verify that a deliberately changed product value arrives through the new path.
    • Run or observe the normal scheduled process and confirm that it uses the same path.
    • Record the time, product tested, expected result, actual result, and validator.

    Product and label validation

    • Check the same representative products captured in the baseline.
    • Compare each expected label character for character.
    • Confirm that intentionally unlabeled products remain unlabeled.
    • Test an ordinary product update after the initial migration so you know the connection handles ongoing changes, not only the first import.

    Campaign validation

    • Inspect every Shopping or Performance Max structure that relies on a migrated feed label.
    • Confirm that each label still selects the intended inventory and that no expected subset has become empty.
    • Check that bidding logic tied to those labels still points to the right product group.
    • Have the paid media owner sign off independently of the developer or integration provider.

    Do not use immediate spend or revenue as your only acceptance test. Auction results vary, and business metrics can lag behind a configuration error. Structural checks – the right products, labels, and campaign relationships – reveal migration mistakes sooner. Performance monitoring should follow, but it cannot replace those checks.

    Keep the validation record with the integration documentation. It should show the old and new connection, the label mapping, the test products, the scheduled-run result, the dependent campaigns, and both approvals. That evidence gives you a precise starting point if a later feed or campaign problem appears.

    Key takeaways

    • A data source marked Content API in Merchant Center Next is a migration dependency that needs a named owner.
    • Moving products is not enough. Feed labels require an explicit before-and-after mapping because they may not transfer cleanly.
    • Separate the API cutover from feed cleanup and campaign restructuring so you retain a useful baseline.
    • Validate the new connection, a normal scheduled update, representative products, labels, and every dependent Shopping or Performance Max structure.
    • Use the dated notice for your own account to determine the applicable cutoff rather than relying on an unqualified calendar date.

    Open Merchant Center Next and inspect Data sources now. If Content API appears, assign a technical owner and a paid media validator in the same work item. Close that item only after a scheduled product update reaches the new connection and the label-dependent campaigns still address the inventory you intended.

    References

  • Agentic Commerce Protocols: A Practical Readiness Plan

    Agentic Commerce Protocols: A Practical Readiness Plan

    You may already have product schema, shopping feeds, and commerce APIs, yet still not know whether your store is ready for an AI agent to recommend an item, verify the offer, and help complete a purchase. That uncertainty is the real protocol problem. The question is not simply which acronym to support, but whether your product facts and transaction controls survive a machine-to-machine buying journey.

    The safest approach is to separate protocol compatibility from commerce readiness. Build one reliable commerce core, then connect protocols to it through controlled adapters. That gives you a practical path into Google UCP and OpenAI ACP without duplicating pricing, inventory, checkout, or policy logic for every new interface.

    Choose the commerce job before you choose the protocol

    An agentic commerce protocol is an interoperability contract. It defines how participating systems exchange commerce information or request actions. That contract matters, but it does not replace your catalog, pricing engine, order system, payment flow, or fulfillment operation.

    Start by naming the buyer journey you want an agent to support. “We support agentic commerce” is too vague to test. “An agent can identify the correct variant, verify the current offer, create a cart, and return a checkout handoff” is specific enough to build and audit.

    Commerce jobRequired source of truthFailure to prevent
    Discover and compareCatalog, product identity, variants, attributes, and relationshipsThe agent selects the wrong product or compares unlike variants
    Verify an offerCurrent price, currency, availability, eligibility, and fulfillment conditionsThe agent presents an expired, unavailable, or inapplicable offer
    Create a cart or checkout handoffCart, promotion, customer, and checkout servicesA discount is misapplied, a cart is corrupted, or the buyer loses context
    Complete a bounded actionAuthentication, authorization, payment, and order servicesAn unauthorized or duplicate transaction is created
    Confirm and support an orderOrder status, fulfillment, cancellation, and return systemsThe agent promises an action that the merchant cannot honor

    A protocol may cover all, some, or none of those jobs. Build a requirements matrix from the actual specification and label each capability as supported, externally handled, unsupported, or subject to approval. Do not turn partial support into a blanket compatibility claim.

    This also prevents a common architecture mistake: wiring business rules directly into a protocol integration. Protocol-specific code should translate requests and responses. Your existing commerce services should continue deciding what an item costs, whether it can be sold, which promotion applies, and what happens after the order.

    Make product and offer data internally consistent

    A product is surrounded by synchronized catalog, inventory, price, variant, shipping, and availability objects while mismatched duplicates are corrected.

    An AI agent cannot resolve contradictions by calling them “close enough.” If a product page says an item is available, a feed carries yesterday’s price, and the transaction API rejects the variant, the agent has no trustworthy offer to present. More interfaces amplify that inconsistency rather than repairing it.

    Build a field-level inventory before adding endpoints. For every fact exposed to an agent, record its format, owner, update path, and authoritative system.

    1. Stabilize identity. Give each sellable product and variant a durable internal identifier. Use the same identifier wherever your catalog, feed, structured data, cart, and order systems can carry it.
    2. Separate products from offers. Descriptive attributes such as material or compatibility do not change on the same schedule as price, availability, delivery options, or promotion eligibility. Model them separately so mutable offer data can be refreshed without rebuilding the whole product record.
    3. Represent variants explicitly. Size, color, capacity, pack quantity, and other purchase-defining options should resolve to an exact sellable item. Do not make an agent infer the variant from an image filename or a paragraph of marketing copy.
    4. State conditions alongside claims. A price or delivery promise without its currency, region, eligibility, or other applicable condition is incomplete. Return the condition with the value rather than expecting the agent to recover it elsewhere.
    5. Connect policies to the affected offer. Return, cancellation, warranty, subscription, and fulfillment terms should be retrievable in the context where they apply. A generic policy page is useful to people, but it may not resolve an exception attached to one product or offer.
    6. Define conflict precedence. Decide which system wins when the page, JSON-LD, feed, cache, and transaction service disagree. Mutable facts should normally be revalidated against the system that can actually accept the transaction.

    JSON-LD remains useful, but it serves a different role from a transaction API. Structured data helps machines interpret what a public page describes. It does not reserve inventory, authorize a discount, create an order, or prove that a cached offer is still valid. Keep page content, markup, feeds, and APIs aligned, then revalidate consequential facts when the buyer moves from discovery to action.

    Give each response an unambiguous outcome. If current availability cannot be confirmed, return an unavailable or indeterminate state and a safe next step. Do not substitute an old value, invent a delivery promise, or turn missing data into a confident answer.

    Put explicit controls around every agent action

    A discovery request is mostly informational. Creating a cart changes state. Placing an order, cancelling one, or requesting a refund can affect money and customer rights. Your controls should become stricter as the consequence increases.

    Put a protocol adapter between the external agent interface and your internal commerce services. The adapter should translate fields, enforce the supported capability set, reject malformed requests, and produce protocol-compatible errors. It should not become a second pricing engine or an alternative order-management system.

    • Authenticate the caller. Establish which agent, platform, account, or delegated identity is making the request.
    • Authorize the exact action. Knowing who called is not enough. Check whether that identity may read an offer, create a cart, place an order, cancel an order, or request another state change.
    • Revalidate server-side. Price, availability, promotion eligibility, shipping conditions, and order totals must be checked by the commerce system before commitment. Values repeated by the agent are inputs to verify, not facts to trust.
    • Make retries safe. State-changing requests need a stable operation identifier or equivalent idempotency control. A timeout followed by a retry must not create a second order or duplicate another irreversible action.
    • Bound delegated authority. Limit what the agent can buy, change, cancel, or approve. When the requested action exceeds that authority, require an explicit user decision rather than stretching the scope silently.
    • Preserve an audit trail. Record the caller, requested action, authorization result, validated commercial state, resulting transaction, and error outcome. Keep sensitive information out of prompts and general-purpose traces.
    • Return recoverable errors. Tell the agent whether it should refresh an offer, request a missing selection, ask the buyer for confirmation, hand off to checkout, or stop. Do not expose credentials or sensitive internal details in the explanation.

    Route payment credentials and personal data through your approved payment, identity, consent, and privacy flows. An agent conversation or model trace is not a safe substitute for those systems. If the agent only needs to hand the buyer into checkout, give it a constrained handoff mechanism rather than unnecessary access to the full payment process.

    Confirmation also needs state awareness. If the price, item, quantity, delivery terms, or another material condition changes after the buyer’s instruction, stop and present the changed state before committing. Agreement to one offer is not blanket permission to accept a different one.

    Optimize discovery and transaction readiness separately

    Protocol support is not a ranking switch. An agent still needs to discover your products, understand them, decide whether they fit the request, and obtain a valid path to action. A working checkout endpoint does not compensate for vague product information, just as excellent content cannot complete a transaction when the offer cannot be verified.

    Treat the journey as four connected layers:

    • Discovery: Can the system find a canonical product page or catalog record for the buyer’s need?
    • Understanding: Can it identify the product, variant, attributes, compatibility, constraints, and applicable policies without guessing?
    • Decision support: Does your content answer the questions that distinguish this option from alternatives?
    • Action: Can the agent verify the live offer and move into a controlled cart, checkout, or order flow?

    Your public content should do more than repeat a product name and a promotional claim. State concrete specifications, intended use, compatibility, included components, variant differences, purchase conditions, and limitations where they matter. Use consistent terminology across prose, tables, structured data, feeds, and APIs. If one surface calls an option a “starter pack” while another exposes only an unexplained internal code, automated matching becomes less reliable.

    Keep canonical pages useful to people even when machines consume their data. Clear explanations help a buyer verify the recommendation and give answer engines grounded material to cite or summarize. The protocol should extend that experience into live commerce operations, not turn the website into a thin wrapper around an endpoint.

    Measure these layers independently. If products are rarely selected, investigate discoverability, identity, attributes, and decision content. If products are selected but transactions fail, investigate offer freshness, authorization, validation, handoff, and error recovery. Combining both failures into one “AI traffic” metric hides the part you need to fix.

    Roll out one bounded journey and test the failure paths

    An abstract shopping agent travels through a guarded test corridor while unavailable inventory, price changes, payment failure, delivery problems, and permission blocks are contained on side paths.

    Do not begin by exposing every catalog action to every agent. Choose one journey with a clear owner, a known source of truth, and a reversible handoff where possible. A narrow implementation reveals data and control problems before they spread across the whole store.

    1. Define the journey. Write the starting request, required product decisions, supported actions, handoff point, completion signal, and responsible internal team.
    2. Write the field contract. List required and optional fields, identifiers, formats, authority, freshness expectations, and what happens when a value is absent.
    3. Write the action contract. For every state change, define authentication, authorization, validation, confirmation, retry handling, audit output, and safe failure response.
    4. Validate read-only behavior first. Confirm that product identity, variants, current offers, and policies resolve consistently before allowing the integration to alter carts or orders.
    5. Simulate state changes. Exercise order creation, retries, timeouts, revocation, changing prices, unavailable variants, expired promotions, and partial service failures without risking a real buyer’s money.
    6. Restrict the first live scope. Limit the supported catalog, actions, regions, accounts, or other meaningful dimensions until the operational signals are stable.
    7. Expand by evidence. Add capabilities only when the previous scope has reliable data, safe authorization, understandable errors, and an owner who can respond to exceptions.

    Test cases that expose weak integrations

    • The chosen variant goes out of stock after discovery but before checkout.
    • The price or promotion changes between recommendation and commitment.
    • A request times out after the order service succeeds, then the agent retries it.
    • The buyer omits a purchase-defining option such as size, quantity, or configuration.
    • The caller’s authorization is revoked during the session.
    • An internal service succeeds while the protocol adapter fails to return the response.
    • The requested shipping, cancellation, or return condition is not available for that offer.
    • The agent requests an action outside its delegated scope.

    A pass is not merely “the endpoint returned a response.” The response must preserve the correct commercial state, avoid duplicate effects, explain what the agent can do next, and leave an auditable record.

    Measure the agent funnel, not just agent traffic

    Give every metric a numerator, denominator, and operational owner. Useful measures include exact product-resolution rate, successful offer-verification rate, cart or handoff success, authorized action success, duplicate requests safely suppressed, policy exceptions, and completed orders associated with an agent-assisted journey. Track stale-data failures separately from authorization and checkout failures because they require different fixes.

    Preserve the boundary between influence and completion. An agent referral, a protocol request, a cart creation, a checkout handoff, and a paid order are different events. Calling all of them conversions will overstate performance and make protocol decisions harder to defend.

    Key takeaways

    • Define the exact discovery or transaction journey before evaluating a protocol.
    • Keep pricing, inventory, policy, checkout, and order rules in your core commerce systems.
    • Use adapters to connect protocols rather than rebuilding business logic for each interface.
    • Align product pages, JSON-LD, feeds, and APIs, but revalidate mutable facts before consequential actions.
    • Require explicit authentication, action-level authorization, safe retries, bounded delegation, and audit records.
    • Launch with a restricted journey, test failure states, and expand only when each stage has measurable reliability.

    Your next move is to pick one sellable journey and document its fields, actions, authorities, and errors on a single implementation map. That map will show whether your immediate constraint is visibility, catalog quality, transaction safety, or protocol translation. Fix that constraint first, then add the interface that gives the journey a useful route into agentic commerce.

    References

  • How to Migrate Google Ads Conversion Tracking Safely

    How to Migrate Google Ads Conversion Tracking Safely

    Your Google Ads reports can look normal right up until an import starts being rejected. If your server-side or offline conversion pipeline includes session attributes or IP address data, the weak point is now the route those fields take, not necessarily the conversion event itself.

    The safest response is a controlled handoff. Identify every affected import, move the restricted data to the Data Manager API, verify the new route without counting the same event twice, and retire the old path only after reporting and error handling are stable.

    First, prove that your conversion import is affected

    This is not a blanket shutdown of every Google Ads API conversion workflow. The immediate trigger is narrower: new users of session attributes or IP address data cannot send those fields through Google Ads API conversion imports. Existing implementations may continue for now, but continued acceptance should not be treated as a permanent architecture guarantee.

    Start with the payload your system actually sends. A design document or old integration ticket may not reflect production behavior, especially if another team added enrichment fields later.

    • Find every sender. Inventory scheduled jobs, CRM connectors, server-side services, data warehouses, tag-management servers, and vendor integrations that import conversions through the Google Ads API.
    • Inspect the request definition. Check the serialized payload, mapping configuration, or schema for session attributes and IP address fields. Inspect field presence without copying raw IP addresses or user data into an audit spreadsheet.
    • Map the affected scope. Record which Google Ads customers and conversion actions receive data from each sender.
    • Identify the developer token. The restriction is tied to allowlisting, so two integrations serving the same advertiser may behave differently if they use different credentials.
    • Search error telemetry. Look specifically for CUSTOMER_NOT_ALLOWLISTED_FOR_THIS_FEATURE rather than relying on a generic failed-jobs total.
    • List downstream users. Note which reports, alerts, budget decisions, and automated bidding strategies depend on the imported conversions.

    You should finish this audit with one of three classifications. If neither field is present, this particular restriction is not an immediate migration trigger. If you are building a new implementation that needs either field, design it around the Data Manager API before launch. If an existing allowlisted implementation still works, use that continuity as a migration window rather than a reason to postpone the work.

    Treat the change as a data-route migration

    An isometric routing junction redirects conversion events from a blocked legacy channel into a secure data channel.

    Simply renaming or deleting fields misses the architectural change. Google is positioning the Google Ads API around campaign management and core conversion workflows while directing more complex conversion and user-data transfer toward the Data Manager API.

    That means your migration plan needs to separate three responsibilities:

    • Event creation: the system that decides a conversion occurred and constructs the business record.
    • Data delivery: the API route that carries the conversion and any associated session or user data.
    • Measurement control: the monitoring that confirms events were accepted once, reached the intended destination, and remained available to reporting and bidding.

    Write a field-level migration contract before changing production code. For each field in the current payload, record its originating system, its purpose, its destination in the new route, whether it may remain in the Google Ads API request, and what should happen if the destination rejects it. Explicitly mark session attributes and IP address data so they cannot leak back into the legacy request through a shared serializer or enrichment step.

    The contract also needs an event identity rule. During a staged migration, two working API clients can be more dangerous than one broken client because both may submit the same conversion. Do not assume the two routes will deduplicate an event for you. Use a non-overlapping test scope or a verified deduplication control, and make the event identifier visible in operational logs without exposing unnecessary user data.

    Use a staged cutover that protects conversion continuity

    Unique conversion tokens pass through parallel migration lanes and a deduplication checkpoint before reaching one counting destination.

    A migration should change one variable at a time. If you replace the API route, revise attribution logic, rename conversion actions, and alter campaign goals in the same release, a reporting difference will be almost impossible to diagnose.

    1. Capture a baseline. Record normal submitted, accepted, rejected, and retried event volumes for each affected conversion action. Include conversion values and delivery delays where those matter to your reporting.
    2. Instrument the current path. Make sure every submission has a traceable status and that policy errors are separated from transient delivery failures. A single generic success rate hides the failure you need to see.
    3. Build the Data Manager route. Implement the mapped destination for the complex conversion and user data, including the session attributes or IP-related data your existing workflow requires.
    4. Clean the Google Ads API payload. Remove session attributes and IP address fields from that route. This can prevent the allowlisting rejection while the new transfer path is established, but it does not prove that the resulting measurement is equivalent.
    5. Test a non-overlapping slice. Route a clearly defined subset through the new path. Keep the rest on the existing path so you can isolate differences without submitting the same events twice.
    6. Reconcile at the event and aggregate levels. Check individual event identity and status, then compare counts, values, rejection reasons, and availability timing for comparable conversion actions and time windows.
    7. Expand gradually. Increase the new route’s scope only after its error behavior is understood. Watch reporting and automated bidding inputs as closely as API health because missing conversions can distort both performance analysis and bidding decisions.
    8. Retire the legacy import. Phase out the affected Google Ads API conversion import only after the Data Manager route, monitoring, replay behavior, and operational ownership have all been validated.

    Define stop and rollback conditions before launch

    Set the conditions that pause the cutover before you begin it. Useful signals include an unexpected rise in rejected events, missing event identifiers, duplicate submissions, a material drop in accepted conversions, or delivery delays outside the range your campaigns normally receive.

    A rollback must not reintroduce restricted fields into a non-allowlisted Google Ads API request. The safer fallback is to pause expansion, keep unaffected conversion imports running, and repair the Data Manager route. Replay failed events only when your retention rules allow it and your event identity controls can prevent duplicates.

    Handle the allowlisting error as a routing failure

    The error CUSTOMER_NOT_ALLOWLISTED_FOR_THIS_FEATURE means the conversion import was rejected because session attributes or IP address data were included without the required allowlisting. Treat it as a deterministic policy failure, not as ordinary network instability.

    Automatic retries with an unchanged payload will repeat the same mistake. Your failure handler should instead follow a specific branch:

    1. Stop blind retries for the rejected payload.
    2. Record the affected customer, conversion action, event identifier, credential path, and prohibited field type without logging the raw IP address or unnecessary user data.
    3. Remove session attributes and IP address fields from the Google Ads API version of the request.
    4. Route the affected complex data through the Data Manager API.
    5. Retry the cleaned conversion only if the remaining request is valid and your event controls show it has not already been accepted.
    6. Alert the integration owner if the same policy error recurs after the payload has supposedly been cleaned. That usually points to a shared serializer, enrichment service, or secondary sender still adding the fields.

    This distinction matters operationally. A transient failure belongs in a delayed retry queue. A policy rejection belongs in a remediation queue because time alone will not change the result.

    Validate reporting and bidding, not just API delivery

    A healthy API dashboard is necessary, but it is not enough. The purpose of the pipeline is to produce trustworthy conversion signals. A request can leave your system without generating the measurement outcome your team expects.

    Use four layers of validation:

    • Transport health: attempted, accepted, rejected, retried, and permanently failed submissions by route.
    • Event integrity: missing identifiers, duplicated identifiers, unexpected field omissions, and events sent through both routes.
    • Measurement continuity: conversion counts and values by conversion action, source system, and comparable time window. Compare like with like; a changed scope can make a correct migration look wrong.
    • Decision continuity: sudden changes in the conversions used for campaign reporting or automated bidding. Avoid declaring a campaign performance change while a known tracking gap is still being repaired.

    Choose alert thresholds from your own baseline rather than copying a universal percentage. Conversion volume and delivery timing differ too much across businesses for one threshold to be meaningful. The important control is that a known policy rejection, duplicate, or unexplained loss cannot remain hidden inside an aggregate success metric.

    Keep the migration observable after cutover. The first clean deployment does not protect you from a later code change that adds the restricted fields back to the Google Ads API payload. Add a schema-level test or outbound request check that fails before such a request reaches production.

    Key takeaways

    • This migration is immediately relevant when Google Ads API conversion imports include session attributes or IP address data.
    • Existing access may continue, but it should be treated as time to migrate rather than proof that the current route is permanent.
    • Move complex conversion and user-data transfer to the Data Manager API, and remove the restricted fields from Google Ads API requests.
    • CUSTOMER_NOT_ALLOWLISTED_FOR_THIS_FEATURE is a policy and routing problem. Retrying an unchanged payload will not resolve it.
    • Test with a non-overlapping event scope, reconcile individual events and aggregate results, and prevent duplicate conversion submissions.
    • Judge the cutover by reporting and automated bidding continuity as well as API acceptance.

    Your next action is small and decisive: open the production request definition and determine whether either restricted field is present. If the answer is yes, name the migration owner, document the current baseline, and create the Data Manager route before changing the legacy importer. That sequence gives you a controlled cutover instead of an emergency caused by rejected conversions.

    References

  • Google-SerpApi Scraping Lawsuit: An SEO Team Playbook

    Google-SerpApi Scraping Lawsuit: An SEO Team Playbook

    Your rank tracker can keep returning data while the legal and commercial assumptions underneath it have already become a business risk. If your dashboards, client reports, competitive research, or AI visibility monitoring depend on SerpApi or another reseller of Google results, you need an exposure map before a court outcome, not a prediction of who will win.

    Google’s claims remain contested, and filing a lawsuit does not prove them. But the dispute targets the collection method, the content being collected, and the resale of that content. Those issues can affect service continuity, field coverage, pricing, and historical comparability long before they establish a legal rule.

    What the lawsuit does and does not establish

    Google is not merely objecting to someone looking at a public results page. It alleges that SerpApi evaded security measures and crawling controls to collect and resell search-result content. More specifically, Google accuses SerpApi of:

    • Circumventing technical protections and standard crawling controls.
    • Disregarding website directives intended to limit content access.
    • Using cloaking, rotating bot identities, and large bot networks to avoid detection.
    • Taking licensed material from search features, including images and real-time data, and selling access to it.

    Those are Google’s allegations, not findings of fact. SerpApi denies wrongdoing, argues that public search data should remain accessible, and has invoked the First Amendment in defending its position. It also warns that restrictions of this kind could damage an open web.

    Do not turn that disagreement into either of two unsupported conclusions: that every form of SERP collection is unlawful, or that anything visible in a browser is automatically unrestricted. The real questions are more specific:

    • How was the data accessed?
    • Which technical controls or publisher directives applied?
    • Does the result contain material licensed from another provider?
    • What exactly is being stored, transformed, displayed, and resold?
    • Which party assumes the risk if access is restricted?

    This distinction matters when you evaluate a supplier. A provider’s broad statement that its data is public does not answer a narrower allegation about evading controls or redistributing licensed content. You need enough provenance to understand the service you are buying, even if the provider cannot disclose its entire technical system.

    Audit your SERP dependency before the data changes

    Analysts trace branching data connections from a generic search-results source to rank tracking, reports, research, storage, alerts, and AI monitoring tools.

    Start with operational exposure rather than courtroom speculation. The goal is to identify what would break if a provider removed fields, reduced request volume, changed its collection method, raised prices, or stopped serving a particular Google feature.

    1. Find direct and indirect dependencies. Search your scripts, workflow automations, data warehouse jobs, dashboards, reporting templates, and vendor integrations for SerpApi and other SERP data services. A platform can expose search data without making its upstream supplier obvious, so ask embedded vendors as well.
    2. Separate the data classes. Record whether each workflow uses organic links, snippets, images, knowledge features, shopping information, local results, or real-time features. The lawsuit’s emphasis on allegedly licensed feature content makes a generic label such as “Google data” too vague for risk review.
    3. Map every downstream commitment. Note which datasets feed internal research, executive reporting, client deliverables, automated alerts, product features, or contractual service levels. A low-volume feed can still be critical if a customer-facing report depends on it.
    4. Capture a baseline. Preserve your field dictionary, query settings, market and device assumptions, freshness expectations, failure rate, and representative outputs, subject to your retention rights. Without a baseline, a provider-side methodology change can look like a ranking or visibility change.
    5. Assign a fallback. Name the replacement method, the owner who can activate it, and the reporting limitation it introduces. “Find another API” is not a fallback plan unless you have tested how its definitions and coverage differ.

    Classify the dependency by the consequence of failure, not by the number of API calls:

    DependencyPractical responseImportant limitation
    Ad hoc researchSave query definitions and identify a manual sampling method.A small manual sample may not reproduce the provider’s location, device, or personalization assumptions.
    Recurring internal dashboardTest a second data path and annotate any supplier or methodology change.Two providers may label positions and search features differently.
    Client or executive reportingDocument the dependency, establish a change-notice process, and prepare a reporting caveat.Combining incompatible series can create a false trend.
    Customer-facing product featureReview the contract, test graceful degradation, and define who can activate the contingency.A legal remedy after disruption will not restore immediate availability.

    For information about your own site’s Google performance, a first-party source such as Google Search Console may cover part of the need. It does not reproduce a complete results page or provide a like-for-like replacement for competitive SERP monitoring. Treat it as one layer of a fallback, not a universal substitute.

    When you test an alternative, overlap the old and new methods before combining their data. Compare query interpretation, country and location handling, device type, result-feature definitions, missing fields, freshness, and error behavior. If the series are not comparable, start a new baseline and mark the break instead of presenting it as an SEO movement.

    Put collection provenance into vendor review

    Two reviewers inspect a transparent data chain linking generic web collection, a vendor server, and an analytics workstation beside blank compliance documents.

    Do not ask only, “Is this legal?” That invites a sales assurance rather than a useful explanation. Ask questions that expose the collection path, rights assumptions, and continuity plan:

    1. What is the origin of each data class? Ask the provider to distinguish directly collected Google output, third-party licensed data, transformed data, estimates, and information obtained through another supplier.
    2. How does the service respond to access restrictions? You do not need instructions for evading controls. You do need to know whether the provider stops, substitutes data, reduces coverage, or changes methods when access is limited.
    3. Which fields may contain third-party licensed material? Images and real-time features deserve separate treatment from ordinary organic URLs because Google has specifically raised licensed-content allegations.
    4. What changes first under pressure? Ask whether a restriction would affect certain countries, devices, result types, request volumes, freshness levels, or historical exports before the entire service failed.
    5. How will customers be notified? Request the provider’s process for communicating collection-method changes, field removals, legal restrictions, and material coverage loss.
    6. Can you export your history and metadata? Historical values without query settings, timestamps, markets, device assumptions, and field definitions may be impossible to interpret after migration.
    7. How does the contract allocate risk? Have qualified counsel review warranties, indemnities, termination rights, notice obligations, permitted uses, and retention terms in the context of your actual implementation.

    A vendor contract cannot guarantee uninterrupted access to an external platform. It can clarify responsibility, but you still need a technical fallback. Keep those two workstreams separate: counsel assesses legal exposure, while your data and SEO teams protect continuity and measurement quality.

    Answers that should slow your decision

    • “The data is public.” This does not explain whether technical controls were bypassed or whether some fields contain licensed material.
    • “Everyone collects search results.” Industry prevalence does not tell you how this provider operates or what rights attach to each data class.
    • “Customers have never had a problem.” That does not establish a continuity plan, a notification process, or a contractual remedy.
    • “Our method is completely legal.” An unqualified conclusion is less useful than a written explanation of the access model, relevant rights, and scope of the assurance.
    • “We cannot discuss any aspect of collection.” A provider may protect proprietary details, but complete opacity prevents you from performing even basic supplier-risk review.

    If your own collection code, or a method disclosed by a supplier, appears to bypass access controls or conceal bot identity, do not expand that deployment until qualified legal counsel has assessed the actual facts. This operational checklist cannot determine whether a particular system is lawful.

    Protect AI visibility and SEO reporting without changing strategy

    The provenance question extends beyond a direct SerpApi account. Reddit has separately accused SerpApi, Perplexity, Oxylabs, and AWMProxy of participating in an indirect scraping chain involving Google results. Reddit says it planted a trap item visible only to Google’s crawler that later appeared in Perplexity results. SerpApi denies the allegations.

    That claim does not prove how every named party obtained every item. It does illustrate why data lineage matters: your dashboard may receive information through several suppliers, and the company selling you the final metric may not be the company collecting the underlying result.

    For an AI visibility, AEO, or GEO platform, document the measurement chain with the same care you would apply to a rank tracker:

    • Label whether each metric comes from a directly observed model response, a Google result, a third-party dataset, or an inferred score.
    • Retain the query or prompt, timestamp, market, device, search feature, and model or product identifier when those fields are available.
    • Require a methodology changelog so a collection change cannot quietly become an apparent visibility gain or loss.
    • Keep observed facts, such as whether a brand appeared, separate from proprietary scores or estimates.
    • Rebaseline a metric when its supplier, collection path, feature definition, or model surface changes materially.
    • Do not use Google SERP coverage as an unlabeled substitute for direct measurement of an AI system. Search visibility and model-response visibility answer different questions.

    The lawsuit itself is not evidence of a Google ranking update, a change to structured-data processing, or a new standard for earning AI citations. Do not rewrite content, remove JSON-LD, or change your internal-link strategy because litigation was filed. Change the governance around the data used to judge those activities.

    Predefine the events that will trigger action: a supplier notice, unexplained field loss, a sustained change in failure behavior, a restriction on a result type, a material pricing change, or a change in collection methodology. Then name who decides whether to continue, degrade the report, activate a fallback, or start a new measurement baseline. That prevents a technical incident from turning into an improvised legal and client-communication decision.

    Key takeaways

    • Google’s claims against SerpApi are contested allegations, not a judgment that all SERP data collection is unlawful.
    • Your immediate exposure is operational as well as legal: access, fields, prices, and historical comparability can change before the case is resolved.
    • Audit direct APIs and hidden upstream suppliers across dashboards, reports, automations, and AI visibility tools.
    • Ask how each data class was obtained, which rights apply, what degrades under restriction, and how methodology changes are disclosed.
    • Use overlapping tests and explicit baseline breaks when changing providers; otherwise a measurement change can masquerade as an SEO trend.
    • Keep your content and schema strategy tied to search performance evidence. The lawsuit calls for stronger data governance, not reactive optimization changes.

    Your next move is concrete: inventory every workflow that depends on full Google results, classify its business impact, and send the seven provenance questions to each supplier. You do not need to predict the verdict to make your measurement stack less fragile.

    References

  • Google Ads API Optimization: A Safe AI-Assisted Workflow

    You have a Google Ads performance question, but answering it means choosing fields, writing GAQL, handling authentication, and turning the result into something the team can review. AI assistance can remove much of that technical friction. It cannot decide whether broader reach, a higher bid, or a new keyword strategy makes financial sense for your business.

    The useful approach is to separate observation from action. Use the Google Ads API Developer Assistant to investigate performance through read-only queries, validate what it returns, and save repeatable analysis. Put any change to budgets, bids, targeting, or keywords through a deliberate human approval process.

    Separate faster analysis from automated optimization

    Google Ads API Developer Assistant v1.0 is a Gemini CLI extension that can translate natural-language requests into GAQL, answers, and Python code built around the google-ads-python client library. This makes it useful when you understand the business question but do not want to reconstruct every query from memory.

    The assistant can also execute read-only API calls from the terminal, display results in formatted tables, export tabular data to CSV, and place generated code in a saved_code folder. Those capabilities shorten the path from a question to an inspectable result.

    That is analysis assistance, not an optimization strategy. A table can show which campaign recorded the most conversions. It cannot determine whether those conversions were valuable, whether lead quality deteriorated, or whether the campaign consumed more budget than the outcome justified. Those judgments depend on business definitions and constraints that sit outside a generic performance query.

    Keep the boundary explicit: the assistant retrieves and organizes evidence; an accountable person decides what the evidence means and whether the account should change.

    Key takeaways

    • Begin with reporting and diagnosis. Do not treat generated output as permission to change the account.
    • Include the account scope, date range, dimensions, metrics, filters, sort order, and desired output in every request.
    • Review generated GAQL and Python as untrusted code before running or reusing it.
    • Treat Google Ads Recommendations as hypotheses to investigate, not instructions to accept.
    • Keep changes to budgets, bids, targeting, and keywords behind human approval and a defined rollback path.

    Ask questions that lead to decisions, not just reports

    A vague request such as analyze my campaigns leaves too many choices to the assistant. It does not identify the problem, the period, the level of detail, or the decision you need to make. The result may be technically valid and still be operationally useless.

    Start with the decision. If you are deciding where to investigate a conversion decline, ask for a result that isolates campaign performance over a named period and includes the metrics needed to distinguish lower volume from higher cost. If you are checking a Google recommendation, request the evidence that would support or contradict its underlying claim.

    Use this prompt pattern: Within [account or campaign scope], for [date range], return [dimensions] and [metrics]. Apply [filters], sort by [metric], and provide [GAQL, Python, a terminal table, or CSV]. Explain the row grain, field choices, and assumptions before the result.

    Each part prevents a common analytical mistake:

    • Scope prevents a manager account, client account, campaign type, or status from being included unintentionally.
    • Date range makes the comparison reproducible. Relative periods are convenient for exploration, while explicit periods are easier to audit later.
    • Dimensions determine what one row represents. Adding a date, device, or other segment can change the grain and produce many rows for a campaign.
    • Metrics determine whether you can connect activity to a business outcome. A ranking by conversions alone does not show the cost or value behind those conversions.
    • Filters remove irrelevant entities, but an overly narrow filter can hide the reason performance changed.
    • Output determines whether you get an explanation, a reusable query, executable code, or an artifact another person can inspect.

    Prompts you can adapt

    • For the previous 30 days, rank campaigns by conversions. Return the GAQL first, explain the selected fields, and then produce a read-only Python script using google-ads-python.
    • Compare campaign cost and conversion performance across two explicitly named periods. Show the row grain and flag any filter that excludes paused or removed entities.
    • Generate a read-only query that provides evidence for or against a recommendation to expand keyword matching. Separate the requested output by campaign so the account owner can review exposure and outcomes.
    • Run this approved query, display a terminal table, and export the same rows to CSV. Include the account scope and date range in the output description.

    The first example closely matches a documented use case: a request for campaigns with the most conversions in the last 30 days can produce both a GAQL query and an optimized Python script. The important addition is the review instruction. You want to see what the assistant plans to ask the API before you rely on the answer.

    Inspect five things before execution: the customer being queried, the dates, the row grain, the filters, and the metric definitions. Then look for a sanity check. Compare a small part of the result with a familiar Google Ads view or an existing trusted report. A plausible table is not proof that the query answered the question you intended to ask.

    Configure Developer Assistant v1.0 for repeatable work

    The documented prerequisites for v1.0 include a Google Ads API developer token, a configured google-ads.yaml file, Python 3.10 or later, Gemini CLI, and a local clone of the google-ads-python library. A setup script handles the library cloning step.

    Do not stop once the assistant returns its first successful table. A useful setup makes the same request behave consistently for different operators and on different days.

    1. Validate the connection with a known read-only question. Choose a result you can verify in the Google Ads interface. This separates authentication or account-scope problems from query-design problems.
    2. Define project conventions in GEMINI.md. The assistant uses GEMINI.md and configuration files as project context when tailoring code. State the expected client library, output conventions, code location, naming rules, and read-only default.
    3. Require an explanation before execution. Ask for the GAQL, selected resources, filters, dates, and row grain in plain language. A reviewer should be able to understand the intended request without reverse-engineering the code.
    4. Keep credentials out of prompts and generated files. Use the supported configuration mechanism. Review saved files before sharing them or adding them to version control.
    5. Review generated Python before running it. Check imports, customer selection, request type, file paths, exception handling, and whether the code does anything beyond retrieval and export.
    6. Preserve a verified query as a smoke test. Run it after configuration or dependency changes. If its known output or shape changes unexpectedly, investigate the environment before trusting new analyses.

    Project context is leverage. Good instructions make repeated analysis more consistent; incorrect instructions make the same mistake repeatable. Keep GEMINI.md short enough to review, specific enough to guide the assistant, and under the same change-control discipline as other project configuration.

    The saved_code folder is most valuable when it becomes a reviewed library rather than a dumping ground. Give each retained script a clear purpose, record its account scope and required inputs, and distinguish experimental output from approved reporting code. Remove ambiguity before another person schedules or modifies it.

    Turn Recommendations into an evidence-backed test queue

    Google Ads Recommendations are prompts to evaluate. They are not proof that the proposed change fits your economics. A suggestion may be informed by patterns across accounts while missing a constraint that matters in yours. For example, an account using Exact and Phrase match keywords may receive a Broad Match suggestion even when its budget or niche requires tighter control.

    The Optimization Score is easy to misread as a performance grade. It reflects how recommendations are being handled, and dismissing a recommendation can affect the score in the same way as applying it. You do not need to accept an unsuitable change merely to clear the prompt or improve the displayed score.

    Use the API assistant to build an evidence packet for each recommendation:

    1. Restate the claimed problem. Is the recommendation trying to expand reach, improve efficiency, repair setup, or remove a limitation?
    2. Request the relevant account evidence. Define the entities, period, metrics, and filters that would show whether that problem exists.
    3. Write down the business constraint. Include budget limits, acceptable lead quality, geographic restrictions, inventory realities, or other rules that the platform cannot infer reliably.
    4. Set success and failure criteria before making a change. Decide what result would justify keeping the change and what result would trigger reversal.
    5. Choose a reversible test. Limit the blast radius and preserve the prior state so the account can be restored if performance or traffic quality deteriorates.
    6. Assign an owner. One person should approve the change, monitor the agreed evidence, and decide whether to keep or roll it back.

    Auto-apply deserves stricter treatment because it can remove that review gate. The documented control path is Recommendations, All Campaigns, and Auto-Apply Settings, where you can confirm that unwanted selections are unchecked. Check the setting at the account level instead of assuming that an earlier choice still reflects current policy.

    This is a financial control, not interface housekeeping. Automatically applied suggestions can affect reach, spending, bids, or keyword behavior. Enable a category only when you have defined who owns it, what changes it permits, how the effect will be monitored, and how the prior state can be recovered.

    Do not give every interface notice the same urgency. Blue or yellow notices can represent suggestions, while red or purple notices can indicate issues such as billing errors or disapproved ads. Investigate actual delivery or account-access problems before spending time on an optional optimization prompt.

    Run one controlled loop from question to verified change

    A reliable optimization process leaves a trail from the original question to the final decision. It should be possible for another person to see what was queried, what came back, why a change was approved, and whether the expected result appeared.

    1. Name the decision. Write the question in a form that could change an action: which campaigns need investigation, whether a recommendation deserves a test, or where a recurring report shows an exception.
    2. Specify the evidence. Add account scope, dates, dimensions, metrics, filters, and output format to the prompt.
    3. Generate before executing. Read the proposed GAQL and code. Correct ambiguous fields, unintended segments, and overly broad scope.
    4. Run read-only. Display the result in the terminal and export CSV when another reviewer or a longer audit trail is needed.
    5. Validate the result. Compare a small slice with a trusted interface view or established report. Confirm that each row represents what you think it represents.
    6. Form a testable explanation. State what appears to be happening, what evidence is still missing, and which reversible change could test the explanation.
    7. Approve and implement separately. Use your normal controlled account-management process for changes. Do not turn generated analysis code into mutation code simply because the first output looked correct.
    8. Run the same query again. Reuse the reviewed query so the before-and-after comparison is based on the same scope, fields, filters, and row grain.

    Label saved queries and exports with enough context to make them interpretable later. At minimum, preserve the account scope, analysis period, purpose, and important filters alongside the artifact. A file called campaign_report.csv creates less accountability than an export tied to a specific question and approved query.

    Automate stable retrieval only after the query has survived review and repeated validation. Keep recommendations and account mutations gated. The cost of manually approving a consequential change is small compared with the cost of allowing a misunderstood prompt, broad filter, or unsuitable recommendation to alter spend without supervision.

    Start with one recurring question your team currently answers by hand. Define it precisely, run it read-only, verify the output, and retain the approved query. Once that loop is dependable, add the next question. The real efficiency gain comes from reusing trusted analysis while keeping financial decisions under human control.

    References

  • Google Ads and Shopping Changes: What to Prioritize Now

    Google Ads and Shopping Changes: What to Prioritize Now

    You’re deciding which Google changes deserve engineering time, which belong in your Shopping plan, and which are still too speculative to enter a forecast. The answer isn’t to treat every announcement, test, and rumor as equally actionable.

    The clearest opportunity is first-party data infrastructure. Local Shopping labels deserve feed preparation and controlled observation. Gemini advertising belongs on a watchlist, not in a committed media plan. That order will help you improve what is available without budgeting against a product that doesn’t exist.

    Key takeaways for advertisers

    • Prioritize the Data Manager API when separate integrations are creating duplicated work or inconsistent first-party data flows.
    • Treat merchant city and town labels in Shopping ads as an observed test. Prepare accurate local inventory data, but don’t forecast an uplift or assume every eligible impression will show the label.
    • Keep Gemini separate from AI Mode in your planning. Google’s stated position is that the Gemini app has no ads and there are no plans to add them.
    • Classify every platform change as available, experimental, or unconfirmed before assigning budget, engineering effort, or performance targets.

    First-party data deserves the engineering time

    Illuminated data pathways connect customer touchpoints to a protected central data hub and several activation modules.

    Google’s Data Manager API is the most concrete change because it solves an operational problem you may already have: audience data, offline conversions, and other first-party signals reaching Google through separate connections. The API is designed to provide one integration point across Google Ads, Google Analytics, and Display & Video 360.

    That consolidation matters when your team maintains one job for customer lists, another for offline conversion uploads, and additional platform-specific logic for authentication, retries, or refreshes. A shared route can reduce that maintenance burden. It can also make ownership clearer when a data flow fails.

    The API supports three jobs that directly affect campaign operations: uploading and refreshing audience lists, sending offline conversions, and supplying richer signals for bidding. Those capabilities don’t guarantee better performance. They give Google’s automated systems more useful inputs, and you still need to verify whether those inputs change measurement or campaign outcomes in your account.

    Use a bounded migration sequence rather than moving every data flow at once:

    1. Inventory the current routes. Record which process sends each audience or conversion type, how often it runs, who owns it, and what happens when records fail.
    2. Choose one well-understood flow. Start with an audience list or offline conversion type whose current volume, update pattern, and business meaning are already known. A familiar baseline makes discrepancies easier to find.
    3. Define the data contract before building the endpoint. Agree on identifiers, event names, time fields, refresh frequency, correction handling, and ownership. A unified API won’t reconcile two teams using different meanings for the same conversion.
    4. Validate the new and existing routes side by side. Compare submitted, accepted, rejected, and delayed records where those measures are available. Do not send the same event through both routes unless you have verified how duplicates are prevented.
    5. Check reporting before changing bidding. Confirm that conversion totals, audience freshness, and processing delays behave as expected. Only then should you evaluate whether richer signals help automated bidding.
    6. Retire an old connection only after reconciliation. Keep a rollback path until the new route has completed its normal refresh and correction cycles without unexplained gaps.

    This sequence protects the part of the account with financial consequences: measurement. If an integration drops conversions, submits duplicates, or changes event meaning, bidding can optimize against a distorted picture. Parallel validation is less expensive than discovering the problem after an automated campaign has reacted to it.

    The strongest adoption case is a team already maintaining several Google connections. If you have one stable data flow and little engineering overhead, consolidation may be less urgent. Start with the operational cost you can document, not the assumption that a new API automatically creates incremental revenue.

    Local Shopping labels make feed accuracy visible

    A retail employee scans a product beside organized shelves, a tablet, a stockroom, and a local pickup counter.

    Some Shopping ads using local inventory data have displayed the merchant’s city or town above the product title. The placement gives shoppers a proximity cue without requiring a separate local ad format. It is distinct from fulfillment labels such as In-store, Pickup later, and Curbside pickup.

    That distinction is important. A city label tells the shopper where the merchant is located. By itself, it doesn’t promise immediate availability, same-day collection, or a particular fulfillment method. Your inventory and pickup information still need to carry those meanings accurately.

    Google has not published rollout, eligibility, or technical requirements for the location-label test. You therefore shouldn’t look for an undocumented switch, promise the placement to stores, or build a performance forecast around it. The practical move is to make the local inventory setup reliable enough to benefit if the label appears.

    • Check store and product coverage. Confirm that the intended locations and locally available products are present in the systems supplying your local inventory data.
    • Standardize location names. Resolve inconsistent city or town naming across store records before those differences become visible to shoppers or fragment your analysis.
    • Audit location and fulfillment separately. A correct city label cannot compensate for stale availability or pickup information, and a pickup label does not confirm that the displayed city is the location you intended to promote.
    • Record observed appearances. When your team sees the label, capture the market, store, query context, device, and date. That record will help you distinguish a limited test from a broader change.
    • Measure at the local level. Compare results by store or market where activity is sufficient, rather than blending exposed and unexposed locations into an account-wide average.

    A recognizable or nearby location could make a merchant feel more relevant than a distant seller. That is a plausible shopper response, not a guaranteed click-through or store-visit lift. Let observed exposure and local results establish the value before you change budgets.

    Gemini advertising is not a 2026 media plan

    Claims that the Gemini app would receive dedicated ad placements in 2026 prompted a direct denial from Google. Its stated position was that there are no ads in the Gemini app and no plans to change that.

    That doesn’t settle how every Google AI experience will be monetized indefinitely. It does settle what belongs in a responsible plan based on the information available: no Gemini inventory, targeting assumptions, pricing model, creative specification, eligibility rule, or measurement framework should appear as a committed line item.

    Keep Gemini and AI Mode in separate rows of your channel plan. Ads associated with AI Mode do not prove that the Gemini app will use the same inventory or commercial model. Product names, interfaces, and user behavior may look related while their advertising availability remains different.

    A useful planning boundary is simple:

    • Available inventory can receive budget when your account is eligible and its economics fit the campaign.
    • An observed test can receive monitoring, data preparation, and a measurement plan, but not assumed reach or revenue.
    • A denied or unconfirmed product stays on a watchlist until Google supplies an official product path, eligibility details, and reporting expectations.

    You can still prepare strategically. Decide which customer questions, product attributes, and conversion events would matter in a conversational ad environment. Do not assume, however, that current Google Ads audiences, Shopping feeds, or Data Manager integrations will automatically transfer to a future Gemini product. No documented product connection supports that implementation decision.

    Use one evidence rule for every platform change

    The three developments require different actions because their evidence states are different. Put them in a change register that your paid media, ecommerce, analytics, and engineering teams can read without translating headlines into strategy on their own.

    Platform changeDocumented statusAction nowDo not assume
    Data Manager APIAvailable across Google Ads, Google Analytics, and Display & Video 360Pilot one audience or offline conversion flow and reconcile it before consolidationThat a new connection fixes weak data or guarantees a performance gain
    Shopping merchant location labelObserved test using local inventory data; rollout and requirements are unannouncedAudit local feeds, standardize locations, and prepare store-level measurementUniversal exposure, a configuration switch, or an automatic traffic lift
    Gemini app adsGoogle denied that ads are present or plannedKeep the possibility on a monitored watchlist2026 inventory, pricing, formats, targeting, or compatibility with AI Mode

    For each entry, record the affected surface, evidence status, business dependency, owner, next action, and condition that would justify changing the status. An official availability notice could move a test into implementation. Repeated sightings without documentation may justify broader measurement, but not a guaranteed forecast. A rumor should not advance because it has been repeated.

    Start with the first-party data inventory because it can improve infrastructure you already use. Then audit local feeds so your stores are ready for location-led Shopping presentation. Remove Gemini placements from committed projections unless Google replaces its denial with a real product announcement. That gives you a plan based on executable changes rather than imagined inventory.

    References

  • A Practical Playbook for Google’s Ads Measurement Changes

    A Practical Playbook for Google’s Ads Measurement Changes

    Your Google advertising stack can collect more data and still produce weaker decisions. That is the risk when lifecycle audiences, automated campaign reporting, and developer support are treated as unrelated features owned by different teams.

    You need one operating loop that connects customer qualification, media delivery, business outcomes, and incident response. The goal is not merely to enable Google’s new options. It is to know what the data means, which decision it supports, and how you will recover when the pipeline fails.

    Key takeaways

    • Define what makes a customer valuable or disengaged before building the Google Analytics audience. A template can apply your rule, but it cannot choose the right commercial rule for you.
    • Validate ecommerce events and audience inputs before increasing spend. Faulty purchase data can distort audience membership, dynamic remarketing, and campaign evaluation at the same time.
    • Use the new Performance Max Search Partners segment as a diagnostic view. Separate reporting shows where activity occurred; it does not, by itself, prove that the activity caused incremental revenue.
    • Evaluate high-value acquisition and customer re-engagement separately. They target different behaviors and should not be judged through one blended campaign average.
    • Replace informal forum troubleshooting with a documented support packet containing identifiers, logs, reproduction steps, expected behavior, and exact errors.

    Define customer value before Google Analytics does the grouping

    A strategist organizes anonymous customer tokens by engagement and value before they enter an automated grouping system.

    Google Analytics now provides suggested audiences for High-Value Purchasers and Disengaged Purchasers. The first can use purchase count or lifetime value, including an LTV percentile field. The second uses the number of days since a customer’s last purchase.

    Those templates remove configuration work, but they do not settle the important business questions. A frequent buyer is not necessarily a profitable buyer. A customer who has not purchased recently is not necessarily disengaged if the normal buying cycle is long. If you accept a convenient threshold without examining the underlying behavior, Google can execute the wrong definition very efficiently.

    Build each audience in this order:

    1. Choose the business behavior you want to influence. For high-value acquisition, decide whether repeat purchasing, lifetime value, or both represent the customers you want more of. For re-engagement, define inactivity relative to the normal interval between purchases.
    2. Check whether Analytics receives the events and values needed to enforce that definition. Reconcile recorded purchases and values with your commerce records before trusting the resulting audience.
    3. Inspect audience membership for obvious mismatches. If customers enter too early, remain too long, or qualify after low-value behavior, revise the definition before activation.
    4. Separate acquisition from re-engagement. One goal seeks new people who resemble valuable customers; the other seeks another purchase from someone who already has a relationship with the business.
    5. Write down the success condition before launching. High-value acquisition should ultimately be assessed against the quality of newly acquired customers. Re-engagement should be assessed against recovered purchasing behavior, not merely ad clicks or return visits.

    This order matters because an audience is both a targeting asset and a measurement claim. Calling someone a high-value customer asserts that your data captures value correctly. Calling someone disengaged asserts that enough time has passed to make intervention appropriate. Review those assertions whenever pricing, product mix, subscription behavior, or the normal repurchase cycle changes.

    Dynamic remarketing still depends on clean inputs

    Google is also moving display dynamic remarketing into Analytics. With Google’s recommended ecommerce event collection in place, Analytics can share the relevant data with a linked Google Ads account when personalized advertising is enabled. That allows product-based ads to be shown to previous site visitors without constructing the entire remarketing setup elsewhere.

    There are two gates to check before treating this as operational. The technical gate is whether ecommerce events and product information arrive consistently and map to what you actually sell. The governance gate is whether personalized advertising is intentionally enabled under your organization’s consent and data-use rules. A linked account is not proof that either gate is healthy.

    Run a test path through a real product interaction and purchase flow. Confirm that the expected ecommerce events appear, their values are credible, and the linked Ads account receives the intended data. If audience counts or remarketing behavior change unexpectedly, investigate collection first. Raising a budget while the qualifying data is unreliable can turn a tracking defect into wasted ad spend.

    Read the PMax Search Partners row without overreading it

    Performance Max channel reporting now breaks out Search Partners in its channel performance tables. You can see how that inventory contributes to overall results, compare it with other PMax channels, and identify the spend associated with it.

    This closes a visibility gap, but visibility is not the same as control or causality. A separately reported channel can appear efficient because of the customers it reaches, the conversions credited to it, or its role in a longer journey. The row tells you where activity was reported. It does not automatically tell you what would have happened without that activity.

    Use a three-stage reading sequence:

    1. Start with allocation. Determine whether Search Partners spend is material enough to affect the campaign-level result and whether its direction changed alongside the overall campaign.
    2. Move to outcomes. Compare the segment with the business result the campaign is meant to produce, such as qualified leads, purchase value, or repeat revenue. Traffic volume alone cannot establish value.
    3. Test the incremental claim. Ask whether the activity appears to add outcomes or merely receives credit for demand that another channel might have captured. Where the financial consequence is meaningful, use an appropriate experiment or a carefully designed analysis rather than declaring incrementality from the reporting row.

    Keep a change log beside this analysis. Record material adjustments to budgets, conversion definitions, assets, feeds, audience signals, and campaign goals. Otherwise, a shift in the Search Partners row can be mistaken for an inventory effect when the campaign’s inputs changed at the same time.

    Also resist ranking every PMax channel from best to worst using one blended efficiency figure. Channels can play different roles in discovery, consideration, and conversion. The useful question is whether the newly visible activity supports the campaign’s intended economic outcome at an acceptable cost, not whether its row wins an internal leaderboard.

    When the data is weak or mixed, preserve the uncertainty. A report that exposes previously hidden spending gives you a better investigation target, not an obligation to make an immediate budget change. Changing bids or budgets on inconclusive evidence can cost money; waiting for a decision-grade pattern is the safer action.

    Replace forum memory with an incident-ready support process

    Two technical specialists document a broken data pipeline and assemble diagnostic evidence for a structured support handoff.

    Google set January 28, 2026 as the cutoff for support-agent replies to new posts in three advertising developer forums. Existing discussions were retained as reference material, while replies to existing threads would move into a new email conversation with support. Your operating process should no longer depend on receiving an answer through a new Google Groups post.

    The replacement paths are product-specific, and the evidence expected from you is more structured:

    ProductSupport routeDiagnostic material to prepare
    Google Ads APIOfficial Google Ads API supportRequest ID plus complete request and response logs
    Google Ads ScriptsOfficial Ads Scripts supportScript name, customer ID, execution logs, and UI error messages
    Campaign Manager 360 APICampaign Manager 360 support teamProfile or account IDs, API method, and request and response logs

    Every ticket should also contain a plain description of the failure, the expected behavior, exact reproduction steps, relevant code, and the complete error message. Prepare that structure before an incident. During a bidding, reporting, or automation outage, the slowest part is often reconstructing what happened across scattered logs and messages.

    A reusable incident packet should contain:

    • A short statement of what failed and which business process is affected.
    • The affected product, account, profile, customer, script, or API operation.
    • The expected result and the actual result.
    • Steps that reliably reproduce the behavior, including the smallest relevant code sample.
    • Request and response evidence, execution logs, interface errors, and the exact error text.
    • A record of recent deployments or configuration changes that could be related.
    • The internal owner who can answer follow-up questions and verify a proposed resolution.

    Keep sensitive logs in an access-controlled location, and remove credentials or tokens before sharing material. Support needs diagnostic context, not access secrets.

    The public forums also served as a searchable memory of unusual failures. Direct support conversations will not recreate that shared knowledge automatically. Preserve the solutions your team repeatedly needs in an internal runbook: the symptom, affected system, confirmed cause, resolution, and any condition that would make the fix unsafe to reuse.

    Google’s Advertising and Measurement Community Discord remains available for general discussion, but it is not an official support channel. Use community conversation to discover terminology, similar symptoms, and possible lines of investigation. Use the official route for account-specific diagnosis, tracking, and resolution.

    Run one control loop across audiences, delivery, and support

    The three changes become useful when they are reviewed as one system. Analytics determines who qualifies for activation. Google Ads determines where automated campaigns deliver and attributes results. APIs and scripts move data or automate decisions between systems. Support becomes the recovery path when any connection breaks.

    Use this sequence during account reviews:

    1. Verify input health. Check purchase events, values, product information, and the fields used to classify high-value or disengaged purchasers.
    2. Verify activation. Confirm that the intended Analytics audiences are available to the correct linked Google Ads account and that personalized advertising is deliberately enabled where dynamic remarketing is required.
    3. Inspect delivery. Use PMax channel reporting to see whether Search Partners activity or spend has changed enough to investigate.
    4. Judge business outcomes. Separate customer acquisition from re-engagement and assess each against the behavior it was designed to change.
    5. Record the decision. Note whether you changed an audience rule, campaign input, budget, or measurement definition, and state what evidence would cause you to revisit it.
    6. Test recoverability. Make sure the owner can produce the correct support packet without searching across several disconnected systems during an outage.

    This sequence prevents several common misdiagnoses. If a lifecycle audience suddenly shrinks, validate collection before blaming demand. If Search Partners spend changes, examine business outcomes and concurrent campaign changes before reallocating money. If an automated report fails, preserve request IDs and logs before rerunning or modifying the job in ways that erase the original evidence.

    Start with one account. Audit its lifecycle definitions, locate Search Partners in the PMax channel table, and assemble a complete support packet for one critical integration. Once that path works from data collection through incident recovery, turn it into the standard your other accounts must meet.

    References