Tag: AI Visibility

  • A Practical Guide to Brand Authority in AI-Driven Search

    A Practical Guide to Brand Authority in AI-Driven Search

    You can publish accurate content, rank for relevant queries, and still be absent when an AI system explains your market. If that is happening, another batch of loosely related articles probably will not solve the problem. The missing ingredient is often a recognizable chain of evidence connecting your brand, your expertise, and independent confirmation of that expertise.

    Your job is to make that chain easy for machines and people to follow. That means clarifying who you are, giving important claims a reliable home, earning corroboration beyond your own domain, and checking how AI systems actually represent you. This guide gives you a practical way to do it.

    Key takeaways

    • Brand authority is not the same as visibility. A brand can appear frequently while remaining poorly defined, weakly supported, or easy to omit from an answer.
    • Build a canonical evidence layer on your site before pursuing more mentions. Your identity, expertise, authorship, claims, and structured data should describe the same entity.
    • Relevant citations, inbound links, expert references, and contextual brand mentions provide different kinds of outside corroboration. Track them separately.
    • Make important pages easy to interpret and quote: answer the question directly, show who is responsible for the information, identify its scope, and support material claims.
    • Audit generated answers for inclusion, accuracy, attribution, and supporting citations. Each failure points to a different repair.

    Brand authority is an evidence chain, not a single score

    In AI-driven search, authority has a practical meaning: a system can identify your brand, connect it to a subject, and find enough supporting evidence to include it confidently in a synthesized answer. That is broader than traditional link authority. Modern off-page signals include inbound links, citations, brand mentions, reputation, and evidence of expertise, not merely the number of sites pointing at a domain.

    No universal public formula tells you how every AI system evaluates a brand. Treat the following chain as a diagnostic model, not a claim about a hidden ranking algorithm:

    1. Identity: Can the system distinguish your brand from similarly named companies, products, and people?
    2. Topic association: Is it clear what subjects, problems, audiences, or markets your brand is genuinely connected to?
    3. Primary evidence: Does your own site contain clear, attributable information supporting the claims you make?
    4. Independent corroboration: Do credible sources outside your control describe, cite, or recommend the brand in a compatible way?
    5. Answer utility: Can a system extract a useful passage without guessing what you mean or stripping away a necessary qualification?

    A weakness at each point produces a different symptom. If your identity is unclear, the answer may confuse you with another entity. If your topic association is weak, the brand may appear for navigational questions but disappear from category discovery. If primary evidence is thin, an AI answer may mention you without being able to support a detailed description. If outside corroboration is missing, your own claims can look isolated. If the content is difficult to interpret, a more clearly written competitor may be easier to cite.

    This is why publishing volume is a poor default response to an authority problem. First identify the broken link in the chain. Then repair that link.

    It also helps to separate three outcomes that are often bundled into one vague idea of “AI visibility”:

    • Presence: Whether the brand appears at all.
    • Representation: Whether the answer describes the brand accurately and in the right context.
    • Authority: Whether the brand is used as a credible source, example, or option rather than receiving a passing mention.

    Measure those outcomes independently. A high mention count does not compensate for an inaccurate description, and an accurate branded answer does not prove that you are discoverable for unbranded category questions.

    Build a canonical evidence layer on your own site
    An orderly glass-and-stone digital library sits on an illuminated foundation as scattered document panels converge on one central source.

    Before you ask other sites to validate the brand, decide exactly what they should be validating. Many authority campaigns begin with outreach while the company’s own pages use different descriptions, audience labels, expert biographies, and product claims. That inconsistency makes every later signal harder to interpret.

    Create a brand authority brief

    Build an internal source of truth that contains the facts your public pages should agree on. It does not need to become a single public document. It should govern what your teams publish.

    • The exact public brand name and any legitimate alternate name.
    • A plain one-sentence description of what the brand does, for whom, and in which context.
    • The subjects on which the brand can support a credible claim to expertise.
    • Subjects that are adjacent but outside that claim. This boundary prevents positioning from expanding into unsupported territory.
    • The official website and public profiles that clearly belong to the same entity.
    • The people responsible for producing or reviewing expert content, along with the credentials relevant to that work.
    • The primary page supporting each important company, product, service, or methodology claim.
    • Independent pages that corroborate those claims.

    The one-sentence description matters more than a slogan. “We transform the future of business” gives a machine almost nothing to connect to a category. A useful description follows a more disciplined pattern: “[Brand] helps [specific audience] perform [specific task] through [method or product category].” Add a limitation when readers could otherwise infer a broader capability than you can support.

    Use the brief to audit your homepage, About page, contact information, product or service pages, author biographies, editorial policy, and public profiles. The wording does not have to be identical everywhere. The facts and relationships do.

    Give every important claim a reliable home

    A claim repeated across promotional pages is not necessarily well supported. Give each material claim a canonical page where a reader can understand its meaning, scope, basis, and owner. Maintain a simple claim ledger with these fields:

    • Claim: The exact statement you want people and systems to understand.
    • Primary evidence: The page on your site that explains or supports it.
    • Responsible expert: The person or team qualified to verify it.
    • Independent corroboration: The strongest relevant evidence outside your domain.
    • Known qualification: The audience, market, use case, or condition that limits the claim.
    • Status: Confirmed, incomplete, outdated, disputed, or unsupported.

    This ledger exposes a common problem quickly: the positioning may be stronger than the evidence. If a claim has no responsible expert, no explanatory page, and no outside corroboration, do not amplify it yet. Narrow it or develop the missing evidence first.

    Pages supporting those claims should make their answer easy to extract correctly. Put the direct answer near the relevant heading. Define unfamiliar terms. State the intended audience and important exclusions. Show authorship or review responsibility where expertise matters. Link to the material that supports the statement. Update the page when the underlying facts change.

    A useful answer passage often has four parts:

    • Answer: The direct response to the question.
    • Boundary: Where the response applies and where it does not.
    • Basis: The evidence, method, or reasoning behind it.
    • Attribution: The brand or expert responsible for the information when that identity is relevant.

    This structure improves clarity without turning every paragraph into a formula. It also reduces the chance that a useful statement becomes misleading when removed from the surrounding page.

    Use structured data to clarify facts, not manufacture them

    Structured data and a consistent brand identity help systems connect content with the right entity and topics. Use your JSON-LD to mirror facts that a visitor can verify on the page. Keep names, official URLs, author relationships, publisher relationships, and content descriptions aligned with the visible site.

    Do not introduce a claim only in markup or use structured data as a substitute for evidence. Schema can reduce ambiguity. It cannot turn an unsupported marketing statement into independent authority. If the visible page, the structured data, and third-party descriptions disagree, repair the underlying facts before adding more markup.

    Earn corroboration that your brand does not control

    Your website establishes the primary record. Outside evidence shows whether anyone else recognizes it. That is the core of modern off-page authority: relevant endorsements from credible sources strengthen trust more than disconnected mentions.

    Do not combine every off-site appearance into one count. An inbound link, a citation, and a brand mention can perform different jobs:

    • Inbound link: Gives readers a path to your evidence and places your page in a specific editorial context.
    • Citation: Identifies your brand, expert, work, or material as support for a claim, whether or not the reference is clickable.
    • Brand mention: Associates the brand with a subject, event, opinion, product, or reputation. The surrounding context determines whether that association helps.

    A passing mention may improve recognition without supporting expertise. A link from an unrelated page may offer little useful context. A detailed citation from a respected source in your field can validate a particular claim even if it does not use your preferred anchor text. Record what each placement proves instead of treating all three as interchangeable.

    Evaluate a potential placement with five practical questions:

    1. Relevance: Is the surrounding page about the subject for which you want authority?
    2. Editorial independence: Did the publisher have a genuine reason to include the brand, expert, or resource?
    3. Specificity: Does the reference connect you to a meaningful claim, or does it merely list the brand name?
    4. Consistency: Does the description agree with the canonical facts on your site?
    5. Reader value: Would the reference still help someone if search engines and AI systems did not exist?

    The last question is a useful filter for manipulative tactics. If a placement has no credible purpose beyond creating a signal, it is unlikely to build the kind of reputation you want machines to reproduce.

    The most sustainable way to earn corroboration is to give other people something worth referencing. Publish a clear definition, a defensible method, an expert explanation, a practical framework, or an analysis that resolves a real question. Make the useful part easy to locate and attribute. Then take it to the publications, communities, professional networks, and content platforms where that exact subject is already discussed.

    Distribution should follow audience behavior, not a demand to occupy every channel. Search discovery now extends beyond conventional results into platforms such as YouTube, TikTok, Pinterest, and Amazon, as well as synthesized AI answers. Choose the places where your audience actually learns, evaluates, or buys. Keep the entity facts stable while adapting the format to the platform.

    Monitor the context as carefully as the quantity. A brand can accumulate mentions while an old description, discontinued positioning, or reputation issue becomes the dominant outside narrative. Correct material inaccuracies at their origin when possible. Then make the accurate record unmistakable on your own site. Repeating the right answer only on pages you control does not remove conflicting third-party evidence.

    Audit how AI systems represent your brand
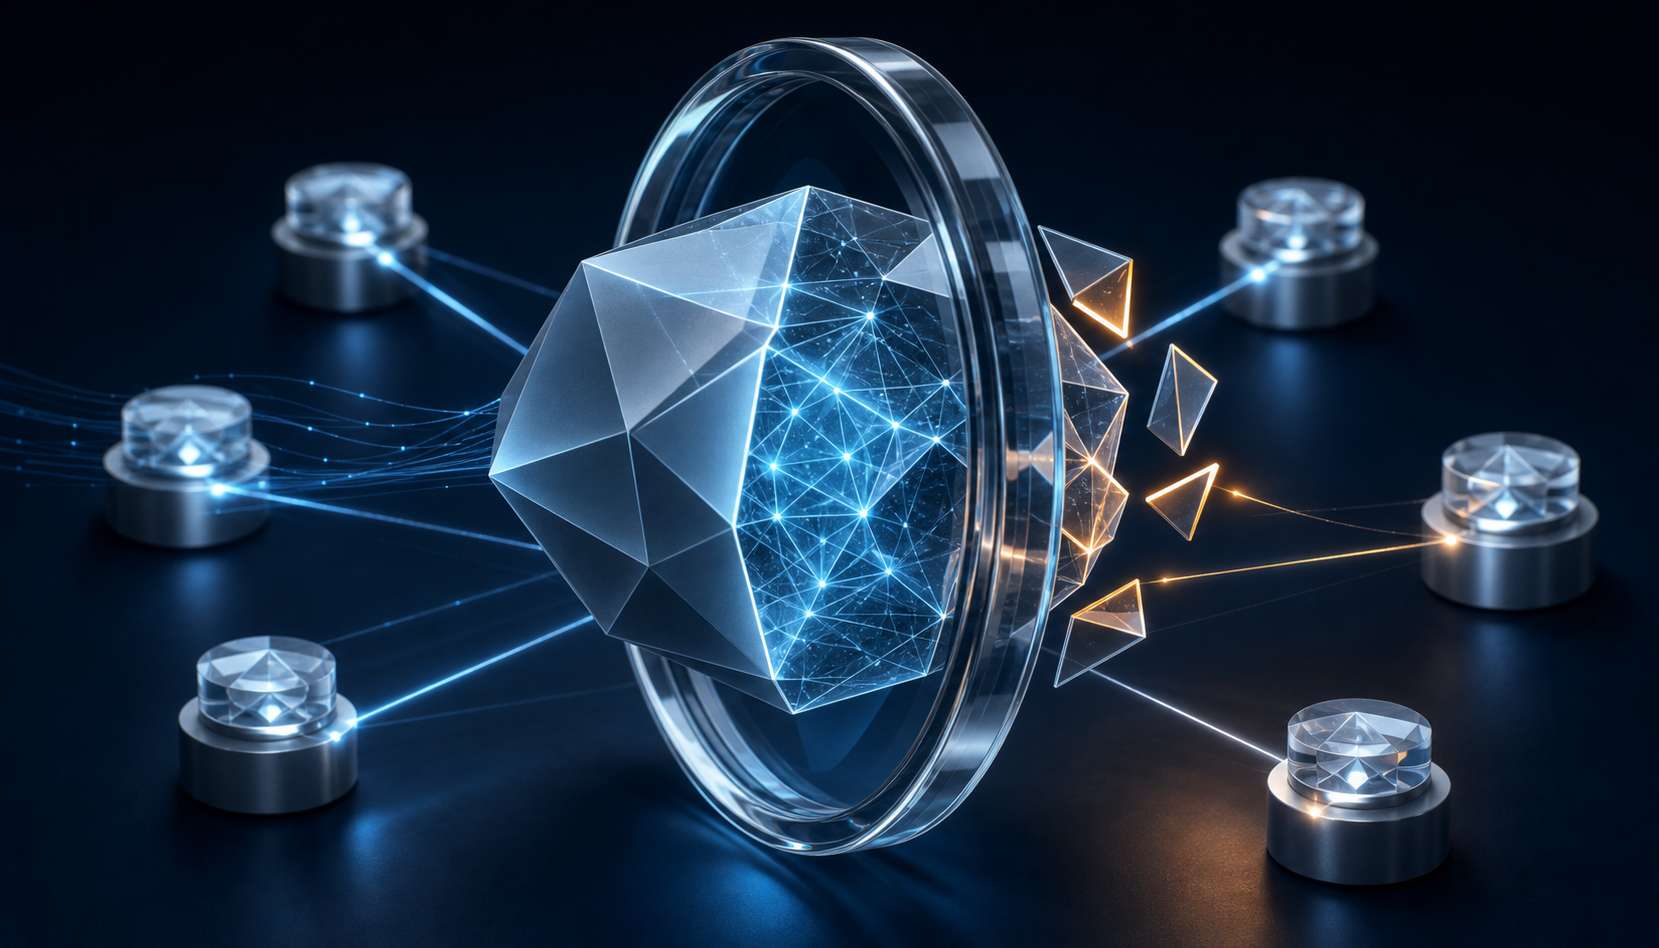
    A transparent inspection lens examines a faceted identity object connected to several source nodes, revealing aligned and misplaced fragments.

    Rank tracking tells you where a page appears in a conventional result set. It does not tell you whether an AI answer omitted the brand, described it incorrectly, relied on an outdated source, or used your expertise without clear attribution. You need an answer-level audit alongside your SEO reporting.

    Start with a stable set of prompts based on real audience decisions. Include prompts from several intent types:

    • Category discovery: “Which companies help [audience] solve [problem]?”
    • Source discovery: “Who are credible sources on [topic]?”
    • Branded understanding: “What does [brand] do, and who is it for?”
    • Expertise association: “What is [brand] known for in [field]?”
    • Evaluation: “What should a buyer consider when choosing a provider for [task]?”
    • Problem solving: “How should [audience] approach [specific problem]?”

    Use the AI systems your customers are likely to use. Keep the prompt wording fixed when you compare results, and repeat checks because generated responses can vary. Capture the complete answer and its citations rather than recording only whether the brand appeared.

    For each result, record:

    • The prompt and the intent it represents.
    • Whether the brand appears.
    • How prominently and in what role it appears: source, example, option, recommendation, or passing mention.
    • Whether the description is factually accurate.
    • Whether important qualifications are preserved.
    • Whether your site is cited.
    • Which third-party pages are cited or appear to support the response.
    • Which competing entities are included.
    • Any unsupported, outdated, or reputation-sensitive claim requiring correction.

    Do not collapse all of this into one opaque visibility score. A compact dashboard can report several separate measures: inclusion across the prompt set, accurate descriptions, citation presence, independent corroboration, and unresolved errors. The detail matters because each pattern implies a different action.

    • Omitted from unbranded prompts: Review topic focus and relevant outside corroboration. Your brand may be identifiable but not strongly associated with the category.
    • Included but described incorrectly: Compare the answer with your brand brief. Find conflicting pages, profiles, markup, or third-party descriptions and correct the most authoritative origin you can reach.
    • Mentioned without supporting citations: Strengthen the canonical evidence page and earn references to that specific evidence.
    • Your page is cited but the brand is not named: Make attribution clearer where it is editorially relevant. Check page titles, authorship, publisher information, and the wording around the cited passage.
    • Accurate for branded prompts but absent from category prompts: Invest in independent category association rather than adding more navigational brand copy.
    • Negative or outdated context dominates: Treat it as a reputation and record-correction problem, not merely an on-page optimization problem.

    This diagnosis is directional, not proof of a hidden cause. AI systems may draw on different material and produce different outputs. Use repeated patterns to prioritize work, then check whether the representation changes after the underlying evidence changes.

    Make authority an operating system, not a campaign

    Brand authority decays when it belongs to one launch or one department. Products change, experts move, pages are rewritten, profiles drift, and third parties keep old descriptions alive. The repair is a lightweight operating process that joins content, technical SEO, communications, subject experts, and reputation monitoring.

    1. Choose an authority territory. Define the audience, problem, and subject for which the brand has credible evidence. Narrow positioning is easier to support than a claim to lead every adjacent topic.
    2. Approve the canonical record. Maintain the brand brief, expert information, official profiles, and claim ledger.
    3. Publish primary evidence. Give priority questions clear answers, visible ownership, sensible qualifications, and supporting material.
    4. Align machine-readable information. Make structured data reflect the visible record and the real relationships among the brand, publisher, experts, and content.
    5. Earn relevant corroboration. Build relationships and reference-worthy resources around specific claims instead of pursuing disconnected link volume.
    6. Audit generated answers. Track presence, representation, authority, citations, and errors across a stable prompt set.
    7. Repair the evidence chain. Assign each omission or error to the page, profile, markup, third-party record, or reputation issue most likely to be responsible.

    Assign an owner to every recurring part of this process. Editorial teams can maintain primary answers. Subject experts can verify claims. Technical teams can keep structured data aligned. Communications teams can pursue and correct outside references. Whoever monitors AI answers should route each finding to the owner who can repair the underlying evidence.

    Clicks still matter, but they are no longer a complete measure of influence. As AI agents perform more browsing and task execution directly, a brand can enter or leave consideration before a person visits its website. Track qualified traffic and conversions, but also track whether machines identify the brand accurately, associate it with the right problems, and support that representation with credible evidence.

    Start with the commercially important topic where omission would hurt most. Write the authority claim you want to support, locate its primary evidence page, identify the strongest independent corroboration, and run the relevant prompts. Any empty or contradictory field in that chain is your next task.
    References

  • How SMBs Should Rebalance Traffic Across Social, SEO and AI

    How SMBs Should Rebalance Traffic Across Social, SEO and AI

    If social now sends more visitors while Google sends fewer, the wrong reaction is to replace your SEO plan with a larger social calendar. The useful move is to redesign acquisition so social creates demand, search captures intent, AI systems can understand the business, and your website turns attention into action.

    For an SMB, this is mainly an ownership and measurement problem. You need to know which channel starts the journey, which page advances it, and whether your business appears when an AI answer creates a shortlist. Once those roles are visible, you can reallocate effort without betting the business on whichever channel happens to be growing fastest.

    Key takeaways

    • A leading traffic source is not automatically the most profitable source. Compare qualified leads and sales, not visits alone.
    • Social, organic search and AI discovery should have different jobs within the same acquisition system.
    • Even when social platforms or marketplaces generate enough leads, an owned website gives every channel a stable destination and a consistent set of business facts.
    • Strengthen the homepage, product or service pages, and contact page before expanding into a large content program.
    • Track AI referral clicks separately from AI mentions. A business can gain or lose visibility without producing a measurable visit.
    • Put the next increment of time or budget into the constraint that is limiting acquisition, not automatically into the channel reporting the most traffic.

    Read the shift as a portfolio signal, not an SEO obituary

    Among more than 300 U.S. small businesses across 24 industries, 64% listed social media as a leading traffic driver, compared with 52% for organic search. About 40% reported losing Google traffic amid algorithm updates and AI-driven search changes. Nearly half of the larger companies within the SMB sample reported a decline.

    That is a meaningful change in the acquisition mix, but it does not establish that social traffic is cheaper, more qualified or more likely to convert. The percentages describe what businesses reported as traffic drivers. They do not measure profit per channel, customer lifetime value or the role one channel played before another received credit.

    The SEO-is-dead interpretation also clashes with the same businesses’ experience: 72% still considered their SEO efforts effective. Search can remain commercially useful while its share of total traffic falls. A service page that attracts fewer but highly qualified visitors may be worth more than a social post that produces a large burst of low-intent sessions.

    The sample ranged from sole proprietors to companies with as many as 100 employees. That range matters. A solo operator selling through social messages has a different acquisition system from a larger SMB with multiple services, sales staff and a mature website. Use the broader numbers to identify what deserves inspection, then let your own conversions determine where money moves.

    There are two expensive overreactions to avoid. The first is protecting every historical SEO activity merely because it used to work. The second is moving most acquisition resources into social because it now leads an aggregate traffic ranking. Either choice can preserve a weak tactic while ignoring the actual constraint in your funnel.

    Keep a baseline for every channel that is still producing qualified demand. Make larger budget changes in reversible increments, and evaluate them against leads, orders and sales quality. Moving too much on the basis of one traffic statistic can cut off a high-intent source before you understand its contribution.

    Give social, search and AI different acquisition jobs

    Three illustrated pathways show social conversation creating interest, search guiding intent and an AI network forming a business shortlist.

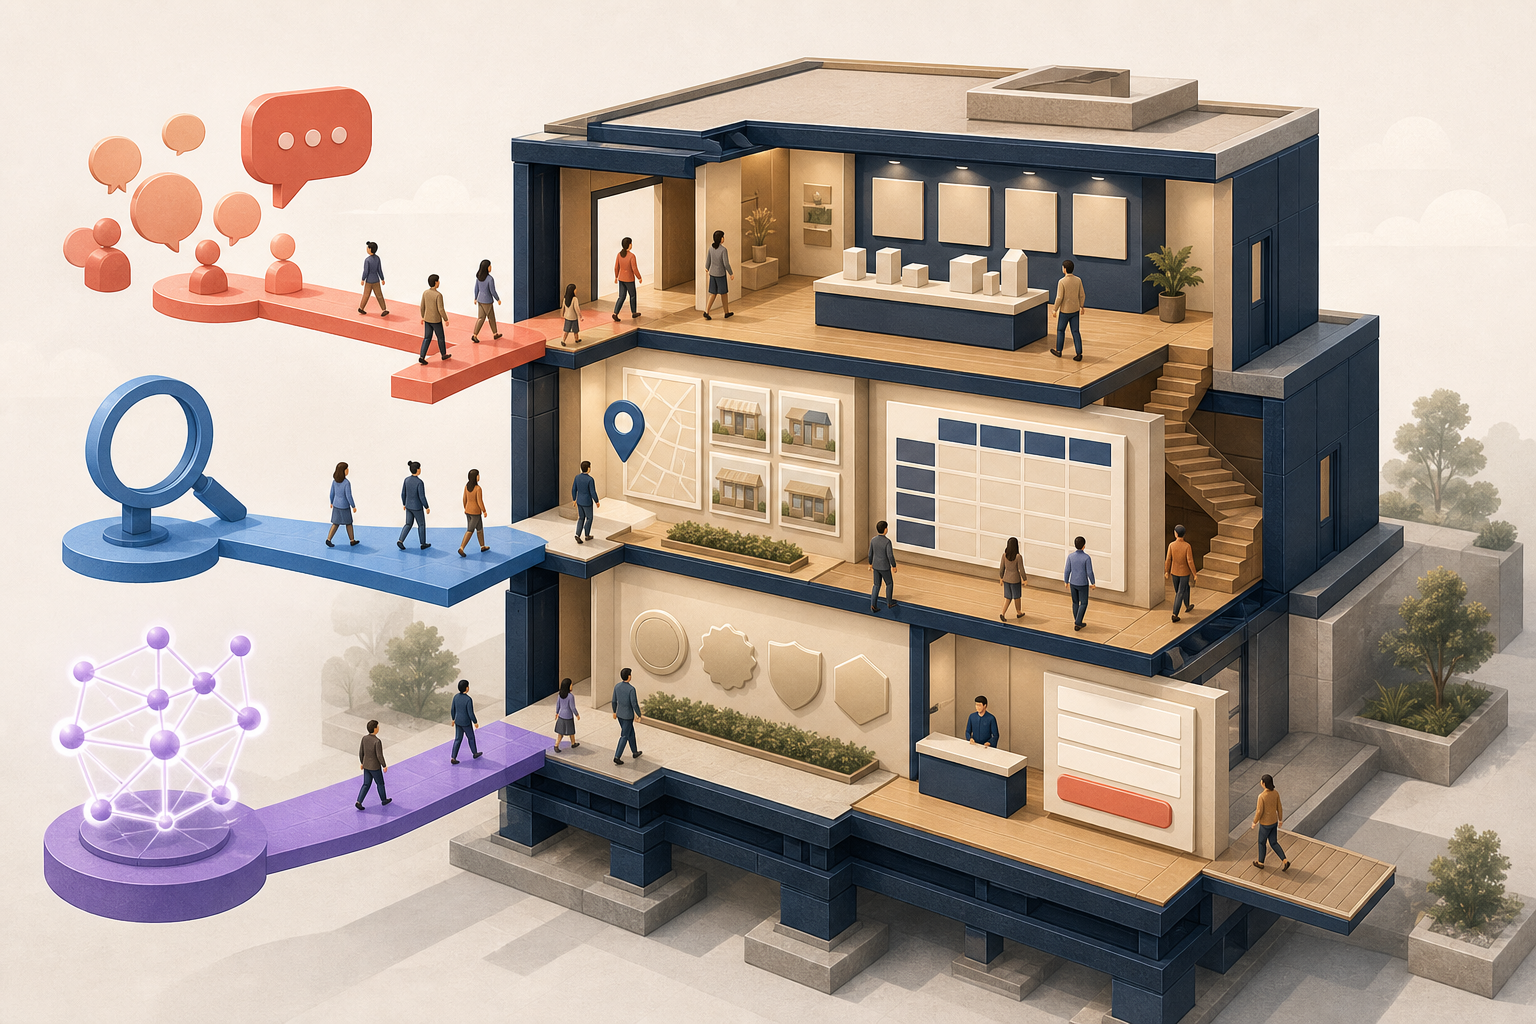
    A channel strategy becomes easier to manage when every surface has a primary job. Social media is well suited to discovery, timely distribution and visible proof that a business is active. Organic search meets people who have expressed a need through a query. AI answers can place a brand into an early shortlist, sometimes before the buyer visits any site. Your owned pages establish the facts and provide the route to an enquiry or purchase.

    SurfacePrimary acquisition jobEvidence to inspectBest handoff
    Social mediaCreate discovery, demonstrate relevance and distribute useful materialTagged visits, qualified enquiries, assisted conversions and the landing pages visitors chooseThe page that directly continues the promise made in the social content
    Organic searchCapture explicit demand and answer high-intent questionsConversions by landing page, changes in qualified visits and performance by intent groupA complete product, service or decision page rather than a generic homepage
    AI answersPlace the business in the consideration set and communicate verifiable factsReferral sessions where a referrer is available, recurring brand mentions and competitor inclusionThe strongest page supporting the exact claim, offer or recommendation
    Owned websiteConfirm the business, reduce uncertainty and convert demandCompleted lead or purchase actions, abandonment points and the path between core pagesA clear contact, booking, enquiry or checkout action

    This division prevents a common attribution mistake. A social interaction can introduce the business, an organic result can bring the person back, and the website can receive credit for the eventual conversion. AI visibility can influence the same journey without generating a click that appears in analytics. Judging each surface only by last-click sessions hides much of that sequence.

    Some businesses can operate without an owned site: 35% of businesses without websites said social channels and marketplaces generated enough leads. That can be a valid distribution choice, especially for a small operator. It is not the same as owning the customer path.

    A platform can change reach, account access, page formats or reporting without preserving your preferred customer journey. An owned site gives social visitors a stable destination, gives search engines durable pages to index, and gives AI systems a consistent place to verify what the business does. If social or a marketplace already works, keep it. Add the smallest useful owned layer instead of replacing a functioning channel.

    That smallest layer does not need to begin as a large blog. Start with a homepage, one strong page for each important product or service, and a contact or conversion page. Those pages can support all three discovery channels while keeping maintenance realistic for a small team.

    Build the owned pages every channel can hand off to

    Cutaway illustration of a modular business website receiving visitors from social, search and AI routes and guiding them through service, proof and contact areas.

    Among businesses monitoring AI-driven traffic, 57% treated the homepage as important, 48% prioritized product or service pages, and 34% emphasized contact pages. These figures reflect business priorities, not a rule that AI systems always prefer one page type or that the homepage receives 57% of AI referrals.

    The practical lesson is that AI optimization begins close to revenue. If an assistant, search result or social post introduces your business, the next page must resolve the buyer’s immediate uncertainty. A large volume of informational content cannot compensate for a vague offer, contradictory business details or a contact path that fails on mobile.

    Make the homepage an unambiguous identity page

    • State what the business provides, who it serves and where it operates near the beginning of the page.
    • Use one consistent business name and keep core facts aligned with the rest of the site and legitimate third-party profiles.
    • Replace broad claims with specific, supportable descriptions of the offer.
    • Link directly to the most important product or service pages instead of making visitors decode a general navigation label.
    • Include a clear next action and place essential information in readable page text, not only inside images or interactive elements.

    The homepage should make the business identifiable even when a system extracts only a few sentences. That does not mean writing robotic copy. It means using complete statements, descriptive headings and consistent facts so a person or machine does not have to infer the basic proposition.

    Turn product and service pages into decision pages

    • Give each important offering a page with a descriptive title rather than grouping unrelated services beneath a generic label.
    • Explain the audience, the problem addressed, what is included, material limitations and the next step.
    • Use headings that match the questions a serious buyer asks while deciding.
    • Keep the answer immediately below its heading and make it understandable without reading the entire page.
    • Support credentials, outcomes and differentiators with evidence you can substantiate.
    • Match the page language to the social post, search intent or AI claim sending the visitor there.

    A mismatch at this handoff is easy to misdiagnose as a traffic problem. If a social post promotes one service but sends visitors to a homepage covering several unrelated offers, more reach may only produce more confusion. The closest relevant commercial page should continue the same promise and vocabulary.

    Treat the contact page as part of acquisition

    • State exactly what the visitor should do and what information the business needs to respond.
    • Provide appropriate contact routes and keep operating area, availability or location details current when they affect eligibility.
    • Test the entire action on a mobile device, including forms, buttons and confirmation messages.
    • Remove fields that do not help qualify or complete the enquiry.
    • Do not publish a response promise unless the business can reliably meet it.

    Contact pages receive less attention than homepages, but they sit closer to the outcome you are trying to acquire. A broken form or unclear service area can make social, SEO and AI traffic appear unproductive even when discovery is working.

    Add machine-readable clarity and outside corroboration

    The most common AI-visibility adaptations were clear, descriptive headlines at 35%, improved readability at 26%, and technical improvements such as speed and mobile performance at 24%. Larger SMBs more often pursued external brand mentions at 33% and structured data at 30%.

    Those percentages are adoption rates, not measured performance lifts. They still point to a sensible implementation order because the first changes help human visitors, search engines and AI systems at the same time: make the page’s purpose explicit, make the answer easy to read, and make the page work reliably.

    Structured data comes after the visible facts are sound. If you use JSON-LD, treat it as a machine-readable restatement of the page, not a hidden place to introduce stronger marketing claims. Keep names, URLs, contact details and offering information consistent. Remove stale values, complete only fields you can support, and validate the markup after material page changes.

    External brand mentions serve a different purpose. They give discovery systems evidence that does not come from the business itself. Pursue accurate mentions on legitimate third-party pages that customers already use, such as relevant organizations, partners, publishers or business profiles. Bulk placements with inconsistent details create noise rather than credible corroboration.

    This work can create openings for smaller businesses because AI summaries can draw on material beyond the conventional top Google results. A business does not necessarily need to outrank every competitor for every query before it can become part of an AI-generated answer. It does need clear claims and enough reliable web evidence for those claims to be understood and checked.

    Measure two kinds of AI visibility, then fund the bottleneck

    AI is not yet the leading traffic source for most SMBs, but it is already entering measurement plans. Half of SMBs monitored AI referrals or mentions, rising to 70% among larger SMBs. Combining referrals and mentions into one metric, however, makes the result hard to interpret.

    Separate referral traffic from answer visibility

    An AI referral is a visit that can be associated with an AI service when the referring information is available. An AI mention is an appearance inside an answer, recommendation or summary. A mention may influence the buyer without producing a visit. A referral proves that someone clicked, but it does not prove that the preceding description was favorable or accurate.

    1. Define the outcome first. Decide which completed actions count as qualified enquiries, purchases, bookings or other meaningful conversions.
    2. Normalize the links you control. Tag social profile and campaign links consistently so intentional social traffic does not disappear into ambiguous reporting.
    3. Report by landing page as well as channel. This exposes whether discovery changed or whether a specific commercial page stopped converting.
    4. Maintain a fixed AI query set. Include branded questions, category or location questions, customer problems and comparison-oriented prompts that reflect real buying decisions.
    5. Record both presence and treatment. Note whether the business appears, which page or third-party evidence is referenced when visible, which competitors appear, and whether material facts are correct.
    6. Keep a change log. Record page rewrites, structured data updates and significant new mentions so later movement can be assessed without assuming that one change caused it.

    A stable query set is more useful than collecting isolated screenshots. It lets you notice repeated exclusion, incorrect descriptions and competitor patterns. It also prevents one favorable answer from being mistaken for broad visibility.

    Move the next unit of effort to the constraint

    What you observeLikely constraint to investigateBest next move
    Social engagement is healthy, but few visitors become qualified leadsThe post-to-page handoff or on-site conversion pathSend traffic to the closest relevant offer page, match its language to the social promise, and remove unnecessary steps before purchasing more reach
    Commercial pages convert qualified visitors, but organic discovery has fallenSearch visibility or technical access rather than the offer itselfProtect the converting pages, improve their clarity and mobile performance, and strengthen relevant supporting content instead of replacing them with generic volume
    Competitors repeatedly appear in AI answers while your business does notUnclear business facts, weak supporting pages or insufficient third-party corroborationClarify the entity and offer, align JSON-LD with visible content, earn accurate external mentions, and recheck the same query set
    Social platforms or marketplaces produce leads, but the business has no siteOwnership and verification rather than immediate lead volumeKeep the working channel and publish a minimal owned spine consisting of a homepage, offer pages and a contact path
    Total traffic looks stable, but enquiries or sales quality has weakenedThe offer, qualification or conversion experienceInspect landing-page intent, calls to action and lead quality before shifting acquisition budget
    AI referrals rise, but the relevant landing pages do not advance visitorsThe AI-to-page handoffIdentify the claims or questions that generated the visits, then make the destination page answer them directly

    This bottleneck rule is more dependable than declaring a permanent winner among social, search and AI. If discovery is strong and conversion is weak, buying more discovery magnifies waste. If pages convert but qualified discovery is shrinking, conversion redesign alone will not restore demand. If competitors dominate AI answers, ordinary traffic reports may not reveal the visibility gap at all.

    Begin with one high-value customer route: a social post to a service page, a search result to a contact page, or an AI mention to the homepage. Measure the route end to end, correct the point where it breaks, and then move to the next constraint. The traffic landscape can continue shifting without forcing you to rebuild your acquisition strategy every time a channel changes position.

    References

  • How to Build an AI-Driven SEO Visibility Reporting System

    How to Build an AI-Driven SEO Visibility Reporting System

    You can have healthy rankings and still be unable to answer a basic leadership question: Are AI answer engines finding, trusting, and naming our brand? A conventional SEO dashboard cannot answer that on its own. It records search exposure and site visits, while AI visibility may occur inside a synthesized answer, through a third-party citation, or without a click.

    The fix is not another disconnected dashboard. You need a reporting system that connects search performance, AI answer visibility, the evidence supporting that visibility, and the business decision that follows. Here is how to build that system without letting an AI model become the judge of its own work.

    Design the scorecard around the decision it must support

    Start by writing a report brief before choosing metrics. If a metric cannot change an action, it belongs in a diagnostic view rather than the executive scorecard.

    • Decision: State what could change because of the report, such as which topic receives content work, digital PR, technical attention, or distribution.
    • Scope: Name the market, language, device, site section, topic, audience, and search or AI surface covered.
    • Evidence: Define which observations count. A ranking, a brand mention, a linked citation, and a qualified conversion are different events.
    • Trigger: Describe the condition that warrants action. Avoid vague rules such as improving visibility.
    • Owner: Assign the person or team that can act on each finding. A report without an owner is an archive.

    The scorecard should preserve four measurement layers. Keeping them separate prevents a familiar reporting error: treating exposure as traffic, traffic as trust, or a brand mention as revenue.

    Measurement layerWhat to recordQuestion it answersTypical action
    Search performanceClicks, impressions, average CTR, average position, query, page, country, device, search appearance, and date contextCan people discover and choose the site in search results?Investigate query demand, page relevance, result presentation, or technical access
    AI answer visibilityExact prompt, platform, model or visible version, date checked, brand inclusion, citation inclusion, cited URL, and answer contextDoes an AI response use, name, cite, or accurately represent the brand?Improve the answer asset, entity clarity, evidence, or external reinforcement
    Evidence footprintOwned pages, structured data, independent coverage, community discussion, and paid distribution connected to the topicWhat evidence could support discovery and inclusion?Fill a specific owned, earned, shared, or distribution gap
    Business effectQualified visits, conversions, leads, assisted outcomes, or another agreed business resultDid the visibility contribute to something the organization values?Continue, change, or stop the work based on business relevance

    Do not collapse these layers into a single AI visibility score too early. A page can be cited without the brand being named. A brand can be mentioned without a link. A response can name the brand inaccurately. Each outcome calls for a different intervention, so the underlying observations must remain available even if leadership receives a summarized score.

    Build a visibility ledger across paid, earned, shared, and owned media

    Four abstract paid, earned, shared, and owned media channels feed colored evidence tokens into a single central ledger.

    AI visibility does not respect the boundaries in your marketing org chart. Generative systems can draw contextual cues from brand sites, independent coverage, forums, and other public material. The paid, earned, shared, and owned media model gives you a practical way to map those cues without pretending every channel affects an AI answer in the same way.

    • Owned media supplies the answer asset you control. Record the canonical page, the question it answers, the named entities it defines, the supporting evidence it contains, and any relevant structured data. Schema can make meaning more explicit, but it does not guarantee inclusion in an AI response.
    • Earned media supplies independent corroboration. Record who mentioned the brand, which claim or capability the mention supports, the destination URL if one exists, and whether the context is current and relevant.
    • Shared media reveals how a topic is discussed in public communities. Record the recurring question, language people use, misconceptions, and whether the brand appears naturally in the discussion.
    • Paid media can distribute useful material and expose it to an audience, but that effect is indirect. An ad impression is not an AI citation and should never be reported as one.

    Fields that make the ledger diagnosable

    Create a row for each priority topic and audience question. Give every row enough context that another analyst could reproduce the observation without guessing.

    • Topic, audience, market, language, and customer question
    • Exact search query or AI prompt used for observation
    • Canonical owned page and the intended answer section
    • Relevant entity names, products, services, and approved descriptions
    • Supporting claims and where their evidence appears
    • Earned mentions, citing domains, and linked URLs
    • Shared discussions and the questions or terminology they reveal
    • Paid distribution connected to the asset, kept separate from visibility outcomes
    • AI platform, model or visible version, observation date, and response context
    • Brand named: yes or no
    • Brand cited or linked: yes or no, with the exact URL when present
    • Representation: accurate, incomplete, misleading, or unrelated
    • Next action, owner, and the condition for checking again

    Interpret mentions and citations as separate signals

    Brand namedBrand page citedWhat you observedWhat to inspect next
    YesYesThe response visibly associates the brand with a traceable brand-controlled resourceCheck whether the description is accurate, relevant, and supported by the cited page
    YesNoThe brand is included, but the response does not expose a brand-controlled citationInspect third-party citations, mention context, and whether an owned answer asset is clear enough
    NoYesBrand content may inform the answer without prominent brand attribution in the wordingCheck titles, publisher identity, entity naming, and the cited section
    NoNoThe brand was absent from this recorded responseCompare relevant cited domains, content coverage, corroboration, and the exact prompt context

    An absence is an observation, not a universal verdict. Preserve the exact prompt, platform, model context, date, and response. When any of those change, you are no longer running the same check. This is why an undocumented screenshot is weak reporting evidence: it cannot tell you whether visibility changed or the test changed.

    Use Search Console AI configuration as an analyst, not an oracle

    Google has been testing an experimental Search Console feature that converts a plain-language request into settings for the Search results Performance report. It can select metrics such as clicks, impressions, average CTR, and average position, then apply filters or comparisons involving queries, pages, countries, devices, search appearance, and dates. Availability is limited during the experimental rollout, so your reporting process should still work when the interface is configured manually.

    Write requests that expose the intended configuration

    A useful configuration request names the metrics, scope, segment, period, comparison, and report surface. Use this pattern:

    Show [metrics] for [query or page scope], filtered by [country, device, or search appearance], during [period], compared with [baseline period or segment].

    For example, you could request these views:

    • Show clicks, impressions, average CTR, and average position for queries containing the named product category, comparing mobile and desktop.
    • Compare clicks and impressions for a specified site directory across the chosen periods, filtered to the target country.
    • Show query performance for a named landing page during the selected period, then compare it with the relevant baseline.

    The language can be natural, but the analytical intent cannot be fuzzy. A request to show pages losing visibility leaves important questions unanswered: Which metric defines visibility? Against which period? In which country and device context? For all pages or a specific section? Resolve those choices before asking AI to configure anything.

    Validate the generated view before reading the trend

    • Confirm that the selected metrics match the question. Impressions, clicks, CTR, and position describe different parts of search performance.
    • Read every query and page filter literally. Check whether the configuration includes, excludes, contains, or exactly matches the intended value.
    • Confirm country, device, search appearance, and date settings rather than assuming the prompt was interpreted correctly.
    • Check that comparison periods or segments are appropriate for the decision. A valid interface configuration can still represent a weak comparison.
    • Record the final settings with the finding. The reproducible filter state is part of the evidence.
    • For a consequential decision, recreate the important view manually or have another analyst verify the configuration.

    The experimental capability is limited to configuration in the Search results Performance report. It does not sort tables or export the data, and it is not available for Discover or News reports. Most importantly, a configured view is not a diagnosis. The interface may help you reach the right slice of data faster, but you still have to determine what the slice means.

    Make the workflow resilient to model changes

    Interchangeable translucent AI modules connect to a stable workflow while a robotic mechanism replaces one module without interrupting the glowing data flow.

    A newer model should be treated as a changed dependency, not an automatic quality upgrade. In one SEO benchmark, Claude Opus 4.5, Gemini 3 Pro, and ChatGPT-5.1 Thinking produced a reported 9% decline in SEO accuracy. That result comes from a particular benchmark rather than a universal test of every SEO task, but it is enough to challenge the assumption that a model switch can be made without validation.

    The durable unit is the workflow, not the prompt. A standalone instruction such as analyze our SEO performance forces the model to invent definitions, choose evidence, infer priorities, and format the result at once. Split those responsibilities into controlled stages.

    1. Fix the context. Store the organization, site, canonical entity names, products, markets, languages, audiences, business goals, exclusions, and metric definitions outside the ad hoc prompt.
    2. Validate the input. Define required fields, accepted values, date context, missing-value treatment, and the origin of each data field before analysis begins.
    3. Constrain the task. Ask the model to configure a report, classify an observation, compare defined fields, or draft an explanation. Do not combine every task into an open-ended request.
    4. Keep calculations controlled. Let the reporting system produce totals, rates, and comparisons, then give those results to the model for explanation. Do not ask the model to reconstruct critical metrics from loosely pasted fragments.
    5. Require a structured output. Separate observation, supporting evidence, interpretation, proposed action, confidence, and unresolved questions.
    6. Add a human review gate. An analyst should approve filters, factual claims, citations, causal interpretations, and recommendations before the report is distributed.
    7. Regression-test changes. Re-run a stable collection of known SEO cases when the model, prompt, context block, tool, or output schema changes. Compare the kinds of errors, not merely how polished the prose sounds.

    Version the context block, prompt, model, input schema, and output schema together. If the result changes, that record lets you identify whether the underlying market moved, the evidence changed, or the measurement machinery changed.

    Use confidence labels that reveal the reasoning boundary

    • Observed: Directly visible in the recorded search data or AI response.
    • Derived: Calculated from defined fields using a documented rule.
    • Inferred: A plausible explanation supported by observations but not proven by them.
    • Unverified: A claim that requires another check before it can guide action.

    This vocabulary stops fluent model output from quietly turning correlation into cause. Require every inferred explanation to point back to the observations supporting it, and allow the report to say that the cause is not yet known.

    Turn every reporting cycle into an operating decision

    The useful endpoint is not a chart. It is a documented decision with an owner and a condition for reassessment. Run the same operating loop each time so that changes in process do not masquerade as changes in performance.

    1. Freeze the measurement context. Save the prompt set, Search Console configuration, market and device scope, AI platform, model context, and observation date.
    2. Collect the layers separately. Record search performance, AI mentions, citations, answer accuracy, evidence footprint, and business effects without merging them prematurely.
    3. Compare like with like. Identify which layer moved while holding the relevant measurement context stable.
    4. Diagnose the gap. Use query and page segments for search changes, response records for AI changes, and the paid-earned-shared-owned ledger for evidence gaps.
    5. Choose the smallest action that tests the diagnosis. Name the page, claim, entity, citation gap, distribution task, or configuration that will change.
    6. Assign an owner and a reassessment condition. State what evidence would support, weaken, or disprove the working explanation.
    Search performanceAI visibilityWorking interpretationNext check
    WeakerWeakerA broader demand, access, relevance, competitive, or evidence problem may be affecting both layersSegment queries and pages, confirm technical access, and inspect which domains or resources now appear
    SteadyWeakerThe change may sit in the AI surface, recorded test context, cited evidence, or external brand footprint rather than conventional rankingsRe-run the fixed prompt set, compare model context, inspect citations, and review earned and shared evidence
    StrongerSteadySearch gains are not yet visible in the tracked AI answersInspect answer clarity, entity naming, supporting claims, structured data relevance, and independent corroboration
    SteadyStrongerThe brand is gaining answer visibility without a corresponding search liftSeparate linked citations from unlinked mentions, verify representation, and check business effects before declaring success
    StrongerStrongerVisibility improved across both discovery paths, but attribution still needs evidenceIdentify which content, technical, earned, shared, or distribution changes preceded the movement and test the explanation

    Key takeaways

    • Measure search performance, AI answer visibility, evidence, and business effects as connected but distinct layers.
    • Keep brand mentions, links, citations, accuracy, and conversions separate in the underlying data.
    • Use paid, earned, shared, and owned media to diagnose why evidence is strong or weak around a topic.
    • Inspect every AI-generated Search Console filter before interpreting the resulting trend.
    • Version prompts, context, schemas, models, and test conditions so reporting changes remain explainable.
    • Treat AI observations as reproducible records and causal explanations as hypotheses that require validation.

    Start the next reporting cycle with a priority topic, a fixed prompt set, a reproducible Search Console view, and a visibility-ledger row. Follow the evidence until you can assign a specific action. Once that loop works reliably, expand it across more topics instead of scaling an unverified score.

    References

  • Google AI Search Personalization: What SEO Teams Should Do

    Google AI Search Personalization: What SEO Teams Should Do

    You may be looking at Google AI Mode and asking a deceptively simple question: if Google can change the interface and tailor the experience to each person, what does ranking even mean? You still need visibility, but a position checked once from one browser is no longer a reliable description of it.

    The workable goal is to make your brand easy to retrieve, understand, compare and trust across different search journeys. That requires a wider testing method, clearer entity information and a sharper distinction between queries that can end with an AI answer and queries that still lead people to evaluate websites.

    Google is changing the entrance to search

    A traditional SEO test begins with a typed query and a results page. That model no longer covers every important entrance into Google Search.

    Uploading a file or image from Google’s homepage can take the user directly into AI Mode instead of a conventional Google Lens results flow. AI Mode has also appeared in the Chrome omnibox, while its tab has received prominent placement in the search interface.

    Those placements do not prove that AI Mode will become the universal default. They do establish a practical problem for SEO teams: the same underlying need can now begin with a keyword, an uploaded object, an image, a document or a conversational follow-up. The interface determines what context the user supplies before Google generates anything.

    Start auditing journeys rather than keywords alone. For each priority need, record:

    • The entrance used: conventional Search, AI Mode, Chrome or an upload flow.
    • The input type: text, image, file or a follow-up inside an existing conversation.
    • The user’s real task: learning, comparing options, choosing a provider or completing an action.
    • Whether the response names your brand, cites your page, offers a link or presents a competing option.
    • What additional evidence a person must obtain before making the decision.

    This prevents a common measurement error. If you test only typed queries in conventional Search, you are measuring one interface rather than your total Google visibility.

    Personalization makes the search session the useful unit

    A person follows a ribbon of connected search steps while two alternate search journeys branch through different interface panels in the background.

    Personalization is not merely a rewritten ranking order. It can affect what appears, when it appears and which part of a broader topic Google considers relevant to the person at that moment.

    Google’s Daily Hub work illustrates the direction. Its design combined full content records containing structured text, Knowledge Graph entity identifiers, embeddings and technical metadata with smaller records for individual entities. Separate personalization systems refined user interests, while an ambient ranking layer considered relevance and timing when choosing what to display. Features such as Preferred Sources and followable profiles in Discover also give people ways to shape what reaches them.

    Daily Hub was paused after its technical complexity became difficult to manage. Its architecture should therefore be treated as evidence of Google’s broader direction, not as a published specification for how every AI Mode result is ranked.

    The distinction matters. You cannot reverse-engineer a universal personalized rank from one experimental system. You can, however, prepare content for the recurring jobs such systems must perform:

    • Identify the entity. Google must be able to distinguish your organization, product, service, person or location from similarly named entities.
    • Connect the entity to the topic. A name alone is weak evidence. Your visible content should explain what the entity does, who it serves and how it relates to the user’s task.
    • Retrieve the right content unit. A focused page with explicit facts is easier to interpret than a broad page that mixes unrelated intentions.
    • Judge contextual relevance. Time-sensitive information needs a visible date or status and must be corrected when it becomes stale.
    • Support a next step. When the user is choosing rather than merely learning, the page must provide evidence and a clear path to act.

    This is where JSON-LD helps, but its role needs to be stated accurately. Structured data can express the entities and relationships already present on the page in a consistent, machine-readable form. It cannot force Google to select the page, override weak content or guarantee the same answer for every person.

    Keep names, URLs, entity types, locations and relationships consistent between visible copy, structured data and important external profiles. If your Organization markup identifies one name while your service pages and business profiles use several unexplained variants, you are creating ambiguity at the exact layer personalized retrieval depends on.

    Transactional searches still create a consideration set

    AI-generated answers can satisfy some informational searches without a website visit. That does not mean every AI search journey ends inside Google, especially when the user must choose a high-commitment service.

    In a UX test involving 52 participants across the United States and Canada and nearly 22 hours of transactional searching, 69% of AI Mode sessions produced a website visit. Only 27% of participants felt ready to decide from the AI summary alone, while 4% moved to traditional Google Search and social media for more information.

    Those figures come from one bounded test of high-commitment services such as doctors and dentists. They should not be treated as a universal AI Mode click-through benchmark. They support a narrower and more useful conclusion: people still seek first-party evidence when the decision carries enough consequence.

    The competitive pattern also changed. In the same test, 89% of participants opened multiple businesses, the average was 3.7 results per session and only 10% considered a single business. AI Mode behaved less like a winner-takes-all ranking and more like a generated shortlist.

    That changes what you should optimize for. Being included among three to five credible options can matter more than treating the first visible mention as the only win. Your landing page then has to survive an active comparison against the other businesses Google presented.

    Do not assume that only content visible at the top of the AI response will be considered. Some 84% of participants scrolled. Once users interpreted the response as a curated set of options, they explored it.

    Social proof deserves particular attention for local services. Reviews were read by 74% of participants, while only 21% examined Google Business Profile photos. Even for Botox searches, photo use rose only to 24%. This does not make images unimportant in every market. It means that, within these service-selection tasks, written experiences helped more users reduce uncertainty.

    For a local or high-consideration business, work through the decision path in this order:

    1. Earn shortlist eligibility. Make the service, location, audience and relevant entity relationships unmistakable across the site and business profile.
    2. Strengthen legitimate social proof. Build a consistent process for requesting honest reviews, monitoring recurring concerns and responding appropriately. Do not manufacture reviews or use markup to imply evidence that users cannot see.
    3. Answer comparison questions on the landing page. State the scope of the service, qualifications, process, constraints and next step in language a prospective customer can verify.
    4. Inspect the whole AI response. Capture what appears below the first screen as well as what appears above it.
    5. Separate informational exposure from transactional opportunity. A summary that satisfies a how-to query and a shortlist that helps someone choose a provider create different traffic expectations.

    Build a playbook for content, entities and measurement

    A strategy team works around a tabletop of connected content cards, entity nodes, trust markers, test screens, and measurement gauges.

    Create content for both retrieval and verification

    An AI answer can mention you before the user visits you. That makes the first-party page a verification layer as well as a ranking asset. It must confirm the claim that brought the visitor there and supply the evidence the generated summary could not fully contain.

    Apply the following checks to each priority topic:

    • Give the page one primary job. Separate a direct explanation from a service-selection page when combining them would obscure both intentions. Link them so the user can move from learning to deciding.
    • Name the subject explicitly. Pronouns, slogans and clever headings are poor substitutes for the actual entity, service and location.
    • Put decisive facts in visible text. JSON-LD should reinforce those facts, not act as a hidden replacement for them.
    • Explain relationships. If a practitioner belongs to a clinic, a product belongs to a brand or a local branch belongs to a parent organization, represent that relationship consistently in copy, links and appropriate schema properties.
    • Preserve context around media. Because a search can begin with an image or file, use useful titles, captions, surrounding explanations and accessible alternative text that connect the asset to a named topic and next step.
    • Maintain status-sensitive details. Remove or correct expired availability, old policies and superseded claims so an ambient system does not retrieve information that no longer applies.

    Replace the single rank check with a repeatable scorecard

    Your measurement unit should be a task, surface and context combination. A broad prompt in AI Mode, a local transactional query and an image-led search should not be collapsed into one average position.

    SignalWhat to recordDecision it supports
    EntranceSearch, AI Mode, Chrome or upload flowWhich interfaces require separate testing
    IntentInformational or transactional taskWhether answer completion or a website visit is the realistic outcome
    Consideration-set presenceWhether your entity appears and which alternatives appear beside itWhere entity relevance or competitive proof is weak
    Evidence selectedClaims, pages, reviews or entity details surfaced by GoogleWhich information Google can retrieve and which evidence is missing
    Click opportunityWhether a usable link is shown and where it appears in the responseWhether visibility can produce a site visit
    Post-click outcomeLanding page reached and meaningful business action completedWhether AI visibility contributes to an actual result

    Use the same query wording, device conditions, location assumptions and account state when you want a controlled comparison. Then run a separate personalized observation when you want to understand variation. Mixing those two purposes makes every change look meaningful, even when the test conditions changed.

    Record the full response rather than only a headline position. Note follow-up prompts, cited pages, the order of businesses considered and the point at which a link becomes available. If personalized results vary, report the distribution of appearances across your observations instead of promoting one favorable screenshot as the result.

    Most importantly, do not average informational and transactional journeys into one AI visibility score. A citation inside an answer, inclusion in a provider shortlist, a qualified website visit and a completed conversion are different outcomes. Each should have its own field in your reporting.

    Key takeaways

    • Google AI visibility now depends on the entrance, input type, intent and context of the search session, not only a fixed results-page position.
    • Daily Hub points toward entity memory, user interests and timely orchestration, but its pause means it should not be treated as a live AI Mode ranking specification.
    • Transactional AI Mode users can still visit websites because a generated shortlist does not replace the evidence needed for a consequential decision.
    • For local services, consideration-set inclusion, credible reviews and a convincing landing page can matter more than obsessing over one first-place mention.
    • JSON-LD should clarify visible entities and relationships. It cannot guarantee selection, citations or personalized visibility.
    • Measure each task and interface separately, capture the complete response and connect AI exposure to post-click outcomes.

    Choose one valuable customer journey and run it through every relevant Google entrance. Capture the full consideration set, inspect the evidence Google selected, and repair the weakest link between entity recognition, user trust and the next action. That gives you an optimization program you can repeat even as the interface changes.

    References

  • AI Observability for WordPress: A Practical Setup Guide

    AI Observability for WordPress: A Practical Setup Guide

    You know AI systems are reaching websites, but your WordPress reports may not show which agents requested which pages, what the site returned, or where the collection gaps are. Without that evidence, AI optimization turns into a series of content changes with no reliable feedback loop.

    The useful goal is not a bigger bot-traffic chart. It is an auditable path from an observed request to the corresponding WordPress content item and delivery result. Build that path first, label what it cannot prove, and the data becomes useful for technical fixes and editorial decisions.

    Define what AI observability can actually prove

    An AI agent request is evidence of access. It is not evidence that a model understood the page, retained its information, cited it in an answer, or sent a visitor. That distinction should shape your dashboard before you collect any data.

    Observed signalQuestion it can answerWhat it does not prove
    Agent-labelled requestWas this URL requested by a client presenting this identity?That the identity is authentic or the content entered a model
    Successful deliveryDid the site return the requested resource without a visible delivery error?That the agent parsed, trusted, or retained the content
    Repeated requestsDid the same declared agent family return to the page?That the page gained AI visibility
    Identifiable AI referralDid a human visit arrive with a recognizable referral signal?Which model answer, citation, or passage caused the visit

    Think of observability as four connected layers: access, delivery, content mapping, and outcome measurement. WordPress-side agent analytics is strongest at the first three. Outcome evidence usually comes from a separate visibility, citation, or referral measurement process.

    Keep those layers separate in reports. A page can receive frequent agent requests without appearing in an answer, while a page can influence an answer without producing an identifiable referral. Calling every request an impression or every request increase a visibility gain creates certainty the data does not support.

    Put the collector where your hosting stack can see requests

    Isometric website hosting stack with request paths crossing a glowing collection sensor before reaching server, cache, application, and database layers, while one path bypasses it.

    Raw edge or server logs are a natural place to observe automated requests, but WordPress teams do not always have access to them. Managed hosting can place the relevant delivery layer outside your control, and an external log drain may not be available on the account.

    A WordPress-specific integration gives you another collection point. Profound Agent Analytics, for example, supports WordPress through a custom plugin intended to track crawler and agent interaction even when traditional CDN log drains are unavailable. The same collection model can be relevant to both managed and self-hosted WordPress, although the visible portion of the request path depends on the hosting architecture.

    The important caveat is caching. If an edge cache answers a request before WordPress runs, a collector operating only inside WordPress may never see it. A plugin can therefore be working correctly while still producing an incomplete view. You need to identify that boundary rather than assume every public request passes through the application.

    Trace the request path before installation

    Draw the actual path from an agent to the requested page. Include the edge network, host-level cache, security layer, web server, WordPress runtime, and analytics collector where each applies. Then answer these questions:

    • Which layer receives every public request first?
    • Which layer can serve a cached page without invoking WordPress?
    • Can your team export logs from that upstream layer?
    • Does the collector receive the original request identity, or a rewritten value from a proxy?
    • Which page types bypass the cache and which are normally served from it?
    • Will multiple collectors create duplicate events for the same request?

    This map tells you whether a plugin is your primary collector, a gap-filler, or one part of a combined dataset. It also gives you a precise limitation to disclose in reports: for example, WordPress-executed requests are visible while edge-served requests are not.

    Use an acceptance test, not a successful activation screen

    Plugin activation only proves that WordPress accepted the plugin. Validate the data path with controlled requests before relying on the dashboard:

    1. Request a public page using a clearly marked test user-agent value. Confirm that the event appears with the expected path and observation time.
    2. Request a URL that redirects. Check whether the collector records the requested address, the destination, and the delivery result without merging away useful evidence.
    3. Compare a route known to reach WordPress with one normally served from an upstream cache. If only the first appears, document the cache blind spot.
    4. Check that query parameters do not fragment a single article into misleadingly separate pages. Preserve the raw request for diagnosis, but report against a normalized content identity.
    5. Verify that private, administrative, preview, login, and account routes are excluded or handled under your data policy.
    6. Export a sample. Confirm that the fields required for analysis are available outside the dashboard and that observation times use an understood time zone.

    A synthetic user-agent request tests capture, not bot authenticity. Keep that distinction in the test record so a validation event is never mistaken for genuine agent activity.

    Build an event model that survives WordPress changes

    A connected sequence links an abstract automated request, timing and origin components, a modular content item, a response package, and a stored event while surrounding website modules change position.

    Raw URLs are fragile analytical keys. Slugs change, tracking parameters multiply, redirects accumulate, and the same content may be reachable through several address variants. Map each observed request to a stable WordPress content identity whenever possible.

    A useful event record contains the following fields, subject to what your stack can expose:

    • Observation time and time zone: needed to align requests with publishing, deployments, and access-rule changes.
    • Raw requested path: preserves the evidence required to diagnose malformed URLs, obsolete links, and parameter noise.
    • Normalized or canonical URL: allows equivalent requests to be grouped for reporting.
    • WordPress content identity: connects the request to the post, page, product, archive, attachment, or other content object that produced the response.
    • Content state: distinguishes a current public item from a redirect, missing resource, preview, or restricted route.
    • Declared agent identity: retains both the raw user-agent value and the normalized family assigned by your detection rules.
    • Request method and delivery result: separates ordinary page retrieval from other request types and highlights redirects, missing pages, blocked requests, and server failures.
    • Collection point: identifies whether the event came from WordPress, the server, an edge layer, or another integration.
    • Cache state, when visible: helps explain why similar requests appear in one collector but not another.

    Do not discard the raw path or raw user-agent value after classification. Detection rules evolve, and retaining the original value lets you reclassify historical events without pretending the earlier label was definitive.

    User-agent text is a claim made by the requester, not proof of identity. If your system performs additional verification, store the verification state separately. Useful labels include declared, verified, unverified, and unknown, but only use verified when an actual verification method ran successfully. A polished agent name in a dashboard should not erase that uncertainty.

    Collect only what the analysis needs. Full query strings can contain identifiers or sensitive values, and administrative routes can expose operational details. Normalize or remove unnecessary parameters, restrict access to raw telemetry, and apply the same retention and privacy review you use for other request logs.

    Turn agent requests into technical and editorial decisions

    Agent request volume is an input to investigation, not a content score. A high count may reflect repeated fetching, a loop, URL duplication, or ordinary rediscovery. A low count may reflect an access problem, an upstream visibility gap, or simply limited observed activity. Start with patterns that lead to a decision.

    • Coverage: Compare requested content with the set of public pages you intended to expose. Investigate important sections that never appear, but first rule out cache blind spots and collection failures.
    • Concentration: Group requests by content type, topic cluster, template, and normalized page. This shows where observed attention is concentrated without treating that attention as endorsement.
    • Delivery quality: Find agent requests ending in redirects, missing resources, access denials, or server failures. Fix broken delivery before rewriting the destination page.
    • Duplicate paths: Look for several URLs mapping to the same WordPress item. Consolidate reporting around the canonical identity and inspect why the variants remain discoverable.
    • Recurrence: Separate isolated retrieval from repeated requests over time. Recurrence can justify closer inspection, but it still does not prove citation or model use.
    • Change alignment: Annotate publishing, schema, template, internal-link, and access-rule changes. Compare the same request signals afterward, while treating movement as correlation unless outcome evidence supports a stronger conclusion.

    The operating loop should move from data quality to site quality and only then to content optimization:

    1. Validate that the relevant delivery layers are represented and that agent classifications have not changed unexpectedly.
    2. Resolve delivery failures, redirect chains, duplicate routes, and unintended access restrictions.
    3. Map the remaining requests to WordPress content objects and group them by meaningful editorial dimensions.
    4. Select a content hypothesis tied to a visible pattern. Examples include answering the page’s central question earlier, clarifying entity relationships, improving descriptive headings, updating stale claims, or adding internal links that expose related material.
    5. Make the smallest change that can test the hypothesis, record it as an annotation, and preserve the prior state when practical.
    6. Revisit the same access and delivery signals, then check separate citation, visibility, and referral evidence before claiming an outcome.

    Structured data belongs in this workflow when it accurately describes the visible page. Agent analytics may help you choose which content to inspect, but request counts cannot establish that a schema change caused a model to cite the page. Keep implementation quality and outcome attribution as separate questions.

    Evaluate an AI observability tool against your blind spots

    Choose the tool that fits your request path and decision process, not the one with the longest list of bot names. Ask each provider or internal implementation owner these questions before rollout:

    • Where does collection occur, and which cache or CDN paths bypass it?
    • Will it work on the current WordPress hosting plan if external log drains are unavailable?
    • Does it retain raw request evidence as well as normalized agent labels?
    • How does it distinguish declared identity from verified identity?
    • Can it map URL variants to canonical URLs and stable WordPress content objects?
    • Can you filter by content type, topic, template, delivery result, and collection point?
    • Can raw and aggregated data be exported in a usable format?
    • How are duplicate events handled when several layers observe the same request?
    • What data is stored, who can access it, and how can sensitive parameters or private routes be excluded?
    • What happens to page delivery if the analytics service or plugin integration fails?
    • Does the reporting distinguish requests from citations, visibility, and human referrals?

    A credible tool should make its coverage boundary understandable. If you cannot determine where an event was observed, how an identity was assigned, or which requests are invisible, the resulting precision is mostly cosmetic.

    Key takeaways

    • AI observability starts with a traceable request, not a visibility claim.
    • A WordPress plugin can restore useful request data when CDN log drains are unavailable, but upstream caching may still create gaps.
    • Normalize URLs to stable WordPress content identities while retaining raw evidence for diagnosis and reclassification.
    • Treat user-agent identity as declared unless a separate verification method confirms it.
    • Fix collection and delivery problems before using request patterns to prioritize content work.
    • Measure citations, AI visibility, and referrals separately from crawler or agent access.

    Before changing another page for AI search, trace a controlled request from its entry point to its normalized WordPress record. If the chain breaks, repair the instrumentation first. Once it holds, use the pattern across genuine requests to choose the next technical or editorial change, and reserve outcome claims for outcome evidence.

    References

  • AI Agent Analytics on Google Cloud: A Practical Setup Guide

    AI Agent Analytics on Google Cloud: A Practical Setup Guide

    If your content sits behind Google Cloud CDN, a rising bot count is not the answer you need. You need to know whether your measurement covers the pages that matter, which agents are reaching them, and what your team should do when the pattern changes.

    The practical goal is a trustworthy measurement chain from an agent request to a content decision. Build that chain carefully, and agent analytics can reveal coverage gaps, unusual behavior, and pages that deserve investigation. Build it loosely, and an incomplete log stream can send your SEO team in the wrong direction.

    Know what Google Cloud agent analytics can actually show

    Profound’s Agent Analytics connects with Google Cloud Platform through Cloud CDN to monitor how AI crawlers and agents interact with GCP-hosted content. That creates visibility at the content-delivery layer: an agent requests a resource, the measured delivery path observes the interaction, and the analytics system classifies and aggregates it.

    This is valuable evidence, but it has a strict boundary. An observed request does not prove that an AI system indexed the page, used its claims in an answer, cited your brand, or sent a visitor. Those are separate stages of the discovery journey.

    • Agent activity means a request associated with an AI crawler or agent reached the part of your delivery stack that you measure.
    • AI visibility means your content or brand appears in an AI-generated response for a relevant prompt.
    • Business impact means that visibility contributes to useful behavior such as a qualified visit, signup, inquiry, or sale.

    Keep those layers separate in your reporting. Agent analytics is strongest at the first layer. It can help you investigate the later layers, but it cannot establish them by itself.

    Coverage matters just as much as classification. Cloud CDN analytics can only describe requests that pass through the connected and measured path. A subdomain, application route, origin, regional setup, or content repository outside that path may be invisible. Before interpreting silence as a discovery problem, confirm that the page was observable in the first place.

    Design the measurement around decisions, not bot counts

    Start by writing down the decisions the data must support. This prevents an attractive activity chart from becoming a substitute for analysis.

    DecisionQuestion to answerAction the answer should trigger
    CoverageWhich priority content groups have observable agent activity?Investigate important groups with no activity, beginning with measurement and access checks.
    DistributionWhich agents, hostnames, and page groups account for the observed requests?Separate broad discovery from activity concentrated on a narrow or low-value part of the site.
    Change validationDid request patterns shift around a content, routing, or CDN change?Inspect the affected paths while treating timing as association, not automatic proof of cause.
    ReliabilityIs an apparent drop a content signal or a telemetry problem?Verify delivery coverage and ingestion before changing SEO strategy.

    You also need a page inventory outside the agent analytics platform. The inventory provides the denominator that request logs lack. Without it, you can count observed URLs but cannot tell whether the agents reached a meaningful share of the content you care about.

    • Group URLs by hostname and content type, such as product pages, documentation, editorial resources, comparison pages, and support content.
    • Assign each group a business role so that a request to an important decision page is not treated as equivalent to a request for a utility asset.
    • Record whether each group is expected to pass through the connected Cloud CDN path.
    • Mark recently published or materially revised groups so you can examine discovery patterns around real changes.
    • Preserve an unknown or unclassified automation category instead of forcing every suspicious request into a named AI-agent bucket.

    Do not begin with a universal target for how much agent traffic is good. A documentation library, ecommerce catalog, and corporate site have different content shapes and discovery patterns. Your useful reference point is your own verified baseline, segmented by agent and content group.

    Implement the Cloud CDN measurement path and validate it

    An isometric cloud CDN measurement path connects AI agent requests, edge servers, log events, and a validation checkpoint.

    The connector is only one part of the setup. The operational work is proving that the resulting data represents the delivery paths and URLs you think it represents.

    1. Map the request path. List the hostnames and content groups served through Cloud CDN, then identify routes that bypass it. Include alternate domains, localized sections, application routes, and other delivery paths that could make coverage partial.
    2. Connect the analytics integration with narrow access. Grant only the access needed for the relevant telemetry. Document the cloud identity, connected properties, responsible owner, and purpose so the setup can be audited later.
    3. Validate a matched sample. For requests classified as agents, compare the time, hostname, path, and available request details with the corresponding delivery evidence. Check time zones, query-string handling, path rewriting, and redirect behavior before comparing totals.
    4. Normalize URLs deliberately. Decide how to handle trailing slashes, query parameters, duplicate hostnames, localized variants, and canonical page groups. Do not merge parameters or routes when they produce meaningfully different content.
    5. Establish a clean baseline. Observe normal patterns before treating every movement as an SEO event. Keep agent identities and content groups separate so a change in one segment does not disappear inside a sitewide total.
    6. Assign an operating owner. Someone must maintain the URL taxonomy, review classification changes, investigate gaps, and record deployments that may explain shifts in the data.

    Run data-quality checks before every strategic interpretation

    • Coverage check: Confirm that the affected hostname and route still pass through the connected CDN configuration.
    • Ingestion check: Look for a broader loss or delay in incoming events before declaring that an agent stopped crawling.
    • Cache-awareness check: Do not use origin-only telemetry as your sole comparison. A request satisfied at the CDN edge may not reach the origin.
    • Classification check: Determine whether an agent label or identification rule changed. If classification relies partly on self-declared identity, spoofing and identity changes can distort the result.
    • URL check: Make sure redirects, rewrites, parameters, and canonical grouping have not split one page across several analytics rows or collapsed different resources into one.
    • Scope check: Separate a single-agent change from a sitewide change. They imply different investigations.

    Treat access telemetry as operational data. Use least-privilege permissions, keep access limited to people who need it, and align retention with your organization’s security and privacy requirements. Agent analysis does not require exposing more request data than the work actually uses.

    Turn agent activity into a disciplined investigation

    Two analysts examine clustered request signals and isolate an unusual path in a cloud operations workspace.

    Read the data as a diagnostic funnel. First ask whether the interaction could be measured. Then ask whether the agent could reach the content. Only after those checks should you investigate the content itself or connect the pattern to external visibility and business outcomes.

    • A priority page group has no observed activity: verify that the URLs are in your inventory, pass through the measured CDN path, and are accessible under your intended bot policy. If those checks pass, inspect discoverability, internal linking, content duplication, and whether the pages answer a distinct need.
    • Activity falls for a single agent: check that agent’s classification, identity behavior, and access path before making sitewide changes. Stable activity from other agents makes a universal delivery failure less likely, though it does not identify the cause by itself.
    • Activity falls across agents and content groups: investigate CDN routing, telemetry ingestion, access controls, and recent deployments before rewriting content. A broad drop is often a measurement or delivery question first.
    • Requests cluster on low-value pages: inspect why those pages are easier to discover than your primary resources. Compare navigation, internal links, URL consistency, duplication, and the clarity of each page’s purpose.
    • Activity rises after an update: record the association, then look for repetition across the affected content group. Do not call it an optimization win until independent outcome evidence also moves.
    • One page is requested repeatedly: do not assume it has greater authority. Repetition can reflect recrawling, volatility, a frequently changing resource, or inefficient access as well as genuine interest.

    A compact operating scorecard can include observed requests by classified agent, distinct requested URLs, the share of your priority inventory with any observed activity, distribution by content group, and the last observed interaction for important pages. Add delivery outcomes only when the connected telemetry actually exposes and defines them. Label every metric precisely so readers know whether they are seeing requests, URLs, pages, or external outcomes.

    Pair the scorecard with a change log for content releases, routing changes, access-policy updates, and analytics configuration changes. The log will not prove causation, but it gives your team specific hypotheses to test instead of encouraging a vague explanation for every spike or drop.

    Finally, connect agent activity to separate outcome evidence. Check whether the same content groups appear in relevant AI answers, earn citations or brand mentions, attract identifiable referrals, and support useful on-site actions. A crawler request is an upstream signal. It becomes strategically meaningful when you can trace it through the rest of the discovery and conversion path.

    Key takeaways

    • Google Cloud agent analytics is request-layer observability, not proof that an AI model used, cited, or recommended your content.
    • Map every hostname and content group to its Cloud CDN delivery path before interpreting missing activity.
    • Use a page inventory as the denominator; request logs alone cannot tell you how much priority content remains unseen.
    • Validate ingestion, classification, URL normalization, and cache behavior before making an SEO change.
    • Segment by agent and content group because a sitewide total can hide the pattern that explains the problem.
    • Connect crawler activity to independent visibility and business evidence before calling a movement a win or loss.

    Start with a domain whose content path you can map confidently. Define its priority page groups, verify that the Cloud CDN integration observes them, and document the first baseline. Once that measurement is trustworthy, expand the scope and let each new dashboard element answer a named decision rather than merely adding another count.

    References

  • Gemini 3 Expands Globally: An AI Mode SEO Action Plan

    Gemini 3 Expands Globally: An AI Mode SEO Action Plan

    If you manage search visibility across countries, Gemini 3’s expansion creates an urgent-looking question: do you need to rework your international content now? The useful answer is narrower. You need to identify where the experience is actually available, which valuable queries activate it, and whether your brand appears in a way that supports a business outcome.

    Gemini 3 has expanded through AI Mode to nearly 120 countries and territories for English searches. That substantially enlarges the testing surface, but it doesn’t prove uniform access, visibility, citations, traffic, or conversions. Treat this as a measured market expansion, not a signal to rewrite every page.

    Separate availability from actual search visibility

    An abstract world map with many illuminated regions but search-result panels appearing over only a few locations.

    The headline number is easy to misread. Geographic availability is only the first condition. The current Gemini 3 expansion in AI Mode applies to Google AI Pro and Ultra subscribers, and the stated language scope is English. A country can therefore be included while a particular user, account, language, or query remains outside the experience you are trying to evaluate.

    Query routing adds another distinction. Google is automatically using Gemini 3 for selected AI Mode queries. Selected queries does not mean every query. A test that produces an ordinary result or a different AI Mode presentation cannot establish that an entire market lacks access.

    The presentation layer matters as well. Gemini 3 can support dynamic visual layouts and interactive tools generated in response to a query. That expands what an AI search result may do, but it does not create a new ranking guarantee. A generated interface can use, summarize, cite, link to, or omit a site. Those outcomes need to be observed separately.

    Nano Banana Pro is a related but distinct rollout. Its generative imagery capability is reaching AI Mode in additional English-speaking countries for Pro and Ultra subscribers. Do not interpret access to an image-generation model as evidence that conventional image-search rankings changed or that adding AI-generated images will improve AI visibility. The expansion concerns what eligible users can generate inside AI Mode, not a documented image SEO signal.

    Build a market-by-query map before changing content

    A global average will hide the decisions you need to make. Build a working matrix in which every row represents one target market and one exact query. This forces your team to distinguish confirmed observations from assumptions inherited from another country.

    • Market: Record the country or territory where the test was performed. Do not label a region as covered merely because one neighboring country is covered.
    • Search language: Record the language of the query and interface. An English page does not prove that the same experience is available for equivalent non-English searches.
    • Account eligibility: Note whether the tester is using an eligible Google AI Pro or Ultra account. Keep tests from ineligible accounts in a separate column rather than mixing them into the same result set.
    • Exact query: Save the wording, not just a broad topic label. Use a stable query set so that later observations remain comparable.
    • Query purpose: Classify the task as discovery, comparison, selection, setup, troubleshooting, or another intent that matches your customer journey.
    • Observed experience: Record whether AI Mode appeared and whether the output included a generated layout, an interactive element, a conventional answer, or no relevant AI experience.
    • Brand and source presence: Capture whether your organization, product, page, or domain appeared. Distinguish a plain mention from a visible citation or a clickable link.
    • Business importance: Mark whether the query can influence a meaningful decision. A fascinating AI result for a low-value query should not outrank work on a high-intent query.

    Start with queries that already matter to the business. Include unbranded questions, comparison searches, branded searches, and tasks that existing customers need to complete. If you test only your company name, you will learn little about whether Gemini 3 can discover and represent you when the user has not chosen a provider.

    Record the date and the testing account with every observation. A single result is a snapshot, not a market-wide conclusion. If a query does not produce the expected experience, label the result as not observed under the tested conditions. That wording preserves the difference between a failed observation and verified unavailability.

    Prepare pages for answers assembled into dynamic interfaces

    Dynamic layouts and interactive tools raise the value of content that exposes its meaning cleanly. Your page should make the answer, scope, entities, choices, and next action easy to identify without requiring a reader or system to reconcile contradictions across several sections.

    Audit each priority page around the task it is supposed to complete:

    • Answer the primary question early. Put a direct, self-contained answer near the relevant heading. Do not make the visitor cross an extended introduction before learning whether the page addresses the query.
    • Name the scope of every important claim. Include the relevant product, plan, country, language, audience, or version where it changes the answer. A statement that is correct only in one market should not read like a universal rule.
    • Turn processes into executable steps. State prerequisites before actions, preserve the correct order, and identify the condition that tells the reader a step is complete.
    • Use stable comparison criteria. When comparing options, give each option the same fields. Switching criteria between rows or sections makes the comparison difficult for people and machines to interpret.
    • Keep decisive facts in visible page content. Do not place an important qualification only in an image, script-driven widget, tooltip, or structured-data field.
    • Resolve entity ambiguity. Use consistent names for the organization, product, service, author, and location. Explain acronyms and distinguish similarly named products.
    • Align structured data with the page. Choose the most specific applicable Schema.org type, represent only content that users can see, and keep names, URLs, dates, offers, and other properties consistent with the rendered page. JSON-LD is an alignment layer, not a substitute for a clear answer.
    • Support visuals with context. Use descriptive alternative text where appropriate, meaningful captions, and surrounding copy that explains what the visual demonstrates. Do this for accessibility and comprehension, not because Nano Banana Pro creates an undocumented image-ranking shortcut.

    This is not a case for a site-wide model-specific rewrite. Pages become fragile when they are tuned to imitate the tone of a current AI answer. The durable work is to remove ambiguity, make claims appropriately scoped, expose useful relationships, and help the visitor finish the task. Those improvements remain valuable even when the interface changes.

    Measure four layers instead of chasing one visibility score

    Four transparent layers display abstract global access, answer panels, interaction paths, and outcome markers.

    An AI visibility score can compress several different events into one number. That makes reporting simple but diagnosis difficult. Measure the rollout as a sequence of four layers:

    LayerQuestionEvidence to record
    AccessCan an eligible user reach the relevant AI Mode experience in this market and language?Country or territory, query language, account tier, interface observed, and test date
    ActivationWhat happens for the exact query under the tested conditions?Saved query, output type, generated layout or tool, and any model identification shown by the interface
    PresenceDoes your organization or content participate in the answer?Brand mention, product mention, citation, clickable link, linked page, and accuracy of representation
    OutcomeDoes that presence help the user or the business?Relevant referral and landing-page signals, engagement, conversions, assisted behavior, and country-level trends available in your own measurement stack

    Keep these layers separate in the dashboard. If access is confirmed but your brand is absent, investigate content coverage, entity clarity, authority signals, and page eligibility. If the brand is mentioned but linked incorrectly, inspect canonical destinations, internal consistency, outdated pages, and ambiguous product naming. If a correct link is present but measurable traffic remains low, the generated answer may satisfy the immediate need, the link may be inconspicuous, or your existing analytics may not expose the journey clearly. Do not declare a cause until the evidence distinguishes among those possibilities.

    Establish a baseline before publishing changes. Log what changed on the page, which query cluster it was intended to help, and which markets were eligible for evaluation. Change a coherent element at a time where practical. Rewriting the answer, altering internal links, replacing structured data, and redesigning the page simultaneously may improve performance, but it will not tell you which change mattered.

    Use the signals your analytics stack actually exposes. Do not manufacture precision by assigning unattributed sessions to AI Mode or by treating every country-level fluctuation as evidence of Gemini 3. Where direct attribution is unavailable, report the observation, the correlated business trend, and the uncertainty as separate fields.

    Key takeaways

    • Gemini 3’s AI Mode expansion covers nearly 120 countries and territories for English searches, with current access tied to Google AI Pro and Ultra subscriptions.
    • Geographic availability does not guarantee that every query activates Gemini 3 or that your content will be mentioned, cited, linked, or visited.
    • A market-by-query matrix is the fastest way to separate verified access from assumptions and to direct optimization toward commercially meaningful searches.
    • Prepare content for generated experiences by clarifying answers, scope, entities, comparisons, steps, and structured data rather than imitating a model’s writing style.
    • Measure access, activation, presence, and business outcome as separate layers so that a weak result points to a specific problem.

    Begin with your highest-priority English-language market and a tightly defined query cluster. Verify eligible access, capture what users can actually see, audit the pages that should answer those searches, and preserve a baseline before editing. Expand the program to more markets only after that loop produces evidence you can interpret.

    References

  • How to Make Your Content Visible and Citable in AI Search

    If an AI answer leaves your brand out, cites another site for your expertise, or repeats an outdated description, publishing more content is not automatically the remedy. You first need to identify whether the failure is coverage, clarity, evidence, entity consistency, or measurement.

    The practical goal is to make your best knowledge easy to find, extract, attribute, and represent accurately. That requires better answer design on the page, honest structured data, usable text for audio and other non-text assets, and a monitoring process built around real customer questions.

    Optimize for the answer your audience actually needs

    Traditional keyword planning often starts with a phrase and ends with a page. AI search optimization needs an additional layer: the answer a person expects after asking that question in context.

    Start by separating the wording of the prompt from its underlying decision. Someone asking whether a platform is suitable for an enterprise team may really need to know about governance, integrations, operating ownership, or implementation risk. A page that repeats the category keyword without resolving that decision is relevant in the shallowest sense, but it is not a strong answer.

    Create a question map before editing pages. For every important customer question, record:

    • The audience: who is asking and what they already understand.
    • The decision: what they are trying to choose, avoid, confirm, or accomplish.
    • The required answer: the shortest accurate statement that would move the decision forward.
    • The qualifications: conditions under which the answer changes.
    • The supporting evidence: documentation, first-party data, named methodology, product specifications, or expert ownership that makes the claim defensible.
    • The destination: the existing page that should own the answer, or the genuine content gap that warrants a new page.

    This exercise prevents a common mistake: creating several pages that target variations of the same phrase while leaving the actual customer question unanswered.

    On the page, build a self-contained answer unit. It should do these jobs in sequence:

    1. Name the question or issue clearly. Use a descriptive heading that still makes sense outside the page navigation.
    2. Answer it immediately. Put the direct response in the opening sentences instead of making the reader cross an introduction to find it.
    3. Define the boundary. State who the answer applies to, what assumptions it uses, and when a different answer would be appropriate.
    4. Support the claim. Place the evidence close to the statement it supports. Do not expect a generic references page to carry every claim on the site.
    5. Offer the next useful step. Link to the comparison, procedure, specification, demonstration, or contact path that naturally follows the answer.

    Use a simple extraction test: copy the passage into a blank document without the page title, sidebar, or previous paragraph. If it becomes unclear what the subject is, who the advice is for, or what a pronoun refers to, revise it. Phrases such as this approach, our solution, and it works better often need an explicit noun and a stated comparison.

    Do not force every paragraph into a miniature definition. The page should still read naturally from beginning to end. Concentrate the strongest answer units around questions that matter to a customer decision, then use the surrounding prose to explain mechanisms, tradeoffs, examples, and exceptions.

    Build pages that can be interpreted and cited cleanly

    A page becomes easier to use when its meaning does not depend on branding language or unstated context. Clear organization also gives you a better chance of noticing contradictions before they spread across product pages, help content, interviews, and profiles.

    Audit each priority page against these criteria:

    • One primary intent: the page has a recognizable job. Related subquestions support that job instead of turning the page into a collection of loosely connected topics.
    • Stable terminology: the same concept has the same name throughout the page. Introduce acronyms, alternate names, and category labels explicitly rather than switching between them without explanation.
    • Explicit entity relationships: state which organization owns a product, how a service relates to the company, and whether two similar names describe a brand, feature, plan, or legal entity.
    • Claim-level support: evidence appears beside the claim it supports. A link should help the reader inspect the basis of the statement, not merely decorate the sentence.
    • Visible ownership: identify the author, editorial owner, or accountable organization when that information helps a reader evaluate the material.
    • Meaningful maintenance signals: show a reviewed or updated date when the page has actually been reviewed or materially changed. A fresh date on stale copy makes the page less trustworthy, not more useful.
    • Descriptive internal links: link broad explanations to the specialist pages that own definitions, methods, specifications, and supporting evidence.
    • A stable citation destination: keep the answer at a durable URL. When consolidation is necessary, preserve the relationship between the old destination and its replacement.

    Pay special attention to unsupported superlatives. Claims such as best, leading, most accurate, or enterprise-ready need a defined comparison and credible support. If you cannot explain the comparison, replace the label with concrete capabilities, limitations, or use cases.

    Use JSON-LD to identify content, not to compensate for it

    Structured data can clarify what a page and its entities represent. It cannot make a vague claim specific, turn promotional copy into evidence, or repair a page that does not answer its stated question.

    Choose the most specific truthful schema type that matches the visible content. An editorial page may use Article or BlogPosting, an episode page may use PodcastEpisode, and entity information may use types such as Organization, Person, Product, or Service when those entities are genuinely present. The exact selection matters less than the consistency between the markup, the visible page, and the rest of the site.

    Check the following before publishing JSON-LD:

    • The headline, description, author, publisher, dates, URL, and named entities agree with the page a visitor can inspect.
    • Identifiers remain consistent wherever the same entity appears.
    • Relationships such as author, publisher, brand, provider, or subject describe the real relationship rather than the one marketing would prefer an engine to infer.
    • FAQ markup corresponds to questions and answers that are genuinely visible on the page.
    • Reviews, ratings, prices, availability, and other material claims are not added to markup unless the page legitimately supports them.
    • Generated markup is validated after templates, plugins, or content fields change.

    Treat structured data as an identification and disambiguation layer. That framing keeps the implementation useful even when a particular search surface does not display a special result for the markup.

    Give podcasts and other audio a usable text surface

    An embedded player tells a visitor that audio exists, but it gives an answer system little visible text to quote or evaluate. A clear and citable audio presence therefore depends on exposing the episode’s meaning in a form that can be read, attributed, and connected to a stable page.

    Build a dedicated page for each episode rather than relying only on a show archive or player feed. The page should include:

    • A specific episode title: name the subject, decision, or question instead of using only a clever theme.
    • An opening summary: state what the episode covers, who it is useful for, and the main conclusion or tension.
    • A readable HTML transcript: do not make a player, audio download, image, or document attachment the only path to the spoken material.
    • Speaker labels: distinguish the host, guest, and quoted parties so a claim is not assigned to the wrong person.
    • Topic headings and timestamps: let people move directly to a section and connect the transcript passage to the corresponding audio.
    • Explicit names and terms: spell out people, companies, products, abbreviations, and specialist concepts that automatic transcription may confuse.
    • Supporting links: connect claims and referenced resources to pages where a reader can inspect the details.
    • Matching episode metadata: keep the visible title, description, people, publication details, canonical URL, and PodcastEpisode markup aligned.

    Clean the transcript with restraint. Correct obvious transcription errors, add punctuation, and organize the text for reading, but preserve meaningful qualifications and uncertainty. If a guest said that an approach may help under certain conditions, the edited transcript should not quietly convert that into an unconditional promise.

    The transcript is not merely an accessibility afterthought or a container for extra keywords. It is a first-class content asset. Use it to create navigable topic sections, clarify who made each statement, and expose valuable explanations that would otherwise remain locked inside the recording.

    Measure representation instead of chasing one AI rank

    AI search visibility is not a single fixed position. A brand can appear for one wording of a question, disappear for a close variation, be mentioned without a link, or be cited while the accompanying description is wrong. Each outcome requires a different response.

    Build a durable prompt set around customer decisions. Include category questions, problem-solving questions, comparisons, validation questions, and direct brand questions. Add audience and use-case variations where they change what a good answer should contain. Preserve the exact wording and relevant context so later observations remain comparable.

    Track the raw components before combining anything into a visibility score:

    MeasureWhat to recordWhat it helps you decide
    Brand presenceWhether the answer names the brand for the target questionWhether the brand is associated with the problem or category at all
    Owned-domain citationWhether the answer links to a page you control, and which page it choosesWhether your site is functioning as a citation destination
    Third-party citationWhich external pages support claims about your brand or categoryWhere the answer is getting its narrative and whether those sources are current
    Factual accuracyEvery checkable claim about the brand, product, people, compatibility, or use caseWhich errors require correction in canonical content or public entity information
    Narrative fitWhether the answer connects the brand to the intended audience, problem, and differentiatorsWhere positioning is absent, vague, or being defined by someone else
    Content coverageWhether each target question has a page capable of answering it with appropriate supportWhether to improve an existing page or create a missing resource

    A mention is not the same as a citation. A citation is not the same as accurate representation. A visit is not the same as visibility, either: an answer may name your brand without producing a click. Keep these outcomes separate or a single aggregate number will hide the problem you need to solve.

    For every observation, retain the prompt, answer, date, AI surface, cited URLs, and any known context that could affect the output. Generated answers can vary, so one run should be treated as an observation rather than proof of a stable result.

    The useful operating model connects current Answer Engine observations with an actionable AI search strategy. Monitoring without a content decision becomes reporting theatre. Editing without a baseline makes it impossible to tell whether you addressed the original failure.

    Use this optimization loop:

    1. Capture the baseline. Run the preserved prompt set and label mentions, citations, claims, and errors.
    2. Classify the gap. Decide whether the problem is missing coverage, an unclear answer, weak support, entity confusion, outdated information, or an inaccurate external narrative.
    3. Choose the page that should own the correction. Avoid scattering slightly different explanations across several URLs.
    4. Make a traceable change. Record the question addressed, passage changed, evidence added, schema updated, and publication date.
    5. Check the page itself. Confirm that the visible answer, internal links, metadata, and structured data agree before looking for movement elsewhere.
    6. Repeat the same prompt set. Compare like with like, while recognizing that answer variation prevents a single rerun from proving causation.
    7. Inspect nearby questions. Make sure the edit improved the intended topic without creating contradictions for related audiences or use cases.

    Prioritize by consequence, not by the easiest available edit. If a high-value question has no adequate page, close that coverage gap. If a strong page exists but buries the answer, restructure it. If the brand is cited inaccurately, establish a clearer canonical explanation and align entity facts across owned properties. If the answer is accurate but gives an interested visitor nowhere useful to go, improve the next-step path without turning the answer into a sales pitch.

    Key takeaways

    • Optimize around the customer’s decision and required answer, not the keyword alone.
    • Write self-contained passages that answer directly, define their limits, and place evidence beside the claim.
    • Keep visible content, entity relationships, metadata, and JSON-LD consistent; schema should describe reality rather than manufacture it.
    • Give every important podcast episode a stable page with an HTML transcript, speaker labels, topic headings, timestamps, and matching episode metadata.
    • Measure mentions, citations, accuracy, narrative fit, and content coverage separately across a preserved set of prompts.
    • Connect each observed visibility gap to a documented content change, then recheck the same questions without treating one output as definitive proof.

    Start with the customer question whose missing or incorrect answer has the greatest consequence for your business. Capture the current outputs, identify the page that should own the answer, make one defensible change, and document it. That gives you a repeatable optimization cycle instead of a collection of pages carrying an untestable AI-optimized label.

    References

  • Gemini 3 in Google AI Mode: A Practical SEO Playbook

    Gemini 3 in Google AI Mode: A Practical SEO Playbook

    If your search visibility depends on Google, it is tempting to treat Gemini 3 as another ranking update and start rewriting pages immediately. That skips the most important distinction: the confirmed rollout placed Gemini 3 inside AI Mode’s answer-generation workflow for selected queries, not across every Google result.

    Your job is to separate access, model routing, source selection, and content representation. Once you measure those as different things, you can improve the pages that support complex answers without chasing an undocumented Gemini-specific trick.

    The initial rollout was narrower than the headline

    Google introduced Gemini 3 on November 18, 2025. Its initial Search deployment used Gemini 3 Pro for some AI Mode responses available to Google AI Pro and Ultra subscribers in the United States. Those access details describe the rollout at that point in time, not a permanent availability policy.

    The product boundary matters. Early messaging mentioned AI Overviews, but the clarified scope focused on AI Mode. If an AI Overview changes, that change should not automatically be attributed to Gemini 3. AI Mode and AI Overviews may look related to a user, but they are not interchangeable measurement surfaces.

    Eligible subscribers could identify access through an option in the AI Mode tab’s model menu. Even that signal needs careful interpretation: seeing the option confirms that the account can access the feature; it does not prove that every default response was automatically routed through Gemini 3 Pro.

    Before reacting to an apparent visibility change, classify what you actually observed:

    • Access: Was the test conducted in the United States with an eligible Google AI Pro or Ultra account, and was the Gemini option visible?
    • Surface: Did the response appear in AI Mode rather than an AI Overview or conventional results page?
    • Routing: Do you have an interface signal showing the selected model, or are you inferring the model from the response’s appearance?
    • Representation: Was your domain cited, merely mentioned, omitted, or represented inaccurately?
    • Performance: Did the response actually help the user complete the task, or did it only look more elaborate?

    This classification prevents two common errors. A non-eligible account cannot establish that a page is excluded from Gemini 3 answers. A visually rich response cannot, by itself, establish which model produced it.

    Automatic routing makes query complexity part of the test

    A glowing input reaches a routing hub, dividing into a short path and a denser branching path before forming a response.

    Google implemented automatic model routing that directs the most challenging AI Mode questions to Gemini 3 Pro. That changes how an SEO or GEO team should design a visibility test. Testing one short keyword is not equivalent to testing the complex task a prospective customer is trying to complete.

    Google did not provide a public scoring rubric for what counts as challenging in this rollout. Treat complexity as an experimental variable, not as a known trigger. You can vary constraints, comparisons, dependencies, and requested output while holding the underlying intent steady.

    Build a prompt ladder around one real decision

    Start with a decision that matters to your audience, then express it in four forms:

    1. Direct: Ask the shortest useful version of the question.
    2. Constrained: Add the user’s situation, requirements, exclusions, or operating limits.
    3. Comparative: Ask for alternatives to be evaluated against named dimensions.
    4. Multi-step: Ask for a recommendation, implementation sequence, risks, and a way to verify the result.

    For example, a direct prompt might ask how to structure a certain kind of page. Its constrained form could specify the business model, audience, and technical limitation. The comparative form could ask how two architectures differ in maintenance, discoverability, and conversion intent. The multi-step form could ask for a choice, migration order, failure conditions, and validation checklist.

    Do not create four near-duplicate pages to match those four prompts. Build one authoritative resource that contains the answer components each variation needs: a clear decision rule, applicable conditions, meaningful comparison criteria, ordered implementation steps, and explicit exceptions.

    When you test the ladder, compare more than whether your domain appears. Notice which claims were used, which page supplied them, whether qualifiers survived the synthesis, and whether citations changed as the task became more demanding. That tells you whether your content supports a complex decision or merely matches a short phrase.

    Build pages that can be assembled into a reliable answer

    Modular page components detach from a structured web page and fit together inside a transparent answer container.

    A model upgrade does not create a new excuse for vague content. Complex answers still need usable components. If a page hides its conclusion inside a long introduction, mixes several entities under ambiguous pronouns, or separates a recommendation from its limitations, an answer system has more opportunities to lose the meaning.

    Audit the page at the level of claims

    1. State the decision rule early. Tell the reader when an option fits, when it does not, and what factor changes the answer. Do not make the model infer your conclusion from a list of features.
    2. Give each section one job. Separate definitions, comparisons, procedures, evidence, limitations, and examples under descriptive headings. A heading such as When this approach fails is more useful than More information.
    3. Keep qualifiers beside the claim. If advice applies only to a platform, plan, region, page type, or version, put that condition in the same paragraph or list item. A distant disclaimer is easy to detach from the recommendation.
    4. Use stable entity names. Introduce the full product, organization, feature, or standard name before relying on abbreviations. Distinguish similarly named entities instead of assuming context will resolve them.
    5. Publish attributable information. First-party specifications, policies, definitions, methods, and documented observations give an answer system something specific to cite. Generic summaries are easier to replace with another generic summary.
    6. Match format to the task. Use ordered steps for sequences, aligned criteria for comparisons, and short lists for requirements. Do not force genuinely different facts into a paragraph for stylistic variety.
    7. Maintain the answer, not just the publication date. When a fact changes, update the visible claim, its qualifier, relevant internal links, and any structured data that repeats it.

    Use JSON-LD to remove ambiguity, not to force routing

    Nothing in the confirmed Gemini 3 rollout establishes a schema type or property that forces a query to use Gemini 3 Pro, guarantees an AI Mode citation, or bypasses source selection. Treat any such promise as unsupported unless Google documents it.

    JSON-LD is still useful when it accurately identifies the page and the entities described on it. Check that:

    • The structured-data type represents the page’s actual subject and purpose.
    • Names, URLs, dates, authorship, identifiers, and relationships agree with the visible page.
    • Every substantive claim in the markup is also available to the reader.
    • Deprecated, copied, or template-generated properties are removed rather than left to conflict with current content.
    • The deployed markup is validated after publishing, not merely inside the CMS editor.

    Think of structured data as a consistency layer. It can clarify identity and relationships; it cannot compensate for an unsupported recommendation, missing evidence, or contradictory visible text.

    Measure citation and representation without guessing the model

    Automatic routing means a single screenshot cannot answer whether your visibility improved. The query wording, task complexity, account eligibility, selected Search surface, and model access all belong in the test record. Without that context, a before-and-after comparison can turn normal test differences into a false algorithm narrative.

    Use a repeatable protocol:

    1. Choose one priority journey. Define the decision or task, the pages that should support it, and the prompt ladder you will use.
    2. Verify the environment. Record the country, subscription tier, Search surface, and whether the Gemini option is present in AI Mode. If the account is not eligible, label the run as a general AI Mode observation rather than a Gemini 3 test.
    3. Preserve the exact input and output. Save the prompt verbatim, the response, visible citations, linked pages, model selection evidence, and test date.
    4. Classify your domain’s role. Use consistent states such as cited accurately, cited incompletely, mentioned without citation, absent, or represented incorrectly.
    5. Map omissions to page evidence. Identify the missing claim, qualifier, comparison dimension, or procedural step. Do not respond to an omission by adding unrelated length.
    6. Change one content layer at a time. A focused revision makes it easier to connect a later difference to clearer content, updated evidence, improved structure, or corrected markup.
    7. Retest the same ladder. Keep at least one unchanged prompt as a control so that every observed difference is not credited to the edit.

    Report metrics with explicit denominators

    A useful AI Mode dashboard can remain simple. Track the number of eligible prompts tested, the number that cite your domain, the number that represent the key claim correctly, and the number that complete the intended task. Keep these counts separate from conventional rankings and organic clicks; they describe different observations.

    • Citation coverage: Eligible tested prompts containing a link to your domain divided by eligible prompts tested.
    • Representation accuracy: Cited or mentioned responses classified as correct, incomplete, or incorrect against the maintained page.
    • Task coverage: The required decision factors or procedural steps that appear in the answer.
    • Source displacement: Cases where another page supplies a claim your own page is better positioned to substantiate.
    • Complexity gap: Differences between the direct, constrained, comparative, and multi-step versions of the same intent.

    These are operational measurements, not proof that a content edit caused a model to cite you. Preserve that distinction in client and executive reporting. It is better to show a small, reproducible observation than a large claim built on an unknown route.

    Key takeaways

    • Gemini 3’s confirmed initial Search rollout covered some AI Mode responses for Google AI Pro and Ultra subscribers in the United States, not every Google search.
    • The clarified rollout scope focused on AI Mode rather than AI Overviews, so the two surfaces should be tested and reported separately.
    • Automatic routing makes prompt complexity an important test variable; one short keyword cannot represent a multi-constraint user decision.
    • No documented schema shortcut forces Gemini 3 routing or guarantees a citation. JSON-LD should accurately reinforce visible entities, facts, and relationships.
    • Measure account eligibility, prompt wording, citations, claim accuracy, and task coverage before attributing a visibility change to the model.

    Start with one commercially important user journey. Build its direct, constrained, comparative, and multi-step prompts; test them in a documented eligible environment; then fix the first page where an essential answer component is missing or ambiguous. That gives you a defensible baseline for later Gemini rollouts and a better resource for the person making the decision now.

    References


  • How to Build AI Search Visibility Without Abandoning SEO

    How to Build AI Search Visibility Without Abandoning SEO

    Your pages can keep their traditional rankings and still become less visible. The gap appears when an AI-generated response satisfies the query before a click, cites another domain, or discusses the category without mentioning your brand. If your reporting stops at positions and organic sessions, you may not notice the loss until it affects qualified demand.

    The answer is not to replace SEO with a new acronym. SEO and answer engine optimization work best as complementary disciplines: SEO makes a page discoverable and competitive, while AEO and generative engine optimization make its answers easier to understand, select, cite, and reuse. You need a wider operating model, not a separate content strategy for every platform.

    Key takeaways

    • Keep the SEO foundation. Crawlability, indexability, internal links, relevance, authority, page experience, and useful content still determine whether your material can be found and trusted.
    • Optimize answer units, not just whole pages. Each important question should have a direct response, the conditions that qualify it, supporting evidence, and a useful next step.
    • Treat structured data as an annotation layer. Schema can clarify what a page contains, but it cannot repair thin, inaccurate, or unsupported content.
    • Build recognition beyond your website. Consistent brand identity, expert attribution, citations, and distribution across relevant surfaces strengthen the signals surrounding your claims.
    • Measure the full visibility path. Track discovery, answer inclusion, citations, brand mentions, referral visits, conversions, and revenue separately. A citation and a qualified visit are different outcomes.

    AI search changes the unit of visibility

    Modular answer blocks move from a complete web page toward a glowing synthesis orb that illuminates only selected blocks.

    Traditional SEO usually treats the ranked page as the unit of success. A query produces a results page, your URL earns a position, and the searcher may click through. That sequence still exists, but it is no longer the only path between a question and an answer.

    Featured snippets, People Also Ask results, AI Overviews, voice assistants, and conversational systems can extract or synthesize the useful part of a page. In those experiences, the visible unit may be a sentence, a list, a comparison, a named entity, or a cited claim. An answer can complete the interaction without producing a website visit, so click-through rate alone cannot tell you whether your brand was present.

    Generative systems expand the target again. Your content may contribute to an answer that combines multiple inputs, or your brand may be mentioned without a clickable citation. Platforms such as ChatGPT and Google AI Overviews therefore create additional surfaces on which discovery can occur. This does not make the page irrelevant. The page remains the place where you can publish a complete explanation, establish provenance, maintain accuracy, and lead an interested reader toward action.

    A more useful visibility model has five stages:

    • Discovery: Can a search or answer system access and retrieve the content?
    • Understanding: Can it identify the subject, entities, relationships, claims, and scope?
    • Selection: Is the material clear and credible enough to use in an answer?
    • Representation: Does the resulting answer describe the claim and the brand accurately?
    • Action: Does that exposure produce a worthwhile visit, lead, purchase, subscription, or other business outcome?

    A failure at each stage needs a different fix. If a page is not discovered, work on technical SEO and internal linking. If it is retrieved but misunderstood, improve structure and entity clarity. If competitors are selected instead, strengthen the answer and its evidence. If you receive citations but no qualified response, revisit intent, positioning, and the next step on the page.

    This is why a number-one ranking is no longer a complete scorecard. Organic performance now includes SERP feature coverage, visitor quality, brand reputation, channel diversification, and business contribution. Rankings remain diagnostic evidence, but they are not the final outcome.

    Use SEO, AEO, and GEO as one visibility stack

    The boundaries between SEO, AEO, and GEO are less important than the jobs they perform. Creating separate teams, duplicate pages, or disconnected reporting for each acronym usually adds work without improving the underlying information.

    SEO establishes technical access, relevance, and authority. AEO makes specific responses easy to locate and extract. GEO improves the likelihood that generative systems can interpret, select, and represent the content. AI SEO is a useful umbrella for coordinating those jobs. The strongest implementation is usually one canonical resource that performs all three.

    LayerQuestion it answersWork to prioritizeEvidence of progress
    Technical SEOCan systems access, render, and navigate the content?Indexability, crawl paths, internal links, mobile usability, performance, and clean page structureIndexed URLs, resolved technical errors, healthy impressions, and stable access to important pages
    Intent and relevanceDoes the page satisfy the searcher’s actual task?Query-family mapping, complete topic coverage, clear scope, and alignment between title, body, and offerRelevant impressions, qualified organic visits, engagement, and conversions
    Answer designCan a system isolate a correct response to a specific question?Question-led headings, answer-first paragraphs, lists for sequences, tables for comparisons, and explicit qualifiersFeatured-result coverage, answer inclusion, and accurate extraction
    Generative visibilityWill an AI system use, cite, or mention the material?Distinct claims, evidence, authorship, entity consistency, supporting context, and appropriate distributionDomain citations, brand mentions, correct descriptions, and AI referrals
    Business performanceDoes the visibility produce value?Relevant calls to action, landing-page continuity, source segmentation, and conversion analysisConversion rate, revenue per session, qualified leads, purchases, or another defined outcome

    The lower layers cannot compensate for a broken foundation. A perfectly phrased answer on a blocked or isolated URL remains hard to discover. Likewise, a technically flawless page is not likely to become a useful answer if it buries the conclusion beneath a generic introduction.

    That is why technical SEO, user intent, direct answers, and editorial quality need to operate together. Use AI tools to accelerate research organization, query mapping, or draft analysis when they help, but do not publish generic output without checking its claims, scope, examples, and language. Automation can speed up production; it cannot supply genuine expertise or evidence by itself.

    Build pages around decisions and answer units

    A keyword is not a content brief. It tells you how demand may be expressed, but not what the reader needs to decide, what could block that decision, or what evidence would resolve the uncertainty. Start with the decision and then map the questions that surround it.

    Map the complete query family

    For each important topic, identify the different jobs a searcher may be trying to complete:

    • Definition: What is this, and what is it not?
    • Suitability: Is it appropriate for my situation?
    • Comparison: How does it differ from the alternatives?
    • Method: What steps, inputs, or settings are required?
    • Constraints: Where does the advice stop applying?
    • Verification: What evidence would show that it works?
    • Action: What should I do after I understand the answer?

    Consider a page targeting AI search visibility. Repeating variants of that phrase will not make the page complete. The reader also needs to know how AI visibility differs from rankings, which surfaces to monitor, what counts as a citation, how to handle an unlinked mention, how to connect exposure to conversion, and what to change when the brand is absent. Those questions form a coherent page because they support the same decision.

    Do not force every adjacent question onto one URL. Keep a question on the page when it helps the same reader finish the same task. Create a supporting page when the question requires a different intent, audience, depth, or action. Then connect the pages with descriptive internal links so that readers and retrieval systems can follow the relationship.

    Give each important question a complete answer unit

    An answer unit is a section that remains accurate and useful when encountered outside the full page. It has a descriptive heading, a direct answer, enough context to prevent misinterpretation, supporting evidence, and a logical next step.

    Use this editing sequence:

    1. State the question in natural language. A heading such as “How should you measure AI search visibility?” communicates more intent than “Measurement considerations.”
    2. Answer immediately. Put the conclusion in the opening sentence or two. Do not make the reader cross several paragraphs to learn your position.
    3. Add the conditions. Explain when the answer changes by platform, audience, location, query type, or business model.
    4. Supply the evidence. Link the claim to a credible reference, an original method, a transparent example, or clearly attributed expertise.
    5. Use the format the information requires. Put steps in an ordered list, alternatives in a real comparison table, and definitions in prose.
    6. Give the reader a next move. Connect the answer to the relevant check, page, calculation, or decision.

    For a narrow question, a concise answer of roughly 50-100 words can be a useful AEO editing range. Treat that as a constraint for clarity, not a universal ranking rule. Complex, disputed, or conditional questions need enough explanation to remain accurate. Brevity that removes the deciding caveat makes the answer easier to extract and easier to misuse.

    Weak: “There are many metrics and tools that businesses can use to monitor AI performance.” This gives neither the reader nor an answer system anything definite to work with.

    Stronger: “Measure AI search visibility at four separate stages: answer presence, domain citations or brand mentions, referral visits, and qualified outcomes. Use the same tracked query set for each platform, preserve the exact prompts and outputs, and analyze conversions separately from exposure.”

    The stronger version defines the components, states the method, and prevents a common measurement error. It can also lead naturally into a deeper explanation. This answer-first pattern reflects how clear headings, direct responses, contextual relevance, and structured formatting make information easier for people and AI systems to interpret.

    Make the claim easy to trust

    Extractability without credibility is not a durable strategy. A polished paragraph can still be a weak candidate when the reader cannot tell who created it, why the claim should be believed, what evidence supports it, or whether it remains current.

    For every commercially or technically important page, check the following:

    • The author or responsible organization is named clearly.
    • Relevant qualifications are specific and verifiable rather than implied by vague language.
    • Claims that depend on external evidence link to that evidence at the point of use.
    • Examples are real or explicitly hypothetical; invented experience is never presented as proof.
    • The scope is clear, including the platform, version, market, or audience when those details affect the answer.
    • The page shows when it was reviewed or materially updated.
    • Brand names, product descriptions, people, and organizational details remain consistent across owned profiles and relevant external surfaces.

    Author information, credible citations, supporting data, and regular review all make a page easier to evaluate. They also support the experience, expertise, authority, and trust signals expected of answer-focused content. If you do not have evidence for a claim, narrow the claim or remove it. More confident wording is not a substitute for support.

    Reputation work belongs in this workflow as well. Search visibility now depends partly on whether people encounter a consistent and trustworthy brand across multiple discovery surfaces. Publish the definitive explanation on your own site, then distribute useful versions where your audience already researches the problem. Keep the underlying facts and identity consistent rather than producing contradictory platform-specific claims.

    Use structured data to describe content, not decorate it

    Structured data can make the page’s entities and content type more explicit. It should describe what a reader can actually see, and the marked-up values should agree with the visible copy. Adding schema for content that is absent, hidden, misleading, or materially different creates ambiguity instead of clarity.

    Choose the most specific schema type that truthfully matches the page. FAQPage is appropriate only when the page contains genuine questions and answers. QAPage describes a genuine question-and-answer page, not an ordinary marketing FAQ. HowTo should correspond to an actual procedural sequence. These formats can help answer systems interpret structure, but schema belongs beside concise, authoritative, question-focused content, not in place of it.

    After implementation, validate the markup, confirm that required and recommended fields reflect the visible page, and recheck it whenever templates or content change. Treat JSON-LD as maintained publishing infrastructure. A one-time installation that drifts away from the page can become less useful than no annotation at all.

    Measure representation, traffic, and value separately

    Three optical instruments separately observe source inclusion, visitor flows, and illuminated outcome tokens within one digital system.

    AI visibility is not one metric. A system may mention your brand without linking it, cite your page without sending a visit, send traffic that never converts, or omit you while your traditional rankings remain strong. Combining those outcomes into a single score hides the location of the problem.

    Measurement questionMetricHow to inspect itWhat the result tells you
    Can the page be discovered?Indexation, impressions, relevant rankings, and search-feature presenceUse search performance and technical diagnostics for the query family and landing pageWhether the SEO foundation is creating retrieval opportunities
    Does the answer surface include you?Answer-presence rate and SERP-feature coverageRun the tracked queries and record whether your material appears in the answer experienceWhether the content is being selected for visible answers
    Is your evidence attributed?Domain citation rateDivide tracked prompts that cite your domain by all eligible tracked promptsWhether your pages are being used as explicit support
    Is your brand represented?Brand-mention rate and description accuracyRecord named mentions, linked or unlinked, and compare the description with your actual positioningWhether AI exposure builds correct recognition rather than mere presence
    Does exposure produce a visit?AI referral sessions and landing-page engagementSegment identifiable AI referrals by platform and destination pageWhich answer surfaces lead people to seek more information
    Does the visit create value?Conversion rate, revenue per session, qualified leads, or the defined business outcomeSegment by source, landing page, intent, audience, and conversion actionWhether visibility reaches the people who can take a worthwhile action

    Use a stable query set tied to real audience decisions. For every check, save the platform, exact prompt, output, date, cited URLs, brand mentions, and any known location or account context. AI answers can reflect user history or location, so personalized results should not be treated as one universal rank. The goal is a repeatable observation method, not a claim that every user sees the same answer.

    Evaluate mention rate and citation rate separately. A mention may improve recognition even when no link is present, while a citation gives the user a path to verify or continue. Neither guarantees a qualified visit. Referral traffic is another stage, and conversion is another. This separation tells you what to change.

    • Healthy rankings but weak AI presence: improve direct answers, entity clarity, evidence, and question coverage.
    • Frequent mentions but inaccurate descriptions: clarify positioning and make brand facts consistent across owned and relevant external surfaces.
    • Citations without visits: check whether the page offers useful depth beyond the extracted answer and a clear reason to continue.
    • Visits without qualified outcomes: revisit search intent, landing-page continuity, audience fit, and the requested action.
    • Strong exposure on one platform only: inspect how the other surfaces represent the query rather than copying the same tactic blindly.

    Visitor quality deserves the final word in the scorecard. Segmenting organic traffic by conversion rate and revenue per session helps distinguish broad exposure from traffic that contributes to a meaningful business result. Apply the same discipline to identifiable AI referrals, but do not assume referral analytics capture all AI influence. Zero-click answers and unlinked mentions may affect discovery without producing a measurable session.

    Begin with the query family closest to a valuable audience decision. Capture its current search features, AI answers, citations, mentions, referrals, and conversions. Upgrade the strongest canonical page with direct answer units, explicit evidence, accurate schema, and a useful next step. Then rerun the same checks. Reviewing how AI systems represent the content can reveal missing context or ambiguous language, while business analytics show whether the added visibility matters.

    That cycle is the practical evolution of SEO: preserve the foundation, make every important answer understandable and defensible, and judge success by representation and business value as well as rank. When the scoreboard shows where the visibility chain breaks, your next optimization decision becomes much easier.

    References