Tag: AI Visibility

  • Legal GEO Agencies: How to Choose the Right Partner

    Legal GEO Agencies: How to Choose the Right Partner

    You are not choosing a legal GEO agency because your firm needs another marketing acronym. You are choosing one because prospective clients can now encounter an AI-generated answer before they see a search result, visit a practice-area page, or recognize your firm’s name. The right partner must improve that discovery path without weakening factual accuracy, attorney-advertising compliance, or your control over the firm’s digital assets.

    The market does not make that choice easy. By the first half of 2025, the field was crowded enough for 43 law firm GEO agency contenders to be evaluated. A large field creates apparent choice, but labels such as GEO, AEO, AI SEO, and AI visibility do not tell you what an agency actually delivers. You need to evaluate the operating model behind the label.

    Map the agency landscape to your actual bottleneck

    Generative engine optimization is the work of making an organization and its information easier for generative systems to retrieve, understand, verify, and use in an answer. It overlaps with SEO, content strategy, structured data, digital public relations, entity management, and reputation work. That overlap explains why very different agencies can all sell a service called GEO.

    Most legal GEO providers can be understood through four broad operating models. These are not rigid categories, and a capable agency may combine several. Use them to identify the provider’s center of gravity:

    • Legal SEO agencies with a GEO practice: These providers usually begin with crawlability, search demand, practice-area architecture, local visibility, and content. They are a sensible fit when your conventional search foundation is weak. Verify that GEO adds prompt research, citation analysis, entity work, and answer-level measurement rather than merely placing a new name on an existing SEO package.
    • GEO or AEO specialists: These agencies tend to start with generative answer surfaces, prompt sets, cited-source patterns, brand mentions, and entity clarity. They may suit a firm with mature SEO operations that needs a dedicated AI-search layer. Verify their understanding of legal review, local discovery, jurisdiction-specific content, and attorney-advertising restrictions.
    • Content and authority specialists: These providers concentrate on expert content, editorial positioning, third-party mentions, and digital PR. They can help when your website is technically sound but your firm lacks corroborating authority beyond its own domain. Verify that they can diagnose technical and entity problems rather than treating every visibility gap as a publishing problem.
    • Technical and structured-data consultancies: These providers focus on information architecture, structured data, feeds, entity reconciliation, and machine-readable consistency. They can resolve foundational ambiguity, but technical markup alone is not a complete GEO strategy. Verify who will improve the underlying legal content and build credible external corroboration.

    Choose the model that matches the constraint. If search systems cannot reliably crawl or interpret your pages, start with technical and entity work. If your pages are accessible but generic, stale, or jurisdictionally vague, prioritize legal editorial operations. If your firm publishes strong material but appears nowhere outside its own properties, authority development may matter most. If you cannot tell whether any of this is working, fix measurement before funding a larger content program.

    This diagnosis also prevents an expensive mismatch. A firm with contradictory attorney biographies does not primarily need more blog posts. A firm with accurate, useful content but weak independent recognition does not primarily need another schema deployment. Make each agency name the bottleneck it believes it is solving and show the evidence behind that diagnosis.

    Define success before an agency defines it for you

    A legal GEO program can generate impressive-looking reports without answering the commercial question: is the firm becoming easier for the right person to discover and evaluate? Avoid that trap by defining the measurement system in your brief, before you review proposals.

    Build a query portfolio, not a keyword list

    Traditional keywords remain useful, but generative searches often contain a situation, constraints, follow-up questions, and evaluation criteria. Build a prompt portfolio around the decisions your prospective clients make. It should cover:

    • Branded accuracy: Questions about your firm, attorneys, offices, services, credentials, and public contact information.
    • Problem discovery: Questions asked before a person knows the legal name of the relevant practice area.
    • Service evaluation: Questions comparing approaches, qualifications, jurisdictional coverage, or the factors involved in choosing counsel.
    • Local and jurisdictional intent: Questions in which location, court, governing law, licensing, or service area materially changes the answer.
    • High-consideration questions: Questions about process, possible costs, timelines, evidence, risk, and what information someone should prepare before contacting a lawyer.

    Do not put confidential intake facts or identifiable client information into this prompt set. Use public facts, redacted patterns, or hypothetical wording approved by the firm. If an agency wants real client material for testing, require a documented data-handling review before sharing anything.

    Keep a stable benchmark set for comparison while allowing a separate exploratory set for emerging questions. For every observation, record the exact prompt, product or answer surface, date, visible location or account context, response, cited pages, brand mentions, factual errors, and relevant call to action. Generative output can change between runs, so a visibility score without the underlying observations is not auditable evidence.

    Separate four outcomes that vendors often blur together

    • Retrievability: Can the system access and interpret the firm’s relevant information?
    • Visibility: Does the firm appear as a mention, cited source, or possible provider for the agreed prompt portfolio?
    • Accuracy: Are descriptions of attorneys, services, locations, qualifications, and legal topics correct and appropriately qualified?
    • Qualified demand: Does visibility contribute to relevant visits, consultations, or intake rather than merely producing more brand mentions?

    A mention is not necessarily a citation. A citation is not necessarily a recommendation. A recommendation is not necessarily a qualified inquiry. Your reporting should preserve those distinctions instead of compressing them into one proprietary score.

    There is also no single permanent AI rank equivalent to a fixed position you can purchase or guarantee. Responses can depend on the wording of the prompt, available sources, product behavior, user context, and changes outside the agency’s control. Treat a promise of guaranteed placement as a warning sign. A credible agency should commit to defined work, transparent evidence, and measurable coverage, not an answer it does not control.

    Inspect the complete GEO delivery system
    Researchers, legal reviewers, and technical specialists work across connected stations containing source materials, compliance checks, publishing tools, and analytics.

    A proposal should connect technical access, entity clarity, content quality, external corroboration, measurement, and legal governance. If any component is missing, ask who owns it. Work divided between your agency, web team, attorneys, public-relations provider, and intake team still needs one accountable workflow.

    Technical access and entity clarity

    The agency should examine whether important pages can be crawled, rendered, indexed, and reached through coherent internal links. It should identify conflicting canonical signals, accidental noindex rules, thin duplicates, broken redirects, fragmented office information, and practice pages that compete with one another. Publishing more content before resolving those issues can expand the ambiguity.

    For a law firm, entity work should reconcile the firm name, offices, attorneys, practice areas, jurisdictions, credentials, public profiles, and relationships between them. An agency should be able to explain which property is authoritative for each fact and how corrections move across the firm’s site and legitimate external profiles.

    Structured data can make those relationships more explicit, but it must describe visible, supportable information. Appropriate organization, legal-service, person, address, article, and breadcrumb markup may help machines interpret a page. Markup must not introduce awards, ratings, locations, services, or credentials that a user cannot verify on the page. Ask for validation results, a mapping between each field and its visible source, and a process for updating markup when attorneys or offices change.

    Legal content that is answerable and reviewable

    Good legal GEO content should answer a defined question directly, state the jurisdiction or scope where it matters, explain material conditions, and give the reader a sensible next step. It should also make authorship, legal review, and update responsibility clear. A disclaimer does not repair inaccurate or overbroad legal information.

    Ask how the agency turns one topic into a coherent information structure. The answer should address the main page, supporting questions, internal links, attorney and practice relationships, source maintenance, consolidation of overlapping pages, and updates when the underlying law or the firm’s services change. A publishing quota without a maintenance plan creates a growing accuracy liability.

    Require a firm-side lawyer or ethics reviewer familiar with the relevant jurisdiction to approve claims about results, specialization, credentials, testimonials, comparisons, and past matters. Attorney-advertising and professional-conduct requirements vary, and an outside marketing agency should not make the final compliance judgment. Unsupported superlatives and invented expertise are dangerous in page copy, structured data, directory profiles, and AI-generated drafts alike.

    External corroboration rather than manufactured signals

    Generative systems may encounter information about your firm on third-party sites as well as your own domain. The agency should therefore audit which external pages appear around your priority questions, which ones describe the firm, whether those descriptions are accurate, and where credible gaps exist.

    Ask how the provider distinguishes legitimate authority development from low-value placement. A relevant editorial mention, accurate professional profile, or genuinely useful expert contribution serves a different purpose from bulk links on unrelated sites. The plan should name the audience and information gap each placement is intended to address. “More backlinks” is not an adequate GEO rationale.

    Governance, correction, and data handling

    No agency can directly control every answer generated by a third-party model. It can, however, detect recurring errors, trace likely contributing pages, correct owned information, request appropriate corrections from external publishers, and document whether the error persists. Require a correction workflow with an owner, evidence log, escalation path, and closure rule.

    Ask which AI tools the agency uses, what it uploads, whether submitted material may be retained or used to improve third-party systems, who can access project data, and what happens to that data after the engagement. Do not permit confidential case files, privileged communications, unannounced matters, intake records, or personal information to be placed in external AI tools without an approved legal, privacy, and security process. Synthetic or redacted test data is the safer default.

    Select an agency with a proof-based procurement process
    Law-firm leaders review anonymized evidence folders, technical samples, ownership documents, and abstract performance dashboards during an agency selection meeting.

    Give every finalist the same brief. Include your priority practices, jurisdictions, office structure, target audiences, known technical constraints, approval requirements, prompt portfolio, and available analytics. Comparable inputs make it harder for polished presentations to hide weak diagnosis.

    Then ask each finalist to assess a small, public portion of your current footprint. The exercise should use no confidential data and require no production access. You are looking for the quality of its reasoning: what it notices, how it separates evidence from inference, which constraint it prioritizes, and how it would verify the result.

    Evaluation areaEvidence to requestWeak response to notice
    BaselineExact prompts, answer captures, cited URLs, factual-error log, and stated testing contextA single visibility percentage with no underlying observations
    DiagnosisA prioritized explanation connecting technical, entity, content, authority, and measurement findingsA generic recommendation to publish more content
    ImplementationNamed deliverables, responsible owners, dependencies, approval steps, and acceptance criteriaA list of activities with no definition of completion
    Legal quality controlA workflow for jurisdictional review, claims approval, corrections, and documented updatesReliance on AI drafting plus a general website disclaimer
    MeasurementRaw prompt-level evidence connected to citations, accuracy, site behavior, and qualified intake where measurableBrand mentions presented as leads or revenue
    Data and ownershipWritten terms covering credentials, content, structured data, dashboards, prompt sets, exports, retention, and deletionCritical assets available only inside the vendor’s account

    Your proposal review should force clear answers to the following questions:

    1. What does the agency’s GEO service add beyond its ordinary SEO, content, public-relations, or technical work?
    2. Which part of our current visibility problem does the agency believe is most important, and what evidence supports that conclusion?
    3. How will it distinguish a brand mention, a linked citation, a favorable description, a recommendation, a site visit, and a qualified inquiry?
    4. Which prompts and answer surfaces will be monitored, and will we receive the raw observations behind every aggregate score?
    5. Who writes, verifies, legally reviews, publishes, and maintains each deliverable?
    6. How are confidential information, personal data, prompts, drafts, account credentials, and third-party AI tools handled?
    7. Does the agency work with competing firms in the same practice and market, and what conflict or exclusivity terms apply?
    8. Which content, code, markup, accounts, dashboards, research, and historical data can we export if the engagement ends?

    Do not let a case study substitute for this examination. Even a real result may depend on a different practice area, market, domain history, brand, content library, or measurement method. Ask the agency to show the starting condition, work performed, evidence captured, and limits on what can be attributed to GEO. If it cannot explain the mechanism, the headline result is not useful for your decision.

    The contract should make the operating model concrete. Define deliverables and acceptance criteria; separate agency responsibilities from firm dependencies; identify third-party costs; preserve your approval rights; prohibit unsupported factual or performance claims; address conflicts, confidentiality, data retention, and AI-tool use; and guarantee usable exports of firm-owned assets at termination. Have qualified counsel review terms that affect confidentiality, intellectual property, professional obligations, privacy, or liability.

    Walk away from guarantees of permanent AI placement, schema-only “optimization,” undisclosed bulk AI publishing, unverifiable proprietary scores, fabricated citations, or a refusal to provide raw evidence. Also be cautious when an agency treats every unfavorable answer as a content-volume problem. Sometimes the correct action is to repair a fact, consolidate pages, clarify an entity relationship, improve an external profile, or stop publishing material that no longer deserves to exist.

    Key takeaways and your first move

    • Choose an agency for the bottleneck it can solve, not the GEO label it places on its services.
    • Define a prompt portfolio and preserve raw answer-level evidence before accepting any visibility score.
    • Measure retrievability, visibility, accuracy, and qualified demand separately.
    • Require technical access, entity clarity, useful legal content, external corroboration, and governance to work as one system.
    • Keep legal approval, sensitive data, account access, and ownership of project assets under firm control.
    • Reject guaranteed placements and demand a traceable connection between diagnosis, work performed, and observed change.

    Your next move is to write a one-page decision brief before contacting more agencies. Name the practices and jurisdictions in scope, the audiences you need to reach, the public facts that must remain accurate, the prompt categories you will test, the internal reviewers who can approve work, and the assets the firm must own. Send the same brief to each finalist and select the team that returns the clearest diagnosis, evidence trail, and operating plan. That discipline will tell you more than any agency ranking can.
    References

  • GPT-5.2 in ChatGPT: What Availability Actually Means

    GPT-5.2 in ChatGPT: What Availability Actually Means

    If you are trying to find GPT-5.2 in the ChatGPT app you use, a general statement that the model is “in ChatGPT” is not enough. It does not automatically tell you whether your account has access, whether every ChatGPT client supports it, or whether you can select it yourself.

    The defensible answer is narrower: GPT-5.2 has been confirmed in ChatGPT, and an external analytics platform is tracking ChatGPT responses generated with it. Universal availability across browser, desktop, mobile, account tiers, managed workspaces, and the API is not established by those facts. Here is how to separate what is known from what you still need to verify.

    What the current GPT-5.2 confirmation actually proves

    OpenAI announced GPT-5.2 on December 11. By December 14, Profound had begun tracking GPT-5.2 responses in ChatGPT across its products. The named products include Answer Engine Insights, Prompt Volumes, and Agent Analytics, with ChatGPT responses in those dashboards reflecting GPT-5.2.

    That confirms two useful points. GPT-5.2 was operating within ChatGPT, and organizations using Profound could analyze ChatGPT output associated with the model. It does not provide a platform-by-platform rollout matrix, plan eligibility, workspace controls, direct-selection details, or API availability.

    Availability questionAnswer you can defend
    Is GPT-5.2 operating in ChatGPT?Yes. Its use in ChatGPT responses is confirmed.
    Is GPT-5.2 reflected in Profound’s ChatGPT tracking?Yes, beginning December 14 across the named product suite.
    Can every ChatGPT account use it?Not confirmed.
    Is it available in every browser, desktop, and mobile client?Not confirmed.
    Can every eligible user select GPT-5.2 directly?Not confirmed.
    Does ChatGPT availability also confirm API access?No. API access is a separate question and is not established here.

    This distinction prevents a common reporting error: turning evidence of model activity into a claim of universal access. If you publish a rollout status, describe GPT-5.2 as confirmed in ChatGPT without adding unsupported claims about every client or account type.

    “Available” can describe four different states

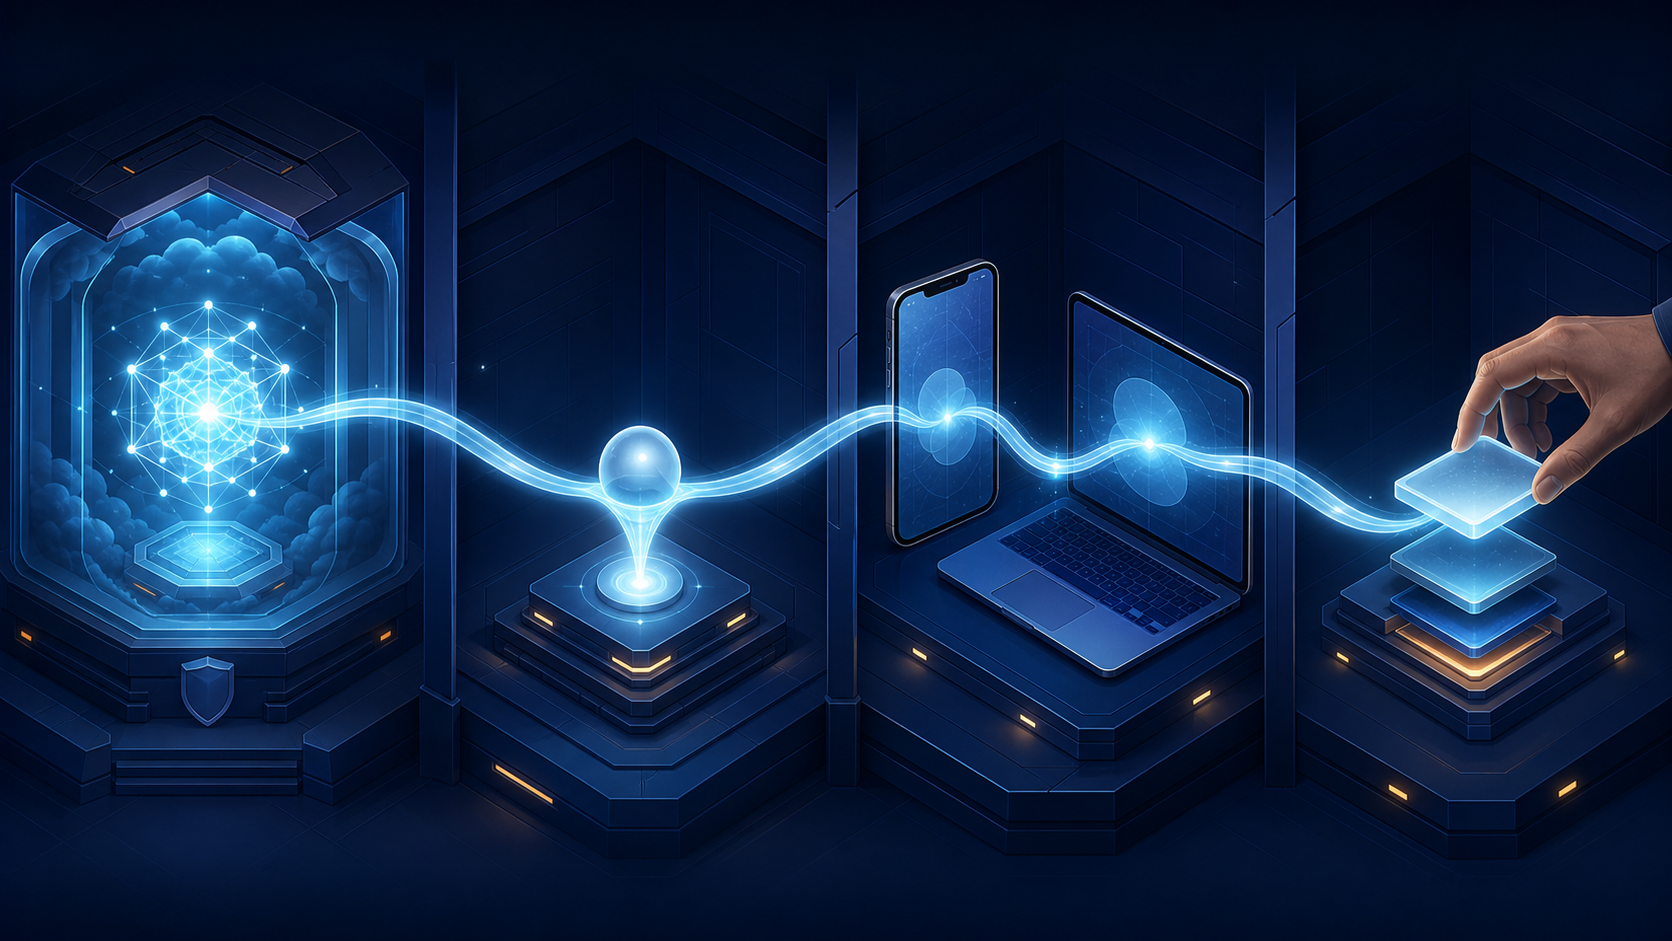
    Four connected scenes depict a model existing on a service, reaching an account, connecting to devices, and being manually selected from interface tiles.

    Teams often use “available” as though it has one meaning. In practice, you need to identify which of four states you are discussing.

    1. Product presence: GPT-5.2 is operating somewhere within ChatGPT. This is the broadest confirmed claim.
    2. Account eligibility: a particular personal or managed account is permitted to use the model. Product presence does not prove this for your account.
    3. Client availability: the model is exposed in the specific browser, desktop, or mobile experience you are using. Access on one client does not demonstrate access on another.
    4. User selection: the interface explicitly lets you choose GPT-5.2. A system may route a request to a model without presenting that model as a selectable option.

    API availability belongs outside this sequence. ChatGPT and an API are different access surfaces, even when they use models with the same name. A confirmation about ChatGPT should not be copied into API documentation, procurement requirements, or production plans without separate evidence.

    The same discipline applies to third-party analytics. A dashboard can accurately identify the model used for the responses it tracks without proving that every consumer account can open ChatGPT and select that model. Tracking coverage and end-user entitlement answer different questions.

    How to verify GPT-5.2 on the ChatGPT platform you use

    Do not ask the model to identify itself and treat the answer as account metadata. A generated response is not an authoritative access record. Use product-controlled labels, account notices, workspace settings, and official release information instead.

    1. Define the exact claim you need to verify. Replace “Do we have GPT-5.2?” with a testable question such as “Can this account select GPT-5.2 in the desktop client?” or “Are responses in this managed workspace being routed to GPT-5.2?”
    2. Start a new conversation. Inspect the model name shown by the interface, any model-selection control, and any account-level release notice. An old conversation may not be useful evidence for the state of a newly enabled model.
    3. Check each client separately. Test the browser, desktop application, and mobile application that matter to your workflow. Record the date, account or workspace, client, application version where applicable, visible model label, and whether direct selection was offered.
    4. Classify the result precisely. Use “selectable” when the interface names GPT-5.2 as an option, “reported as routed” when a trusted system identifies the backend model, and “unconfirmed” when neither form of evidence is present. Do not translate “unconfirmed” into “unavailable.”
    5. Verify managed access at the workspace level. A result from a personal account does not establish the state of an organization-controlled workspace. Capture evidence from the account that will perform the actual work.
    6. Keep API verification separate. If your implementation depends on programmatic access, confirm the model name, permissions, and availability in the API environment itself before changing production workflows.

    A small access register is enough for most teams. Give it one row per account and client, with columns for the check date, workspace, platform, application version, visible model, selection status, and evidence. This turns an ambiguous rollout conversation into a list of claims that can be rechecked.

    AI visibility teams should treat December 14 as a measurement boundary

    A stream of abstract response records crosses a bright vertical boundary while two analysts observe the change at a transparent console.

    For SEO, AEO, and GEO teams, model availability is not only an access question. It is also a measurement variable. A model change can alter which brands, pages, facts, and citations appear in generated answers even when your content has not changed.

    Profound’s switch to GPT-5.2 tracking across Answer Engine Insights, Prompt Volumes, and Agent Analytics creates a practical boundary on December 14. If a visibility metric or answer pattern changes across that date, the model transition is one possible cause. It should not automatically be interpreted as a ranking gain, content loss, competitive move, or change in audience demand.

    • Annotate the transition date. Add December 14 to reports that include Profound’s tracked ChatGPT responses so later readers can see that the measurement environment changed.
    • Segment before and after the switch. Compare GPT-5.2 observations with other GPT-5.2 observations when making trend claims. A blended series can hide a model-driven break.
    • Rerun your baseline prompt set. Keep the prompts and other controlled inputs unchanged, then establish a fresh GPT-5.2 baseline for mentions, citations, answer position, sentiment, and factual accuracy.
    • Store raw responses with model metadata. A score without its answer, collection date, and model context is difficult to audit after a platform transition.
    • Delay causal claims. If the only known event near a metric change is the model cutover, label the result as a change in observed output. Do not claim that an optimization caused it until you have evidence that separates the two effects.
    • Do not infer consumer rollout coverage from tracking coverage. Dashboard-wide GPT-5.2 measurement tells you which model underlies the monitored responses, not which ChatGPT clients or account types expose it to every user.

    This is especially important for reports shared with clients or leadership. “ChatGPT visibility increased after GPT-5.2 entered the measurement environment” is supportable when the data shows it. “Our visibility strategy caused the increase” requires additional evidence.

    Key takeaways

    • GPT-5.2 is confirmed in ChatGPT, but universal access across every account, workspace, client, and plan is not confirmed.
    • Profound began tracking GPT-5.2 ChatGPT responses across its named product suite on December 14.
    • Product presence, account eligibility, client availability, direct selection, and API access are separate claims.
    • Verify access using interface and account metadata, not the model’s generated description of itself.
    • For AI visibility reporting, annotate December 14 and establish a new GPT-5.2 baseline before interpreting changes as SEO, AEO, or GEO performance.

    Your next step is simple: write down the exact account-and-client claim your work depends on, verify that claim in the relevant interface, and add the result to your access register. Until that check is complete, use “confirmed in ChatGPT” rather than “available everywhere.”

    References

  • How to Capture AI-Driven E-commerce Demand on Black Friday

    How to Capture AI-Driven E-commerce Demand on Black Friday

    If your Black Friday plan stops at rankings, feeds, paid media, and conversion rate, it now has a blind spot. A shopper can ask an AI system to narrow a category, compare products, judge whether a discount is worthwhile, and recommend where to buy – without following the search journey you designed.

    Your job is not to make an AI repeat your promotion. It is to make your products easy to identify, compare, and verify while demand moves from early research to live deal hunting. That requires coordinated work across your own site, retailers, marketplaces, review coverage, video, and genuine customer discussion.

    Black Friday creates two different AI demand states

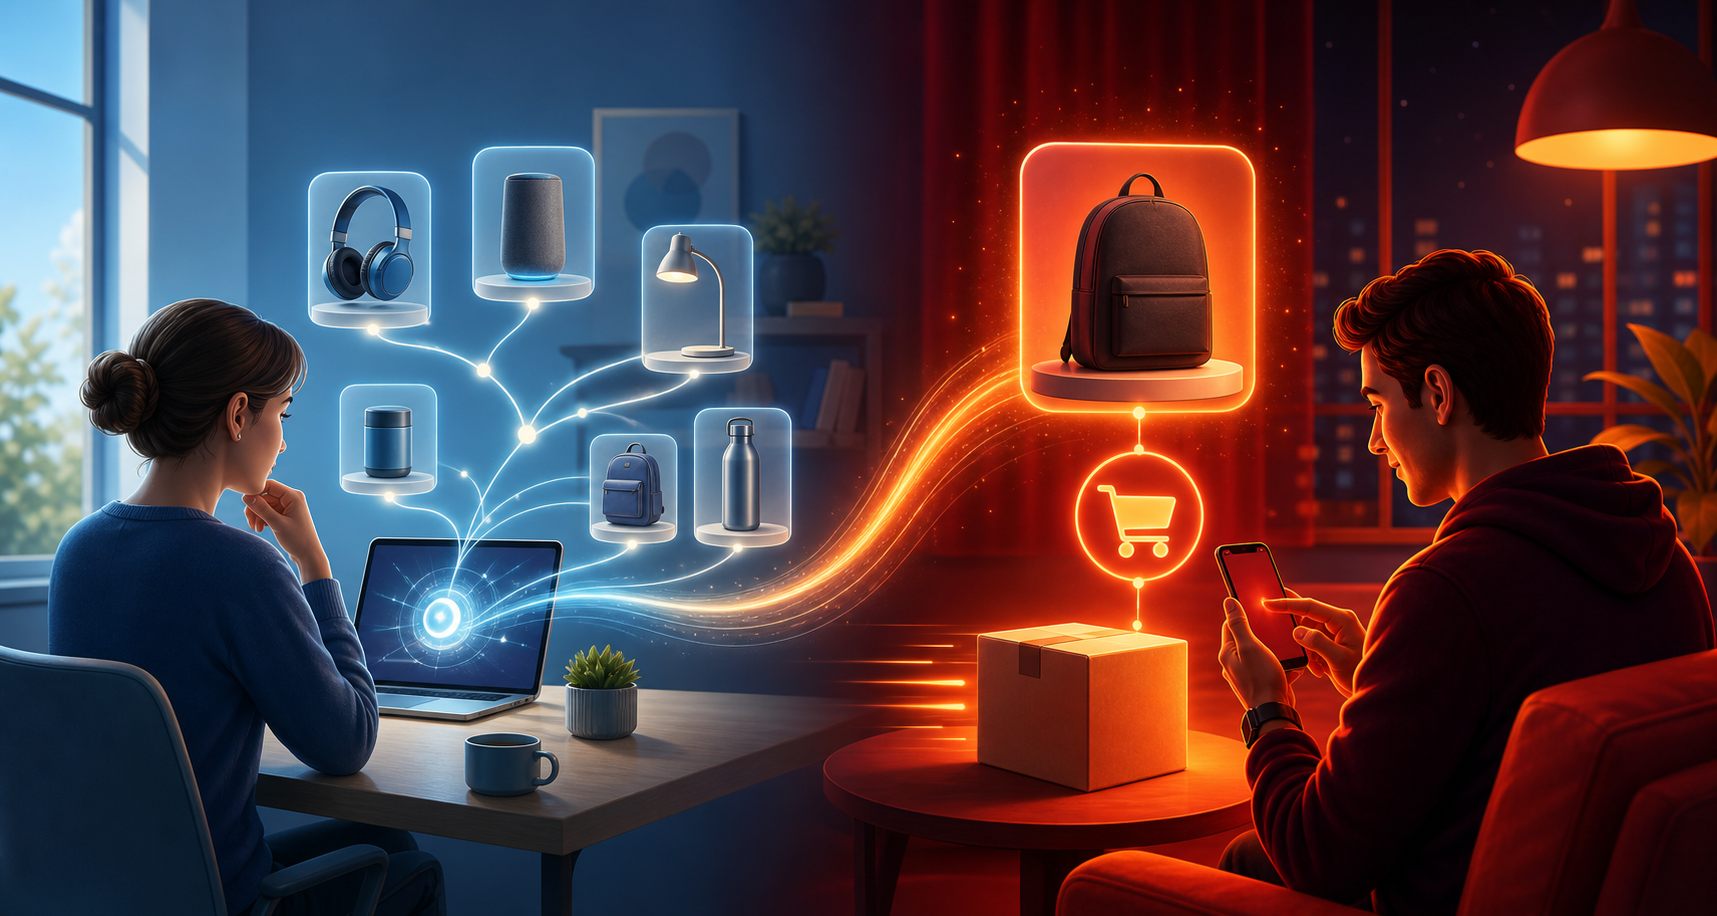
    A split scene contrasts calm product research at a desk with urgent mobile deal shopping at night.

    Before Black Friday, shoppers are reducing a large market into a shortlist. Their questions tend to concern suitability: which product fits a use case, what features matter, which compromises are acceptable, and whether waiting for a sale makes sense. When the event begins, the task changes. Price, availability, seller credibility, current sentiment, and the quality of the deal become more important.

    That change is visible in the domains AI systems use. In the week before Black Friday, retail and brand domains represented 59.6% of cited sources, media represented 23.4%, and social or user-generated content represented 17%. During Black Friday, the social and user-generated share rose to 25.1%, while retail and media lost share.

    Those percentages do not establish a permanent formula for every category or model. They do expose a useful operating distinction: the content that builds a shortlist is not sufficient on its own when shoppers want current confirmation from other people.

    Build your campaign around four information layers:

    • The identity layer explains what your brand sells, which categories it belongs in, and who its products are for.
    • The decision layer supplies specifications, use cases, limitations, compatibility details, and defensible comparisons.
    • The offer layer states the current price, discount terms, sale window, availability, fulfillment conditions, and applicable returns information.
    • The verification layer gives shoppers independent evidence through reviews, demonstrations, retailer listings, comparison coverage, and legitimate customer discussion.

    The first two layers should be settled before promotional demand arrives. The offer layer must be updated whenever the commercial facts change. The verification layer takes longer to earn, so it cannot be manufactured credibly on launch day.

    Make every offer answerable without reconstruction

    An AI system should not have to combine a slogan on your homepage, specifications in a PDF, a discount in a banner, and shipping terms in a support page to explain your offer. Every extra reconstruction step creates another opportunity for omission, confusion, or a stale answer.

    Start at the homepage because it is more than a navigational doorway. Within the examined brand-site citations, homepages accounted for 40%. Give that page a plain statement of what the brand is, the categories it serves, the customer problems it solves, and the main paths to product information. A clever campaign line can support that explanation, but it should not replace it.

    Then audit each priority product or offer page in this order:

    1. Use the exact product name and model consistently in the title, visible copy, structured data, retailer listings, and supporting content.
    2. State what the product is and who it suits near the top of the page. Do not make the reader infer the category from branding language.
    3. Present specifications as labeled facts. Include the dimensions, materials, capacity, compatibility, included components, or technical requirements that actually drive a decision in your category.
    4. Explain the important tradeoffs. A page that identifies who should not buy the product can be more useful than one that describes every shopper as an ideal customer.
    5. Place the live offer in visible text. Include the current price, reference price where applicable, conditions, start and end information, seller, stock state, and fulfillment details that a buyer needs to interpret the promotion.
    6. Add concise questions and answers for real research intents: compatibility, setup, maintenance, warranty, returns, common alternatives, and differences between adjacent models.
    7. Provide evidence close to the claim it supports. Demonstrations should show the use case, while reviews and technical documentation should be clearly attributable and reachable.

    Keep stable product facts separate from volatile promotional facts in your content workflow. The product’s dimensions should not change because a sale begins, but price and availability might. Assign ownership accordingly: merchandising maintains the offer state, while product or content teams maintain the underlying facts.

    Structured data can make those facts less ambiguous to machines, but it cannot rescue incomplete visible content. Product and Offer markup should agree with the page a shopper sees. If a price, availability value, model identifier, or seller differs between the markup and the page, the markup has added conflict instead of clarity.

    Finish with a manual extraction test. Give someone who did not build the page the URL and ask them to answer: What is this product? Who is it for? Why would they choose it over the closest alternative? What exactly is the Black Friday offer? What restriction could change the decision? If any answer requires another tab or an assumption, the page is not finished.

    Build comparison coverage before the promotion starts

    Brand pages are good at establishing first-party facts. Shopping recommendations require a second job: organizing choices and reducing uncertainty. That is why AI systems repeatedly draw from retailers, review publishers, video platforms, and community conversations when they construct commercial answers.

    Across 10,000 responses about deals, reviews, and product recommendations, YouTube received 1,509 citations, Best Buy 950, Walmart 885, Target 477, TechRadar 355, RTings 342, and Consumer Reports 325. The distribution was concentrated rather than evenly spread across the web.

    Retail concentration matters too. Generalist retailers held 48% of retail citations, while electronics specialists held 23%. Large retailers have broad assortments, familiar identities, and enough product information to answer many different shopping questions. A smaller brand is unlikely to reproduce that footprint, but it can make its category knowledge and product distinctions much easier to reuse.

    Create comparison pages around decisions, not around the phrase “best product.” A useful comparison should tell the reader:

    • Which products are genuinely comparable and which belong to a different use case.
    • What each option is best suited to, using a stated criterion rather than a vague superlative.
    • Which specifications materially change the experience.
    • What the buyer gives up by choosing the cheaper, smaller, faster, or more capable option.
    • Whether accessories, subscriptions, installation, or compatibility requirements affect the practical cost.
    • Which facts are stable product attributes and which are temporary Black Friday conditions.

    Publish first-party comparisons even when an independent reviewer would be more persuasive. Your version establishes accurate entities, specifications, and distinctions that other people can check. It should disclose its perspective and link to the underlying product details rather than pretending to be neutral.

    For third-party coverage, prioritize relevance over raw volume. Give suitable reviewers and publishers clean model names, current specifications, images, documentation, and access to products where your normal review policy allows it. Correct factual errors without trying to dictate conclusions. Inclusion in a trusted comparison is valuable because the comparison answers a real decision, not merely because it creates another brand mention.

    Treat off-site evidence as part of product information

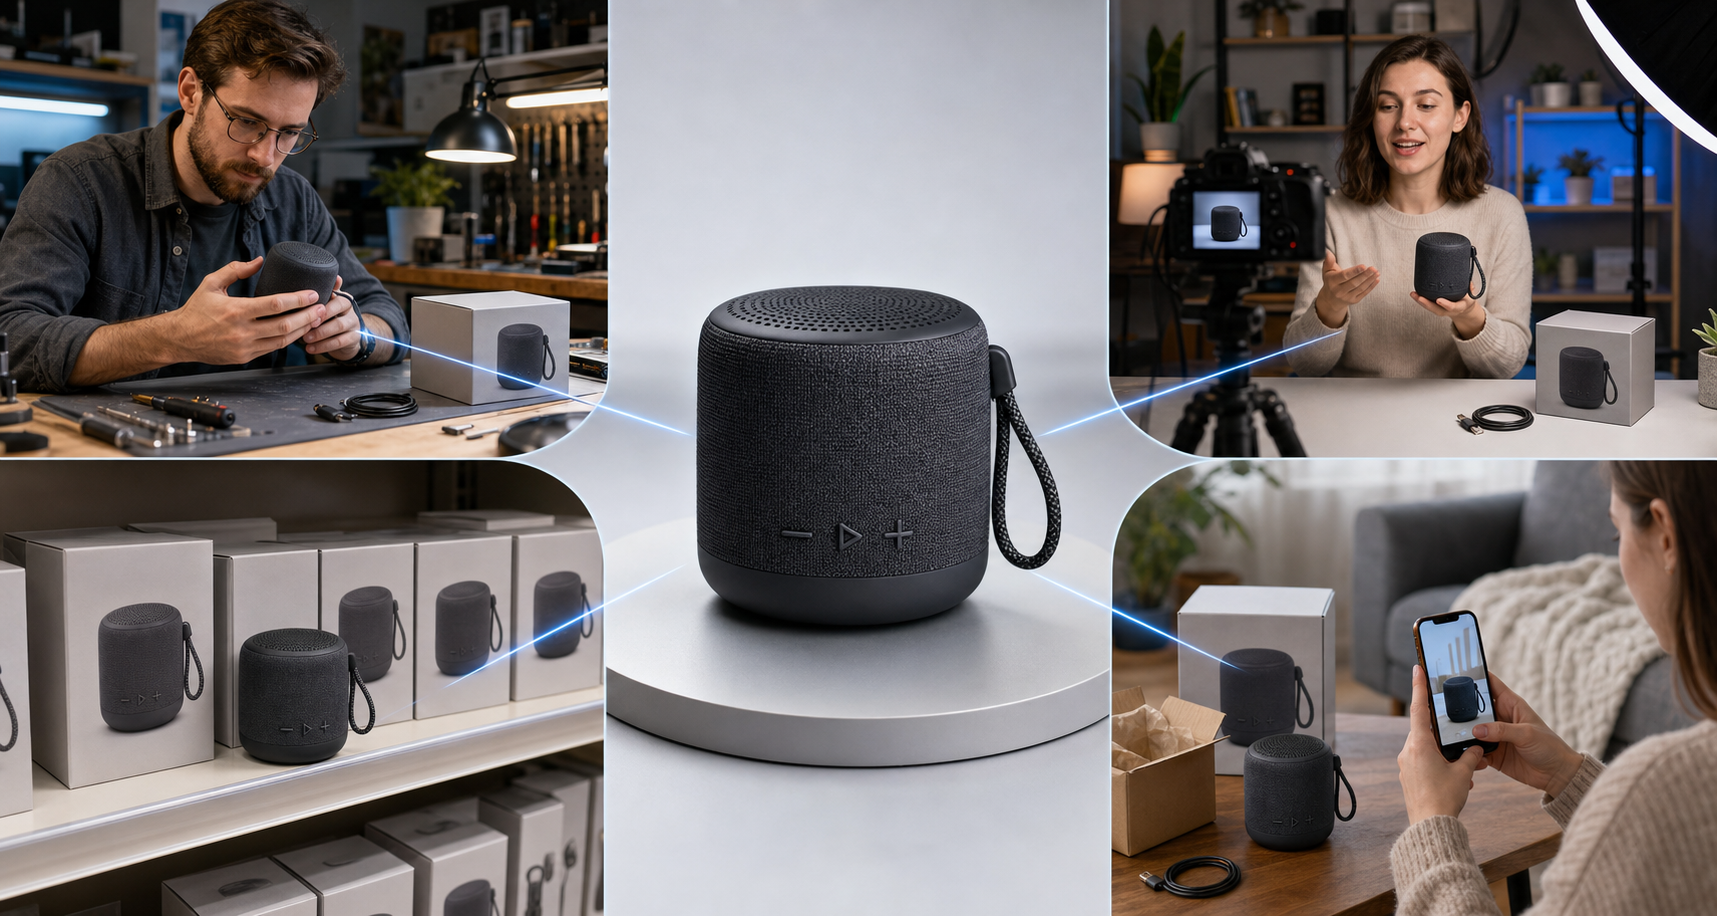
    An unbranded device is connected to scenes of a reviewer, video creator, retailer display, and customer photo.

    Your website can declare what a product does. It cannot independently establish how the product behaves in ordinary use or how buyers feel about its compromises. AI shopping answers often seek that corroboration elsewhere.

    Within the observed set of key off-page signals, Reddit represented 34%, YouTube 19.5%, Amazon 15.5%, Business Insider 9.2%, and Walmart 8.9%. Treat these figures as evidence of concentrated influence in the examined responses, not as channel budgets or universal weights.

    Each environment contributes a different kind of evidence:

    • YouTube can show setup, scale, sound, motion, results, and other experiential details that are difficult to communicate in a specification table. Use accurate titles and descriptions, identify the exact model, and make spoken explanations clear enough to stand without promotional visuals.
    • Retailer and marketplace listings connect the product to a category, seller, price, reviews, and comparable inventory. Keep identifiers, variants, specifications, and images consistent with your own site.
    • Review coverage organizes alternatives and makes tradeoffs explicit. Give reviewers enough factual material to distinguish models without forcing them to decode your catalog.
    • Community conversations reveal recurring questions, edge cases, frustrations, and unexpected use cases. Use those conversations to improve product information and support. Do not simulate participation or manufacture endorsements.

    Consistency is the operational priority. If your site calls a product one name, a retailer shortens it, a video uses a family name, and marketplace variants omit the model number, you have created several weak identities instead of one strong one. Maintain a shared product record containing the approved name, model identifier, category, key specifications, variant labels, current imagery, and canonical URL. Give every channel owner access to it.

    Do not turn this into a backlink-counting exercise. A mention that does not help identify, compare, or verify the product contributes little to the shopping decision. Audit off-site presence by question instead: Where can a shopper see the product used? Where can they compare it with the nearest alternative? Where can they verify specifications? Where can they find credible discussion of its limitations?

    Run a two-phase AI visibility operation

    Black Friday AI optimization should operate in a preparation phase and a live phase. The preparation phase builds retrievable facts and comparison context. The live phase protects accuracy while offers, availability, and public conversation change.

    Before the promotion, build a fixed prompt set from customer decisions rather than from your target keywords alone. Include category discovery, a constrained use case, a direct product comparison, a compatibility question, a value question, and a deal-verification question for every priority category. Keep the wording stable enough that later results are comparable.

    Run those prompts separately on the AI platforms your customers are likely to use. Do not collapse their responses into one score. In the observed Black Friday sample, Gemini responses averaged 606 words, OpenAI responses averaged 401, and Perplexity responses averaged 288. Those are sample characteristics, not permanent product specifications, but they show why a citation or mention can play a different role on each platform.

    Use one tracking row for each prompt and platform. Record:

    • The exact prompt, model or product name, and time of the check.
    • Whether the brand and correct product appear.
    • How the product is framed: recommended, compared, merely listed, or excluded.
    • Which URLs support the answer.
    • Whether the price, specifications, seller, availability, and promotion terms are accurate.
    • Which competitor or third-party page supplied information you did not make easy to find.
    • The correction required: page content, structured data, marketplace data, comparison coverage, video, or support documentation.

    At sale launch, rerun the deal and verification prompts. Repeat the check after any material price, inventory, seller, or terms change. If an answer is wrong, correct the authoritative page and connected listings first. A prompt variation may produce a different answer, but it does not repair the underlying information conflict.

    Judge progress by failure mode rather than by a single visibility number. A missing brand is a discovery problem. The wrong model is an identity problem. An incorrect price is a freshness problem. A competitor winning every comparison may indicate weak decision content or stronger independent corroboration. Each diagnosis leads to different work.

    Key takeaways

    • Plan separately for pre-sale research and live deal verification because the source mix changes when Black Friday begins.
    • Give every priority offer a clear identity, complete decision facts, current commercial terms, and evidence a shopper can verify.
    • Build comparisons around use cases and tradeoffs, not unsupported claims that a product is “best.”
    • Coordinate product information across your site, retailers, marketplaces, video, review coverage, and community support.
    • Test the same customer decisions across AI platforms and classify failures before choosing a fix.

    Before your next promotion, choose one prompt for each major customer decision in your highest-value category. Run the set when product pages are frozen, again when the sale launches, and whenever a material offer fact changes. The gaps you find will give your content, merchandising, SEO, marketplace, and communications teams a concrete Black Friday worklist – before shoppers ask AI to make the choice for them.

    References

  • How to Protect Search Visibility Through Google and AI Shifts

    How to Protect Search Visibility Through Google and AI Shifts

    Your organic traffic drops during a Google update, while AI answers mention competitors and sometimes describe your brand incorrectly. The tempting response is to rewrite everything. That usually destroys the baseline you need to work out what actually changed.

    You need a diagnosis before you need a recovery campaign. The practical approach is to separate short-term ranking volatility from page-level relevance problems, entity confusion, and the slower process of becoming a dependable source for AI systems.

    Treat an update rollout as an observation window, not a verdict

    Core updates change broad ranking systems rather than applying a simple penalty to one page. The December 2025 release was Google’s third core update of that year, and its rollout could take up to three weeks. March and June core updates and an August spam update had already made repeated change an operating condition, not an exceptional event.

    If rankings move while a rollout is still active, you don’t yet have a settled result. That doesn’t mean you should ignore the data. It means you should preserve it and avoid attributing every movement to a content defect.

    1. Mark the timeline. Record the announced start of the update, the pages that changed, and the first date each change became visible. Keep unrelated site releases, migrations, and content edits on the same timeline.
    2. Rule out faults that cannot wait. Check whether affected URLs still load, remain indexable, return the intended status, and are accessible to crawlers. An accidental noindex directive, broken canonical, blocked resource, or server failure should be fixed immediately.
    3. Segment the movement. Break the loss down by page type, topic, query intent, country, device, and branded versus non-branded demand. A sitewide average can hide one damaged template or one declining topic cluster.
    4. Save the pre-edit baseline. Export page and query data before changing titles, copy, internal links, or templates. Without that record, you cannot distinguish recovery from normal volatility.
    5. Delay broad conclusions until the rollout settles. Continue publishing and fixing verified defects, but postpone mass rewrites, deletions, and structural changes made solely in reaction to daily ranking movement.

    Read the metrics as clues, not diagnoses. Falling impressions and positions across a related group of pages point toward a relevance or competitiveness problem. Stable positions with fewer clicks call for a closer look at result presentation, query demand, and search features. One template disappearing while the rest of the site holds steady calls for a technical check before a content review.

    Google’s standing position is that a core-update decline does not automatically mean a page is defective and that there is no single recovery action. Improvements can be recognized between core updates, although larger changes may become visible after a later update. Set expectations accordingly: make changes because the diagnosis supports them, not because an update created pressure to look busy.

    Diagnose search, entity, and AI visibility separately

    Three separate workstations display page tiles, connected identity nodes, and abstract AI response shapes while an investigator compares them.

    Search visibility now depends on three connected systems that operate at different speeds. Traditional search engines retrieve current web information. Knowledge graphs organize facts about entities and their relationships. Large language models synthesize information into conversational answers. A brand can be healthy in one layer and weak in another.

    The operating horizons are different as well: search improvements may affect near-term discovery, knowledge-graph education can take months, and durable representation in LLM knowledge can take years. Treating all three as one SEO score produces bad priorities.

    Visibility layerQuestion to answerEvidence to inspectBest next move
    Traditional searchCan the right page be crawled, understood, and ranked for the current query?Indexing, impressions, positions, clicks, affected queries, page groups, and competing resultsRepair technical access, intent alignment, content usefulness, or internal discovery
    Entity and knowledge graphCan systems identify the organization, people, products, and relationships correctly?Conflicting names, descriptions, ownership details, profile facts, structured data, and third-party corroborationEstablish one canonical fact set and make every machine-readable claim agree with visible content
    LLM and AI answersCan an assistant accurately include, explain, cite, or recommend the brand for the relevant task?Repeatable prompt tests, factual accuracy, brand inclusion, cited pages, and consistency across answer variantsStrengthen the underlying entity record and publish information that can be extracted and supported

    This separation prevents a common category error. If Google still ranks your pages but an AI assistant misstates your company, rewriting a high-performing page around more keywords is unlikely to solve the identity problem. If your brand facts are consistent but a commercial page loses non-branded rankings, an organization-wide entity project should not replace a page-level relevance audit.

    AI answers also need their own measurement discipline. Save the exact prompt, model, date, answer, cited URLs, and whether your brand appeared accurately. One favorable answer is an observation, not a trend. Reuse a fixed set of prompts so that changes in wording do not masquerade as changes in visibility.

    Repair relevance without chasing the update

    Once a decline remains visible after the rollout and technical checks are clean, work at the level where the evidence concentrates. If one topic cluster lost visibility, audit that cluster. If one page type fell, inspect its template and purpose. A domain-wide rewrite is justified only by domain-wide evidence.

    1. Define the searcher’s job. Write down what the affected query asks the reader to understand, decide, compare, or complete. Then check whether the page performs that job without forcing the reader through a long preamble.
    2. Compare the promise with the delivery. The title and search snippet create an expectation. The opening, headings, and main answer must satisfy the same intent. A compelling title cannot rescue a page that answers a neighboring question.
    3. Locate the information gap. Check whether the page gives a direct answer, explains the mechanism behind it, covers the important limitations, and supplies enough evidence for the reader to verify consequential claims.
    4. Make accountability visible. Show who created or reviewed the content, why that person or organization is qualified, when meaningful changes were made, and where factual claims come from. Treat authority, notability, and transparency as audit questions, not as invented ranking factors.
    5. Resolve internal competition. When several pages perform the same job, decide which one should be canonical. Differentiate pages that serve distinct intents. Consolidate genuine duplicates carefully, and redirect a retired URL to the appropriate surviving resource rather than simply deleting accumulated value.
    6. Reduce extraction friction. Use descriptive headings, explicit names, concise definitions, coherent internal links, and structured data that matches what a person can see. Machines should not have to infer whether two slightly different names refer to the same entity.
    7. Update substance, not timestamps. Correct outdated facts, improve weak explanations, and remove unsupported claims. Changing a date without materially improving the page gives readers and machines no new reason to trust it.

    People-first content is not a license to ignore retrieval. A useful page still needs to be accessible, clearly scoped, internally connected, and written in language that makes its main claims easy to identify. Technical clarity and human usefulness reinforce each other.

    Avoid using word count as a repair target. More text can make the answer harder to retrieve and harder to trust. Add material only when it closes a real information gap: a missing condition, an unexplained decision, an absent method, or evidence the reader needs before acting.

    Build a brand record that AI systems can reuse

    A faceted ceramic object is documented and repeated consistently across blank archival materials and a glowing network of connected nodes.

    Page optimization helps a system retrieve an answer. Entity optimization helps it understand who supplied that answer. You need both. The goal is to create a consistent, corroborated record of the brand rather than repeat a slogan across hundreds of pages.

    1. Create a canonical fact inventory. Record the preferred organization name, concise description, official domain, principal offerings, relevant people, locations, and important relationships. Mark which page is authoritative for each fact.
    2. Publish stable identity pages. Your organization, about, author, product, and contact pages should state their purpose plainly. Keep durable facts separate from campaign language that changes frequently.
    3. Align visible and structured claims. JSON-LD should describe the content on the page, not introduce a second version of reality. Conflicting names, URLs, roles, or descriptions increase ambiguity. Structured data can clarify a trustworthy fact; it cannot manufacture authority for an unsupported one.
    4. Connect entities deliberately. Make the relationships among the organization, authors, products, services, and subject areas explicit in copy, navigation, internal links, and structured data. Do not rely on proximity or branding alone to communicate the relationship.
    5. Seek relevant corroboration. Accurate independent mentions, profiles, citations, and references help systems verify that the brand’s self-description is not the only available account. Correct contradictions at their origin when possible instead of adding more duplicate claims to your own site.
    6. Publish citation-ready knowledge. Give important topics stable URLs, direct definitions, clear methods, named ownership, and inspectable evidence. If a claim is an opinion or company position, label it as such. If it is factual, make the support easy to follow.
    7. Audit machine representation. Test how search results and AI assistants identify the brand, explain its offerings, and associate it with relevant topics. Log factual errors separately from simple absence: correcting a wrong identity requires different work from earning consideration for a new topic.

    This is algorithmic education in practical terms: consistently presenting connected facts that search systems can discover, reconcile, and reuse. It is not a prompt trick, and it does not guarantee inclusion in a model’s training data. Training inclusion is a long-term outcome that you cannot force or confirm from a single AI response.

    Your intermediate measures should therefore stay observable. Track whether canonical facts agree across owned pages, whether relevant third parties corroborate them, whether search engines retrieve the intended pages, whether AI answers become more accurate, and whether repeated prompt tests show more stable inclusion. Those indicators won’t prove that a model has learned the brand permanently, but they will reveal whether the evidence environment is improving.

    Key takeaways: run one visibility program at three speeds

    • During a core-update rollout, preserve your baseline, fix verified technical faults, and avoid broad edits based on unsettled movement.
    • Diagnose traditional rankings, entity understanding, and AI-answer visibility as separate layers with different evidence and timelines.
    • Apply content repairs to the page type or topic cluster where the loss is concentrated instead of rewriting the whole site.
    • Use structured data to clarify visible, supported facts. It is not a substitute for consistent identity, useful content, or outside corroboration.
    • Measure AI visibility with a fixed prompt set and a log of models, dates, answers, citations, and factual errors.
    • Expect page-level search work to operate faster than knowledge-graph development, while durable LLM representation remains a long-term objective.

    Turn this into a routine. During a confirmed rollout, save a daily snapshot without making a daily strategic decision. After the result settles, review affected page groups weekly while improvements are in progress. Check canonical brand facts monthly, and run the same AI prompt set on a regular schedule that your team can maintain.

    Start with one important topic cluster. Export its current search baseline, identify whether the failure sits in retrieval, relevance, entity understanding, or AI representation, and make the smallest change that addresses that diagnosis. That gives you a result you can evaluate and a method you can repeat when the next shift arrives.

    References

  • How to Expand an AEO Strategy Across Markets and Industries

    How to Expand an AEO Strategy Across Markets and Industries

    Your AEO playbook is producing useful answers in one market. Then the expansion request lands: take it into a new country, a new industry, or an agency-wide client portfolio. The tempting response is to duplicate content, translate keywords, and add locations to the dashboard. That scales output. It does not necessarily scale answer quality.

    With zero-click discovery becoming central to AEO, expansion depends on whether an answer engine can identify your entity, understand your answer, and find credible support for it under a different set of market conditions. You need a system that preserves factual consistency while allowing questions, terminology, evidence, and search platforms to change.

    Give the expansion one primary axis

    Start by deciding what is actually expanding. Geography, industry, client type, and product scope are different variables. Change all of them at once and you will struggle to identify why an answer performs well, fails to appear, or appears with the wrong context.

    Choose one primary axis for the first expansion unit:

    • Geographic expansion: the offering stays largely stable, but language, search behavior, platform mix, availability, and evidence may change.
    • Industry expansion: the market may stay stable, but buyer questions, terminology, use cases, proof requirements, and decision criteria change.
    • Portfolio expansion: an agency or enterprise team applies one operating method across brands, business units, or clients with different entity structures.
    • Product expansion: the audience may be familiar, but the claims, comparisons, limitations, and supporting evidence are different.

    An expansion unit should be narrower than a country or a broad vertical. “Healthcare” is not an operating unit. A defined audience evaluating a defined type of solution for a defined decision is. That tighter boundary tells you which questions belong in the prompt set, which claims require evidence, and who can approve the answers.

    Put the unit into a short expansion brief before commissioning content:

    • Audience: who is asking, buying, recommending, or implementing?
    • Decision: what are they trying to understand or choose?
    • Entity: which company, product, service, person, or location must an answer engine identify correctly?
    • Claim set: which facts can remain global, and which vary by market or industry?
    • Discovery environment: which AI interfaces and search engines does this audience actually use?
    • Owner: who validates the content, evidence, technical implementation, and measured result?

    If you cannot fill those fields without phrases such as “all prospects” or “all AI platforms,” the unit is still too broad.

    Separate the portable answer system from local decisions

    An isometric modular system has a stable central core connected to interchangeable components for different local environments.

    A scalable AEO program does not force every market to publish identical pages. It standardizes the parts that protect accuracy and measurement, then gives local owners explicit control over the parts that genuinely differ.

    LayerKeep consistentAdapt when justified
    Entity factsOfficial names, relationships, ownership, and product scopeAliases, scripts, transliterations, local availability, and locally used names
    Answer patternA direct response, supporting explanation, evidence, and clear limitationsQuestion wording, terminology, examples, and market-specific context
    Evidence policyEvery material claim has an owner and a verifiable basisThe most relevant locally valid evidence and citation targets
    Schema policyMarkup reflects visible content and consistent entity relationshipsLanguage, location, availability, and other properties that truly differ
    MeasurementDefinitions for presence, citation, accuracy, market fit, and actionabilityThe prompt set, engine mix, interface, and language used for each market

    Build an answer brief for every priority question. It should contain the exact question, a short standalone response, the explanation needed to support it, the underlying claim, the evidence location, the claim owner, relevant limitations, the target entity, and the next useful action for the reader. This becomes the common object that content, schema, review, and measurement teams work from.

    AEO execution commonly joins relevant schema, trust signals, and citation tactics, but those components have different jobs. Structured data clarifies entities and relationships. Visible evidence supports the claim. Clear prose supplies the answer. Treat citation as an earned outcome, not as something a schema property can compel.

    That distinction prevents a common failure: technically elaborate markup attached to thin or ambiguous content. Mark up what the page actually establishes. If a qualification, relationship, availability statement, or answer is absent from the visible content, adding it only to structured data does not repair the underlying information.

    Maintain a claim ledger alongside the answer briefs. Each row should identify the claim, evidence, owner, markets where it is valid, pages that use it, and the event that should trigger review. When a product changes or a local team discovers an exception, you can update every affected answer without relying on memory.

    Localize discovery conditions, not just vocabulary

    One glowing question signal follows different paths through a home, a research workspace, and a mobile urban setting before reaching the same answer form.

    A translation can be linguistically correct and still miss the question a buyer asks, the entity name an engine recognizes, or the evidence the market trusts. Localization starts before drafting, with discovery research in the target environment.

    Dragon Metrics built its international footprint by supporting brands and agencies in more than 50 countries, with particular strength across markets such as China, Korea, and Japan. The practical lesson is that a Google-only view cannot be assumed to represent every market. Your expansion brief must name the actual engines, AI interfaces, languages, and result formats relevant to the audience.

    Create a market discovery sheet with these fields:

    • Question language: native phrasing, abbreviations, category terms, and the words used at different stages of the decision.
    • Discovery surfaces: the search engines, assistants, AI answer features, and industry platforms where the audience asks those questions.
    • Entity variants: official names, common aliases, transliterations, parent-company relationships, and product naming differences.
    • Offer boundaries: features, support, availability, or terms that differ from the original market.
    • Evidence environment: which internal documents and external pages can substantiate each locally relevant claim.
    • Local validator: the person who can reject wording that is technically translated but commercially or factually wrong.

    Use the sheet to rebuild the question set rather than merely translating the original prompts. Preserve the intent, then test several natural ways a local user might express it. A single prompt is not a market, and one favorable output is not a repeatable result.

    Apply the same discipline to structured data. Keep stable entity identifiers and relationships consistent, but do not copy market-specific properties blindly. The page copy, schema, internal links, availability statements, and supporting evidence should describe the same local reality. Contradictions between those layers create an interpretation problem that more markup cannot solve.

    Finally, test for the wrong-market answer. A brand mention can look like success while recommending an unavailable product, citing evidence from another jurisdiction, or describing the wrong business entity. Market validity therefore needs its own review field; it should not be hidden inside a generic visibility score.

    Make the operating model part of the AEO design

    Expansion changes who knows the audience, who owns the data, and who is allowed to approve a claim. An office, acquisition, reseller network, or regional partner can add proximity and capability, but none of them automatically creates a consistent answer system.

    Profound positioned its London office as a way to work closer to UK clients and partners. That kind of local presence can shorten feedback loops, provided the regional team has a defined route for turning what it learns into revised questions, evidence, and content.

    Acquisition creates a different integration problem. Semify’s announced plan for Dragon Metrics kept the platform operating as an independent brand while combining engineering capability and product leadership. AEO teams face the same design choice at a smaller scale: decide which systems must converge and which local strengths should remain intact.

    Choose an operating model deliberately:

    • Centralized: one team controls questions, content, schema, and reporting. This protects consistency but can make local validation a bottleneck.
    • Hub and spoke: a central team owns definitions, templates, entity rules, and measurement; local teams own phrasing, market facts, evidence, and final validation.
    • Federated: regional or industry teams run their own programs under a shared minimum standard. This supports local speed but needs strong claim and entity governance to prevent drift.
    • Integrated capability: an acquired platform or specialist partner retains useful workflows while selected data, engineering, or reporting layers are connected to the wider system.

    We would use hub and spoke as the default when the product truth is global but the questions and proof are local. The central team should not rewrite language it does not understand, and the local team should not redefine global product facts without approval.

    Assign a named owner to each decision, not merely to each department:

    • The claim owner approves what may be stated and where it is valid.
    • The market owner validates terminology, intent, local applicability, and evidence.
    • The technical owner verifies rendered content, structured data, entity consistency, and discoverability.
    • The measurement owner maintains the prompt set, capture method, definitions, and change log.

    This prevents a familiar handoff failure in which content assumes schema will add meaning, technical teams assume claims were approved, and reporting teams measure prompts that local buyers never use.

    Launch with a fixed baseline and separate measures

    Traditional rankings remain useful context, but they cannot tell you whether an AI answer mentioned the correct entity, cited adequate evidence, described the right market, or sent the user toward a useful next step. Measure those outcomes separately.

    Create one row for every prompt captured in every measurement run. Record the exact prompt and language, target market, interface used, capture date, entity presence, context of the mention, cited URLs, factual claims made, validation result, and available action path. Preserve the output or a reproducible record of it so reviewers can inspect why a row passed or failed.

    Use clear internal definitions:

    • Prompt coverage: the share of eligible tracked prompts where the intended entity appears in a relevant context.
    • Citation incidence: the share of eligible prompts where the response cites a page that supports the relevant answer or claim.
    • Factual accuracy: the share of captured claims that pass validation against the claim ledger.
    • Market fit: the share of captured answers that apply to the target audience, product, and location without importing an invalid condition.
    • Actionability: whether the response gives the user an appropriate path to verify, compare, learn more, or proceed.
    • Downstream response: attributable visits, qualified actions, or business outcomes where your analytics can observe them.

    These are operating definitions, not universal industry standards. Keep their denominators and pass criteria stable within your program so changes remain interpretable. Do not compress them into one visibility score. High prompt coverage with poor factual accuracy is not a weaker version of success; it is a different and potentially damaging outcome.

    Run the expansion as a controlled sequence:

    1. Freeze a baseline prompt set for the defined audience and decision. Keep exploratory prompts in a separate set.
    2. Capture the baseline on the target market’s actual discovery surfaces before changing content.
    3. Publish a coherent question cluster with aligned answers, evidence, entity signals, internal links, and structured data.
    4. Repeat the fixed prompt set using the same capture method.
    5. Classify failures as missing presence, wrong entity, weak context, unsupported claim, poor citation, market mismatch, or unusable next step.
    6. Change the layer responsible for the failure. Do not rewrite content when the real issue is an inconsistent entity, invalid local claim, inaccessible evidence, or irrelevant prompt.
    7. Expand the question set or move into the next unit only after the workflow can reproduce accurate, market-valid answers.

    Key takeaways

    • Expand one primary variable at a time so you can tell whether geography, industry language, product scope, or governance caused the result.
    • Keep entity facts, evidence rules, schema policy, and measurement definitions stable; localize questions, terminology, platform mix, and market-specific claims.
    • Use structured data to clarify visible facts, not to compensate for vague answers or unsupported claims.
    • Measure entity presence, citation, factual accuracy, market fit, and actionability separately.
    • Give every claim, market decision, technical implementation, and measurement set a named owner.

    Take the next market or industry already on your roadmap and force it through the expansion brief before commissioning more pages. If a priority question lacks a claim owner, locally valid evidence, a target discovery surface, or a measurement row, the launch is not ready. Close those gaps first, then use the same controlled system for the next expansion unit.

    References

  • How to Track Brand Visibility Across AI Search Platforms

    How to Track Brand Visibility Across AI Search Platforms

    You ask an AI assistant for the best options in your category. Your brand appears. You change a few words, try another platform, or add a location, and it disappears. That is a useful spot check, but it is not visibility tracking.

    A defensible tracking program uses a fixed set of prompts, consistent labels, and saved answer evidence. It tells you where your brand is mentioned, whether it is recommended, which sources support the answer, which competitors occupy the same space, and whether the description is accurate. More importantly, it tells you what to fix next.

    Stop treating AI visibility like a single keyword rank

    A traditional rank tracker asks where a URL appears for a keyword. AI search often returns a synthesized answer instead of a stable list of links, and those answers may mention, recommend, or cite only a small selection of brands and sources. A position-based metric cannot describe all of those outcomes.

    Use a prompt-level definition instead: AI search visibility is your brand’s observable presence and representation across a controlled set of prompts, platforms, markets, and collection runs. The basic unit is not a keyword position. It is a platform-prompt-market observation with a saved response behind it.

    Each observation should distinguish several states:

    • Mention: The answer names your brand, product, service, or another recognized brand entity.
    • Recommendation: The answer explicitly presents the brand as a suitable choice, shortlist candidate, or conditional fit.
    • Citation: The answer links to or identifies a source associated with the brand. Record this only when the interface exposes citations.
    • Representation: The answer describes the brand favorably, neutrally, unfavorably, or with a meaningful qualification.
    • Accuracy: The claims about the brand are correct, incorrect, ambiguous, or too incomplete to evaluate.

    These states are not interchangeable. A mention can be negative. A citation can support a category fact without recommending the company that published it. A recommendation can rely on a third-party source rather than the brand’s own site. If your dashboard collapses all of them into a single visibility score, you will not know whether you have a discovery problem, an evidence problem, a positioning problem, or a reputation problem.

    That is also why a successful ChatGPT result cannot stand in for the entire market. Visibility can differ across ChatGPT, Claude, Gemini, and Perplexity. Report each surface separately before producing any aggregate view.

    Build a prompt set around real customer decisions

    Your prompt set determines what your visibility score means. If every prompt includes your brand name, the tracker measures how the systems describe a known entity. It does not measure whether the brand gets discovered when a buyer has not named it.

    Build separate prompt groups for the decisions you need to observe:

    • Category discovery: Which [category] options fit [audience or use case]?
    • Problem-led discovery: What is a good way to solve [specific problem] under [constraint]?
    • Comparison: How do [brand or product] and its alternatives differ for [use case]?
    • Requirement matching: Which options support [required capability, integration, market, or workflow]?
    • Branded validation: Is [brand] appropriate for [audience], and what are its limitations?
    • Factual verification: Does [brand] provide [specific feature, service, policy, or availability]?
    • Post-purchase help: How do users complete [task] with [brand or product]?

    Unbranded prompts measure discovery and category association. Branded prompts measure understanding, accuracy, and reputation. Keep their results separate. Otherwise, strong performance on easy branded questions can conceal absence from the category questions that introduce new buyers to a company.

    Use neutral wording. A prompt such as Why is [brand] the best choice? presupposes the result and cannot tell you whether the brand would appear naturally. Ask which options fit a defined need, then let the answer reveal the competitive set.

    Store enough metadata to reproduce each observation:

    • A stable prompt ID and the exact prompt text.
    • The intent group and business question behind the prompt.
    • Whether the brand was named in the prompt.
    • The platform and any model or search-surface label displayed to the user.
    • The market, location, and language used for the run when they matter.
    • The audience, product line, or use case being tested.
    • The prompt version and the date that version became active.

    Location deserves its own field rather than a note buried in the prompt. Tracking by location can expose market-specific gaps that disappear inside a global average. This is especially relevant when availability, terminology, regulations, service areas, or competitors differ between markets.

    Freeze the wording once a prompt enters the benchmark set. If you discover a better version, create a new version and establish a new baseline. Quietly rewriting prompts between runs makes a reporting change look like a visibility change.

    Record answer evidence, not just a visibility score

    Abstract AI response cards are organized with colored evidence markers, source tiles, and saved snapshots on a dark tabletop.

    Define every metric before collecting results. In particular, define an eligible answer as a completed response to an in-scope prompt. Log platform errors, refusals, and unavailable responses separately. Treating a failed run as a brand omission would contaminate the denominator.

    MetricOperational calculationWhat it helps you diagnoseMain caution
    Mention rateEligible answers naming the brand divided by all eligible answers in the segmentBasic discovery and entity recognitionA mention is not necessarily positive or prominent
    Recommendation rateEligible answers explicitly recommending or shortlisting the brand divided by all eligible answers in the segmentWhether the brand is presented as a viable choiceSeparate unconditional recommendations from recommendations limited by a caveat
    Citation rateEligible answers citing a brand-associated source divided by answers for which citations are exposedWhether the brand’s evidence is being selected as supportNot all interfaces expose citations; mark those cases unavailable rather than uncited
    AI share of voiceBrand mentions divided by mentions of the defined competitor set within the same prompt segmentRelative presence in competitive answersThe result depends on the prompt mix and competitor definition
    RepresentationDistribution of favorable, neutral, unfavorable, and qualified descriptionsPositioning, reputation, and recurring objectionsSave the exact claim and reason for the label; sentiment alone is too blunt
    Factual accuracyDistribution of accurate, inaccurate, ambiguous, and unevaluable brand claimsEntity consistency and misinformation riskReviewers need an approved factual reference for comparison
    Platform coveragePlatforms with an observed mention divided by platforms tested for the same prompt segmentCross-platform resilienceDo not let an aggregate hide a weak individual platform

    Citation frequency, brand visibility, AI share of voice, sentiment, and cross-platform coverage belong in the same scorecard because each answers a different question. If your tool supplies a composite visibility score, document its formula and retain the component metrics. A rising aggregate can otherwise conceal worsening accuracy or a loss of recommendations on commercially important prompts.

    Save the evidence needed to audit a result

    A row with only a yes-or-no mention field is not enough. Save the exact response, collection time, prompt version, platform label, market, citation URLs, cited domains, competitor mentions, recommendation wording, representation label, factual issues, and reviewer notes. Where the platform permits it, retain a response link or screenshot as well.

    Classify cited domains as owned, independent third-party, competitor-owned, or another relevant type. That distinction matters. An answer citing your documentation points to a different opportunity than an answer recommending your brand while relying entirely on an external review or directory.

    Human review remains important for conditional language. Suitable for small teams that do not need [capability] is not equivalent to a general endorsement. A tracker that counts both as positive recommendations may produce a clean chart and a misleading decision.

    Use a collection cadence you can reproduce

    Begin with a baseline run across the full prompt-platform-market matrix. Repeat the same matrix at a regular interval, and capture additional before-and-after runs around material content, product, or entity changes. Keep prompt versions and segments consistent during the comparison.

    Do not interpret one generated answer as a trend. Look for a pattern that repeats across related prompts, collection runs, platforms, or markets. A manual spreadsheet can establish this discipline while the prompt set is small. When the workload grows, evaluate GEO tracking tools on prompt control, raw-response retention, citation capture, platform and location segmentation, competitor grouping, historical comparisons, exports, and transparent metric definitions.

    Turn recurring patterns into specific GEO work

    A strategist turns repeated patterns from abstract AI answer chambers into website, source, location, and fact-checking work.

    Start with the pattern in the evidence, not with a general instruction to publish more. Different gaps call for different work.

    Your brand is absent from unbranded discovery prompts

    First, check whether the absence repeats across related prompts and whether competitors appear consistently. Then inspect the claims and sources used in those answers. You are looking for a missing association: a category, use case, audience, capability, problem, or market that competitors explain more clearly.

    Create or strengthen a focused page that answers the missing intent directly. State who the offering is for, which problem it solves, what it supports, where it applies, and what its meaningful limits are. Link that page to the relevant product and organization entities. Use appropriate structured data to reinforce names and relationships already visible in the content, but do not treat markup as a substitute for a clear answer.

    This is the practical meaning of expanding your semantic footprint, fact density, and entity authority: cover the relationships buyers ask about, make important claims explicit and supportable, and keep the identity of the organization and its offerings consistent.

    Your brand is mentioned but rarely cited or recommended

    A mention without a citation can indicate that the entity is recognized while its owned evidence is not being selected. Review which domains the answers do cite. If they consistently provide concise definitions, comparison criteria, specifications, or market facts that your pages obscure, improve the relevant evidence on your site and remove contradictions between pages.

    A citation without a recommendation is a different gap. Your content may be useful as evidence while the offering’s fit remains unclear. Strengthen the pages that explain the intended audience, requirements, tradeoffs, integrations, constraints, and differentiators. Do not manufacture praise. Give the system enough accurate context to determine when the brand is and is not a sensible option.

    The answer gets your brand wrong

    Record the exact incorrect claim rather than assigning only a negative sentiment label. Then identify whether your own site contains conflicting names, outdated facts, unclear availability, or ambiguous product relationships. Establish a canonical location for each important fact, correct internal contradictions, and align visible copy with structured entity information.

    If the claim comes from external coverage, the work may involve reputation management, clearer public documentation, or credible third-party corroboration. Do not try to suppress a valid limitation. Explain the current position accurately and address the underlying issue where possible.

    One platform or market underperforms

    Do not rewrite the entire site because one surface produced a weak answer. Confirm that the same prompt, language, location, and evaluation rules were used. Compare the source types and competitor claims selected by the stronger and weaker platforms. A platform-specific gap may point to missing evidence in the sources that surface retrieves, while a market-specific gap may point to unclear local availability, terminology, or entity information.

    Prioritize changes using business impact, repeatability, evidence, and control. A recurring absence on important unbranded prompts is more actionable than an isolated wording difference. A verified factual error on a decision-stage prompt deserves attention before a minor shift in a blended score. A gap tied to a page you control can usually be addressed more directly than a change in an opaque platform behavior.

    After making a change, measure both layers. The first layer is the AI response: mentions, citations, recommendations, representation, and accuracy. The second is the business outcome available in your analytics, such as relevant referral activity, branded interest, or qualified conversions. An AI mention is evidence of visibility, not proof of revenue.

    Key takeaways

    • Track platform-prompt-market observations, not a supposed universal AI rank.
    • Separate unbranded discovery prompts from branded reputation and accuracy prompts.
    • Measure mentions, recommendations, citations, share of voice, representation, accuracy, and platform coverage independently.
    • Preserve exact prompts and raw responses so every chart can be audited.
    • Diagnose repeated patterns before choosing a content, entity, technical, or reputation fix.
    • Keep AI visibility metrics connected to business outcomes without treating a mention as a conversion.

    Your next move is simple: open a tracking sheet, choose a small but balanced set of branded and unbranded prompts, run the same set across the platforms and markets that matter, and label each answer with the definitions above. Select the clearest recurring gap, make the narrowest relevant improvement, and preserve the prompt set for the next run. Once you can explain why a metric moved and what evidence changed, you are tracking visibility rather than collecting screenshots.

    References

  • AI Marketing Operations: Move Faster Without Losing Brand Control

    AI Marketing Operations: Move Faster Without Losing Brand Control

    Your team can now generate campaign concepts, creative variants, audience-specific copy and performance summaries faster than a traditional request can move between departments. That speed is useful, but it also exposes every weak approval rule, scattered brand document and unreliable data handoff in your operation.

    The answer is not another collection of AI tools. You need an operating system that tells AI what it may do, gives it reliable brand context, checks the consequences and feeds results back into the next decision. Build that system well and you can move faster without turning brand management into a permanent cleanup exercise.

    Give AI a clear operating envelope

    AI-enabled marketing operations should begin with a workflow, not a product. AI can support personalization, predictive insight, content production, customer experience and digital presence, but those capabilities do not tell you where automation belongs in your business.

    Choose a recurring marketing job and map how it works before adding AI. If nobody can explain where the input comes from, who owns the decision or what happens when the output is wrong, automation will only make the ambiguity run faster.

    Map the complete decision path

    Document the workflow in operational terms:

    1. Trigger: Define the event that starts the work, such as a new lead, an approved campaign concept, a reporting deadline or a change in performance.
    2. Inputs: Identify the customer data, campaign data, approved claims, brand rules and channel constraints needed to make the decision.
    3. Transformation: State exactly what AI should classify, generate, summarize, predict or recommend.
    4. Decision: Name the person or rule that determines whether the output proceeds, returns for revision or stops.
    5. Action: Specify which system may be changed, which audience may receive the output and which permissions are required.
    6. Evidence: Record what was produced, what was approved, what changed and what business or brand outcome followed.

    This map separates useful automation from vague ambition. Generate variants is not a workflow. Generate channel-specific variants from an approved concept, verify every claim, send them to a named reviewer and retain the final edits is a workflow.

    Grant autonomy according to consequence

    A positionless marketing model can bring data, creativity and optimization into the same working loop. It does not mean every marketer should receive unrestricted access to customer records, publishing systems or campaign budgets. Faster execution still needs explicit decision rights.

    • Draft: AI creates an internal brief, summary or variation. Nothing reaches a customer or changes a live system.
    • Recommend: AI proposes a segment, route, response or optimization. A named person accepts or rejects it.
    • Execute within rules: The workflow performs a reversible action inside approved conditions, such as normalizing a tracking value or sending an exception into the correct queue.
    • Escalate: The workflow stops when data is missing, a claim lacks support, a request falls outside policy or an action could create material cost, legal exposure or reputational damage.

    Attach an owner to every level. The owner is accountable for the live workflow even if a vendor model, automation platform or specialist built part of it. AI can propose a budget change, for example, but it should not receive permission to spend beyond an approved rule merely because its recommendation sounds confident. Keep consequential actions behind human approval until you have reliable evidence that the narrower automation behaves as intended.

    This approach removes unnecessary handoffs while preserving specialist judgment. A marketer may be able to retrieve data, create assets and orchestrate a journey independently, while security, legal, analytics and brand specialists still define the boundaries that protect the business.

    Turn brand standards into system inputs

    Color swatches, textures and image samples pass through modular sorting chambers and emerge as a consistent family of campaign designs.

    A conventional brand guide is usually written for a person who can interpret context. An AI workflow needs more explicit instructions. Telling a model to sound clear, premium or human leaves too much room for interpretation, especially when different teams use different prompts and different versions of the brand rules.

    Create a machine-usable brand control pack. It should be short enough to retrieve for each task, structured enough to validate and owned by someone who can resolve conflicts.

    • Brand identity: Approved name, description, product names, product relationships and the URLs that represent the business.
    • Audience definitions: Who each message is for, what that person is trying to accomplish and which assumptions the copy must not make.
    • Message hierarchy: The primary promise, supporting themes and the distinction between an approved message and a claim that requires evidence.
    • Claim ledger: Approved wording, supporting evidence, permitted channels, restrictions, owner and review status. If a claim is absent or out of date, the workflow should flag it instead of improvising.
    • Voice rules: Concrete instructions for sentence length, terminology, point of view, tone and calls to action, supported by accepted and rejected examples.
    • Visual rules: Approved assets, treatments, layouts, accessibility requirements and prohibited combinations.
    • Channel constraints: What may change across ads, social posts, landing pages, email, search content and AI-facing brand descriptions.
    • Escalation rules: Topics, audiences, claims or actions that always require review by brand, legal, compliance, security or another accountable specialist.

    Do not hide this information in one large prompt that nobody owns. Store the control pack as versioned, reusable components. A creative workflow may need voice, visual and claim rules. A reporting workflow may need metric definitions and approved interpretations instead. Supplying only the relevant context makes conflicts easier to detect and revisions easier to govern.

    Record the version used for every externally visible output. When brand guidance changes, you can then identify which campaigns used the old rule and decide whether they require correction. Without that record, a policy update changes future prompts but leaves you unable to trace earlier decisions.

    Test the rules with adversarial examples

    Before connecting the workflow to a live channel, give it difficult examples from the work it will actually encounter:

    • A request that contains an unsupported performance claim.
    • A source asset that uses an obsolete product name.
    • Two brand instructions that point toward different tones.
    • An audience request that would require unavailable personal data.
    • A prompt asking the model to ignore the review process.
    • An input with missing campaign, market or channel context.

    The correct result is not always polished copy. Sometimes it is a refusal, a clarification request or an exception ticket. Treat those outcomes as signs that the control system is working.

    Build workflows around failure-safe boundaries

    Abstract campaign assets move through automated checks, a human review bay and a quarantine chamber in a branching workflow system.

    The best first workflow is frequent, bounded and reversible. Practical candidates already include lead enrichment and routing, UTM normalization, performance reporting and creative variation. Each has a visible input and output, but each needs a different automation boundary.

    WorkflowSafe starting boundaryMandatory checkUseful signal
    Creative variationGenerate variants only from an approved concept, asset set and claim ledger.Review factual accuracy, brand voice, visual treatment and channel suitability before publication.Approval without revision, reasons for rejection and performance by approved variation.
    Lead enrichment and routingRecommend or perform routing inside documented segments; send uncertain records to an exception queue.Check data permission, route quality, duplicate handling and whether the receiving team can act on the record.Reroutes, unresolved exceptions and downstream lead quality.
    UTM normalizationApply deterministic mappings to known values; quarantine unknown or conflicting values.Confirm that raw parameters are preserved and that normalized values match the analytics taxonomy.Invalid values, quarantined records and attribution completeness.
    Performance reportingRetrieve and structure platform metrics, then draft a summary without changing campaigns.Reconcile the underlying data and separate observed changes from AI-generated explanations.Data discrepancies, corrected interpretations and decisions produced by the report.
    AI search visibility monitoringTrack a stable set of relevant questions, audiences and competitors before recommending content changes.Inspect the underlying answers and distinguish a missing mention from an inaccurate or unfavorable brand narrative.Relevant mentions, description consistency, competitor gaps and recurring factual errors.

    Place human review where an error becomes consequential

    A generic human-in-the-loop requirement is too vague to govern anything. Name the reviewer, the exact evidence they see and the decision they are expected to make. A brand reviewer should not be asked to verify data extraction they cannot inspect. An analyst should not become the final authority on a legal claim simply because the claim appeared in a report.

    Separate the checks so failures have an owner:

    • Input validity: Are required fields present, current and permitted for this use?
    • Factual validity: Does every material claim trace to approved evidence?
    • Brand validity: Does the output use the correct identity, message, voice and visual rules?
    • Operational validity: Is the destination correct, is the action permitted and can it be reversed?
    • Measurement validity: Can the result be attributed to this workflow without confusing correlation with causation?

    Do not let the same AI output serve as both the work and its only approval. Automated checks can catch missing fields, prohibited terms, malformed links and taxonomy mismatches. A model can also highlight possible inconsistencies. Neither is a substitute for an accountable reviewer when an error could affect customers, public claims, regulated content or material spend.

    Design the failure path before the happy path

    Workflow automation often depends on APIs, JSON payloads, authentication and platform-specific integrations. That flexibility introduces real implementation and security work, and a misconfigured system can expose data or behave differently when an integration is incomplete.

    • Give each connector only the permissions required for its task.
    • Preserve the original input before normalizing or enriching it.
    • Prevent the same event from creating duplicate sends, records or campaign changes.
    • Route malformed, ambiguous and policy-breaking inputs into an exception queue.
    • Alert a named owner when a dependency fails or an error repeats.
    • Keep a readable log of the trigger, data version, brand-rule version, model or tool used, output, approval and final action.
    • Provide a kill switch and a documented rollback path before enabling live execution.

    These controls are not administrative decoration. They determine whether a problem remains one rejected draft or becomes a large batch of off-brand assets, incorrectly routed leads or corrupted attribution data.

    Measure the operation, not the volume of AI output

    Counting prompts, generated assets or automated tasks rewards activity. It does not show whether marketing improved. Your scorecard needs to connect operational speed with quality, business performance and brand representation.

    • Flow health: Track cycle time, queue time, failed runs, repeated attempts, manual interventions and unresolved exceptions.
    • Output quality: Track approval without revision, edit reasons, unsupported claims, data corrections and brand-rule violations.
    • Business outcome: Use the outcome the workflow is meant to affect, such as qualified demand, campaign efficiency, completed journeys or another metric your business already owns.
    • Brand outcome: Monitor whether approved identity, positioning and claims remain consistent across channels.
    • AI visibility: Examine whether relevant AI answers mention the brand accurately, represent its solution consistently and expose recurring competitor or messaging gaps.

    Specialized AI visibility platforms can provide persona-level, competitor-level and brand-narrative views. Treat those outputs as diagnostic evidence, not proof that one content change caused an AI model to respond differently. Keep the question set and evaluation method stable enough to distinguish a real pattern from ordinary answer variation.

    Capture a baseline before automation. When an A/B test is appropriate, define the primary outcome, guardrail metric, assignment method and stopping rule before launch. When controlled testing is not practical, compare like-for-like work and document other changes that could explain the result. A faster workflow that produces more corrections or weaker campaign outcomes is not an improvement.

    Buy tools for replaceability

    AI products and features change quickly, so avoid making the operating model depend on one vendor’s interface or a long commitment before the workflow is proven. Caution around long-term contracts is especially sensible while the toolset continues to evolve.

    Evaluate a tool against the system you need, not the most impressive demonstration:

    • Can you export prompts, templates, outputs, evaluations and logs in usable formats?
    • Can you replace the underlying model without rebuilding the entire workflow?
    • Does it support the authentication, access controls and data handling your systems require?
    • Can reviewers see the input, evidence and transformation behind an output?
    • Can failed actions retry safely without duplicating work?
    • Does it integrate with the systems that hold your actual campaign, customer and brand data?
    • How does cost change when usage moves from evaluation to routine production?
    • Can you disable it and return to a documented manual process?

    Use the same evaluation set when testing alternatives: representative inputs, edge cases, prohibited requests and previously rejected outputs. Score correctness, brand fit, required editing, operational reliability and total workflow cost. This makes a tool change an evidence-based decision rather than a reaction to a new feature announcement.

    Keep a shared workflow library and changelog as well. Record changes to prompts, brand rules, models, integrations, permissions and review steps. Regular knowledge-sharing matters because an improvement discovered by one campaign team should not remain trapped in that team’s private prompt history.

    Key takeaways

    • Start with a recurring workflow and define its trigger, inputs, decision owner, action and evidence before selecting an AI tool.
    • Grant AI more autonomy only when the action is bounded, reversible and covered by explicit escalation rules.
    • Convert brand guidance into versioned identity, audience, message, claim, voice, visual and channel controls that workflows can retrieve and validate.
    • Place named reviewers at the point where an error would affect a customer, public claim, regulated message, live system or material spend.
    • Measure cycle time and automation reliability alongside factual accuracy, brand consistency and the business outcome the workflow exists to improve.
    • Favor portable workflows, exportable records and reversible vendor commitments so the operation survives changes in models and tools.

    If your governance is still new, begin with a workflow whose mistakes are easy to detect and reverse, such as UTM normalization or a draft-only reporting summary. Define the baseline, brand context, exception path and owner, then run it on representative work before allowing a live action. The goal is not maximum autonomy. It is the smallest reliable loop that helps your team learn safely and earn the next level of autonomy.

    References

  • AI Search Visibility: Measuring Citations and Referral Value

    AI Search Visibility: Measuring Citations and Referral Value

    Your analytics can show no traffic at the exact moment an AI answer starts putting your brand into a buyer’s consideration set. The inverse happens too: a citation looks impressive in a visibility tracker but sends no qualified visitor and supports no observable decision.

    The fix is not to choose between citations and traffic. You need a measurement chain that separates presence, citation, referral, and commercial value. Once those signals have distinct definitions, you can see where your visibility is working, where the journey stops, and what to improve next.

    A citation is not a click, and a mention is not a citation

    AI search visibility is often compressed into one score. That hides four different events:

    • A mention occurs when an answer names your brand, product, expert, or other identifiable entity.
    • A citation occurs when the answer attributes information to your domain or links to one of your URLs.
    • A referral occurs when a person follows an AI-generated link and reaches your site in a way you can observe.
    • An outcome occurs when that visitor completes a meaningful action, such as starting a trial, requesting a quote, buying a product, subscribing, or entering a qualified sales process.

    These events do not always happen in sequence. An answer can mention your brand without linking to it. It can cite a supporting page without naming the brand prominently. A person can encounter your brand in an answer, return later through branded search, and leave no direct AI referrer. A crawler or agent can also retrieve a page without producing a human visit.

    Choose the primary metric from the job you expect the content to do. For discovery content, measure whether the brand appears accurately in relevant answers. For evidence-led content, measure citation coverage and the contexts in which the page is used. For decision pages, measure qualified referrals and outcomes. Do not grade all three content types against the same click target.

    This distinction matters because generative systems can handle much of the early research journey before a person reaches a website. Traditional impressions, sessions, and click-through rates therefore describe only part of the path. Pricing, comparison, product, and validation pages may receive the eventual visit, while explanatory content did the earlier work of making the brand visible.

    Build a visibility scorecard with separate denominators

    Four unlabeled measurement stations use separate containers and markers to represent appearances, citations, referrals, and commercial value.

    A useful scorecard starts with a fixed set of prompts that represents the decisions your audience actually makes. Include non-branded prompts. A test set dominated by your company name will measure retrieval of a known entity, not discovery among alternatives.

    Group prompts by intent before running them:

    • Discovery prompts ask what a problem is, why it occurs, or how to approach it.
    • Evaluation prompts ask about criteria, methods, categories, risks, or suitable options.
    • Comparison prompts weigh named alternatives, features, costs, or trade-offs.
    • Validation prompts look for reviews, evidence, limitations, implementation details, or compatibility.
    • Transaction prompts ask where to buy, what something costs, or how to begin.

    Run the same prompt set separately in each engine. Preserve the wording and record the date, engine, answer, brand mentions, cited URLs, cited domains, source type, and intended landing page. If language, location, account state, or another test condition changes, record that as well instead of mixing the results into one trend line.

    One industry analysis covered 250 million AI-generated responses. That scale is a useful warning against treating a few favorable screenshots as a baseline. Generative answers can vary, so repeat the same test design and compare like with like.

    SignalHow to calculate itWhat it tells youCommon misreading
    Mention coverageEligible prompt runs containing the entity divided by all eligible prompt runsWhether the brand enters relevant answersTreating any mention as positive without checking context or accuracy
    Owned citation coverageEligible prompt runs citing an owned domain divided by all eligible prompt runsHow often your site supplies answer evidenceCalling a citation a visit
    Citation shareUnique citations to your domain divided by all unique citations in the tested answersYour presence within the observed source setPresenting test-set share as market-wide share
    Qualified referral rateAI-referred visits meeting your quality criteria divided by all tracked AI referralsWhether arriving visitors fit the page’s intended audienceJudging value from raw sessions alone
    Outcome rateDesired outcomes divided by tracked AI referralsHow observable AI traffic contributes to the businessCrediting every later direct or branded visit to AI

    Define a unique citation consistently. Counting the same URL several times inside one answer can inflate the result, so a practical default is one occurrence per unique URL per response. Keep domain-level and URL-level views. The domain view shows authority concentration; the URL view reveals which content actually earns the citation.

    Do not roll every prompt into a single average too early. A brand may be absent from discovery prompts but dominant in transaction prompts. That is a very different problem from broad underperformance. Report by engine, intent, topic cluster, market, and source role first. Use an overall score only as a navigation aid.

    Match your source strategy to the engine and the prompt

    AI engines do not necessarily choose the same kinds of evidence for the same request. In a 2025 holiday-season analysis of tens of thousands of identical ecommerce prompts, retailer sources appeared in about 4% of Google AI Overview results and 36% of ChatGPT results. Google leaned more heavily on YouTube, Reddit, Quora, and editorial sources, while ChatGPT more often surfaced retailers, brand pages, and manufacturer pages.

    That finding is specific to ecommerce prompts from that holiday period. It is not a universal rule for B2B software, healthcare, local services, finance, or every future version of either engine. The actionable lesson is narrower: segment your citation strategy by platform and query type instead of assuming one source profile applies everywhere.

    Build a source-role map before creating more content

    For each important prompt cluster, label every recurring citation as an owned brand source, retailer, editorial publication, community discussion, video source, or another relevant category. Then look for the missing role.

    • If owned pages are repeatedly cited, identify the exact passages and page formats supporting the answers. Maintain those facts instead of replacing a successful page simply because it is old.
    • If editorial and video sources dominate, give legitimate reviewers accurate specifications, evidence, and access to the material they need. Independent coverage cannot be replaced by publishing another self-authored claim.
    • If community discussions recur, improve the underlying product information and customer experience that people can discuss. Manufactured participation creates reputation risk and does not provide durable corroboration.
    • If retailer pages dominate, make product names, variants, attributes, and purchasing details consistent across the manufacturer site and authorized listings.
    • If competitors appear through a source type you lack, close that source-role gap rather than copying the competitor’s wording.

    For retail research prompts following the observed Google pattern, an owned product page alone may not cover the sources the answer prefers. You may also need accurate independent reviews, useful demonstrations, and authentic community evidence. For ChatGPT prompts following the observed retail pattern, complete brand, manufacturer, and retailer pages deserve closer attention because those sources appeared much more often.

    Validate both patterns against your own prompt set. Platform averages are a starting hypothesis, not a substitute for sector-specific observation.

    Keep discovery content even when its clicks decline

    Across an analysis of more than 7.2 million sessions to industry blog content, pricing and cost pages showed the strongest growth, comparison content also gained, and traditional guides declined. The scope matters: this was blog performance, not every content format, and the pattern does not by itself prove that AI caused the changes.

    Deleting top-of-funnel content would still be the wrong response. Discovery material can supply the definitions, criteria, and explanations that generative engines use before a person is ready to visit. If you remove it because direct sessions fell, you may also remove the material capable of earning early mentions and citations.

    Give each content layer a clear job:

    • Discovery pages should answer a narrow question directly, state their scope, distinguish easily confused concepts, and lead to the next decision.
    • Evaluation pages should provide criteria, trade-offs, limitations, and evidence a buyer can use to narrow the field.
    • Decision pages should expose pricing, comparisons, compatibility, availability, implementation requirements, or another concrete next step appropriate to the offer.
    • Product and service pages should keep names, claims, attributes, and calls to action consistent with the supporting content that introduces them.

    Connect these layers explicitly. A cited explainer should link to the relevant comparison or decision page, while the decision page should link back to the evidence behind its claims. This gives a human visitor a coherent path even when the AI engine exposes only one page.

    Use JSON-LD as a consistency layer, not as a citation counter. Mark up entities and attributes that are visible on the page, and keep names and relationships consistent with the readable content. Deployment is not the result. The result is whether the intended entity is understood accurately, cited in the right context, and connected to a useful next action.

    Turn sparse AI referrals into commercial evidence

    Three glowing droplets pass through transparent tracking rings and illuminate objects representing an inquiry, an opportunity, and realized value.

    AI referral volume can be small while the visitors who do arrive are close to a decision. Generative systems may complete much of the discovery and evaluation work before sending a person to a pricing, comparison, calculator, retailer, or product page. Measure the quality of that arrival before deciding the channel has little value.

    Build attribution in layers:

    1. Create an analytics channel for observable AI referrers. Keep the underlying source visible so you can compare engines instead of hiding them under one label.
    2. Record the landing page, content type, engagement events, and business outcome. A visit to a decision page should not be evaluated like a visit to an explainer.
    3. Separate human referrals from bot and agent retrievals in server-side reporting. A fetch can indicate access or use, but it is not a human session and should not be counted as one.
    4. Pass the original source into your CRM or lead system when your setup allows it. This lets you inspect lead quality, pipeline progression, and revenue instead of stopping at form completion.
    5. Add a short self-reported discovery field where the value of the decision justifies the extra question. Treat the answer as complementary evidence because memory and channel overlap make it imperfect.

    Not every AI-influenced journey will carry a usable referrer. A person may see a mention, open a separate tab, search the brand, or return later. Branded search growth, direct navigation, and self-reported discovery can help you notice that spillover, but they do not prove that a particular answer caused a particular visit.

    Keep direct attribution and assisted evidence in separate columns. The first contains observable referrals and outcomes. The second contains correlated signals such as stronger branded demand following improved answer visibility. Combining them produces an impressive number but a weak decision tool.

    Evaluate referral value with metrics that reflect your business:

    • Qualified visit rate: the share of tracked AI visits that meet your engagement or audience criteria.
    • Decision-action rate: the share that completes the action the landing page was designed to support.
    • Lead acceptance or sales progression: whether AI-sourced leads remain useful after the initial conversion.
    • Observable pipeline or revenue: the commercial result tied to tracked referrals under your normal attribution rules.
    • Landing-page concentration: which pages and intent stages receive the traffic, even when total volume is limited.

    Compare equivalent journeys. An AI referral landing on a pricing page should be compared with other channels entering that pricing page or the same intent stage, not with the sitewide average. Otherwise, differences in landing intent can be mistaken for differences in channel quality.

    Use the same discipline when evaluating citations. A citation on a broad educational prompt and a citation on a named comparison prompt have different commercial proximity. Report both, but do not assign them the same expected referral value.

    Key takeaways

    • Measure mentions, citations, human referrals, machine retrievals, and outcomes as separate events.
    • Use a stable, non-branded prompt set grouped by intent, then report results by engine before calculating an overall score.
    • Count citation coverage against eligible prompt runs and define duplicate handling before collecting data.
    • Audit the source roles each engine favors. Improve owned pages where owned sources win, and earn legitimate independent evidence where editorial, video, or community sources dominate.
    • Maintain discovery content for mentions and citations while strengthening pricing, comparison, and decision pages for the visits that arrive later.
    • Judge AI referrals by qualified actions, pipeline, and revenue, while keeping unproven assisted effects in a separate evidence column.

    Start with your highest-value prompt cluster and one engine. Freeze the prompt wording, capture the current answers and citations, map each cited source to its role, and connect every owned landing page to a measurable action. Change one content or source gap, repeat the same test, and let the movement in the correct signal determine the next change.

    References

  • A Practical Scorecard for AI-Era Digital Visibility

    A Practical Scorecard for AI-Era Digital Visibility

    Your rankings can hold steady while your brand quietly falls off the buyer’s shortlist. A prospect may ask ChatGPT, Gemini, or Claude for options, encounter you in a comparison without visiting your site, see a social post, and convert long after the first interaction. Traffic and last-click conversions record only fragments of that journey.

    You don’t need another all-purpose visibility score. You need a measurement system that separates business results, early intent, channel reach, AI perception, and volatility. That separation tells you whether to fix discoverability, positioning, conversion, or the metric itself.

    Key takeaways

    • Keep business outcomes, validated proxy events, channel visibility, and AI perception in separate layers. They answer different questions.
    • Measure AI visibility as a current state, a change from the previous baseline, and a pattern of stability over time.
    • Use a fixed prompt library and consistent test conditions. Otherwise, changes in your test can masquerade as changes in brand perception.
    • Promote a micro-conversion into reporting or bidding only after it predicts a downstream outcome, occurs early enough to be useful, and remains dependable.
    • Treat every unusual metric pattern as a diagnosis to test, not an automatic instruction to publish more content or increase spend.

    Build a layered scorecard instead of one blended score

    Five distinct transparent measurement layers align around a central axis, with blocks, pulses, nodes, prisms, and ribbons representing different metric types.

    A single score is attractive because it makes reporting look simple. It also hides the reason performance changed. An increase in AI mentions cannot compensate for declining qualified pipeline, just as revenue alone cannot tell you whether a recent visibility initiative is starting to work.

    Build the dashboard in layers. Let each layer retain its own denominator, time horizon, and decision owner.

    Measurement layerWhat to trackQuestion it answersDecision it supports
    Business outcomesQualified opportunities, pipeline, revenue, or the final outcome your organization acceptsDid marketing contribute to valuable demand?Budget allocation and commercial priorities
    Validated leading indicatorsEvents shown to precede the business outcome, such as a qualified demo request or meaningful product evaluationAre high-intent behaviors moving before revenue appears?Campaign optimization and faster testing
    Search and social discoveryImpressions, query coverage, clicks, referrals, and channel-specific engagementWhere can people encounter the brand?Distribution, content coverage, and channel investment
    AI perceptionMentions, recommendations, prominence, category associations, factual accuracy, and cited supportHow do AI systems recall and represent the brand?Entity clarity, positioning, documentation, and third-party evidence
    Signal stabilityChanges in inclusion, recommendation, position, and associations across comparable snapshotsIs visibility persistent or fragile?Investigation, monitoring, and risk prioritization

    The business-outcome layer remains the truth layer. The other layers shorten your feedback loop or explain how the outcome developed. Calling an AI mention, a scroll, or an impression a conversion erases that distinction and encourages the team to optimize activity instead of value.

    Channel data is also becoming less isolated. Google has begun integrating social channel data into Search Console Insights. That can make discovery reporting more convenient, but placement in one interface doesn’t turn social exposure into search performance or revenue. Preserve the channel label and follow the signal downstream.

    Make AI visibility a repeatable measurement

    AI visibility deserves its own layer because buyers are using generative systems during vendor discovery. A Responsive survey found that 80% of tech buyers use generative AI to research vendors as often as traditional search. That figure describes one surveyed market rather than every buyer, but it is strong enough to make AI recommendations relevant to B2B measurement.

    The difficult part is that an AI answer isn’t a fixed search result. Output can vary with the model, prompt, access mode, available context, underlying data, and model updates. A screenshot proves what appeared once. It does not establish durable visibility.

    Freeze a core prompt library

    Start with the decisions a buyer asks an AI system to help make. Keep a frozen core for period-over-period measurement and a separate exploratory set for new questions. Your core can cover:

    • Non-branded category discovery: which products address a defined problem or use case?
    • Shortlisting: which options fit a specified company type, constraint, or workflow?
    • Comparison: how do named alternatives differ on criteria buyers actually evaluate?
    • Risk and suitability: when is a product a poor fit, and what limitations should a buyer consider?
    • Implementation: which products integrate with the relevant ecosystem or operating environment?

    Record the exact prompt, model, date, access mode, language, location when relevant, repeat count, and full response. Keep these conditions consistent across snapshots. If you revise a prompt, preserve it as a new series instead of splicing its results into the old one.

    Run the same prompt more than once within each measurement window. Repeated runs help you distinguish answer variability from a broader shift. Keep the number of runs consistent so that a larger sample in one period does not create an artificial change.

    Score representation, not just mentions

    Define an eligible prompt before calculating any rate. A prompt is eligible when your offering could reasonably satisfy the stated need. Counting irrelevant prompts in the denominator suppresses the score and encourages category sprawl.

    • Mention rate: the share of eligible responses that name your brand.
    • Recommendation rate: the share that presents your brand as a suitable option rather than mentioning it incidentally.
    • Prominence rate: the share that places the brand in the opening recommendation set or another consistently defined prominent position.
    • Category-association rate: the share that connects the brand to the category, use case, audience, or capability you intentionally target.
    • Representation accuracy: the share of evaluated claims that match your current, verifiable product information.
    • Source-support rate: among answers that provide citations, the share that supports the brand description with an appropriate first-party or credible third-party page.

    A commercial AI brand score may combine visibility and rank in one number. Keep the underlying components accessible. A brand can be mentioned more often while becoming less prominent, or remain prominent while being associated with the wrong use case. Those situations demand different fixes.

    Separate state, drift, and stability

    Your current score is the state. The change between comparable snapshots is drift. The persistence of the signal across several snapshots is stability. Report all three.

    • Express rate changes in percentage points so the size and direction of movement remain visible.
    • Track which brands entered or left the recommendation set, not merely the average number mentioned.
    • Log association gains and losses. A brand may remain visible while moving from a core category into an adjacent one.
    • Compare models separately before calculating any aggregate. Agreement across models is stronger evidence than a gain confined to one system.
    • Measure persistent inclusion by checking which core prompts continue to mention or recommend the brand in adjacent periods.

    A September-to-October 2025 project-management snapshot recorded Atlassian gaining prominence while Slack declined. The same dataset showed category boundaries extending into operations, digital transformation, workflow orchestration, enterprise productivity, and IT consulting. This is one case, not a universal benchmark or proof of causation. It demonstrates why rank alone is insufficient: the conceptual neighborhood around a category can move along with the brands inside it.

    When an association changes, audit the evidence available across your site, technical documentation, integration material, reputable directories, GitHub repositories where relevant, reviews, and community discussions. These environments can reinforce different parts of an entity’s identity. The goal is not to manufacture mentions. It is to make the same accurate category, audience, capabilities, and limitations legible wherever people genuinely evaluate the product.

    Validate proxy metrics before algorithms optimize them

    Long B2B sales cycles create an uncomfortable gap: the team needs feedback before enough opportunities or revenue mature. Proxy metrics can fill that gap, but only if they predict the result you care about. A frequent event isn’t automatically a useful signal.

    Use four tests when deciding whether a candidate event belongs in your scorecard:

    • Correlation strength: people or accounts that complete the event should reach the downstream outcome more often than comparable ones that do not.
    • Timeliness: the event must occur early enough to change a live campaign, audience, message, or budget decision.
    • Actionability: your team must know which lever to adjust when the metric changes.
    • Stability: the relationship should persist across reporting periods and relevant audience segments rather than appearing in one temporary spike.

    Validate the event in a defined sequence:

    1. Name the downstream outcome precisely. Do not mix raw leads, accepted opportunities, and revenue in one target.
    2. Identify candidate events that happen before that outcome and can be joined to the same person or account without breaking your consent and data-governance rules.
    3. Compare downstream outcome rates for entities that completed each event with suitable entities that did not.
    4. Check the lead time. A strongly related event that occurs immediately before the final outcome may explain performance but still arrive too late for optimization.
    5. Repeat the comparison by period, channel, and meaningful audience segment. Promote the proxy only when its direction remains dependable.

    Keep events in three operational tiers. Business outcomes belong in executive reporting. Validated proxies can support campaign learning and, when appropriate, bidding. Diagnostic engagement events such as time on site or scroll depth should remain investigative until you demonstrate a downstream relationship.

    This matters when supplying early signals to Google or Meta optimization systems. Micro-conversions can help an algorithm learn when final-conversion volume is sparse, but the system will pursue the behavior you define. If scroll depth is cheap and loosely related to qualified demand, optimizing for it can produce more scrolling rather than more customers.

    Context changes the quality of a proxy. A newsletter signup may indicate continuing interest, while an add-to-cart event can mislead when abandonment is common. Neither event should inherit value from its name. Let its observed relationship with your own accepted outcome determine how you use it.

    Read cross-metric patterns before choosing a fix

    A strategist examines separate glowing signal forms whose connecting beams lead toward a compass, tuning dial, and open gateway.

    The scorecard becomes useful when you read movement across layers. The combinations below are working diagnoses, not conclusions. Use the next check to confirm or reject each interpretation.

    Observed patternWorking diagnosisWhat to check next
    AI mentions fall while search visibility holdsBrand perception, model behavior, or category association may have shifted without a traditional ranking lossCompare models, inspect lost prompts, review association changes, and verify that the test conditions stayed constant
    AI mentions hold but recommendation rate fallsThe brand remains known but appears less suitable or less prominentExamine stated limitations, comparison criteria, audience fit, and the brands now recommended ahead of it
    Search impressions fall while AI visibility holdsThe problem may sit in traditional search demand, coverage, ranking, or technical visibilitySegment branded and non-branded queries, inspect affected pages, and keep the AI series separate
    A proxy rises while qualified outcomes remain flatThe proxy may have weakened, the audience mix may have changed, or a later handoff may be failingRecalculate the proxy-to-outcome relationship and trace the journey after the event
    AI visibility rises while referral traffic stays flatThe gain may represent exposure rather than visitsCheck recommendation quality, branded demand, assisted journeys, and downstream outcomes before declaring success or failure
    Social discovery rises while search remains flatDistribution may be broadening in one channel without changing search demandPreserve channel attribution and test whether the added audience reaches a validated proxy or business outcome
    Discovery improves across channels but pipeline does notThe constraint may be message fit, offer fit, conversion, qualification, or the sales handoffInspect landing behavior and stage-to-stage progression before buying more reach

    At each reporting review, identify the largest meaningful movement, write down the most plausible explanations, and assign a check that can distinguish among them. Record the decision and its expected effect in the next comparable snapshot. That decision log prevents the team from retrofitting a success story to whichever metric happened to rise.

    Start your next dashboard revision by adding the missing layer, not by adding more charts. If you already report revenue and search traffic, build a fixed AI prompt baseline. If you already monitor AI mentions, add representation accuracy and stability. If micro-conversions drive optimization, revalidate their relationship with qualified outcomes. The next useful metric is the one that resolves a real decision your current reporting leaves ambiguous.

    References

  • Profound’s G2 AEO Leadership: A Practical Buyer’s Guide

    Profound’s G2 AEO Leadership: A Practical Buyer’s Guide

    If Profound’s G2 recognition has put the platform on your AEO shortlist, don’t ask only whether the badge is impressive. Ask what decision it can safely support. The answer is useful but narrow: it can justify a closer look, not a purchase.

    Profound publicly reports that it was recognized as the definitive Leader in G2’s Winter Reports for the AEO category. That gives you a named market signal from a specific report cycle. It doesn’t establish how the product will perform against your prompts, markets, workflow, or technical requirements. A defensible decision requires you to verify the recognition and test the platform separately.

    Read the G2 leadership claim at its actual scope

    A precise procurement note should preserve four parts of the claim: the vendor, the label, the category, and the report cycle. In this case, those parts are Profound, definitive Leader, AEO, and G2 Winter 2026.

    Keep those qualifiers together whenever you brief your team or repeat the recognition publicly. Removing AEO can make a category-specific result sound like a company-wide judgment. Removing Winter 2026 turns time-bounded recognition into an indefinite status. Replacing the exact label with broader wording can create a claim that the underlying record may not support.

    The recognition does not, by itself, establish any of the following:

    • That Profound received the highest result on every criterion used in the category.
    • That its measurements are technically accurate for every answer engine, language, or market.
    • That it supports every workflow, integration, or governance requirement your organization has.
    • That using the platform will cause your brand to appear, rank, or receive citations in an external answer engine.
    • That it is a better fit than every alternative for your particular team.

    Those limitations don’t invalidate the recognition. They place it in the right part of the decision: market evidence. Product capability, data quality, operational fit, and business value still need their own proof.

    Verify the recognition before you circulate it

    An analyst uses a magnifier to inspect a generic award marker beside layered source documents, a calendar tile, and a category folder.

    Before the accolade enters a business case, sales deck, board update, or vendor scorecard, ask Profound for the originating G2 record. A badge graphic or a restatement on another company-controlled page is not the same as primary verification.

    1. Request a direct G2 URL, accessible report, or exported record that identifies the relevant Winter 2026 result.
    2. Confirm that the product name, AEO category, and Leader wording match the language you intend to use.
    3. Read the category criteria and methodology rather than assuming what Leader means. Record which inputs affect placement and which do not.
    4. Check the applicable data window, review base, customer segments, geographic qualifications, and any inclusion thresholds shown in the primary record.
    5. Save the verification artifact with the date you accessed it. If the recognition later changes, your team will know which decision relied on which report cycle.

    Use a simple evidence status in your internal records. Mark the claim verified when an originating G2 artifact supports the exact wording. Mark it partially verified when the placement is visible but your proposed wording is broader than the record. Mark it vendor-reported when only Profound’s own publication is available.

    For now, the conservative wording is that Profound reports receiving the recognition. That distinction is not pedantry. It prevents a vendor-supplied claim from quietly becoming an independently checked fact as it moves through your organization.

    Make Profound earn the shortlist with your workload

    An AEO platform is valuable when it helps your team observe answer-engine behavior, diagnose meaningful gaps, choose sensible actions, and measure what happens next. A polished demonstration can show how an interface works. Only your own workload can show whether the system is useful to you.

    Freeze the evaluation scope before the demonstration

    Create a prompt inventory before anyone logs into the platform. Each row should identify the answer engine or surface, market, language, customer-journey stage, exact prompt, relevant brand or entity spelling, and pages that could credibly support an answer.

    Include the query types your customers actually use: branded questions, non-branded category questions, problem-led questions, comparisons, and questions about implementation or suitability. Cover every material segment of your business. Do not let canned demonstration prompts replace this inventory; a vendor-selected prompt can prove interface behavior without proving coverage of your use case.

    Define acceptance conditions at the same time. Decide which answer engines, languages, markets, exports, integrations, user roles, and historical views are must-haves. When a requirement is left undefined until after the demonstration, an attractive feature can distract the team from a missing capability.

    Audit the observations behind each metric

    Run the chosen prompts manually and through the proposed workflow over multiple recorded occasions. A single run shows one moment. Repetition helps you notice whether differences come from changing answer-engine output, collection timing, classification rules, or a data-ingestion problem.

    For every sampled result, retain the exact prompt, named engine or surface, timestamp, market and language, account or session state where relevant, raw answer, cited URLs, and the platform’s classification. You should be able to trace a dashboard result back to an observable answer. If the system cannot expose that trail, ask how your team is expected to audit a disputed metric.

    Interrogate every metric label that appears in the evaluation. For mention, citation, visibility, share of voice, sentiment, or rank, ask for the unit of analysis, denominator, retry behavior, treatment of missing answers, aggregation method, and update frequency. Familiar names can hide materially different calculations. A percentage is not decision-grade until you know what entered it.

    Require an evidence-to-action workflow

    Select one real query cluster where your brand appears to have a meaningful gap. Ask the evaluator to trace that gap to the underlying evidence, separate controllable issues from external behavior, identify the relevant page or entity, recommend a prioritized action, and state what observable result would count as improvement.

    Then have the person who would own the work judge the recommendation. A generic suggestion to improve authority or create better content is not operational guidance. A useful recommendation identifies the affected query set, the evidence behind the diagnosis, the asset to change, and the reason that change is relevant.

    If structured data is recommended, require the proposed schema type and properties to match the visible content and the entity being described. Validate the markup, but keep the inference modest: technically valid JSON-LD does not prove that an answer engine will select or cite the page.

    Record every action in a change log. Avoid changing content, entity information, internal linking, and structured data simultaneously when you want to understand what helped. External answer systems can change independently, so treat movement as evidence to investigate rather than automatic proof of causation.

    Use a pass-or-fail scorecard, not a badge-weighted impression

    A luminous platform cube passes through evaluation gates represented by speech bubbles, a globe, gears, a shield, integrations, and a stopwatch, while an award medallion sits aside.

    Separate must-haves from differentiators and nice-to-haves before scoring Profound. Third-party market recognition normally belongs among the differentiators unless your procurement policy explicitly makes it mandatory. It should not compensate for a failed data, coverage, security, or workflow requirement.

    Decision areaEvidence that supports a passReason to pause
    RecognitionAn originating G2 record matches the product, label, AEO category, and Winter 2026 report cycle.Only vendor-controlled wording is available, or the marketing language is broader than the primary record.
    CoverageLive testing includes every answer engine, market, language, and prompt class marked as a must-have.Coverage is described broadly while an important engine, region, language, or query type remains untested.
    Metric traceabilitySample metrics can be traced to raw prompts, answers, citations, timestamps, and documented calculations.Scores are opaque, definitions are incomplete, or disagreements cannot be audited.
    RepeatabilityRepeated runs produce explainable results, with collection timing and output changes visible.Material inconsistencies appear without enough evidence to distinguish engine volatility from platform error.
    ActionabilityYour own query gap leads to a specific, evidence-linked action that the responsible operator considers sound.Recommendations remain generic or cannot be connected to a page, entity, citation, or technical issue.
    Operational fitExports, APIs, history, collaboration, permissions, and integrations meet the requirements defined before the demo.A critical workflow depends on an undocumented feature or a manual workaround your team cannot sustain.
    Commercial and governance fitPricing units, usage limits, support, onboarding, data retention, access controls, and contractual responsibilities are confirmed in writing.A material cost, limit, ownership question, or data-handling requirement remains unknown.

    Have each evaluator record pass, fail, or unknown beside an evidence link. Unknown is not a provisional pass. Give every unknown an owner and a deadline, then resolve disagreements by examining the evidence rather than averaging enthusiasm from the demonstration.

    If Profound fails a must-have, stop and decide whether the requirement can genuinely change. Do not quietly reclassify it because the platform has strong recognition. If Profound passes the must-haves, the G2 result becomes relevant supporting evidence and may help distinguish otherwise suitable choices.

    Key takeaways

    • Profound reports that it was recognized as the definitive Leader in G2’s Winter 2026 Reports for the AEO category.
    • Treat that recognition as a time-bounded, category-specific market signal, not blanket proof of technical accuracy, business impact, or universal product fit.
    • Verify the exact wording against an originating G2 artifact before presenting the claim as independently confirmed.
    • Evaluate the platform with a frozen inventory of your own prompts, markets, languages, answer surfaces, and operational requirements.
    • Require every important metric to connect back to raw answers, citations, timestamps, and a documented calculation.
    • Let must-have evidence determine the purchase decision; use the G2 recognition as supporting context after those requirements are satisfied.

    Your next move is to create a one-page evidence register before the next conversation with Profound. Put the four-part G2 claim at the top, list what remains unverified, and attach a pass-or-fail pilot plan based on your real workload. If the platform clears those tests, the leadership recognition will have the context it needs to support a defensible decision.

    References