Tag: AI Visibility

  • How to Make Products Visible to AI Personal Shoppers

    How to Make Products Visible to AI Personal Shoppers

    Your product can rank in conventional search and still disappear when a shopper asks an AI assistant what to buy. The missing piece is usually not another generic category paragraph. It is making the product easy to identify, test against constraints, and defend in a recommendation.

    AI personal shoppers can shape which products make the shortlist. That changes your visibility target. You are no longer optimizing only for a page visit; you are helping a system decide whether your product is eligible, relevant, credible, and safe to recommend for a particular request.

    AI shopping visibility is a three-gate problem

    There is no universal ranking formula for AI shopping. Assistants use different catalogs, retrieval systems, merchant feeds, pages, and models. Their answers can also change as availability, prices, prompts, and underlying systems change. A practical three-gate model is more useful than pretending every platform works the same way.

    1. Discovery: Can the assistant find and identify the correct product or variant?
    2. Qualification: Can it determine whether the product satisfies the shopper’s stated constraints?
    3. Selection: Is there enough relevant evidence to choose the product and explain that choice?

    A product has to pass the gates in that order. Better promotional copy cannot rescue a product the system cannot identify. Strong reviews cannot compensate for an unspecified compatibility requirement. Complete structured data does not prove a broad superiority claim.

    This sequence gives you a diagnostic method. If the product never appears, inspect discovery before rewriting the sales copy. If it appears for broad prompts but disappears when a constraint is added, inspect the relevant attribute. If it remains eligible but another product receives the recommendation, inspect comparative relevance and supporting evidence.

    The important distinction is between being mentioned and being recommendable. A system may know that your product exists while lacking the facts needed to place it in a defensible shortlist.

    Build one canonical product truth
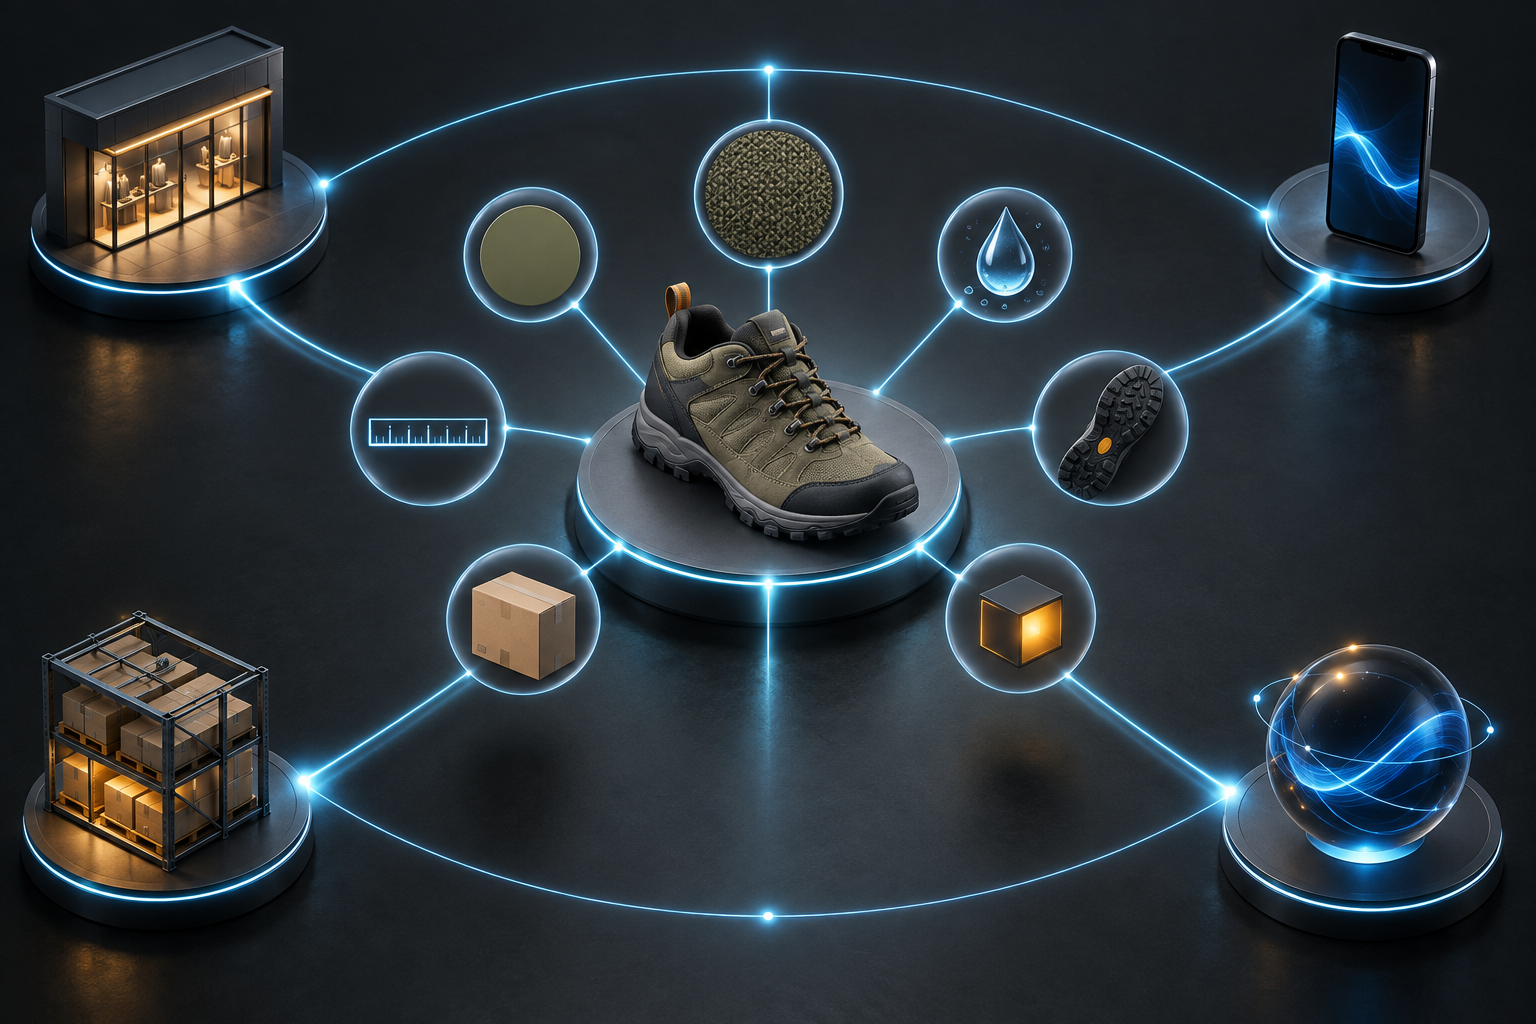
    A hiking shoe on a central platform sends the same set of visual product attributes to a storefront, phone, warehouse shelf, and AI orb.

    Start with an internal product record, not a block of marketing copy. This record should be the authoritative source for the product page, structured data, merchant feeds, marketplace listings, comparison pages, and support content. When those surfaces disagree, an assistant has to choose among conflicting claims or avoid repeating them.

    For each product and meaningful variant, define the following fields explicitly:

    • Identity: brand, product name, model, assigned SKU or GTIN, canonical URL, and product category.
    • Variant: color, size, capacity, material, pack quantity, configuration, and the relationship to the parent product.
    • Eligibility attributes: dimensions, weight, compatibility, intended use, required accessories, included components, operating conditions, and other category-specific constraints.
    • Commercial facts: price, currency, condition, availability, fulfillment terms, returns, and warranty terms.
    • Evidence: certifications, documented test conditions, review data, manuals, specifications, and the exact scope of each claim.

    Do not populate a field because competitors use it or because a schema validator permits it. An unknown value should remain unknown until the business can verify it. A precise false claim is worse than an honest omission because the false claim can be repeated in a recommendation, create a poor purchase, and undermine trust in the rest of your data.

    Keep the visible page, schema, and feeds aligned

    Product structured data should encode facts that a shopper can also verify on the page. Use Product markup to identify the item and its attributes. Use Offer data only for an offer that actually exists. Add rating or review properties only when the corresponding information is genuine, visible, and attached to the correct product or variant.

    JSON-LD does not create product truth. It translates product truth into a machine-readable form. If the page says one material, the markup says another, and the feed omits the field, adding more schema will multiply the ambiguity rather than fix it.

    Variant handling deserves particular attention. A family page may describe several configurations, but price, dimensions, availability, ratings, and compatibility can belong to only one of them. Give meaningful variants stable identities and make the selected variant unambiguous in the page content, URL behavior, structured data, and feed.

    Separate durable facts from fast-changing facts

    Product data fails at different speeds. Model identity, dimensions, materials, compatibility, and included components are usually durable. Price, availability, promotions, delivery estimates, and review aggregates can change much faster.

    Give each fast-changing field an owner, a system of record, and a refresh trigger. Avoid embedding volatile values in editorial prose unless that prose is updated from the same source. A stale promotional page and a current product feed can leave an assistant with two plausible answers and no reliable way to reconcile them.

    Match shopper constraints and support every important claim

    Traditional product copy often begins with a head keyword and expands into benefits. AI shopping requests are more likely to combine a job, a hard constraint, and a preference: a product for a particular use, compatible with something the shopper already owns, within a budget, and with a preferred trade-off.

    Create a prompt set from the decisions people make, not just the phrases with the highest search volume. Include several distinct request types:

    • Job prompts: What is the shopper trying to accomplish?
    • Constraint prompts: What would make a product ineligible, such as size, compatibility, material, price, or availability?
    • Trade-off prompts: Which quality matters more when no option maximizes everything?
    • Comparison prompts: Which alternatives are genuinely close enough to compare?
    • Risk prompts: What must the shopper verify before buying?

    Then map every consequential question to a field and a piece of evidence. The map exposes a common failure: the marketing team believes a benefit is obvious, but the product page never supplies the fact an assistant would need to infer it safely.

    Shopper questionMachine-readable answerHuman-verifiable support
    Will it fit?Dimensions, weight, capacity, or supported size rangeSpecification table, diagram, or installation instructions
    Will it work with what I own?Compatible models, interfaces, versions, or required accessoriesCompatibility page, manual, or clearly scoped support content
    Can I buy it under my stated conditions?Current price, currency, condition, availability, and offer detailsVisible offer and fulfillment information
    Is it suitable for this use?Intended use and relevant product attributesUse-case explanation tied to specifications rather than slogans
    Can I trust this claim?Named evidence and its scopeCertification details, documented method, policy, or attributable review data

    State who the product is and is not for

    A useful product page helps an assistant eliminate the wrong matches. State the primary use, the buyer or environment it suits, the constraints it satisfies, and any condition that would make another option more appropriate.

    This does not weaken the offer. A clear limitation can make the positive recommendation more credible. If a product requires an adapter, has a fixed dimension, excludes a particular model, or is designed for one usage pattern rather than another, say so close to the relevant benefit. Hiding the qualifier may generate more initial interest, but it gives an assistant less reason to trust or repeat the claim.

    Comparison content should use decision criteria rather than a list of adjectives. Explain which product fits which condition and why. Avoid declaring an item the best without naming the use case, comparison set, and evidence. An unqualified superlative is difficult to defend and easy for a recommendation system to ignore.

    Maintain a claim-to-evidence ledger

    For every claim that could change a purchase decision, keep an internal ledger containing the claim, its exact qualifier, the supporting evidence, the page where that evidence is visible, the responsible owner, and the event that should trigger a review.

    The qualifier matters. A certification may apply to one variant, a test may use specific conditions, and a warranty may differ by market. Preserve that scope everywhere the claim appears. Do not turn narrow evidence into a product-wide promise.

    Customer reviews can help describe recurring strengths and limitations, but keep review data attached to the product or variant it evaluates. Combining materially different variants may produce a stronger aggregate while giving the assistant a less accurate picture of the item in front of the shopper.

    Support pages, manuals, compatibility resources, return policies, and comparison pages should link back to the canonical product and use the same names and identifiers. That creates a coherent evidence trail instead of a set of disconnected documents with slightly different terminology.

    Audit the complete path from prompt to recommendation
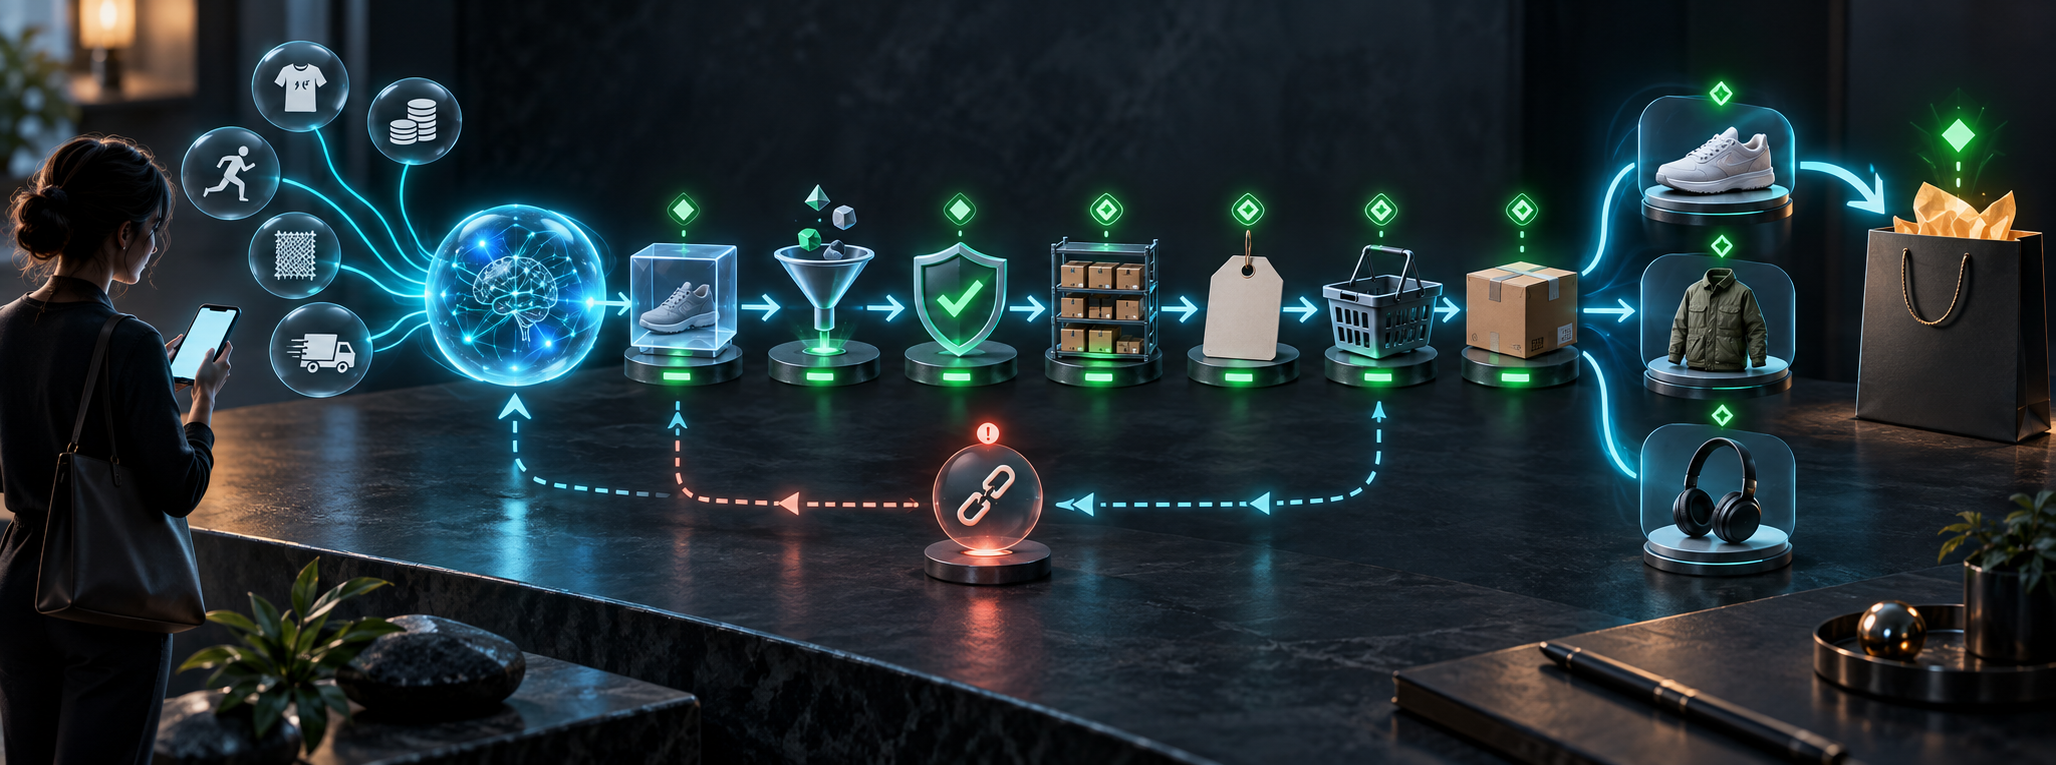
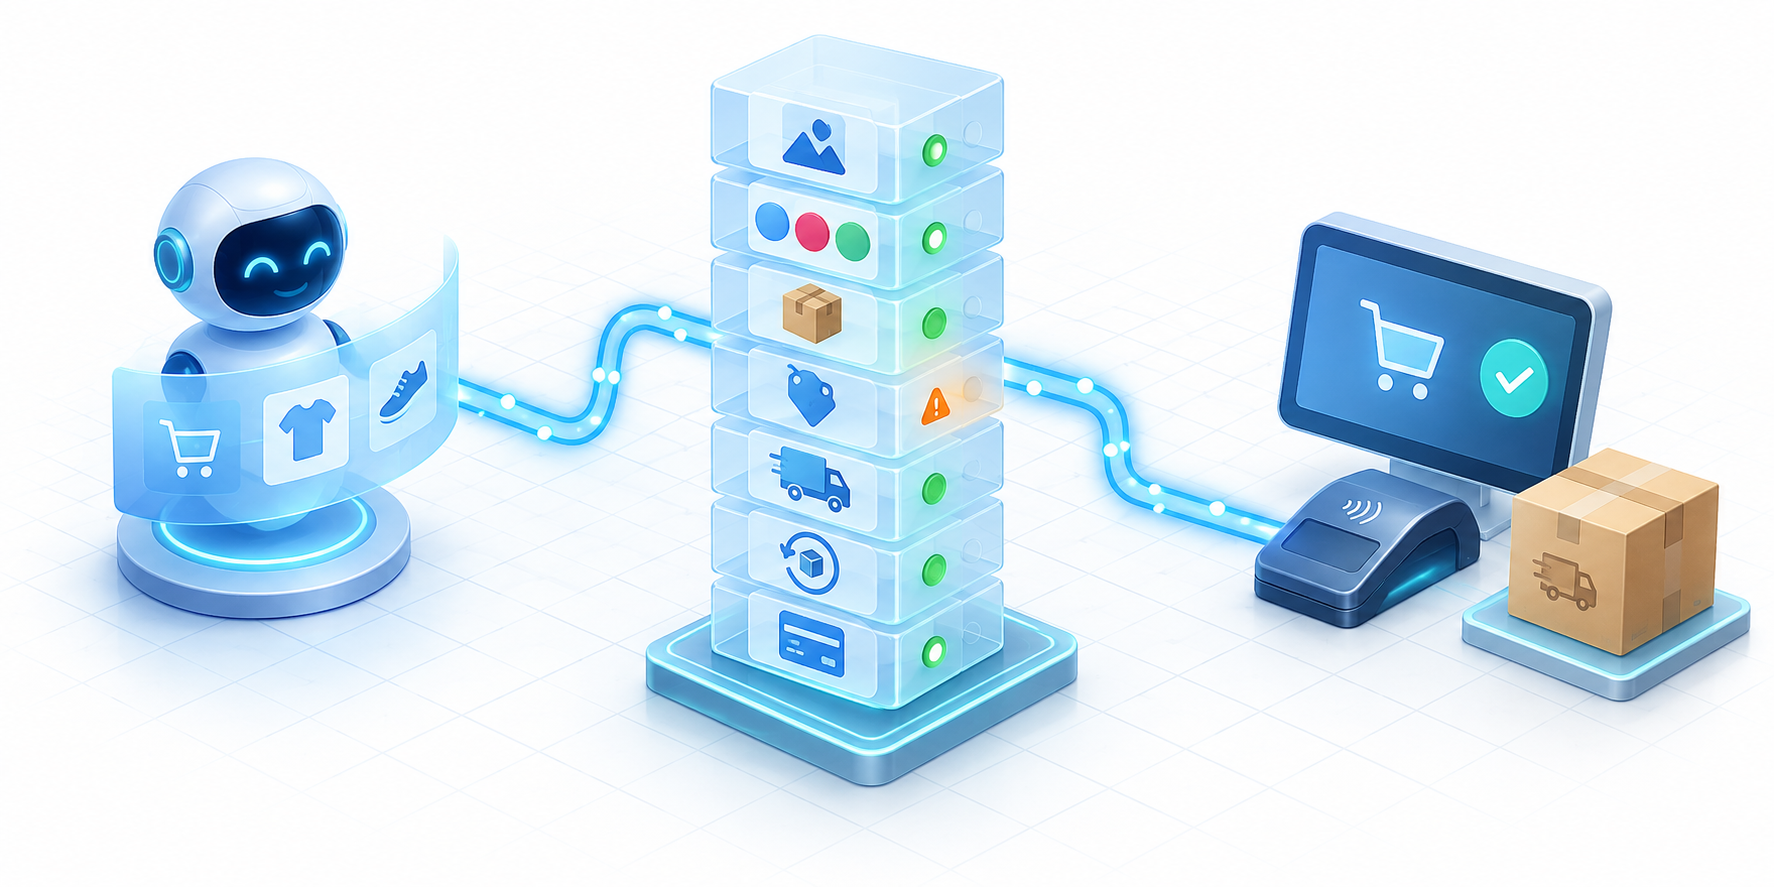
    A shopper request travels through product, evidence, inventory, checkout, and delivery checkpoints before reaching an unbranded product shortlist.

    Do not reduce AI shopping visibility to a rank check. You need to see where the product exits the decision process and whether the answer is factually correct when it does appear.

    1. Choose eligible prompts. Test requests for which the product could honestly be a suitable answer. Irrelevant prompts distort the score and tempt teams to broaden claims beyond the product’s real fit.
    2. Record a baseline. Save the exact prompt, assistant, date, market or locale, response, recommended products, stated reasons, and any surfaced links.
    3. Label the outcome. Distinguish absence, failed qualification, incorrect description, unsupported mention, and an eligible product that lost on a documented trade-off.
    4. Trace the earliest failed gate. Repair identity and discovery before attributes, attributes before evidence, and evidence before promotional expansion.
    5. Rerun the same prompt set. Compare changes in coverage and accuracy while recognizing that any individual generated response can vary.
    6. Inspect the commercial handoff. If the recommendation is accurate but the shopper does not proceed, examine the offer, availability, landing experience, and product-market fit rather than calling every weak outcome an AI visibility problem.

    The failure pattern tells you where to look first:

    Observed resultLikely failure areaFirst inspection
    The product never appearsDiscoveryIndexability, canonical URL, feed inclusion, product identity, and internal linking
    The wrong variant appearsIdentityVariant names, identifiers, URLs, parent relationships, and selected-offer data
    The product disappears after a valid constraint is addedQualificationThe missing, ambiguous, or conflicting attribute associated with that constraint
    The assistant states an incorrect factProduct truthConflicts and stale values across the page, schema, feed, marketplace, and support content
    The product is considered but not recommendedSelectionUse-case specificity, comparison criteria, limitations, and claim-level evidence
    The recommendation is accurate but does not convertCommercial handoffPrice, availability, trust, offer clarity, landing experience, and actual product fit

    Track metrics that correspond to those states. Prompt coverage shows whether the product appears for eligible requests. Attribute resolution shows whether the assistant can answer the important constraint questions. Answer accuracy catches misdescription. Evidence visibility shows whether useful supporting pages are surfaced. Recommendation share shows how often the product is selected when it is genuinely eligible. Commercial outcomes tell you whether improved visibility creates useful demand.

    Keep the prompt set and eligibility rules stable while evaluating a change. If you change the content, prompts, markets, and success definition at the same time, you will not know what improved. Treat assistant outputs as observations, not permanent rankings.

    Key takeaways

    • Optimize for discovery, qualification, and selection as separate gates.
    • Create one canonical product record before expanding copy, schema, feeds, or comparison content.
    • Make decisive constraints explicit; do not ask an assistant to infer compatibility, fit, or eligibility from vague prose.
    • Keep visible content, Product structured data, offers, variants, and merchant feeds consistent.
    • Attach meaningful claims to scoped evidence and state important limitations plainly.
    • Measure eligible prompt coverage and factual accuracy before treating recommendation share as the main result.

    Start with one commercially important product family. Establish its canonical facts, build prompts around real purchase constraints, and fix the earliest gate that fails. Once that path is reliable, extend the same operating model to the rest of the catalog. That gives you a repeatable visibility system instead of a collection of schema additions and copy changes whose effect you cannot explain.

    References


  • Content Refresh or New Page? A Decision Guide for AI Search

    Content Refresh or New Page? A Decision Guide for AI Search

    You have a page whose answer is getting stale, but the URL may still hold useful search visibility, links, and recognition. Editing it too aggressively could erase what made it useful. Publishing another page could split one clear answer across two competing URLs.

    The decision turns on continuity: does the existing URL still represent the question you want to answer? The right planning question is not simply how often to update. It is when to refresh and when to create something new for AI search. Use the framework below to make that call before anyone starts rewriting.

    Start with answer continuity, not publication age

    Every useful URL makes an implicit promise. Its title, opening, headings, internal links, and search snippets tell a reader what question the page will resolve. A refresh is appropriate when that promise remains valid and the answer needs to become more accurate, complete, or usable. A new page is appropriate when the promise itself has changed.

    This distinction matters more than the size of the edit. You can rebuild most of a page and still call it a refresh if the same reader arrives with the same question and should reach the same kind of outcome. Conversely, a short addition can deserve a separate URL if it serves a materially different intent, audience, entity, version, or decision.

    Use this three-step test before looking at traffic charts:

    1. Write the existing page’s primary question in one sentence, using the language a reader would use.
    2. Write the proposed page’s primary question in another sentence. Do not describe the content format; describe the decision or task the reader needs to complete.
    3. Compare the expected outcomes. If both questions lead to the same outcome, refresh the existing page. If they lead to different outcomes and both remain useful, create a new page.

    Suppose an existing page explains what answer engine optimization is. Adding current terminology, clearer examples, better sourcing, and a stronger definition would preserve its promise. A page that helps a marketing lead choose an AEO measurement platform serves a different job. Forcing that purchasing decision into the definition page would make both answers harder to extract and harder to trust.

    A refresh is usually the cleaner choice when the target question, intended reader, principal entity, and required answer format remain stable. It is also appropriate when outdated claims can be replaced without changing the page’s central conclusion.

    Create a new page when the reader now needs a different task completed, such as moving from learning to comparing, implementing, troubleshooting, or buying. A separate page is also warranted when a new product version, market, audience, or use case has enough distinct constraints to support its own complete answer.

    Do not let a traffic decline make the decision for you. Declining traffic can trigger an audit, but it does not prove that the URL is obsolete. The page may have weak evidence, an indirect opening, an outdated title, changed search demand, stronger competition, or technical problems. Diagnose the mismatch before choosing the remedy.

    Audit the question, claims, entities, and page structure

    A magnifying lens examines layered document components, connected spheres, evidence tiles, and modular page blocks.

    A useful content audit separates five layers that teams often collapse into one vague judgment about freshness. Review each layer independently. One outdated statistic may require a correction; a changed audience may require an entirely new page.

    Audit layerQuestion to askSignal to refreshSignal to create a new page
    QueryWhat specific question should this URL answer?The wording has evolved, but the reader’s task is unchanged.The proposed query represents another task or decision stage.
    AnswerWhat must the reader know or do after reading?The conclusion still holds and needs better support or explanation.The new conclusion would conflict with or displace the existing answer.
    AudienceWho is the answer for, and what do they already know?The same audience needs a clearer or more current explanation.A distinct audience needs different assumptions, terminology, or actions.
    EntityWhich product, organization, concept, location, or version is central?The same entity needs corrected attributes or relationships.A separate entity or version deserves independent treatment.
    StructureCan the answer remain coherent on the current page?Sections can be repaired without changing the page’s purpose.The proposed material would overwhelm the original answer or create two competing introductions.

    Begin the audit with the rendered page, not just the draft in your content management system. Record the title, opening answer, headings, important claims, citations, internal links, media, structured data, canonical target, and displayed publication or modification dates. Save a version before editing so you can distinguish the effect of the change from your memory of the old page.

    Next, label every consequential claim as current, obsolete, unsupported, ambiguous, or outside the page’s scope. Pay particular attention to claims that can change independently of the main topic: product features, prices, eligibility rules, named executives, legal requirements, performance figures, dates, and version-specific instructions. Do not preserve an unsupported statement merely because the page performs well.

    Then inspect the answer a machine or hurried reader is likely to encounter first. If the title promises one question while the opening answers another, the page has an alignment problem. If the direct answer appears only after a long historical preamble, the page has an extraction problem. Both are refresh problems when the underlying intent remains stable.

    Entity ambiguity deserves its own pass. A page that alternates between a company, its platform, a feature, and an industry category without defining their relationships may be readable to an insider but unclear outside that context. Introduce the principal entity explicitly, use consistent names, and clarify relationships that affect the answer. Structured data cannot repair contradictory prose.

    Use performance evidence after the semantic audit. Review the queries and landing-page behavior available to you, conversions tied to the page’s intended outcome, internal-search terms, links, and any reliable records of AI referrals or citations. Treat AI answer observations as directional rather than deterministic: outputs can vary by prompt, model, context, location, and time. A single missing citation is not enough evidence to replace a URL.

    Calendar age should trigger inspection, not automatic rewriting. Set review frequency according to the page’s rate of change. Version-dependent instructions should be reviewed when the product changes. Pages built around external rules or figures should be checked when the underlying authority changes. Stable conceptual pages can be reviewed when query patterns, audience needs, or the evidence base shifts. The useful cadence is therefore page-specific rather than one site-wide interval.

    Refresh the URL without blurring its original promise

    Once you choose a refresh, define what will remain unchanged. Write a one-sentence content brief containing the primary question, intended reader, required outcome, and central entity. That sentence becomes the boundary for the revision. Any proposed section that serves another substantial question goes into a separate-page backlog.

    1. Capture a baseline. Save the current page, record the change date, and preserve the available query, engagement, conversion, link, and AI-visibility evidence. Without a baseline, a later increase or decline will be difficult to interpret.
    2. Repair the opening answer first. Make the page’s conclusion or recommended action visible near the start. State important conditions and exceptions where they affect the answer rather than hiding them in a closing note.
    3. Replace obsolete material in place. Do not leave a wrong claim in the main text and append a correction at the bottom. Remove or rewrite passages that no longer help the reader complete the stated task.
    4. Strengthen the evidence chain. Connect consequential claims to appropriate supporting references, identify versions and dates when they matter, and distinguish established facts from editorial judgment or uncertain observations.
    5. Rebuild the heading structure around real subquestions. Each section should resolve a distinct part of the primary question. If two sections repeat the same conclusion in different language, combine them.
    6. Align internal links with the revised role of the page. Links pointing in should accurately describe what the reader will find. Links pointing out should handle adjacent questions without making this page compete with them.
    7. Update machine-readable information to match the visible page. Structured data should describe the content that is actually present, use the applicable type, and remain consistent with names, dates, authorship, and entities shown to readers.
    8. Publish with an honest modification signal. Update a modification date when a substantive revision occurred, not as a cosmetic attempt to make unchanged material look current. Keep an internal change log so the team knows what was altered and why.

    Preserve the existing slug unless changing it solves a real information-architecture problem. A refreshed page does not need a new URL merely because its title changed. If a slug must change, map the old URL to the most appropriate replacement and update important internal links; otherwise, you introduce avoidable routing and measurement noise.

    Be equally disciplined with schema. Adding more JSON-LD types does not compensate for a weak answer. Markup should represent visible, accurate information and should not imply reviews, FAQs, authorship, products, or organizational relationships the page does not substantiate. Validate the markup after publishing, but treat technical validity as a floor rather than proof that the content is useful.

    After publication, confirm that the page renders correctly, remains indexable where intended, exposes the expected canonical URL, and includes the revised structured data. Annotate the release in your reporting. Then watch the same measures captured in the baseline. Do not change the page repeatedly in response to isolated fluctuations; overlapping revisions make it impossible to learn which change mattered.

    Create a new page when the reader needs a separate answer

    A luminous information stream divides into two non-overlapping paths leading to separate pavilions with distinct clusters of connected nodes.

    A new page should exist because it resolves a distinct question, not because the editorial calendar needs another URL. Before commissioning it, complete this sentence: “Unlike the existing page, this page helps [audience] accomplish [outcome] under [relevant conditions].” If the difference cannot be expressed without vague words such as deeper, broader, or updated, the proposed page probably belongs in the refresh.

    Distinct search intent is the strongest reason to separate pages. A definition, implementation tutorial, vendor comparison, troubleshooting workflow, and measurement plan may concern the same topic while serving different decisions. Giving each substantial task a clear home lets you answer it directly without turning one page into a collection of half-developed responses.

    A separate audience can also justify a new URL, but only when the difference changes the answer. Replacing “marketing leader” with “agency” in the title is not enough. The agency page should have meaningfully different constraints, examples, evaluation criteria, responsibilities, or actions. Otherwise, you have created a near-duplicate with a new label.

    When both pages will remain live, design their relationship before publishing:

    • Assign one primary question and one intended outcome to each page.
    • Give each page a distinct title, opening answer, heading plan, and internal anchor language.
    • Link between the pages with explanatory context, such as moving from a definition to an implementation process, rather than using the same generic anchor everywhere.
    • Keep each page’s canonical treatment consistent with its intended indexing role. Do not point one page at another as canonical while also expecting both to function as independent search results.
    • Avoid copying a large shared introduction into both pages. State only the background each reader needs, then move into the page-specific answer.
    • Update relevant hub pages, breadcrumbs, navigation, and XML sitemap handling so the new page has a clear place in the site architecture.

    If the new page replaces the old answer rather than complementing it, decide whether any meaningful reason remains to visit the old URL. When the old page has no independent purpose, consolidate useful material into the replacement and route the old URL appropriately. When the old question still matters, retain it and narrow its content so the boundary between the two pages is obvious.

    Define measurement before launch. The old and new pages should have separate expected query themes and reader outcomes. Track whether each URL begins attracting the intended demand, whether internal and external references point to the appropriate page, and whether conversions or downstream actions match the page’s role. If you monitor AI answers, use a stable prompt set and record the model, context, and observation date so comparisons are at least directionally consistent.

    When the pages begin appearing for the same queries, do not assume consolidation is immediately necessary. First inspect whether the queries are genuinely identical in intent. Tighten titles, openings, headings, and internal links if the distinction exists but is poorly communicated. Merge only when you cannot maintain a useful boundary or when one page adds no independent value. If you do consolidate, preserve the strongest answer, update links, and redirect deliberately rather than simply deleting the weaker URL.

    Key takeaways

    • Refresh an existing page when the same audience still asks the same primary question and needs the same kind of outcome.
    • Create a new page when intent, audience needs, central entity, version, or decision stage changes enough to require an independent answer.
    • Treat page age and traffic decline as audit triggers, not automatic reasons to rewrite or replace a URL.
    • Audit the query, answer, audience, entities, claims, structure, links, and structured data before choosing an editorial action.
    • When refreshing, preserve the page’s promise while replacing obsolete claims, strengthening evidence, and aligning JSON-LD with visible content.
    • When creating a page, define its boundary, relationship to existing URLs, indexing role, and success measures before publication.

    Start with one page that is due for review. Write its current question and proposed question side by side. If the reader and outcome remain continuous, refresh it with a recorded baseline. If the outcome changes, write the new page’s distinct job before creating the URL. That small decision document will prevent most accidental duplication and unfocused rewrites.

    References

  • What Conductor’s Leadership Transition Means for AEO

    What Conductor’s Leadership Transition Means for AEO

    If you use Conductor, compete with it, or are considering it for enterprise search, the CEO change matters for a reason that goes beyond the name on the leadership page. A product executive closely associated with Conductor’s AI and data foundation is taking control just as the company puts answer engine optimization at the center of its strategy.

    Your immediate task isn’t to react to the announcement. It is to determine whether the transition will turn AI visibility data into reliable explanations and useful website decisions. That measurement-to-action handoff is where an AEO platform proves its value.

    The handoff signals continuity, but not business as usual

    Co-founder Seth Besmertnik is stepping down after two decades as CEO. Chief Product Officer Wei Zheng is succeeding him, while Besmertnik remains on Conductor’s board and plans to support the company as a major shareholder. This is an internal succession with continued founder involvement, not a clean break led by an outside turnaround executive.

    Continuity should not be confused with stasis. Zheng spent the previous five years overseeing product strategy. She led the development of Conductor AI and the company’s wider AI and data strategy, including the data foundation beneath its enterprise platform. Besmertnik also credited her with pushing Conductor to build a data platform four years before the leadership change. That platform now brings together signals used to measure visibility in AI search.

    The change closes an unusually long founder-led chapter. Besmertnik co-founded the business in 2006, when it operated as LinkExperts, before it became Conductor in 2008. He later led the company through its 2018 acquisition by WeWork and a 2019 employee buyback that restored its independence and gave more than 250 employees co-founder status. That history makes this succession significant even though the founder is staying involved.

    Key takeaways

    • Conductor is moving from a long-serving founder-CEO to an internal product leader, while preserving board-level founder involvement.
    • Wei Zheng’s prior remit connected product strategy, AI development and the enterprise data foundation, so her appointment reinforces the direction already underway.
    • Conductor is explicitly placing AEO at the center of platform development, customer service and growth investment.
    • The important product test is no longer whether a tool can count AI mentions. It is whether it can explain recommendation patterns and guide changes that can be evaluated afterward.
    • Customers should separate announced direction, currently available functionality and independently demonstrated outcomes.

    The strategic shift is from rankings to recommendations

    Stacked translucent result tiles feed through streams of light into a focused group of illuminated recommendation objects.

    Conductor says AEO will shape how it develops its platform, works with customers and invests for growth. That is more consequential than simply adding another dashboard. Traditional search programs usually begin with rankings, impressions, clicks and landing-page performance. AEO adds a different question: when an answer engine constructs a response, why does it represent or recommend one brand instead of another?

    The distinction matters because an AI appearance is not a single outcome. A brand can be mentioned without being recommended. A page can be cited without the brand becoming the preferred choice. An answer can also describe a company accurately while excluding it from a shortlist. If a platform combines those events into one visibility score, the number may be easy to report but difficult to act on.

    Conductor’s stated next phase is to move beyond checking whether a brand appears in an AI answer. The company wants to help teams understand why a brand is or is not recommended, then translate that diagnosis into content and website changes. Treat that as a strategic destination rather than proof that every part of the workflow is already available at the same level of maturity.

    AEO layerQuestion it must answerEvidence you should expectCommon failure
    MeasurementWhere and how does the brand appear?Prompt set, answer engine, market, date, answer text, citation and recommendation statusReducing every appearance to one visibility score
    DiagnosisWhat may explain the inclusion or exclusion?Traceable connections to pages, entities, claims, citations, competitors or technical conditionsPresenting a plausible explanation as proven causation
    ActivationWhat should the team change?A prioritized action tied to an owner, affected asset and intended question or entityGenerating a generic content task with no relationship to the observed answer
    ValidationDid the change improve the intended outcome?A controlled change log and repeated measurement using a consistent methodClaiming success from a single variable AI response

    This is the standard to carry into any AEO conversation. Measurement tells you what happened. Diagnosis proposes why. Activation gives someone a bounded change to make. Validation checks whether the expected movement followed. A tool that stops after the first layer is monitoring software, even if the dashboard is labeled AEO.

    What customers and buyers should ask Conductor now

    A leadership transition does not require you to pause a procurement process or rewrite an existing search program. It does justify a more precise product review. Use one real customer question throughout the next demonstration, renewal discussion or roadmap session, and ask the team to show the complete path from observed answer to validated action.

    1. Separate shipped capabilities from strategic intent. Ask which AEO functions are generally available, which are limited releases or tests, and which remain on the roadmap. A future direction can be credible without being a current product feature, but the distinction belongs in your decision.
    2. Inspect the measurement frame. Ask which answer engines are covered and how prompts, locations, languages and time periods are handled. Find out whether the system stores the underlying answer and citations or only a derived score. Without that context, you cannot investigate a visibility change.
    3. Clarify what counts as visibility. Require separate treatment of mentions, citations and recommendations. Then ask how sentiment, factual errors and competitor inclusion are represented. A single blended metric can conceal the event your team actually needs to fix.
    4. Challenge every explanation. When the platform says why a brand was excluded, ask which observable evidence supports that conclusion. A diagnosis should identify its inputs and uncertainty. It should not turn correlation into a promise that one page edit will change a model’s answer.
    5. Follow the recommendation into the website. Ask whether an insight points to a specific URL, template, entity, claim or technical issue. Check whether your team can assign the work, record what changed and rerun the same analysis later. Advice that cannot survive this handoff tends to become another unprioritized content backlog.
    6. Verify how the platform’s components work together. Conductor expanded through the acquisitions of ContentKing and Searchmetrics. Do not assume acquired data or capabilities automatically form one workflow. Ask the vendor to demonstrate exactly how monitoring, search intelligence, AI visibility and recommended actions connect in the product you would license.
    7. Define the business outcome before discussing the score. Decide whether you need accurate brand representation, shortlist inclusion, cited authority, qualified visits, assisted conversions or sales enablement insight. You can then judge whether the platform supplies evidence for that outcome rather than accepting visibility as a substitute for it.

    Use the same scenario with every platform you evaluate. A consistent task exposes differences that a polished feature tour can hide. It also keeps the buying decision anchored to your workflow instead of each vendor’s preferred terminology.

    Run a vendor-neutral AEO test before changing strategy

    Three unbranded AI systems process identical source materials through the same transparent verification setup in a neutral laboratory.

    You do not need to wait for Conductor’s roadmap to mature before improving your AEO practice. Build a small, vendor-neutral test that you can later run through Conductor or another platform. The goal is to preserve your own evidence and decision logic.

    1. Create a stable question set. Start with real questions a buyer asks while defining a problem, comparing approaches or selecting a provider. Group them by intent. Save the exact wording rather than keeping only a topic label.
    2. Capture the complete response context. Record the answer engine, date, market, prompt, response text, cited pages, named competitors and whether your brand was mentioned, cited or recommended. This becomes the baseline against which later changes are judged.
    3. Write one evidence-based hypothesis for each problem. A missing recommendation might relate to weak comparative evidence, an unclear entity, inconsistent claims, inaccessible content or insufficient support for the answer being requested. Treat each as a hypothesis to test, not a diagnosis already proven by the output.
    4. Make a bounded change. Update the smallest defensible set of pages or templates. Record the URLs, the claims added or corrected, the technical changes and the publication date. If you change the whole site at once, you lose the ability to learn which intervention mattered.
    5. Repeat the same collection method. Generative answers can vary, so do not treat one favorable response as proof. Look for repeated directional change while keeping the prompt set and observation method as consistent as possible.
    6. Connect the result to an operating decision. Decide whether the evidence supports expanding the change, revising the hypothesis or leaving the page alone. The purpose of an AEO system is to improve this decision loop, not merely produce a larger report.

    If a recommendation involves schema or JSON-LD, treat structured data as machine-readable corroboration rather than a switch that guarantees inclusion. The markup should match the visible page, describe the relevant entity and relationship precisely, and avoid claims the page cannot substantiate. Your AEO workflow should also explain which observed question or ambiguity the markup is intended to address.

    This test gives you an asset the vendor cannot own: a stable set of questions, observations, hypotheses and change records. You can use it to evaluate new functionality without resetting your measurement whenever a platform changes its labels or scoring model.

    Watch for evidence that AEO has become an operating system

    Conductor launched Conductor AI about a year before announcing the succession and says hundreds of enterprises have adopted it. That indicates market uptake, but adoption is not the same as a demonstrated customer outcome. The next phase should be judged by what teams can reliably do after they receive an AI visibility result.

    Look for four forms of evidence as Wei Zheng takes over: transparent measurement methods, diagnoses linked to inspectable signals, actions tied to specific website assets, and validation that distinguishes a repeated pattern from a single fluctuating answer. Customer examples become more meaningful when they show this chain rather than reporting adoption or visibility growth without the underlying method.

    Also watch how the company balances AEO with the search work enterprises still have to run. AI recommendations depend on accessible, accurate and well-supported information. Technical health, content quality, entity clarity and conventional search discovery remain inputs to that work. A credible AEO strategy should connect those disciplines instead of treating AI visibility as a detached channel.

    Your next move is straightforward: put one real question set through the measurement, diagnosis, activation and validation loop, then ask Conductor to show its evidence at every handoff. If the new strategy makes that loop clearer and faster, the transition will matter to your program. If it produces only a renamed visibility report, keep your AEO decisions anchored to the evidence you control.

    References


  • How to Run an AI Brand Visibility Audit That Drives Action

    How to Run an AI Brand Visibility Audit That Drives Action

    Your search rankings can look healthy while an AI answer ignores your brand, describes it incorrectly, or recommends a competitor. That does not mean SEO stopped mattering. It means the outcome you need to measure has changed.

    A useful AI brand visibility audit shows where your brand appears, what the system claims about it, which evidence supports the answer, and why another brand may be selected instead. Traditional search visibility and AI visibility can diverge, so you cannot use rankings or local-pack presence as a substitute for this work.

    Key takeaways

    • Measure mentions, recommendations, citations, and factual accuracy separately. They are different outcomes with different fixes.
    • Test the questions customers ask while choosing, comparing, and validating options. A branded lookup alone cannot reveal whether AI systems discover your brand.
    • Check crawler access, entity consistency, factual specificity, claim support, unique information, and JSON-LD before treating missing visibility as a content-volume problem.
    • Treat one generated answer as an observation. Prioritize patterns that recur across relevant prompts, sessions, or AI surfaces.
    • Fix access barriers and incorrect facts before chasing more mentions. Being visible with the wrong information is not a win.

    Build a prompt set around customer decisions

    Blank prompt tiles branch between objects symbolizing product discovery, comparison, selection, purchase, and customer support.

    Start with the decision your customer is trying to make. A prompt such as What is [brand]? tests recognition and basic factual recall. It does not show whether your brand would be found when the customer has not named it.

    Create prompts for each commercially important audience, need, location, and constraint. Keep the wording neutral. If you tell the system that your brand is the leading option or ask why it was excluded, you have already biased the test.

    1. Discovery: Which [category] providers serve [audience or location] and meet [specific need]?
    2. Fit: Which option is suitable for someone who needs [feature, policy, use case, or constraint]?
    3. Comparison: How do [brand] and [competitor] differ for [specific decision]?
    4. Fact retrieval: What does [brand] offer, where is it available, and what policies apply?
    5. Validation: Is [brand] a credible option for [use case], and what evidence supports that assessment?

    Reuse the same wording when you want comparable observations. Begin a fresh conversation where possible, preserve the complete response, and record any visible citations. Do not reduce the result to a yes-or-no mention check.

    DimensionWhat to recordWhat it reveals
    PresenceAbsent, named, or described without a clear nameWhether the system associates your entity with the prompt
    ProminencePrimary recommendation, alternative, comparison subject, or passing mentionWhether visibility is commercially meaningful
    CitationYour site, another site, or no visible citationWhich evidence is available for inspection
    AccuracyCorrect, outdated, contradictory, unsupported, or unclearWhether visibility helps or harms the customer decision
    Competitive displacementWhich alternative appears and the stated reasonWhere another brand supplies stronger relevance or evidence

    Paid monitoring platforms can automate structured prompts across multiple AI surfaces and track mentions, citations, competitors, and inconsistencies over time. That automation is difficult to reproduce at scale, but the initial diagnostic can still be performed manually if you preserve the evidence and apply consistent labels.

    Inspect the signals behind each answer

    A glowing answer orb connected to layered source signals, including a webpage, document, storefront, reviews, and citation nodes, with strong, weak, and broken links.

    Prompt results show the symptom. Your next job is to find the upstream reason. More content is not the default answer: an access restriction, contradictory business fact, vague claim, or missing entity relationship can undermine an otherwise substantial site.

    Confirm that AI crawlers can reach meaningful content

    Open yourdomain.com/robots.txt and inspect any rules for GPTBot, ClaudeBot, PerplexityBot, and Google-Extended. A disallow rule may be an intentional policy choice, so document it before changing it. The audit question is whether access matches the organization’s actual policy, not whether every crawler should automatically be allowed.

    Then visit the site as a new user. Check whether the homepage or important landing pages hide their substantive content behind a cookie wall, language selector, location picker, or another interstitial. These gates can leave less-established crawlers unable to reach the facts even when conventional search crawling appears healthy.

    Map the entities the brand needs AI to understand

    List each distinct thing an answer may need to describe: the business, products or service lines, relevant staff, policies, locations, and location context. For each entity, record its canonical name, defining attributes, public URL, supporting evidence, and the person responsible for keeping it current.

    Do not treat a passing marketing mention as documentation. A location page that says conveniently located but gives no nearby landmarks, distances, transport details, or service area leaves the location entity underdefined. A service page that promises flexible options but never names those options creates the same problem.

    Compare important facts across the website, Google Business Profile, and other public representations. Different names, addresses, policies, descriptions, or availability statements create entity drift. Consistency is a foundational trust signal; decide which location is canonical, correct it first, and then align the rest.

    Test whether the facts are extractable and defensible

    AI systems can reuse a direct factual statement more cleanly than a sentence built from vague adjectives and unclear pronouns. Paste a priority page into an AI assistant and ask it to identify every pronoun, adjective, or phrase whose referent or meaning is ambiguous. Require a fact-specific rewrite for each flagged sentence, then verify the rewrite yourself before publishing it.

    Audit claims separately. Search your pages for best, most, only, award-winning, leading, and similar language. Record the evidence behind each claim, the entity that granted any award, and the page where a reader can verify it. If the evidence does not exist, narrow the statement to a supportable fact or remove it. An uncheckable superlative gives an AI system little reason to repeat the claim.

    Look for information gain and meaningful structured data

    Take several sentences from a priority page and search for them in quotation marks. If competitors could publish the same wording without changing a detail, the page contributes little unique evidence. Replace generic language with information your organization can substantiate: named processes, exact policy conditions, original measurements, specific product attributes, or first-party findings.

    View the page source and search for application/ld+json. No match means that page has no JSON-LD block. A match is only the beginning of the check: inspect whether the markup represents the actual entities and relationships on the page or merely supplies a thin, flat label.

    Verify that names, URLs, locations, and relationships agree with visible content. Inspect sameAs values carefully and use them only for records that genuinely identify the same entity, including applicable Wikidata or Knowledge Graph identifiers. Structured data can clarify identity and relationships, but its presence does not guarantee a recommendation.

    Turn response patterns into a prioritized diagnosis

    A single visibility percentage conceals the difference between absence, weak prominence, missing evidence, and factual error. Diagnose each repeated pattern before assigning work.

    Observed patternInvestigate firstAction to take
    Brand is absent from non-branded discovery promptsCrawler access, category association, location facts, and incomplete entitiesResolve access barriers and add explicit, supportable facts connecting the brand to the relevant need
    Brand appears only when namedWeak association with the use case, audience, category, or locationStrengthen the relevant entity pages with decision-ready facts rather than repeating the brand name
    Brand is mentioned with incorrect factsContradictory or outdated public representationsCorrect the canonical page, align external profiles, and document the changed fact for retesting
    A competitor is recommended and citedThe cited page’s specificity, proof, entity coverage, and fit to the promptIdentify the evidence your page lacks; do not copy the competitor’s wording
    Your site is cited but the brand is not recommendedEvidence for customer fit, limitations, policies, and differentiatorsMake the decision criteria explicit and support each material claim
    A recommendation appears without a visible citationAccuracy and reproducibility of the stated reasoningRecord the answer without guessing its origin, verify every claim, and look for the pattern in other tests

    Prioritize by consequence and dependency, not by whichever gap is easiest to edit.

    1. Remove access barriers that prevent important pages from being reached.
    2. Correct wrong or contradictory business facts, especially facts that could change a customer’s decision.
    3. Complete the commercially important entities and their location, product, service, staff, and policy attributes.
    4. Replace generic claims with verifiable evidence and information the brand uniquely possesses.
    5. Refine JSON-LD so it faithfully represents the corrected visible content and entity relationships.
    6. Rerun the unchanged prompts and compare the complete answers, not just the mention count.

    Each resulting ticket should contain the prompt, the complete observed answer, the affected customer decision, the suspected cause, the page or profile to change, the evidence required, and the retest condition. This keeps an AI visibility problem from becoming a vague request to improve the content.

    Make the audit repeatable without turning it into dashboard theater

    Keep a durable audit log. At minimum, capture the prompt, audience, need, location or constraint, AI surface, conversation state, observation date, full answer, prominence label, cited URLs, factual errors, named competitors, suspected cause, owner, and fix status. Preserve raw outputs even if you later calculate summary metrics.

    Repeat the audit with the same core prompt set after material changes to the website, business facts, policies, products, services, or locations. Add prompts when a genuinely new customer decision appears, but do not silently rewrite old prompts and compare the results as if the test stayed constant.

    Automation becomes useful when the number of prompts, AI surfaces, locations, or competitors makes manual tracking unreliable. Some platforms let teams ask natural-language questions and receive answers grounded in their own visibility data. That can speed up investigation, but the interface should still lead you back to inspectable evidence.

    Before adopting a paid visibility platform, verify that it can retain raw responses, expose citations, preserve prompt wording, distinguish mentions from recommendations, compare competitors, flag entity inconsistencies, and show change history. A polished composite score is not enough if you cannot trace it to the answer that created it.

    Begin with the customer decision that matters most. Capture the current answers, label what happened, and fix the first upstream failure: access, identity, specificity, evidence, or structure. Then rerun the same prompt. The practical goal is fewer missing, unsupported, and incorrect brand answers when a customer is ready to choose.

    References


  • Google Search Visibility Data Changed: What to Trust Now

    Google Search Visibility Data Changed: What to Trust Now

    Your SEO dashboard can look worse even when your site has not lost meaningful Google visibility. If total ranking keywords or SERP features suddenly collapse while clicks and leads remain steady, do not declare a ranking loss until you determine whether the site changed or the measurement system did.

    Google has changed how third-party tools can collect search results, altered an important result-depth parameter, and added first-party reporting for multimodal searches. The practical challenge is no longer choosing one perfect metric. It is knowing which question each metric can still answer.

    Three breakpoints changed the meaning of your trend lines

    A rank tracker can lose the ability to observe a result without your page losing its position. That distinction became more important after three Google changes:

    Each change makes large-scale collection more difficult or expensive. Losing num=100 means a provider can no longer request the first 100 results in one operation. Resolving passthrough links adds work for each affected result. A provider may respond by collecting fewer positions, sampling more aggressively, refreshing less frequently, or charging more for equivalent coverage.

    The distortion is most likely to appear deep in the results because positions below the first page are expensive to collect and usually less valuable to customers. This turns a platform’s total keyword count into two measurements at once: your site’s search footprint and the platform’s ability to observe that footprint. Treating it as a pure performance metric is now a category error.

    Recognize the signature of a collection failure

    Luminous result tiles pass through a scanning tunnel, where a blocked aperture causes only part of the continuing stream to reach the collection trays.

    A genuine visibility loss and a collection failure can both produce a falling graph. The distribution of the decline tells you which explanation is more plausible.

    For Reddit, Semrush data from May to June 2026 showed more than 60 million fewer ranking keywords and more than 13 million fewer SERP features. Those represented month-over-month declines of 25% and 21%, respectively, while estimated traffic remained steady. The loss also became progressively larger at deeper positions:

    Position bandChange from May to June 2026What the pattern indicates
    Position 1+16%The most visible rankings remained observable
    Top 3+11%High-value coverage did not collapse
    Positions 4-10-8%Loss began within the remaining first-page results
    Positions 11-20-28%Missing coverage accelerated beyond page one
    Positions 21-50-34%Deep-result visibility deteriorated sharply
    Positions 51+-35%The deepest rankings were the least observable

    This is not a universal benchmark. It is a diagnostic pattern. A real sitewide ranking collapse of that scale would not normally erase progressively more deep positions while expanding Position 1 and Top 3 counts and leaving estimated traffic unchanged. A depth-weighted decline points more strongly to reduced collection coverage.

    It can also make the surviving data look deceptively healthy. If a tool stops observing positions 40 through 80 but retains positions 1 through 10, the reported keyword total falls while the average position may improve. That apparent improvement is survivor bias, not necessarily better SEO.

    Use this sequence whenever a visibility graph breaks:

    1. Start with business outcomes. Check whether organic leads, sales, sign-ups, or other meaningful actions declined during the same period. Stable outcomes do not prove that rankings were stable, but they reduce the likelihood of a commercially significant collapse.
    2. Check Google Search Console clicks and landing pages. If third-party keyword totals plunge while clicks and the pages receiving those clicks remain broadly stable, investigate collection coverage before changing content.
    3. Split rankings into Position 1, Top 3, positions 4-10, 11-20, 21-50, and 51+. A drop concentrated in the deepest bands is more consistent with an observation problem than an across-the-board ranking loss.
    4. Compare branded and non-branded priority queries separately from the provider’s entire discovered keyword universe. A controlled set of commercially important queries is more useful for tactical decisions than a volatile inventory of every term the tool happened to find.
    5. Look for provider-specific discontinuities. If one platform changes abruptly while first-party clicks, outcomes, and another independent ranking view do not, label the event as a probable measurement break.
    6. Allow for mixed diagnoses. A collection change and a real traffic decline can happen together. If clicks, conversions, important landing pages, and high-ranking priority queries all deteriorate, continue the SEO investigation even if deep-result coverage also changed.

    Rebuild reporting around questions, not one visibility score

    No single visibility number can now support every decision. Give each reporting layer a defined job and state its limitation beside it.

    Reporting layerUse it to answerMain limitation
    Business outcomesIs organic search contributing qualified leads, sales, or other valuable actions?Demand, attribution, and conversion behavior can change independently of rankings
    Google Search Console clicks and pagesDid Google Search send traffic, and which landing pages received it?Reporting definitions and automated search activity can affect historical comparability
    Priority rank setDid a controlled set of branded, commercial, and strategically important queries move?Results vary by location, device, and the provider’s collection method
    Total keywords and SERP featuresWhere might new topics, competitors, or result features be emerging?These inventory metrics are highly exposed to collection-depth changes
    Multimodal performanceAre visual search experiences discovering the site’s content?It is a distinct search surface and does not replace conventional ranking or generative AI query data

    Your report also needs a measurement change log. Record the date, affected tool, affected metric, likely mechanism, position bands involved, and whether the provider changed its collection method. Put the annotation on the chart itself. A note hidden in a separate methodology document will not stop someone from treating the break as a performance event.

    Keep the original series, but do not draw an unqualified continuous trend across an incompatible baseline. Compare periods collected under the same method where possible. If that is not possible, present pre-change and post-change periods as separate regimes and label the comparison as measurement-affected. Do not invent a correction factor unless you have enough overlapping data to defend it.

    September 2026 year-over-year reports require particular care. Search Console impressions fell after num=100 disappeared in September 2025 because automated requests had previously generated impressions for deep results. That creates a suppressed comparison baseline, so double-digit year-over-year impression growth can appear without an equivalent improvement in actual performance.

    Do not present that percentage alone. Put absolute clicks, business outcomes, priority-query movements, and landing-page performance beside it. If only impressions rebound against the lower baseline, describe the result as affected by measurement history rather than evidence of equivalent SEO growth.

    Measure multimodal discovery as a separate search surface

    An object on a pedestal is examined through three separate pathways represented by a visual sensor, an acoustic sensor, and a magnifying lens.

    While third-party result coverage is becoming less complete, Search Console is adding a first-party view of visual discovery. Its multimodal search filter covers Google Lens, Circle to Search on Android, image uploads to Google Search, and Chrome’s Search this image action. The data is rolling out globally and appears when a site receives traffic from those experiences.

    Multimodal visibility should not be folded silently into a general visibility score. A person searching with an image is expressing intent differently from someone typing a conventional query, and the optimization work is often different. Track the surface separately so you can see whether visual discovery is growing, which pages participate, and whether that exposure leads to useful behavior.

    • Record when multimodal data first becomes available for your property. Do not interpret the first visible reporting period as the date your site first appeared in visual search.
    • Review the landing pages associated with multimodal activity. Check that their images are useful to the page’s purpose, accessible to crawlers, supported by clear nearby text, and described with accurate text alternatives.
    • Keep structured data faithful to the visible page. Schema can clarify products, organizations, articles, and other entities, but it should not describe an image, offer, or claim that users cannot find on the page.
    • Connect multimodal reporting to page-level outcomes. More visual discovery is interesting; it becomes valuable when the discovered pages attract relevant engagement or conversions.
    • Do not manufacture query-level precision where Google does not supply it. The generative AI search performance report still lacks click and query data, so a generative visibility narrative should acknowledge that blind spot.

    The new filter is an additional lens, not compensation for missing third-party keyword coverage. It answers a new question: whether people are finding your content through visual and multimodal behavior. It does not tell you that a disappearing position-50 keyword remained stable, and it does not provide the prompt-level attribution many teams want from generative search.

    Key takeaways for your next SEO report

    • A falling third-party keyword count is not, by itself, evidence of lost Google traffic.
    • A decline concentrated below positions 10 or 20 is more suspicious as a collection problem than a uniform loss across top rankings.
    • Clicks, landing pages, and business outcomes should determine the severity of the response; discovered keyword totals should support exploration, not act as the verdict.
    • January 2025, September 2025, and August 2026 belong in your reporting change log because each altered how search visibility could be observed.
    • September 2026 year-over-year impression growth may be inflated by the lower post-num=100 baseline from September 2025.
    • Multimodal reporting deserves its own baseline, goals, and page-level analysis. Do not merge it into conventional web or generative AI visibility without a label.

    Before your next report goes out, annotate the three collection breakpoints, split ranking data by depth, and place first-party clicks and business outcomes ahead of total keyword counts. Then establish a separate baseline for multimodal discovery. That small reporting redesign can keep a measurement change from triggering the wrong content rewrite, budget decision, or performance diagnosis.

    References


  • Goodie vs. Profound: Which AEO Platform Fits Your Team?

    Goodie vs. Profound: Which AEO Platform Fits Your Team?

    You are not choosing between two AI visibility dashboards. You are choosing where your team will do the hardest part of answer engine optimization: finding worthwhile prompts, deciding what to change, shipping the work, or proving that the work affected the business.

    If you are stuck between Goodie and Profound, start with that bottleneck. Goodie is the clearer fit when you want prompt research, prioritized actions, execution, and revenue attribution in one operating loop. Profound is the stronger candidate when deep prompt intelligence, crawler analysis, and configurable enterprise workflows matter more than receiving a tightly prescribed action queue.

    The practical answer: choose the workflow your team can run

    Both platforms can help you monitor how a brand appears in AI-generated answers. That overlap is real, but it is not where the buying decision lives. The meaningful difference is what happens before monitoring and after a visibility problem appears.

    Decision areaGoodieProfoundWhat it means for you
    Primary orientationClosed-loop AEO operationsEnterprise AI-search intelligence and automationChoose between a more prescribed operating loop and a deeper intelligence layer your team can configure.
    Prompt researchTurns prompt opportunities into monitored topics and optimization workConversation Explorer emphasizes prompt demand and audience-question intelligenceDecide whether you need an actionable queue or a larger research environment.
    OptimizationPrioritized actions tied to visibility gapsWorkflows and agents that can support automated content operationsGoodie reduces interpretation work; Profound can reward teams able to design their own processes.
    Technical intelligenceConnects monitoring with recommended content and technical changesAgent Analytics examines how AI crawlers interact with a siteProfound deserves close attention when crawler behavior is a central diagnostic requirement.
    Business measurementRevenue attribution is presented as part of the native AEO loopStrong visibility, crawler, and referral analysis; revenue-level measurement needs closer validationIf finance expects pipeline or revenue evidence, test the attribution chain rather than accepting an integration logo.
    Operating fitTeams that want fewer handoffs between analysis and executionEnterprises with analysts, marketing engineers, or established content operationsThe more capable your internal operating team is, the more value it can extract from a flexible intelligence platform.

    Goodie positions its product around a research-to-revenue loop, while Profound emphasizes Conversation Explorer, Agent Analytics, and agentic workflows. Those capability claims originate with Goodie, one of the vendors being evaluated, so treat them as hypotheses for your proof-of-fit rather than as an independent benchmark.

    The short recommendation is straightforward. Choose Goodie when the missing link is turning visibility data into owned work and connecting that work to commercial outcomes. Put Profound first when you already have people who can interpret data and execute, but they need richer prompt intelligence, crawler evidence, and automation infrastructure.

    Prompt research: decide whether you need a map or a queue

    Two strategists compare a broad constellation of connected prompt signals with a focused queue of prompt cards in a digital studio.

    Your prompt set is not a minor configuration detail. It defines the market the platform measures. If you track only brand-name questions, your score can look healthy while you remain absent from the unbranded questions buyers ask before they know you. If you fill the set with broad informational prompts, you can generate a large dashboard with little connection to a purchase decision.

    A useful prompt library should cover distinct stages of the decision, including:

    • Problem recognition: questions asked before the buyer knows which category could help.
    • Category discovery: requests for approaches, products, providers, or methods.
    • Comparison: questions that place alternatives, features, constraints, or use cases side by side.
    • Validation: questions about proof, reliability, security, implementation, or compatibility.
    • Purchase friction: questions about price, migration, onboarding, contracts, and switching risk.
    • Post-purchase use: questions that can influence retention, adoption, and recommendation.

    Profound’s Conversation Explorer is built around discovering and evaluating what people ask answer engines. That makes Profound compelling when your first problem is demand intelligence: you do not yet know which conversations matter, how questions cluster, or where the relevant opportunity sits.

    Goodie’s Prompt Research is designed to feed discovered opportunities into monitoring and optimization actions. That orientation is useful when your team already understands the market reasonably well but struggles to convert research into an ordered backlog.

    Make both vendors work from the same prompt brief

    Do not let either demo begin with a polished sample category. Give both vendors the same brief containing your products, markets, buyer roles, competitors, and exclusions. Include questions where you expect to appear, questions where a competitor usually appears, and questions for which you do not yet know the answer.

    1. Ask the platform to expand your seed questions without adding irrelevant informational demand.
    2. Require an explanation for why each suggested prompt belongs in the monitored set.
    3. Inspect the raw answer-engine responses behind every aggregate score.
    4. Check whether prompts can be segmented by intent, audience, market, product, and stage of the buying journey.
    5. Change the prompt set and confirm that historical reporting remains interpretable.
    6. Ask how a discovered opportunity becomes assigned work, not merely another saved chart.

    The winner is not the platform that returns the largest list. It is the one that helps you defend why a prompt matters and shows what your team should do with it. A vast prompt database can still produce a weak AEO program if no one can distinguish buyer demand from topical noise.

    Optimization and attribution reveal the real split

    Visibility monitoring tells you that an answer engine mentioned a competitor, cited another domain, or described your brand inaccurately. That is diagnosis. The operational value begins when someone can identify the underlying cause, choose an intervention, assign an owner, publish or deploy the change, and watch the relevant answers afterward.

    Goodie puts prioritized optimization actions and revenue attribution inside the same product scope as prompt research and monitoring. For a lean team, that can remove the recurring handoff from analyst to strategist to writer or developer. It also gives leadership a more direct narrative: this was the visibility gap, this was the action, and this was the observed business outcome.

    Profound should not be dismissed as a monitoring-only product. Its Workflows support automated content operations, while Agent Analytics examines crawler activity and answer-engine referrals. The distinction is that Profound’s value leans more heavily on the sophistication of the operator. A marketing engineering team may prefer that flexibility. A small SEO team may discover that it has bought a powerful system without enough capacity to design and maintain the workflows around it.

    Test whether an optimization is evidence, advice, or execution

    Vendors often place all three under the word optimization, but they are different deliverables:

    • Evidence identifies the prompt, response, cited sources, competitor, and affected page.
    • Advice explains the likely cause and recommends a specific change.
    • Execution creates, exports, assigns, publishes, or deploys the work.

    During the evaluation, select a genuine visibility gap and follow it all the way through the product. Ask which page should change, what should change on it, why that intervention matches the evidence, who receives the task, and how the system detects a later answer change. If the workflow ends with generic advice such as improve authority or create better content, you are still buying diagnosis.

    Do not confuse an AI referral report with revenue attribution

    A referral dashboard can show visits from an answer engine. Revenue attribution has to explain how those visits, leads, opportunities, or purchases are associated with the channel. A visibility trend is further removed: a brand can gain mentions without receiving a click, and a later conversion may have several earlier influences.

    Goodie’s native attribution proposition gives it the clearer advantage when proving commercial impact is a purchase requirement. You should still make the team expose the method. Ask these questions on screen:

    • Which outcomes are observed directly, and which are modeled?
    • How are direct referrals distinguished from zero-click exposure?
    • Can reporting separate first-touch, last-touch, and assisted influence?
    • Can you trace a prompt, visibility gap, optimization action, changed response, visit, and conversion without manually joining exports?
    • Which analytics and CRM fields are required?
    • Can your analysts export the underlying events and reproduce the reported total?
    • How does the system avoid claiming causation from a visibility increase that merely occurred before a revenue increase?

    If the platform cannot answer those questions, call the feature directional measurement rather than revenue attribution. That does not make it useless. It makes the claim precise enough for your finance and analytics teams to use responsibly.

    Enterprise pricing: model the total cost of operation

    The headline prices create an easy trap. Goodie lists Core at $399 per month and Pro at $999 per month, while Profound lists Starter at $99 per month and Growth at $399 per month; broader enterprise packages use custom pricing. Those figures do not represent equivalent scopes.

    A lower subscription can become the more expensive operating model if you must add analyst time, workflow tooling, content production, technical implementation, and a separate attribution layer. An integrated platform can also become expensive if the features you need sit above the entry plan or if usage expands with prompts, answer engines, brands, markets, and response volume.

    Calculate total operating cost as the subscription plus usage expansion, onboarding, integrations, internal analysis, content and technical execution, data engineering, security review, and ongoing administration. Use the same scope for both quotes.

    Quote lineWhat to requireWhy it changes the real price
    Prompt economicsTracked prompts, research queries, generated responses, refresh frequency, and overage rulesVendors can meter different units even when their plan labels look similar.
    Engine coverageExact answer engines available on the quoted tierA long platform list is irrelevant if the engines you need require an upgrade.
    Organizational scopeBrands, products, markets, countries, languages, seats, roles, and workspacesEnterprise cost often grows through organizational complexity rather than a single feature.
    Data accessHistory, retention, raw responses, exports, API access, and business-intelligence connectionsA dashboard can become a data silo if usable evidence cannot leave it.
    ExecutionAction allowances, workflow or agent credits, publishing paths, approvals, and task-system integrationsAn action layer may be available but metered separately from monitoring.
    AttributionAnalytics connections, CRM support, identity handling, models, and raw event accessAttribution may require implementation work outside the license.
    GovernanceSSO, permissions, audit records, data handling, and procurement documentationRequired controls can move an otherwise affordable deployment into an enterprise contract.
    ServiceOnboarding, strategist access, support channel, response commitments, and trainingA platform that requires specialist operation should be priced with that labor included.
    Commercial termsBilling period, minimum commitment, renewal mechanics, overages, implementation fees, and exit accessThe monthly figure alone does not reveal contractual risk.

    Key takeaways

    • Choose Goodie when your main gap is turning prompt and visibility data into prioritized work and connecting the result to revenue.
    • Choose Profound when deep prompt intelligence, crawler analysis, and configurable enterprise automation are the priority, and you have specialists who can operate them.
    • Do not treat visibility, referral traffic, and revenue attribution as interchangeable measurements.
    • Compare quotes using the same engines, prompts, brands, markets, seats, integrations, data access, service, and execution workload.
    • Treat every vendor-supplied capability claim as something to reproduce with your own prompts, pages, and analytics path.

    Run a proof-of-fit that produces work, not screenshots

    A cross-functional team moves prompt artifacts through testing stations for discovery, content improvement, release, verification, and outcome validation.

    A polished dashboard demo tells you very little about whether the platform will survive contact with your organization. A useful proof-of-fit starts with your evidence and ends with a decision or deliverable your team would genuinely use.

    1. Write the operating problem in one sentence. For example: the content team cannot tell which unbranded buyer questions deserve work, or leadership cannot connect AEO activity to pipeline.
    2. Provide an identical prompt set, competitor set, market scope, and group of existing pages to both vendors.
    3. Require access to the raw responses, citations, timestamps, segmentation, and calculation behind every score shown.
    4. Select a real visibility gap and make each platform diagnose it, recommend a change, and route the work to the person who would own it.
    5. Run the proposed change through your approval and publishing process. Note every manual export, copy-and-paste step, missing integration, and specialist handoff.
    6. Connect the relevant analytics environment and trace what the platform can observe after the change. Separate answer visibility, referrals, conversions, and modeled influence.
    7. Request a production quote for the exact tested scope, including expansion rules and the controls procurement will require.

    Score the result on prompt relevance, diagnostic transparency, action quality, workflow fit, measurement credibility, governance, and total operating cost. Do not create a broad feature checklist in which every row has equal value. A missing capability that blocks your operating loop matters more than several interesting features your team will not use.

    Goodie should win your evaluation if it consistently turns relevant prompt gaps into work your existing team can ship, then gives your analysts a defensible path to business outcomes. Profound should win if its prompt and crawler intelligence changes your decisions materially, and your team can exploit its workflows without adding an unplanned operating layer.

    If neither vendor can reproduce its claims using your prompts and data, do not force a selection. Tighten the use case, establish a manual baseline, and return when you know which part of the AEO loop deserves software. Before the next demo, complete this sentence: We are buying this platform so that a named owner can make a named decision and ship a named change without a named bottleneck. The product that proves that workflow is the better choice for you.

    References


  • SEO for AI-Mediated Search: A Practical Visibility Plan

    SEO for AI-Mediated Search: A Practical Visibility Plan

    Your rankings can look healthy while your brand is missing from the answer a customer actually sees. Or an AI system can mention you, describe you incorrectly, and send no visit that your analytics can attribute. If you still judge organic performance only by positions and clicks, those failures stay hidden.

    The practical response is not to abandon SEO for a new acronym. It is to extend your existing search system so that machines can retrieve your pages, understand your entities, quote your claims, represent your brand accurately, and give an interested person a clear route to act.

    Run SEO and AI visibility as separate, connected scorecards

    Traditional rankings tell you whether a URL can compete in a search results page. They do not tell you whether ChatGPT, Gemini, Google AI Mode, or another generated-answer experience mentions your brand, cites your site, or repeats the right facts. AI visibility therefore needs its own measurements.

    This distinction matters because an answer interface can satisfy part of a search without passing the user to a website. In a March 2026 randomized field experiment involving 1,100 U.S. Chrome users, forcing nearly 95% of searches through Google AI Mode reduced the share that led to an external website by 18.8 percentage points. Participants also reported lower satisfaction, usefulness, control, personalization, and trust than people using Google normally.

    Do not turn that number into a universal traffic forecast. The treatment lasted seven days, the sample skewed younger, highly educated, and politically left-leaning, and participants were pushed into AI Mode rather than choosing it. The sound conclusion is narrower: AI-mediated discovery can materially reduce referral opportunities, and fewer clicks do not necessarily mean the answer experience served the user better.

    Build your reporting around three connected outcomes:

    • Retrieval: Can search engines and answer systems find the right page for the question? Track crawlability, indexation, rankings, relevant internal links, and whether the page appears as a cited or consulted resource.
    • Representation: Does the generated answer name the correct entity, describe it accurately, preserve important qualifications, and link to the appropriate URL? A positive-sounding mention is still a failure if it assigns the wrong feature, location, price, audience, or availability.
    • Response: What happens after exposure? Track referral visits where they are available, branded demand, assisted conversions, leads, sales, bookings, subscriptions, or the business action appropriate to the page.

    Keep these columns separate. A mention is not a citation. A citation is not a visit. A visit is not a conversion. Combining them into one visibility score hides the exact problem you need to fix.

    Turn keyword research into a prompt-and-decision map

    An overhead worktable displays blank cards, colored markers, branching threads, and comparison objects arranged from broad research to final choices.

    Keywords still reveal language, demand, and the pages competing for attention. Prompts reveal something different: the decision a person is trying to make, the conditions attached to it, and the comparison set an AI system may assemble before answering.

    A query such as “project management software” names a category. A prompt such as “Which project management platform suits a distributed agency that needs client approvals but has no dedicated administrator?” also supplies an audience, operating constraint, required capability, and evaluation criterion. A generic category page may rank for the first expression and still be unusable for the second.

    Create a prompt map for each product, service, location, person, or topic that matters commercially:

    1. Choose the entity. Start with one thing you need an answer engine to understand unambiguously: a product, service, organization, location, event, or expert.
    2. List the decisions surrounding it. Include discovery, comparison, validation, objection handling, and action. These are different information needs and may require different pages.
    3. Add real constraints. Capture the audience, use case, location, compatibility requirement, budget condition, risk, or desired outcome that changes the answer.
    4. Assign a canonical destination. Decide which page should answer each prompt family. If several URLs compete to make the same claim, consolidate the information or define a clear primary page.
    5. Record the proof required. Specifications, policies, examples, qualifications, prices, availability, authorship, and dates should sit close to the claims they support.
    6. Define the next action. A person who wants more than the generated answer should land on a page that continues the same task rather than restarting the journey.
    Decision momentPrompt patternJob of the destination pageUseful visibility signal
    DiscoverWhat approaches solve this problem for this audience?Explain the category, tradeoffs, and situations in which each approach fits.Your entity appears in the correct category and context.
    CompareWhich option fits these requirements or constraints?Make differentiators, exclusions, and supporting evidence easy to verify.The comparison includes you and states the right distinctions.
    ValidateDoes this option support a particular requirement?Provide an explicit answer, scope, conditions, and authoritative details.The answer uses the correct fact and cites its canonical page.
    ActWhere can I buy, book, apply, contact, or begin?Present current availability and a direct next step.The answer sends the user to the correct action page.

    For every tracked prompt, save the exact wording, platform, language, market or location, intended destination, expected facts, observed competitors, and business stage. This prevents a common reporting error: treating two prompts as equivalent even though one asks for information and the other asks for a recommendation.

    Your tooling should preserve this prompt-level detail. Rank Math AI, for example, tracks brand appearances in ChatGPT and Gemini separately from traditional rankings, with daily, weekly, or monthly monitoring in more than 30 languages. If you use a different platform or an internal process, require the same basic separation. The tool is instrumentation; your prompt set and evaluation criteria are the strategy.

    Make important pages easy to quote and hard to misread

    An answer engine should not have to assemble your central claim from an opening anecdote, a feature grid, a footnote, and a support page. Put the answer where a person can find it quickly, then place the evidence and limitations beside it.

    Use this structure on pages mapped to consequential prompts:

    • Direct answer: State the conclusion in plain language near the relevant heading. Answer the question before expanding it.
    • Named entity: Identify exactly which product, service, organization, location, event, version, or plan the statement concerns. Pronouns and vague category labels create avoidable ambiguity.
    • Qualifications: State who the answer applies to, where it applies, and which conditions or exclusions can change it.
    • Supporting evidence: Put specifications, policies, examples, definitions, and source links close to the claims they substantiate.
    • Freshness signal: Show a meaningful updated date when the information can change, and remove stale claims rather than leaving conflicting versions around the site.
    • Next step: Link to the comparison, documentation, product, booking, contact, or transaction page that continues the reader’s task.

    This is not permission to flatten every page into short answers. A concise answer earns comprehension; depth earns confidence. The page still needs the reasoning, evidence, alternatives, and boundaries a serious reader requires.

    Use structured data to corroborate visible facts

    JSON-LD should describe the same reality a visitor can see. It does not repair weak content, create an entity by itself, or make a stale offer current. Its useful role is to make entities, attributes, and relationships explicit without forcing a machine to infer them from presentation alone.

    Select the type that matches the actual entity. A product page may support Product markup; a property page may call for Hotel; an event page may use Event; and an important visual may be represented with ImageObject. Then verify that names, URLs, images, locations, dates, attributes, prices, and offers agree with the visible page and any current feed, inventory, booking, or location data.

    Audit these relationships as a system:

    • The entity has one preferred name and a stable canonical URL.
    • Alternate names do not accidentally create what looks like a second entity.
    • The structured description does not make claims absent from the page.
    • Offer, availability, date, location, and attribute data match operational systems.
    • Images and videos point to the entity and variant they actually depict.
    • Third-party profiles and distribution feeds do not contradict the first-party record.

    More markup is not the goal. Fewer unresolved contradictions is the goal.

    Use internal links to define the evidence path

    Internal links help a crawler discover URLs, but their strategic value goes further. They show how an overview, a detailed claim, its supporting documentation, and the action page relate to one another.

    Run a crawl and fix the basics first: broken destinations, redirect chains, and important pages with no contextual internal links. Then connect each canonical page in both directions. A category overview should point to the relevant detail page; the detail page should connect back to its parent and onward to proof or action. Use anchor text that names the relationship instead of repeating “learn more” throughout the site.

    Do not add links to every possible page. A dense but indiscriminate link graph blurs hierarchy. Link when the destination answers the next reasonable question, verifies the current claim, distinguishes a related entity, or enables the next action.

    Treat images and video as evidence, not decoration

    A tabletop studio photographs a generic mechanical component alongside close-up tools, material samples, and separated parts that reveal its construction.

    Visual optimization is no longer limited to image rankings or faster page loads. AI systems can interpret objects, attributes, surroundings, and relationships within a scene, then connect those observations to a product, place, business, or other entity. Google reports that Lens supports more than 25 billion visual searches per month, with one in five showing commercial intent.

    The important unit is therefore not the image alone. It is the relationship among the asset, the entity it depicts, the page around it, the metadata describing it, and the operational data that keeps the claim current.

    For every decision-relevant image or video:

    • Show useful attributes clearly. Original imagery should reveal the color, material, configuration, room type, amenity, dish, location, feature, or experience that affects a customer’s decision.
    • Identify the correct entity. A product image must connect to the right product and offer. A hotel image must connect to the correct property, room type, amenity, and location.
    • Write literal metadata. Use a descriptive filename, accurate alt text, and a caption when the caption adds context. Do not stuff the target phrase into descriptions of things the asset does not show.
    • Add explanatory surroundings. The heading, nearby copy, and page purpose should reinforce what the asset depicts and why it matters.
    • Make video language accessible. Supply a transcript and useful metadata so the information is available without requiring a system to infer everything from frames and audio.
    • Connect structured data. Associate the visual with the same entity, attributes, and canonical URL described on the page.
    • Keep distribution consistent. Website pages, profiles, publishers, booking platforms, product feeds, and social channels should not attach contradictory names or attributes to the same visual.

    Consider a hypothetical hotel image labeled as a rooftop pool on the property page while a booking feed assigns it to a different room category and a third-party profile calls the pool indoor. A person sees an appealing photograph; a machine sees competing entity relationships. Rewriting the alt text will not resolve that conflict. The property record, amenity data, page copy, structured data, and distribution feeds must agree.

    An asset register makes this manageable at scale. For each important visual, record its URL, depicted entity, visible attributes, canonical page, relevant structured-data type, associated feed or listing, usage rights, and last verification date. That turns visual SEO from a tagging task into a maintainable information system.

    Measure what the answer changed, then fix the weakest link

    Generated answers are observations at a point in time, not permanent rankings. Save enough context to reproduce each check: exact prompt, platform, language, location when relevant, date, answer text, cited URLs, brand description, competitors included, and the intended destination page.

    Use separate rates instead of one opaque score:

    • Mention coverage: tracked prompts in which your entity appears, divided by prompts tested.
    • First-party citation rate: answers citing your site, divided by answers in which your entity appears.
    • Representation accuracy: audited brand claims that are correct and properly qualified, divided by brand claims checked.
    • Destination accuracy: citations that lead to the canonical page for the task, divided by first-party citations observed.
    • Response value: attributable visits, engaged sessions, assisted outcomes, and completed business actions associated with AI discovery.

    Choose a monitoring cadence based on how quickly the underlying information and competitive answer set can change. A fast-moving offer or event warrants closer observation than an evergreen definition. Whatever cadence you choose, compare like with like; changing the prompt wording, language, geography, and platform at once makes the result impossible to diagnose.

    When performance changes, work through the failure in order:

    1. Not retrieved: Check indexation, crawl access, canonicalization, internal links, page relevance, and whether the necessary information exists in accessible text.
    2. Retrieved but absent from the answer: Tighten the direct answer, make the entity explicit, add the missing qualification or proof, and remove competing pages that make the canonical source unclear.
    3. Mentioned inaccurately: Locate contradictions across visible copy, JSON-LD, feeds, profiles, media metadata, and older pages. Correct the underlying record before adding more content.
    4. Mentioned but not cited: Strengthen the first-party page as the clearest source for the claim. Put evidence and the canonical fact together rather than distributing them across weak fragments.
    5. Cited but not visited: Determine whether the answer already completed the task. If a click is still useful, make the linked page promise a clear next layer: a tool, full comparison, current inventory, detailed method, documentation, or transaction.
    6. Visited but not converted: Treat this as a landing-page and journey problem. Ensure the page fulfills the prompt’s intent and makes the appropriate next action obvious.

    Do not judge an optimization by mention growth alone. A larger number of inaccurate mentions can damage understanding, while a smaller number of well-qualified citations on high-intent prompts may be more useful. Read representative answers, not just dashboard totals.

    Key takeaways

    • Keep classic rankings, AI mentions, citations, representation accuracy, visits, and conversions as distinct metrics.
    • Map prompts to customer decisions, constraints, expected facts, canonical pages, and next actions.
    • Place direct answers, qualifications, proof, and freshness signals together on the page that owns the claim.
    • Use JSON-LD, internal links, feeds, profiles, and visual metadata to reinforce one consistent entity record.
    • Diagnose the stage that failed before changing content: retrieval, inclusion, accuracy, citation, visit, or conversion.

    Start with one commercially important entity and the prompt family closest to a real decision. Record a baseline in the answer systems your audience uses, audit the canonical page and its supporting signals, correct the largest contradiction, and run the same prompts again. That small loop will teach you more than a sitewide program built around an undefined AI visibility score.

    References


  • Profound’s Gartner 2026 Recognition: What It Signals

    Profound’s Gartner 2026 Recognition: What It Signals

    If Profound’s Gartner recognition has put the platform on your shortlist, treat that as a reason to investigate, not a reason to buy. The useful question isn’t whether the recognition sounds impressive. It’s whether Profound can help your team turn an AI visibility problem into a specific intervention and then show what changed.

    That distinction matters because AI search programs often become reporting programs. Teams collect mentions, citations, prompts, and competitor comparisons, but the findings never become owned work with measurable consequences. The strongest interpretation of this recognition is that the market is beginning to demand a complete operating loop rather than another dashboard.

    What the Gartner mention does and does not prove

    Profound reports that it was named in Gartner’s 2026 Coolest Vendor Innovations in CRM alongside Canva, Decagon, dx0, and Twenty. That makes the company relevant to a serious evaluation of emerging AI marketing infrastructure.

    It does not, by itself, establish that Profound is the best platform for your organization. A recognition is not a product benchmark, an implementation plan, or proof of business impact in your environment. It doesn’t answer questions about data coverage, workflow fit, measurement quality, integrations, governance, or the effort required to turn a recommendation into a deployed change.

    The claim also comes from Profound’s own account of the recognition. That doesn’t make it unimportant, but it does set the correct evidence standard: use the mention to justify deeper due diligence, then make the product earn its place through your own workflow and data.

    Don’t turn the recognition into an improvised ranking. The named companies address different parts of customer and marketing work, so their appearance together doesn’t mean they are interchangeable competitors. For your decision, the relevant comparison is between Profound and the other ways you could operate your AI visibility program, including internal analysis, specialist tools, agencies, and connected systems.

    Why the insight-to-outcome loop matters in AI visibility

    An isometric circular workflow carries search inputs through analysis, assigned work, production, and measured feedback while team members collaborate at each stage.

    Profound interprets the recognition as evidence that marketers increasingly expect a closed loop from insight to action to measured outcome. That is a vendor-held interpretation, but it gives buyers a much better evaluation standard than feature counting.

    AI visibility work starts with an observation: perhaps a brand is missing from an important answer, a competitor is cited more often, or a product is described inaccurately. None of those observations creates value on its own. Value appears only when the team can diagnose a plausible cause, assign a suitable intervention, publish or distribute the change, and measure the result against a defined baseline.

    StageQuestion your workflow must answerEvidence to request
    InsightWhat exactly is happening, for which queries, audiences, markets, and AI experiences?Saved answer-level observations, timestamps, query definitions, cited domains, and a clear distinction between collected data and inferred explanations.
    ActionWhat should change, where should it change, and who owns the work?A recommendation tied to the original observation, a destination such as a page or entity record, an owner, status, and change history.
    OutcomeDid visibility, representation, referral activity, or a downstream business measure improve after the intervention?A preserved baseline, comparable follow-up observations, deployment dates, and an outcome definition agreed before the work began.

    This framework also prevents a common category error. A suggested content revision, outreach task, or JSON-LD update is an action, not an outcome. Schema markup can make eligible facts easier for machines to interpret when it accurately represents visible content, but merely deploying markup doesn’t prove that an AI system used it or that customer behavior changed.

    The CRM context is useful here. Customer and revenue consequences usually live downstream from visibility data. A credible closed loop therefore needs either native connections or documented handoffs between AI answer monitoring, content operations, technical implementation, analytics, and customer systems. It doesn’t all have to happen inside one platform, but the path between systems must be traceable.

    Run this six-part evaluation before you choose a platform

    A cross-functional team tests six connected evaluation stations in a modern workshop while an out-of-focus trophy sits to the side.

    A polished demonstration can hide the hardest operational gaps. Use one real topic from your business and ask the vendor to follow it from observation through measurement. The following test works whether you are assessing Profound or another AI visibility system.

    1. Define your evaluation set before the demonstration. Include branded questions, category questions, comparison questions, and problem-led questions that matter to actual buyers. Specify the markets, languages, products, and AI experiences in scope. This prevents a vendor from selecting only the examples that make its interface look strong.
    2. Inspect the underlying observation. Ask to see the answer captured, when it was captured, the query used, and any citations or brand mentions detected. You need to know which elements are direct observations and which are scores, classifications, or interpretations produced by the platform.
    3. Challenge the diagnosis. Ask why the system believes a particular content, technical, entity, or authority gap caused the observed result. A useful platform should let your team examine the evidence behind a recommendation. Treat unexplained scores and confident causal claims cautiously.
    4. Follow the recommendation into an owned task. Identify who receives it, where the work happens, what approval is required, and how completion is recorded. If staff must copy findings manually into another system, count that labor and the risk of lost context when you compare options.
    5. Agree on the outcome before making the change. Decide whether success means more relevant mentions, more accurate representation, stronger citation presence, qualified referral activity, or a business result recorded downstream. Don’t substitute a platform’s convenient metric for the decision your organization actually cares about.
    6. Repeat the measurement with a change log. Preserve the initial query set and observation dates, record exactly what was deployed, and compare like with like. AI-generated answers can vary, so a single favorable response is weak evidence. Look for a pattern that is meaningful enough to justify the next round of work.

    This evaluation does not require the vendor to promise perfect attribution. In fact, causal humility is a positive sign. Content changes, model behavior, competitor activity, retrieval choices, and outside coverage can all affect an answer. What you need is a system that preserves enough evidence to distinguish a plausible result from a convenient story.

    Watch for the gaps that turn a closed loop into a slogan

    The phrase “closed loop” sounds complete, but several missing links can make it operationally empty. Look for these gaps during procurement and pilot design:

    • Undefined coverage: The platform reports a visibility score without showing which prompts, markets, models, or observation periods produced it.
    • Diagnosis without evidence: It recommends creating or changing content but cannot connect the recommendation to a captured answer, citation pattern, or identifiable information gap.
    • Action without ownership: Findings remain in the dashboard because no person, destination, approval state, or deadline is attached to them.
    • Publishing without verification: A page or schema change is marked complete, but nobody checks whether the intended fact is visible, accurate, indexable, and consistent across relevant brand properties.
    • Measurement without comparability: The follow-up uses different questions, filters, markets, or definitions, making apparent improvement difficult to interpret.
    • Visibility without business context: The team celebrates more mentions without asking whether the brand is represented accurately, appears in relevant buying situations, or influences a meaningful downstream behavior.

    You should also separate platform capability from implementation maturity. A product may support the required workflow while your organization lacks owners, publishing access, analytics connections, or an agreed measurement model. Buying more software will not repair those operating gaps. Document them before procurement so that platform limitations and internal limitations don’t get confused.

    Key takeaways

    • Profound’s Gartner 2026 recognition is a credible reason to include the company in an evaluation, not proof that it fits your stack or will improve your results.
    • The most useful signal is the emphasis on connecting insight, action, and outcome. Test that complete path rather than comparing dashboard features in isolation.
    • Use a real business topic during the demonstration and require answer-level evidence, an owned action, a deployment record, and a comparable follow-up measurement.
    • Define success before the pilot. Mentions, citations, representation accuracy, referral activity, and business outcomes answer different questions.
    • A closed loop can span several systems. What matters is preserved context, clear ownership, and a traceable line from observation to consequence.

    Make the next step a workflow test, not a prestige vote

    Choose one commercially important topic cluster and map its complete path: the questions people ask, the answers you can observe, the evidence behind any diagnosis, the person who can make a change, and the outcome you will examine afterward. Then ask Profound to demonstrate that path using your definitions rather than a prepared success case.

    If the workflow remains traceable from observation to consequence, the recognition has helped you discover a platform worth piloting. If the trail disappears between dashboard insight and business action, the Gartner mention should not carry the decision. Your next move is to test the loop.

    References


  • Google AI Shopping: Prepare for Search-to-Checkout

    Google AI Shopping: Prepare for Search-to-Checkout

    If you run a Shopify store, a customer may soon discover your product and buy it without visiting your website. Eligible products can now move from recommendation to direct checkout inside Google AI Mode and the Gemini app.

    That changes more than the checkout button. You need to decide where the transaction should happen, make your product data reliable enough for an AI-assisted purchase, and measure sales that browser analytics may not fully capture. The right response is an operational audit, not an indiscriminate AI content campaign.

    Key takeaways

    • Eligible U.S. Shopify stores may have Google-native checkout activated automatically, so inspect Sales channels > Agentic before assuming you opted in or out.
    • Merchant Center data is becoming part of the transaction interface, not merely a way to qualify for product exposure.
    • Native checkout can shorten the buying path, but certain checkout blocks, bundles, custom pixels, and client-side Google Analytics tracking are not supported.
    • Measure answer presence, visible citations, product visibility, and completed transactions separately. They are related outcomes, not interchangeable versions of one ranking metric.

    Search visibility now has separate discovery and commerce layers

    AI-generated search results are no longer a fringe surface. Google AI Overviews appeared in 39.4% of U.S. desktop searches in June 2026, up from 25.8% in July 2025. That measurement describes how often the feature appeared. It does not measure clicks, visits, or sales.

    Search demand has not simply vanished into AI interfaces. U.S. desktop search volume reached 77 billion searches in the second quarter of 2026, 8% above the 71 billion recorded in the second quarter of 2024. The practical change is in what can happen between the query and your website. Google can answer the question, cite a page, present a product, and, for some shoppers and merchants, complete the transaction before a site session begins.

    Do not use the AI Overview figure as a proxy for native-checkout adoption. AI Overviews, AI Mode, and Gemini are distinct experiences, and the available checkout rollout is limited to eligible merchants and shoppers. Combining them into one AI traffic number will hide which part of the journey is actually changing.

    Track four outcomes instead of one AI visibility score

    1. Answer presence: Does the AI response discuss your brand, product, category, or information?
    2. Visible attribution: Does it name or link to your domain, product page, video, marketplace listing, or another asset you control?
    3. Product availability: Does the relevant product surface with accurate information for the shopper?
    4. Transaction availability: Can the shopper buy inside the AI experience, or are they transferred to your store?

    The first two outcomes need to remain separate. A system can use a domain while giving another domain the visible link. In lodging-related AI responses measured from December 2025 through May 2026, Tripadvisor had 61% source presence but only 21% visible citation presence. Hotels.com moved from 50% source presence to 18% citation presence, while Booking.com moved from 33% to 9%. Those numbers come from lodging, not retail, but the measurement lesson applies directly: being used, being named, and receiving a click opportunity are different results.

    Build your monitoring sheet around those distinctions. For every important query, record the date, device type, Google surface, whether your brand appeared, whether a link appeared, which URL received the link, whether a product was shown, and whether checkout was available. Use the same query set on a fixed cadence. AI responses can vary, so one screenshot should be treated as an observation rather than a permanent ranking.

    Keep traditional ranking and organic traffic beside this view, not inside it. A page can rank conventionally without appearing in an AI answer. It can inform an answer without receiving a citation. A product can also generate an order without producing the client-side visit your existing dashboard expects.

    Decide whether native checkout fits your store before leaving it enabled

    The first task is to establish your actual state. Shopify stores may be eligible when they are based in the United States, sell to U.S. customers, have a valid Merchant Center account, and make eligible products available through Merchant Center, among other requirements. Products can be synchronized through Shopify’s Google & YouTube channel or supplied through another feed method.

    For a matched store and Merchant Center account, eligible products may be included automatically. Shopify also activates purchasing by default for eligible stores. The rollout remains selective, however, so an eligible merchant should not assume that every shopper can see the same experience.

    1. Open Shopify and inspect Sales channels > Agentic.
    2. Record whether direct checkout is enabled before changing anything. Add the date to your analytics annotations or internal change log.
    3. Confirm which Merchant Center account is matched to the store and how products reach that account.
    4. Identify the products that are intended to be available through Merchant Center. Check whether their price, availability, variants, images, and descriptions match the live store.
    5. List every onsite feature involved in conversion or measurement, especially bundles, checkout blocks, custom pixels, and client-side Google Analytics tracking.
    6. Choose deliberately between native checkout and website checkout. If you disable direct checkout, products can still be discovered in AI Mode and Gemini, but shoppers will be sent to your site to purchase.

    The choice is not simply more distribution versus less distribution. It is a tradeoff between reducing steps and preserving the parts of your onsite experience that help the customer choose, configure, or understand the product.

    Decision questionLean toward native checkoutLean toward website checkout
    Can the customer understand and select the product from the information available in the AI experience?The product and its variants are straightforward.The purchase needs detailed education, configuration, or onsite assistance.
    Does the current offer depend on unsupported checkout behavior?Standard product and checkout behavior is sufficient.Bundles or specific checkout blocks are central to the offer.
    Can you evaluate performance from order and platform records?Order-level reconciliation gives you enough evidence to make a decision.Essential attribution or optimization depends on unsupported custom pixels or browser events.
    What is the primary experience goal?Removing steps between product discovery and purchase matters most.Preserving a controlled, branded onsite journey matters most.

    Native checkout does not remove the merchant from the commercial relationship. Merchants retain the underlying customer and order relationship. But that does not mean the Google-hosted experience reproduces the store’s checkout. Certain checkout blocks, product bundles, custom pixels, and client-side Google Analytics tracking are not supported.

    If one of those features affects pricing, fulfillment, compliance, or the customer’s understanding of the order, resolve that dependency before leaving native checkout enabled. If it only affects reporting, determine whether order-level reconciliation can replace the missing browser signal. Do not reject a sales channel solely because it produces fewer sessions, and do not keep it solely because it produces more orders without checking cancellations, refunds, and operational quality.

    Treat Merchant Center data as transaction infrastructure

    Structured product-data tiles for inventory, pricing, shipping, returns, and payment connect an AI interface to checkout and fulfillment.

    Merchant Center used to be easy to treat as a distribution feed sitting beside the store. That mental model is now incomplete. Eligible products supplied through Merchant Center can support discovery and direct purchase, which means a catalog error can travel farther down the buying journey before anyone notices it.

    The transaction layer is powered by the Universal Commerce Protocol, or UCP. It is an open standard developed by Google with companies including Shopify so AI agents can interact with merchants and payment systems across the shopping journey. UCP is the connection layer; it does not make incomplete, stale, or ambiguous product information reliable.

    Audit the product facts an agent must act on

    • Identity: Make titles, brand information, item identifiers, and variant identifiers stable enough to distinguish one product from another.
    • Choice: Represent differences such as size, color, quantity, and compatibility clearly. Do not bury a purchase-critical distinction in promotional copy.
    • Offer: Keep price, availability, and condition aligned with what the customer can actually buy.
    • Media: Make sure the primary image represents the selected product or variant rather than a broader collection.
    • Description: Put the facts needed to make a decision near the start. A product description should identify what the item is, who or what it is for, and the distinctions that change the choice.
    • Consistency: Align Merchant Center data, the rendered product page, and any Product structured data on the site. JSON-LD can clarify the page, but it is not a substitute for the Merchant Center feed used in this checkout rollout.

    Work from the sale backward. Ask what would cause the wrong variant, stale availability, misleading image, or incorrect price to appear at the point of purchase. Those are higher-priority defects than minor differences in promotional wording because they affect whether the transaction can be completed accurately.

    Do not add more feed detail than your team can maintain. A complete field that becomes stale is not better than a concise field tied to a reliable system of record. Assign ownership for each changing fact and document whether Shopify, another catalog system, or a feed tool controls it.

    Replace browser-only attribution with commerce reconciliation

    Client-side analytics cannot be your only conversion record when checkout may occur outside your pages. A lower session count can coexist with valid orders, while a missing browser event can look like a failed conversion even when payment completed.

    Create a compact operating view with five layers:

    1. Configuration: The Agentic setting, Merchant Center account, feed method, and dates when any of them changed.
    2. Catalog: The products intended for AI discovery, their current feed status, and material errors or exclusions.
    3. Visibility: Observations from your fixed query set, separated into answer presence, citation presence, product appearance, and checkout availability.
    4. Transactions: Orders and sales attributed to the experience when Shopify or another available record identifies them. Keep onsite orders separate.
    5. Order quality: Cancellations, refunds, fulfillment problems, and product-selection errors. These show whether a shorter checkout path is producing usable revenue.

    Annotate promotions, stockouts, price changes, feed repairs, and setting changes. A simple before-and-after comparison cannot prove that native checkout caused a sales change when inventory, demand, and rollout availability also moved. Treat it as directional evidence unless you have a controlled comparison with stable conditions.

    If direct checkout is enabled but the available records cannot distinguish its orders, document that limitation instead of filling the gap with estimated attribution. The immediate objective is to make the unknown visible. That prevents a dashboard built around website sessions from silently declaring offsite transactions nonexistent.

    Build citation opportunities around how people research products

    Shoppers compare unbranded products using visual evidence cards connected to an abstract AI search assistant.

    Your product feed supports commerce eligibility, but it is not the whole discovery strategy. In June retail searches, YouTube appeared in 23% of searches among the top listed AI Overview citations. Amazon appeared in 14%, Reddit in 12%, and Wikipedia in 11%.

    Those percentages are not traffic share, sales share, or proof that publishing on a particular platform causes an AI citation. They show that retail answers draw visible support from several kinds of destinations: video, marketplaces, communities, reference material, and merchant sites. Your visibility plan should therefore cover the questions people ask before they are ready to transact.

    1. Map real buying questions. Include category questions, comparisons, compatibility concerns, variant selection, use cases, and the policy questions that can stop a purchase.
    2. Assign one dependable destination to each answer. Use a product page for product facts, a comparison or support page for decision criteria, and a video when the customer needs to see setup, scale, movement, or results.
    3. Keep claims consistent across surfaces. Conflicting specifications, product names, availability, or positioning create ambiguity for shoppers and machines. Correct the canonical store information first, then update other profiles and listings you control.
    4. Use YouTube when demonstration adds evidence. Give the video a descriptive title and make the spoken and written explanation specific enough to stand on its own. Do not create video merely because YouTube appears frequently in citations.
    5. Treat Reddit as a listening environment, not a placement inventory. Use recurring community questions to improve your pages and documentation. Do not manufacture endorsements or disguise promotional participation as customer experience.
    6. Review marketplace information where it already matters to your business. If your products are legitimately sold on Amazon, make names, variants, and core facts consistent. The citation data alone is not a reason to open a marketplace channel.

    When reviewing a query, ask whether the AI answer contains the right fact, whether your brand is represented accurately, and whether the visible citation leads to the best page. A citation to an obsolete support page is not automatically a win. Neither is an uncited brand mention that describes the wrong product.

    Your first move should be small and observable. Check Sales channels > Agentic, capture the current state, confirm the matched Merchant Center account, and list the checkout or analytics features that would not carry into native checkout. Then choose whether to keep direct purchasing enabled and begin a recurring product-data and query review. That sequence gives you a controlled decision now while preserving room to adapt as Google expands the experience.

    References


  • Practical SEO Measurement: How to Prioritize What Works

    Practical SEO Measurement: How to Prioritize What Works

    You can have rankings, clicks, conversions, and a polished dashboard yet still be unable to answer the question that matters: should you put another sprint, another content batch, or another dollar into this SEO initiative?

    The practical goal isn’t to prove that SEO caused every conversion. It is to build enough reliable evidence to decide what to continue, what to expand, what to repair, and what to stop. That requires a measurement contract for every meaningful initiative, explicit thresholds, and an honest separation between what you observed and what you inferred.

    Measure for the decision, not the dashboard

    An architectural model shows a central evidence platform leading to four distinct routes, with a pointer aimed toward one path.

    Start by naming the decision your measurement must support. Are you deciding whether to launch, wait, expand, revise, or stop? A metric can be useful without answering all five questions.

    Separate the evidence into four levels:

    • Delivery evidence: Did the planned pages, templates, links, or technical changes actually ship? Until they do, you are measuring execution failure or delay, not SEO impact.
    • Leading indicators: Did search engines discover and index the affected pages? Are nonbrand impressions, rankings, or other early visibility signals moving in the expected direction?
    • Observed business outcomes: Did the affected traffic produce qualified leads, revenue, subscriptions, lower acquisition costs, affiliate earnings, or another unit of value that the business recognizes?
    • Attributed influence: How much of that outcome can reasonably be connected to the initiative? This is usually the least certain layer because SEO changes overlap with seasonality, algorithm changes, product releases, competitor activity, and work elsewhere on the site.

    Do not promote evidence from one level into another. Indexation shows that pages entered the search system; it does not show that the pages created profitable demand. More impressions indicate visibility; they do not prove incremental revenue. An organic conversion is observable, but its recorded channel does not reveal every earlier interaction that influenced the buyer.

    This distinction also keeps disagreements about tools from derailing the decision. Search Console and web analytics observe different events, while Search Console totals may not reconcile when segmented. Assign one system of record to each metric, document the definition, and judge movement within that system. Do not force unlike datasets to produce an artificial match.

    For every metric on your scorecard, complete this sentence: “If this crosses the agreed threshold by the review date, we will make this decision.” If you cannot finish the sentence, the metric may be informative, but it is not yet operational.

    Write a measurement contract before the work starts

    A project board is arranged with a target, balance scale, hourglass, boundary blocks, and separate trays of evidence stones.

    A forecast describes what you hope will happen. A measurement contract states how the team will decide what to do after reality arrives. Write it while everyone is still neutral, before delayed results and sunk costs make the thresholds negotiable.

    The contract should contain:

    <!– wp:list {