Tag: AI Transparency

  • Human Factors That Make Agentic AI Deployments Work

    Human Factors That Make Agentic AI Deployments Work

    Your agent can draft pages, change metadata, select audiences, trigger campaigns, and coordinate customer journeys. The hard question isn’t whether it can perform those actions. It’s whether it should be allowed to perform each one without stopping for a person.

    If you’re deciding how much autonomy to grant, treat the deployment as an operating-model decision rather than a software installation. Define who owns the outcome, which actions require approval, how people will detect a bad decision, and how they can stop or reverse it. Those human controls determine whether the agent produces useful leverage or merely executes mistakes faster.

    Start with a decision, not an AI agent

    Agentic AI projects often begin with a capability demonstration: the system can plan a campaign, create content, update a workflow, or act across several tools. A convincing demonstration doesn’t establish that the workflow is worth automating or safe to delegate.

    The warning is concrete. Gartner expects more than 40% of agentic AI projects to be canceled by the end of 2027. The projection, based on more than 3,400 organizations investing in the technology, points to unclear value, weak governance, and hype-led experimentation rather than a simple lack of technical capability. Treat that percentage as a forecast, not a settled outcome, but don’t miss the operational problem behind it.

    Before you select a product or build an agent, write a decision brief for one workflow. It should answer these questions:

    • What outcome changes? Name the business result, not the AI activity. “Reduce the time required to prepare a technically reviewed content brief” is an outcome. “Use an agent for briefs” is not.
    • What does the workflow look like now? Record its inputs, decisions, handoffs, failure points, review work, and final action. Otherwise, you won’t know whether the agent improved the process or merely moved effort into supervision and repair.
    • Which judgment is scarce? Separate repetitive coordination from decisions that depend on audience knowledge, brand context, ethics, or commercial priorities. Automating the former may create capacity. Hiding the latter inside a prompt creates unmanaged risk.
    • What evidence would justify continuation? Choose outcome, quality, intervention, and recovery measures before launch. A pilot without an exit rule tends to survive because it exists, not because it works.
    • Who can stop it? Assign a named operational owner with authority to pause actions, narrow scope, and require remediation.

    This brief also protects you from “agent washing.” A conventional chatbot or fixed automation shouldn’t be purchased as an autonomous agent simply because the label changed. Ask the vendor or internal team to demonstrate the operating loop: what the system observes, which choices it makes, what it can change, how it checks the result, when it stops, and when it escalates. If every meaningful path was predetermined, you may still have useful automation, but you don’t have the adaptive autonomy the name implies.

    For an SEO or GEO workflow, make the distinction visible. An agent that recommends schema corrections is materially different from one that edits production markup. An agent that identifies possible internal links is different from one that publishes them. An agent that proposes a redirect is different from one that changes routing. Evaluate the authority being granted, not just the sophistication of the output.

    Design human control before you grant autonomy
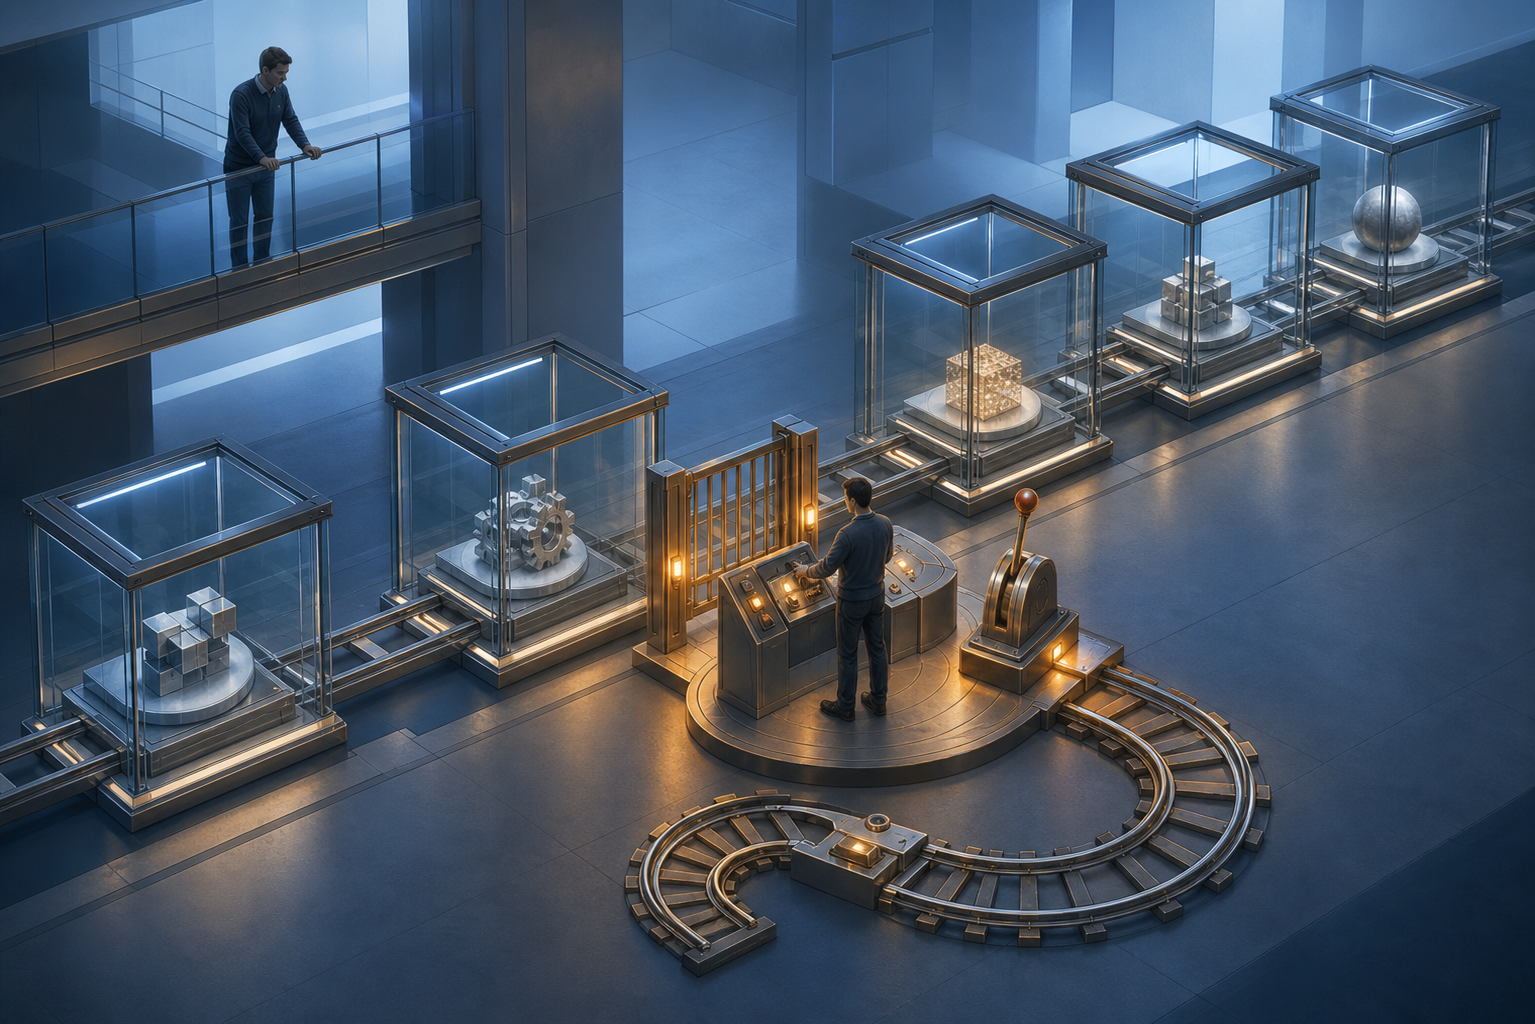
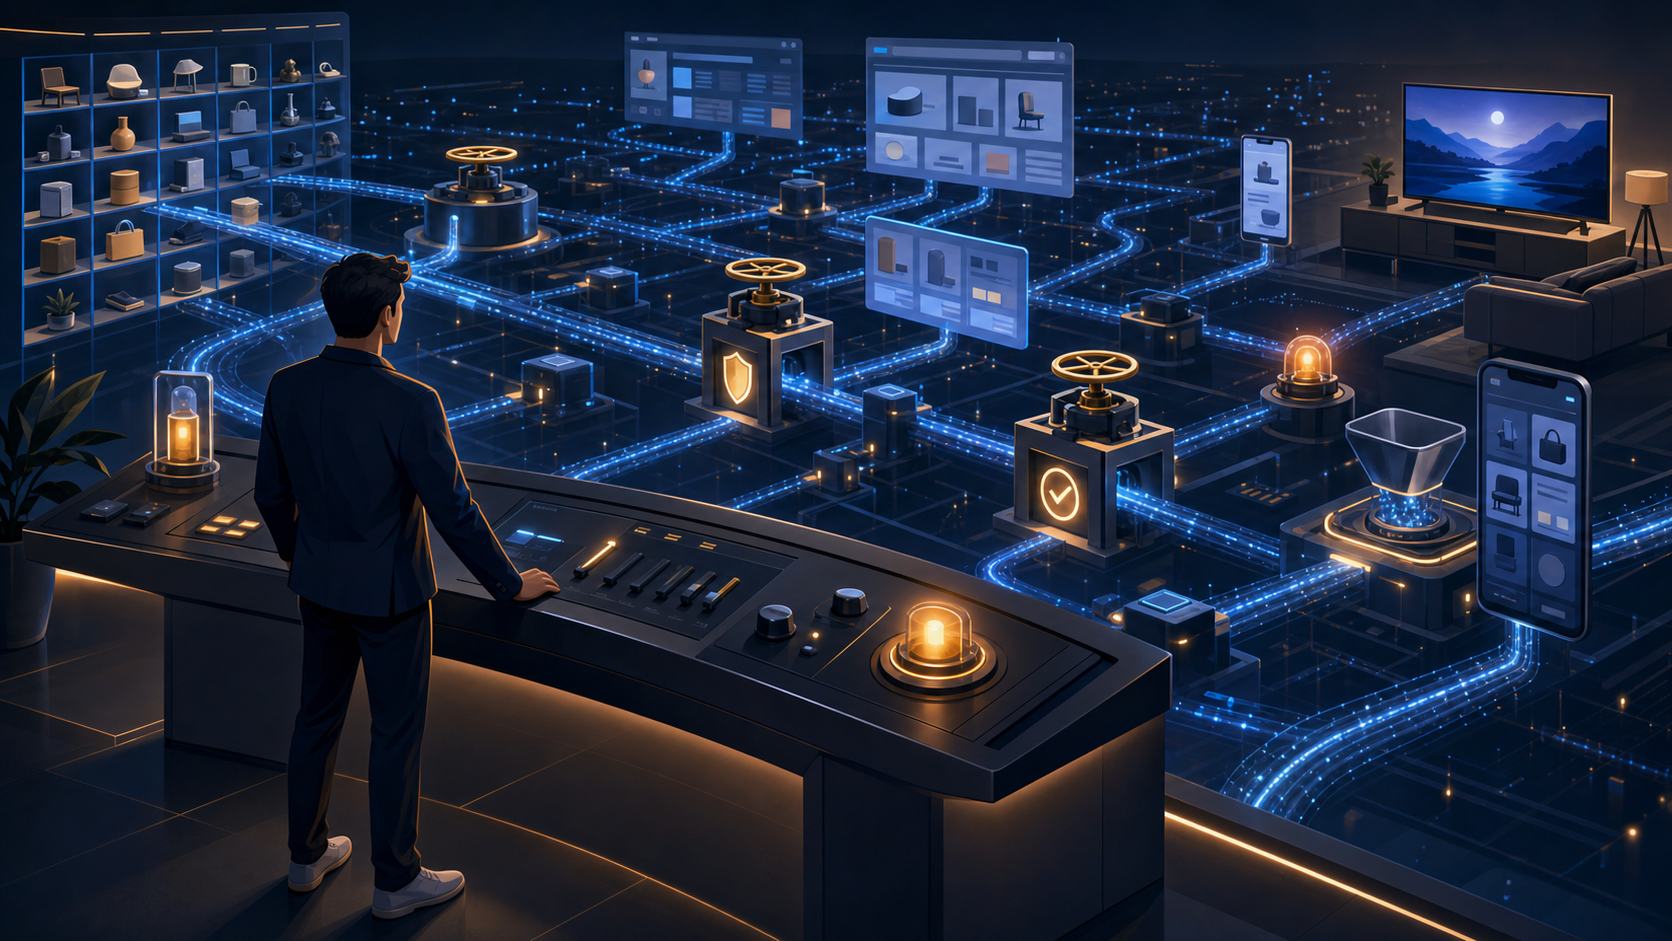
    Two operators oversee a modular automated workflow equipped with an approval gate, a pause lever, and a track that can reverse direction.

    “Human in the loop” is too vague to serve as a control. A person can technically appear in a workflow while lacking the context, time, authority, or evidence needed to catch a problem. Effective oversight specifies the decision rights on both sides of the human-agent boundary.

    Classify every action the agent may take using four practical questions:

    • Can it be reversed? Saving a draft is easy to undo. Sending a customer message, changing access, publishing an unsupported claim, or allowing a damaging URL change to propagate may not be.
    • How wide is the impact? A suggestion affecting one draft has a smaller blast radius than a template change affecting thousands of pages or an audience rule applied across campaigns.
    • How much context does the decision require? Stable rules are easier to delegate than choices involving brand nuance, conflicting evidence, unusual customer circumstances, or several acceptable outcomes.
    • Will failure be visible quickly? A malformed output may be obvious. A plausible but strategically wrong recommendation can remain unnoticed while it influences content, spend, or customer treatment.

    Use the answers to assign authority. Reversible, narrow, observable actions with clear rules are reasonable candidates for bounded autonomy. Irreversible, broad, ambiguous, or slow-to-detect actions should require approval or remain human-owned. Don’t use one autonomy setting for the entire workflow.

    ControlQuestion it must answerEvidence to retain
    Named ownerWho is accountable for the business outcome and failure response?Owner, backup, authority, and escalation route
    Scope boundaryWhich systems, records, audiences, and actions may the agent touch?Allowlist, denied actions, and permission configuration
    Approval gateWhich conditions force a person to decide?Trigger, reviewer, required context, and decision record
    Stop controlHow can a person halt new actions without waiting for the agent?Pause procedure, access owner, and confirmation that execution stopped
    Recovery pathHow will the team contain and reverse a bad action?Rollback method, affected-system inventory, and notification route
    Audit trailCan reviewers reconstruct what the agent knew, chose, and changed?Inputs, retrieved context, proposed action, approval, execution result, and exceptions

    The audit trail needs to capture more than generated text. Store the context used for the decision, the action requested, the tools called, the result returned, any human intervention, and the final system state. A polished explanation generated after the event isn’t a substitute for an execution record.

    Approval interfaces deserve the same care. Don’t ask a reviewer to click “approve” after showing only the agent’s preferred answer. Show the original input, relevant constraints, proposed change, affected assets, uncertainty or missing information, and available alternatives. Make rejection and escalation as easy as approval. Otherwise, the interface quietly trains people to accept.

    For content and search operations, require explicit review before actions such as publishing factual claims, changing canonical directives, modifying crawl controls, issuing broad redirects, altering product or business data, sending outreach, or communicating with customers. Your exact gates should reflect your systems and risk, but the rule is stable: the person must intervene before the consequential action, not after the impact appears in analytics.

    Increase autonomy only after the workflow becomes observable
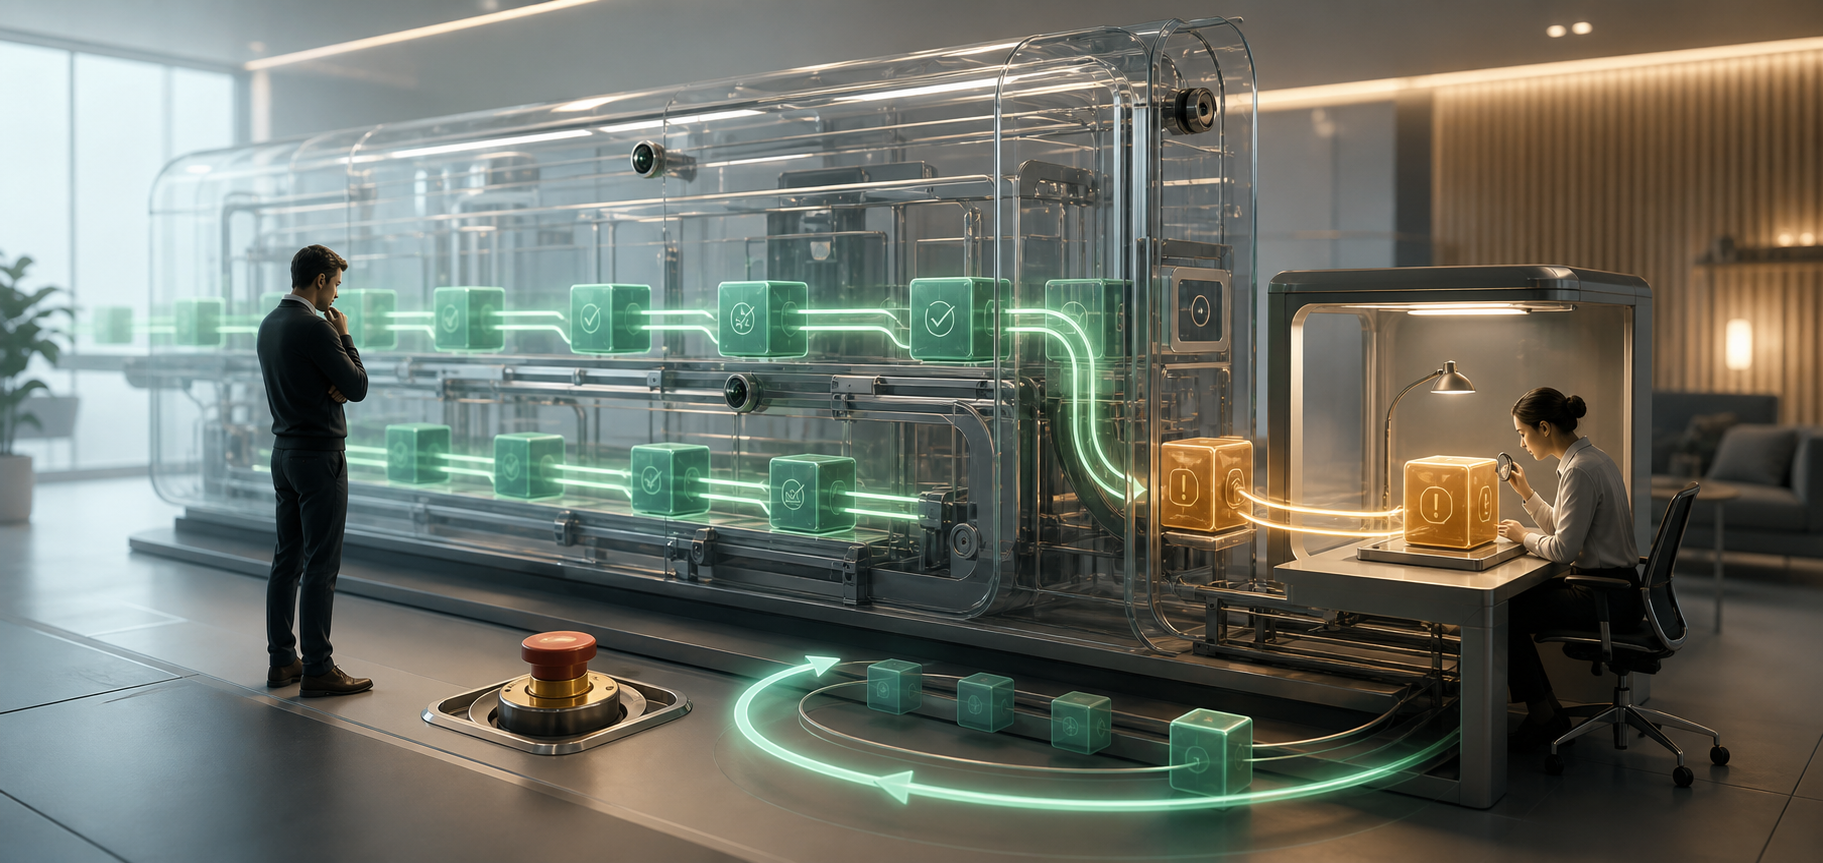
    Analysts monitor tasks moving through a transparent automated system while an unusual task is diverted into a separate human review bay.

    A pilot should test the complete operating system around the agent. Testing only whether the model can produce a good answer leaves permissions, handoffs, monitoring, escalation, and recovery unexamined.

    Move through these modes in order:

    1. Shadow mode: Let the agent observe real inputs and record what it would do, but prevent external actions. Compare its proposed decisions with actual outcomes and inspect where its context is incomplete.
    2. Advisory mode: Let it recommend actions to a responsible operator. Record approvals, edits, rejections, escalation reasons, and the time required to review. Heavy correction is evidence that the workflow or context is not ready for autonomy.
    3. Bounded action mode: Allow a defined set of reversible actions within an allowlisted scope. Keep consequential actions behind approval gates and enforce a direct stop mechanism.
    4. Expanded autonomy: Broaden authority only when the existing scope produces acceptable outcomes, exceptions are understood, logs support investigation, and the team can demonstrate recovery.

    Promotion between modes should be an evidence decision. Don’t advance because the pilot deadline arrived or because a successful demonstration created executive enthusiasm. Review routine cases, edge cases, ambiguous requests, missing-data situations, conflicting instructions, permission failures, and attempts to push the agent beyond its assigned scope.

    Measure the deployment across four layers:

    • Outcome: Did the workflow improve the business result named in the decision brief?
    • Quality: Were outputs accurate, complete, on-brand, appropriately sourced, and suitable for the intended audience?
    • Control: How often did people edit, reject, stop, or escalate an action, and why?
    • Recovery: Could the team identify affected assets, contain the problem, restore the correct state, and learn from the failure?

    Don’t optimize the intervention rate toward zero. A falling rate can mean the system improved, but it can also mean reviewers stopped looking carefully. Read intervention data alongside sampled quality checks, downstream outcomes, and exception reports. The useful question is whether human attention is landing on the decisions where it changes the outcome.

    FOMO creates pressure to skip this progression and move directly from demo to production. That pressure is especially dangerous when an agent can act at campaign or site scale. Speed comes from making the safe path repeatable: clear permissions, reusable evaluation cases, reliable logs, tested rollback, and known escalation owners.

    Protect human judgment and customer trust as operating assets

    An agent’s output can look coherent even when its recommendation is unsuitable. That makes reviewer competence part of the control environment. If the person approving an action can’t recognize a strategic, factual, or ethical error, the approval step is ceremonial.

    One projection expects half of organizations to reassess their competencies as reliance on AI threatens critical thinking. You don’t need to reject automation to respond. You need to keep the relevant judgment active.

    • Require a reason for consequential approvals. The reviewer should identify why the action fits the goal and constraints, not merely confirm that the output reads well.
    • Keep people capable of performing the underlying task. Rotate qualified operators through manual cases and exception handling so the team retains a working model of what good looks like.
    • Separate creation from high-impact approval. The person who configured or champions the agent shouldn’t be the only person judging its production readiness.
    • Review disagreements, not just errors. Repeated edits and rejected recommendations reveal missing context, unclear policy, or a task that requires more human judgment than expected.
    • Run post-incident reviews around the system. Examine instructions, data, permissions, interface design, workload, escalation, and incentives. Telling reviewers to “be more careful” leaves the mechanism intact.

    Customer trust needs its own controls. A related forecast warns that poorly applied agentic AI could damage customer relationships by 2026. The risk isn’t limited to obviously nonsensical responses. An agent can send a polished message to the wrong person, apply a reasonable rule at the wrong moment, or take an authorized action that conflicts with the customer’s circumstances.

    Map each customer-facing action to an identity, authority, and escalation rule. The customer should be able to tell what happened, correct wrong information, reach a person when the automated path is unsuitable, and receive a clear resolution when an action causes harm. Internally, the team should be able to identify which agent acted, under whose authority, using what information.

    Brand alignment can’t live only in a long prompt. Translate it into reviewable policies: prohibited claims, evidence requirements, tone boundaries, audience exclusions, escalation topics, and actions the agent may never take. Give each policy an owner and a process for change. That turns “use good judgment” into controls a team can inspect.

    Key takeaways

    • Begin with one defined business decision and its current workflow, not a general mandate to deploy an agent.
    • Evaluate actual autonomy by inspecting what the system observes, decides, changes, verifies, and escalates.
    • Grant authority action by action. Reversibility, impact, ambiguity, and observability should determine where people intervene.
    • Test in shadow, advisory, bounded-action, and expanded-autonomy modes, with evidence required before each increase in authority.
    • Retain execution logs, explicit stop controls, and tested recovery paths before the agent touches consequential systems.
    • Treat reviewer competence and customer escalation as core infrastructure, not training tasks to add after launch.

    Before your next agent demo, produce a one-page deployment contract for the workflow: outcome, owner, allowed actions, prohibited actions, approval triggers, stop mechanism, recovery path, and evidence required for more autonomy. If the team can’t agree on that page, the agent isn’t ready for broader access. Resolving those human decisions first is the shortest route to a deployment you can trust.
    References

  • How to Earn Accurate AI Citations and Protect Brand Trust

    How to Earn Accurate AI Citations and Protect Brand Trust

    An AI answer can cite your website and still get your product wrong. It can also describe your brand accurately while sending the reader somewhere else. If your reporting treats both outcomes as a visibility problem, you won’t know what to fix.

    You need to evaluate three things separately: whether your brand was selected, whether the cited evidence supports the generated claim, and whether a person would trust the answer enough to act. This framework helps you diagnose each layer without mistaking citation volume for accuracy or brand authority.

    Key takeaways

    • A citation proves that a page was selected as a reference. It does not prove that the generated sentence is accurate, complete, current, or supported by that page.
    • Audit the relationship between each claim and its citation. Counting links or brand mentions alone hides the errors most likely to damage trust.
    • Segment testing by platform, query language, market, intent, and phrasing. A blended visibility score can conceal serious gaps in a priority language or buying journey.
    • Maintain a canonical claim layer with explicit evidence, scope, market, and update information. Align your visible content and JSON-LD with that same version of the truth.
    • Earn independent confirmation by helping people in the communities and channels where decisions are verified. Repetition from your own properties is not the same as corroboration.

    A citation proves selection, not accuracy

    Grounding means connecting a generated answer to external evidence. It can reduce unsupported generation, but it does not turn every cited sentence into a verified fact. Retrieval can surface a relevant page while the model overgeneralizes its wording, misses a qualifier, combines incompatible details, or attaches the citation to a broader claim than the page supports.

    Suppose an answer says a company provides same-day support in every market. Its citation leads to a support page that promises that service only to selected customers in one region. The link is real and topically relevant, but the generated claim is still wrong. A dashboard that records only citation presence would count that outcome as a success.

    That is why an AI visibility audit needs four separate tests:

    LayerQuestion to askCommon false conclusionWhat to inspect
    Citation presenceWas your brand or page selected?Being cited means being represented correctly.The cited URL, its position, the surrounding answer, and competing domains.
    Claim supportDoes the cited passage support the exact generated claim?A relevant page is sufficient evidence.Wording, scope, qualifiers, dates, markets, exceptions, and the cited passage itself.
    Entity accuracyAre the brand, product, policy, location, and relationships correct?A fluent description must be reliable.Names, attributes, availability, ownership, pricing claims, and product-to-brand relationships.
    User trustWould a reasonable reader accept and act on the answer?Exposure automatically creates confidence.Independent corroboration, transparency, review quality, community sentiment, and unresolved contradictions.

    The practical unit of analysis is the claim-citation pair. Break an answer into factual claims, then open the citation attached to each one. Grade the pair as supported, partially supported, unsupported, or contradicted. Use a separate label when no citation is provided.

    Partial support deserves its own category. It often reveals the most important content problem: your page contains the right concept but leaves enough ambiguity for the model to enlarge its scope. A statement that is correct for one plan, country, customer type, or time period needs that qualifier in the same sentence as the claim. Do not leave the limitation in a footnote, accordion, or unrelated section and expect retrieval to preserve it.

    Accuracy and trust also need different owners. A content or product team may be able to correct an outdated policy page. Public relations or community teams may need to address persistent third-party confusion. Technical SEO can improve entity consistency and structured data, but it cannot manufacture independent belief. Your audit should route each failure to the team that can change its underlying cause.

    Query language can change who gets cited

    A glowing inquiry passes through a prism and branches toward three different source documents, with each path representing a different citation outcome.

    You cannot infer global AI visibility from English-language testing. In one large cross-platform analysis, 3.25 billion citations across seven AI models and 14 countries showed query language as the main catalyst changing citation rates. Google AI Overviews and ChatGPT also displayed different response patterns for non-English prompts. That finding should be treated as a strong warning about aggregation, not as a universal rule for every query or brand.

    Language changes more than the words in the prompt. It can change the pool of retrievable pages, the entities a model recognizes, the regional sources available to support an answer, and the way a user expresses intent. A literal translation of an English prompt may therefore test translation quality rather than the search behavior of a person in that market.

    Build your prompt set from real decisions instead of a list of brand keywords. Include the questions people ask when they are discovering a category, comparing options, checking a claim, assessing risk, resolving a problem, and preparing to buy. Then vary the constraints that matter to the decision: location, use case, customer type, compatibility, availability, policy, or another relevant condition.

    Use a segmented test matrix

    For every prompt, record the exact wording and the conditions under which the answer appeared. At minimum, preserve:

    • The user’s underlying intent and the decision the answer is meant to support.
    • The exact prompt, including follow-up questions and any constraints introduced earlier in the conversation.
    • The query language and intended market. Keep them separate because a language can span several markets, and a market can contain several languages.
    • The AI platform or search surface. Do not merge ChatGPT results with Google AI Overviews or another system under a single generic AI ranking.
    • The date of capture and any visible model or product label, so later retests can be compared with the right context.
    • Whether the session was signed in, personalized, location-aware, or part of an existing conversation.
    • The complete answer, every citation URL, and the passage that supports or fails to support each material claim.

    Have a fluent local speaker or market specialist adapt important prompts. Ask how a real customer would phrase the problem, what local terminology they would use, and which proof they would expect. The localized prompt should preserve the intent, not the English syntax.

    Report results by language and platform before calculating any overall figure. If your brand performs well in English but disappears or becomes inaccurate in another priority language, an average can make the program look healthy while the affected market sees a different brand. The segment is the truth; the blended number is only a summary.

    Build a truth layer that models and people can verify

    A central knowledge core sends consistent product and policy information to web pages, documents, an AI system, and a human reviewer.

    The safest way to improve citation accuracy is to make consequential claims easy to retrieve, hard to misread, and consistent across the properties you control. That work begins before schema markup. A perfectly marked-up contradiction is still a contradiction.

    Create a canonical claim ledger

    Maintain a working record of the claims that affect whether someone chooses, trusts, or rejects your brand. Each record should contain the entity, approved wording, supporting URL, evidence, scope, exceptions, applicable language and market, content owner, review date, and current status.

    Prioritize claims about what a product does, who it is for, where it is available, what it costs, what is included, what it integrates with, and what policies govern its use. These are the statements most likely to change a decision. They are also vulnerable to drift when product pages, help documentation, sales copy, partner listings, and old announcements describe different versions of reality.

    Give each consequential claim a clear canonical home. The page should state the fact directly, place its qualifier beside it, explain the evidence, identify the applicable product or market, and make the update status visible. If the answer differs by plan or region, present those differences as structured comparisons rather than scattering them across several pages.

    Review conflicting owned pages before publishing more content. A new explainer cannot establish clarity while an old pricing page, support document, or local site still makes the opposite claim. Correct, redirect, archive, or clearly date obsolete material according to its purpose. If an older page must remain accessible, label its historical status where a person and a retrieval system can encounter it.

    Use JSON-LD as a consistency layer

    JSON-LD can clarify entities, properties, and relationships. It cannot supply evidence that the visible page lacks, resolve disagreement between departments, or make an exaggerated claim trustworthy. Treat structured data as a machine-readable expression of the same facts a reader can verify on the page.

    • Use the schema type that accurately describes the visible entity or content, such as Organization, Person, Product, or Article where appropriate.
    • Keep names, canonical URLs, identifiers, brand relationships, and other entity attributes consistent with the page and your canonical claim ledger.
    • Do not place a material claim only in markup. If it matters enough to encode, it should be supported in the visible content.
    • Match market- and language-specific markup to the corresponding page. Do not attach a global claim to content that supports only one region.
    • Update structured data when the underlying fact changes. A stale JSON-LD property can preserve the contradiction you just removed from the copy.
    • Validate syntax and then inspect meaning. Technically valid markup can still identify the wrong entity or express an unsupported relationship.

    This approach gives you one controlled path from approved fact to human-readable evidence to structured representation. It also makes corrections easier: when an AI answer exposes a problem, you can trace the claim to its owner and every place where it appears.

    Earn confirmation outside your own website

    People rarely make an important decision inside one answer box. The search journey can move through AI tools, marketplaces, reviews, forums, video, friends, and knowledgeable people as the user looks for stronger confirmation. Yext reported that 75% of consumers were using more platforms than a year earlier, while only 10% trusted the first result.

    That behavior reflects three judgments: whether people trust themselves to evaluate the subject, whether they trust the platform presenting the answer, and whether they trust the underlying information source. Your citation work can improve the last layer, but brand trust also depends on what people encounter when they leave the generated answer to verify it.

    Independent confirmation cannot be produced by repeating the same marketing claim across more company profiles. It comes from useful participation in places where people exchange experience: practitioner communities, customer conversations, events, forums, reviews, social channels, and expert-led media. The operating rule is simple: listen for the unresolved question, help with that question, and let the brand mention remain secondary to the answer.

    • Track recurring questions, objections, misconceptions, and vocabulary in the communities relevant to your buyers.
    • Answer with specific, verifiable information. Link to documentation when it genuinely helps rather than treating every interaction as a distribution opportunity.
    • Turn recurring questions into durable resources on your own site, then keep those resources aligned with the conversations that inspired them.
    • Make it easy for customers, partners, practitioners, and journalists to verify factual details without copying promotional language.
    • Correct errors openly and precisely. State which claim is wrong, what the accurate scope is, and where the supporting information lives.
    • Never manufacture reviews, personas, community conversations, or supposed independent consensus. Discovery gained through deception creates the exact trust problem the program is meant to solve.

    The goal is not to control every mention. It is to make the accurate account easier for other people to confirm and repeat in their own words. That creates a healthier evidence environment than a large collection of identical brand-authored claims.

    Audit the failure pattern before choosing the fix

    A useful AI citation audit should reproduce an answer, isolate the error, identify the controllable cause, and verify the correction. Screenshots of favorable mentions are not enough.

    1. Define the decision. Start with prompts tied to meaningful user actions or material brand risk. Record what a correct answer must help the user understand.
    2. Capture the full context. Save the exact prompt sequence, language, market, platform, date, answer, citations, and visible session conditions.
    3. Split the answer into claims. Separate factual statements from recommendations, opinions, and connective language. Mark the claims that could change a purchase, eligibility, support, compliance, or reputation decision.
    4. Check every citation. Open the linked page, locate the supporting passage, and grade the relationship as supported, partially supported, unsupported, contradicted, or uncited.
    5. Check the entity. Verify names, product relationships, attributes, locations, policies, availability, and other details against the canonical claim ledger.
    6. Trace the likely cause. Look for unclear wording, missing qualifiers, stale owned pages, inconsistent markup, weak localized evidence, entity ambiguity, or repeated third-party misinformation.
    7. Fix the highest-consequence origin. Correct the canonical page and contradictory owned properties first. Then update structured data, partner records, listings, and other controllable representations. Seek corrections from external publishers or platforms where an appropriate process exists.
    8. Retest the original conditions. Use the same prompt and context, then test natural variants. A changed answer may indicate improvement, but it does not prove that every platform, language, or user will now receive the same result.

    Measure accuracy and trust separately from reach

    Your reporting should preserve the distinction between being visible and being represented well. Useful measures include:

    • Citation presence: how often your brand, canonical pages, or relevant independent pages appear for eligible prompts.
    • Claim support rate: how often cited passages fully support the claims attached to them. Keep partial support visible instead of counting it as success.
    • Brand claim accuracy: how often material statements about your entity match the approved facts and their qualifications.
    • Uncited material claim rate: how often consequential factual statements appear without a reference a reviewer can inspect.
    • Cross-platform consistency: whether different AI surfaces agree on the material facts, not whether they use identical wording.
    • Language and market gap: the difference in citation presence, support, and accuracy between priority segments.
    • Independent confirmation: whether the answer’s important claims can be verified through credible, non-owned evidence where independent evidence should exist.
    • Correction latency: how long your organization takes to correct the controlled origin of a material error and complete the relevant retest.

    Avoid setting a citation target without a support target. A campaign can increase the number of citations while also increasing the number of confidently misstated claims. That is not improved visibility; it is wider distribution of an accuracy problem.

    Let the pattern determine the intervention

    • High citation presence, low claim support: clarify the canonical content, move qualifiers beside their claims, remove contradictions, and inspect why irrelevant passages are being treated as evidence.
    • Low citation presence, high brand accuracy: improve retrievability, entity clarity, localized coverage, content distribution, and credible external confirmation without rewriting already-clear facts for novelty.
    • High accuracy, low user trust: examine reviews, community sentiment, transparency, proof quality, and what a person encounters after clicking. More owned content may not solve this failure.
    • Strong English results, weak priority-language results: build native-language evidence and entity consistency for that market. Do not rely on literal translation or a global average.
    • Conflicting answers across platforms: preserve the platform split in reporting, inspect each citation pool, and fix shared contradictions before chasing platform-specific tactics.
    • A material uncited error: treat the incorrect claim as the incident, even if the rest of the answer is favorable. Prioritize errors that change cost, availability, eligibility, obligations, safety, or a buyer’s ability to make an informed choice.

    Start with the decision-heavy query where a wrong answer would cost the most trust. Test it in your primary language and the highest-priority additional language, grade every claim-citation pair, and correct the most consequential contradiction you control. Do that before pursuing a larger citation count. The citation is not the finish line; an accurate, verifiable, and trusted answer is.

    References


  • How to Build Trust With Data in AI and SEO Decisions

    How to Build Trust With Data in AI and SEO Decisions

    Your dashboard can be technically correct and still fail the meeting. If nobody can explain who is represented, how the number was produced, or whether automated and fraudulent activity was removed, the chart asks people to take your conclusions on faith.

    Trust comes from making the evidence inspectable. You should be able to move from a recommendation to its claim, from the claim to its metric, from the metric to the underlying records, and from those records back to their origin. Assumptions, exclusions, and uncertainty need to remain visible throughout that chain.

    Trust starts with a claim your data can support

    A precise-looking number is not automatically a trustworthy number. Decimal places, clean schemas, polished charts, and large record counts can make data appear authoritative without proving that it represents the right people, activities, or period.

    This distinction matters when AI enters the workflow. An AI system can process weak data efficiently, but it cannot independently establish that an identity is genuine or an event is meaningful. In practice, AI can amplify fragmented, outdated, or manipulated inputs and return the result with more confidence than the evidence deserves.

    Before you analyze a dataset, make its intended claim explicit. Then test the claim against six questions:

    • Entity: Who or what does each record represent? Determine whether identifiers refer to the same person, account, page, organization, query, or session across the systems involved.
    • Activity: What actually happened? Separate a recorded event from an authentic action with business or user value.
    • Time: When was the record true, collected, and refreshed? A valid historical snapshot should not be treated as a current state.
    • Origin: Which system created the record, and which system merely copied or transformed it? Name the accountable owner.
    • Exclusions: Which records were filtered out, suppressed, deduplicated, or classified as suspicious? Record the rule and its reason.
    • Decision fit: Does the dataset measure the decision in front of you, or only a convenient proxy for it?

    If you cannot answer one of those questions, narrow the claim. For example, do not report that AI visibility improved everywhere when you measured only a defined set of prompts and answer environments. State that limited scope in the claim itself. A smaller claim that can be verified is more useful than a sweeping conclusion that cannot survive inspection.

    Clean structure is still valuable, but it solves a different problem. A record can have the expected fields, valid syntax, and consistent formatting while referring to the wrong identity or a fabricated activity. Structural validity tells you that the data can be processed. It does not prove that the data is accurate.

    Create an evidence card for every decision-bearing claim

    Hands arrange transparent evidence tiles linked to a central token, with one tile lifted to reveal the granular pieces beneath it.

    A dashboard rarely carries enough context on its own. Filters live in one tool, transformations in another, and caveats in somebody’s memory. When the result is challenged, the team has to reconstruct the reasoning after the fact.

    Use a compact evidence card for each claim that could change a budget, campaign, content plan, model, or workflow. Store it beside the analysis rather than in private notes.

    1. Decision: Write the choice this evidence is meant to inform. If no decision changes, question whether the metric belongs in the report.
    2. Claim: State one sentence that the data directly supports. Avoid combining an observation, an explanation, and a recommendation in the same sentence.
    3. Scope: Name the entity, population, channel, property, prompt set, and time window included. Record the denominator where the metric has one.
    4. Definition: Define the metric in operational terms. Specify what creates an event, what qualifies it, and how duplicates are handled.
    5. Lineage: List the originating system, collection method, joins, transformations, filters, and derived fields used to produce the result.
    6. Quality gates: Document the checks applied to identity, authenticity, freshness, completeness, and consistency.
    7. Limitations: Separate known gaps from suspected gaps. Explain how each one could change the conclusion rather than hiding them under a generic disclaimer.
    8. Action and owner: Name the proposed action, the person responsible, the signal that will be monitored, and the condition that would trigger reconsideration.

    The evidence card also protects metric definitions from drifting. If one reporting period counts all detected visits and another excludes suspected automation, the results are not directly comparable. The definition and filter change must travel with the number.

    Keep rejected records and reason codes available for review when your systems permit it. Silently removing questionable data makes a clean result harder to audit. A visible exclusion such as duplicate identity, stale record, suspected automated activity, or missing attribution shows exactly where judgment entered the pipeline.

    Audit AI and SEO inputs before you automate decisions

    AI readiness is often assessed through volume, match rates, or the apparent precision of model output. None of those signals proves that the underlying identities are stable or that the recorded behavior is authentic. Consumers move between devices and profiles, while systems often treat a temporary identity snapshot as permanent. Fraud and low-value activity can then distort both model output and the performance data used to retrain or evaluate it.

    Run an input audit at each layer of an AI SEO or analytics workflow. The purpose is not to certify data as perfect. It is to prevent the claim from becoming broader than the evidence.

    LayerQuestion to verifyMisleading conclusion to prevent
    Observed AI visibilityWhich prompts, answer environments, properties, locations, settings, and collection windows were monitored?A sampled result presented as universal visibility.
    On-site activityAre sessions and events authentic, consistently defined, and separated from suspected automated or fraudulent activity?Machine activity presented as audience demand.
    Identity and attributionCan records be matched to the intended person, account, organization, or journey without treating uncertain matches as confirmed?Inflated reach, duplicated users, or credit assigned to the wrong interaction.
    Business outcomeDoes the conversion represent a reachable, meaningful outcome rather than a form event or low-value identity?Nominal conversions presented as genuine pipeline or customer value.
    Model inputAre the records current, relevant, authentic, and appropriate for the task the model will perform?Confident automation built on an unreliable foundation.

    Treat identity validity and activity authenticity as gates, not decorative quality scores. If either one cannot be established, the affected data may still support exploration, but it should not silently drive targeting, outreach, optimization, or other automated actions.

    Use sensitivity checks when uncertainty is concentrated in a recognizable subset. Compare the conclusion with and without low-confidence identities, suspected automation, stale records, or unmatched events. If removing that subset reverses the recommendation, the recommendation is fragile. Report that dependence before anyone acts on it.

    Watch for feedback loops as well. If fraudulent or low-value behavior improves a reported metric, an optimization system may learn to seek more of it. The apparent performance improvement then reinforces the very contamination that produced it. Suppress or quarantine questionable inputs before they become training signals, targeting criteria, or success labels.

    Separate observation, interpretation, and recommendation

    Three connected workbench stations show raw data pieces, a lens revealing patterns, and several possible paths around a decision marker.

    Many data presentations lose trust because they slide from measurement to causation without marking the transition. A result occurred after a change, so the change is credited with causing it. A visibility metric rose, so business impact is implied. A model found a pattern, so the pattern is treated as a stable rule.

    Use four explicit labels in reports, dashboards, and decision memos:

    • Observed: What the collection method directly recorded within its stated scope.
    • Calculated: What was produced through a documented formula, join, classification, or transformation.
    • Inferred: What the evidence may explain or predict, including plausible alternatives.
    • Unknown: What the current design cannot establish.

    A careful AI visibility statement might say that a page appeared more frequently in the monitored answer set during the review window. That is the observation. Content or structural changes may be plausible contributors, but prompt sampling, model behavior, competitor changes, and measurement differences remain alternative explanations unless the evaluation design rules them out. The recommendation can still be to retain or extend the change, provided the team continues testing the explanation.

    This language is not weakness. It tells the decision-maker which parts are facts, which parts are judgment, and which parts require another measurement cycle. Use causal words such as caused, produced, or drove only when the evaluation was designed to support causality. Otherwise, use language such as coincided with, is consistent with, or may have contributed.

    Do not turn uncertainty into an arbitrary confidence percentage. If confidence has not been calibrated, a precise score creates another unsupported claim. Name the evidence that raises confidence, the gap that lowers it, and the observation that would change your position.

    Use a three-act narrative without turning evidence into theater

    People need more than a pile of verified metrics. They need to understand why the evidence matters and what should happen next. A setup, confrontation, and resolution structure can organize that reasoning while keeping the decision-maker at the center of it.

    1. Setup – establish the baseline and objective. State the decision, the prior strategy, the relevant success criteria, and the conditions in which the data was collected. Show what was working as well as what was not.
    2. Confrontation – expose the obstacle and competing explanations. Present the gap between the objective and the observed state. Include identity problems, suspicious activity, measurement changes, missing coverage, and other facts that could challenge the easy interpretation.
    3. Resolution – connect action to evidence. Recommend the next move, explain which claim supports it, and define the guardrails. State what will be measured next and what result would cause the team to revise the plan.

    The narrative should organize evidence, not rescue it. Do not remove an inconvenient metric because it interrupts the story. Do not portray a forecast as the ending. The resolution is a justified next action with a way to learn, not a guaranteed outcome.

    At the presentation level, use one decision-bearing claim per chart or report block. Put the scope in the title or immediately below it. Display the comparison window, unit, denominator, filters, and relevant definition change close to the result. Place a material limitation beside the claim it limits, where it can affect the decision, rather than collecting caveats at the end.

    Finish each claim with an action, an owner, and a revisit condition. That turns the presentation from a performance into a shared operating record. It also gives future analysis a clean baseline: the team can see what it believed, why it believed it, what it decided, and which evidence later confirmed or challenged that decision.

    Key takeaways

    • Make every claim no broader than the identities, activities, channels, and time window you can verify.
    • Do not confuse structured or complete-looking records with accurate identities and authentic behavior.
    • Give each decision-bearing claim an evidence card containing its scope, definition, lineage, quality checks, limitations, action, and owner.
    • Audit data before it enters an AI workflow because automation can scale unreliable inputs and reinforce contaminated feedback loops.
    • Label observations, calculations, inferences, and unknowns so readers can see where evidence ends and judgment begins.
    • Present the decision as a setup, a confrontation with the real constraints, and a resolution tied to a measurable next action.

    Before your next dashboard review or model run, choose the one claim most likely to change a decision and complete its evidence card. If you cannot identify the entity, activity, window, origin, exclusions, and limitation, narrow the claim before you polish the presentation. Then give the decision-maker a clear next action and a defined reason to revisit it.

    References


  • AI Search Data Access and Platform Control: A Practical Guide

    AI Search Data Access and Platform Control: A Practical Guide

    You publish a technically sound page. One AI engine cites it, another repeats an older version of the information, and a third never mentions your brand. That doesn’t automatically mean the page is weak. Each engine may be working from a different pool of accessible data.

    Your job is no longer just to rank one URL. You need to make important facts discoverable, retrievable, understandable, and attributable across systems you don’t control. The way to do that is to diagnose the access path, strengthen the parts you own, and measure each platform separately.

    AI search doesn’t operate from one universal index

    From 2023 through 2026, deals, restrictions, and lawsuits changed how data could flow into AI systems. By 2026, tighter platform control was contributing to more fragmented answers. A page can therefore be visible in one AI product and effectively absent from another without changing at all.

    That fragmentation makes a single visibility score misleading. AI search products can differ at several layers:

    • Discovery: The system has to find the URL through a crawl, feed, index, link, API, licensed collection, or another permitted route.
    • Access: The relevant crawler or retrieval service has to receive the content rather than a block, login screen, consent wall, empty shell, or error response.
    • Parsing: The system has to extract the main facts, entities, relationships, dates, and supporting evidence from the returned content.
    • Retrieval: The page has to be considered relevant when a user asks a particular question. Being stored somewhere does not guarantee selection for that query.
    • Synthesis: The answer generator has to use the retrieved information accurately and preserve material qualifications.
    • Attribution: The interface has to decide whether and how to display a citation. An accurate mention and a visible link are separate outcomes.

    This distinction matters because each failure calls for a different fix. Adding more schema won’t correct a crawler block. Rewriting a page won’t repair an outdated third-party profile. Securing a brand mention won’t necessarily produce a clickable citation.

    Use the following as a fault-isolation chart, not as proof of a cause. One observation is a lead; repeated tests and access evidence are what establish the diagnosis.

    What you observeEarliest likely failureWhat to inspect next
    The URL is absent everywhere you testDiscovery or accessSitemaps, internal links, server responses, robots.txt, page-level directives, and authentication requirements
    One engine uses the current fact while another gives an older answerRetrieval freshness or a stale copyThe URLs each engine cites, cached or syndicated versions, and the last verified canonical update
    The answer is accurate but has no linkAttribution or interface behaviorTrack the mention as answer inclusion, then record citation presence separately
    A third-party profile is cited instead of your siteSource selection or owned-page accessWhether the profile is more complete, more current, easier to parse, or the only version available to that engine
    Your page is cited for branded questions but absent for category questionsRetrieval or evidence strengthWhether the page directly answers the non-branded need and supports its claims with specific, verifiable information

    Audit the entire route from page to AI answer

    An abstract web page passes through a series of gated processing chambers before its information reaches an AI answer interface.

    Start with a query-level audit. A domain-wide score can hide the difference between a commercially important failure and an irrelevant miss. Choose questions tied to an actual decision: selecting a provider, verifying a product capability, comparing an approach, confirming eligibility, or checking whether information is current.

    1. Define the fact that should survive the journey. Write down the exact claim an accurate answer needs to contain, the canonical URL that supports it, and any condition that must remain attached. If a limitation changes the meaning, include it in the expected answer.
    2. Separate branded, non-branded, and verification queries. A branded prompt tests whether the engine recognizes your entity. A non-branded prompt tests whether you are retrieved for the problem you solve. A verification prompt tests whether the engine can confirm a precise fact. Do not blend these intents into one score.
    3. Keep test conditions stable. Use the same query wording while comparing engines. Record the product, model or mode when displayed, date and time, account state, region when relevant, and whether web retrieval was enabled. Change one variable at a time.
    4. Capture the answer before judging it. Save the wording, named entities, qualifications, citations, linked URLs, and any visible freshness indicators. Mark factual accuracy and citation presence in separate fields.
    5. Trace every cited URL. Determine whether the engine selected your canonical page, a syndicated copy, a marketplace listing, a social profile, an aggregator, or another publisher. That choice reveals which data route is currently carrying your visibility.
    6. Inspect the owned page as a machine receives it. Check the response status, redirect chain, canonical target, robots.txt rules, meta robots directives, X-Robots-Tag headers, rendered content, and the text available without a user completing an interaction. Confirm that the critical claim is present in the accessible page body.
    7. Classify the earliest failure. Label it discovery, access, parsing, retrieval, synthesis, attribution, or external-copy drift. Fix that layer first. Later-stage optimization cannot compensate for an earlier-stage block.

    Your audit sheet should preserve evidence, not just a final grade. Useful columns include query ID, intent, expected fact, canonical URL, engine, mode, test conditions, answer text, accuracy, qualification preserved, citation present, cited domain, cited URL, access result, failure class, owner, and next action.

    Retest after a meaningful change to content, access controls, structured data, distribution, or a cited external record. Avoid repeatedly changing the prompt until you receive the answer you want. That measures prompt manipulation, not dependable visibility.

    Build visibility that can survive platform boundaries

    You cannot force every AI platform to ingest, retrieve, or cite your content. You can make your facts easier to obtain through permitted routes and reduce the damage when a platform changes its access policy.

    Maintain a canonical fact layer on property you control

    Give every decision-critical fact a stable home. The page should state the fact plainly, identify the entity it belongs to, carry necessary conditions beside the claim, and show the information needed to judge freshness. Essential information should not exist only in an image, video, downloadable file, tab, or client-side widget.

    Create a fact register for content that commonly drifts. For each item, record:

    • The approved wording and any mandatory qualification
    • The canonical URL and responsible owner
    • The visible page element where the fact appears
    • The structured-data field, if one legitimately applies
    • The event that should trigger an update
    • The approved external channels carrying a copy

    This turns freshness into an operating process. When a product detail, policy, service area, leadership record, or other material fact changes, you know which owned page and external records need attention.

    Use external platforms as distribution, not the master record

    Third-party platforms can be valuable discovery routes, especially when an AI engine has stronger access to them than to your site. They also create dependency. A profile can become stale, change format, restrict access, or disappear from an engine’s retrieval set.

    Publish a compact, consistent version of important facts on approved channels, then maintain a map from each external record back to its canonical owner. Avoid copying every page everywhere. Full duplication multiplies the places where old wording can survive. Distribute the facts a channel genuinely needs, preserve qualifications, and link to the canonical page where the channel permits it.

    If a platform restricts automated access or reuse, do not bypass its controls to create an unofficial data pipeline. Use its approved API, feed, export, publishing workflow, or licensing route. Circumventing access rules can create contractual or legal exposure, and the resulting pipeline is likely to break without notice.

    Treat structured data as translation, not permission

    JSON-LD helps a parser connect a page to an entity and interpret supported properties. It does not grant crawler access, compel retrieval, prove a claim, or guarantee a citation.

    Use the schema type that matches the visible entity and content. Keep names, identifiers, URLs, dates, and relationships consistent with the page. Do not place promotional or unsupported claims in markup that a reader cannot verify in the visible content. After publishing, validate both the syntax and the rendered values; syntactically valid markup can still describe the wrong entity or carry an outdated field.

    Support the same canonical layer with ordinary discovery mechanisms such as coherent internal links, XML sitemaps, useful page titles, stable URLs, and feeds where appropriate. For partners that accept structured submissions, maintain those feeds from the same fact register instead of editing each destination independently.

    Measure access, inclusion, and citation separately

    Three inspection stations separately examine whether web information passes an access gate, enters a knowledge repository, and remains linked to a source in an AI response.

    A blended AI visibility score can rise while the wrong fact is being repeated, or fall because an interface stopped displaying citations even though your information still shapes answers. Keep the signals separate so each metric leads to a clear decision.

    SignalEvidence to recordDecision it supports
    Technical availabilityResponse, redirect, crawler rule, authentication, and returned HTMLWhether discovery and access need repair
    Content extractabilityWhether the expected fact and qualification appear in the fetched or rendered textWhether essential content must be moved, clarified, or exposed more reliably
    Answer inclusionWhether the answer accurately contains the expected fact or entityWhether retrieval and content relevance are working
    Citation attributionWhether a citation appears and which exact domain and URL receive itWhether owned visibility or an external dependency carries the answer
    Factual alignmentCorrect, incomplete, contradicted, or unsupported, with the answer text preservedWhich misinformation or missing qualification needs priority
    FreshnessWhether the answer matches the current canonical record and which version appears to be usedWhether an old owned page, stale external copy, or retrieval lag needs investigation
    Cross-platform coverageThe result for each engine and query rather than one combined rankWhich platforms matter enough to justify targeted work
    Dependency concentrationWhich external domains repeatedly carry mentions or citationsWhere loss of access could remove a large part of your visibility

    Use clear labels such as pass, partial, fail, and not observable, then retain the underlying evidence. Not observable is important: you usually cannot inspect an engine’s private corpus or prove why it selected a particular passage. State what the test demonstrates and keep inference separate.

    Prioritize wrong and outdated facts before missing citations. Next, fix owned-page access and parsing problems that affect several queries. Then address stale external copies and weak non-branded retrieval. An accurate uncited answer may still matter, but it should not be reported as equivalent to an owned citation.

    Do not treat every engine discrepancy as a data-access failure. Query wording, retrieval timing, answer mode, personalization, and normal generation variation can also change the result. A stable query set, captured citations, server evidence, and repeated observations help you distinguish a platform pattern from a one-off response.

    Key takeaways for an AI search access strategy

    • AI visibility is platform-specific because engines do not necessarily discover, access, retrieve, or cite the same data.
    • A public URL is not automatically discoverable, fetchable, parseable, retrievable, or eligible for visible attribution.
    • Audit the answer path in order and fix the earliest failing layer before changing later-stage content or schema.
    • Track accurate inclusion and visible citation as separate outcomes.
    • Keep critical facts on an owned canonical page, then distribute controlled versions through approved external routes.
    • Use JSON-LD to clarify visible information, not to replace access, evidence, maintenance, or content quality.
    • Measure each engine and query independently, preserve the evidence, and mark private platform behavior as inference rather than fact.

    Start with one page tied to a real customer decision. Write down the fact it must communicate, test the corresponding query across the AI products your audience uses, and trace the route from discovery through citation. Fix the first broken layer, update every approved copy from the same fact register, and repeat the test after the change. That gives you a visibility system you can operate even when the surrounding platforms keep moving.

    References


  • Perplexity’s Amazon Bot Block: What Commerce Teams Should Do

    Perplexity’s Amazon Bot Block: What Commerce Teams Should Do

    If your AI commerce plan assumes an assistant can find a product, sign in and complete the purchase, the Perplexity-Amazon dispute exposes a flaw in that model: discovery, account access and transaction authority are separate permissions.

    A preliminary injunction now prevents Perplexity’s Comet agent from entering Amazon’s password-protected areas and requires Perplexity to delete the Amazon data it collected. That does not end AI shopping, but it gives SEO, ecommerce and agent teams a practical warning: being visible to an AI system does not give that system permission to act inside a platform.

    The injunction targets authenticated access, not all AI shopping

    The scope matters. U.S. District Judge Maxine Chesney issued a preliminary injunction concerning Comet’s access to password-protected parts of Amazon, including areas used by Prime members. It is not a final judgment declaring every AI shopping agent unlawful, nor does it establish that public product pages cannot be found, interpreted or recommended by AI systems.

    The central distinction is between two kinds of authorization. A customer may authorize an assistant to use the customer’s account, but the platform may still withhold authorization from the assistant itself. The judge cited strong evidence that users granted Comet access while Amazon did not. For anyone building an agent, user consent is therefore necessary but may not be sufficient.

    Amazon has accused Perplexity of computer fraud and unauthorized access, including allegedly allowing Comet to make purchases without identifying itself properly as a bot. Those are Amazon’s allegations, not settled findings on every claim. At issuance, the injunction was suspended for one week so Perplexity could appeal.

    The deletion requirement deserves as much attention as the access restriction. An agent team may need to identify and remove data by platform, account, user and collection method. If you cannot isolate data at that level, a dispute over one integration can turn into a much larger data-governance problem.

    Discovery, recommendation and purchase are separate systems

    Three connected but separate spaces represent product discovery, recommendation, and a locked checkout process.

    AI commerce is often discussed as one continuous journey, but three layers determine whether it works. Each has a different owner, failure mode and remedy.

    LayerQuestion it answersTypical responsibilityCommon failure
    VisibilityCan an AI system find and understand the product?SEO, content, structured data and public-site engineeringThe product is absent, misunderstood or cited inaccurately
    RecommendationDoes the product fit the user’s request well enough to be selected?Product information, positioning, availability and the agent’s decision logicThe product is understood but not chosen
    ExecutionCan the agent enter an account, modify a cart or complete a purchase?Authentication, platform policy, security, legal review and approved integrationsThe journey stops at sign-in, checkout or another protected action

    Schema markup can improve machine understanding at the visibility layer. Clear product details can strengthen the recommendation layer. Neither one grants an agent access to an authenticated account. Treating them as substitutes for platform permission creates a false sense of readiness.

    The same distinction applies to robots.txt and other crawl controls. A public crawling directive is not a purchasing authorization system. It does not answer whether an agent may use a signed-in session, accept terms, place an order or retain account data. Those questions need explicit product, security and legal decisions.

    Your SEO work still matters, but it cannot grant access

    The wrong reaction would be to stop optimizing products for AI discovery. The injunction concerns authenticated access, while much of the discovery and evaluation journey happens through public information. Your content can still help an assistant understand what a product is, who it suits and where the customer can continue safely.

    • Give each important product a stable public destination. Use a consistent canonical URL and make variant handling predictable so an agent does not have to reconcile several conflicting versions of the same offer.
    • Put decision-critical facts in accessible page text. Product names, identifiers, specifications, compatibility, options, limitations and fulfillment conditions should not exist only inside images or interface states that require interaction.
    • Keep structured data aligned with the visible page. Markup that contradicts the page can produce incorrect extraction and erode trust. Treat structured data as a machine-readable representation of the offer, not a place to publish claims the customer cannot verify.
    • Separate product availability from transaction capability. An agent may be able to report that an item appears available without being authorized to buy it. Use language and interfaces that do not blur those two states.
    • Provide a durable human handoff. If automated checkout is unavailable, preserve the selected product or variant in a public deep link and let the customer sign in, review the cart and confirm the purchase.
    • Publish an approved path for automation if you offer one. Document the permitted integration, identity requirements, data limits and prohibited actions. Do not force agent developers to infer transactional permission from crawlability.

    Measure these layers separately as well. AI referrals and product-page visibility tell you about discovery. Product selection or cart initiation tells you about consideration. Completed orders tell you about execution. Combining all three into a single “AI traffic” measure hides the exact permission gate where the journey fails.

    Audit the handoff before an agent reaches login

    A commerce specialist inspects digital permission tokens before an automated shopping device reaches a secured account gate.

    You do not need to wait for another court dispute to find the weak point in your own workflow. Trace one high-value purchasing journey from the first public result through order confirmation, then record the identity, permission and data rules at every transition.

    1. Mark every access boundary. Label which pages and actions are public, account-gated, membership-gated or restricted to an approved integration. Include cart changes, saved payment methods, order history and purchase confirmation.
    2. Name the permission owner. Record whether the customer, merchant, marketplace, payment provider or another party controls each action. If two parties must consent, capture both rather than treating the customer’s approval as universal authorization.
    3. Define agent identity. Decide how an automated system identifies itself and how your service distinguishes it from the human account holder. Do not rely on the fact that the agent is operating through a customer’s browser session.
    4. Minimize retained data. Keep only what the approved workflow needs, attach provenance to it and make deletion possible by source and account. The Amazon data-deletion requirement shows why broad, unlabelled data stores create operational exposure.
    5. Design a graceful stop. When the next action is not authorized, the agent should explain the boundary, preserve useful context and return control to the customer. It should not repeatedly retry, conceal its identity or route around the restriction.
    6. Test the fallback as a primary path. Confirm that the customer lands on the correct product and variant, can see what remains to be reviewed and can complete the protected steps without rebuilding the transaction.

    If your agent enters authenticated services or makes purchases, do not attempt to evade a platform block or disguise automated traffic. That can increase contractual, security and legal exposure. Have qualified counsel review the relevant terms, authorization model and data practices before launch; this dispute is too narrow and preliminary to serve as a universal legal rule for another platform or implementation.

    Key takeaways for AI commerce teams

    • A user’s permission to use an account does not necessarily provide the platform’s permission for an agent to access it.
    • The injunction is specific to Perplexity’s Comet agent and password-protected Amazon areas; it is not a general ban on AI product discovery or shopping assistance.
    • SEO, AEO and structured data improve visibility and understanding, but they do not authorize account access or transactions.
    • A useful agent-ready journey needs both a machine-readable discovery layer and an explicitly permitted execution path.
    • When full automation is unavailable, a precise human handoff is better than an agent that fails silently at login or checkout.
    • Data provenance and targeted deletion are core integration requirements, not cleanup tasks to invent after a dispute begins.

    Your next move should be concrete: diagram one purchasing journey, circle every point where the agent crosses from public information into protected action, and assign an owner to each permission. Keep optimizing the public layer for discovery, but do not describe the journey as agent-ready until the authenticated steps have an approved path or a tested human handoff.

    References

  • AI Marketing Governance: Scale Creative Without Losing Trust

    AI Marketing Governance: Scale Creative Without Losing Trust

    You have a campaign due, the platform wants more assets than your team can shoot, and an AI tool can produce the missing scenes in minutes. The production problem looks solved. The harder question arrives at approval: does the result still represent the product, the customer and the brand truthfully?

    You do not need to choose between using AI and being authentic. You need a governance system that distinguishes harmless assistance from consequential manipulation, preserves evidence for every claim and stops questionable work before speed turns it into scale.

    Key takeaways

    • Authenticity is not the absence of AI. It is the absence of a misleading gap between what your marketing depicts and what a reasonable customer would believe.
    • Govern the output and its likely interpretation, not the name of the tool that produced it.
    • Give every AI-assisted asset a source record, a named approver and a defined withdrawal path before publication.
    • Disclosure can explain how an asset was made, but it cannot make a false product claim, invented testimonial or nonexistent result acceptable.
    • Use the same approved facts across ads, landing pages, product feeds, public relations, structured data and answer-engine content. Contradictory claims weaken both customer trust and machine-readable credibility.

    Authenticity is a truth boundary, not a production method

    A manually produced campaign can be deceptive. An AI-assisted campaign can be accurate. The relevant distinction is not human versus machine; it is faithful representation versus manufactured belief.

    That distinction matters because AI can now support a wide range of creative operations, including background removal, lifestyle-scene generation, synthetic people and rapid asset variation. The resulting production capacity is useful, but technical permission is not the same as brand permission. Your policy has to decide what the audience may reasonably infer from the finished asset.

    Use four questions at the creative brief, review and approval stages:

    1. What will the audience think is real? Identify the likely interpretation, not merely the literal elements on screen. A person may understand that a decorative background is illustrative while assuming a product demonstration, testimonial or before-and-after image records a real event.
    2. Does the synthetic element affect the decision? Color accuracy, dimensions, included features, product condition, customer identity, quoted experience and demonstrated outcomes can all influence a purchase or trust decision. Treat those elements as material.
    3. Can the implied claim be substantiated? You should be able to trace a factual statement or visual implication to an approved product record, documented result or other internal evidence. If the evidence cannot be found, the asset is not ready.
    4. Would knowledge of the AI intervention change the audience’s judgment? If the answer is yes, redesign the asset, disclose the intervention clearly or do both. Do not hide a consequential transformation behind a broad statement that AI was used somewhere in production.

    A synthetic background behind an unchanged product may create little expectation risk. A synthetic person presented in a way that resembles a customer, employee or expert creates much more. A generated product feature that does not exist crosses the truth boundary entirely.

    Disclosure belongs after this truth test, not in place of it. A label can tell someone that an image is simulated. It cannot repair an inaccurate price, fake endorsement, invented review, altered package size or performance claim that your evidence does not support. When the underlying claim could create compliance or legal exposure, pause publication and route it to the appropriate qualified reviewer. A creative approval is not a substitute for legal review.

    Use a four-level integrity ladder for AI-assisted work

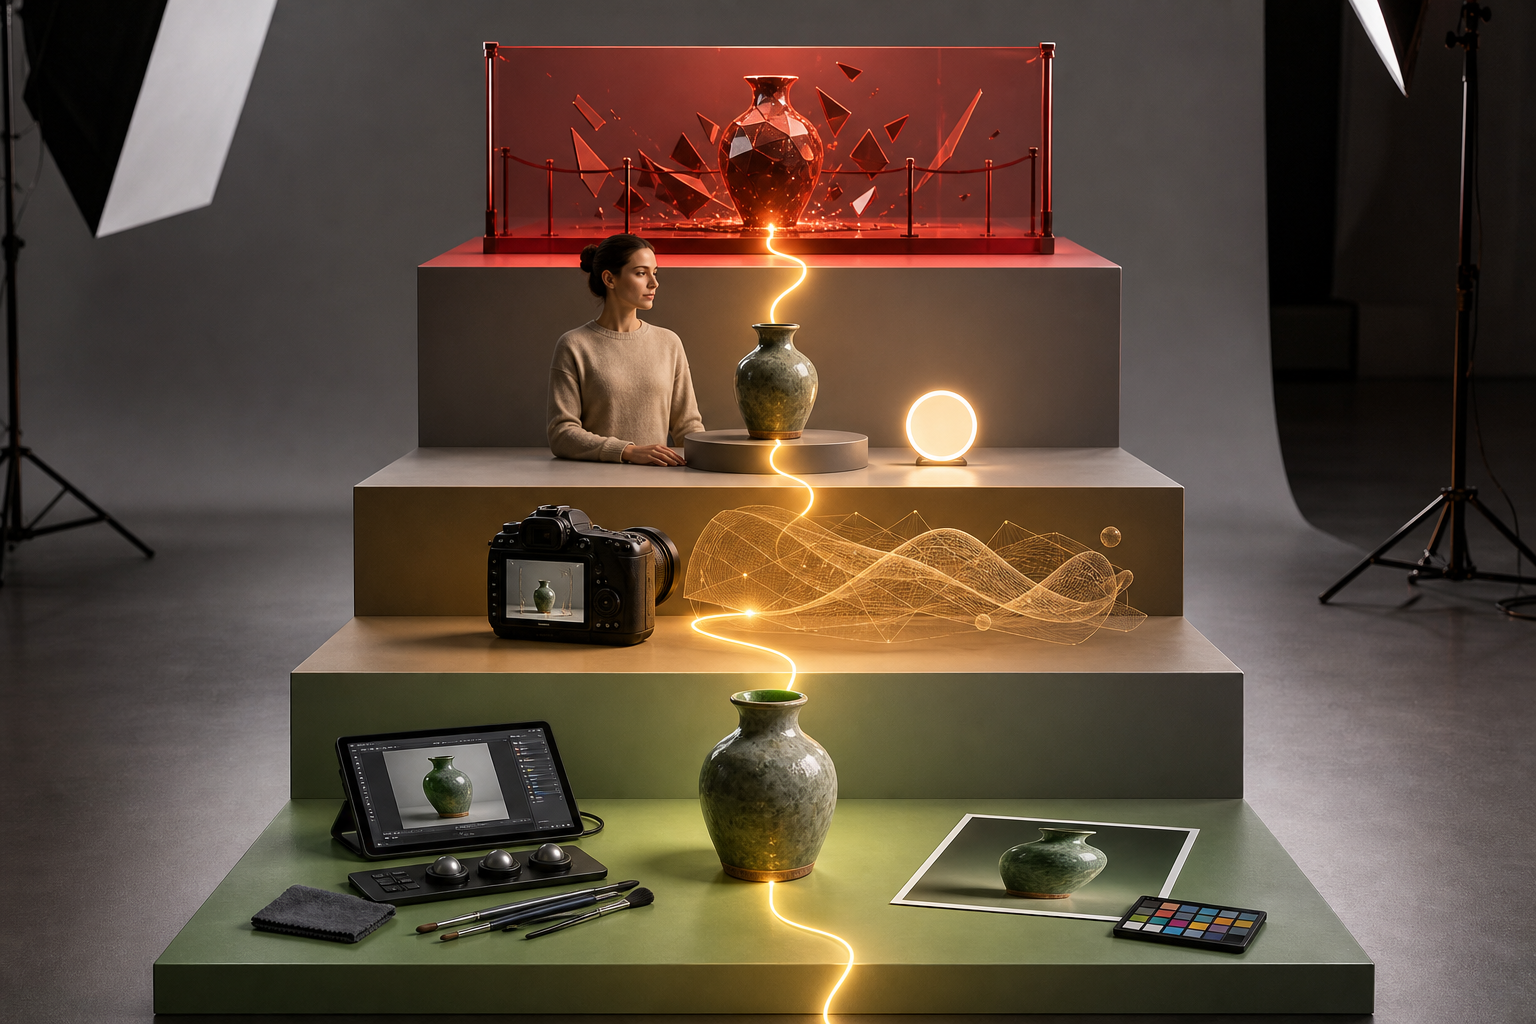
    Four ascending studio platforms show increasingly consequential forms of AI-assisted product imagery connected to a real product by a golden thread.

    A practical policy needs more than a general instruction to use AI responsibly. A four-level brand integrity hierarchy gives marketers, agencies and approvers a shared way to classify work before debating individual assets.

    Integrity levelTypical outputDefault decisionRequired control
    AssistanceResizing, cropping, cleanup, formatting or copy variation that preserves the approved meaningAllowed within documented brand rulesRetain the original and confirm that facts, qualifications and visual product attributes did not change
    AdaptationBackground replacement, contextual scenes, localization or audience variants built around a real product or approved claimAllowed with reviewRecord what was synthetic, verify the product representation and decide whether the context needs disclosure
    SynthesisSynthetic people, realistic events, demonstrations or scenes that an audience could interpret as documentary evidenceConditional and escalatedRequire an accountable approver, a documented disclosure decision, substantiation for every implication and confirmation that no real person’s identity is being misrepresented
    FabricationInvented testimonials, nonexistent features, unsupported outcomes, fake certifications or materially altered productsProhibitedDo not publish; correct the brief or obtain valid evidence for a truthful alternative

    Classify the finished output, not the software. The same generator could perform low-risk cleanup in one workflow and create an unacceptable customer simulation in another. Tool-based rules age quickly and invite loopholes; output-based rules remain understandable when platforms change their features.

    Context can also move an asset up the ladder. Replacing the background behind a product is usually adaptation. It becomes more consequential if the new setting implies that the product is certified for a particular environment, fits a space it does not fit or has a capability it does not have. Likewise, a synthetic human used as decorative illustration differs from one presented beside testimonial language that implies a genuine experience.

    Write examples from your own campaigns beside each level. Include one clearly allowed example, one conditional example and one prohibited example for the channels your team actually uses. Those precedents will resolve ordinary decisions faster than an abstract ethics statement.

    Turn the policy into a publishing gate

    Reviewers inspect a marketing image, a physical product and supporting papers as creative assets pass through a transparent publishing checkpoint.

    A governance document does not protect the brand if approval still happens in chat threads, source files disappear and nobody can identify who accepted the risk. The control has to sit inside the publishing workflow.

    Your operating policy should define:

    • Scope: the channels, teams, contractors, agencies and asset types covered by the policy.
    • Allowed uses: transformations that can proceed under standard review.
    • Conditional uses: outputs that require disclosure, specialist review or approval from a more accountable role.
    • Prohibited uses: transformations that cannot be published even when labeled as AI-generated.
    • Evidence requirements: the records that must support factual, comparative, visual and testimonial claims.
    • Disclosure rules: when a disclosure is required, where it must appear and who approves its wording and placement.
    • Responsibility: who creates, verifies, approves, publishes, monitors and withdraws an asset.
    • Exception handling: who can authorize an exception, what evidence is required and when that decision must be revisited.

    Move each asset through the same evidence path

    1. Set the truth boundary in the brief. List the product attributes, claims, qualifications and visual details that cannot change. State what may be synthesized and what the asset must not imply.
    2. Assemble an approved reference pack. Give the creator the current product images, specifications, brand terminology, claim substantiation and required qualifications. Do not make the reviewer reconstruct the ground truth after generation.
    3. Create within the assigned integrity level. Record the tool or production path, the original materials and the meaningful transformations. You do not need to archive every inconsequential interaction, but you do need enough provenance to reproduce the decision and investigate a problem.
    4. Verify the rendered output. Check the actual sizes, crops, overlays, captions, product details and landing-page destination that the audience will see. A correct master file can become misleading when a placement removes a qualification or crops out context.
    5. Approve the claim and the presentation separately. One check asks whether the underlying statement is supported. The other asks what a reasonable person will infer from the combination of words, images and placement. Passing one does not guarantee the other.
    6. Publish with a withdrawal record. Log the channels and destinations where the asset appears. If a claim changes or an error is found, the team should know where to remove or replace every affected version.

    The asset record can be compact. Capture the campaign and channel, source materials, meaningful AI transformations, claims used, disclosure decision, reviewer, approval state and publication locations. What matters is that someone other than the creator can understand why the asset was approved.

    Human review is not a control by itself. The reviewer needs access to the evidence, clear authority to stop publication and enough time to inspect the final placement. A person who can only click approve is part of the production sequence, not an effective safeguard.

    Paid media needs particular care because asset demand, automated combinations and placement variation can multiply one error quickly. Product imagery deserves a hard verification gate: visual inaccuracies can produce disapprovals or account risk in Merchant Center. Compare the rendered product with the approved reference, including packaging, included components, proportions, color and visible features. If the generated scene obscures that comparison, use a more faithful asset.

    Exceptions should be visible and temporary. Record the business reason, risk owner, supporting evidence and condition that ends the exception. The person requesting an exception should not be its sole approver. Otherwise, deadlines will quietly rewrite your policy one campaign at a time.

    Connect creative governance to SEO, AEO, GEO and PR

    Authenticity problems rarely stay inside the ad account. A generated claim can reach a landing page, product feed, public-relations pitch, social caption, FAQ and structured-data field. Each copy may look defensible in isolation while the combined public record becomes contradictory.

    Build a claim register as the shared layer beneath those channels. For each meaningful claim, record:

    • the canonical wording and any required qualification;
    • the internal evidence or approved public page that supports it;
    • the product, market and context in which it applies;
    • the accountable owner;
    • the channels where it may be used;
    • the disclosure or presentation restrictions attached to it;
    • the condition that should trigger review, correction or withdrawal; and
    • the structured-data properties, feed fields and content components that repeat it.

    This register gives your teams one approved truth rather than several channel-specific versions. Copywriters know which qualifications must survive a short format. PPC teams know which visual implications require evidence. SEO and GEO teams know which public pages should explain and substantiate the claim. Schema implementers know which statements are safe to mark up.

    Structured data should describe visible, supported content. It does not validate a claim merely because the markup is syntactically correct. If the page, product feed and JSON-LD disagree about a product attribute, fix the underlying content system instead of choosing the version most likely to attract a machine.

    Citation readiness also belongs in the governance process. Citations in AI-generated answers can contribute to credibility, and understanding how a brand appears through publicly available information can inform PR decisions. That makes the quality of your supporting pages important beyond conventional rankings.

    A citation-ready page should make the supported claim easy to identify, define its scope and keep the qualification beside it. It should also use consistent product and organization names, connect the claim to the relevant entity and avoid implying that a synthetic scene is proof. A citation can carry an unsupported statement farther; it cannot convert that statement into evidence.

    Monitor governance signals that reveal process failure rather than treating campaign performance as proof that the process worked. Useful signals include assets published without complete provenance, unresolved evidence gaps, exceptions still open, corrections caused by product mismatch, platform disapprovals associated with altered creative and the time required to withdraw a faulty claim across channels.

    Audit what is already live

    Start with a representative set of active ads, landing pages, product feeds, social assets, PR materials and structured data. Classify each AI-assisted element on the integrity ladder. Then trace every consequential claim backward to its evidence and forward to every place it appears.

    Prioritize assets with realistic people, demonstrations, testimonials, product alterations or purchase-critical details. If you cannot identify the source fact, the approving person or all publication locations, you have found a governance gap. Pause the highest-risk asset, establish the missing record and use that case to write the first concrete rule in your policy.

    For your next campaign, define the prohibited transformations in the brief, assign the integrity level before production and name the approver before generation begins. Once those decisions become routine, AI can increase creative capacity without multiplying ambiguity about what your audience is being asked to believe.

    References

  • ChatGPT Ad Rollout: A Practical Readiness Plan for Marketers

    ChatGPT Ad Rollout: A Practical Readiness Plan for Marketers

    If you are deciding whether to reserve budget for ChatGPT ads, do not start with a media plan. Start by separating the small amount that is known from the much larger set of assumptions now forming around the channel.

    The rollout is real, early, and deliberately iterative. Your advantage will not come from treating every unknown as an opportunity. It will come from being ready to evaluate access, economics, measurement, privacy, and organic AI visibility without confusing one with another.

    Start with the rollout’s actual boundary

    A small group of users stands inside an illuminated test zone around a generic chat interface, while a larger digital environment remains outside the boundary.

    OpenAI has begun implementing ads for U.S. users on ChatGPT’s free and Go tiers. That is a meaningful product change, but it is not the same as a global, all-tier advertising launch. Keep that distinction intact in forecasts, presentations, and client conversations.

    OpenAI has described the rollout as iterative, with user trust and privacy central to its approach. Treat that as the company’s stated direction, not proof that every eventual format, targeting method, or data practice will meet your requirements. Those details must be evaluated when actual campaign terms become available.

    The most important strategic distinction is between three different assets:

    • Paid exposure: inventory purchased under campaign terms, with delivery and billing controlled by the advertising system.
    • Earned AI visibility: mentions, citations, recommendations, or inclusion in an answer that you did not buy.
    • Owned conversion experience: the product page, landing page, form, checkout, or other destination where the user can act.

    ChatGPT advertising does not, by itself, establish that buying an ad changes what the model says in its answer. It also does not establish that strong organic visibility will produce paid access or preferential pricing. Until campaign documentation demonstrates an interaction, manage paid ChatGPT inventory and organic AI visibility as separate systems.

    That separation should appear in your language as well as your reporting. Use “ChatGPT ads” for paid placements. Use “ChatGPT visibility” for unpaid appearances in answers. Use “ChatGPT referral traffic” only for visits you can identify. A single label such as “AI performance” hides the very differences you will need to make budget decisions.

    Treat the early economics as an entry gate, not a benchmark

    Early reports put pricing at up to $60 CPM, with commitments beginning at about $200,000. CPM means cost per thousand impressions. These figures tell you that early participation may require a substantial test budget; they do not give you a universal rate card, expected return, available audience, or final buying model.

    If a $200,000 buy were billed entirely at exactly $60 CPM, the simple calculation would produce roughly 3.33 million billed impressions. That is a scenario, not a forecast. “Up to” and “about” are material qualifiers, and impressions alone do not reveal unique reach, frequency, attention, qualified visits, conversions, or incrementality.

    Do not turn those two reported numbers into a business case. Ask for the actual proposal and resolve what the commitment covers: media only or a larger package, guaranteed or estimated delivery, targeting controls, placement definitions, reporting access, cancellation rights, invalid-traffic treatment, and remedies for underdelivery. If those terms are unavailable, waiting is safer than committing money on the strength of a headline CPM.

    Access also appears selective. Shopify is enabling merchants to participate through Shop Campaigns, while Target and Adobe are among the early testers. If you use Shopify, verify access in your own account or through your account representative. Do not assume that being a Shopify merchant automatically makes you eligible, or that early commerce access describes the eventual program for every advertiser.

    Decision questionA pilot may be justified whenWait when
    AccessYour eligibility, inventory, geography, tier, and buying route are confirmed in writing.Your plan depends on press coverage or an assumed self-service launch.
    Learning valueThe test will answer a decision that affects your future media, search, or commerce strategy.The main rationale is simply to be early.
    MeasurementYou can isolate the destination, traffic, conversion event, and campaign cost.Paid visits will be blended with organic AI, direct, or other referral traffic.
    EconomicsThe full commitment fits an experimental budget even if the test does not produce an efficient return.The spend must deliver immediate efficiency to be financially acceptable.
    GovernancePrivacy, data use, ad disclosure, brand suitability, and contract terms have named reviewers.Those questions will be handled only after the campaign starts.

    An early pilot is most defensible when the learning itself has value and the possible loss is affordable. It is much harder to justify when the team needs a mature channel’s predictability from an iterative product.

    Build the measurement contract before the media contract

    Analysts connect a blank conversational ad panel to privacy, conversion, and reporting checkpoints while a separate organic discovery path leads toward the same outcome.

    A new advertising surface creates a familiar attribution problem: delivery is easy to count, while business impact is easy to overstate. Prevent that by agreeing internally on what evidence will count before anyone sees a favorable dashboard.

    1. Write one falsifiable hypothesis. Use the form: “Exposure through this placement will increase a named business event for a defined audience compared with our documented baseline.” Avoid goals such as awareness or learning unless you also define how they will be observed.
    2. Name the primary outcome. Choose the event closest to business value that the campaign can credibly influence, such as a qualified lead, completed purchase, activated account, or another verified conversion. Impressions are a delivery measure, not the final outcome.
    3. Isolate the destination. Use a dedicated landing path, campaign parameters, and separate campaign naming wherever the platform permits. Preserve the original referrer and campaign data through redirects, analytics, customer relationship management, and checkout systems.
    4. Capture the pre-campaign baseline. Record the same business metric before the pilot. Also preserve a controlled set of relevant ChatGPT prompts so you can see whether unpaid visibility changes independently of the advertising campaign.
    5. Set guardrails. Define the maximum acceptable acquisition cost, minimum data quality, prohibited adjacency, privacy requirements, and landing-page conditions before launch. A result that violates a guardrail is not a successful test because its headline metric looks good.
    6. Write a stop rule. Specify who can pause spend and what triggers that decision, such as unusable reporting, incorrect destinations, brand-suitability problems, privacy concerns, or spending that cannot be reconciled with delivery.

    Your vendor questions should be equally concrete:

    • What exactly counts as an impression, and how is viewability or equivalent exposure defined?
    • Where can an ad appear relative to the user’s prompt and the generated answer?
    • How is the paid placement disclosed to the user?
    • Which geography, account tier, device, language, and context controls are available?
    • What reporting can be exported, and at what level of aggregation?
    • Which conversion methods are supported, and what attribution window or model is used?
    • What user or conversation data is exposed to the advertiser, retained, or used for targeting?
    • How are invalid traffic, underdelivery, billing disputes, and makegoods handled?
    • Can creative, destination, or campaign settings be changed during the test without resetting measurement?

    A platform may not answer every question during an early rollout. That is useful information. Reduce the test’s scope, change the success criteria, or wait; do not silently fill reporting gaps with assumptions.

    Protect organic AI visibility from paid-channel attribution

    Marketers working on AEO, GEO, structured data, and AI search have a second job: keep the ad experiment from contaminating the organic program. A paid impression can create awareness and a later search. An organic answer can send a referral visit. A user can also see both. Your reporting should acknowledge those paths without assigning causality you cannot demonstrate.

    Maintain two scorecards. The paid scorecard can contain spend, billed impressions, clicks or visits when available, conversion events, acquisition cost, and evidence of incremental lift. The organic scorecard can track whether the brand appears in controlled prompts, what claims are made, which destinations or citations appear, whether the answer is accurate, and whether identifiable referral traffic follows.

    Use controlled, synthetic prompts for monitoring rather than collecting private customer conversations. For every observation, record the date, market, ChatGPT tier, exact prompt, whether an ad was present, how the placement was labeled, the advertiser and destination, and the separate contents of the unpaid answer. The tier and market matter because the known rollout is scoped to U.S. free and Go users.

    Before a campaign begins, save a baseline from the same controlled prompt set. During the campaign, preserve creative and landing-page versions alongside the observation log. Afterward, compare paid delivery and business outcomes with the organic record. Do not claim that advertising improved model mentions, citations, or recommendations unless a designed experiment supports that causal conclusion.

    Your organic work should continue on its own merits: publish accurate, directly answerable information; make brand and product entities unambiguous; keep commercial details current; show ownership and editorial responsibility; and use structured data that faithfully represents visible page content. Schema can help machines interpret a page, but it is not an ad-access switch and should not be altered merely to imitate an unconfirmed advertising requirement.

    Commerce teams should audit the owned destination before pursuing inventory. Verify that catalog information, price, availability, policy language, product claims, and checkout behavior agree. An ad can accelerate discovery, but it also accelerates the consequences of inconsistent merchant data.

    Key takeaways

    • The confirmed rollout is limited in scope: ads are being implemented for U.S. users on ChatGPT’s free and Go tiers.
    • OpenAI is treating the program as iterative, so early formats, access rules, and economics should not be mistaken for a finished market.
    • Paid ChatGPT exposure and organic ChatGPT visibility are different systems. Budget, track, and describe them separately.
    • Reported pricing of up to $60 CPM and commitments beginning around $200,000 are qualification signals, not performance benchmarks.
    • Shopify’s Shop Campaigns route and the participation of early testers show that access is developing, not that every advertiser has an open buying path.
    • The right preparation is a measurement and governance plan that can survive incomplete platform data.

    Your next move is a one-page readiness brief. Give it an eligibility owner, campaign hypothesis, audience, destination, baseline, primary business event, guardrails, stop rule, privacy reviewer, and list of unanswered vendor questions. If your team cannot complete those fields without guessing, do not reserve budget yet. If it can, you will be able to evaluate an invitation quickly without mistaking paid reach for earned AI authority.

    References

  • What Perplexity’s Ad Retreat Means for AI Search Strategy

    What Perplexity’s Ad Retreat Means for AI Search Strategy

    If Perplexity appears in your paid AI media plan, change the plan, not the audience strategy. The company has phased out its sponsored-placement experiment and has no current intention of bringing it back. Brands can still pursue visibility across Perplexity’s answers, but they cannot currently treat that visibility as inventory they can buy.

    The practical shift is from placement control to evidence quality. You need content that an answer engine can understand, claims it can support, a brand it can identify consistently, and measurement that distinguishes citations from mentions, referrals, and actual business results.

    Perplexity is treating trust as part of the product

    Perplexity began testing sponsored placements in 2024. Sponsored answers appeared beneath chatbot responses, were labeled as advertising, and were presented as separate from the system’s answer selection. The experiment still created a deeper problem: disclosure can identify a commercial relationship, but it cannot force a user to believe that the surrounding answer is free from commercial influence.

    That distinction matters in an answer engine. A conventional results page visibly separates advertisements from organic links and leaves the user to choose among them. An AI interface synthesizes information into a direct response. If an advertisement sits close to that response, the user may wonder whether payment affected the conclusion, even when the company says it did not. Perplexity decided that protecting the belief that users receive the best available answer was more valuable than continuing the test.

    This is not simply an anti-advertising position. It is a choice about which revenue model creates the least damaging perceived conflict. Perplexity is relying primarily on subscriptions, with paid plans reported between $20 and $200 per month, more than 100 million users, and approximately $200 million in annual revenue. Those are reported company-scale figures, not proof that subscriptions will fund every future ambition, but they explain why Perplexity can give trust more weight in the trade-off.

    The same boundary appears in commerce. Perplexity has introduced shopping features but does not take a cut of the transaction. That keeps the platform from earning more merely because it recommends one purchasable result over another. Subscriptions still create business incentives, but the revenue connection is more direct: users pay for access rather than brands paying for proximity to an answer.

    Do not turn the current decision into a permanent promise. A platform strategy can change as costs, competition, and user behavior change. Treat Perplexity as ad-free for planning purposes while maintaining a watchlist for any documented relaunch, rather than building a forecast around an assumed future product.

    Remove paid Perplexity inventory from forecasts, not Perplexity from the plan

    Perplexity reportedly handles 780 million queries per month. That signals substantial usage, but it is not an advertising forecast. Query volume does not tell you how many impressions a brand could buy, which audiences would be reachable, what targeting would exist, or whether exposure would produce qualified visits. Without an active ad product, it cannot be converted into CPMs, clicks, or revenue projections.

    If you own a media plan, make four operational changes:

    1. Move Perplexity advertising out of committed spend. Do not promise inventory, delivery, or launch dates based on the discontinued test. That creates a budget gap and a client commitment you cannot fulfill.

    2. Keep Perplexity in the discovery strategy. Assign ownership to the SEO, AEO, GEO, content, or digital PR workstream responsible for earned visibility.

    3. Preserve relevant creative and audience hypotheses. If ads return, the messaging lessons may remain useful even if the eventual format, targeting, and reporting differ.

    4. Define relaunch evidence in advance. Require an official product announcement, access terms, placement rules, pricing, labeling, targeting, measurement, and brand-safety controls before moving money back into the forecast.

    Do not create one universal policy for all AI products. At the time Perplexity ended its experiment, OpenAI was testing ads for free ChatGPT users, Google was placing ads in AI Mode but not Gemini, and Anthropic was keeping Claude ad-free. Monetization can differ between companies and between products owned by the same company.

    Your channel sheet should therefore use the product surface as the unit of planning. For each surface, record the current ad status, who can access it, where sponsorship appears, how it is labeled, what can be targeted, which reports are available, and when the status was last verified. A row labeled only “AI advertising” is too broad to support a real budget decision.

    Build the visibility that sponsored answers can no longer provide

    A bridge assembled from documents, evidence blocks, and verification seals leads toward a glowing abstract answer engine.

    You cannot choose where Perplexity mentions or cites you in the way you choose an ad placement. You can improve the inputs that make your organization useful as an answer source. The goal is eligibility and clarity, not a guaranteed citation.

    1. Map the questions that precede a decision. Include problem-identification queries, category questions, comparisons, brand-verification questions, objections, risks, and action-oriented queries. Use the language customers use, not only the terms in your navigation.

    2. Give each important page a clear answer job. State the useful answer near the top, then support it with definitions, evidence, limitations, examples, and next steps. A page that hides its conclusion behind a long preamble makes the core claim harder for both people and machines to isolate.

    3. Make claims attributable. Identify who produced the information, when it was updated, what the claim covers, and where its limits begin. If you publish original data, explain the method and scope. If you make a comparison, name the criteria instead of declaring a vague winner.

    4. Keep entity facts consistent. Your company name, product names, author names, service descriptions, locations, and ownership relationships should agree across the site. Conflicting facts create an identification problem before they create a ranking problem.

    5. Use structured data to clarify, not decorate. Organization and Person markup can express publisher and author identity; Article can describe editorial content; Product belongs on genuine product pages; and FAQPage should represent questions and answers visitors can actually see. JSON-LD can make relationships explicit, but it cannot rescue unsupported claims or guarantee inclusion in Perplexity.

    6. Close evidence gaps outside your site. If competing brands are repeatedly supported by independent explanations, reviews, or industry references and yours is not, publishing more self-description may not solve the gap. Give credible third parties something verifiable to reference: transparent data, a useful tool, clear documentation, expert commentary, or a defensible point of view.

    7. Maintain the pages that carry important facts. Correct obsolete details, preserve useful URLs, show meaningful update information, and avoid leaving contradictory versions live. An answer engine cannot reliably resolve a disagreement your own site has not resolved.

    This work should not imitate an advertisement. Promotional adjectives, unsupported superlatives, and repeated brand mentions add little evidence. A strong answer asset lets the underlying facts do the selling: it answers the question, shows why the answer is credible, states who the answer is for, and acknowledges conditions where a different choice may be better.

    Trust is also part of your own publishing system. Label sponsorships, disclose affiliate relationships, separate editorial conclusions from commercial arrangements, and make corrections visible. Perplexity’s decision shows why technical disclosure alone is not enough. Readers also judge whether the surrounding incentives could have shaped the answer.

    Measure answer visibility without pretending it is a fixed ranking

    Multiple translucent lenses show different arrangements of source cards and pathways around a spherical answer engine.

    A generative answer is an observation made under particular conditions, not a permanent search position. Record enough context to reproduce the check: the exact prompt, date and time, account state, answer text, brand mentions, cited URLs, linked pages, competitor mentions, and whether each statement about your brand is accurate.

    Repeat the same query set on a fixed cadence and preserve the results. If you change prompts continually, you cannot tell whether the platform changed or the question changed. If you check only once, you cannot distinguish a durable pattern from normal answer variation.

    Observed stateWhat it meansWhat to do next
    Cited and described accuratelyYour page is functioning as supporting evidence for that query.Preserve the useful URL, keep its facts current, and examine which passage appears to support the answer.
    Mentioned without a citationThe brand is present, but the answer does not visibly attribute the claim to your page.Identify the claim being made and strengthen the page that can support it with explicit, attributable evidence.
    Cited but described inaccuratelyVisibility is creating a reputation or conversion risk.Publish the correct fact prominently, remove contradictions, verify canonical pages, and monitor whether the answer changes.
    Absent while relevant competitors appearThe gap may involve content coverage, entity clarity, evidence quality, or independent corroboration.Compare the cited pages by question answered, evidence supplied, freshness, specificity, and source authority. Fix the missing component instead of copying their wording.
    Results vary across repeated checksThe evidence is not stable enough for a strategic conclusion.Expand the observation history and avoid reporting a gain or loss until a pattern emerges.

    Separate visibility metrics from outcome metrics. Useful visibility measures include brand inclusion rate, citation coverage, citation accuracy, and share of observed answers relative to named competitors. Outcome measures include referral sessions, engaged visits, assisted conversions, leads, and revenue from identifiable Perplexity traffic. A citation can be strategically valuable without generating a click, but that does not justify presenting it as traffic or sales.

    When a result changes, diagnose it at the query-and-page level. Ask which claim disappeared, which URL replaced yours, whether your linked page changed, and whether the competing evidence is more direct. A single sitewide “AI visibility score” can be useful for reporting direction, but it cannot tell an editor which paragraph, fact, entity relationship, or evidence gap needs attention.

    Key takeaways

    • Perplexity’s discontinued ad test removes a direct paid route to its audience; it does not remove the audience from your search strategy.

    • Labeled advertising can satisfy disclosure requirements while still weakening perceived answer independence. Trust depends on incentives as well as interface labels.

    • Do not convert monthly query volume into an advertising forecast when no active inventory, targeting, pricing, or reporting product exists.

    • Treat Perplexity visibility as earned. Improve answer coverage, attributable evidence, entity consistency, structured data, independent corroboration, and factual maintenance.

    • Measure citations, uncited mentions, accuracy, competitor inclusion, referrals, and conversions separately. They answer different business questions.

    • Track advertising status by product surface. ChatGPT, Google AI Mode, Gemini, Claude, and Perplexity do not share one monetization policy.

    Start by moving Perplexity from the paid-inventory line of your plan into an owned-and-earned AI visibility workstream. Establish a repeatable query set, capture the current baseline, and assign each meaningful gap to a specific page, fact, schema relationship, or authority-building task. If advertising returns, evaluate the actual product then. Until it does, the durable advantage is being useful enough to earn a place in the answer.

    References

  • Advertising in AI Experiences: A Practical Readiness Plan

    Advertising in AI Experiences: A Practical Readiness Plan

    If you’re being asked for an “AI ads strategy,” don’t start by moving a search campaign into a new interface. An AI experience may be answering a question, narrowing a comparison, selecting an offer, or helping complete a purchase. Your ad has to help with that task without pretending to be the answer.

    The practical job is to make four things line up: the user’s decision, the claim the system can verify, the offer you can honor, and the next action you can measure. When one breaks, more targeting or more generated creative won’t rescue the experience.

    AI ads compete for the next useful action

    A conventional search ad usually occupies a known slot between a query and a landing page. An ad inside an AI experience enters a more fluid sequence. The user may have already described constraints, rejected alternatives, requested a comparison, or asked the system to help complete a task.

    That does not mean advertisers automatically receive the conversation or control the answer. In the initial ChatGPT design, ads are limited to the Free and Go tiers, kept separate visually and technically from model answers, and hidden from Plus, Pro, and Enterprise users. The model is not informed that an ad is present and does not refer to it unless the user asks. Treat that separation as a real product boundary, not a temporary obstacle to work around.

    Google is pursuing a different but related path. Conversational and visual discovery in AI Mode can include sponsored retail listings and Direct Offers intended to help a user continue a shopping journey. The useful planning unit is therefore not merely the keyword, placement, or audience. It is the decision the user is trying to make.

    Rewrite each campaign brief as a decision task. “Reach operations leaders” is an audience description. “Help an operations leader compare tools that meet a stated integration requirement” is a task. The second version tells your team what facts, offer, destination, and measurement the experience needs.

    • User state: What has the person probably established before a sponsored option becomes useful?
    • Decision constraint: Which requirement, location, budget condition, compatibility need, or availability question narrows the choice?
    • Verifiable claim: What can your site, feed, structured data, or product record support without interpretation?
    • Useful next action: Should the user inspect an offer, compare configurations, check availability, request qualification, or complete a purchase?
    • No-ad condition: In which contexts would promotion be irrelevant, sensitive, misleading, or unsafe?

    The same principle applies outside chat. AI can help connect brands with YouTube creators and turn creator-led discovery into commerce. Define creator fit through the audience problem, acceptable claims, and commercial handoff – not reach alone. A highly visible creator cannot repair a mismatched offer or an unsupported product promise.

    Build answer, offer, and transaction readiness in that order

    Three connected stations depict product answers and evidence, an available offer, and a secure transaction in sequence.

    AI advertising readiness is not a media-only project. The system may need to understand your business, retrieve a current offer, and pass the user into a reliable transaction. Those are separate layers, and each can fail independently.

    Answer readiness: make the commercial facts unambiguous

    Your organic AI visibility and your paid eligibility are different, but they depend on a shared factual foundation. A discovery system should be able to identify what you sell, who it is for, where it is available, what conditions apply, and which page is authoritative.

    • Give every important product, service, location, and offer a stable name and a canonical destination.
    • State the qualifying details in visible page copy. Do not leave essential limitations inside an image, sales deck, or support conversation.
    • Keep names, identifiers, prices, service areas, availability, and eligibility language consistent across pages.
    • Use relevant Schema.org types such as Organization, Product, Service, Offer, and LocalBusiness where they accurately describe visible content.
    • Make JSON-LD match the page. Structured data that promises more than the user can see creates ambiguity rather than authority.
    • Separate factual descriptions from promotional language so a system can retrieve a supportable claim without inheriting the slogan around it.

    No schema type guarantees inclusion in an AI answer or an ad placement. The point of structured data is to reduce ambiguity and connect entities, properties, and offers. It cannot compensate for missing content or contradictory records.

    Offer readiness: synchronize what the user can actually receive

    An AI-matched ad becomes unhelpful the moment its offer is stale. This matters more when a sponsored option is presented after the user has already supplied detailed constraints. The apparent relevance raises the cost of a mismatch.

    For retail, reconcile the identifier, title, destination URL, price, currency, availability, variant, shipping terms, return terms, and promotion conditions across the feed, landing page, structured data, and checkout. For services, do the equivalent with the service area, qualification rules, deliverable, capacity, expected handoff, and any condition that can disqualify the lead.

    Assign an owner to every field that can change. Then define which system is authoritative when two records disagree. “The feed team owns price” is incomplete if checkout can display something else. The useful rule is operational: when the source of record changes, every consumer of that field must receive the update, and the affected offer should stop serving if synchronization fails.

    Transaction readiness: design for safe completion and failure

    Agentic commerce shortens the distance between recommendation and purchase. Google’s Universal Commerce Protocol is intended to standardize AI-assisted browsing, purchasing, and transaction completion. That makes checkout reliability, inventory state, and exception handling part of advertising quality.

    • Require clear authorization before a charge, booking, subscription, or binding order.
    • Make order creation idempotent so a retry does not create a duplicate transaction.
    • Validate price, inventory, tax, shipping, eligibility, and promotion status at the point of commitment.
    • Return an unambiguous confirmation with the item or service, amount, status, and next step.
    • Provide a usable path for cancellation, correction, refund, and human escalation.
    • Preserve enough event history to determine whether an error began in the ad, offer record, handoff, or transaction system.

    Do not enable an automated purchase path while duplicate-order protection, cancellation, or exception handling remains untested. The downside is not a weak engagement metric; it is an incorrect charge, unavailable order, or commitment the user did not understand. Keep a confirmation step and a conventional checkout alternative until the failure paths are reliable.

    Make trust part of delivery, not a policy page

    Relevance does not excuse hidden influence. An AI answer carries a different kind of perceived authority from a familiar ad slot, so sponsorship has to remain legible at the moment the user evaluates the recommendation.

    ChatGPT’s initial guardrails include not sharing conversations with advertisers, excluding ads from health, politics, and other sensitive discussions, and giving users personalization controls. These are platform-specific commitments, not universal rules for every AI ad product. Verify the controls and exclusions of each channel before you approve a campaign.

    Your own delivery specification should cover the following:

    • Sponsorship: Do not write creative that could be mistaken for the assistant’s independent conclusion or an organic citation.
    • Context exclusions: Document the tasks and sensitive situations in which your offer should not appear, even if the platform allows the placement.
    • Data boundary: Record which contextual signals the platform exposes and which user data reaches your systems. Do not reconstruct a private conversation from unrelated identifiers.
    • Claim control: Link every material claim to an approved fact, product record, policy, or landing-page statement.
    • Personalization control: Make consent, preference changes, and opt-out behavior understandable wherever your own data collection begins.
    • Correction path: Give users and internal reviewers a direct way to report an inaccurate offer, misleading claim, or broken handoff.

    Keep paid visibility and AI visibility on separate scorecards

    Do not report a sponsored appearance as proof that a model independently recommends your brand. Do not report an organic mention as paid campaign delivery. They answer different questions.

    • Organic AI visibility: Can the system identify the brand, retrieve accurate facts, answer the relevant question, and cite or mention the right entity?
    • Paid AI delivery: Was the sponsored option eligible, shown in an appropriate context, acted on by a qualified user, and connected to a valid offer?
    • Shared quality: Did the destination substantiate the claim, preserve context, and produce an acceptable customer outcome?

    This separation protects your reporting and your optimization. A bid or budget cannot make weak facts more authoritative. Better organic answer coverage does not guarantee sponsored distribution. Both programs can improve the same landing pages and entity records without pretending to be the same channel.

    Put generated creative behind a claim gate

    Generative tools can make asset production much faster. Google’s advertising direction includes Gemini 3, Nano Banana, Veo 3, and AI Max for creative production, reach, and campaign optimization. Faster production increases the need for tighter review because one outdated input can be repeated across many polished variations.

    Start creative generation from an approved claim set, not an open-ended prompt. Require each variation to retain the qualifying language, destination, and current offer. Store the asset with its source claim and offer identifier. When the underlying fact changes, you can then find and retire every affected version instead of searching campaigns by eye.

    Run the first pilot around one decision, not a whole funnel

    A shopper compares three products with help from verified evidence and a distinct promotional offer while a small team observes the decision.

    A broad launch makes diagnosis difficult. If performance disappoints, you will not know whether the problem was matching, creative, answer readiness, offer accuracy, the landing-page handoff, or transaction friction. A narrow pilot gives each failure somewhere specific to land.

    1. Choose a bounded decision task. Define what the user is trying to decide and the conditions that make your offer relevant or irrelevant.
    2. Create a truth set. Record approved claims, prohibited claims, current offers, exclusions, systems of record, and field owners.
    3. Build the complete path. Review the sponsored message, destination, structured data, offer record, form or checkout, confirmation, and exception route as one experience.
    4. Instrument the handoff. Capture the channel, placement type, campaign, asset, offer identifier, destination, qualified action, completed outcome, and any reversal without collecting private conversational content.
    5. Establish a counterfactual. Use a platform experiment or holdout when available. If neither is available, document a stable baseline and state clearly that the result is directional rather than incremental.
    6. Expand only after quality holds. Increase the range of tasks, offers, or creative after the pilot produces accurate offers, acceptable outcomes, and no recurring trust failure.

    Click-through rate can diagnose whether a sponsored option attracts attention, but it cannot tell you whether the AI-assisted decision was good. Define qualification and completion before launch, then measure the handoff with metrics that expose both performance and failure.

    MetricHow to calculate itWhat it helps you decide
    Qualified action rateQualified actions divided by attributed AI ad visitsWhether matching and creative are producing commercially relevant responses
    Offer consistency rateAudited offers whose ad, destination, structured data, and transaction terms agree divided by all audited offersWhether the commercial data is dependable enough to scale
    Decision completion rateConfirmed target outcomes divided by eligible initiated pathsWhether the handoff helps the user finish the intended task
    Outcome quality rateAccepted, retained, or otherwise qualified outcomes divided by completed outcomesWhether apparent conversions remain valuable after validation
    Mismatch or complaint rateRecorded relevance, sponsorship, offer, or transaction complaints divided by attributable interactionsWhether utility is being purchased at the cost of trust
    Incremental outcomeDifference between exposed and valid comparison groupsWhether the channel created value beyond outcomes that would have happened anyway

    Set the definitions, data owner, and decision rule for each metric before anyone sees campaign results. Otherwise, teams tend to relax the meaning of “qualified” or emphasize whichever event improved.

    Pause the affected offer or path when the ad claim is absent from the destination, displayed terms disagree with checkout, inventory cannot be confirmed, users mistake sponsorship for an independent answer, or additional conversions arrive with a corresponding rise in reversals, refunds, or disqualified leads. These are not creative-learning signals. They indicate that the experience is making a promise the operating system cannot reliably keep.

    Key takeaways

    • Plan AI advertising around a user’s decision task, not merely a keyword, audience, or placement.
    • Treat answer readiness, offer accuracy, and transaction reliability as separate layers with named owners.
    • Keep sponsored delivery visibly separate from model answers and report paid exposure separately from organic AI visibility.
    • Use structured data to clarify visible facts, never to introduce claims or terms that the page does not support.
    • Measure qualified outcomes, offer consistency, completion, and trust failures alongside attention metrics.
    • Scale only after the entire path can preserve context, honor the offer, and handle exceptions safely.

    Your first move does not need to be a large media commitment. Choose a commercially important decision, make its facts and offer machine-readable, connect it to a dependable action, and define the conditions that will stop the campaign. That foundation will remain useful as AI ad formats, matching systems, and agentic purchase paths continue to change.

    References