Tag: AI Transparency

  • AI Watermarks: What Actually Matters for Search Quality

    AI Watermarks: What Actually Matters for Search Quality

    You are about to publish an AI-assisted page, and a watermark or detector score has turned an editorial decision into an SEO worry. The useful question is not whether a machine touched the draft. It is whether the finished page earns its place in search results and AI-generated answers.

    Treat the watermark as a clue about production, then audit the work itself. That keeps your attention on the failure modes that can damage visibility and trust: unsupported claims, recycled ideas, generic advice, near-duplicate pages, and automation without accountable review.

    A watermark describes provenance, not quality

    A machine-readable watermark associated with Claude-generated text can indicate that AI participated in the production process. It cannot tell a reader who originated the idea, how much of the finished work came from the model, whether its claims are correct, or whether the page is useful.

    Those questions belong to three separate layers:

    SignalWhat it can tell youWhat it cannot establish
    AI watermark or provenance markerAn AI system participated somewhere in generationOriginality, accuracy, usefulness, or the extent of human contribution
    AI detector scoreA tool estimates that the text resembles patterns it checksCertain authorship, reader value, or search quality
    Byline or author markupA named person or organization accepts ownershipThat the information is distinctive or deserves citation

    Conflating these layers leads to the wrong work. A team may rewrite sound sentences solely to reduce a detector percentage while leaving weak reasoning, unverified claims, and duplicated ideas untouched. The page then looks less detectable without becoming more valuable.

    AI use also is not one uniform editorial practice. Asking a model to organize your notes, challenge an argument, expose missing questions, or improve a draft is materially different from publishing its first response. In both cases, however, the publisher remains responsible for the result. If you would be uncomfortable defending the page once its AI involvement became visible, send it back through editorial review instead of trying to disguise the workflow.

    Search risk comes from low-value automation, not AI involvement alone

    Google has not treated AI authorship as an automatic reason to penalize content. Its relevant distinction is what automation produces and why it was produced. Generative AI can help with research and structure. The problem emerges when automation is used to manufacture large amounts of low-value material primarily to manipulate rankings.

    That is the mechanism behind the SEO risk. Giving a model broad publishing autonomy makes it cheap to produce generic recommendations, unsupported assertions, lightly altered pages, and summaries of information already present throughout the search results. Scaling those defects does not create authority. It multiplies reasons for search systems and readers to ignore the site.

    There is likewise no universal rule that a Claude watermark excludes a page from AI-generated answers. Answer engines still need material worth retrieving, citing, or synthesizing. A process signal does not erase original evidence, firsthand knowledge, a useful framework, or a defensible opinion. It also cannot rescue a page that merely repeats the prevailing consensus in slightly different words.

    Hold publication when any of these conditions is true:

    • Your editor cannot name the page’s unique contribution in one sentence.
    • A group of pages differs mainly by replacing a location, product, industry, or target keyword.
    • The copy makes factual claims that no reviewer has traced and verified.
    • The only reason for creating the page is that a keyword exists, not that a defined reader needs the answer.
    • No named person owns the final decision to publish, correct, or withdraw the content.
    • The page would lose nothing important if it were replaced by a generic search-results summary.

    This test applies equally to human and AI writing. A human-written page does not gain a competitive advantage merely by being human if it offers the same information as a thousand other pages. A watermarked page does not lose a genuine advantage merely because AI helped shape its presentation.

    Use a citation-worthiness audit before publication
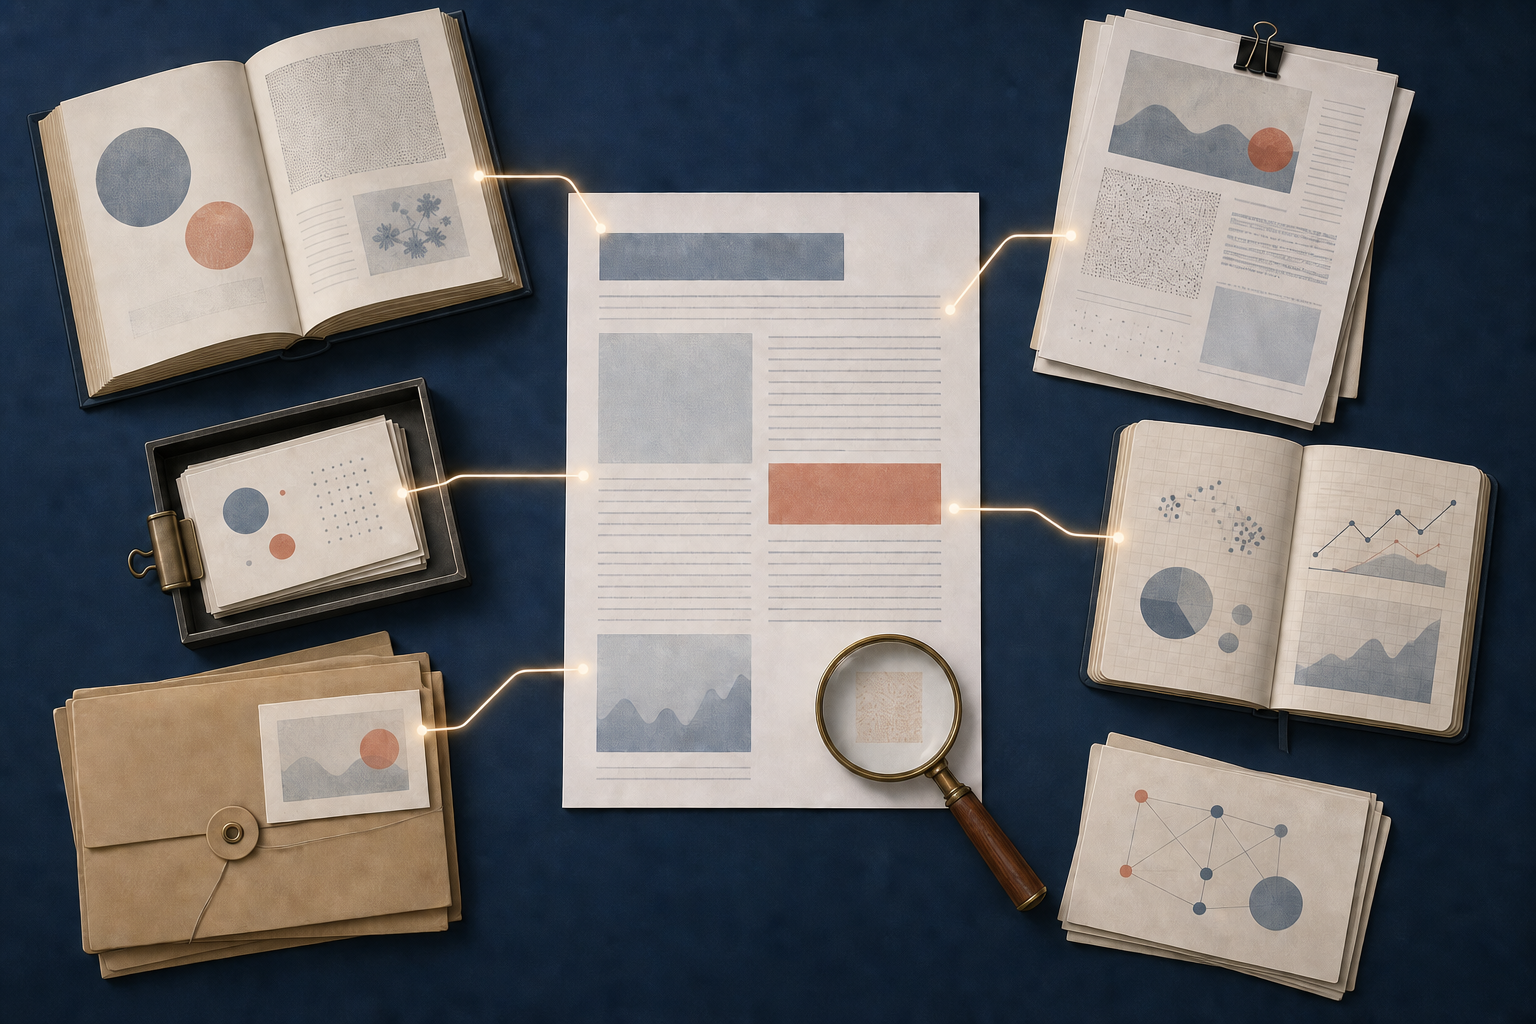
    An article page surrounded by reference materials, with visual lines linking parts of the page to supporting sources and one area under a magnifying lens.

    A normal copy edit is not enough for AI-assisted work. You need a release process that tests why the page should exist, which claims deserve trust, and what an answer engine could retrieve from it. Use this sequence for every page, whether AI wrote one sentence or most of the first draft.

    1. Define the page’s job. Complete this sentence before drafting: This page helps a specific reader complete a specific task under a specific constraint. A broad topic such as AI content quality is not a job. Deciding whether to publish an AI-assisted landing page after detecting a watermark is.
    2. Name the unique contribution. Write down what the reader can obtain here that is difficult to obtain elsewhere. It could be original data you actually collected, a documented procedure, firsthand operational knowledge, a new comparison, or a reasoned interpretation. New wording is not new value.
    3. Build an evidence ledger. Record the support for every claim on which the reader might base a decision. Include the relevant URL, named authority, date or product version when needed, verification status, and reviewer. Do not ask a model to invent citations or treat its confidence as verification.
    4. Give AI bounded roles. Decide in advance whether the model may organize notes, propose an outline, challenge assumptions, generate alternatives, or improve clarity. Do not let the same automated process generate a claim, declare it verified, approve the page, and publish it without independent review.
    5. Run the genericity test. Replace the important nouns with those from another company or topic. If the paragraph still sounds equally plausible, it probably contains interchangeable advice. Cut it or add the missing evidence, constraint, example, or point of view.
    6. Make the useful answer retrievable. Put the direct answer close to the heading that asks the question. Keep its supporting evidence adjacent. Use stable entity names, descriptive headings, and a table only when the reader is genuinely comparing fields. Appropriate structured data can clarify what a page contains, but it cannot turn recycled copy into evidence.
    7. Assign a real owner. Name the person responsible for checking the claims and maintaining the page. Use a byline, credentials, and author markup only when they accurately represent that ownership. A byline can support identity consistency for AI crawlers, but it cannot make repetitive information citation-worthy.

    The release gate: can you defend the finished page?

    Before the page enters your CMS workflow, require clear answers to four questions:

    • Is it accurate? Every consequential claim has traceable support, and uncertainty is visible instead of being edited away.
    • Is it original enough to justify existing? The unique contribution is information, reasoning, or experience, not merely different phrasing.
    • Is it useful to the intended reader? That reader can make a decision, complete a task, avoid a mistake, or understand a meaningful distinction after reading it.
    • Will someone stand behind it? A named owner is prepared to explain the reasoning, correct errors, and accept scrutiny of the production process.

    If one answer is missing, the page is not ready. A lower AI score would not change that decision.

    Measure the finished page instead of chasing an AI percentage
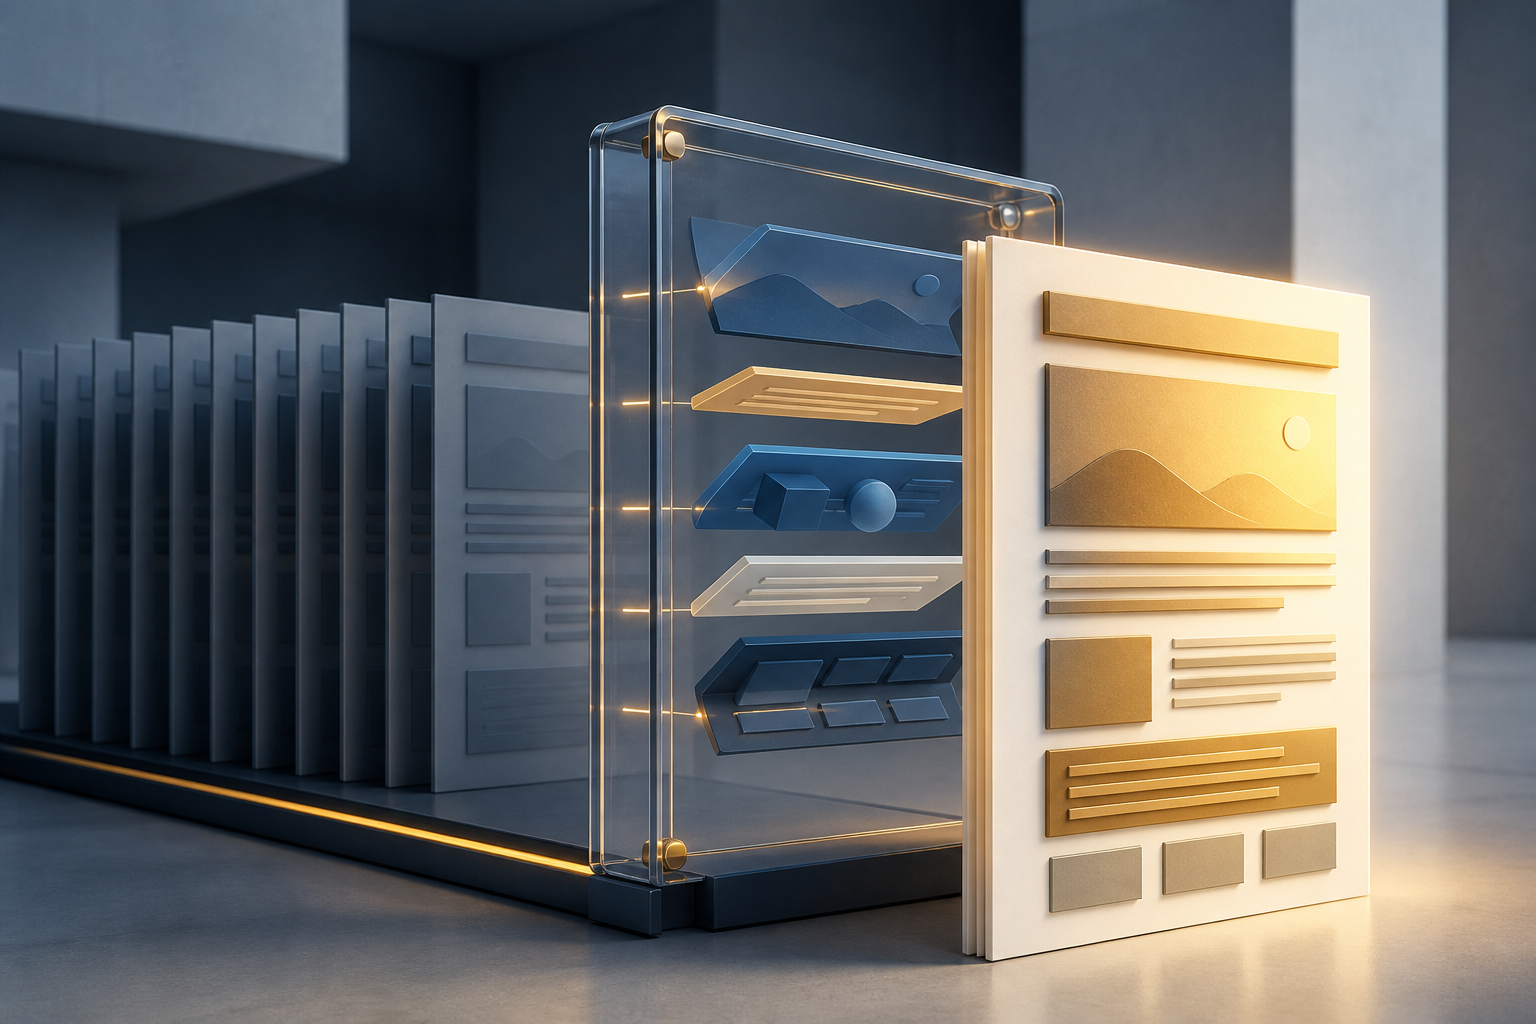
    A layered page passing through a transparent inspection frame while a stack of nearly identical thin pages fades into the background.

    An AI score cannot tell you whether a reader finished the page, trusted it, shared it, subscribed, or completed the intended action. It also cannot tell you whether an answer engine cited the page accurately. Those are outcomes a detector percentage does not measure.

    Build reporting around the page’s actual job:

    OutcomeWhat to observeWhat to do when it fails
    Search discoveryIndex status, impressions for relevant queries, and qualified organic visitsCheck technical access, intent alignment, internal discovery, and whether the page adds enough value to compete
    AI-answer visibilityWhether relevant answer surfaces cite, link to, or accurately represent the pageStrengthen distinctive facts, make the answer easier to extract, and keep evidence beside the claim it supports
    Reader usefulnessCompletion of the action the page was designed to support, plus meaningful shares, subscriptions, or return visits where relevantFind the unanswered question, missing proof, or unnecessary friction instead of adding more generic copy
    Editorial trustCorrections, challenged claims, review failures, and substantive reader feedbackRepair the evidence and workflow before increasing production volume

    Do not mislabel all of these observations as direct ranking factors. They serve different purposes: search metrics show discoverability, citation checks show retrievability, and reader or business outcomes show whether the page fulfilled its intended role. Together, they provide a more useful diagnosis than a single AI-likelihood score.

    A detector result can still trigger a process check. An unexpected score may prompt you to confirm how a draft was produced, whether your editorial policy was followed, and whether required review occurred. It should not become a target that writers optimize at the expense of clarity. Rewriting accurate text until a detector approves its style is not content improvement.

    The same logic applies to watermark-removal tools. If removal is the only change, the page gains no new evidence, insight, or usefulness. Review the claims, eliminate sameness, add the missing contribution, and document accountable ownership before spending effort on the provenance signal.

    Key takeaways

    • An AI watermark can indicate something about production; it cannot determine accuracy, originality, usefulness, or search quality.
    • AI involvement is not an automatic search penalty. Low-value content produced at scale to manipulate rankings is the relevant risk.
    • Use AI for bounded tasks such as organization, critique, and editing, while keeping evidence checks and publication approval independent.
    • Bylines, author markup, headings, and schema can clarify ownership and meaning, but they cannot make generic information worth citing.
    • Judge a page by search discovery, answer-engine citations, reader usefulness, and editorial trust rather than an AI detector percentage.
    • If revealing AI involvement would make your team reluctant to defend the work, improve the work before publishing it.

    For your next AI-assisted page, require four fields before publication: the intended reader, the unique contribution, the evidence ledger, and the accountable owner. Leave the page in draft if any field is blank. If all four withstand scrutiny, publish the work and stand behind it, watermark or not.

    References


  • Google Ads AI Transparency: A Practical Audit Framework

    Google Ads AI Transparency: A Practical Audit Framework

    When Google Ads can rewrite the product title a shopper sees, knowing what you entered in Merchant Center is no longer enough. And when an AI coding assistant can generate integrations, troubleshoot failures, and query a live advertising account, working code is no longer sufficient proof that the work is correct.

    You need an evidence chain: what the AI changed, what rules or schema supported the change, what actually ran or served, and what happened afterward. Two Google Ads developments make that easier: reporting for AI-generated Shopping titles and a schema-aware Google Ads API assistant. Used carefully, they let you audit automation without giving up its speed.

    Treat Google Ads AI as two separate control problems

    Google Ads AI acts at more than one point in the advertising workflow. The control you need depends on where the automation operates.

    AI layerWhat can changeEvidence availableYour control decision
    Ad deliveryThe product title presented in a Shopping adOriginal and customized titles plus impressions, product clicks, CTR, cost, and average CPCDetermine whether the generated wording preserves product identity and attracts useful traffic
    API developmentIntegration code, GAQL queries, diagnostics, and reporting workflowsGoogle Ads-specific rules, GAQL validation, Protobuf schema inspection, and live query resultsDetermine whether the implementation is valid for the intended API version, account, and business question

    The first layer is a message-governance problem. The second is a software-governance problem. Combining them under a vague instruction to “monitor the AI” produces weak reviews because the artifacts, risks, and owners are different.

    Use the same principle for both: never approve an AI output without identifying the input, the transformation, and the observed result. A generated title is an output. So is a valid GAQL query. Neither tells you by itself whether the outcome serves your commercial intent.

    Audit the product title shoppers actually see

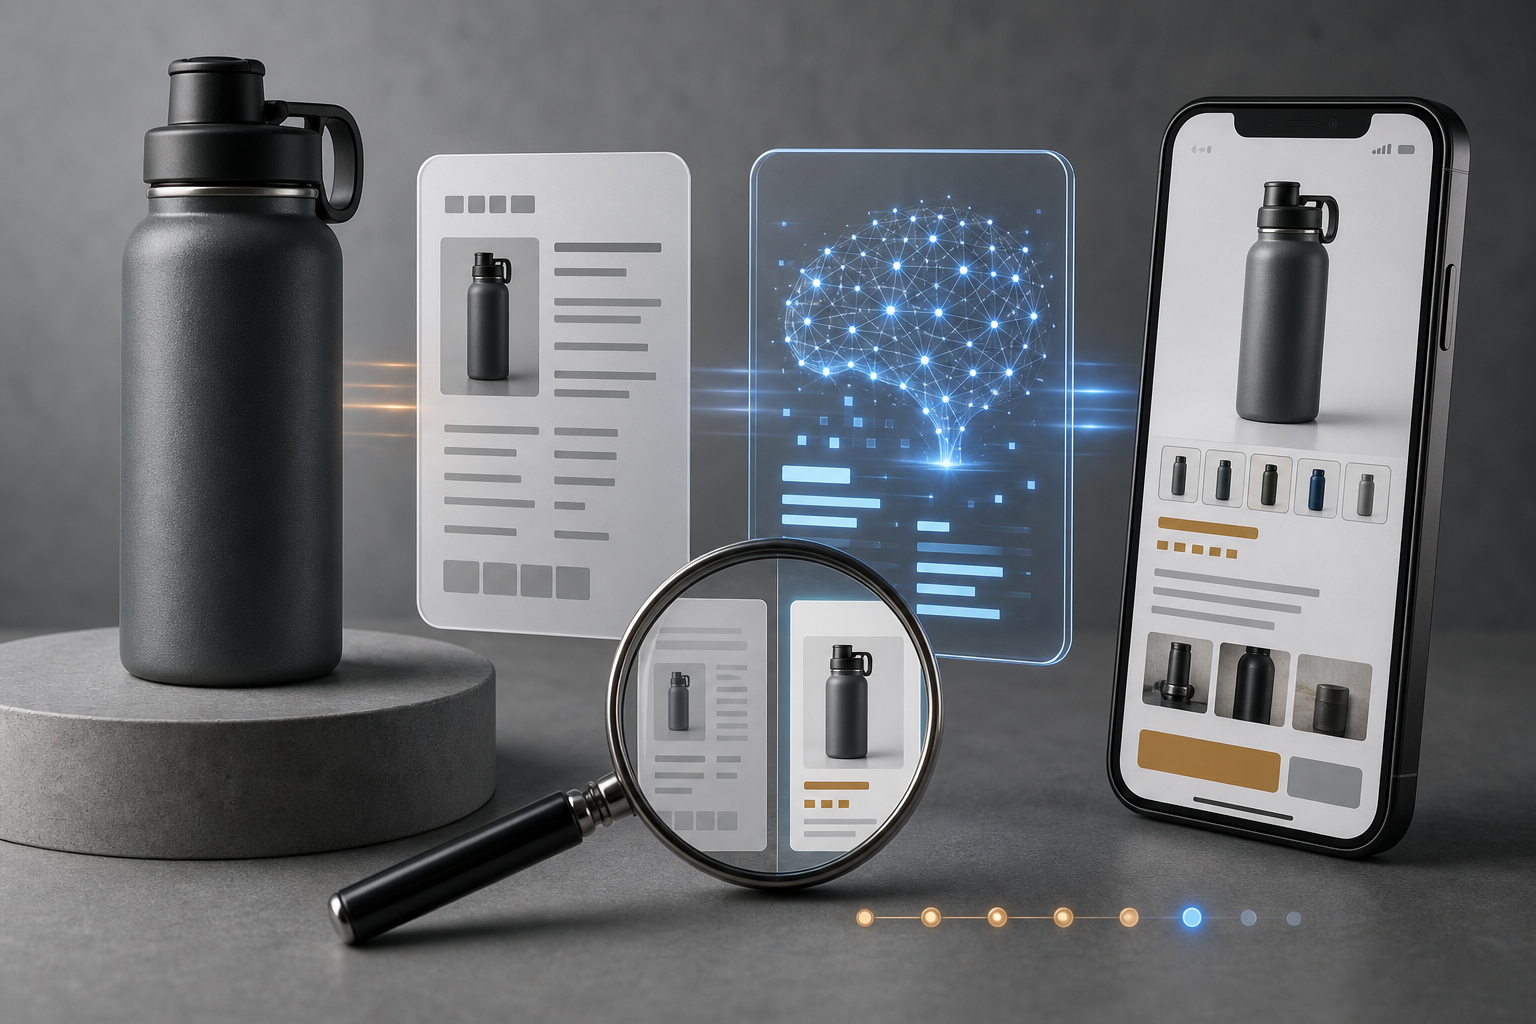
    A magnifying glass compares a source product record with an AI-processed shopping listing shown on a smartphone.

    Google AI can create a customized product title and serve it when it considers that version more relevant than the advertiser-provided title. The original remains eligible to appear when Google considers it more relevant. The practical consequence is simple: your feed title is an input to ad delivery, not a guarantee of the final wording.

    The Product titles report is beginning to appear in Google Ads, so availability may not be uniform across every account. Where it is available, it can place the original and AI-customized titles beside delivery and traffic metrics. That gives you something much more useful than a general notice that automation may alter copy: it gives you inspectable examples.

    Review meaning before performance

    Start by checking whether the generated title still identifies the product accurately. A higher CTR cannot repair a title that creates the wrong expectation.

    1. Compare the identifying details. Check whether the generated wording preserves the brand, model, product type, variant, size, material, compatibility, or other detail a buyer needs to distinguish the item.
    2. Look for a change in promise. Flag wording that implies a feature, bundle, use case, audience, or level of compatibility that the product page does not support.
    3. Check brand and legal sensitivity. Route regulated claims, trademarks, guarantees, and tightly controlled brand language to the appropriate reviewer before treating the title as acceptable.
    4. Inspect the landing-page match. A title may be technically accurate but still emphasize something the landing page does not make easy to find. That mismatch can attract a click while weakening the visit.
    5. Classify the change. Record whether the generated title clarifies the product, rearranges existing details, introduces a new interpretation, or removes a distinguishing detail. This turns isolated examples into patterns you can act on.

    When generated titles repeatedly clarify information that was buried or absent in your originals, treat that as a feed-quality hypothesis. Do not merely admire the AI version. Ask whether the original titles should communicate the same useful distinction more directly.

    Read the metrics as observation, not a controlled test

    The report can include impressions, product clicks, CTR, cost, and average CPC. Those measures answer different questions:

    • Impressions show how much exposure a title received. A dramatic-looking CTR difference attached to limited exposure deserves caution.
    • Product clicks show traffic volume, but not whether those visitors produced valuable outcomes.
    • CTR describes the rate at which impressions produced clicks. It can help you spot wording that attracts attention, but it does not establish why the difference occurred.
    • Cost and average CPC show the price of the traffic. They do not, by themselves, establish revenue, margin, lead quality, or profitability.

    Do not label this comparison an A/B test unless you have a genuinely controlled experimental design. Google may select an original or customized title because it considers one more relevant in a particular serving context. Different contexts can therefore influence both which title appears and how it performs. The report reveals an association between a served title and its results; it does not automatically isolate the title as the cause.

    Your decision should combine three checks: semantic accuracy, sufficient exposure, and downstream business value from your existing measurement setup. A title that earns more clicks but brings poorly matched visitors is not an improvement.

    Make the API assistant prove technical validity

    Google Ads API Developer Assistant v4.0.0 moves from the earlier standalone local-workspace structure to a globally available plugin architecture. It can supply Google Ads-specific rules, skills, and diagnostic commands across projects. The architecture is not compatible with previous releases, so adopting version 4 should be treated as a migration rather than a routine in-place update.

    The assistant supports AI coding workflows in Antigravity and Claude Code. It can generate integration code for Python, Java, PHP, .NET, and Ruby. More importantly for reliability, it can inspect local Protobuf schemas and client-library code instead of depending entirely on what the underlying model remembers about Google Ads.

    That grounding is most useful when you require it as part of the workflow. Use this review sequence:

    1. Identify the intended API version. Record it with the task so a reviewer can distinguish current fields and enums from suggestions that belong to another version.
    2. Inspect the relevant schema before accepting generated code. Confirm resource names, available fields, data types, and enum values against the active version.
    3. Validate every GAQL query before execution. The local validator can check syntax, field compatibility, date segmentation, resources, metrics, date clauses, and zero-impression rules in one pass.
    4. Review account and time context. Before a natural-language request runs against live data, verify the customer ID, manager-account relationship where relevant, date range, segments, metrics, and expected level of aggregation.
    5. Read the generated code as code. Schema validity does not replace review of authentication, account selection, data handling, error paths, and whether the integration performs only the operations you intended.
    6. Save a reproducible result. The assistant can return live results as a formatted table and can save ad hoc reporting output as CSV. Preserve the validated query with the output so another person can reproduce what was retrieved.

    This approach is faster than asking a general-purpose model to guess at a broken query over multiple attempts. It is also safer because the query is checked against Google Ads-specific constraints before it reaches the account.

    Use conversational troubleshooting as triage

    The assistant can investigate offline conversion upload failures, manager-account hierarchy problems, and Performance Max listing filters. It can also help answer broader questions, such as which ads have problems and how those problems might be addressed.

    Treat the response as structured triage. Ask it to identify the failing object, inspect the applicable schema, show the relevant error or rule, and separate confirmed findings from proposed fixes. Then review the recommendation before changing production code or campaign configuration. A conversational explanation is easier to consume than a raw error, but readability is not evidence.

    Know what grounding does not prove

    Schema inspection and local validation reduce a specific class of AI failure: invented fields, incompatible combinations, and version-mismatched configurations. They do not prove that the request reflects the business question you meant to ask.

    • Syntactic validity: Can the query be parsed? The validator can address this.
    • Schema validity: Do the resources, fields, metrics, types, and enums exist and work together for the active version? Schema inspection and Google Ads-specific rules can address much of this.
    • Account validity: Is the query running for the correct customer, through the intended manager hierarchy, over the correct dates? The assistant can help retrieve customer IDs and diagnose hierarchy issues, but you still need to confirm the intended account context.
    • Business validity: Does the output answer the decision you need to make? A perfectly valid cost query is still wrong if the decision depends on profitable conversions or qualified leads.

    The same distinction applies to Shopping titles. Transparency shows you the generated wording and associated performance. It does not prove the wording is accurate, brand-safe, incrementally better, or responsible for the observed result.

    Google says the plugin architecture improves speed and reduces resource and token consumption by loading only the rules and schemas needed for a task, with caching to avoid repeated lookups. Those efficiency claims are useful for adoption planning, but they are separate from auditability. Faster generation changes how quickly work arrives; it does not lower the review standard.

    Build one evidence trail across marketing and development

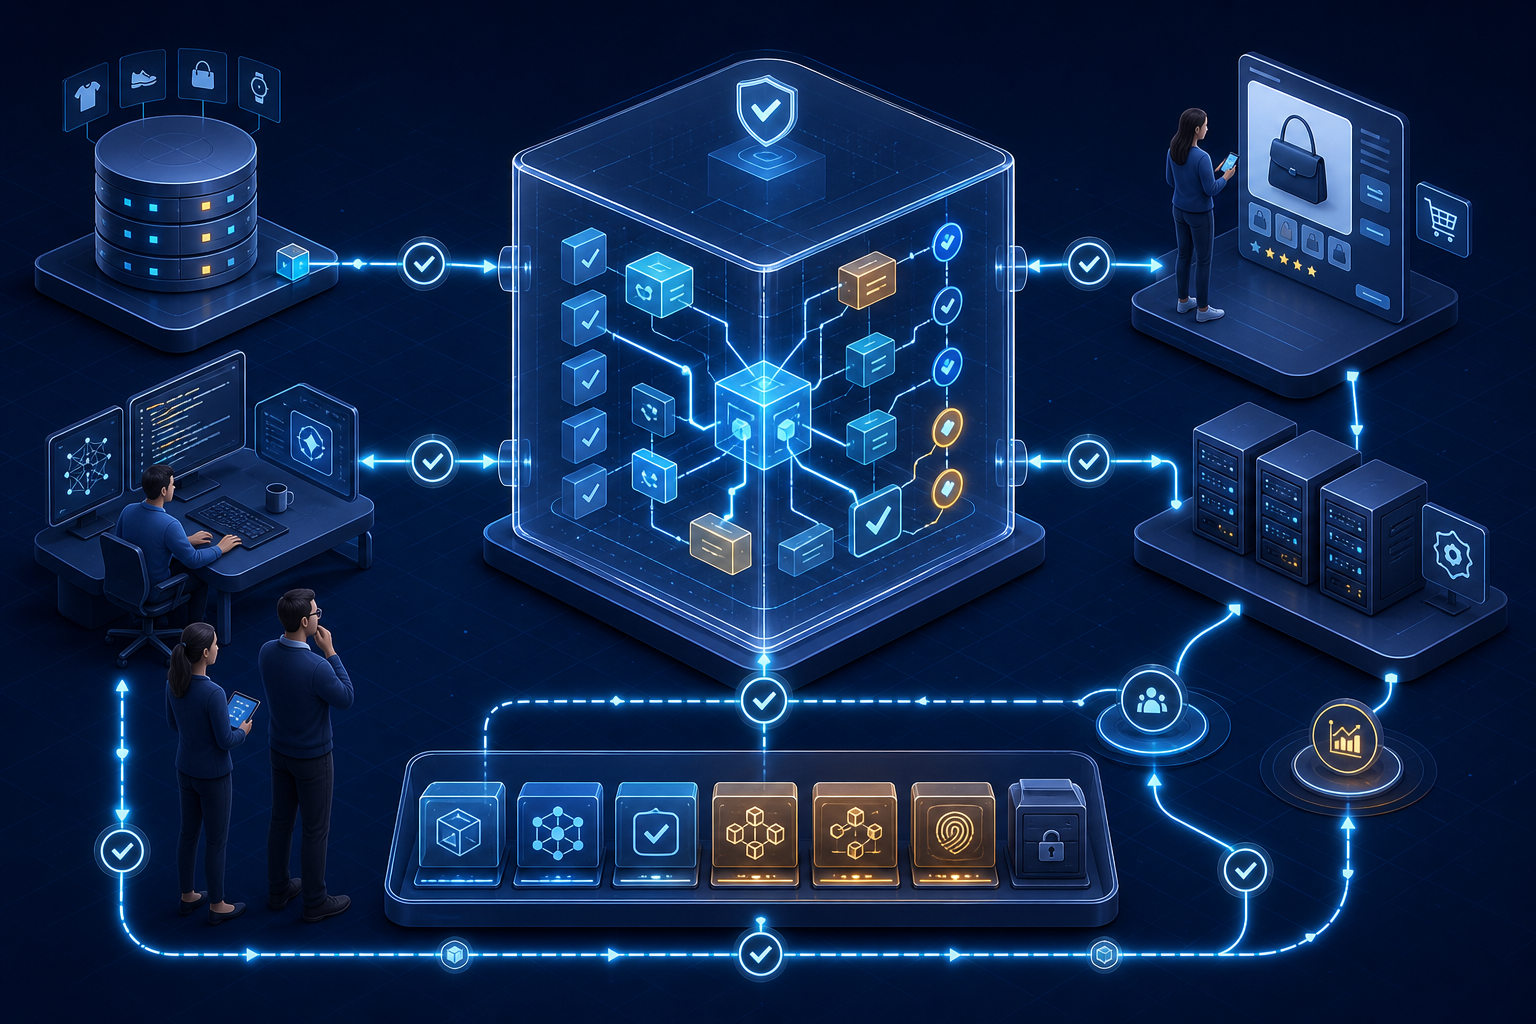
    Marketing and engineering specialists inspect a connected evidence trail linking product data, validated code, live advertising outputs, and archived outcomes.

    You do not need a large governance program to make these tools accountable. You need a compact record that joins the AI output to the decision made about it.

    For AI-generated product titles, record the product or internal SKU, original title, generated title, review classification, impressions, product clicks, CTR, cost, average CPC, relevant downstream outcome from your measurement system, reviewer, and decision. This is your internal audit log; it should not be confused with a claim that every field appears in the Product titles report.

    For API work, record the customer context, intended API version, client language, user request, generated GAQL or code, validation result, schema fields inspected, date clauses, output location, reviewer, and deployment decision. If the work concerns an offline conversion upload, account hierarchy, or Performance Max listing filter, preserve the original failure details with the diagnosis.

    Assign ownership by artifact:

    • The feed owner is accountable for the original product data and for recurring weaknesses exposed by generated titles.
    • The performance marketer assesses title accuracy, delivery metrics, traffic quality, and the business relevance of the comparison.
    • The developer owns API-version selection, schema verification, query validation, code review, and reproducibility.
    • The appropriate brand, compliance, or business owner approves wording or implementation decisions that exceed the marketer’s or developer’s authority.

    Use event-based reviews instead of checking everything indiscriminately. Review when customized titles first appear, after meaningful feed changes, when a high-impression title changes the product’s meaning, before adopting the incompatible version 4 plugin architecture, before deploying generated integration code, and when a known troubleshooting case affects reporting or conversion data.

    Key takeaways

    • Google may serve an AI-customized Shopping title instead of the title you supplied, so audit the message that appeared rather than assuming feed copy reached the shopper unchanged.
    • Use the Product titles report to inspect original and generated titles with impressions, product clicks, CTR, cost, and average CPC, but do not mistake an observational comparison for a controlled experiment.
    • Check semantic accuracy before celebrating performance. More clicks are not useful when the title attracts the wrong buyer or changes the product promise.
    • Require the Google Ads API Developer Assistant to inspect the active schema and validate GAQL before execution. A fluent answer without those checks is weaker evidence.
    • Separate syntax, schema, account context, and business intent. An implementation can pass the first two tests while still answering the wrong question.
    • Keep an internal record connecting each AI output to its input, validation evidence, reviewer, observed result, and final decision.

    Start with the Shopping products receiving the most impressions and one API workflow where validation failures currently consume time. Establish the evidence record there, assign an owner, and make approval depend on inspectable proof. The aim is not to block automation. It is to shorten the distance between an AI-made change and your ability to understand, verify, and correct it.

    References

  • AI Training Data Licensing: A Practical Guide for Brands

    AI Training Data Licensing: A Practical Guide for Brands

    If an AI company asks to train on your content archive, the first question should not be, “What should we charge?” It should be, “What exactly would we be allowing, and do we control every item we plan to deliver?” Pricing before answering those questions is how a promising data deal becomes a rights problem.

    You need a way to separate legitimate commercial value from vague promises about “AI exposure.” The process below will help you audit the material, define the permitted uses, structure compensation, protect your brand, and decide whether the proposed license deserves to move forward.

    First determine whether your content is actually licensable

    The commercial backdrop is changing: AI labs are paying for curated, high-quality data instead of depending only on scraping. That does not make every large archive a valuable training corpus. A buyer needs content it can lawfully use, reliably process, and connect to a defined model or product objective.

    Start with a rights inventory, not a page count. Your CMS may contain material created under several different arrangements, even when all of it carries your branding. Employee-written copy, commissioned work, syndicated material, customer submissions, licensed photography, embedded media, and acquired archives can each carry different permissions.

    1. Divide the archive into meaningful content classes, such as editorial text, product data, customer questions, reviews, research records, images, audio, and video transcripts.
    2. Identify who created each class and the agreement that governs it. Record whether you own the relevant rights or merely have permission to publish it in a particular channel.
    3. Mark third-party elements inside otherwise original pages. A page you own can still contain a photograph, quotation, data table, or embedded asset that is outside your licensing authority.
    4. Separate confidential, personal, regulated, and user-submitted information from content already approved for commercial reuse. Public visibility is not proof of permission for model training.
    5. Create an exclusion list for anything with missing agreements, disputed ownership, unclear consent, contractual restrictions, or an unacceptable privacy risk.

    Do not rely on a copyright notice, a byline, or administrative access to the CMS as evidence that you can license an item for machine learning. If ownership, privacy, or consent is unclear, hold the material out until qualified intellectual-property or privacy counsel confirms how it may be used. Otherwise, you may be promising rights that your organization does not possess.

    Audit usefulness as well as ownership

    A legally clean collection can still be difficult to use. Training-data buyers benefit from records that are consistent, attributable, documented, and easy to update. Before discussing a license, examine whether you can deliver the following:

    • A stable identifier for every record, independent of a changeable page title or URL.
    • Clean primary content separated from navigation, advertising, comments, and duplicated boilerplate.
    • Reliable metadata for content type, language, publication date, revision date, author or publisher, and canonical URL.
    • A documented origin and rights basis for each content class.
    • Version history that shows what changed and when.
    • A consistent method for issuing additions, corrections, withdrawals, and deletions.
    • Clear definitions for fields, labels, categories, and any editorial annotations.
    • A manifest that lets both parties confirm exactly which records appeared in each delivery.

    This work affects both value and risk. A smaller corpus with dependable rights and metadata may be more usable than a much larger archive full of duplicates, unexplained fields, and uncertain ownership. It also lets you create separate licensing tiers instead of placing the entire archive into one irreversible package.

    Separate the AI permissions that vague contracts bundle together

    A sealed archive case connects to five separate transparent pathways, each controlled by its own valve and lock.

    “Use our content for AI” is not a workable grant of rights. A single URL can be crawled for discovery, stored in a retrieval index, used to evaluate answers, included in model training, displayed as a quotation, or transformed into another dataset. Those activities have different commercial consequences and should not be treated as one permission.

    ActivityWhat you need to define
    Public crawling and indexingWhich properties may be fetched, how often access occurs, what may be cached, and whether the purpose is search, retrieval, or another named function.
    Retrieval for generated answersWhat content may be stored and retrieved, how current it must remain, how excerpts are displayed, and whether answers include attribution and a link.
    Foundation-model trainingWhich model families, versions, products, and purposes may learn from the corpus, including whether commercial deployment is permitted.
    Fine-tuning or adaptationWhich named model or application may be adapted, who may operate it, and whether the adapted model may be transferred or reused elsewhere.
    Evaluation and safety testingWhat tests may use the data, how long test copies are retained, who can review outputs, and whether the material can later move into training.
    Output displayWhether the product may quote, summarize, reproduce, translate, or otherwise present the content, along with attribution and linking requirements.
    Synthetic or derivative dataWhether transformed records may be created, retained, combined with other datasets, sublicensed, or used after the original license ends.

    These distinctions also matter for AI search visibility. Training does not, by itself, guarantee that a model will cite your site, link to a page, use the current version, or represent your brand faithfully. If your business goal is discoverability, retrieval and output-display terms may matter more than a broad training grant.

    Turn the permission into a bounded scope

    A usable proposal should identify the parties, the data, the technology, the purpose, and the duration without forcing you to infer any of them. Require clear answers to these questions before quoting a price:

    • Which legal entity receives the license, and may its affiliates, contractors, hosting providers, or customers access the data?
    • Which records and versions are included? Does the grant cover one delivery, scheduled updates, or everything you publish in the future?
    • Which model families, checkpoints, applications, and product surfaces may use the corpus?
    • Is the use limited to internal development, or does it include commercial products offered to customers?
    • May the buyer combine the corpus with other data, create embeddings, produce annotations, or generate derivative datasets?
    • May the data or anything derived from it be transferred, assigned, sold, or sublicensed?
    • Is the license exclusive? If so, what subject, market, product, geography, language, and time period does the exclusivity cover?
    • What uses are expressly prohibited, including products designed to replace your publication, impersonate your brand, or expose restricted material?
    • What survives expiration or termination: raw files, retrieval indexes, embeddings, trained models, checkpoints, backups, derived datasets, or deployed products?

    A phrase such as “all artificial-intelligence purposes” gives the buyer flexibility by moving uncertainty onto you. Replace it with named uses and named products. If the buyer cannot identify the intended model, purpose, retention period, or downstream recipients, you do not yet have enough information to assess the risk or calculate a defensible fee.

    Price the defined scope, not the size of the archive

    There is no responsible universal price per page, word, or record. Volume affects processing costs, but it does not capture scarcity, freshness, rights quality, exclusivity, labeling, or the commercial freedom a license gives the buyer.

    Build your internal price floor from the work and exposure the deal creates. Include rights review, data cleaning, redaction, formatting, secure delivery, engineering support, update handling, reporting, contract administration, and the opportunity cost of restrictions placed on future deals. Then evaluate the buyer’s requested scope separately.

    • Uniqueness: Is the information readily available elsewhere, or does your organization hold a difficult-to-recreate collection?
    • Quality: Is the material edited, labeled, deduplicated, and accompanied by dependable metadata?
    • Freshness: Is this a historical delivery, or will your team provide continuing corrections and new records?
    • Rights assurance: How much review has been completed, and how broad a warranty is the buyer requesting?
    • Permitted use: Evaluation carries a different commercial footprint from unrestricted commercial training and deployment.
    • Downstream reach: Will one team use the corpus, or can affiliates, customers, contractors, and sublicensees benefit from it?
    • Exclusivity: What future buyers, products, markets, or partnerships would you be giving up?
    • Duration and survival: Does the buyer receive temporary access, or can trained and derived assets remain in service indefinitely?
    • Operational burden: How much continuing delivery, support, auditing, correction, and incident response will your team owe?

    Compensation can take several forms. A fixed fee is simple but must be tied to a fixed scope. A usage-based fee can expand with deliveries, records, model runs, or products, but only if the usage can be measured and audited. A minimum guarantee plus variable payments can cover your baseline work while preserving participation in broader use. Revenue sharing can align incentives, but it becomes fragile when revenue attribution is vague. Whichever structure you choose, define the measurement method, reporting schedule, audit rights, payment trigger, and treatment of disputed calculations.

    Negotiate in an order that preserves leverage

    1. Set your non-negotiable exclusions, privacy boundaries, brand protections, and prohibited uses.
    2. Obtain the buyer’s written description of the model, product, users, purpose, and data flow.
    3. Offer a specific corpus tier rather than opening the entire archive by default.
    4. Price the narrow base use first.
    5. Price additional models, products, affiliates, territories, updates, derivative data, and exclusivity as separate expansions.
    6. Require written approval and additional compensation before the buyer crosses from one tier into another.

    Watch for terms that make a seemingly attractive payment disproportionate to the rights surrendered. Common warning signs include perpetual and irrevocable use across undefined AI systems, automatic rights to all future content, unrestricted sublicensing, vague exclusivity, unilateral changes to the use case, broad warranties about third-party material, and liability that is uncapped or disconnected from your control. These are legal and financial exposure points, so have qualified counsel assess the actual agreement rather than relying on a commercial checklist alone.

    Build operational controls around the contract

    A legal, content, and technical team monitors a controlled data transfer into a locked server enclosure in a secure data room.

    A signed license is only useful if both parties can administer it. The contract may say that one content class is excluded, for example, while the export pipeline quietly delivers it with everything else. Connect each important term to a technical control, an owner, and a record that can later show what happened.

    • Attach a dataset schedule describing included content classes, excluded classes, fields, formats, languages, and delivery frequency.
    • Generate a manifest for every delivery with stable record IDs, versions, timestamps, and license status.
    • Keep approval records for additions and document every correction, withdrawal, and deletion request.
    • Specify access controls, approved storage locations, security duties, incident notification, and whether the corpus must remain segregated from other collections.
    • Require usage reports that correspond to the pricing and scope terms, including the models, products, recipients, and dataset versions involved.
    • Assign responsibility for rights questions, privacy requests, technical delivery, invoices, audits, brand issues, and termination.
    • Create a change process for new products, model families, acquisitions, corporate reorganizations, and transfers to another operator.
    • Schedule periodic reviews so a narrow experiment does not quietly become a broader production use without new approval.

    Deleting delivered files does not by itself reverse model training that has already occurred. Treat raw data, embeddings, derivative datasets, model checkpoints, future model releases, backups, and deployed products as separate post-termination states. The agreement should say which states may continue, which must stop, which must be deleted where technically applicable, and what evidence the buyer must provide. Resolve this before delivery, because the available remedies may be narrower after training begins.

    Protect AI visibility as a separate outcome

    If your objective includes visibility in AI answers, put that outcome into the deal rather than assuming it follows from training access. Consider terms covering attribution wording, canonical links, use of your current brand and entity names, update handling, correction escalation, and reporting on answer displays or citations where the product can measure them.

    You may also want a retrieval feed that remains distinct from the training corpus. A retrieval system can consult current records when producing an answer, while a trained model reflects an earlier training process. Keeping those permissions separate lets you negotiate freshness, citation, withdrawal, and link behavior without granting every training right at the same time.

    Your publishing infrastructure still matters outside the license. Maintain stable canonical URLs, explicit publisher and author information, clear publication and revision dates, consistent entity names, and structured data that agrees with the visible page. Provide machine-readable correction and withdrawal signals where your workflow supports them. Monitor priority questions to see whether AI products identify your brand, use current facts, and link to the intended page.

    Keep the three control layers distinct. Structured data describes the meaning and relationships on a page; it does not transfer content rights. Site access controls regulate automated access; they are not a substitute for negotiated permission. The license defines authorized uses between the contracting parties. Treating any one layer as if it performs all three jobs creates gaps.

    Key takeaways

    • Audit ownership, third-party rights, consent, privacy, and contractual restrictions before offering an archive.
    • Exclude uncertain material instead of representing that you control rights you may not have.
    • Separate crawling, retrieval, training, fine-tuning, evaluation, output display, and derivative-data permissions.
    • Define the receiving entities, dataset versions, models, products, purposes, duration, downstream users, and post-termination treatment.
    • Price legal review, preparation, delivery, governance, commercial scope, exclusivity, and continuing obligations rather than relying on content volume alone.
    • Connect every important contract restriction to a technical control, responsible owner, usage record, and review process.
    • Negotiate citation, linking, freshness, brand representation, and correction workflows explicitly when AI visibility is part of the business case.

    Your next move is to create a one-page licensing brief before discussing price. List the proposed corpus, excluded material, rights basis, permitted AI activities, prohibited uses, buyer entities, model or product scope, delivery schedule, duration, post-termination states, visibility requirements, and internal approval owners. Have the appropriate rights, privacy, technical, commercial, and legal stakeholders review that brief.

    If the buyer can answer those points, you can negotiate a bounded transaction. If it cannot, keep narrowing the request. The valuable asset is not merely a large body of content. It is a defensible, structured, maintainable corpus offered under terms your organization can actually enforce.

    References

  • AI Slop Detection: Prove Quality With Content Provenance

    AI Slop Detection: Prove Quality With Content Provenance

    You ran a page through an AI detector. It returned a high probability of machine-generated text. Now you have to decide whether to rewrite the page, remove it, disclose AI use, or ignore the score.

    Do not make that decision from the score alone. AI detection, slop detection, content quality, and provenance answer different questions. Treating them as interchangeable can make you discard useful work, preserve polished nonsense, or spend hours rewriting text without improving what readers receive.

    Stop asking one detector to answer four different questions

    The first step is to separate four concepts that are often collapsed into one label:

    • AI detection estimates whether a model may have generated or transformed text. It does not determine whether the text is accurate, useful, original, or fit to publish.
    • Watermark detection looks for a signal deliberately introduced during generation. A positive result indicates that a participating system likely touched the output. It does not reveal how much was generated, what was edited, or whether a qualified person approved it.
    • Slop detection is an attempt to identify low-value, repetitive, manipulative, or mass-produced material. Slop is an outcome, not an authorship category. Humans produced commodity content long before generative AI existed.
    • Content provenance is the evidence trail behind a published asset: where its claims came from, who created and changed it, what automation did, how it was checked, and who accepted responsibility for publication.

    These distinctions matter because the signals are imperfect. Text-watermark detectors generally need enough material to observe a pattern. Published benchmarks put the workable floor at roughly 100 tokens in favorable conditions, while SynthID evaluations truncate samples to 200 tokens. Short comments, titles, summaries, and rewritten excerpts may fall below that floor.

    Editing creates another limitation. Paraphrasing, translation, model chaining, and combining marked output with other text can weaken or remove a watermark. A paraphrasing attack presented at ICML 2025 achieved nearly 100% success against seven watermarking methods at a reported cost of $0.88 per million tokens. Open-weight models add a more fundamental gap: watermarking is applied by the sampling pipeline, so someone running a model independently can omit that step.

    This produces two dangerous errors. A false positive can send a strong page into unnecessary rewrites. A false negative can give weak or fabricated material an undeserved pass. Even a system reported at 94% accuracy can make consequential mistakes when it operates across enormous volumes, especially when you do not know the evaluation set, class balance, or error distribution.

    Use detection as a routing signal. A high score can send a page to closer editorial review, but it should never be the reason the page fails. Make the final decision with four questions: Is the page accurate? Does it contribute something distinct? Can its important claims be traced? Is a named person accountable for it?

    Distribution systems are reacting to low-value supply

    Generative tools have made production cheap. They have not made attention abundant. When thousands of interchangeable assets can be produced in the time previously required for one, distribution systems become stricter selectors.

    Platforms are responding at several points in that supply chain:

    The implementations differ, but the operational lesson is consistent: publishing more units does not guarantee more distribution. A system may label an asset, suppress it, remove its monetization, filter it from recommendations, or delete it as spam. The marginal cost of production may approach zero while the cost of selection keeps rising.

    None of this proves that search engines or frontier models apply a universal penalty to anything touched by AI. It shows that platforms increasingly act against repetition, manipulation, undisclosed synthetic media, and low-value supply. Do not turn that observation into an imaginary ranking factor. Turn it into a stricter publishing standard.

    A page deserves publication when it performs a specific job that another page on your site does not already perform. It should resolve the promised question, support material claims, make uncertainty visible, and give the reader a usable next step. If you cannot name its distinct contribution in one sentence, producing another variation will increase inventory without increasing value.

    Run a slop audit that measures usefulness, not writing style

    An editor reviews an unmarked digital page beside source documents, a balance scale, a toolbox, and a tray of duplicate sheets.

    Most detector-led cleanups begin at the wrong end. Teams scan thousands of URLs, sort by an AI probability, and rewrite whatever appears most synthetic. That process optimizes the detector’s reaction. It does not tell you whether the revised page deserves attention.

    Use the following audit instead.

    1. Write down the page’s job. Record the intended reader, the question or decision that brought them there, and the action they should be able to take afterward. If the job is unclear, the page cannot be evaluated coherently.
    2. Identify the distinct contribution. Look for an original observation, a precise definition, a decision rule, a useful constraint, a first-party example, a sourced fact, or a synthesis that removes work for the reader. A topic is not a contribution. Neither is a fresh arrangement of familiar sentences.
    3. Check every consequential claim. Mark statistics, dates, product behavior, legal obligations, quotations, named entities, and strong causal statements. Each one needs an appropriate basis. If the evidence cannot be recovered, soften the claim, replace it, or remove it.
    4. Inspect the page as part of a collection. Compare it with assets targeting adjacent intents. Repeated introductions, interchangeable sections, overlapping target queries, and multiple pages with no independent purpose are stronger slop indicators than a model’s preferred punctuation.
    5. Assign an accountable owner. A byline is not enough if no one checked the substance. Record who drafted, edited, verified, and approved the page. One person may fill several roles, but responsibility should still be explicit.
    6. Choose a disposition. Keep, improve, consolidate, or withdraw the page based on reader value and evidence. Do not add a fifth category called rewrite until the detector turns green.

    Your audit sheet only needs a small set of fields: URL, intended query or task, audience, distinct contribution, consequential claims, evidence status, overlap, owner, reviewer, last substantive update, and disposition. Add the detector result in a separate field if you use one. Keeping it separate prevents the score from masquerading as an editorial verdict.

    Apply the dispositions consistently:

    • Keep a page when it is accurate, distinct, appropriately supported, and still fulfills its intended job. An AI flag alone is not a reason to disturb it.
    • Improve a page when it has a useful core but withholds the information needed to act. Replace generic explanation with evidence, constraints, examples, decision criteria, or a clearer sequence.
    • Consolidate pages that repeat the same answer without serving meaningfully different intents. Preserve the strongest material, select one primary destination, and map the old URLs deliberately rather than creating another near-duplicate.
    • Withdraw material that is wrong, untraceable, misleading, or functionally empty. Preserve a recoverable copy before a bulk removal and assess redirects, inbound links, and downstream references so cleanup does not create avoidable breakage.

    The fastest diagnostic is subtraction. Remove the throat-clearing, generic benefits, predictable transition paragraphs, and unsourced superlatives. If nothing meaningful remains, the problem is not that the text sounds like AI. The problem is that the asset has no information payload.

    When something useful does remain, edit around that value. Put the direct answer near the top. Attach evidence to the claim it supports. State who the advice is for, where it stops applying, and what could change the decision. This improves the page for readers, search systems, and answer engines without trying to reverse-engineer a detector.

    Build provenance into publishing instead of adding it later

    A connected publishing workflow links research, review, version checkpoints, and a finished page with a continuous provenance chain.

    Provenance is strongest when it is captured during creation. Reconstructing it months later usually produces a folder of broken links, missing approvals, and vague memories about what the model did.

    Keep a private production record

    Create one record for each publishable asset. It can live in your content system, project tracker, or repository, but it should stay connected to a stable content ID or canonical URL.

    • Purpose: the audience, target task, search intent, and expected reader outcome.
    • People: the drafter, subject reviewer, editor, fact checker where applicable, and final approver.
    • Evidence: the sources used for consequential claims, access dates where they matter, first-party data inputs, and any unresolved uncertainty.
    • AI role: whether a model was used for ideation, outlining, drafting, transformation, extraction, classification, proofreading, or another defined task.
    • Verification: what a human checked, which claims were changed, and what could not be independently confirmed.
    • Version history: the published version, substantive updates, correction reasons, and approval status.

    Record the model’s role at a useful level of detail. AI-assisted proofreading and unsupervised generation of product specifications present different risks. A single yes-or-no field hides that difference. At the same time, do not retain raw prompts or uploaded material indiscriminately. They may contain confidential information, personal data, unpublished strategy, or licensed text. Apply the same access and retention controls you would use for other production records.

    A watermark can complement this record, but it cannot replace it. Anthropic announced machine-readable watermarks for Claude text and file output across its model access routes. Article 50 of the EU AI Act is a major reason model providers are moving toward machine-readable marking. That obligation concerns providers of generative systems; it does not make a marketer’s detector result a legal finding. If your organization provides or deploys a covered system in the EU, have qualified counsel assess the actual duty instead of relying on a content-scoring tool.

    Publish the evidence a reader can use

    Your private record establishes accountability. The public page should expose the parts that help a reader evaluate it:

    • A real byline connected to a useful author profile, not an unexplained house persona.
    • An accurate publication date and a modified date when the substance changes.
    • A concise change note when an update corrects, replaces, or materially qualifies earlier information.
    • Inline citations placed beside the claims they support.
    • A methodology note for first-party tests, calculations, surveys, or datasets.
    • An AI-use disclosure when the role of automation is material to interpretation, trust, rights, or platform policy.

    Disclosure and provenance are not synonyms. A sentence saying that AI was used is disclosure. The chain showing what it did, which evidence informed the result, who reviewed it, and what changed is provenance. You may need both, but one cannot stand in for the other.

    Structured data should mirror that visible evidence. On an Article or BlogPosting page, properties such as author, publisher, datePublished, and dateModified can make the stated identity and timing easier for machines to parse. They do not authenticate a weak byline, prove that a review happened, or turn an invented citation into evidence. Do not place claims in JSON-LD that the visible page does not support, and do not invent non-standard properties for internal provenance fields.

    This is where provenance supports AI search without becoming schema theater. A frontier model or answer engine still needs a reason to select the page. Give it compact, attributable claim-and-evidence pairs; stable names for people, organizations, products, and concepts; a direct answer before elaboration; and a visible record of substantive updates. Consolidate interchangeable pages so the strongest evidence is not scattered across thin variants.

    Provenance cannot guarantee rankings, citations, or inclusion in an AI-generated answer. It makes a more defensible asset available for selection. That is the useful goal: not proving that no machine ever touched the words, but showing why the result deserves to be trusted and distributed.

    Key takeaways

    • An AI score estimates origin patterns; it does not measure truth, usefulness, originality, or accountability.
    • Watermarks can indicate that a participating model touched enough text, but editing, paraphrasing, translation, short samples, and unmarked open-weight pipelines limit what they can prove.
    • Use detectors to prioritize human review, never as automatic publish-or-delete gates.
    • Audit each page for a defined reader job, a distinct contribution, traceable claims, collection-level overlap, and a named owner.
    • Capture sources, AI involvement, verification, approvals, and substantive changes while the asset is being produced.
    • Keep visible content and JSON-LD consistent. Structured data exposes claims to machines; it does not create provenance by itself.

    Start with five pages that matter to your business. Write down each page’s job, identify its unique contribution, trace its consequential claims, and assign an owner. You will learn more from that exercise than from rescoring your entire site, and you will have the beginnings of a provenance system that can survive the next detector, watermark, and distribution-policy change.

    References


  • AI-Generated Images in Google Search: A Publisher Playbook

    AI-Generated Images in Google Search: A Publisher Playbook

    If you publish recipes, tutorials, or any page that depends on original visuals, the immediate question is practical: can Google generate an image that answers the query before your work earns a visit?

    Do not cancel an image shoot or replace your library with synthetic assets based on one search experiment. Google stopped the recipe-image test that triggered this concern. The useful response is to make your visuals stronger as evidence, connect them cleanly to your content, and measure whether a generated answer actually changes user behavior.

    What Google tested, and what it did not establish

    Google tested AI-generated illustrations inside AI Overviews for recipe results. The generated visual compressed the cooking process from preparation to the finished dish. Google subsequently said the small experiment was no longer running.

    The company also distinguished that experiment from Nano Banana, an image-generation feature announced in July that activates when a user explicitly asks to create an image. That distinction matters. An automatically generated visual inserted into a search answer is a different product behavior from an image a user deliberately requests.

    The narrow reading is the reliable one:

    • Google is willing to test generated visuals within the search-results experience.
    • The recipe experiment described here has ended.
    • The test does not establish a general rollout for generated images in AI Overviews.
    • It does not establish how Google ranks AI-generated images published on your own site.
    • It provides no measured traffic-loss figure that you can apply to your pages.

    That last point should guide your budget decisions. A generated answer could reduce the need to click, but a stopped experiment cannot tell you how large that effect would be. Treat displacement as a hypothesis to measure, not a loss percentage to assume.

    Separate the three image questions people keep mixing together

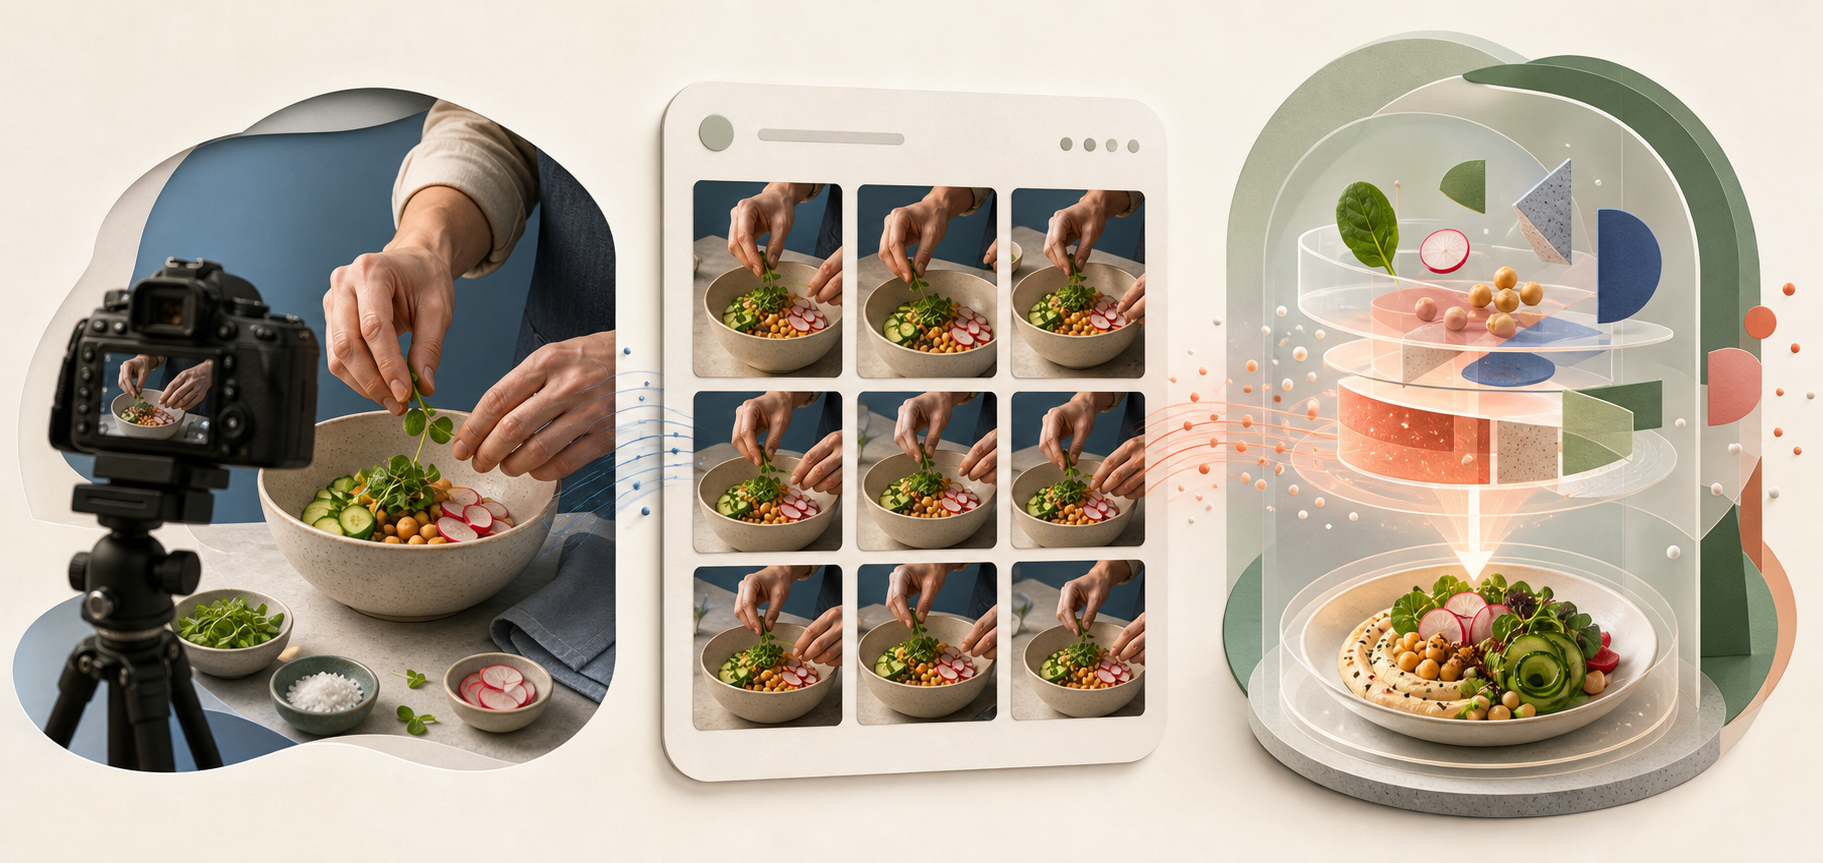
    A three-part illustration shows an original cooking photograph, image thumbnails organized for search, and visual fragments forming a newly generated dish image.

    “AI-generated images in Google Search” can describe three different situations. Confusing them leads to bad SEO decisions.

    QuestionWhat the recipe test tells youYour decision
    Will Google generate a visual inside the result?Google tested this in recipe AI Overviews and then stopped the experiment.Monitor the search surface for your important queries instead of assuming a permanent rollout.
    Will Google show or cite an image from my page?The stopped test does not answer that broader visibility question.Keep original images accessible, useful, and clearly associated with the visible page content.
    Can I publish an AI-generated image on my site?The event establishes no general ranking treatment for publisher-created AI images.Judge the asset by accuracy, transparency, reader value, and your content standards rather than an assumed SEO advantage.

    The most immediate concern is the first situation: Google owns the generated visual, while publisher citations may appear nearby. A recipe publisher affected by the experiment warned that users could mistake nearby citations for credit for the illustrations. That concern is plausible, but it should not be inflated into a claim that every AI Overview misattributes images.

    When you inspect a result, ask two separate questions: “Where did the factual instructions come from?” and “Who created this visual?” If the interface makes only the first answer clear, a citation does not necessarily give you visual attribution.

    Make original images carry evidence a summary cannot preserve

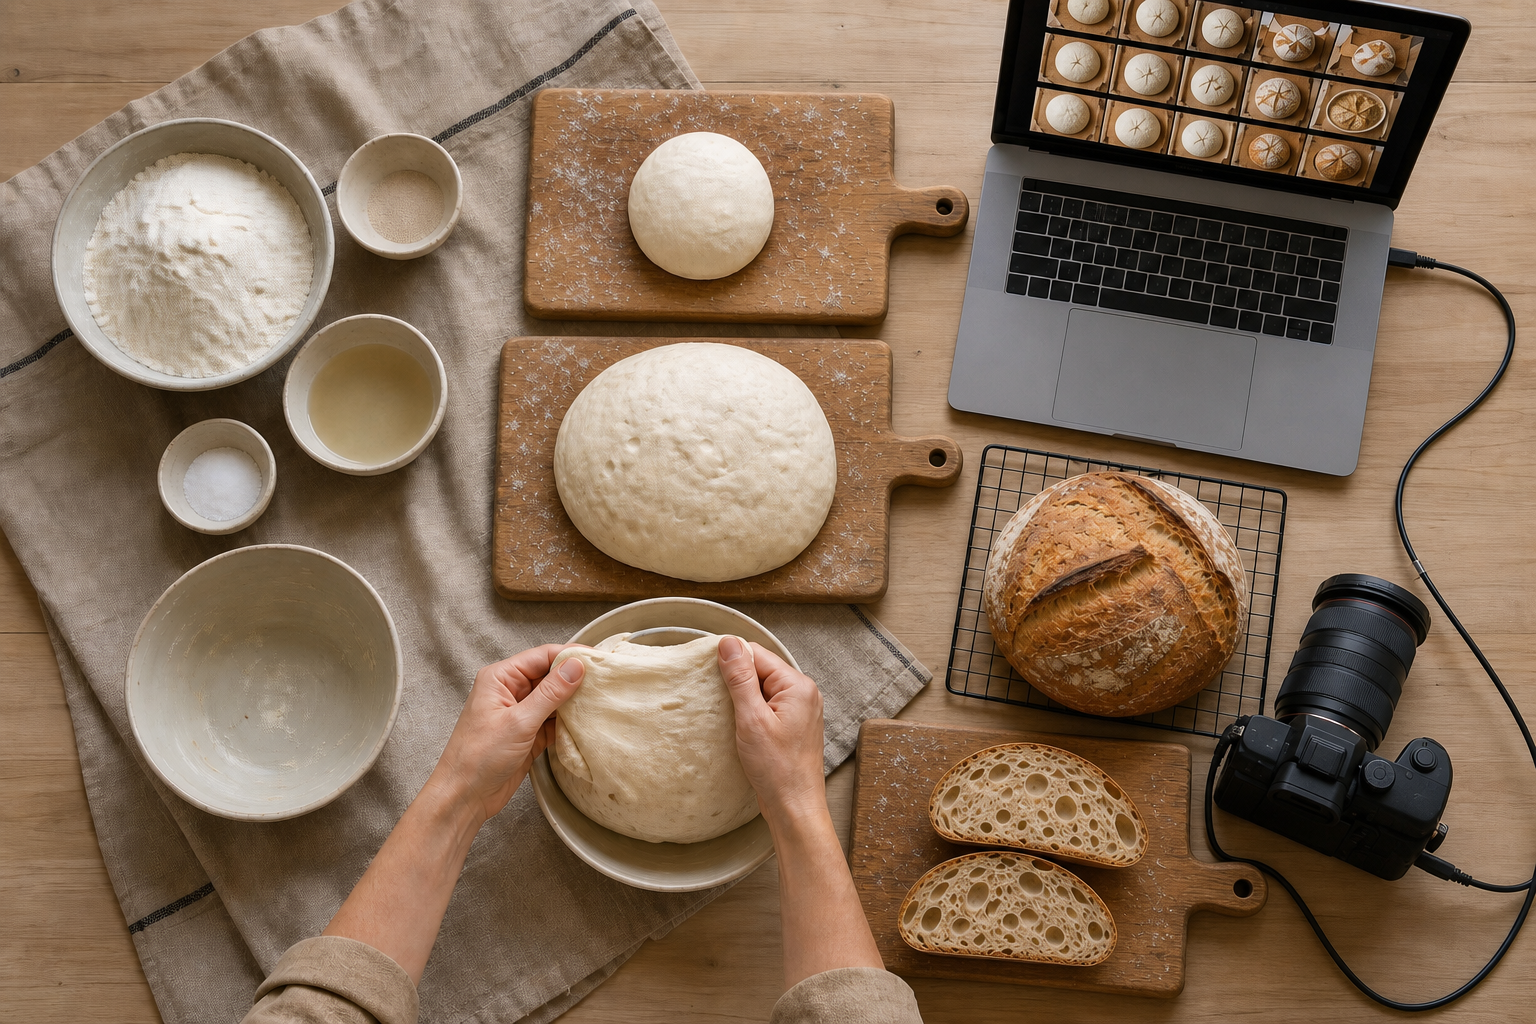
    An overhead workspace shows a creator photographing measured ingredients, dough stages, and the interior of a finished loaf as a consistent visual sequence.

    Your strongest response is not to publish more decorative images. It is to make each original visual communicate something a simplified reconstruction could omit, blur, or invent.

    • Give every image a defined job. Show a decision, condition, comparison, or outcome that the surrounding prose cannot communicate as quickly.
    • Capture consequential stages. For a recipe, that might be texture, color, consistency, assembly, or the difference between an intermediate stage and the finished result. For a repair tutorial, it might be component orientation or correct tool placement.
    • Keep the visual and written sequences aligned. If the text changes order during editing, update the image order and captions at the same time. A polished image attached to the wrong step is worse than no image.
    • Write captions that interpret the evidence. Name the stage and tell the reader what to notice. “Mixture after folding, with visible streaks remaining” is more useful than “Step three.”
    • Use accurate alt text. Describe the relevant content and purpose of the image. Do not turn alt text into a list of target keywords.
    • Keep credits in visible page context. If the photographer, illustrator, tester, or organization matters, identify that contributor where readers can see it rather than relying only on the file name.
    • Align structured data with the page. If you use Recipe or ImageObject markup, reference an image that represents the visible content. JSON-LD is a consistency layer; it is not proof of authorship or a guarantee that an image will appear in search.

    This changes the role of image production. A generic hero image decorates a page. A well-captioned process image documents a claim. When Google or another answer engine compresses the page, the second asset gives the system and the reader a clearer reason to preserve the connection to your work.

    If the image itself was generated

    An AI-generated image can be an illustration without being evidence that you performed a process, tested a product, or produced the depicted result. Keep that boundary explicit.

    • Check every depicted step against the instructions a reader will follow.
    • Look for invented ingredients, tools, components, labels, textures, and transitions.
    • Do not present a generated process scene as documentary photography.
    • Label the image’s role when the difference between illustration and documentation could affect trust.
    • Have a human editor verify the final asset in the context of the page, not only as a standalone image.
    • Replace the asset when an error could lead the reader to perform the process incorrectly; a disclaimer does not repair a misleading instruction.

    For image-led instructional content, consistency matters more than visual polish. If the prose says one thing and the image shows another, the page has an accuracy problem regardless of whether a camera, design tool, or generative model produced the asset.

    Measure exposure before changing your production budget

    A sitewide traffic change cannot tell you whether a generated image displaced a click. You need query-level evidence that the search feature appeared and page-level evidence that behavior changed.

    1. Define the exposed content group. Start with pages whose value can be compressed into a visual sequence: recipes, assembly instructions, repairs, demonstrations, comparisons, and other image-led tutorials.
    2. Record the actual result. For each important query, save the query wording, generated visual, visible citations, search language, location context, device context, and date observed. Search interfaces change, so the screenshot is part of your evidence.
    3. Annotate the first observation. Add it to the same change log you use for site releases, content updates, and search-feature changes. Without that marker, later traffic comparisons become guesswork.
    4. Compare the affected pages and queries. Use Google Search Console to review impressions, clicks, and click-through rate. Use analytics to examine entrances and the business actions that follow those visits. If your reporting does not identify the generated feature directly, pair performance data with the search-result captures.
    5. Use a relevant comparison group. Compare image-led pages where you observed the feature with similar pages where you did not. Do not use unrelated sitewide traffic as the only baseline.
    6. Inspect attribution and accuracy separately. A citation can be present while the generated visual remains confusing. Record whether the source of the instructions and the creator of the visual are each clear.
    7. Change strategy only when the pattern repeats. A generated visual appearing alongside a decline isolated to the same queries is more informative than a single screenshot or a broad organic fluctuation.

    If impressions remain stable but clicks decline only where the generated visual appears, the displacement hypothesis becomes more credible. If no such visual appears, or the decline affects unrelated pages, look for another explanation before changing your image workflow.

    Also separate visibility from value. A page can receive fewer visits without losing the same proportion of conversions, subscriptions, or qualified inquiries. Conversely, a visible citation can look positive while contributing little meaningful traffic. Track both search presence and the outcome you actually need.

    When you find an inaccurate or confusing generated visual, capture the evidence before the interface changes. Preserve the query, complete visual, citations, and relevant landing pages. Use any feedback or reporting control available in the result, then check whether ambiguity on your own page contributed to the problem. Correct your page when it is unclear, but do not rewrite accurate instructions merely to match a generated mistake.

    Key takeaways

    • Google stopped the small recipe experiment that automatically generated process illustrations inside AI Overviews.
    • The experiment was separate from image generation triggered by an explicit user request.
    • A Google-generated search visual, a publisher image shown in search, and an AI image published on your site are three different SEO questions.
    • The stopped test does not establish a general ranking penalty or benefit for AI-generated images on publisher sites.
    • Original visuals become more defensible when they document meaningful stages, match the instructions, include precise captions, and align with structured data.
    • Do not infer traffic loss from the feature’s existence. Record the result and compare affected queries and pages before changing your production strategy.

    Start with your highest-value image-led template. Audit the relationship among its instructions, visuals, captions, credits, alt text, and structured data, then establish a performance annotation you can use if generated visuals reappear. The next experiment may take a different form, but clear evidence and clean measurement will leave you in a position to respond without guessing.

    References


  • Claude AI Text Watermarking: What Content Teams Should Do

    Claude AI Text Watermarking: What Content Teams Should Do

    If Claude touches your copy anywhere between the first draft and publication, you now need a better answer than simply saying that AI was or was not used. A machine-readable watermark may remain in the text, but that signal cannot tell a client, reviewer, regulator, or editor who supplied the ideas or how much human work followed.

    The practical response is not to avoid Claude or scramble to remove the mark. It is to record how Claude was used, keep disclosure decisions separate from detector results, and make sure your team does not treat a provenance clue as an authorship verdict.

    A Claude watermark is a provenance clue, not an authorship verdict

    When a supported Claude model generates text, it embeds an imperceptible, machine-readable watermark in the response. The signal is part of the text rather than a visible label attached to the interface. Anthropic says it does not alter the meaning, quality, or readability of the output.

    That distinction matters. A person reading the copy will not necessarily notice anything different. Detection requires a tool designed to recognize the embedded signal. Anthropic has said that detection tools and technical documentation will be released, so teams should verify which detector, model, and content version are involved before relying on a result.

    Most importantly, a detected watermark only indicates that the text may have been processed by Claude. It does not prove that Claude originated the ideas, wrote the first draft, or produced every sentence. Claude could have rewritten a human draft, shortened existing copy, adjusted its tone, or performed another transformation. The signal does not reconstruct that history.

    Detector resultDefensible conclusionConclusion to avoid
    A Claude watermark is detectedThe tested text may have been processed by a supported Claude model.Claude necessarily originated the text, ideas, or claims.
    No Claude watermark is detectedThe detector did not find a detectable mark in the version tested.The text was written entirely by a human or never involved AI.

    The second row is easy to overlook. An absent watermark does not rule out AI use. The text may come from an older or unsupported model, may have been heavily edited, or may have passed through a process that made the signal undetectable. A detector can contribute evidence, but it cannot close the case by itself.

    Coverage depends on the model, not the Claude interface

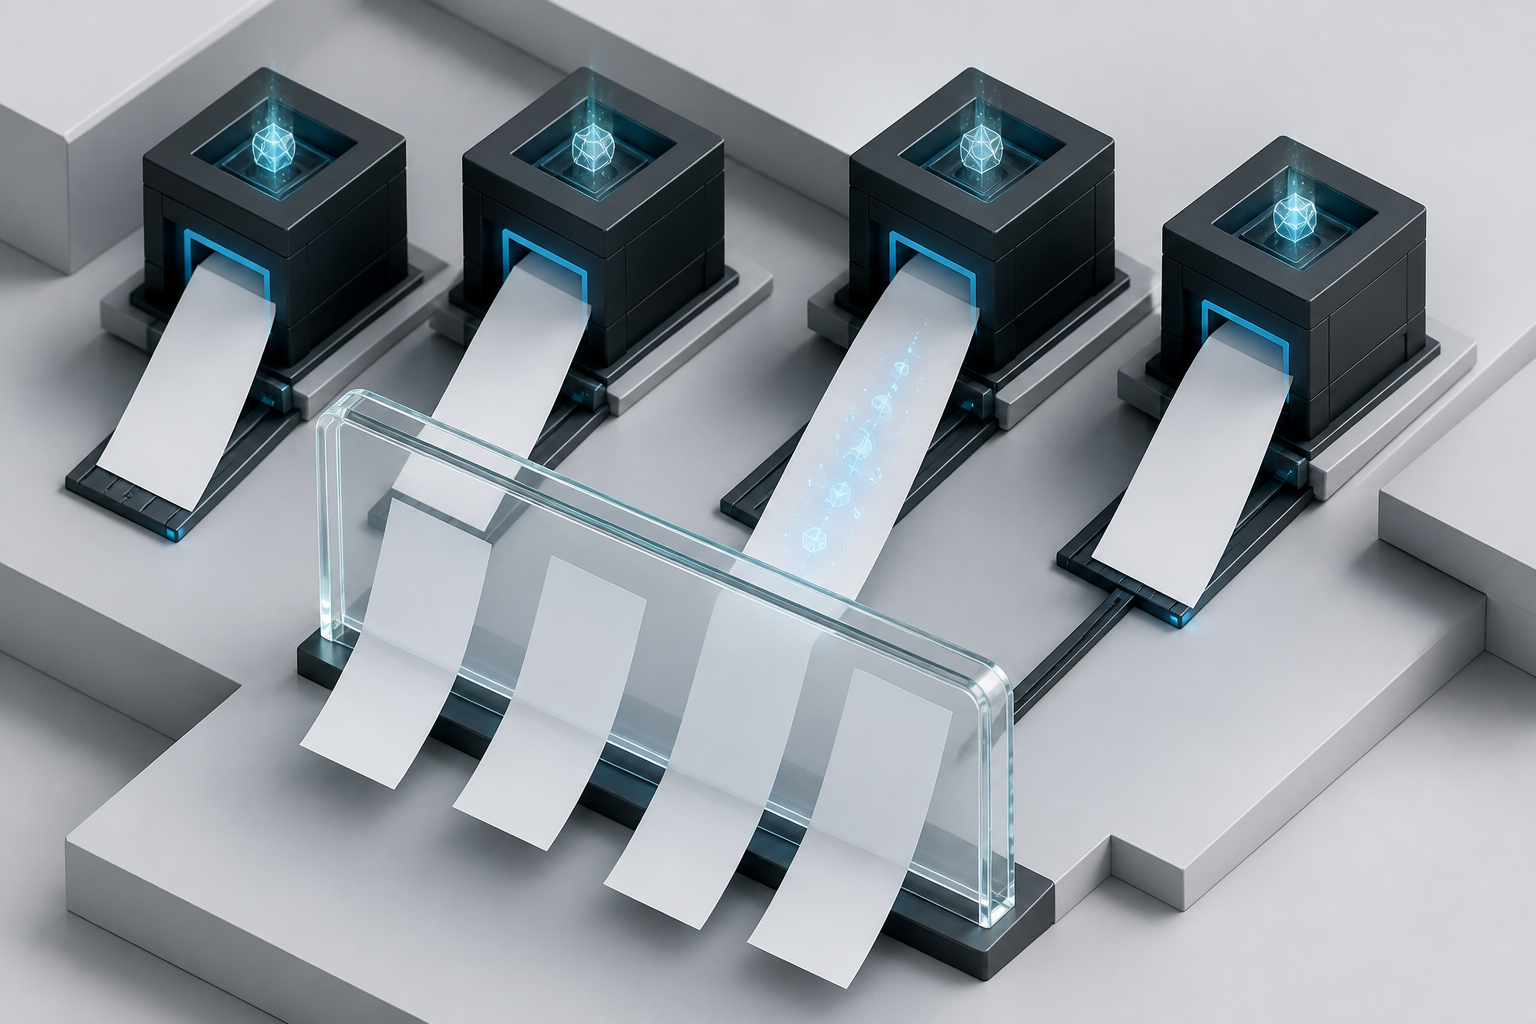
    Blank document sheets from different abstract processing cores pass through one shared glass portal, with a glowing particle trail visible in only one sheet.

    Anthropic is implementing watermarking at the model level. For supported models, the watermark is intended to appear whether the output comes through Claude, the Claude API, Claude Code, Claude Cowork, or Claude Tag. The change is tied to commitments under the European Union’s AI Act transparency code, but the rollout applies worldwide rather than only in Europe.

    Do not turn that into the broader claim that every piece of text associated with Claude must contain a detectable mark. The initial coverage concerns supported new models, and Anthropic also plans to extend watermarking to models released earlier during the transition period. Outputs can therefore differ by model even when the team informally describes all of them as Claude copy.

    If watermark status matters to a client policy, contract, or compliance process, capture the exact model identifier whenever the product exposes it. Also record the Claude surface used and the date of the interaction. A brand-level note such as AI assisted is useful context, but it is not detailed enough to explain why one output tests differently from another.

    Text and images use different provenance mechanisms

    Claude’s text watermark travels within the generated text and can remain when that text is copied and pasted. Supported PNG, JPG, and SVG files use a different mechanism: signed C2PA provenance metadata.

    Treat these as separate evidence paths. Copying text into a content management system is different from exporting, compressing, or reprocessing an image. File metadata can be stripped, so preserve the original exported asset when provenance matters. Do not assume that a derivative image will retain the same detectable record.

    Editing can change detectability without changing authorship

    The text watermark may survive some editing, but heavy revision can make it undetectable. That creates an important operational problem: the draft tested by an editor may produce a different result from the version that was first generated or eventually published.

    Always attach a detector result to the exact revision that was tested. Preserve that revision if the result could lead to a contractual dispute, disciplinary decision, or public claim. A screenshot of a detector score without the underlying text, model context, and test date is not a reliable audit record.

    Build provenance into your editorial workflow

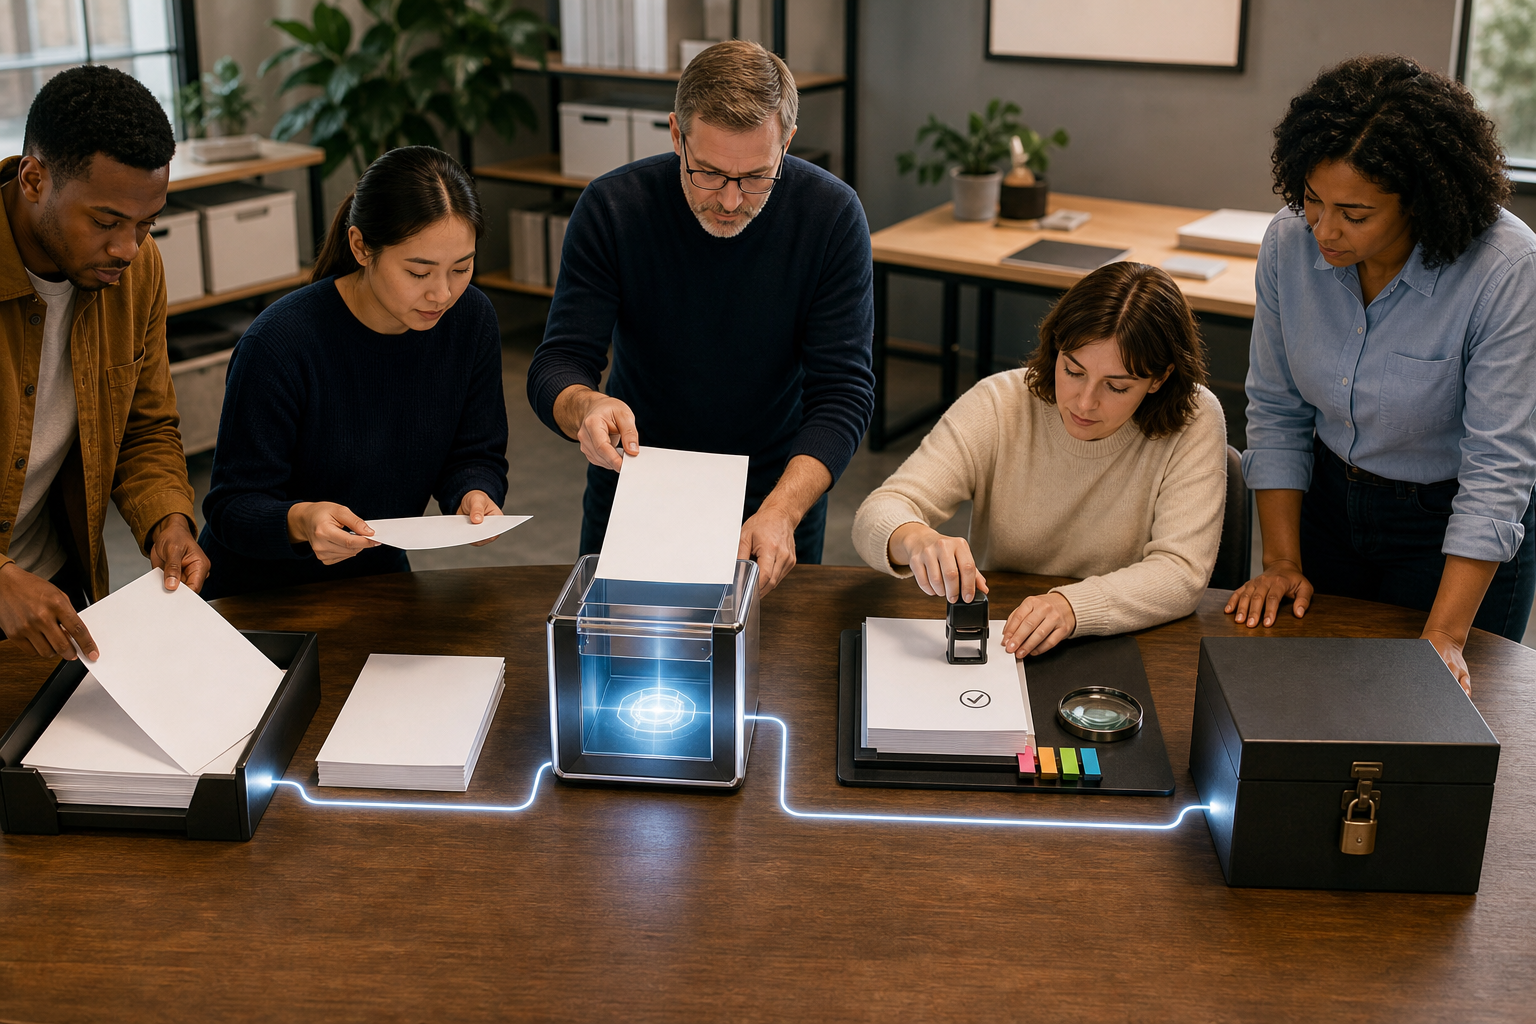
    A content team organizes blank manuscript pages across an AI processing device, a human review station, and a locked archive connected by illuminated paths.

    Watermark detection should be a backstop, not your primary record of AI use. A small provenance log will answer questions that the watermark cannot: what Claude received, what it returned, what role it played, and what a human changed before publication.

    Before publication

    1. Inventory every Claude touchpoint. Include direct chats, API calls, coding workflows, and automated content pipelines. Claude may transform copy inside a system even when the final editor never opens the Claude interface.
    2. Record the role, not just the tool. Use specific labels such as outline generation, first draft, headline options, summarization, translation, tone editing, or final copyediting. The statement Claude was used is too broad to explain authorship.
    3. Capture the model and surface when available. Model-level implementation means this detail can explain why one output contains a watermark and another does not.
    4. Keep the human review trail. Identify who checked the facts, approved the claims, and accepted the final wording. A watermark does not establish whether anyone verified the content.
    5. Apply disclosure rules independently. Decide whether disclosure is required by your contract, internal policy, platform rules, or applicable law. Do not let the presence or absence of a detectable mark make that decision for you.
    6. Retain the relevant versions. Keep the input, raw Claude output, materially revised draft, and published copy when the stakes justify an audit trail. For supported images, retain the original file containing its provenance metadata.

    You do not need to retain every brainstorming exchange forever. Match the record to the risk. A disposable list of headline ideas needs less documentation than regulated copy, a signed client deliverable, or a page containing consequential claims. What matters is that your retention policy is deliberate and consistent.

    When a detector flags published copy

    1. Preserve the exact text and result. Do not begin rewriting before you know which revision produced the detection.
    2. Confirm what the tool actually detected. A generic AI-likelihood score is not automatically evidence of a Claude-specific watermark. Check the detector’s stated capability and supporting documentation.
    3. Compare the result with your provenance log. Identify the model, workflow, source draft, and human edits associated with that content.
    4. Describe the role precisely. If Claude edited human-written copy, say that. If it produced a draft that a person later verified and rewrote, say that instead. Avoid the unsupported extremes that Claude wrote everything or that the content was wholly human-made.
    5. Escalate before making a consequential accusation. If the result could trigger a contract dispute, employment action, regulatory issue, or public correction, involve the appropriate legal or compliance professional. A watermark result alone does not establish who authored the work or whether a rule was broken.

    This process also protects the person reviewing the content. It replaces an argument over an opaque detector result with a documented account of what the tool did and what people did afterward.

    Do not confuse watermarking with SEO, AEO, or schema

    Claude watermarking is a transparency and provenance feature. Nothing in its stated purpose establishes it as a Google ranking signal, an AI-search citation factor, a spam label, or an automatic content penalty. Do not launch a rewrite project simply because supported Claude output may carry the mark.

    The watermark also is not JSON-LD. It does not describe your organization, author, product, article, or cited entities to a crawler. Adding structured data will not erase it, and removing structured data will not address it. Maintain schema because it accurately represents the visible page and its entities, not because a watermark was found.

    For SEO, AEO, and GEO work, keep the content review focused on questions the watermark cannot answer:

    • Are the factual claims correct and supported?
    • Does the page answer the reader’s actual question directly?
    • Are authorship and editorial responsibility represented accurately?
    • Do citations lead to evidence that supports the adjacent claims?
    • Does the structured data match what users can see on the page?
    • Does the final copy satisfy the organization’s disclosure policy?

    A detected mark does not make weak content trustworthy, and an undetected mark does not make strong content deceptive. Content quality, provenance, and policy compliance are related review areas, but they are not interchangeable scores.

    Key takeaways

    • A detected Claude watermark means the tested text may have been processed by a supported Claude model. It does not prove who originated the ideas or wrote the first draft.
    • No detectable watermark does not prove human authorship. Older models, unsupported models, heavy editing, and stripped file metadata can leave no detectable signal.
    • Coverage is implemented at the model level across supported Claude products, including the Claude API and Claude Code.
    • Text uses an embedded machine-readable watermark, while supported PNG, JPG, and SVG files receive signed C2PA provenance metadata.
    • Record Claude’s exact role, the model when available, the human review, and the relevant revisions instead of relying on detection as your audit trail.
    • Do not treat the watermark as a ranking factor, a content-quality score, a substitute for disclosure policy, or a form of structured data.

    Start by adding one field to your editorial record: Claude’s role in the content. Once that field is consistently completed, add the model, surface, reviewer, and retained versions needed for your risk level. That record will remain useful even when editing changes the watermark or detection tools improve.

    References


  • AI Watermarking in SEO and GEO: What Publishers Should Do

    AI Watermarking in SEO and GEO: What Publishers Should Do

    If your publishing workflow includes Gemini, Claude, or ChatGPT, the practical question is whether a machine-readable marker could affect Google rankings or citations in AI-generated answers. You need an answer that protects visibility without forcing your team into an unnecessary ban on useful tools.

    The defensible response is to treat watermarking as a measurable risk variable, not as proof of an AI-content penalty. Early B2B evidence shows a meaningful performance gap, but it does not separate the watermark from differences in authorship, judgment, and content quality. Audit what your tools actually mark, strengthen the editorial process, and test your own publishing workflow before changing it at scale.

    The performance gap is a warning, not proof of a penalty

    A controlled August 2026 comparison tracked 1,682 pages across 139 websites in four B2B industries. The unwatermarked group reached an average Google position of 6, while AI-created, watermarked content averaged position 11. The corresponding AI citation rates were 12% and 7%.

    Visibility measureUnwatermarked contentWatermarked, AI-created contentWhat was counted
    Average Google position611Position for the target keyword within three days of publication
    AI citation rate12%7%Share of pages cited for at least one target query in Google AI Overview, ChatGPT, or Claude

    Those are commercially relevant gaps. Five positions can separate prominent first-page visibility from a much weaker result, while a five-percentage-point citation difference matters when only a small portion of eligible pages earns a citation at all. The direction was also consistent across B2B SaaS, manufacturing, financial services, and healthcare.

    But the comparison cannot establish that a watermark caused either gap. Four limitations should control how you use these numbers:

    • Production method and watermark status moved together. The 1,060 watermarked pages were created with AI tools; the 622 unwatermarked pages were produced without AI. There was no otherwise identical set of pages in which only the watermark changed.
    • Content quality was not controlled through a common objective measure beyond the publisher’s professional standards. Human-created pages may have received more original judgment, better reasoning, or more careful treatment even when the AI output was reviewed.
    • Google positions were measured within three days of publication. That makes the result useful for examining early visibility, but it does not establish a durable ranking effect after indexing settles and longer-term signals accumulate.
    • The sample covered four B2B industries. It does not establish the same effect for ecommerce product pages, local service pages, news, consumer publishing, or other formats.

    This is enough evidence to add provenance to your SEO and GEO monitoring. It is not enough to tell clients that Google has confirmed an AI-watermark penalty, to rewrite an entire content library, or to attribute every weak page to its generation tool.

    A watermark is not one universal signal

    Several scanning devices examine one translucent digital document and reveal different abstract particle, color, mesh, and block layers.

    Watermarking is an umbrella term for several machine-readable mechanisms. Treating them as interchangeable will produce a bad audit because the relevant signal depends on the platform and the type of output.

    A statistical text watermark, an image-pixel signal, and signed provenance metadata are not the same artifact. A generic AI-detector score is different again: it is an inference about how text looks, not proof that a cryptographic credential or an official platform watermark is present. Copying text into a CMS, uploading an image through a media library, or seeing a low detector score does not tell you which machine-readable signal survived publication.

    Build your inventory at the output level rather than assigning one AI-generated flag to a whole URL:

    1. Record the exact generator and modality: Gemini text, Claude text, ChatGPT image, or another defined output. Note which parts of the page were human-created, AI-assisted, or directly generated.
    2. Retain the original generated file or output with its provenance information. Once an asset has passed through several editors and export tools, reconstructing its origin becomes much harder.
    3. Fetch the public version of each image after the CMS and CDN have processed it. Inspect that served asset with a verifier that supports the relevant credential rather than assuming the uploaded and delivered files are identical.
    4. For text, record the generating platform and workflow. Do not substitute the verdict of a general-purpose AI detector for platform-specific watermark evidence.
    5. Keep a private provenance log connected to the URL, author or reviewer, publication date, material revisions, and disclosure decision. This gives SEO, editorial, legal, and compliance teams one consistent record.

    This audit tells you what you are actually testing. Without it, a performance report may combine text patterns, image credentials, different levels of human involvement, and ordinary editorial quality under one label.

    Strengthen the page instead of laundering its provenance

    Removing metadata to make synthetic material appear human-created is a poor SEO strategy. It attacks a suspected signal before the causal mechanism has been established, does nothing to improve weak reasoning, and may remove useful provenance. A text-level statistical pattern may also be unrelated to the metadata attached to an image, so changing one does not neutralize the other.

    Google, Anthropic, and OpenAI have described their adoption of watermarking as a response to disclosure requirements such as Article 50 of the EU Artificial Intelligence Act and to concerns about undisclosed synthetic media. If those obligations may apply to your organization, market, or content type, obtain qualified legal guidance before removing credentials or changing disclosures. The safe operational choice is to preserve provenance while legal applicability is being assessed.

    For pages expected to rank, convert, or earn AI citations, apply a review that improves the factors obscured by the watermark comparison:

    • Assign an accountable human editor who can verify every material claim, resolve contradictions, and approve publication. A name added after the fact is not a review process.
    • Answer the target question near the relevant heading before expanding into qualifications. AI answer systems need a passage they can extract, while readers need a direct answer before supporting detail.
    • Maintain a claim ledger for statistics, product behavior, dates, named standards, and legal assertions. Each consequential claim should map to a real reference that supports that exact statement.
    • Add original examples, experience, internal data, or expert judgment only when they genuinely exist and can be defended. Never fabricate first-hand evidence to make generated copy look distinctive.
    • Remove generic transitions, repeated conclusions, unsupported superlatives, and sections that merely rephrase the query. These are quality failures regardless of whether a machine can identify their origin.
    • Check that visible authorship, publisher information, publication dates, revision dates, and primary images agree with the page’s JSON-LD. Structured data should describe what a reader can verify, not create a false provenance story.

    Schema cannot wash away an embedded signal. Use properties such as author, publisher, datePublished, dateModified, and image only when the corresponding facts are visible and accurate. Do not create a fictional human author, mislabel generated material, or change a modification date without a material revision.

    These controls do not guarantee rankings or citations. They address the largest unresolved variable in the available evidence: watermarked pages and human-created pages may have differed in thoughtfulness and judgment as well as provenance. A disciplined edit gives you better content and a cleaner test.

    Test your publishing workflow without fooling yourself

    Two matching digital manuscript workflows run in parallel through review modules, with one lane passing through an additional glowing sensor.

    If AI-assisted publishing is material to your operation, run a prospective workflow test on representative, low-risk content. The goal is to find out whether your normal AI workflow is associated with different visibility on your site. Unless a platform provides an official watermark control, the test will not isolate the watermark as the sole cause.

    1. Choose comparable queries within the same site, topic area, search intent, page type, and publishing period. Comparing an established product page on a strong domain with a new informational page on a weaker domain will tell you very little.
    2. Assign the workflow before drafting. Use a fully human-created cohort and a cohort produced through your normal AI-assisted process. Do not move difficult topics into one group after seeing the briefs.
    3. Give both cohorts the same editorial requirements: comparable briefs, claim verification, subject-matter review, internal-link treatment, template, and publication approval. Keep the standard high enough that you would be comfortable publishing either group.
    4. Log generator, modality, human contribution, reviewer, asset credentials, publication time, indexing state, internal links, later backlinks, and material revisions. These annotations help explain a gap that is not actually caused by provenance.
    5. Measure each target keyword at the same early checkpoint used in the 2026 comparison – within three days – and continue at consistent later checkpoints. Record the actual position and indexing status rather than reducing every result to page one or page two.
    6. Measure GEO separately. Enter the same target queries into Google AI Overview, ChatGPT, and Claude, then record the date, locale, account state, cited URL, and whether your page was cited at least once. AI answers can vary, so keep the measurement setup consistent across cohorts and checkpoints.
    7. Define the decision rule before reviewing the outcome. Decide which metric matters, what operational change a repeatable gap would justify, and which confounders require a retest. This prevents one surprising URL from becoming company policy.

    Interpret the result in layers. If no repeatable gap appears, retain the workflow and continue monitoring instead of treating external averages as your own. If a gap disappears after stricter editing, quality is a more plausible explanation than watermark status. If it persists across matched content and checkpoints, route the most commercially important pages through a more human-led process, preserve the provenance record, and test again. Even then, describe what you found as a workflow association rather than a confirmed algorithmic penalty.

    Do not blend SEO and GEO into one success score. Ranking position shows where a page appears in conventional results. Citation rate shows whether an answer surface selected the page as supporting material. A workflow can perform differently on those outcomes, and each failure points to a different investigation.

    Key takeaways

    • Early B2B evidence found unwatermarked content averaging Google position 6 versus position 11 for watermarked, AI-created content.
    • The same comparison found AI citation rates of 12% for unwatermarked pages and 7% for watermarked pages.
    • Those differences show correlation, not causation, because watermark status, AI involvement, and possible quality differences were not independently controlled.
    • Text watermarks, image-pixel signals, C2PA credentials, and generic AI-detector scores are different things. Audit the exact platform, modality, and delivered asset.
    • Do not strip provenance as a speculative SEO fix. Preserve credentials, check disclosure obligations, and improve the page’s evidence, accountability, directness, and structured-data accuracy.
    • Use matched cohorts and separate SEO ranking from GEO citation measurements. Your test should evaluate your real workflow, not claim to prove a universal watermark penalty.

    Start with your next planned content cluster. Add a provenance field to the brief, require a named reviewer, verify the live assets, and record early rankings and AI citations separately. That gives you evidence you can act on without hiding how the content was made or letting one preliminary correlation dictate your entire strategy.

    References


  • Google Ad Automation Updates: What Teams Should Change Now

    Google Ad Automation Updates: What Teams Should Change Now

    You are losing some control over how paid listings may be explained to shoppers at the same time that Google is adding more machine-readable controls behind the scenes. The mistake is to treat both changes as one vague wave of “more AI.” They require different responses.

    For Shopping and Product ads, your immediate job is to make the product information you control difficult to misinterpret and to document any AI-generated wording you observe. For Display & Video 360, the job is more concrete: move bulk workflows to Structured Data Files v10.1 and test every dependent parser, template and validation rule.

    Key takeaways

    • AI-generated descriptions in Shopping and Product ads remain an experiment, not a confirmed universal feature. Do not redesign an entire account around an isolated appearance.
    • Because advertisers do not directly write the generated description, product-feed accuracy, landing-page consistency and evidence capture become more important.
    • Structured Data Files v10.1 is generally available in Display & Video 360. Versions earlier than v10 have been deprecated, so bulk-management workflows need a planned migration.
    • The new SDF field for AI transparency applies to whether a YouTube video asset was created or edited using AI. It is not a control for the AI-generated descriptions being tested in paid search placements.
    • Separate release management from experiment monitoring: migrate the confirmed file format now, while observing generated ad context without making unsupported causal claims about performance.

    Separate the shipped release from the ad-copy experiment

    A specialist examines a solid automated data pipeline beside a separate translucent experiment involving an unbranded product.

    Two Google advertising changes can contain AI and still have completely different operational status.

    Structured Data Files v10.1 is generally available to Display & Video 360 users. It changes a documented bulk-management format, adds fields and resource support, and deprecates older versions. If your systems import or export SDF files, this is release-management work with identifiable dependencies.

    AI-generated descriptions beside Shopping and Product ads are different. Their appearance indicates that Google may be extending a limited Search ads experiment into Shopping placements, but Google has not announced a broad rollout. The stated purpose of the earlier experiment was to test whether extra generated context helps people make more informed decisions.

    This distinction should determine your response. A generally available file version belongs in your implementation queue. A partially observed interface experiment belongs in your monitoring log. If you reverse those priorities, you may spend days reacting to generated copy that most customers never see while leaving production bulk jobs exposed to a deprecated format.

    Make AI-generated ad context easier to get right

    An unbranded shoe is surrounded by organized product attributes that flow through an automated system into consistent shopping ad layouts.

    Shopping advertisers traditionally shape the listing through product titles, descriptions, images and related product data. An AI-generated description inserts wording that the advertiser does not directly approve. You cannot govern that output like a conventional text asset, so govern the information surrounding it.

    Start with products where inaccurate compression would have the highest consequence: items with variants, compatibility requirements, conditional promotions, subscriptions, bundles or material exclusions. The practical question is not whether the feed contains enough keywords. It is whether a short generated explanation could preserve the product’s important distinctions.

    • Resolve contradictions across controlled assets. A title, product description and landing page should not describe the same variant in materially different ways. If a promotion has conditions, keep those conditions visible wherever the offer appears.
    • Put decisive facts near the product itself. Do not depend on a shopper inferring compatibility, quantity, included components or eligibility from an image alone. State the fact plainly in the appropriate product information and on the destination page.
    • Remove stale claims before polishing prose. An elegant description cannot compensate for an expired offer, obsolete specification or mismatched landing page. Accuracy comes before style.
    • Preserve product identity. Keep identifiers and variant distinctions consistent enough that your team can connect a generated description to the exact item that triggered it.
    • Define an escalation threshold. A harmless paraphrase and a material misrepresentation are not the same incident. Prioritise wording that changes price conditions, compatibility, quantity, availability or what the customer receives.

    Do not rewrite a whole catalogue after one screenshot. The feature is still experimental, and an isolated observation does not reveal how often it appears or how Google selected that presentation. Correct clear defects in your owned data, but keep speculative changes small and reversible.

    <!– wp:heading {
  • AI-Generated Creatives in Google Ads: A Practical Control Plan

    AI-Generated Creatives in Google Ads: A Practical Control Plan

    You turned on AI-generated assets to cover more searches without writing every headline and description by hand. The hard part is not getting Google to produce usable copy. It is giving the system enough freedom to improve relevance without letting it invent an offer, weaken an audience qualifier, or claim credit for conversions that merely moved from another campaign.

    Treat AI creative as controlled production, not unattended optimization. Start where automation has a clear job, encode the claims it must not make, review what it produces, and judge the result at account level. That operating model gives you useful scale without making brand safety and performance impossible to audit.

    Give AI creative a narrow job before expanding it

    Your best-managed campaigns are rarely the safest place to begin. Their assets may reflect years of query analysis, qualification language, pinning decisions and offer testing. Replacing that accumulated control with generated variants creates a high bar: the automation must outperform deliberate human work without disrupting traffic elsewhere.

    A better starting point is a long-tail campaign that performs acceptably in aggregate but receives less creative attention. In an evaluation spanning ecommerce, B2B lead generation and B2C lead generation, AI text customization was less effective than human asset management in highly optimized campaigns but useful in the less-attended long tail. That is directional evidence, not a universal promise, but it gives you a sensible placement rule: use automation first where the alternative is limited human coverage, not where your team already has a refined message.

    The scale of that evaluation matters. Its selected campaigns were nonbrand, spent at least $20,000 per month and contained at least 100 ad groups. Those were eligibility conditions, not minimum requirements for using AI Max. If your account is smaller, do not assume the same behavior or copy those thresholds as a prescription.

    1. Select a nonbrand campaign with a stable conversion setup. Brand traffic can hide weak creative because the searcher already knows what they want.
    2. Prefer a long-tail campaign with a real coverage gap. Define that gap explicitly, such as neglected ad groups or repetitive assets that do not reflect query themes.
    3. Avoid a first test in campaigns that depend heavily on pinning. Pinning often protects message order, legal language or audience qualification. If it is essential, do not remove it merely to make the test easier.
    4. Keep final URL expansion off during the initial creative test. If copy and destinations change together, you will not know which intervention caused the result.
    5. Write down the permitted scope. Name the campaign, ad groups, markets, offers and landing pages included. Anything not listed remains outside the test.
    6. Define the stopping conditions before launch. Pause or narrow the test if generated copy misstates the offer, attracts the wrong audience, shifts valuable traffic from established campaigns or reduces account-level business results.

    Do not enable every automation in the same experiment. A test that changes copy, query matching and landing-page selection at once may produce a result, but it will not produce a useful decision.

    Turn brand policy into enforceable messaging restrictions

    Abstract advertising asset cards pass through policy gates, while noncompliant cards are diverted into a separate review bin.

    AI Max text customization can tailor assets to the keywords in each ad group. That flexibility is also the risk: auto-created assets can promote products, services or promotions that the advertiser does not offer. A general instruction to follow the brand voice is too vague to prevent that failure.

    Messaging restrictions should translate your approval policy into explicit boundaries. The fastest way to find those boundaries is to make the model fail deliberately before Google writes on your behalf.

    1. Build an approved-claims inventory. List the products and services you sell, the audiences you serve, the promotions currently available, the geographic limits and any wording that must appear.
    2. Generate ordinary sample ads. Use Gemini to produce initial assets from the approved inventory. Mark anything that is factually wrong, commercially misleading or off-brand.
    3. Red-team the message. Prompt the model to become overly promotional, make stronger promises, broaden the audience and invent adjacent offers. The goal is to expose plausible copy that your team would reject.
    4. Convert each failure pattern into a restriction. Write a direct rule for the category, not just the rejected sentence. For example: do not imply guaranteed outcomes; do not mention discounts unless an approved promotion is supplied; do not advertise services outside the approved list.
    5. Run the hostile prompts again. Keep refining the restrictions until the generated set remains within your approved boundaries, including when the prompt pressures the model to overstate the offer.
    6. Assign an owner and version the restrictions. Record who approved them and which campaigns use them. When the offer or brand policy changes, update the restrictions before expanding automation.

    Audience qualification deserves its own rules. A B2B ad often needs to discourage consumers while attracting business buyers. If phrases such as “for businesses,” an industry requirement or another qualifier are essential and accurate, protect them. A higher conversion count is not an improvement if the generated copy removes the language that kept unsuitable leads out.

    Restrictions are preventive controls, not approvals. They reduce the range of unacceptable output, but every generated asset can still fail in a way you did not anticipate. That is why the next layer is asset-level review.

    Review every asset, then measure the whole account

    Inspect generated copy before it earns material delivery

    Generated assets can be easy to miss in the interface. When looking for them, change the default filters so the ad is included; that option is not selected by default. Review newly created assets repeatedly while the test is active and remove unacceptable variants before they collect substantial impressions.

    This is not a ceremonial check. In the monitored ecommerce and B2C activity, excluding the B2B result, reviewers removed approximately 19% of auto-created assets. That percentage should not be treated as an industry benchmark, but it demonstrates why an enabled feature cannot also be an assumed approval.

    • Offer accuracy: Does the company sell exactly what the asset promises?
    • Claim support: Could the team substantiate every benefit, comparison and outcome?
    • Promotion validity: Is the price, discount or time-sensitive offer real and currently available?
    • Audience fit: Does the wording retain the qualifiers that separate suitable buyers from unsuitable clicks?
    • Destination alignment: Can the landing page fulfil the expectation created by the ad without making the visitor search again?
    • Brand acceptability: Would the team approve this language if a person had written it?
    • Disclosure status: If the asset is an AI-generated or AI-modified image or video, has its provenance and required labelling been recorded?

    Separate campaign performance from incremental growth

    A successful-looking automated campaign can be a redistribution mechanism. In the ecommerce evaluation, AI Max initially appeared highly successful, but deeper analysis found that it was taking impressions, clicks and conversions from other campaigns while total account revenue declined. The local dashboard improved while the business result worsened.

    Review levelWhat to inspectWarning signResponse
    AssetGenerated headlines and descriptionsUnsupported claims, invalid offers or lost qualifiersRemove the asset and strengthen the matching restriction
    Search termQueries receiving impressions, clicks and conversionsValuable intent moves from a controlled campaign into the automated oneImprove query routing with keywords and negatives
    Campaign familyResults across the test campaign and campaigns serving similar demandThe test gains while established campaigns lose comparable volumeTreat the gain as possible cannibalization and narrow the scope
    AccountTotal revenue or qualified lead outcomesThe automated campaign improves while the account declinesDo not declare a win; correct routing and rerun the test

    When search-term overlap appears, use the observed data to restore control. In the ecommerce account, the response was to add relevant search terms as keywords, introduce more negative keywords and use audience lists to slow cannibalization before rerunning the test. Those controls are not a guaranteed recipe for every account. They illustrate the right sequence: diagnose where demand moved, change routing, and then test again rather than accepting campaign-level attribution at face value.

    For ecommerce, keep account revenue in view. For lead generation, inspect qualification and downstream outcomes, not just submitted forms. In both cases, ask the decisive counterfactual: did the AI creative create additional business, or did Google move existing demand into a campaign that could claim it?

    Make AI disclosure a workflow, not a last-minute badge

    Two marketers review blank creative cards at a light table as approved assets are linked to provenance markers and campaign containers.

    Creative governance now includes provenance. Google is gradually rolling out AI content labelling across Google Ads, Display & Video 360, Campaign Manager 360, Merchant Center and Google Ads Editor. Advertisers can add text or visual disclosures to eligible image and video creatives or use the platform’s AI label setting. Labelled assets display an AI disclosure icon where they appear.

    Google may also label certain assets created with its own AI tools automatically. Those platform-applied disclosures do not violate the existing creative policies that prohibit text overlays or watermarks. Neither point means that every AI-assisted asset will be identified for you, especially while availability is rolling out gradually.

    1. Record the asset’s origin. Mark each image and video as human-created, AI-generated or AI-modified.
    2. Record the production path. Keep the tool, responsible owner and approval status with the asset so the team can answer how it was made.
    3. Map where it will run. List the campaigns and markets using the asset; disclosure obligations can vary by jurisdiction.
    4. Apply the relevant label. Use the built-in setting or an eligible text or visual disclosure as appropriate, then verify the status in the available AI Label field and the rendered ad.
    5. Retain the approval record. If an asset is revised, update its provenance and reassess whether its disclosure status changed.

    The built-in control is not a legal safe harbor. It was designed to help advertisers address emerging transparency requirements in markets including the European Union, India and New York, but using Google’s AI label setting alone does not guarantee compliance. If your campaigns create regulatory exposure, obtain jurisdiction-specific legal guidance instead of treating a platform toggle as the final interpretation of the rules.

    Keep the four controls separate. A disclosure explains that AI was involved. A messaging restriction limits what the system may say. Human review decides whether a particular asset is acceptable. Account-level measurement decides whether the automation creates incremental value. None can substitute for the others.

    Key takeaways

    • Start AI-generated copy in a nonbrand, long-tail campaign where creative coverage is limited, not in the account’s most carefully optimized campaign.
    • Test creative separately from final URL expansion so you can attribute the result to the asset change.
    • Red-team your own offer, then convert every unacceptable claim, promotion and audience expansion into a messaging restriction.
    • Review auto-created assets explicitly and measure search-term movement, related campaigns and total account outcomes before calling the test successful.
    • Track the provenance of AI-generated and AI-modified images and videos; use Google’s labels where applicable, but verify legal requirements separately.

    Your next move is small: choose one bounded long-tail campaign, write its prohibited claims and audience rules, and record the account-level outcome that must improve. Do not expand AI creative until the generated assets pass review and the account shows genuine additional value rather than rearranged attribution.

    References


  • AI Ad Products Are Expanding Faster Than Disclosure Rules

    AI Ad Products Are Expanding Faster Than Disclosure Rules

    AI advertising is developing along two connected tracks: platforms are adding tools that make campaigns easier to create and manage, while also deciding how much people should be told about the technology behind an ad.

    Google’s creative-origin disclosures and OpenAI’s expanding ChatGPT Ads product show why transparency cannot be reduced to a single label. Users need to recognize paid placements, understand when AI shaped the creative, and know who remains responsible for the resulting claims.

    Key takeaways

    • Google is adding a “How this ad was made” section to My Ad Center for ads across Search, YouTube, and Discover, according to CrushPress.AI’s coverage.
    • Google will automatically disclose the use of its own generative AI ad tools, but advertisers using third-party AI tools will have control over disclosure, subject to local requirements.
    • ChatGPT Ads is adding audience, reporting, draft, and format capabilities, while its suggested ad drafts reportedly reuse website metadata rather than generating new copy or images with AI.
    • Effective transparency needs to distinguish the presence of an ad, the origin of its creative assets, and responsibility for its content.

    Advertising transparency now has two separate jobs

    A digital ad card is shown between symbols for paid placement and AI-assisted creation, with a human advertiser standing behind it.

    The first job is placement transparency: making it apparent that a recommendation, card, or other interface element is advertising. CrushPress.AI reported that OpenAI’s refreshed static ChatGPT ad card uses a clearer “Ad” badge, a more readable presentation, and larger visuals. That addresses the commercial status of the content rather than how it was produced.

    The second job is production transparency: explaining whether generative AI created or modified the ad creative. According to CrushPress.AI’s Google coverage, users will be able to open the three-dot menu or information icon on an ad and find a dedicated “How this ad was made” section inside My Ad Center. The disclosure is expected to cover ads on Search, YouTube, and Discover.

    These signals answer different questions. An ad badge tells a person why content is being shown commercially. A creative-origin disclosure explains something about how that content came into existence. A platform can provide one without fully providing the other, so treating either signal as complete transparency would leave an important gap.

    Google’s disclosure model mixes automation and advertiser choice

    Google’s reported approach creates two disclosure paths. When an advertiser uses Google’s own generative AI advertising tools, Google will automatically place the relevant information in My Ad Center. Because the platform can observe the use of its own creation tools directly, disclosure can be built into the workflow.

    The process is less uniform when creative comes from elsewhere. CrushPress.AI reported that advertisers using third-party AI tools will control whether to disclose that use. Depending on local requirements, an AI label may also appear on the ad itself, either automatically or after the advertiser uses the available control.

    This split reveals a central difficulty for AI ad governance: platforms have stronger evidence about activity within their own systems than about assets imported from outside. A dependable program therefore needs both technical detection or provenance signals and accurate declarations from advertisers.

    Google already embeds imperceptible signals, including SynthID, in material created with its generative AI tools, according to the same coverage. The source also noted that Google has required election advertisers to disclose synthetic or digitally altered content in political ads under a policy introduced in 2023. Those measures offer context for the new My Ad Center information, but they do not make all disclosure scenarios identical.

    Product automation does not always mean generative creation

    OpenAI’s reported suggested-ad workflow illustrates why precise language matters. When a campaign needs broader content coverage, ChatGPT Ads Manager may offer an “Add new ad” option that prefills an image, title, and description from existing website metadata. The advertiser can then review, edit, and assign the draft to a campaign and ad group.

    CrushPress.AI emphasized OpenAI’s statement that this feature does not generate new copy or imagery with AI. It is automated assembly, according to the description, rather than generative production. Labeling every automated advertising workflow as “AI-generated” would therefore obscure meaningful differences in how assets are sourced and transformed.

    That distinction becomes more important as the product develops. The reported ChatGPT Ads updates also include an overview tab for account health, recommended tasks and performance trends; audience-list uploads containing at least 25,000 users; audience inclusion or suppression; and ad-group bid multipliers. These are campaign-management capabilities, not evidence that the visible creative was generated by AI.

    The same report said ChatGPT Ads had expanded to Japan and South Korea. As an advertising system reaches more markets and adds targeting and optimization controls, transparency must cover the entire experience without collapsing targeting, workflow automation, generative creation, and sponsored placement into one ambiguous category.

    A practical transparency standard for advertisers

    A marketing professional reviews an advertisement through transparent layers representing sponsorship, AI involvement, and human approval.

    Advertisers can prepare for this environment by maintaining an internal record of where each asset originated, which tools materially changed it, who approved it, and which platform disclosures were selected. That record is a general operational safeguard rather than a platform-specific requirement, but it can support consistent decisions when rules differ by market, format, or creation tool.

    Teams should also separate three reviews. The first confirms that a placement is visibly identified as an ad. The second determines whether the creative requires an AI-origin disclosure. The third checks the underlying claims, identity, and offer for accuracy. Google’s existing prohibition on misleading or deceptive advertising still applies regardless of whether AI was involved, according to CrushPress.AI’s report; provenance information does not validate an ad’s message.

    Clear terminology will be as important as the controls themselves. “AI-assisted,” “AI-generated,” “AI-modified,” and “assembled from existing metadata” describe different processes. Platforms that make those distinctions understandable can give users useful context without implying that automation alone determines whether an advertisement is trustworthy.

    As AI advertising products mature, the strongest transparency systems will connect visible ad identification, reliable creative provenance, and continuing advertiser accountability. The next test is whether those elements remain coherent as more creation tools, formats, and markets enter the workflow.

    References