Tag: AI Transparency

  • AI Advances in Healthcare: A Practical Evaluation Guide

    AI Advances in Healthcare: A Practical Evaluation Guide

    You’ve got a healthcare AI announcement in front of you and a decision to make: is this a meaningful advance, a promising demonstration, or a polished claim that has outrun its evidence? The model’s reputation won’t answer that question.

    You need to connect the technology to a care task, the care task to evidence, and the evidence to a controlled workflow. That framework works whether you’re evaluating a product, planning adoption, writing clinical content, or deciding which claims deserve visibility in search and AI-generated answers.

    The useful unit of progress is the care task

    The potential of healthcare AI extends from diagnostics to patient care. That range is also why broad statements about AI transforming healthcare tell you so little. Diagnostics, documentation, scheduling, patient education, and clinical decision support are different jobs with different users, failure modes, and consequences.

    Start by reducing every claimed advance to one task statement. It should identify five things:

    1. User: Who receives or acts on the output: a patient, clinician, administrator, researcher, or another system?
    2. Input: What information does the system receive, and where did that information come from?
    3. Output: Does it draft text, summarize a record, flag a case, rank options, predict an event, or initiate an action?
    4. Decision: What real decision could change because of the output?
    5. Failure consequence: What happens if the output is incomplete, late, biased, misleading, or wrong?

    For example, AI that summarizes clinician-authored encounter notes for clinician review is an assessable use case. AI that improves patient care is not. The first statement identifies a user, input, output, and review step. The second jumps directly to an outcome without showing the mechanism.

    Once the task is clear, ask what actually improved. An advance might reduce the time required for a task, make documentation more consistent, identify relevant cases, expand access, or reduce avoidable administrative work. Those are separate claims. Evidence for faster drafting does not establish better diagnosis, and stronger performance on a technical evaluation does not automatically establish better patient outcomes.

    This distinction should shape your language. If a system generates possibilities for a qualified professional to consider, say that. Don’t say it diagnoses. If it drafts an explanation that must be reviewed, call it a draft. Don’t describe it as patient guidance delivered independently. Precise verbs prevent a capability claim from quietly becoming a clinical claim.

    Separate assistance, recommendation, and action
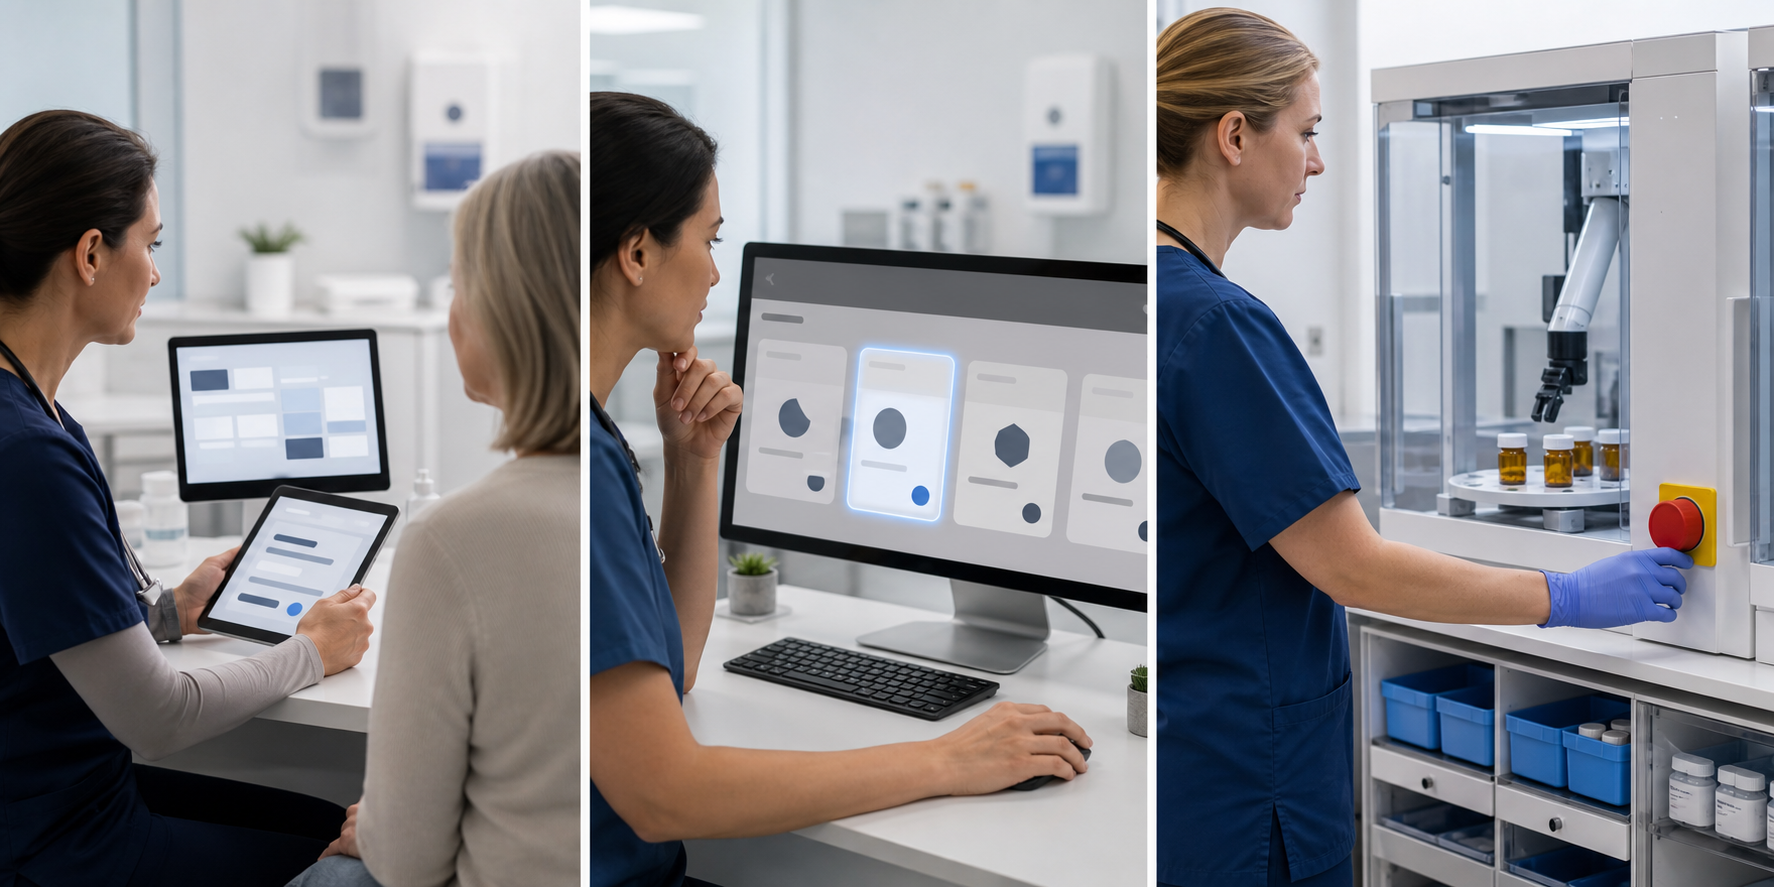
    A three-part clinical scene shows AI organizing information, presenting a recommendation, and operating supervised medication equipment.

    Healthcare AI systems can occupy very different positions in a workflow. A useful first classification is whether the system assists, recommends, or acts. This is an evaluation framework, not a regulatory classification, but it quickly exposes how much control the workflow needs.

    ModeWhat the AI doesHuman control to verifyClaim discipline
    AssistsDrafts, organizes, retrieves, or summarizes informationA person can inspect, edit, reject, and replace the outputDescribe the task support, not an unmeasured care outcome
    RecommendsFlags cases, ranks options, or proposes a next stepA qualified person evaluates the recommendation before it affects careName the intended user, decision, evaluation context, and known limits
    ActsTriggers, routes, schedules, or changes something in the workflowThe system has defined boundaries, escalation paths, and a way to stop or reverse inappropriate actionExplain exactly what is automated and where human oversight remains

    Risk does not begin only when AI acts autonomously. An incorrect summary can carry an old fact forward. A fluent explanation can make uncertain information sound settled. A recommendation can attract more trust than its evidence deserves. Human review is not a meaningful safeguard unless the reviewer has the information, authority, time, and interface needed to catch a problem.

    Inspect the control itself. A reviewable workflow should make the AI-generated material identifiable, preserve relevant input context, let the reviewer edit or reject the output, provide an escalation route, and record what was accepted or changed. A button labeled approve is not sufficient if the reviewer cannot see how the output was produced or cannot safely disagree with it.

    The closer an output gets to diagnosis, medication, treatment, or urgent-care decisions, the more explicit these boundaries must become. Patient-facing AI must not be presented as a substitute for a qualified healthcare professional. If an output conflicts with a clinician’s instructions or a medication label, the safe next step is to contact the appropriate clinician or pharmacist rather than act on the AI response. Situations involving possible immediate harm require established local emergency channels, not another chatbot prompt.

    Match every claim to its actual level of evidence

    A compelling output proves that the system produced a compelling output once. It does not establish reliability, clinical usefulness, or patient benefit. To avoid that leap, place evidence on a ladder and stop at the highest rung the evaluation genuinely supports.

    1. Capability evidence: The system can produce the intended kind of output in selected examples.
    2. Task validation: Its outputs have been evaluated against a predefined reference, process, or reviewer judgment for the stated task.
    3. Workflow validation: Intended users have used it under conditions that resemble the intended setting, including realistic inputs and handoffs.
    4. Outcome evidence: The evaluation measured the patient, clinical, or operational outcome named in the claim rather than using a technical metric as a substitute.
    5. Post-deployment evidence: Performance, failures, overrides, and changes continue to be monitored in actual use.

    Each rung answers a different question. Task validation may show that a system performs a bounded function well. Workflow validation asks whether people can use that function safely and effectively. Outcome evidence asks whether the claimed real-world result occurred. Post-deployment monitoring matters because users, data, interfaces, prompts, retrieval material, and models can change after an initial evaluation.

    When you inspect an evaluation, ask questions that reveal what the headline leaves out:

    • Which population, language, care setting, and task were represented?
    • What counted as success, and was that definition chosen before the results were reviewed?
    • What was the comparison: no tool, the existing workflow, another system, or an expert judgment?
    • Which failures occurred, who was affected, and which failures carried the greatest clinical consequence?
    • Were intended users evaluating the output, or was the system assessed only outside the care workflow?
    • What happens when information is missing, contradictory, unusually phrased, or outside the intended scope?
    • Which model, configuration, retrieval material, interface, and review process produced the result?

    If those details are unavailable, treat that absence as an evidence limit. Don’t fill the gap with a stronger adjective. Promising can be appropriate for an early capability. Validated needs a stated task and context. Effective should identify the outcome that improved. Safe is usually too broad to stand alone because safety depends on the user, setting, controls, and type of failure being considered.

    Keep the evaluated system distinct from the underlying model. A healthcare AI implementation may include a model, prompts, retrieval sources, interface rules, access controls, escalation policies, and human review. Changing any of those elements can change the behavior that users experience. Record them together, and retest material changes instead of assuming that an earlier result transfers automatically.

    Test the workflow around the model, not just the model
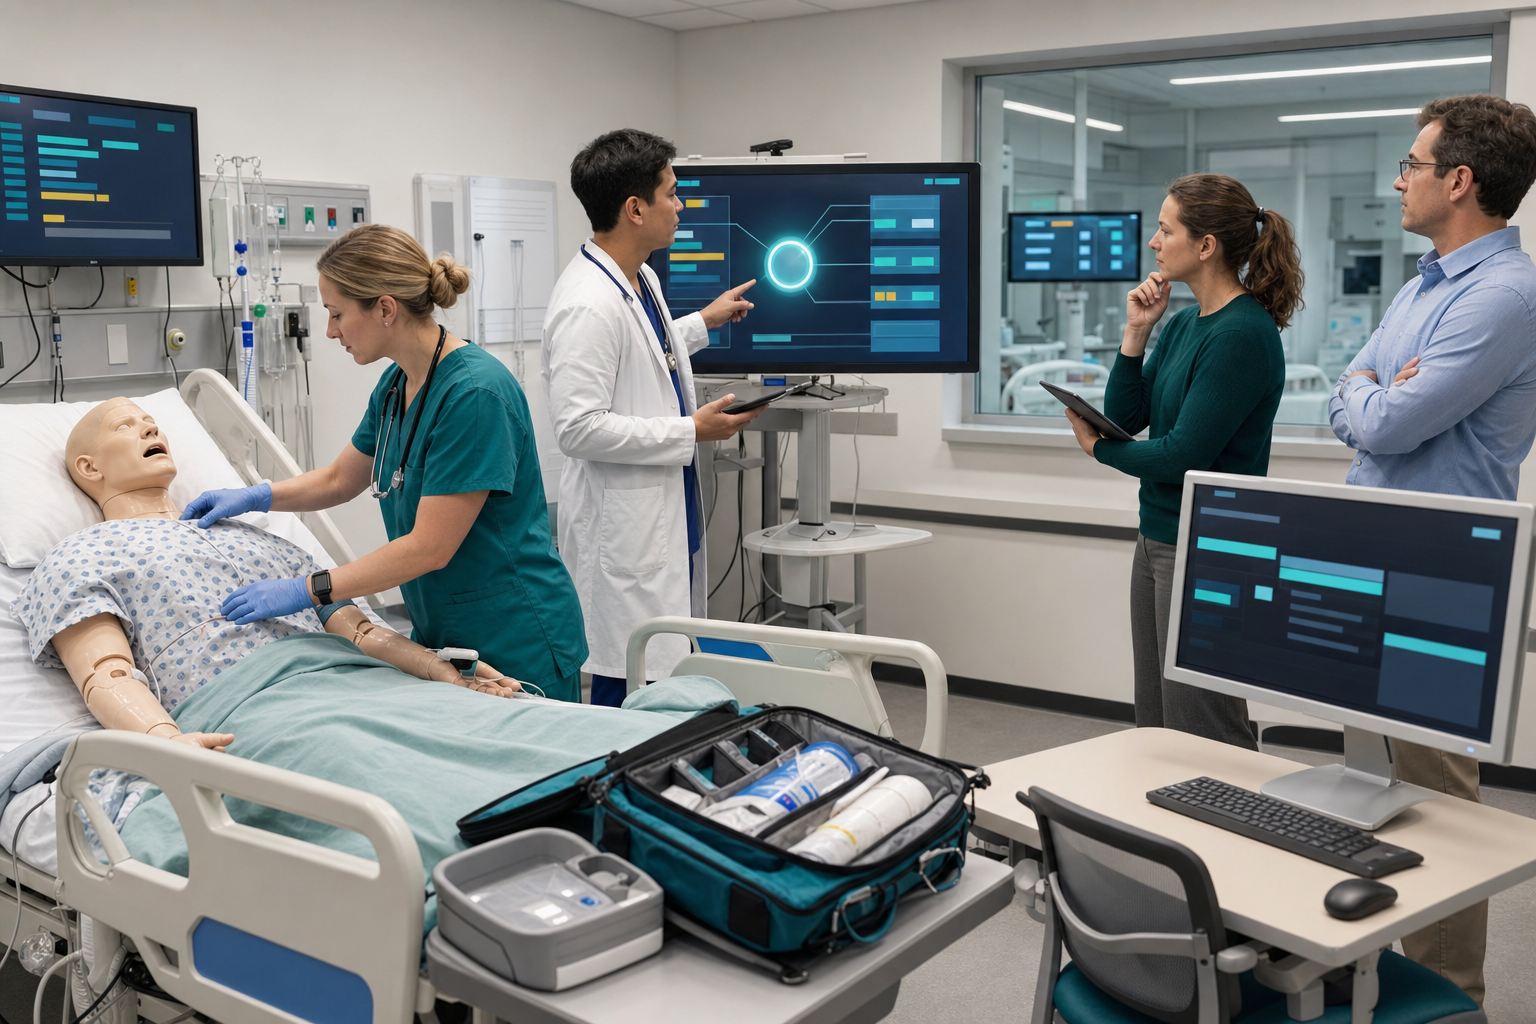
    A nurse, physician, informaticist, and human-factors specialist test an AI-supported process with a training mannequin in a clinical simulation room.

    A technically capable model can still fail as a healthcare system. The failure often appears at the handoff: the wrong information enters, the output reaches the wrong person, a warning arrives too late, or nobody owns the exception. Evaluate the full route from input to consequence.

    Use these six gates before treating a capability as deployment-ready:

    1. Context match: Confirm that the intended users, population, language, setting, and task resemble those represented in the evaluation.
    2. Input control: Define which data the system may receive, how missing or conflicting information is handled, and who is responsible for input quality. Never place identifiable patient information into an AI tool that your organization has not approved for that use.
    3. Output routing: Specify who sees the result, when they see it, what supporting context accompanies it, and whether it can alter a decision before review.
    4. Human factors: Verify that users can understand the output’s role, identify uncertainty, disagree with it, and complete the task without becoming dependent on it.
    5. Failure response: Decide in advance how the workflow handles false alarms, missed cases, unsupported statements, system outages, and outputs outside the intended scope.
    6. Change monitoring: Assign an owner to watch failures, overrides, complaints, model or configuration changes, and performance drift after launch.

    Run the workflow with difficult cases before routine ones create false confidence. Test missing context, ambiguous requests, contradictory records, out-of-scope questions, and attempts to bypass the intended process. The goal is not to prove that the system never fails. It is to learn whether failures are visible, containable, recoverable, and routed to someone able to respond.

    Define a stop condition as well as a success condition. A responsible deployment plan says who can pause the system, which events trigger review, what work continues without it, and how affected users are notified or corrected. If nobody has authority to stop an unsafe workflow, the oversight plan is incomplete.

    Publish healthcare AI claims that can survive scrutiny

    Healthcare AI content has to work for a person assessing risk and for search or answer systems extracting a concise statement. Both benefit from the same thing: explicit claims with their qualifications attached. A vague page cannot become trustworthy through optimization, and structured data cannot turn unsupported language into evidence.

    Put the central claim in a form that can stand on its own: the system, intended user, task, setting, oversight, and demonstrated evidence level should appear together. Put an important limitation in the same sentence or adjacent paragraph, not in a distant disclaimer that disappears when the sentence is quoted.

    A useful claim pattern is: [System] helps [intended user] perform [task] in [setting]. [Reviewer or control] checks [output] before [decision or action]. Current evidence establishes [capability, task performance, workflow performance, or outcome], while [important limitation] remains unresolved.

    Before publication, apply these editorial thresholds:

    • Can generate or summarize: Show that the capability was tested with the stated input and output. Don’t convert generation into an accuracy or outcome claim.
    • Supports review or decision-making: Identify the qualified user, the decision being supported, the review step, and the context in which the support was evaluated.
    • Improves a workflow: Name the measured operational result and the workflow used for comparison. Don’t use an isolated model score as proof of workflow improvement.
    • Improves diagnosis or patient outcomes: Reserve this language for evidence that measured the named diagnostic or patient outcome in the defined population and setting.
    • Is safe: Replace the blanket claim with the risks evaluated, controls used, limitations found, and context covered. No system is safe independently of its use.

    Keep vendor, model, product, and care provider roles separate. OpenAI, Google, and Anthropic may be relevant to the underlying AI landscape, but a familiar model developer’s name does not establish that a particular healthcare implementation is clinically validated. State who built the model, who configured the system, who operates the workflow, and who is responsible for clinical review whenever those roles differ.

    Your maintenance process matters as much as the launch page. Keep a claim inventory linking each public statement to its evidence, evaluated configuration, owner, review date, limitations, and correction route. When a model, prompt, retrieval source, interface, intended use, or oversight process changes, review the dependent claims. Otherwise, accurate content can become misleading while its publication date and search visibility remain unchanged.

    Use schema and other machine-readable markup to describe what the visible page actually says. Keep the evidence level, intended use, limitations, author or reviewer responsibility, and update history readable on the page itself. Machines may extract the markup, but people still need enough context to judge the claim.

    Key takeaways

    • Judge healthcare AI at the level of a defined care task, not the reputation of a model or developer.
    • Separate systems that assist, recommend, and act; each position requires a different degree of control and claim restraint.
    • Don’t treat a demonstration, task evaluation, workflow evaluation, outcome evaluation, and monitored deployment as interchangeable evidence.
    • Evaluate inputs, handoffs, human review, failure response, and change control alongside model performance.
    • Keep qualifications beside the claim so readers and AI answer systems do not receive a stronger statement than the evidence supports.
    • Do not present patient-facing AI as a replacement for qualified medical care, especially where diagnosis, medication, treatment, or urgent decisions are involved.

    For the next healthcare AI claim you encounter, write the five-part task statement before you draft a headline, approve a tool, or publish a page. Then label the highest evidence rung it has reached. If you cannot complete either step, hold the claim at capability level until the missing context is available.
    References

  • ChatGPT Ads and Privacy Controls: What You Can Change

    ChatGPT Ads and Privacy Controls: What You Can Change

    If you turn off ad personalization in ChatGPT, will your conversation stop influencing the ad you see? Under the early design, no. Personalization off prevents saved ad history and inferred interests from shaping ads, but ChatGPT may still use the current conversation to select a relevant ad.

    That distinction is the key to making a sensible privacy choice. What has surfaced so far spans an early in-app advertising test and a preview of the settings framework. Treat the controls as a provisional operating model, not a promise that every account will have the same menus, defaults, or options.

    Key takeaways

    • Ads and answers are separate. In the initial test, ads appeared beneath the chat window as distinct messages, and advertisers were not supposed to influence ChatGPT’s responses.
    • No advertiser access does not mean no contextual processing. Advertisers are not meant to receive your chats, history, personal details, or IP address, but ChatGPT may still use conversational context when deciding which ad to show.
    • Personalization off is not an ad blocker. Ads may continue to appear, selected using the current conversation rather than saved ad history and inferred interests.
    • Ad data can be managed separately. The previewed controls let you inspect and delete ad history and interests without deleting other ChatGPT data.
    • Memory introduces another choice. An additional option may let past conversations and Memory contribute to personalization. The preview indicated that this option stays inactive when Memory is disabled.

    Read the privacy promise precisely

    Several different privacy questions tend to get compressed into one: Where does the ad appear? What information selects it? What remains saved? What reaches the advertiser? Does payment affect the answer? The early framework gives different answers to each question.

    QuestionEarly positionWhat it means for you
    Where is the ad?Below the chat window and separate from the responseCheck the placement and labeling before treating commercial material as part of ChatGPT’s answer.
    Can the current conversation select an ad?Yes, even with personalization disabledTurning the toggle off does not make the conversation irrelevant to ad selection.
    What supports persistent personalization?Saved ad history and inferred interestsThese are the records to inspect or delete if you do not want past ad activity shaping later ads.
    Can past conversations and Memory be used?An additional option was previewed; it is inactive when Memory is disabledDo not assume the main personalization toggle is the only setting that matters.
    What does the advertiser receive?Not your chats, history, personal details, or IP addressA relevant ad should not be interpreted as proof that the advertiser saw your prompt.
    Can the advertiser change the answer?No influence over ChatGPT’s response was promisedPaid placement and inclusion in the generated answer should be evaluated as separate channels.

    The most important distinction is between use and disclosure. A platform can use a signal internally to choose an ad without handing the underlying material to the advertiser. That is how an ad could reflect your current question while the advertiser remains unable to read the conversation.

    This does not make every privacy question disappear. The preview does not establish how long each signal is retained, how quickly deletion takes effect, how sensitive conversational contexts are handled, or what reporting an advertiser receives. “Advertisers cannot access my chat” is a meaningful boundary, but it is not a complete description of the data lifecycle.

    Set the controls around the outcome you actually want

    A glowing current conversation connects to a blank promotional tile while an enclosed archive of older messages remains disconnected behind a privacy shield.

    Before changing anything, decide which outcome matters to you. Fewer ads, less persistent personalization, no use of past conversations, and correction of a bad inferred interest are four different goals. The previewed controls do not solve all four with one switch.

    1. Confirm that you are looking at an ad. In the initial format, commercial messages were placed beneath the chat and kept distinct from the answer. Use the visible placement and labeling rather than assuming that every product mention is sponsored.
    2. Inspect Ad History before clearing it. The preview included a history of ads viewed inside ChatGPT. Reviewing it first lets you see whether persistent ad activity reflects how you actually use the service.
    3. Review inferred interests. The Interests area was designed to collect preferences inferred from interactions and feedback. Remove an interest if it is wrong or if you simply do not want it retained for advertising.
    4. Choose whether saved signals may personalize ads. Turn personalization off if you do not want ad history and inferred interests used across conversations. Expect ads to remain, with the current conversation still available as a relevance signal.
    5. Check the separate past-conversation and Memory option. If it appears on your account, make an explicit choice instead of assuming the main personalization toggle covers it. If you already keep Memory disabled, the preview indicates that this additional feature should remain inactive.
    6. Delete ad-specific records if you want a clean slate. The preview allowed users to delete ad history and interests without changing other ChatGPT data. That makes deletion more targeted than clearing unrelated conversations or account information.
    7. Use Hide and Report for different purposes. Hide an ad you do not want. Report one that you believe needs platform review. Neither action should be confused with changing the account-wide personalization setting.

    If your priority is minimum persistent personalization, the practical configuration is straightforward: disable ad personalization, leave the past-conversation and Memory option off if it is offered, and delete ad history and inferred interests. You should still expect contextually selected ads because the current conversation remains a possible signal.

    If your priority is relevance, keep personalization enabled only after reviewing the interests attached to your account. Revisit them periodically rather than assuming an inference stays accurate. A preference inferred from one task can become misleading when your work, client, purchase, or research subject changes.

    For brands, paid placement is not the ChatGPT answer

    Blank assistant message cards and a separate advertising card move through two divided channels as three anonymous brand representatives observe.

    The initial format creates two separate visibility problems for marketers. One is earning a distinct paid placement near a conversation. The other is becoming a useful source for the answer itself. The promise that advertisers will not affect ChatGPT’s responses means an ad budget should not be treated as a shortcut to organic answer visibility.

    Build ads for the immediate decision context

    With personalization disabled, the current conversation can still provide relevance. That shifts the creative question from “Who is this person?” toward “What are they trying to decide right now?” Organize potential messages around tasks and decision stages: learning the category, comparing approaches, resolving an objection, or choosing a next step.

    • Make the offer understandable without relying on a detailed audience profile.
    • Match the ad’s promise to the destination so contextual relevance survives after the click.
    • Avoid wording that implies you have read the user’s private conversation. High relevance can already feel personal; copy that says or implies “we know what you asked” needlessly undermines trust.
    • Plan contextual and persistent-personalization campaigns as different conditions. Do not merge their performance and assume the targeting mechanism made no difference.
    • Keep paid campaign identifiers separate from organic AI referrals if the eventual buying and analytics tools permit it. Otherwise, paid placement can be mistaken for improved answer visibility.

    Keep AEO and GEO work on its own track

    Your answer-engine and generative-engine strategy still needs content that resolves the user’s question directly, uses precise language, exposes important facts clearly, and makes claims easy to verify. Advertising may create another route to attention, but it does not remove the need to earn relevance in the generated response.

    Set separate success criteria before spending begins. A paid placement can be judged by the action it generates. Organic AI visibility should be judged by whether the brand, product, evidence, or explanation appears accurately when relevant. Combining those outcomes into one “ChatGPT visibility” number would hide which system actually produced the result.

    Keep a short list of what the early controls do not prove

    A surfaced settings panel shows product direction, not a permanent contract. The initial advertising test included some Free users and users on the Go subscription, but that does not establish final eligibility, worldwide availability, frequency, pricing, or a permanent subscription policy.

    Before you write an internal policy, reassure customers, or commit campaign budget, look for explicit answers to these questions in the version available to your account:

    • Which plans and regions receive ads?
    • Is personalization on or off by default for each eligible account?
    • Exactly which interactions create or update an inferred interest?
    • How quickly do deleted ad history and interests stop affecting selection?
    • Which parts of the current conversation are eligible to provide context, especially around sensitive subjects?
    • What targeting, reporting, attribution, and retention information is available to advertisers?
    • Can users see why a particular ad was selected?
    • Do Hide and Report affect only one ad, an advertiser, an interest, or future selection more broadly?

    If the controls are not visible on your account, do not infer a hidden setting from a screenshot or preview. A limited rollout can produce different interfaces for different users. Record the account, plan, date, and options you can actually see, then base your decision on those controls.

    Marketing teams should keep a one-page assumption log with three labels: confirmed for our account, observed only in testing, and unknown. Put placement, targeting inputs, privacy boundaries, measurement, and rollout eligibility into those buckets. That small discipline prevents a previewed feature from quietly turning into a campaign promise.

    You do not need to wait for the final interface to decide your boundary. Decide now whether you accept current-conversation context, saved interests, ad history, and past-conversation or Memory use. When the controls reach your account, configure each layer deliberately. For brands, keep the channel distinction just as clear: paid placement buys an advertising opportunity; useful, verifiable content earns its chance to inform the answer.

    References

  • AI Assistant Advertising Models: A Practical Brand Guide

    If you are deciding whether to move media budget into AI assistants, the first question is not how much to spend. It is whether the assistant sells influence at all and, if it does, whether you can identify exactly what your money changes.

    That distinction matters because assistant advertising is not developing as one standardized channel. Claude has committed to an ad-free experience, while ChatGPT is opening a path toward advertising. Your plan therefore needs two lanes: paid distribution where inventory exists and organic AI visibility everywhere users may ask for recommendations.

    There is no single AI assistant advertising model

    Search advertising has familiar boundaries. A user enters a query, paid placements occupy identifiable positions, and organic results remain available alongside them. An AI assistant can collapse research, comparison, and recommendation into one generated response. That makes the commercial model more consequential: a paid element may sit much closer to the assistant’s advice than a conventional display or search ad does.

    Three relationships are especially important for planning. They are not mutually exclusive; one assistant can support user-initiated commerce while refusing advertiser-funded placements.

    ModelHow the brand participatesWhat the user experiencesYour planning priority
    Ad-supported conversationThe brand pays for eligibility in a sponsored message, link, product unit, or branded placement.Commercial content appears in or around the conversation.Verify disclosure, context controls, billing, and the separation between sponsorship and the assistant’s answer.
    Ad-free assistantThere is no sponsored-response inventory to purchase.The assistant answers without advertiser-funded placements.Invest in accurate, accessible, well-structured information that can qualify for unpaid discovery.
    User-initiated commerceThe brand can be considered when the user asks the assistant to research, compare, or help purchase something.Commercial help begins with the user’s request rather than an advertiser inserting a pitch.Make product facts, conditions, limitations, and supporting evidence easy to retrieve and verify.
    User-directed integrationA tool or service performs a function after the user chooses to invoke or connect it.The integration helps complete a task without necessarily creating sponsored exposure.Treat integration availability as product distribution or functionality, not as proof of advertising reach.

    The split is already commercially meaningful. Claude’s approximately 30 million users are outside its potential sponsored-placement market, while ChatGPT offers a possible advertising surface connected to an estimated 800 million weekly users. Those are estimates of platform audiences, not estimates of purchasable reach. They do not tell you how many people are eligible for an ad, which markets or accounts have access, how often ads appear, or whether a particular placement can reach your buyers.

    Do not put total assistant users into a media plan as though they were impressions. Ask for the addressable audience, eligible conversation contexts, available markets, delivery rules, and reporting definitions. If those details are unavailable, the audience number is market context rather than a forecast.

    The deeper difference is incentive design. Anthropic’s stated position is that advertising could undermine trust, encourage assistants to find monetizable moments, and create pressure to prolong engagement. That is Anthropic’s strategic argument for keeping Claude ad-free, not proof that every assistant ad will corrupt every answer. It does identify the right questions for a buyer to test:

    • Does sponsorship affect only the placement, or can it affect the substance, ordering, or framing of the assistant’s answer?
    • Can the user distinguish the sponsored element before interacting with it?
    • Does the disclosure remain visible when the response is expanded, copied, shared, or revisited?
    • Can you prevent placements from appearing in sensitive or unsuitable conversational contexts?
    • Is the system rewarded for resolving the user’s task, extending the conversation, or generating more commercial opportunities?
    • Can you retrieve a record of the creative, disclosure, destination, and context category that were served?

    If a platform cannot answer these questions clearly, you do not yet have enough information to evaluate brand risk. Novelty is not a substitute for placement transparency.

    Build paid distribution and organic AI visibility as separate lanes

    Assistant marketing becomes muddled when paid ads, organic citations, product recommendations, and tool integrations all appear under one AI visibility label. Separate them before assigning work, budget, or performance targets.

    Lane one: paid assistant distribution

    A paid program starts with the unit being purchased. Do not approve a line item called AI assistant ads unless the brief states whether you are buying a sponsored message, a branded module, a link, a product placement, or another clearly defined format.

    • Confirm access. Record the assistant, account type, market, language, device coverage, campaign objective, and inventory status. A platform announcement does not guarantee that your account can buy the format.
    • Define eligible context. Document what user intent or conversation category can trigger the placement. A broad audience label is not enough when the placement appears inside a highly specific exchange.
    • Capture the disclosure. Obtain an example showing the complete placement as the user sees it. Review the label, visual boundary, advertiser identity, and destination before launch.
    • Set exclusions. Identify contexts in which a commercial message would be inappropriate or risky for your brand. If the platform cannot support necessary exclusions, do not assume that careful creative will solve the placement problem.
    • Match the destination. The landing page should preserve the product, offer conditions, limitations, and expectations established by the placement. A conversational ad can feel unusually personal, so a mismatched handoff is especially conspicuous.
    • State one testable hypothesis. Decide whether the pilot is meant to generate qualified visits, purchases, leads, product consideration, or learning about a new format. Do not use platform audience size as the success metric.

    Lane two: unpaid assistant eligibility

    An ad-free policy does not make an assistant irrelevant to commerce. Claude can still help a user research, compare, or purchase products when the user requests that help; its distinction is that the commercial task is user-initiated rather than advertiser-driven. That means a brand can be discoverable without being able to buy its way into the conversation.

    This is where SEO, AEO, GEO, content quality, and structured data meet. Your objective is not to manufacture a recommendation. It is to make verifiable information available when an assistant needs to answer a relevant question.

    1. Map real decision questions. Start with the questions a buyer must resolve: what the product does, who it is for, what it works with, where it is available, what it costs, what is included, and when it is not a suitable choice.
    2. Create a canonical answer for each decision. Put the authoritative fact on a stable page instead of scattering conflicting versions across campaign pages, support documents, and old announcements.
    3. Make qualifiers explicit. Attach version, region, date, plan, compatibility, availability, and pricing conditions to the claim they qualify. An assistant cannot preserve a limitation that your page leaves implicit.
    4. Align JSON-LD with visible content. Use applicable structured-data types, such as Organization, Product, Offer, or SoftwareApplication, only for information that a reader can also verify on the page. Structured data can clarify entities and relationships; it does not make an unsupported marketing claim true or guarantee inclusion in an answer.
    5. Support important comparisons. Explain the basis of a compatibility, performance, feature, or suitability claim. Separate measured facts from editorial positioning and avoid presenting a slogan as evidence.
    6. Remove retrieval barriers. Check that public decision pages can be fetched, rendered, and understood without a login or a fragile interaction. Keep essential facts in readable page content rather than only in images or interactive widgets.
    7. Assign an owner. Product, policy, price, and availability pages need someone responsible for correcting stale facts. Display an updated date only when it reflects a genuine review.

    Paid placement may create exposure on one assistant. It will not repair contradictory specifications, inaccessible pages, vague entities, or unsupported claims. Organic readiness therefore remains infrastructure, not a fallback campaign.

    Use a six-part gate before approving an AI ad test

    A small pilot can be reasonable when the format is new, but small does not mean ungoverned. Require a written answer to each gate before money moves.

    1. Inventory gate: Is the placement available to your account in the intended market, language, device environment, and campaign period? If not, keep the item out of the committed budget.
    2. Influence gate: What exactly does payment buy? Separate eligibility for a labeled placement from influence over the assistant’s non-sponsored response. If the boundary is unclear, pause.
    3. Disclosure gate: Can a reasonable user tell what is sponsored, who paid for it, and where it leads? Review the complete rendered experience, not just the advertiser dashboard preview.
    4. Context gate: Can you target useful commercial intent and exclude contexts that would make the message intrusive, unsafe, or damaging? If context controls are weaker than your brand requirements, the inventory is not suitable.
    5. Measurement gate: Will reporting expose delivery, interaction, cost, and outcome definitions? A dashboard number without a denominator or documented event definition cannot support a scale decision.
    6. Economics gate: Is the test budget tied to a customer-value hypothesis and a stopping rule? Do not derive an acceptable price from the assistant’s total user count. Set it from the value of the outcome you can actually measure.

    Pass all six gates before treating the channel as performance media. If disclosure and context control pass but conversion measurement is weak, classify the activity as a learning or awareness test. If disclosure or answer independence fails, waiting is the clearer decision. If the assistant is ad-free, redirect the work to organic eligibility instead of searching for an unofficial shortcut.

    Include procurement, legal, privacy, and brand-safety reviewers when the placement uses personal data, operates in sensitive contexts, or creates claims with contractual consequences. The specific review depends on your market and use case; the novelty of the format does not remove existing obligations.

    Measure paid delivery, business outcomes, and organic visibility separately

    An assistant interaction can influence a decision without producing an immediate click. That does not justify vague attribution. It means you need a measurement structure that shows what is directly observed, what is attributed under your rules, and what remains unknown.

    Build the paid scorecard in layers:

    • Delivery: eligible conversation contexts, sponsored impressions, viewable placements, reach, and frequency, but only where the platform reports and defines them.
    • Interaction: placement opens, expansions, clicks, product-detail views, or other actions that can be tied to the sponsored unit.
    • Business outcome: qualified leads, purchases, subscriptions, booked meetings, or another outcome your existing analytics can validate.
    • Efficiency: cost per defined interaction and cost per defined business outcome. Preserve the event definition next to the number.
    • Quality: lead quality, cancellations, returns, or downstream customer value where those measures are relevant and available.
    • Trust and safety: complaints, unsuitable-context incidents, misleading renderings, disclosure failures, and brand-safety escalations.

    Tag paid destinations with campaign parameters and preserve the assistant, campaign, placement, creative, market, and date in your analytics records. Do not adopt a special attribution window merely because the channel uses AI. Apply your documented attribution rules, report direct and assisted outcomes separately where possible, and label modeled results as modeled.

    Incrementality deserves its own line. Use a randomized holdout when the platform supports one. Without a valid control, describe changes as observed or attributed rather than claiming the ads caused every conversion. A before-and-after increase can be useful evidence, but seasonality, other campaigns, and changes in demand can also move it.

    Organic AI visibility needs a different scorecard because no impression was purchased. Maintain a fixed set of decision prompts based on real buyer questions. For every check, record the assistant, model or product surface, market, date, account state, prompt, response, cited pages, brand inclusion, factual accuracy, and important omissions. Consistent conditions make changes interpretable; an isolated screenshot does not.

    • Track whether the brand is mentioned, but do not treat every mention as a recommendation.
    • Track whether a relevant page is cited, but inspect whether the citation actually supports the answer.
    • Track factual accuracy separately from visibility. A prominent but incorrect description is not a win.
    • Track referral traffic where it is observable, while acknowledging that some assisted journeys may not pass a usable referrer.
    • Keep paid appearances out of the organic visibility total. Sponsorship, citation, recommendation, and integration are different events.

    The final decision should be channel-specific. Scale a paid format only when delivery, business value, and placement integrity remain acceptable together. Improve organic content when assistants omit the brand, cite weak pages, or repeat stale facts. Escalate a platform issue when the disclosure, rendering, or context differs from what was approved.

    Key takeaways

    • AI assistant advertising is a platform policy, not a universal media category. Confirm that purchasable inventory exists before assigning budget.
    • Claude’s ad-free model still permits user-initiated research and commerce, so organic discoverability remains commercially relevant even where sponsored responses are unavailable.
    • A platform’s total users are not the same as addressable audience, eligible conversations, sponsored impressions, or conversions.
    • Before testing, require clear answers on paid influence, disclosure, context controls, measurement, and economics.
    • Build paid distribution and organic AI visibility as separate programs with separate metrics. Never report a sponsored appearance as an organic recommendation.
    • Accurate pages, explicit qualifiers, aligned JSON-LD, retrievable content, and maintained facts strengthen your eligibility across both ad-supported and ad-free assistants without guaranteeing selection.

    Your next move is practical: create a one-page inventory brief for every assistant ad opportunity, run it through the six gates, and establish an organic prompt-and-citation baseline before the campaign begins. You will then know whether you are buying measurable distribution, improving unpaid eligibility, or merely reacting to a large audience number.

    References

  • Publisher Opt-Outs From Google AI Search: A Practical Plan

    Publisher Opt-Outs From Google AI Search: A Practical Plan

    You want Google Search to keep finding your work, but you may not want that work used to produce answers in AI Overviews or AI Mode. The problem is that changing the wrong control could limit ordinary Search visibility without giving you the AI-specific choice you intended.

    Don’t add a guessed directive or treat every Google AI control as interchangeable. Google has confirmed that it is exploring updates that would let sites opt out of Search generative AI features, but it did not provide a launch date, directive name, implementation syntax, or final description of the consequences. Your useful work now is to separate the controls, define your decision criteria, and prepare a reversible rollout.

    The proposed opt-out is not an implementation instruction

    Google identified AI Overviews and AI Mode as the Search generative experiences at issue. It also said any new publisher control must preserve the usefulness of core Search and avoid creating a fragmented or confusing experience. That tells you why the problem is difficult, but not how the eventual mechanism will behave.

    Until Google publishes the actual specification, nobody can responsibly tell you what token to add, whether the setting will work at the domain, directory, or page level, how quickly a change will take effect, or whether opting out will alter links, previews, rankings, or eligibility elsewhere in Search. Those are unresolved product questions, not details you should fill in by analogy.

    Key takeaways

    • Google is exploring a dedicated opt-out for Search generative features; the disclosed proposal did not include deployable syntax or a release date.
    • Google-Extended addresses how site content helps train Gemini models. It should not be treated as a confirmed AI Overviews or AI Mode opt-out.
    • Robots controls, preview controls, model-training controls, and Search generative controls answer different questions.
    • Do not precommit to opting in or out until you know the final control’s scope and its relationship with ordinary Google Search.
    • Prepare an inventory, measurement baseline, approval owner, and rollback plan before the mechanism arrives.

    Separate four control layers before changing anything

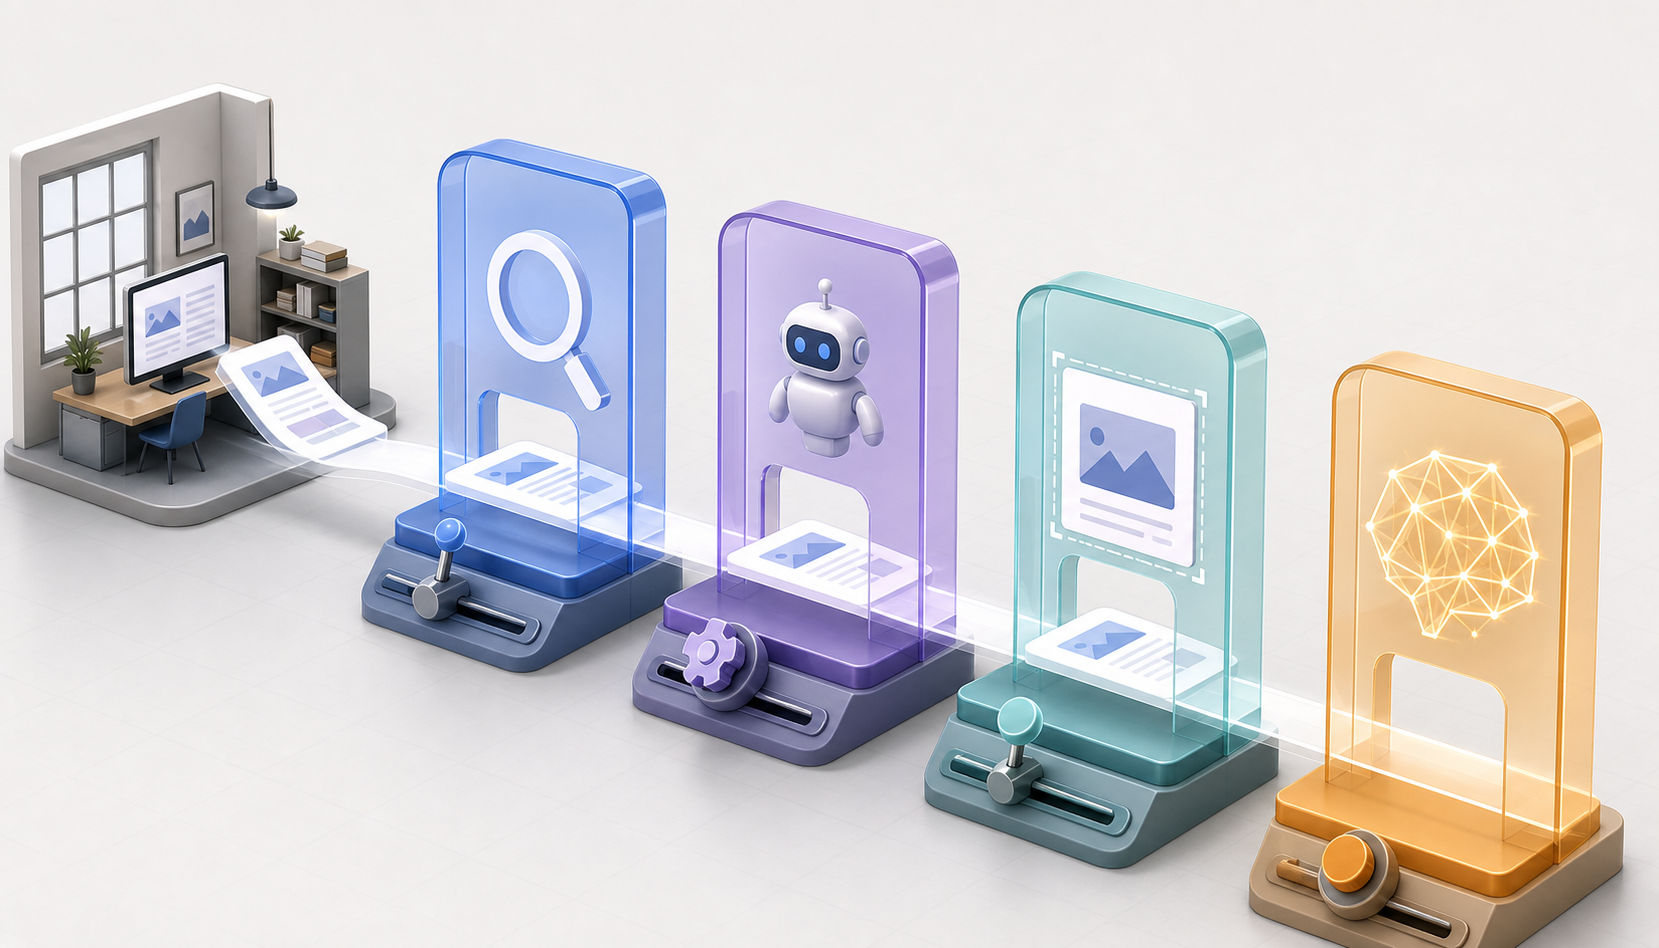
    An isometric publishing system sends a page through four separate adjustable gates representing discovery, crawler access, previews, and generative processing.

    The phrase “AI opt-out” is too broad to drive a technical change. It can refer to training a model, generating a search answer, displaying an extract, or accessing a page for core Search. Write down which use you mean before evaluating any directive.

    Control layerWhat Google has describedThe decision it addresses
    Core Search access and appearanceLong-standing publisher controls based on standards such as robots.txtHow Google may access and handle content for ordinary Search
    Search-result presentationControls for Featured Snippets and image previews, which can also be relevant to AI OverviewsHow much content Google may show as a preview or extract
    Gemini model trainingGoogle-ExtendedWhether site content may help train Gemini models
    Search generative useA proposed, not yet specified, opt-out for AI Overviews and AI ModeWhether content may be used in Google’s generative Search experiences

    The most important distinction is between model training and generation at search time. Google discussed Google-Extended as a Gemini training control and then described a separate control under consideration for Search generative features. That separate treatment means the presence of Google-Extended does not establish that a page is excluded from AI Overviews or AI Mode.

    If an audit, policy, or vendor report labels your site “opted out of Google AI” solely because Google-Extended is present, ask for product-specific evidence. The accurate statement is narrower: the setting concerns Gemini training. Keep the Search generative status marked as unresolved until Google publishes a dedicated mechanism and its scope.

    Structured data is separate as well. Schema markup helps machines interpret entities, attributes, and relationships on a page; it is not a consent or exclusion directive. Continue improving useful structured data for discoverability, but do not represent it internally as a way to grant or deny generative use.

    Decide what you are protecting and what you depend on

    Google’s stated position is that AI Overviews help people discover content and explore more topics. That is the platform’s case for generative Search, not a guarantee that your pages will receive qualified visits, conversions, subscriptions, or revenue. Your decision has to reflect how each part of your publishing business creates value.

    Start with two questions: how important is Google discovery to this content, and how strict is your policy on generative reuse? Those answers may differ across a single domain. A public help center, subscriber analysis, licensed database, product catalog, and evergreen editorial library do not necessarily need the same rule.

    • If discovery is the priority and reuse concerns are limited: do not promise an opt-out in advance. Preserve the current configuration, establish a baseline, and evaluate the documented effects when the control is released.
    • If control is the priority and Search discovery is secondary: prepare the internal approval to opt out, but make deployment conditional on confirmation that the mechanism does what your policy requires.
    • If your content portfolio is mixed: make granularity a go-or-no-go criterion. A path-level or page-level option could support different policies; a domain-wide switch could force a much larger business decision.
    • If you cannot quantify the tradeoff: plan a limited, reversible test if the final mechanism supports one. Do not turn uncertainty into a sitewide default.

    For every content family, record the outcome that matters on your own site: advertising consumption, a lead, a sale, a subscription, a download, account usage, or support deflection. Then record the competing concern: licensing limits, exclusivity, editorial policy, brand representation, or a general preference against generative use. This turns an abstract argument about AI into an explicit operating decision.

    Do not assume that the future opt-out will remove your words from a generated answer while preserving a citation, or that it will leave ordinary Search performance untouched. Do not assume the opposite either. Google has said it wants new controls to avoid breaking Search, but the final interaction has not been specified.

    If third-party licenses or contracts limit machine use, have the person responsible for those rights review the final specification before deployment. A technical setting can support a rights policy, but the mere presence of a setting does not establish that contractual obligations have been satisfied.

    Build a publisher decision package before launch

    Four publishing professionals review blank documents, a server model, abstract dashboard shapes, and two color-coded pathways around a meeting table.

    The fastest safe response to a new control will come from work that does not depend on its syntax. Build one compact decision package now so your SEO, editorial, legal, product, and engineering teams are not debating first principles after a release.

    1. Assign one accountable owner. Name the person who will confirm the final documentation, collect stakeholder approval, authorize production changes, and own rollback. Consultation can be broad; deployment authority should not be ambiguous.
    2. Inventory content by policy-relevant group. Use hostnames, directories, templates, or content types rather than starting with individual URLs. Record the business owner, discovery goal, onsite outcome, third-party rights, and desired AI policy for each group.
    3. Document the controls already in production. Capture your current robots.txt rules, Featured Snippet and image-preview choices, Google-Extended configuration, relevant page-level directives, and the systems that generate them. Label each control by its actual purpose.
    4. Save a pre-change baseline. Export organic Search impressions and clicks, important landing-page actions, conversion or subscription outcomes, and a representative record of crawl and index status. Preserve the reporting definitions so the later comparison uses the same measurements.
    5. Write a conditional decision. Use language such as: “Opt out for this section only if the final control covers AI Overviews and AI Mode, supports directory-level scope, and does not remove the section from core Search.” A condition is useful before launch; guessed syntax is not.
    6. Prepare change and rollback records. Your deployment entry should capture the exact directive, affected properties, implementation location, approver, release time, validation result, monitoring owner, and reversal procedure.

    A useful inventory can be a single sheet with columns for hostname, path or template, content owner, revenue or user outcome, Search dependency, rights constraints, existing Google controls, preferred generative policy, required granularity, approver, and rollback owner. The point is not to score every URL. It is to expose where one sitewide setting would combine content with different needs.

    Keep the measurement claim modest. A before-and-after change can show whether important site outcomes moved, but it may not prove that the opt-out caused the movement. Search demand, rankings, publishing volume, and product changes can move at the same time. Log other releases and compare equivalent content groups where the final control makes that possible.

    Require clear answers before production deployment

    When Google releases a control, read its final documentation as a specification. A headline saying that publishers can opt out is not enough. Your owner should be able to answer every question below with product documentation before approving a change.

    • Product coverage: Does the control apply to AI Overviews, AI Mode, or both? Does it cover every content format you publish?
    • Prohibited use: Does it prevent content from contributing to generated text, or does it also change links, citations, extracts, images, and previews?
    • Scope: Can you configure it by domain, subdomain, directory, template, page, or asset?
    • Core Search interaction: What happens to crawling, indexing, ranking eligibility, result links, Featured Snippets, and image previews?
    • Relationship with existing controls: Which rule wins when robots, preview, Google-Extended, page-level, and Search generative settings differ?
    • Processing: How does Google discover a change, how long may processing take, and what happens to content processed before the change?
    • Verification: Is there a testing tool, status report, inspection result, or other way to confirm that Google recognized the setting?
    • Reversibility: How do you restore eligibility, and is restoration processed on the same timetable as exclusion?

    If the mechanism is delivered through robots.txt, validate the public production file rather than only the CMS setting that is supposed to generate it. Check the response status, exact user-agent grouping, syntax, and the version served through your CDN. Confirm that an automated deployment cannot overwrite it. A misplaced rule in robots.txt can affect more than the feature you intended to control.

    If Google uses a page-level meta directive or HTTP response header instead, inspect the server-rendered HTML and live headers across representative templates. Check canonical and alternate versions, cached pages, and any CMS plugin that can emit competing directives. These are conditional validation steps; Google has not specified which delivery method the proposed control will use.

    For now, document your existing settings, correct any internal claim that Google-Extended already excludes AI Overviews, and set a release trigger. When Google publishes the final scope and syntax, your owner can compare them with the decision package, approve a narrow rollout where possible, and monitor the outcomes that matter to your business. Until that trigger is met, the right preparation is governance and measurement, not speculative code.

    References

  • How to Build Trust in AI-Driven Financial Research

    How to Build Trust in AI-Driven Financial Research

    You can make financial research easy for an AI system to find, summarize, and cite. The harder question is whether the answer remains trustworthy after the system compresses it. A careful analysis can become a dangerously confident sentence when its evidence, assumptions, or limits disappear.

    Your job is therefore larger than increasing AI visibility. You need to publish answers whose meaning survives extraction: the claim stays connected to its evidence, the reasoning can be inspected, and the boundary between general research and personal financial advice remains unmistakable.

    Key takeaways

    • Optimize financial research for verification before visibility. Search exposure cannot make an unsupported conclusion reliable.
    • Place the evidence, reasoning, relevant date, and limiting condition close to every consequential claim.
    • Connect technical signals, fundamentals, alternative data, and portfolio context without forcing them into artificial agreement.
    • Write important qualifiers into the sentence an AI system is most likely to extract, not into a distant disclaimer.
    • Use structured data and on-page optimization to describe trustworthy content, never to manufacture the appearance of authority.

    Trust begins where the answer can be checked

    Financial information has a short trust fuse because weak or inaccurate research can produce fast, measurable consequences. A vague answer about an ordinary purchase might waste time. A vague answer that influences a trade, allocation, credit decision, or risk assessment can lose money.

    That changes the minimum standard for a useful page. A reader should be able to identify what you know, how you know it, what you inferred, and what could invalidate the inference. An AI-generated summary should preserve those distinctions instead of presenting every sentence as an equally established fact.

    Use a six-field answer card

    Before drafting a financial answer, complete these six fields. They can live in your editorial brief, content management system, or review checklist:

    1. User question: Record the exact decision or uncertainty the page will address. A broad topic such as market risk is not yet a usable question.
    2. Bounded answer: Write the shortest conclusion the available evidence can support. Include the market, asset, period, or scenario that limits the claim.
    3. Evidence: Identify the underlying observations and where they came from. Preserve relevant dates, units, definitions, and methodology.
    4. Reasoning: Show how the evidence leads to the conclusion. Name any assumption that the argument needs in order to hold.
    5. Limit: State what the evidence does not establish, which alternative explanation remains possible, and what would change the conclusion.
    6. Ownership: Assign responsibility for reviewing, updating, correcting, or withdrawing the answer when its basis changes.

    If you cannot complete the evidence or limit field, do not ask a language model to fill the gap. Its fluent transition may disguise the absence of support. Publish a narrower answer, label the uncertainty, or withhold the conclusion until it can be checked.

    Separate observation, calculation, and interpretation

    A trustworthy answer distinguishes three layers that are often blended together:

    • Observation: What was measured, reported, or recorded?
    • Calculation: What transformation or comparison did you apply to those observations?
    • Interpretation: Why might the result matter, and which assumptions connect it to that meaning?

    Labeling these layers prevents an interpretation from inheriting the apparent certainty of the underlying data. It also gives an AI system clearer units of meaning to retrieve. Instead of receiving a paragraph that mixes facts and forecasts, the system encounters an explicit evidence chain.

    Keep the safety boundary close to the consequential statement. If a conclusion could influence an individual’s financial decision, present it as general research and direct the reader to a qualified financial professional for advice based on their circumstances. A footer disclaimer does not repair personalized or overly certain language in the main answer.

    Connect the evidence without hiding disagreement

    Blue and amber evidence trails remain visibly separate while connecting to a shared transparent model on a research table.

    Trust weakens when readers have to assemble an answer from unrelated dashboards, definitions, charts, and commentary. Each extra handoff introduces another opportunity to misread the period, use a different definition, or miss an important qualification. Fragmentation also makes it harder to demonstrate that you understand how the pieces relate.

    A stronger research experience connects technical signals, fundamentals, alternative data, and portfolio analysis in context. This does not mean squeezing every available metric onto one screen. It means giving the user a coherent route from question to conclusion.

    For a consequential research question, organize that route in this order:

    1. Answer: Give the bounded conclusion and its main limitation.
    2. Change: Show what happened and the comparison that makes the change meaningful.
    3. Drivers: Explain the mechanisms that could account for it.
    4. Cross-checks: Show which other evidence supports, weakens, or contradicts the interpretation.
    5. Relevance: Explain how the finding may affect a general research or portfolio question without turning it into personal advice.
    6. Method: Make definitions, provenance, calculations, and update information available where the reader needs them.

    The cross-check stage matters. Connected research is not research in which every indicator agrees. If a technical signal points one way while fundamentals or alternative data point another, preserve the disagreement. Explain whether the measures cover different time horizons, definitions, or mechanisms. If you cannot reconcile them, say that plainly.

    Clarity does not mean removing complexity. It means helping the reader distinguish relevant complexity from clutter. Even an experienced investor benefits when you explain why a development is significant rather than merely reporting that it occurred.

    A useful explanation answers five questions: What happened? Compared with what? Through which mechanism could it matter? What else could explain it? What evidence would make us revise the conclusion? Those questions turn a data display into reasoning the reader can inspect.

    Centralization can be achieved without creating an enormous page. Use shared definitions, consistent labels, visible dates, stable identifiers, and direct links between related modules. The goal is continuity of meaning. A reader moving from a chart to a methodology note should not have to guess whether the same term, period, or calculation still applies.

    Optimize for AI retrieval without manufacturing authority

    Keyword coverage can help a page become discoverable, but it cannot establish financial expertise. In AI-driven discovery, visibility increasingly depends on being consistently useful and demonstrating depth, consistency, and reasoning. That requires three separate layers of work.

    LayerQuestion to askWhat to doWhat it cannot fix
    Technical accessCan a search or AI system reach and read the main answer?Keep the substantive answer in accessible page content, maintain clear internal links, and make machine-readable descriptions consistent with what users can see.Missing evidence or an unsupported conclusion.
    Semantic extractionCan a passage retain its meaning when removed from the page?Use descriptive headings, stable terminology, explicit relationships, and short passages that keep claims beside their qualifiers.Ambiguous reasoning or conflicting definitions.
    Epistemic credibilityCan a reader inspect why the claim should be believed?Expose provenance, calculations, assumptions, counterevidence, limitations, and review ownership.Stale, inaccurate, or fabricated inputs.
    Decision safetyCould the answer be mistaken for individualized advice?Define the intended use, avoid prescriptive language about personal circumstances, and place warnings beside the relevant conclusion.A risky claim hidden behind a general disclaimer.

    Apply these layers in order. Making weak analysis easier to crawl only distributes the weakness. Adding structured data to vague content only describes the vagueness more efficiently. Technical optimization should expose a sound evidence structure that already exists on the page.

    At the page level, use these rules:

    • Lead with the bounded answer. State the conclusion, scope, and main qualification before expanding the analysis.
    • Use headings that describe the reasoning. A heading such as “Why the indicators disagree” carries more information than “Analysis.”
    • Keep one main claim per paragraph. This makes extraction cleaner and reduces the chance that a qualifier will attach to the wrong conclusion.
    • Put evidence links beside the supported claim. A generic bibliography forces readers and machines to reconstruct the relationship.
    • Keep critical qualifiers in the same sentence. Write “under these assumptions” or “for this period” where the conclusion appears.
    • Define terms once and use them consistently. If two metrics sound similar but differ, explain the distinction before comparing them.
    • Make visible content and machine-readable markup agree. Structured data should reflect the answer, authorial responsibility, and other information actually available to the reader.

    Avoid producing thin pages for every wording of the same query. Financial authority emerges from linking concepts and showing their relationships in a comprehensive answer. One well-maintained explanation with clear subtopics is usually a stronger foundation than a collection of near-duplicates that omit context.

    Run a trust audit before the page becomes an AI answer

    Three analysts inspect linked evidence nodes, blank source documents, and output layers during a research trust review.

    Your final review should test more than grammar, keyword use, and formatting. It should simulate what happens when a search engine, assistant, analyst, or hurried reader extracts only the most quotable part of the page.

    1. Build a claim ledger. Copy each consequential claim into a review sheet. Label it as an observation, calculation, interpretation, scenario, or recommendation. If the label is unclear, the sentence probably blends categories.
    2. Trace the evidence. Confirm that every observation has identifiable provenance and that the relevant date, definition, unit, and scope remain available. Do not accept a citation that merely discusses the same topic.
    3. Reperform the reasoning. Follow the path from evidence to conclusion without relying on the prose’s confidence. Check whether a missing assumption or alternative explanation breaks the chain.
    4. Test the qualifier. Copy the key conclusion into a blank document. If it becomes misleading without a nearby paragraph, rewrite the sentence so its essential boundary travels with it.
    5. Look for forced agreement. Identify evidence that conflicts with the conclusion. Explain the disagreement, narrow the claim, or state that the result is unresolved.
    6. Check the decision boundary. Ask whether a reasonable reader could mistake general research for an instruction tailored to their finances. If so, revise the language and position professional-help guidance next to the risk.
    7. Assign the next review. Record what type of change would trigger reassessment and who can correct or withdraw the conclusion. Trust depends on how you handle changed information, not only how carefully you launch a page.

    Use a simple release gate. Publish when the evidence, reasoning, scope, and limits are all inspectable. Revise when the evidence is sound but the extracted answer could mislead. Hold the page when a consequential conclusion cannot be verified. Do not let polished AI-generated prose turn that third condition into the second.

    Start with one financial page that already attracts an important question. Rebuild it around the six-field answer card, connect the evidence that a reader would otherwise have to assemble, and run every key sentence through the extraction test. Once it passes, use that page as the editorial pattern for your wider AI search strategy.

    References

  • Are ChatGPT App Suggestions Ads? How to Tell What You Saw

    Are ChatGPT App Suggestions Ads? How to Tell What You Saw

    If a Target or Peloton card appeared inside your ChatGPT experience, you weren’t unreasonable to read it as an ad. A brand logo, a shopping-oriented message, and a call to action are the same visual signals that advertising uses across the web.

    But appearance alone doesn’t tell you whether a brand paid for the placement. OpenAI’s stated position was that these were recommendations for apps on its platform, with no financial component and no live advertising test. That distinction matters to users deciding whether to trust the interface and to marketers deciding whether a new media channel actually exists.

    An ad-like recommendation is not necessarily a paid ad

    The word “ad” can collapse three different questions into one. Separate them before you judge a ChatGPT suggestion:

    • How does it look? A logo, prominent brand name, product message, or action button gives a suggestion a promotional appearance.
    • Why was it selected? The recommendation mechanism determines why one app or brand appeared instead of another. A screenshot normally cannot reveal that mechanism.
    • Was money involved? Payment, sponsorship, bidding, or another financial arrangement would support calling the placement advertising. Promotional presentation by itself does not prove any of them.

    The controversial suggestions clearly triggered the first question. Their presentation looked commercial. OpenAI denied the third: it said the recommendations had no financial component. The available information did not explain enough about the second question for anyone outside OpenAI to make a reliable claim about selection or ranking.

    The most accurate description is therefore narrower than either “ChatGPT launched ads” or “nothing happened.” Users encountered app recommendations with an ad-like presentation, while OpenAI maintained that the placements were unpaid.

    That wording doesn’t excuse the design. People interpret an interface through the signals it gives them, not through distinctions supplied after screenshots circulate. OpenAI acknowledged that it had fallen short and disabled the app suggestions while working on accuracy and better user controls. The response confirms that perceived promotion was a product and trust problem even under the company’s unpaid-recommendation explanation.

    Use this six-question test for any branded suggestion

    Hands use a magnifying glass to inspect visual clues on a generic digital recommendation card displayed on a tablet.

    You don’t need to accept a platform’s label blindly, but you also shouldn’t infer an advertising program from one brand card. Work through the visible evidence in order.

    1. What did you ask for? Save the prompt and the preceding messages. A relevant app suggestion after you requested help shopping is materially different from an unexplained retail card during an unrelated task.
    2. What label appeared? Record the exact wording, including terms such as “ad,” “sponsored,” “promoted,” “recommended app,” or “suggested.” No label is also a meaningful observation.
    3. What promotional elements were present? Note the logo, brand name, offer language, image, button text, and prominence relative to the answer. These elements establish how the placement was presented, even when they don’t establish payment.
    4. Where did the action lead? Check whether the button opens an app within ChatGPT, starts an installation flow, or sends you to an external merchant. The destination helps identify the surface you are evaluating.
    5. Is a financial relationship disclosed or confirmed? Look for an explicit sponsorship disclosure or a clear platform statement about payment. If neither exists, the economics are unknown. Don’t convert “unknown” into either “paid” or “organic.”
    6. Could you control it? Check for dismiss, hide, feedback, personalization, or recommendation controls. Record whether the choice applies to one card or to future suggestions. A dismiss button reduces immediate friction; it does not answer how the placement was selected.

    This test gives you defensible language for reporting what happened. Use confirmed paid placement only when payment or sponsorship is established. Use unpaid app recommendation with promotional presentation when the platform denies a financial component but the interface resembles an ad. Use unexplained branded suggestion when neither the selection process nor the economics is known.

    A single screenshot can document that a placement appeared. It cannot, by itself, prove broad availability, personalization, targeting, payment, ranking criteria, or a permanent product launch. Keep each claim within the evidence you captured.

    What to do when a suggestion crosses the line for you

    If you’re a ChatGPT user, a precise report is more useful than a general accusation that the product is “showing ads.” It lets the product team identify the prompt, placement, label, and missing control that created the problem.

    1. Capture the complete context. Save the prompt, relevant earlier messages, full recommendation, visible label, account tier, and destination. Include the time if you are reporting an intermittent experience. Redact personal or commercially sensitive information before sharing a screenshot publicly.
    2. Describe the mismatch. State whether you asked for shopping help, an app, or a brand recommendation. If the suggestion was irrelevant, name the task it interrupted.
    3. Describe the presentation. Instead of relying only on the word “ad,” identify the elements that made it feel paid: logo, retail language, button, placement, repetition, or lack of separation from the answer.
    4. Use available feedback and controls. Dismiss or hide the card if those options are present, then report whether the preference persists. If no meaningful control exists, say that explicitly.
    5. Ask the questions the interface didn’t answer. Was the placement paid? Why was this app selected? Did the recommendation use conversation context? Can similar suggestions be disabled? These are separate questions and deserve separate answers.

    Don’t infer a privacy violation merely because a branded card appeared. The card may give you a reason to ask how relevance was determined, but it does not prove that personal data was sold, shared with the brand, or used for behavioral targeting. Those claims require evidence beyond the visual placement.

    Paying for ChatGPT can make an unexpected commercial-looking prompt feel especially intrusive, but subscription status doesn’t reveal the placement’s economics either. Keep the complaint focused on what can be established: the suggestion appeared, it looked promotional, it was or wasn’t relevant, and the interface did or didn’t provide adequate disclosure and control.

    Marketers should classify the surface before claiming a win

    A marketing analyst compares three unlabeled display panels representing organic, partnership, and paid app exposure.

    For marketers, the biggest immediate risk is not missing an ad opportunity. It is reporting an app suggestion as paid media, organic visibility, or GEO performance without evidence for any of those classifications.

    SurfaceEvidence you needHow to report it
    Brand mention in an answerThe generated response names or discusses the brandAI brand visibility; do not call it paid or organic unless the mechanism is known
    App suggestionA distinct app card, logo, recommendation label, or app-opening actionApp recommendation, with its label, prompt context, and destination recorded
    Paid advertisementA confirmed financial component, sponsorship disclosure, or explicit ad labelAdvertising, separated from answer visibility and app discovery

    That separation prevents three common errors.

    • Don’t create a media budget from screenshots. OpenAI said the disputed suggestions were unpaid and that no live ad test was running. Without inventory, buying terms, targeting options, pricing, or reporting, there is no verified advertising product to plan against.
    • Don’t claim an AI optimization result without a selection model. A brand’s appearance does not reveal whether content, app metadata, platform integration, prompt context, an experiment, or another factor caused the selection. If the mechanism is unknown, attribution is unknown.
    • Don’t merge app referrals with answer visibility. A click from an app card and a brand citation inside a generated answer are different user journeys. Track them separately if your analytics can identify them, and leave the source unclassified when it cannot.

    If your organization has an app available through ChatGPT, review the experience from the user’s side. The app name should make its purpose clear. The call to action should accurately describe what happens next. The destination should match the promise in the card. And the experience should not depend on users mistaking a recommendation for a neutral part of the answer.

    Actual advertising, if it arrives later, should be evaluated as a separate product. OpenAI’s advertising initiatives were reported as delayed while the company prioritized ChatGPT quality. A delayed initiative is not live inventory, but it is not a guarantee that advertising will never launch. Wait for verified buying documentation and visible disclosure rules before treating it as a channel.

    A credible AI advertising product would need to answer practical questions before a marketer commits money: What is sponsored? Where can it appear? How is it separated from the generated answer? Why was it shown? Can a user dismiss or disable it? What does the advertiser receive in reporting? Until those answers exist, planning should remain a scenario exercise rather than a forecast.

    Key takeaways

    • The Target and Peloton-style suggestions looked like ads because they used familiar promotional signals, including brand identity and calls to action.
    • OpenAI said the placements were app recommendations with no financial component and denied that live advertising tests were underway.
    • An ad-like appearance establishes a transparency concern, not a paid relationship. Payment, selection, and presentation are separate questions.
    • Users should capture the prompt, label, card, destination, relevance, and available controls before reporting a questionable suggestion.
    • Marketers should report answer mentions, app recommendations, and confirmed paid ads as separate surfaces.
    • No brand should treat a screenshot as proof of ad inventory, GEO performance, targeting, or a repeatable ranking advantage.

    For the next branded suggestion you encounter, don’t start with the argument over what to call it. Capture what appeared, test what the interface discloses, and classify only what the evidence supports. That gives users a sharper complaint and marketers a cleaner decision than the word “ad” can provide on its own.

    References

  • CrushPress AI Schema Suite 4.2.63: Practical Upgrade Guide

    CrushPress AI Schema Suite 4.2.63: Practical Upgrade Guide

    If you’re moving from CrushPress AI Schema Suite 4.2.43 to 4.2.63, the biggest change is operational: the plugin now makes it easier to see what is blocking automation, understand what the dashboard is showing, and control when work runs.

    Your first job after the upgrade isn’t to launch a site-wide run. It is to verify billing, privacy, OpenAI access, and queue behavior in that order. This prevents a configuration problem from being mistaken for a processing problem.

    Clear the dependencies that can block every run

    Four gated system checkpoints show payment, privacy, cloud access, and queued processing in a left-to-right sequence.

    Version 4.2.63 puts billing and connectivity notices at the top of every CrushPress screen. Treat those notices as prerequisites. A missing billing plan, an invalid OpenAI key, and a privacy opt-out can all stop the workflow, but they require different fixes.

    1. Open the CrushPress dashboard and deal with any billing-plan alert first. The alert includes a direct route to the relevant fix, so you don’t need to search through unrelated settings.
    2. Open the Privacy tab before testing the AI connection. If remote access is opted out, 4.2.63 deliberately pauses all remote calls. That is expected privacy behavior, not evidence of a broken key.
    3. Validate the OpenAI key with the inline diagnostic. When a submitted key is incorrect, the plugin explains the problem in plain language and retains an already working key instead of replacing it with the invalid value.
    4. Check the AI Engine card. Confirm that its connection status, selected model, and reasoning-effort display match the configuration you intend to use.
    5. Read the remaining checklist reminders, then use the one-click diagnostic before starting a larger processing run.

    This order matters. Testing an OpenAI connection while remote calls are paused can send you toward the wrong repair. Likewise, changing a valid key won’t resolve a missing billing plan. Diagnose the visible prerequisite rather than rotating settings until an alert disappears.

    Set automation limits before you process content

    The general settings in 4.2.63 bring four important automation decisions into one place. Make each decision deliberately before running the plugin across more than a small set of content.

    • FAQ limits: Set a limit that matches the amount of FAQ output your team can inspect. A larger queue has little value if nobody can review whether the questions and answers accurately reflect the page.
    • Speakable: Turn this on only when Speakable output is part of your implementation plan. Don’t enable it simply because the control is available.
    • Queue-only mode: Use this when you want work collected in the queue for deliberate processing. It is the safer choice when an editor or technical owner needs to inspect scope before execution.
    • Recurring refresh schedules: Match the refresh schedule to how often the underlying content materially changes. Stable pages do not need the same operational cadence as frequently revised content.

    Run, queue, and purge controls are available from both the dashboard and the Pages & Posts screens. Use the page-level controls when you are validating a known piece of content; use broader dashboard actions only after that smaller test behaves as expected.

    Treat purge as a potentially destructive operation. Before using it, read the scope presented in your installation and preserve any logs or state you may need for diagnosis. If the scope isn’t clear, stop and confirm it rather than using purge as a generic troubleshooting button.

    Do not mistake sample data for live performance

    A fresh 4.2.63 installation can display realistic sample information in trend charts, schema coverage, FAQ activity, and processing logs. This is an onboarding aid: it shows you how a populated dashboard will look before automation has produced enough real activity.

    The practical distinction is simple. Sample trends help you learn where information will appear; they do not prove that your pages have been processed or that schema coverage has changed.

    1. Verify the AI Engine connection and clear the visible alerts.
    2. Select one known page from Pages & Posts.
    3. Queue or run that page using the control appropriate to your workflow.
    4. Review the resulting processing log and activity areas.
    5. Only then use dashboard-wide coverage and trend views to monitor actual work.

    This small test gives you a recognizable input to follow through the system. If the result isn’t what you expected, you have a narrow case to diagnose instead of an ambiguous site-wide run.

    Turn persistent alerts and logs into an operating routine

    An operator reviews abstract status indicators and blank log cards while an amber alert moves into a resolved tray.

    System notices and logs now remain visible at the top of CrushPress screens, so a billing or connectivity issue is harder to miss while you move between settings and content. Scan that area whenever you begin a processing session and again before investigating an empty or stalled queue.

    The interface also uses more consistent buttons, inline status messages, and clearer empty states. Pay attention to those messages after an action. They are the fastest way to distinguish an accepted command from a screen that merely has nothing to display yet.

    If you need support, build the ticket around one reproducible action. Include the screen involved, the action you selected, what you expected, the exact alert or diagnostic explanation, and the relevant log context. The richer media-upload workflow in 4.2.63 lets you attach visual evidence without moving through a separate support process, while the tightened privacy flow helps keep the submission deliberate.

    The sticky WordPress administration footer also remains visible when the CrushPress billing view is locked. Its standard WordPress text and version information provide useful environment context when you document a problem, even though the footer itself does not change automation behavior.

    Key takeaways for a controlled 4.2.63 rollout

    • Resolve missing billing-plan notices before troubleshooting processing.
    • Check the Privacy tab before diagnosing OpenAI connectivity because opting out intentionally pauses every remote call.
    • Use the inline key validator; an invalid submitted key will not displace a working one.
    • Configure FAQ limits, Speakable, queue-only mode, and recurring refreshes before broad runs.
    • Regard fresh-install charts and activity as sample data until a known page has moved through your own workflow.
    • Test one page first, inspect its logs, and expand the processing scope only after the result is understood.

    Once 4.2.63 is installed, start with the dashboard alerts and finish with one controlled page-level run. That short validation path gives you a known-good configuration before recurring schedules or broader automation increase the scope.

    References

    • CrushPress.AI – Version 4.2.63 released